Tag: AI Tools

  • How to Evaluate Leading AI Software Companies in 2026

    How to Evaluate Leading AI Software Companies in 2026

    If you are shortlisting AI software companies, a generic ranking answers the wrong question. A company can lead at the model layer and still be a poor choice for deploying a governed workflow inside your business.

    Your real task is to identify the kind of company you need, define what leadership means for your use case, and make each candidate prove it with your workflow and representative data. That turns a crowded market into a decision you can defend.

    Start with the job, not the company ranking

    There is no useful universal winner. A packaged AI application, a model provider, a cloud platform, and a custom development company solve different parts of the problem. Ranking them together is like ranking an engine, a delivery van, and a logistics contractor on the same scale.

    Before you collect vendor names, write a short procurement brief. It should be specific enough that another person could recognize a successful deployment without hearing the sales pitch.

    • Workflow: Name the task or decision the software will support. Avoid broad goals such as “use AI for marketing.” A workable definition is closer to “produce a cited first draft from approved product documentation for an editor to review.”
    • Owner: Identify the person accountable for the workflow after launch. A sponsor can approve a purchase, but an operational owner has to manage errors, updates, and user adoption.
    • Inputs: List the documents, databases, messages, images, or application events the system may use. Record where that data lives and who has permission to expose it.
    • Output and action: State what the system produces and what happens next. Distinguish a suggestion shown to a person from an action executed in another system.
    • Failure boundary: Describe acceptable mistakes, unacceptable mistakes, and the point at which a human must intervene. A formatting error and an invented compliance claim cannot share the same severity.
    • Environment: Name the identity system, content repository, analytics stack, customer platform, or other software the product must work with.
    • Evidence: Define what a candidate must demonstrate using representative cases. A polished demonstration using vendor-selected examples is not evidence of fit.
    • Exit conditions: Decide what data, configurations, prompts, evaluation cases, logs, and code you must be able to recover if you change providers.

    If you cannot complete this brief, pause the vendor search. When the outcome is vague, almost any demonstration can look successful, and disagreements about quality appear only after money and integration work have been committed.

    Compare companies that perform the same role
    Four distinct AI software workstations connect to the same central business task for a role-based comparison.

    The label leading AI software development companies can cover businesses with very different products and delivery models. Put each candidate into a functional category before you compare features, pricing, or market visibility.

    Company typeChoose it whenEvidence to requestCommon mismatch
    Model or API providerYour team is building its own application and needs model capabilities as a component.Results on your evaluation cases, usage controls, model-change procedures, latency behavior, and data-handling terms.Buying raw capability when you do not have the engineering or operational team to turn it into a reliable workflow.
    Cloud or data platformYour priority is connecting AI to governed data, existing infrastructure, and enterprise controls.Architecture fit, identity integration, data boundaries, deployment options, monitoring, and portability.Assuming platform breadth means the desired business application is already complete.
    Packaged AI applicationYou need a defined outcome in a familiar function such as content operations, support, analytics, or sales workflow.Workflow coverage, administrator controls, export options, user permissions, integration depth, and evidence from representative tasks.Paying for a broad feature set while the product remains weak at the narrow task that matters.
    Workflow or agent platformYou need AI to coordinate steps, tools, and approvals across systems.Action permissions, state handling, retries, approval gates, audit logs, failure recovery, and limits on autonomous behavior.Treating an impressive prototype as a dependable operational process.
    Custom AI development companyNo packaged product fits the workflow, or your process and data create meaningful differentiation.Proposed architecture, delivery ownership, evaluation method, repository access, documentation, deployment plan, support model, and intellectual-property terms.Commissioning custom software before confirming that the workflow is stable enough to specify and maintain.
    AI operations or governance providerYou already have AI systems and need evaluation, observability, policy enforcement, or control across them.Coverage of your actual stack, alert quality, policy implementation, evidence retention, and response procedures.Expecting a control layer to repair poor application design or unsuitable source data.

    A candidate can belong to more than one category, but you should still name the role you are buying from it. Otherwise, a vendor’s strength in one layer can distract you from a gap in another. If you need a finished application, model quality alone does not settle the decision. If you need a model component, a large catalogue of packaged features may be irrelevant.

    Turn “leading” into pass-or-fail requirements

    Feature counts reward breadth, and weighted scorecards can hide a fatal weakness behind a high total. Use non-negotiable gates first. Score or rank only the companies that pass every gate that protects the workflow.

    • Task performance: The product must produce usable results on ordinary cases, difficult edge cases, and inputs that should trigger refusal or escalation. Define “usable” in terms of the next step in the workflow, not whether the output sounds polished.
    • Evaluation discipline: Ask how the company detects regressions and separates different error types. For generated answers, completeness, factual support, citation quality, format compliance, and harmful fabrication are different dimensions. A blended quality claim can conceal the failure that matters most to you.
    • Data governance: Get written answers about retention, use of customer data for training, storage location, deletion, subprocessors, tenant separation, and access by vendor personnel. Product controls and contract language should agree.
    • Security and human control: Confirm authentication, role-based access, approval steps, auditability, and the ability to stop or override automated actions. The more consequential the action, the less acceptable an invisible decision path becomes.
    • Integration depth: Distinguish a live, supported integration from a demonstration, roadmap item, or generic API. Verify the exact records the system can read, create, update, and export.
    • Operational resilience: Ask what happens when a model, connector, data source, or downstream system fails. A production workflow needs observable errors, safe fallbacks, ownership, and a recovery procedure.
    • Commercial fit: Calculate the cost of the working process, including usage, integration, human review, monitoring, support, and ongoing evaluation. A low software price can still produce an expensive workflow if reviewers must repair most outputs.
    • Exit viability: Confirm that you can retrieve business data and the operational assets needed to continue elsewhere. For custom development, define ownership of code, prompts, configurations, documentation, and deployment materials before work begins.

    Treat unsupported roadmap promises as unavailable. Record each capability as proven, contractually committed, or absent. Those labels keep a persuasive demonstration from turning future intent into present functionality.

    References and customer logos can help you understand where to investigate, but they do not replace workflow evidence. Ask references about deployment effort, failure handling, support after the sale, and what their internal team still has to operate. A similar industry is useful; a similar data shape, risk level, and workflow is better.

    Run a production-shaped proof before you commit
    A business and engineering team observes an AI proof-of-concept moving through security, human review, monitoring, and final delivery stages.

    A proof should test the operating system around the AI, not just the most attractive output. Keep the workflow narrow enough to inspect closely, but preserve the data conditions, permissions, integrations, and review steps that will exist in production.

    1. Freeze the use case. Give every candidate the same workflow definition, input boundaries, expected output, and failure rules. Do not let each vendor redefine success around its strongest feature.
    2. Build the evaluation set. Include routine examples, ambiguous inputs, incomplete information, edge cases, and requests the system should decline or escalate. Keep a portion of the cases out of vendor-led configuration so you can see how the system handles unfamiliar inputs.
    3. Protect sensitive information. Use de-identified or synthetic material until contractual, security, and internal approvals permit representative production data. When real data becomes necessary, expose only what the approved test requires.
    4. Record configuration work. Track the prompts, rules, connectors, data cleanup, and human assistance required to achieve the result. A system that performs well only after extensive hidden preparation may carry a much higher operating cost than the demonstration implies.
    5. Test the whole handoff. Measure whether users can review, correct, approve, reject, and trace the output inside the intended workflow. A strong answer copied manually between applications may still be a weak production solution.
    6. Force recoverable failures. Remove a source, deny a permission, provide conflicting information, or interrupt a downstream service in a controlled test. Check whether the system fails visibly, preserves state, avoids unsafe actions, and gives an operator a clear recovery path.
    7. Review the evidence by error type. Keep a failure log that identifies what went wrong, its consequence, whether a person detected it, and whether the proposed fix is repeatable. Do not average a severe failure into a reassuring overall score.
    8. Price the observed workflow. Use the actual configuration, workload shape, review effort, support requirement, and integration pattern from the proof. Model an increase and decrease in usage so you can see which charges are fixed and which scale with activity.
    9. Test the exit. Export representative data and configuration, inspect its format, and identify what cannot move. For a custom system, verify access to the repository, build instructions, environment configuration, and operating documentation.

    The proof should leave you with artifacts you can inspect later: the frozen evaluation set, result sheet, failure log, data-flow map, architecture diagram, cost model, operating runbook, and exit plan. If the only durable artifact is a presentation, you have evaluated a sales process rather than a production system.

    Reject any company that fails a non-negotiable gate, even if it has the highest total score. Among the survivors, prefer the option that reaches the required outcome with the clearest controls, lowest operational burden, and most credible path out. That is a more useful definition of leadership than size, visibility, or the longest feature list.

    Key takeaways for your shortlist

    • Define the workflow, owner, data, action, failure boundary, evidence, and exit conditions before collecting vendor names.
    • Compare model providers with model providers, applications with applications, and development companies with development companies.
    • Make task performance, data governance, security, operational resilience, economics, and exit viability pass-or-fail gates.
    • Use the same production-shaped evaluation cases for every candidate, and keep severe errors visible instead of burying them in an average.
    • Count configuration, integration, review, monitoring, and support when calculating cost.
    • Choose the company that can prove the required outcome and remain operable when inputs, systems, or providers change.

    Take your current list and write each company’s intended role beside its name. Remove candidates that solve a different layer, send the survivors the same procurement brief, and do not declare a leader until the proof produces evidence your operational owner is willing to accept.
    References

  • Rubric-Based AI Prompting: A Practical Reliability Framework

    Rubric-Based AI Prompting: A Practical Reliability Framework

    The draft looks finished. The structure is clean, the tone is right, and the citations look plausible. Then you check one claim and discover that the evidence is not there. Editing that sentence treats the symptom; the prompt still rewards a complete answer more than a defensible one.

    Rubric-based prompting changes that incentive. You tell the model not only what to produce, but how to decide whether it has enough support, when it may infer, when it must qualify, and when it should stop. That is the difference between requesting a polished deliverable and defining a controlled production process.

    Why polished prompts still fail when information is missing

    A conventional prompt usually describes the destination: write an article, analyze a competitor, summarize a document, or recommend a strategy. It may specify the audience, tone, length, headings, and output format. Those instructions can improve presentation without resolving the most important question: what should the model do when it cannot support part of the requested answer?

    If you request a complete deliverable but provide incomplete evidence, the model faces competing objectives. It can acknowledge the gap and leave part of the task unfinished, or it can produce something fluent enough to resemble completion. Unless you define which objective has priority, fluency can win.

    This matters in content, SEO, AEO, and GEO workflows because unsupported material rarely stays in one draft. A fabricated statistic can migrate into a headline, executive summary, FAQ, metadata, structured data, presentation, or client recommendation. The first error may be a sentence. The operational problem is the chain of assets built from it.

    The downside is not theoretical. In 2025, Deloitte had to refund substantial costs associated with a government report containing AI errors, including fabricated citations. That is an extreme outcome, but it illustrates the basic risk: an authoritative-looking answer can travel farther than its evidence warrants.

    A vague prompt is not the only reason an AI system can be wrong, and no rubric can guarantee truth. Models can misunderstand material, mishandle conflicting evidence, or generate an incorrect answer despite clear instructions. A rubric addresses the preventable part of the problem: ambiguity about evidence, uncertainty, inference, and failure behavior.

    The distinction is simple. A prompt describes what a successful output should contain. A rubric defines the decisions the model must make when success is not fully possible. It replaces requests such as be accurate or do not hallucinate with conditions that can actually govern the response.

    Build the rubric around decisions, not aspirations

    Hands sort abstract document cards through green, amber, and red decision paths for supported, uncertain, and unsupported material.

    An instruction such as use reliable information sounds responsible, but it leaves every operational term undefined. Which information is authorized? What counts as support? May the model draw an inference? Should it omit an unsupported section, qualify it, or ask you a question?

    A useful rubric resolves those choices before generation starts. Build yours around the following decisions.

    1. Define the evidence boundary. Name the material the model may use: supplied documents, approved URLs, a product fact sheet, a transcript, a dataset, or general background knowledge. If freshness matters, state whether information outside the supplied material is prohibited or must be separately verified. Do not use an open-ended phrase such as credible sources when you need a closed evidence set.
    2. Classify claims by support. Tell the model to distinguish facts directly supported by the authorized material from reasonable inferences, unresolved conflicts, and unavailable information. Give each state a visible treatment. A supported fact may be stated normally. An inference should be labeled. A conflict should remain visible. An unavailable claim should be omitted or marked as needing evidence.
    3. Identify material uncertainty. Not every missing detail should stop the task. Define a gap as material when it could change the central claim, recommendation, audience, scope, or risk. The model may proceed with a harmless formatting choice, but it should not quietly invent a product capability, legal requirement, price, quotation, date, or performance result.
    4. Specify the fallback behavior. Decide what should happen when a criterion fails. Your choices include asking a blocking question, returning a partial answer, labeling a provisional assumption, inserting a clear evidence placeholder, or declining the unsupported portion. Without a fallback, even a good accuracy rule leaves the model to improvise.
    5. Set an acceptance test. Describe what must be true before the response is considered complete. For example, every factual claim must map to authorized evidence; every inference must be labeled; every citation must support the adjacent claim; and summaries, FAQs, metadata, and structured fields must not introduce facts absent from the approved material.

    Put these rules in priority order. If accuracy and completeness conflict, say which one wins. If the requested format requires a statistics section but no statistics are available, the rubric should instruct the model to flag the missing evidence instead of manufacturing a plausible number to preserve the format.

    The same principle applies to conflicts among inputs. Do not tell the model merely to resolve discrepancies. Tell it whether to prefer a designated primary record, use the most applicable version, present both positions, or stop and ask. Otherwise, the final answer may hide the disagreement behind confident prose.

    Keep the rubric concise enough to enforce. Repeated rules written in slightly different ways can create new conflicts. Each criterion should contain a trigger, a required action, and a visible outcome. If you cannot tell whether the output passed a criterion, rewrite the criterion.

    A copy-ready rubric for content and SEO workflows

    You do not need to rebuild the framework for every task. Keep a stable core and add task-specific rules only where the risk changes.

    Reusable prompt block

    Place this block after the task, audience, context, and required output format. Replace the bracketed fields with boundaries that match your workflow.

    • Priority: Factual support and transparent uncertainty take precedence over completeness, fluency, tone, and length.
    • Authorized evidence: Use only [approved inputs] for factual claims about [subject]. Do not treat a requested claim as evidence that the claim is true.
    • Supported claims: State a factual claim only when the authorized evidence supports that specific wording and scope. Do not broaden a narrow claim.
    • Inferences: You may infer only when the conclusion follows reasonably from the evidence and does not introduce a new factual detail. Label the conclusion as an inference and identify the evidence behind it.
    • Missing or conflicting information: Do not invent names, numbers, dates, quotations, citations, URLs, capabilities, examples presented as real, or research findings. Mark unsupported items as [preferred label]. Preserve material conflicts instead of silently choosing a side.
    • Clarification rule: Ask a blocking question before drafting when the missing information could change the central claim, recommendation, audience, scope, or risk. Otherwise, continue and record the limitation.
    • Final check: Before returning the answer, remove or label every unsupported claim, confirm that each citation supports the claim beside it, and confirm that derivative sections introduce no new facts.
    • Response: Return the requested deliverable followed by a short exception log containing material omissions, labeled inferences, unresolved conflicts, and blocking questions. Do not return hidden reasoning or a generic assurance that the answer is accurate.

    The exception log is important because it makes failure visible without requiring you to inspect the model’s internal reasoning. If the log is empty but the draft contains unsourced specifics, the output has failed the rubric.

    Worked example: an evidence-controlled content brief

    Suppose you ask AI to create an AEO-focused brief from an approved product fact sheet, a set of customer questions, and selected reference pages. A normal prompt may request key claims, search intent, supporting statistics, FAQs, and suggested structured content. The format is clear, but the evidence rules are not.

    Add task-specific criteria such as these:

    • Use the approved packet for every product claim, date, number, quotation, comparison, and attributed statement.
    • Do not invent search volume, ranking difficulty, trend data, customer stories, survey findings, product limitations, or competitor capabilities.
    • Separate evidence-backed audience questions from editorial questions proposed for further research. Do not present a suggested question as observed search behavior.
    • Separate factual claims from recommendations about page structure. A heading recommendation does not need to masquerade as a fact about the market.
    • Create a claim register that pairs each publishable factual claim with the item that supports it. If no item supports the claim, label it Needs evidence.
    • Apply the same evidence boundary to the summary, FAQ, metadata, and any structured fields. Changing the format does not authorize a new claim.
    • Return blocking questions before the brief when missing information would change the page’s audience, core promise, or factual position.

    This version still lets the model help with organization and editorial planning. It removes permission to imitate missing research. That distinction prevents a common failure: treating the model’s familiarity with the shape of an SEO brief as evidence for the facts inside it.

    Test the rubric with deliberately incomplete input. Remove the support for a requested statistic, product claim, or quotation while leaving the request in place. A passing response should flag the gap, ask a material question, or omit the unsupported item according to your rule. If it produces a plausible replacement, tighten the evidence boundary and failure action before using the prompt in an automated workflow.

    Review the output with a separate acceptance rubric

    A separate reviewer checks an AI-produced manuscript against evidence tokens and sets one questionable fragment aside.

    The generation rubric controls how the draft should be produced. An acceptance rubric controls whether that draft can move forward. Separating the two prevents a polished response from being treated as approved merely because it followed the requested structure.

    Use clear statuses such as pass, revise, and block. A numeric score can hide a serious defect inside an acceptable average. One fabricated citation should block publication even if the tone, organization, and formatting are excellent.

    CriterionPass conditionFailure action
    Evidence coverageEvery externally verifiable factual claim is traceable to an authorized input or visibly labeled as an inference.Remove the claim, add appropriate evidence, or change its status.
    Citation fitEach citation exists and supports the exact claim, scope, and qualification beside it.Replace the citation, narrow the wording, or block the claim.
    Uncertainty handlingMaterial gaps and conflicts remain visible; low-impact assumptions are identified where relevant.Add a qualification, request clarification, or return the item for research.
    Instruction priorityThe output meets the task without violating higher-priority evidence and uncertainty rules.Revise the deliverable instead of waiving the higher-priority rule.
    Claim propagationSummaries, FAQs, metadata, and structured fields contain no unsupported facts copied from or added to the main draft.Remove the derivative claim or supply support before publishing.
    Exception logMaterial omissions, inferences, conflicts, and questions are specific enough for a reviewer to resolve.Replace generic caveats with the affected claim, missing input, and required next action.

    You can ask the model to apply this acceptance rubric to its own output, but treat that as a consistency check, not independent verification. The same system that generated an unsupported claim can overlook it during self-evaluation. A person should still open important citations, compare claims with the underlying material, and review conclusions that affect money, legal exposure, health, reputation, or publication under someone else’s name.

    When a rubric performs badly, the pattern usually points to the missing rule:

    • The answer is fluent but contains invented specifics. The evidence boundary is open-ended, or unsupported claims have no mandatory failure action.
    • The model refuses to complete useful work. The rubric treats every uncertainty as blocking. Define which inferences and low-impact assumptions are allowed.
    • The answer is buried in caveats. The rubric does not distinguish material uncertainty from details that do not affect the outcome. Add a materiality test.
    • The citations look correct but do not support the claims. The rubric checks citation presence rather than citation fit. Require support for the exact adjacent statement.
    • Different sections contradict one another. The rubric evaluates local sentences but not the deliverable as a whole. Add a cross-section consistency check.
    • The model follows some rules and ignores others. The rubric is probably too long, repetitive, or internally conflicted. Remove overlap and state the priority order.
    • The self-review always passes. The acceptance criteria are subjective, or the same model is being treated as an independent reviewer. Replace impressions such as high quality with observable pass conditions and retain human verification where the consequence warrants it.

    A rubric does not replace retrieval, source selection, subject-matter expertise, or fact-checking. It governs what the model should do with the information and uncertainty it has. That narrower role is still valuable because it makes incomplete evidence visible before fluent prose conceals it.

    Key takeaways

    • A standard prompt defines the deliverable; a rubric defines how the model must behave when evidence is missing, conflicting, or insufficient.
    • Prioritize factual support over completeness explicitly. Otherwise, a request for a finished answer can compete with the instruction to avoid unsupported claims.
    • Every criterion needs a trigger, required action, and visible outcome. Be accurate is a goal, not an enforceable rule.
    • Define allowed evidence, labeled inference, material uncertainty, clarification conditions, and failure behavior before generating the draft.
    • Use a separate acceptance rubric for publication. Self-review can improve consistency, but it is not independent factual verification.

    Start with one prompt you already use. Add an evidence boundary, an uncertainty classification, a stop condition, and an acceptance check. Then test it against incomplete or conflicting input. If the model fills a gap you expected it to expose, revise the decision rule before you scale the workflow. The useful rubric is not the one that sounds strict; it is the one that produces the correct behavior when the easy answer is unavailable.

    References

  • Discover Google’s Universal Commerce Protocol: Revolutionizing AI Shopping

    Discover Google’s Universal Commerce Protocol: Revolutionizing AI Shopping

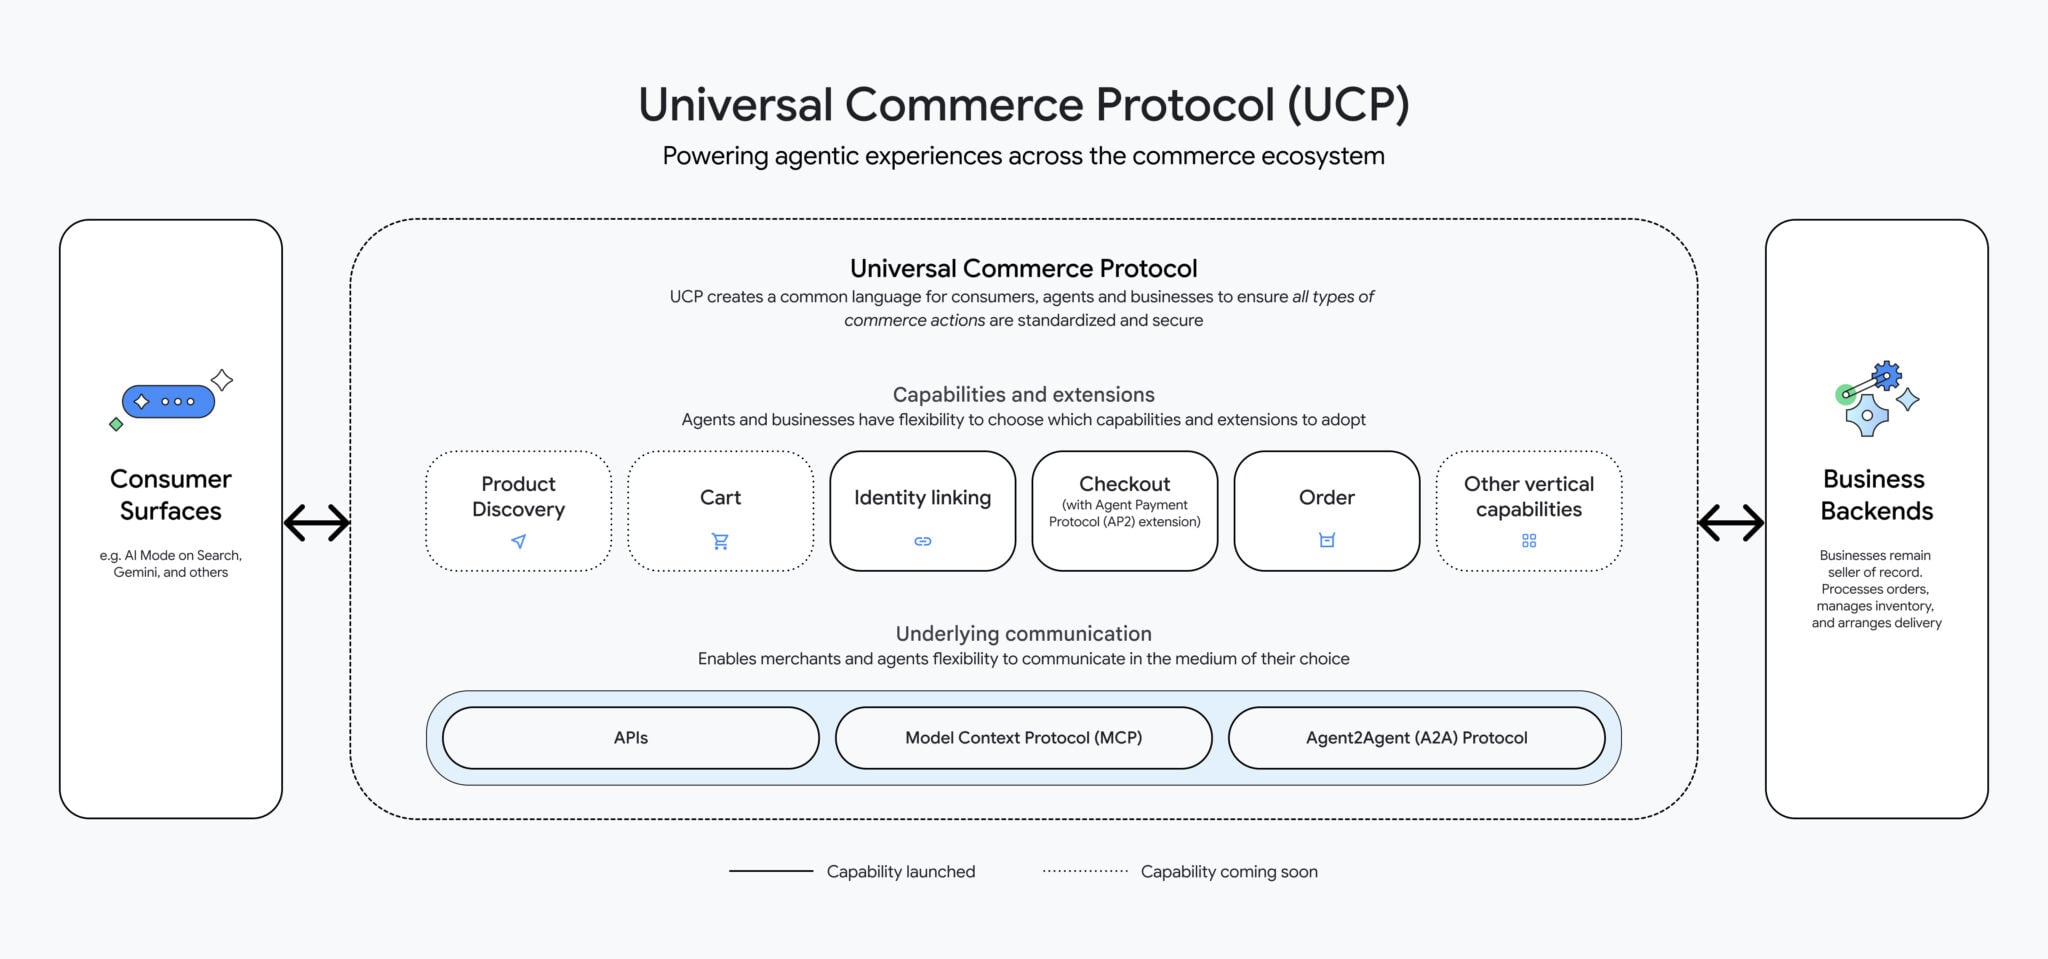
    Have you heard the news? Google has just launched the Universal Commerce Protocol (UCP), an innovative open standard that integrates AI agents throughout the entire shopping experience. From discovering products to making purchases and even receiving support after the sale, UCP facilitates it all.

    In exciting developments for retailers, Google is also rolling out new AI tools. These include branded shopping agents and ad formats that enhance AI-driven discovery, making the shopping experience more streamlined and engaging.

    About UCP

    This protocol offers a common language for AI agents and commerce systems, greatly simplifying the need for custom integrations across different platforms.

    • UCP is compatible with existing standards like Agent2Agent and the Model Context Protocol.
    • The protocol was co-developed with prominent partners such as Shopify, Etsy, Wayfair, and Target.
    • It’s already endorsed by over 20 additional companies in the retail and payments sectors.

    What’s Changing

    The UCP is set to enhance the checkout experience for Google product listings via AI Mode in Search and the Gemini app. Shoppers can make purchases through Google Pay, with options to use saved payment and shipping details. Integration with PayPal is also on the horizon.

    ```json
{
  "alt": "Diagram of Universal Commerce Protocol showing interaction between consumer surfaces and business backends with capabilities like product discovery and checkout.",
  "caption": "Exploring the Universal Commerce Protocol (UCP), this diagram illustrates seamless connections between consumer interfaces and business operations, highlighting essential capabilities such as product discovery and checkout.",
  "description": "This image of the Universal Commerce Protocol (UCP) depicts a framework that connects consumer interfaces with business operations. The diagram highlights capabilities like Product Discovery, Cart, Identity Linking, Checkout, and Order, along with extensions for various vertical capabilities. It shows underlying communication methods including APIs and protocols to facilitate flexible merchant-agent interactions, aimed at enhancing commerce actions' standardization and security."
}
```
    • Google aims to lower cart abandonment and provide retailers with tailored integration options suited to their needs.
    • Upcoming features include loyalty rewards and personalized shopping experiences.

    Business Agent

    In tandem with UCP, Google is unveiling the Business Agent, a branded AI assistant that provides shoppers with direct interaction opportunities on Search. Think of it as a virtual sales associate offering real-time responses in your brand’s own tone.

    • Major retailers like Lowe’s, Michael’s, Poshmark, and Reebok are already on board. Future capabilities may include deeper customization, data training, and a seamless agent-led checkout.

    Direct Offer

    Google is also testing Direct Offers, a fresh initiative within Google Ads tailored for AI adoption. When AI senses that a shopper is likely to make a purchase, a special discount can be presented.

    • This pilot will soon expand to incorporate offers such as product bundles, complimentary shipping, and more enticing incentives.

    Why It Matters

    The rise of agent-led shopping reshapes where and how buying choices are made. Google’s new AI tools and protocols are taking the lead, allowing advertisers to influence these pivotal moments during an AI-driven shopping journey.

    ```json
{
  "alt": "A smartphone screen displaying 'Meet AI Mode' with a virtual assistant query typed below.",
  "caption": "Explore the future of AI interaction with a sleek smartphone interface showcasing the 'Meet AI Mode' feature.",
  "description": "Image of a smartphone screen highlighting the new 'Meet AI Mode' feature, where a user has typed a query seeking a modern, stylish rug for a dining room. The keyboard and various icons such as GIF, voice input, and settings are visible, providing a glimpse into the seamless integration of AI in everyday tech use. This dynamic interface suggests an empowered user experience with cutting-edge AI capabilities."
}
```

    Tools like Direct Offers and branded agents create new pathways for advertisers to finalize sales efficiently, all while safeguarding profit margins. The balance between conversion improvements and losses in direct site traffic remains an open discussion.

    Bottom Line

    According to Google, agentic shopping is unstoppable. With innovations like UCP and its complementary retail tools, Google ensures that AI-driven commerce remains inclusive and accessible, keeping retailers engaged as agents transform the buying landscape.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Revolutionize Your Marketing with AI: Discover Genmark Flow

    Revolutionize Your Marketing with AI: Discover Genmark Flow

    Have you ever imagined a marketing approach where the emphasis is on outcomes rather than just the tools? Let me introduce you to Genmark Flow, a groundbreaking concept in AI marketing that is more than just software; it’s a comprehensive service.

    Genmark Flow is an AI Service as Software solution that delivers results through expertly managed growth strategies. This revolutionary system prioritizes delivering tangible results over merely providing tools. AI-powered and expertly managed, it ensures your marketing goals are not just met, but exceeded.

    With Genmark Flow, you’re not only accessing cutting-edge technology, but you’re also leveraging a service that supports you in achieving your growth ambitions. Get ready to transform your marketing strategies and witness significant outcomes.


    Inspired by this post on genmark.ai Blog.


    crushpress.ai community screenshot
  • Discover the Most Impactful SEO Insights of 2025: A Must-Read Guide

    Discover the Most Impactful SEO Insights of 2025: A Must-Read Guide

    Wow, what a whirlwind 2025 was in the ever-evolving world of SEO! I found myself constantly amazed at the pace of change, especially with the rise of GEO and AI-driven discoveries.

    The incredible advances—from multi-platform searches to innovative AI applications—made this year truly groundbreaking. As I dove into these shifts, Search Engine Land remained my trusted guide, helping me navigate what’s happening, what’s on the horizon, and, most importantly, what really matters.

    I’m thrilled to share with you the 10 most-read SEO columns of 2025. These pieces, penned by some of the best minds in the field, captivated and informed readers like never before.

    10. Will GEO replace SEO – or become part of it?

    Roslyn Ayers explores the vibrant world where SEO meets GEO, showing us how AI powers this multi-dimensional experience. (Published Aug. 8)

    9. Meet llms.txt, a proposed standard for AI website content crawling

    Rob Garner dives deep into the mechanics of llms.txt, shedding light on its impact—it’s an indispensable read to stay ahead. (Published March 28)

    8. SEO vs. GEO: What’s different? What’s the same?

    Join Dan Taylor as he unpacks the synergy between SEO and GEO strategies, unlocking new opportunities for visibility. (Published July 28)

    7. How AI Mode and AI Overviews work based on patents and why we need new strategic focus on SEO

    Michael King offers a fascinating analysis of patents that is a must-read for anyone interested in the future of SEO. (Published June 2)

    6. How to get cited by AI: SEO insights from 8,000 AI citations

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    James Allen provides key insights into how AI models like ChatGPT trust strategic content to shine in search results. (Published May 12)

    5. AI search is booming, but SEO is still not dead

    Lily Ray highlights the intersection of AI and foundational SEO practices, emphasizing the enduring power of core strategies. (Published July 18)

    4. 11 free Chrome extensions you need for SEO

    Stephanie Wallace shares her toolkit for efficiency, introducing extensions that complement traditional SEO tools. (Published Jan. 16)

    3. AI traffic is up 527%. SEO is being rewritten.

    David Bell interprets the Previsible AI Traffic Report, urging us to adapt as AI revolutionizes site traffic dynamics. (Published Aug. 5)

    2. AI optimization: How to optimize your content for AI search and agents

    Jed White delves into optimizing sites for AI, stressing the need for clean HTML and quick response times. (Published Jan. 29)

    1. The end of the web? Goodbye HTML, hello AIDI!

    Mario Fischer ponders the monumental shift toward AI interfaces, contemplating the implications for SEO and digital commerce. (Published Nov. 14)


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Measure SEO and Choose Tools That Earn Their Budget

    How to Measure SEO and Choose Tools That Earn Their Budget

    Your SEO stack can produce a dashboard full of green arrows and still leave you unable to defend the next renewal. If you are deciding whether to keep a platform, add AI-search monitoring, or build an internal agent, the first question is not which option has the longest feature list. It is what decision the investment must improve.

    Build the measurement system before the shortlist. You will expose missing data, avoid paying twice for the same capability, and give every candidate a real job to perform.

    Key takeaways

    • Define the business outcome, search signal, diagnostic evidence, decision, and owner before evaluating any tool.
    • Use the 24-hour view for investigation, weekly reporting for operating decisions, and monthly reporting for direction and resource allocation.
    • Buy a capability only when it closes a documented measurement or workflow gap. An AI label is not a use case.
    • Run trials with representative weekly work, the same inputs, and pass-or-fail criteria that matter after the demo.
    • Separate observed trial evidence from forecast business impact. A short trial can validate a workflow, but it cannot prove future revenue.

    Build a measurement brief before opening a vendor tab

    Five connected groups of objects represent a business target, search signals, evidence, a decision gate, and an action on a strategy table.

    SEO tool evaluations often begin with feature inventories because features are easy to count. That produces a weak business case: leadership generally needs a connection to business results, while many platforms stop at keyword volume, optimization speed, or activity.

    Replace the feature wish list with a short measurement brief. Complete these fields before you request a demo:

    • Business question: State the decision in plain language. Examples include which landing-page group deserves investment, whether a technical release repaired organic acquisition, or which market needs local content.
    • Outcome: Name the result the business already recognizes, such as qualified leads, completed orders, subscriptions, booked consultations, or another defined conversion.
    • Search-performance signal: Identify what you expect to move before the outcome does. Depending on the job, that could include impressions, clicks, landing-page traffic, organic conversions, or search visibility for a defined query set.
    • Diagnostic evidence: List the information needed to explain the movement, such as indexation status, page-template defects, query mix, SERP composition, country, language, or device.
    • Decision rule: Describe what you will do when the evidence changes. A metric without a resulting action is reporting inventory, not a requirement.
    • Owner and cadence: Name who reviews the result, who receives the work, and whether the decision belongs in incident response, a weekly queue, or monthly planning.
    • Boundary: Record what the measurement will not prove. This prevents a ranking change, an alert, or an AI-generated recommendation from being presented as revenue attribution.

    Keep outcomes, performance indicators, and diagnostics separate

    A useful SEO measurement model has distinct layers:

    • Outcome measures describe business results: revenue, qualified demand, completed transactions, subscriptions, or another accepted conversion.
    • Performance indicators describe how organic search contributed: query impressions, clicks, landing-page visits, conversions attributed to organic sessions, and visibility within a defined search set.
    • Diagnostic measures help explain why performance changed: crawling and indexation states, template issues, internal-linking gaps, SERP changes, or differences between markets and devices.

    Do not collapse these layers into a proprietary health score and assume the result has business meaning. A technical score can improve without demand changing. Visibility can rise on queries that never produce a useful visit. Organic conversions can move because of a pricing change, promotion, tracking repair, or landing-page redesign rather than the SEO work being evaluated.

    Write the evidence chain explicitly: the work performed, the observable search change, the on-site action, and the business outcome. Annotate releases and tracking changes. Compare the affected page or query group with a relevant unaffected group when one exists. If the chain is incomplete, call the result an association or an operational improvement rather than attribution.

    Measure at the level where the intervention happened. A template fix should be evaluated on the affected template group. A localized content program should be separated by country and language. A rewrite aimed at one query theme should not be judged only through a sitewide total. Aggregation can make a successful change disappear, or make an unrelated gain look like success.

    Match the reporting interval to the decision

    Google Search Console performance reporting now includes weekly and monthly views in addition to the familiar 24-hour perspective. The practical benefit is not another way to format a chart. It is the ability to choose a reporting grain that fits the question.

    Reporting viewQuestion it should answerWhat not to use it for
    24-hourDid an abrupt change coincide with a release, tracking failure, indexing problem, or other incident?Declaring a durable trend from a short movement.
    WeeklyIs the movement persistent enough to enter the operating queue, and did recent work affect the intended pages or queries?Proving long-term business return from a single reporting period.
    MonthlyIs the program moving in the intended direction, and should priorities or resources change?Finding the exact cause of a sudden failure.

    Use the shortest interval that can answer the decision without letting routine variation dominate it. Then preserve the finer view for diagnosis. A monthly decline can justify investigation; the weekly and 24-hour views help locate when it began and which segment moved.

    Reporting grain does not fix a poor comparison. Compare complete periods with complete periods. Keep seasonal demand and major campaigns in view. Do not compare a global total after launching a new locale without separating the new market from established ones.

    Segment before you explain. Useful cuts include query theme, landing-page group, template, device, country, language, and a documented branded-versus-non-branded rule. A flat sitewide result can conceal growth in one segment and decline in another.

    Maintain a change log next to the performance data. Include site releases, migrations, tracking changes, canonical-rule updates, internal-linking work, and major campaigns. When performance moves, check those known events before assigning the change to an algorithm, competitor, or tool recommendation.

    Turn capability gaps into must-pass jobs

    A shortlist should reflect the gaps in your measurement brief. Useful evaluation areas include advanced data analysis, SERP intelligence, meaningful automation, multilingual support, and transparent pricing. Those labels are still too broad to purchase. Convert each one into a task and a required form of evidence.

    CapabilityTrial jobEvidence required
    Advanced analysisConnect search performance, landing-page behavior, and the defined business outcome for the affected page group.Repeatable definitions, visible transformations, segment-level results, and an export that another analyst can inspect.
    SERP intelligenceExplain a visibility change for a defined query set and market.The underlying queries, capture context, date, location, device, competing results, and relevant search features rather than an unexplained score.
    AutomationComplete a recurring weekly task from detection to prioritized handoff.Rules, exceptions, deduplication, evidence attached to each recommendation, an owner, and a record of what happened after the alert.
    Multilingual supportAnalyze a real country-and-language workflow without merging markets that require different decisions.Locale-specific query and page context, correct filters, preserved terminology, and reporting that can be reviewed by the market owner.
    Pricing clarityPrice the expected operating state rather than the demo environment.A written breakdown of seats, tracked entities, usage limits, exports, integrations, AI consumption, implementation, support, and overage conditions.

    If AI-search visibility is the stated gap, define the observation before accepting a visibility score. Ask which model or search surface was checked, in which locale, against which prompt or query set, at what time, with what captured answer, and under what entity-matching rule. Treat the tracked set as a measurement panel with documented boundaries. An opaque score can summarize evidence, but it should not replace the evidence.

    The replacement standard should be especially high for established crawling and technical-audit workflows. Core technical SEO tooling is comparatively stable. If your current system reliably finds relevant issues, preserves history, and routes work to the right owner, adding an AI label is not enough reason to replace it.

    Decide whether to buy an AI tool or build an agent

    The choice between a ready-made platform and a custom AI agent belongs after the workflow is defined.

    • Buy a platform when the task is standardized and the main value comes from vendor-maintained datasets, integrations, interfaces, support, and ongoing product upkeep.
    • Build an agent when the useful context lives in internal data, business rules, approval paths, or proprietary workflows that a general platform cannot represent. Include evaluation, monitoring, security review, maintenance, and internal ownership in the cost.
    • Keep the existing stack when the real bottleneck is an undefined decision, weak implementation discipline, missing conversion data, or unclear ownership. A new interface will not repair those conditions.

    For a small team, automation must remove work rather than produce more material to review. Outputs without market and business context tend to create noise. Require the system to suppress duplicates, show supporting evidence, explain uncertainty, and hand the next action to a named owner.

    Run a trial that can survive the sales demo

    Three evaluators observe two identical workstations completing the same controlled trial with blank result cards and evidence boxes.

    Do not evaluate a tool through a polished example that the vendor selected. Start with understandable pricing, secure a trial, and test the work your team actually performs in a normal week.

    1. Lock the use case and finish line. Describe the input, expected output, decision, owner, and acceptable evidence before anyone sees the product.
    2. Capture the current baseline. Record active work time, waiting time, systems touched, manual handoffs, recurring errors, and the decision produced by the current workflow.
    3. Use representative inputs. Include ordinary data and a known difficult case. A candidate that works only on a tidy sample has not passed the operational test.
    4. Separate setup from recurring operation. Record configuration, integration, tagging, permissions, and training effort independently from the work expected after adoption.
    5. Run the same task across candidates. Keep the data, operator instructions, and required output consistent so the comparison reflects the tools rather than different demonstrations.
    6. Trace every important output. Follow recommendations back to queries, pages, captured results, or other underlying evidence. Label generated explanations separately from observed data.
    7. Count decisions changed, not alerts created. Record whether the output changed a priority, prevented an error, removed a manual step, or supplied evidence the current stack could not provide.
    8. Test the handoff. Export the result, route it to the intended owner, apply permissions, and verify that history remains understandable outside the person who configured the trial.
    9. Price the operating state. Obtain the expected cost at normal usage, including implementation, integrations, support, consumption limits, internal administration, quality assurance, and any tools the purchase would actually retire.

    Apply pass-or-fail gates before scoring convenience features:

    • Data fitness: It covers the required sites, markets, languages, queries, pages, and business data at a usable level of detail.
    • Evidence quality: Important outputs are reproducible, traceable, and explicit about assumptions or uncertainty.
    • Workflow value: It removes a documented step, improves a defined decision, or enables a necessary analysis that is currently impractical.
    • Operational fit: The intended users can configure, review, export, and act on the output without relying indefinitely on a vendor specialist.
    • Governance: Access controls, retention, deletion, input reuse, and approval requirements fit your organization’s rules.
    • Commercial clarity: The written price covers the expected usage, dependencies, overages, implementation, renewal conditions, and exit path.

    Do not upload confidential query, customer, conversion, or client data until the appropriate security, privacy, and legal owners have approved the environment. Use a sanitized export or synthetic test set while that review is incomplete. The convenience of a trial is not worth creating an uncontrolled copy of sensitive data.

    Ask vendor questions that expose operating cost

    Send the use case before the call, then ask questions that require specific answers:

    • Which assumptions about seats, sites, markets, tracked queries, prompts, exports, API use, and AI consumption are included in this quote?
    • Which capabilities shown in the demonstration require another package, service, integration, or implementation fee?
    • What work is required from our team during setup and during normal operation?
    • Which claims describe production functionality, and which depend on a roadmap?
    • Can we export raw observations, definitions, configurations, and history in a usable format?
    • How are AI inputs retained, reused, isolated, and deleted, and where can those terms be verified?
    • What happens to access, stored data, reports, and integrations if usage changes or the contract ends?

    Build a budget case without pretending the trial proved revenue

    A short trial can establish data coverage, repeatability, workflow fit, evidence quality, and whether the output changes a decision. It usually cannot establish that the tool caused a durable ranking, conversion, or revenue increase. The business case should keep observed evidence, forecasts, assumptions, and unknowns in separate fields.

    Calculate full cost as the subscription, expected usage and overages, implementation, integrations, training, quality assurance, administration, and any internal build or maintenance effort, minus only the cost of tools that will genuinely be retired.

    Treat saved labor carefully. It becomes direct financial savings only when it avoids actual spending. Otherwise, describe it as capacity and name where that capacity will be redeployed. Treat incremental business impact as a forecast with an explicit mechanism: better evidence leads to a different decision, that decision changes the work, and the work may affect the defined outcome.

    Present a range of choices: keep the current stack, make a narrow change that closes the priority gap, or fund a broader platform or internal build. Include dependencies, risks, and exit criteria for each. That is more credible than forcing every benefit into an optimistic return figure, especially while direct connections between search activity and tangible business outcomes remain uncommon in tool offerings.

    Set checkpoints before signing. Confirm usability and evidence quality at the end of the trial, review operational value after a complete reporting period, and revisit adoption, overlap, business impact, and full cost before renewal. If the tool does not improve the decision named in the original brief, downgrade it, replace it, or stop paying for it.

    Your next move should be a blank measurement brief, not another demo booking. Choose a real decision from the next closed weekly or monthly period and ask each candidate to produce evidence your current stack cannot. A tool that cannot change that decision has not earned a place in the budget.

    References

  • Profound’s G2 AEO Leadership: A Practical Buyer’s Guide

    Profound’s G2 AEO Leadership: A Practical Buyer’s Guide

    If Profound’s G2 recognition has put the platform on your AEO shortlist, don’t ask only whether the badge is impressive. Ask what decision it can safely support. The answer is useful but narrow: it can justify a closer look, not a purchase.

    Profound publicly reports that it was recognized as the definitive Leader in G2’s Winter Reports for the AEO category. That gives you a named market signal from a specific report cycle. It doesn’t establish how the product will perform against your prompts, markets, workflow, or technical requirements. A defensible decision requires you to verify the recognition and test the platform separately.

    Read the G2 leadership claim at its actual scope

    A precise procurement note should preserve four parts of the claim: the vendor, the label, the category, and the report cycle. In this case, those parts are Profound, definitive Leader, AEO, and G2 Winter 2026.

    Keep those qualifiers together whenever you brief your team or repeat the recognition publicly. Removing AEO can make a category-specific result sound like a company-wide judgment. Removing Winter 2026 turns time-bounded recognition into an indefinite status. Replacing the exact label with broader wording can create a claim that the underlying record may not support.

    The recognition does not, by itself, establish any of the following:

    • That Profound received the highest result on every criterion used in the category.
    • That its measurements are technically accurate for every answer engine, language, or market.
    • That it supports every workflow, integration, or governance requirement your organization has.
    • That using the platform will cause your brand to appear, rank, or receive citations in an external answer engine.
    • That it is a better fit than every alternative for your particular team.

    Those limitations don’t invalidate the recognition. They place it in the right part of the decision: market evidence. Product capability, data quality, operational fit, and business value still need their own proof.

    Verify the recognition before you circulate it

    An analyst uses a magnifier to inspect a generic award marker beside layered source documents, a calendar tile, and a category folder.

    Before the accolade enters a business case, sales deck, board update, or vendor scorecard, ask Profound for the originating G2 record. A badge graphic or a restatement on another company-controlled page is not the same as primary verification.

    1. Request a direct G2 URL, accessible report, or exported record that identifies the relevant Winter 2026 result.
    2. Confirm that the product name, AEO category, and Leader wording match the language you intend to use.
    3. Read the category criteria and methodology rather than assuming what Leader means. Record which inputs affect placement and which do not.
    4. Check the applicable data window, review base, customer segments, geographic qualifications, and any inclusion thresholds shown in the primary record.
    5. Save the verification artifact with the date you accessed it. If the recognition later changes, your team will know which decision relied on which report cycle.

    Use a simple evidence status in your internal records. Mark the claim verified when an originating G2 artifact supports the exact wording. Mark it partially verified when the placement is visible but your proposed wording is broader than the record. Mark it vendor-reported when only Profound’s own publication is available.

    For now, the conservative wording is that Profound reports receiving the recognition. That distinction is not pedantry. It prevents a vendor-supplied claim from quietly becoming an independently checked fact as it moves through your organization.

    Make Profound earn the shortlist with your workload

    An AEO platform is valuable when it helps your team observe answer-engine behavior, diagnose meaningful gaps, choose sensible actions, and measure what happens next. A polished demonstration can show how an interface works. Only your own workload can show whether the system is useful to you.

    Freeze the evaluation scope before the demonstration

    Create a prompt inventory before anyone logs into the platform. Each row should identify the answer engine or surface, market, language, customer-journey stage, exact prompt, relevant brand or entity spelling, and pages that could credibly support an answer.

    Include the query types your customers actually use: branded questions, non-branded category questions, problem-led questions, comparisons, and questions about implementation or suitability. Cover every material segment of your business. Do not let canned demonstration prompts replace this inventory; a vendor-selected prompt can prove interface behavior without proving coverage of your use case.

    Define acceptance conditions at the same time. Decide which answer engines, languages, markets, exports, integrations, user roles, and historical views are must-haves. When a requirement is left undefined until after the demonstration, an attractive feature can distract the team from a missing capability.

    Audit the observations behind each metric

    Run the chosen prompts manually and through the proposed workflow over multiple recorded occasions. A single run shows one moment. Repetition helps you notice whether differences come from changing answer-engine output, collection timing, classification rules, or a data-ingestion problem.

    For every sampled result, retain the exact prompt, named engine or surface, timestamp, market and language, account or session state where relevant, raw answer, cited URLs, and the platform’s classification. You should be able to trace a dashboard result back to an observable answer. If the system cannot expose that trail, ask how your team is expected to audit a disputed metric.

    Interrogate every metric label that appears in the evaluation. For mention, citation, visibility, share of voice, sentiment, or rank, ask for the unit of analysis, denominator, retry behavior, treatment of missing answers, aggregation method, and update frequency. Familiar names can hide materially different calculations. A percentage is not decision-grade until you know what entered it.

    Require an evidence-to-action workflow

    Select one real query cluster where your brand appears to have a meaningful gap. Ask the evaluator to trace that gap to the underlying evidence, separate controllable issues from external behavior, identify the relevant page or entity, recommend a prioritized action, and state what observable result would count as improvement.

    Then have the person who would own the work judge the recommendation. A generic suggestion to improve authority or create better content is not operational guidance. A useful recommendation identifies the affected query set, the evidence behind the diagnosis, the asset to change, and the reason that change is relevant.

    If structured data is recommended, require the proposed schema type and properties to match the visible content and the entity being described. Validate the markup, but keep the inference modest: technically valid JSON-LD does not prove that an answer engine will select or cite the page.

    Record every action in a change log. Avoid changing content, entity information, internal linking, and structured data simultaneously when you want to understand what helped. External answer systems can change independently, so treat movement as evidence to investigate rather than automatic proof of causation.

    Use a pass-or-fail scorecard, not a badge-weighted impression

    A luminous platform cube passes through evaluation gates represented by speech bubbles, a globe, gears, a shield, integrations, and a stopwatch, while an award medallion sits aside.

    Separate must-haves from differentiators and nice-to-haves before scoring Profound. Third-party market recognition normally belongs among the differentiators unless your procurement policy explicitly makes it mandatory. It should not compensate for a failed data, coverage, security, or workflow requirement.

    Decision areaEvidence that supports a passReason to pause
    RecognitionAn originating G2 record matches the product, label, AEO category, and Winter 2026 report cycle.Only vendor-controlled wording is available, or the marketing language is broader than the primary record.
    CoverageLive testing includes every answer engine, market, language, and prompt class marked as a must-have.Coverage is described broadly while an important engine, region, language, or query type remains untested.
    Metric traceabilitySample metrics can be traced to raw prompts, answers, citations, timestamps, and documented calculations.Scores are opaque, definitions are incomplete, or disagreements cannot be audited.
    RepeatabilityRepeated runs produce explainable results, with collection timing and output changes visible.Material inconsistencies appear without enough evidence to distinguish engine volatility from platform error.
    ActionabilityYour own query gap leads to a specific, evidence-linked action that the responsible operator considers sound.Recommendations remain generic or cannot be connected to a page, entity, citation, or technical issue.
    Operational fitExports, APIs, history, collaboration, permissions, and integrations meet the requirements defined before the demo.A critical workflow depends on an undocumented feature or a manual workaround your team cannot sustain.
    Commercial and governance fitPricing units, usage limits, support, onboarding, data retention, access controls, and contractual responsibilities are confirmed in writing.A material cost, limit, ownership question, or data-handling requirement remains unknown.

    Have each evaluator record pass, fail, or unknown beside an evidence link. Unknown is not a provisional pass. Give every unknown an owner and a deadline, then resolve disagreements by examining the evidence rather than averaging enthusiasm from the demonstration.

    If Profound fails a must-have, stop and decide whether the requirement can genuinely change. Do not quietly reclassify it because the platform has strong recognition. If Profound passes the must-haves, the G2 result becomes relevant supporting evidence and may help distinguish otherwise suitable choices.

    Key takeaways

    • Profound reports that it was recognized as the definitive Leader in G2’s Winter 2026 Reports for the AEO category.
    • Treat that recognition as a time-bounded, category-specific market signal, not blanket proof of technical accuracy, business impact, or universal product fit.
    • Verify the exact wording against an originating G2 artifact before presenting the claim as independently confirmed.
    • Evaluate the platform with a frozen inventory of your own prompts, markets, languages, answer surfaces, and operational requirements.
    • Require every important metric to connect back to raw answers, citations, timestamps, and a documented calculation.
    • Let must-have evidence determine the purchase decision; use the G2 recognition as supporting context after those requirements are satisfied.

    Your next move is to create a one-page evidence register before the next conversation with Profound. Put the four-part G2 claim at the top, list what remains unverified, and attach a pass-or-fail pilot plan based on your real workload. If the platform clears those tests, the leadership recognition will have the context it needs to support a defensible decision.

    References

  • How to Build an AI Marketing Tool Stack That Actually Works

    How to Build an AI Marketing Tool Stack That Actually Works

    If every campaign begins with hunting through tabs, copying context between tools, and checking which draft is current, your marketing stack is consuming the attention it was supposed to save. Another AI subscription will not fix a broken handoff.

    The fix is to design the stack around a repeatable workflow: where trustworthy information enters, what each tool changes, who approves the result, where the finished work goes, and how the outcome informs the next decision. Do that first, and choosing tools becomes much easier.

    Map the campaign before you choose the software

    Marketing software already spans content creation, conversion-rate optimization, design, analytics, and AI visibility. That breadth creates a predictable buying mistake: teams compare tools within each category before deciding how those categories need to work together.

    Start with a campaign your team performs often. Map the work from the event that starts it to the decision made after results arrive. Do not map an idealized process. Use the path a real brief, asset, landing page, email, or report currently follows.

    For every stage, complete a workflow card with these fields:

    • Trigger: the event that starts the work, such as an approved campaign objective, a product update, or a performance question.
    • Authoritative input: the facts, instructions, audience data, brand rules, and approved claims the stage is allowed to use.
    • Transformation: the specific job performed, such as turning a brief into draft copy or converting approved copy into channel variants.
    • Output: the artifact produced, including its required format, fields, status, and destination.
    • Approval: the person accountable for deciding whether the output can move forward.
    • Feedback: the evidence that should change the next brief, asset, audience choice, or optimization decision.

    This exercise exposes the real gaps. You may discover that several tools can generate copy while none carries an approved product claim into the prompt. You may find that design files lose their campaign identifiers before analytics can connect them to outcomes. You may also find that a report is produced regularly but never changes a decision.

    Mark every place where a person copies information, renames an artifact, changes a format, requests approval, or reconciles conflicting versions. Those seams are usually better automation candidates than the visible creative task. Generating another draft is less valuable if someone still has to determine which facts it used, paste it into another system, and rebuild its history by hand.

    Also separate assistance from authority. An AI tool can classify feedback, propose a campaign angle, rewrite copy, or summarize performance. It should not quietly become the source of truth for product facts, consent status, approved language, pricing, or campaign results. Keep those records in the systems that already own them, and pass only the required context into the AI layer.

    Give each layer a job, an owner, and a handoff

    Five connected campaign stations show team members handing work from research and creation through approval, publishing, and measurement.

    A useful stack is not a pile of applications. It is a chain of accountable artifacts. A tool may serve more than one layer, but two tools should not silently own competing versions of the same brief, asset, audience, or performance record.

    Stack layerJob it ownsRequired handoffWarning sign
    FoundationMaintains approved facts, audience definitions, brand rules, permissions, and campaign identifiers.Current, structured context with a named owner and status.People use an AI-generated summary as the authoritative record.
    Planning and researchTurns an objective and evidence into a brief, audience question, channel plan, or test hypothesis.An approved brief that states the goal, constraints, evidence, and decision to be made.The rationale disappears and only the generated idea survives.
    Content and designCreates draft copy, visual directions, variants, and production assets from the approved brief.Reviewable assets carrying the campaign identifier, source context, and approval status.Drafts multiply faster than reviewers can verify them.
    Conversion and deliveryAssembles the customer-facing experience and sends or publishes approved material.A published identifier, destination, audience or variant record, and rollback path.Publishing is automated before claims, links, targeting, and tracking are checked.
    AnalyticsConnects delivery records with observable behavior and business outcomes.Evidence tied back to the campaign, asset, audience, and decision.A dashboard reports activity without identifying what should change.
    AI visibilityObserves how the brand, products, and pages appear in relevant AI-generated answers.The tested question, exact answer, mention or citation, cited URL, and content change under review.A visibility score is reported without the prompts and answers behind it.

    The foundation layer deserves more attention than it usually gets. Generated work is only as dependable as the context supplied to it. If a prompt can pull an outdated claim, an unapproved positioning statement, and a current product description with equal confidence, better generation will only produce a more convincing inconsistency.

    Make the handoff itself a contract. Define the fields that must be present, the allowed source, the owner, the approval state, and the destination. A content handoff might require a campaign identifier, target question, approved factual claims, audience, call to action, destination URL, reviewer, and status. If an output lacks a required field, it is incomplete even when the writing looks polished.

    The AI visibility layer needs the same discipline. Build a stable set of questions that reflect how prospective buyers investigate the problem, compare approaches, and evaluate risk. For each check, preserve the question, the generated answer, whether the brand or page appeared, the exact cited URL when one is present, and whether the representation was accurate. A single answer is an observation. A controlled record gives you something you can compare after content, entity information, or internal linking changes.

    Your operating flow should now be legible in a single line: approved context becomes a brief; the brief becomes reviewable assets; approved assets become a published experience; delivery records become evidence; evidence and AI visibility observations become the next decision. Any tool that cannot participate in that flow needs an exceptional reason to remain in the stack.

    Put every candidate through a real task and a failure test

    Two marketers test an AI tool with normal campaign materials and problematic inputs while checking its outputs against source cards.

    Feature lists reward breadth. Your team benefits from fit. A tool that can perform many impressive tasks may still create more work if it requires special input formatting, hides its references, traps approved output, or cannot preserve the identifiers your workflow needs.

    Run the task trial

    Use a representative task from the workflow map, including the awkward parts. Vendor samples and pristine prompts remove the context conflicts, exceptions, and approval requirements that determine whether a tool survives normal use.

    1. Prepare a real input package. Include the approved brief, source material, brand constraints, required output format, and an intentionally irrelevant document. The candidate should use the right context and ignore the wrong context.
    2. Define acceptance before generating. State which facts must be preserved, what the output must contain, what it must avoid, who will review it, and where it needs to go next.
    3. Complete the task without hidden cleanup. Record every manual copy, format conversion, prompt repair, factual check, permission change, and upload required to reach an approved output.
    4. Force an exception. Remove a required field, introduce conflicting instructions, deny a permission, or supply an unsupported request. Check whether the tool stops clearly, requests clarification, or produces a plausible but unusable answer.
    5. Inspect the handoff. Export the output and confirm that its identifier, status, references, and revision context survive. A polished artifact with no reliable lineage is difficult to govern and measure.
    6. Test reversibility. Confirm that your team can correct, replace, unpublish, or roll back the result without reconstructing the workflow from memory.

    Apply non-negotiable buying gates

    Do not average a serious weakness into a high overall score. A candidate should be disqualified if it fails a requirement that protects data, approvals, measurement, or continuity. Use these questions as gates:

    • Workflow fit: Does it remove a defined bottleneck, or does it merely produce another version of an artifact you already have?
    • Context control: Can you specify which material is authoritative, restrict irrelevant context, and update stale information without rebuilding everything?
    • Traceability: Can reviewers determine which inputs, instructions, and revisions produced the output?
    • Output control: Can approved work leave the tool in the format your CMS, campaign platform, analytics process, or archive requires?
    • Access control: Can permissions separate viewing, generating, approving, publishing, spending, and administrative actions where your workflow requires that separation?
    • Integration fit: Does it work with the identifiers and systems you already use, or will the team maintain a fragile manual bridge?
    • Failure behavior: When context, permissions, integrations, or instructions fail, does the problem become visible before the output reaches a customer?
    • Economic fit: Which usage driver creates cost, and does that driver grow with valuable approved work or with drafts, retries, storage, and duplicated seats?
    • Exit readiness: Can you retrieve approved assets, history, configuration, and required metadata if the tool no longer fits?

    Once the non-negotiable candidates survive, compare the work removed from the complete process. Count review and correction as part of the task. A generator that produces drafts quickly but shifts substantial verification and formatting onto senior staff has not eliminated that work; it has moved it to a more expensive point in the workflow.

    Overlap should face the same test. If two tools generate similar outputs, decide which one owns the artifact, which one handles an explicitly different exception, and where the final version lives. If you cannot state those roles plainly, the overlap will eventually create duplicate spend, inconsistent instructions, or conflicting campaign records.

    Control automation, then measure the decisions it improves

    Limit write access until the workflow is proven

    Automation becomes materially riskier when it can publish, message customers, change targeting, alter advertising spend, or overwrite business records. A wrong draft is recoverable. A wrong draft sent to an audience, attached to live spend, or written over trusted data can create financial, reputational, and data-integrity damage.

    Evaluate new automation with read-only access or in a separate test environment where practical. Keep a person in the approval path for factual and legal claims, public publishing, audience-wide sends, budget or bid changes, and destructive record updates. Expand permissions only after the team has documented the normal path, exception path, owner, and rollback procedure.

    For every automated step, record:

    • the event that triggered it;
    • the authoritative inputs and campaign identifier;
    • the instruction or workflow version;
    • the output and destination;
    • the checks applied;
    • the approver when approval is required;
    • the exception raised, if any; and
    • the action needed to reverse or correct the result.

    This record is not bureaucracy for its own sake. It lets you distinguish a bad instruction from stale context, an integration failure from a model error, and an approved change from an unauthorized one. Without that distinction, the team can see that something went wrong but cannot correct the mechanism that caused it.

    Measure approved work, not raw generation

    Output volume is an easy metric and often the wrong one. More drafts can increase review queues, version conflicts, and publishing delays. Evaluate the stack at the point where work becomes usable and at the point where it informs a business decision.

    • Flow: Track elapsed time from the workflow trigger to approved output, not merely generation time.
    • Acceptance: Track how much generated work reaches approval without substantial factual, brand, or structural correction.
    • Rework: Record why work returns for revision. Repeated failures usually point to missing context, a weak handoff contract, or an unsuitable task.
    • Exception load: Track how often people must rescue, reroute, or reconstruct the process outside the intended workflow.
    • Unit economics: Include subscriptions, usage charges, integration upkeep, review, correction, and administration when comparing the cost of approved output.
    • Downstream outcome: Connect the approved artifact to the relevant campaign result before claiming that the stack improved marketing performance.
    • Decision value: Name the decision each report or visibility check changed. If it never changes a brief, budget, page, message, audience, or test, reconsider why it exists.

    Preserve campaign and asset identifiers through publication and measurement. That lineage lets analytics connect an outcome to the actual approved artifact instead of to a generic channel label. It also prevents a common attribution error: crediting an AI tool for a business result when the result may also reflect the offer, audience, distribution, timing, page experience, or human edits.

    Apply the same restraint to AI visibility. If a relevant answer begins mentioning or citing a page after you change it, record the sequence as a useful signal, not automatic proof of causation. Preserve the prompt, answer, cited page, content revision, and test conditions. The purpose of the visibility layer is to produce evidence your content and SEO teams can inspect, not a score that floats free of observable answers.

    At campaign close, review the tools alongside the workflow. Keep a tool when it owns a necessary job, passes its handoff cleanly, and improves a decision or an approved outcome. Reconfigure it when the problem is context or process. Remove it from the workflow when it duplicates an owner, creates persistent hidden work, blocks traceability, or produces information nobody uses.

    Key takeaways

    • Map a real campaign from trigger to decision before comparing AI tools.
    • Keep approved facts and business records in authoritative systems; use AI to transform controlled context rather than replace the source of truth.
    • Assign every layer a job, an artifact owner, a required handoff, and an exception path.
    • Trial candidates with representative inputs, explicit acceptance criteria, an induced failure, and an export test.
    • Keep publishing, customer messaging, spend changes, and destructive record updates behind appropriate approval and rollback controls.
    • Measure time to approved work, rework, exception load, complete cost, downstream outcomes, and the decisions changed.
    • For AI visibility, preserve the question, exact answer, mention or citation, cited URL, and related content change.

    Open your last completed campaign and list every handoff from approved context to measured outcome. Mark where information was copied, ownership became unclear, or a result failed to reach the next decision. Fix the most consequential seam before you add another subscription. That is where a tool stack begins to become an operating system for marketing rather than a collection of accounts.

    References

  • Google DeepMind Nano Banana Pro: A Marketer’s Workflow

    Google DeepMind Nano Banana Pro: A Marketer’s Workflow

    If your team can already make one attractive AI image, the harder problem is repeatability. Can the same product, character, visual hierarchy, and approved copy survive the next ten versions without a cleanup cycle wiping out the time you saved?

    Google DeepMind’s Nano Banana Pro is relevant because it brings stronger reasoning, multi-reference consistency, text rendering, and targeted editing into one image workflow. Its value, however, depends less on the first impressive render than on how you brief, review, publish, and test the resulting assets.

    Decide whether the job matches Nano Banana Pro

    Nano Banana Pro builds on the original Nano Banana and combines image generation and editing with Gemini 3 Pro’s reasoning capabilities. That combination is designed for more controlled production work, not merely open-ended image prompting.

    Those capabilities make Nano Banana Pro a strong candidate when your bottleneck is controlled variation: adapting one approved concept into new layouts, markets, scenes, or campaign treatments. It is less convincing as an unsupervised authority for exact logos, prices, measurements, product claims, or factual diagrams. Those elements still need deterministic files, approved copy, and human sign-off.

    Access should also be treated as product-dependent. The rollout was described as progressive across Google’s platforms, while image-generation enhancements were made available in Google Ads. Confirm that the surface your team intends to use actually provides the required controls before you redesign a production process around it.

    Build a controlled brief, not a clever prompt

    An overhead workspace shows an unbranded product, character model, color swatches, material samples, and blank composition cards arranged as a controlled visual brief.

    A clever sentence may produce an interesting image. It rarely produces a dependable asset system. For repeatable work, separate the business objective, reference material, fixed constraints, creative variables, and approval criteria.

    1. Define the asset’s job. State where the image will appear, who it is for, what it must communicate, and what action it supports. A product-page hero, paid-ad variant, visual explainer, and storyboard frame need different compositions even when they share a subject.
    2. Curate the reference set. Nano Banana Pro can work across up to 14 inputs, but that is a ceiling rather than a target. Include only references with a clear role, then label each role: product geometry, character appearance, palette, environment, lighting, typography direction, or composition.
    3. List the non-negotiables. Specify what must remain unchanged, such as product proportions, wardrobe, brand colors, approved terminology, packaging structure, or the number and position of objects. Do not hide these requirements inside a long mood description.
    4. Separate creative variables. Name the elements that may change: background, camera angle, lighting, crop, season, supporting props, or emotional tone. This gives the model room to work without making every part of the asset unstable.
    5. Supply approved on-image copy. Put every required word in a dedicated field, including capitalization, punctuation, language, and desired line breaks. Multilingual rendering is useful only after a qualified reviewer has approved the translation itself.
    6. Describe the composition explicitly. Identify the focal subject, foreground and background relationship, viewing angle, negative space, intended crop, lighting direction, color treatment, and required aspect ratio. Terms such as premium or cinematic are too broad unless you explain what they mean visually.
    7. Approve one master before making variants. Resolve product shape, character continuity, hierarchy, copy, and overall art direction in a master image. Only then use localized edits and detailed visual controls to create derivatives.
    8. Record what produced the approved result. Save the references, prompt, approved copy, output, requested edits, intended channel, and reviewer decisions together. Without that record, the next campaign starts as another guessing exercise.

    A reusable Nano Banana Pro brief

    You can turn the workflow into a short production template. Replace each instruction with project-specific language:

    • Objective: Create an image for a named page, campaign, or presentation and state the decision or action it should support.
    • Reference roles: Input 1 controls product shape; input 2 controls palette; input 3 controls character appearance; input 4 controls composition.
    • Must preserve: List the objects, proportions, colors, expressions, terminology, and layout relationships that cannot change.
    • Scene and treatment: Define environment, camera position, focal length in plain visual terms, lighting direction, depth, color balance, and mood.
    • Exact copy: Provide the approved words, language, capitalization, punctuation, and hierarchy. Instruct the system not to add other text.
    • Output: State the required aspect ratio, placement of negative space, and any crop-safe area your channel needs.
    • Edit rule: Preserve every approved element and change only the named variable in each revision.

    The edit rule is especially important. Instead of asking for a better version, request a defined delta: keep the subject, pose, product, copy, palette, and framing unchanged; adjust only the background lighting. A narrow instruction gives you a result that is easier to compare and approve.

    Review the image like a production asset

    A reviewer compares an unbranded running shoe on a monitor with a physical sample while inspecting enlarged details, shadows, and materials.

    Rendering quality and correctness are different tests. Text may look polished while containing a substituted character. A product may remain recognizable while its controls, label, or proportions drift. Search-connected context may help the model build a scene, but it does not transfer responsibility for the scene’s claims to Google.

    • Check text character by character. Compare every word, numeral, unit, punctuation mark, and line break with the approved copy. Review the exported size as well as the large preview; small labels can fail only after resizing.
    • Review each language independently. Legibility does not prove that a translation is accurate, culturally appropriate, or compliant with your terminology. Give a fluent reviewer the copy and the rendered image, not the image alone.
    • Compare products and brand elements with their references. Inspect silhouettes, component count, labels, materials, colors, logo geometry, and relative scale. If exactness is mandatory, replace generated brand marks or copy with approved production assets.
    • Verify factual content against approved data. Recheck names, quantities, relationships, ingredients, annotations, and visualized facts. For an infographic, keep the underlying data and its provenance with the review record.
    • Inspect continuity across the set. Look beyond facial resemblance. Check clothing details, accessories, object placement, shadows, materials, and environmental logic from one image to the next.
    • Test the real crop. Preview every destination rather than assuming one output will adapt cleanly. Confirm that the focal subject, required copy, and important context remain visible wherever the image will appear.
    • Provide a text equivalent. If an image contains information needed to understand the page, repeat that information in HTML. Alt text should describe the image’s purpose in context, not become a list of target keywords.

    Assign ownership before review begins. A creative owner can approve composition and consistency, a subject or language owner can approve claims and copy, and a channel owner can approve crop, accessibility, and placement. A general request for everyone to check everything usually leaves the riskiest detail without a named decision-maker.

    If repeated local corrections begin changing previously approved areas, return to the master and regenerate the derivative from there. A chain of patched exports is harder to reproduce, audit, and update than one approved base with documented variations.

    Make each output useful to search systems and ad testing

    For SEO, AEO, and GEO content

    A generated image can explain an idea, establish context, or make a page easier to scan. It cannot replace the page’s evidence. If the answer exists only inside pixels, you make it harder for people using assistive technology and for systems that depend on accessible page text to interpret and cite the underlying information.

    • Place the image beside the passage it supports rather than treating it as detached decoration.
    • Repeat essential labels, claims, instructions, and data in visible HTML. For a detailed infographic, provide a compact text explanation or accessible transcript.
    • Write alt text around the image’s function on that page. Describe what a reader needs to understand; do not paste a keyword list or duplicate a long caption.
    • Add a caption when the visual needs a title, data context, methodology note, or explanation that would be awkward in alt text.
    • Use consistent names for products, entities, and concepts in the image, heading, body copy, and metadata. Visual creativity should not introduce new terminology for the same thing.
    • Where the page’s existing schema type supports an image property, connect it to the final image URL and keep the structured description aligned with the visible page. JSON-LD expresses a relationship; it does not verify that a generated claim is true.

    This distinction matters for Search-connected generation. Real-world context can accelerate visual creation, but it is not a citation or a provenance record. Keep the factual basis of the image visible, inspectable, and consistent with the surrounding content.

    For Google Ads and campaign experiments

    Nano Banana Pro’s availability through Google Ads can reduce the handoff between asset creation and campaign setup. That convenience does not demonstrate that an image will improve performance. Treat every generated variation as a creative hypothesis.

    • Start with one approved master so visual differences are intentional rather than accidental.
    • Change one meaningful variable per test, such as background context, camera angle, product emphasis, or lighting treatment.
    • Keep the offer, audience, landing experience, and other campaign conditions stable when you need to learn whether the visual caused the difference.
    • Choose the decision metric before launching. A higher click-through rate may be useful, but it should not justify broader spend if the campaign’s actual conversion or cost objective deteriorates.
    • Name and archive variants by the changed variable. Labels such as blue-background or close-product-crop are more useful than final-7.
    • Do not increase spend merely because a generated asset looks more polished. Use your normal budget controls until performance against the campaign objective supports the change.

    The production advantage is the ability to explore more controlled variations without rebuilding every asset manually. The measurement advantage appears only when those variations remain controlled enough to teach you something.

    Key takeaways

    • Nano Banana Pro is most useful for constrained visual production: consistent references, exact copy requirements, localized edits, and planned variants.
    • Although it can work across as many as 14 inputs, use only the references that have a defined role in the output.
    • Approve one master before creating derivatives, and request one explicit change at a time.
    • Readable multilingual text, Search-connected context, and polished rendering still require language, factual, product, and brand review.
    • For search content, keep essential information in HTML and align the image with visible copy, alt text, captions, and applicable structured data.
    • For advertising, evaluate generated variants through controlled tests rather than assuming faster production or better-looking creative will improve results.

    Start with one existing asset that already creates expensive variation work. Define what must stay fixed, choose one variable, produce and approve a master, then run a small controlled test. If Nano Banana Pro preserves the constraints and makes the next version easier to reproduce, it belongs in the production workflow. If it cannot, keep it upstream as a concept and storyboard tool.

    References

  • OpenAI Agent Automation Tools: A Practical Build Guide

    OpenAI Agent Automation Tools: A Practical Build Guide

    You have a recurring marketing workflow that is too judgment-heavy for a simple rule and too repetitive to justify doing by hand. That is a sensible place to consider an OpenAI agent. The mistake is handing it a broad objective such as “manage PPC” or “run content operations” before you have defined what it may read, decide, change, and escalate.

    OpenAI’s AgentKit brings visual workflow building together with familiar tools such as Gmail and Dropbox, reducing how much glue code may be needed around an agent. That makes construction easier. It does not remove the harder work: designing a workflow that produces useful results without creating expensive surprises.

    Give the first agent a narrow outcome, not a department

    An agent is most useful in the gap between rigid automation and unrestricted human judgment. It can interpret messy inputs, choose among permitted actions, and use connected tools. It should not be treated as an autonomous employee with an implied understanding of your business.

    Start with a workflow that has a recognizable trigger, a bounded decision, a small set of tools, and an output you can inspect. A strong candidate can usually be described in one sentence: “When this event occurs, use these approved inputs to prepare this defined result for this person or system.”

    • Turn campaign data into an exception brief that identifies what needs a human decision.
    • Collect approved reporting inputs, prepare a dashboard entry, and draft the accompanying client summary.
    • Check draft ad copy against explicit brand rules and flag the exact rule behind each problem.
    • Prepare a meeting agenda from an approved account summary and unresolved action items.
    • Review an existing content brief for missing entities, unanswered questions, or unsupported claims before publication.

    Each example ends in an inspectable artifact. None asks the agent to “improve performance” without defining what improvement means or what authority the agent has.

    Use a simple eligibility test

    Before building, answer the following questions. If several answers are unclear, the process is not ready for an agent yet.

    • What exact event starts the workflow?
    • Which systems contain the facts the agent is allowed to use?
    • Which part requires interpretation rather than a fixed rule?
    • What does a complete output contain?
    • How can a reviewer verify the result without recreating all the work?
    • What is the worst plausible result of a wrong decision?
    • Can that result be prevented with permissions, validation, or approval?

    A poor starting workflow has an ambiguous goal, no authoritative data source, broad credentials, and no obvious stopping point. It may still be worth redesigning, but adding an agent will not repair those weaknesses.

    Know when ordinary automation is enough

    If the same input should always produce the same action, use a deterministic rule. Scheduling a recurring run, checking whether a required field is empty, applying a known naming convention, and moving an approved file do not require model judgment.

    Use an agent for the step that genuinely needs interpretation: classifying an unusual campaign change, reconciling context from a client email with a performance report, or explaining why draft copy conflicts with a brand rule. The strongest design is often a hybrid. Conventional automation handles triggers and validation; the agent handles a bounded judgment; conventional automation checks the output and routes it to the next stage.

    Separate facts, reasoning, actions, and controls

    A four-part automation model separates source records, a reasoning chamber, an action mechanism, and an independent control frame with locks and an approval gate.

    A visual canvas can make a complicated workflow look like one continuous chain. Operationally, you should still treat it as distinct layers. That separation tells you where an error started and which safeguard should catch it.

    LayerIts jobMarketing exampleMain failure to prevent
    FactsRetrieve authoritative input without changing itCampaign data, an approved brief, or brand rulesUsing stale, incomplete, or unapproved material
    ReasoningClassify, compare, prioritize, or draftExplain which exception deserves reviewProducing a plausible conclusion that the evidence does not support
    ActionWrite or send an approved result through a toolCreate a report draft or update a workflow statusChanging the wrong record or acting before approval
    ControlValidate, log, stop, or request authorizationRequire evidence fields and approval before publicationAllowing an error to pass silently into a consequential action

    Your language model should not become the system of record. Let tools retrieve facts from the authoritative system, and require the agent to preserve the identifiers that connect every conclusion to those facts. If it says a campaign needs attention, the output should identify the campaign, the relevant observation, the input used, and the proposed next step.

    Policies deserve the same separation. Brand requirements, approval rules, prohibited claims, and escalation conditions should be maintained as explicit instructions or structured data. Do not hide critical policy in an example and expect the agent to infer that the example is binding.

    A useful division of labor is straightforward: tools fetch facts, the agent interprets them, deterministic checks validate required conditions, and a person approves consequential changes. You can relax an approval later if the workflow earns that authority. Recovering from an unreviewed budget change or public claim is much harder.

    Write an executable contract before you build

    The workflow specification is the real product. The canvas, model, prompts, and connectors implement it. Write the specification in operational language that a reviewer can challenge before the agent touches live data.

    1. Define the outcome. Name the artifact or state the workflow must produce, not the general business goal it supports.
    2. Define the trigger. Identify the approved event, schedule, or human request that starts a run.
    3. Define the inputs. List the allowed systems, records, fields, and policy documents. State which one wins if two inputs conflict.
    4. Define the decision. Explain what the agent may infer and the criteria it must apply.
    5. Define the output. Require a stable structure with evidence, unresolved questions, and approval status.
    6. Define the tools. Grant only the operations needed for this workflow.
    7. Define the boundaries. State forbidden actions, stop conditions, and matters that always require escalation.
    8. Define completion. Say what must be true before a run can be marked successful.
    9. Define the evidence trail. Preserve the input references, tool results, output, approval, and final action.

    A practical specification for a PPC reporting agent

    Suppose you want an agent to prepare a campaign exception brief. The specification could read like this:

    • Outcome: prepare a review brief describing campaign exceptions; do not optimize the account.
    • Trigger: an approved reporting request with an account identifier and reporting context.
    • Inputs: current campaign data, the agreed comparison context, active brand rules, and unresolved items from the previous review.
    • Allowed decisions: group related observations, rank them by the supplied business criteria, and propose questions or next actions.
    • Required output: campaign identifier, observation, supporting evidence, applicable rule or objective, proposed action, uncertainty, and approval status.
    • Allowed actions: read approved inputs and create a draft in the designated location.
    • Forbidden actions: change bids or budgets, alter targeting, send client communications, publish copy, or invent a missing value.
    • Stop conditions: required data is missing, identifiers do not match, instructions conflict, or a tool returns an uncertain result.
    • Approval: the account owner reviews the brief before any recommendation enters a live campaign workflow.
    • Completion: every recommendation has evidence, every unresolved issue is labeled, and no prohibited action was attempted.

    This contract turns a vague assistant into a bounded operator. It also makes evaluation possible. A reviewer can test whether the agent followed each condition instead of debating whether the response merely looked intelligent.

    Express authority with precise verbs

    Words such as read, classify, draft, propose, update, send, publish, and delete represent very different levels of authority. Use them deliberately. “Handle the client report” conceals several decisions. “Read approved campaign data, draft the report summary, and request approval” exposes them.

    Do the same with uncertainty. If a required value is absent, tell the agent to stop or label the gap. Never ask it to complete a record using “the most likely” value unless inference is explicitly acceptable and clearly marked. A polished guess is still a data-quality failure.

    Place controls at the action boundary

    Permissions should follow a ladder. Reading is less consequential than drafting; drafting is less consequential than committing a database change; an internal change is usually less consequential than sending a message, publishing content, or changing advertising spend.

    • Begin with read-only access wherever the workflow allows it.
    • Write drafts to a staging location rather than replacing an approved asset.
    • Require a human decision immediately before an external, public, financial, destructive, or difficult-to-reverse action.
    • Use separate credentials or scoped permissions so one workflow cannot inherit unrelated authority.
    • Require the tool to return a stable record identifier and confirmation before the agent treats a write as successful.
    • Make repeated runs safe. A duplicate trigger should find the existing draft or action record rather than create another one.
    • Log the request, retrieved input references, tool calls, result, approval, and final action in a form that can be reviewed later.

    Connected email and document stores introduce another boundary: retrieved content is data, not authority. An email, attachment, or cloud document may contain text that tells the agent to ignore its rules or use another tool. The workflow should treat those instructions as untrusted unless they arrive through the approved control path. Keep system instructions, business policy, and retrieved content distinct.

    Test the agent’s failures before trusting its successes

    An engineer observes an automated agent being tested against missing inputs, conflicting records, unavailable tools, and a blocked unsafe action in a simulation lab.

    A smooth demonstration proves that the happy path can work. It does not show what happens when data is absent, tools fail, instructions conflict, or the same event arrives twice. Those cases determine whether the automation is fit for routine use.

    Build a test set from the ways the real workflow can break. It should include:

    • An ordinary case with complete, consistent inputs.
    • A case with a required input missing.
    • A stale, malformed, or mismatched record.
    • Two approved inputs that disagree.
    • An ambiguous request that permits more than one interpretation.
    • Retrieved content containing instructions the workflow must not obey.
    • A tool timeout, rejection, or incomplete response.
    • A duplicate trigger for a run that already produced an output.
    • A proposed action that violates a brand, permission, or approval rule.
    • A case where the correct behavior is to stop and ask for help.

    Score behavior against the contract, not writing quality. Check whether the conclusion is supported, required fields are present, prohibited actions are avoided, tool results match the intended record, and uncertainty is visible. Also record how much human correction the result needs. An agent that saves preparation time but creates a difficult verification job has moved the work rather than removed it.

    Roll out in stages

    Start in shadow mode: let the agent process real workflow inputs without writing to production systems or contacting anyone. Compare its proposed output with the existing process, classify the differences, and revise the contract or controls when the same error pattern returns.

    Next, allow draft creation while keeping approval mandatory. Expand authority only after the defined test set and real shadow runs show that failures are visible and contained. Increase one dimension at a time, such as the range of accepted inputs or the ability to update an internal status. If you broaden the workflow and its permissions simultaneously, you will not know which change caused a new failure.

    Monitor the operating result after launch. Useful measures include successful completions, stops and escalations, human edits, attempted policy violations, tool failures, duplicate prevention, and time saved after review and recovery work are included. Review the failure categories themselves. A rising cluster of missing-data errors may point to an upstream process problem rather than a prompt problem.

    Keep rollback practical. Preserve the previous state for reversible updates, retain the identifiers returned by action tools, and document how a reviewer disables the workflow without disabling unrelated automations. If a safe rollback is impossible, keep a person at the commit boundary.

    Key takeaways

    • Choose a narrow workflow with a clear trigger, bounded judgment, limited tools, and a verifiable output.
    • Keep deterministic triggers and validation outside the model; use agent reasoning only where interpretation adds value.
    • Treat the workflow specification as an executable contract covering inputs, decisions, outputs, permissions, stops, and evidence.
    • Start with read or draft access and require approval before public, financial, destructive, or difficult-to-reverse actions.
    • Treat email, attachments, and retrieved documents as untrusted data rather than instructions.
    • Test missing data, conflicting instructions, tool failures, duplicate events, and safe escalation before expanding authority.
    • Measure correction and recovery work as well as successful task completion.

    Pick one recurring workflow and write its contract before opening the visual builder. If you cannot identify the authoritative inputs, forbidden actions, approval point, and proof of completion on one page, narrow the job again. Once those boundaries are clear, OpenAI’s agent tools can automate the judgment bottleneck without quietly taking control of the whole operation.

    References