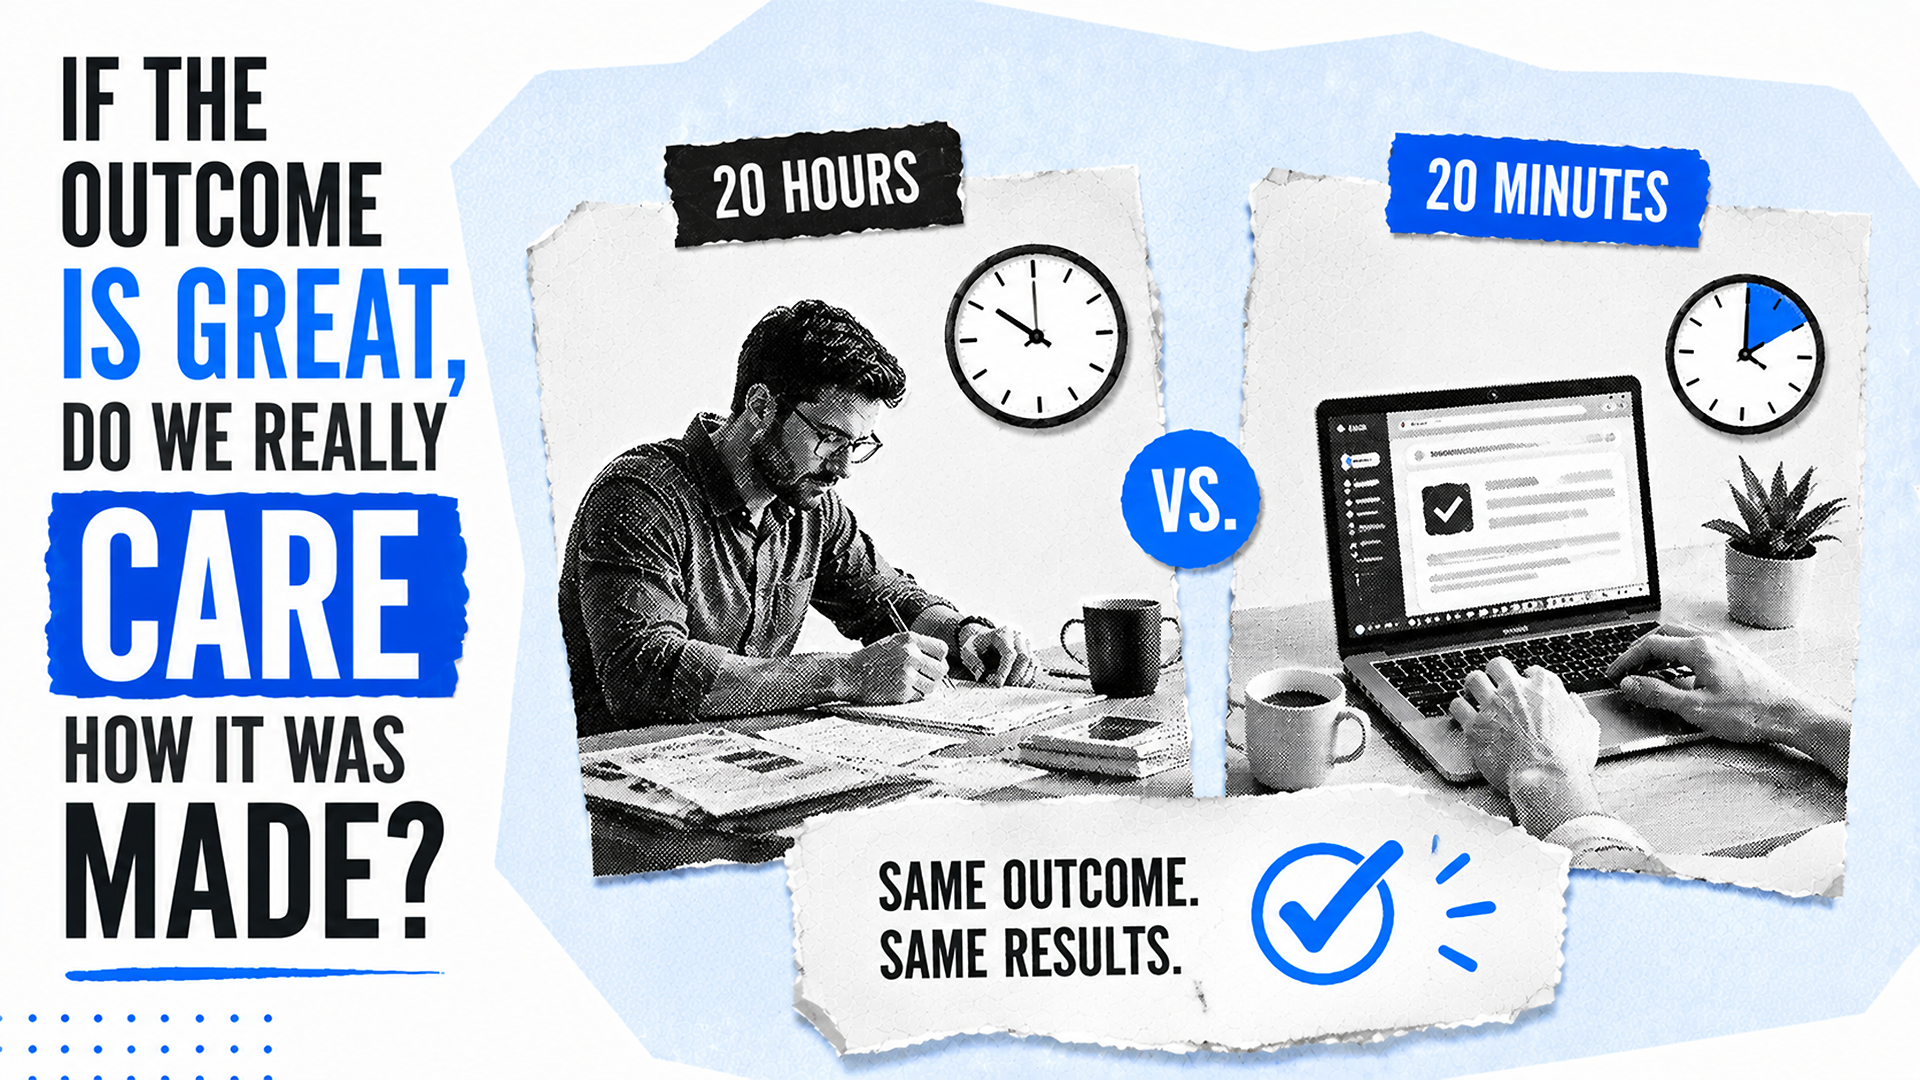
When I think about AI deliverables, I keep coming back to a simple scenario: a client receives two pieces of work.
Both deliverables solve the problem they were hired to solve. Both are accurate, useful, and tied to the same business outcome. The client is happy, and from the outside, there is no meaningful difference in the results.
Then the client learns that one took 20 hours to create, while the other took 20 minutes. That is when the uncomfortable questions begin.
Was AI involved? Should the faster deliverable cost less? Is the person who completed it less skilled because they found a faster, more efficient way to reach the same result?
What I find most interesting is how differently many of us react to AI depending on which side of the transaction we are on. I love using AI when it saves me time, but I also understand why customers can feel uneasy when they discover AI helped create something they paid for.
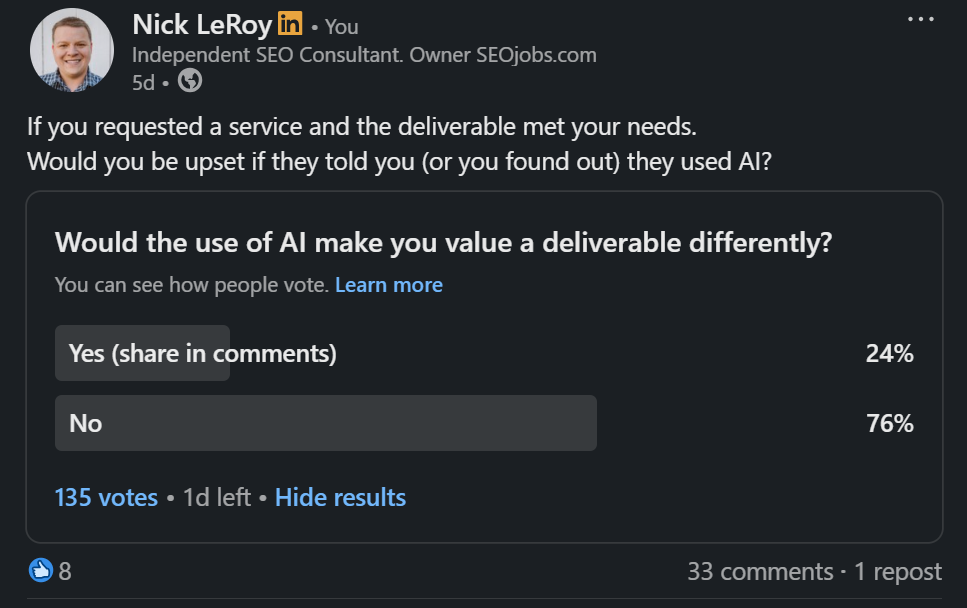
I recently ran a LinkedIn poll asking a simple question: if the outcome is great, do we really care how it was made?
The responses reinforced something I have been thinking about for a while. Many of the strongest objections people have to AI are not really about quality at all.
The Time vs. Value Fallacy
I think part of the discomfort comes from the fact that we have spent decades tying value to effort.
Long hours feel valuable. Fast work feels suspicious. Struggle often gets mistaken for expertise.
The harder something appears to be, the easier it becomes to justify the price attached to it.
There is an old story about a ship engine that stopped working. After multiple failed attempts to repair it, the owners brought in an engineer with decades of experience. He inspected the engine, tapped it once with a small hammer, and the machine roared back to life.
His invoice was $10,000.
The owners were furious and demanded an itemized bill. The response was simple: hammer tap, $2. Knowing where to tap, $9,998.
People debate whether that story is true or just a useful tale for people like me who believe in value-based pricing. But whether it really happened almost does not matter. The lesson still holds.
People are not paying for the tap. They are paying for the expertise behind it.
That is what makes AI such an important topic for me. It forces us to confront a question many of us have avoided for years: are we paying for expertise, or are we paying for visible effort?
Those are not always the same thing.
The Objections That Actually Matter
To be clear, I do not think every objection to AI is unreasonable. I have shared plenty of my own concerns, and some of them are serious.
In fact, I think the strongest arguments against AI have very little to do with how quickly something was created.
Those are legitimate concerns. What stands out to me is that none of them has much to do with how long it took to create the deliverable.
They are questions of trust.
Can the output be trusted? Can the recommendation be defended? Can someone confidently stand behind the work if it is questioned six months from now?
Because when something goes wrong, nobody gets to blame the AI. The employee is accountable. The consultant is accountable. The company is accountable.
That is why I have always found the quality debate to be the least interesting part of the conversation. The more important question is not whether AI was involved. It is whether the outcome is trustworthy enough for someone to put their name behind it.
The Outcome Test
The more I think about AI, the less interested I become in whether it was used.
Instead, I find myself asking a different set of questions. Was the outcome accurate? Was it useful? Was it better than the alternative? Would I be willing to stand behind it with my name, reputation, and credentials on the line?
If the answer to all of those questions is yes, then I have a hard time arguing that the production method matters more than the result.
Ironically, this is also where humans become more important, not less.
The future is not machines versus humans. I know, "The Terminator" and "I, Robot" movies will never feel the same. The real shift is humans using AI versus humans who refuse to adapt.
AI can accelerate execution, but people still decide what should be built, what should be published, and what risks are acceptable. More importantly, people are still responsible for the outcome.
The people who lose to AI will not be the ones using it. They will be the ones still evaluating effort while everyone else is measuring outcomes.
This post first appeared on the author’s website and is republished here with permission.
My heart sank when I learned that Bruce Clay had passed away. I knew he had been in the hospital, but my mind went straight to the two long conversations we had last fall: one simply to catch up, and one for what would become a deeply meaningful podcast interview.
I first reached out to Bruce nearly 25 years ago. I had emailed him cold to ask whether I could republish some of his industry writing about ethics. He said yes. Somehow, the article I cited unintentionally ranked No. 2 on Google for “Bruce Clay” for years. I joked with him about that more than once, and he always seemed both amused and slightly annoyed, probably because I had done it with his own content and his own blessing.
A few years later, I worked with Bruce and many other search professionals on the board of the Search Engine Marketing Professionals Organization, better known as SEMPO. It was a business nonprofit built to support and legitimize the then-new search industry. We promoted best practices, helped make the business case for search, and later became involved in U.S. Internet policy work in the early 2010s.
SEMPO brought together board members from around the world, and in a very literal way, it took some of us around the world. That work is where I really got to know Bruce. Later, we would run into each other at conferences, sometimes even on the same panels. We were doing serious work, but we also had a great time doing it. The organization lasted about 15 years, and if I remember correctly, Bruce was one of its founding members around 2000 or 2001.
One memory of Bruce has stayed with me vividly. A group of us from the SEMPO board were walking back to our hotel on the east side of Midtown Manhattan after dinner. A snowstorm had just begun, one that would leave several feet of snow by the next day. The usual roar of traffic had been softened by the weather and the empty streets. It was eerie, but almost joyously quiet. The city that never sleeps seemed to be taking a nap under a blanket of snow.
Then something happened that I had never seen before, and have never seen since.
As snow poured silently into the streets, a massive lightning strike hit just a few blocks away, over Bruce’s shoulder. I do not know whether he saw it directly. It felt like an explosion. We stood there for several minutes trying to understand the contrast: a shattering bolt of lightning between skyscrapers, in the middle of a torrent of snowflakes, with not a drop of rain.
None of us knew what to call it. I believe Bruce called it “thunder snow,” and the name stuck. In that moment, his naming streak continued.
Bruce was, and remains, the real deal in search. His legacy was never only about coining a term. He pushed the field forward, taught others generously, and stayed deeply connected to the people he cared about. Like many of the earliest professionals in search, he helped shape practices that still feel foundational today. Through his writing, interviews, books, tools, and hundreds of industry events, he became one of the people the industry looked to for clarity. For many who remember the beginning, and for many who still followed him closely, Bruce was the GOAT.
I always felt that Bruce approached search intellectually. I do not think he saw it only as a job. It was exciting, unfinished, and new. Very few people get to help invent an entirely new discipline, and Bruce understood what that meant. He also recognized that AI is one of those moments now, and he approached it with the same curiosity, energy, and insight he brought to early search. Many people in the industry may only now be realizing that Bruce pioneered things they do every day. They feel obvious now, but they were not obvious then. Even the basics had to be debated and established.
He was not only passionate about search. He was passionate and generous toward the people in search. If you cared about the work, you were part of his tribe. That was true for thousands of people in the industry, myself included.
With Bruce, I could get deep into the weeds of the trade and still talk broadly about where everything was headed. He was an engineer with an MBA, and that combination came through in his leadership, expertise, and authority. He understood the work from top to bottom, and then back to the top again.
He was also genuinely kind. He had friends around the world. In our last conversations, I sensed that he was content with his life and accomplishments, and that he felt blessed by the path life had given him. He had nothing left to prove.
In the podcast interview, Bruce was as sharp and insightful as ever. He offered some of the most sensible thinking I have heard about where search is going in the world of LLMs. He was still innovating, just as he had been when search first began taking shape nearly 30 years ago.
Because search is so closely tied to language, I have been especially interested in how we think about, and what we call, this “new” thing. Bruce’s perspective helped crystallize my own research. Over the last year, I have watched much of the industry move toward the same conclusion he shared in our discussion.
If you are one of the many thousands of people who talked shop with Bruce over the years, I think you will recognize him in the ideas that follow. You may even relive some of your own conversations with him.
As I reviewed the podcast transcript, I realized we had recorded hours of conversation beyond search, including cars and all kinds of other subjects. At the end of our first conversation, he said goodbye with great love and care. That was Bruce. Those words land differently with me now, and they always will.
Rest in peace, Bruce. I miss you already.
What Bruce taught me in our final industry conversation
When I asked Bruce to talk about how he got started in the 1990s, he took us back to 1996. He had been working in corporate roles and wanted to become a consultant. His background was in math, programming, mainframes, PCs, networking, and optimization. When the Internet began moving into the mainstream, he saw something that matched both sides of his skill set: marketing and technical work.
He started studying search engines because that was where the opportunity was. He experimented with what they wanted, adjusted web pages, and watched rankings appear. Then people began calling him and paying him. What he thought might become a one-person consulting business grew quickly into something global, with offices and work across Japan, Australia, Asia, Europe, India, and beyond. Bruce told me he never would have predicted it would take off the way it did.
I reminded him how small the field was in those days. There were literally only tens of people doing this early on. Bruce was one of the first to build a legitimate service for businesses that needed to rank for their own brand names and for broader generic terms, while other corners of the field were still experimenting with black-hat tactics.
Bruce pointed out that this was three years before Google. Search was a wild west. There were more than 20 major search engines, and many of them were taking data from one another. At the first SEO conference he remembered attending, all of the leading people in the field sat together at one round table in a bar. He joked that if a natural disaster had happened there, the whole industry might have disappeared.
We talked about Danny Sullivan, Search Engine Watch, Search Engine Strategies, and the early vocabulary of the industry. Bruce had long been credited with helping coin the term “SEO,” though he was careful to say that no one can know who said something first. What he did know was that only a handful of people were in the room when the term started to take hold.
At the time, other terms were in play, including “search engine positioning” and “ranking.” Bruce believed “optimization” won because it sounded technical, valuable, and precise. It was like fine-tuning a race engine. People could see themselves building a profession around it. Once the industry attached itself to that word, the term spread quickly around the world.
That led us into the newer terms now being proposed around AI, including AIO, GEO, and AEO. I have been writing about how many of these terms still depend on the word “optimization.” Bruce’s view was clear: search engine optimization was never limited to organic blue links. It was about optimizing for anything a search engine produces that can drive business and traffic.
In Bruce’s view, if AI appears inside search and influences discovery, citations, visibility, or traffic, then it belongs under SEO. GEO and AIO were not separate disciplines to him. They were extensions, just like link building or on-page optimization. He warned that many new terms are marketing labels more than practical new fields. If the work required to appear in AI results is still mentions, links, schema, authority, content structure, and rankings, then the work is still SEO.
That point stayed with me. Bruce said that if someone claims you no longer need SEO and only need AI optimization, you should watch closely, because either they are going to do SEO under a different name or they do not understand what they are doing. He believed ranking in AI was possible, but the method was deeper and more complex than traditional SEO. To him, it was still SEO, just several levels more advanced.
We also discussed whether AI feels like search did in the late 1990s. Bruce believed it does in important ways. AI depends heavily on search engines because search engines have spent decades fighting spam and building trust signals. AI systems do not yet have that same history, so they rely on what search engines have already learned to filter, evaluate, and rank.
Bruce also believed AI could still be gamed at the content level. If enough pages repeat a false idea, an AI system may begin to treat it as true. He had already seen examples of people trying to influence AI answers by placing their names into “best SEO” lists across enough sources. To him, this was a sign that AI would need its own version of the spam fight search engines have been having for decades.
One of the most important parts of our conversation was Bruce’s explanation of Google AI Mode and how it changes the way SEOs should think about structure. He described how a query can produce an overview, followed by sections and subsections that allow users to drill into narrower parts of a topic. When a user clicks into a section, the supporting sites can change to match that specific subtopic.
That means content cannot simply be built around one broad keyword anymore. Bruce believed pages need to be structured so each section can stand on its own as an expert answer. A page should support a topic, but every H2-level section may need its own clarity, completeness, and internal logic. In his view, this raises the importance of siloing across a site and within a page.
I framed this as a shift from keyword-led thinking to context-led thinking. Bruce agreed and connected it to entities, fan-outs, references, and cross-links. Keywords helped build the industry, but he believed the future depends on understanding entities in context. If content cannot answer the question clearly, it fails the core purpose of AI-assisted search.
Bruce described the long-term target as something like the Star Trek computer: no matter what question someone asks, the system provides the answer. We are not there yet, but that is the direction. For websites, he believed the future architecture is question-centered, highly usable, structured into sub-silos, and able to answer and refer within a page while also fanning out to supporting pages.
That naturally led us to content. Bruce said that for years SEO treated content like a stepchild, but now content is a peer. If SEO teams and content teams do not share the same goal, they will keep writing the way they did 20 years ago and fail in the AI search environment. He was already being hired to train content teams, even though he did not consider himself a “content guy” in the traditional sense.
He believed the industry still suffers because SEO and content do not cross-pollinate enough. Content marketers may not attend SEO conferences, and SEOs may not spend enough time learning how content teams actually work. That separation matters more now because the structure of a page, the expertise of each section, and the way a topic is divided all affect visibility in AI-driven search experiences.
Bruce’s advice was direct: stop spreading one keyword across a page and calling that optimization. Instead, build each section as if it were a standalone expert answer. If the sections belong to the same theme, they should support one another, but each needs to carry its own weight. In his words, the hierarchy is no longer only the page. The hierarchy is also the section of the page.
When I asked Bruce about AI-generated content, he made an important distinction. AI is a tool, not a solution. He did not believe businesses should simply generate content, read it once, and publish it. Detection tools are inconsistent, and search engines may not reliably identify every AI-generated page. But that does not make low-effort AI content a good strategy.
Bruce believed AI is strongest as a research assistant. His own Pre-Writer product was built around that idea: gather deep research and give a human writer a stronger starting point. The writer still finishes the work, adds style, voice, judgment, compliance, and business understanding. For Bruce, reducing a four- or five-hour writing project to two hours was a win. Replacing the writer entirely was not.
He was especially clear that writers are artists. AI does not know a business the way its people do, and it does not bring the same finesse or judgment. The future, in Bruce’s view, requires writers, SEOs, and AI workflows to be integrated around shared goals. Without that maturity, teams will keep producing pages that look like they were built for search 10 years ago, and those pages will be ignored.
We ended by talking about tools. Bruce reminded me that in the beginning, he wrote tools because none existed. He built one of the first page analyzers, including what he once called a keyword density analyzer. He later received a patent related to that kind of technology. His tools were never meant to replace large platforms like Semrush, Ahrefs, or Surfer. They were meant to extend them by analyzing things those platforms did not.
Bruce pointed people to seotools.com and described the tools as inexpensive power tools, not products designed for the masses. Some users did not understand them at first, but came back later when they saw the value. He was still building, still solving problems, and still thinking about what the industry needed next.
Near the end, Bruce mentioned a newer tool designed to show traffic loss through Search Console data over time, helping site owners see whether they had fallen off a cliff or declined gradually. It struck me as classic Bruce: while others complained that something should exist, he was building it.
I thanked him for the conversation, and he answered with warmth: he was glad I had him on, and he loved talking with me. I hear those words differently now. I am grateful we had that final conversation, and I am grateful for everything Bruce gave to search, to this industry, and to the people inside it.
A modern SEO workflow has to do more than collect rankings and audit errors. It must distinguish visibility from traffic opportunity, focus limited time on pages that matter to the business, and turn recurring analysis into reliable automation.
The most useful operating model is therefore not a wholesale replacement of traditional SEO software. It is a layered system in which established data sources reveal the problem, people choose the intervention, and AI-assisted tools reduce the cost of repeating proven work.
The operating model matters more than the size of the stack
Rank trackers, keyword platforms and site crawlers remain useful because search engines still need to discover, interpret and evaluate pages. However, the reported case for a new SEO stack is that those tools describe only part of a more fragmented search environment. AI Overviews, local packs, shopping features and other result formats can change how much value a nominal ranking produces. Historical search volume can likewise remain stable while an answer displayed in the results reduces the traffic available to publishers.
That changes the role of measurement. A ranking is an observation, not an outcome. The workflow must connect traditional visibility, AI-search presence, landing-page behavior and conversion evidence before deciding what deserves attention. The same source reported that LLM referral traffic in its cited dataset grew by 80% between the first and second halves of 2025 and converted at 18%, while accounting for 2% or less of total traffic. Those figures were presented as evidence of a small but potentially meaningful channel, not as proof that conventional search had ceased to matter.
Workflow layer
Question it answers
Typical inputs
Required output
Observe
Where is visibility, demand or performance changing?
Search Console, analytics, rank tracking, crawls and AI-visibility observations
A short list of material signals
Decide
Which signal is worth acting on now?
Business value, intent, conversion proximity and implementation effort
One prioritized intervention
Ship
What can improve the page or remove the constraint?
Content edits, internal links, technical fixes and clearer conversion support
A completed change or actionable brief
Systematize
Which repeated work should become faster and more consistent?
APIs, scripts, notebooks and carefully supervised LLMs
A documented, testable process
This sequence prevents a common tooling mistake: automating a report before establishing which decision the report should support. It also preserves a place for human judgment between data collection and implementation.
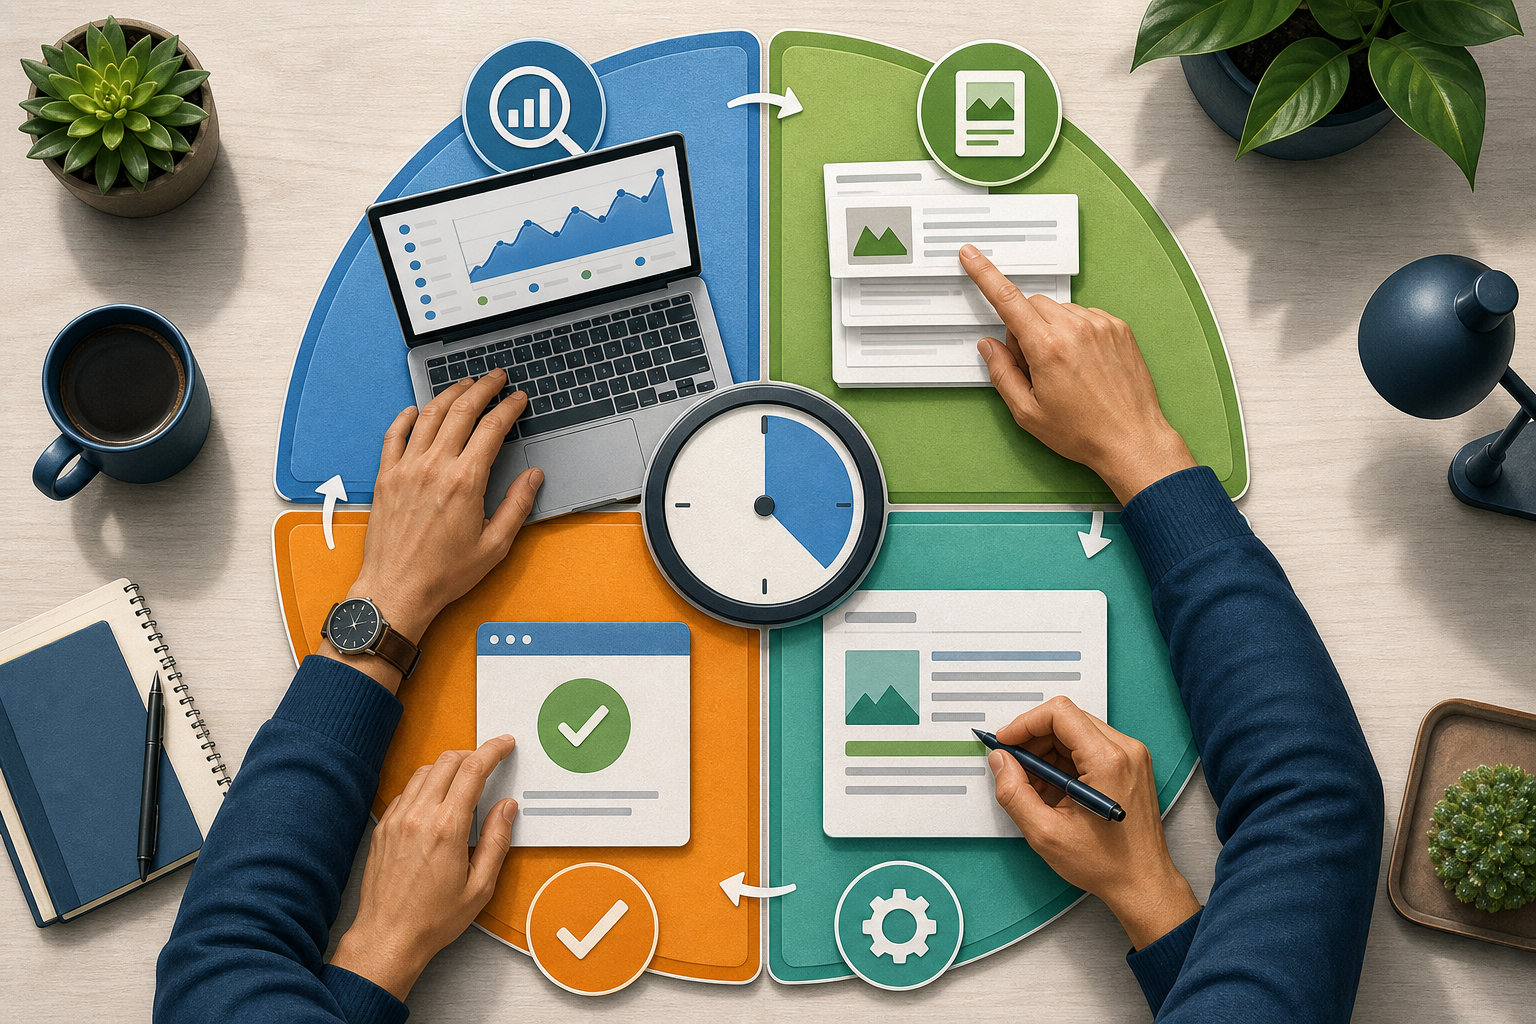
A 120-minute loop can connect monitoring with delivery
The reported 120-minute workflow addresses a practical constraint: on a lean marketing team, SEO competes with campaigns, reporting, email, social publishing and website requests. Its strongest principle is that a weekly session should finish with work shipped, not merely with more metrics reviewed.
The first five time boxes below follow the source’s reported schedule. The final 20-minute block is a synthesis of the other sources’ automation guidance, turning the weekly session into a tool-development feedback loop.
Minutes 0-15: inspect Search Console and analytics for meaningful movement, including clicks, impressions, click-through rate, landing-page performance, conversions and critical indexing warnings. Record the largest win, concern and investigation target rather than building a presentation.
Minutes 15-35: identify a small number of query opportunities. The source recommends examining queries in positions 4-15 with meaningful impressions, pages with weak click-through rates and results where the ranking page only partly satisfies intent.
Minutes 35-60: improve one page close to revenue, such as a product, service, category, pricing, comparison or consultation page. The change might address an objection, clarify the audience, add proof, answer a relevant question or make the next action easier to understand.
Minutes 60-80: resolve one consequential technical or indexing problem. If a direct fix is not possible, produce an assigned issue or a developer brief with affected URLs and the expected behavior.
Minutes 80-100: strengthen internal links between useful informational pages and relevant commercial destinations, while also connecting supporting guides and newer strategic content.
Minutes 100-120: verify what changed, document the result and mark one repetitive task as a possible automation candidate. That candidate should enter a backlog rather than becoming an improvised build during the same session.
The value of this cadence is not the clock alone. It creates a recurring path from signal to decision to change. It also generates concrete automation ideas: a comparison performed every week, a recurring CSV cleanup, a repeated title check or a manual alert that depends on the same thresholds each time.
Small tools should begin with a bounded decision
The source on vibe coding describes a low-barrier pattern: specify a program in natural language, run the generated code in an environment such as Google Colab, inspect the output and return errors to the AI for another iteration. It distinguishes this from AI-assisted coding, where a developer remains more directly responsible for the system, and from no-code platforms, which expose automation through visual interfaces.
The distinction helps set an appropriate ceiling. Vibe coding is presented as suitable for prototypes, internal utilities, demonstrations and tasks where a useful result does not have to be perfect. Commercial software, sensitive systems and products requiring dependable maintenance call for stronger engineering, security and testing practices.
A reported SEO example makes the right project shape clear. After a site crawl produced vector embeddings, the author prompted an AI to create a Colab tool that would compare vectors with cosine similarity and suggest related pages within each locale. The program had an explicit input, a defined matching rule and a CSV output. It did not attempt to automate an entire SEO strategy.
Before generating code, a useful tool brief should define:
The decision or bottleneck the tool is meant to improve.
The exact input source, required columns and accepted file format.
The transformation or rule applied to the data.
The expected output format and who will use it.
A small set of known examples for checking correctness.
The behavior when data is absent, duplicated, malformed or unexpectedly large.
The APIs, credentials, usage charges and execution environment involved.
Tool choice can then follow complexity. An LLM may be enough to explore a one-off dataset or review copy. An API becomes useful when manual exports are the bottleneck. A lightweight script suits a stable transformation such as flagging performance changes or checking metadata. A notebook is appropriate when code, commentary and outputs need to remain together. A maintained application is warranted only when the process has durable users, permissions, interfaces and support requirements.
Validation is part of the workflow, not a final polish
All three sources point toward speed, but they also expose different reasons to retain human control. The new-stack article recommends using LLMs for analysis, content review, competitor comparison, metadata and structured data while keeping editorial and strategic oversight. The weekly workflow keeps prioritization tied to commercial importance. The vibe-coding account shows why plausible-looking output cannot be accepted on appearance alone.
In one example from the vibe-coding source, an underspecified prompt failed to explain that the input would be a CSV. The generated tool responded with invented URLs, traffic figures and charts. The same source reports that generated code can depend on packages that are not installed, and that paid APIs may introduce authentication steps and usage costs. These are not edge concerns: they demonstrate that execution, factual grounding and operating cost must all be tested separately.
Ground the run: identify the authoritative input and reject synthetic substitutes unless test data is explicitly requested.
Test a sample: compare several outputs with results that can be checked manually, including an ordinary case and an edge case.
Inspect failure behavior: confirm that missing columns, empty files, invalid credentials and API errors produce understandable messages.
Protect access: keep credentials out of prompts, shared notebooks, exported files and source code intended for distribution.
Track cost: estimate which calls consume paid API units or usage-based platform resources before scheduling repeated runs.
Preserve review: require a person to approve consequential content changes, redirects, canonical decisions, schema deployment or other site-wide actions.
Document ownership: record the tool’s purpose, dependencies, expected inputs, validation method and person responsible for maintenance.
A prototype should be promoted into a recurring workflow only after it produces repeatable results on known data. If the logic affects many pages or a revenue-critical system, code review and stronger testing become proportionally more important.
Key takeaways
Keep traditional SEO data, but interpret rankings and search volume alongside result features, traffic opportunity and business outcomes.
Time-box reporting so that every weekly SEO session produces a shipped improvement, an assigned fix or a precise implementation brief.
Use recurring manual work to discover automation opportunities; do not begin with a tool and search for a problem afterward.
Give every small SEO utility explicit inputs, transformation rules, outputs, test cases and failure behavior.
Treat LLMs, APIs and scripts as accelerators within a reviewed process, not as substitutes for strategy, factual checks or technical ownership.
As search interfaces continue to diversify, the durable advantage will come from shortening the distance between a trustworthy signal and a verified improvement. Teams can build that capability incrementally, one weekly decision and one well-scoped tool at a time.
With Projects in Profound, I can turn my AEO data into a clear, ranked list of opportunities instead of another report I have to interpret from scratch.
Each opportunity is broken into practical tasks, with an agent ready to help do the work. That makes it easier for me to move from insight to execution without getting stuck in endless analysis.
For me, Projects is about spending less time deciding what to do next and more time acting on the opportunities that can improve visibility, performance, and momentum.
I see existing content as a goldmine, but only when I have a practical way to improve it. The hard part is usually finding the time, and that is where Claude has made a large, messy job feel much more manageable for me.
I do not start by building a giant content audit system. I start with one article, run one focused audit, refine the output, and then turn the prompt into a reusable Claude skill. Over time, those one-off audits become a working library I can improve every time I use it.
I use Claude to uncover topical gaps, flag outdated information, check brand voice, and evaluate whether a page is easy for AI systems to retrieve and cite. The real value comes from iteration: each time I improve a skill, the next audit becomes faster and more useful.
Here are six content audit workflows I would build in Claude. The first four work at the page level, so I can start with a single article before moving into larger library-wide analysis.
Page-level audits
When I am not ready to build a full workflow, I start with page-level audits. These audits only require one article, which means I do not need a content inventory, a data export, or a complicated setup. After each session, I ask Claude to turn the process into a reusable skill for future page-level reviews.
1. Brand voice consistency
I use a brand voice consistency audit when a content library has drifted over time. Voice can shift because of new writers, changing services, product updates, or evolving positioning. This audit helps me spot where a page no longer sounds aligned with the brand.
If I do not have detailed brand guidelines with strong examples, I let Claude extract the voice guide from high-quality content. That usually works better than relying on vague phrases like “conversational but authoritative” or “educational, not too formal.”
I pick three to five articles that represent the brand at its best. If possible, I download them as markdown files and ask Claude to describe how the voice works in concrete terms.
How the articles usually open, such as whether they begin with a direct claim, a counterintuitive statement, or a specific scenario.
How sentences and paragraphs are built, including average length, range, rhythm, and how paragraphs tend to close.
Three to five personality dimensions framed as “We say X, but not Y,” with do and don’t examples.
Words and phrases the brand tends to use, and words or phrases it should avoid.
Specific constructions, phrases, and conventions the brand never uses.
Instead of accepting a vague voice description, I want Claude to return concrete observations. For example, it might say that articles open with a direct claim rather than a scene-setting paragraph, sentences average 15 to 20 words and rarely exceed 30, and transitions are functional, such as “here’s why that matters,” rather than formulaic, such as “furthermore.”
I also want example pairs, such as: “We’d say ‘the data shows three things,’ not ‘there are multiple factors to consider.’” The goal is not to create a voice guide for writers. The goal is to create one an LLM can understand and apply consistently.
Once I like the output, I ask Claude to save it as a skill and evaluate an article against it. If Claude flags issues I disagree with, I update the skill until the feedback becomes useful and repeatable.
I can then use that skill to find voice inconsistencies in older content, check new drafts for alignment, and even generate more on-brand first drafts. I still edit the output, but the starting point is much stronger.
When I need to improve content performance, I use a coverage comparison to find topical gaps. This helps me understand what competing pages cover that my article misses.
I use the Claude in Chrome extension to have Claude review the top three to five ranking pages for my target keyword. Then I ask Claude to compare those pages against my content and highlight the most important gaps.
What competitors are doing well.
What my article already does well.
Where I can improve the piece without bloating it.
If I want the output in a table, I ask Claude to format it that way. If I want a downloadable DOCX for review or handoff, I ask for that instead.
When Claude recommends additions I would never publish, I make a note of those exclusions before packaging the workflow into a skill. That way, the skill gets closer to my editorial standards each time I refine it.
3. Freshness audit
Old content adds up quickly, and it is hard to prioritize refreshes while I am also producing new material. A freshness audit skill helps me identify what needs attention without rereading every older article from scratch.
I give Claude an older article and ask it to flag anything time-sensitive: statistics tied to a specific year, named tools or platforms, references to “current” or “recent” trends, and claims that depend on a market, regulatory, or product context that may have changed. I am not asking Claude to rewrite the article yet. I am asking it to build an issue list I can act on.
If my company has launched new products, removed old services, changed positioning, or updated terminology, I include that context in the input. That helps Claude flag what should be added, removed, or revised.
I use an AEO and AI retrievability audit to understand whether a page is likely to be surfaced in AI-generated answers. Tools such as ChatGPT, Perplexity, and Google AI Overviews tend to favor content that answers questions directly. If an article buries the answer under too much preamble, or structures key information in a way that is hard to extract, it becomes less useful for those systems.
I give Claude the article and the target query, then ask it to evaluate several retrieval signals.
Whether the article answers the main question directly and early.
Whether key statements are specific enough for an LLM to quote or cite.
Where an FAQ-style section would improve clarity.
Whether the page includes authority signals, such as primary research, first-person experience, outbound citations, or specific examples.
Once I save this as a skill, it becomes an extra editor focused specifically on AI visibility and answer retrieval.
Library-level audits
Once I am ready to move beyond individual pages, I use library-level audits. These require performance data, a content inventory, a connector, or a manual export.
5. Performance triage
When I think about a traditional content audit, performance triage is usually what comes to mind. It helps me analyze a content library and identify the pages that deserve attention first.
Before I begin, I make sure Claude has access to the right data through a connector such as BigQuery or the Semrush API. If that is not available, I export the data I normally use for large-scale audits, such as traffic, clicks, engagement metrics, conversions, rankings, and related performance signals.
I ask Claude to prioritize pages that have suffered meaningful performance drops in the past six to 12 months, pages with high impressions but consistently low click-through rates, and pages that have been live long enough to rank but never gained traction.
I also define what a meaningful performance drop looks like for the site I am analyzing, because traffic patterns vary by industry, audience, and page type. Then I ask Claude for a prioritized list of what is worth investigating and why. From there, I use the page-level audits above to diagnose the problem.
If I have run this analysis before, I give Claude the previous output. That helps the skill learn the kind of prioritization and reasoning I expect.
I treat entities as a major part of AEO and semantic search. A topical gap analysis helps me see whether my content library has enough coverage to build authority around the entities tied to my brand.
The core question I ask is simple: what is my content library not covering that it should?
To start, I create a list of target entities. For example, at my agency, I want to be known for SEO and AEO. If I have a clear list of services or products, I can use that instead of a formal entity list.
Using Cowork or Code, I ask Claude to analyze my sitemap and compare it to those target entities. If I have a Screaming Frog export with URLs, page titles, and meta descriptions, I use that as input for a more accurate analysis.
Then I ask Claude to identify topic clusters that are missing or underrepresented based on the target entities, services, or products. If I want prioritization, I can use the Semrush MCP so Claude can check search volume for potential keywords.
Not every gap is worth filling. I filter the results against audience needs, business relevance, and editorial standards. Then I feed those decisions back into Claude so the skill produces better recommendations next time. The final list can go directly into my content creation workflow or be handed off to a content team.
I do not try to audit everything at once
I have seen content audits stall because the scope feels too large, not because the team lacks data. My preferred approach is to pick one audit and one article, run the workflow, save the skill, and use it again on the next piece.
For me, iteration is part of the value. I enjoy taking one Claude skill, improving it, and then chaining it with other skills to uncover more content opportunities. Starting small is what makes the system easier to keep using.
AI-era SEO is not simply conventional optimization with a new set of acronyms. It is an operating-model problem: companies must coordinate technical infrastructure, content, authority, product experience, analytics, automation and emerging discovery channels without turning every requirement into one impossible job or one sprawling tool.
The two source articles illuminate complementary sides of that problem. One examines the search leader capable of connecting functions; the other examines the technology decisions that support the work. Together, they suggest that durable performance depends less on finding a universal expert or building a universal platform than on establishing clear ownership, decision rights and maintenance standards.
Treat search as a connected business system
The leadership source describes employers seeking candidates who can span technical SEO, content, public relations, product, engineering, analytics, performance media and brand. Titles vary across SEO, AI search, AEO, GEO and agentic commerce, but the underlying demand is similar: someone must understand how decisions in one part of the organization affect discovery and growth elsewhere.
This interconnectedness matters because the apparent source of a search problem may not be its actual cause. The article notes that what looks like a content deficiency can originate in a product or technical constraint, while weak visibility can reflect insufficient authority rather than on-page optimization. Paid search can also reveal messaging problems that have consequences beyond the paid channel.
The tooling source reaches the same organizational boundary from a different direction. Its examples include workflows that evaluate content against personas, support translation and reporting, summarize activity from meeting notes, Slack and Jira, and turn recorded meetings into landing-page briefs. These are not isolated SEO tasks; they depend on information and participation distributed across teams.
An effective operating model therefore needs a connective layer. Its purpose is to identify where a discovery problem originates, assign it to the function able to resolve it and relate the result to a business outcome. This becomes especially important when generative systems provide answers directly and traffic is no longer the only meaningful expression of search visibility, as the leadership article argues.
Design the function before recruiting its leader
The leadership article reports substantial inconsistency between search job titles, descriptions, recruiter screening and interview expectations. It cites postings ranging from Head of SEO and Director of AI & Organic Search to AEO/GEO Manager and Agentic Commerce GEO Consultant. In some cases, an advertised SEO role reportedly emphasizes paid platforms or other responsibilities that do not match its title.
This is more than a naming problem. A company may need a specialist who executes, a manager who builds a team, an executive who integrates search with adjacent functions or a consultant who determines what should be done. Those are different mandates. Combining them without defining authority, resources and expected outcomes makes both hiring and subsequent performance management unreliable.
The practical response is to define the function before defining the candidate. The organization should decide which decisions the role owns, which work it performs directly and which capabilities remain with engineering, content, brand, analytics or media teams. The search leader can then serve as an integrator without being treated as a substitute for every specialist.
Selection should also test judgment rather than depend entirely on title history or software keywords. The leadership source emphasizes the ability to distinguish material technical issues from distractions, recognize when a content problem requires an external solution, and decide when to invest, automate, pause or advise against an initiative. It also warns that conventional applicant-tracking and recruiting processes may exclude candidates whose cross-functional experience appears nonlinear.
A scenario-based hiring process is better aligned with that need. Candidates can be asked to diagnose an ambiguous visibility decline, allocate ownership across functions or explain what evidence would justify a new automation investment. This tests the integrative capability the role actually requires while exposing whether the company has given the position enough support to succeed.
Build a portfolio of tools, workflows and services
The technology decision should begin with precise classification. The tooling source distinguishes a custom internal tool from a repeatable multi-application workflow, a custom layer built on a software-as-a-service platform and a more autonomous AI agent. Calling all four an agent or an AI tool conceals meaningful differences in cost, risk and maintenance.
AI has lowered the barrier to prototypes, according to that article, allowing SEO teams to assemble assistants, connect data and automate analyses with less engineering help. It has not eliminated the obligations that follow a successful experiment. Token consumption, API calls, infrastructure, engineering time, security reviews and ongoing upkeep can remain real costs even when they do not appear in the SEO budget.
The source’s prompt-tracking example demonstrates the gap between a prototype and an operational system. A colleague initially created a tracker, but manual trend visualization and changes among large-language-model tools produced a maintenance burden. The team ultimately moved to a specialist platform because dependable data presentation mattered more than preserving the internal build.
That experience supports a portfolio approach. Stable, business-critical capabilities such as crawling, rank tracking and AI-visibility monitoring may favor established platforms when the team cannot sustain them internally. Context-heavy processes tied to proprietary knowledge may favor custom workflows. A custom layer over purchased software can provide the middle ground by combining reliable external capabilities with analytics or prioritization based on internal data such as Google Analytics, Google Search Console or CRM information.
The decision is therefore not a permanent contest between building and buying. A small internal prototype can clarify requirements and reveal complexity before a purchase, while a purchased platform can supply dependable foundations for differentiated internal processes. The relevant question is which parts of the capability create unique value and which parts merely need to work consistently.
Govern initiatives from problem definition through maintenance
Clear intake criteria connect the leadership and tooling models. The tooling source recommends beginning with the problem, its expected value, the intended users, the relative cost of available approaches and the consequence of doing nothing. It also advises mapping the current workflow against the desired workflow, looking for revenue contribution, time saved, quick returns and benefits shared across teams.
Those questions should become a standing governance process rather than a one-time procurement exercise. Each initiative needs an accountable business owner, an operational owner and an explicit maintenance commitment. Reliability, data access, security and usage-based costs belong in the initial decision because they determine whether an experiment can become part of routine operations.
The search leader’s role in this process is not to approve every tool personally. It is to keep local automations aligned with the wider discovery strategy, surface dependencies and prevent teams from optimizing a narrow metric at the expense of the customer journey. Engineering and security can evaluate technical exposure; content and brand teams can protect accuracy and positioning; analytics can establish measurement; and operational users can determine whether a workflow remains useful.
This structure also creates a rational stopping rule. A pilot that produces insight but cannot meet reliability or maintenance requirements may still be valuable if it improves the specification for a purchased service. Conversely, a workflow that depends heavily on internal context and produces repeatable value may justify further investment even when a generic platform is available.
Key takeaways
Define search as a cross-functional system with explicit ownership, rather than a collection of isolated SEO tasks.
Separate the mandates of specialist, team leader, integrating executive and adviser before opening a search role.
Evaluate leadership candidates through judgment and cross-functional scenarios, not title matching alone.
Distinguish custom tools, workflows, software layers and autonomous agents before comparing costs or risks.
Treat prototyping, procurement, security, measurement and maintenance as one governed investment lifecycle.
As AI discovery develops, the most resilient SEO organizations will be those that can change tools and channel tactics without repeatedly redesigning accountability. A clear operating model makes that adaptation possible: leadership connects the system, specialists retain depth, and technology is selected according to the work it must sustain.
AI can make hreflang sitemap production far more manageable, but the useful automation is not simply XML generation. The difficult part is deciding which URLs represent equivalent pages across domains, languages and regional site structures.
A reported multilingual SEO project shows how crawl data, deterministic matching, semantic analysis and repeated human review can be combined into a practical workflow. Its broader lesson is that AI works best as a tool for developing and refining the matching system, while SEO specialists retain control of equivalence rules and quality assurance.
The real challenge is URL equivalence, not XML syntax
An hreflang sitemap groups alternate versions of a page and associates each version with an appropriate language or language-region value. Writing those relationships into XML is comparatively mechanical. Establishing that the relationships are correct is where complexity accumulates.
The supplied case study involved more than a dozen websites across three businesses and eight regional domains. The sites covered several languages as well as three English dialects, while years of independent site development had produced translated folders, inconsistent slugs, changed directory structures and revision years appended to some URLs.
Those conditions make a single matching rule unreliable. Identical paths can sometimes identify alternates, but translated slugs will not match character for character. Conversely, two pages with similar titles may serve different purposes and should not automatically be placed in the same hreflang cluster.
A defensible automation workflow starts with crawl data
The case study began by asking Google Gemini to propose an approach rather than immediately requesting finished code. That distinction mattered: the proposed architecture separated data collection, URL processing, matching and XML output, making each stage easier to inspect and revise.
Crawl every participating site and export live URLs with useful comparison fields such as status codes, titles and H1 headings.
Remove URLs that should not become hreflang destinations, including non-indexable pages and URLs that return errors or redirect elsewhere.
Assign the intended language or language-region value through an explicit domain or directory mapping.
Normalize URLs so superficial differences do not prevent legitimate comparisons.
Run high-confidence deterministic matching before applying semantic methods to unresolved pages.
Review candidate clusters, investigate unmatched URLs and correct false matches.
Generate the XML only after the underlying relationship data passes validation.
In the reported implementation, Screaming Frog supplied a unified CSV, while Python code ran in Google Colab and produced the XML tree. The author reported that Colab’s free version was sufficient for that project. These tools are implementation choices rather than requirements; the transferable principle is to preserve a clear path from crawl evidence to every generated relationship.
Matching should progress from certainty to inference
A reliable matcher benefits from layers. Exact and rule-based comparisons should resolve obvious cases first because their behavior is explainable. More flexible semantic methods can then focus on the smaller set of URLs that deterministic rules leave unresolved.
Normalize without erasing meaning
Normalization can remove known structural noise, such as a regional folder convention or a predictable revision suffix. The case study also encountered a US blog that had moved articles into topical directories while other regional sites retained flatter paths. Flattening those directories for comparison allowed related slugs to align.
That technique should be scoped carefully. A directory may encode a content type, product family or audience distinction rather than incidental structure. The safe question is not whether a path segment can be removed, but whether removing it preserves the page’s identity.
Use semantic signals as evidence, not proof
The reported script used SentenceTransformers for fuzzy matching based on titles and normalized URLs. Its rules initially rejected a legitimate English-Italian article pair because their titles were not close enough. The author responded by relaxing some controls for broad industry concepts while keeping tighter requirements around critical terms.
Another unresolved pair exposed a different limitation: the Spanish and English slugs expressed the same idea in different languages. The script was subsequently changed to build a combined semantic signature that translated slug meaning and used it alongside other page signals. This illustrates why title similarity, URL meaning and site context are stronger together than any one field in isolation.
Human review remains part of the production system
AI-assisted code does not eliminate the need for editorial and technical judgment. In the case study, the first output left some URLs orphaned, and later adjustments could have introduced overly aggressive matches. The improvement came through a repeated loop: run the script, inspect exceptions, provide concrete examples and revise the logic.
Quality control should examine both sides of the matching problem. False negatives leave legitimate alternates disconnected; false positives assert equivalence between pages that do not satisfy the same user need. Review is therefore better organized around risk than around a single similarity score.
Confirm that every destination is live, indexable and intended for search discovery.
Check that each cluster contains genuinely equivalent content rather than merely related subject matter.
Inspect low-confidence matches and unmatched URLs separately.
Test normalization rules against pages where folders or suffixes carry real meaning.
Keep domain-to-language mappings explicit rather than asking a model to infer them repeatedly.
Validate generated XML structure and sample the resulting relationships before publication.
The development process also needs an audit trail. Retaining the crawl input, normalized fields, match method and review status makes questionable clusters easier to diagnose. It also turns future reruns into a controlled workflow instead of an opaque model decision.
Key takeaways
Hreflang automation is primarily a page-equivalence problem; XML generation comes after the relationships are established.
Clean crawl data and explicit language mappings provide the foundation for trustworthy output.
Deterministic rules should handle high-confidence matches before semantic techniques evaluate difficult cases.
Titles, normalized paths and translated slug meaning can complement one another, but none should be treated as conclusive alone.
Concrete mismatches and orphaned URLs are useful test cases for refining both code and business rules.
AI can accelerate tool development, while an SEO specialist remains responsible for validation and publication decisions.
The most sustainable next step is to treat the matcher as maintained SEO infrastructure. As sites migrate, localization practices change and new content types appear, its rules and review samples should evolve with them. AI can shorten that maintenance cycle, but dependable hreflang still comes from observable data, bounded inference and accountable human approval.
I’ve recently delved into the world of veterinary SEO agencies and analyzed a whopping 73 companies. With a robust scoring system, I’ve ranked each based on eight criteria to ensure the firms making the list are truly top-notch.
The criteria include average review scores, leadership experience, being founder-led, notable clients, years established, average client tenure, and media references. Extra emphasis was placed on reviews from veterinary clientele, signaling relevance and client satisfaction.
After rigorous analysis, I’ve narrowed it down to the top 6 companies, and here’s the detailed ranking:
The Top Veterinary SEO Companies of 2026
1. First Page Sage: Leading the chart with an impressive blend of local SEO and GEO targeting.
2. Beyond Indigo Pets: Known for their holistic digital marketing strategies tailored for vet clinics.
3. LifeLearn: Offers an integrated platform that blends SEO with practice management.
4. True North Social: Focuses on SEO and social media to engage and convert pet owners.
5. Veterinary Marketing: Ideal for budget-conscious practices, offering essential digital marketing packages.
6. UppercutSEO: Renowned for their technical SEO expertise and local search improvements.
Insights on First Page Sage
Ranked first, First Page Sage utilizes a comprehensive thought-leadership SEO strategy. I found their approach to blend SEO with geo-targeting, engaging qualified veterinary leads. Their techniques help transform veterinary practices into authoritative local resources, driving meaningful traffic poised for conversion.
With AI becoming more prevalent in decision-making, they’ve innovated through generative engine optimization, giving clients a visible edge in AI-generated search results.
Highlights:
Average Review Score: 4.9
Leadership Experience Score: 4.9
Founder Led: Yes
Notable Clients: San Francisco SPCA, Blue Cross Pet Hospital, Lakeview Veterinary Hospital
Year Established: 2009
Average Client Tenure: 3.2 years
Media References: ~820
Approach to SEO: Local SEO and GEO targeting
Beyond Indigo Pets: A Closer Look
Beyond Indigo Pets tailors marketing strategies for veterinary practices, focusing on seasonal needs and competitive dynamics. While their services cover a wide array of digital marketing aspects, they do not specialize solely in SEO, which may be a consideration for practices in hyper-competitive areas.
Approach to SEO: Digital marketing for vet clinics
Exploring LifeLearn
LifeLearn offers a comprehensive suite integrating SEO with practice management, making it an appealing choice for those desiring a one-stop solution. However, if dedicated SEO specialization is your focus, you might explore other firms on this list.
Details:
Average Review Score: 4.6
Leadership Experience Score: 4.4
Founder Led: No
Notable Clients: N/A
Year Established: 1994
Average Client Tenure: 3.0 years
Media References: ~75
Approach to SEO: Integrated platform with SEO
Diving into True North Social
True North Social curates content that strikes an emotional chord with pet owners, transforming them into clients through strategic SEO and advertising. They prioritize intimate client engagement, which might limit their capacity for larger veterinary organizations.
Average Review Score: 4.4
Leadership Experience Score: 4.5
Founder Led: Yes
Notable Clients: N/A
Year Established: 2016
Average Client Tenure: 2.4 years
Media References: ~70
Approach to SEO: SEO, social media marketing, PPC
Understanding Veterinary Marketing
If your practice operates on a tighter budget, Veterinary Marketing offers essential services to get you started with online growth. While their packages are budget-friendly, you might need additional expertise for advanced SEO strategies.
Approach to SEO: Veterinary-specific SEO, PPC, social media
Delving into UppercutSEO
UppercutSEO focuses on technical SEO fundamentals, beneficial for practices needing foundational web optimization. They may not cover veterinary-specific insights that others on this list specialize in, so keep that in mind.
Average Review Score: 4.4
Leadership Experience Score: 4.4
Founder Led: Yes
Notable Clients: N/A
Year Established: 2020
Average Client Tenure: 1.8 years
Media References: ~95
Approach to SEO: Technical SEO and local search
The Best Veterinary SEO Companies by Specialty
Our in-depth analysis also classified top veterinary SEO agencies into three key specialties reflecting unique client needs: content marketing, local search optimization, and technical implementation.
AI is making many familiar SEO outputs faster and cheaper to produce, but it is not making the underlying decisions easier. The emerging premium is on expertise that can distinguish plausible advice from worthwhile action, connect search work to business outcomes, and carry priorities through implementation.
Across technical SEO, content, and AI visibility, the practical question is therefore no longer how many recommendations a team can generate. It is which intervention deserves scarce time, what evidence supports it, and how success should be measured.
Recommendation volume is becoming a weak proxy for expertise
The career analysis in Search Engine Land argues that AI is changing the value of SEO skills more than it is directly targeting the profession. Audits, briefs, keyword work, and optimization suggestions remain useful, but AI can produce versions of them quickly. If recommendations become inexpensive, a long report is less persuasive evidence of expertise than the judgment used to select, sequence, and implement its best ideas.
The same pressure is visible in content. Search Engine Land’s article on firsthand experience describes a web crowded with interchangeable advice and says AI has made generic production still easier. Its proposed differentiators are concrete examples, test results, candid opinions, client outcomes, and lessons from failed work. That is the content equivalent of the career shift: readily generated output loses relative value, while evidence rooted in actual decisions and consequences gains it.
Together, these accounts suggest a more demanding definition of SEO expertise. Knowledge remains the foundation, but the differentiating layer is the ability to challenge an answer, identify the assumptions behind it, and convert a recommendation into an outcome. AI can accelerate analysis and drafting without deciding which organizational constraint, commercial objective, or uncertain premise matters most.
Prioritization should operate as a portfolio discipline
A backlog cannot be prioritized credibly when every item is labeled urgent. Search Engine Land’s forecasting framework contrasts a minor schema issue with a title-tag problem affecting thousands of pages to show why technical seriousness and business impact are not necessarily the same. It recommends estimating likely traffic impact before work begins, while acknowledging that traffic is not the only objective when brand visibility or user experience is at stake.
Estimate the opportunity that is actually exposed
The first distinction is scope: a sitewide change, a template-level repair, and a single-page optimization create different opportunity sizes. The forecasting source recommends filtering affected URLs in Google Search Console and examining current clicks, impressions, ranking positions, and the surrounding search-result features. It identifies pages ranking from positions 8 through 15 as potential near wins, but also warns that an improvement can produce very different click gains depending on the result layout and the presence of AI experiences.
Replace a precise promise with explicit scenarios
Potential lift can then be grounded in outcomes from similar past changes, competitor and search-result analysis, and assumptions appropriate to AI-influenced click behavior. Rather than presenting one apparently certain number, the source recommends conservative, expected, and aggressive scenarios. That approach makes uncertainty visible: partial implementation and competitive responses can be represented separately from stronger execution and faster indexing.
Compare expected value with delivery cost
The forecast becomes useful only when it changes the roadmap. Comparing the expected effect with effort through a framework such as RICE can expose large, scalable opportunities that would otherwise lose attention to smaller and more appealing technical tasks. For initiatives whose primary outcome is not traffic, the same discipline still applies: define the intended result, select an observable measure, state the uncertainty, and compare the opportunity cost with competing work.
Evidence must cover both execution and search context
The sources point to two complementary forms of evidence. Internal evidence comes from implementation: previous fixes, controlled tests, client work, failures, and observed results. External evidence comes from the environment in which a brand or page must compete: result layouts, competitors, third-party coverage, and the associations AI systems appear to use.
This distinction helps explain why AI fluency alone is insufficient. The career article recommends evaluating how an SEO handled a disagreement, responded to a failed test, or caught an AI mistake. Those questions test whether the candidate can reason under uncertainty and continue after an initial plan breaks down. The content article makes a parallel case for publishing details that could come only from real practice rather than another summary of established advice.
A useful workflow therefore treats AI output as a hypothesis generator. An audit suggestion, content angle, or visibility diagnosis should be checked against the site’s data, the actual search environment, and relevant operational experience. When evidence is incomplete, the appropriate response is a bounded test or a qualified forecast, not greater confidence in the wording of the recommendation.
AI visibility requires separating recognition from recommendation
Prioritization becomes more complicated when the objective extends beyond conventional rankings and clicks. A Search Engine Land study conducted through Friction AI examined 12 activewear brands across more than 14,000 API tests. The researchers reported that strong Knowledge Graph recognition did not consistently translate into recommendations for related prompts, describing the difference as a framing gap.
The study’s co-mention analysis suggests why those outcomes may diverge. It found that brands could become associated with particular competitors and category leaders through the contexts in which they appeared together. Nike, for example, was reported to appear prominently in recommendation prompts despite sharing a broad company description with other footwear brands; the researchers connected that result to its recurring association with category leaders.
This was an exploratory study in the UK athleisure sector, and its authors said additional categories and regions would need examination. It should not be treated as a universal ranking formula. It does, however, identify an important planning distinction: improving the clarity of a brand’s own pages may support recognition, while earning relevant third-party coverage and category associations may support recommendation. Those are related objectives, but they call for different actions and should not be collapsed into a single visibility score.
The distinction also changes content strategy. Firsthand case studies and specific results can make owned content more credible, as the experience-focused source argues. Yet the co-mention research indicates that a brand’s self-description is only part of its AI-visible context. A mature plan must consider both what the brand demonstrates directly and how independent sources position it within the market.
Key takeaways
Judge SEO work by the quality of decisions and delivered outcomes, not the number of recommendations produced.
Estimate scope, exposed traffic, potential lift, uncertainty, and implementation effort before assigning roadmap priority.
Use AI to accelerate hypotheses and production, then validate its output against data, search context, and firsthand experience.
Preserve real examples, failed tests, observed results, and informed opinions because generic information is increasingly easy to reproduce.
Measure brand recognition and AI recommendation separately; owned-page clarity and third-party category associations may require different investments.
As AI lowers the cost of producing SEO artifacts, teams will need clearer decision records, stronger testing habits, and measures tied to the outcome each initiative is meant to change. The durable advantage will belong to practitioners who can make uncertainty legible and direct limited resources toward work that survives contact with real users, search systems, and organizational constraints.
You have an AI answer that sounds precise, uses the right vocabulary, and gives you a clear next step. The problem is that you cannot tell whether it is correct without already knowing the subject.
You do not need to reject AI or fact-check every sentence with equal intensity. You need a verification process that becomes stricter as the cost of being wrong rises.
Confidence is not evidence
An AI hallucination is a plausible response that is incorrect, unsupported, or assembled from assumptions the model has not made clear. It can include real terminology, a logical sequence, and a confident conclusion. Those qualities make the answer readable. They do not make it reliable.
This distinction matters when you are working outside your expertise. A weak answer does not always look weak. You may notice an obvious factual error in your own field, yet accept the same style of answer about a vehicle repair, a legal requirement, analytics configuration, or unfamiliar platform.
Consequences can escalate quickly. Confident AI recommendations have included faulty technical SEO direction and a premature vehicle diagnosis. In the SEO case, misleading language about penalties could also have changed how leadership viewed a necessary migration. The risk was not limited to implementation. It extended to budgets, trust, and internal decision-making.
Treat polished language as a presentation layer. Evidence must still come from observable behavior, authoritative documentation, original data, or a qualified person who accepts responsibility for the judgment.
Match verification effort to the cost of being wrong
Start by asking what happens if you follow the answer and it fails. This is more useful than asking whether the output merely feels accurate.
Low consequence: The output is easy to reverse and affects no customer, budget, production system, or factual claim. Use it as a working draft and review it normally.
Meaningful consequence: The answer could affect rankings, reporting, client communication, or a public page. Verify its important claims against direct evidence before publishing or deploying.
High consequence: The recommendation could trigger substantial spending, irreversible changes, legal or security exposure, health decisions, or damage across a live site. Stop and obtain qualified human approval.
Raise the verification level when the answer contains absolute language such as “always,” “must,” or “penalty,” especially when no condition or evidence accompanies it. Also slow down when the AI reaches a diagnosis before gathering enough context, changes its conclusion after receiving basic facts, or recommends an action you cannot safely undo.
Your own familiarity is part of the risk calculation. If you cannot explain why the recommendation should work, you are not in a good position to approve it alone. That is a signal to involve an expert, not a reason to ask the model for an even more confident version.
Use a verification workflow that separates claims from decisions
Do not verify a long AI response as one object. Break it into the claims you can test and the decisions that require judgment.
State the proposed action. Reduce the output to a plain sentence: “Change this canonical,” “replace this component,” or “publish this claim.” If the action remains vague, it is not ready for approval.
Extract the supporting claims. List the facts that must be true for the action to make sense. Separate observed facts from assumptions and predictions.
Ask what is missing. Identify the data, configuration, version, environment, symptoms, or business constraint the AI did not have. Missing context is often where a persuasive answer becomes brittle.
Inspect direct evidence. Open any cited material, check the actual system, and compare the recommendation with real output. A citation generated by AI is only a lead until you confirm that it exists and supports the claim.
Test reversibly. Use a draft, preview, staging environment, isolated sample, or limited rollout where one is available. Record the expected result before testing so that you do not reinterpret failure as success.
Assign approval. Name the person who can judge the evidence and accept the consequence. High-risk work should not be approved by the person who merely generated or copied the AI response.
For technical SEO, this means checking the site rather than debating terminology with the model. Inspect the rendered canonical, the destination URL, parameter behavior, templates, and the affected page set. Test the proposed change in a controlled environment when possible. A model can help you form hypotheses and test cases, but the implementation decision should follow what the site actually does.
For content and structured data, verify each factual statement and each property that describes a real entity. Do not let AI invent credentials, reviews, product details, authorship, or organizational relationships. The final markup should agree with the visible page and the underlying business record.
Give experts a verification packet, not a chat transcript
Expert review works best when the reviewer can see the decision, evidence, and uncertainty without reconstructing your entire AI conversation. Prepare a compact verification packet with:
the exact action you are considering;
the material claims on which it depends;
the AI output, clearly labeled as unverified;
the documentation, screenshots, logs, crawl results, or other direct evidence you checked;
the assumptions and unanswered questions;
the likely consequence if the recommendation is wrong; and
the specific approval or correction you need from the reviewer.
Ask the expert to challenge the reasoning, not merely confirm the conclusion. Useful prompts include: “Which assumption is weakest?”, “What evidence would disprove this?”, and “What should we inspect before changing production?” These questions make disagreement visible while there is still time to act on it.
Keep the resulting decision record. Note what was approved, by whom, from which evidence, and under what conditions. If the recommendation later appears in a client deliverable, optimization playbook, or automated workflow, your team can trace why it was accepted instead of treating repeated AI language as established fact.
Key takeaways
Fluent, specific language does not prove that an AI answer is correct.
Verify more aggressively when an error could affect money, rankings, customers, production systems, or trust.
Separate testable claims from the judgment required to approve an action.
Use direct evidence and reversible tests before relying on another AI-generated explanation.
Bring in a qualified expert when you cannot evaluate the reasoning or safely absorb the failure.
Before acting on your next AI recommendation, write down the proposed action, the evidence it depends on, and the person qualified to approve it. If any of those fields is blank, the answer is still a hypothesis.