Tag: AI Search

  • How to Protect Search Visibility Through Google and AI Shifts

    How to Protect Search Visibility Through Google and AI Shifts

    Your organic traffic drops during a Google update, while AI answers mention competitors and sometimes describe your brand incorrectly. The tempting response is to rewrite everything. That usually destroys the baseline you need to work out what actually changed.

    You need a diagnosis before you need a recovery campaign. The practical approach is to separate short-term ranking volatility from page-level relevance problems, entity confusion, and the slower process of becoming a dependable source for AI systems.

    Treat an update rollout as an observation window, not a verdict

    Core updates change broad ranking systems rather than applying a simple penalty to one page. The December 2025 release was Google’s third core update of that year, and its rollout could take up to three weeks. March and June core updates and an August spam update had already made repeated change an operating condition, not an exceptional event.

    If rankings move while a rollout is still active, you don’t yet have a settled result. That doesn’t mean you should ignore the data. It means you should preserve it and avoid attributing every movement to a content defect.

    1. Mark the timeline. Record the announced start of the update, the pages that changed, and the first date each change became visible. Keep unrelated site releases, migrations, and content edits on the same timeline.
    2. Rule out faults that cannot wait. Check whether affected URLs still load, remain indexable, return the intended status, and are accessible to crawlers. An accidental noindex directive, broken canonical, blocked resource, or server failure should be fixed immediately.
    3. Segment the movement. Break the loss down by page type, topic, query intent, country, device, and branded versus non-branded demand. A sitewide average can hide one damaged template or one declining topic cluster.
    4. Save the pre-edit baseline. Export page and query data before changing titles, copy, internal links, or templates. Without that record, you cannot distinguish recovery from normal volatility.
    5. Delay broad conclusions until the rollout settles. Continue publishing and fixing verified defects, but postpone mass rewrites, deletions, and structural changes made solely in reaction to daily ranking movement.

    Read the metrics as clues, not diagnoses. Falling impressions and positions across a related group of pages point toward a relevance or competitiveness problem. Stable positions with fewer clicks call for a closer look at result presentation, query demand, and search features. One template disappearing while the rest of the site holds steady calls for a technical check before a content review.

    Google’s standing position is that a core-update decline does not automatically mean a page is defective and that there is no single recovery action. Improvements can be recognized between core updates, although larger changes may become visible after a later update. Set expectations accordingly: make changes because the diagnosis supports them, not because an update created pressure to look busy.

    Diagnose search, entity, and AI visibility separately
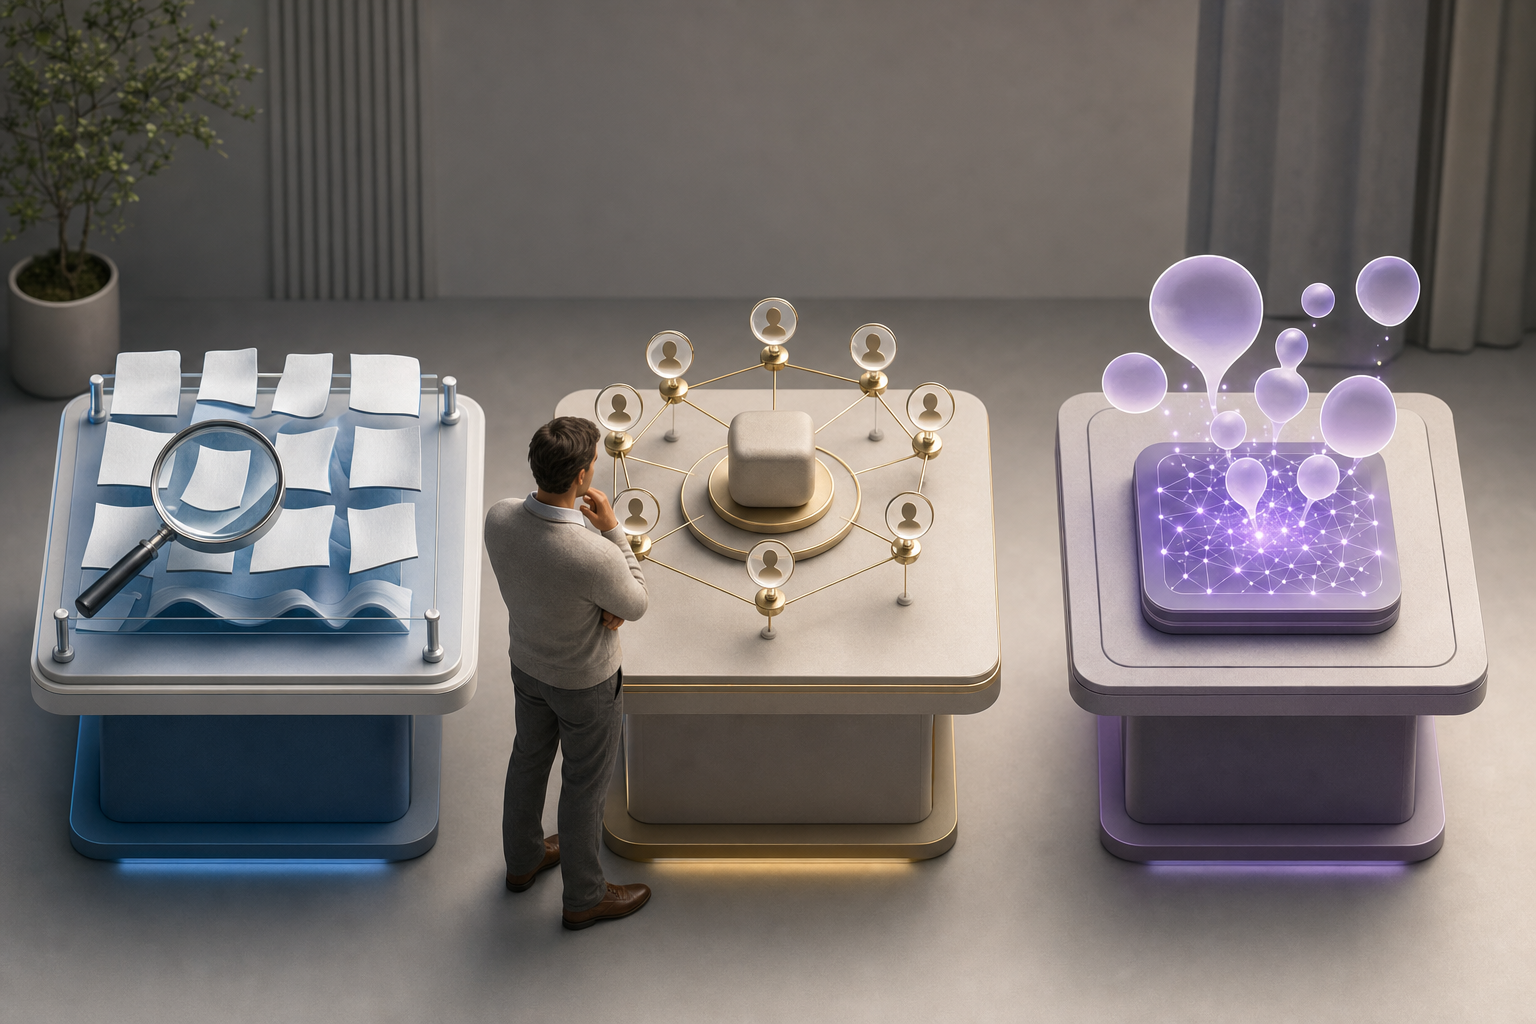
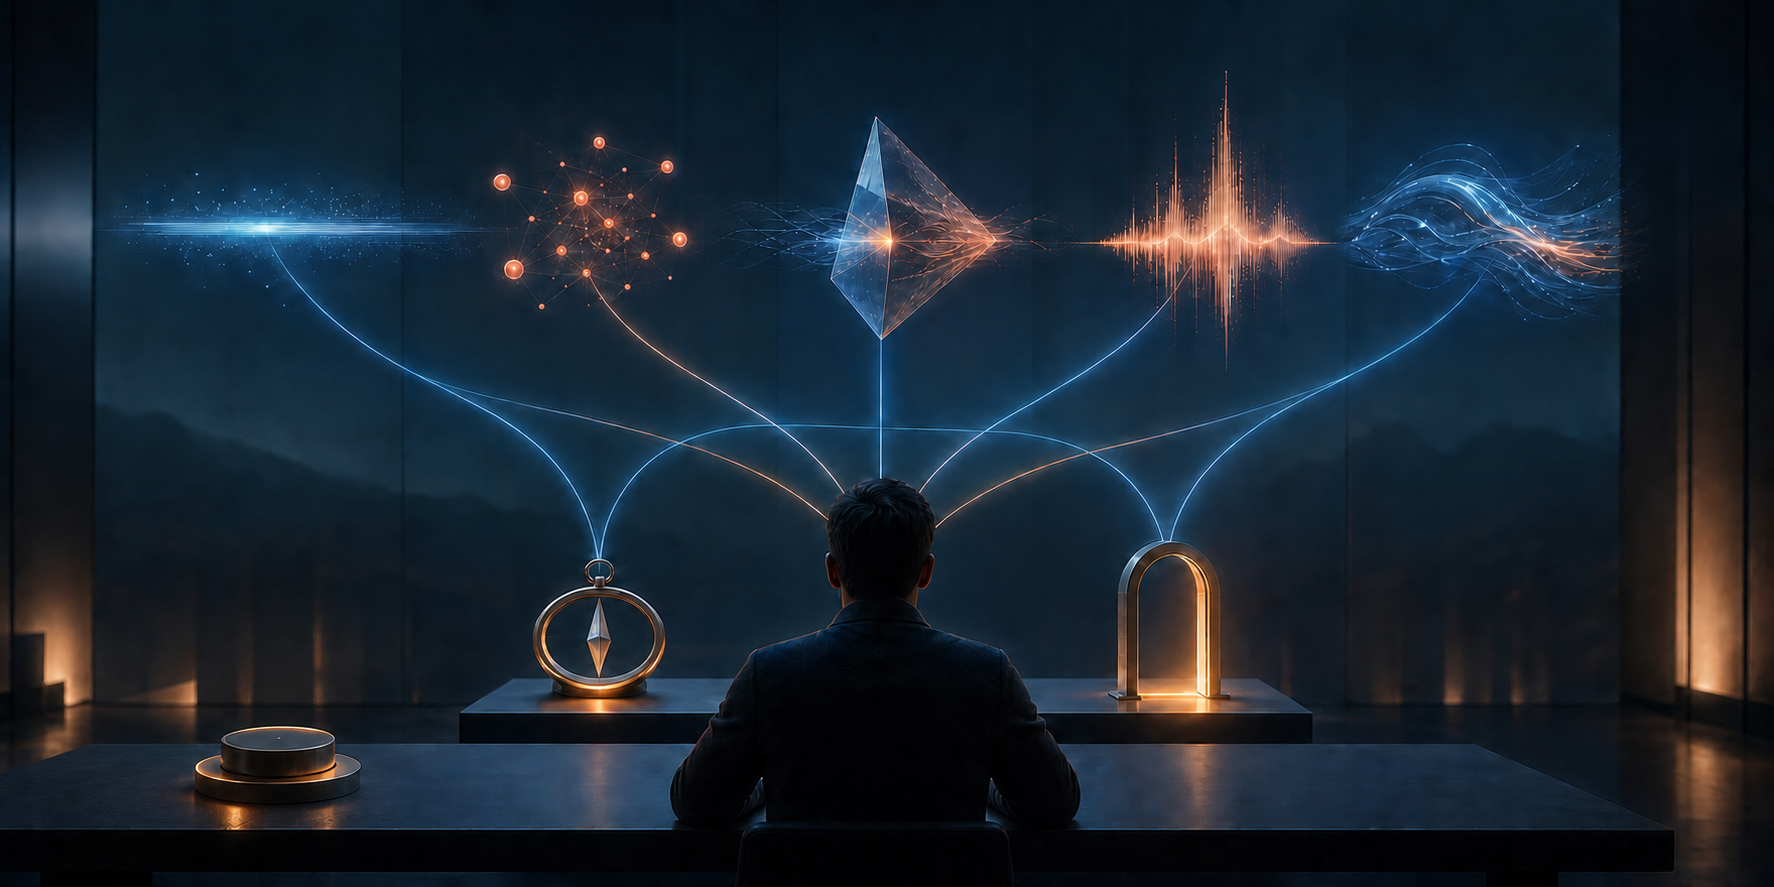
    Three separate workstations display page tiles, connected identity nodes, and abstract AI response shapes while an investigator compares them.

    Search visibility now depends on three connected systems that operate at different speeds. Traditional search engines retrieve current web information. Knowledge graphs organize facts about entities and their relationships. Large language models synthesize information into conversational answers. A brand can be healthy in one layer and weak in another.

    The operating horizons are different as well: search improvements may affect near-term discovery, knowledge-graph education can take months, and durable representation in LLM knowledge can take years. Treating all three as one SEO score produces bad priorities.

    Visibility layerQuestion to answerEvidence to inspectBest next move
    Traditional searchCan the right page be crawled, understood, and ranked for the current query?Indexing, impressions, positions, clicks, affected queries, page groups, and competing resultsRepair technical access, intent alignment, content usefulness, or internal discovery
    Entity and knowledge graphCan systems identify the organization, people, products, and relationships correctly?Conflicting names, descriptions, ownership details, profile facts, structured data, and third-party corroborationEstablish one canonical fact set and make every machine-readable claim agree with visible content
    LLM and AI answersCan an assistant accurately include, explain, cite, or recommend the brand for the relevant task?Repeatable prompt tests, factual accuracy, brand inclusion, cited pages, and consistency across answer variantsStrengthen the underlying entity record and publish information that can be extracted and supported

    This separation prevents a common category error. If Google still ranks your pages but an AI assistant misstates your company, rewriting a high-performing page around more keywords is unlikely to solve the identity problem. If your brand facts are consistent but a commercial page loses non-branded rankings, an organization-wide entity project should not replace a page-level relevance audit.

    AI answers also need their own measurement discipline. Save the exact prompt, model, date, answer, cited URLs, and whether your brand appeared accurately. One favorable answer is an observation, not a trend. Reuse a fixed set of prompts so that changes in wording do not masquerade as changes in visibility.

    Repair relevance without chasing the update

    Once a decline remains visible after the rollout and technical checks are clean, work at the level where the evidence concentrates. If one topic cluster lost visibility, audit that cluster. If one page type fell, inspect its template and purpose. A domain-wide rewrite is justified only by domain-wide evidence.

    1. Define the searcher’s job. Write down what the affected query asks the reader to understand, decide, compare, or complete. Then check whether the page performs that job without forcing the reader through a long preamble.
    2. Compare the promise with the delivery. The title and search snippet create an expectation. The opening, headings, and main answer must satisfy the same intent. A compelling title cannot rescue a page that answers a neighboring question.
    3. Locate the information gap. Check whether the page gives a direct answer, explains the mechanism behind it, covers the important limitations, and supplies enough evidence for the reader to verify consequential claims.
    4. Make accountability visible. Show who created or reviewed the content, why that person or organization is qualified, when meaningful changes were made, and where factual claims come from. Treat authority, notability, and transparency as audit questions, not as invented ranking factors.
    5. Resolve internal competition. When several pages perform the same job, decide which one should be canonical. Differentiate pages that serve distinct intents. Consolidate genuine duplicates carefully, and redirect a retired URL to the appropriate surviving resource rather than simply deleting accumulated value.
    6. Reduce extraction friction. Use descriptive headings, explicit names, concise definitions, coherent internal links, and structured data that matches what a person can see. Machines should not have to infer whether two slightly different names refer to the same entity.
    7. Update substance, not timestamps. Correct outdated facts, improve weak explanations, and remove unsupported claims. Changing a date without materially improving the page gives readers and machines no new reason to trust it.

    People-first content is not a license to ignore retrieval. A useful page still needs to be accessible, clearly scoped, internally connected, and written in language that makes its main claims easy to identify. Technical clarity and human usefulness reinforce each other.

    Avoid using word count as a repair target. More text can make the answer harder to retrieve and harder to trust. Add material only when it closes a real information gap: a missing condition, an unexplained decision, an absent method, or evidence the reader needs before acting.

    Build a brand record that AI systems can reuse
    A faceted ceramic object is documented and repeated consistently across blank archival materials and a glowing network of connected nodes.

    Page optimization helps a system retrieve an answer. Entity optimization helps it understand who supplied that answer. You need both. The goal is to create a consistent, corroborated record of the brand rather than repeat a slogan across hundreds of pages.

    1. Create a canonical fact inventory. Record the preferred organization name, concise description, official domain, principal offerings, relevant people, locations, and important relationships. Mark which page is authoritative for each fact.
    2. Publish stable identity pages. Your organization, about, author, product, and contact pages should state their purpose plainly. Keep durable facts separate from campaign language that changes frequently.
    3. Align visible and structured claims. JSON-LD should describe the content on the page, not introduce a second version of reality. Conflicting names, URLs, roles, or descriptions increase ambiguity. Structured data can clarify a trustworthy fact; it cannot manufacture authority for an unsupported one.
    4. Connect entities deliberately. Make the relationships among the organization, authors, products, services, and subject areas explicit in copy, navigation, internal links, and structured data. Do not rely on proximity or branding alone to communicate the relationship.
    5. Seek relevant corroboration. Accurate independent mentions, profiles, citations, and references help systems verify that the brand’s self-description is not the only available account. Correct contradictions at their origin when possible instead of adding more duplicate claims to your own site.
    6. Publish citation-ready knowledge. Give important topics stable URLs, direct definitions, clear methods, named ownership, and inspectable evidence. If a claim is an opinion or company position, label it as such. If it is factual, make the support easy to follow.
    7. Audit machine representation. Test how search results and AI assistants identify the brand, explain its offerings, and associate it with relevant topics. Log factual errors separately from simple absence: correcting a wrong identity requires different work from earning consideration for a new topic.

    This is algorithmic education in practical terms: consistently presenting connected facts that search systems can discover, reconcile, and reuse. It is not a prompt trick, and it does not guarantee inclusion in a model’s training data. Training inclusion is a long-term outcome that you cannot force or confirm from a single AI response.

    Your intermediate measures should therefore stay observable. Track whether canonical facts agree across owned pages, whether relevant third parties corroborate them, whether search engines retrieve the intended pages, whether AI answers become more accurate, and whether repeated prompt tests show more stable inclusion. Those indicators won’t prove that a model has learned the brand permanently, but they will reveal whether the evidence environment is improving.

    Key takeaways: run one visibility program at three speeds

    • During a core-update rollout, preserve your baseline, fix verified technical faults, and avoid broad edits based on unsettled movement.
    • Diagnose traditional rankings, entity understanding, and AI-answer visibility as separate layers with different evidence and timelines.
    • Apply content repairs to the page type or topic cluster where the loss is concentrated instead of rewriting the whole site.
    • Use structured data to clarify visible, supported facts. It is not a substitute for consistent identity, useful content, or outside corroboration.
    • Measure AI visibility with a fixed prompt set and a log of models, dates, answers, citations, and factual errors.
    • Expect page-level search work to operate faster than knowledge-graph development, while durable LLM representation remains a long-term objective.

    Turn this into a routine. During a confirmed rollout, save a daily snapshot without making a daily strategic decision. After the result settles, review affected page groups weekly while improvements are in progress. Check canonical brand facts monthly, and run the same AI prompt set on a regular schedule that your team can maintain.

    Start with one important topic cluster. Export its current search baseline, identify whether the failure sits in retrieval, relevance, entity understanding, or AI representation, and make the smallest change that addresses that diagnosis. That gives you a result you can evaluate and a method you can repeat when the next shift arrives.
    References

  • How to Track Brand Visibility Across AI Search Platforms

    How to Track Brand Visibility Across AI Search Platforms

    You ask an AI assistant for the best options in your category. Your brand appears. You change a few words, try another platform, or add a location, and it disappears. That is a useful spot check, but it is not visibility tracking.

    A defensible tracking program uses a fixed set of prompts, consistent labels, and saved answer evidence. It tells you where your brand is mentioned, whether it is recommended, which sources support the answer, which competitors occupy the same space, and whether the description is accurate. More importantly, it tells you what to fix next.

    Stop treating AI visibility like a single keyword rank

    A traditional rank tracker asks where a URL appears for a keyword. AI search often returns a synthesized answer instead of a stable list of links, and those answers may mention, recommend, or cite only a small selection of brands and sources. A position-based metric cannot describe all of those outcomes.

    Use a prompt-level definition instead: AI search visibility is your brand’s observable presence and representation across a controlled set of prompts, platforms, markets, and collection runs. The basic unit is not a keyword position. It is a platform-prompt-market observation with a saved response behind it.

    Each observation should distinguish several states:

    • Mention: The answer names your brand, product, service, or another recognized brand entity.
    • Recommendation: The answer explicitly presents the brand as a suitable choice, shortlist candidate, or conditional fit.
    • Citation: The answer links to or identifies a source associated with the brand. Record this only when the interface exposes citations.
    • Representation: The answer describes the brand favorably, neutrally, unfavorably, or with a meaningful qualification.
    • Accuracy: The claims about the brand are correct, incorrect, ambiguous, or too incomplete to evaluate.

    These states are not interchangeable. A mention can be negative. A citation can support a category fact without recommending the company that published it. A recommendation can rely on a third-party source rather than the brand’s own site. If your dashboard collapses all of them into a single visibility score, you will not know whether you have a discovery problem, an evidence problem, a positioning problem, or a reputation problem.

    That is also why a successful ChatGPT result cannot stand in for the entire market. Visibility can differ across ChatGPT, Claude, Gemini, and Perplexity. Report each surface separately before producing any aggregate view.

    Build a prompt set around real customer decisions

    Your prompt set determines what your visibility score means. If every prompt includes your brand name, the tracker measures how the systems describe a known entity. It does not measure whether the brand gets discovered when a buyer has not named it.

    Build separate prompt groups for the decisions you need to observe:

    • Category discovery: Which [category] options fit [audience or use case]?
    • Problem-led discovery: What is a good way to solve [specific problem] under [constraint]?
    • Comparison: How do [brand or product] and its alternatives differ for [use case]?
    • Requirement matching: Which options support [required capability, integration, market, or workflow]?
    • Branded validation: Is [brand] appropriate for [audience], and what are its limitations?
    • Factual verification: Does [brand] provide [specific feature, service, policy, or availability]?
    • Post-purchase help: How do users complete [task] with [brand or product]?

    Unbranded prompts measure discovery and category association. Branded prompts measure understanding, accuracy, and reputation. Keep their results separate. Otherwise, strong performance on easy branded questions can conceal absence from the category questions that introduce new buyers to a company.

    Use neutral wording. A prompt such as Why is [brand] the best choice? presupposes the result and cannot tell you whether the brand would appear naturally. Ask which options fit a defined need, then let the answer reveal the competitive set.

    Store enough metadata to reproduce each observation:

    • A stable prompt ID and the exact prompt text.
    • The intent group and business question behind the prompt.
    • Whether the brand was named in the prompt.
    • The platform and any model or search-surface label displayed to the user.
    • The market, location, and language used for the run when they matter.
    • The audience, product line, or use case being tested.
    • The prompt version and the date that version became active.

    Location deserves its own field rather than a note buried in the prompt. Tracking by location can expose market-specific gaps that disappear inside a global average. This is especially relevant when availability, terminology, regulations, service areas, or competitors differ between markets.

    Freeze the wording once a prompt enters the benchmark set. If you discover a better version, create a new version and establish a new baseline. Quietly rewriting prompts between runs makes a reporting change look like a visibility change.

    Record answer evidence, not just a visibility score

    Abstract AI response cards are organized with colored evidence markers, source tiles, and saved snapshots on a dark tabletop.

    Define every metric before collecting results. In particular, define an eligible answer as a completed response to an in-scope prompt. Log platform errors, refusals, and unavailable responses separately. Treating a failed run as a brand omission would contaminate the denominator.

    MetricOperational calculationWhat it helps you diagnoseMain caution
    Mention rateEligible answers naming the brand divided by all eligible answers in the segmentBasic discovery and entity recognitionA mention is not necessarily positive or prominent
    Recommendation rateEligible answers explicitly recommending or shortlisting the brand divided by all eligible answers in the segmentWhether the brand is presented as a viable choiceSeparate unconditional recommendations from recommendations limited by a caveat
    Citation rateEligible answers citing a brand-associated source divided by answers for which citations are exposedWhether the brand’s evidence is being selected as supportNot all interfaces expose citations; mark those cases unavailable rather than uncited
    AI share of voiceBrand mentions divided by mentions of the defined competitor set within the same prompt segmentRelative presence in competitive answersThe result depends on the prompt mix and competitor definition
    RepresentationDistribution of favorable, neutral, unfavorable, and qualified descriptionsPositioning, reputation, and recurring objectionsSave the exact claim and reason for the label; sentiment alone is too blunt
    Factual accuracyDistribution of accurate, inaccurate, ambiguous, and unevaluable brand claimsEntity consistency and misinformation riskReviewers need an approved factual reference for comparison
    Platform coveragePlatforms with an observed mention divided by platforms tested for the same prompt segmentCross-platform resilienceDo not let an aggregate hide a weak individual platform

    Citation frequency, brand visibility, AI share of voice, sentiment, and cross-platform coverage belong in the same scorecard because each answers a different question. If your tool supplies a composite visibility score, document its formula and retain the component metrics. A rising aggregate can otherwise conceal worsening accuracy or a loss of recommendations on commercially important prompts.

    Save the evidence needed to audit a result

    A row with only a yes-or-no mention field is not enough. Save the exact response, collection time, prompt version, platform label, market, citation URLs, cited domains, competitor mentions, recommendation wording, representation label, factual issues, and reviewer notes. Where the platform permits it, retain a response link or screenshot as well.

    Classify cited domains as owned, independent third-party, competitor-owned, or another relevant type. That distinction matters. An answer citing your documentation points to a different opportunity than an answer recommending your brand while relying entirely on an external review or directory.

    Human review remains important for conditional language. Suitable for small teams that do not need [capability] is not equivalent to a general endorsement. A tracker that counts both as positive recommendations may produce a clean chart and a misleading decision.

    Use a collection cadence you can reproduce

    Begin with a baseline run across the full prompt-platform-market matrix. Repeat the same matrix at a regular interval, and capture additional before-and-after runs around material content, product, or entity changes. Keep prompt versions and segments consistent during the comparison.

    Do not interpret one generated answer as a trend. Look for a pattern that repeats across related prompts, collection runs, platforms, or markets. A manual spreadsheet can establish this discipline while the prompt set is small. When the workload grows, evaluate GEO tracking tools on prompt control, raw-response retention, citation capture, platform and location segmentation, competitor grouping, historical comparisons, exports, and transparent metric definitions.

    Turn recurring patterns into specific GEO work

    A strategist turns repeated patterns from abstract AI answer chambers into website, source, location, and fact-checking work.

    Start with the pattern in the evidence, not with a general instruction to publish more. Different gaps call for different work.

    Your brand is absent from unbranded discovery prompts

    First, check whether the absence repeats across related prompts and whether competitors appear consistently. Then inspect the claims and sources used in those answers. You are looking for a missing association: a category, use case, audience, capability, problem, or market that competitors explain more clearly.

    Create or strengthen a focused page that answers the missing intent directly. State who the offering is for, which problem it solves, what it supports, where it applies, and what its meaningful limits are. Link that page to the relevant product and organization entities. Use appropriate structured data to reinforce names and relationships already visible in the content, but do not treat markup as a substitute for a clear answer.

    This is the practical meaning of expanding your semantic footprint, fact density, and entity authority: cover the relationships buyers ask about, make important claims explicit and supportable, and keep the identity of the organization and its offerings consistent.

    Your brand is mentioned but rarely cited or recommended

    A mention without a citation can indicate that the entity is recognized while its owned evidence is not being selected. Review which domains the answers do cite. If they consistently provide concise definitions, comparison criteria, specifications, or market facts that your pages obscure, improve the relevant evidence on your site and remove contradictions between pages.

    A citation without a recommendation is a different gap. Your content may be useful as evidence while the offering’s fit remains unclear. Strengthen the pages that explain the intended audience, requirements, tradeoffs, integrations, constraints, and differentiators. Do not manufacture praise. Give the system enough accurate context to determine when the brand is and is not a sensible option.

    The answer gets your brand wrong

    Record the exact incorrect claim rather than assigning only a negative sentiment label. Then identify whether your own site contains conflicting names, outdated facts, unclear availability, or ambiguous product relationships. Establish a canonical location for each important fact, correct internal contradictions, and align visible copy with structured entity information.

    If the claim comes from external coverage, the work may involve reputation management, clearer public documentation, or credible third-party corroboration. Do not try to suppress a valid limitation. Explain the current position accurately and address the underlying issue where possible.

    One platform or market underperforms

    Do not rewrite the entire site because one surface produced a weak answer. Confirm that the same prompt, language, location, and evaluation rules were used. Compare the source types and competitor claims selected by the stronger and weaker platforms. A platform-specific gap may point to missing evidence in the sources that surface retrieves, while a market-specific gap may point to unclear local availability, terminology, or entity information.

    Prioritize changes using business impact, repeatability, evidence, and control. A recurring absence on important unbranded prompts is more actionable than an isolated wording difference. A verified factual error on a decision-stage prompt deserves attention before a minor shift in a blended score. A gap tied to a page you control can usually be addressed more directly than a change in an opaque platform behavior.

    After making a change, measure both layers. The first layer is the AI response: mentions, citations, recommendations, representation, and accuracy. The second is the business outcome available in your analytics, such as relevant referral activity, branded interest, or qualified conversions. An AI mention is evidence of visibility, not proof of revenue.

    Key takeaways

    • Track platform-prompt-market observations, not a supposed universal AI rank.
    • Separate unbranded discovery prompts from branded reputation and accuracy prompts.
    • Measure mentions, recommendations, citations, share of voice, representation, accuracy, and platform coverage independently.
    • Preserve exact prompts and raw responses so every chart can be audited.
    • Diagnose repeated patterns before choosing a content, entity, technical, or reputation fix.
    • Keep AI visibility metrics connected to business outcomes without treating a mention as a conversion.

    Your next move is simple: open a tracking sheet, choose a small but balanced set of branded and unbranded prompts, run the same set across the platforms and markets that matter, and label each answer with the definitions above. Select the clearest recurring gap, make the narrowest relevant improvement, and preserve the prompt set for the next run. Once you can explain why a metric moved and what evidence changed, you are tracking visibility rather than collecting screenshots.

    References

  • Commercial Intent in AI Chats: Where Brands Should Focus

    Commercial Intent in AI Chats: Where Brands Should Focus

    If you are budgeting for AI visibility on the assumption that every product mention is close to a sale, stop and reclassify the opportunity. Commercial demand exists in AI chats, but much of it appears while people are framing a problem, weighing approaches, or trying to succeed with something they already bought.

    Your job is to recognize those moments without forcing a sales funnel onto every conversation. That changes which pages you prioritize, how you structure an answer, where you place the next action, and what you count as success.

    Commercial intent is a minority, but it is not one moment

    Across a corpus covering 4.4 billion characters, 613 million words, and 3.9 million conversation turns, people used AI heavily for tasks such as planning, brainstorming, analysis, learning, transformation, and creation. Those activities may happen at work or mention a product, but that does not automatically make them commercial.

    Within a categorized sample of 24,259 sessions spanning 42 intent categories, 64.6% did not fit a purchase funnel, while 35.4% showed some form of commercial intent. The useful correction is not that AI chats have no commercial value. It is that commercial value is distributed across several different jobs, most of which are not an immediate purchase request.

    Awareness accounted for 10% of the categorized sessions and consideration for 8.5%. Together, those early stages represented 18.5% of all sessions and the largest block of commercial activity. Discovery accounted for 4.1%, decision support for 2.8%, transactional support for 4.8%, and post-purchase needs for 5.1%.

    That distinction matters when you set priorities. If your AI strategy watches only prompts containing words such as buy, price, best, or demo, it will miss people who are still deciding what kind of solution they need. It will also miss existing customers asking how to configure, use, integrate, or repair what they own.

    Do not treat the percentages as a universal forecast for every market. They describe the analyzed corpus, not the exact intent mix for your category. Use them to challenge an overly transactional strategy, then classify the questions that appear in your own sales, support, search, and customer research.

    Classify the user’s job before choosing the content

    Four connected rooms show a user investigating a problem, exploring approaches, comparing products, and learning to use an owned device.

    A noun is not an intent signal. A user can mention your category while asking for writing help, summarization, technical instruction, product evaluation, or troubleshooting. Classify the job being done before deciding whether the conversation belongs in a commercial funnel.

    Intent classObserved shareWhat the user is trying to doWhat your content should accomplish
    Outside the purchase funnel64.6%Create, learn, analyze, plan, transform, or converse without making a product choiceComplete the requested task honestly; introduce a commercial path only when it is genuinely relevant
    Awareness10%Name a problem, understand its causes, or learn what kinds of solutions existDefine the problem, explain when it matters, and make the available approaches understandable
    Consideration8.5%Compare approaches, requirements, or tradeoffsProvide selection criteria, limitations, alternatives, and use-case fit
    Discovery4.1%Find products, providers, or options in a categoryHelp the user build a defensible shortlist without hiding eligibility criteria or constraints
    Decision support2.8%Choose among known optionsSupply verifiable details about fit, evidence, implementation, cost factors, and risk
    Transactional support4.8%Complete or manage a commercial actionRemove uncertainty about requirements, process, timing, and what happens next
    Post-purchase5.1%Set up, use, improve, or troubleshoot something already acquiredHelp the customer reach the intended result and recover from predictable failures

    The percentages in the table are rounded shares of the categorized sample. The user-job descriptions and content responses are practical applications of those intent classes.

    Context is decisive. Create a launch brief for this product is primarily a creation task. Which type of platform should our distributed team use to manage a launch? is consideration. Why did this feature stop working after setup? is post-purchase. The same category terms can appear in all three prompts, but only the latter two have an explicit relationship to choosing or owning a solution.

    Use a strict operational rule: label a conversation commercial only when the user is making an economic choice, evaluating a solution, completing a transaction, or seeking help with something already acquired. Do not inflate your opportunity estimate by treating every workplace task as latent demand.

    Build for exploration and ownership, not just selection

    Early-stage content should make the decision legible

    Awareness and consideration together accounted for 18.5% of all categorized sessions. This is where product-led content often arrives too early. A user who is still defining the problem does not need an unsupported claim that your product is the answer. They need enough structure to decide whether the category is relevant at all.

    A useful awareness or consideration page should do the following:

    • Answer the initiating question immediately. State the practical answer before company history, positioning, or a lead form.
    • Define the decision context. Identify who the advice applies to, the conditions that change it, and any prerequisites the user may not have mentioned.
    • Separate symptoms from causes. Help the user avoid buying a solution for the wrong problem.
    • Expose the criteria that change the choice. Explain requirements, constraints, tradeoffs, and cases in which a simpler approach is sufficient.
    • Include credible alternatives. A comparison is more useful when it covers different approaches, including doing nothing yet, rather than presenting a disguised product pitch.
    • Provide a natural next question. Link the problem explanation to criteria, the criteria to options, and the options to decision evidence.

    The first answer carries unusual weight. The median conversation in the corpus had two turns and 430 words, and more than 80% of chats stayed below 1,000 words. Many users therefore do not spend a long sequence teaching the assistant their context. Your page should state its audience, assumptions, constraints, and core answer clearly enough to survive a short exchange.

    This is also where answer-engine optimization and conversion writing need to part company for a moment. The strongest opening is the one that resolves the question accurately. The commercial handoff comes after the user can see why a category, method, or product deserves consideration.

    Post-purchase content belongs in the commercial strategy

    Post-purchase needs represented 5.1% of sessions, exceeding discovery at 4.1% and decision support at 2.8%. That is a clear reason not to limit AI optimization to comparison and product pages.

    Support content should be designed around the customer’s actual failure state, not your internal feature taxonomy. A page titled with the symptom a user can observe is more useful than one that assumes they already know which component caused it.

    • Name the symptom, task, or desired outcome in the title and opening.
    • State the applicable product state, configuration, prerequisites, and access requirements.
    • Put the resolution steps in the order the user must perform them.
    • Describe the expected result so the user can verify that each meaningful step worked.
    • Branch explicitly when different causes require different fixes.
    • Say when self-service should stop and what information support will need.
    • Connect the fix to related setup or usage guidance without turning the page into a sales pitch.

    Where security and account privacy allow it, publish general help in accessible, indexable page content. Keep account-specific data and privileged actions behind authentication. An AI visibility goal never justifies exposing information that should remain private.

    Audit AI demand by prompt, page, and outcome

    A strategist sorts abstract chat bubbles through webpage cards toward discovery, comparison, purchase, and customer-success outcomes.

    You do not need to guess whether your opportunity is mostly awareness, decision support, or ownership. Build an intent inventory from questions people already ask, then connect each question to a page and a measurable next step.

    1. Collect real questions. Pull wording from site search, sales conversations, support records, community discussions, product research, and known AI referrals. Preserve the original phrasing instead of rewriting everything as a target keyword.
    2. Assign one primary job. Label each question as non-funnel, awareness, consideration, discovery, decision, transactional support, or post-purchase. Record a secondary intent only when it changes the answer the user needs.
    3. Map the best existing page. Choose the page that should answer the question, not merely the page currently ranking for adjacent terms. A product page is not automatically the right destination.
    4. Find coverage and answer gaps. Mark questions with no page, pages that bury the answer, unsupported claims, missing limitations, stale instructions, or no sensible continuation.
    5. Repair the visible content first. Make the answer, scope, evidence, and next step explicit. Structured data should reflect what a user can actually see on the page; it cannot manufacture commercial intent or compensate for an evasive answer.
    6. Run repeatable prompt checks. Log the exact prompt, assistant, exposed model or version, date, language or market, answer, brand representation, and cited URLs. A single response is an observation, not a stable visibility benchmark.
    7. Measure the outcome appropriate to the stage. Evaluate awareness content by accurate inclusion and progression to deeper evaluation. Evaluate decision content by qualified actions. Evaluate post-purchase content by successful task completion and reduced escalation where those signals are available.

    Keep visibility and progression as separate measures. Visibility asks whether the assistant represents the right answer, entity, or page. Progression asks whether the user then reaches a useful next step. Combining them into one score hides whether you have a retrieval problem, an answer-quality problem, or a conversion-path problem.

    Referral traffic is also incomplete by definition. You can observe a visit only when a user follows a link; an interaction that ends inside the chat produces no referral session. Use AI referral data as evidence of visits and downstream behavior, not as a complete count of AI influence.

    Finally, compare like with like. Do not blend troubleshooting prompts and product-selection prompts into one visibility rate, then judge both by purchases. Segment the prompt set by intent, page type, market, and user state. The resulting report will tell you which content is failing and what kind of repair it needs.

    Key takeaways

    • Commercial intent appeared in 35.4% of the categorized AI chat sessions, while 64.6% did not fit a purchase funnel.
    • Awareness and consideration formed the largest commercial block, so problem framing and selection criteria deserve more attention than purchase language alone.
    • Post-purchase demand exceeded both discovery and decision support, making setup and troubleshooting content part of AI commerce strategy.
    • Classify the user’s job, not the presence of a product or business keyword.
    • Because the median chat was short, make the first answer self-contained, scoped, and useful before asking the user to take a commercial action.
    • Measure visibility, answer accuracy, progression, and business outcomes separately for each intent stage.

    Start with your own prompt inventory. Find an early-stage cluster and a post-purchase cluster with weak coverage, repair the answers and their handoffs, and retest them consistently. You will see where AI visibility can support demand and where usefulness should stand on its own.

    References

  • AI Search Visibility: Measuring Citations and Referral Value

    AI Search Visibility: Measuring Citations and Referral Value

    Your analytics can show no traffic at the exact moment an AI answer starts putting your brand into a buyer’s consideration set. The inverse happens too: a citation looks impressive in a visibility tracker but sends no qualified visitor and supports no observable decision.

    The fix is not to choose between citations and traffic. You need a measurement chain that separates presence, citation, referral, and commercial value. Once those signals have distinct definitions, you can see where your visibility is working, where the journey stops, and what to improve next.

    A citation is not a click, and a mention is not a citation

    AI search visibility is often compressed into one score. That hides four different events:

    • A mention occurs when an answer names your brand, product, expert, or other identifiable entity.
    • A citation occurs when the answer attributes information to your domain or links to one of your URLs.
    • A referral occurs when a person follows an AI-generated link and reaches your site in a way you can observe.
    • An outcome occurs when that visitor completes a meaningful action, such as starting a trial, requesting a quote, buying a product, subscribing, or entering a qualified sales process.

    These events do not always happen in sequence. An answer can mention your brand without linking to it. It can cite a supporting page without naming the brand prominently. A person can encounter your brand in an answer, return later through branded search, and leave no direct AI referrer. A crawler or agent can also retrieve a page without producing a human visit.

    Choose the primary metric from the job you expect the content to do. For discovery content, measure whether the brand appears accurately in relevant answers. For evidence-led content, measure citation coverage and the contexts in which the page is used. For decision pages, measure qualified referrals and outcomes. Do not grade all three content types against the same click target.

    This distinction matters because generative systems can handle much of the early research journey before a person reaches a website. Traditional impressions, sessions, and click-through rates therefore describe only part of the path. Pricing, comparison, product, and validation pages may receive the eventual visit, while explanatory content did the earlier work of making the brand visible.

    Build a visibility scorecard with separate denominators

    Four unlabeled measurement stations use separate containers and markers to represent appearances, citations, referrals, and commercial value.

    A useful scorecard starts with a fixed set of prompts that represents the decisions your audience actually makes. Include non-branded prompts. A test set dominated by your company name will measure retrieval of a known entity, not discovery among alternatives.

    Group prompts by intent before running them:

    • Discovery prompts ask what a problem is, why it occurs, or how to approach it.
    • Evaluation prompts ask about criteria, methods, categories, risks, or suitable options.
    • Comparison prompts weigh named alternatives, features, costs, or trade-offs.
    • Validation prompts look for reviews, evidence, limitations, implementation details, or compatibility.
    • Transaction prompts ask where to buy, what something costs, or how to begin.

    Run the same prompt set separately in each engine. Preserve the wording and record the date, engine, answer, brand mentions, cited URLs, cited domains, source type, and intended landing page. If language, location, account state, or another test condition changes, record that as well instead of mixing the results into one trend line.

    One industry analysis covered 250 million AI-generated responses. That scale is a useful warning against treating a few favorable screenshots as a baseline. Generative answers can vary, so repeat the same test design and compare like with like.

    SignalHow to calculate itWhat it tells youCommon misreading
    Mention coverageEligible prompt runs containing the entity divided by all eligible prompt runsWhether the brand enters relevant answersTreating any mention as positive without checking context or accuracy
    Owned citation coverageEligible prompt runs citing an owned domain divided by all eligible prompt runsHow often your site supplies answer evidenceCalling a citation a visit
    Citation shareUnique citations to your domain divided by all unique citations in the tested answersYour presence within the observed source setPresenting test-set share as market-wide share
    Qualified referral rateAI-referred visits meeting your quality criteria divided by all tracked AI referralsWhether arriving visitors fit the page’s intended audienceJudging value from raw sessions alone
    Outcome rateDesired outcomes divided by tracked AI referralsHow observable AI traffic contributes to the businessCrediting every later direct or branded visit to AI

    Define a unique citation consistently. Counting the same URL several times inside one answer can inflate the result, so a practical default is one occurrence per unique URL per response. Keep domain-level and URL-level views. The domain view shows authority concentration; the URL view reveals which content actually earns the citation.

    Do not roll every prompt into a single average too early. A brand may be absent from discovery prompts but dominant in transaction prompts. That is a very different problem from broad underperformance. Report by engine, intent, topic cluster, market, and source role first. Use an overall score only as a navigation aid.

    Match your source strategy to the engine and the prompt

    AI engines do not necessarily choose the same kinds of evidence for the same request. In a 2025 holiday-season analysis of tens of thousands of identical ecommerce prompts, retailer sources appeared in about 4% of Google AI Overview results and 36% of ChatGPT results. Google leaned more heavily on YouTube, Reddit, Quora, and editorial sources, while ChatGPT more often surfaced retailers, brand pages, and manufacturer pages.

    That finding is specific to ecommerce prompts from that holiday period. It is not a universal rule for B2B software, healthcare, local services, finance, or every future version of either engine. The actionable lesson is narrower: segment your citation strategy by platform and query type instead of assuming one source profile applies everywhere.

    Build a source-role map before creating more content

    For each important prompt cluster, label every recurring citation as an owned brand source, retailer, editorial publication, community discussion, video source, or another relevant category. Then look for the missing role.

    • If owned pages are repeatedly cited, identify the exact passages and page formats supporting the answers. Maintain those facts instead of replacing a successful page simply because it is old.
    • If editorial and video sources dominate, give legitimate reviewers accurate specifications, evidence, and access to the material they need. Independent coverage cannot be replaced by publishing another self-authored claim.
    • If community discussions recur, improve the underlying product information and customer experience that people can discuss. Manufactured participation creates reputation risk and does not provide durable corroboration.
    • If retailer pages dominate, make product names, variants, attributes, and purchasing details consistent across the manufacturer site and authorized listings.
    • If competitors appear through a source type you lack, close that source-role gap rather than copying the competitor’s wording.

    For retail research prompts following the observed Google pattern, an owned product page alone may not cover the sources the answer prefers. You may also need accurate independent reviews, useful demonstrations, and authentic community evidence. For ChatGPT prompts following the observed retail pattern, complete brand, manufacturer, and retailer pages deserve closer attention because those sources appeared much more often.

    Validate both patterns against your own prompt set. Platform averages are a starting hypothesis, not a substitute for sector-specific observation.

    Keep discovery content even when its clicks decline

    Across an analysis of more than 7.2 million sessions to industry blog content, pricing and cost pages showed the strongest growth, comparison content also gained, and traditional guides declined. The scope matters: this was blog performance, not every content format, and the pattern does not by itself prove that AI caused the changes.

    Deleting top-of-funnel content would still be the wrong response. Discovery material can supply the definitions, criteria, and explanations that generative engines use before a person is ready to visit. If you remove it because direct sessions fell, you may also remove the material capable of earning early mentions and citations.

    Give each content layer a clear job:

    • Discovery pages should answer a narrow question directly, state their scope, distinguish easily confused concepts, and lead to the next decision.
    • Evaluation pages should provide criteria, trade-offs, limitations, and evidence a buyer can use to narrow the field.
    • Decision pages should expose pricing, comparisons, compatibility, availability, implementation requirements, or another concrete next step appropriate to the offer.
    • Product and service pages should keep names, claims, attributes, and calls to action consistent with the supporting content that introduces them.

    Connect these layers explicitly. A cited explainer should link to the relevant comparison or decision page, while the decision page should link back to the evidence behind its claims. This gives a human visitor a coherent path even when the AI engine exposes only one page.

    Use JSON-LD as a consistency layer, not as a citation counter. Mark up entities and attributes that are visible on the page, and keep names and relationships consistent with the readable content. Deployment is not the result. The result is whether the intended entity is understood accurately, cited in the right context, and connected to a useful next action.

    Turn sparse AI referrals into commercial evidence

    Three glowing droplets pass through transparent tracking rings and illuminate objects representing an inquiry, an opportunity, and realized value.

    AI referral volume can be small while the visitors who do arrive are close to a decision. Generative systems may complete much of the discovery and evaluation work before sending a person to a pricing, comparison, calculator, retailer, or product page. Measure the quality of that arrival before deciding the channel has little value.

    Build attribution in layers:

    1. Create an analytics channel for observable AI referrers. Keep the underlying source visible so you can compare engines instead of hiding them under one label.
    2. Record the landing page, content type, engagement events, and business outcome. A visit to a decision page should not be evaluated like a visit to an explainer.
    3. Separate human referrals from bot and agent retrievals in server-side reporting. A fetch can indicate access or use, but it is not a human session and should not be counted as one.
    4. Pass the original source into your CRM or lead system when your setup allows it. This lets you inspect lead quality, pipeline progression, and revenue instead of stopping at form completion.
    5. Add a short self-reported discovery field where the value of the decision justifies the extra question. Treat the answer as complementary evidence because memory and channel overlap make it imperfect.

    Not every AI-influenced journey will carry a usable referrer. A person may see a mention, open a separate tab, search the brand, or return later. Branded search growth, direct navigation, and self-reported discovery can help you notice that spillover, but they do not prove that a particular answer caused a particular visit.

    Keep direct attribution and assisted evidence in separate columns. The first contains observable referrals and outcomes. The second contains correlated signals such as stronger branded demand following improved answer visibility. Combining them produces an impressive number but a weak decision tool.

    Evaluate referral value with metrics that reflect your business:

    • Qualified visit rate: the share of tracked AI visits that meet your engagement or audience criteria.
    • Decision-action rate: the share that completes the action the landing page was designed to support.
    • Lead acceptance or sales progression: whether AI-sourced leads remain useful after the initial conversion.
    • Observable pipeline or revenue: the commercial result tied to tracked referrals under your normal attribution rules.
    • Landing-page concentration: which pages and intent stages receive the traffic, even when total volume is limited.

    Compare equivalent journeys. An AI referral landing on a pricing page should be compared with other channels entering that pricing page or the same intent stage, not with the sitewide average. Otherwise, differences in landing intent can be mistaken for differences in channel quality.

    Use the same discipline when evaluating citations. A citation on a broad educational prompt and a citation on a named comparison prompt have different commercial proximity. Report both, but do not assign them the same expected referral value.

    Key takeaways

    • Measure mentions, citations, human referrals, machine retrievals, and outcomes as separate events.
    • Use a stable, non-branded prompt set grouped by intent, then report results by engine before calculating an overall score.
    • Count citation coverage against eligible prompt runs and define duplicate handling before collecting data.
    • Audit the source roles each engine favors. Improve owned pages where owned sources win, and earn legitimate independent evidence where editorial, video, or community sources dominate.
    • Maintain discovery content for mentions and citations while strengthening pricing, comparison, and decision pages for the visits that arrive later.
    • Judge AI referrals by qualified actions, pipeline, and revenue, while keeping unproven assisted effects in a separate evidence column.

    Start with your highest-value prompt cluster and one engine. Freeze the prompt wording, capture the current answers and citations, map each cited source to its role, and connect every owned landing page to a measurable action. Change one content or source gap, repeat the same test, and let the movement in the correct signal determine the next change.

    References

  • A Practical Scorecard for AI-Era Digital Visibility

    A Practical Scorecard for AI-Era Digital Visibility

    Your rankings can hold steady while your brand quietly falls off the buyer’s shortlist. A prospect may ask ChatGPT, Gemini, or Claude for options, encounter you in a comparison without visiting your site, see a social post, and convert long after the first interaction. Traffic and last-click conversions record only fragments of that journey.

    You don’t need another all-purpose visibility score. You need a measurement system that separates business results, early intent, channel reach, AI perception, and volatility. That separation tells you whether to fix discoverability, positioning, conversion, or the metric itself.

    Key takeaways

    • Keep business outcomes, validated proxy events, channel visibility, and AI perception in separate layers. They answer different questions.
    • Measure AI visibility as a current state, a change from the previous baseline, and a pattern of stability over time.
    • Use a fixed prompt library and consistent test conditions. Otherwise, changes in your test can masquerade as changes in brand perception.
    • Promote a micro-conversion into reporting or bidding only after it predicts a downstream outcome, occurs early enough to be useful, and remains dependable.
    • Treat every unusual metric pattern as a diagnosis to test, not an automatic instruction to publish more content or increase spend.

    Build a layered scorecard instead of one blended score

    Five distinct transparent measurement layers align around a central axis, with blocks, pulses, nodes, prisms, and ribbons representing different metric types.

    A single score is attractive because it makes reporting look simple. It also hides the reason performance changed. An increase in AI mentions cannot compensate for declining qualified pipeline, just as revenue alone cannot tell you whether a recent visibility initiative is starting to work.

    Build the dashboard in layers. Let each layer retain its own denominator, time horizon, and decision owner.

    Measurement layerWhat to trackQuestion it answersDecision it supports
    Business outcomesQualified opportunities, pipeline, revenue, or the final outcome your organization acceptsDid marketing contribute to valuable demand?Budget allocation and commercial priorities
    Validated leading indicatorsEvents shown to precede the business outcome, such as a qualified demo request or meaningful product evaluationAre high-intent behaviors moving before revenue appears?Campaign optimization and faster testing
    Search and social discoveryImpressions, query coverage, clicks, referrals, and channel-specific engagementWhere can people encounter the brand?Distribution, content coverage, and channel investment
    AI perceptionMentions, recommendations, prominence, category associations, factual accuracy, and cited supportHow do AI systems recall and represent the brand?Entity clarity, positioning, documentation, and third-party evidence
    Signal stabilityChanges in inclusion, recommendation, position, and associations across comparable snapshotsIs visibility persistent or fragile?Investigation, monitoring, and risk prioritization

    The business-outcome layer remains the truth layer. The other layers shorten your feedback loop or explain how the outcome developed. Calling an AI mention, a scroll, or an impression a conversion erases that distinction and encourages the team to optimize activity instead of value.

    Channel data is also becoming less isolated. Google has begun integrating social channel data into Search Console Insights. That can make discovery reporting more convenient, but placement in one interface doesn’t turn social exposure into search performance or revenue. Preserve the channel label and follow the signal downstream.

    Make AI visibility a repeatable measurement

    AI visibility deserves its own layer because buyers are using generative systems during vendor discovery. A Responsive survey found that 80% of tech buyers use generative AI to research vendors as often as traditional search. That figure describes one surveyed market rather than every buyer, but it is strong enough to make AI recommendations relevant to B2B measurement.

    The difficult part is that an AI answer isn’t a fixed search result. Output can vary with the model, prompt, access mode, available context, underlying data, and model updates. A screenshot proves what appeared once. It does not establish durable visibility.

    Freeze a core prompt library

    Start with the decisions a buyer asks an AI system to help make. Keep a frozen core for period-over-period measurement and a separate exploratory set for new questions. Your core can cover:

    • Non-branded category discovery: which products address a defined problem or use case?
    • Shortlisting: which options fit a specified company type, constraint, or workflow?
    • Comparison: how do named alternatives differ on criteria buyers actually evaluate?
    • Risk and suitability: when is a product a poor fit, and what limitations should a buyer consider?
    • Implementation: which products integrate with the relevant ecosystem or operating environment?

    Record the exact prompt, model, date, access mode, language, location when relevant, repeat count, and full response. Keep these conditions consistent across snapshots. If you revise a prompt, preserve it as a new series instead of splicing its results into the old one.

    Run the same prompt more than once within each measurement window. Repeated runs help you distinguish answer variability from a broader shift. Keep the number of runs consistent so that a larger sample in one period does not create an artificial change.

    Score representation, not just mentions

    Define an eligible prompt before calculating any rate. A prompt is eligible when your offering could reasonably satisfy the stated need. Counting irrelevant prompts in the denominator suppresses the score and encourages category sprawl.

    • Mention rate: the share of eligible responses that name your brand.
    • Recommendation rate: the share that presents your brand as a suitable option rather than mentioning it incidentally.
    • Prominence rate: the share that places the brand in the opening recommendation set or another consistently defined prominent position.
    • Category-association rate: the share that connects the brand to the category, use case, audience, or capability you intentionally target.
    • Representation accuracy: the share of evaluated claims that match your current, verifiable product information.
    • Source-support rate: among answers that provide citations, the share that supports the brand description with an appropriate first-party or credible third-party page.

    A commercial AI brand score may combine visibility and rank in one number. Keep the underlying components accessible. A brand can be mentioned more often while becoming less prominent, or remain prominent while being associated with the wrong use case. Those situations demand different fixes.

    Separate state, drift, and stability

    Your current score is the state. The change between comparable snapshots is drift. The persistence of the signal across several snapshots is stability. Report all three.

    • Express rate changes in percentage points so the size and direction of movement remain visible.
    • Track which brands entered or left the recommendation set, not merely the average number mentioned.
    • Log association gains and losses. A brand may remain visible while moving from a core category into an adjacent one.
    • Compare models separately before calculating any aggregate. Agreement across models is stronger evidence than a gain confined to one system.
    • Measure persistent inclusion by checking which core prompts continue to mention or recommend the brand in adjacent periods.

    A September-to-October 2025 project-management snapshot recorded Atlassian gaining prominence while Slack declined. The same dataset showed category boundaries extending into operations, digital transformation, workflow orchestration, enterprise productivity, and IT consulting. This is one case, not a universal benchmark or proof of causation. It demonstrates why rank alone is insufficient: the conceptual neighborhood around a category can move along with the brands inside it.

    When an association changes, audit the evidence available across your site, technical documentation, integration material, reputable directories, GitHub repositories where relevant, reviews, and community discussions. These environments can reinforce different parts of an entity’s identity. The goal is not to manufacture mentions. It is to make the same accurate category, audience, capabilities, and limitations legible wherever people genuinely evaluate the product.

    Validate proxy metrics before algorithms optimize them

    Long B2B sales cycles create an uncomfortable gap: the team needs feedback before enough opportunities or revenue mature. Proxy metrics can fill that gap, but only if they predict the result you care about. A frequent event isn’t automatically a useful signal.

    Use four tests when deciding whether a candidate event belongs in your scorecard:

    • Correlation strength: people or accounts that complete the event should reach the downstream outcome more often than comparable ones that do not.
    • Timeliness: the event must occur early enough to change a live campaign, audience, message, or budget decision.
    • Actionability: your team must know which lever to adjust when the metric changes.
    • Stability: the relationship should persist across reporting periods and relevant audience segments rather than appearing in one temporary spike.

    Validate the event in a defined sequence:

    1. Name the downstream outcome precisely. Do not mix raw leads, accepted opportunities, and revenue in one target.
    2. Identify candidate events that happen before that outcome and can be joined to the same person or account without breaking your consent and data-governance rules.
    3. Compare downstream outcome rates for entities that completed each event with suitable entities that did not.
    4. Check the lead time. A strongly related event that occurs immediately before the final outcome may explain performance but still arrive too late for optimization.
    5. Repeat the comparison by period, channel, and meaningful audience segment. Promote the proxy only when its direction remains dependable.

    Keep events in three operational tiers. Business outcomes belong in executive reporting. Validated proxies can support campaign learning and, when appropriate, bidding. Diagnostic engagement events such as time on site or scroll depth should remain investigative until you demonstrate a downstream relationship.

    This matters when supplying early signals to Google or Meta optimization systems. Micro-conversions can help an algorithm learn when final-conversion volume is sparse, but the system will pursue the behavior you define. If scroll depth is cheap and loosely related to qualified demand, optimizing for it can produce more scrolling rather than more customers.

    Context changes the quality of a proxy. A newsletter signup may indicate continuing interest, while an add-to-cart event can mislead when abandonment is common. Neither event should inherit value from its name. Let its observed relationship with your own accepted outcome determine how you use it.

    Read cross-metric patterns before choosing a fix

    A strategist examines separate glowing signal forms whose connecting beams lead toward a compass, tuning dial, and open gateway.

    The scorecard becomes useful when you read movement across layers. The combinations below are working diagnoses, not conclusions. Use the next check to confirm or reject each interpretation.

    Observed patternWorking diagnosisWhat to check next
    AI mentions fall while search visibility holdsBrand perception, model behavior, or category association may have shifted without a traditional ranking lossCompare models, inspect lost prompts, review association changes, and verify that the test conditions stayed constant
    AI mentions hold but recommendation rate fallsThe brand remains known but appears less suitable or less prominentExamine stated limitations, comparison criteria, audience fit, and the brands now recommended ahead of it
    Search impressions fall while AI visibility holdsThe problem may sit in traditional search demand, coverage, ranking, or technical visibilitySegment branded and non-branded queries, inspect affected pages, and keep the AI series separate
    A proxy rises while qualified outcomes remain flatThe proxy may have weakened, the audience mix may have changed, or a later handoff may be failingRecalculate the proxy-to-outcome relationship and trace the journey after the event
    AI visibility rises while referral traffic stays flatThe gain may represent exposure rather than visitsCheck recommendation quality, branded demand, assisted journeys, and downstream outcomes before declaring success or failure
    Social discovery rises while search remains flatDistribution may be broadening in one channel without changing search demandPreserve channel attribution and test whether the added audience reaches a validated proxy or business outcome
    Discovery improves across channels but pipeline does notThe constraint may be message fit, offer fit, conversion, qualification, or the sales handoffInspect landing behavior and stage-to-stage progression before buying more reach

    At each reporting review, identify the largest meaningful movement, write down the most plausible explanations, and assign a check that can distinguish among them. Record the decision and its expected effect in the next comparable snapshot. That decision log prevents the team from retrofitting a success story to whichever metric happened to rise.

    Start your next dashboard revision by adding the missing layer, not by adding more charts. If you already report revenue and search traffic, build a fixed AI prompt baseline. If you already monitor AI mentions, add representation accuracy and stability. If micro-conversions drive optimization, revalidate their relationship with qualified outcomes. The next useful metric is the one that resolves a real decision your current reporting leaves ambiguous.

    References

  • Should You Block AI Crawlers? A Publisher Access Plan

    You’re deciding whether to shut out AI crawlers, but the cost of a mistake is lopsided. Allow too much and you may give away valuable access while absorbing the infrastructure cost. Block too broadly and you may cut off search discovery that still brings readers, customers, and subscribers.

    The workable approach is to stop treating “AI” as one access category. Decide which systems may retrieve which content, for which purpose, under which conditions. Then enforce that policy in layers and measure the result.

    Separate discovery, retrieval, training, and licensing

    A crawler request is a technical event, not a complete explanation of intent. The same public page can have several distinct uses, and your business may benefit from some while rejecting others.

    • Conventional search discovery: A search crawler retrieves a page so the page can be considered for a search index. Access makes discovery possible; it does not guarantee indexing or rankings.
    • Live AI retrieval: A system fetches current information to help answer a user’s request. You may value the resulting visibility, but allowing retrieval does not guarantee a citation or referral visit.
    • Model development: An operator collects content for training or related model-improvement work. This can involve a different value exchange from answering a current query.
    • Licensed access: A publisher deliberately supplies content under agreed technical and commercial terms, potentially through authentication, metering, or a dedicated feed.

    These purposes are strategically separate even when a platform does not give you separate crawler controls. That limitation matters: you can only implement distinctions that the operator exposes and your infrastructure can verify. Where an operator combines purposes, record the exception and make the resulting trade deliberately.

    Key takeaways

    • Preserve conventional search access unless you have consciously decided that its discovery value no longer justifies it.
    • Set policy by crawler identity, declared purpose, and content class rather than using one domain-wide rule for every automated request.
    • Use robots.txt to communicate crawl preferences, but use server-side controls or authentication when access must actually be prevented.
    • Roll out narrow, reversible rules and compare infrastructure savings with changes in discovery, revenue, and AI visibility.

    A blanket block creates an asymmetric business risk

    The volume is large enough to justify active management. Cloudflare reported that, following the July 1 launch of its pay-per-crawl initiative, customers had blocked 416 billion AI-bot requests. That figure demonstrates the scale of crawler demand on participating sites. It does not establish that every blocked request would have harmed a publisher or that blocking is the right default for every site.

    Access is also uneven. Cloudflare argues that publishers cannot cleanly separate Google Search access from Google AI access, and puts Google’s page visibility at 3.2 times OpenAI’s, 4.6 times Microsoft’s, and 4.8 times Anthropic’s or Meta’s. Those are vendor-supplied measurements, so treat the ratios as a directional view of the access imbalance rather than universal traffic benchmarks.

    This is why “block all AI” can be a misleading objective. If the platform connects conventional search crawling with AI use, the technical setting may force a wider business decision than you intended. Before deploying a rule, write down which benefit you are prepared to lose. If the answer is “none of our organic search discovery,” a domain-wide crawler block is too blunt.

    The reverse is also true. “Allow everything for visibility” is not a strategy. An allowed request may generate no referral, citation, subscription, or licensing opportunity. Access should remain open because it serves a defined outcome, not because the crawler includes “AI” in its name.

    Build an access matrix your engineers can enforce

    Turn the policy into a small matrix before touching robots.txt or a firewall rule. Start with four access tiers and assign each content class to one of them.

    Access tierUse it forTechnical defaultBusiness condition
    Open discoveryPublic pages intended for broad distributionAllow verified search crawlers and selected AI access; monitor usageReach and discoverability outweigh reuse concerns
    Search-preservedPublic pages that should remain searchable but are not offered for wider AI collectionAllow conventional search where the operator exposes a separate identity; deny or throttle named AI crawlersThe technical identities can be separated reliably
    Metered or licensedOriginal archives, structured collections, or other material with concentrated reuse valueRequire authentication, rate limits, or a controlled delivery channelAccess is granted under recorded operational and commercial terms
    ClosedSubscriber-only, internal, personal, or otherwise non-public materialRequire authentication and enforce denial at the server or application layerPublic crawler access is unnecessary or inappropriate

    Do not classify the whole site by its most valuable page. A public news story, an evergreen guide, a subscriber archive, an image library, and an internal search endpoint can justify different rules. URL groups make the policy more precise and make mistakes easier to reverse.

    For every crawler-policy combination, record the operator, declared purpose, method used to verify identity, allowed URL groups, rate limit if any, enforcement layer, policy owner, and review date. If you cannot verify the operator or purpose, classify the traffic according to your risk tolerance rather than guessing from a friendly-looking user-agent string.

    Keep the technical policy separate from the legal permission. A crawler being able to retrieve a page does not by itself define the terms under which the content may be reused. If you intend to sell or contractually license access, have appropriate legal counsel establish the rights, attribution, payment, update, termination, and enforcement terms.

    Enforce the policy in layers, not with one bot rule

    Robots.txt is useful for expressing crawl instructions to compliant operators. It is not authentication, and it does not prevent an unidentified or non-compliant client from requesting a public URL. Use the control that matches the consequence of failure.

    1. Capture a baseline. Before changing access, record crawler requests, transferred bytes, cache misses, origin load, requested URL groups, response codes, search crawl health, search traffic, observable AI referrals, and conversions. Note campaigns or publishing spikes that could distort the comparison.
    2. Inventory and verify identities. Group requests by claimed user agent, network identity, paths requested, rate, and behavior. A user-agent string can be copied, so do not approve or block high-impact access solely because a request claims a recognizable name. Use verification information supplied by the relevant operator where it is available.
    3. Publish the intended crawl rules. Add crawler-specific robots.txt instructions only after confirming that the rule preserves the search access you want. Test the deployed file, including rules inherited from broader user-agent groups.
    4. Enforce consequential restrictions upstream. Use your CDN, web application firewall, origin, or application to throttle or deny matching requests. Keep each rule narrow, log its matches, return a consistent response, name an owner, and document the rollback procedure.
    5. Put valuable non-public material behind authentication. Do not rely on robots.txt to protect subscriber content, private files, customer information, unpublished drafts, or licensed datasets. If anonymous visitors can retrieve a URL, an automated client may be able to retrieve it too.
    6. Stage the rollout. Begin with one verified crawler identity or one low-risk URL group. Review false positives and business metrics before extending the rule. This limits the damage if a shared identity, proxy, or overly broad path pattern catches traffic you meant to preserve.

    Blocking only affects requests that reach your controls and match your rules. It does not prove that a model lacks the content, and allowing a crawler does not prove that the content will appear in an answer. Describe the operational outcome accurately: you allowed, throttled, or denied a particular access path.

    Measure whether blocking improved your position

    A successful block is not merely a rising denial count. The useful question is whether the policy improved the exchange between access granted and value received. Review the same scorecard before and after each staged change.

    • Infrastructure: Requests, bandwidth, cache misses, origin work, and load associated with each verified crawler and content class.
    • Search discovery: Crawl errors, accessible pages, index coverage, organic impressions, clicks, and landing-page conversions. Investigate changes that coincide with a rule deployment before expanding it.
    • AI visibility: Observable AI referrals, cited pages found through a consistent sample of relevant prompts, brand mentions, and resulting conversions. Referral logs measure visits, not every unseen citation or model use, so do not treat zero referrals as proof of zero exposure.
    • Content value: Subscriptions, leads, revenue, partnership requests, and licensing discussions associated with the affected material.
    • Policy quality: False positives, unidentified automation, repeated requests against denied paths, operator verification failures, and rules that no longer match your content structure.

    Set the decision rule before examining the result. Retain a restriction when it materially reduces unwanted access or resource use without damaging the outcomes you chose to preserve. Roll it back when search discovery or legitimate partner access declines because the match was too broad. Move valuable, persistent demand toward authenticated or licensed access when the opportunity justifies the operational and legal work.

    Your first action can be small: write one policy sentence for conventional search, one for live AI retrieval, one for model-development access, and one for premium content. Compare those sentences with the controls your platforms actually expose. Where policy and tooling do not line up, start with the narrowest reversible restriction and preserve the baseline you will need to judge it.

    References

  • A Practical Guide to Brand Authority in AI-Driven Search

    A Practical Guide to Brand Authority in AI-Driven Search

    You can publish accurate content, rank for relevant queries, and still be absent when an AI system explains your market. If that is happening, another batch of loosely related articles probably will not solve the problem. The missing ingredient is often a recognizable chain of evidence connecting your brand, your expertise, and independent confirmation of that expertise.

    Your job is to make that chain easy for machines and people to follow. That means clarifying who you are, giving important claims a reliable home, earning corroboration beyond your own domain, and checking how AI systems actually represent you. This guide gives you a practical way to do it.

    Key takeaways

    • Brand authority is not the same as visibility. A brand can appear frequently while remaining poorly defined, weakly supported, or easy to omit from an answer.
    • Build a canonical evidence layer on your site before pursuing more mentions. Your identity, expertise, authorship, claims, and structured data should describe the same entity.
    • Relevant citations, inbound links, expert references, and contextual brand mentions provide different kinds of outside corroboration. Track them separately.
    • Make important pages easy to interpret and quote: answer the question directly, show who is responsible for the information, identify its scope, and support material claims.
    • Audit generated answers for inclusion, accuracy, attribution, and supporting citations. Each failure points to a different repair.

    Brand authority is an evidence chain, not a single score

    In AI-driven search, authority has a practical meaning: a system can identify your brand, connect it to a subject, and find enough supporting evidence to include it confidently in a synthesized answer. That is broader than traditional link authority. Modern off-page signals include inbound links, citations, brand mentions, reputation, and evidence of expertise, not merely the number of sites pointing at a domain.

    No universal public formula tells you how every AI system evaluates a brand. Treat the following chain as a diagnostic model, not a claim about a hidden ranking algorithm:

    1. Identity: Can the system distinguish your brand from similarly named companies, products, and people?
    2. Topic association: Is it clear what subjects, problems, audiences, or markets your brand is genuinely connected to?
    3. Primary evidence: Does your own site contain clear, attributable information supporting the claims you make?
    4. Independent corroboration: Do credible sources outside your control describe, cite, or recommend the brand in a compatible way?
    5. Answer utility: Can a system extract a useful passage without guessing what you mean or stripping away a necessary qualification?

    A weakness at each point produces a different symptom. If your identity is unclear, the answer may confuse you with another entity. If your topic association is weak, the brand may appear for navigational questions but disappear from category discovery. If primary evidence is thin, an AI answer may mention you without being able to support a detailed description. If outside corroboration is missing, your own claims can look isolated. If the content is difficult to interpret, a more clearly written competitor may be easier to cite.

    This is why publishing volume is a poor default response to an authority problem. First identify the broken link in the chain. Then repair that link.

    It also helps to separate three outcomes that are often bundled into one vague idea of “AI visibility”:

    • Presence: Whether the brand appears at all.
    • Representation: Whether the answer describes the brand accurately and in the right context.
    • Authority: Whether the brand is used as a credible source, example, or option rather than receiving a passing mention.

    Measure those outcomes independently. A high mention count does not compensate for an inaccurate description, and an accurate branded answer does not prove that you are discoverable for unbranded category questions.

    Build a canonical evidence layer on your own site

    An orderly glass-and-stone digital library sits on an illuminated foundation as scattered document panels converge on one central source.

    Before you ask other sites to validate the brand, decide exactly what they should be validating. Many authority campaigns begin with outreach while the company’s own pages use different descriptions, audience labels, expert biographies, and product claims. That inconsistency makes every later signal harder to interpret.

    Create a brand authority brief

    Build an internal source of truth that contains the facts your public pages should agree on. It does not need to become a single public document. It should govern what your teams publish.

    • The exact public brand name and any legitimate alternate name.
    • A plain one-sentence description of what the brand does, for whom, and in which context.
    • The subjects on which the brand can support a credible claim to expertise.
    • Subjects that are adjacent but outside that claim. This boundary prevents positioning from expanding into unsupported territory.
    • The official website and public profiles that clearly belong to the same entity.
    • The people responsible for producing or reviewing expert content, along with the credentials relevant to that work.
    • The primary page supporting each important company, product, service, or methodology claim.
    • Independent pages that corroborate those claims.

    The one-sentence description matters more than a slogan. “We transform the future of business” gives a machine almost nothing to connect to a category. A useful description follows a more disciplined pattern: “[Brand] helps [specific audience] perform [specific task] through [method or product category].” Add a limitation when readers could otherwise infer a broader capability than you can support.

    Use the brief to audit your homepage, About page, contact information, product or service pages, author biographies, editorial policy, and public profiles. The wording does not have to be identical everywhere. The facts and relationships do.

    Give every important claim a reliable home

    A claim repeated across promotional pages is not necessarily well supported. Give each material claim a canonical page where a reader can understand its meaning, scope, basis, and owner. Maintain a simple claim ledger with these fields:

    • Claim: The exact statement you want people and systems to understand.
    • Primary evidence: The page on your site that explains or supports it.
    • Responsible expert: The person or team qualified to verify it.
    • Independent corroboration: The strongest relevant evidence outside your domain.
    • Known qualification: The audience, market, use case, or condition that limits the claim.
    • Status: Confirmed, incomplete, outdated, disputed, or unsupported.

    This ledger exposes a common problem quickly: the positioning may be stronger than the evidence. If a claim has no responsible expert, no explanatory page, and no outside corroboration, do not amplify it yet. Narrow it or develop the missing evidence first.

    Pages supporting those claims should make their answer easy to extract correctly. Put the direct answer near the relevant heading. Define unfamiliar terms. State the intended audience and important exclusions. Show authorship or review responsibility where expertise matters. Link to the material that supports the statement. Update the page when the underlying facts change.

    A useful answer passage often has four parts:

    • Answer: The direct response to the question.
    • Boundary: Where the response applies and where it does not.
    • Basis: The evidence, method, or reasoning behind it.
    • Attribution: The brand or expert responsible for the information when that identity is relevant.

    This structure improves clarity without turning every paragraph into a formula. It also reduces the chance that a useful statement becomes misleading when removed from the surrounding page.

    Use structured data to clarify facts, not manufacture them

    Structured data and a consistent brand identity help systems connect content with the right entity and topics. Use your JSON-LD to mirror facts that a visitor can verify on the page. Keep names, official URLs, author relationships, publisher relationships, and content descriptions aligned with the visible site.

    Do not introduce a claim only in markup or use structured data as a substitute for evidence. Schema can reduce ambiguity. It cannot turn an unsupported marketing statement into independent authority. If the visible page, the structured data, and third-party descriptions disagree, repair the underlying facts before adding more markup.

    Earn corroboration that your brand does not control

    Your website establishes the primary record. Outside evidence shows whether anyone else recognizes it. That is the core of modern off-page authority: relevant endorsements from credible sources strengthen trust more than disconnected mentions.

    Do not combine every off-site appearance into one count. An inbound link, a citation, and a brand mention can perform different jobs:

    • Inbound link: Gives readers a path to your evidence and places your page in a specific editorial context.
    • Citation: Identifies your brand, expert, work, or material as support for a claim, whether or not the reference is clickable.
    • Brand mention: Associates the brand with a subject, event, opinion, product, or reputation. The surrounding context determines whether that association helps.

    A passing mention may improve recognition without supporting expertise. A link from an unrelated page may offer little useful context. A detailed citation from a respected source in your field can validate a particular claim even if it does not use your preferred anchor text. Record what each placement proves instead of treating all three as interchangeable.

    Evaluate a potential placement with five practical questions:

    1. Relevance: Is the surrounding page about the subject for which you want authority?
    2. Editorial independence: Did the publisher have a genuine reason to include the brand, expert, or resource?
    3. Specificity: Does the reference connect you to a meaningful claim, or does it merely list the brand name?
    4. Consistency: Does the description agree with the canonical facts on your site?
    5. Reader value: Would the reference still help someone if search engines and AI systems did not exist?

    The last question is a useful filter for manipulative tactics. If a placement has no credible purpose beyond creating a signal, it is unlikely to build the kind of reputation you want machines to reproduce.

    The most sustainable way to earn corroboration is to give other people something worth referencing. Publish a clear definition, a defensible method, an expert explanation, a practical framework, or an analysis that resolves a real question. Make the useful part easy to locate and attribute. Then take it to the publications, communities, professional networks, and content platforms where that exact subject is already discussed.

    Distribution should follow audience behavior, not a demand to occupy every channel. Search discovery now extends beyond conventional results into platforms such as YouTube, TikTok, Pinterest, and Amazon, as well as synthesized AI answers. Choose the places where your audience actually learns, evaluates, or buys. Keep the entity facts stable while adapting the format to the platform.

    Monitor the context as carefully as the quantity. A brand can accumulate mentions while an old description, discontinued positioning, or reputation issue becomes the dominant outside narrative. Correct material inaccuracies at their origin when possible. Then make the accurate record unmistakable on your own site. Repeating the right answer only on pages you control does not remove conflicting third-party evidence.

    Audit how AI systems represent your brand

    A transparent inspection lens examines a faceted identity object connected to several source nodes, revealing aligned and misplaced fragments.

    Rank tracking tells you where a page appears in a conventional result set. It does not tell you whether an AI answer omitted the brand, described it incorrectly, relied on an outdated source, or used your expertise without clear attribution. You need an answer-level audit alongside your SEO reporting.

    Start with a stable set of prompts based on real audience decisions. Include prompts from several intent types:

    • Category discovery: “Which companies help [audience] solve [problem]?”
    • Source discovery: “Who are credible sources on [topic]?”
    • Branded understanding: “What does [brand] do, and who is it for?”
    • Expertise association: “What is [brand] known for in [field]?”
    • Evaluation: “What should a buyer consider when choosing a provider for [task]?”
    • Problem solving: “How should [audience] approach [specific problem]?”

    Use the AI systems your customers are likely to use. Keep the prompt wording fixed when you compare results, and repeat checks because generated responses can vary. Capture the complete answer and its citations rather than recording only whether the brand appeared.

    For each result, record:

    • The prompt and the intent it represents.
    • Whether the brand appears.
    • How prominently and in what role it appears: source, example, option, recommendation, or passing mention.
    • Whether the description is factually accurate.
    • Whether important qualifications are preserved.
    • Whether your site is cited.
    • Which third-party pages are cited or appear to support the response.
    • Which competing entities are included.
    • Any unsupported, outdated, or reputation-sensitive claim requiring correction.

    Do not collapse all of this into one opaque visibility score. A compact dashboard can report several separate measures: inclusion across the prompt set, accurate descriptions, citation presence, independent corroboration, and unresolved errors. The detail matters because each pattern implies a different action.

    • Omitted from unbranded prompts: Review topic focus and relevant outside corroboration. Your brand may be identifiable but not strongly associated with the category.
    • Included but described incorrectly: Compare the answer with your brand brief. Find conflicting pages, profiles, markup, or third-party descriptions and correct the most authoritative origin you can reach.
    • Mentioned without supporting citations: Strengthen the canonical evidence page and earn references to that specific evidence.
    • Your page is cited but the brand is not named: Make attribution clearer where it is editorially relevant. Check page titles, authorship, publisher information, and the wording around the cited passage.
    • Accurate for branded prompts but absent from category prompts: Invest in independent category association rather than adding more navigational brand copy.
    • Negative or outdated context dominates: Treat it as a reputation and record-correction problem, not merely an on-page optimization problem.

    This diagnosis is directional, not proof of a hidden cause. AI systems may draw on different material and produce different outputs. Use repeated patterns to prioritize work, then check whether the representation changes after the underlying evidence changes.

    Make authority an operating system, not a campaign

    Brand authority decays when it belongs to one launch or one department. Products change, experts move, pages are rewritten, profiles drift, and third parties keep old descriptions alive. The repair is a lightweight operating process that joins content, technical SEO, communications, subject experts, and reputation monitoring.

    1. Choose an authority territory. Define the audience, problem, and subject for which the brand has credible evidence. Narrow positioning is easier to support than a claim to lead every adjacent topic.
    2. Approve the canonical record. Maintain the brand brief, expert information, official profiles, and claim ledger.
    3. Publish primary evidence. Give priority questions clear answers, visible ownership, sensible qualifications, and supporting material.
    4. Align machine-readable information. Make structured data reflect the visible record and the real relationships among the brand, publisher, experts, and content.
    5. Earn relevant corroboration. Build relationships and reference-worthy resources around specific claims instead of pursuing disconnected link volume.
    6. Audit generated answers. Track presence, representation, authority, citations, and errors across a stable prompt set.
    7. Repair the evidence chain. Assign each omission or error to the page, profile, markup, third-party record, or reputation issue most likely to be responsible.

    Assign an owner to every recurring part of this process. Editorial teams can maintain primary answers. Subject experts can verify claims. Technical teams can keep structured data aligned. Communications teams can pursue and correct outside references. Whoever monitors AI answers should route each finding to the owner who can repair the underlying evidence.

    Clicks still matter, but they are no longer a complete measure of influence. As AI agents perform more browsing and task execution directly, a brand can enter or leave consideration before a person visits its website. Track qualified traffic and conversions, but also track whether machines identify the brand accurately, associate it with the right problems, and support that representation with credible evidence.

    Start with the commercially important topic where omission would hurt most. Write the authority claim you want to support, locate its primary evidence page, identify the strongest independent corroboration, and run the relevant prompts. Any empty or contradictory field in that chain is your next task.

    References

  • Google Discover and AI Mode: An Emerging-Query Workflow

    Google Discover and AI Mode: An Emerging-Query Workflow

    If your Google strategy begins when someone types a query, you may be entering the journey too late. A person can encounter a story in Discover, open the page, and then continue exploring it through AI rather than returning to a conventional results page.

    That changes the content problem in two directions. You need to recognize demand before it becomes an obvious keyword opportunity, and the page you publish must remain useful when a reader asks an AI system to summarize it, answer a follow-up, or go deeper.

    Optimize the whole discovery journey, not one ranking

    The emerging Google journey has three distinct moments, and each asks something different of your content:

    1. Discovery: A topic, headline, image, or entity earns attention in a personalized feed. The reader may not have expressed a conventional search query.
    2. Evaluation: The reader opens the page and decides whether it answers the immediate question clearly enough to trust and continue.
    3. Exploration: The reader uses AI to condense the page, ask another question, or investigate the subject in more depth.

    The third moment is no longer theoretical. In the observed Google app for Android flow, a menu available after opening a URL offered Summarize with AI Mode, Ask a follow-up with AI Mode, and Dive deeper with AI Mode. The behavior was not confined to stories selected from Discover; AI Mode controls were also available for other pages opened through the app.

    This means a click is not necessarily the end of the search experience. Your page can become material the reader interrogates. A catchy headline may win the first transition, but it cannot compensate for vague entities, buried conclusions, unsupported assertions, or sections that repeat the same point.

    Plan the journey backward. Start with the useful action or decision the reader should reach. Then identify the questions that lead there:

    • What happened, or what is changing?
    • Why does it matter to this reader?
    • What is still uncertain?
    • What should the reader compare, check, or do next?
    • What related question becomes important after the first answer?

    Those questions should determine the article structure before you write the headline. They also give you a practical standard for deciding whether a trend deserves coverage at all.

    Find rising demand before it looks like a mature keyword

    A strategist observes scattered digital signals converging into a bright rising pattern on a translucent display.

    Traditional keyword research is strongest when a query already has enough repeated behavior to measure. Emerging demand often appears first as an event, product, person, phrase, policy, cultural reference, or unfamiliar entity. By the time every tool reports stable volume, the easiest editorial opening may have passed.

    Google’s 2025 Year in Search was organized around rapidly rising searches rather than a simple ranking of the largest query totals. The U.S. list crossed technology, policy, entertainment, sport, and public affairs with queries such as DeepSeek, iPhone 17, tariffs, KPop Demon Hunters, and the FIFA Club World Cup. The global list included Gemini, DeepSeek, major cricket matchups, the Club World Cup, and iPhone 17.

    The more useful lesson is not which names appeared. It is how many different forms new demand can take. Additional U.S. trends included AI action figure, a long viral-dish phrase, a Boston travel-itinerary query, and a question about why children say 67. A useful trend radar therefore cannot be limited to short commercial keywords. It has to notice new entities, new behaviors, new language, and old needs expressed in unfamiliar ways.

    Keep a signal log that captures what keyword volume misses

    Create one shared record for emerging topics. For each signal, capture:

    • The exact phrase or entity: Preserve the wording people are using instead of immediately translating it into an established keyword.
    • The trigger: Record the launch, event, announcement, controversy, release, match, meme, or behavior that created the question.
    • The audience connection: State why your existing reader would care. A topic can be popular without belonging on your site.
    • The first practical question: Identify what the reader needs to understand, decide, buy, avoid, or explain.
    • The likely follow-ups: Write down the next questions before search-volume data exists for them.
    • The evidence available: Note what can be verified now and what remains unknown. If you cannot support the central answer, speed will not improve the page.
    • The expiry condition: Decide what event would make the page outdated, incomplete, or misleading.

    This log prevents a common mistake: treating a growing entity as if it were already a settled keyword cluster. Early in a trend, people may search for the name alone because they do not yet know the vocabulary for a more precise question. Your job is to infer the legitimate questions cautiously, then revise the page as the language becomes clearer.

    Use a publication gate before chasing the spike

    Run every candidate through five questions:

    1. Is the reader ours? Define the person who needs the answer without relying on a phrase such as everyone is talking about it.
    2. Is there a real job to do? Name the decision, explanation, comparison, or action the page will support.
    3. Can we add clarity? If the page will merely restate the event, it has little reason to exist after the first wave of coverage.
    4. Can we maintain it? A fast-changing page needs an owner and an explicit update trigger.
    5. Does it connect to durable expertise? The best emerging topic opens a path into subjects your site can continue to explain after the spike fades.

    If you cannot answer the first three questions, skip the topic. If you cannot support the final two, narrow the scope until you can. Publishing a thin page for every rising name creates an archive of disconnected updates, not topical authority.

    Once a topic passes the gate, prepare a brief containing the provisional query cluster, the one-sentence answer, the follow-up question map, the entities that require disambiguation, the supporting evidence, the intended URL, and the conditions that will trigger an update. That is enough structure to move quickly without turning speed into guesswork.

    Build pages that survive summary, follow-up, and depth

    Cutaway illustration of readers exploring an overview, branching answer areas, and deeper research layers within a structured web page.

    The three AI Mode commands provide a useful editorial test. Apply all three before publication, even if a particular reader never opens the AI controls.

    The summary test

    Could a reader identify the subject, central answer, significance, and main limitation from the opening and section headings? If not, the page is making both readers and machines reconstruct a conclusion that you should have stated directly.

    • Name the primary entity in the title, introduction, and relevant heading instead of relying on ambiguous pronouns.
    • Give the direct answer before the chronology or background.
    • Separate confirmed facts from interpretation and unresolved questions.
    • Use one section for each distinct idea. Do not scatter the same conclusion across several headings.
    • Remove paragraphs that merely announce what the next paragraph will explain.

    A good summary test is not an instruction to make every article short. It is an instruction to make the hierarchy unmistakable. A detailed page can still have a clear central answer.

    The follow-up test

    After reading the answer, what would a sensible person ask next? Turn the strongest second-order questions into substantive sections. Depending on the topic, these may concern eligibility, cost, timing, alternatives, consequences, definitions, examples, or what changed.

    Do not manufacture a question section from keyword variants that all have the same answer. Each follow-up should move the reader to a new understanding or decision. If two questions collapse into the same paragraph, combine them.

    Internal links should continue the same logic. Link to a durable explainer when the reader needs background, a comparison when the next task is choosing, and a process page when the next task is acting. Generic related-reading blocks leave that choice to chance.

    The depth test

    What can the reader learn from your page that would be lost in a one-paragraph recap? Depth comes from useful distinctions, not word count. Add the material that changes interpretation: definitions, boundaries, named entities, evidence, exceptions, trade-offs, and the point at which the advice no longer applies.

    For a fast-moving topic, show what is known at publication and what still needs confirmation. Update the existing URL when the central intent remains the same. Create a separate page only when a genuinely different intent appears. That keeps one answer coherent while preventing a single URL from becoming an undifferentiated timeline.

    Make the structured data agree with the visible page

    JSON-LD should describe the page you actually published. For editorial content, use Article or a truthful, more specific subtype. Keep the structured headline, author, publication date, modification date, canonical page identity, and publisher consistent with what the reader can see.

    • Use stable identifiers for people and organizations so the same entity is not represented as several unrelated things across the site.
    • Change the modification date when the content receives a substantive update, not when an automated process touches the template.
    • Represent the page’s primary subject consistently in the copy, metadata, internal links, and structured data.
    • Add a schema type only when the visible content meets its meaning. Anticipating follow-up questions does not require disguising an ordinary article as a different content format.
    • Validate the markup and inspect the rendered page. Syntactically valid JSON-LD can still contradict the content it describes.

    Structured data can make relationships more explicit, but it cannot turn a vague page into a reliable answer or guarantee distribution in Discover, Search, or an AI response. Treat it as a consistency layer, not a substitute for editorial substance.

    Measure whether early attention becomes durable value

    A trend page can produce a traffic spike and still fail strategically. Measure the complete path: how early you recognized the signal, whether the page satisfied the immediate need, whether readers continued into relevant content, and whether the topic strengthened a durable area of expertise.

    QuestionSignal to recordDecision it supports
    Did we recognize the topic early?First-observed date, assignment date, and publication dateWhether the discovery workflow is fast enough
    Did the page match the emerging need?Queries where available, landing-page behavior, and movement to the next relevant pageWhether the angle and follow-up map were accurate
    Did the topic matter to our audience?Qualified subscriptions, leads, purchases, saves, or other site-specific outcomesWhether attention was useful rather than merely large
    Did the opportunity become durable?New recurring questions, internal-link use, and continued interest in the surrounding topicWhether to build an evergreen supporting resource
    Does the page need maintenance?Material changes to the entity, event, availability, policy, or reader intentWhether to update, narrow, redirect, or stop promoting the URL

    Keep these observations attached to the topic record. Keyword volume seen later cannot tell you what your team knew when it made the editorial decision. The first-observed date and original question map let you review whether you spotted a real signal or merely followed an already visible spike.

    Judge trend coverage against its intended role. An emerging explainer should not be evaluated like a mature evergreen guide, and an audience-building story should not be declared successful solely because it attracted raw visits. Define the meaningful next action before publication, then measure that action consistently.

    When interest declines, preserve what remains useful. If the original question still exists, update the page and connect it to an evergreen resource. If the event has ended but the surrounding need persists, create a separate durable page and link the two in both directions. Do not keep producing minor update pages that compete to answer the same intent.

    Key takeaways

    • Google discovery can begin before a conventional query and continue through AI after the click, so optimize the complete question journey.
    • Use a signal log for new entities, phrases, triggers, audience questions, evidence, and expiry conditions; keyword volume alone will often arrive too late.
    • Publish a trend only when it serves your established audience, answers a real question, adds clarity, can be maintained, and connects to durable expertise.
    • Test every page for summary, follow-up, and depth: state the answer clearly, anticipate the next useful questions, and add distinctions that survive compression.
    • Keep visible content, metadata, internal links, and JSON-LD consistent. Schema clarifies meaning but does not replace trustworthy content.
    • Measure lead time, useful onward behavior, audience outcomes, and long-term topic value instead of treating a temporary traffic spike as the goal.

    Start with one rising topic already sitting in your editorial backlog. Write its trigger, reader, first question, next three questions, available evidence, and update condition. If those lines are clear, you have the basis for a useful page. If they are not, waiting or declining the topic is a better decision than publishing a fast page with no durable answer.

    References

  • Google AI Search Personalization: What SEO Teams Should Do

    Google AI Search Personalization: What SEO Teams Should Do

    You may be looking at Google AI Mode and asking a deceptively simple question: if Google can change the interface and tailor the experience to each person, what does ranking even mean? You still need visibility, but a position checked once from one browser is no longer a reliable description of it.

    The workable goal is to make your brand easy to retrieve, understand, compare and trust across different search journeys. That requires a wider testing method, clearer entity information and a sharper distinction between queries that can end with an AI answer and queries that still lead people to evaluate websites.

    Google is changing the entrance to search

    A traditional SEO test begins with a typed query and a results page. That model no longer covers every important entrance into Google Search.

    Uploading a file or image from Google’s homepage can take the user directly into AI Mode instead of a conventional Google Lens results flow. AI Mode has also appeared in the Chrome omnibox, while its tab has received prominent placement in the search interface.

    Those placements do not prove that AI Mode will become the universal default. They do establish a practical problem for SEO teams: the same underlying need can now begin with a keyword, an uploaded object, an image, a document or a conversational follow-up. The interface determines what context the user supplies before Google generates anything.

    Start auditing journeys rather than keywords alone. For each priority need, record:

    • The entrance used: conventional Search, AI Mode, Chrome or an upload flow.
    • The input type: text, image, file or a follow-up inside an existing conversation.
    • The user’s real task: learning, comparing options, choosing a provider or completing an action.
    • Whether the response names your brand, cites your page, offers a link or presents a competing option.
    • What additional evidence a person must obtain before making the decision.

    This prevents a common measurement error. If you test only typed queries in conventional Search, you are measuring one interface rather than your total Google visibility.

    Personalization makes the search session the useful unit

    A person follows a ribbon of connected search steps while two alternate search journeys branch through different interface panels in the background.

    Personalization is not merely a rewritten ranking order. It can affect what appears, when it appears and which part of a broader topic Google considers relevant to the person at that moment.

    Google’s Daily Hub work illustrates the direction. Its design combined full content records containing structured text, Knowledge Graph entity identifiers, embeddings and technical metadata with smaller records for individual entities. Separate personalization systems refined user interests, while an ambient ranking layer considered relevance and timing when choosing what to display. Features such as Preferred Sources and followable profiles in Discover also give people ways to shape what reaches them.

    Daily Hub was paused after its technical complexity became difficult to manage. Its architecture should therefore be treated as evidence of Google’s broader direction, not as a published specification for how every AI Mode result is ranked.

    The distinction matters. You cannot reverse-engineer a universal personalized rank from one experimental system. You can, however, prepare content for the recurring jobs such systems must perform:

    • Identify the entity. Google must be able to distinguish your organization, product, service, person or location from similarly named entities.
    • Connect the entity to the topic. A name alone is weak evidence. Your visible content should explain what the entity does, who it serves and how it relates to the user’s task.
    • Retrieve the right content unit. A focused page with explicit facts is easier to interpret than a broad page that mixes unrelated intentions.
    • Judge contextual relevance. Time-sensitive information needs a visible date or status and must be corrected when it becomes stale.
    • Support a next step. When the user is choosing rather than merely learning, the page must provide evidence and a clear path to act.

    This is where JSON-LD helps, but its role needs to be stated accurately. Structured data can express the entities and relationships already present on the page in a consistent, machine-readable form. It cannot force Google to select the page, override weak content or guarantee the same answer for every person.

    Keep names, URLs, entity types, locations and relationships consistent between visible copy, structured data and important external profiles. If your Organization markup identifies one name while your service pages and business profiles use several unexplained variants, you are creating ambiguity at the exact layer personalized retrieval depends on.

    Transactional searches still create a consideration set

    AI-generated answers can satisfy some informational searches without a website visit. That does not mean every AI search journey ends inside Google, especially when the user must choose a high-commitment service.

    In a UX test involving 52 participants across the United States and Canada and nearly 22 hours of transactional searching, 69% of AI Mode sessions produced a website visit. Only 27% of participants felt ready to decide from the AI summary alone, while 4% moved to traditional Google Search and social media for more information.

    Those figures come from one bounded test of high-commitment services such as doctors and dentists. They should not be treated as a universal AI Mode click-through benchmark. They support a narrower and more useful conclusion: people still seek first-party evidence when the decision carries enough consequence.

    The competitive pattern also changed. In the same test, 89% of participants opened multiple businesses, the average was 3.7 results per session and only 10% considered a single business. AI Mode behaved less like a winner-takes-all ranking and more like a generated shortlist.

    That changes what you should optimize for. Being included among three to five credible options can matter more than treating the first visible mention as the only win. Your landing page then has to survive an active comparison against the other businesses Google presented.

    Do not assume that only content visible at the top of the AI response will be considered. Some 84% of participants scrolled. Once users interpreted the response as a curated set of options, they explored it.

    Social proof deserves particular attention for local services. Reviews were read by 74% of participants, while only 21% examined Google Business Profile photos. Even for Botox searches, photo use rose only to 24%. This does not make images unimportant in every market. It means that, within these service-selection tasks, written experiences helped more users reduce uncertainty.

    For a local or high-consideration business, work through the decision path in this order:

    1. Earn shortlist eligibility. Make the service, location, audience and relevant entity relationships unmistakable across the site and business profile.
    2. Strengthen legitimate social proof. Build a consistent process for requesting honest reviews, monitoring recurring concerns and responding appropriately. Do not manufacture reviews or use markup to imply evidence that users cannot see.
    3. Answer comparison questions on the landing page. State the scope of the service, qualifications, process, constraints and next step in language a prospective customer can verify.
    4. Inspect the whole AI response. Capture what appears below the first screen as well as what appears above it.
    5. Separate informational exposure from transactional opportunity. A summary that satisfies a how-to query and a shortlist that helps someone choose a provider create different traffic expectations.

    Build a playbook for content, entities and measurement

    A strategy team works around a tabletop of connected content cards, entity nodes, trust markers, test screens, and measurement gauges.

    Create content for both retrieval and verification

    An AI answer can mention you before the user visits you. That makes the first-party page a verification layer as well as a ranking asset. It must confirm the claim that brought the visitor there and supply the evidence the generated summary could not fully contain.

    Apply the following checks to each priority topic:

    • Give the page one primary job. Separate a direct explanation from a service-selection page when combining them would obscure both intentions. Link them so the user can move from learning to deciding.
    • Name the subject explicitly. Pronouns, slogans and clever headings are poor substitutes for the actual entity, service and location.
    • Put decisive facts in visible text. JSON-LD should reinforce those facts, not act as a hidden replacement for them.
    • Explain relationships. If a practitioner belongs to a clinic, a product belongs to a brand or a local branch belongs to a parent organization, represent that relationship consistently in copy, links and appropriate schema properties.
    • Preserve context around media. Because a search can begin with an image or file, use useful titles, captions, surrounding explanations and accessible alternative text that connect the asset to a named topic and next step.
    • Maintain status-sensitive details. Remove or correct expired availability, old policies and superseded claims so an ambient system does not retrieve information that no longer applies.

    Replace the single rank check with a repeatable scorecard

    Your measurement unit should be a task, surface and context combination. A broad prompt in AI Mode, a local transactional query and an image-led search should not be collapsed into one average position.

    SignalWhat to recordDecision it supports
    EntranceSearch, AI Mode, Chrome or upload flowWhich interfaces require separate testing
    IntentInformational or transactional taskWhether answer completion or a website visit is the realistic outcome
    Consideration-set presenceWhether your entity appears and which alternatives appear beside itWhere entity relevance or competitive proof is weak
    Evidence selectedClaims, pages, reviews or entity details surfaced by GoogleWhich information Google can retrieve and which evidence is missing
    Click opportunityWhether a usable link is shown and where it appears in the responseWhether visibility can produce a site visit
    Post-click outcomeLanding page reached and meaningful business action completedWhether AI visibility contributes to an actual result

    Use the same query wording, device conditions, location assumptions and account state when you want a controlled comparison. Then run a separate personalized observation when you want to understand variation. Mixing those two purposes makes every change look meaningful, even when the test conditions changed.

    Record the full response rather than only a headline position. Note follow-up prompts, cited pages, the order of businesses considered and the point at which a link becomes available. If personalized results vary, report the distribution of appearances across your observations instead of promoting one favorable screenshot as the result.

    Most importantly, do not average informational and transactional journeys into one AI visibility score. A citation inside an answer, inclusion in a provider shortlist, a qualified website visit and a completed conversion are different outcomes. Each should have its own field in your reporting.

    Key takeaways

    • Google AI visibility now depends on the entrance, input type, intent and context of the search session, not only a fixed results-page position.
    • Daily Hub points toward entity memory, user interests and timely orchestration, but its pause means it should not be treated as a live AI Mode ranking specification.
    • Transactional AI Mode users can still visit websites because a generated shortlist does not replace the evidence needed for a consequential decision.
    • For local services, consideration-set inclusion, credible reviews and a convincing landing page can matter more than obsessing over one first-place mention.
    • JSON-LD should clarify visible entities and relationships. It cannot guarantee selection, citations or personalized visibility.
    • Measure each task and interface separately, capture the complete response and connect AI exposure to post-click outcomes.

    Choose one valuable customer journey and run it through every relevant Google entrance. Capture the full consideration set, inspect the evidence Google selected, and repair the weakest link between entity recognition, user trust and the next action. That gives you an optimization program you can repeat even as the interface changes.

    References

  • How to Act When AI Search Evidence Contradicts Itself

    How to Act When AI Search Evidence Contradicts Itself

    You need to set a content plan, defend a traffic forecast, or explain why AI visibility and organic visits are moving in opposite directions. One dataset makes AI search look like a traffic problem. Another makes it look like a source of unusually valuable visitors. Choosing the more convenient story is tempting, but it can send your budget in the wrong direction.

    The useful question isn’t which claim wins. It is which evidence applies to your audience, your business model, your search surfaces, and the decision in front of you. Once you separate those variables, much of the apparent contradiction becomes measurable rather than mysterious.

    Translate every claim into a measurable outcome

    Claims such as “AI search is good for brands” or “AI Overviews reduce traffic” are too broad to guide a decision. They compress several different events into one conclusion:

    • Your page is eligible to appear for a query or prompt.
    • Your brand or page is mentioned, cited, or linked.
    • The user clicks through.
    • The visitor completes an on-site action.
    • That action produces business value.

    Those events form a chain, but they are not interchangeable. Citation visibility is not referral traffic. Referral traffic is not conversion. Conversion rate is not total conversions. Revenue is not profit. A claim about one link in the chain cannot establish what happened at every later link.

    Claim you want to evaluateEvidence you needWhat would not establish it
    AI results reduce click opportunityClicks divided by eligible impressions, separated by observed AI-result exposure and a comparable baselineA decline in total organic visits without query-level or exposure context
    Your brand is becoming more visible in AI answersBrand mentions or citations across a fixed, repeatable set of relevant promptsA few favorable screenshots or a changing prompt sample
    AI-referred visitors convert betterConversions divided by consistently classified AI-referral visits, using the same conversion definition as the comparison channelA high conversion rate with no session volume, source rules, or audience breakdown
    AI search creates more business valueTotal qualified outcomes or attributed value, measured with a consistent window and cost definitionMore citations, a higher conversion rate, or more visits considered in isolation

    This distinction resolves a common false conflict. AI exposure can coincide with fewer clicks while the smaller group of visitors who do click converts at a higher rate. That does not make AI search wholly beneficial or wholly harmful. It means traffic volume and visitor quality moved differently.

    Write the numerator and denominator beside every percentage you use. For clickthrough rate, that may be clicks divided by eligible impressions. For conversion rate, it is conversions divided by classified visits. For citation rate, it may be prompts containing a citation divided by eligible prompts in a fixed panel. If you cannot observe the denominator, report a count and state that coverage is unknown. Do not manufacture a rate from incomplete exposure data.

    Check whether the evidence belongs to your situation

    Colored evidence fragments pass through nested transparent filters while mismatched pieces remain outside the aligned frames.

    A result can be valid inside its sample and still be a poor forecast for your site. AI-search effects vary with intent, audience, industry, and business model. Those differences are not footnotes. They determine what success means and which behavior is visible in the data.

    Before carrying an external conclusion into a forecast or strategy deck, identify these boundaries:

    • Search surface: Was the observation about AI Overviews, a standalone assistant, an AI search mode, or all of them combined? A citation in a generated answer and a link in a conventional results page are different exposures.
    • Query or prompt intent: Separate requests for an explanation, comparison, recommendation, transaction, navigation, and support. A change concentrated in informational discovery should not automatically govern transactional pages.
    • Audience: Record market, language, device, customer type, and any other audience dimension that materially changes the journey. An aggregate can hide opposing movements between groups.
    • Business model: A publisher dependent on pageviews, an ecommerce store measuring orders, and a B2B company measuring qualified opportunities do not receive the same value from a click.
    • Outcome definition: Check whether “conversion” means a purchase, lead, registration, assisted action, or another event. Two conversion rates are incomparable when their underlying events differ.
    • Time window: Note the observation period and reporting cadence. Do not merge a one-time snapshot with continuous monitoring and treat both as equivalent evidence.
    • Method: Distinguish an observed association from a controlled comparison. The presence of an AI feature alongside lower clicks does not, by itself, prove that the feature caused the decline.
    • Coverage and exclusions: Look for omitted queries, zero-traffic pages, unclassified referrals, geographic limits, and minimum-volume rules. Each one can change the population represented by the result.

    Sample size belongs on this list, but it should not dominate it. A large dataset reduces some forms of random noise; it does not repair a mismatched audience, an unstable source classification, or the wrong outcome. Precision about the wrong population is still the wrong answer for your decision.

    Use a simple portability test: would the same user, surface, intent, action, and value definition exist in your business? If several answers are no, treat the finding as a hypothesis to investigate, not a benchmark to inherit.

    Build a site-level AI search evidence set

    You do not need a perfect attribution system before you can make a better decision. You do need fixed definitions, repeatable observations, and a record of what remains unknown. The following workflow creates a minimum viable evidence set without pretending that every AI interaction is traceable.

    1. State the decision in one sentence. Use a question such as, “Should we change this informational page group to improve qualified visits from queries where AI Overviews appear?” A decision tied to one surface, page group, and outcome is testable. “What is AI doing to SEO?” is not.
    2. Create a metric dictionary. Define an impression, AI exposure, mention, citation, linked citation, AI-referred visit, conversion, qualified conversion, and attributed value. Record the formula and data owner for each metric. Keep these definitions unchanged across comparison periods.
    3. Separate visibility from traffic classification. A brand mention without a link is visibility, not a session. A visit carrying an assistant referrer is traffic, but it does not prove that your brand was cited in the answer the visitor saw. Store these as separate observations.
    4. Build a fixed query and prompt panel. Select prompts that represent actual stages of your audience’s journey. Label each one by intent, topic, audience, and target page. Avoid adding favorable prompts midway through a reporting period; create a new panel version when the set changes.
    5. Log each observation consistently. Capture the surface, query or prompt, observation date, market or language when relevant, whether your brand appeared, whether a citation appeared, the cited URL, and the position or context of the mention. Record “not observed” separately from “not checked.”
    6. Connect downstream outcomes. For the same page and audience groups, monitor conventional search impressions and clicks, classified AI referrals, conversions, qualified outcomes, and attributed value where available. Keep unknown or unclassified traffic in its own bucket instead of assigning it to AI by assumption.
    7. Segment before you aggregate. Inspect results by intent, page type, market, audience, and business outcome before producing a sitewide number. If two segments move in opposite directions, preserve that difference in the conclusion.
    8. Maintain a change log. Record content updates, template changes, tracking changes, campaigns, and other interventions that could alter the same metrics. A movement that begins after several simultaneous changes cannot safely be credited to one of them.

    Read combinations of metrics as diagnostic signals, not instant verdicts:

    • Citations rise while clicks fall: inspect the affected intent and the value offered after the click. An answer may be satisfying part of the need before the visit, but the pattern alone does not prove that mechanism.
    • AI referrals rise while conversion rate falls: check referral classification, landing-page mix, audience mix, and conversion definitions before changing content.
    • Conversion rate rises while total conversions stay flat or fall: report improved rate and weak or declining volume separately. The channel has not produced more total value merely because its percentage improved.
    • Mentions rise without linked citations or referrals: you have evidence of visibility, not evidence of site traffic or commercial impact. Decide whether visibility itself serves a defined brand objective.
    • Aggregate performance looks stable while segments diverge: act at the segment level. A sitewide average can conceal both a genuine loss and a genuine opportunity.

    Do not force every observation into a single AI score. A composite number hides the very disagreements you need to diagnose. Keep exposure, citation, traffic, conversion, and value visible as a sequence.

    Use a decision rule instead of waiting for certainty

    A strategist faces a branching path controlled by transparent threshold chambers filled with blue and amber particles.

    Complete certainty is not a realistic prerequisite for action in a changing search environment. That does not justify acting on the loudest claim. It means matching the strength of the action to the strength and relevance of the evidence.

    For a site-specific decision, use this evidence order:

    1. Your correctly measured business outcome for the relevant cohort. This is closest to the decision, provided the classification and conversion definitions are sound.
    2. Your repeatable observations of the search surfaces that audience uses. These show whether exposure, mentions, and citations are actually changing for your target prompts.
    3. External evidence that matches your surface, intent, audience, business model, and metric. This can strengthen or challenge your working explanation.
    4. Broad industry averages and headline claims. These are useful for discovering questions, but weak as direct forecasts for an individual site.

    Your own data does not automatically win. Broken attribution, changing definitions, and sparse coverage can make first-party numbers misleading. The hierarchy assumes you have tested those weaknesses. When your measurement cannot answer the question, label the gap instead of filling it with an industry average.

    Then choose the action that fits the pattern:

    • Relevant external evidence and your own outcomes point in the same direction: run a contained, reversible change on the affected page or query group and continue measuring the full outcome chain.
    • An external warning has no matching local signal: keep monitoring, but do not rewrite an entire content program to solve an unobserved problem.
    • Your local data shows a material segment-level effect without broad external agreement: respond to the local effect. Your audience does not need an industry consensus before its behavior matters.
    • Your own metrics conflict: inspect denominators, attribution, cohort mix, and funnel stages before choosing a narrative. The conflict is diagnostic information.
    • No direction remains stable: improve instrumentation and favor low-cost tests over broad changes. Uncertainty should reduce the size of the bet, not disappear from the report.

    Keep traditional rankings and AI citations as separate measures unless your own evidence establishes a dependable relationship between them. A page can retain conventional visibility without earning citations, or receive mentions without meaningful referral traffic. Replacing one metric with the other prematurely creates a new blind spot.

    When you test a content change, define one primary outcome and the metrics that must not deteriorate. Change one meaningful element for a clearly identified page group, preserve a comparison group when feasible, and record the decision rule before viewing the result. That prevents a favorable secondary metric from replacing the outcome the test was meant to improve.

    Key takeaways

    • Conflicting AI-search claims may measure different stages: exposure, citation, click, conversion, or business value.
    • Never compare percentages until you know their numerators, denominators, cohorts, and outcome definitions.
    • Match evidence to your search surface, intent, audience, business model, time window, and method before applying it.
    • Track AI visibility, linked citations, referrals, conversions, and value separately rather than collapsing them into one score.
    • Let uncertainty control the size and reversibility of your action. It should not be hidden behind a confident average.

    At your next reporting cycle, take the most consequential AI-search claim in your plan and write down its metric, denominator, cohort, surface, and decision. If any field is missing, instrument that gap before committing more budget or changing a large body of content. A narrow answer that fits your audience is more useful than a universal answer built from someone else’s mix of users.

    References