Tag: AI Search

  • How Food Publishers Can Adapt to AI Search Disruption

    How Food Publishers Can Adapt to AI Search Disruption

    If a holiday recipe still ranks but sends fewer people to your site, you may not be dealing with an ordinary SEO decline. The search result itself may now provide the ingredients, summarize the method, combine advice from several creators, and leave the reader with little reason to click.

    Publishing more recipes won’t solve that problem by itself. You need to make each recipe easier to interpret accurately, harder to replace with a compressed answer, and more valuable after the click. You also need measurements that distinguish rankings, AI citations, answer accuracy, traffic, and revenue instead of treating them as the same outcome.

    AI search has changed what a ranking is worth

    The familiar search journey moved a reader from a query to a results page and then to a publisher. An AI answer can interrupt that journey. It may resolve the immediate question before the reader encounters your testing notes, photographs, troubleshooting advice, newsletter offer, ads, or affiliate links.

    This creates several separate risks for food publishers:

    • Answer interception: The generated response satisfies a simple request without requiring a visit.
    • Source dilution: Instructions from different publishers can be blended into one method, weakening the connection between the recipe and the person who developed it.
    • Instruction degradation: A shortened or rearranged method can separate a warning from the step where it matters. Documented examples include an AI answer that would have led a reader to over-bake a cake.
    • Asset extraction: Original food photography can appear in generated visual experiences without delivering the same recognition or value as a visit to the originating page.
    • Imitation pressure: AI-operated sites can reproduce the shape of a successful recipe, alter some details, and compete with the creator whose work supplied the idea.

    The commercial effect can be severe, but it shouldn’t be turned into a universal benchmark. Reported creator declines range from 30% to 80%, with individual accounts including a 40% traffic loss and a 30% decline in cocktail click-through rate. Those are experiences from affected publishers, not a measurement of every food site.

    Key takeaways

    • A ranking is no longer the complete outcome. Track whether an AI answer appears, whether you are cited, whether the citation is linked, and whether anyone visits.
    • Recipe clarity matters twice: it helps readers complete the method, and it reduces the chance that a generated answer disconnects a condition from an instruction.
    • Structured data improves interpretation, but it cannot make a commodity answer click-worthy or prove that a recipe is original.
    • Your strongest defense is source value: real testing evidence, sensory endpoints, constrained substitutions, troubleshooting, recognizable authorship, and useful original media.
    • Protect the business separately from the ranking by creating direct audience relationships and measuring revenue per useful visit.

    Start your response with triage, not a site-wide rewrite. Classify recipe groups by commercial exposure, ease of summarization, consequence of distorted instructions, and strength of original evidence. A seasonal page that generates meaningful revenue, answers a compact question, and offers little beyond the basic method deserves attention before an evergreen recipe with strong branded demand and extensive troubleshooting.

    Make each recipe legible without making it disposable
    An overhead arrangement shows a finished vegetable tart surrounded by ingredients, preparation stages, tools, and test slices.

    Food publishers face an awkward design problem. A vague recipe is difficult for people and machines to interpret, but a page that contains nothing beyond a clean ingredient list and short method is easy to compress into an answer. The solution isn’t to obscure the recipe. It is to separate the recipe’s authoritative path from the evidence and decision support that make the page indispensable.

    Establish one recipe truth set

    Every representation of the recipe should agree: the visible recipe card, surrounding instructions, print view, video, image captions, internal summaries, and Recipe JSON-LD. Contradictory timings, ingredient forms, quantities, or sequencing give an answer system several plausible versions to combine.

    For each important recipe, check the following fields against one authoritative version:

    • The recipe name and the specific variation being prepared.
    • Yield and portion assumptions.
    • Ingredient quantities, preparation state, and meaningful alternatives.
    • Equipment or vessel requirements that affect the result.
    • Preparation, cooking, resting, cooling, and total timing where those distinctions matter.
    • The order of operations and dependencies between steps.
    • Observable doneness cues rather than time alone.
    • Storage, reheating, and make-ahead instructions.
    • Warnings, allergen information, and substitution limits that affect safety or outcome.

    Recipe JSON-LD should describe the visible recipe faithfully. Don’t use markup as a second, keyword-expanded version of the page, and don’t add claims that a reader cannot verify in the content. Validate the syntax, but also perform a semantic check: the markup can be technically valid while describing a different yield, duration, or instruction order.

    Structured data is an interpretation layer, not a defensive moat. It can help a system identify ingredients, instructions, images, authorship, and other recipe entities. It cannot guarantee a citation, compel a click, establish ownership, or preserve every caveat in a generated answer.

    Write steps that survive separation

    A generated answer may extract a step without carrying over the paragraph before it. Write each critical instruction so its condition travels with it. A useful pattern is: action, relevant setting or tool, observable endpoint, exception, and recovery.

    For example, don’t place an important exception in a general note and assume the reader will connect it to the method. Put it next to the affected step, then repeat it in the notes when repetition prevents a bad outcome. If a substitution, storage instruction, allergen warning, or doneness cue has safety implications, it belongs at the point of action. A summary’s brevity is not a safe place to entrust that connection.

    Use time as one signal rather than the whole definition of success. Texture, color, volume, aroma, resistance, and appearance can tell a cook what state the food should reach. Include only the cues you have genuinely verified. Their purpose is to help a person make the right decision in a different kitchen, not to decorate the prose.

    Give readers a reason to need the original source

    An AI answer is strongest when the request can be reduced to a short list and a linear sequence. Your page becomes harder to replace when it helps the reader diagnose, choose, adapt, and recover. That value must be concrete. A longer personal introduction doesn’t create defensibility if it never changes what the reader can do.

    Add source value where it is true and useful:

    • Testing context: State what was actually tested, which variables changed, and what remained constant. Don’t claim a recipe was extensively tested unless you can support that claim.
    • Sensory checkpoints: Show the meaningful transition at a stage, not merely another attractive photograph of the finished dish.
    • Failure diagnosis: Connect a visible symptom to likely causes, the immediate recovery, and the change to make next time.
    • Constrained substitutions: Explain what function an ingredient serves, which replacement can perform it, and what tradeoff the reader should expect. A replacement isn’t automatically equivalent.
    • Decision branches: Distinguish what changes with equipment, batch size, preparation schedule, or desired result.
    • Revision history: Record substantive corrections and retests. A transparent update is more useful than silently changing the instruction that returning readers saved.
    • Recognizable authorship: Use consistent bylines, complete author pages, and clear editorial responsibility. Readers should be able to identify who stands behind the method.

    Place this information where it is needed. A troubleshooting section is valuable, but the most consequential warning should also appear beside the relevant step. A process photo should be attached to a stage and captioned with the change the reader needs to see. A testing note should explain a decision, not simply assert expertise.

    Treat original images as evidence as well as media

    Original photography now does more than attract a click. It can demonstrate process, establish continuity between author and recipe, and help readers verify an endpoint. It can also be reused outside the page: Gemini 3 has been observed using publisher photographs in interactive graphics, while AI-run sites have mirrored recipes and altered personal images.

    Keep original files, creation records, licenses, commissioned-work agreements, and dated publication records organized. Apply consistent, unobtrusive branding where it doesn’t interfere with the reader’s ability to inspect the food. Use descriptive captions and alt text for accessibility and context, not as a place to repeat keywords.

    No watermark, metadata field, schema property, or technical setting can prevent every form of copying. The operational goal is to make attribution obvious, preserve evidence of creation, and detect material reuse early. If you are considering a formal infringement claim, preserve the relevant pages and records before making changes and obtain appropriate legal advice for the jurisdiction involved.

    Build an audience path that an answer box cannot own
    A home cook uses a phone in a warm kitchen where a glowing path connects the device to a recipe box, cookbook, produce, speaker, and prepared dish.

    Search optimization still matters, but a business that depends on a platform sending every informational click is exposed to product changes it cannot control. Food publishers need both discoverability and a reason for the audience to return directly.

    Match your investment to the query’s real value

    Group queries by what the cook is trying to accomplish:

    • Lookup intent: The reader wants a compact fact, ingredient, time, ratio, or basic method. These queries are especially easy to satisfy in a generated response.
    • Decision intent: The reader must choose among methods, ingredients, schedules, or equipment under a constraint.
    • Execution intent: The reader needs sequencing, visual confirmation, troubleshooting, or help recovering during the cook.
    • Trust intent: The reader is looking for a particular creator, named recipe, known method, or previously successful result.

    Don’t abandon lookup content. It can introduce the brand, earn visibility, and support a broader recipe cluster. But don’t value its rankings as if every impression should become a session. Connect the concise answer to a genuinely useful next decision: choosing a method, planning the meal, avoiding a known failure, adapting the recipe, or coordinating the cooking sequence.

    Build named collections and navigable hubs around a real cooking task rather than assembling loosely related pages for search coverage. A holiday hub might connect planning, preparation order, core recipes, variations, storage, and troubleshooting. The hub should reduce work for the cook; its value isn’t the number of internal links.

    Convert a useful visit into a direct relationship

    Give each commercially important page a clear primary next step. Depending on the reader’s task, that might be saving the recipe, printing a usable version, joining an email sequence for the relevant season, following a coordinated meal plan, or moving to the next preparation stage. Avoid surrounding the reader with unrelated prompts that compete with the recipe.

    The direct asset must be worth keeping. A generic newsletter promise is weak beside a specific utility such as a sequenced preparation plan, an organized shopping list, a tested make-ahead path, or updates to recipes the reader has saved. Only promise what you can maintain.

    Diversification also applies to discovery platforms. AI-generated material is already adding noise to Pinterest and Etsy, so distributing the same asset across more platforms doesn’t necessarily reduce dependency. Separate borrowed reach from owned access. Search, social feeds, and marketplaces can introduce you; email lists, bookmarks, saved collections, and branded demand make it easier for the reader to come back.

    Run an AI search audit that connects visibility to revenue

    A conventional rank report cannot tell you whether an AI answer intercepted the click, credited the wrong source, merged incompatible instructions, or used an image without sending a visit. Add an answer-layer audit to your existing search and analytics process.

    1. Freeze a baseline. Record organic landing sessions, query impressions, click-through rate, engaged visits, conversions, and page-level revenue before editing priority content. Preserve comparable seasonal periods where the business depends on holiday demand.
    2. Build prompts from demonstrated demand. Start with queries that already generate impressions or valuable visits. Expand them into direct requests, constraint-based questions, troubleshooting questions, follow-ups, and brand-qualified prompts.
    3. Observe the actual answer surface. Record the exact prompt, date, search interface, device context, location context, and signed-in state. Generated results can vary, so a screenshot without its conditions is weak evidence.
    4. Separate mention, citation, link, and click. A brand name in an answer is not the same as a citation. A citation is not necessarily a usable link. A link is not a visit. Track each state independently.
    5. Review instruction fidelity. Check ingredient forms, quantities, ordering, dependencies, substitutions, timing, endpoints, warnings, and image attribution against your authoritative recipe. Label the answer as accurate, incomplete, mixed, or materially unsafe rather than giving it a vague quality score.
    6. Connect the observation to business results. Compare answer presence with organic clicks, landing sessions, return behavior, subscriptions, and revenue. Don’t attribute every decline to AI when seasonality, rankings, demand, site changes, or result-page features could also explain it.
    7. Change one class of problem at a time. Correct conflicting recipe facts before adding more content. Improve source value before redesigning every call to action. Keeping interventions distinct makes the next observation more informative.

    A compact decision table keeps the audit actionable:

    Observed stateLikely problemNext action
    Cited accurately and receiving visitsThe source is visible and still adds valueProtect accuracy, strengthen the reader’s next step, and monitor important prompts
    Cited accurately but receiving few visitsThe generated answer may satisfy the immediate needAdd decision support the answer cannot carry and improve the value promised by the result
    Mentioned without a clear linkRecognition exists without a reliable traffic pathStrengthen consistent brand and author entities, then measure branded demand separately
    Cited with mixed or incorrect instructionsThe system may be compressing, separating, or combining recipe detailsRemove internal contradictions, attach conditions to steps, and clarify the authoritative method
    Absent while competitors are citedThe page may lack relevance, clarity, authority signals, or distinctive evidenceCompare the answered intent with your coverage and improve the underlying page where a genuine gap exists
    Images reused without useful attributionAsset visibility isn’t creating source valuePreserve evidence, review branding and captions, document reuse, and assess the appropriate rights response

    Keep AI visibility and commercial performance beside each other in the same working view. Useful fields include recipe cluster, query or prompt, answer type, citation state, link state, instruction fidelity, image use, organic click-through rate, landing sessions, subscriber conversion, and revenue. The point isn’t to invent one blended score. It is to see where visibility stops turning into business value.

    Before the next important seasonal window, choose a revenue-critical recipe cluster and preserve its baseline. Reconcile the recipe truth set, validate the visible content against its JSON-LD, add the missing evidence and troubleshooting, define the page’s primary conversion, and begin a repeatable prompt audit. Then apply what you learn to the next cluster. That gives you a controlled publishing system instead of a rushed reaction to every new AI result.
    References

  • How to Build AI Search Visibility With a Practical GEO System

    How to Build AI Search Visibility With a Practical GEO System

    You can rank for important Google queries and still disappear when a buyer asks ChatGPT, Claude, Gemini, or Perplexity to explain the market. The generated answer may frame the decision before that buyer has any reason to visit your website.

    The fix is not to publish more content and hope an AI notices. You need a repeatable GEO system that shows where your brand is absent, how it is portrayed, which competitors occupy the answer, and which URLs support the response. Then you can make a targeted change and measure the same question again.

    Build your prompt map around buyer decisions

    An overhead branching pathway links blank content cards with symbolic objects for comparison, research, solutions, risk, and purchase decisions.

    A conventional keyword tells you what someone searched. A useful GEO prompt also captures the decision they are trying to make, the constraints they care about, and the kind of answer they expect. That context determines whether your brand is even eligible to appear.

    Monitoring only questions that contain your brand name creates a reassuring but misleading baseline. Someone who asks whether your product supports a feature already knows you. The more important visibility gap often appears earlier, when that person asks which category, method, or provider can solve the problem.

    Build the prompt map from the real stages of a decision:

    • Category education: What is this type of solution, and when is it appropriate?
    • Problem diagnosis: What causes the issue, and which approaches address it?
    • Solution discovery: Which products, services, or methods fit a stated use case?
    • Evaluation: How should someone compare the available options?
    • Objections: What are the costs, risks, limitations, implementation demands, or prerequisites?
    • Brand validation: Is a named provider suitable for a particular audience or requirement?
    • Visual discovery: What is the item in an uploaded image, and which comparable products meet the user’s constraints?

    Before collecting answers, decide which brands could reasonably appear in each prompt. If a question asks for a general definition and does not call for examples, your absence is not automatically a visibility failure. This eligibility rule keeps the mention metric honest.

    Keep a prompt register rather than a loose list of interesting questions. For every check, record:

    • The exact prompt wording and the intent it represents.
    • The platform and model label displayed in the interface.
    • Relevant settings, location, language, or signed-in state.
    • The date of the response.
    • Whether your brand appeared and what role it played.
    • The exact descriptors and qualifications attached to the brand.
    • Which competitors appeared and how they were positioned.
    • Every cited URL, or an explicit note that the answer supplied no citations.

    Preserve the original wording as your benchmark. Add realistic variants as separate prompts instead of silently editing the baseline. Generated answers can vary, so a single response is a diagnostic observation, not a final verdict. Repeated patterns across the same decision set are more useful than an isolated win or loss.

    Turn four AI visibility signals into editorial decisions

    Four symbolic signal objects connect a modular content asset to a refinement station in a continuous circular feedback loop.

    Brand inclusion, framing, competitive presence, and cited URLs answer different questions. Combining them into a single visibility score may look tidy, but it hides the reason you are winning or losing. Keep the signals separate until you know which intervention each one requires.

    Mentions reveal where you are missing from the journey

    Track presence only across prompts where your brand is a plausible answer. Record the role as well as the mention: recommended option, specialist alternative, example, comparison point, warning, or incidental reference. A brand included only as an afterthought does not have the same visibility as one used to define the category.

    The location of the gap tells you what to build. Sparse mentions in educational questions point toward category definitions, original explanations, and authoritative problem-solving material. Absence from solution-selection questions points toward clearer use-case pages, differentiators, comparison criteria, and evidence of fit. Do not respond to every missing mention with another generic blog entry.

    Framing tells you which narrative needs evidence

    Do not reduce an entire answer to positive, neutral, or negative. Capture the actual adjectives, qualifiers, recommended audiences, and stated limitations. A brand can be praised for capability while simultaneously being framed as difficult to adopt. That mixed description is more actionable than a positive sentiment label.

    Match the response to the narrative. If cost repeatedly dominates the description, publish transparent value evidence, pricing context, or an ROI framework that explains when the expense is justified. If complexity dominates, improve onboarding material, implementation diagrams, migration instructions, and realistic prerequisite information. If trust or reliability recurs, reinforce that claim with verifiable proof rather than repeating the adjective in marketing copy.

    Competitive presence shows which prompts deserve priority

    Compare brands only within the same eligible prompt set. Then note whether a competitor is the default recommendation, a niche choice, a cited authority, or merely part of a long list. Raw mention totals can conceal those differences.

    Create a gap queue from prompts where credible competitors recur and your brand does not. Prioritize by the importance of the buyer decision, not by how irritating the result feels. Inspect what the recurring competitor contributes: a clear category definition, a defensible comparison, an original data asset, a detailed implementation resource, or stronger third-party corroboration. Your task is to answer the unmet information need, not imitate the competitor’s wording.

    Cited URLs show which material carries the answer

    A mention and an attribution are different outcomes. Log the exact URL, domain, page type, and claim each citation appears to support. Also distinguish your own page from an independent page that discusses your brand. You control the former directly and can only influence the latter through accurate information, public evidence, and distribution.

    When a competitor’s report, whitepaper, or explainer repeatedly supports an answer, inspect why that asset is usable. It may state the question clearly, expose its method, define terms precisely, present original evidence, or organize the material in extractable sections. Build the missing evidence on its own merits. A longer page is not automatically a more authoritative one.

    Build an answer asset instead of another generic page

    Every priority prompt should map to a clear primary URL. Several related prompts can belong on the same page, but the reader and the machine should not have to choose among near-duplicate pages to find your definitive answer.

    1. Assign the question to a primary page. Improve an appropriate existing URL before creating a competing version.
    2. Answer the core question near the beginning. State the conclusion, then explain the conditions and reasoning behind it.
    3. Name the entities and relationships explicitly. Identify the product, company, category, audience, use case, and limitation instead of relying on slogans or implied context.
    4. Attach evidence to the claim it supports. Include methodology, examples, comparison criteria, prerequisites, dates where they matter, and honest boundaries.
    5. Use descriptive headings, short explanatory paragraphs, genuine lists, and real tables where the information is tabular. Structure should reflect meaning, not merely break up text.
    6. Add JSON-LD that accurately describes the visible page and its entities. Structured data should confirm the content; it cannot turn an unsupported marketing claim into a fact.
    7. Connect the page to the rest of your site through relevant category, product, documentation, author, and company pages. Consistent names and relationships reduce ambiguity.

    The appropriate format depends on the diagnosed gap:

    • For an educational gap, create a precise explainer, glossary entry, or category definition with examples and boundaries.
    • For a solution-discovery gap, create a use-case page that names the problem, audience, requirements, and situations where the offering is not suitable.
    • For an evaluation gap, publish neutral comparison criteria before arguing that your option performs well against them.
    • For a perception gap, add the missing proof: onboarding instructions, implementation requirements, pricing context, case evidence, or a clear account of limitations.
    • For a citation gap, invest in material worth referencing, such as an original methodology, transparent analysis, detailed technical documentation, or a definitive first-party explanation.

    Avoid FAQ sections assembled only to capture prompt variations. Keep a question when it solves a distinct user problem and supply a complete answer. Near-identical questions with thin replies create more URLs or sections without creating more knowledge.

    Give every important claim one preferred URL

    Generative visibility work becomes fragile when the same claim exists at several addresses with conflicting titles, dates, product names, or specifications. Canonicalization helps search systems consolidate duplicate versions and identify the preferred origin. It does not guarantee an AI citation, but it removes avoidable uncertainty about which page represents you.

    Audit each priority answer asset for the following:

    • The preferred URL resolves correctly and is eligible for indexing.
    • The page carries a self-referencing canonical when it is the preferred version.
    • HTTP and HTTPS, www and non-www, trailing-slash variations, and parameterized duplicates consistently resolve or canonicalize to the intended URL.
    • Internal links and XML sitemaps use the same preferred address rather than feeding mixed signals.
    • Cross-domain copies identify the original where the publishing arrangement allows it.
    • Product variants, filtered category pages, faceted navigation, and pagination follow deliberate rules rather than CMS defaults that nobody has reviewed.
    • Google Search Console and a crawler such as Screaming Frog are used to find declared canonicals, selected canonicals, redirect conflicts, and duplicate clusters.

    Canonical tags are source-control signals, not a substitute for a coherent content model. If several live pages make materially different claims, pointing them all at one canonical does not repair the inconsistency. Decide which version is correct, update the public pages that still matter, and retire obsolete material through an intentional migration.

    Be careful when changing canonicals, redirects, or large groups of product URLs. A broad rule can suppress a valid variation, break an integration, or send authority to the wrong page. Review traffic, backlinks, feed requirements, and platform dependencies first; stage the rule where possible; then crawl the affected templates before deploying it widely.

    Treat visual assets as searchable product information

    Text optimization is only part of GEO for ecommerce and visually selected products. Multimodal systems can interpret objects, embedded words, style, context, and likely use cases. That makes product images and packaging part of the machine-readable information layer, not decoration added after the product page is finished.

    Use a visual-readiness checklist:

    • Show the real product at useful resolution from multiple angles, including scale cues, color, construction details, labels, openings, controls, pockets, stitching, or other decision-critical features.
    • Use original photography when the image is evidence of appearance, packaging, authenticity, or condition. A generated approximation should not stand in for factual product proof.
    • Keep critical packaging text high contrast. Clean sans-serif type on a solid background is easier to read than script type laid over a pattern.
    • Avoid placing required information where glare, glossy material, folds, curves, or creases make optical character recognition unreliable.
    • Run a grayscale check. If hierarchy and legibility disappear without color, the design is too dependent on color contrast.
    • Provide a QR code when the physical package needs a direct route to a canonical HTML page containing complete, structured product information.
    • Make the product name, model, variant, and image relationship explicit on the web page. Do not force a system to infer which nearby caption belongs to which asset.

    The surrounding objects matter too. Props, rooms, clothing, people, adjacent products, and photographic style can imply luxury, utility, sport, age, or intended audience. Those associations may conflict with the position stated in your copy.

    Run a co-occurrence audit on official product and lifestyle images. Ask a multimodal system to identify every visible object, infer likely use cases, and describe the apparent owner or audience. Compare those outputs with your intended positioning. Record unexpected associations, then turn the findings into concrete creative rules for backgrounds, props, wardrobe, image crops, and prohibited adjacencies.

    Extend the audit beyond current campaign files. Old product photography, public archives, distributor listings, user images, and social posts can preserve a discontinued visual identity. You may not control every external image, but you can update the assets you own, make current product imagery easier to identify, and stop distributing obsolete files.

    Close the GEO loop without creating a vanity dashboard

    You do not need a universal AI visibility platform to begin. A disciplined spreadsheet can connect prompts, responses, URLs, interventions, and outcomes. The important part is preserving enough context to explain why a metric moved.

    1. Capture a baseline across the stable prompt register.
    2. Choose a gap with meaningful buyer intent and a recurring pattern.
    3. Diagnose whether it is primarily an inclusion, framing, competitive, citation, technical, or visual problem.
    4. Make the smallest change that directly addresses that diagnosis.
    5. Log the affected URL, the change, the expected signal, and the deployment date.
    6. Recheck the same prompt set under comparable conditions after the changed material is available to search systems.
    7. Keep, revise, or reverse the intervention based on the observed pattern and any downstream business evidence.

    Separate visibility outputs from business outcomes. Mentions, framing, competitive presence, and citations tell you whether the generated answer changed. Qualified visits, inquiries, assisted conversions, and customer-reported discovery tell you whether that visibility mattered. Where analytics cannot prove a causal connection, label the relationship as an observation rather than assigning revenue to an AI mention.

    Do not change several content, schema, canonical, and visual elements at once unless a serious defect requires it. A broad redesign may improve the result, but it will teach you very little about which signal mattered. Controlled changes build a reusable operating model.

    Key takeaways

    • GEO is the work of improving accurate inclusion, framing, competitive position, and attribution in generated answers.
    • Measure visibility at the prompt and buyer-decision level, not through brand-name questions alone.
    • Use mentions, descriptors, competitive presence, and cited URLs as separate diagnostics with different remedies.
    • Map each priority question to a clear, evidence-rich primary page supported by accurate JSON-LD and consistent internal relationships.
    • Remove canonical ambiguity and make images, packaging, labels, and visual context legible to multimodal systems.
    • Recheck stable prompts after each intervention, while keeping AI visibility signals separate from business attribution.

    Start with the highest-value decision prompt where credible competitors recur and you do not. Assign its preferred URL, identify the most visible gap, make a targeted repair, and log what changed. That small closed loop will give you more strategic information than a large dashboard full of unexplained mention counts.

    References

  • How to Build AI Search Visibility With a Practical GEO System

    How to Build AI Search Visibility With a Practical GEO System

    If your pages rank but your brand disappears when a buyer asks an AI assistant for options, you do not have a conventional ranking problem. You have a retrieval and representation problem.

    Generative engine optimization, or GEO, addresses that gap. The goal is to make your expertise easy for AI systems to find, extract, verify, attribute, and present accurately. That requires more than adding schema or rewriting a few introductions. You need a connected system for content, entities, citations, visuals, and measurement.

    Define the visibility outcome before you optimize

    A traditional SEO program often treats the ranked page as the primary outcome. GEO adds another outcome: selection inside a generated answer. Your brand might be named, used as supporting evidence, linked as a citation, represented through an image, or omitted entirely even when your page ranks.

    This is happening because search can summarize information before a click, support comparisons inside AI tools, and move product discovery beyond a conventional results page. SEO, PPC, and AI visibility therefore solve different parts of the same discovery problem.

    Visibility layerPrimary jobWhat to measureFirst practical move
    SEOMake pages discoverable, relevant, and authoritative in searchQualified impressions, rankings, clicks, and conversionsResolve crawl, intent, content, and authority weaknesses
    PPCBuy controlled placement where advertising is availableImpression share, acquisition cost, and conversionsUse paid coverage for immediate or commercially important demand
    AI discoveryGet facts, entities, and recommendations selected for generated answersMentions, citations, representation accuracy, and cited competitorsBuild a prompt set and establish a repeatable baseline

    Do not collapse these layers into one metric. A paid placement does not prove that an AI system regards your site as an organic reference. A brand mention without a link is not the same as a citation. A citation is not automatically a qualified visit. Each result tells you something different.

    Key takeaways

    • GEO extends SEO; it does not replace the technical, content, and authority foundations that make information discoverable.
    • Optimize individual claims and answer passages, not only whole pages or target keywords.
    • Make your brand, authors, products, and claims consistent across visible content, structured data, and credible external mentions.
    • Measure mentions, citations, accuracy, competitor inclusion, and business outcomes separately.
    • Treat images as retrievable assets because AI search can select visuals as well as text.

    Build answer passages that can stand on their own

    A complete content module passes through a retrieval prism and emerges intact in an AI answer surface.

    An AI system rarely needs every sentence on a page. It needs a passage that resolves the user’s question and enough surrounding context to use that passage correctly. Long introductions, vague claims, and answers scattered across several sections make that job harder.

    A strong GEO passage starts with a direct answer in two or three short sentences, then adds the qualifications, evidence, method, and next action. Concise answers followed by layered context, lists, clear logic, and genuine depth give retrieval systems both a usable summary and the detail needed to support it.

    Use this sequence on pages that address an important customer decision:

    1. Name the exact question. Use a descriptive heading that matches the decision, such as who a service is for, how two approaches differ, or what a buyer should check before choosing.
    2. Answer immediately. State the conclusion before background or brand positioning. If the correct answer depends on conditions, name those conditions in the opening answer.
    3. Explain the mechanism. Show why the answer is true, what changes it, and where a simplified answer would fail.
    4. Add verifiable support. Connect the claim to a method, named author, relevant date, comparison, definition, or other evidence that a reader can inspect.
    5. Use the right structure. Put sequences in ordered lists, criteria in bullets, and real comparisons in tables. Do not turn ordinary prose into a table merely to look structured.
    6. End with the decision. Tell the reader what to choose, check, calculate, or do next.

    Make each important passage self-contained. A sentence such as “This is the best option for them” loses its meaning when extracted. Name the option, audience, and condition instead. The result may sound slightly more explicit to a human reader, but it is also clearer.

    Do not manufacture dozens of near-identical pages for every prompt variation. Build one authoritative page around a coherent decision, then give its distinct subquestions clear headings and direct answers. This preserves topical depth without creating a site full of interchangeable fragments.

    Make every important entity consistent and verifiable

    AI visibility depends partly on whether a system can resolve who made a claim and what that person or organization represents. If your About page uses one brand description, author pages use another, and structured data introduces a third version, you create avoidable ambiguity.

    About pages, author biographies, structured markup, and other trust signals help establish the entities behind content. Treat these elements as one evidence set rather than unrelated publishing tasks.

    Audit the following for each commercially important topic:

    • Organization identity: Use the same official name, preferred description, canonical URL, logo, and relevant external profiles wherever they appear.
    • Author identity: Give the author a stable name, role, affiliation, biography, and page that demonstrates why the person is qualified to cover the subject.
    • Offering identity: Keep product or service names, categories, availability, and defining characteristics consistent across landing pages, supporting content, and markup.
    • Page identity: Align the visible headline, author, publication date, substantive modification date, and canonical page with the values supplied in structured data.
    • Relationship clarity: Make it clear which organization publishes the content, which person wrote or reviewed it, and which product, service, place, or concept the page discusses.

    JSON-LD is useful here, but it is not a substitute for visible evidence. Organization, Person, Article, Product, and applicable local-business types can describe relationships explicitly. They cannot make an unsupported claim authoritative, reconcile contradictory facts, or turn a thin page into a reliable reference.

    Freshness needs the same discipline. Update a page when its answer, evidence, comparison, or recommendation has materially changed. Keep the original publication date and provide an accurate modification date where appropriate. Changing a timestamp without improving the content gives readers no new value and weakens the meaning of your freshness signal.

    Close citation gaps, not just keyword gaps

    A keyword gap tells you what competitors rank for. A citation gap tells you which external sources an AI system uses to support an answer when it does not use you. The second gap matters because a well-optimized page can still lose selection to a source with a clearer claim, stronger evidence, or better third-party corroboration.

    Start with the prompts that influence an actual decision. Run them in the AI experiences your audience uses, then record every cited domain and the claim each citation supports. Do not merely count competitor appearances. Ask why each cited page was useful.

    • Did it provide a direct definition that your page leaves implicit?
    • Did it publish a comparison with explicit criteria?
    • Did it show a method, date, author, or limitation that made the claim easier to verify?
    • Did a trusted third party corroborate the brand or idea?
    • Did it answer a narrower question more precisely than your broader page?
    • Was it materially fresher for a query whose answer changes over time?

    Turn those observations into an evidence plan. If the gap is definitional, publish the clearest defensible definition you can support. If the gap is comparative, state the selection criteria and explain where each option fits. If the gap is external validation, focus digital PR on earning relevant mentions from credible publications, associations, partners, or specialists in your field. Citation-oriented visibility depends on authoritative mentions as well as material on your own domain.

    Do not chase mentions with no relationship to the claim you want an AI system to verify. A general company mention and a specific endorsement of your expertise are not interchangeable. Record the entity named, the claim made, the page linked, and the context around it. That is the evidence you are trying to strengthen.

    Prepare images for multimodal discovery

    Visual search visibility is no longer limited to image-result pages. ChatGPT can place web images beside relevant answer text and let a user open the image and its source. For brands in product, place, person, design, travel, or instructional queries, the selected image can become part of the answer itself.

    Audit your visuals as retrieval assets:

    • Give each image a job. Use it to identify an object, demonstrate a step, compare options, show a result, or explain a relationship. Decorative images add little evidence.
    • Place it beside relevant text. The heading, caption, surrounding explanation, and alt text should agree about what the image shows and why it matters.
    • Keep the source usable. Put the image on an accessible canonical page with a stable URL and enough HTML text to explain the visual without forcing a system to infer everything from pixels.
    • Preserve factual alignment. Product names, labels, versions, and claims in the image should match the page. Replace obsolete screenshots and diagrams when the underlying information changes.
    • Explain charts in text. State the conclusion, method, scope, and limitations in HTML near the visual. A chart should support an answer rather than conceal the answer.
    • Check the destination. When your visual appears in an AI response, verify that the source link reaches the authoritative page and that the page satisfies the intent created by the image.

    Image optimization does not mean placing a logo over every asset or repeating keywords in filenames and alt text. The practical goal is accurate association: the system should understand what the image depicts, which entity it belongs to, and where a user can verify it.

    Measure GEO with a controlled prompt set

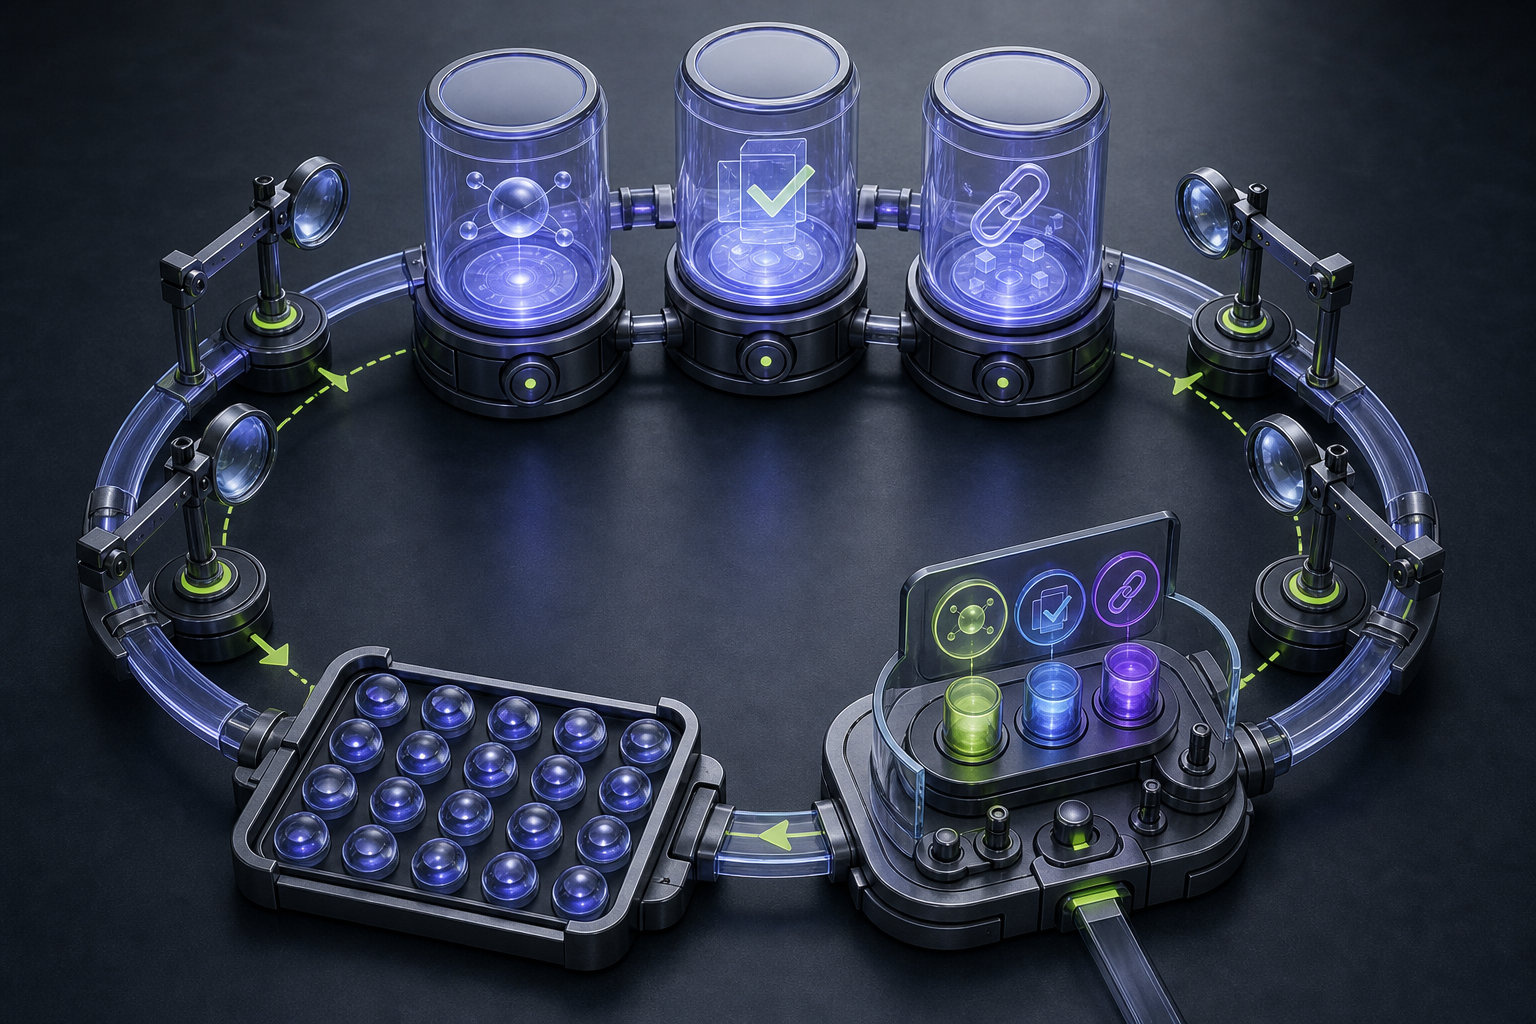
    A circular tabletop system sends identical prompt tokens through response chambers, inspection lenses, and an adjustment station.

    One favorable screenshot is not a visibility report. Generated answers can vary, prompts can change the comparison set, and different systems may retrieve different evidence. You need a stable set of prompts and a record of what happened on each run.

    Build the set around real stages of discovery:

    • Category prompts: questions that ask what options or approaches exist.
    • Problem prompts: questions that begin with a constraint, symptom, or desired outcome.
    • Evaluation prompts: questions about criteria, suitability, risks, or tradeoffs.
    • Comparison prompts: questions that compare named approaches, products, or providers.
    • Verification prompts: questions about your brand, experts, claims, policies, or product details.
    • Visual prompts: questions for which an image, diagram, screenshot, place, person, or product could materially improve the answer.

    For every run, log the AI product, model when visible, date, exact prompt, brand mention, linked citation, cited page, competitors included, factual errors, recommendation context, images shown, and image destination. Keep prompt wording stable when comparing one run with another. Add new prompts separately instead of silently changing the baseline.

    Use separate measures so the result remains diagnosable:

    • Mention rate: prompts that name your brand divided by prompts run.
    • Owned citation rate: prompts that link to your domain divided by prompts that produce sourced answers.
    • Accurate representation rate: brand mentions that describe your entity or offering correctly divided by all brand mentions.
    • Competitor presence: how often each relevant competitor is named or cited across the same prompt set.
    • Visual inclusion: visual prompts that show an accurate image from your site divided by visual prompts tested.
    • Business response: qualified visits, leads, sales, or other outcomes attributable to AI referrals where that data is available.

    Referral traffic alone is an incomplete GEO measure because AI interfaces can answer questions and conduct comparisons before a user visits a site. At the same time, mention rate alone cannot prove commercial value. Keep visibility, accuracy, traffic, and conversion measures adjacent, but do not pretend they are the same outcome.

    Turn the audit into an operating loop

    GEO works best as a focused extension of your search and content program. SEO and SEM have always had to evolve with the search experiences around them; AI discovery changes the surfaces and measurements, not the need for relevant pages, credible evidence, and a path to conversion.

    Use this implementation order:

    1. Select one valuable decision area. Choose a topic connected to a product, service, audience need, or strategic reputation question.
    2. Establish the baseline. Run the controlled prompt set and record mentions, citations, errors, competitors, and visual results.
    3. Repair entity ambiguity. Align visible identity information, author evidence, canonical pages, and relevant structured data.
    4. Improve the source page. Add a direct answer, meaningful headings, verifiable support, conditions, comparisons, and a clear next step.
    5. Close the strongest citation gap. Create the missing evidence or earn relevant third-party corroboration for the claim that matters.
    6. Upgrade useful visuals. Add or correct images where visual context genuinely improves the answer.
    7. Rerun the same prompts. Compare like with like, document changes, and choose the next bottleneck based on evidence.

    Set the review cadence according to how quickly the topic changes. Current products, prices, policies, and platform features need closer monitoring than stable definitions. Review sooner after a material content, entity, or citation change, but avoid declaring success from a single response.

    Start with one topic rather than attempting a site-wide GEO rewrite. If mentions improve but citations do not, strengthen source quality and external corroboration. If citations improve but the brand is described incorrectly, repair entity consistency. If visibility grows without qualified action, improve the page and offer that receive the visit. That loop turns AI visibility from a vague ambition into work your team can prioritize.

    References

  • Industrial SEO Agency Landscape: How to Choose the Right Fit

    Industrial SEO Agency Landscape: How to Choose the Right Fit

    You are not choosing between agencies that all sell the same service. You are choosing which team can understand a technical product, translate it into real search demand, earn access to your subject-matter experts, and connect visibility to qualified opportunities. A polished pitch can conceal weaknesses in any one of those areas.

    The field is crowded: more than 50 industrial SEO firms were evaluated against six selection factors in 2025. You do not need to investigate every firm. You need a commercial brief, a shortlist organized by operating model, and evidence standards that expose whether an agency can work inside your business.

    Understand the agency models before comparing names

    Industrial SEO, manufacturing SEO, and B2B SEO are loose labels. Two agencies may use the same label while offering very different capabilities. One may excel at technical websites and product catalogs. Another may be a content operation with light technical support. A third may coordinate SEO with paid media, conversion work, and a website redesign.

    Organize the market by operating model first. This prevents you from rejecting a capable specialist for lacking services you do not need, or hiring a broad agency whose industrial expertise exists only in its sales presentation.

    Agency modelBest suited toEvidence to requestMain risk to test
    Industrial SEO specialistTechnical products, application-led demand, specification-heavy buying, and close collaboration with engineers or product teamsQuery maps, technical briefs, product architecture work, and examples of turning expert knowledge into useful pagesA fixed industrial playbook that ignores your route to market, margins, capacity, or buying committee
    B2B SEO and content agencyMarkets where education, problem awareness, comparison, and category discovery create demand before an RFQEvidence connecting informational content to product evaluation, conversion paths, and qualified pipelineBroad thought leadership that attracts readers but never helps a buyer select a product or supplier
    Technical SEO consultancyLarge catalogs, faceted navigation, JavaScript problems, migrations, international sites, duplicate pages, or persistent indexing issuesPrioritized technical backlogs, implementation specifications, validation methods, and developer collaborationA technically cleaner site with no plan for demand, content, authority, or lead quality
    Full-service digital agencyOrganizations that need SEO coordinated with paid search, analytics, conversion work, creative, and website developmentNamed SEO ownership, channel-specific deliverables, reporting boundaries, and examples of cross-channel decision-makingSEO being bundled into a larger retainer without enough specialist attention
    Consultant and internal-team hybridCompanies that already have writers, developers, analysts, and subject-matter experts but need direction and governanceDecision frameworks, templates, training materials, review processes, and a realistic division of responsibilitiesA strategy that depends on internal capacity your team does not actually have

    These models are not a ranking. The right one depends on the bottleneck. If search engines cannot reliably crawl and interpret your catalog, a content-heavy engagement will not solve the root problem. If your site is technically sound but says little beyond product specifications, another audit may only document work you already know is needed.

    Diagnose that bottleneck before building a shortlist. Ask whether the constraint is discoverability, page usefulness, technical access, industry authority, conversion, measurement, or internal execution. If several are involved, decide which one has to move first.

    Define the commercial job before requesting an SEO plan

    Write a brief around revenue, not rankings

    An agency cannot prioritize intelligently if the brief is simply to increase organic traffic. It needs to know which product families matter, where you can sell, what a qualified inquiry looks like, and which demand is commercially useless.

    Give every candidate the same decision inputs:

    • Commercial scope: priority product families, services, applications, territories, and customer types.
    • Economic context: which offerings are strategic, constrained by capacity, dependent on distributors, or poor fits despite apparent search demand.
    • Conversion events: RFQs, specification requests, distributor searches, sample requests, calls, CAD or technical-document downloads, and other actions that matter to your sales process.
    • Qualification rules: the characteristics that distinguish a viable opportunity from a student, job seeker, consumer, existing customer, or out-of-market inquiry.
    • Operational constraints: developer availability, legal or regulatory review, subject-matter expert access, publishing permissions, and analytics limitations.
    • Business measurement: the CRM stages, opportunity fields, and revenue signals that should eventually connect search activity to commercial outcomes.

    A useful one-sentence brief follows this pattern: Increase qualified discovery and inquiries for [priority offerings] among [buyer groups] in [markets], while excluding [poor-fit demand], with progress judged by [commercial signals].

    This sentence forces an important distinction. Search volume describes attention; it does not establish value. An industrial term can look attractive while referring to the wrong material, tolerance, application, geography, order size, or buyer. The agency should investigate those differences before proposing a publishing calendar.

    Map searches to the decisions a buyer must make

    Industrial demand rarely fits into a simple split between informational keywords and product keywords. A buyer may begin with a failure mode, move through an application or process, compare materials or capabilities, verify specifications, and then evaluate suppliers. Different pages should support different parts of that path.

    • Problem and application searches need pages that explain conditions, constraints, and suitable approaches without forcing a premature product pitch.
    • Category and capability searches need clear product-family or service pages that define fit, differentiation, limitations, and next steps.
    • Specification, material, model, and part searches need accurate technical pages with unambiguous attributes, relationships, and supporting documents.
    • Supplier and location searches need credible evidence about service areas, facilities, lead handling, certifications, distribution, and relevant capabilities.
    • Comparison and alternative searches need honest selection criteria, trade-offs, compatibility details, and reasons to rule an option in or out.

    Ask each agency to map a representative offering through that path during discovery. You are not testing whether its team already knows every technical detail. You are testing whether it asks the questions needed to learn, distinguishes buyer intent from keyword similarity, and can turn the result into page-level decisions.

    Use a six-part scorecard to test real capability

    Six different precision inspection tools surround a complex machined component on a clean industrial workbench.

    A useful scorecard separates capabilities that agencies often blend together in a proposal. Score the evidence, not the confidence of the presentation. If a capability matters to your brief, require an artifact, a worked example, or a clear operating process.

    1. Commercial prioritization. Ask how the agency would choose among product families, applications, buyer roles, and markets. A strong answer requests margin, capacity, sales, qualification, and territory inputs before committing to targets. A weak answer treats search volume or keyword difficulty as the entire business case.
    2. Industrial fluency. Ask the team to trace a product from the problem it solves through its specifications, alternatives, decision-makers, and conversion path. Strong teams separate terms that look similar but imply different applications or buyer needs. They also identify where an engineer, operator, procurement lead, distributor, or executive may need different evidence. Be wary of an agency that repeats your terminology without testing what it means.
    3. Technical search execution. Ask how the agency will evaluate crawling, indexation, internal linking, canonicalization, faceted navigation, duplicate content, PDFs, JavaScript rendering, structured data, site speed, international targeting, and migration risk where relevant. The expected output should be a prioritized implementation backlog with owners, dependencies, and validation steps. A long issue inventory without impact or sequence is not a strategy.
    4. Expert-led content operations. Ask who interviews subject-matter experts, drafts briefs, verifies technical claims, obtains images or diagrams, manages approvals, and updates aging pages. Inspect a sample brief and an edited deliverable. The process should preserve technical nuance while making the page understandable to the intended buyer. If the plan assumes your engineers will write finished copy on demand, execution will probably stall.
    5. Relevant authority building. Ask how the agency identifies credible places where your expertise, data, tools, or resources deserve mention. Good answers are grounded in trade relationships, useful assets, professional communities, distributors, associations, partners, and publications relevant to the market. Opaque backlink packages and generic authority scores do not show that a link will be contextually appropriate or commercially useful.
    6. Measurement and search-change readiness. Ask how reporting will connect Google Search Console, site analytics, forms, calls, CRM stages, and revenue data without pretending attribution is perfect. Then test the agency’s approach to AEO and generative engine optimization. It should make important facts clear, visible, crawlable, internally connected, and supported by accurate JSON-LD where appropriate. Structured data must describe claims that users can verify on the page; it cannot compensate for missing evidence. Require the agency to distinguish established SEO work from experiments in AI visibility, citations, and brand mentions.

    The final capability deserves particular scrutiny. Adding AI language to a conventional proposal is easy. A serious plan identifies what will change on the site, how entities and relationships will become clearer, which technical or editorial assumptions are being tested, and how the team will monitor outcomes without promising control over an external model’s answer.

    Weight the scorecard according to your actual constraint. A catalog with severe indexation problems should place more weight on technical implementation. A technically healthy site with thin product explanations should emphasize industrial fluency and content operations. Do not average away a critical failure: an agency that cannot support your primary bottleneck is not the right choice simply because it scores well elsewhere.

    Normalize proposals, interrogate proof, and protect the handoff

    An engineer, a commercial leader, and two agency specialists review an industrial component during a factory-side handoff meeting.

    Make every proposal answer the same questions

    Agency proposals are hard to compare because similar labels can conceal different amounts of work. One content deliverable might mean a title and keyword list; another might include expert interviews, technical diagrams, writing, review, publishing, internal links, schema, and measurement.

    Create a comparison sheet with these fields:

    • The business outcome and search problem being addressed.
    • The exact deliverable, including what is and is not included.
    • The agency role, client role, and approval owner.
    • The systems and access required.
    • The implementation owner for technical recommendations.
    • The reporting method and commercial signals being monitored.
    • The assumptions that could change scope, sequence, or cost.
    • Ownership of content, data, creative assets, accounts, dashboards, and documentation at the end of the engagement.

    That last field is not administrative trivia. If the agency controls accounts, tracking infrastructure, domains, content, or essential documentation, switching providers can create operational and data risk. Keep core business assets in accounts your company owns, with access granted to the agency.

    Ask for proof that reveals the mechanism

    A chart moving upward is not enough. It may combine branded and non-branded demand, hide changes in paid activity, reflect a website launch, or show traffic that never became qualified pipeline. Confidentiality may limit what an agency can reveal, but it should still be able to explain its reasoning and show sanitized work.

    Use these questions to inspect a case example:

    • What was the original commercial and search problem?
    • Which pages, templates, technical systems, or content processes changed?
    • What did the agency deliver, and what did the client implement?
    • Which results were branded, non-branded, local, product-led, or informational?
    • How did the team assess inquiry quality rather than form volume alone?
    • What evidence connects the work to the result, and what other explanations remain possible?
    • What would the agency do differently if the same constraints appeared in our organization?

    Direct artifacts usually tell you more than awards or directory positions. Request a sample technical ticket, query map, content brief, reporting view, editorial workflow, or decision memo. You are looking for whether the agency can convert analysis into work that your developers, marketers, engineers, and sales team can use.

    Treat these promises as decision-level warnings

    • Guaranteed rankings or visibility. An agency can control its work, not search-engine or AI-system placement. Replace the guarantee with commitments about deliverables, quality controls, implementation support, and transparent measurement.
    • A strategy built entirely from high-volume keywords. Volume does not account for product fit, margin, capacity, geography, or lead quality. Require a commercial prioritization layer.
    • Large-scale AI publishing without expert review. Industrial errors can affect credibility, sales conversations, and potentially product use. Require named review ownership, claim verification, and a correction process before scaling output.
    • An unexplained link package. If the agency cannot describe relevance, editorial standards, acquisition methods, and ownership, you cannot evaluate reputational risk.
    • Reporting limited to sessions, impressions, and rankings. These are diagnostic signals, not the complete business outcome. Require a plan for connecting search activity to qualified actions and CRM data where feasible.
    • A redesign or migration proposed before diagnosis. Moving URLs, templates, navigation, and content can create avoidable visibility loss. Preserve a crawlable inventory, redirects, measurement, and validation steps before approving an irreversible launch.
    • A plan that assumes unlimited access to your experts. Ask how the agency will batch questions, prepare interviews, manage reviews, and proceed when an expert is unavailable.

    Begin with a diagnostic commitment when uncertainty is high

    If neither side understands the full scope, start with a defined diagnostic phase rather than pretending the annual roadmap is already known. That phase can produce an access inventory, measurement baseline, demand map, technical priorities, representative content brief, implementation backlog, and division of responsibilities.

    Define the outputs before signing. A diagnostic should reduce uncertainty and support a go, revise, or stop decision. It should not become an open-ended audit that repeats known issues without establishing what happens next.

    Before the larger engagement begins, name an internal owner, a technical implementation contact, a sales or CRM contact, and the subject-matter experts who can validate priority topics. Agree on how decisions are logged and what happens when approvals stall. In industrial SEO, the agency’s plan is only one part of the operating system; your access and review process determine whether that plan can leave the slide deck.

    Key takeaways

    • Choose an agency model that matches the bottleneck: technical access, content depth, industry authority, measurement, or internal execution.
    • Give every candidate the same commercial brief, including priority offerings, markets, qualification rules, conversion events, and operational constraints.
    • Test commercial prioritization, industrial fluency, technical execution, expert-led content, authority building, and measurement as separate capabilities.
    • Require artifacts and causal explanations. Traffic charts, awards, testimonials, and confident presentations are supporting evidence, not proof of fit.
    • Evaluate AEO and GEO through concrete site changes, accurate visible facts, retrieval-friendly content, appropriate JSON-LD, and clearly labeled experiments.
    • Keep core accounts, data, content, and documentation under your ownership so a future handoff does not endanger continuity.

    Your next move is to choose one commercially important product family and write the brief around it. Give that same brief to a small shortlist, ask each agency to map the buyer’s search path, and score the evidence with the same criteria. The differences between a sector label and a workable industrial SEO partnership will become visible quickly.

    References

  • Google AI Mode Ads: A Practical Plan for Search Marketers

    Google AI Mode Ads: A Practical Plan for Search Marketers

    If you manage paid search, SEO, or both, Google AI Mode puts you in an awkward position. Ads are beginning to appear inside generated answers, yet you do not have the rollout details or clean reporting needed to treat AI Mode as a mature channel.

    You can still prepare without rebuilding your search program around an experiment. The useful work is to identify the complex decisions that matter to your customers, connect each decision to a clear answer and landing experience, and separate confirmed performance data from assumptions about AI Mode.

    Start with what Google has actually put in motion

    Google confirmed that it was testing ads in AI Mode on desktop, and documented sightings have since become more frequent. Ads have appeared within generated results for commercial searches, including an HVAC repair query. That establishes AI Mode as a real advertising surface under test rather than a purely hypothetical format.

    It does not establish the size of the audience, the range of eligible campaigns, the auction mechanics, the controls advertisers will receive, or the performance you should expect. Repeated screenshots demonstrate availability, not reach or return on ad spend. Do not use them as a forecast.

    The larger strategic possibility is that some users may not have to select AI Mode themselves. A Google industry representative described a US test in which complex searches entered through standard Google Search could be sent directly to AI Mode with Gemini 3. That account was awaiting confirmation from Google, so it should be treated as an early signal rather than a settled product policy. Google has also played down speculation that AI Mode will simply become the default search experience.

    This distinction matters. An optional tab creates a new destination for a subset of users. Automatic routing would change the path for users who believe they are conducting an ordinary search. Your preparation should be useful under either scenario.

    Key takeaways

    • Treat AI Mode as an emerging surface inside Google Search, not as a separately measurable channel you can already manage with confidence.
    • Organize your strategy around complex customer tasks, because those are the searches most plausibly affected by direct routing into an AI experience.
    • Connect the generated answer, organic page, ad message, landing page, and conversion action around the same user decision.
    • Keep reported, observed, and inferred evidence separate. A screenshot can confirm that an ad appeared, but it cannot prove incremental traffic or revenue.
    • Use bounded tests with explicit spending and lead-quality limits. Do not make a broad budget shift before eligibility, controls, and reporting are clear.

    Map the complex decisions behind your valuable searches

    A strategist's hands place markers on branching tabletop paths that pass research, comparison, risk, and selection objects before converging.

    AI Mode matters because a generated response can combine discovery, clarification, and evaluation in the same interaction. A conventional keyword plan may tell you what phrase brought someone to Google, but it often misses the decision that person is trying to complete.

    Start with the commercial decisions that deserve visibility. Useful groups include urgent service needs, comparisons with several constraints, troubleshooting that may lead to a purchase, and planning questions with multiple steps. These are planning categories, not claims about Google’s targeting rules.

    Prioritize a group when it has meaningful business value, requires more explanation than a short product description can provide, and has a credible next action. A complex query with no relevant offer should not receive budget merely because it looks suited to AI Mode.

    Use a query-to-answer worksheet

    For each priority query group, document the following fields:

    • User task: the decision the person wants to complete, expressed without marketing language.
    • Required context: the constraints that could change the answer, such as location, use case, urgency, compatibility, company size, or budget sensitivity.
    • Direct answer: the shortest accurate response your page can support.
    • Decision criteria: the factors a buyer should evaluate before choosing an option.
    • Evidence: product specifications, service boundaries, policies, demonstrations, or other verifiable support for your claims.
    • Next action: the appropriate conversion for that stage, such as checking availability, viewing a relevant product, requesting an assessment, or starting a purchase.
    • Destination: the page that continues the decision without forcing the visitor to restart on a generic homepage.

    Consider a hypothetical search about choosing payroll software for a multi-location company with hourly employees. The underlying task is not merely finding payroll software. The person needs to know whether a product fits distributed locations, hourly work, administration requirements, and implementation constraints. A useful destination addresses those factors directly, shows what can be verified, and offers a next step suited to an evaluator. A generic product page that repeats a broad value proposition leaves the actual decision unresolved.

    This worksheet gives paid and organic teams a shared unit of work. SEO can build the complete explanation. Paid search can match the commercial intent and lead to the right destination. Conversion teams can remove friction from the next action. You are no longer optimizing three disconnected assets against the same keyword list.

    Build one coherent journey across AI, organic, and paid results

    You do not need a separate species of content called “AI content.” You need pages whose meaning, audience, evidence, and next step are easy to identify. That improves the material available to an answer system while preserving its usefulness for people who arrive through a conventional result or an ad.

    Make the organic page answer-ready

    • Use a descriptive heading for the actual decision. A vague heading such as “Solutions” hides the subject from readers and machines alike.
    • Give the direct answer before expanding into criteria, alternatives, and caveats. Do not make the visitor excavate a recommendation from a long introduction.
    • Name the relevant entity, product, audience, location, and limitations precisely. Pronouns and slogans are weak substitutes for clear relationships.
    • Separate facts from recommendations. Specifications, availability, eligibility, and service boundaries should be explicit; editorial guidance should explain how to use them.
    • Support consequential claims with evidence on the page. If a claim cannot be substantiated, weakening or removing it is safer than making it more prominent for AI discovery.
    • Keep structured data consistent with the visible content. JSON-LD can clarify entities and relationships, but it should not introduce claims, ratings, questions, or offers that a visitor cannot see and verify.
    • Link to the next decision rather than merely to a parent category. A comparison page may need a product detail page, pricing information, an implementation explanation, or a location-specific service page.

    Do not rewrite every page in response to early ad sightings. Apply this structure first to query groups closest to meaningful business outcomes. That keeps the work testable and prevents a speculative interface change from driving a site-wide content overhaul.

    Make the paid destination continue the answer

    An ad shown during an AI-assisted journey may meet a user who has already received definitions, options, or preliminary guidance. Sending that person to a page that starts again with a generic brand introduction creates a reset. The ad and destination should advance the task.

    • Align the ad message with the same decision criteria used on the organic page.
    • Send distinct intent groups to distinct destinations when the answer, eligibility, or next action genuinely differs.
    • State important restrictions before the conversion action. Hiding geography, compatibility, minimum requirements, or service limits can produce clicks that were never qualified.
    • Match the conversion to the user’s stage. A person comparing requirements may need detailed information before being ready for a sales conversation.
    • Preserve accurate conversion tracking and lead-quality feedback. More exposure in a new interface is not useful if you cannot distinguish qualified outcomes from superficial engagement.

    Avoid writing ad copy that implies endorsement by Google’s generated answer. Placement inside an AI experience does not turn a sponsored claim into an independent recommendation. Clear brand identification and defensible language remain essential.

    Paid and organic teams should review the journey together before launch. Check whether the organic explanation, paid promise, landing-page evidence, and conversion action describe the same offer for the same audience. If they conflict, AI Mode is not the first problem to solve; the search experience is already inconsistent.

    Measure AI Mode without pretending the data is cleaner than it is

    An analyst separates solid, hazy, and missing result tokens into translucent trays while examining them with measurement tools.

    Separate Search Console reporting for AI Mode and AI Overviews has been described as under exploration, not announced, while the existing data is grouped. Until a dedicated dimension appears in the interfaces you use, you cannot reliably label every change in organic impressions, clicks, or conversions as an AI Mode effect.

    The same discipline should govern paid analysis. Use whatever placement and campaign detail Google actually reports in your account. If AI Mode is not identified as a distinct dimension, do not manufacture that distinction in a dashboard and present the result as platform data.

    Maintain three evidence levels

    Evidence levelWhat belongs in itWhat it can support
    ReportedMetrics and dimensions explicitly supplied by Google Ads, Search Console, analytics, and your conversion systemsOptimization within the scope those systems actually identify
    ObservedDated screenshots or reproducible appearances showing an ad in AI Mode for a particular query, device, and marketConfirmation that the surface appeared under those conditions
    InferredTraffic shifts, query-pattern changes, or conversion movements that coincide with AI Mode activity but lack a dedicated source dimensionA hypothesis that requires further testing, not a claim of causation

    Record observed appearances with the query, date, device type, market, visible ad, destination, and a screenshot. This log can help you spot recurring conditions. It cannot reveal impression share, incremental reach, auction cost, or conversions that Google has not attributed to the surface.

    For reported performance, monitor the full path rather than stopping at click-through rate. Review landing-page engagement, completed conversions, lead quality, sales acceptance, and revenue signals available to your business. A new placement can generate attention while weakening commercial efficiency, so a click increase alone is not enough to justify more spending.

    Run bounded tests instead of making a speculative budget shift

    A large budget reallocation based on screenshots creates direct financial risk: you may pay to chase inventory that is limited, inconsistently available, or not separately controllable. Use a test structure that remains valuable even if AI Mode exposure cannot be isolated.

    1. Choose a commercially important query group from the query-to-answer worksheet.
    2. Write a falsifiable hypothesis, such as whether a decision-specific destination will improve qualified conversion performance compared with the current generic destination.
    3. Define the primary outcome, the lead-quality check, the maximum acceptable spend, and the stopping condition before changing the campaign.
    4. Change only the elements needed to test that hypothesis. Preserve a usable comparison wherever campaign volume and account structure allow it.
    5. Annotate changes to copy, landing pages, targeting, budgets, measurement, and site content so later movements are not casually attributed to AI Mode.
    6. Evaluate reported outcomes first. Add AI Mode observations as context, and label any connection between them as an inference unless Google provides direct attribution.

    This approach also protects you if the product direction changes. Better intent mapping, clearer evidence, more relevant destinations, and stricter measurement improve conventional search campaigns and organic pages as well as emerging AI experiences.

    Start with the high-value decision your existing search journey handles least clearly. Put the organic owner, paid-search owner, and conversion owner around the same query-to-answer worksheet, then fix the handoffs you can already measure. When Google supplies broader access or dedicated reporting, you will have a coherent system to test rather than a collection of guesses to unwind.

    References

  • AI-Era SEO: An Operating Model for Search and AI Visibility

    AI-Era SEO: An Operating Model for Search and AI Visibility

    Your team may have an SEO roadmap, an AI visibility dashboard, and several departments publishing different versions of the same product story. That is not mainly a tooling problem. It is an ownership problem.

    AI-era SEO still depends on discoverable pages, clear answers, credible evidence, and a usable website. The job has widened, though. You now need to keep your brand understandable across search results, generative answers, third-party mentions, sales conversations, and the journey that follows discovery. Here is a practical operating model for doing that without building a separate strategy around every new acronym.

    The channel changed; the job got wider

    People can investigate the same decision through a search results page, an AI-generated response, a publisher, a social discussion, or a vendor website. Those routes overlap, but they do not retrieve, summarize, or present information in exactly the same way.

    The behavioral shift is substantial enough to plan for. Of 2,000 consumers surveyed in June, 82% described AI-powered search as significantly more useful than traditional methods. That result reflects one survey, not a universal migration away from search engines, but it is a strong reason to examine whether your brand can be represented accurately outside a conventional results page.

    The terminology remains unsettled. GEO currently has enough recognition to work as a strategy label: 84% of surveyed practitioners recognized GEO, while 42% selected it when asked for one term to describe generative-platform visibility. Yet no acronym resolves the operational question: who is responsible when a system cannot understand, support, or accurately explain what your company does?

    Use the following as working definitions, not universal standards:

    LabelUseful operating meaningWhat it does not mean
    SEOThe umbrella discipline for making content discoverable, understandable, relevant, and useful throughout an organic search journey.Rankings alone, or work that ends when a visitor reaches the website.
    GEOA strategy for helping generative systems represent a brand, entity, product, or idea accurately and with support.A guaranteed method for earning a mention or citation from an AI system.
    AEOThe practice of making important questions and answers explicit, concise, and well supported.A reason to turn every page into a shallow collection of question-and-answer blocks.
    AISEO or AISOUmbrella language for SEO roles or programs that explicitly include AI-mediated discovery.A settled technical standard or a replacement for content, technical, authority, and user-experience work.

    A simple nomenclature policy prevents weeks of internal debate. Keep SEO as the established business function, use GEO for the generative-discovery workstream, and use AEO for answer design when that distinction helps. If your organization prefers another label, document it once and move on. The operating model matters more than the name.

    Treat visibility as an answer supply chain

    An isometric workflow moves source materials through verification and publishing stations before branching to web, search, AI, media, and sales channels.

    A search or AI answer is the visible end of a longer supply chain. Customer language enters the business, teams turn it into positioning and evidence, publishers distribute it, systems interpret it, and a person decides whether to take the next step. Weakness at any handoff can make an otherwise strong page irrelevant.

    1. Capture the decision. Start with what a person is trying to choose, verify, compare, or accomplish. Search queries are one input. Add recurring sales objections, customer-success questions, support language, account discussions, and the reasons prospects choose you or reject you.
    2. Define the facts. Establish the approved names, descriptions, relationships, capabilities, limitations, audiences, and differentiators that every team should communicate consistently.
    3. Attach evidence. Connect each material claim to a page, case study, demonstration, policy, customer example, or other evidence that actually supports it. If nobody can point to support, rewrite or remove the claim.
    4. Publish and reinforce. Express the same core meaning across product pages, educational content, communications, public relations materials, customer resources, and relevant third-party profiles. Adapt the format to each audience without changing the underlying fact.
    5. Complete the journey. After discovery, make the logical next action obvious. A correct answer that leads to an unclear page, an unexplained form, or an irrelevant call to action has not created much business value.

    This model changes how you diagnose poor visibility. Do not begin with, “How do we get mentioned by an AI tool?” Begin with, “Which decision are we failing to support, and where does the answer supply chain break?” The problem might be missing evidence, contradictory descriptions, weak distribution, inaccessible content, or a landing page that does not continue the conversation.

    Empathy becomes operational here. You need to understand the person’s uncertainty, the constraints of the platform presenting the answer, and the internal team responsible for the missing input. Machines do not need empathy. The people asking questions, building platforms, approving claims, and acting on answers do.

    Build a canonical brand knowledge layer

    Six workplace teams connect to one illuminated central archive containing organized product facts, evidence, policies, insights, and visual assets.

    Most large organizations do not lack content. They lack agreement. A product page uses one category name, sales uses another, public relations emphasizes a third, and customer success explains the offer in language that never reaches the website. Each version may be defensible in isolation while the combined brand becomes difficult to interpret.

    Create a claim ledger before creating more pages

    A claim ledger is a controlled record of what the organization is prepared to say and prove. Build it around one priority offer first. Give every entry the fields needed for review, reuse, and correction:

    • The entity, product, service, or capability being described.
    • The approved name and concise description.
    • The audience and customer problem to which the claim applies.
    • The exact claim, including any limitation or qualification needed to keep it accurate.
    • The evidence and canonical URL supporting the claim.
    • The business owner responsible for accuracy.
    • Permitted wording variants for different channels or audiences.
    • The review trigger, such as a product change, policy change, expired proof point, or revised positioning.

    Separate facts from promotional language. “The product includes capability X” is a factual claim that product should verify. “The easiest way to solve Y” is a comparative or persuasive claim that requires a different standard of support. Mixing the two is how unsupported superlatives spread across pages and later become difficult to correct.

    Turn the ledger into an enterprise ontology

    An ontology is the organized map behind the ledger: what the important entities are, which names refer to them, how they relate, and which attributes belong to each one. You do not need to model the entire company at once. Start with the entities needed to explain one buyer decision without ambiguity.

    • Define the company, brand, offer, category, audience, problem, capability, and evidence entities involved in the decision.
    • Record preferred names, accepted variants, and terms that should not be treated as synonyms.
    • Map relationships explicitly: which company offers which product, which capability addresses which problem, and which evidence supports which claim.
    • Identify exclusions and limits. Knowing what an offer does not do can prevent a damaging overstatement.
    • Assign an owner to each business-critical entity so changes have a clear path into content and data.

    Consistency does not require identical copy everywhere. A technical page, a press briefing, and a sales deck serve different readers. Their depth and tone should differ. The entity name, category, capability, limitation, and proof should not contradict one another.

    Align visible content and JSON-LD

    Treat JSON-LD as the machine-readable expression of the same knowledge layer, not as an independent growth hack. The visible page and its structured data should describe the same entity, relationships, and facts. Markup should never introduce an aspirational claim that the page itself does not support.

    Use this order of operations: approve the fact, publish a clear human-readable explanation, encode the matching structured data, and then distribute or reinforce the fact elsewhere. Starting with markup merely gives a contradictory organization another place to contradict itself.

    • Check that names, descriptions, and relationships match the approved knowledge layer.
    • Confirm that important claims have visible evidence a reader can inspect.
    • Remove stale markup when the corresponding offer, fact, or page changes.
    • Find older pages, profiles, and downloadable assets that still use obsolete positioning.
    • Record corrections in the ledger so the same discrepancy does not return during the next campaign.

    Structured data can reduce ambiguity, but it cannot force a search engine or generative system to use, cite, or endorse your content. Its strategic value comes from expressing a truthful and consistent model of information you have already made clear.

    Make every function responsible for one part of the answer

    AI-era visibility becomes fragmented when each department optimizes its own output. Product focuses on features, public relations focuses on reputation, analytics focuses on exposure, and SEO tries to reconcile the results after publication. Give each function a defined responsibility inside the answer supply chain instead.

    • Product marketing owns the approved positioning, audience, differentiators, and visual explanation of the offer.
    • Product confirms feature names, current behavior, limitations, and changes that make existing content inaccurate.
    • Communications and public relations carry consistent facts into announcements, briefings, profiles, and outreach while respecting the editorial independence of third parties.
    • Customer success contributes recurring questions, implementation language, adoption barriers, and evidence that reflects real customer needs.
    • Sales and account executives contribute decision-makers, objections, comparison criteria, buying language, and reasons a prospect chooses or rejects the offer.
    • Analytics connects discovery activity with useful actions and distinguishes exposure from qualified progression.
    • Compliance reviews claims whose wording creates regulatory, contractual, or reputational exposure and states the boundaries teams must preserve.

    Do not ask every department to “do GEO.” That request is too abstract to own. Bring each team a named discrepancy: an outdated product description, a missing proof point, an objection nobody answers, a case study disconnected from the relevant offer, or a discovery path that ends on the wrong page.

    Run a narrow pilot around one decision

    A useful pilot is organized around a customer decision, not an AI platform. Choose one important offer, one audience, and one decision where inaccurate or incomplete representation has a plausible business consequence.

    1. Write the questions a person asks while discovering, comparing, validating, and acting on that decision.
    2. Capture the current environment: search results, relevant AI answers, owned pages, third-party profiles, sales materials, and the destination pages offered to the user.
    3. Classify each problem as absent, inaccurate, unsupported, inconsistent, inaccessible, or a journey dead end. This makes the remediation assignable.
    4. Trace every problem back to its owner. Product corrects a capability. Customer success supplies an implementation answer. Communications resolves a stale profile. Content publishes missing evidence. Web teams repair the next step.
    5. Update the canonical facts before updating individual channels. Otherwise, each team may solve the same discrepancy differently.
    6. Revise the relevant pages, structured data, supporting assets, and approved external materials.
    7. Repeat the documented questions, inspect the resulting pages, and test the user’s path to the intended action. Record what changed and what remains unresolved.

    This framing can change internal participation. A cross-functional GEO pilot can turn a resisted outreach task into a shared brand-clarity problem because every participant can see the inaccurate representation and the part they control.

    Do not confuse consistency with syndicating identical copy. Preserve the same factual meaning while allowing each channel to serve its audience. You can govern your claims and approved assets; you cannot require an independent publisher to use your preferred wording or reach your preferred conclusion.

    Measure accuracy and decisions, not just exposure

    Traffic, rankings, and visibility remain useful diagnostics. They are not a complete account of AI-era performance. A report that ends with those metrics cannot show whether teams corrected a false claim, supported a buyer decision, or removed friction after discovery.

    Use a scorecard tied to the answer supply chain

    • Decision-question coverage: the share of monitored priority questions for which the brand is represented in a relevant and accurate context.
    • Claim accuracy: the share of sampled statements about the brand that are correct and supportable under your agreed review rubric.
    • Evidence coverage: the share of material claims connected to current, accessible proof.
    • Cross-surface consistency: the share of checked priority surfaces that agree on core names, categories, capabilities, and limitations.
    • Correction cycle time: the elapsed time between identifying a material discrepancy and correcting the surfaces under your control.
    • Journey completion: the share of tested discovery paths on which a person can find the promised information and complete the intended next action without an avoidable block.
    • Business contribution: qualified inquiries, assisted opportunities, retained accounts, or other business outcomes in which a monitored discovery path played a documented role.

    Define the rubric before scoring results. Decide what counts as a relevant appearance, a material error, acceptable supporting evidence, and a completed journey. Establish your own baseline rather than borrowing a universal benchmark that ignores your category, buying cycle, risk, and current visibility.

    Sample AI answers as observations, not fixed rankings

    Log enough context to make each observation interpretable: the exact question, platform, model or mode when displayed, language, location, observation date, logged-in state, response, cited URLs, and evaluator. Repeat the same controlled question set over time and retain the outputs.

    A single response is evidence of what happened in one run, not a stable market-share percentage. Look for repeated patterns: the same factual error, the same missing proof, the same competitor framing, or the same destination-page problem. Those patterns tell you where to intervene even when individual wording changes.

    Connect visibility to the nearest defensible outcome. If revenue attribution is not available, use qualified progression, completed tasks, evidence coverage, resolved objections, or correction speed. Label proxies as proxies. Do not convert an appearance count into an invented revenue claim.

    Key takeaways

    • Keep SEO as the operating foundation; use GEO and AEO to describe distinct work when the labels improve ownership.
    • Organize the program around customer decisions and answer supply chains, not around whichever AI platform is receiving attention.
    • Build a controlled knowledge layer linking approved claims, entities, evidence, owners, pages, and structured data.
    • Require consistency of meaning across teams and channels, not word-for-word duplication.
    • Start with one offer, one audience, and one decision so every discrepancy has an accountable owner.
    • Measure accuracy, evidence, journey completion, correction speed, and business contribution alongside traffic and visibility.

    Your next move is small but consequential. Select one high-value question a buyer asks before choosing your offer. Trace the answer from customer language to approved claim, supporting evidence, search or AI representation, destination page, and next action. Mark every contradiction and dead end, then bring the responsible teams together to resolve those specific failures.

    That completed loop is more valuable than another visibility dashboard. It gives you the repeatable unit from which an AI-era SEO operating model can grow.

    References

  • Choosing an SEO Agency for Regulated, Technical Markets

    Choosing an SEO Agency for Regulated, Technical Markets

    You are not hiring for traffic alone. In healthcare, cybersecurity, or another technical market, an agency can improve visibility and still create a worse business outcome if it publishes an inaccurate claim, breaks your approval process, exposes sensitive information, or attracts visitors your team cannot serve.

    The right agency should make expertise easier to verify, approve, publish, retrieve, and measure. That requires more than industry-themed case studies. You need to test how the agency handles evidence, subject-matter review, technical implementation, AI-search visibility, data access, and accountability before you trust it with production work.

    Key takeaways

    • Treat an industry-specialist label as a reason to interview an agency, not proof that it can manage your risk.
    • Make factual accuracy and required approvals release gates inside the workflow, not corrections added after publication.
    • Ask for redacted working artifacts such as briefs, claims logs, technical issue records, revision histories, and measurement plans.
    • Evaluate traditional SEO, answer engine optimization, and generative engine optimization as related but distinct capabilities.
    • Reject performance reporting that cannot separate visibility, qualified demand, content quality, and observed AI-search presence.
    • Use pass-or-fail gates for accuracy, governance, security, and ownership before comparing creative ideas or presentation quality.

    A niche label is a filter, not proof of operating fit

    Labels such as healthcare SEO agency and cybersecurity SEO agency are useful for discovery. They tell you where a firm wants to compete. They do not tell you whether its writers can distinguish an approved claim from a plausible one, whether its technical recommendations will survive security review, or whether its production schedule can accommodate your internal experts.

    The cybersecurity field alone has supported a candidate pool of more than 75 agencies. Client rosters, leadership experience, review averages, and innovation in generative engine optimization can help sort a field that large. They are longlist signals. Your final decision needs evidence of fit at the task and workflow level.

    Assess fit across three separate dimensions:

    • Subject-matter fit: Can the team understand the product, audience, terminology, evidence, and limits of what may be claimed?
    • Operating fit: Can it work inside your review, security, publishing, and escalation processes without routing around them?
    • Commercial fit: Does the scope reward useful business outcomes, or merely the production of pages and reports?

    A polished case study may support the first dimension, but it rarely establishes all three. Give each serious candidate the same representative hiring brief. Include a real audience question, the intended reader, the action you want that reader to take, the materials the agency may rely on, the statements that require review, the people authorized to approve them, and the systems the work will touch.

    Then ask the agency to describe how that brief moves from intake to publication. A strong answer identifies factual unknowns, dependencies, reviewers, records, and stop conditions. A weak answer jumps directly to keywords, word counts, or a publishing calendar.

    Build accuracy and approval into the production system

    A document passes through evidence, expert review, compliance approval, secure implementation, and publication workstations.

    Compliance cannot be a final proofreading pass. If writers develop an entire page around wording that your legal, security, medical, or product reviewers cannot approve, the problem began at the brief. The agency should identify constrained claims before drafting and resolve missing evidence before those claims become structural parts of the page.

    A workable content path usually contains these stages:

    1. Define the reader, intent, business action, and qualification criteria.
    2. Assemble an approved source pack and mark unresolved factual questions.
    3. Map important claims to supporting material and an internal owner.
    4. Draft with visible assumptions, limitations, and reviewer notes.
    5. Run subject-matter and required compliance reviews before final production.
    6. Complete on-page, structured-data, link, accessibility, and publishing checks.
    7. Record what was approved, what changed, and what should trigger a future review.

    The source pack matters. It defines which product documentation, policies, expert notes, approved messages, and evidence the agency may use. When support is missing, the agency should raise a question or narrow the statement. It should not fill the gap with language that merely sounds credible.

    For claims-heavy pages, ask for a claims ledger. It can be simple, but it should connect each material statement with its approved wording, supporting evidence, reviewer, status, and update trigger. This gives your team a reusable fact layer for page copy, metadata, structured data, answer-focused sections, and later revisions. It also makes corrections targeted instead of forcing reviewers to reconstruct the reasoning behind an old page.

    Structured data belongs inside that control system. JSON-LD should describe content that is actually visible and entities the page genuinely represents. It cannot make an unsupported assertion authoritative, repair a weak source trail, or substitute for expert review. Ask the agency who maps schema properties, who verifies the underlying facts, and how markup is revalidated when the visible page changes.

    Your workflow also needs an exception path. Ask what happens when an expert disputes a draft, an approval is delayed, a published claim becomes outdated, or a technical recommendation conflicts with security policy. The answer should identify who pauses publication, who decides, where the decision is recorded, and how affected pages are found. An escalation path that exists only in someone’s inbox will fail when staff or vendors change.

    Keep data handling within the same review. Identify which employees and subcontractors can access your CMS, analytics, search data, shared documents, customer information, and AI tools. Define how access is granted, limited, logged, and revoked. Do not provide confidential or sensitive material to an external AI system unless your authorized security, privacy, and legal reviewers have approved that use. An SEO agency can follow your controls, but it should not make those risk decisions for you.

    Test expertise with artifacts, not adjectives

    A magnifying lens rests over connected evidence cards, blank documents, a technical model, and a security key on a dark workbench.

    Industry fluency is easiest to evaluate in work products. Ask finalists to show redacted examples of the documents their delivery teams actually use. Reasonable redaction protects clients; it should not prevent an agency from demonstrating its method.

    • A query-to-page map that separates informational questions, comparison needs, implementation concerns, and high-intent searches.
    • A content brief that marks factual unknowns, source requirements, prohibited assumptions, internal links, and the intended conversion action.
    • A source-to-claim record showing how important statements were substantiated and approved.
    • A revision history that explains why wording changed after expert or compliance review.
    • A technical issue record containing the affected page or template, evidence, expected mechanism, dependencies, risk, and validation method.
    • A measurement plan connecting page-level work to qualified business actions rather than traffic alone.
    • An escalation record showing how a factual, technical, or approval conflict was resolved.

    These artifacts reveal more than a logo slide. A familiar client name tells you the agency entered that organization; it does not tell you what the proposed team delivered, how much responsibility it held, or whether the engagement resembled yours. Ask which work the agency performed, which part was handled by another vendor or the client, who reviewed it, and what the agency learned when an expected result did not appear.

    Listen for operational detail when candidates make common claims:

    • If the agency says it uses expert writers, ask what qualifies the assigned writer, how experts are briefed, and who resolves a disagreement between the writer and your subject-matter reviewer.
    • If it says it understands compliance, ask which decisions remain with your organization, what records it maintains, and how rejected language is prevented from returning in a later draft.
    • If it says it provides technical SEO, ask for an example that connects evidence to a proposed change, a dependency, and a post-release validation step.
    • If it says it provides GEO or AEO, ask which answer surfaces it monitors, how it chooses representative queries, what it records, and what it refuses to guarantee.

    Confirm who will do the work after the sales process. You need the roles responsible for strategy, writing, subject-matter interpretation, technical analysis, structured data, analytics, project management, and final quality control. Ask which roles are subcontracted, who can replace an unavailable specialist, and who owns escalation. Senior leadership experience is useful, but it does not compensate for an underqualified delivery team.

    Demand separate proof for SEO and AI discovery

    Traditional SEO, answer engine optimization, and generative engine optimization overlap, but they are not interchangeable labels. SEO work addresses discoverability and usefulness in search, including crawlability, indexation, architecture, page relevance, internal links, and technical quality. AEO makes direct answers easier to locate and understand. GEO focuses on whether generative systems can find, interpret, and accurately represent your organization and its knowledge.

    A competent strategy can share one approved fact layer across all three. That does not mean one tactic controls every surface. No agency controls whether a third-party generative system includes your brand, cites your page, or preserves your wording in a particular response. Treat guarantees of placement or exact answer language as a stop signal.

    Ask the agency to separate what it controls, what it can influence, and what it can only observe:

    • Controlled: your page content, templates, internal links, structured data, author and organization information, publishing checks, and approved update process.
    • Influenced: external mentions, links, citations, reputation signals, and whether other sites find your material worth referencing.
    • Observed: search results and generative answers produced by third-party systems under a recorded query and context.

    AI-visibility reporting needs an audit trail. For each observation, the agency should retain the exact query, the surface or model observed, the observation date, the relevant response, whether your brand or domain appeared, whether it was cited, and any known context that may affect the result. A visibility score without its monitored query set and observation method is not decision-grade evidence.

    Your reporting should also keep different outcome layers separate:

    • Business outcomes: qualified inquiries, accepted opportunities, purchases, applications, or another action your organization recognizes as valuable.
    • Search outcomes: relevant impressions, visits, query coverage, landing-page engagement, and conversions from organic discovery.
    • Content-control outcomes: approval friction, factual corrections, unresolved claims, stale pages, and update completion.
    • AI-discovery observations: brand appearances, citations, linked pages, answer accuracy, and changes across the monitored query set.

    This separation prevents a common reporting error: using a visibility gain to imply a revenue gain, or using an observed AI mention to imply durable placement. Traffic may rise without improving qualified demand. A brand may appear in an answer without being cited. A cited page may contain an outdated claim. Each result calls for a different action, so it needs its own evidence.

    Technical recommendations deserve the same discipline. Every significant item should identify the affected URL or template, the observed problem, the proposed mechanism, implementation dependencies, foreseeable risks, and the validation plan. Reject bulk recommendations that cannot explain which user or discovery problem they solve. In a controlled environment, a technically possible change is not automatically an authorized change.

    Use hard gates before a bounded pilot

    Build your scorecard around evidence and stop conditions. Accuracy, governance, security, and ownership should be pass-or-fail gates. Do not average a failure in one of those areas against an impressive presentation or a lower fee.

    Decision gateEvidence to requestStop condition
    Subject-matter accuracyAnnotated brief, approved source pack, claims record, and named review pathThe team cannot show how unsupported or disputed claims are stopped
    Governance and complianceApproval map, revision history, exception process, and publication recordThe agency treats required review as optional or as a final cleanup step
    Technical SEOIssue evidence, affected scope, dependency analysis, risk, and validation methodRecommendations are generic, unauditable, or detached from your technical constraints
    Content operationsReal briefs, reviewer instructions, quality checks, update triggers, and escalation ownershipThe process depends on undocumented knowledge or unidentified subcontractors
    AI-search capabilityDefined monitored surfaces, recorded queries, observation history, and explicit limitationsThe agency guarantees inclusion, citation, ranking, or exact wording in third-party answers
    MeasurementBaseline, metric definitions, qualification rules, source systems, and reporting caveatsTraffic or a proprietary score is presented as a substitute for business outcomes
    Data and accessAccess list, tool inventory, subcontractor disclosure, revocation process, and approved data usesSensitive information may enter unapproved systems or access cannot be promptly removed
    Commercial controlClear scope, review responsibilities, asset ownership, account ownership, export terms, and exit processYour organization cannot retain its work product, history, or core accounts after termination

    Ask questions that force the process into view

    Generic questions invite polished answers. Use questions that require the candidate to expose a decision, record, or boundary:

    • Show us how an important statement moves from a source into an approved page.
    • What happens when our subject-matter expert says a draft is technically plausible but wrong?
    • Which recommendations would you refuse to implement without development, security, privacy, or legal review?
    • How do you define qualified organic demand for our business, and which system supplies that definition?
    • How do you report AI visibility when answers vary or when a brand mention appears without a citation?
    • Which people and external providers can access our systems or information, and how is that access removed?
    • Who owns the briefs, research notes, content, markup, dashboards, analytics properties, and historical records if the engagement ends?
    • What evidence would cause you to update, consolidate, redirect, or remove existing content?

    Use a pilot to test the real delivery system

    A bounded paid pilot is more revealing than another pitch meeting. Choose work representative of the eventual engagement, such as revising an existing claims-heavy page, producing a new evidence-backed brief, diagnosing a technical issue, and establishing a measurement baseline. Keep production permissions limited to what the pilot requires, and use staging or an internal handoff where direct access is unnecessary.

    Agree on acceptance criteria before work starts. Review the quality of the rationale, source-to-claim mapping, reviewer handoffs, technical evidence, risk identification, documentation, responsiveness, and ownership of outputs. Do not grade the pilot on rankings alone. Search and AI-search outcomes are partly outside the agency’s control; the pilot should first prove that its work is accurate, implementable, auditable, and useful to your team.

    Put commercial edge cases in writing as well. Define included revisions, responsibilities for approval delays, expected subject-matter input, subcontractor use, account ownership, source-file delivery, access removal, and the format of a final export. These details determine whether the relationship remains manageable when a launch stalls, a reviewer rejects a claim, or you change vendors.

    Give each finalist the same representative brief and compare the operating evidence, not the vocabulary of the pitch. The best candidate will make your constraints visible early, show where every important claim comes from, and leave your organization with a process it can inspect and control. That is the agency to advance to a pilot.

    References

  • Answer Engine Optimization: A Practical AEO Framework

    Answer Engine Optimization: A Practical AEO Framework

    Your page can rank and still disappear from an AI-generated answer. It can also be mentioned without a link, summarized incorrectly, or stripped of the detail that makes your offer different. Those outcomes rarely come down to one missing schema property. They expose a gap between content that can be found and content that can be interpreted, trusted, and reused accurately.

    Answer Engine Optimization closes that gap. The practical work is to choose the answer you want associated with your brand, express it without ambiguity, support it with visible evidence, describe it consistently in structured data, and measure what answer engines actually return. SEO still earns discoverability. AEO determines whether your meaning survives when an AI system answers first and presents links later.

    Choose the answer before you optimize the page

    A keyword identifies language. An answer identifies the decision behind that language. If you optimize only around a broad phrase such as “enterprise SEO,” you leave the system to infer whether the page defines the service, compares providers, explains implementation, or helps a buyer choose a plan. AEO starts by removing that uncertainty.

    Classify the question before drafting. Most useful answer targets fall into one of four working types:

    • Factual: the reader needs a clear, verifiable explanation of what something is or how it works.
    • Comparative: the reader needs named criteria, meaningful differences, and tradeoffs rather than a declaration that one option is “best.”
    • Conditional: the correct answer changes with the reader’s context, so the page must state when each branch applies.
    • Procedural: the reader needs an ordered sequence, a decision point, and a way to notice whether the process worked.

    Build a short answer brief for every priority page. Record the exact question, the intended reader, the direct answer, the facts that must survive summarization, the conditions that could change the answer, the evidence that supports it, and the action the reader should take next. If your editorial, product, and subject-matter teams cannot agree on those fields, an answer engine has no stable version of your meaning to recover.

    This is also where SEO and AEO separate without becoming rivals. SEO helps a page become accessible, relevant, and discoverable. AEO extends that work into how AI systems interpret, summarize, and cite the information. A page that cannot be discovered has little chance of being used. A discoverable page with an evasive or contradictory answer is still a weak answer candidate.

    Key takeaways

    • AEO is the practice of making an answer clear, bounded, credible, and easy to represent accurately in an AI-generated response.
    • It builds on technical SEO, content quality, and authority signals; it does not replace them.
    • The visible page, structured data, feeds, author information, and cited evidence should describe the same entity and the same facts.
    • Generic information may earn inclusion, but original data, tools, inventory, expert insight, and interactive experiences give the reader a reason to continue to your site.
    • Success requires monitoring answer accuracy and citations as well as rankings, traffic, and conversions.

    Write an answer that remains correct when extracted

    A translucent answer card is lifted from an abstract document while its qualifier, evidence marker, date token, and source link remain attached.

    An answer engine may use a small passage without carrying over the paragraphs around it. Your most important answer therefore needs to remain accurate when read on its own. That does not mean every paragraph should be short or every heading should be phrased as a question. It means the page should contain a self-sufficient answer unit at the point where the reader expects it.

    A dependable answer unit has six layers:

    1. Direct answer: respond in the first sentence instead of opening with history, positioning, or a sales claim.
    2. Scope: identify the audience, product type, market, use case, or other context to which the answer applies.
    3. Reasoning: explain the mechanism behind the answer so it is more than an unsupported conclusion.
    4. Evidence: connect material claims to named data, documentation, expert review, or another visible basis.
    5. Exceptions: state the conditions that would make the answer incomplete or wrong.
    6. Next action: give the reader a useful step, tool, comparison, or deeper explanation that logically follows.

    Run an isolation test before publishing. Copy the answer unit into a blank document and remove its heading. Check whether pronouns still have clear referents, whether comparative words identify what is being compared, whether qualifications remain attached to the claims they limit, and whether a recommendation is visibly separate from a fact. If the passage changes meaning when removed from the page, rewrite it until its boundaries travel with it.

    Use headings to expose the information architecture. A heading such as “Which option fits a multi-location retailer?” signals a real decision. “Benefits” does not. Under a comparison heading, keep each item on parallel criteria. Under a process heading, preserve the actual order and identify the checkpoint between stages. Under a conditional heading, state the condition before the recommendation rather than adding it as an afterthought.

    Do not manufacture an FAQ section from keyword variants that all produce the same answer. Consolidate duplicates into one stronger explanation and use adjacent questions only when they represent different decisions. Repetition makes a page longer without making its meaning clearer.

    Extractability is only half the job. If a concise AI answer satisfies the entire need, the page may win visibility without earning a visit. Add value that cannot be reduced to the same generic paragraph: original measurements, a calculator, a live product catalog, an interactive lesson, a detailed comparison method, local availability, first-party reporting, or an expert interpretation. The answer earns consideration; the destination earns the next action.

    Make visible content, structured data, and trust agree

    A central faceted object is aligned with an abstract content pane, a data-node lattice, and a ring of evidence and freshness symbols.

    Schema can clarify what a page contains, but it cannot turn an unclear claim into a credible one. Strong AEO depends on structure, conversational clarity, transparent sourcing, and expert attribution working together. Treat JSON-LD as a precise description of the page, not as a substitute for the page.

    Content layerQuestion it must answerFailure to look for
    Visible copyWhat can the reader learn or verify here?The main answer is vague, buried, outdated, or contradicted elsewhere on the page.
    Structured dataWhich entity, properties, and relationships does the page explicitly describe?Markup claims a type, review, price, event, or attribute that the visible content does not support.
    Feeds and integrationsWhich changing facts are supplied to product, travel, commerce, or other external systems?Price, availability, specifications, location, or event details disagree with the page.
    Authorship and oversightWho created, reviewed, and takes responsibility for the information?Expertise is implied through tone but no author, reviewer, credential, or review process is visible.
    Cited evidenceWhat supports the consequential claims?A conclusion has no traceable basis, or a citation does not support the sentence carrying it.

    Use the following implementation order:

    1. Correct the visible answer and remove conflicts across the page.
    2. Identify the primary entity and the properties the page genuinely establishes.
    3. Select the most specific applicable schema type rather than attaching every plausible type.
    4. Add only properties that match content a reader can find on the page or in the legitimate data source represented by the markup.
    5. Validate the JSON-LD syntax, then perform a separate semantic review to confirm that valid code still describes the page accurately.
    6. Recheck the page, markup, and connected feeds whenever a meaningful fact changes.

    That last distinction matters. A validator can tell you that markup is syntactically acceptable. It cannot decide whether the marked-up claim is current, adequately qualified, or supported by the visible page. Technical validity and factual integrity are separate checks.

    For product pages, reconcile the displayed price, specifications, reviews, availability, structured data, and feed values. For events and travel pages, reconcile dates, locations, review information, and availability. For any page giving medical or financial guidance, route the content through qualified expert review and applicable compliance checks before publication. Greater visibility amplifies an error; AEO is not a substitute for professional oversight.

    Adapt the AEO playbook to your business model

    The same checklist cannot carry equal weight in every industry. Retail, healthcare, finance, travel, education, and publishing face different visibility and control problems. Prioritize the failure that would matter most to your reader and your business.

    • Ecommerce and retail: AI-generated product answers can present prices, specifications, and reviews before a shopper visits a store. Keep Product markup, feeds, visible product details, and conversational buying guidance aligned. Preserve the reason to continue through current inventory, useful comparison criteria, configuration choices, or a purchasing path.
    • Healthcare: an oversimplified answer can cause more than a lost click. Put reviewer identity, relevant credentials, sourcing, qualifications, and the limits of general information beside the claim they govern. Symptom-oriented content should make uncertainty and escalation paths visible rather than presenting a confident diagnosis.
    • Finance and banking: context is part of correctness. Identify who a financial explanation applies to, separate education from individualized advice, attribute authorship, and show the basis for data-dependent claims. Calculators and scenario tools can give the reader value that a generic summary cannot reproduce.
    • Travel and hospitality: itinerary answers depend on exact place, timing, events, reviews, and changing availability. Strengthen local intent signals and keep structured details current, but retain descriptive information that helps a traveler judge fit rather than merely supplying a list of entities.
    • Education and EdTech: answer the concept clearly, then move the learner into application. Interactive exercises, instructor-certified interpretation, feedback, and progressive modules are harder to replace with a compressed definition because the learning value lies in doing, not only reading.
    • Media and publishing: generic commentary is easy to paraphrase. Original reporting, proprietary data, distinctive analysis, and transparent provenance give an answer engine something specific to attribute. Citation visibility and content licensing may become strategic concerns alongside referral traffic, but neither should weaken the editorial value of the destination.

    You can reduce that industry choice to two questions: what harm follows if the answer is wrong, and what value disappears if the user never clicks? High-consequence answers require stronger review and qualification. Fast-changing answers require dependable feeds and update ownership. Easily summarized answers require proprietary depth. Transactional journeys benefit from integrations that keep the brand inside the action path, not only the information path.

    Measure whether the answer is accurate, attributable, and useful

    Pageviews alone cannot measure an environment where a user may receive product details, explanations, or an itinerary without visiting the cited site. At the same time, a brand mention is not automatically a win. The answer may attribute the wrong feature, omit an essential qualification, cite another publisher, or satisfy an informational query that never had commercial value.

    Create a repeatable answer evaluation rather than relying on occasional screenshots:

    1. Define the query set. Use questions tied to actual discovery, comparison, validation, and action stages. Keep the wording and user context recorded so later checks are comparable.
    2. Write the expected answer first. Record the facts that must be present, the qualifications that must not be lost, and the claims that would be unacceptable if attributed to your brand.
    3. Observe the relevant answer surfaces. Record whether your brand or page appears, whether it is linked, what claim is attributed to it, and whether the summary preserves the intended scope.
    4. Classify the failure. Separate discoverability problems, citation problems, factual distortion, stale data, and weak continuation value. Each requires a different fix.
    5. Change the responsible layer. Revise the answer passage for ambiguity, the schema for entity mismatch, the feed for stale facts, the evidence for weak support, or the on-page experience for poor continuation.
    6. Repeat over time. Generated responses can vary, so do not infer a durable result from one prompt on one occasion. Preserve the query, context, date, output, and page version used in each review.

    Your scorecard should distinguish five outcomes. Track answer coverage across the query set, citation rate, factual accuracy, quality of brand representation, and the business continuation that follows. Citation rate is the share of tested queries that visibly cite your brand or page. Accuracy is a separate pass-or-fail review against the expected answer. Business continuation may be a qualified visit, use of a tool, product exploration, registration, or another action appropriate to the page.

    The failure pattern tells you where to work. If the brand never appears, inspect indexing, relevance, entity clarity, and competitive authority before polishing another summary paragraph. If it appears but is represented incorrectly, tighten the answer’s scope and reconcile conflicting facts. If it is mentioned without attribution, strengthen the page’s provenance and original value, while recognizing that a citation cannot be guaranteed. If it is cited accurately but the visit has little value, improve what happens after the answer rather than rewriting the answer itself.

    Start with one commercially or reputationally important question. Write the answer you want preserved, test the passage in isolation, align the visible page with its JSON-LD and connected data, and record the current answer-engine result. Fix the layer that fails, then move to the next question. That turns AEO from a speculative content exercise into an operating discipline your team can repeat.

    References

  • How to Choose a Manufacturing SEO Agency That Drives Leads

    How to Choose a Manufacturing SEO Agency That Drives Leads

    You are not hiring a manufacturing SEO agency to produce rankings in isolation. You are hiring a team to help technical buyers find the right capability, trust what they find, and take a measurable commercial step. An agency can grow traffic and still fail if visitors reach generic pages, cannot verify whether your product fits their application, or never become qualified opportunities.

    The decision becomes much easier when you separate proof from pitch. Define the business job first, shortlist agencies by their real specialty, inspect how they turn technical knowledge into accurate content, and make them explain how search activity will connect to sales. The framework below gives you a practical way to do that.

    Define the commercial job before you compare agencies

    A sales leader, engineer, and marketer arrange a metal component, factory model, blank cards, phone, and sample case into a sequence on a conference table.

    A vague objective such as increasing organic traffic gives an agency room to succeed on paper without improving the business. Start with the action you need a qualified visitor to take. That action should shape the keyword strategy, page architecture, content plan, tracking, and reporting.

    Select a primary commercial action for the initial scope. Depending on your sales model, that might be:

    • Submitting an RFQ with enough technical detail for sales to respond.
    • Requesting a consultation, sample, prototype, demonstration, or facility visit.
    • Downloading a CAD file, specification sheet, technical drawing, or selection resource.
    • Finding an authorized distributor or contacting a regional sales representative.
    • Requesting maintenance, retrofit, replacement, or field-service support.

    Then define what qualified means. A workable internal sentence is: A qualified inquiry comes from [target account or buyer], in [served market], asking about [priority product or capability], for [relevant application], with [information sales needs]. If your marketing and sales teams cannot complete that sentence together, an agency will not be able to build reliable conversion reporting around it.

    Give every prospective agency the same one-page campaign brief. It should identify:

    • The product families, processes, applications, or aftermarket services that matter most.
    • The people involved in discovery, technical evaluation, approval, purchasing, and implementation.
    • The countries, regions, industries, account types, and distribution arrangements you can actually serve.
    • The approved evidence available to support claims, such as data sheets, certifications, test information, case material, drawings, videos, and subject-matter experts.
    • The commercial action attached to each part of the buying journey.
    • The way your CRM or sales team distinguishes a qualified opportunity from spam, recruitment inquiries, consumer requests, and poor-fit leads.
    • Constraints the agency must respect, including approval workflows, dealer relationships, regulated claims, legacy systems, and pages that cannot be changed without review.

    Use a measurement ladder rather than a single traffic target. At the top are accepted opportunities, qualified pipeline, and attributable revenue where your systems support that connection. Below those are primary conversions such as qualified RFQs and consultations. Supporting actions might include specification downloads, distributor lookups, return visits, or contact with a technical representative. Search visibility and site-health metrics belong underneath those commercial measures, not in place of them.

    This hierarchy exposes incentive problems early. If a proposal promises sessions and keyword positions but does not define qualified demand, the agency can complete its stated job while your sales team sees no improvement.

    Build your shortlist around the bottleneck, not the rank

    You can start with eight names drawn from a November 2025 field of 54 firms. Because First Page Sage evaluated that field and placed itself first, use the names as candidates to investigate rather than as an independent endorsement. That conflict does not make the information useless; it changes what the placement itself can prove.

    AgencyDocumented November 2025 focusInterview when your main need is
    First Page SageThought leadership, SEO, and AI search optimizationTurning internal expertise into organic and generative-search visibility
    Kula PartnersSEO-focused web design and account-based marketingConnecting a website program with named-account demand generation
    Industrial Strength MarketingBrand strategy and sales enablementAligning market positioning, marketing assets, and the sales conversation
    Windmill StrategyTechnical SEO and web designImproving the technical and structural foundation of a complex site
    Factory Web SourceSocial media and video SEOMaking demonstrations, processes, equipment, and other visual material discoverable
    Aviate CreativeBranding for manufacturing companiesClarifying or modernizing the brand before scaling acquisition
    EcreativePaid search and web developmentCoordinating organic search, paid acquisition, and website execution
    BrandpointMAT releases combined with SEOConnecting distributed editorial material with search visibility

    The third column is a decision heuristic, not a claim that the firm will fit your account. Treat every service label from November 2025 as time-bound. Ask each agency to confirm its current scope, current delivery team, and current examples before putting it on a final shortlist.

    AI-search capability needs that freshness check in particular. Only First Page Sage was marked as offering GEO in the November 2025 comparison. That does not establish that the other seven still lack a GEO service, nor does a checked box establish the depth of any service. Ask what the agency actually changes, what it measures, which systems it observes, and how the work differs from its conventional SEO program.

    Published ranking signals also need to be reordered around your risk. For context, notable clients carried 20% of the 2025 scoring; leadership experience and founder status, agency age, and review score carried 15% each; employee tenure, GEO, and SEO approach carried 10% each; and media references carried 5%. Those factors can narrow a broad market, but your own scorecard should give more weight to the capability most likely to constrain the engagement.

    • If technical accuracy is the constraint, prioritize the subject-matter-expert workflow, writer background, and claim-approval process.
    • If an old website is the constraint, prioritize technical diagnosis, development capacity, migration controls, quality assurance, and ownership of implementation.
    • If buyers do not understand a new category, prioritize positioning, thought leadership, evidence development, and sales alignment.
    • If named accounts drive growth, prioritize the connection between SEO, account-based marketing, CRM data, and sales follow-up.
    • If visibility in generative systems matters, prioritize a current GEO method with explicit deliverables and observable measures.

    Longevity, recognizable clients, reviews, and media mentions can support confidence. None of them answers the decisive question: Can the people assigned to your account execute the work your commercial problem requires?

    Pressure-test the delivery system before you buy it

    An engineer explains a valve assembly while a content strategist documents it and an analyst reviews an abstract digital interface in an adjoining studio.

    Run the same diligence exercise with every finalist. Comparable inputs make vague answers, hidden dependencies, and major scope differences easier to notice. You are evaluating a production system, not just the strategy presented in a sales call.

    Test whether the specialty is real

    Many agencies can list manufacturing among the sectors they serve. That is not the same as having a manufacturing operating model. Ask:

    • What does your agency specialize in, and which services are secondary?
    • Which part of manufacturing SEO do you deliberately not lead?
    • What type of manufacturer, sales motion, or website is a poor fit for your team?
    • Which deliverables are completed in-house, and which are handled by partners or freelancers?
    • Can you show an engagement with comparable technical complexity, channel structure, or buying process?
    • What changed because of your work, and how was that change connected to a business measure?

    Do not grade the answer by the prestige of a client logo alone. A familiar manufacturer may have bought a different service, worked with a different team, or presented a much simpler problem. Ask what the agency owned, who performed it, and which evidence the example can legitimately support.

    Test the technical-content workflow

    Give each finalist the same public or sanitized set of product materials. The goal is to test the process without exposing proprietary information. Ask the team to explain how it would turn those materials into a search and content plan. Do not ask for a free finished campaign; ask for the operating logic.

    A credible answer should identify:

    • Which document, system, or person becomes the source of truth for each technical claim.
    • How search intent will be separated across products, capabilities, applications, industries, problems, and buying stages.
    • How writers will interview engineers, product managers, service teams, salespeople, or other relevant experts without wasting their time.
    • Who drafts, technically verifies, edits, approves, publishes, and maintains each asset.
    • How conflicting terminology, outdated documents, market-specific naming, and unsupported claims will be resolved.
    • How one page will earn a distinct purpose instead of repeating a slightly altered template across the catalog.

    Useful diligence questions include how your experts will be involved, how the content plan is organized, how many people will work on the account, and what background the writer has. Push past general assurances. You need names, roles, handoffs, approval points, and an example of the brief the writer would receive.

    A weak answer relies on a generalist writer researching the product independently and sending a polished draft for your team to repair. That transfers the hardest part of the work back to you. A stronger model captures expert knowledge deliberately, records the supporting evidence, and makes technical review a defined stage rather than a last-minute rescue.

    Test technical execution and account ownership

    Ask the agency to separate diagnosis from implementation. A technical audit has limited value if no one converts findings into approved development work, verifies the release, and confirms that the intended behavior reached production.

    Request a sample issue or development ticket with sensitive information removed. It should show the problem, affected templates or URLs, business consequence, recommended change, owner, dependencies, acceptance criteria, and quality-assurance step. Then ask who writes that ticket, who answers developer questions, and who checks the completed change.

    Complex manufacturing sites may combine product pages, application pages, filterable catalogs, distributor locations, technical PDFs, support material, multiple languages, and several conversion paths. Your finalist should be able to explain how it will decide what belongs in the search index, which page owns each intent, how internal links support that ownership, and where a visitor should go next. It should also state what requires your developer, CMS vendor, analytics team, or legal and compliance review.

    Get the account map in writing. Identify the strategist, technical lead, writer or editor, project manager, analyst, and executive sponsor where those roles exist. Confirm which people will attend recurring meetings and which person has authority when priorities conflict. A senior salesperson who disappears after signature is not part of the delivery team.

    Test reporting with a real lead path

    Give every finalist the same scenario: a buyer discovers an application page through non-branded search, returns through a branded search, downloads a specification, and later submits an RFQ that sales accepts. Ask how that journey would appear in reporting and which limitations would remain.

    The core questions are straightforward: How will campaign success be measured? How often will progress be reviewed? How will marketing activity be connected to sales outcomes? Can the agency provide relevant manufacturing references or testimonials? These questions belong in procurement because client-specific metrics and ROI are stronger service signals than a standard report applied to every account.

    A credible reporting plan distinguishes what is directly observed, what is assisted, what is inferred, and what cannot be known with the available systems. It also includes sales feedback about lead quality. Be cautious when rankings are presented as revenue, all organic conversions are treated as equally valuable, or attribution is described without reference to your CRM and sales process.

    Require one operating plan for SEO, AEO, GEO, and handoff

    SEO, answer engine optimization, and generative engine optimization should not become three disconnected content programs. For procurement purposes, use simple operational definitions. SEO makes relevant pages discoverable and competitive in conventional search. AEO makes important questions easy to answer directly from clear, supported content. GEO organizes the brand, entities, expertise, and evidence so generative systems can more reliably understand and potentially surface them.

    The labels overlap because the same technical truth may serve all three. Your agency should show how one validated knowledge base becomes useful pages, concise answers, consistent entity information, structured data, internal links, and commercial pathways.

    For one priority product family or capability, ask for an integrated deliverable map containing:

    • An intent map that separates product, capability, application, problem, comparison, support, and purchase-oriented needs where they genuinely exist.
    • A canonical commercial destination with the information a qualified buyer needs to evaluate fit and take the next step.
    • Supporting pages that answer distinct technical or commercial questions instead of competing with the canonical page.
    • An evidence inventory showing which statements are supported by approved specifications, certifications, testing, case material, or named expertise.
    • A terminology and entity map covering the company, brands, product families, processes, locations, industries, and alternate names that must remain consistent.
    • An internal-link plan connecting educational discovery to evaluation and action.
    • An AEO plan that answers real presales and support questions without manufacturing an FAQ section merely to occupy search space.
    • A GEO plan that defines target query sets, systems observed, checks performed, changes made, and the difference between a brand mention and an attributable commercial result.
    • A JSON-LD plan that describes accurate, visible page content and assigns responsibility for generation, validation, deployment, and maintenance.
    • A measurement map connecting each asset to its intended search behavior, user action, and commercial signal.

    Structured data deserves particular scrutiny because it can look impressive in a deliverables list while doing little to correct weak information. JSON-LD is machine-readable labeling, not evidence. It should match the visible page, use the right entity relationships, and be maintained when templates, products, locations, or claims change. Ask who validates it after deployment and how errors or stale values enter the work queue.

    Put the operating model into the contract. Define deliverables, exclusions, dependencies, approval responsibilities, acceptance criteria, reporting cadence, account access, and ownership of content and data. State what happens to analytics configurations, keyword sets, briefs, drafts, dashboards, schema, and other working assets when the engagement ends.

    Vague ownership and termination language can leave you paying for unusable work or losing access to accounts and materials. Have your procurement or legal team review confidentiality, intellectual-property, liability, data-access, and termination clauses before signature; an SEO evaluation cannot resolve those legal terms for you.

    Use acceptance gates instead of authorizing an undifferentiated stream of activity. The first gate should confirm the baseline, priorities, measurement design, and dependencies. Later gates can cover technical implementation, content production, publication, and performance review. If the agency cannot define what complete means at each handoff, the scope is not ready to sign.

    Manufacturing SEO agency FAQ

    Must the agency have experience in your exact manufacturing niche?

    Exact-niche experience can shorten the learning curve, but it should not replace process evidence. A team with an excellent technical-review workflow, a comparable sales model, and experience handling complex product information may be stronger than a niche specialist that relies on generic pages and weak measurement. Ask both candidates to demonstrate how they learn terminology, verify claims, protect confidential information, and distinguish qualified demand. Also check whether a direct competitor relationship creates practical conflicts.

    Should the engagement include a website redesign?

    Only when the current site prevents the agreed strategy from being implemented effectively. Require three options where practical: retain the present site, make targeted structural or template changes, or replace it. Each option should identify the SEO consequence, implementation dependency, content work, measurement impact, and ownership. An agency whose main strength is web design may naturally see a rebuild as central; one focused on content may prefer to work around the platform. Your diagnosis and business case should decide, not the agency’s preferred service line.

    How can you compare proposals with different scopes?

    Normalize them into the same worksheet. Create rows for discovery, technical SEO, implementation, content strategy, expert interviews, writing, editing, design, publication, authority development, AEO, GEO, structured data, analytics, CRM connection, reporting, and project management. Mark every row as included, dependent on your team, handled by a third party, optional, or excluded. Then record the responsible role, deliverable, acceptance condition, and ownership after termination. This exposes a low proposal that depends heavily on your staff and a broad proposal that includes work you do not need.

    Write the one-page brief before your next agency call. Give every finalist the same sanitized product-family scenario, commercial action, and reporting question, and ask the people who will perform the work to join the discussion. Choose the team that can trace a validated technical fact into a discoverable page, a useful buyer answer, and a measurable sales action – then put that chain of responsibility in writing.

    References

  • How Google AI Is Changing Marketing and the Open Web

    How Google AI Is Changing Marketing and the Open Web

    If your organic dashboard still treats rankings and clicks as the whole search funnel, it is measuring too little. Your business can appear inside a generated answer, be reduced to a generic summary, or disappear from the decision altogether without producing a clean, familiar ranking change.

    The practical response is not to abandon SEO or hand every campaign to automation. You need to separate four jobs that Google Search once bundled together: earning inclusion, preserving a reason to visit, testing paid reach, and keeping control of what you learn about your market.

    Key takeaways

    • Measure AI representation separately from rankings, citations, referral traffic, and conversions. They are related outcomes, not interchangeable ones.
    • Generic consensus content is easy for an answer engine to compress. Give it distinctive evidence, explicit scope, and claims that remain useful after summarization.
    • Treat Google AI Max as a test for incremental demand, not as a replacement for your proven keyword structure.
    • Require automated advertising to produce both commercial lift and reusable customer insight. A better platform result with less business understanding is an incomplete win.
    • Keep the canonical version of your work on an owned website, then use social, video, community, and paid media as distribution rather than substitutes for it.

    The organic bargain has split into separate outcomes

    The old search bargain was imperfect but legible: publish something valuable, make it discoverable, earn a position, and receive a chance to win a visit. An AI answer can use a page as an input while becoming the destination itself. Meanwhile, ads are already appearing within AI Overviews, placing monetization inside the same interface that can reduce the need to open an organic result.

    That does not make organic visibility worthless. It makes the word “visibility” too vague for serious reporting. Replace the single visibility metric with a ledger that distinguishes these outcomes:

    • Eligibility: Can the relevant page be crawled, indexed, understood, and associated with the right entity and topic?
    • Representation: Does the brand, product, expert, or argument appear when an AI result is generated for an important query?
    • Fidelity: Does the generated answer preserve the meaning, limitations, and differentiators of the underlying material?
    • Referral: Is there a visible citation or link, and does it send qualified visits?
    • Commercial effect: Do those visits, mentions, or assisted journeys lead to enquiries, subscriptions, purchases, or another defined outcome?

    Do not collapse those measurements into a proprietary “AI visibility score” before you can inspect the parts. A cited page with no visits may still influence awareness. A brand mention with no citation may be strategically relevant but difficult to attribute. A high citation count for the wrong claim can be actively harmful. The labels only become useful when they tell you what happened.

    Build a query set from real customer decisions rather than from search volume alone. Include questions about choosing, comparing, troubleshooting, pricing, risk, and suitability. For each query, record whether an AI feature appeared, which entities and claims it included, whether it cited your page, where the citation led, and what happened after the visit. Repeat the review after meaningful content, product, or campaign changes. This gives you a testable view of AI search without pretending that every mention has the same value.

    Create content that survives consensus compression

    Varied source materials pass through a transparent funnel, where generic items fade while distinctive evidence and tools remain visible.

    There is a credible risk that generated search results will favor established brands and consensus positions, making independent or divergent perspectives harder to discover. That outcome is not inevitable, but it is important enough to plan around. If every page repeats the same safe answer, an AI system has little reason to preserve the identity of any individual publisher.

    Recent search disruption also showed that being useful was not a guaranteed defense for every small publisher. Smaller affiliate sites lost substantial organic visibility during Helpful Content changes, including sites built around reviews and comparisons that their operators considered valuable. The lesson is not that independent publishing is futile. It is that a strategy based only on producing a slightly better version of an established format is fragile.

    Make each important page pass a distinctiveness test before you optimize its title or markup:

    • Publish inspectable evidence. Show the method, criteria, inputs, examples, calculations, or decision rules behind the conclusion. “We tested it” is not evidence if the reader cannot understand what was tested.
    • State the boundary of the answer. Identify who the recommendation is for, when it applies, what would change it, and where the common answer fails.
    • Preserve legitimate disagreement. If credible positions differ, explain the deciding conditions instead of flattening them into a false universal answer.
    • Separate facts from judgement. A clear editorial conclusion is useful, but readers and machines should be able to tell which claims support it.
    • Give the page a reason to be cited. Original data, a transparent framework, a primary document, a named method, or a genuinely useful decision tool is harder to replace than a generic overview.

    Structured data supports this work when it clarifies what the visible page already says. Use appropriate schema to identify entities, authorship, products, organizations, articles, or other relevant relationships, but keep the markup aligned with the content a visitor can see. Schema can reduce ambiguity; it cannot make an unsupported claim authoritative or force an AI system to cite the page.

    Run a final compression check before publishing. Ask what would remain if a search interface summarized the page in a few sentences. If the answer is only the same advice available everywhere else, the page needs stronger evidence or a sharper scope. If the summary would preserve a proprietary finding but remove every reason to visit, add something that requires interaction or inspection: the complete method, comparison criteria, examples, tool, dataset, or implementation detail.

    Test automated advertising for incrementality and insight

    Google positions AI Max for Search as a way to capture relevant demand beyond an advertiser’s existing keywords. Its matching can combine broad-match logic, keywordless discovery from landing pages, generated text, and Final URL expansion. Existing keywords still receive priority when they match the query. That makes AI Max an expansion layer, not a reason to discard a keyword structure that already performs.

    Your starting setup changes what a plausible gain looks like. Phrase- and exact-heavy campaigns leave more demand for broader and keywordless matching to find. Broad-match-heavy campaigns may have less room to expand. Advertisers already using Dynamic Search Ads may see less new keywordless reach, although asset-driven signals can still change performance. This is why a result from another account tells you very little about the lift available in yours.

    Judge the system by incremental campaign value at an acceptable blended CPA or ROAS. Do not demand that every newly discovered conversion match the efficiency of mature, curated keywords. Marginal demand may cost more. At the same time, do not accept “incremental” as an excuse for spending that misses your business economics.

    Use this testing sequence:

    1. Write the hypothesis in commercial terms. Specify which demand you believe the current campaign misses and which conversion action represents genuine value.
    2. Use a control-and-treatment experiment where the available controls fit the question. Keep unrelated campaign changes out of the test so that creative, landing-page, budget, or tracking edits do not obscure the result.
    3. Set guardrails before launch. Define acceptable campaign-level CPA or ROAS, brand-suitability requirements, valid landing pages, and conversion-quality checks.
    4. Exclude the learning period from the final comparison. A system that is still adapting should not be treated as settled performance.
    5. Inspect the search terms, creative assets, and landing pages selected by the system. Aggregate lift matters, but so does understanding where it came from.
    6. Compare the whole campaign, not isolated match types. The real question is whether the treatment produced additional conversion value within the agreed economics.

    Start with a contained experiment if you cannot yet verify query quality, generated assets, landing-page selection, or conversion value. Broad activation can spend real money on marginal demand before you know whether the traffic is suitable. The safer alternative is a limited test with explicit stop conditions and a person responsible for reviewing what the automation chooses.

    There is also a strategic cost to opacity. Highly automated systems can use your budget and conversion data to improve targeting while revealing less about the audience signals that drove the result. Performance Max illustrates the concern when control and reporting are limited. If your team cannot carry the learning into another channel, Google has improved its model while your own understanding may have barely moved.

    Protect that understanding before and during the test. Preserve your query themes, audience hypotheses, landing-page roles, creative propositions, conversion definitions, margin assumptions, and observed objections in records your team controls. A useful automation test should produce two outputs: incremental business value and a clearer picture of demand. If it produces only the first, record that trade-off honestly.

    Build a marketing system that still supports the open web

    A central marketing hub connects directly with a website, inbox, forum, storefront, analytics workspace, audiences, and independent publisher sites.

    When independent publishers lose search visibility, many shift their effort to TikTok, Instagram, or other platforms. Google is also bringing more social material into discovery through YouTube Shorts, short-video results, Reddit, and LinkedIn content. That can expose searchers to more individual voices, but it does not fully replace an accessible, linkable, independently published web.

    A social clip is good at earning attention. A durable web page is better at preserving context, documenting evidence, receiving links, supporting structured data, and remaining available outside a feed. Treat those formats as complementary parts of a publishing system:

    • Keep the canonical explanation on a website you control. Preserve the complete evidence, limitations, authorship, update history, and relevant structured data there.
    • Adapt the idea for social, video, community, and professional platforms. Match the native format, but point interested people toward the durable resource when deeper context matters.
    • Create a direct return path. Give people a legitimate reason to bookmark the resource, subscribe with consent, join a community, or otherwise return without repeating the same platform-mediated search.
    • Retain portable business knowledge. Keep your raw content, research materials, analytics definitions, audience findings, and creative learnings in systems your organization can access independently.
    • Diversify discovery deliberately. Organic search, AI answers, paid search, social distribution, partnerships, referrals, and direct audiences should have defined roles rather than serving as interchangeable traffic taps.

    This is also an industry problem, not only a site-level optimization problem. Publishers, advertisers, and marketers have shared reasons to demand workable standards for permission, attribution, compensation, transparency, and auditability. Collective standards could provide protection while formal AI regulation develops. Self-governance will not settle every copyright, competition, or data-use dispute, but isolated businesses have less leverage than an industry that can define unacceptable practices clearly.

    Start with your highest-value search journey. Map the question, the generated answer, the citation or ad, the landing experience, the conversion, and the knowledge your team retains afterward. Fix the point where Google can absorb the value without giving your audience a reason to recognize, visit, or return to you. That is the practical work of adapting to AI search without surrendering the open web that makes useful AI answers possible.

    References