Tag: AI Discovery

  • Google Ask Maps SEO: A Practical Local Visibility Guide

    Google Ask Maps SEO: A Practical Local Visibility Guide

    A customer no longer has to search for a broad category such as a restaurant, charging point, or tennis court. They can describe the whole situation: what they need, where they need it, which constraints matter, when they plan to go, and what they want to do next.

    If your business is technically present on Google Maps but its listing does not answer those details, it may be difficult to match with that request. Preparing for Google Ask Maps is therefore less about adding more keywords and more about making your business accurate, specific, credible, and easy to act on.

    Ask Maps matches a situation, not just a search phrase

    Ask Maps uses Google’s Gemini models to turn complex local questions into a conversational response accompanied by a custom map. A request can include several kinds of information at once:

    • Intent: what the person wants to accomplish.
    • Hard constraints: features or conditions that must be present.
    • Context: preferences, urgency, companions, or the purpose of the visit.
    • Time: whether the place must work tonight, during a journey, or at another relevant moment.
    • Location: nearby, in a particular area, or along an existing route.
    • Action: getting directions, making a reservation, saving a place, or sharing it.

    That is a different optimization problem from trying to rank for a short phrase such as vegan restaurant near me. The useful question is no longer only, Does Google know our category? It is also, Can Google determine which real-world situations we fit?

    A practical way to evaluate your local presence is to use four recommendation gates:

    • Eligibility: Is this actually the type of place or service the person requested?
    • Fit: Does it satisfy the stated location, timing, amenity, preference, or route constraints?
    • Confidence: Are the relevant facts consistent, current, and supported by useful customer context?
    • Actionability: Can the person complete the next step without encountering a broken link, unavailable option, or contradictory information?

    Eligibility gets you into consideration. Fit and confidence help distinguish you from other eligible businesses. Actionability determines whether the recommendation can become a visit, booking, call, or direction request.

    Personalization adds another layer. Ask Maps can use a person’s search and save history, so two people may receive different recommendations for similar questions. It can also surface route information, directions, estimated arrival details, and tips informed by a community of more than 500 million contributors. There is no single universal Ask Maps position that every customer will see.

    Make your Maps profile answer the customer’s next question
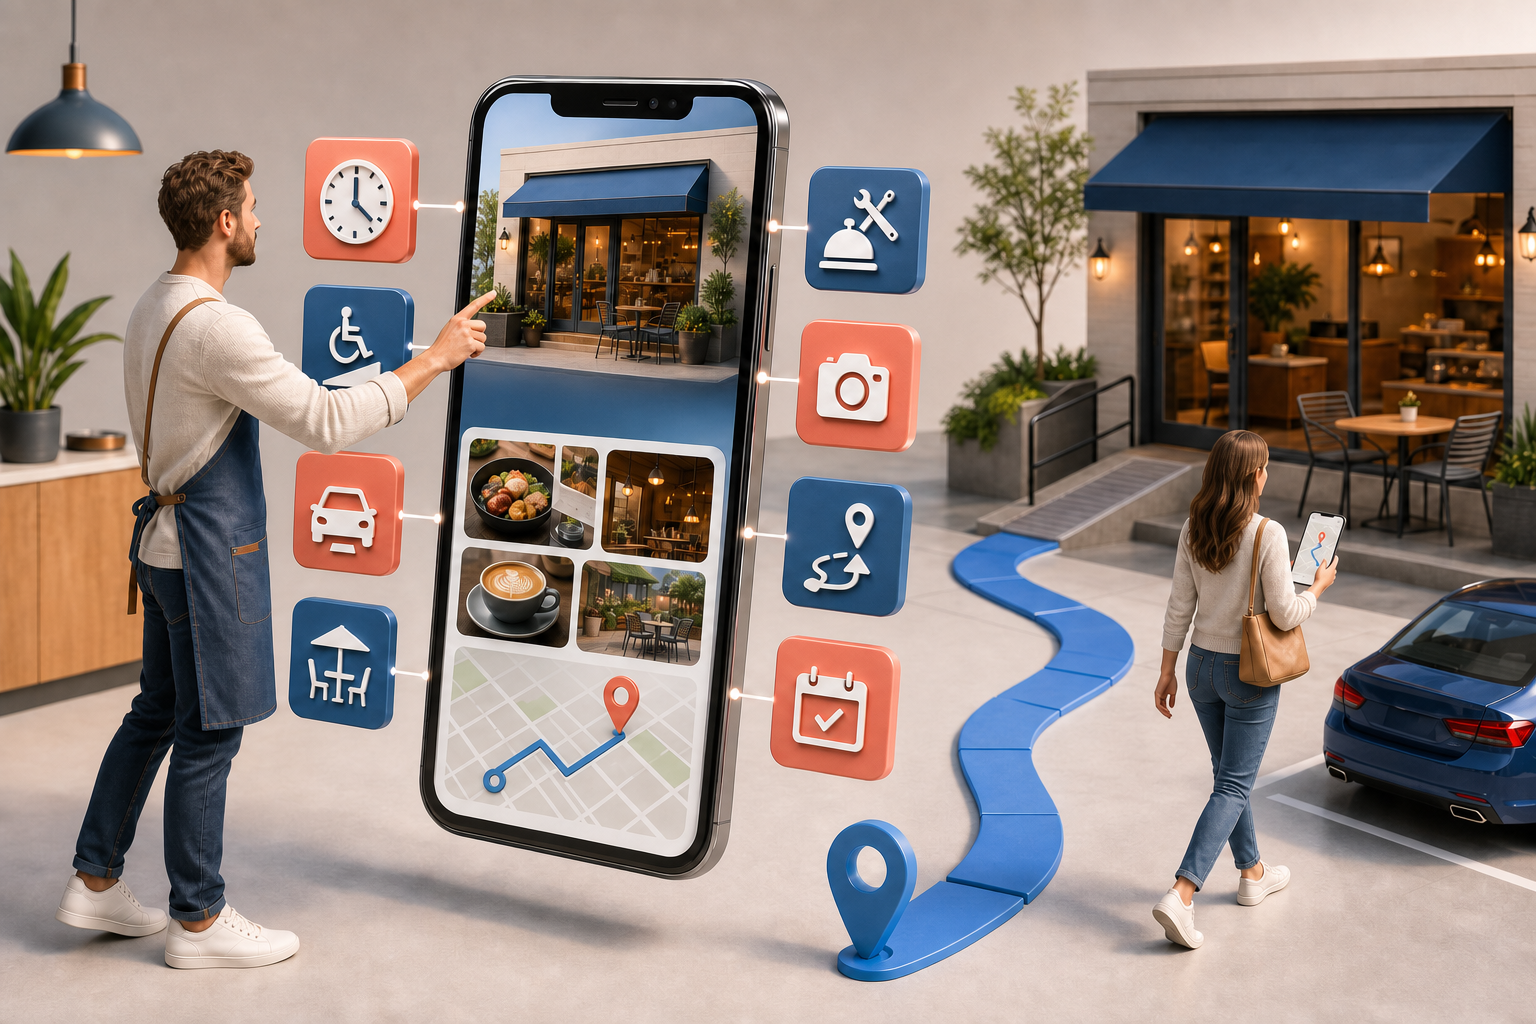
    A business owner updates a map profile surrounded by symbols for hours, accessibility, parking, amenities, directions, and booking.

    Your Google Maps presence should do more than identify the business. It should resolve the follow-up questions a customer would normally ask before choosing it. Start with the facts you directly control, then examine the customer-generated context surrounding them.

    Audit the facts you control

    1. Confirm the canonical identity. Use the real business name, primary category, address or service area, phone number, and official website. Do not add promotional phrases or location keywords to the business name.
    2. Describe the actual offer. Select the most accurate categories and complete the applicable product, service, menu, or description fields. A broad category may establish eligibility, but specific services help establish fit.
    3. Keep availability dependable. Check regular hours, special hours, appointment requirements, and temporary changes. A recommendation for tonight is only useful if the customer can rely on the availability shown.
    4. Complete relevant attributes. Record supported amenities, accessibility information, reservation options, service modes, and other fields available for your business type. Do not select an attribute merely because customers search for it.
    5. Verify every action path. Test the website, call, directions, menu, ordering, and reservation links visible on the listing. The landing page should open the relevant location or service rather than forcing the customer to start again.
    6. Use current, representative media. Photos should help a person verify the entrance, environment, products, facilities, or amenities that affect the decision. Remove or replace media you control when it no longer represents the experience.

    Focus on decision-changing facts. A public tennis facility, for example, should make lighting, access, availability, and reservation requirements clear wherever the applicable fields allow it. A restaurant should not stop at its cuisine category if dietary suitability, booking, service mode, or opening hours are the details that determine whether it fits a request.

    Do not hide a qualification. If an amenity is available only in part of the venue, during limited hours, or by prior arrangement, state that plainly on the website and in any profile field that can represent it accurately. A precise limitation is more useful than an attractive claim that produces a failed visit.

    Build useful review context without scripting customers

    Reviews can add real-world context that controlled business descriptions cannot. They may reveal which services people used, what conditions they encountered, and which details mattered during the visit. That makes a healthy body of honest, specific reviews more useful than a collection of repetitive compliments.

    Ask customers for an honest account of their experience, not a required keyword or prewritten sentence. Neutral prompts such as What was most useful about your visit? or Is there anything another customer should know before arriving? leave the substance with the reviewer. Never manufacture reviews or ask people to claim they used a service they did not use.

    Read reviews as a data-quality queue. When several customers mention confusing parking, an outdated menu, inaccessible directions, or a service that is difficult to locate, correct the underlying information. If a review contains a factual mistake, respond calmly with the accurate detail and update your controlled pages if the confusion is understandable.

    There is no dependable Ask Maps threshold for a particular review count or rating. Treat reviews as evidence and customer feedback, not as a number you can mechanically convert into conversational visibility.

    Keep your profile, website, and JSON-LD consistent
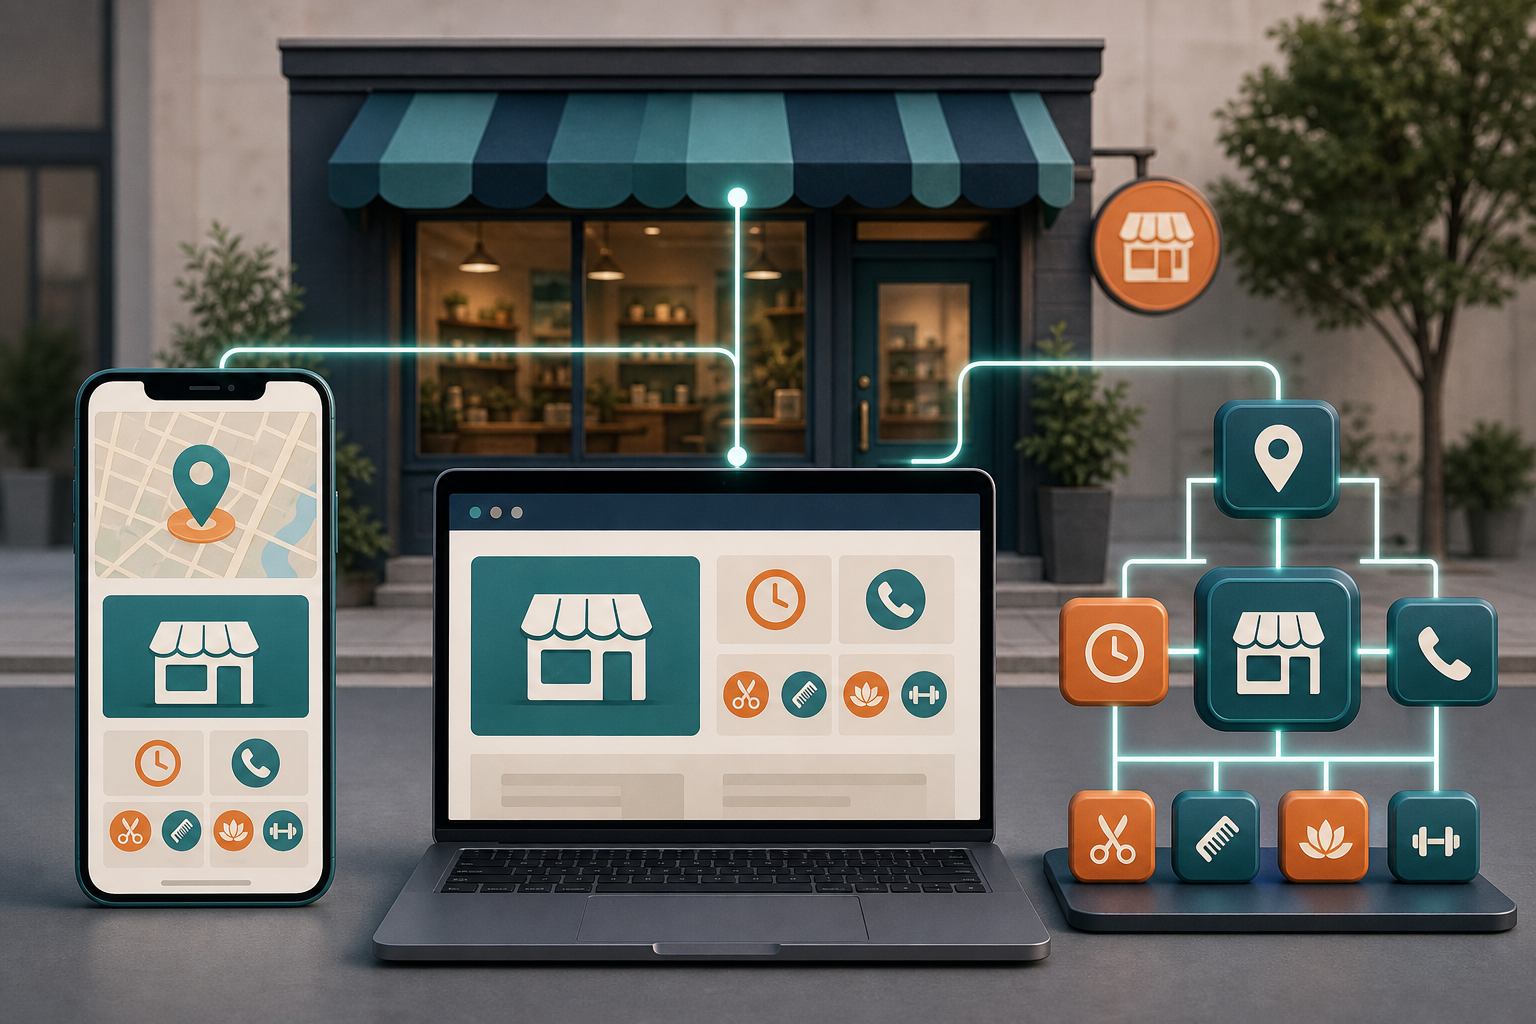
    A storefront connects to matching location, hours, contact, and service symbols on a phone, laptop, and structured data network.

    Your Maps listing, visible website content, and structured data have different jobs. They should describe the same business reality without being identical copies of one another.

    Information layerPrimary jobWhat to includeCommon failure
    Google Maps and Business ProfileProvide immediate local facts and actionsIdentity, category, location, hours, applicable attributes, contact details, and booking or direction pathsIncomplete fields, stale hours, duplicate listings, or broken actions
    Location pageExplain details that require contextServices, restrictions, amenities, arrival instructions, availability, policies, and a clear next stepGeneric copy that does not answer location-specific questions
    JSON-LDRestate supported facts in a machine-readable formBusiness type, name, URL, telephone, address, hours, and relevant supported propertiesMarkup that conflicts with visible content or describes unavailable features
    Customer reviewsDescribe observed experiencesUnscripted details about actual visits, services, conditions, and outcomesManipulated, repetitive, irrelevant, or unanswered feedback

    Use a dedicated page for each real location. The page should identify what is offered there, where it is, when it is available, which important constraints apply, and how the visitor can act. A generic corporate page that merely lists city names gives both customers and machines little evidence about the individual location.

    Write nuanced facts in visible page copy before trying to encode them. If evening access ends earlier than the venue’s general opening hours, explain that limitation where a visitor can see it. Structured data should support visible, accurate information rather than introduce a more favorable version of the business.

    For JSON-LD, choose the most specific LocalBusiness subtype that accurately represents the location. Common factual properties include name, url, telephone, address, and openingHoursSpecification. Add business-specific properties only when they apply and are supported by the page. Restaurant properties such as servesCuisine, menu, and acceptsReservations, for example, should not be copied into unrelated business types.

    Do not promise that adding LocalBusiness JSON-LD will earn an Ask Maps recommendation. Schema can make website facts explicit; it cannot prove that Gemini will select the business for a personalized request. Treat structured data as corroboration and entity clarification, not as a hidden command to the recommendation system.

    Consistency matters more than repetition. If Maps shows one closing time, the location page shows another, and JSON-LD contains a third, the solution is not to choose the most SEO-friendly version. Determine the real operating time, correct every controlled surface, and establish one internal source of truth for future updates.

    Avoid creating thin pages for every conceivable conversational query. One detailed location page can answer many situations when it organizes accurate information clearly. Separate pages make sense when the underlying offer, place, audience need, or conversion path is genuinely distinct.

    Test scenarios instead of chasing one Maps position

    Conventional rank tracking asks where a business appears for a fixed keyword at a fixed point. Ask Maps requires a broader test because wording, timing, route, location, and personal history can change the answer. Your objective is to find out whether Google understands the situations your business can truthfully satisfy.

    Build prompts from actual customer decisions using this pattern:

    intent + hard constraint + time or context + location or route + desired action

    A recreation venue might test a request for a public court with lighting that can be used in the evening. A restaurant might test a dietary preference, neighborhood, reservation requirement, and arrival time in the same question. A route-based business might test whether it is a suitable stop without forcing the traveler to leave the planned journey.

    Use scenarios that reflect profitable or strategically important customer needs, but keep every constraint truthful. There is little value in being considered for a high-intent request that the location cannot reliably fulfill.

    1. Write down the exact question. Small wording changes can alter which constraint receives the most weight.
    2. Record the test context. Note the location, time, route context, device, and relevant search or save history rather than treating the response as neutral.
    3. Capture the complete result. Record which businesses appear, which facts the answer cites, which pins are shown, and which actions are offered.
    4. Check factual accuracy. Look for wrong hours, missing services, mistaken attributes, outdated links, or ambiguity about the correct location.
    5. Trace each issue to a controlled surface. Correct the Maps profile, location page, structured data, booking flow, or internal operating record responsible for the gap.
    6. Retest under comparable conditions. Treat movement as directional evidence, not proof that a single edit caused a universal ranking change.

    Maintain an observation log with the query, context, recommendation set, cited details, available actions, factual errors, and changes made. This produces a more useful record than a screenshot labeled only with a rank.

    Classify what you see before deciding what to change:

    • If the business is absent and a required fact is missing, complete or correct that fact first.
    • If the business appears for a poor-fit scenario, look for an overly broad category, ambiguous service description, or outdated customer-facing information.
    • If the business appears but the answer cites the wrong detail, repair the canonical information across controlled surfaces.
    • If the recommendation is accurate but the action fails, fix the booking, calling, website, or directions path before doing more visibility work.
    • If the profile is accurate and the business still does not appear, do not invent a feature or manipulate reviews. Continue improving legitimate local evidence and assess the pattern across several relevant contexts.

    Measure business outcomes conservatively. Direction requests, calls, reservations, visits, and location-page conversions matter, but do not label every change as Ask Maps traffic unless the available analytics actually identify it. Recommendation inclusion, factual accuracy, and working actions are useful leading indicators; completed customer actions are the outcome.

    Key takeaways

    • Optimize for customer situations, not isolated local keywords. Ask what intent, constraints, context, timing, location, and action a recommendation must satisfy.
    • Make the Maps profile operationally complete. Accurate hours, categories, attributes, service details, and action links determine whether a recommendation remains useful.
    • Encourage honest, specific reviews without scripting customers. Use recurring confusion in reviews to improve controlled business information.
    • Keep the Maps listing, location page, and JSON-LD aligned with one real source of truth. Schema should clarify supported facts, not promise selection.
    • Test realistic prompts and record personalization context. An Ask Maps response is an observation under particular conditions, not a universal rank.
    • Fix failed actions as seriously as missing visibility. A recommendation that leads to an unavailable service or broken booking path does not serve the customer.

    Start with the highest-value situation your location genuinely serves. Write the customer’s full question, inspect whether your profile and location page answer every constraint, correct the first material gap, and test the scenario again. That turns Ask Maps optimization into a manageable data-quality practice rather than a guessing game about AI.
    References

  • How Tripadvisor Supports Local SEO for Travel Businesses

    How Tripadvisor Supports Local SEO for Travel Businesses

    If you market a hotel, restaurant, tour, or attraction, a weak Tripadvisor listing can shape the decision before a traveler reaches your website. The platform can occupy valuable search-result space for your business name, appear during category discovery, and expose reviews, photos, and business details while the customer is deciding where to book.

    Your goal is not to make Tripadvisor the center of your local SEO strategy. It is to manage the listing as one coordinated part of your search presence: accurate business facts, a clearly described experience, fresh evidence, useful customer language, and a credible path from discovery to action.

    Tripadvisor influences discovery before it influences rankings

    Tripadvisor performs three jobs at once. It is a search result, a comparison marketplace, and a reputation page. That combination matters because travelers visiting it are often beyond general inspiration and actively comparing places, experiences, or meals.

    The scale is difficult to dismiss: Tripadvisor receives about 490 million monthly visits. Its large, programmatically structured collection of indexable destination, category, and business pages also gives it substantial visibility in conventional search results. In some tourism and hospitality searches, a Tripadvisor listing can even appear above the business’s own website.

    That does not mean optimizing Tripadvisor will directly raise your website or Google Business Profile rankings. There is no defensible reason to report it as a guaranteed ranking shortcut. Its local SEO contribution is broader and more practical:

    • Search-result coverage: A complete listing gives searchers a credible third-party result when they look for your brand, location, or business type.
    • Internal discovery: Categories, tags, reviews, and profile content help Tripadvisor understand where the business belongs within its own marketplace.
    • Entity consistency: Matching identity information across Tripadvisor, your website, and Google Business Profile reduces ambiguity about which business each page represents.
    • Decision support: Current photos, detailed reviews, and clear descriptions answer questions that might otherwise stop a booking.
    • Qualified referral traffic: Visitors who reach your website after comparing options on Tripadvisor may arrive with stronger intent than someone conducting broad destination research.

    Tripadvisor can also contribute to AI discovery, but the mechanism should be described carefully. Detailed profile text and factual owner responses create more explicit language about your amenities, audience, setting, and experiences. That gives AI-driven search systems more context to interpret; it does not guarantee that an AI answer will mention or recommend you. For AEO and GEO, prioritize clear passages and verifiable details, not inserted keyword strings.

    Fix identity, duplicates, categories, and tags before polishing copy

    Isometric illustration of duplicate map listings merging into one organized listing for a boutique inn.

    A beautifully written description cannot repair a fragmented business identity. Begin with the fields that determine which entity the listing represents and where it can be discovered.

    1. Look for duplicate and outdated listings. Search Tripadvisor and conventional search results using the exact business name, previous names, address, and common variations. Do this before creating anything new. A duplicate can divide attention, reviews, photos, and brand signals between competing pages.
    2. Claim and verify the correct listing. Use the profile representing the current operating business. Resolving duplicates can require official business documents and information that matches Google Business Profile, so keep the legal and customer-facing identity records available.
    3. Align the core facts. Check the operating name, address, website, primary business type, and other defining details against your website and Google Business Profile. Consistency means the facts agree; it does not mean every platform needs an identical marketing description.
    4. Select accurate categories and tags. Represent the full set of experiences the business genuinely provides. Tripadvisor uses these classifications for internal discovery and curated collections, so an omitted attribute can prevent an otherwise suitable business from appearing in a relevant list.
    5. Complete the decision-making fields. Describe the experience, amenities, menu, and other material offerings that a prospective guest needs to understand. Remove details that are no longer true.
    6. Review the public page as a customer. Confirm that the lead image, summary information, categories, and recent customer feedback create one coherent expectation. Owner dashboards can hide how disconnected a listing feels when its public elements are viewed together.

    Do not add categories merely because they attract desirable searches. If the listing claims a romantic dining experience, family-oriented amenity, or particular type of cuisine, the photos, menu, description, and customer feedback should support that claim. A misleading classification may win an impression but lose the booking when the visitor inspects the page.

    Use this priority order when resources are limited: correct identity, remove duplication, choose the right categories, update the offer, refresh the visual evidence, and then refine promotional wording. The early steps determine whether the right listing can be found; the later steps help it convert.

    Reviews and images should explain the experience, not decorate it

    Traveler photographing a guide presenting a regional dish to a small group inside an independent restaurant.

    Write owner responses that add useful context

    A review response is not only reputation management. It is public content attached to a specific customer experience. A thoughtful reply can turn a vague mention into a clearer explanation of what the business offers.

    If a guest says only that the pool was enjoyable, for example, a useful response can acknowledge the comment and mention a relevant family feature or activity, provided that feature genuinely exists. This creates additional semantic context around the property’s amenities. The response should still sound like a reply to a person, not a paragraph built to carry search terms.

    A reliable response structure is:

    • Acknowledge the specific experience. Refer to what the customer actually mentioned instead of opening with a generic template.
    • Add one relevant clarification. Explain a feature, setting, audience, or use case that helps the next reader understand the experience. Only add details you can substantiate.
    • Close naturally. Keep the response proportionate to the review. Repeating the business name, location, and service keywords adds clutter rather than value.

    You can also encourage more informative reviews without scripting praise. After the visit, invite the customer to describe which experience they booked, what stood out, who the experience suited, or what they would tell another traveler. That produces more decision-useful language than asking only for a star rating.

    Review velocity matters as an operational signal, but do not confuse velocity with sudden volume. The sustainable objective is a continuing stream of feedback from real customers, followed by regular owner attention. A burst of requests followed by months of silence leaves the listing looking less current and gives you fewer recent customer questions to learn from.

    Use current images as evidence of what someone can book

    Travel and hospitality decisions are visual. The strongest images quickly show what the guest will receive: the room, dish, view, activity, atmosphere, or defining feature. Replace photos that show an old menu, previous decor, unavailable amenities, or an experience that no longer represents the business.

    You do not need to guess which creative deserves the lead position. If you already publish comparable photos on Instagram, use the engagement data as a directional signal for which subjects and compositions attract attention, then confirm that the selected image accurately represents the bookable experience. Popularity is useful only after accuracy.

    Captions should describe the image in natural language. A practical formula is: what is shown, where or how it is experienced, and who or when it may be relevant. For example, a dish caption can identify the meal, the terrace or dining setting, and the season in which it is offered. Include audience claims such as “popular with solo travelers” only when you have a real basis for them. A string of location and service keywords does not help a traveler understand the image.

    Manage Tripadvisor as a measurable local search channel

    Profile optimization becomes difficult to defend when the only metric is average rating. Rating matters to customers, but it does not tell you whether the listing is accurate, discoverable, engaging, or sending qualified demand.

    Track the channel in layers:

    • Presence: Record whether the correct Tripadvisor page appears for your business name and relevant local discovery searches. Note duplicate or outdated results separately.
    • Profile health: Monitor completeness, category accuracy, current menu or experience information, image freshness, and unanswered-review backlog.
    • Activity: Watch review velocity, owner response activity, new image publication, and recurring themes in customer language.
    • Engagement: Use the interaction and click information available to the account to identify whether people are moving beyond a listing impression.
    • Business outcomes: In your web analytics, segment Tripadvisor referral visits and evaluate them against the booking, reservation, enquiry, or purchase action that matters to the business.

    Capture a baseline before making a substantial change. Compare equivalent reporting periods and annotate major profile updates, promotions, closures, and seasonal offer changes. This will not prove that a single caption or response caused a result, but it will prevent you from attributing every movement to the most recent edit.

    Website traffic is only one part of the journey. Tripadvisor also functions as a comparison environment where a customer may make a decision without visiting your domain. Read referral traffic alongside profile engagement and actual bookings rather than declaring the channel successful or unsuccessful from sessions alone.

    A manageable recurring workflow is to inspect identity fields and duplicates, clear the review-response backlog, replace outdated images or offer information, record emerging customer themes, and review referral outcomes. Assign ownership to a person or role. A listing that belongs vaguely to “marketing” is likely to remain untouched until a negative review or incorrect detail creates urgency.

    Key takeaways

    • Use Tripadvisor as a distributed local landing page and comparison surface, not merely a place to collect ratings.
    • Resolve duplicate listings and align core identity information with your website and Google Business Profile before rewriting promotional copy.
    • Choose categories and tags for experiences the business actually delivers; those classifications affect internal discovery and customer expectations.
    • Respond to reviews with one useful, factual layer of context instead of inserting keywords or repeating a template.
    • Refresh images, captions, menus, and experience details whenever the public offer changes.
    • Measure profile health, engagement, qualified referral traffic, and business outcomes separately so you can see where the journey is improving or breaking.

    Start with a duplicate and identity audit of the listing that already exists. Once the correct entity is established, improve one decision layer at a time: classification, offer clarity, reviews, images, and measurement. That sequence turns Tripadvisor from an unmanaged reputation page into a useful part of your local search system.

    References

  • AI Search Visibility Starts With Five Technical SEO Gates

    AI Search Visibility Starts With Five Technical SEO Gates

    You published a useful page, submitted it for discovery, and confirmed that it loads in a browser. Yet your brand still disappears when an AI system answers the questions that page was built to solve. Rewriting the introduction or adding another block of schema may feel productive, but either move can target the wrong layer.

    Before your content can win on relevance, authority, or corroboration, its meaning has to reach the system intact. Audit that journey in sequence. Find the earliest failure, repair it, and only then work on the prompts and competitive signals that determine whether the page is used in an answer.

    AI visibility is a chain, not a single ranking event

    The familiar instruction to “crawl and index” compresses several different decisions into one checkbox. In practice, content must pass through discovery, selection, crawling, rendering, and indexing. Each gate asks a different question:

    • Discovery: Does the system know that the URL exists and how it relates to the rest of your site?
    • Selection: Is the URL worth fetching relative to the other URLs competing for attention?
    • Crawling: Can the system retrieve the page reliably?
    • Rendering: Does the retrieved version contain the main content, links, and facts?
    • Indexing: Can the system identify and retain the page’s essential meaning?

    These gates are sequential, but their failures don’t always look dramatic. A page can be fetched successfully while its main explanation remains trapped behind JavaScript. It can then be indexed from a thin or misleading representation. Your monitoring may show an accessible URL even though the information needed for an AI answer never survived.

    That distinction changes what you do next. If the URL hasn’t been discovered, editing the copy won’t help. If the initial response omits the core answer, additional authority signals won’t restore it. If the indexed representation is accurate but the page still isn’t selected for relevant prompts, you can move downstream to task coverage, corroboration, and authority.

    Indexing is therefore a prerequisite, not proof of AI visibility. AI systems don’t share one index or one diagnostic console, and evidence from a traditional search engine doesn’t confirm inclusion everywhere else. Record what you can confirm for each system, mark what remains unknown, and avoid turning an assumption into a passing audit grade.

    Audit the five infrastructure gates in order

    An isometric pathway shows five technical checkpoints, with a diagnostic light stopping at the first blocked gate.

    Start with one commercially or strategically important URL. A sitewide score can hide the failure you need to see, while a single-URL evidence sheet forces each conclusion to be testable. Use the following sequence as your first-pass audit.

    GateQuestion to answerUseful evidenceFirst corrective action
    DiscoveryCan systems find the URL and connect it to a known topic or entity?Current XML sitemap, IndexNow submission where supported, contextual internal links, relevant hub placementRemove orphan status and create a clear route from an established page
    SelectionWhy should this URL be fetched instead of another URL?Sitemap quality, duplication patterns, stale inventory, competing variants, internal-link prominenceReduce discovery noise and consolidate pages that perform the same task
    CrawlingCan the intended machine client retrieve the URL reliably?Server logs, access rules, HTTP response, redirects, authentication, rate limitsRemove the access or response failure before changing the content
    RenderingDoes the retrievable version contain the main answer?Initial response HTML, rendered output, JavaScript-disabled view, extracted text and linksDeliver essential content in server-generated HTML
    IndexingCan a machine identify the page’s subject, entities, claims, and relationships?Heading outline, semantic markup, text extraction, structured data, stored search representation where availableClarify the main topic and make visible content agree with the markup

    Discovery: remove orphan status

    Discovery is signal-based. XML sitemaps and supported submission mechanisms can announce a URL, but internal links explain where it belongs. A page that appears only in a sitemap may be technically known while remaining weakly associated with your products, expertise, or topic clusters.

    • Confirm that the intended URL is present in the current sitemap and resolves to the page you expect.
    • Link to it from at least one established, relevant page using anchor text that describes the destination.
    • Place it within the appropriate topic, product, documentation, or resource hub rather than relying on a generic archive.
    • Use IndexNow when it fits your platform and the receiving system supports it, especially after meaningful publication or revision events.
    • Check that the page names its primary entity and subject consistently with the pages linking to it.

    The practical test is simple: begin on a page that already represents the topic and follow ordinary links to the target. If you can reach it only through a sitemap, an internal search box, or a manually pasted URL, discovery needs work.

    Selection: stop making every URL look equally important

    Discovery adds a candidate; selection determines whether that candidate receives attention. This is where oversized inventories become a technical SEO problem. Facets, parameter combinations, near-duplicate location pages, expired material, and lightly altered variants can consume signals without adding distinct value.

    For crawl selection, less can be more. That isn’t permission to delete URLs blindly. It is a reason to decide which pages perform unique audience tasks and which merely repeat an existing answer.

    • Group URLs by the task they solve, not merely by their keyword variation.
    • Flag pages whose purpose, answer, and supporting evidence substantially overlap.
    • Keep discovery feeds focused on URLs you genuinely want systems to process.
    • Consolidate overlapping information where one stronger page can satisfy the task without erasing a necessary user path.
    • Give important pages stronger contextual links instead of treating every item in a large archive as equal.

    If several pages compete to define the same entity or answer the same question, the problem isn’t a lack of content. It is an excess of ambiguous choices.

    Crawling: verify retrieval rather than assuming it

    A browser visit proves that your browser can retrieve the page under your conditions. It doesn’t prove that every machine client can do the same. Access rules, authentication, rate controls, redirect behavior, and unstable server responses can affect automated retrieval differently.

    • Inspect server logs when available to determine whether the relevant client requested the URL and what happened.
    • Check that automated access isn’t blocked by authentication, consent handling, security middleware, or bot controls.
    • Follow the complete redirect path and confirm that it ends on the intended content.
    • Test the response without browser cookies, cached assets, or an authenticated session.
    • Separate a retrieval failure from a rendering failure: receiving HTML doesn’t prove that the HTML contains the answer.

    When you can’t directly observe a particular AI crawler, record the status as unknown rather than passed. Use the server and retrieval evidence you do have, then make the page robust enough that it doesn’t depend on a privileged browser session.

    Rendering: inspect what arrives before JavaScript runs

    Rendering is often the hidden break. Modern browsers assemble pages from scripts, APIs, templates, and client-side components. Not every system invests in executing JavaScript, and those that do may not reproduce the same result as a user’s browser.

    Run a content-survival test:

    1. Retrieve the initial HTML returned by the server.
    2. Locate the page’s main answer, defining facts, entity names, headings, comparison data, and contextual links.
    3. Compare that material with the fully rendered browser version.
    4. Disable JavaScript and repeat the comparison.
    5. Classify every missing item as essential content, useful enhancement, or interaction-only functionality.

    Move essential content into server-generated HTML. Server-side rendering is one route; the implementation matters less than the result. The main answer, supporting facts, meaningful link relationships, and labels needed to interpret data should exist before client-side enhancement.

    This isn’t a ban on JavaScript. Filters, calculators, personalization, and interface behavior may legitimately depend on it. The mistake is making JavaScript the only delivery route for the information you expect machines to quote, compare, or recommend.

    Indexing: make the essential meaning unmistakable

    After retrieval and rendering, a system still has to decide what the page is about and which information deserves storage. A technically complete page can remain difficult to interpret if its topic is implied, entity names change between sections, visual position carries the meaning, or the main answer is buried among navigation and promotional copy.

    • State the page’s primary subject and purpose near the beginning.
    • Use descriptive headings whose sections answer distinct parts of the task.
    • Name entities consistently instead of alternating among unexplained labels.
    • Represent real relationships with semantic elements: lists for sequences, tables for tabular comparisons, and links for navigable connections.
    • Give data and claims explicit labels so they remain intelligible after visual layout is removed.
    • Make structured data agree with the visible page rather than introducing a second, conflicting version of the facts.

    Read the page as extracted text, without its design. If you can no longer tell which value belongs to which product, which condition qualifies a recommendation, or which entity a pronoun refers to, conversion into an indexable representation is likely to lose confidence.

    Deliver the meaning before adding more schema

    Structured data is valuable when it confirms an already coherent page. It can clarify entity types and relationships, but it can’t compensate for a URL that wasn’t selected, content that wasn’t retrieved, or an answer that exists only after an unreliable rendering step.

    Use this order of operations:

    1. Put the complete core answer in the HTML delivered by the server.
    2. Organize that answer with meaningful headings, paragraphs, lists, tables, and links.
    3. Use explicit entity names and relationship language in the visible copy.
    4. Add JSON-LD that describes the same entities, properties, and relationships.
    5. Validate the markup, then compare it with the rendered and extracted page for factual consistency.

    Passing a structured-data validator confirms syntax and recognizable fields. It doesn’t prove that an AI system discovered the URL, retained the content, trusts the claim, or will select the page for an answer. Keep validation in its proper place: it is a markup check inside a larger delivery and interpretation audit.

    Pay particular attention to information encoded visually. A row of feature icons, a color-coded pricing grid, or a diagram with unlabeled connections may be obvious to a person while becoming ambiguous in text conversion. Repeat consequential labels in machine-readable text and use a real table when the information genuinely has rows and columns.

    Alternative machine-facing pathways such as WebMCP, Markdown for Agents, or Cloudflare-provided markup may also be worth evaluating for your stack. Treat them as additional delivery routes to test, not universal substitutes for accessible HTML. Before relying on one, verify that the intended recipient can retrieve it, that it carries the complete answer, and that its facts stay synchronized with the public page.

    Build for prompt fan-out without publishing endless pages

    A central knowledge hub branches toward many question-shaped nodes while connecting to a small set of substantial pages.

    Once the infrastructure works, the optimization question changes. People no longer have to compress every need into a neat keyword. They can include their situation, constraints, doubts, preferences, and desired outcome in one request. This creates an effectively infinite tail of prompt variations.

    Keyword research still has a role. It reveals recognizable language and established demand. What it can’t do alone is model all the ways a person frames a task or all the subquestions an AI system may generate while building an answer.

    Replace the keyword-only map with a task map:

    1. Write the real task the reader is trying to complete.
    2. Identify the reader’s stage: learning, diagnosing, comparing, deciding, implementing, or verifying.
    3. List constraints that change a useful answer, such as platform, resources, risk tolerance, or an existing technical limitation.
    4. List the uncertainties that block the next decision.
    5. Break the task into the subquestions a careful evaluator would need answered.
    6. Assign each subquestion to a page or a clearly labeled section.
    7. Identify what evidence would reduce uncertainty: definitions, mechanisms, comparisons, limitations, examples, or external corroboration.

    Consider a reader asking, “Our documentation ranks in search but stopped appearing in AI answers after a JavaScript redesign. Should we rewrite it or change the site?” The wording is only one possible prompt. The durable task contains several subquestions: Can systems discover the documentation? Is it selected for retrieval? Does the initial response contain the text? Does rendering preserve links and labels? Is the indexed meaning accurate? Do other credible pages corroborate the important claims?

    A page that answers those subquestions in a logical sequence can support many prompt variations without repeating the exact sentence. A collection of thin pages targeting minor wording changes may do the opposite: increase crawl-selection noise while splitting the evidence needed to complete the task.

    Prompt fan-out also changes how you think about authority. Complex requests can be decomposed into multiple queries, while grounding queries check consistency and reputation across the wider web. Schema can describe your claim, but it can’t make several pages on your own domain count as independent confirmation.

    You can still reduce uncertainty. Keep names, descriptions, product facts, and definitions consistent across your site. Link supporting material to the claim it substantiates. Correct conflicting legacy pages. Make primary evidence easy to retrieve. Then pursue genuine external validation where the decision warrants it. Technical clarity helps a system understand your evidence; independent corroboration helps it decide how much confidence to place in that evidence.

    Track infrastructure and competitiveness separately

    Mixing the two layers produces misleading reports. Maintain one scorecard for URL survival and another for answer eligibility.

    • Infrastructure scorecard: discovery signals present, retrieval observed or unknown, essential content in the initial HTML, rendered content complete, extracted meaning accurate, structured data consistent.
    • Competitive scorecard: audience task defined, prompt constraints covered, fan-out subquestions answered, claims supported, entity facts consistent, external corroboration present, next action clear.

    Use confirmed, failed, and unknown as status values. A false pass is more damaging than an honest unknown because it sends the team downstream to rewrite content or build authority around a page whose evidence may not be reaching the system.

    Key takeaways

    • AI search visibility begins with five sequential infrastructure gates: discovery, selection, crawling, rendering, and indexing.
    • A successful fetch doesn’t prove that the main answer survived rendering or that the stored representation is accurate.
    • Audit the earliest possible failure first; downstream content and authority work can’t recover information that never arrived.
    • Serve essential meaning in initial HTML, organize it semantically, and use JSON-LD to confirm the visible facts.
    • Plan around audience tasks and fan-out subquestions rather than publishing a separate page for every prompt variation.
    • Measure technical survival separately from competitive selection, corroboration, and authority.

    Your next move is a one-URL audit. Choose a page that matters, create an evidence row for every gate, and stop at the first failure you can prove. After the complete answer survives extraction, map one audience task and its subquestions against the page. That sequence gives every later SEO, AEO, GEO, and schema decision something solid to build on.

    References

  • A Practical ChatGPT Shopping Strategy for Ecommerce Brands

    A Practical ChatGPT Shopping Strategy for Ecommerce Brands

    If your shopping plan starts and ends with getting products into a native ChatGPT checkout, it is aimed at a moving target. The more durable opportunity is to help ChatGPT understand your products, select them for the right shopping questions, and send an informed buyer into a purchase path that works.

    That distinction matters because OpenAI is reportedly moving Instant Checkout into Apps within connected services while putting more emphasis on product search and discovery. Your strategy should therefore separate AI discovery from transaction execution, then make the handoff between them consistent, trustworthy, and measurable.

    Treat ChatGPT as a decision channel, not merely a checkout

    A shopper rarely begins with your product identifier. They begin with a constraint: a budget, use case, compatibility requirement, delivery concern, size, material, feature, or reason another option did not work. ChatGPT can influence which products enter the shortlist before the shopper reaches a retailer.

    Build around three separate jobs:

    • Eligibility: Give AI systems enough accurate product information to determine when an item fits the request.
    • Selection: Supply clear evidence, limitations, comparisons, and policies that help the shopper choose among plausible options.
    • Conversion: Preserve the selected product, variant, price, and context when the shopper moves to your site or connected app.

    Do not combine these jobs into a single metric. A product can be recommended but lose the sale during the handoff. It can receive qualified visits but fail because the product page contradicts the information used during discovery. It can also convert well once visited yet remain absent from relevant AI answers because its differentiators are vague or inaccessible.

    This is not a theoretical distinction. OpenAI found that people were exploring products in ChatGPT but often completing purchases elsewhere, while only a handful of merchants fully used native ChatGPT checkout. That does not prove the same behavior in every category, but it is a strong reason not to make native checkout adoption your only definition of progress.

    Use a measurement ladder instead. Monitor whether your products appear for a stable set of relevant shopping questions. Track identifiable traffic from AI surfaces when a referrer, campaign parameter, or app link survives the handoff. Measure product-detail views, variant selections, add-to-cart actions, checkout starts, and purchases. Add a post-purchase discovery question if your analytics cannot observe the complete journey. Keep those signals separate so that a weak checkout does not get mistaken for weak discovery.

    Build a product truth layer before creating more content

    Three unbranded products sit above connected layers of color, size, material, inventory, compatibility, and shipping symbols.

    AI shopping optimization breaks when the same product has different facts across its page, structured data, feed, app, and checkout. A persuasive description cannot compensate for conflicting prices, ambiguous variants, or stale availability. Establish one operational product record and make every public representation inherit from it.

    For each product and variant, maintain the fields a buyer actually needs to make a decision:

    • A stable product identifier, variant identifier, canonical URL, and exact product name.
    • Brand, category, intended use, defining features, dimensions, materials, compatibility, and other category-specific attributes.
    • Current price, currency, availability, condition, and a clear relationship between the parent product and its variants.
    • Images that correspond to the selected variant rather than a generic family image.
    • Shipping scope, fulfillment limitations, return conditions, warranty terms, and any purchase restrictions that can change the decision.
    • Evidence for material claims, with unsupported superlatives and vague labels removed.

    Use Product and Offer JSON-LD to represent applicable facts in a machine-readable form, but treat markup as a copy of the truth rather than a separate marketing layer. The name, price, currency, availability, URL, image, brand, SKU, and offer details in the markup should agree with the visible page. If a rating, price range, or availability claim is not supported on the page, do not manufacture it in structured data.

    JSON-LD is also not an inclusion switch for ChatGPT. It reduces ambiguity and gives machines a cleaner representation of the page; it does not guarantee that a product will be discovered, recommended, or ranked. Visible product copy still needs to explain fit, tradeoffs, and purchase conditions in language a shopper can understand.

    Catalog synchronization deserves the same attention as schema. Normalizing real-time catalog information across large numbers of SKUs remains an infrastructure problem. Prevent it from becoming a customer-facing problem by assigning ownership for every field, documenting which system is authoritative, and defining what happens when feeds disagree.

    Before expanding the work, run a sampled audit that compares the visible page, rendered JSON-LD, feed output, app view, cart, and checkout. The release gate should be simple: no sampled price, currency, availability, product identity, or variant mismatch. If you cannot meet that gate, adding more discovery content will amplify unreliable information.

    Create pages around shopping constraints, not keyword permutations

    A conventional product page often describes what an item is without explaining when someone should choose it. ChatGPT shopping questions tend to expose that gap because the user can combine several conditions in one request. Your content needs to resolve those conditions explicitly.

    Build a question map from the language already present in customer support, on-site search, product reviews, returns, sales conversations, and merchandising filters. Group the questions by decision type:

    • Fit: Who is this product for, and when is another option more suitable?
    • Compatibility: What systems, sizes, accessories, materials, environments, or use cases does it support?
    • Tradeoffs: What does the buyer gain, and what must they accept in exchange?
    • Comparison: Which factual criteria distinguish this item from the closest alternatives?
    • Purchase conditions: What will shipping, setup, returns, replacement, or ongoing use require?

    Map each question to the most appropriate page instead of forcing every answer into the product description. Put item-specific facts on the product page. Use category pages to explain selection criteria. Use comparison pages when buyers repeatedly choose between named options. Use support content for setup and compatibility details, then link it directly from the commercial page.

    On a product page, answer the decision in a useful order: state the best-fit use case, show the facts supporting that fit, disclose meaningful limitations, explain the available variants, and present the purchase conditions. A clear not-suitable-for statement is often more useful than another paragraph of universal claims. It helps an AI system and a human buyer avoid a recommendation that will produce a return or a poor experience.

    Comparison content should define the decision rule before declaring a winner. If the correct choice changes with budget, environment, compatibility, or desired feature, say so. Do not create a false universal ranking merely to target a best-product query. A conditional answer is more accurate and more reusable across the specific prompts shoppers actually ask.

    Keep decisive facts in visible HTML. Structured data can reinforce those facts, but it should not contain essential claims that a shopper cannot verify on the page. The same principle applies to FAQs: publish them when they answer recurring purchase questions, not as a container for hidden keyword variants.

    Make the external handoff trustworthy and measurable

    An unbranded product crosses an illuminated bridge from an AI conversation portal to a storefront with security, delivery, and analytics symbols.

    The handoff is now a core part of ChatGPT shopping strategy. If discovery occurs in an AI conversation and the purchase occurs in a retailer app or site, any lost product context creates friction at the point of highest intent.

    Resolve links to the exact product and selected variant whenever the originating surface provides that context. Show the same name, image, price, availability, and offer conditions the shopper just encountered. Keep return and shipping information easy to find before checkout. Avoid sending a buyer to a category page where they must reconstruct the selection from scratch.

    Trust matters alongside technical capability. Consumers are accustomed to familiar purchase processes such as Apple Pay, Google Wallet, and Amazon. An external checkout is not automatically a strategic failure if it gives the buyer a recognizable, reliable place to complete the transaction. The failure is an external handoff that changes the offer, loses the variant, hides important terms, or cannot be measured.

    Instrument the journey with a shared product and variant identifier across the landing view, variant selection, add-to-cart, checkout start, and purchase events. Add campaign parameters to links you control, but do not depend on referrer data alone. App transitions and privacy controls can interrupt the chain. Use session-level analytics, transaction data, and a customer-reported discovery field to create a more defensible view.

    Run a narrow pilot before rebuilding your commerce stack:

    1. Select a category in which buyers ask meaningful comparison or compatibility questions.
    2. Audit the product truth layer and correct disagreements across pages, schema, feeds, apps, carts, and checkout.
    3. Create or revise content for the real constraints that determine product fit.
    4. Test every discovery-to-product link, including variant resolution, offer consistency, mobile behavior, and return paths.
    5. Record baseline discovery, referral, engagement, cart, checkout, and purchase signals before judging the pilot.
    6. Review failed recommendations and abandoned handoffs as separate problems, then fix the layer responsible for each one.

    Keep the Agentic Commerce Protocol on your standards watchlist because OpenAI is continuing its work with Stripe on the protocol as transactions move toward connected-service Apps. That is a reason to preserve clean, portable product and offer data. It is not a reason to commit your full catalog or checkout roadmap before the integration can maintain product accuracy, customer trust, and usable measurement.

    Expand only when the pilot can answer three operational questions: Did the right products appear for the right constraints? Did the landing experience preserve what the shopper selected? Did qualified AI-led visits produce downstream commercial actions? If one answer is unclear, improve its measurement before scaling.

    Key takeaways

    • Optimize first for accurate product discovery and selection; native ChatGPT checkout is not the only route to value.
    • Separate eligibility, selection, and conversion so you can locate the actual failure in the journey.
    • Create one product truth layer and keep visible pages, JSON-LD, feeds, apps, carts, and checkout consistent.
    • Answer fit, compatibility, tradeoff, comparison, and purchase-condition questions in visible content.
    • Treat an external checkout as a designed handoff, preserving the exact product, variant, offer, and measurement context.
    • Pilot connected commerce narrowly and expand only after catalog accuracy, customer trust, and attribution are working together.

    Start with a narrow product category and inspect the journey from a constrained shopping question through the completed order. Fix the first point where product truth, decision support, or handoff context breaks. That work will remain useful whether ChatGPT sends the transaction to your site, a connected app, or a future commerce protocol.

    References

  • Content Structure and Technical SEO for Machine Retrieval

    Content Structure and Technical SEO for Machine Retrieval

    If a page contains the right answer but rarely becomes the answer that search engines or AI systems retrieve, topic coverage may not be the problem. The useful passage could be buried in a multi-purpose paragraph, separated from a vague heading, added only after a click, or obscured by an unnecessarily complex DOM.

    You need two conditions to hold at the same time: the answer must form a clear unit of meaning, and the rendered page must expose that unit in a structure a crawler can reach and interpret. Here is how to build and test both without turning useful prose into disconnected fragments.

    Diagnose the content layer and delivery layer separately

    Machine retrieval can fail at either of two layers. A content-layer failure makes the answer hard to isolate. A delivery-layer failure prevents the machine from reliably receiving the answer at all. Rewriting copy will not repair content that never enters the crawler’s DOM, while a rendering fix will not clarify a paragraph that tries to answer four questions at once.

    LayerTypical failureFirst check
    Content structureThe answer is scattered across sections, introduced by a generic heading, or dependent on distant context.Copy the relevant heading and passage into a blank document. Check whether they still answer the target question clearly.
    DOM structureThe heading and answer have an unclear relationship because of excessive nesting, misplaced elements, or JavaScript changes.Inspect the live DOM and confirm that the passage sits under the intended heading in a logical hierarchy.
    Content deliveryImportant text or links appear only after a click, selection, or other user action.Reload the page and check what exists before any interaction.
    Crawler accessGoogle may render the content, but another crawler that does not execute JavaScript receives an incomplete page.Compare the initial HTML, the browser DOM, and the crawler-rendered HTML.

    Start with the layer that fails. If the passage is missing after a fresh load, fix delivery first. If it is present but ambiguous outside the full page, restructure it. If both tests pass, investigate relevance, authority, and other ranking factors rather than repeatedly editing an already retrievable answer.

    Build answer-sized sections without writing fragments

    A useful content chunk is a self-contained unit centered on one idea. It is not a fixed word count, a paragraph chopped at an arbitrary length, or a collection of terse statements written to resemble search snippets. Its boundary follows a change in the reader’s question.

    Build those boundaries into the outline before drafting:

    1. Assign one job to each section. An H2 can cover a major decision or task. Use an H3 only when that task divides into a distinct question that deserves its own answer.
    2. Write the heading as a promise. Replace labels such as Overview, Details, or Implementation with language that identifies what the reader will learn. A heading such as How JavaScript-loaded content affects crawling establishes a much clearer retrieval target.
    3. Answer the heading promptly. Put the direct answer in the opening sentence or paragraph, then add the mechanism, conditions, exceptions, and next action.
    4. Keep each paragraph on one idea. Start a new paragraph when you move from definition to consequence, from consequence to procedure, or from a general rule to an exception.
    5. Use a list only when the items are genuinely parallel. Steps, criteria, checks, and alternatives belong in lists. A connected explanation still belongs in prose.

    Run the self-contained passage test

    Copy a heading and the passage immediately below it into a blank document. Do not include the title, introduction, sidebar, or preceding section. Then ask:

    • Does the heading identify the actual question or decision?
    • Does the first sentence give a direct answer rather than a transition?
    • Are important nouns named, or does the passage rely on vague references such as this, that, it, or they?
    • Does the passage contain the condition that limits the advice?
    • Can a reader act without searching the rest of the page for a missing step?

    For example, Implementation considerations followed by This can create problems is not independently useful. How interaction-dependent content affects crawling followed by Content added only after a user action may be absent from a crawler’s initial view establishes the subject, mechanism, and risk immediately.

    Preserve the reading path between chunks

    Self-contained does not mean isolated. A section should carry enough context to survive retrieval while still advancing the page’s larger argument. Keep necessary transitions, define a term before relying on it, and let supporting paragraphs deepen the answer instead of restating it.

    Do not split one coherent explanation merely to manufacture more headings. The practical case for chunking is that clear sections help people scan and give machines more precise passages to interpret. If the result feels repetitive or jerky to a reader, the boundaries are too aggressive.

    Make the content hierarchy explicit in the DOM

    An isometric document structure shows orderly nested content blocks beside a smaller cluster of tangled and disconnected elements.

    A person sees a rendered page. A crawler works with a document structure. The DOM is the browser’s in-memory tree of elements and their parent, child, and sibling relationships. Those relationships help establish which paragraph belongs to which heading and which sections belong to the main article.

    Use HTML that expresses those relationships directly:

    • Place the primary editorial content in an <article> element rather than mixing it with navigation and unrelated interface components.
    • Use heading levels to represent hierarchy, not visual size. An H3 should describe a subsection of the preceding H2.
    • Group a coherent topic in a <section> when that grouping adds meaning to the document structure.
    • Use <p> for paragraphs and real <ul> or <ol> elements for lists instead of constructing their appearance from generic containers.
    • Remove empty wrappers and repeated layout containers that make the tree deeper without adding structure.

    Semantic markup is not a substitute for relevant content, and changing a <div> to a <section> does not guarantee a ranking gain. Its value is more basic: it reduces ambiguity and makes the intended hierarchy easier to preserve across browsers, templates, crawlers, and assistive systems.

    The HTML response is only the starting point. As the browser parses that HTML into nodes, JavaScript can pause construction, add elements, replace text, or change links. The result can be a final DOM that differs materially from the original HTML.

    Keep three versions of the page distinct

    • Initial HTML: the response returned by the server before client-side scripts modify it.
    • Current browser DOM: the live tree shown in the Elements panel after scripts have run and possibly after a person has interacted with the page.
    • Crawler-rendered HTML: the version a particular crawler produced with its own rendering capabilities, timing, and interaction limits.

    These versions can match, but you should not assume they do. That distinction matters whenever a template relies on client-side rendering, delayed components, tabs, expandable panels, or JavaScript navigation.

    Test retrieval on the rendered page before publishing

    A scanning probe traces a clear path through a rendered web page and illuminates one visible, self-contained content block.

    The safest delivery rule is simple: important content should enter the DOM during the initial page load. Googlebot can parse HTML, execute JavaScript, and evaluate a rendered DOM, but it does not interact with a page as a person would. Other crawlers may not render JavaScript at all.

    This creates an important distinction for tabs and accordions. If the text is already in the DOM and the control merely changes its presentation, the content is present for inspection. If clicking the control fetches or creates the text, a non-interacting crawler may never receive it. Move essential answers into the initial render or provide an ordinary crawlable page that contains them.

    Run this release check on every important template and on any page where machine visibility matters:

    1. Choose the target answer. Write down the exact question the page should answer and identify the heading and passage intended to answer it.
    2. Reload without interacting. Confirm that the complete answer appears without a click, scroll-triggered action, selection, or form submission.
    3. Inspect the live DOM. Open browser DevTools, select Elements, and use Ctrl+F or Cmd+F to search for a distinctive phrase from the answer. Confirm that it appears once, in the intended section, under the correct heading.
    4. Inspect internal links. Important navigation should use real <a> elements with usable destinations. JavaScript event handlers that merely imitate links create avoidable crawlability risk.
    5. Check the crawler’s render. Use Google Search Console’s URL Inspection tool to examine the rendered HTML available to Google. Search that output for the same distinctive phrase, heading, and essential internal links.
    6. Use a public fallback when needed. If you do not have Search Console access, the Rich Results Test can provide a rendered-page view for investigation. Treat it as a diagnostic aid, not proof of what has already been indexed.
    7. Review DOM size. In the browser console, document.querySelectorAll('*').length provides a simple element count. Treat about 1,500 nodes as a reason to investigate unnecessary complexity, not as a universal ranking cutoff. Remove redundant wrappers and duplicated components only after confirming they are not required by the interface.

    Choose legacy pages by expected return

    You do not need to rechunk an entire archive at once. Start with high-value pages where structure is most likely to be limiting performance:

    • Pages with meaningful traffic but weak engagement, especially when readers must hunt for the promised answer.
    • Pages that already rank for relevant queries but are not being surfaced or cited for the specific answers they contain.
    • Complex explanations where headings are generic and paragraphs routinely change subject midway through.
    • JavaScript-heavy pages where important text is absent from the initial response or appears only after interaction.

    For each candidate, record whether the failure is structural, technical, or both. That prevents a content team from rewriting material that actually needs a template fix, and it keeps developers from rebuilding components when clearer headings would solve the immediate retrieval problem.

    Key takeaways for machine-retrievable content

    • A retrievable answer needs both a clear unit of meaning and reliable delivery in the rendered page.
    • Let each heading make a specific promise, then answer it promptly in a focused passage.
    • Split content when the reader’s question changes, not when a paragraph reaches an arbitrary length.
    • Use semantic HTML and a logical heading hierarchy to make relationships explicit in the DOM.
    • Put important text and links in the initial page state rather than behind required interaction.
    • Compare the initial HTML, live DOM, and crawler-rendered HTML instead of assuming that one represents all three.
    • Use DOM size as an investigation signal, not as a standalone SEO score.

    Pick one commercially important URL and test one intended answer from outline to rendered DOM. Repair the first broken handoff you find, validate the crawler-visible result, and only then scale the same audit across the rest of the template or content set.

    References

  • How to Measure AI Discovery, Attribution, and Conversion

    How to Measure AI Discovery, Attribution, and Conversion

    You can be named in AI answers, receive almost no identifiable referral traffic, and still influence a sale. You can also collect a burst of chatbot visits that never becomes revenue. If your dashboard treats those outcomes as the same thing, you will optimize the wrong part of the customer journey.

    The practical fix is to separate AI discovery visibility, attribution, and conversion, then reconnect them with an evidence chain. That gives you a defensible answer to three different questions: Are AI systems recommending you? Can you identify their influence? Does that influence create valuable outcomes?

    Key takeaways

    • Measure AI discovery, attribution, and conversion as separate stages. A strong result at one stage does not prove success at the next.
    • Treat AI visibility as sampled visibility, not a permanent ranking position. Track a fixed set of prompts, repeated outputs, mentions, recommendations, citations, and cited pages.
    • Build consistency around an entity home: one authoritative place where your identity, offers, audience, availability, and supporting facts agree with your visible content and JSON-LD.
    • Separate observed referrals, customer-reported AI influence, assisted journeys, and broader trend signals. Combining them into one conversion count creates false certainty.
    • Compare conversion rates only after checking traffic volume, intent, landing-page purpose, outcome quality, and measurement coverage.
    • Use one scorecard across content, analytics, CRM, and revenue systems so each team is working from the same channel definitions.

    Measure discovery, attribution, and conversion separately

    Three connected scenes show an AI highlighting an option, evidence trails converging through a lens, and a verified path reaching a purchase package.

    AI discovery visibility is your presence inside an assistant’s answer. It includes being mentioned, recommended, described accurately, cited, or used as the basis for an answer. The user does not have to visit your site for that visibility to matter.

    Attribution is the evidence connecting that exposure to a later action. A detectable referral is one form of evidence, but AI-assisted decisions can occur without producing the traditional click. That makes attribution a confidence problem rather than a simple channel lookup.

    Conversion is the valuable outcome: a purchase, booking, qualified lead, application, subscription, or another action your business has defined in advance. It belongs at the end of the chain. A brand mention is not a conversion, and a chatbot session is not proof of revenue.

    StageQuestion to answerUseful evidenceCommon mistake
    DiscoveryDoes the assistant include and represent us for relevant needs?Mentions, recommendations, citations, cited pages, answer accuracy, and repeatability across tracked promptsTreating one favorable answer as a stable ranking
    AttributionWhat evidence connects AI exposure with a visit or decision?Detectable referrals, customer reports, identifiable journey sequences, and directional demand signalsCalling every direct visit or branded search an AI visit
    ConversionDid identifiable or reported AI influence create a valuable outcome?Conversions, qualified outcomes, revenue, conversion rate, and time to conversionComparing rates without checking volume, intent, or measurement coverage

    Define the measurement contract before collecting results. Fix the audience, market, use case, conversion event, reporting window, and set of assistants you intend to evaluate. Otherwise, a change in prompt mix or business definition can look like a performance change.

    Your prompt set should cover distinct stages of intent. Category prompts reveal whether you are discovered at all. Comparison prompts reveal whether you enter a shortlist. Validation prompts reveal whether the assistant can explain your fit, limitations, and evidence. Decision prompts reveal whether it can direct a user toward the right next step. Keep these groups separate because an improvement in broad discovery can hide a decline among high-intent questions.

    Make your brand easy to identify and corroborate

    AI recommendations can vary considerably between outputs. There is no single position to check and declare permanent. Your first visibility metric should therefore be repeatability: does the same brand appear, for the same relevant need, often enough to indicate more than a one-off answer?

    Record the exact prompt, assistant, date, account state, answer, brand position within the answer, cited URLs, and any material factual errors. Repeat the same prompts under comparable conditions. This does not remove model variability, but it stops your own testing process from introducing avoidable noise.

    Establish an entity home

    An entity home is the authoritative page, or tightly connected group of pages, where a machine can resolve what your brand is. It should make the following facts explicit rather than forcing an assistant to infer them:

    • Your canonical brand name and website.
    • What you provide, using the terms customers use to describe the need.
    • Who the offer is for and when it is not a fit.
    • Where the offer is available and which limitations matter.
    • The relationship between the brand, its products, and any parent or operating organization.
    • The evidence supporting important claims.
    • The correct next step for someone who wants to evaluate, contact, buy, or book.

    Visible copy, navigation labels, page metadata, and JSON-LD should express the same facts. Structured data is a clarification layer, not a way to publish a second version of the business. If the page calls an offer a platform, the markup describes a service, and external profiles use a third label, you have created an identity-resolution problem.

    Keep a claim ledger

    Create a working list of the claims you want an assistant to repeat. For each claim, record the approved wording, the controlled page that supports it, the evidence behind it, the machine-readable representation, the external locations that mention it, and the person responsible for keeping it current.

    This catches a common failure mode: marketing changes a promise, product changes an availability condition, and structured data or external profiles retain the old version. An assistant may then omit the claim, hedge it, or reproduce the wrong version. Fix the disagreement before producing more pages about the same subject.

    Build corroboration, not repetition

    Repeating a claim across your own site can improve clarity, but it does not create independent support. More consistent AI visibility tends to emerge when your controlled identity and authoritative third-party information align. The practical goal is not to manufacture mentions. It is to make legitimate profiles, listings, coverage, documentation, and references accurate enough to confirm the same core facts.

    Audit contradictions before chasing additional coverage. Start with the facts most likely to affect a recommendation: category, audience, capabilities, availability, pricing model if publicly stated, location, ownership, and material limitations. A smaller set of consistent claims is more useful than a larger footprint full of stale descriptions.

    Write pages that can support an answer

    A page should answer one identifiable decision question well. Put the direct answer near the start, define who it applies to, show the supporting facts, state meaningful limits, and link to the canonical pages behind those facts. Give comparison and use-case pages enough context to stand alone; an isolated slogan is difficult to verify and easy to misrepresent.

    Do not judge these pages only by search visits. In an AI journey, a page can help establish the facts used in an answer even when the user never opens it. Track whether the page is cited, whether its language appears accurately in answers, and whether improvements make recommendations more consistent across your prompt set.

    Build attribution that survives a missing click

    A person researches on a tablet and later buys on a laptop, with indirect signal trails bridging the missing digital connection.

    No single attribution method will reveal every AI-influenced journey. The defensible approach is to keep evidence classes separate and assign each one an appropriate level of confidence.

    1. Observed AI referral: A visit arrives with a detectable referring platform or a campaign link you deliberately placed. This is the strongest channel evidence, but it covers only journeys that produce a visible handoff.
    2. Customer-reported AI influence: A lead or buyer identifies an AI assistant when asked how they discovered you or what helped them decide. Preserve the original response and map it to a reporting category without discarding the raw wording.
    3. Identifiable assisted journey: An AI referral occurs earlier in a known journey and a later session converts. Report it as assisted rather than relabeling the final touch.
    4. Directional influence signal: AI visibility changes alongside branded demand, direct visits, sales questions, or conversions. This can support an investigation, but correlation alone does not prove that AI caused the result.
    5. Unknown: No reliable connection can be established. Keep this category. Forcing unknown journeys into AI reporting makes the dashboard look complete while weakening every decision based on it.

    Use separate reporting fields for observed, reported, assisted, directional, and unknown influence. Your deduplicated AI-influenced conversion total may include the first three when their identities are clear. Directional signals should remain outside that total because they describe context, not attributable conversions.

    Preserve the evidence at collection time

    At the first identifiable visit, preserve the raw referrer, landing page, timestamp, campaign value when present, and assistant name when it can be observed. Do not overwrite those fields when your channel-classification rules change. Retaining the raw values lets you repair historical classification without inventing history.

    At a lead or purchase step, ask an optional discovery question such as, “Where did you first hear about us?” A second question such as, “What helped you decide?” distinguishes discovery from decision support. Offer an AI-assistant option, but retain an open field because customers may name a platform, describe a generated answer, or use terminology your choices did not anticipate.

    Do not quietly infer and store a person’s private prompt. Record only the information the platform legitimately passes or the customer voluntarily provides. Attribution does not become more accurate merely because more sensitive data is collected.

    Use the same definitions in every system

    A common channel taxonomy should flow through web analytics, lead records, customer systems, the data warehouse, and revenue reporting. If marketing defines an AI-assisted lead differently from sales operations, the reconciliation meeting will become an argument over labels rather than a decision about performance.

    Enterprise teams also need a repeatable way to move search intelligence into the systems where decisions are made. Conductor’s Data API is designed to extend search data across enterprise platforms and AI infrastructure. Whether you use that product or another integration route, the architectural requirement is the same: prompt-level visibility, visit evidence, customer-reported influence, and commercial outcomes need shared identifiers and shared definitions.

    Run a reconciliation check before presenting an AI revenue figure. Confirm that a conversion has not been counted once as an observed referral, again as a reported discovery, and a third time as an assisted journey. Preserve the separate flags, but deduplicate the commercial outcome.

    Read AI conversion rates without fooling yourself

    During Airbnb’s Q4 2025 earnings call, CEO Brian Chesky said chatbot traffic converted at a higher rate than Google traffic. The disclosure did not include the underlying conversion rates, referral volume, or the chatbots responsible for those visits. It is a useful signal that chatbot referrals can carry strong intent, but it is not a benchmark you can transfer to another business.

    A plausible interpretation is that some users arrive from assistants after narrowing their choices, which places them further along in the journey. Other explanations remain possible: different landing pages, audience composition, attribution coverage, device mix, or a small group of unusually motivated visitors. Your own data must distinguish those possibilities.

    Check six things before calling AI traffic a better channel:

    • Denominator: Decide whether the rate uses sessions, users, leads, or another unit. Do not compare rates built from different denominators.
    • Volume: Show the conversion count beside the rate. A small stream can produce a high rate while contributing little total revenue.
    • Intent: Compare visitors who were trying to complete a similar task. A decision-ready referral should not be compared casually with broad informational traffic.
    • Landing experience: Check whether channels enter through pages with different purposes. A booking or product page naturally has a different job from an educational page.
    • Outcome quality: Measure the outcome the business values, not merely the easiest event to count. For a complex sale, that may be a qualified opportunity rather than a form submission.
    • Coverage and lag: State how much traffic could be classified and how long conversions typically remain connected to an earlier touch in your reporting model.

    Keep rate, volume, and value in adjacent columns. If AI referrals convert strongly but remain small, expand visibility around the prompts and pages already producing qualified visitors. Do not treat the rate alone as a reason to reallocate a large budget. If referral volume rises while conversion weakens, inspect query intent and landing-page continuity before trying to increase visibility further.

    When visibility rises but detectable traffic does not, check which pages assistants cite and whether users have a clear reason to continue to your site. Some answers may satisfy the question without a click. Others may mention the brand but omit a usable next step. That is a discovery-to-handoff problem, not yet a conversion-rate problem.

    When referrals and customer-reported influence rise but qualified outcomes do not, the break is later. Compare the promise made in AI answers with the landing page, offer, eligibility conditions, and sales follow-up. A mismatch at that handoff can produce plenty of apparently relevant traffic without commercial value.

    Run one AI discovery-to-revenue review

    A useful review follows the journey in order. It does not open with a single visibility score or end with a single attribution number. Use the same prompt set and definitions for each reporting cycle, then organize the scorecard into four layers.

    Visibility layer

    • Mention rate: tracked runs in which the brand appears divided by total tracked runs.
    • Recommendation rate: tracked runs in which the brand is presented as a suitable option, kept separate from incidental mentions.
    • Citation rate: tracked answers that link to a controlled page, with the actual cited URLs listed.
    • Accuracy rate: appearances that represent the monitored brand facts correctly.
    • Repeatability: prompts for which the brand remains present across repeated comparable runs.

    Do not merge all prompts into one opaque score. Break these measures out by category discovery, comparison, validation, and decision intent. A stable overall percentage can otherwise hide movement at the stage closest to conversion.

    Attribution layer

    • Detectable AI referrals and the landing pages receiving them.
    • Customers who report discovering the brand through an assistant.
    • Customers who report that an assistant helped with the decision.
    • Identifiable journeys in which an AI referral assisted a later conversion.
    • Directional signals, displayed as context and clearly labeled as non-causal.
    • The share of outcomes that remains unknown or unclassified.

    Conversion layer

    • Sessions or users, conversion count, and conversion rate for observed referrals.
    • Qualified outcomes and value from customer-reported or identifiable assisted journeys.
    • Time from first known AI interaction to conversion.
    • Performance against a comparable non-AI cohort with similar intent.
    • Results by landing page, prompt-intent group, audience, and market where the data supports that split.

    Evidence-quality layer

    • Changes to the prompt set, assistant mix, account conditions, or collection process.
    • Changes to channel-classification rules or customer-survey wording.
    • Missing data, small groups, duplicate records, and known tracking gaps.
    • Entity-home, JSON-LD, content, or third-party corrections made during the period.

    End the review with one test tied to the weakest link. If visibility is inconsistent, reconcile the entity home and external descriptions around one important claim. If mentions are stable but citations are poor, improve the page that should substantiate the answer. If referrals are visible but influence disappears in customer records, repair the data handoff. If qualified conversions are weak, examine intent and promise continuity before publishing more content.

    You can start with a fixed prompt set, a canonical-fact audit, two optional attribution questions, and separate fields for observed, reported, assisted, and directional evidence. After one complete review cycle, invest in the stage where the chain actually breaks. That is how AI visibility becomes a measurable acquisition system instead of another disconnected dashboard.

    References

  • SaaS AI Referral Traffic Is Down: A Practical Diagnostic

    SaaS AI Referral Traffic Is Down: A Practical Diagnostic

    Your SaaS dashboard shows fewer visits from AI assistants. Before you rewrite the content roadmap or declare the channel dead, find out exactly which line moved. A fall in standalone-assistant referrals, a shift toward workflow-embedded tools, and poor landing-page routing are three different problems. They require three different responses.

    The goal isn’t to recover every lost session. It is to make your product easy to retrieve at the right moment, send qualified users to a page that resolves their question, and measure whether those visits produce meaningful actions.

    Key takeaways

    • A decline in attributed AI referrals is not the same as a decline in AI visibility. Referral analytics capture recognized visits, not every citation, recommendation, or answer that produces no click.
    • The widely discussed 53% decline applied to standalone AI discovery sessions in one SaaS dataset. It occurred while workflow-embedded Copilot traffic grew by more than 20 times, so the pattern is better read as channel redistribution than universal disappearance.
    • Internal search deserves its own landing-page segment. About 41% of the dataset’s LLM sessions landed on search-result pages, which can reveal that an assistant could not identify a better direct answer.
    • Compare equivalent buying periods. The dataset peaked in July and weakened through Q4, making a simple month-over-month chart especially easy to misread.
    • Prioritize landing-page relevance, qualified actions, referrer mix, and content penetration. Total sessions alone cannot tell you whether your AI search strategy is improving.

    Read the decline as a distribution problem first

    The 53% figure does not establish that every SaaS company lost half its AI audience. It describes a decline in discovery sessions from standalone AI tools within a particular dataset. Between November 2024 and December 2025, that dataset recorded 774,331 sessions attributed to large language models.

    Its referrer mix was highly concentrated: ChatGPT accounted for 82.3% of the sessions. When one platform supplies that much traffic, a change in its usage, interfaces, link behavior, or audience mix can dominate the aggregate chart. A top-line decline can therefore hide growth elsewhere.

    Copilot demonstrates the point. It generated 148 sessions near the end of 2024, grew by more than 20 times by May 2025, and then averaged 3,822 sessions per month from June through December. It had become the second-largest AI referrer by the end of 2025.

    The pattern is consistent with intent moving into the user’s existing workflow. Someone already working in an embedded assistant may ask a product or implementation question without opening a separate discovery tool. That does not settle the larger question of whether agents will replace parts of SaaS. It does tell you that measuring all AI platforms as one homogeneous channel will produce poor decisions.

    Start by classifying the shape of your own decline:

    Pattern in your analyticsWorking interpretationNext check
    Standalone assistants fall while an embedded assistant growsReferrer mix is changingCompare landing pages, intent, and conversion by platform
    AI and other non-paid channels weaken in the same periodDemand or B2B seasonality may be involvedCompare equivalent periods and commercial outcomes
    AI sessions increasingly land on internal searchAssistants may not be resolving a direct destinationInspect the query, result quality, and crawl path
    AI sessions fall but qualified actions hold steadyLost visits may have been lower-value, or attribution may have shiftedReview conversion counts, not only conversion rate
    Sessions hold steady while qualified actions fallLanding-page relevance or intent quality has deterioratedAudit the promise-to-page match for the affected referrers

    These are diagnostic hypotheses, not conclusions. Use them to choose the next report or page inspection rather than to explain the result in advance.

    Audit measurement before changing your content

    A magnifying lens reveals a hidden signal path beside an abstract attribution funnel and tracking nodes on an analyst workstation.

    An analytics tool’s AI channel is a record of identifiable referrals. It is not a complete count of how often an assistant mentions your company, uses your information, recommends your product, or answers a question without sending a visit. Call the metric what it is: attributed AI referral sessions.

    Lock the channel definition

    Export the referrer rules behind your AI segment. Keep the same platform list, source normalization, bot filtering, and session definition throughout the comparison. If you add a newly discovered referrer halfway through the audit, recalculate the earlier period under the same rule set. Otherwise, taxonomy maintenance will look like growth.

    Keep an explicit “unknown or unclassified” bucket. Do not silently assign direct traffic to AI just because a visitor viewed an AI-oriented page. That may be a useful hypothesis for investigation, but it is not referrer evidence.

    Build a platform-by-page-type view

    For each complete month, split AI referrals by platform and landing-page template. At minimum, separate the homepage, product or feature pages, pricing, comparisons, documentation, blog content, and internal search results. Preserve the full landing URL in the underlying export so query parameters do not disappear inside a grouped page report.

    This matrix exposes changes that a channel total conceals. ChatGPT might stop sending exploratory blog visits while Copilot begins sending fewer but more commercial visits to product documentation. Calling that a single traffic decline would erase the useful part of the change.

    Use seasonally comparable periods

    SaaS discovery in the observed dataset peaked in July and declined through Q4, alongside normal B2B work, budget, and holiday cycles. That is not a universal calendar for every SaaS company. It is a warning against treating an autumn-to-December decline as proof of an AI-specific loss.

    Compare the same quarter year over year when you have consistent data. If you do not, compare AI referrals with non-paid search, direct visits, demo activity, and other demand indicators over the same months. A decline shared across channels points toward a different diagnosis than an isolated fall from one AI platform.

    Measure penetration, relevance, and outcomes

    Create a small scorecard with definitions your team can reproduce:

    • Referrer share: each AI platform’s sessions divided by all attributed AI referral sessions. This shows concentration and redistribution.
    • Landing-page relevance rate: AI sessions reaching a page that directly answers the apparent intent divided by all AI sessions. Define the intended destination for each query or intent class before scoring it.
    • Commercial action rate: trials, demos, sign-ups, or another agreed activation event divided by AI sessions. Report the action count beside the rate so a tiny denominator does not mislead you.
    • AI landing-page penetration: eligible product, comparison, pricing, and answer pages receiving at least one attributed AI visit divided by all eligible pages. Use this as an internal coverage metric, not an industry benchmark.
    • Search-result dependency: AI sessions landing on internal search divided by all AI sessions. A rising share deserves a query-level inspection even when total traffic is stable.

    Keep visibility and referral performance as separate columns. If you monitor assistant mentions or citations, compare them with clicks rather than combining them into an invented all-purpose score. Visibility can remain stable while click behavior changes.

    Treat internal search landings as a retrieval clue

    A search beam selects one webpage tile from a floating digital library and connects it to a brightly lit destination doorway.

    Internal search was the largest destination class in the observed traffic. Search-result pages received 320,615 sessions, or about 41% of all LLM referrals, exceeding blog, pricing, and product destinations.

    That does not mean internal search was the best content. A more useful interpretation is that the assistant found a searchable route but not a confident direct answer. Your search interface became a fallback discovery layer.

    Open the top AI-referred search URLs and inspect them as a user and as a crawler:

    • Reproduce the query from the landing URL. Confirm that it returns relevant results rather than an empty state, generic category, or different query after a redirect.
    • Check whether the public result can be fetched without authentication, cookies, or a browser-only interaction. If useful results appear only after client-side execution, provide a crawlable path to the primary answer.
    • Expose the query, result summary, and important destination links in visible HTML. A search shell with no meaningful server response gives an assistant little to interpret.
    • Verify the status code, robots directives, canonical target, and rendering behavior. A result page should not claim to be a successful answer while returning an error, canonicalizing to an unrelated page, or hiding every result from crawlers.
    • Trace each recurring high-intent query to its best permanent destination. If people repeatedly search for pricing, a named integration, a comparison, or a specific capability, create or improve the dedicated page and link it prominently.
    • Make the onward path explicit. A useful result should lead directly to the relevant product, pricing, comparison, documentation, or contact page instead of forcing another search.

    Do not respond by indexing every possible internal-search combination. Unlimited query parameters, spelling variants, and empty result sets can create a large collection of duplicate or low-value URLs. Keep crawlable search states finite and useful. Promote recurring, commercially meaningful questions into governed landing pages with stable URLs, original answers, and intentional internal links.

    Think of public search as an interface an AI system may use, not as a substitute for information architecture. If the same search query repeatedly attracts referrals, the durable fix is usually a direct answer page that no longer requires the fallback.

    Rebuild around moments of intent, then test one cycle

    Workflow-embedded assistants change when discovery happens. The user may already be writing a specification, comparing tools, diagnosing an integration, or preparing a purchase request. Your page has to resolve that immediate task. A broad brand narrative is rarely enough on its own.

    User’s moment of intentBest destinationInformation that must be visible
    “What does it cost?”Pricing or plan pagePricing basis, plan differences, limits, conditions, and the next buying step
    “Can it handle this use case?”Capability or use-case pageDirect answer, supported inputs, prerequisites, limitations, and a relevant example
    “How does it compare?”Comparison pageDecision criteria, material differences, suitability, migration considerations, and current facts
    “How do I complete this task?”Documentation or task pagePrerequisites, ordered steps, expected result, failure points, and the appropriate next action
    “Where is the relevant feature or resource?”Help, navigation, or curated search pageExact destination, concise context, and direct links without another discovery loop

    Make critical facts available in the main page content. Do not leave pricing conditions, compatibility, product limits, or differentiators only inside images, tabs that never render for a crawler, or downloadable collateral. Clear headings, concise answers, comparison tables, and descriptive internal links make the page easier for people and retrieval systems to interpret. The broader SaaS pattern favors transparent, crawlable, comparison-oriented information.

    Use structured data to clarify, not manufacture, the answer

    JSON-LD should describe the content a visitor can verify. Use the most accurate entity types for the page, such as Organization and SoftwareApplication where they genuinely apply. Represent offers only when the visible pricing information is current and complete enough to support them. Use FAQPage only for questions and answers that are actually present for the reader, and BreadcrumbList only when it reflects the real hierarchy.

    Keep names, URLs, product descriptions, and relationships consistent between markup and visible copy. Do not stack loosely related schema types in the hope of earning AI visibility. Structured data can reduce ambiguity; it cannot repair a missing price, an evasive comparison, an inaccessible result, or an unsupported claim.

    Run a controlled repair cycle

    1. Freeze the baseline. Save monthly sessions, referrer share, landing-page type, search-result dependency, qualified actions, and your current channel rules.
    2. Choose pages from three evidence-backed groups: high-intent pages receiving no AI referrals, internal-search URLs receiving AI referrals, and pages that attract visits but fail to resolve the apparent intent.
    3. Repair the answer path. Put decisive facts in visible content, connect recurring searches to permanent destinations, improve internal links, and align JSON-LD with the finished page.
    4. Annotate the publication and crawl dates. Keep unrelated template and attribution changes out of the same evaluation window where practical.
    5. Review one complete reporting period using the frozen definitions. Compare platform mix, relevant landings, action counts, and search dependency before looking at the aggregate traffic line.

    The decision after that cycle should follow the observed failure. If one referrer is shrinking while another is growing, adapt destinations to the growing moment of intent. If search-result dependency is rising, repair retrieval and information architecture. If comparable periods weaken across several acquisition channels, do not blame AI alone. If qualified actions hold while raw visits fall, protect the pages producing those actions before chasing volume.

    Your first move can be small: open a platform-by-page-type report, select the highest-traffic internal-search landing, and follow its path to the page that should have answered the query directly. Repairing that path gives you a measurable change. A generic push to publish more does not.

    References

  • Local Discovery in Google and ChatGPT: A Practical Plan

    Local Discovery in Google and ChatGPT: A Practical Plan

    If your business appears in Google for one service but disappears for a broader search, adding more reviews may not solve the problem. If ChatGPT overlooks you, turning every keyword into a long conversational question may not solve it either.

    Local discovery starts with recognition: can the system confidently identify what your business is, what it offers and where it operates? Selection comes next. Your strategy should strengthen that identity first, then give Google, ChatGPT and prospective customers enough evidence to choose you.

    Google has to recognize you before it can rank you

    Google does not begin every local search by lining up all nearby businesses and comparing reviews, links and proximity. It first has to decide which businesses plausibly satisfy the query. That eligibility decision precedes the familiar ranking competition.

    This distinction changes how you diagnose weak local visibility. A business that is not recognized as an eligible match cannot review its way to the top of that result set. The immediate problem is interpretation, not popularity.

    Your business name and primary category are central to that interpretation. Google processes them as a combined identity signal: the name communicates how the business identifies itself, while the category supplies a structured description of what kind of business it is. Together, they create an entity boundary around the searches Google can confidently associate with you.

    The boundary changes with query breadth. A narrow service query may require a close match between the requested service and your recognized identity. A broad query such as “restaurants” creates a larger eligible set because many categories and business concepts can satisfy it. Once the set exists, reviews, clicks, relevance and real-time facts such as whether a location is open can help distinguish the candidates.

    A highly specific business name can reinforce a niche interpretation while making a broader interpretation less obvious. That is not a reason to add keywords to your official business name. It is a reason to keep the name accurate, choose the most truthful primary category and understand which queries that combination naturally supports.

    Run this eligibility audit before starting another general link or review campaign:

    1. List your commercially important query families. Write the service and location combinations customers actually use, including both specialist and broad category terms.
    2. Separate narrow queries from broad ones. “Emergency dentist in [area]” asks for a more specific interpretation than “dentist in [area].” Do not assume one result represents the other.
    3. Place your exact business name and primary Google Business Profile category beside each family. Ask whether that pair makes you an obvious candidate without relying on a human to infer services that are not stated.
    4. Mark each family clear, ambiguous or outside the boundary. “Outside” is acceptable when the service is not genuinely part of your business. The objective is accurate eligibility, not visibility for every adjacent phrase.
    5. Correct factual mismatches first. If the primary category understates or misrepresents the core business, fix that identity issue before treating reviews or links as the main remedy.

    You can use result patterns as a working diagnosis, although they are not proof of Google’s internal decision. If you are absent for a highly specific service you genuinely provide, inspect the identity and service signals first. If you appear for specialist queries but not broader ones, your entity boundary may be too narrow. If you appear consistently but lose position, selection signals are the more plausible next area to investigate.

    Design for the short local prompts people actually use

    Using ChatGPT does not automatically turn a local transaction into a long conversation. In observed local healthcare and aesthetic service searches, 75% of sessions contained at least one keyword-style prompt. Participants often entered compact combinations such as a service and location instead of explaining their full situation in a sentence.

    The same behavior appeared in the length of the interaction. Forty-five percent of sessions ended after one prompt, the overall average was about 2.1 prompts and 34% of follow-up prompts simply asked for more results. These observations came from a limited set of local healthcare and aesthetic tasks, so they should not be treated as a universal law for every market. They do, however, give you a strong reason not to abandon concise service-and-location language.

    For a one-shot prompt, your first-answer visibility matters. You cannot depend on every user conducting a long dialogue that eventually uncovers your business. You need to be understandable from compact intent such as “dentist 11214,” “chiropractor [city]” or “hair transplant [area].”

    Give each real service a clear discovery layer

    A service page should make its basic proposition recoverable without requiring interpretation across several paragraphs. Near the beginning of the page, state:

    • The plain-language name of the service.
    • The business or practitioner providing it.
    • The city, neighborhood or genuine service area.
    • What the service includes and, just as importantly, what it does not include.
    • The next step a prospective customer can take.

    This is not an instruction to repeat the same keyword mechanically. It is an instruction to remove avoidable ambiguity. If a visitor has to infer the service from brand language such as “complete transformation solutions,” an automated system has to resolve the same ambiguity.

    Do not create a separate thin page for every rearrangement of the same phrase. Build pages around real distinctions: a separate service, a location where the service is genuinely available or a decision that needs materially different information. A page should exist because the offer is distinct, not because the word order changed.

    Add the evidence a person needs after discovery

    Keyword clarity may help a system understand the candidate, but it does not finish the customer’s decision. People searching for local services still move among websites, social profiles and reviews. Your page should therefore answer the practical questions that arise after recognition: availability, location, relevant qualifications, service scope, appointment process and any constraints that could make the business unsuitable.

    Keep transactional content concise, but do not remove useful explanations merely to imitate a short prompt. Longer, question-led content remains valuable when the user’s intent is informational. The mistake is making an extended conversational format the only place where a transactional service is named clearly.

    Build one consistent local facts layer for both paths

    A central business building and fact symbols connect consistently to a map interface and a conversational assistant interface.

    You do not need a “Google identity” and a separate “ChatGPT identity.” You need one accurate public description of the business that remains coherent wherever a customer or system encounters it. The platforms can produce different results, but contradictory source facts make recognition harder in either environment.

    Fact to alignWhy it mattersWhat to inspect
    Business nameEstablishes the entity’s self-identificationGoogle Business Profile, website header and contact information, major public profiles
    Primary categoryDefines the structured business type and helps set the eligibility boundaryWhether it truthfully represents the core offer rather than a secondary service
    ServicesConnects narrow prompts with specific capabilitiesProfile services, service-page headings and visible descriptions
    Location or service areaConnects the business to local intentContact page, location pages and public profiles
    Hours and availabilityCan affect results when the user needs an open businessHoliday hours, temporary closures and discrepancies between profiles and the site
    Decision evidenceHelps an eligible candidate earn selectionReviews, qualifications, policies, service details and clear next steps

    Start with the highest-authority fields you directly control. Confirm the exact business name, primary category, current hours, location and core services in Google Business Profile. Then compare those facts with the website. Correct contradictions before expanding the site with more articles.

    Next, standardize the vocabulary used for genuine services. A business can keep its brand voice while still using the ordinary nouns customers put into short prompts. If your profile calls an offering one thing, the service page calls it another and customers use a third term, connect those terms explicitly in visible copy instead of expecting a system to infer the relationship.

    Structured data belongs after this factual alignment. If you publish local business or service markup, make it reflect the verified information visible on the page. Do not use markup to introduce an alternative identity, an unsupported service or different hours. Machine-readable inconsistency is still inconsistency.

    Apply corrections in this order:

    1. Identity: official name, core business type and primary category.
    2. Offer: the services the business actually provides and the distinctions among them.
    3. Place and time: location, service area, hours and availability.
    4. On-page explanation: one substantial destination for each real service-and-location need.
    5. Selection evidence: accurate reviews, qualifications, policies and useful decision details.

    This order prevents a common waste of effort. Reviews and links may strengthen an eligible candidate, but they do not repair a basic misunderstanding about what the business is. Identity work and selection work support different stages of discovery.

    Measure recognition separately from selection

    A visual sequence moves from identifying one relevant storefront on a street to narrowing several business cards and highlighting a final choice.

    A single visibility score will hide the problem you need to fix. Build a small, repeatable prompt set and record two separate outcomes: whether your business enters consideration and what happens after it does.

    Start with 12 prompts as a manageable diagnostic baseline. This is a working set, not a platform requirement:

    • Four narrow prompts: a specific service plus city, neighborhood or postal code.
    • Four broad prompts: the primary business category plus the same locations.
    • Four constraint prompts: a service and location combined with a real decision factor such as current availability or a relevant specialty.

    Run the same core set in Google and ChatGPT. For ChatGPT, also test the natural follow-up “more results” because expansion requests made up a substantial share of the observed follow-ups. Preserve the exact wording instead of rewriting prompts between checks; otherwise, you will not know whether the business changed or the test changed.

    For every prompt, record:

    • Inclusion: did the business appear at all?
    • Interpretation: was it described as the correct type of business and matched to the correct service?
    • Accuracy: were the location, hours, service and other stated facts correct?
    • Selection: did it appear in the initial result or only after expansion, and what evidence was presented with it?
    • Context: the date, prompt wording and any visible citation or destination, so the observation can be compared later.

    Do not treat a manual prompt check as a permanent rank. Results can vary, and the two platforms do not expose the same discovery process. The value of the record is diagnostic: it shows repeated patterns across a controlled set.

    Use those patterns to choose the next action:

    Observed patternLikely area to inspect first
    Absent from narrow and broad Google queriesBusiness identity, primary category and basic location eligibility
    Present for narrow Google queries but absent for broad onesWhether the recognized entity boundary is narrower than the intended market
    Present in Google but absent from ChatGPT checksWhether public service-and-location information is explicit, consistent and supported by usable decision details
    Present in ChatGPT but absent from relevant Google resultsGoogle Business Profile identity and the name-category relationship
    Present in both but rarely selected earlyReviews, accurate availability, usefulness of landing pages and other selection evidence
    Present with incorrect factsThe conflicting public profile or page before any visibility campaign continues

    These are triage rules, not claims about a platform’s private logic. Use them to decide where to inspect, then verify the underlying facts. Change one class of signal at a time – identity, service content or selection evidence – and rerun the same set. A change log will tell you more than an expanding collection of unrelated prompts.

    Key takeaways

    • Local visibility begins with eligibility. Google must recognize the business as a plausible match before reviews, links and other ranking signals can differentiate it.
    • Your business name and primary category form a combined identity signal. Audit that pair against both narrow service queries and broad category queries.
    • Do not abandon keywords for elaborate ChatGPT prompts. In one set of local healthcare and aesthetic searches, 75% of sessions included keyword-style input and 45% ended after one prompt.
    • Use one consistent facts layer across your profile, website, public profiles and structured data: accurate identity, services, location, hours and decision evidence.
    • Track recognition separately from selection. Absence, incorrect interpretation and weak placement are different problems and require different work.

    Your next move is small and concrete: choose four narrow queries and four broad ones, place your exact business name and primary category beside them, and mark where the match becomes ambiguous. That sheet will show whether you need to repair recognition or strengthen the evidence that earns selection.

    Once the identity is clear, carry the same service and location facts through the pages and profiles a customer can encounter. Then repeat the same prompts. Local discovery becomes manageable when you stop treating every absence as a ranking problem.

    References

  • Brand Discovery Beyond Search: Organic and Paid Channels

    Brand Discovery Beyond Search: Organic and Paid Channels

    If your brand ranks for useful queries but still fails to make the buyer’s shortlist, another position in Google may not solve the problem. By the time many people reach a conventional search result, they have already encountered names, checked public reactions, watched demonstrations and asked an AI assistant to reduce the options.

    You need a discovery system that works across that entire decision chain. The practical job is to coordinate earned authority, social validation, AI-readable owned content and emerging paid placements without treating every platform as another place to publish the same message.

    Key takeaways

    • Map the questions and uncertainties that move a buyer toward a decision, then assign each one to the channel best suited to resolve it.
    • Use digital PR to establish credible evidence, social platforms to demonstrate and discuss it, and owned content to preserve the complete, accurate version.
    • Treat AI visibility as a distinct outcome. A brand mention, a citation, an accurate description and a recommendation are not interchangeable.
    • Keep conversational advertising separate from organic AI authority. A relevant sponsored placement can create discovery, but it does not mean the assistant endorsed the advertiser.
    • Measure movement across the journey with tagged links, assisted paths, branded demand, repeatable AI checks and qualified actions. Last-click conversions alone will undervalue discovery channels.

    Map the decision chain, not a list of platforms

    A modern discovery journey can begin with a short demonstration, move into a community discussion, continue through a long-form explanation and end with an AI-generated comparison. People are already moving from TikTok to Reddit, YouTube and AI summaries as they form and validate preferences. Google may still participate, but it no longer owns every stage.

    This changes the planning unit. A channel plan starts with places: a TikTok plan, a Reddit plan or an AI search plan. A discovery plan starts with a buyer’s unresolved question. That distinction prevents a common failure in which a brand maintains many accounts but provides no connected path from recognition to confidence.

    Build a decision-question inventory before you choose formats. For each meaningful audience and use case, record:

    • The trigger: What happened that made the person look for an answer now?
    • The question: What would that person actually type, say or ask another person?
    • The uncertainty: What could stop the decision – cost, complexity, compatibility, risk, proof or trust?
    • The required evidence: What would resolve that uncertainty: a demonstration, an independent mention, a technical specification, a customer perspective or a clear limitation?
    • The likely surface: Where would the person expect to find that kind of evidence?
    • The next useful action: What should become easier after the evidence is consumed?

    Organize this inventory around uncertainty rather than generic funnel stages. Someone searching Reddit for hidden drawbacks and someone watching a YouTube setup walkthrough may both be close to a purchase, but they need different proof. Sending both people to the same promotional landing page ignores the reason they chose those surfaces.

    Then audit whether your brand appears when those questions are explored. Search the platforms directly, review relevant community discussions and ask representative questions in the AI products your audience uses. Record absence as well as inaccuracy. An absent brand has a distribution problem; a misdescribed brand may have an entity, evidence or consistency problem. Those require different fixes.

    Give each discovery channel a distinct job

    An unbranded product passes through separate stations for conversation, demonstration, validation, information synthesis and final selection.

    Cross-channel visibility works when each surface contributes something the others cannot. It breaks when a campaign simply copies the same claim into a press release, social caption, community reply and landing page.

    SurfacePrimary jobUseful assetFailure to avoid
    Digital PREstablish independent authorityVerifiable finding, expert explanation, original resource or documented developmentTreating coverage as a link transaction with no durable evidence
    TikTok and short-form videoCreate recognition and make an idea tangibleFocused demonstration, before-and-after process or concise explanationCompressing away the conditions and limitations that make the claim credible
    Reddit and other communitiesExpose real objections, tradeoffs and languageTransparent participation, useful answers and links only when they genuinely resolve the questionAstroturfing, disguised promotion or inserting the brand into unrelated discussions
    YouTube and long-form videoReduce uncertainty through depthWalkthrough, comparison method, implementation explanation or detailed demonstrationUsing a long introduction to delay the answer the viewer came for
    Owned websitePreserve the canonical factsClear product, service, use-case, methodology, limitation and evidence pagesPublishing vague claims that third parties and AI systems cannot verify
    AI discovery surfacesSynthesize options and explain relevanceConsistent entity information, answerable content and corroborated claimsAssuming schema or repeated brand copy can manufacture authority
    Paid discoveryPlace a relevant option in an active decision contextIntent-matched message and a landing experience that continues the questionTreating placement as proof of endorsement

    Start with evidence that can travel

    Digital PR is most valuable here as an authority layer, not as a temporary traffic event. Credible third-party coverage can turn a brand assertion into something audiences, creators and machines can evaluate outside the brand’s own website. Social discovery then gives that evidence context: people can see how it works, question it and decide whether it applies to them. That combination of earned credibility and platform-native validation is stronger than reach on either side alone.

    For every campaign claim, create a compact evidence packet that other teams can use without changing its meaning:

    • The exact claim in plain language.
    • The evidence supporting it and where that evidence lives.
    • The method, scope or conditions needed to interpret it correctly.
    • The limitations or cases where the claim does not apply.
    • The approved entity names, product names and descriptions.
    • The canonical URL that holds the complete version.
    • Visual or demonstrative material that shows the claim rather than merely repeating it.

    This packet prevents narrative drift. The PR team can pitch the defensible development. A video producer can demonstrate it. A community manager can answer the difficult question without improvising. The SEO and content teams can maintain a canonical explanation that remains useful after the campaign ends.

    Make owned content easy to interpret and hard to misquote

    Your canonical page should identify the entity, intended audience, use case, evidence, important limitations and next action without forcing a reader to reconstruct them from promotional language. Put the answer near the question it resolves. Use descriptive headings, stable terminology and internal links that explain related entities and concepts.

    Add appropriate JSON-LD only when it accurately represents the visible page. Organization, product, service, person and other entity markup can clarify relationships, but structured data cannot replace missing evidence or create third-party agreement. Treat schema as a consistency layer, not a reputation shortcut. If the visible copy, markup and external descriptions disagree, fix the underlying facts before adding more markup.

    Portability also requires restraint. A short video should lead with the demonstration, not attempt to contain every technical caveat. A Reddit response should answer the thread’s actual concern, not paste the campaign slogan. A YouTube explanation can carry the method and tradeoffs. The canonical page holds the complete record. The story remains consistent while the form changes to fit the reason someone uses each platform.

    Use conversational ads as paid context, not borrowed authority

    A person consults a glowing AI-style assistant surrounded by reference materials and community input, with a separate unbranded promotional tile nearby.

    Conversational advertising could become an important discovery channel because the placement can appear while a person is actively defining a need or comparing options. That is closer to a live decision context than a demographic feed placement. It is also easy to misunderstand.

    ChatGPT’s announced U.S. test was designed to put clearly labeled, relevant sponsored options at the bottom of responses. The planned audience included logged-in adults using the free tier or the $8-per-month ChatGPT Go plan. Pro, Business and Enterprise plans were set to remain ad-free, and users under 18 were excluded. Politics, health and mental-health conversations were also excluded from placement.

    Those are announced test conditions, not a permanent media specification. Availability, targeting, reporting, pricing and policy can change as the format is tested. Do not build a forecast that assumes this inventory is broadly available or that its initial rules will remain fixed. Verify the current buying interface, eligible audience, exclusions and measurement options before assigning budget.

    The most important boundary is answer independence. OpenAI says the advertisements will not affect the assistant’s response, conversation data will not be sold to advertisers, and users will be able to inspect why an ad appeared, dismiss it, disable personalization or clear ad-related data. The practical consequence is simple: an advertiser must not present the placement as an organic recommendation from ChatGPT.

    A conversational ad and an AI recommendation perform different jobs:

    • The unsponsored answer reflects the assistant’s generated response to the conversation.
    • The sponsored placement gives an eligible advertiser visibility beside that response when the system considers the offer relevant.
    • A citation points to material used or surfaced as support.
    • A brand mention shows recognition, but does not necessarily indicate preference or authority.

    Keep these outcomes separate in creative, reporting and executive updates. If a sponsored placement produces visits, report paid conversational discovery. Do not add those impressions to an organic AI visibility score or use them as evidence that the brand has become more authoritative in generated answers.

    Build an answer-adjacent campaign

    The strongest initial use case is likely to be a product or service that helps with the decision under discussion. Plan around the decision context rather than a broad audience label. A useful brief should state the question being asked, the unresolved need, the offer that genuinely fits and the reason the landing page is the logical next step.

    • Match the message to the conversation: Respond to the likely need instead of repeating a general brand line.
    • Continue the answer: Send the person to a page that immediately addresses the use case, comparison or constraint implied by the ad.
    • Show your status clearly: Do not mimic an assistant response, a citation or an independent recommendation.
    • Respect exclusions: Confirm topic, age, geography and plan eligibility before estimating reach.
    • Audit claims: Make sure every ad promise is supported on the destination page and remains consistent with your canonical facts.
    • Preserve choice: Do not design copy that obscures personalization, dismissal or privacy controls.

    Before buying, ask how conversational relevance is determined, what controls exist for placement and exclusions, which reporting dimensions are available, how personalization works, what data the advertiser receives and how conversions are attributed. The announced test does not establish all of those operational details. If the buying product cannot answer them, treat the channel as experimental and cap its role accordingly.

    Measure the journey, then launch a connected campaign

    Discovery channels often look weak in last-click reports because their work happens before the final visit. That does not make every impression valuable. It means you need measures that distinguish exposure, belief, machine visibility and commercial action.

    Use a layered scorecard

    Track the same decision question across the journey, then group signals by the job they perform:

    • Discovery: Relevant earned placements, on-platform search visibility, qualified video views, participation in useful community discussions, paid conversational impressions and new branded queries.
    • Authority: Independent mentions, links or citations from credible coverage, accurate reuse of your evidence and inclusion in serious category discussions.
    • Belief: Questions answered, substantive comments, saves, repeat brand mentions, comparison inclusion and reductions in recurring objections.
    • AI visibility: Brand mentions, cited pages, factual accuracy, recommendation context and the use cases with which the brand is associated.
    • Action: Engaged visits, returning direct traffic, assisted conversions, qualified enquiries, trials, purchases or another outcome tied to the actual business model.

    Do not collapse these into a single visibility score. A brand can be frequently mentioned and inaccurately described. It can be cited but not recommended. It can receive paid impressions while remaining absent from unsponsored answers. Keeping the dimensions separate tells you whether to improve distribution, authority, entity clarity, product fit or conversion design.

    AI checks need a reproducible log. Use a fixed set of real decision questions from your inventory. For each check, record the exact prompt, AI product or model, date, region, account state, personalization state, response, cited URLs and whether the brand was mentioned accurately. Repeat the checks under comparable conditions. A favorable screenshot from an isolated conversation is an anecdote, not a trend.

    For traffic and conversion analysis, tag every link you control with consistent campaign and content identifiers. Preserve referring pages where analytics allow it. Compare new and returning visitors, review assisted paths, monitor branded demand and include a self-reported discovery question when the buying journey makes that practical. If your volume supports a valid holdout, use it to test whether paid distribution creates incremental action rather than claiming conversions that would have happened anyway.

    Launch from a decision, not a content calendar

    Use this sequence for the next campaign:

    1. Select a consequential decision question. Choose one that sits close enough to commercial value to justify coordinated work and broad enough to appear on more than one discovery surface.
    2. Identify the belief gap. Write down what the audience would need to see, understand or verify before your brand becomes a credible option.
    3. Assemble defensible evidence. Reject claims that cannot survive independent scrutiny, community questions or a detailed comparison.
    4. Publish the canonical explanation. Make the entity, use case, proof, limitations and next action explicit. Align visible content, metadata and appropriate structured data.
    5. Create native expressions. Turn the same evidence into a demonstration, a deeper explanation, a transparent community response and a PR angle. Preserve the claim while adapting the format.
    6. Distribute by channel role. Use earned outreach for authority, social search for demonstration and validation, owned pages for completeness, and paid media for relevant additional reach.
    7. Separate paid and organic AI outcomes. Label conversational ad results as paid discovery and audit unsponsored mentions independently.
    8. Review the full path. At campaign checkpoints, compare discovery, authority, belief, AI visibility and action. Fund the channels that remove a documented decision barrier, not merely those that generate the largest surface-level count.

    Before approving another isolated channel campaign, choose the decision question it is meant to change and identify the other surfaces a buyer will use to verify the answer. Connect those surfaces around defensible evidence. That is how an emerging channel becomes part of a durable discovery system instead of another disconnected experiment.

    References

  • Apple’s Gemini-Powered Siri: An AI Search Action Plan

    Apple’s Gemini-Powered Siri: An AI Search Action Plan

    If you lead SEO or content discovery, Apple’s deal with Google changes what you should prepare for, but not what you can claim to measure. A more capable, personalized Siri could answer more questions inside Apple’s interface, leaving fewer searches that begin with a conventional results page.

    Your job now isn’t to chase a secret Siri ranking factor. It is to make your best information easy for an answer system to retrieve, understand, verify, and hand off, then preserve enough evidence to recognize when the upgraded Siri actually changes discovery.

    What Apple has confirmed, and what remains unknown

    Apple and Google have entered a multi-year collaboration covering Gemini models and cloud technology. Apple’s next generation of foundation models will be based on that technology and will help power future Apple Intelligence features, including a more personalized Siri expected later this year. Apple says Apple Intelligence will continue to run on its devices and through Private Cloud Compute.

    The architecture matters. Calling the upgrade “Gemini-powered Siri” is convenient shorthand, but it can create the wrong mental model. The confirmed relationship places Gemini beneath Apple’s next generation of foundation models. It does not establish that every Siri request will go directly to the public Gemini service, that Siri will become a reskinned Gemini app, or that Google will control the Siri experience.

    AreaConfirmedNot yet confirmed
    Model foundationApple’s next-generation foundation models will be based on Google’s Gemini models and cloud technology.The exact Gemini model, request-routing logic, and division of work between models.
    Siri upgradeA more personalized Siri is among the future Apple Intelligence features the collaboration will help power.An exact release date, supported-device list, language coverage, and regional availability.
    Privacy architectureApple says Apple Intelligence will continue to operate on Apple devices and Private Cloud Compute.How each category of Siri request will be partitioned across device, private cloud, and underlying model infrastructure.
    Content discoveryNo Siri-specific ranking, citation, or publisher-reporting mechanism has been disclosed.Which indexes Siri will use, how sources will be selected, when links will appear, and what referral data publishers will receive.

    Use that boundary in your roadmap. Put confirmed capabilities in the planning column and everything else in a testing backlog. If a proposed project depends on Siri supporting a particular schema type, exposing citations, or copying Google rankings, it is not ready to become a production requirement.

    Treat Siri as a distribution layer, not a Google ranking tab

    A smartphone routes an abstract question through connected information sources and produces a concise answer with several handoff paths.

    Gemini beneath Apple’s model stack does not mean Siri will inherit the Google Search index, ranking system, or citation behavior. A model can formulate an answer without owning the retrieval system that found the facts. Apple can also apply its own interfaces, policies, personalization, and privacy controls after a model generates or interprets information.

    That distinction changes the goal. A traditional search program often treats the ranked page and the resulting visit as the main units of success. An assistant can split that journey into three separate outcomes:

    • Selection: Your information helps form the answer, whether or not the page is shown.
    • Attribution: Siri names your organization, product, expert, or page as the source of a claim.
    • Action: The user visits, calls, navigates, subscribes, buys, books, or completes another useful next step.

    Do not collapse those outcomes into a vague idea of “ranking in Siri.” A page could influence an answer without receiving a visit. A brand could be named without a clickable citation. A linked page could earn traffic while contributing little to the generated wording. Each outcome needs its own observation and objective.

    Assign the objective by task. For an educational question, prioritize factual inclusion, accuracy, and attribution. For a commercial comparison, prioritize correct qualification and a useful destination page. For a local or service task, prioritize accurate entity data and a low-friction handoff. This keeps your strategy useful even if Apple’s final interface differs from current AI answer products.

    Build content Siri can extract, verify, and hand off

    Structured content cards pass through an illuminated verification system before reaching a smartphone and a webpage handoff.

    You do not need a speculative Siri optimization layer. You need pages whose important facts survive when separated from navigation, brand language, and surrounding prose. Audit the pages closest to a decision or action in this order:

    1. Start with assistant-shaped tasks. Collect the questions people ask before contacting support, choosing a product, visiting a location, or completing a purchase. Preserve the natural wording instead of converting every task into a short keyword. “Does this work with my current plan?” carries conditions that a generic phrase such as “plan compatibility” loses.
    2. Put the decisive answer before the sales argument. The first relevant subsection should identify the subject and answer the question directly. Follow it with conditions, exceptions, evidence, and the next step. Avoid introductions that require an answer system to infer the conclusion from several paragraphs of positioning.
    3. Scope every fact that can change. Name the product edition, software version, location, audience, availability condition, or effective date when it affects the answer. Replace floating statements such as “it is included” with language that identifies what is included, for whom, and under which plan or version.
    4. Align visible content with JSON-LD. Use structured data to label facts a visitor can verify on the page, not to insert claims that the page does not make. Names, descriptions, relationships, availability, authorship, locations, and other entity details should agree across markup and visible copy. More schema is not automatically better; accurate schema attached to a clear page is the useful target.
    5. Give important entities a stable home. Maintain a canonical page for the organization, product, service, location, or expert that matters to the query. Use consistent names and internal links so an answer system does not have to guess whether abbreviations, old product names, and near-duplicate pages describe the same entity.
    6. Make proof adjacent to the claim. Link consequential claims to the primary policy, specification, methodology, or other supporting material. Identify who owns the information and when it was last reviewed where freshness matters. A generic references page is less useful than evidence connected to the exact statement it supports.
    7. Remove retrieval barriers. Check that the intended page returns a successful response, is not accidentally excluded from indexing, declares the correct canonical URL, and exposes its main answer without requiring a login or an interaction. Do not place an essential fact only inside an image, video, downloadable file, or script-dependent interface when it can also appear as clear HTML text.
    8. Design the handoff. When a user needs to continue, provide a destination that matches the answer: the relevant booking screen, product configuration, support procedure, location page, or contact route. A generic homepage forces both the assistant and the user to reconstruct the journey.

    This work is not a guarantee of inclusion in Siri. It improves the properties that any retrieval-and-answer system needs: identifiable entities, explicit facts, credible support, accessible pages, and a coherent next action. It also strengthens your content before Apple reveals any Siri-specific controls.

    Measure Siri visibility without inventing a rank

    No query-level Siri reporting, citation rule, or referral format has been confirmed. A single “Siri rank” is therefore not a defensible key performance indicator. Build a repeatable observation system instead.

    Create a query ledger before the rollout

    Save the tasks that matter while your team still has a clean baseline. Record the exact prompt, not just its topic. Because Apple is promising a more personalized Siri, context will matter when you compare results. Keep test conditions consistent where possible and record meaningful differences rather than treating every response as universal.

    FieldWhat to record
    Business taskThe decision or action the user is trying to complete.
    Exact promptThe full wording, including follow-up questions in a multi-turn interaction.
    Test contextDate, device, operating-system version, language, region, and any relevant account state that can be documented safely.
    Observed answerThe material claims, recommendations, omissions, and errors in the response.
    AttributionWhether the brand, expert, page, or another source is named or linked.
    HandoffThe page, app, action, or service offered as the next step.
    OutcomeWhether the user could complete the intended task accurately and with reasonable effort.

    Classify each result rather than assigning an improvised position. Was your information included? Was the entity identified correctly? Was there visible attribution? Did the handoff reach the right destination? Was the task completed? Those questions reveal where the discovery chain works and where it breaks.

    Use web analytics conservatively. A recognizable referral can support attribution when one is exposed, but missing referral data does not prove that Siri had no influence. An unexplained increase in direct traffic does not prove Siri caused it either. Corroborate analytics with captured responses, destination-page changes, and repeated tests from your defined query set.

    Once the upgraded Siri reaches the devices, languages, and regions relevant to your audience, rerun the same tasks before changing your content strategy. Look for stable patterns across repeated observations. One surprising answer is a test case, not an algorithm update.

    FAQ for SEO and AI visibility teams

    Will strong Google rankings automatically produce Siri visibility?

    No automatic relationship has been confirmed. Gemini is part of the model foundation in Apple’s plan, but a model foundation is not the same thing as a search index or ranking pipeline. Keep improving conventional search performance, but measure Siri selection, attribution, and handoffs independently when the upgrade becomes available.

    Do you need special Siri schema markup?

    No Siri-specific schema requirement has been announced. Use the schema vocabulary that accurately describes the visible page and validate the resulting JSON-LD. Do not add irrelevant types, invented properties, or hidden claims merely to mention Apple, Siri, Gemini, or AI.

    Should you change traffic forecasts before Siri launches?

    No. Model the upgrade as a discovery scenario, not a booked traffic gain or loss. Fund improvements that help across search and answer systems now, such as entity cleanup, answer-focused editing, evidence mapping, technical accessibility, and baseline testing. Wait for observable Siri behavior before attaching a platform-specific forecast.

    In your next planning cycle, choose the assistant-shaped questions tied to real decisions, audit the pages responsible for answering them, and start the query ledger. When the upgraded Siri reaches your audience, test those same tasks first. Let observed selection, attribution, and action patterns determine the next investment, not the presence of the Gemini name.

    References