Tag: AI Discovery

  • How to Build Trust in AI-Driven Financial Research

    How to Build Trust in AI-Driven Financial Research

    You can make financial research easy for an AI system to find, summarize, and cite. The harder question is whether the answer remains trustworthy after the system compresses it. A careful analysis can become a dangerously confident sentence when its evidence, assumptions, or limits disappear.

    Your job is therefore larger than increasing AI visibility. You need to publish answers whose meaning survives extraction: the claim stays connected to its evidence, the reasoning can be inspected, and the boundary between general research and personal financial advice remains unmistakable.

    Key takeaways

    • Optimize financial research for verification before visibility. Search exposure cannot make an unsupported conclusion reliable.
    • Place the evidence, reasoning, relevant date, and limiting condition close to every consequential claim.
    • Connect technical signals, fundamentals, alternative data, and portfolio context without forcing them into artificial agreement.
    • Write important qualifiers into the sentence an AI system is most likely to extract, not into a distant disclaimer.
    • Use structured data and on-page optimization to describe trustworthy content, never to manufacture the appearance of authority.

    Trust begins where the answer can be checked

    Financial information has a short trust fuse because weak or inaccurate research can produce fast, measurable consequences. A vague answer about an ordinary purchase might waste time. A vague answer that influences a trade, allocation, credit decision, or risk assessment can lose money.

    That changes the minimum standard for a useful page. A reader should be able to identify what you know, how you know it, what you inferred, and what could invalidate the inference. An AI-generated summary should preserve those distinctions instead of presenting every sentence as an equally established fact.

    Use a six-field answer card

    Before drafting a financial answer, complete these six fields. They can live in your editorial brief, content management system, or review checklist:

    1. User question: Record the exact decision or uncertainty the page will address. A broad topic such as market risk is not yet a usable question.
    2. Bounded answer: Write the shortest conclusion the available evidence can support. Include the market, asset, period, or scenario that limits the claim.
    3. Evidence: Identify the underlying observations and where they came from. Preserve relevant dates, units, definitions, and methodology.
    4. Reasoning: Show how the evidence leads to the conclusion. Name any assumption that the argument needs in order to hold.
    5. Limit: State what the evidence does not establish, which alternative explanation remains possible, and what would change the conclusion.
    6. Ownership: Assign responsibility for reviewing, updating, correcting, or withdrawing the answer when its basis changes.

    If you cannot complete the evidence or limit field, do not ask a language model to fill the gap. Its fluent transition may disguise the absence of support. Publish a narrower answer, label the uncertainty, or withhold the conclusion until it can be checked.

    Separate observation, calculation, and interpretation

    A trustworthy answer distinguishes three layers that are often blended together:

    • Observation: What was measured, reported, or recorded?
    • Calculation: What transformation or comparison did you apply to those observations?
    • Interpretation: Why might the result matter, and which assumptions connect it to that meaning?

    Labeling these layers prevents an interpretation from inheriting the apparent certainty of the underlying data. It also gives an AI system clearer units of meaning to retrieve. Instead of receiving a paragraph that mixes facts and forecasts, the system encounters an explicit evidence chain.

    Keep the safety boundary close to the consequential statement. If a conclusion could influence an individual’s financial decision, present it as general research and direct the reader to a qualified financial professional for advice based on their circumstances. A footer disclaimer does not repair personalized or overly certain language in the main answer.

    Connect the evidence without hiding disagreement
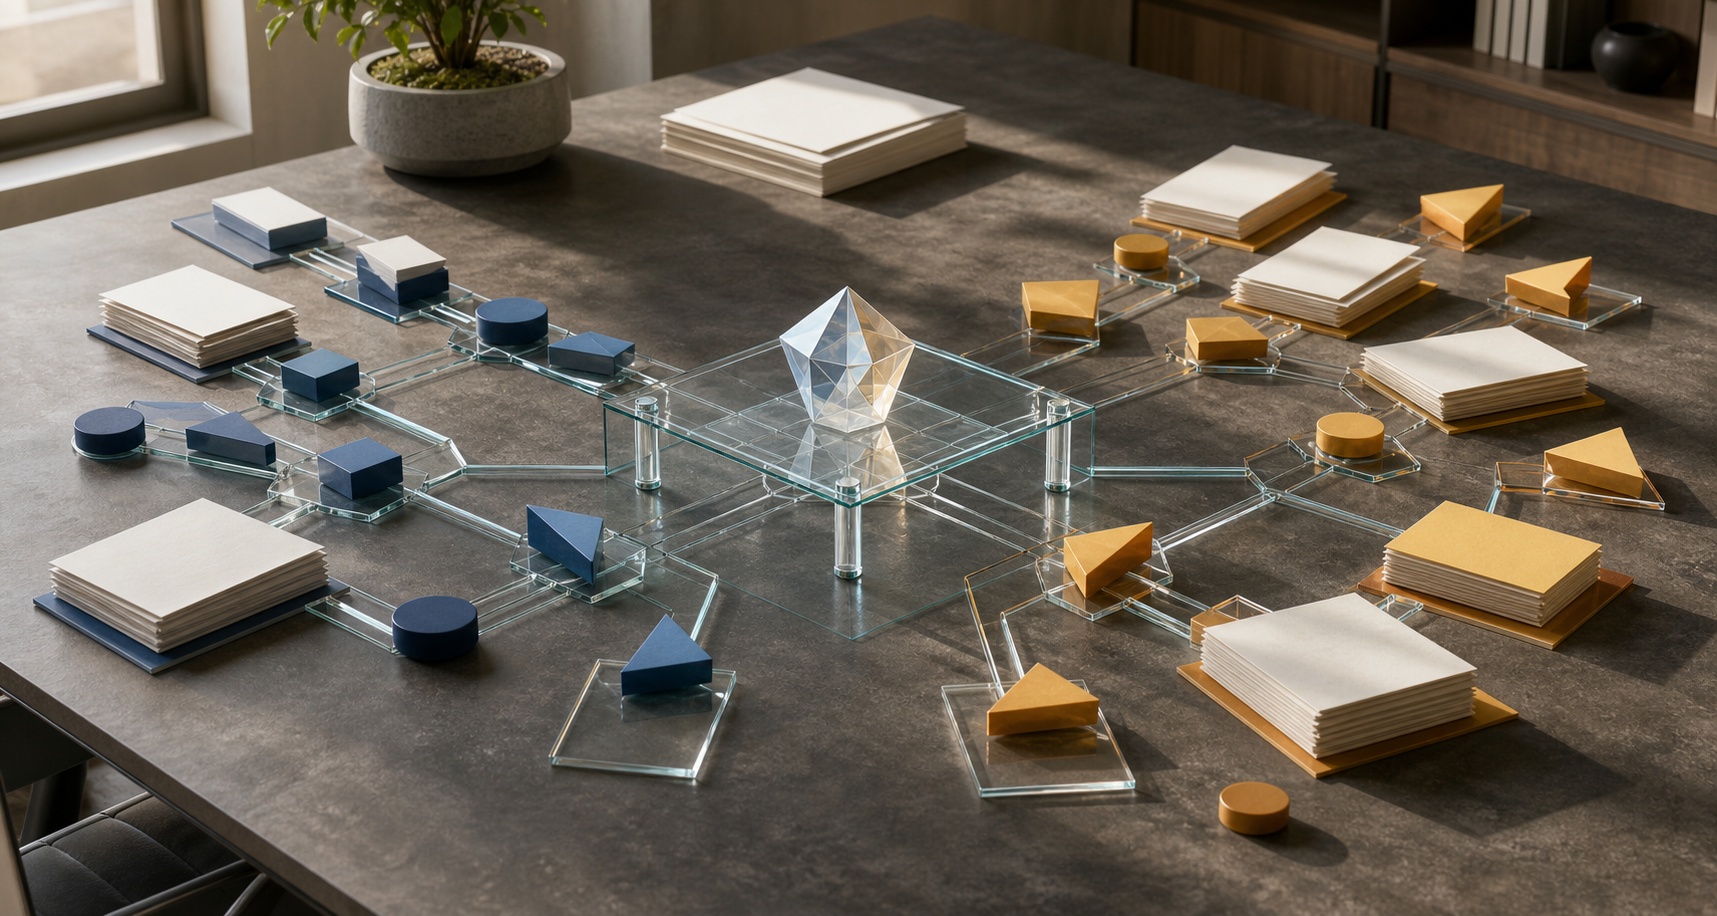
    Blue and amber evidence trails remain visibly separate while connecting to a shared transparent model on a research table.

    Trust weakens when readers have to assemble an answer from unrelated dashboards, definitions, charts, and commentary. Each extra handoff introduces another opportunity to misread the period, use a different definition, or miss an important qualification. Fragmentation also makes it harder to demonstrate that you understand how the pieces relate.

    A stronger research experience connects technical signals, fundamentals, alternative data, and portfolio analysis in context. This does not mean squeezing every available metric onto one screen. It means giving the user a coherent route from question to conclusion.

    For a consequential research question, organize that route in this order:

    1. Answer: Give the bounded conclusion and its main limitation.
    2. Change: Show what happened and the comparison that makes the change meaningful.
    3. Drivers: Explain the mechanisms that could account for it.
    4. Cross-checks: Show which other evidence supports, weakens, or contradicts the interpretation.
    5. Relevance: Explain how the finding may affect a general research or portfolio question without turning it into personal advice.
    6. Method: Make definitions, provenance, calculations, and update information available where the reader needs them.

    The cross-check stage matters. Connected research is not research in which every indicator agrees. If a technical signal points one way while fundamentals or alternative data point another, preserve the disagreement. Explain whether the measures cover different time horizons, definitions, or mechanisms. If you cannot reconcile them, say that plainly.

    Clarity does not mean removing complexity. It means helping the reader distinguish relevant complexity from clutter. Even an experienced investor benefits when you explain why a development is significant rather than merely reporting that it occurred.

    A useful explanation answers five questions: What happened? Compared with what? Through which mechanism could it matter? What else could explain it? What evidence would make us revise the conclusion? Those questions turn a data display into reasoning the reader can inspect.

    Centralization can be achieved without creating an enormous page. Use shared definitions, consistent labels, visible dates, stable identifiers, and direct links between related modules. The goal is continuity of meaning. A reader moving from a chart to a methodology note should not have to guess whether the same term, period, or calculation still applies.

    Optimize for AI retrieval without manufacturing authority

    Keyword coverage can help a page become discoverable, but it cannot establish financial expertise. In AI-driven discovery, visibility increasingly depends on being consistently useful and demonstrating depth, consistency, and reasoning. That requires three separate layers of work.

    LayerQuestion to askWhat to doWhat it cannot fix
    Technical accessCan a search or AI system reach and read the main answer?Keep the substantive answer in accessible page content, maintain clear internal links, and make machine-readable descriptions consistent with what users can see.Missing evidence or an unsupported conclusion.
    Semantic extractionCan a passage retain its meaning when removed from the page?Use descriptive headings, stable terminology, explicit relationships, and short passages that keep claims beside their qualifiers.Ambiguous reasoning or conflicting definitions.
    Epistemic credibilityCan a reader inspect why the claim should be believed?Expose provenance, calculations, assumptions, counterevidence, limitations, and review ownership.Stale, inaccurate, or fabricated inputs.
    Decision safetyCould the answer be mistaken for individualized advice?Define the intended use, avoid prescriptive language about personal circumstances, and place warnings beside the relevant conclusion.A risky claim hidden behind a general disclaimer.

    Apply these layers in order. Making weak analysis easier to crawl only distributes the weakness. Adding structured data to vague content only describes the vagueness more efficiently. Technical optimization should expose a sound evidence structure that already exists on the page.

    At the page level, use these rules:

    • Lead with the bounded answer. State the conclusion, scope, and main qualification before expanding the analysis.
    • Use headings that describe the reasoning. A heading such as “Why the indicators disagree” carries more information than “Analysis.”
    • Keep one main claim per paragraph. This makes extraction cleaner and reduces the chance that a qualifier will attach to the wrong conclusion.
    • Put evidence links beside the supported claim. A generic bibliography forces readers and machines to reconstruct the relationship.
    • Keep critical qualifiers in the same sentence. Write “under these assumptions” or “for this period” where the conclusion appears.
    • Define terms once and use them consistently. If two metrics sound similar but differ, explain the distinction before comparing them.
    • Make visible content and machine-readable markup agree. Structured data should reflect the answer, authorial responsibility, and other information actually available to the reader.

    Avoid producing thin pages for every wording of the same query. Financial authority emerges from linking concepts and showing their relationships in a comprehensive answer. One well-maintained explanation with clear subtopics is usually a stronger foundation than a collection of near-duplicates that omit context.

    Run a trust audit before the page becomes an AI answer
    Three analysts inspect linked evidence nodes, blank source documents, and output layers during a research trust review.

    Your final review should test more than grammar, keyword use, and formatting. It should simulate what happens when a search engine, assistant, analyst, or hurried reader extracts only the most quotable part of the page.

    1. Build a claim ledger. Copy each consequential claim into a review sheet. Label it as an observation, calculation, interpretation, scenario, or recommendation. If the label is unclear, the sentence probably blends categories.
    2. Trace the evidence. Confirm that every observation has identifiable provenance and that the relevant date, definition, unit, and scope remain available. Do not accept a citation that merely discusses the same topic.
    3. Reperform the reasoning. Follow the path from evidence to conclusion without relying on the prose’s confidence. Check whether a missing assumption or alternative explanation breaks the chain.
    4. Test the qualifier. Copy the key conclusion into a blank document. If it becomes misleading without a nearby paragraph, rewrite the sentence so its essential boundary travels with it.
    5. Look for forced agreement. Identify evidence that conflicts with the conclusion. Explain the disagreement, narrow the claim, or state that the result is unresolved.
    6. Check the decision boundary. Ask whether a reasonable reader could mistake general research for an instruction tailored to their finances. If so, revise the language and position professional-help guidance next to the risk.
    7. Assign the next review. Record what type of change would trigger reassessment and who can correct or withdraw the conclusion. Trust depends on how you handle changed information, not only how carefully you launch a page.

    Use a simple release gate. Publish when the evidence, reasoning, scope, and limits are all inspectable. Revise when the evidence is sound but the extracted answer could mislead. Hold the page when a consequential conclusion cannot be verified. Do not let polished AI-generated prose turn that third condition into the second.

    Start with one financial page that already attracts an important question. Rebuild it around the six-field answer card, connect the evidence that a reader would otherwise have to assemble, and run every key sentence through the extraction test. Once it passes, use that page as the editorial pattern for your wider AI search strategy.
    References

  • SEO and AEO for AI Discovery: A Practical Playbook

    SEO and AEO for AI Discovery: A Practical Playbook

    Your team has a practical decision to make: keep investing in conventional SEO, redirect the budget toward answer engine optimization, or somehow do both without doubling the workload. Treating those as competing programs is the mistake.

    The stronger approach is one discovery system. SEO makes your pages eligible to be found and trusted. AEO makes their answers easier to extract, verify, cite, and recommend. The work overlaps, but the outcomes and measurements are not identical.

    Key takeaways: build one discovery system, not two

    • Protect the SEO fundamentals that still produce most discoverable traffic: query alignment, useful content, internal links, authority, freshness, performance, and conversion paths.
    • Give every important page a specific query, audience, intent, answer unit, supporting evidence, and next action.
    • Place direct answers near the headings that introduce them. Add conditions, evidence, and limitations close to the claims they support.
    • Use JSON-LD to clarify visible entities and relationships. It cannot compensate for thin content, ambiguous positioning, or unsupported claims.
    • For buying-intent queries, improve your presence on relevant review platforms, directories, publications, marketplaces, and video channels instead of relying only on your own domain.
    • Measure search performance, tested AI visibility, referral traffic, and conversions separately. A brand mention is not automatically a citation, a visit, or a sale.

    Start with the query and the decision behind it

    A professional considers several symbolic options as branching paths narrow toward one illuminated solution.

    ‘Optimize for AI’ is too vague to guide a page edit. A person asking for a definition needs a concise explanation. A person comparing vendors needs criteria, tradeoffs, and corroboration. A person ready to buy needs accurate product facts and a clear next step. Those are different retrieval tasks, even when they contain the same topic keyword.

    Before changing content, create a discovery brief for each query cluster:

    1. Write the actual query. Include the audience, use case, constraint, or purchase stage that changes the answer. ‘Payroll software’ is a topic; ‘payroll software for a small nonprofit’ expresses a decision.
    2. Label the intent. Decide whether the person wants an explanation, instructions, a comparison, reassurance, a shortlist, or a transaction.
    3. Define the answer unit. Choose the smallest useful form of the answer: a definition, ordered process, criteria list, comparison table, calculation, specification, or recommendation with conditions.
    4. Identify the required proof. List the facts, examples, first-party details, independent reviews, author credentials, or other evidence a reader would need before relying on the answer.
    5. Choose the next action. Decide what a satisfied visitor should do after receiving the answer. That could be reading a deeper explanation, checking compatibility, comparing plans, requesting a demonstration, or buying.

    This brief tells you whether an existing page should be improved, merged with an overlapping page, or replaced with a more appropriate format. It also prevents a common AEO failure: adding repetitive FAQ sections to pages that still do not resolve the underlying decision.

    Use the found-understood-extracted test

    Review the page in three passes. First, can a search system find and interpret it? Check crawl access, indexability, canonicalization, internal links, title, main heading, and the relationship between the query and the page. Second, can a reader or machine determine who and what the page is about? Check named entities, terminology, authorship, dates, and contextual links. Third, can the answer be lifted without losing a critical condition? Check whether the conclusion, evidence, scope, and caveats appear together.

    If the page fails the first pass, answer formatting will not rescue it. If it fails the third, it may rank and still be difficult to reuse in an AI-generated response.

    Fix the SEO layer that AEO still relies on

    AI discovery is growing, but it does not justify abandoning the channel already producing demand. One reported benchmark puts collective LLM referral volume at roughly 2%-3% of the organic traffic supplied by Google. That ratio is directional, not a universal forecast: it will vary by market, audience, attribution method, and the kinds of questions customers ask.

    The implication is straightforward. Fund AI visibility by extending sound SEO work, not by suspending it. Audit in this order:

    1. Align the title with the query and page promise. Include the language your audience uses when it accurately describes the page. A title should distinguish the page, not collect every keyword variation.
    2. Resolve intent near the top. The opening should confirm the audience’s problem and provide the core answer. Do not make a reader cross a long general introduction before learning whether the page applies.
    3. Strengthen the information architecture. Link to the page from relevant hub and supporting pages with descriptive anchor text. Link back to definitions or evidence when the current page depends on them.
    4. Refresh substance, not only dates. Correct stale facts, remove obsolete recommendations, improve weak examples, close missing subtopics, and preserve a useful URL when its purpose has not changed. Updating a timestamp by itself creates no new value.
    5. Resolve duplication. When several pages answer the same intent, choose the strongest destination and consolidate the useful material. Competing pages make it harder to establish a clear canonical answer.
    6. Protect the visit after the click. Keep pages fast and stable, make navigation predictable, and give the visitor a next step that matches the query. More visibility has limited value if the page cannot convert attention into progress.

    Make changes in identifiable batches and keep a log. If a title, internal-link module, content revision, and template redesign launch together, you will struggle to tell which intervention affected impressions, clicks, AI citations, or conversions.

    Use JSON-LD as clarification, not decoration

    Structured data should express what the page visibly contains. Mark up the real publisher, author, product, organization, or other applicable entity; keep identifiers consistent across templates; and connect related entities only when the relationship is supported on the page.

    • Select the most specific applicable schema type rather than attaching unrelated types in the hope of gaining visibility.
    • Keep names, URLs, dates, availability, prices, ratings, and other marked-up properties consistent with the visible content.
    • Do not manufacture reviews, ratings, authors, or credentials for markup.
    • Use stable identifiers for the same entity across pages instead of describing it as a new object on every URL.
    • Validate the generated JSON-LD after theme, plugin, field, or template changes. Correct source fields can still produce broken output when templates change.

    Schema can reduce ambiguity. It does not force a model to quote the page, make an unsupported claim credible, or turn a generic article into the best answer.

    Make text and images easy to extract without stripping context

    Structured content blocks lift from a complete web page into abstract search, AI answer, and image preview panels while remaining connected to their source.

    AEO is partly an information-design problem. A useful answer must be easy to locate, but it must also remain accurate when a system separates the passage from the rest of the page. That requires more than writing a short paragraph.

    Build answer units around complete claims

    For every important heading, place the direct answer in the first paragraph that follows it. Then add the evidence, method, conditions, exceptions, and next level of detail. A reader should be able to understand the short answer immediately and inspect the reasoning without leaving the section.

    • State the conclusion. Answer the heading in plain language before expanding it.
    • Carry the scope with the answer. If a recommendation applies only to a platform, audience, use case, geography, or time period, name that boundary in the same passage.
    • Put evidence beside the claim. Link the words that depend on external evidence rather than dropping an unexplained reference at the end of the page.
    • Define terms once. Use the same name for the same concept or entity throughout the page. Unnecessary synonyms can make relationships less clear.
    • Use the format the answer requires. Processes belong in ordered lists, criteria in lists, and genuine field-by-field comparisons in tables. Do not force prose into a table simply to appear structured.
    • Separate fact from judgement. Label editorial recommendations as recommendations, and explain the criteria used to reach them.

    This structure helps human readers scan while giving answer systems a coherent passage to reuse. It also reduces the risk that a caveat sits several paragraphs away from the claim it limits.

    Audit images for the machine eye

    Images now carry extractable information as well as visual appeal. OCR can read labels and annotations, while multimodal systems can interpret objects, context, and relationships inside a scene. Compression damage, tiny text, weak contrast, and ambiguous alt text can therefore change what a machine believes the image shows.

    Keep the established performance work: serve appropriately sized files, compress them carefully, reserve their display dimensions, and use lazy loading where it does not interfere with important above-the-fold media. Then add a machine-readability pass:

    • Inspect the image at its rendered size, not only in the original design file.
    • Use 30 pixels as an audit target for the height of critical embedded characters, not as a guarantee that every OCR system will read them correctly.
    • Increase contrast between text and its background. Avoid placing essential wording over glare, reflections, textures, or visually busy areas.
    • Write alt text that identifies the meaningful subject and context. Do not turn it into a list of target keywords.
    • Place a useful caption or nearby explanation beside images whose meaning is not obvious from the pixels alone.
    • Use original diagrams, screenshots, and product photography when they add evidence or experience that generic stock media cannot provide.
    • Repeat essential specifications, prices, warnings, and instructions as accessible page text. Do not make OCR the only route to important information.

    For a chart, annotated screenshot, or product label, perform a simple failure test: if the text inside the image vanished or was read incorrectly, would the surrounding page still communicate the fact? If not, add a textual equivalent.

    Earn third-party validation and measure the right outcome

    Informational visibility can often begin with a strong answer on your own site. Commercial recommendations are more dependent on corroboration. A model evaluating ‘best,’ ‘top,’ ‘most reliable,’ or ‘alternatives to’ queries may look for evidence beyond what a brand says about itself.

    Within one company-run 2025 dataset of 36,127 ChatGPT buying-intent queries, product-recommendation media received 7,642 citations, consumer-review platforms 5,983, traditional media 4,581, commercial or brand sites 2,208, and forum communities 674. Treat those figures as a directional snapshot of one methodology, query definition, model, and period. They do not establish permanent citation weights or prove that placement on a particular site causes inclusion.

    They do expose a useful planning error: publishing more brand copy is not the same as building recommendation evidence. For every high-intent query, create a citation-gap record with these fields:

    1. Prompt and purchase stage: record the exact question and whether the person is exploring, comparing, validating, or ready to choose.
    2. Named and cited brands: distinguish a brand mention from a linked or named supporting page.
    3. Evidence surfaces: classify the cited domains as publications, review platforms, directories, marketplaces, video channels, communities, institutions, or brand sites.
    4. Selection criteria: identify the features, reputation signals, use cases, or constraints used to justify the recommendation.
    5. Legitimate gap: determine whether your brand actually qualifies. If it does, correct inaccurate listings, complete relevant profiles, make verifiable product information available, or pursue editorial coverage on its merits.
    6. Owned-page correction: update the page that should act as the definitive first-party record for features, positioning, compatibility, policies, or other facts.

    Do not fabricate reviews, seed undisclosed endorsements, or force a brand into irrelevant directories. Those tactics create reputation risk and unreliable evidence. The goal is consistent, independently supportable information across the places a buyer would reasonably consult.

    Evaluate AEO vendors by the work behind the label

    The AEO label covers a wide range of services: 78 firms were screened to create one eight-company shortlist during a 2025 provider review. The size of that field is a reason to inspect methods, not a reason to accept a category label as proof.

    Ask a prospective provider to show how it handles technical SEO, answer architecture, structured data, entity consistency, off-site citations, reputation signals, image readability, controlled prompt tracking, and business attribution. Ask which changes happen on your site, which depend on third parties, which outputs you will own, and how it separates tested visibility from actual traffic and conversions. A single proprietary visibility score cannot answer all of those questions.

    Keep four measurements separate

    Search and AI discovery create different observable signals. Put them on one scorecard, but do not collapse them into one number.

    MeasurementWhat it can showWhat it cannot prove
    Search impressions, rankings, and clicksWhether pages are being surfaced and chosen in conventional results for tracked queriesWhether an answer engine mentions or cites the brand
    Mentions and citations across a fixed prompt setHow the brand appears for the specific models, versions, prompts, locations, and test dates recordedUniversal visibility across every user, prompt variation, or generated answer
    AI referral sessions and landing pagesWhich answer platforms send trackable visits and what those visitors do nextThe effect of unclicked mentions or answers whose referral data is missing or misclassified
    Qualified actions and conversionsWhether discovery produces meaningful business progress on the destination pageWhich individual edit caused the result when several changes launched together

    For prompt monitoring, store the exact prompt, model and version when available, test date, response, brand mention, cited URL, and recommendation context. Reuse the same core set after material changes. Generated answers can vary, so look for direction across repeated observations rather than treating one response as a stable rank.

    Start with one query cluster that matters to the business. Repair its titles and internal links, consolidate overlapping pages, rewrite the main answer units, validate the JSON-LD, audit the critical images, and map the third-party evidence gap. Record the baseline before publishing. Once that cluster gains stronger search visibility, more consistent answer inclusion, or better qualified actions, extend the same system to the next decision your customers need to make.

    References

  • Brand Visibility in Meta AI: A Practical Optimization Plan

    Brand Visibility in Meta AI: A Practical Optimization Plan

    Your Instagram and Facebook accounts can look active while your brand remains difficult for Meta AI to identify, explain or recommend. More posts won’t solve that problem if your name, category, offer and supporting evidence are inconsistent or buried inside promotional language.

    A better plan starts with the questions you want your brand to appear for. You then create a stable record of what the brand is, publish content that answers those questions, adapt that evidence to each Meta surface and test the resulting answers under repeatable conditions.

    Define the visibility outcome before you optimize

    “Brand visibility” is too broad to be a useful target. It can mean that Meta AI recognizes your name, understands what you sell, includes you in an unbranded recommendation or gives someone an accurate next step. Those are different outcomes, and each one exposes a different problem.

    Start with real user situations, not a generic goal such as “rank in Meta AI.” Group the questions that matter to your business by intent:

    • Discovery: Someone knows the problem or category but doesn’t know your brand.
    • Fit: Someone wants to know whether an option suits a particular audience, location, use case or constraint.
    • Evaluation: Someone is comparing approaches and needs meaningful differences, limitations and proof.
    • Validation: Someone has heard of your brand and wants to confirm what it does, whether it is credible or whether a claim is accurate.
    • Action: Someone wants the correct page, account, contact route or purchasing path.

    Write down the exact questions people are likely to ask. For each question, define what a satisfactory appearance would contain. A useful target might require the correct brand name, the right category, an accurate description of the offer, a relevant piece of evidence and a safe next step. “We should appear” isn’t specific enough to audit.

    Don’t make branded questions your only test. Asking “What is [Brand]?” measures whether the system can discuss a name the user has already supplied. Asking “Which providers solve [problem] for [audience]?” tests whether the brand can be discovered in the context that creates new demand.

    This distinction also prevents a common reporting mistake. Follower growth, feed reach and engagement can be useful channel metrics, but they don’t establish that Meta AI can represent the brand accurately. Track assistant visibility as its own outcome.

    Give Meta AI one coherent brand to understand

    A coordinated product box, bag and several blank social media content frames share the same teal-and-apricot geometric design.

    Before you create more content, establish a canonical brand record. This is the factual spine that should remain stable across your website, Instagram profile, Facebook presence and supporting content.

    Your internal record should settle the following points in plain language:

    • The exact brand name and any legitimate name variants.
    • The category the business belongs to.
    • The audience it serves and the problems it addresses.
    • The products, services or programs currently offered.
    • The geographic market or service area, where relevant.
    • The distinctions you can support with evidence.
    • The official website, social accounts and action paths.
    • Important boundaries, exclusions or eligibility conditions.

    Turn the core into a direct sentence: “[Brand] is a [category] for [audience] that provides [offer] in [market].” That sentence is an editorial control, not a slogan. It tells everyone producing content which facts must not drift.

    Consistency doesn’t require copying the same bio everywhere. It means the factual meaning survives every variation. One profile can be conversational and another can be detailed, but they shouldn’t assign the business to different categories, describe different audiences or send people to conflicting destinations.

    Run a contradiction audit before launching a new campaign. Compare your website, profile descriptions, About information, recurring captions and high-visibility explainers. Look specifically for:

    • Old names that remain in current-looking content.
    • Broad slogans that replace a clear category description.
    • Offers that have been renamed, narrowed or discontinued.
    • Different locations or service areas across properties.
    • Claims on social media that the website cannot substantiate.
    • Links that lead to obsolete pages or an unrelated homepage.
    • Third-party terminology that conflicts with the language you now use.

    Correct the properties you control before trying to overpower an error with more posts. Publishing new claims while prominent old claims remain live creates another version of the brand rather than a clearer one.

    Disambiguation matters when a name is generic, abbreviated or shared. Pair the name with its category, audience or location in visible text. A logo may tell a loyal customer who you are, but a sentence such as “[Brand] provides [service] for [audience]” gives both people and automated systems an explicit identity to work with.

    Publish evidence in a form that can answer a question

    A brand claim is not yet an answer. “Built for modern teams” doesn’t explain which teams, what the product does, when it fits or why anyone should believe the claim. If your content never resolves those points, an AI-generated answer has little dependable material to carry forward.

    Create a query-to-content map. Each priority question should have a clear, maintained destination that contains:

    • A direct answer: State the essential fact before the promotional explanation.
    • Scope: Identify the relevant audience, market, use case and conditions.
    • Support: Connect the claim to product details, documentation, policies, named credentials or other evidence you can verify.
    • Boundaries: Explain when the offer isn’t a fit or when the answer depends on a condition.
    • A next step: Point to the most relevant page or action rather than defaulting to a generic homepage.

    A practical content unit can follow this sequence: name the question, answer it in one plain sentence, explain the conditions, show the evidence, state the limitation and provide the appropriate action. The format works for product explanations, service-area pages, comparisons, policy answers and social captions because every element has a distinct job.

    Make important passages understandable on their own. Pronouns such as “it,” “this” and “they” become ambiguous when a sentence is separated from the surrounding post. Repeat the brand, product or service name where clarity requires it. This is useful writing, not keyword repetition.

    Apply the same rule to visual content. If a video or image contains an important product fact, include that fact in accessible supporting text such as the caption or transcript. The visual can carry the emotion and demonstration; the text should still identify the object, audience, claim and context. Essential meaning shouldn’t depend on a viewer recognizing an unlabeled product.

    Keep volatile facts maintainable. Pricing, availability, locations, eligibility and product status should have a clear canonical home. Update that destination when the fact changes, then align the social content that still receives attention. Scattering the same changing fact across many permanent assets makes contradictions more likely.

    If your website uses structured data, make sure the markup agrees with the visible page. Treat schema as a consistency and interpretation layer, not as proof of a direct Meta AI ranking lever. Perfect markup cannot repair vague copy, unsupported claims or conflicting brand information.

    Give each Meta surface a distinct content job

    Your brand can be encountered across Instagram, Facebook and the Meta AI chatbot. The factual spine should remain consistent, but the content unit that earns attention in a feed isn’t necessarily the one that resolves a detailed question.

    ContextPrimary content jobWhat to prepareFailure to catch
    InstagramMake the brand and its proof recognizable in a visual settingVisual demonstrations supported by captions that name the product, audience, use case and evidenced benefitThe content looks polished, but a new viewer cannot tell what is offered or for whom
    FacebookCarry fuller explanations, current business context and practical detailsMaintained profile information, clear explainers, question-led updates and links to canonical evidenceAn old description, link or offer conflicts with the current website
    Meta AI chatbotResolve a user’s question with an accurate brand representationDirect, self-contained answers and verifiable supporting pages for the prompts that matterThe brand is absent, placed in the wrong category, described inaccurately or mentioned without support
    Owned websiteAct as the canonical evidence layerStable brand facts, focused answer pages, clear ownership and aligned structured data where usedSocial claims have no durable destination where a person can verify them

    On Instagram, don’t force every caption to become a miniature landing page. Give the visual one clear proof job, then use the caption to identify what is being shown and why it matters. If the post demonstrates a workflow, name the workflow. If it shows a result, state what produced the result and avoid implying that one example is universal.

    On Facebook, use the room available to answer the questions that arise after initial interest: who the offer is for, what the process involves, where it is available and which conditions apply. Keep profile-level facts especially clean because they frame everything published beneath them.

    For chatbot visibility, work backward from the prompt. If someone asks for options in a category, can your public content connect the brand to that category without interpretation? If someone asks whether the offer fits a constraint, is the condition stated explicitly? If someone asks why the brand is credible, can they reach evidence rather than another assertion?

    Don’t clone every asset across every surface. Preserve the names, categories, claims and proof, then change the delivery. Instagram may demonstrate the claim, Facebook may explain its context and the website may hold the complete evidence. The message should become richer as the user needs more detail, not mutate into a different brand story.

    Audit prompts, diagnose the gap and fix it in order

    A laptop with a blank conversational interface sits beside organized brand evidence trays, while a magnifying glass highlights a broken connection in a chain of glowing nodes.

    AI visibility cannot be managed from a single screenshot. Wording and context can change an answer, so save the exact prompts you use and repeat them under comparable conditions. The goal isn’t to manufacture a universal score. It is to notice persistent omissions, factual errors and unsupported representations.

    Build the audit from your visibility brief. Include unbranded discovery questions, fit questions, comparison questions, brand-validation questions and action questions. Avoid leading every prompt with your desired answer. A test such as “Why is [Brand] the best option?” presupposes both inclusion and superiority; it tells you little about natural discovery.

    For every run, record:

    • The exact prompt and the user intent it represents.
    • The surface and testing context.
    • Whether the brand appeared without being named in the prompt.
    • Whether its category, audience, offer and location were correct.
    • Which material claim was present, missing or wrong.
    • Whether evidence or a useful path was surfaced, when the interface provided one.
    • Which controlled page or Meta asset should resolve the gap.
    • What you changed before the next comparable test.

    Use descriptive states instead of fake precision: absent, mentioned, accurately represented, supported and actionable. A brand can move through those states without becoming the first name in an answer. That movement still matters because correct representation is a prerequisite for trustworthy discovery.

    Read each pattern as a diagnostic hypothesis, not as proof of a hidden ranking factor:

    • Absent from unbranded prompts: Check whether your content explicitly connects the brand to the category, problem, audience and market in question.
    • Mentioned in the wrong category: Look for outdated bios, vague slogans, legacy pages and inconsistent third-party descriptions.
    • Correctly described but unsupported: Strengthen the evidence destination and connect relevant social claims to it.
    • Visible for the brand name but not the problem: Build content around the user’s situation instead of publishing more brand announcements.
    • Visible on a Meta profile but inaccurate in an answer: Compare prominent profile facts with the canonical website record and remove contradictions you control.
    • Accurate but not actionable: Replace generic links with a destination that matches the prompt’s intent.

    Fix gaps in a deliberate order. Accuracy comes first because additional distribution can spread an error. Resolve conflicting identity facts next. Then add the missing answer and evidence. Adapt it to the relevant Meta surface after the canonical version is sound. Amplification belongs at the end.

    1. Correct factual errors and potentially misleading claims.
    2. Align the canonical brand record across controlled properties.
    3. Create or improve the answer and its supporting evidence.
    4. Package the material for the relevant Meta context.
    5. Retest the same prompt before expanding the change.
    6. Apply the lesson to the next high-value query.

    Change one meaningful layer at a time when you want to learn from the result. If you rewrite the website, replace every profile description and launch a large campaign simultaneously, you may improve visibility but won’t know which gap mattered. Keep a simple change log tied to the prompt set.

    Key takeaways

    • Meta AI visibility is query-specific; define the user question and the acceptable answer before measuring it.
    • A stable brand record matters more than repeating identical promotional copy across channels.
    • Answer-ready content pairs a direct claim with scope, evidence, boundaries and a relevant next step.
    • Instagram, Facebook, the chatbot context and your website should perform different jobs while preserving the same facts.
    • Track absence, accuracy, support and actionability separately so you can fix the actual weakness.
    • Treat audit patterns as clues to investigate, not as proof that you have discovered Meta AI’s internal ranking formula.

    Start with the unbranded question that matters most to your next customer. Write the canonical answer, align the brand facts around it, publish evidence that can be checked and record a baseline response. Once that question is represented accurately, move to the next one. You will be building a maintainable visibility system rather than another stream of disconnected content.

    References

  • How to Capture AI-Driven E-commerce Demand on Black Friday

    How to Capture AI-Driven E-commerce Demand on Black Friday

    If your Black Friday plan stops at rankings, feeds, paid media, and conversion rate, it now has a blind spot. A shopper can ask an AI system to narrow a category, compare products, judge whether a discount is worthwhile, and recommend where to buy – without following the search journey you designed.

    Your job is not to make an AI repeat your promotion. It is to make your products easy to identify, compare, and verify while demand moves from early research to live deal hunting. That requires coordinated work across your own site, retailers, marketplaces, review coverage, video, and genuine customer discussion.

    Black Friday creates two different AI demand states

    A split scene contrasts calm product research at a desk with urgent mobile deal shopping at night.

    Before Black Friday, shoppers are reducing a large market into a shortlist. Their questions tend to concern suitability: which product fits a use case, what features matter, which compromises are acceptable, and whether waiting for a sale makes sense. When the event begins, the task changes. Price, availability, seller credibility, current sentiment, and the quality of the deal become more important.

    That change is visible in the domains AI systems use. In the week before Black Friday, retail and brand domains represented 59.6% of cited sources, media represented 23.4%, and social or user-generated content represented 17%. During Black Friday, the social and user-generated share rose to 25.1%, while retail and media lost share.

    Those percentages do not establish a permanent formula for every category or model. They do expose a useful operating distinction: the content that builds a shortlist is not sufficient on its own when shoppers want current confirmation from other people.

    Build your campaign around four information layers:

    • The identity layer explains what your brand sells, which categories it belongs in, and who its products are for.
    • The decision layer supplies specifications, use cases, limitations, compatibility details, and defensible comparisons.
    • The offer layer states the current price, discount terms, sale window, availability, fulfillment conditions, and applicable returns information.
    • The verification layer gives shoppers independent evidence through reviews, demonstrations, retailer listings, comparison coverage, and legitimate customer discussion.

    The first two layers should be settled before promotional demand arrives. The offer layer must be updated whenever the commercial facts change. The verification layer takes longer to earn, so it cannot be manufactured credibly on launch day.

    Make every offer answerable without reconstruction

    An AI system should not have to combine a slogan on your homepage, specifications in a PDF, a discount in a banner, and shipping terms in a support page to explain your offer. Every extra reconstruction step creates another opportunity for omission, confusion, or a stale answer.

    Start at the homepage because it is more than a navigational doorway. Within the examined brand-site citations, homepages accounted for 40%. Give that page a plain statement of what the brand is, the categories it serves, the customer problems it solves, and the main paths to product information. A clever campaign line can support that explanation, but it should not replace it.

    Then audit each priority product or offer page in this order:

    1. Use the exact product name and model consistently in the title, visible copy, structured data, retailer listings, and supporting content.
    2. State what the product is and who it suits near the top of the page. Do not make the reader infer the category from branding language.
    3. Present specifications as labeled facts. Include the dimensions, materials, capacity, compatibility, included components, or technical requirements that actually drive a decision in your category.
    4. Explain the important tradeoffs. A page that identifies who should not buy the product can be more useful than one that describes every shopper as an ideal customer.
    5. Place the live offer in visible text. Include the current price, reference price where applicable, conditions, start and end information, seller, stock state, and fulfillment details that a buyer needs to interpret the promotion.
    6. Add concise questions and answers for real research intents: compatibility, setup, maintenance, warranty, returns, common alternatives, and differences between adjacent models.
    7. Provide evidence close to the claim it supports. Demonstrations should show the use case, while reviews and technical documentation should be clearly attributable and reachable.

    Keep stable product facts separate from volatile promotional facts in your content workflow. The product’s dimensions should not change because a sale begins, but price and availability might. Assign ownership accordingly: merchandising maintains the offer state, while product or content teams maintain the underlying facts.

    Structured data can make those facts less ambiguous to machines, but it cannot rescue incomplete visible content. Product and Offer markup should agree with the page a shopper sees. If a price, availability value, model identifier, or seller differs between the markup and the page, the markup has added conflict instead of clarity.

    Finish with a manual extraction test. Give someone who did not build the page the URL and ask them to answer: What is this product? Who is it for? Why would they choose it over the closest alternative? What exactly is the Black Friday offer? What restriction could change the decision? If any answer requires another tab or an assumption, the page is not finished.

    Build comparison coverage before the promotion starts

    Brand pages are good at establishing first-party facts. Shopping recommendations require a second job: organizing choices and reducing uncertainty. That is why AI systems repeatedly draw from retailers, review publishers, video platforms, and community conversations when they construct commercial answers.

    Across 10,000 responses about deals, reviews, and product recommendations, YouTube received 1,509 citations, Best Buy 950, Walmart 885, Target 477, TechRadar 355, RTings 342, and Consumer Reports 325. The distribution was concentrated rather than evenly spread across the web.

    Retail concentration matters too. Generalist retailers held 48% of retail citations, while electronics specialists held 23%. Large retailers have broad assortments, familiar identities, and enough product information to answer many different shopping questions. A smaller brand is unlikely to reproduce that footprint, but it can make its category knowledge and product distinctions much easier to reuse.

    Create comparison pages around decisions, not around the phrase “best product.” A useful comparison should tell the reader:

    • Which products are genuinely comparable and which belong to a different use case.
    • What each option is best suited to, using a stated criterion rather than a vague superlative.
    • Which specifications materially change the experience.
    • What the buyer gives up by choosing the cheaper, smaller, faster, or more capable option.
    • Whether accessories, subscriptions, installation, or compatibility requirements affect the practical cost.
    • Which facts are stable product attributes and which are temporary Black Friday conditions.

    Publish first-party comparisons even when an independent reviewer would be more persuasive. Your version establishes accurate entities, specifications, and distinctions that other people can check. It should disclose its perspective and link to the underlying product details rather than pretending to be neutral.

    For third-party coverage, prioritize relevance over raw volume. Give suitable reviewers and publishers clean model names, current specifications, images, documentation, and access to products where your normal review policy allows it. Correct factual errors without trying to dictate conclusions. Inclusion in a trusted comparison is valuable because the comparison answers a real decision, not merely because it creates another brand mention.

    Treat off-site evidence as part of product information

    An unbranded device is connected to scenes of a reviewer, video creator, retailer display, and customer photo.

    Your website can declare what a product does. It cannot independently establish how the product behaves in ordinary use or how buyers feel about its compromises. AI shopping answers often seek that corroboration elsewhere.

    Within the observed set of key off-page signals, Reddit represented 34%, YouTube 19.5%, Amazon 15.5%, Business Insider 9.2%, and Walmart 8.9%. Treat these figures as evidence of concentrated influence in the examined responses, not as channel budgets or universal weights.

    Each environment contributes a different kind of evidence:

    • YouTube can show setup, scale, sound, motion, results, and other experiential details that are difficult to communicate in a specification table. Use accurate titles and descriptions, identify the exact model, and make spoken explanations clear enough to stand without promotional visuals.
    • Retailer and marketplace listings connect the product to a category, seller, price, reviews, and comparable inventory. Keep identifiers, variants, specifications, and images consistent with your own site.
    • Review coverage organizes alternatives and makes tradeoffs explicit. Give reviewers enough factual material to distinguish models without forcing them to decode your catalog.
    • Community conversations reveal recurring questions, edge cases, frustrations, and unexpected use cases. Use those conversations to improve product information and support. Do not simulate participation or manufacture endorsements.

    Consistency is the operational priority. If your site calls a product one name, a retailer shortens it, a video uses a family name, and marketplace variants omit the model number, you have created several weak identities instead of one strong one. Maintain a shared product record containing the approved name, model identifier, category, key specifications, variant labels, current imagery, and canonical URL. Give every channel owner access to it.

    Do not turn this into a backlink-counting exercise. A mention that does not help identify, compare, or verify the product contributes little to the shopping decision. Audit off-site presence by question instead: Where can a shopper see the product used? Where can they compare it with the nearest alternative? Where can they verify specifications? Where can they find credible discussion of its limitations?

    Run a two-phase AI visibility operation

    Black Friday AI optimization should operate in a preparation phase and a live phase. The preparation phase builds retrievable facts and comparison context. The live phase protects accuracy while offers, availability, and public conversation change.

    Before the promotion, build a fixed prompt set from customer decisions rather than from your target keywords alone. Include category discovery, a constrained use case, a direct product comparison, a compatibility question, a value question, and a deal-verification question for every priority category. Keep the wording stable enough that later results are comparable.

    Run those prompts separately on the AI platforms your customers are likely to use. Do not collapse their responses into one score. In the observed Black Friday sample, Gemini responses averaged 606 words, OpenAI responses averaged 401, and Perplexity responses averaged 288. Those are sample characteristics, not permanent product specifications, but they show why a citation or mention can play a different role on each platform.

    Use one tracking row for each prompt and platform. Record:

    • The exact prompt, model or product name, and time of the check.
    • Whether the brand and correct product appear.
    • How the product is framed: recommended, compared, merely listed, or excluded.
    • Which URLs support the answer.
    • Whether the price, specifications, seller, availability, and promotion terms are accurate.
    • Which competitor or third-party page supplied information you did not make easy to find.
    • The correction required: page content, structured data, marketplace data, comparison coverage, video, or support documentation.

    At sale launch, rerun the deal and verification prompts. Repeat the check after any material price, inventory, seller, or terms change. If an answer is wrong, correct the authoritative page and connected listings first. A prompt variation may produce a different answer, but it does not repair the underlying information conflict.

    Judge progress by failure mode rather than by a single visibility number. A missing brand is a discovery problem. The wrong model is an identity problem. An incorrect price is a freshness problem. A competitor winning every comparison may indicate weak decision content or stronger independent corroboration. Each diagnosis leads to different work.

    Key takeaways

    • Plan separately for pre-sale research and live deal verification because the source mix changes when Black Friday begins.
    • Give every priority offer a clear identity, complete decision facts, current commercial terms, and evidence a shopper can verify.
    • Build comparisons around use cases and tradeoffs, not unsupported claims that a product is “best.”
    • Coordinate product information across your site, retailers, marketplaces, video, review coverage, and community support.
    • Test the same customer decisions across AI platforms and classify failures before choosing a fix.

    Before your next promotion, choose one prompt for each major customer decision in your highest-value category. Run the set when product pages are frozen, again when the sale launches, and whenever a material offer fact changes. The gaps you find will give your content, merchandising, SEO, marketplace, and communications teams a concrete Black Friday worklist – before shoppers ask AI to make the choice for them.

    References

  • Google Discovery and Local Visibility: A Practical Plan

    Google Discovery and Local Visibility: A Practical Plan

    If your business appears when someone searches its name but disappears when they search for a service nearby, you don’t have a single ranking problem. You have a discovery mismatch. Google can surface a business through the Local Pack, cite a page in AI Mode, group it under a Web Guide topic, or favor a publisher a searcher has deliberately chosen.

    Your job is to determine which discovery path matters for each query, then give that system the information and evidence it needs. That calls for more precision than completing the same SEO checklist for every location.

    Map the Google surface before you change the page

    A strategist sorts query tokens across a blank city map into routes leading to a map pin, an AI-like orb, page clusters, and editorial sheets.

    A conventional rank tracker can tell you where a URL appears, but it may not explain what now occupies the useful part of the results page. Start by identifying the surface that answers the query:

    • Local Pack: The searcher is choosing a nearby business. Location, category relevance, operating details, reputation and local behavior matter more than a generic national content campaign.
    • AI Mode: Google synthesizes an answer and may attach links to particular claims or branches of the question. Google has been adding more inline links and contextual introductions that explain why a linked page may be useful.
    • Web Guide: Google organizes links into topic groups rather than presenting one undifferentiated list. Its custom version of Gemini interprets the query and page content, while query fan-out runs multiple related searches. The expansion into the all tab still required a Search Labs opt-in, so you shouldn’t assume every searcher sees the same layout.
    • Preferred Sources: This applies to publishers appearing in Top Stories. A searcher can choose publications they want Google to show more often when those publications have relevant, recent coverage.

    Create a query map with a row for each commercially important search. Record the likely intent, the dominant Google surface, the location implied by the query, the page or profile you expect to qualify, and what actually appears. A query such as “accountant near me” needs a different asset from “how to choose an accountant for a growing company,” even when both ultimately support the same business.

    This diagnosis prevents a common waste of effort: rewriting an informational page when the Local Pack owns the decision, or editing a Google Business Profile when Google is looking for a page that answers a detailed question.

    Build signal fit into every Google Business Profile

    Profile completeness is a baseline, not a complete local strategy. Google is trying to identify which nearby result best fits what people expect from that kind of business. Those expectations change by category and can vary by region.

    A Yext analysis of 8.7 million Google Business Profiles found that review activity, profile information and visual content did not carry the same apparent importance across every industry. Because this was a vendor analysis of observed profiles, it should guide prioritization rather than be treated as proof of a universal ranking formula.

    Business typeSignals to inspect firstPractical response
    HospitalityHours, descriptions and complete practical informationMake arrival, availability and operating details easy to verify before investing in more image volume.
    HealthcareReviews, accurate hours and clear location detailsRemove uncertainty about access and reliability. Check every location independently.
    RetailReview volume, sentiment and listing upkeepTreat reputation and profile maintenance as operating signals, not occasional marketing tasks.
    Food and diningRatings and continuing engagement with feedbackMonitor new reviews and respond sincerely; basic completeness alone may not distinguish a competitive listing.
    Financial servicesGenuine reviews and real-world reputationPrioritize trust evidence over accumulating polished photos that add little decision value.

    Use three layers when you audit a location. First, verify the stable identity: business name, address, phone number, primary category, hours and destination URL. Second, inspect the signals customers use to choose within your category. Third, compare the location with nearby competitors serving the same intent. A national average can hide the gap that determines whether one branch appears locally.

    Don’t copy a successful location’s profile changes across the entire estate in one move. A restaurant in one region may benefit from a feature that produces no meaningful difference elsewhere. Test the change on comparable locations, keep the untouched profiles as a reference where practical, and judge the result using both visibility and customer actions.

    Reviews deserve an operating process of their own. Ask real customers for honest feedback without scripting the sentiment. Route new reviews to the person who can answer them accurately. A quick, specific response shows that the location is active; a batch of generic replies creates activity without adding much trust.

    Publish pages that fit a branch of the search journey

    AI-organized search makes broad relevance less useful than precise usefulness. Web Guide can fan a query out into related searches and group the resulting pages by facet. AI Mode can then present a link next to the part of an answer it supports. Neither feature means you should generate a page for every wording variation. It means each worthwhile page should have a clear job.

    1. Break the query into genuine decision branches. Someone looking for an emergency dentist may need to know whether the practice is open, which urgent problems it handles, where it is and how to contact it. Those are user needs, not keyword variants.
    2. Assign each branch to the right asset. Put operating facts on the location page and profile. Use a focused service page for a service that needs explanation. Use an educational page when the person is still deciding what kind of help they need.
    3. State the page’s value early. Identify the service, audience, location and question being answered before drifting into background copy. A visitor following an inline AI link should be able to confirm immediately that the page matches the context around that link.
    4. Supply verifiable detail. Include the facts a customer would need to act, such as availability, eligibility, process, location or limitations, when they genuinely apply. Replace generic claims with information the business can keep current.
    5. Connect the page to the location. Keep business identity, service descriptions and operating details consistent with the corresponding Google Business Profile. Link users to the appropriate location rather than forcing them through a generic homepage.

    Applicable LocalBusiness structured data can describe facts already visible on the page and reduce ambiguity about the entity. Use it as a consistency layer. It cannot compensate for stale hours, a mismatched category, weak reputation or a page that never answers the query.

    Avoid mass-produced city pages that change only the place name. They don’t give Google a distinct facet to retrieve, and they give the reader no local reason to trust the page. Create a separate location page when you can maintain distinct operating facts, directions, services or other genuinely local information.

    Use Preferred Sources only when you are really a publisher

    Preferred Sources can be valuable for a local news organization, trade publication or other site that regularly qualifies for Top Stories. It is not a general local ranking switch for every service business.

    Google expanded the feature globally for English-language users after launches in the United States and India. Searchers use the star beside Top Stories to choose publications they prefer, and Google can show more of those publications’ recent work when it is relevant. People have selected nearly 90,000 sources, ranging from local blogs to global outlets.

    Google also reported that people clicked a chosen publication about twice as often on average. That does not mean asking readers to select you will double traffic. People who deliberately choose a publication are already more likely to value it, and relevance and freshness still determine whether suitable coverage exists.

    If the feature fits your publication, add a brief instruction near the places where loyal readers already engage, such as a subscriber message or membership page. Explain what the star does and let the reader decide. Then maintain a dependable publishing rhythm around the local topics for which you want to be found. Preference cannot make an unrelated story relevant.

    If you run a clinic, restaurant, retailer or professional practice without a genuine news operation, leave this tactic alone. Put the effort into the Local Pack, location pages and useful answers connected to your services. A feature being available does not make it appropriate to your discovery problem.

    Measure each location and discovery surface separately

    An analyst compares six separate abstract measurement panels positioned above different miniature neighborhoods and storefronts.

    A single visibility score conceals too much. Local results depend on the searcher’s location. AI and experimental layouts can differ by account or feature access. Preferred Sources are explicitly personalized. Keep the measurements separate enough to tell which change produced which result.

    • For the Local Pack: Check a stable set of query-and-location combinations. Record whether the correct branch appears, which competitors surround it, and whether profile actions such as calls, website visits or direction requests change when those measurements are available.
    • For standard organic and Web Guide discovery: Group Search Console queries by intent rather than tracking isolated wording. Watch the landing pages receiving impressions and clicks, and annotate meaningful page revisions.
    • For AI surfaces: Record the exact query, observed linked page and context in which the link appeared. Keep the account state and test conditions consistent enough to make repeated observations useful. Treat a single appearance as a lead to investigate, not proof of stable inclusion.
    • For Preferred Sources: Monitor relevant Top Stories appearances and returning search traffic. Separate that audience from first-time discovery so loyalty does not disguise weak reach.

    Change one class of signal at a time where practical. If you revise categories, hours, photos, landing pages and review outreach together, even a positive result won’t tell you what to repeat. Compare similar locations, preserve a baseline and look for movement in both discovery and the user action tied to the query.

    Key takeaways

    • Identify whether the query is governed by a local choice, an AI answer, a grouped web result or a publisher preference before editing anything.
    • Complete every Google Business Profile, then prioritize the reputation, access, information or engagement signals that matter in that location’s category.
    • Build pages around real branches of intent, not slight keyword or city-name variations.
    • Use structured data to reinforce visible, accurate facts; don’t treat markup as a substitute for content or profile maintenance.
    • Reserve Preferred Sources promotion for sites that genuinely publish timely material and can appear in Top Stories.
    • Measure locations and discovery surfaces separately so you can connect a change with an outcome.

    Start with one revenue-relevant query and one location. Identify the surface that controls the decision, find the largest mismatch between user intent and your profile or page, and correct that mismatch. Once you can see what changed in visibility and customer action, apply the lesson to the next comparable location.

    References

  • Google Discover and AI Mode: An Emerging-Query Workflow

    Google Discover and AI Mode: An Emerging-Query Workflow

    If your Google strategy begins when someone types a query, you may be entering the journey too late. A person can encounter a story in Discover, open the page, and then continue exploring it through AI rather than returning to a conventional results page.

    That changes the content problem in two directions. You need to recognize demand before it becomes an obvious keyword opportunity, and the page you publish must remain useful when a reader asks an AI system to summarize it, answer a follow-up, or go deeper.

    Optimize the whole discovery journey, not one ranking

    The emerging Google journey has three distinct moments, and each asks something different of your content:

    1. Discovery: A topic, headline, image, or entity earns attention in a personalized feed. The reader may not have expressed a conventional search query.
    2. Evaluation: The reader opens the page and decides whether it answers the immediate question clearly enough to trust and continue.
    3. Exploration: The reader uses AI to condense the page, ask another question, or investigate the subject in more depth.

    The third moment is no longer theoretical. In the observed Google app for Android flow, a menu available after opening a URL offered Summarize with AI Mode, Ask a follow-up with AI Mode, and Dive deeper with AI Mode. The behavior was not confined to stories selected from Discover; AI Mode controls were also available for other pages opened through the app.

    This means a click is not necessarily the end of the search experience. Your page can become material the reader interrogates. A catchy headline may win the first transition, but it cannot compensate for vague entities, buried conclusions, unsupported assertions, or sections that repeat the same point.

    Plan the journey backward. Start with the useful action or decision the reader should reach. Then identify the questions that lead there:

    • What happened, or what is changing?
    • Why does it matter to this reader?
    • What is still uncertain?
    • What should the reader compare, check, or do next?
    • What related question becomes important after the first answer?

    Those questions should determine the article structure before you write the headline. They also give you a practical standard for deciding whether a trend deserves coverage at all.

    Find rising demand before it looks like a mature keyword

    A strategist observes scattered digital signals converging into a bright rising pattern on a translucent display.

    Traditional keyword research is strongest when a query already has enough repeated behavior to measure. Emerging demand often appears first as an event, product, person, phrase, policy, cultural reference, or unfamiliar entity. By the time every tool reports stable volume, the easiest editorial opening may have passed.

    Google’s 2025 Year in Search was organized around rapidly rising searches rather than a simple ranking of the largest query totals. The U.S. list crossed technology, policy, entertainment, sport, and public affairs with queries such as DeepSeek, iPhone 17, tariffs, KPop Demon Hunters, and the FIFA Club World Cup. The global list included Gemini, DeepSeek, major cricket matchups, the Club World Cup, and iPhone 17.

    The more useful lesson is not which names appeared. It is how many different forms new demand can take. Additional U.S. trends included AI action figure, a long viral-dish phrase, a Boston travel-itinerary query, and a question about why children say 67. A useful trend radar therefore cannot be limited to short commercial keywords. It has to notice new entities, new behaviors, new language, and old needs expressed in unfamiliar ways.

    Keep a signal log that captures what keyword volume misses

    Create one shared record for emerging topics. For each signal, capture:

    • The exact phrase or entity: Preserve the wording people are using instead of immediately translating it into an established keyword.
    • The trigger: Record the launch, event, announcement, controversy, release, match, meme, or behavior that created the question.
    • The audience connection: State why your existing reader would care. A topic can be popular without belonging on your site.
    • The first practical question: Identify what the reader needs to understand, decide, buy, avoid, or explain.
    • The likely follow-ups: Write down the next questions before search-volume data exists for them.
    • The evidence available: Note what can be verified now and what remains unknown. If you cannot support the central answer, speed will not improve the page.
    • The expiry condition: Decide what event would make the page outdated, incomplete, or misleading.

    This log prevents a common mistake: treating a growing entity as if it were already a settled keyword cluster. Early in a trend, people may search for the name alone because they do not yet know the vocabulary for a more precise question. Your job is to infer the legitimate questions cautiously, then revise the page as the language becomes clearer.

    Use a publication gate before chasing the spike

    Run every candidate through five questions:

    1. Is the reader ours? Define the person who needs the answer without relying on a phrase such as everyone is talking about it.
    2. Is there a real job to do? Name the decision, explanation, comparison, or action the page will support.
    3. Can we add clarity? If the page will merely restate the event, it has little reason to exist after the first wave of coverage.
    4. Can we maintain it? A fast-changing page needs an owner and an explicit update trigger.
    5. Does it connect to durable expertise? The best emerging topic opens a path into subjects your site can continue to explain after the spike fades.

    If you cannot answer the first three questions, skip the topic. If you cannot support the final two, narrow the scope until you can. Publishing a thin page for every rising name creates an archive of disconnected updates, not topical authority.

    Once a topic passes the gate, prepare a brief containing the provisional query cluster, the one-sentence answer, the follow-up question map, the entities that require disambiguation, the supporting evidence, the intended URL, and the conditions that will trigger an update. That is enough structure to move quickly without turning speed into guesswork.

    Build pages that survive summary, follow-up, and depth

    Cutaway illustration of readers exploring an overview, branching answer areas, and deeper research layers within a structured web page.

    The three AI Mode commands provide a useful editorial test. Apply all three before publication, even if a particular reader never opens the AI controls.

    The summary test

    Could a reader identify the subject, central answer, significance, and main limitation from the opening and section headings? If not, the page is making both readers and machines reconstruct a conclusion that you should have stated directly.

    • Name the primary entity in the title, introduction, and relevant heading instead of relying on ambiguous pronouns.
    • Give the direct answer before the chronology or background.
    • Separate confirmed facts from interpretation and unresolved questions.
    • Use one section for each distinct idea. Do not scatter the same conclusion across several headings.
    • Remove paragraphs that merely announce what the next paragraph will explain.

    A good summary test is not an instruction to make every article short. It is an instruction to make the hierarchy unmistakable. A detailed page can still have a clear central answer.

    The follow-up test

    After reading the answer, what would a sensible person ask next? Turn the strongest second-order questions into substantive sections. Depending on the topic, these may concern eligibility, cost, timing, alternatives, consequences, definitions, examples, or what changed.

    Do not manufacture a question section from keyword variants that all have the same answer. Each follow-up should move the reader to a new understanding or decision. If two questions collapse into the same paragraph, combine them.

    Internal links should continue the same logic. Link to a durable explainer when the reader needs background, a comparison when the next task is choosing, and a process page when the next task is acting. Generic related-reading blocks leave that choice to chance.

    The depth test

    What can the reader learn from your page that would be lost in a one-paragraph recap? Depth comes from useful distinctions, not word count. Add the material that changes interpretation: definitions, boundaries, named entities, evidence, exceptions, trade-offs, and the point at which the advice no longer applies.

    For a fast-moving topic, show what is known at publication and what still needs confirmation. Update the existing URL when the central intent remains the same. Create a separate page only when a genuinely different intent appears. That keeps one answer coherent while preventing a single URL from becoming an undifferentiated timeline.

    Make the structured data agree with the visible page

    JSON-LD should describe the page you actually published. For editorial content, use Article or a truthful, more specific subtype. Keep the structured headline, author, publication date, modification date, canonical page identity, and publisher consistent with what the reader can see.

    • Use stable identifiers for people and organizations so the same entity is not represented as several unrelated things across the site.
    • Change the modification date when the content receives a substantive update, not when an automated process touches the template.
    • Represent the page’s primary subject consistently in the copy, metadata, internal links, and structured data.
    • Add a schema type only when the visible content meets its meaning. Anticipating follow-up questions does not require disguising an ordinary article as a different content format.
    • Validate the markup and inspect the rendered page. Syntactically valid JSON-LD can still contradict the content it describes.

    Structured data can make relationships more explicit, but it cannot turn a vague page into a reliable answer or guarantee distribution in Discover, Search, or an AI response. Treat it as a consistency layer, not a substitute for editorial substance.

    Measure whether early attention becomes durable value

    A trend page can produce a traffic spike and still fail strategically. Measure the complete path: how early you recognized the signal, whether the page satisfied the immediate need, whether readers continued into relevant content, and whether the topic strengthened a durable area of expertise.

    QuestionSignal to recordDecision it supports
    Did we recognize the topic early?First-observed date, assignment date, and publication dateWhether the discovery workflow is fast enough
    Did the page match the emerging need?Queries where available, landing-page behavior, and movement to the next relevant pageWhether the angle and follow-up map were accurate
    Did the topic matter to our audience?Qualified subscriptions, leads, purchases, saves, or other site-specific outcomesWhether attention was useful rather than merely large
    Did the opportunity become durable?New recurring questions, internal-link use, and continued interest in the surrounding topicWhether to build an evergreen supporting resource
    Does the page need maintenance?Material changes to the entity, event, availability, policy, or reader intentWhether to update, narrow, redirect, or stop promoting the URL

    Keep these observations attached to the topic record. Keyword volume seen later cannot tell you what your team knew when it made the editorial decision. The first-observed date and original question map let you review whether you spotted a real signal or merely followed an already visible spike.

    Judge trend coverage against its intended role. An emerging explainer should not be evaluated like a mature evergreen guide, and an audience-building story should not be declared successful solely because it attracted raw visits. Define the meaningful next action before publication, then measure that action consistently.

    When interest declines, preserve what remains useful. If the original question still exists, update the page and connect it to an evergreen resource. If the event has ended but the surrounding need persists, create a separate durable page and link the two in both directions. Do not keep producing minor update pages that compete to answer the same intent.

    Key takeaways

    • Google discovery can begin before a conventional query and continue through AI after the click, so optimize the complete question journey.
    • Use a signal log for new entities, phrases, triggers, audience questions, evidence, and expiry conditions; keyword volume alone will often arrive too late.
    • Publish a trend only when it serves your established audience, answers a real question, adds clarity, can be maintained, and connects to durable expertise.
    • Test every page for summary, follow-up, and depth: state the answer clearly, anticipate the next useful questions, and add distinctions that survive compression.
    • Keep visible content, metadata, internal links, and JSON-LD consistent. Schema clarifies meaning but does not replace trustworthy content.
    • Measure lead time, useful onward behavior, audience outcomes, and long-term topic value instead of treating a temporary traffic spike as the goal.

    Start with one rising topic already sitting in your editorial backlog. Write its trigger, reader, first question, next three questions, available evidence, and update condition. If those lines are clear, you have the basis for a useful page. If they are not, waiting or declining the topic is a better decision than publishing a fast page with no durable answer.

    References

  • Google AI Travel Planning: An Action Plan for Travel Brands

    Google AI Travel Planning: An Action Plan for Travel Brands

    If you market a hotel, airline, restaurant, destination, or travel platform, the uncomfortable question is not whether travelers will use AI to brainstorm trips. It is whether your offer will remain visible when the same interface can compare the options and move the traveler toward a reservation.

    Google is connecting discovery, itinerary planning, deal-finding, and booking inside AI Mode. You do not need to chase every new feature. You need to separate live capabilities from planned ones, make your inventory easy to compare, and test whether a traveler can move from a conversational request to a correct booking without hitting conflicting information.

    Separate the live travel tools from planned booking features

    Google’s travel rollout is not one feature with one availability date. Some capabilities are already rolling out in particular markets and devices. Others describe the direction of flight and hotel booking but should not yet be treated as universally available. That distinction should determine what your team fixes now and what it prepares for next.

    CapabilityDocumented availabilityWhat your business should do
    Dinner reservations in AI ModeAgentic dinner reservations are rolling out in the U.S. through services including OpenTable and Resy, without being confined to a Google Labs opt-in.Check that your restaurant name, location, availability, party rules, and booking destination agree across your website, Google presence, and reservation provider.
    Canvas for trip planningCanvas is available for travel planning on desktop in the U.S.Publish information that remains useful within an itinerary, including location context, operating constraints, policies, and what must be reserved in advance.
    Flight DealsFlight Deals is expanding to more than 200 countries and multiple languages, and it accepts travel requests written in conversational terms.Make route, schedule, price, and eligibility information unambiguous. Review localized content as operational data, not merely translated marketing copy.
    Agentic flight and hotel bookingGoogle plans to help travelers compare flights and hotels by schedule, price, and reviews before completing a booking with a selected partner. Booking.com, Expedia, and Marriott are among the companies working with Google on the experience.Prepare your content, inventory, and distribution handoffs, but do not tell customers that universal AI Mode flight or hotel booking is already available.

    This prevents two expensive mistakes. The first is postponing all work because flight and hotel transactions are still developing, even though restaurant reservations and conversational deal discovery already create practical work. The second is promising a booking experience that a traveler cannot access in their market, device, or category.

    Label every internal project as live optimization, rollout monitoring, or future readiness. A U.S. restaurant connected to a supported reservation service belongs in the first group. A hotel preparing its distribution data for agentic booking belongs in the third. Flight offers shown across languages need both optimization and monitoring because geographic expansion does not guarantee that every offer is eligible or represented correctly.

    Optimize for a travel brief, not just a destination keyword

    A traveler's preferences for family, timing, budget, dining, and transportation flow into three consistently arranged trip options.

    A conventional travel query often looks like a destination plus a category. A conversational request can contain the whole decision: origin, timing, budget, preferred pace, who is traveling, acceptable connections, desired amenities, and conditions the traveler wants to avoid. Google is explicitly letting people describe the flight deal they want as they would describe it to another person.

    That changes the useful unit of content. A page that repeats a broad phrase such as “city hotel” may match a category, but it does not resolve whether the property fits a particular trip. Your page should help a planning system answer selection questions without inventing the missing context.

    1. State the fit. Say which traveler, occasion, route, or itinerary the offer serves. Avoid claiming that every product is ideal for everyone.
    2. Expose the constraints. Put operating days, stay requirements, connection rules, age or party restrictions, accessibility details, and booking conditions where they are relevant and visible.
    3. Explain the tradeoff. If an option is cheaper because it is less flexible, farther away, indirect, or limited to particular inventory, make that distinction explicit.
    4. Define the price context. Identify what the displayed amount covers, what may change it, what is excluded, and where the traveler must confirm the current total.
    5. Give the next action. Link the exact offer to the matching availability or booking step instead of sending every traveler to a generic homepage.

    Use that sequence as a content brief. Start with the travel need, answer the constraints, present the tradeoffs, supply evidence, and expose the booking path. It works better than manufacturing a separate page for every conversational variation because the underlying offer stays canonical while its decision facts become clearer.

    Do the same with destination content. A useful neighborhood page should explain what the location makes convenient, what remains inconvenient, which transport assumptions matter, and how the property or experience fits into a realistic itinerary. Generic inspiration can attract attention, but comparison-ready facts help a traveler make a choice.

    Make every offer comparable, verifiable, and machine-readable

    Google’s planned flight and hotel experience centers on schedules, prices, and reviews. Those are not decorative content fields. They are decision inputs. If your website, feed, booking engine, and distribution partners describe them differently, an AI interface has no reliable version to carry into the traveler’s plan.

    Audit each bookable offer as a record with the following components:

    • A stable identity: the exact property, route, room, fare, table, package, or experience being offered.
    • A precise location or operating area: not just a destination label, but the information needed to place the offer in an itinerary.
    • Availability context: the dates, times, operating pattern, inventory status, or conditions that control whether the offer can actually be selected.
    • Price context: currency, inclusions, exclusions, mandatory charges, variability, and the point at which the traveler receives the final amount.
    • Policies: cancellation, changes, refunds, deposits, check-in or arrival rules, and any restriction that could reverse the decision.
    • Fit attributes: the amenities, service conditions, accessibility information, traveler requirements, and limitations that distinguish the option.
    • Review evidence: ratings or review summaries that are genuine, attributable, current enough to use, and consistent with what the visitor can see.
    • A specific booking destination: the page or provider that can act on the offer without making the traveler reconstruct the search.

    Then compare the record across every system that publishes it. Begin with the visible page, continue through your structured data and feeds, and finish in the booking flow. A price that is correct in a feed but stale on the page is still a problem. So is an amenity marked up in JSON-LD that the visible content does not support.

    Use structured data as a consistency layer. Choose the narrowest valid type and properties supported by the page, connect records with stable identifiers, and make the marked-up values agree with the content a visitor can read. Do not use markup to assert unavailable inventory, hidden reviews, or an offer that the linked booking page cannot reproduce. Schema can reduce ambiguity; it cannot compensate for contradictory business data or guarantee inclusion in an AI response.

    Keep critical decision facts in readable page text rather than only inside promotional images or an interaction that reveals nothing until checkout. You should not require a person or a machine to infer whether breakfast is included, whether the rate can be canceled, or whether a venue accepts the requested party. If a fact materially changes the booking decision, publish it before the handoff.

    Test the booking handoff as carefully as the search result

    A traveler follows a connected path from trip planning through room selection and payment to a hotel reservation, beside a second path that ends at a disconnected doorway.

    Agentic booking does not remove the rest of the travel stack. Google is working with reservation and travel partners, and its planned flow still ends with a chosen booking partner. Your visibility can therefore depend on information and transaction paths that your own marketing site does not fully control.

    Run a complete journey for each priority offer:

    1. Start with a realistic conversational request that includes the constraints your customers actually use.
    2. Check whether your business or offer appears, whether it is described accurately, and which page or provider is attached to it.
    3. Select the offer and compare the displayed schedule, price, availability, review information, and policy with your authoritative records.
    4. Continue to the reservation provider. Confirm that dates, party details, route, room, fare, or package context survives the handoff.
    5. Proceed far enough to see the payable amount and essential terms. Stop before creating a charge unless the test booking is authorized and can be safely reversed.
    6. Test an unavailable option and a changed option. The experience should return a clear alternative or current status rather than a dead end or misleading confirmation.
    7. Verify the confirmation path. The traveler should know who holds the reservation, where support comes from, and which rules govern changes or cancellation.

    For a U.S. restaurant, include the reservation provider you actually use when checking the live dinner-booking path. For a hotel or airline, start with existing distribution relationships and monitor Google’s flight and hotel rollout. The fact that Booking.com, Expedia, and Marriott are named collaborators is not evidence that every supplier, property, or rate connected to them will automatically qualify.

    Do not move inventory to a new channel solely because its company appears in a product rollout. A change in distribution can alter commissions, contract terms, customer ownership, support obligations, and margin. First ask your existing provider what data it sends, which identifiers it preserves, how corrections propagate, and whether your inventory is eligible for the relevant Google experience. Review the commercial terms before changing the channel mix.

    Assign ownership for mismatches. Marketing can maintain descriptive content, but pricing, inventory, distribution, and reservation failures often sit elsewhere. Give each field an authoritative system and an escalation path. Otherwise, the first person to discover the inconsistency will be the traveler attempting to book.

    Measure the full prompt-to-reservation journey

    Organic clicks alone cannot tell you whether Google AI travel planning is helping or displacing your business. If more comparison happens inside the planning interface, a visitor may arrive later in the decision process, transact through a partner, or remember the brand and return directly. None of those possibilities makes a click unimportant; they make it incomplete as a standalone measure.

    Build a repeatable prompt set from real customer questions and group the observations by market, language, device, and travel category. Record the prompt, test conditions, options shown, facts attributed to your offer, linked destination, booking provider, and result of the handoff. Keep the conditions with the result so that a desktop Canvas observation in the U.S. is not silently treated as evidence of identical availability everywhere.

    Use operational measures that point to a fix:

    • Discovery rate: the share of applicable test prompts in which the business or eligible offer appears.
    • Fact accuracy rate: the share of checked decision fields that agree with the authoritative record.
    • Price parity rate: the share of tested offers whose displayed price context matches the booking destination.
    • Handoff success rate: the share of selections that reach the correct bookable inventory with the important context preserved.
    • Confirmation rate: the share of authorized test or customer journeys that produce a valid reservation rather than an error, unavailable result, or abandoned mismatch.
    • Correction time: how long it takes an updated schedule, policy, price, or availability status to become consistent across the systems you control.

    Do not collapse all of this into one AI visibility score. An appearance with the wrong cancellation policy is not a success. Neither is an accurate citation that sends the traveler to an unrelated booking page. Diagnose the failing stage: discovery, comparison, handoff, or transaction. Then fix the system responsible for that stage.

    Key takeaways

    • Treat U.S. dinner reservations, desktop Canvas, international Flight Deals, and planned flight or hotel booking as different rollouts with different actions.
    • Write for the complete travel brief by exposing fit, constraints, tradeoffs, price context, policies, and the exact next step.
    • Keep visible content, structured data, feeds, provider records, and checkout information consistent.
    • Test whether offer context survives the move from an AI recommendation to the reservation provider.
    • Measure accurate discovery and successful booking separately; visibility with incorrect facts is a failure, not a partial win.

    Start with the journey tied to your most important bookable offer. Reproduce it from a realistic prompt to the final reservation step, find the first fact or handoff that fails, and correct its authoritative record. Repeat that process across the markets and languages you actually serve. That work will remain useful as Google’s travel features expand because it improves the same thing every planning interface needs: an offer that can be understood, compared, and booked without surprises.

    References