Tag: AI Ads

  • Google AI Mode Visibility Is Splitting Into Three Channels

    Google AI Mode Visibility Is Splitting Into Three Channels

    Commercial visibility in Google AI Mode is developing along several paths at once. Advertisers can buy placements, publishers and brands can earn citations, and businesses can appear through Google-hosted profiles or product panels.

    Two separate reports show why these surfaces should not be treated as one ranking system. Paid coverage is expanding across commercially valuable queries, while Google is also becoming a more prominent source inside its own AI-generated answers. The practical payoff is a clearer way to assign budgets, ownership and measurement.

    Key takeaways

    • CrushPress.AI’s summary of an SE Ranking study reported text ads on 29.45% of the commercial AI Mode queries examined.
    • Ad incidence rose with keyword cost, but the study did not find the same relationship with search volume or keyword difficulty.
    • Paid placement provided little overlap with cited or traditionally ranked URLs, indicating that advertising, citations and organic search require separate strategies.
    • A second CrushPress.AI report said google.com became AI Mode’s second-most-cited domain in Profound’s tracking, driven mainly by Google Business Profiles and Product Knowledge Panels.
    • Commercial visibility therefore depends on both website performance and the quality of information presented on Google-controlled surfaces.

    Commercial visibility now has three distinct layers

    The reports describe complementary changes rather than competing explanations. The SE Ranking analysis covered paid text placements, whereas Profound tracked the domains AI Mode cited. Together, the findings suggest that appearing near an AI-generated response can happen through three substantially different mechanisms: an ad auction, selection as a cited source, or a Google-hosted information surface.

    The distinction matters because each layer answers a different business need. Advertising can provide purchased exposure on a relevant query. A citation can establish a website as supporting material for the generated answer. A Google Business Profile or Product Knowledge Panel can present decision-making information without requiring the user to reach the company’s website first.

    Profound’s tracking, as summarized by CrushPress.AI, found that citations to google.com increased 8.4-fold in roughly two months, making it the second-most-cited domain in the data. The report attributed almost all of that increase to Google Business Profiles and Product Knowledge Panels. Its analysis ran from April 15 through June 30 and covered more than 32 million google.com/searchviewer instances.

    The reported shift was especially relevant to local searches in hospitality and travel, home services, restaurants and dining, real estate, and healthcare. For product-oriented queries, panels appeared more often around comparisons, compatibility and specifications. These are situations in which structured facts can influence consideration before a conventional website visit.

    Paid reach follows commercial value, not general popularity

    CrushPress.AI’s account of the SE Ranking study reported ads across 14,733 queries, or 29.45% of the commercial searches analyzed. The study examined 50,032 U.S. keywords across 20 niches, using results collected on June 30. It focused on queries eligible for text ads and excluded product carousels.

    Cost per click was the clearest reported indicator of whether an ad appeared. Ad incidence was 24.33% among keywords with CPCs below $2, 32.45% in the $2-to-$10 group and 53.56% for keywords at $10 or more. Search volume and keyword difficulty did not show the same relationship in the study. This pattern supports a cautious interpretation: AI Mode ad deployment appears more closely aligned with the economic value of a query than with its popularity or organic competitiveness alone.

    When an ad block appeared, it usually included more than one advertiser. The study found two ads in 71.1% of ad-triggering responses and one ad in the remaining 28.9%. Category results varied sharply, from a reported 72.38% ad rate for pets to 2.64% for healthcare. Those differences warn against using the overall 29.45% rate as a forecast for every market.

    The study also noted that AI Mode results can vary between sessions. Its percentages should therefore be read as observations from the stated collection date and methodology, not permanent delivery guarantees. The source further cautioned that the pattern could change as Google introduces more AI-specific advertising formats.

    Buying an ad does not secure the other layers
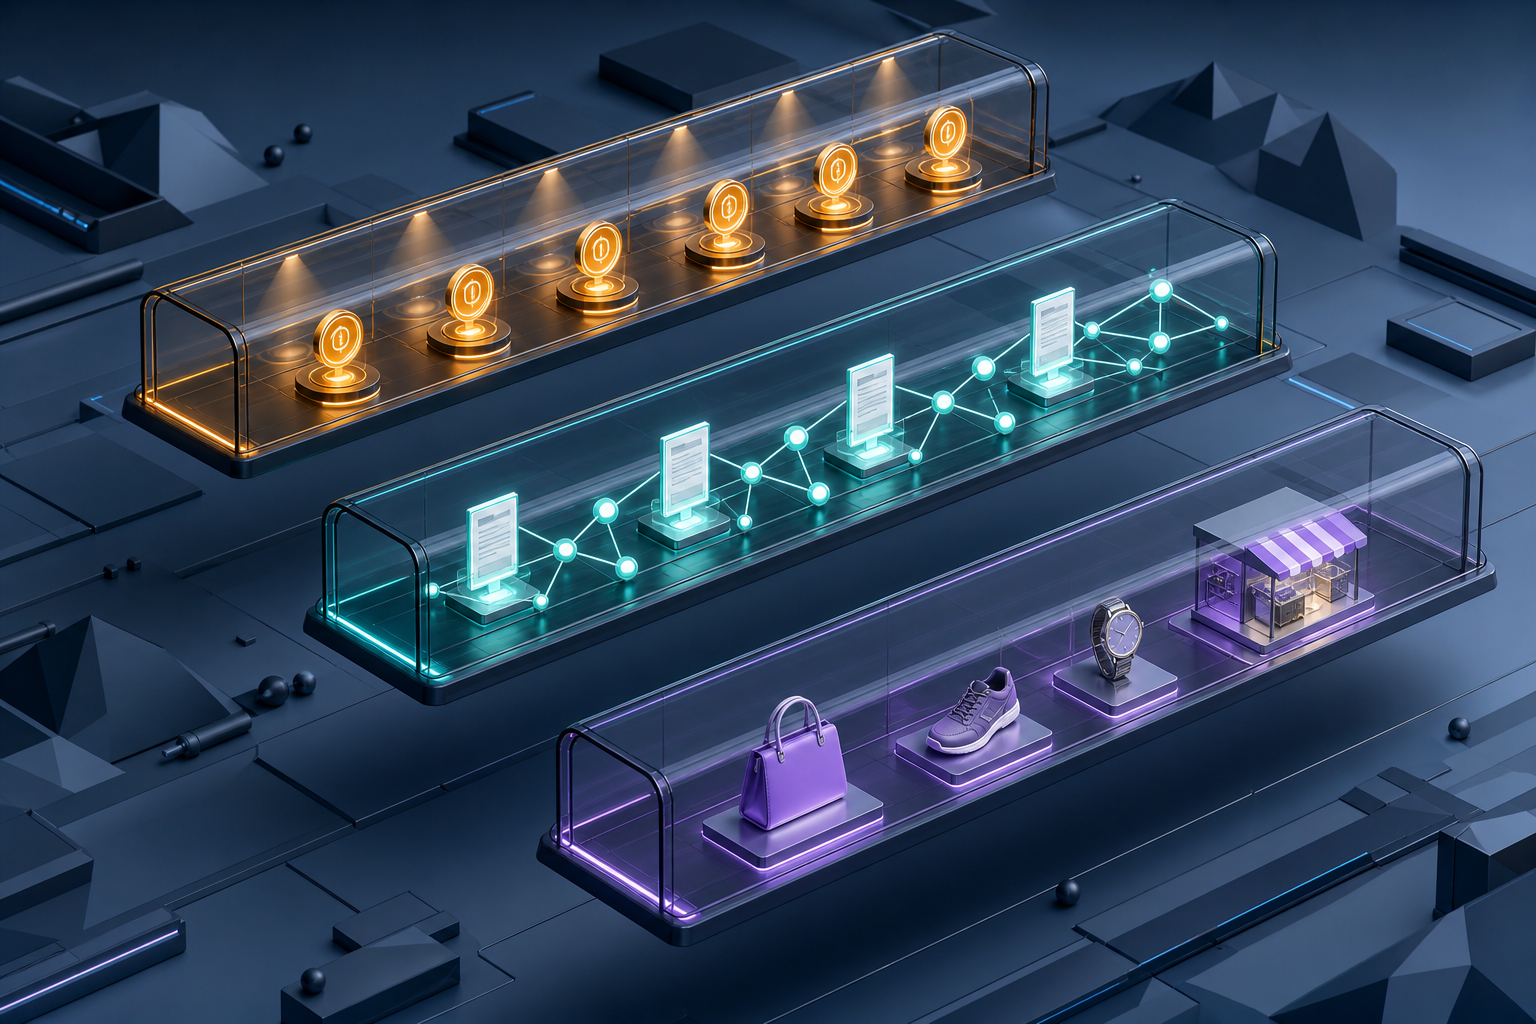
    Three separate glass corridors contain bid tokens, connected source pages, and a digital storefront with products.

    The most consequential finding for planning was the limited overlap between advertisers and unpaid visibility. According to the SE Ranking analysis summarized by CrushPress.AI, only 11.53% of advertiser domains appeared among cited sources for the keywords on which they advertised. At the individual URL level, overlap fell to 1.95%.

    Traditional organic results showed a similar separation. Just 2.32% of advertised URLs also ranked organically for the corresponding queries, while domain-level overlap reached 15.35%. In other words, approximately 85% of advertisers did not appear in organic results for the same keywords, according to the source.

    Visibility comparisonReported overlapPlanning implication
    Advertiser domain and cited domain11.53%Paid reach is not a substitute for earning citations.
    Advertised URL and cited URL1.95%The landing page is rarely the exact source selected for the answer.
    Advertiser domain and organic domain15.35%Advertising and domain-level organic visibility remain largely separate.
    Advertised URL and organic URL2.32%Buying exposure does not ensure that the same page ranks.

    The researchers reportedly compared advertisers with similar non-advertising domains while accounting for domain strength, backlinks, referring domains and organic visibility. Even so, the findings are observational. They do not establish that advertising causes or prevents citation and ranking outcomes. They do show that purchasing an AI Mode placement should not be assumed to improve either one.

    A practical operating model for AI Mode visibility
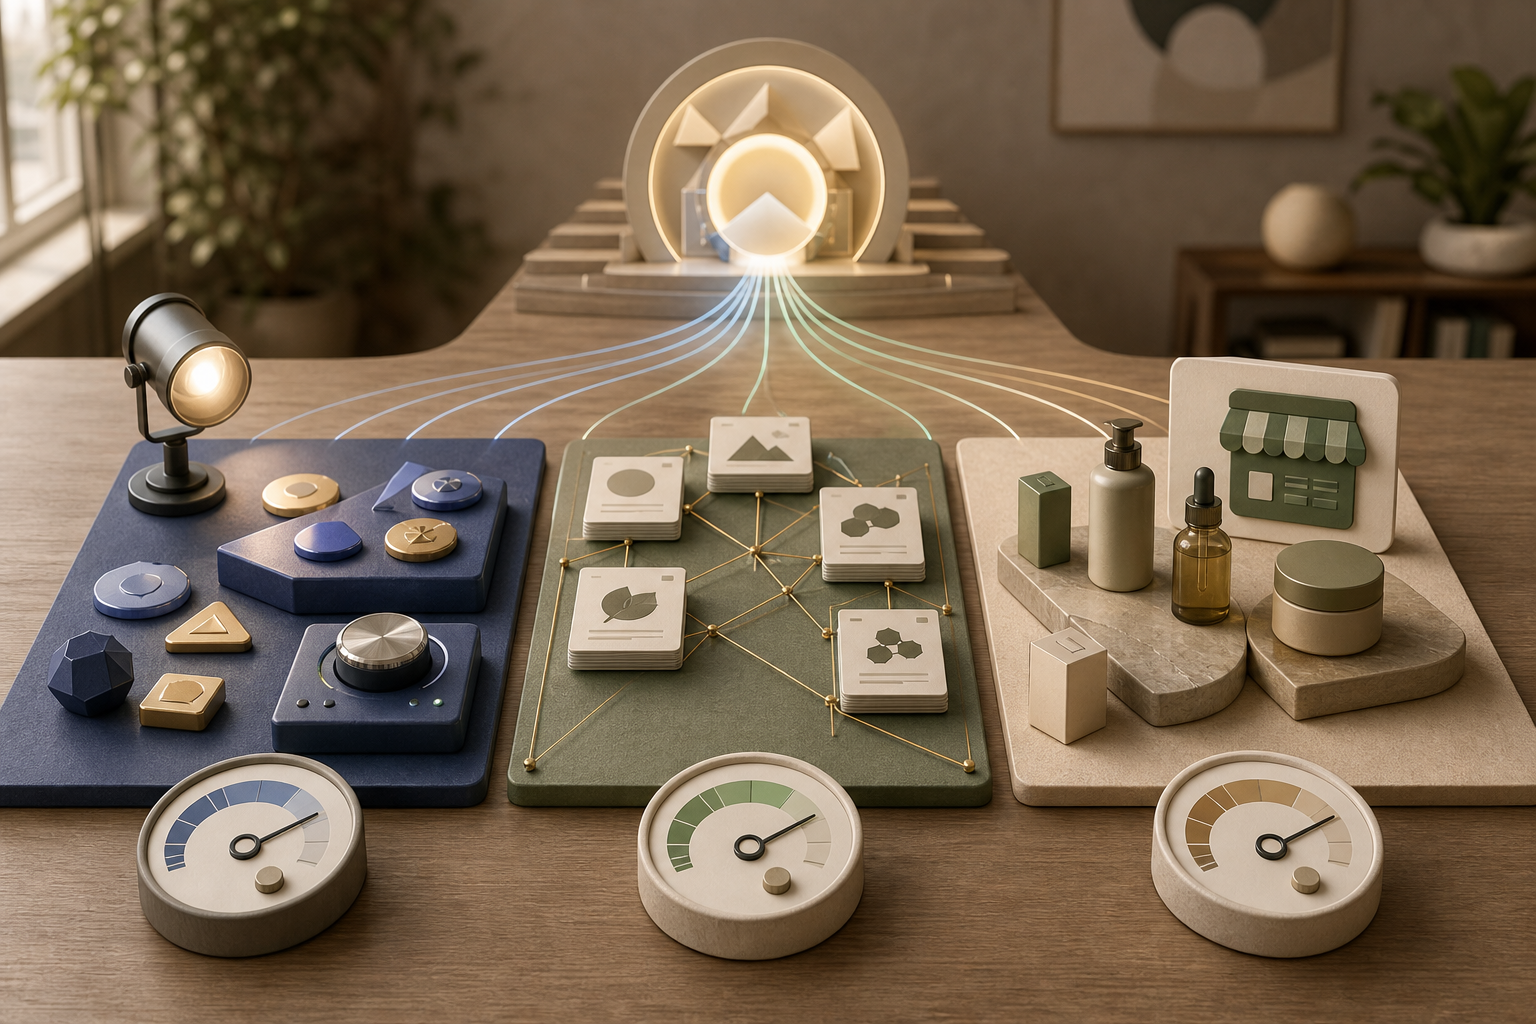
    An operations table is divided into zones for paid media, source citations, and product profiles, each with separate measurement tools.

    Organizations can respond by assigning each visibility layer a distinct job. Paid-search teams can evaluate AI Mode ads according to query economics, placement availability and conversion performance. SEO and content teams can monitor whether the brand’s pages are cited or ranked, then improve the relevance and usefulness of the pages intended to earn that exposure.

    Local and commerce teams need a third workstream for Google-hosted information. Business hours, locations, photos and reviews can become part of the AI Mode experience through Google Business Profiles. Product specifications and compatibility information may surface through Product Knowledge Panels. Because those details can be encountered before the website, maintaining them is part of commercial presentation rather than a secondary listing task.

    Reporting should preserve the same separation. A combined visibility score can conceal whether progress came from spending more, earning stronger source selection, improving organic rankings or maintaining a more complete Google-hosted profile. Channel-specific reporting makes it possible to connect each outcome to the team and investment responsible for it.

    The next useful evidence will be longitudinal: whether ad incidence continues to rise, whether new formats change advertiser competition, and whether Google’s share of citations remains concentrated in its own local and product surfaces. Until those patterns are clearer, the sound approach is to manage AI Mode as a portfolio of paid, earned and platform-hosted visibility rather than as a single search position.
    References

  • ChatGPT Ad Generation Puts Review Ahead of Automation

    ChatGPT Ad Generation Puts Review Ahead of Automation

    A reported ad-generation feature inside ChatGPT Ads could shorten the path from campaign setup to a usable creative variation. The important distinction is that the interface appears to generate a draft for approval, not a finished ad that bypasses advertiser judgment.

    For marketers, the practical value lies in faster iteration. The corresponding risk is treating generated copy as campaign strategy rather than as a starting point that still needs brand, accuracy, and performance review.

    What the reported workflow actually automates

    A visual workflow turns campaign inputs into several advertising drafts that await human selection.

    CrushPress.AI reported that an option to generate ads appears under the ChatGPT Ads platform’s ad-creation controls. According to the report, the system produces an ad variation using the advertiser’s website and campaign settings, then presents it for review, editing, and activation.

    That sequence matters. The reported interface positions artificial intelligence as a drafting layer within a conventional approval workflow. The marketer remains responsible for deciding whether the variation accurately reflects the offer, fits the campaign, and is ready to run.

    The report also describes a quick duplication option. Used carefully, that could support faster variation building: an advertiser could copy an existing ad, adjust one meaningful element, and compare the result with the original. The screenshot evidence does not, however, establish how widely the generation feature is available or how its output performs.

    Key takeaways

    • The reported tool uses website information and campaign settings to produce an ad variation.
    • Its workflow retains a human checkpoint before an ad is activated.
    • A duplication control could make structured creative variation easier, although speed alone does not create a sound experiment.
    • Generated copy still requires checks for factual accuracy, brand fit, campaign intent, and expected business value.
    • The available report shows an interface preview, not evidence of reach, output quality, or return on investment.

    Where generation can help and where it cannot

    Ad generation is most useful when the strategic inputs are already clear. A defined audience, offer, objective, and brand position give the system boundaries within which to draft. If those inputs are weak or inconsistent, quicker copy production can simply multiply the ambiguity.

    The feature may reduce mechanical work involved in producing a first variation. It cannot determine by itself whether a claim is sufficiently supported, whether the message creates the right expectation after the click, or whether a variation addresses the campaign’s actual constraint. Those are business and editorial judgments.

    The reported reliance on a website also introduces a source-quality issue. A generated ad may inherit unclear positioning, stale language, or overly broad claims from the page it uses. The output should therefore be checked against the current offer and campaign brief rather than assumed to be reliable because it originated inside the advertising platform.

    A review standard for AI-generated ads

    A marketing team checks an AI-generated ad mockup for imagery, layout, and approval criteria.

    A useful approval process begins with fidelity: the ad should describe the offer accurately and avoid introducing promises that the destination page cannot support. Reviewers should then assess whether the message reflects the intended audience and campaign objective instead of merely sounding polished.

    Brand review should cover voice, terminology, and the impression created by the ad as a whole. A grammatically clean variation can still be wrong for a brand if it exaggerates urgency, flattens an important distinction, or uses language the organization would not otherwise publish.

    Performance review requires discipline as well. The duplication control described in the report could encourage a large volume of near-identical ads. Marketers can preserve learning value by changing a deliberate variable, recording the hypothesis behind it, and judging results against the campaign’s established success measure. Generation increases the supply of options; it does not replace experimental design.

    The larger implication for campaign operations

    Embedding generation directly in an ad manager reduces the distance between source material, campaign configuration, and creative production. That convenience could lead to more variations being drafted and submitted, a commercial benefit that CrushPress.AI identified as potentially helpful to OpenAI’s advertising revenue.

    For advertisers, the more consequential change may be operational. As drafting becomes easier, quality control becomes the scarce capability. Teams will need clear ownership for approving claims, protecting brand standards, and deciding which variations deserve budget.

    The feature should therefore be evaluated less as an autonomous creative system and more as a workflow accelerator. Its long-term usefulness will depend on whether advertisers can turn faster production into better-controlled learning rather than simply a larger inventory of ads.

    References

  • ChatGPT Ads Manager: A Practical Launch Plan for Marketers

    ChatGPT Ads Manager: A Practical Launch Plan for Marketers

    You are probably not asking whether advertising in ChatGPT sounds interesting. You are asking whether it deserves a line in your media plan, which bidding model fits your goal, and how to test it without creating an expensive attribution problem.

    The sensible answer is a bounded pilot. OpenAI’s self-serve ChatGPT Ads Manager removes the former $50,000 minimum for U.S. advertisers and adds CPC bidding alongside CPM. That lowers the barrier to testing, but it does not remove the need for a clear objective, validated measurement, and a hard spending limit.

    The platform change is access, not proof of performance

    Removing a minimum spend changes who can run an experiment. It does not tell you whether ChatGPT ads will work for your audience, what a conversion will cost, or how the channel should fit alongside search, social, display, and earned AI visibility.

    Start by treating self-service access as permission to investigate, not as a reason to move budget immediately. The stated scope is U.S. advertisers. Do not assume that the same access, placements, policies, controls, or reporting apply in another country or account.

    Before approving spend, open the account and answer these questions from the terms and controls actually shown to you:

    • Is your advertiser, billing entity, product category, and target geography eligible?
    • Where can the ad appear, how is it labeled, and can you preview its presentation?
    • What does the platform count as an impression and a click?
    • Which targeting, exclusion, frequency, placement, and brand-safety controls are available?
    • Which creative formats and landing-page destinations are accepted?
    • What conversion tracking, attribution windows, exports, or integrations can you use?
    • Which campaign, bid, budget, and account-level spending limits can you enforce?
    • How are invalid interactions, refunds, taxes, data use, and ad review handled?

    These are verification questions, not assumptions about the product. Save the definitions and settings you use in the campaign brief. If an impression, click, or attribution rule changes later, you will need that record to interpret the trend correctly.

    Choose CPC or CPM from the business objective

    A marketer considers two paths, one showing individual interactions with blank cards and the other showing many viewed cards across an audience.

    CPC and CPM do not merely offer two ways to pay the same bill. They place the immediate economic risk in different places.

    Bid modelYou pay forBest starting objectiveMain measurement trap
    CPMImpression delivery, priced per thousand impressionsControlled exposure or message reachTreating a served impression as attention, interest, or demand
    CPCRecorded clicksSending people to a page where a meaningful action can occurTreating a click as a qualified visit, lead, sale, or customer

    Choose CPM when exposure is the actual job. That may fit a campaign intended to introduce a category, establish a message, or reach an audience before a later action. You still need a way to judge whether exposure created useful movement. An impression count alone proves delivery, not attention or business impact.

    Choose CPC when the landing page can carry the next part of the journey and you can measure what happens after the click. CPC transfers some delivery risk away from you because impressions without recorded clicks do not create click charges. It does not protect you from irrelevant clicks, weak landing pages, poor qualification, or broken conversion tracking.

    Compare the models through a common business outcome rather than comparing their headline prices. Calculate effective CPC as spend divided by clicks, effective CPM as spend divided by impressions multiplied by 1,000, and cost per acquisition as spend divided by attributed acquisitions. Use the platform’s precise definitions for every input.

    If your finance-approved allowable cost per acquisition is known and your landing-page conversion rate is reliable, a simple ceiling for CPC is:

    Maximum CPC = allowable cost per acquisition x expected click-to-acquisition conversion rate.

    This is a planning ceiling, not a bid recommendation. The conversion rate must come from a comparable audience and journey. If it comes from branded search, returning customers, or a different offer, it may overstate what unfamiliar ChatGPT traffic can support. If you have no reliable rate, describe the campaign honestly as a traffic-quality experiment rather than a test of profitable acquisition.

    Build a pilot that can answer one decision

    A marketer observes a blank advertising card moving through a small testing chamber bounded by a budget rail and a sealed container of tokens.

    A useful pilot does not need to answer whether the entire platform works. It needs to answer one decision your team will make next: continue, stop, change the offer, change the audience hypothesis, or repair measurement before spending more.

    1. Write one hypothesis. Use this form: For this audience and context, this message will produce this business action within our allowable outcome cost.
    2. Select one primary business event. A qualified lead, completed purchase, activated account, or another value-bearing event is more useful than a page view. Define exactly when the event counts.
    3. Validate the full measurement path before launch. Follow a test visit from the ad destination through the primary event, analytics, CRM or commerce system, and revenue record where applicable.
    4. Match the advertisement to the landing page. Keep the promise, terminology, product scope, and expected next step consistent. A click bought with one promise and handed to a different page cannot diagnose channel quality cleanly.
    5. Limit simultaneous variables. If you change the audience, bid model, message, offer, and page at once, a good or bad result will not tell you which change mattered.
    6. Set financial guardrails. Record the total cap, any daily control available, the person allowed to approve an increase, and the condition that pauses spending. Paid experiments can consume budget before a delayed conversion report catches up, so the cap must exist before launch.
    7. Write the decision rule in advance. State which primary metric, cost boundary, data-quality checks, and minimum evidence your team requires before it will scale, revise, or stop.

    Do not use a cheap click as the decision rule unless a cheap click is genuinely the business outcome. Rank the metrics so that the platform metric remains subordinate to the business metric: delivery supports clicks, clicks support qualified actions, and qualified actions support revenue or another defined result.

    Run an A/B test only when the campaign can produce enough observations for a defensible comparison. If volume is too low, do not declare a winner from a handful of outcomes. Treat the result as directional, retain the uncertainty, and use it to design the next test rather than to justify a broad rollout.

    Keep paid performance separate from AI visibility

    ChatGPT advertising and visibility inside unpaid AI answers belong in the same executive conversation, but not in the same measurement bucket. Paying for distribution does not, by itself, demonstrate that your brand will be mentioned, recommended, or cited in an unpaid response.

    Maintain three distinct layers in your reporting:

    • Paid delivery: spend, impressions, clicks, effective CPC or CPM, and other delivery measures the account exposes.
    • On-site response: engaged visits, qualified events, conversion rate, cost per acquisition, revenue, and downstream lead quality where those measures apply.
    • Earned AI visibility: unpaid brand mentions, citations, answer inclusion, referral visits, and conversions from AI discovery measured through a consistent monitoring method.

    Use consistent campaign parameters and retain platform, campaign, creative, and destination identifiers wherever the system supports them. Keep paid ChatGPT traffic out of organic AI referral reporting. Otherwise, an increase purchased through ads can be mistaken for progress in generative engine optimization.

    Measure earned visibility with a stable prompt set, documented locale and account conditions, and timestamps. AI responses can vary, so a single favorable answer is not a trend. Compare repeated observations under the same method and label the result as monitored visibility, not guaranteed ranking.

    The same separation applies to technical optimization. Clear entity information, useful content, and accurate structured data may support machine understanding, but JSON-LD is not an ad setting and does not guarantee an AI citation. Likewise, ad spend is not a substitute for the content and authority work required to earn unpaid visibility.

    Automate reporting before you automate campaign control

    Four OpenAI Ads nodes for Profound Agents can bring advertising data into agentic workflows. That creates useful options for recurring analysis, but the existence of four nodes does not tell you which data each one reads, which actions it can write, or which permissions it requires. Inspect those details before connecting a live account.

    A safe first workflow should do the following:

    • Begin with read-only access if that permission is available.
    • Pull a defined account, campaign scope, date range, timezone, currency, and attribution setting.
    • Check for missing records, delayed conversions, duplicate rows, and inconsistent campaign identifiers before calculating performance.
    • Calculate derived metrics from the raw values and retain those values beside every conclusion.
    • Flag a breached budget, tracking anomaly, or performance threshold for review rather than silently changing the campaign.
    • Require human approval before an agent changes a bid, budget, audience, destination, creative, campaign status, or account permission.
    • Log the input data, generated recommendation, approver, resulting action, and rollback path.

    If a connected node can write changes, give it the narrowest permission that supports the approved workflow. An agent asked to maximize click-through rate can rationally chase more clicks even when those clicks do not become customers. Every optimization instruction therefore needs a business constraint, a spending limit, and a metric that represents value after the click.

    An automated report should also expose its boundaries. Include the reporting window, currency, attribution rule, conversion lag, excluded campaigns, missing fields, and the raw numerator and denominator behind each rate. A fluent narrative without those details is presentation, not a reliable decision system.

    Key takeaways

    • Self-serve access and removal of the former $50,000 minimum make a smaller U.S. advertiser pilot feasible; they do not establish likely performance.
    • Use CPM when controlled exposure is the objective and CPC when a measurable post-click journey is the objective.
    • Judge both models against the same business outcome, not against impressions or clicks in isolation.
    • Launch one hypothesis with validated tracking, a hard spending cap, a pause condition, and a decision rule written before the first charge.
    • Report paid ChatGPT results separately from unpaid AI mentions, citations, referrals, and other GEO or AEO indicators.
    • Use agentic integrations for scoped data collection and anomaly detection first; keep spend-changing actions behind explicit human approval.

    Your next step is a one-page test brief. Fill in the eligible account and geography, objective, bid basis, audience hypothesis, landing-page event, allowable outcome cost, attribution rule, budget cap, pause condition, and final decision rule. If any field is blank, the campaign is not ready to buy useful learning.

    Once every field is defined, launch the smallest controlled test capable of answering the decision. At the first review, expand only when the business result and data quality support the rule you set in advance. Otherwise, repair the measurement, revise one variable, or stop.

    References

  • ChatGPT Advertising Insights: A Practical Pilot Playbook

    ChatGPT Advertising Insights: A Practical Pilot Playbook

    If you are deciding whether ChatGPT advertising deserves budget, do not start by asking whether it resembles paid search. Start with the moment the ad enters: the user has already described a need, added constraints, and moved partway toward a decision.

    A ChatGPT ad can appear inline within that conversation, marked as Sponsored and presented with a headline, short body, and destination. Your job is not to interrupt the journey. It is to offer a credible next step that fits the journey already underway. That difference should shape your creative, measurement, landing pages, and relationship between paid advertising and organic AI visibility.

    Use the early data as a format signal, not an ROI benchmark

    The first useful insight is about the strength and limits of the evidence. The early U.S. trial launched on February 9 for Free and Go users, while Adthena tracked more than 50,000 daily placements from over 600 advertisers across B2B software, ecommerce, fintech, and consumer categories.

    That is enough activity to reveal recurring creative conventions. It is not enough to establish a universal cost per acquisition, return on ad spend, or incrementality benchmark. The observations come from a vendor-tracked index during a trial, span materially different verticals, and do not provide one standardized performance baseline for every advertiser.

    Use the data to answer questions such as how much copy the format can carry, which information tends to appear first, and how closely creative reflects the conversation. Do not use it to forecast your return before you have campaign-level evidence from your own offer, audience, and destination.

    Before assigning meaningful budget, make sure your pilot can answer a defined question:

    • Can you identify a narrow group of commercial topics where the user is likely to be comparing options or preparing to act?
    • Do you have a specific, verifiable benefit that can be understood without several lines of explanation?
    • Does the destination continue the exact promise made in the ad?
    • Can you separate ChatGPT placements from your other paid traffic when evaluating outcomes?
    • Have you defined what would justify expanding, revising, or stopping the test before spend begins?

    Rollout status is time-sensitive, so confirm actual inventory and account eligibility before committing budget or launch dates. A projected geographic expansion is not the same thing as inventory you can buy.

    Write an answer fragment, not a compressed search ad

    A distinct sponsored module fits into a flowing sequence of text-free conversation cards while a separate banner sits outside the flow.

    A traditional search ad often has several components competing for attention: multiple headlines, descriptions, sitelinks, extensions, and other assets. The early ChatGPT format is more restrained. That makes every word carry more of the decision.

    The strongest working model is an answer fragment. It should make sense beside the assistant’s response, acknowledge the user’s decision criteria, and introduce a next step without pretending to be the neutral answer.

    The tracked placements show several compact patterns. Headlines averaged about 30 characters and peaked at 36, body copy averaged roughly 19 words, and many ads used two short sentences. These are observed conventions, not confirmed platform character limits.

    Creative elementEarly patternWhat to do with it
    HeadlineAbout 30 characters on average, with a peak at 36Lead with the decision-driving benefit. Do not spend the available space on a generic slogan.
    Headline openingMost begin with the brand nameTest a Brand: Benefit construction when recognition and accountability matter.
    BodyAbout 19 words, commonly split into two sentencesUse the first sentence for proof and the second for a low-friction action.
    RelevanceStronger creative mirrors the user’s contextReflect the category, constraint, or desired outcome instead of repeating a loose keyword.
    Offer detailDollar signs, rates, and concrete figures were associated with stronger conversion performancePrioritize a specificity test, but treat the pattern as a hypothesis to validate in your own campaign.

    Build each variation from three prompt components

    When a user asks for accounting software for a small team, for example, accounting software is only the category. Small team is the constraint. The unstated decision criterion might be fast setup, predictable cost, or limited administrative work. Creative that reflects only the category will feel generic even if it contains the right keyword.

    1. Extract the category: what kind of product, service, or action does the user want?
    2. Extract the constraint: what price, use case, location, feature, risk, or timing narrows the choice?
    3. Choose one decision criterion your offer can substantiate.
    4. Write the headline as Brand: Verified Benefit.
    5. Use the body for one proof point and one proportionate call to action.
    6. Remove any claim that the landing page cannot immediately confirm.

    A useful template is: Brand: [specific outcome]. [Proof tied to the user’s constraint]. [Simple next action]. The brackets are not an invitation to stuff several benefits into one placement. Choose one reason to continue.

    Specificity needs controls. If you advertise a price, rate, discount, delivery window, or availability claim, it must be current, approved, and visible at the destination. A concrete figure can improve clarity, but an outdated figure creates both conversion friction and potential compliance exposure. When the value changes frequently, build a review process before testing it in ad copy.

    Test in an order that explains the result

    Changing the headline, proof, call to action, and landing page at the same time may produce a winner, but it will not tell you why it won. Start with the variables most closely tied to conversational relevance:

    1. Specific offer versus general benefit.
    2. Query-matched benefit versus broad category language.
    3. Quantified proof versus qualitative proof.
    4. Low-commitment call to action versus immediate purchase or signup language.
    5. General landing page versus a page that continues the same constraint and benefit.

    Hold the other elements steady during each comparison. The point is not merely to improve the ad. It is to learn which part of the conversation your audience needs resolved before moving forward.

    Measure prompt coverage and response duplication before calling it reach

    An overhead arrangement of varied prompt tokens connects to response cards, including a magnified cluster of visibly duplicated cards.

    Clicks and conversions still matter, but they do not tell you whether your brand is present across the conversations that matter. Conversational inventory needs an observation layer organized around topics, prompts, and individual responses.

    That becomes especially important because one brand has been observed appearing twice within the same ChatGPT response. This double-parked behavior creates more placements, but it does not automatically create more unique reach. Counting each placement as a separate conversation would overstate coverage.

    For every observed placement, record the topic, prompt or prompt class, response identifier, timestamp, position, advertiser, headline, body, and destination. Add post-click outcomes when your analytics can connect them. That record supports several more useful measurements:

    • Observed prompt coverage: the portion of your monitored commercial prompts in which your brand appeared.
    • Observed response presence: responses containing your brand divided by eligible responses you actually monitored.
    • Duplication rate: brand-present responses containing more than one placement for the same brand.
    • Competitor overlap: responses where your brand and a named competitor appeared together.
    • Creative-context match: whether the ad reflects the category, constraint, and decision criterion in the prompt.
    • Post-click continuity: whether the destination preserves the offer and language that earned the click.
    • Business outcome: qualified lead, sale, signup, or another result defined before the pilot.

    Call these observed rates, not platform-wide impression share. A monitoring sample cannot tell you the total number of eligible conversations unless the platform provides that denominator. This naming discipline prevents a directional visibility metric from turning into a false market-share claim.

    Review duplication separately from performance. Two appearances might reinforce recall, or they might add no incremental value. The placement pattern alone cannot settle that question. Compare duplicated and single-placement responses only when you have enough campaign data to evaluate their downstream outcomes.

    Your landing-page review should be just as specific. Check whether the advertised benefit appears without searching, whether the price or rate matches, whether the next action is obvious, and whether the page answers the constraint expressed in the originating conversation. A relevant ad that lands on a general homepage throws away the context that made the placement useful.

    Coordinate ChatGPT ads with AEO and GEO without merging the KPIs

    Paid presence and organic AI visibility can occur in the same conversational environment, but they are not the same achievement. A sponsored placement buys labeled exposure. An organic citation, recommendation, or brand mention depends on how the system constructs its answer. Early placement observations do not establish that buying ads improves organic answer inclusion.

    Keep the two lanes separate in reporting. If you combine them into one AI visibility number, you will not know whether a change came from media spend, content improvements, brand demand, or answer-engine behavior.

    • Use one shared topic map. Organize paid monitoring and organic visibility work around the same commercial questions, constraints, entities, and decision criteria.
    • Give paid media its own outcomes. Track observed presence, duplication, clicks, qualified actions, and campaign economics.
    • Give AEO and GEO their own outcomes. Track whether the brand is mentioned, cited, represented accurately, and connected to the intended category across monitored answers.
    • Align the factual layer. Prices, rates, features, availability, and offer terms should agree across ad copy, visible page content, and applicable structured data.
    • Investigate cross-channel clues. A commercial prompt with competitor ads but weak organic answers may expose a content opportunity. Strong organic visibility with no paid presence may identify a conversation worth testing, but neither observation guarantees demand or return.

    JSON-LD can clarify entities, products, offers, and other machine-readable facts when it accurately represents visible content. It does not purchase inventory, guarantee inclusion in an AI response, or repair a weak offer. Use structured data to reduce ambiguity, then use advertising to test whether a clear commercial promise earns action.

    This coordinated model also gives you a cleaner competitive view. You can distinguish a competitor that is buying exposure from one that is repeatedly earning non-sponsored visibility. The response is different: one may call for a media test, while the other may require better content, stronger entity signals, clearer proof, or a more competitive offer.

    Key takeaways for your first ChatGPT ad pilot

    • Treat early placement data as evidence about format and creative conventions, not as a guaranteed ROI benchmark.
    • Write for a user who has already supplied context: lead with the brand, one verified benefit, one proof point, and one next action.
    • Use the observed 30-character headline and 19-word body patterns as editing discipline, not as assumed platform limits.
    • Test concrete figures before vague claims when your offer supports them, but keep every price, rate, and term synchronized with the destination.
    • Measure prompts and unique responses as well as placements, because two appearances in one response do not equal two reached conversations.
    • Coordinate paid, AEO, GEO, landing-page content, and structured data around one topic map while reporting paid and organic outcomes separately.

    Your next move is a narrow pilot, not a platform-wide commitment. Choose a small set of high-intent topics, document the user’s constraints, create controlled variations, and establish an organic visibility baseline before ads run. You will then be able to decide from your own evidence whether conversational advertising adds qualified demand, merely adds placements, or reveals a larger content opportunity.

    References

  • How to Prepare for ChatGPT’s Advertising Expansion

    How to Prepare for ChatGPT’s Advertising Expansion

    If you’re deciding whether ChatGPT belongs in your paid media plan, don’t treat its advertising expansion as a cue to move budget immediately. Treat it as a cue to become test-ready. The opportunity may be meaningful, but availability, targeting, reporting, and campaign economics still need to be proved.

    Your advantage won’t come from being first at any cost. It will come from knowing exactly what you want to learn, what evidence would justify more investment, and how paid placement fits beside your existing SEO, AEO, and generative engine optimization work.

    The expansion addresses inventory, not the whole advertising case

    Early observations indicate that ads are appearing within conversations for some logged-out users, although OpenAI had not formally announced the expansion. That uncertainty matters. A visible rollout can establish that inventory is growing without establishing who can buy it, which users are eligible, how delivery is priced, or whether the experience is stable enough for forecasting.

    The immediate pressure appears to be supply. Pilot advertisers have reportedly struggled to spend their intended budgets because inventory was limited, even after the financial hurdle fell from $200,000 to $50,000. Opening more conversations to ads is a logical way to create additional opportunities for delivery.

    That doesn’t automatically make ChatGPT a scalable performance channel. More inventory can help campaigns spend, but it doesn’t prove that the added impressions will produce qualified traffic, incremental customers, or acceptable acquisition costs. Logged-out reach could also differ from logged-in reach in ways that affect relevance and measurement. Until the buying interface or your agreement provides the details, don’t assume the platform can recognize, target, exclude, or report on these two audiences in the same way.

    Keep ChatGPT out of your dependable base forecast for now. Put it in an experimental budget with its own success criteria and loss limit. That protects the budget you already rely on while giving you room to learn if access becomes available.

    Key takeaways

    • Wider logged-out reach may relieve an inventory constraint, but it doesn’t yet establish stable campaign economics.
    • Conversational placement deserves its own creative and landing-page strategy; repurposing a display banner is unlikely to answer the user’s immediate need.
    • Require definitions for delivery, targeting, attribution, and logged-in versus logged-out reporting before committing meaningful budget.
    • Measure paid placement separately from organic AI visibility. Buying an ad doesn’t demonstrate that ChatGPT knows, cites, or recommends your brand.
    • Prepare a controlled pilot now, but release money only after the platform can support the decisions you need to make.

    Build the pilot around one commercial decision

    A hand adjusts one control on a transparent testing chamber as a single campaign tile moves toward two possible outcomes.

    Novelty is not a campaign objective. A useful pilot answers a decision such as: Should we add this channel to our acquisition mix? Can it reach buyers earlier than search ads? Does it create qualified demand we wouldn’t otherwise capture? Choose one question. A pilot designed to prove awareness, traffic quality, lead generation, and revenue at once usually produces an ambiguous answer to all four.

    1. Choose one demand state. Define the situation in which your offer helps, such as comparing approaches, narrowing a shortlist, solving an urgent problem, or selecting a provider. Don’t assume the platform lets you bid on exact prompts. Ask what targeting controls actually exist, then translate your demand state into the controls available.
    2. Name one primary business outcome. Use a completed purchase, qualified lead, activated account, booked consultation, or another event connected to value. A click can diagnose delivery, but it shouldn’t become the business case merely because it is easy to count.
    3. Set a quality guardrail. For lead generation, that could be lead acceptance or sales qualification. For commerce, it could be cancellation, return, or contribution margin. A campaign can report an attractive acquisition cost while sending customers who never become profitable.
    4. Create a landing page for the conversational handoff. Restate the promise plainly, answer the next likely question, provide evidence for important claims, and make the next step obvious. If the advertisement answers one question but the page opens with a generic corporate message, you lose the contextual advantage of the placement.
    5. Prepare multiple message angles. Ads have been observed fitting into the conversation rather than behaving like conventional banners. Write concise copy around the user’s task: a direct answer or benefit, a relevant qualification, and a proportionate next step. Keep every claim defensible when read outside the surrounding conversation.
    6. Write the expansion rule before launch. Define the acquisition cost, conversion quality, and measurement confidence needed for more investment. Also define the conditions that stop the test. Historical economics from your own business are more useful here than an arbitrary industry benchmark.

    Your test charter should also identify the comparison that matters. If ChatGPT merely receives budget that would have converted through paid search, platform-reported conversions may look encouraging without adding much business value. Compare the pilot with your normal channel mix, not with doing nothing in an imaginary market.

    Demand measurement answers before you demand scale

    Conversational advertising can create a less familiar path than keyword, feed, or social advertising. A person may ask several questions, see a commercial placement, leave, research the brand elsewhere, and convert later. That makes a clean platform dashboard especially tempting. It also makes unexamined platform attribution especially risky.

    Before launch, get written answers to the questions that can change your interpretation of performance:

    • What event counts as an impression, and can one conversation generate more than one?
    • What counts as a click or other engagement?
    • Which click-through or view-through attribution windows are used?
    • Can you change those windows or compare them with your analytics standard?
    • Can results be segmented by logged-in status, placement type, geography, device, creative, and audience method?
    • What contextual, behavioral, demographic, or account-level signals can influence delivery?
    • Which exclusion, frequency, suitability, and sensitive-topic controls are available?
    • How are duplicate conversions, invalid interactions, refunds, cancellations, and offline outcomes handled?
    • Can you export event-level or sufficiently granular campaign data for independent reconciliation?

    A missing answer is information. If you can’t distinguish the new logged-out inventory from the rest of delivery, you won’t know whether the expansion improved reach, reduced quality, or simply changed the mix. If you can’t align attribution windows, you won’t be able to compare ChatGPT with another channel fairly.

    Build reporting in four layers. Delivery tells you whether the campaign can spend. Response tells you whether people engage. Business quality tells you whether those interactions become valuable outcomes. Incrementality asks whether the outcomes would have happened without the campaign. Keep these layers separate so a strong click rate cannot disguise weak economics.

    Use a controlled comparison if one is available and proportionate. A randomized holdout is the clearest option when the platform supports it. Otherwise, use a carefully chosen geographic or time-based comparison and document its limitations. Seasonality, promotions, sales activity, and changes in other media can all create false lift. Don’t call a before-and-after difference incremental merely because the dates line up.

    Preserve campaign and creative identifiers in your analytics, connect conversions to revenue or lead quality where consent and applicable rules allow, and deduplicate outcomes across platforms. Compare the platform’s totals with your own analytics before increasing spend. A disagreement doesn’t automatically mean one system is wrong; attribution systems can assign the same conversion differently. It does mean you need to understand the difference.

    Keep paid ChatGPT reach separate from organic AI visibility

    ChatGPT advertising and generative engine optimization address different problems. An ad buys an opportunity to appear under specified campaign conditions. Organic visibility depends on whether a system can discover, interpret, trust, and use information about your brand or subject. Paid delivery is not evidence of organic inclusion, and an organic mention is not evidence that advertising caused it.

    This distinction should shape both your dashboard and your content plan. Report paid impressions, engagements, conversions, acquisition cost, and incrementality as campaign metrics. Track organic citations, brand mentions, referred visits, answer accuracy, and visibility across relevant prompts as a separate program. You can examine relationships between them, but don’t combine them into one score that hides which mechanism changed.

    The landing pages used for conversational ads should still meet the same evidence standard as your organic content:

    • Answer the visitor’s central question before forcing them through a broad brand narrative.
    • Use descriptive headings that make each section understandable on its own.
    • Identify products, services, organizations, and authors consistently across the page and site.
    • Support material claims with evidence a reader can inspect.
    • Keep prices, availability, policies, and other changeable facts current wherever you publish them.
    • Use schema types and properties that accurately represent visible content. JSON-LD can clarify entities and relationships, but it cannot guarantee inclusion in an AI answer or eligibility for an advertisement.
    • Make ownership, contact details, and the path to a real next step easy to verify.

    Use paid learning to improve content only when the data supports the connection. If a message angle attracts qualified visitors, examine the underlying need and build a fuller answer around it. Don’t manufacture near-duplicate pages for every phrasing variation, and don’t turn an advertising result into an unsupported claim about what all ChatGPT users want.

    The reverse is useful too. Organic visibility analysis can reveal questions where your brand is absent, misunderstood, or poorly supported. Those gaps can inform a paid hypothesis while you improve the underlying content. The advertisement may create immediate reach; the content fixes the durable information problem.

    Use a readiness gate before committing budget

    A strategist waits beside budget tokens while an amber checkpoint keeps a multi-stage gate partly closed before a field of blank message shapes.

    You don’t need to choose between rushing in and ignoring the channel. Use three readiness states.

    • Prepare now if ChatGPT is relevant to how your buyers research or compare solutions. Create the test charter, conversion definitions, landing page, creative hypotheses, suitability rules, and reporting requirements without assuming access.
    • Test when available if you can isolate a meaningful business outcome, cap the downside, reconcile conversion data, and learn something that affects a real channel decision. Learning value matters, but it should be named rather than used as an excuse for unlimited spending.
    • Delay investment if access requires a commitment your experiment cannot justify, essential targeting or safety controls are missing, results cannot be independently reconciled, or your landing experience is not ready. Scarcity of access is not proof of value.

    The reported reduction from $200,000 to $50,000 still represents material exposure for many organizations. Don’t commit merely to reserve a place in a pilot. Confirm the contract terms, cancellation rights, measurement access, inventory expectations, and responsibility for unsuitable placement before funds become difficult to recover.

    Start with a one-page test charter. Write down the user need, primary outcome, quality guardrail, maximum acceptable downside, required platform answers, and expansion rule. When broader access arrives, that page will let you evaluate the opportunity on business evidence instead of launch momentum.

    References


  • Google AI Ads and Sales Lift: A Practical Testing Playbook

    Google AI Ads and Sales Lift: A Practical Testing Playbook

    You have probably seen the headline number: a retailer used Google AI advertising and revenue rose by 80%. The useful question is not whether AI ads can work. It is whether they can produce profitable, incremental sales for your business without weakening measurement or surrendering control of your brand.

    You can answer that question, but not by switching on every automated feature and comparing this month’s revenue with last month’s. Treat AI Max, Performance Max, reusable text rules, and recommendation reporting as separate tools inside a controlled commercial test. That gives you a result you can defend when someone asks what actually caused the lift.

    An 80% lift is a case result, not your forecast

    Google has highlighted Aritzia as having achieved an 80% increase in revenue with AI Max. That is evidence of possibility, not a transferable benchmark. It does not tell you what Aritzia would have earned without AI Max, how much media spend changed, which customers were new, or what happened to margin.

    Revenue lift can come from several places. An advertiser may reach previously missed queries, improve the match between a shopper and a product, spend more, capture demand that another campaign would have converted, or count conversions differently. Only the first two clearly demonstrate better advertising. Additional spend can still be worthwhile, but it is a different claim and should be judged against your allowable acquisition cost.

    Write your expected mechanism before starting. A useful hypothesis is specific: AI Max will find additional non-brand demand for selected products and increase contribution profit without pushing customer acquisition cost above our limit. A weak hypothesis is that AI will increase sales. The stronger version identifies the demand, the product scope, the business outcome, and the constraint.

    Set a budget boundary and stop conditions at the same time. Automation can spend into newly discovered demand quickly. Without a pre-agreed limit, higher expenditure can resemble growth even when each additional order is less valuable. Your own margins, return rates, sales cycle, and cash constraints should determine that limit; a vendor case result should not.

    AI changes matching, but your inputs set its ceiling

    Traditional search advertising starts with keywords chosen by the advertiser. Google’s newer systems place more weight on inferred intent. They assess the retailer’s website and creative assets, interpret a search, and dynamically match products and messages to that context. Performance Max and AI Max are designed to operate within this more intent-driven model.

    The opportunity is clearest in conversational search. Google says queries in AI Mode tend to be two to three times longer, giving the matching system more context. Google also says 15% of daily searches are novel. A rigid keyword list cannot anticipate every new formulation, while an intent model can potentially connect unfamiliar wording with an appropriate offer.

    That does not remove the need for optimization. It moves optimization upstream. The system cannot reliably distinguish two similar products if your pages use vague names, bury the differences, or contradict the creative. It cannot protect a nuanced brand position that has never been translated into operational rules.

    • Clarify the product: Make the product type, variant, intended buyer, availability, price, and material differences easy to identify on the landing page and in the product data you provide.
    • Align the promise: Check that advertising claims, promotions, shipping terms, and calls to action agree with the destination page. Automation can scale a mismatch as easily as it scales a good message.
    • Supply useful creative range: Give the system assets that express different legitimate benefits, use cases, and objections. Cosmetic variations of the same vague claim do not create meaningful choice.
    • Define the sale correctly: Confirm that the primary conversion represents a commercially useful outcome. If low-value actions sit beside completed purchases without a clear hierarchy, more reported conversions may not mean more revenue.
    • Separate brand rules from campaign ideas: Tone, prohibited language, required qualifications, product naming, and legal restrictions should remain stable. Offers and audience-specific messages can change by campaign.

    Google Ads is testing a beta capability that lets advertisers clone approved AI text guidelines from an existing campaign. If it is available in your account, use it to turn recurring brand decisions into reusable instructions. A practical rule set should cover voice, required product terminology, claims the system must not make, promotion wording, and acceptable calls to action.

    Cloning saves setup time; it does not eliminate review. Read the copied rules in the context of the destination campaign. A restriction written for one market, product category, or promotion can be incomplete or actively wrong elsewhere. Assign an owner and version the rules internally so your team knows which guidance was approved and why.

    Build a test that can explain where sales came from

    Two matched groups of product boxes travel through separate treatment and control lanes toward individual checkout stations.

    The main measurement mistake is changing automation, budget, creative, offers, landing pages, and conversion tracking at once. A good result then produces enthusiasm but little knowledge. A bad result creates the same problem because you cannot identify which change failed.

    1. Choose one commercial hypothesis. Name the customer demand you expect AI matching to capture, the products included, the primary business metric, and the maximum cost you will tolerate.
    2. Set a clear boundary. Limit the first test to a defined campaign, product group, market, or customer cohort. Avoid exposing the entire account before you know how the system behaves with your inputs.
    3. Preserve a comparison. Keep a control when account structure and volume permit it. Otherwise, save the pre-change campaign data and identify a comparable product or market that will not receive the change.
    4. Reduce simultaneous changes. Hold pricing, promotions, landing pages, inventory policy, and conversion definitions steady where practical. Record anything that cannot be held steady, including stockouts and major merchandising events.
    5. Allow for conversion lag. Do not declare a winner while one group has had more time to accumulate purchases, cancellations, or returns. Read both groups over equivalent conversion windows.
    6. Review three layers of evidence. Check delivery, customer response, and business value separately. More reach may explain more orders, but only revenue quality and cost reveal whether the expansion was worthwhile.

    At the delivery layer, inspect spend, impressions, click volume, and the kinds of demand being reached. At the response layer, inspect purchases, conversion rate, and average order value. At the business layer, inspect net revenue, contribution margin, new-customer share where you can measure it, cancellations, and returns. A campaign can look strong in the advertising interface while failing the business layer.

    Split branded and non-branded demand in the analysis wherever your reporting allows. AI can appear efficient when it captures customers already searching for your company or products. That traffic may still deserve coverage, but it should not be presented as newly created demand. The same principle applies to returning customers: retained revenue and acquired revenue answer different questions.

    Google Ads has also added a Results tab intended to show the impact of recommendations. Use it to investigate what changed after a recommendation was applied, not as automatic proof that the recommendation caused incremental profit. Platform reporting can identify a useful correlation and shorten diagnosis, but it does not control for promotions, seasonality, inventory, competitor behavior, or sales that another campaign might have captured.

    Key takeaways

    • An 80% revenue increase from one retailer establishes potential, not an expected return for your account.
    • AI Max and Performance Max can interpret demand beyond a fixed keyword list, which matters as searches become longer and more conversational.
    • Clear product information, aligned landing pages, useful creative, and correctly defined conversions are inputs to the system, not cleanup tasks for later.
    • Reusable AI text rules can speed campaign setup, but every cloned rule set still needs market- and product-specific review.
    • Measure incremental business value rather than reported conversions alone. Separate brand demand, returning customers, media spend, returns, and margin.
    • Use recommendation results as diagnostic evidence. Validate causation with a control or the strongest comparable baseline available.

    Scale only after the result survives business checks

    A stream of purchase tokens passes through margin, inventory, and quality checkpoints before reaching a larger retail network.

    A successful test should answer more than whether sales rose. You should know which products gained, what type of demand expanded, how much spend changed, whether acquisition remained within your limit, and whether the revenue retained its value after discounts, cancellations, and returns.

    Before expanding the campaign, require the result to pass five checks:

    • Incrementality: The gain remains credible after separating branded demand and other traffic the campaign may have absorbed.
    • Economics: Acquisition cost and contribution margin stay within the limits set before the test.
    • Quality: Search intent, generated messaging, landing pages, and purchased products align with the hypothesis.
    • Durability: The outcome is not explained by a short promotion, inventory event, reporting delay, or one unusually strong segment.
    • Control: Brand and compliance reviews find no unacceptable claims, tone, targeting pattern, or customer experience.

    Scale in stages if those checks pass. Expand one boundary at a time, such as the eligible product set or budget, and keep the same business metrics visible. If revenue rises but margin, new-customer acquisition, or message quality deteriorates, pause the expansion and correct the input or objective before spending more.

    Google is also experimenting with personalized direct offers and supporting a broader move toward purchases inside AI interactions through the Universal Commerce Protocol developed with Shopify. Those developments point toward a shorter path from conversational discovery to checkout, but experiments and infrastructure plans are not guaranteed sales. Your immediate advantage comes from making your business legible to intent-matching systems and building measurement that can distinguish a real commercial gain from a persuasive dashboard.

    Start with one bounded campaign. Write the hypothesis, unit-economics limit, brand rules, comparison method, and stop conditions before enabling the change. That single page of decisions will do more for your eventual sales result than adopting every AI feature at once.

    References

  • Google’s AI Mode: Revolutionizing Ad Monetization

    Google’s AI Mode: Revolutionizing Ad Monetization

    As I explore the ever-evolving landscape of Google’s AI Mode, it’s fascinating to witness how ad formats, reporting, and control are taking shape. Google seems to have a master plan in place that competitors just can’t keep up with.

    I find myself intrigued by Google’s entry into this next phase of conversational search. It’s not just about user numbers but who can effectively monetize them. Google’s mature ad systems and extensive advertiser base offer a significant edge.

    The initial panic surrounding Google’s position is over. Google’s long-standing advantages and huge investments have leveled the playing field with ChatGPT in LLM search.

    Back in December 2025, when Google declared code red, it became clear that they were serious. Apple’s decision to partner with Google for its AI needs is indeed telling.

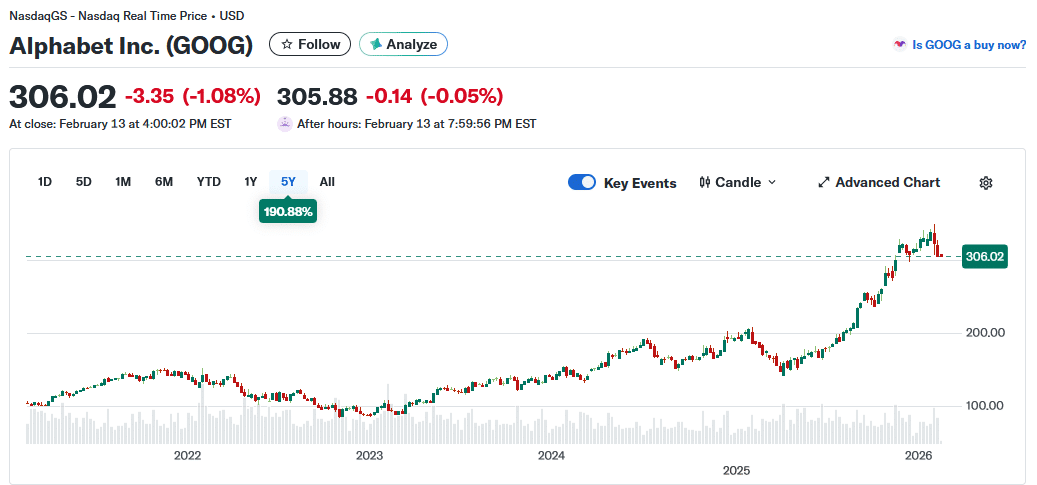
    Initially, it seemed plausible that Google would struggle against ChatGPT, but the market has since adjusted its views. The company’s valuation reflects renewed confidence, rivaling even Apple at a substantial $3.6 trillion.

    As I dive deeper into how monetization will shape this race, I’m struck by how Google’s recent advances have significantly boosted its valuation.

    ```json
{
  "alt": "Alphabet Inc. (GOOG) stock performance chart over five years, showing growth of 190.88%.",
  "caption": "Alphabet Inc.'s (GOOG) stock chart reveals a significant upward trend over the past five years, with a marked growth of 190.88%.",
  "description": "This image displays a five-year stock performance chart for Alphabet Inc. (GOOG), highlighting a substantial gain of 190.88%. The chart features key stock prices at the market close on February 13, with a closing price of 306.02, reflecting a decrease of 1.08%. The after-hours price is 305.88, down by 0.05%. The chart tracks the stock's fluctuations, offering insights into significant trends and key events impacting performance in the NasdaqGS market."
}
```

    It’s clear that the visibility of financial projections plays a massive role in how the company is perceived financially. Google’s approach to shifts in user behavior is crucial in maintaining its robust business model.

    From my perspective, much of your digital advertising budget likely goes to Google. Its prominence demands attention, not just in search but also in emerging AI platforms like ChatGPT and Claude.

    The competition in LLM conversations is intriguing. Google and ChatGPT are vying for different monetization models, a fascinating case study of differing strategies.

    For those of us in advertising, it’s essential to monitor developments like ad formats, rollout pace, and public reception to ads within these platforms.

    OpenAI’s current monetization model is intriguing but still nascent, reliant on a small group of major advertisers. We’ll see how they expand and fine-tune this model over time.

    ```json
{
  "alt": "Weather forecast indicating rain in Sarasota on February 22, 2026, with a summary of rain chances over the next 14 days.",
  "caption": "Stay prepared, Sarasota! Rain is likely on February 22, with varying chances throughout the next two weeks. Know what's coming your way!",
  "description": "This image shows a weather forecast for Sarasota, highlighting expected rain on February 22, 2026, with a 40% to 70% chance of showers. The forecast includes a detailed 14-day rain outlook with additional chances of rain later in the week and into March. A summary table provides daily rain chances and expected conditions. A side panel lists various weather services providing localized forecasts."
}
```

    Outsourcing inventory to programmatic partners is a smart move for OpenAI but highlights their early stage in building an ads business.

    For Google advertisers, the shift to AI Mode need not be alarming. I’m watching for the ways these LLM sessions are shaping user experiences and ad placements.

    One thing is for sure; the enhancements in AI Mode continue, promising more seamless and user-friendly interactions. The potential for ads remains, though their form is still evolving.

    Monitoring key areas like the extent of monetization, advertiser control, and campaign types becomes more important as we navigate this new landscape.

    Ultimately, the future of advertising in AI-driven search is one of adaptability and strategic planning, aligning closely with user and advertiser behaviors in this exciting yet challenging era.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Master Google Ads Audits: Navigate the Changes in 2026

    Master Google Ads Audits: Navigate the Changes in 2026

    I recently tuned into an episode of Google’s Ads Decoded podcast where Brandon Ervin, Director of Product Management for Google Search Ads, shared insights on campaign consolidation, AI Max, and the future of advertiser control as we approach 2026. It was enlightening to hear a product team so in tune with advertiser concerns.

    However, I felt the podcast left some gaps. There’s a significant disconnect between Google’s narrative and what advertisers truly experience on the ground. While Ervin’s team is making strides, the fast-evolving platform presents new challenges, shifting performance measurement onto economic standards. This change fundamentally alters how we should approach search ad audits.

    As I reflect on recent improvements, it’s clear that enhancements like brand exclusions in Performance Max and Demand Gen, exclusion of site visitors in PMax campaigns, and improved search term visibility are crucial. These are responses to issues caused by bundling and aggressive automation. It’s worth noting that these controls arrived after advertisers were already knee-deep in implementation.

    In an era where Google’s product team pushes for advancement, it’s vital for us to audit whether these new tools genuinely expand control or simply restore baseline transparency lost with earlier automation efforts.

    In building the foundation for a 2026 search audit, we need to start with the basics, ensuring full ad extensions, strategic automated bidding, and maintaining negative keyword lists, among others. These are undeniable essentials that set the stage for deeper audits.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    Focusing on the intricacies of signal architecture, I realize that while traditional controls like exact match and manual bids gave us direct oversight, the new controls shift focus to data quality, density, and selectivity. These influence the algorithm, which ultimately makes the decisions.

    An effective audit in this context addresses three core aspects: the quality of the data imported, the density of high-quality data available for modeling, and the selectivity of the data shared with Google. These elements are pivotal in shaping campaign success.

    Being mindful of incrementality is another key consideration. Google optimizes towards reported conversions, often encompassing brand search and retargeting signals that may not truly reflect incremental gains.

    It’s critical to analyze marginal returns as Google’s system operates on a blended cost-per-action model. Without understanding the incremental cost at each spend tier, advertisers risk overspending without realizing diminishing returns.

    ```json
{
  "alt": "Sales funnel process from meaningful engagement to a closed-won deal, highlighting stages and predictions.",
  "caption": "Navigating the sales funnel: From initial engagement to securing the deal, each stage plays a critical role in success.",
  "description": "This image illustrates a sales funnel process, moving from meaningful engagement with high-quality non-conversion activity to a closed-won deal with revenue booked. It highlights stages such as Lead, Strong Lead, MQL, SQL, OPP, culminating in WON. The funnel emphasizes prediction and density levels, with notes like 'We are here' at Strong Lead and 'These are our money makers' at MQL. It provides clarity on how leads progress to sales."
}
```

    Furthermore, as Ervin acknowledged, AI-driven campaigns sometimes misalign with intended targets. Query mapping has deteriorated over time, and AI Max exacerbates irrelevant matches, underlining the need to rigorously classify queries by intent to maintain high-value engagements.

    Lastly, the economics of network performance in bundled campaigns like Performance Max and Demand Gen need thorough examination as they obscure valuable insight into actual network-driven outcomes.

    By focusing on value redistribution through audits, we can ensure that the surplus value generated by high-intent searches isn’t misallocated into Google’s weaker inventory, thereby optimizing ad spend efficiency and accountability.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Get Ready for ChatGPT Ads: A New Era in Demand Capture

    Get Ready for ChatGPT Ads: A New Era in Demand Capture

    I’ve been keeping an eye on the latest developments in AI advertising, and it’s time to prepare for something big: ChatGPT ads are on the horizon. As consumers shift towards shopping through AI prompts, ChatGPT could potentially rival search as a powerful demand-capture channel, leading to a redirection of ad budgets.

    Recently, OpenAI began testing ads in ChatGPT for a limited group of U.S. users, clearly marking these placements as sponsored content. Based on the platform’s internal dynamics, it won’t be long before this feature becomes widely available.

    As advertisers, we have a unique opportunity to tap into a fresh demand-capture channel. However, it’s crucial to approach this space with clear expectations and understanding.

    For ChatGPT advertising to truly succeed, consumer behaviors will need to evolve. And even if they do, remember that ChatGPT won’t expand the market but rather, redistribute it.

    Why ChatGPT is Embracing Ads

    It’s no shock that ChatGPT is moving towards advertising. Running an LLM query is estimated to be ten times the cost of a simple search query. With users generating 2.5 billion prompts daily, expenses pile up swiftly.

    The core difference here isn’t just a model shift; it’s the data landscape. Over the years, users have fed personal information into ChatGPT, giving it insights unmatched by traditional advertising tools. The burning question is how ChatGPT will use this data to target its users effectively.

    Advertisements have traditionally relied on repetition to generate demand, whereas search meets buyers with intent. ChatGPT might forge a similar path, equipped with more user context.

    Imagine this: asking which security camera works with a certain system and receiving an informed answer and purchase link because the platform already knows about your existing setup.

    Should this happen, ChatGPT could be the first new demand-capture channel since Google’s PPC ads launched two decades ago. Yet, obstacles remain.

    Today’s AI queries largely lack buying intent, serving more informational needs. When buying happens, the conversion tracking might fall short due to users completing purchases on platforms like Amazon or Google after doing their research on ChatGPT.

    Don’t be discouraged; such challenges are surmountable. Google’s journey from a homework help tool to shopping powerhouse wasn’t overnight. Likewise, ChatGPT will need time to educate consumers about shopping through AI.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    While a brand-new demand-capture platform is exciting, have realistic expectations about its potential.

    Market Share Reality Check

    Despite the capabilities of AI, it won’t expand the advertising marketplace. ChatGPT ads won’t magically bring a wave of new consumers.

    Instead, it will capture pieces of the existing market shared by Google, Meta, and Amazon. It’s more about shifting budgets rather than expanding them.

    Competition will be fierce, particularly with Google’s AI platform, Gemini, presenting a formidable challenge. Market consolidation seems inevitable as AI races towards profitability.

    The Differentiator: Hyper-Personalization

    AI’s true edge might be in hyper-personalization. With their vast knowledge of user preferences, these platforms can deliver perfectly tailored recommendations.

    This feature could make AI incomparable, offering personalized results seamlessly. However, this comes with risk, as hyper-personalization might feel invasive to some users.

    If AI can maintain trust and avoid crossing privacy boundaries, its personalized convenience will likely be favored by most.

    Steps to Take Now

    While widespread ChatGPT advertising is still on the horizon, preparation is key. Here’s how to get ahead:

    • Align on Measurement: Consider research-heavy metrics and assisted conversions.
    • Optimize Mobile UX: Ensure a smooth, fast purchasing experience to avoid loss in demand capture.
    • Plan Early Tests: Testing carries risks but can provide an early competitive edge.

    Being strategic now will set the stage for success when ChatGPT advertising becomes fully operational.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • ChatGPT Ad Rollout: A Practical Readiness Plan for Marketers

    ChatGPT Ad Rollout: A Practical Readiness Plan for Marketers

    If you are deciding whether to reserve budget for ChatGPT ads, do not start with a media plan. Start by separating the small amount that is known from the much larger set of assumptions now forming around the channel.

    The rollout is real, early, and deliberately iterative. Your advantage will not come from treating every unknown as an opportunity. It will come from being ready to evaluate access, economics, measurement, privacy, and organic AI visibility without confusing one with another.

    Start with the rollout’s actual boundary

    A small group of users stands inside an illuminated test zone around a generic chat interface, while a larger digital environment remains outside the boundary.

    OpenAI has begun implementing ads for U.S. users on ChatGPT’s free and Go tiers. That is a meaningful product change, but it is not the same as a global, all-tier advertising launch. Keep that distinction intact in forecasts, presentations, and client conversations.

    OpenAI has described the rollout as iterative, with user trust and privacy central to its approach. Treat that as the company’s stated direction, not proof that every eventual format, targeting method, or data practice will meet your requirements. Those details must be evaluated when actual campaign terms become available.

    The most important strategic distinction is between three different assets:

    • Paid exposure: inventory purchased under campaign terms, with delivery and billing controlled by the advertising system.
    • Earned AI visibility: mentions, citations, recommendations, or inclusion in an answer that you did not buy.
    • Owned conversion experience: the product page, landing page, form, checkout, or other destination where the user can act.

    ChatGPT advertising does not, by itself, establish that buying an ad changes what the model says in its answer. It also does not establish that strong organic visibility will produce paid access or preferential pricing. Until campaign documentation demonstrates an interaction, manage paid ChatGPT inventory and organic AI visibility as separate systems.

    That separation should appear in your language as well as your reporting. Use “ChatGPT ads” for paid placements. Use “ChatGPT visibility” for unpaid appearances in answers. Use “ChatGPT referral traffic” only for visits you can identify. A single label such as “AI performance” hides the very differences you will need to make budget decisions.

    Treat the early economics as an entry gate, not a benchmark

    Early reports put pricing at up to $60 CPM, with commitments beginning at about $200,000. CPM means cost per thousand impressions. These figures tell you that early participation may require a substantial test budget; they do not give you a universal rate card, expected return, available audience, or final buying model.

    If a $200,000 buy were billed entirely at exactly $60 CPM, the simple calculation would produce roughly 3.33 million billed impressions. That is a scenario, not a forecast. “Up to” and “about” are material qualifiers, and impressions alone do not reveal unique reach, frequency, attention, qualified visits, conversions, or incrementality.

    Do not turn those two reported numbers into a business case. Ask for the actual proposal and resolve what the commitment covers: media only or a larger package, guaranteed or estimated delivery, targeting controls, placement definitions, reporting access, cancellation rights, invalid-traffic treatment, and remedies for underdelivery. If those terms are unavailable, waiting is safer than committing money on the strength of a headline CPM.

    Access also appears selective. Shopify is enabling merchants to participate through Shop Campaigns, while Target and Adobe are among the early testers. If you use Shopify, verify access in your own account or through your account representative. Do not assume that being a Shopify merchant automatically makes you eligible, or that early commerce access describes the eventual program for every advertiser.

    Decision questionA pilot may be justified whenWait when
    AccessYour eligibility, inventory, geography, tier, and buying route are confirmed in writing.Your plan depends on press coverage or an assumed self-service launch.
    Learning valueThe test will answer a decision that affects your future media, search, or commerce strategy.The main rationale is simply to be early.
    MeasurementYou can isolate the destination, traffic, conversion event, and campaign cost.Paid visits will be blended with organic AI, direct, or other referral traffic.
    EconomicsThe full commitment fits an experimental budget even if the test does not produce an efficient return.The spend must deliver immediate efficiency to be financially acceptable.
    GovernancePrivacy, data use, ad disclosure, brand suitability, and contract terms have named reviewers.Those questions will be handled only after the campaign starts.

    An early pilot is most defensible when the learning itself has value and the possible loss is affordable. It is much harder to justify when the team needs a mature channel’s predictability from an iterative product.

    Build the measurement contract before the media contract

    Analysts connect a blank conversational ad panel to privacy, conversion, and reporting checkpoints while a separate organic discovery path leads toward the same outcome.

    A new advertising surface creates a familiar attribution problem: delivery is easy to count, while business impact is easy to overstate. Prevent that by agreeing internally on what evidence will count before anyone sees a favorable dashboard.

    1. Write one falsifiable hypothesis. Use the form: “Exposure through this placement will increase a named business event for a defined audience compared with our documented baseline.” Avoid goals such as awareness or learning unless you also define how they will be observed.
    2. Name the primary outcome. Choose the event closest to business value that the campaign can credibly influence, such as a qualified lead, completed purchase, activated account, or another verified conversion. Impressions are a delivery measure, not the final outcome.
    3. Isolate the destination. Use a dedicated landing path, campaign parameters, and separate campaign naming wherever the platform permits. Preserve the original referrer and campaign data through redirects, analytics, customer relationship management, and checkout systems.
    4. Capture the pre-campaign baseline. Record the same business metric before the pilot. Also preserve a controlled set of relevant ChatGPT prompts so you can see whether unpaid visibility changes independently of the advertising campaign.
    5. Set guardrails. Define the maximum acceptable acquisition cost, minimum data quality, prohibited adjacency, privacy requirements, and landing-page conditions before launch. A result that violates a guardrail is not a successful test because its headline metric looks good.
    6. Write a stop rule. Specify who can pause spend and what triggers that decision, such as unusable reporting, incorrect destinations, brand-suitability problems, privacy concerns, or spending that cannot be reconciled with delivery.

    Your vendor questions should be equally concrete:

    • What exactly counts as an impression, and how is viewability or equivalent exposure defined?
    • Where can an ad appear relative to the user’s prompt and the generated answer?
    • How is the paid placement disclosed to the user?
    • Which geography, account tier, device, language, and context controls are available?
    • What reporting can be exported, and at what level of aggregation?
    • Which conversion methods are supported, and what attribution window or model is used?
    • What user or conversation data is exposed to the advertiser, retained, or used for targeting?
    • How are invalid traffic, underdelivery, billing disputes, and makegoods handled?
    • Can creative, destination, or campaign settings be changed during the test without resetting measurement?

    A platform may not answer every question during an early rollout. That is useful information. Reduce the test’s scope, change the success criteria, or wait; do not silently fill reporting gaps with assumptions.

    Protect organic AI visibility from paid-channel attribution

    Marketers working on AEO, GEO, structured data, and AI search have a second job: keep the ad experiment from contaminating the organic program. A paid impression can create awareness and a later search. An organic answer can send a referral visit. A user can also see both. Your reporting should acknowledge those paths without assigning causality you cannot demonstrate.

    Maintain two scorecards. The paid scorecard can contain spend, billed impressions, clicks or visits when available, conversion events, acquisition cost, and evidence of incremental lift. The organic scorecard can track whether the brand appears in controlled prompts, what claims are made, which destinations or citations appear, whether the answer is accurate, and whether identifiable referral traffic follows.

    Use controlled, synthetic prompts for monitoring rather than collecting private customer conversations. For every observation, record the date, market, ChatGPT tier, exact prompt, whether an ad was present, how the placement was labeled, the advertiser and destination, and the separate contents of the unpaid answer. The tier and market matter because the known rollout is scoped to U.S. free and Go users.

    Before a campaign begins, save a baseline from the same controlled prompt set. During the campaign, preserve creative and landing-page versions alongside the observation log. Afterward, compare paid delivery and business outcomes with the organic record. Do not claim that advertising improved model mentions, citations, or recommendations unless a designed experiment supports that causal conclusion.

    Your organic work should continue on its own merits: publish accurate, directly answerable information; make brand and product entities unambiguous; keep commercial details current; show ownership and editorial responsibility; and use structured data that faithfully represents visible page content. Schema can help machines interpret a page, but it is not an ad-access switch and should not be altered merely to imitate an unconfirmed advertising requirement.

    Commerce teams should audit the owned destination before pursuing inventory. Verify that catalog information, price, availability, policy language, product claims, and checkout behavior agree. An ad can accelerate discovery, but it also accelerates the consequences of inconsistent merchant data.

    Key takeaways

    • The confirmed rollout is limited in scope: ads are being implemented for U.S. users on ChatGPT’s free and Go tiers.
    • OpenAI is treating the program as iterative, so early formats, access rules, and economics should not be mistaken for a finished market.
    • Paid ChatGPT exposure and organic ChatGPT visibility are different systems. Budget, track, and describe them separately.
    • Reported pricing of up to $60 CPM and commitments beginning around $200,000 are qualification signals, not performance benchmarks.
    • Shopify’s Shop Campaigns route and the participation of early testers show that access is developing, not that every advertiser has an open buying path.
    • The right preparation is a measurement and governance plan that can survive incomplete platform data.

    Your next move is a one-page readiness brief. Give it an eligibility owner, campaign hypothesis, audience, destination, baseline, primary business event, guardrails, stop rule, privacy reviewer, and list of unanswered vendor questions. If your team cannot complete those fields without guessing, do not reserve budget yet. If it can, you will be able to evaluate an invitation quickly without mistaking paid reach for earned AI authority.

    References