Tag: AEO

  • Answer Engine Optimization Tools: A Practical Buyer’s Guide

    Answer Engine Optimization Tools: A Practical Buyer’s Guide

    You are not choosing an AEO tool to make a visibility chart go up. You are choosing it to answer a business question: where does an answer engine fail to mention, cite, or describe your brand correctly, and what should your team change next?

    That distinction matters because similar-looking platforms can serve very different purposes. One may monitor answers well but offer little help fixing the underlying content. Another may generate recommendations but provide weak evidence that those changes affect the prompts your customers use. The right choice starts with the decision you need to make, not the longest feature list.

    Decide which AEO job you are actually buying

    AEO is now sold through specialized software, tools, and platforms, but the category label hides several distinct jobs. Most teams need a combination of them, yet one should be the primary reason for buying.

    • Visibility monitoring: Track whether selected answer engines mention your brand for a controlled set of prompts, how that presence changes, and which competitors appear instead.
    • Citation intelligence: Identify the domains and pages used as supporting sources, then find where your site is cited, omitted, or displaced by a third party.
    • Content and technical optimization: Turn answer-level findings into page-level work, such as clarifying an answer, strengthening supporting evidence, correcting entity information, improving internal connections, or fixing inaccurate structured data.
    • Reporting and operations: Give marketers, subject-matter experts, executives, agencies, or clients a repeatable workflow for reviewing findings, assigning work, and documenting outcomes.

    A tool can perform more than one job. The problem begins when you assume that strength in one proves strength in the others. A broad visibility score does not automatically explain why a competitor was cited. A content recommendation does not prove that an answer engine saw or used the revised page. An attractive executive dashboard may still leave the content team without a URL to edit.

    Primary jobMinimum evidence to demandDecision it should support
    Visibility monitoringExact prompts, named answer surfaces, captured answers, dates, and historical comparisonsWhere the brand is absent, present, or represented inaccurately
    Citation intelligenceCited domains and URLs connected to the answers and prompts in which they appearedWhich pages, publishers, or evidence types influence the answer
    OptimizationAffected page, specific issue, recommendation, rationale, and a way to verify the changeWhat the content or technical team should change next
    OperationsOwnership, annotations, exports, permissions, saved views, and durable historyWho acts, how progress is reviewed, and what can be reported

    Before attending a demo, complete this sentence: We need to identify or decide ___ so that ___ can take ___ action in their normal workflow. If you cannot fill in all three blanks, you are still shopping for a category rather than solving a problem.

    Demand prompt-level evidence, not one visibility score
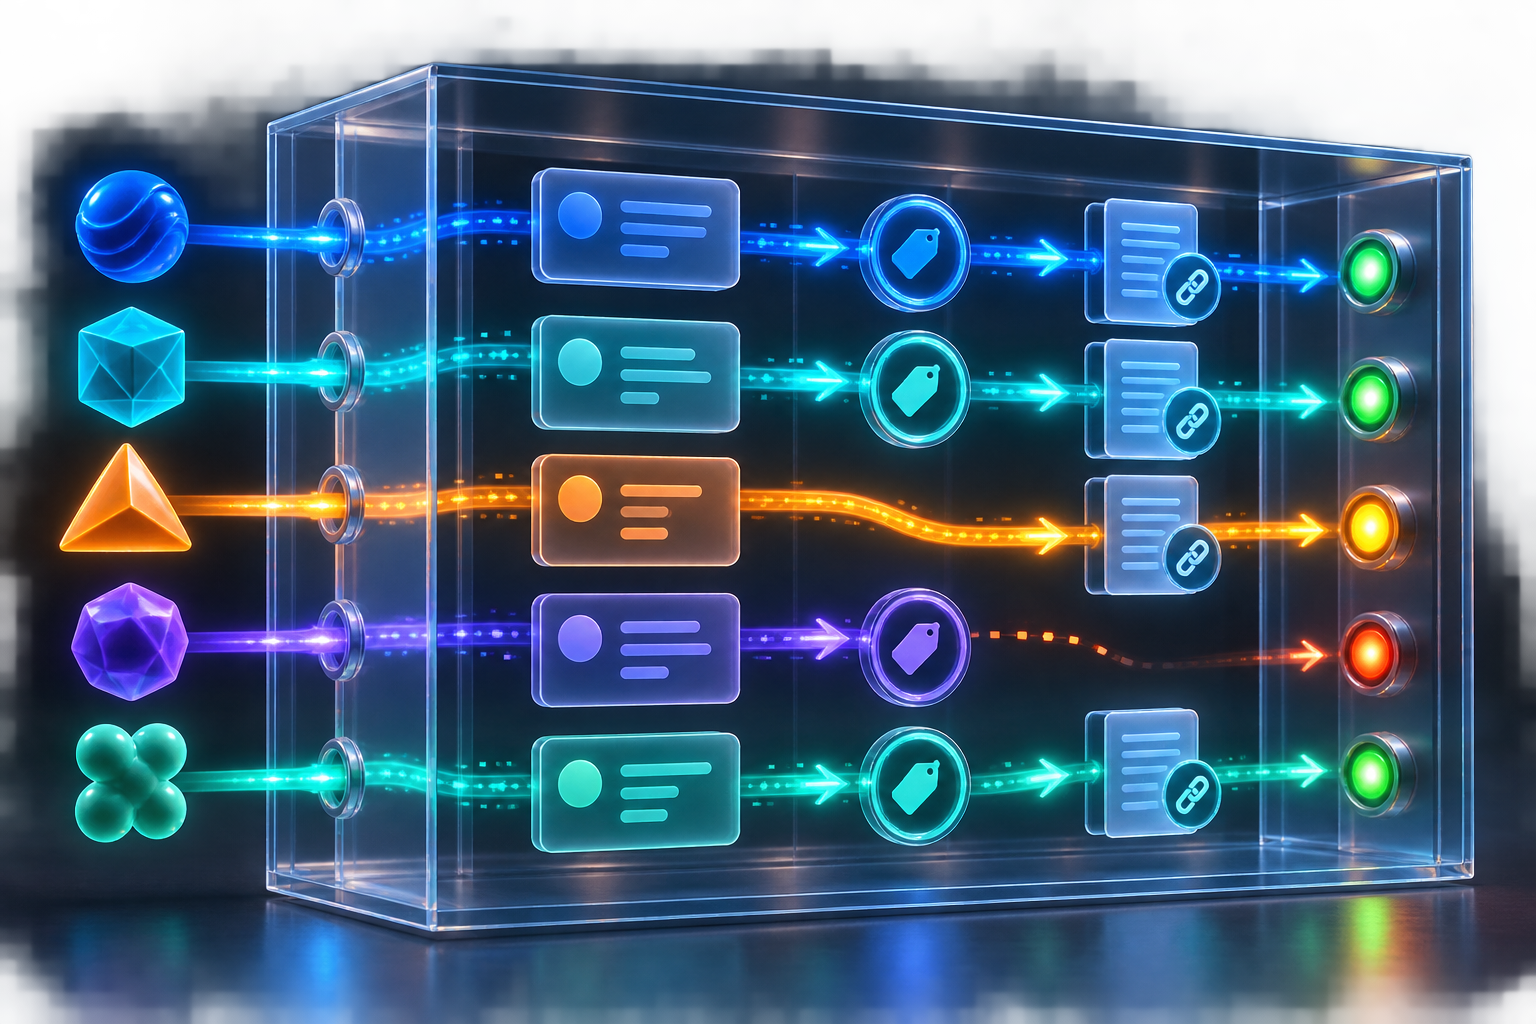
    Abstract prompt tokens follow separate paths through answer panels, brand indicators, and source documents, with two paths visibly missing evidence.

    Answer engines do not behave like a conventional rank tracker. The wording of a prompt, its context, the product surface, location, language, account state, and collection time can all affect what appears. Generated answers can also vary between runs. A score that compresses this complexity may be useful for reporting, but it should never be the only evidence available.

    Treat every observation as a record you can inspect. At minimum, a useful record should preserve:

    • The exact prompt, not merely a shortened topic label.
    • The answer engine or product surface that was checked.
    • The captured answer or enough underlying evidence to verify the result.
    • Whether the brand appeared and how it was described.
    • Any cited domain and destination URL the tool could identify.
    • The competing brands or entities included in the same answer.
    • The collection date and the relevant market, language, or device context when supported.
    • The previous observation, so changes can be distinguished from a newly added prompt.

    Keep different outcomes separate

    A mention, a citation, and a recommendation are not interchangeable. Your tool should let you inspect each outcome independently:

    • Mention: Your brand or product appears in the answer. This proves inclusion, not endorsement.
    • Citation: Your domain or page appears as supporting evidence. This does not by itself prove that a user visited the page.
    • Framing: The answer describes your brand in a particular role, category, or comparison. A visible brand can still be framed inaccurately.
    • Factual accuracy: Claims about features, availability, audience, locations, policies, or other attributes match your source of truth.
    • Business response: Referral traffic, assisted conversions, branded demand, or another downstream signal changes. Only claim this connection when your analytics and attribution setup can support it.

    If a vendor combines these outcomes into a proprietary index, ask how each component is weighted and whether you can drill into the underlying prompts. A score can prioritize investigation. It cannot replace the investigation.

    Build a prompt set that reflects real decisions

    AEO monitoring is only as relevant as the prompts being monitored. A large collection of synthetic questions can produce a busy dashboard without representing the decisions your customers make.

    Organize prompts by intent rather than mixing everything into one average:

    • Branded prompts test whether the engine describes your organization and products accurately.
    • Category prompts test whether you appear when a user is discovering possible solutions.
    • Problem prompts reveal which methods, products, or publishers are introduced before a buyer knows what category to search.
    • Comparison prompts show which alternatives are placed together and which attributes drive the comparison.
    • Validation prompts test the questions buyers ask before acting, such as suitability, limitations, compatibility, implementation, or trust.

    Source the language from places where customers already express needs: search queries, sales notes, support conversations, on-site search, community discussions, and research interviews available to your organization. Label each prompt by audience, intent, market, and owner. Keep a stable control set for trend reporting and a separate exploratory set for new questions. Do not silently rewrite an old prompt and present the result as historical change.

    Run a controlled proof of value before signing a contract
    A digital test bench compares baseline and modified content in parallel lanes as identical answer-engine orbs produce observable mention and citation signals.

    A polished demonstration tells you that the platform can present selected data. A proof of value tells you whether it can support your decisions with your prompts, competitors, markets, and workflow.

    1. Define the decision first. Name the person who will use the finding and the action available to them. Examples include updating a product page, correcting an entity description, pursuing a cited publisher, or briefing leadership on a competitive gap.
    2. Supply your own prompt set. Include prompts from different intents and areas of the buyer journey. Avoid letting the vendor choose only queries on which your brand already performs well.
    3. Configure entities carefully. Enter brand aliases, product names, domains, important competitors, and ambiguous terms. Check whether the platform can distinguish your organization from another entity with a similar name.
    4. Validate a representative sample manually. Compare the recorded prompt, answer, brand classification, citations, and URLs with the underlying answer surface. Note where the platform infers a result rather than capturing it directly.
    5. Check how variation is handled. Repeat selected prompts and inspect whether the tool preserves separate observations, replaces an earlier result, or converts variable answers into a stable-looking score. Ask what the history actually represents.
    6. Carry one finding through to action. Select a genuine visibility or accuracy problem, identify the affected page or information source, assign a change, and confirm that the platform can monitor the relevant prompt after publication.
    7. Export the evidence. Verify that the prompt, engine, observation date, answer, classification, and citation data survive outside the dashboard in a usable format. This protects your workflow if reporting needs change or the contract ends.

    Pause the purchase if the tool cannot show what sits underneath its headline metrics. Other warning signs include undisclosed collection timing, unexplained engine coverage, recommendations with no affected URL, citations without destination links, lost prompt history, or exports that contain only summary scores. These are not cosmetic omissions. They prevent your team from checking the result and deciding what to do.

    Choose the platform your team can operate every week

    Feature depth matters only when evidence reaches the person able to act on it. Evaluate workflow fit with the same care you apply to engine coverage.

    • Coverage and fidelity: Which answer surfaces, languages, locations, and device contexts are actually supported? Is the response captured directly, reconstructed, or classified after collection? How quickly does new data become available?
    • Prompt management: Can you group prompts by intent, product, market, funnel stage, and owner? Can you version a prompt set without destroying the baseline? Can you annotate campaigns, launches, content changes, or known engine updates?
    • Actionability: Does every recommendation lead to a page, template, entity, source, or outreach target? Can the owner see why the action was proposed and which prompts it may affect?
    • Integrations: Can findings enter your analytics, business-intelligence, project-management, editorial, or CMS workflow without manual transcription? If an API is important, test the endpoints and fields you need rather than accepting API access as a checkbox.
    • Governance: Look for suitable roles, workspace separation, audit history, retention controls, and exports. Agencies also need dependable client separation; larger organizations may need identity management and approval controls.
    • Reporting: Executives may need trends and business implications, while practitioners need prompt-level evidence and affected URLs. Confirm that the platform can serve both without hiding the details behind the summary.
    • Commercial fit: Normalize pricing to your planned engines, prompt groups, markets, collection cadence, users, retention, exports, and API use. A nominally generous prompt allowance may be poor value if the surfaces or markets you need are unavailable.

    Content and schema recommendations deserve particular scrutiny. Structured data can make page information more explicit when the markup accurately represents visible content, but it does not guarantee inclusion in a generated answer. A credible recommendation should identify the affected URL or template, the property or entity involved, the supporting source of truth, and the method for validating the change. Never let an automation invent ratings, prices, credentials, availability, authorship, or other factual values merely to fill a schema field.

    Apply the same standard to writing suggestions. The tool should show which question is underserved, what evidence is missing, where the answer belongs, and how success will be observed. Generic instructions to add more keywords, create longer copy, or publish a new page are not an AEO strategy. They are unverified content tasks.

    You also need a review rhythm. Assign someone to examine new gaps, someone to validate factual errors, and someone to move approved changes into the content or technical backlog. Preserve annotations around releases and major edits. Without ownership and change history, the dashboard becomes a passive report instead of an optimization system.

    Key takeaways

    • Buy an AEO tool for a named decision: monitoring visibility, understanding citations, improving content, or operating a reporting workflow.
    • Demand exact prompts, captured answers, dates, engine context, citations, and historical observations beneath every summary metric.
    • Measure mentions, citations, framing, factual accuracy, and business response separately; one does not prove another.
    • Test the platform with your own prompts, entities, competitors, and workflow before committing to it.
    • Reject recommendations that cannot identify an affected page, explain the reasoning, and provide a way to verify the result.
    • Choose the tool your team can run repeatedly, govern responsibly, and export from when its needs change.

    Start with one decision your current reporting cannot support. Build a small, representative prompt set around it, define the evidence required, and make shortlisted platforms prove that they can carry a real finding from observation to verified action. The best AEO tool for you is the one that makes the next responsible decision clear.

    References


  • How to Build Authority That Earns Citations in AI Search

    How to Build Authority That Earns Citations in AI Search

    Your brand appears in an AI answer, but the link goes to a competitor, a publisher, or nowhere at all. That is not simply a visibility problem. It means you have been recognized without becoming the evidence behind the answer.

    You can close that gap by building authority in three connected layers: a clear source of truth on your site, evidence that deserves to be cited, and independent corroboration across relevant third-party properties. The work compounds, but only when you do it in that order.

    Key takeaways

    • Separate brand mentions from citations. A mention shows recognition; a citation points users to the evidence supporting an answer.
    • Make each priority page easy to access, parse, interpret, and quote before you invest heavily in promotion.
    • Build content around the decisions and follow-up questions in real user prompts, not around content volume alone.
    • Publish evidence with clear methods, scope, ownership, limitations, and stable URLs.
    • Earn corroboration from relevant publications, podcasts, newsletters, communities, and specialist creators instead of depending entirely on claims from your own domain.
    • Measure which prompts produce mentions, which produce citations, and whether those citations point to owned or third-party pages.

    Build a source of truth AI systems can retrieve

    An organized digital knowledge cabinet connects structured documents and records to a cluster of abstract AI nodes.

    A brand mention and a citation are different outcomes. A mention places your name, product, or point of view in the answer. A citation identifies a page that supports the answer. You can earn the first because your brand is broadly associated with a subject while still losing the second because another page presents stronger, clearer, or more independently supported evidence.

    This distinction matters because third-party content already shapes a large share of AI discovery. AirOps research has put the proportion of top-of-funnel B2B brand mentions coming from third-party content at up to 85%. That figure does not establish a universal ranking rule for every model or query, but it does expose the weakness in an owned-media-only strategy.

    Your site still has a crucial job. It is the place where you control the baseline description of your company, products, services, expertise, and evidence. If that source of truth is inaccessible, vague, inconsistent, or difficult to quote, outside coverage has nothing reliable to reinforce.

    Check the three layers of citation readiness

    LayerQuestion to answerCommon failureCorrection
    AccessibilityCan a retrieval system reach and parse the important information?Essential facts are buried in confusing navigation, visual-only elements, or poorly structured copy.Use logical navigation, descriptive headings, accessible markup, visible text, and direct internal links.
    ClarityCan the system identify your entity, offering, claim, and scope?Different pages and profiles describe the brand or product in conflicting language.Standardize names, categories, descriptions, qualifications, and relationships across owned properties.
    AuthorityIs there enough evidence and corroboration to support the claim?The page makes promotional assertions without methods, expert ownership, limitations, or outside validation.Add verifiable evidence, accountable authorship, supporting context, and relevant third-party coverage.

    Technical SEO, accessibility, structured content, and user experience do most of the work in the first two layers. They also prevent a familiar mistake: trying to solve an authority problem with markup alone.

    JSON-LD can clarify what a page and its entities represent. FAQ schema can make genuine question-and-answer content more explicit. An llms.txt file may provide additional machine-facing guidance. None of them can transform an unsupported claim into trusted evidence. Treat these elements as foundational considerations within a larger SEO and AEO system, and keep every marked-up fact consistent with the visible page.

    Audit priority pages in a useful order

    1. Confirm access. Make sure a user can reach the page through logical navigation and relevant internal links. Put essential information in visible, machine-readable copy rather than relying on an image, animation, or interface interaction to communicate it.
    2. Establish identity. State the organization, product, service, category, intended audience, and relevant relationships plainly. Use the same official names and descriptions on company profiles and owned social properties.
    3. Structure the answer. Give the primary question a direct answer near the beginning. Use accurate H2 and H3 headings, lists for criteria or steps, and tables only when readers genuinely need to compare fields.
    4. Qualify important claims. State who or what a claim applies to, what evidence supports it, and where its limits sit. A precise claim is easier to reuse accurately than a sweeping marketing statement.
    5. Show ownership and maintenance. Identify a real author or subject matter expert where expertise matters. Keep material facts current and make substantive updates when the underlying information changes.
    6. Align structured data. Use schema to describe the content that is actually present. Do not mark up facts, reviews, questions, or relationships that a reader cannot verify on the page.
    7. Choose a primary destination. Avoid scattering the best explanation of one question across several weak pages. Give internal links, outreach, and repurposed content a strong URL to point back to.

    Apply this audit to more than blog posts. Product and service pages, comparison pages, company profiles, resource hubs, and high-performing older content all contribute to machine understanding. A product page, for example, should have a product-focused heading, segmented features, a clear description, meaningful comparisons, and enough context to distinguish the offering from nearby alternatives.

    Passing this audit makes a page eligible to do more work. It does not make the page authoritative by itself. Once retrieval and clarity are in place, the next question is whether the page contains anything another writer or answer system would actually need to cite.

    Turn expertise into evidence worth citing

    Publishing more pages is not an authority strategy. You need pages that resolve specific decisions, contribute verifiable evidence, and remain useful when separated from your sales copy.

    Start with prompts rather than isolated keywords. Keywords reveal recurring language and demand. Prompts reveal the full task: the user’s situation, constraints, desired outcome, comparison set, and likely follow-up questions. Combining the two gives you a better map of what an answer must cover.

    Build a prompt and evidence map

    1. Name the decision. Write down what the user is trying to choose, understand, fix, compare, or justify. Do not reduce the decision to a head term.
    2. Fan the query out. Branch the initial question into definitions, requirements, use cases, tradeoffs, alternatives, risks, implementation questions, and proof. This exposes the subquestions an AI answer may try to resolve before presenting a recommendation.
    3. Inspect existing answers. Record which organizations are mentioned, which pages are cited, what claims those pages support, and whether the cited material is owned, editorial, community-generated, or another type of third-party content.
    4. Map your current assets. Identify whether you already have a strong page for each subquestion. Mark pages that are inaccessible, outdated, duplicative, thin, or unsupported.
    5. Identify the evidence gap. Ask what a neutral writer would need before repeating your claim. The answer might be a clear method, first-party data, an expert explanation, a comparison framework, a visual, or a documented limitation.
    6. Assign a primary asset. Give each important question a stable destination with a defined owner. Supporting posts, newsletters, graphics, videos, and social content should strengthen that asset instead of competing with it.

    This is where keyword research and AI-result analysis become more useful together. A query fan-out built from prompts, keywords, cited domains, and result gaps shows both what needs to be created and where independent authority is already concentrated.

    Give every evidence page a citation unit

    A citation unit is the smallest complete passage that can support a claim without becoming misleading when quoted or summarized. It normally needs three things: the claim, the evidence behind it, and the context that limits its meaning.

    • A direct answer: Put the conclusion close to the question it resolves.
    • Defined terms: Explain specialized terms and use stable names for entities, products, metrics, and methods.
    • Visible evidence: Present the relevant data, observation, process, or expert reasoning rather than merely asserting that proof exists.
    • A method: For original analysis, explain how information was collected, filtered, classified, and interpreted. Include the real sample size and period when those details exist; never imply a larger or more current dataset than you have.
    • Scope and limitations: State where the conclusion applies, where it may not apply, and which variables could change the answer.
    • Accountable expertise: Identify the qualified person or team responsible for the material and explain the role that makes the expertise relevant.
    • A stable location: Keep the evidence at a durable URL with descriptive headings so another page can link to the exact supporting section.

    Original evidence can be especially useful because it gives other people a reason to reference your domain. That does not mean inventing a survey or dressing ordinary opinions up as data. Use appropriately governed first-party information, disclose the method, separate observation from interpretation, and publish limitations alongside the result. If you cannot support a quantitative claim, a carefully bounded expert framework is better than a decorative number.

    Create fresh assets and refresh proven ones

    Create a new asset when a valuable prompt has no adequate destination, when you possess genuinely new evidence, or when a distinct seasonal question needs its own treatment. Refresh an existing asset when it already has a useful foundation but its answer, structure, examples, data, or expert context no longer meets the question.

    A refresh is not a changed date at the top of the page. Recheck the claim, replace stale evidence, tighten the direct answer, add missing qualifications, repair internal links, and make the important passage easier to locate. Updating a strong URL preserves a coherent destination for readers and for people who may cite it.

    Then repurpose deliberately. A strong informational page can become an infographic, a newsletter section, a short-form video, or a series of focused social posts. A broad topic can become a hub with narrower spokes. This fresh-and-refreshed content model expands distribution without requiring every format to start from zero.

    Repurposing only helps authority when the claim remains consistent and each format has a clear job. Let the core page hold the full evidence. Use an infographic to clarify a process, a video to explain a difficult tradeoff, and a social post to answer one narrow follow-up. Point people to the canonical evidence instead of creating several near-duplicate pages with slightly different claims.

    Earn independent corroboration beyond your domain

    Independent research, publishing, archive, and professional workspaces direct confirming beams toward the same faceted object.

    Your owned content tells the market what you want to be known for. Independent coverage shows that someone without direct control over your messaging found the expertise useful enough to include. You need both.

    That does not mean chasing the largest possible publication for every topic. A specialist editorial site, respected niche newsletter, relevant podcast, or knowledgeable creator may be more closely aligned with the prompts you need to influence. The practical question is not whether a domain looks famous in isolation. It is whether it already informs the subject your audience asks about.

    Use cited domains to focus digital PR

    1. Build a citation inventory. Run your priority prompt set and list the domains, individual URLs, contributors, formats, and claims appearing in citations. Separate recurring topical authorities from one-off appearances.
    2. Group realistic targets. Segment relevant publications, niche blogs, podcasts, Substacks, professional communities, reviewers, and specialist creators. Prioritize topical fit and editorial usefulness.
    3. Match evidence to each target. Do not send a generic company announcement. Offer a finding, framework, dataset, expert explanation, visual, or timely angle that improves the target’s coverage of a question.
    4. Prepare the expert. Give your subject matter expert a narrow brief, defensible claims, useful caveats, and a link to the supporting asset. A concise, attributable explanation is easier to use than a promotional interview answer.
    5. Make the destination ready. Before outreach, confirm that the linked page contains the evidence, method, author information, and context promised in the pitch.
    6. Record what was earned. Track the placement, link destination, claim used, contributor, publication date, and target prompt. Note whether the result is an unlinked mention, a third-party citation, or a link to your owned evidence.

    The target list should come from the actual information environment around the topic. Publications, podcasts, specialist newsletters, niche editorial sites, and industry creators all belong in the mix. Reviews and public discussion on platforms such as Trustpilot, Reddit, and TikTok may also affect how consistently a brand and its value proposition are represented.

    Do not treat those communities as places to manufacture consensus. Repeated promotional language, scripted customer responses, or unsupported claims create noise rather than credible corroboration. The useful work is to make accurate information available, answer questions transparently, correct genuine factual inconsistencies, and let independent people retain editorial control.

    Small brands should compete on specificity

    You do not need constant Tier 1 coverage to make progress. A small brand can contribute a highly specific insight to the people already explaining its niche. Internal subject matter experts are often the most valuable starting point because they can supply the definitions, edge cases, tradeoffs, and operational detail that generic commentary lacks.

    Build outreach around one usable contribution:

    • The question or change that makes the contribution relevant.
    • The specific finding, framework, or expert insight being offered.
    • The evidence and limitations behind it.
    • The named expert who can explain it.
    • The audience that will benefit from it.
    • The stable page where the complete supporting material lives.

    This approach also works with microinfluencers and specialist creators. Give them access to accurate evidence and qualified expertise, not a script designed to make independent voices sound identical. A placement that describes your contribution honestly can strengthen corroboration even when it does not link to you. A placement that also points to the original evidence can support both authority and an owned citation path.

    Digital PR and content therefore need to share one operating plan. Content creates the asset worth referencing. Outreach puts it in front of people with relevant audiences and editorial authority. Their coverage adds third-party context. That context can lead users and retrieval systems back to the original evidence.

    Measure the authority loop, not just AI traffic

    An AI answer can influence a decision without producing an immediate visit. In that sense, AI visibility can behave more like a billboard than a conventional conversion channel. A dashboard limited to referral sessions will miss mentions, unclicked citations, third-party corroboration, and changes in how your brand is described.

    Track prompt-level evidence first. Use a fixed set of priority prompts and repeat the review on a consistent schedule. Record the platform, mode, date, and relevant market or language context because outputs can vary. A single favorable screenshot is an observation, not a trend.

    Keep a citation ledger

    • Prompt and prompt family: Preserve the exact wording and connect it to the broader decision or topic cluster.
    • Journey stage: Mark whether the prompt concerns initial education, evaluation, comparison, or implementation.
    • Brand mention: Record whether the brand appears and what claim is made about it.
    • Citation presence: Record whether the answer supplies supporting links and which statement each link appears to support.
    • Citation destination: Separate owned URLs from publications, communities, review sites, creator properties, and other third parties.
    • Competitor evidence: Note which competing entities appear, where their citations point, and what kind of asset earned the reference.
    • Message fidelity: Compare the answer with your verified source of truth. Flag outdated descriptions, missing qualifications, and claims you cannot support.
    • Next action: Assign the gap to technical optimization, content creation, content refresh, expert review, structured data, digital PR, or profile correction.

    From that ledger, calculate metrics that correspond to different failures:

    • Mention coverage: The share of tracked prompts in which your brand appears.
    • Citation coverage: The share of citation-eligible tracked prompts that cite an owned or relevant third-party page supporting your brand.
    • Owned citation share: The portion of your observed citations that lead directly to your domain.
    • Mention-to-citation gap: Prompts where you are named but no supporting citation points to your evidence or meaningful third-party corroboration.
    • Corroboration coverage: The important claims supported by at least one relevant independent property.
    • Message fidelity: The degree to which repeated descriptions match your current, substantiated positioning.
    • Business response: The actions that matter for your model, such as qualified visits to cited assets, branded demand, product exploration, inquiries, or assisted conversions.

    Do not combine these into one opaque authority score too early. Each metric diagnoses a different problem. Low mention coverage may signal weak topical association. Strong mentions with weak citations point toward an evidence or corroboration gap. Third-party citations with few owned citations may mean outside writers understand the brand but your own evidence pages are not strong enough to become destinations.

    Run the work as a compounding sequence

    1. Make the priority pages accessible and unambiguous. Repair navigation, structure, visible content, profiles, accessibility signals, and accurate schema.
    2. Publish or refresh evidence for the prompt cluster. Give the primary questions direct answers, accountable expertise, useful proof, limitations, and stable destinations.
    3. Earn relevant third-party corroboration. Use cited-domain analysis, subject matter experts, and targeted digital PR to place useful evidence in the information sources surrounding the topic.
    4. Measure the resulting mention and citation changes. Feed each observed gap back into the appropriate layer instead of responding with indiscriminate content production.

    You do not need to perfect an entire domain before beginning outreach, but you should not promote a claim before its supporting destination is ready. Work one high-value prompt cluster through the complete loop. Audit the existing citations, repair the primary page, add one defensible evidence asset, approach the most relevant independent authorities, and log what changes.

    Once that loop reliably produces clearer mentions, stronger corroboration, or better citation destinations, expand it to the next cluster. That is how AI citation authority becomes an operating system rather than another publishing campaign.

    References

  • AI Search Accuracy: Audit Citations and Brand Visibility

    AI Search Accuracy: Audit Citations and Brand Visibility

    You run an AI search, see your company named with a citation, and assume your visibility work is paying off. Or a competitor appears first, so you assume it has won. Either conclusion can be wrong when it rests on one generated answer.

    A useful AI search audit has to answer three separate questions: Is the claim correct? Does the cited page support it? Does the result persist when you repeat the search? Once you separate those questions, you can stop treating citations as proof and start measuring what users are actually likely to encounter.

    Separate answer accuracy, citation support, and repeatability

    An answer can be correct while citing the wrong page. It can also quote a page accurately even though the page itself contains an outdated or incorrect fact. A perfectly supported answer may disappear on the next run. These are different failures, and each requires a different fix.

    LayerQuestion to askWhat a failure meansWhat you should do
    Claim accuracyIs the statement factually correct?The model generated, repeated, or combined incorrect information.Find the authoritative fact and identify where the wrong version may be coming from.
    Citation supportDoes the linked page substantiate the exact statement beside it?The citation is related to the topic but does not entail the claim.Record the mismatch and improve the page that should support the claim.
    Source qualityIs the cited information current, specific, and appropriate for the claim?The answer may be grounded in weak, stale, or indirect evidence.Strengthen first-party evidence and correct external profiles you control.
    RepeatabilityDoes the claim, citation, or recommendation recur across runs?The observed result may be sampling variation rather than durable visibility.Measure occurrence rates across repeated prompts and engines.

    A citation is reliable only when the linked material materially supports the claim attached to it. Topical relevance is not enough. A page about a business does not automatically support every statement an AI answer makes about that business. Authority does not repair that mismatch either: a respected domain can still be the wrong citation for a particular sentence.

    This is why accuracy belongs at the claim level. Work involving 158,000 AI claims validated through FactCheck used individual claims as the unit of analysis rather than assigning one broad true-or-false label to an entire response. Your audit should use the same basic unit. One answer may contain several supported claims, one unsupported inference, and one factual error.

    Audit each AI answer at the claim level

    Separate claim cards are linked by green, amber, and red threads to supporting source documents as a hand inspects one connection with a magnifying lens.

    Start with the exact answer the user saw. Do not rewrite it into a cleaner version before checking it. Small qualifiers such as location, availability, price conditions, service area, or timing often determine whether a citation really supports the statement.

    1. Capture the query context. Save the precise prompt, AI product or search surface, displayed model when available, location, date, and whether the session was signed in or personalized. A later result is not comparable if those conditions changed.
    2. Split the answer into atomic claims. Turn “Company A offers emergency plumbing throughout Toronto and is open all night” into separate claims about the service, service area, and hours. A citation may support one part without supporting the others.
    3. Mark opinions separately. Statements such as “best,” “most reliable,” or “ideal for families” are conclusions, not simple facts. Identify the factual premises that would be needed to justify the conclusion.
    4. Open every cited URL. Find the passage, field, table, or listing that is supposed to support the claim. Do not give credit merely because the page mentions the same entity or topic.
    5. Score correctness and support independently. Verify whether the claim is true, then decide whether the cited page proves it. A correct claim with an unrelated citation is still a citation failure.
    6. Save a short evidence note. Record what the page supports, what it omits, and any conflicting detail. This makes later reviews possible even if the page changes.

    Use a small, explicit verdict set so different reviewers make comparable decisions:

    • Supported: The cited material clearly substantiates the entire claim, including its qualifiers.
    • Partially supported: The citation proves only part of a compound claim or leaves an important qualifier unresolved.
    • Unsupported: The page is related but contains no evidence for the claim.
    • Contradicted: The cited material states something incompatible with the answer.
    • Unverifiable: The page is unavailable, the relevant content has changed, or the claim cannot be checked from accessible evidence.

    Do not let a polished sentence hide a weak inference. If an AI answer calls a provider “the best option” because it has evening hours, the hours may be supported while the recommendation is not. Record the factual premise as supported and the superlative as unsubstantiated unless the answer supplies a defensible comparison.

    The resulting audit should preserve four separate fields: the claim, its factual verdict, its citation-support verdict, and the reason for each verdict. A single “accurate” column collapses too much information to guide a correction.

    Measure AI visibility as a distribution, not a ranking

    Many floating result panels show cobalt and coral geometric objects appearing in different positions or disappearing across repeated searches.

    Traditional rank tracking encourages you to ask where a business appeared. Generative search requires an earlier question: how often did it appear at all?

    The instability can be substantial. Across 14,472 Gemini citations from 1,487 local queries in 50 large U.S. metro areas and ten service categories, repeated identical searches produced only about 40% overlap among cited sources. Gemini selected the same top business about 7% of the time, while a Google local-pack control returned the same top listing about 90% of the time.

    Engine-to-engine agreement was even lower in that local-search sample. Gemini and ChatGPT cited the same domains in only about 8% of the compared searches and recommended the same top business 4.2% of the time. Gemini leaned heavily on business websites, while ChatGPT relied more on Reddit and business directories. Success in one engine therefore cannot stand in for visibility across AI search as a whole.

    Those percentages are not universal benchmarks. They come from a defined set of U.S. local-service searches and should not be projected onto every industry, country, prompt type, or AI product. They do establish why a screenshot from one run is weak evidence of either success or failure.

    A practical starter protocol, rather than a claim of statistical certainty, is to select ten commercially important prompts and run each one five times per engine. Keep the wording and observation conditions fixed. Treat alternative phrasings as separate prompts instead of changing the text between repetitions.

    1. Choose prompts by user decision. Include discovery, comparison, eligibility, trust, and branded-fact questions that can influence whether someone contacts or excludes you.
    2. Run a fixed batch. Capture every answer, including runs where your brand is absent and runs with no citation.
    3. Keep engines separate. Report Gemini, ChatGPT, and any other surface independently before creating an aggregate view.
    4. Repeat on a consistent cadence. Use the same batch before and after material content changes, and maintain unchanged prompts as controls.
    5. Compare rates, not anecdotes. Look for changes across the batch rather than celebrating or diagnosing one favorable result.

    Calculate at least four rates:

    • Mention rate: Runs that mention your entity divided by all runs for that prompt and engine.
    • Citation rate: Runs that cite your domain divided by all runs.
    • Recommendation rate: Runs that recommend your entity, with a separate field for first or primary recommendation.
    • Supported-citation rate: Audited citation occurrences that fully support the attached claim divided by all audited citation occurrences.

    Do not report “average rank” without a written rule for absent brands, unordered lists, and narrative recommendations. In many generated answers, numerical position implies a precision the interface does not provide. Mention and recommendation rates are usually easier to interpret.

    This approach also prevents you from mistaking normal variation for the effect of an optimization change. If visibility rises from one run to the next while unchanged control prompts move just as much, you do not yet have convincing evidence that your edit caused the difference.

    Build pages that can support the claims you want cited

    Your own website is not merely a conversion destination. It can be the evidence layer behind an AI answer. In the defined Gemini local-search sample, nearly 60% of citations led directly to business websites, more than the combined share for directories, review platforms, and forums. Reddit was the second-largest category at 13.7%.

    That does not mean publishing a page guarantees selection. It means you should give an AI system a clear, defensible first-party page to cite when it needs to verify a claim about you.

    Create a claim-to-page map

    List the claims that matter in a buying decision, then assign one canonical page to substantiate each one. Typical groups include services offered, locations served, eligibility or customer fit, operating hours, pricing conditions, product capabilities, policies, credentials, and named people responsible for the work.

    For every claim, ask:

    • Is the answer stated directly in visible page copy?
    • Does the page identify the exact company, product, service, and location involved?
    • Are conditions and exclusions placed beside the claim rather than hidden elsewhere?
    • Does the page contain evidence appropriate to the statement?
    • Is there a clear owner responsible for keeping the fact current?
    • Does the page use a stable canonical URL that can remain valid when the content is updated?

    A vague marketing page forces the answer engine to infer. A factual page reduces the number of inferences it has to make. Replace “solutions for every need” with explicit services, intended users, locations, and constraints. If availability depends on location or plan level, state that condition in the same passage.

    Make JSON-LD agree with the visible evidence

    Treat structured data as a machine-readable map of facts that a person can also verify on the page. For a local organization, use the most specific applicable Organization or LocalBusiness type and populate relevant properties such as name, URL, telephone, address, opening hours, and service area only when the page substantiates them.

    Do not use JSON-LD to introduce claims the visible content cannot support. If the markup says a location is open all night but the location page lists limited hours, you have created ambiguity rather than authority. The same rule applies to ratings, prices, service areas, authors, dates, and product availability.

    Check consistency across the page title, headings, body copy, structured data, internal links, and canonical URL. Schema cannot rescue a fact that is vague, contradictory, or attached to the wrong entity.

    Audit external descriptions without manufacturing consensus

    Your website may dominate citations in one engine while community discussions and directories carry more weight in another. Search for your brand, products, locations, and key claims across the pages that already appear in AI answers. Flag incorrect hours, old service descriptions, duplicate listings, former locations, and unsupported reputation claims.

    Correct profiles and listings you legitimately control. Where a third-party page has a documented correction process, submit accurate evidence. Do not create fake reviews, staged forum discussions, or undisclosed endorsements to imitate independent agreement. Apart from the ethical problem, manufactured material gives answer engines more low-quality claims to misread and repeat.

    When an inaccurate AI claim recurs, trace the wording across cited and uncited pages. If several pages repeat the same obsolete fact, updating only your homepage may not resolve the conflict. Record which representations you control, which have correction channels, and which must simply be monitored.

    Key takeaways

    • A correct answer can still have an unreliable citation, so score factual accuracy and citation support separately.
    • Audit atomic claims, not entire responses. Compound sentences often mix supported facts with unsupported conclusions.
    • One AI result is an observation, not a visibility trend. Repeat identical prompts and report occurrence rates by engine.
    • Do not assume visibility transfers between Gemini, ChatGPT, or other AI search surfaces; their source preferences and recommendations can differ sharply.
    • Publish canonical factual pages, align their visible content with JSON-LD, and correct external descriptions you legitimately control.
    • Judge optimization work by changes across a fixed prompt set, not by a favorable screenshot.

    On your next monitoring pass, keep the first batch deliberately small: ten decision-stage prompts, five identical runs per engine, and a claim-level review of every citation. That baseline will show whether your immediate problem is inaccurate information, weak evidence, unstable visibility, or a combination of all three. Fix the diagnosed layer, then rerun the same batch before expanding the program.

    References


  • Off-Page SEO Beyond Followed Links: A Practical Strategy

    Off-Page SEO Beyond Followed Links: A Practical Strategy

    Your PR placement named your brand but did not include a followed link. Your monthly report may call that a miss. That is the wrong diagnosis.

    Followed backlinks still matter, especially when a commercial page needs authority. But off-page SEO now has a broader job: make your brand visible, credible and closely associated with the topics on which you want search engines and AI systems to recognize it. That requires a coordinated mix of direct link building, linkable assets, digital PR and mention reclamation.

    Key takeaways for off-page SEO

    • Use direct link building when a landing page or bottom-of-funnel resource needs a relevant backlink. It gives you more control over the destination and, subject to editorial approval, the surrounding context.
    • Count relevant unlinked brand mentions and nofollow citations as real outcomes. They can build topical visibility, create discovery paths and become candidates for later link reclamation.
    • Create useful assets that writers can cite without being asked, but reserve journalist outreach for assets with a genuine story rather than ordinary utility.
    • Judge link building, linkable assets and digital PR by different primary outcomes. A single followed-link target will misrepresent the work.
    • Track links and mentions together. Evidence connects both link quality and brand mentions with AI-search visibility, although correlation does not establish that either one caused a particular answer.

    Give each off-page tactic the right job

    A followed link answers a narrow reporting question: did another page create a crawlable connection to yours under the expected link attributes? It does not tell you whether an authoritative publication discussed your brand in the right context, whether an asset became a standard reference or whether your name is becoming associated with a valuable subject.

    That does not make backlinks obsolete. They have long been a confirmed part of Google’s ranking systems, and the quality of a site’s link profile has shown a strong correlation with AI-search visibility. The practical change is to stop forcing every off-page activity into a followed-link KPI.

    ApproachWhat you ask forBest primary jobEvidence of progress
    Direct link buildingA link, link correction or linked attributionSupport a specific commercial or bottom-of-funnel pageA relevant editorial link to the intended destination
    Linkable assetsUsually nothing after distributionBecome a reusable reference for writers and publishersNew citations and referring domains acquired naturally
    Digital PRConsideration of a newsworthy storyEarn relevant coverage and strengthen brand-topic associationQualified coverage, accurate mentions and any resulting links
    Mention reclamationAdd or correct a useful linkTurn existing recognition into a better citationAn unlinked or incomplete mention becomes a relevant linked reference

    Direct link building is the strongest choice when the destination matters. Because you are explicitly requesting a link, it has the highest probability of supporting landing pages and converting bottom-of-funnel content. Guest contributions can also give you some influence over context and anchor text, provided the publisher approves them editorially.

    Apply a strict quality screen before making that request. The publisher should cover the relevant subject, the link should help a reader understand or complete something, and the destination should fulfill the promise made by the surrounding text. Site-level authority scores and estimated traffic can inform the review, but neither rescues an irrelevant placement.

    Do not solve the scaling problem by buying placements or arranging excessive exchanges. Those practices conflict with Google’s link-spam policies. An outreach system that produces fewer editorially defensible links is safer and more useful than a high-volume system built around placements that can be ignored, devalued or removed.

    Linkable assets serve a different need. Free tools, industry lists, templates, checklists and current statistics pages give writers something useful to reference. They can earn links after becoming discoverable through search, email, social distribution or existing audience channels. If an asset is not visible anywhere, its usefulness alone will not create discovery.

    Match the format to the intended route. A calculator or template may attract citations steadily, but ordinary utility is rarely a compelling media story. A collection of third-party statistics can become a convenient reference in search, yet it is weak PR material because the underlying data is not yours. Use that kind of page as a durable citation asset; do not pitch it as exclusive research.

    Digital PR begins with the story. You ask an editor or journalist to consider something timely, consequential or genuinely revealing, not to satisfy a link quota. A relevant mention in respected coverage may be more strategically valuable than an unrelated followed link, even when the publisher leaves the mention unlinked or applies a nofollow attribute.

    Build a flywheel instead of running isolated campaigns

    A circular mechanism connects content creation, editorial coverage, relevant linking, and audience attention in a continuous loop.

    The strongest off-page programs let each approach create opportunities for the others. Treating PR, content and outreach as separate queues throws away much of that compounding value.

    1. Choose a narrow authority territory. Define the problem, category or decision for which your brand should be recognized. A broad ambition such as owning marketing is not actionable; a bounded subject gives content creators, outreach specialists and PR teams the same target.
    2. Map the destination pages. Identify the commercial page that needs support, the bottom-of-funnel resource that answers buying questions and the informational asset other writers could reasonably cite. Do not expect one URL to perform every role.
    3. Publish the reusable reference. Build the tool, template, checklist, list or statistics page around a recurring research need. Make its methodology, ownership, update status and intended use clear enough that a writer can assess it quickly.
    4. Seed discovery carefully. Initial guest contributions or broken-link outreach can help a new asset earn its first relevant links and improve its chance of being found. Existing email, social and community distribution can expose it without turning every interaction into a link request.
    5. Pitch the story when a story exists. If the asset contains original findings or supports a timely development, lead with what changed and why the publication’s audience should care. The asset provides evidence; the request is for editorial consideration.
    6. Reclaim the strongest coverage. Review accurate unlinked mentions, nofollow citations and references pointing to an inferior destination. Ask for a link only when it improves the reader’s path to evidence, a tool or a fuller explanation.
    7. Maintain what keeps earning attention. Links decay, lists become stale, statistics age and tools break. Refresh assets that continue attracting citations, and record lost links so you can distinguish normal decay from a correctable problem.

    This sequence also prevents a common targeting mistake. Commercial URLs usually need deliberate link outreach because publishers rarely cite sales pages spontaneously. Reference assets can earn links naturally, while PR can expand the number and quality of people who discover them. Coverage then supplies a qualified pool of mentions for selective reclamation.

    Measure links, mentions and visibility without mixing them up

    An analyst sorts link, conversation, and visibility symbols into three separate trays on a desk.

    Your scorecard should preserve the distinction between outputs and outcomes. A media mention, a followed link and an AI citation are different observations. Combining them into a single authority number makes a neat dashboard but hides what is actually working.

    Measurement areaRecordQuestion it answers
    Editorial linksDestination, linking page, topical context, anchor, link attribute and live statusDid we earn a defensible link that supports the intended page?
    Brand coveragePublication, topic, linked or unlinked status, mention accuracy and prominenceAre relevant publishers associating the brand with the intended subject?
    Linkable assetsPages citing the asset, discovery channel, repeat citations and update needsIs the asset becoming a reusable reference rather than relying on repeated asks?
    Search and AI visibilityQueries or prompts checked, engine or model, date, brand inclusion and cited pagesIs visibility changing across a consistent observation set?
    Business responseReferral activity where available, assisted journeys, qualified inquiries and relevant branded demandDid off-page exposure contribute to discovery or consideration?
    DurabilityLive, changed, lost and reclaimed links or mentionsHow much earned visibility remains intact?

    The AI-search row needs particular care. One analysis found that AI Overview visibility had a correlation of 0.664 with brand mentions and 0.218 with backlinks. That is a strong reason to monitor mentions alongside links. It is not proof that placing a mention will cause an AI system to include your brand, nor does it establish that backlinks are unimportant.

    Use a stable set of commercially relevant prompts when observing AI visibility. Record the model or search experience, the date, whether the brand appeared, what claim surrounded it and which pages were cited. Repeating the same observation method is more informative than collecting isolated screenshots of favorable answers.

    Keep tactic-level evaluation equally disciplined. Judge direct outreach by the quality and destination of the links it earns. Judge a reference asset by whether independent pages keep citing it. Judge PR by the relevance, accuracy and reach of its coverage, with links recorded as an additional result. Then review how those outputs relate to search visibility, referral activity and buying journeys without claiming causation you cannot demonstrate.

    Choose your next move from the constraint you actually have

    You do not need to launch every tactic at once. Start with the gap that is preventing useful off-page recognition:

    • Your commercial page has little authority: use selective direct outreach, guest contributions or relevant link reclamation. Make the reader benefit of the destination explicit.
    • Writers discuss the topic but have nothing from you to cite: create a durable tool, template, checklist, list or statistics resource that satisfies a recurring reference need.
    • You have an original and timely finding: develop a clear story and use digital PR. Pitch the finding and its consequence, not the desire for a backlink.
    • Your brand already appears in relevant coverage: review the mentions for accuracy, destination quality and link status. Reclaim only the cases where a link would materially improve the citation.
    • Your old assets once earned links but have slowed down: check freshness, broken functionality, changed URLs and lost citations before producing another asset on the same subject.
    • Your reporting shows links but cannot explain authority growth: add separate views for relevant mentions, asset citations, AI visibility observations and link durability.

    For your next campaign, decide in advance whether its primary job is to support a destination page, become a reference or earn a story. Record followed links, nofollow citations and unlinked mentions separately. That small change gives every off-page result a fair test while keeping the link equity your important pages still need in view.

    References


  • AI Search Optimization Strategy: A Practical Framework

    AI Search Optimization Strategy: A Practical Framework

    You can rank well in Google and still disappear when someone asks an AI assistant which vendor, product, or approach fits their situation. Publishing more AI-written pages rarely closes that gap. Your business has to be easy to find, easy to understand, and easy to verify.

    A workable AI search optimization strategy connects traditional SEO, answer-ready content, and independent authority signals. It also gives you a repeatable way to diagnose why you are missing from an answer, so each change addresses an identifiable problem.

    Optimize for the whole recommendation path

    An isometric network guides several candidate solutions through evidence and validation gates toward one highlighted recommendation.

    AI visibility is often treated as a content-formatting exercise. Formatting matters, but it is only one part of the path from a user’s question to a recommendation. Your strategy has to perform three jobs:

    • Retrieval: Make the right pages and third-party mentions discoverable for the language your buyers use.
    • Extraction: State your category, specialization, evidence, and limitations clearly enough that a system can reuse them without guessing.
    • Corroboration: Support important claims with reviews, comparison pages, awards, accreditations, affiliations, directories, and customer evidence outside your own website.

    Traditional rankings contribute directly to retrieval. Pages holding the top three to five organic positions were almost always read first in live-search testing, while pages in positions six through twenty were more likely to be consulted when the leading results lacked the necessary detail. Unindexed pages were effectively unavailable unless a system received a direct route to them. These are test-derived observations rather than permanent platform rules, but they give you a sensible order of operations: fix discoverability before trying to optimize how an invisible page is quoted.

    External recommendation pages deserve equal attention. Estimated weights for authoritative list mentions reached 41% for ChatGPT, 49% for Google AI Overviews and Gemini, and 38% for Claude in one 2026 weighting model. Those percentages are not official algorithm disclosures, and they should not be treated as literal shares of a platform’s ranking formula. They are useful as directional evidence that prominent, relevant comparison pages can matter more than another unsupported claim on your own site.

    This gives you a simple diagnostic:

    • If your pages and credible mentions cannot be found for the query, you have a retrieval problem.
    • If your page is cited but the answer omits or misstates your differentiator, you have an extraction problem.
    • If competitors are recommended while your claims appear only on your own website, you probably have a corroboration problem.
    • If you are mentioned for the wrong customer or use case, you have a positioning problem that should be corrected before you pursue more exposure.

    Do not begin with a favorite tactic. Begin with the missing job. Schema cannot repair weak discovery, publisher outreach cannot clarify an ambiguous product page, and more copy cannot manufacture independent evidence.

    Win the pages AI systems already use for decisions

    Start with the questions a buyer asks immediately before making a shortlist. Use the exact category, comparison, specialization, and validation language that appears in the decision. A useful prompt inventory includes queries such as best category for a particular use case, one option versus another, category alternatives, brand reviews, and which providers hold a relevant accreditation.

    Run those prompts in the AI surfaces that matter to your audience. Record which businesses appear, which attributes are repeated, and which URLs are cited when citations are visible. Then search the same language traditionally. You are looking for the pages that repeatedly shape the answer: comparison lists, directories, review profiles, industry resources, and high-ranking explanatory pages.

    For this purpose, an authoritative page is not merely a domain with a high third-party score. It should address the same decision, compare the relevant category, use understandable criteria, and be visible for the query itself. A famous publication with a generic mention may contribute less useful context than a focused industry resource that explains exactly who each option suits.

    Earn inclusion with a verification package

    When a relevant list excludes your company, make the editor’s verification work easier. Send a concise package containing:

    • Your precise category and the customer or use case you serve best.
    • The specialization that distinguishes you from the companies already listed.
    • Links supporting any awards, accreditations, or affiliations you claim.
    • Published customer examples or usage data that support adoption and fit.
    • Your canonical company and product URLs, using the name you want represented consistently.
    • A factual correction if the page already contains outdated or inaccurate information about you.

    Do not ask an editor to declare you the best without evidence. Ask to be evaluated for the correct category, and supply the material needed to make that evaluation. This produces a more defensible mention and reduces the chance that your positioning is flattened into a generic company description.

    Publish a comparison resource only when it can stand on its own

    You can also create a comparison page that deserves to rank. A useful format places a summary table near the top and follows it with substantive analysis of every entry. Define the criteria, apply the same fields to each option, disclose relevant commercial relationships, and explain the situations in which different choices make sense.

    A self-published list should resolve a buyer’s decision, not disguise a promotional page as independent analysis. Include meaningful alternatives and limitations. If the only conclusion the methodology can produce is that your company wins every category, the resource will not help a careful reader evaluate anything.

    Treat directories as identity and trust infrastructure

    Prioritize directories and databases that real participants in your market recognize. Complete the relevant fields, choose the correct category, link to the canonical site, and keep the brand name and specialization consistent. Do not spread contradictory descriptions across dozens of low-value profiles. The goal is a coherent external record that confirms what the company is and where it belongs.

    Make every important claim extractable and corroborated

    Your page should let a reader locate the answer quickly and let a machine isolate the same passage. Clear headings, short paragraphs, bullets, comparison tables, concise answers, and query-aligned keywords all support that job. The point is not to make every page short. It is to remove the distance between a question and the evidence-backed answer.

    Use a decision-page anatomy

    For an important category or use-case page, include these elements in a logical sequence:

    • A direct category statement: Name what the product or service is without relying on a slogan.
    • A qualified fit statement: Identify who it is for, the problem it addresses, and any condition that changes the answer.
    • A comparison structure: Use a table only when several options share the same meaningful dimensions.
    • Evidence beside the claim: Place the customer example, accreditation, data, or external reference close to the sentence it supports.
    • Limitations: State where the offering is not the right fit. Qualification is more useful than universal superiority language.
    • Consistent terminology: Use the phrases buyers use for the category while preserving accurate technical language.

    Concise writing is not shallow writing. Put the direct answer first, then supply the method, evidence, exceptions, and detail needed to trust it. Do not make a system infer your specialization from a case study buried several screens below an abstract brand message.

    Apply structured data after the visible evidence layer is correct. JSON-LD can clarify entities and relationships, but it cannot turn an unsupported superlative into independent proof. The page should remain understandable if its markup is removed, and the markup should describe only information you can substantiate on the page or through a legitimate reference.

    Build an evidence matrix before rewriting copy

    List every important claim you want an AI answer to repeat. Then identify both the owned explanation and the external evidence that could corroborate it.

    Claim you want to earnWhat your page should explainUseful external corroboration
    Fit for a specialized customerThe qualifying use case, requirements, and limitationsA relevant comparison list or customer example
    Recognized professional standingThe credential, issuing body, scope, and statusAn accreditation, award, or affiliation record
    Meaningful customer adoptionWhat the usage measure represents and where it appliesThird-party usage data or a published customer account
    Positive customer experienceAn accurate description of support and product expectationsLegitimate reviews on a relevant review platform
    Established category identityA consistent company name, category, and specializationA trusted database or industry directory profile

    Platform weighting was not uniform in the available testing. Awards, accreditations, and affiliations received weights across ChatGPT, Google, and Claude; reviews received ChatGPT and Google weights but no Claude weight; customer examples and usage data appeared for ChatGPT and Claude; Google website authority was specific to Google; and social sentiment appeared as a smaller ChatGPT factor. Traditional databases and directories were especially prominent in the Claude model.

    Use those differences as a reason to diversify credible evidence, not to create a separate version of reality for each engine. A durable authority profile combines strong owned pages with accurate external records, real customer evidence, and editorial mentions relevant to the buying decision.

    Run AI visibility as a repeatable operating cycle

    Four connected workstations form a circular process around a glowing knowledge core, with outside source beacons supporting the loop.

    An AI answer is not a fixed organic rank. Measure a stable set of decisions and preserve enough context to tell whether an apparent change is meaningful.

    1. Define the eligible prompt set. Include only questions for which your business could truthfully be a relevant answer. Group them by discovery, comparison, validation, and use case.
    2. Capture a baseline. Record the exact prompt, model or surface, access mode when known, answer text, cited URLs, brands mentioned, fit description, and date.
    3. Classify each absence. Mark it as a retrieval, extraction, corroboration, or positioning gap. This turns an ambiguous visibility problem into a specific work queue.
    4. Make the smallest coherent intervention. Improve ranking and internal linking for retrieval, restructure the answer passage for extraction, pursue credible external evidence for corroboration, or correct inconsistent category language for positioning.
    5. Repeat the same prompts and inspect the path. Look beyond whether the brand appears. Check which pages were retrieved, which claims survived, and whether the recommendation describes the right customer fit.
    6. Feed the result back into the backlog. Route technical discovery problems to SEO, ambiguous answers to content, external proof gaps to public relations or reputation work, and inconsistent company records to the owner of directory data.

    Track measures that correspond to those jobs:

    • Eligible-prompt inclusion rate: the share of relevant prompts in which the brand receives a valid mention.
    • Citation coverage: the share that cites your site or an independent page validating the relevant claim.
    • Accurate-fit rate: the share of mentions that describe your specialization and limitations correctly.
    • External evidence coverage: the share of priority claims supported by a credible third party.
    • Retrieval coverage: the share of priority queries for which an owned page or qualified external mention is visible in traditional results.

    Do not collapse everything into one visibility score. A brand can appear frequently for the wrong reason, be cited without being recommended, or be recommended to customers it cannot serve. Keep inclusion, accuracy, citations, and commercial relevance separate.

    Timing also requires restraint. AI answers may rely on stored training patterns or live search results, so a newly published correction does not guarantee an immediate, uniform change across systems. Report what changed in the observable answer path; do not promise a universal refresh deadline.

    Key takeaways

    • AI search optimization has three core jobs: retrieval, extraction, and corroboration.
    • Traditional SEO remains a discovery layer because live-search systems often consult highly ranked pages first.
    • Relevant comparison lists can be powerful recommendation surfaces, but test-derived weights are not official platform formulas.
    • Write direct, qualified answers and place evidence beside the claims it supports.
    • Use JSON-LD to clarify accurate visible content, not to compensate for missing proof.
    • Measure a repeatable prompt set and classify each gap before choosing a tactic.

    Start with the buyer decision closest to your actual business value. Map the pages shaping that decision, repair the most important answer on your own site, and pursue the strongest missing external proof. That sequence gives you an AI search backlog tied to a reason for absence, rather than a collection of disconnected optimization tasks.

    References


  • How to Choose an AI Search Agency for Home Services or Dental

    How to Choose an AI Search Agency for Home Services or Dental

    You are not choosing between three interchangeable labels. You are choosing whether an agency can make your business understandable, credible, and selectable when someone asks an AI system whom to hire.

    That decision looks different for a plumbing company and a dental practice. A homeowner may need an agent to identify an available contractor and request an estimate. A prospective patient needs an accurate recommendation that reflects treatment needs, provider fit, and location. The right agency will build around that decision path instead of selling you a renamed SEO package.

    The acronym matters less than the decision path

    Generative engine optimization, or GEO, focuses on earning visibility and recommendations in generative answers. Answer engine optimization, or AEO, focuses on becoming a useful source for direct answers. Agentic search optimization, or ASO, extends the job into actions an AI agent may take for the user.

    For home services, that final stage is already central to the proposition: contractor selection, estimate requests, and service-call scheduling are the kinds of outcomes an ASO program is expected to support. Dental GEO and AEO remain more heavily centered on local provider recommendations and new-patient appointment demand.

    An agency does not need to use your preferred acronym. It does need to show how it will improve retrieval, evaluation, and action for the decisions your customers or patients actually make.

    Decision layerHome servicesDentalWhat the agency must demonstrate
    Candidate retrievalRecognition for the right trade, service, problem, and service areaRecognition for the relevant treatment, specialty, provider type, and locationA controlled set of non-branded questions that represents real demand
    Suitability evaluationClear project types, exclusions, coverage, availability, and customer fitClear treatments, provider qualifications, patient concerns, and practice fitPages and corroborating facts that help an AI system distinguish suitable from unsuitable choices
    ActionA working path to call, request an estimate, or schedule serviceA working path to call or request an appointment without replacing clinical judgmentConversion tracking, action-path testing, and an agreed definition of a qualified lead
    Accuracy riskWrong service-area or capability information can create wasted calls and dispatch problemsWrong treatment or provider information can mislead a person making a healthcare decisionA named owner for fact approval, correction, and ongoing updates

    Key takeaways

    • Hire for the vertical decision path, not for the agency’s preferred GEO, AEO, or ASO label.
    • Home-services programs need strong action readiness: accurate coverage, suitability, and a reliable route to an estimate or booking.
    • Dental programs need clinically reviewed patient information and precise treatment, provider, and location positioning.
    • Use agency rankings to discover candidates, not as a substitute for case evidence, capacity checks, and references.
    • Require reporting that separates AI visibility from qualified calls, appointments, booked work, and revenue.

    Build your shortlist around operating fit

    You can find plenty of agency leaderboards. Their scores may help you discover firms, but they cannot tell you whether a team fits your footprint, operating model, budget, or approval process. The agency operating each publication used here also places itself first in its own ranking. A self-ranking result is not automatically wrong, but it is not independent validation. Treat the numerical scores as screening material and verify every consequential claim yourself.

    Home-services agencies to interview

    The home-services candidate field covers contractors in HVAC, plumbing, electrical, roofing, restoration, pest control, insulation, and adjacent services. The useful distinction is not who occupies which rank. It is what kind of operation each agency appears built to serve.

    Your situationAgencies worth an initial interviewWhy they fit the shortlistWhat to verify
    You want a full-cycle retrieval, evaluation, and action programFirst Page SageIts disclosed model combines authority content, service-area positioning, and suitability work across several home-services categoriesThe longer onboarding process, assigned capacity, lead attribution method, and ownership of finished assets
    You are a contractor, remodeler, architect, or design-build businessSiana MarketingIts narrow construction and AEC focus includes project type, budget, and regional suitabilityAvailability, execution bandwidth, and whether its experience matches your exact trade rather than construction generally
    You run a regional or single-trade operation with a tighter budgetFocus DigitalIts positioning emphasizes accessible SEO and ASO strategy for smaller and midsize operatorsPublishing pace, team depth, and capacity if you add locations or service lines
    You want AI search inside a broader home-services marketing programRYNO Strategic SolutionsIts home-services background and full-funnel positioning may suit an operator that wants channels managed togetherWhich deliverables are genuinely AI-search-specific and which belong to conventional SEO, paid media, or web work
    You need a contractor-focused web and search partnerCI Web Group or Hook AgencyBoth are positioned around contractor marketing, with trade exposure that includes HVAC, roofing, plumbing, and related servicesExamples showing improvements in AI answers, not only traditional rankings, traffic, or website performance

    A roofing franchise with several markets should not select the same delivery model as an owner-operated plumbing company serving one region. Ask each agency to state how many service-location combinations it can support, who approves operating facts, and what happens when capacity or coverage changes. If the proposed system cannot absorb those changes, it will publish stale suitability signals.

    Dental agencies to interview

    For dental, start with firms whose disclosed work matches your actual growth problem. The dental field spans content-led GEO specialists, healthcare-focused teams, established dental web agencies, and platform-based providers.

    Your situationAgencies worth an initial interviewWhy they fit the shortlistWhat to verify
    You want a long-term, content-led GEO and SEO programFirst Page SageIts dental work emphasizes local landing pages, patient guides, comparisons, and new-patient lead generationClinical review, content differentiation, appointment attribution, and support for every specialty and location in scope
    You are making an earlier or more budget-conscious GEO investmentFocus DigitalIts healthcare-oriented model is positioned as an accessible way to build AI visibility and organic demandAdditional resource needs when the campaign expands across several specialties or locations
    You specifically want an AI-era lead-generation firmSignal Hill StrategiesIts model was designed around generative search for medical industries rather than added to a long-standing web packageDocumented dental outcomes and references, because the firm was established in 2026 and has a developing case library
    You primarily need dental web design and SEO, with GEO as a secondary objectiveRosemont MediaIts dental and elective-healthcare experience dates to 2008 and includes websites, content, SEO, and paid mediaThe depth of its GEO process beyond established dental SEO and web-design capabilities
    You want a brand-led dental marketing programWonderist AgencyIts stated specialty combines dental branding, website design, and SEOHow brand work will translate into measurable candidate inclusion and recommendation accuracy
    You prefer a broad, platform-oriented, or midsize-practice providerTitan Web Agency, Officite, or DentalScapesTheir stated positions respectively cover practices of different sizes, a platform-based model, and midsize dental practicesCustom strategy, account ownership, AI-search evidence, and any limitations imposed by the platform or service tier

    This is a first-call map, not a winner table. A strong traditional dental agency may be right when your website and local search foundation are weak. A dedicated GEO firm may be the better choice when your fundamentals are sound and the unresolved problem is AI recommendation visibility. Make the agency diagnose that distinction before it proposes work.

    Put six concrete artifacts in the scope of work

    Six unlabeled planning artifacts with maps, pathways, entity blocks, credibility symbols, content placeholders, and booking icons are arranged on a strategy table.

    Promises such as better AI authority or more visibility are not deliverables. Before you sign, turn the pitch into artifacts that your team can inspect, approve, and retain.

    1. A controlled question set. For home services, organize questions by service, customer problem, geography, suitability, and desired action. For dental, organize them by treatment, patient question, specialty, provider criteria, geography, and appointment intent. Include non-branded discovery questions as well as comparative and action-oriented questions. Otherwise, the agency can produce a flattering report by monitoring only prompts where you already appear.
    2. A canonical fact and entity ledger. Record the approved business name, locations, coverage, hours, services, exclusions, providers, credentials, contact routes, and booking options that apply. Add an owner and an approval status to each consequential fact. A dental clinician should approve treatment and patient-education claims; the marketing agency should not become the final clinical authority.
    3. A retrieval and evaluation content map. Every proposed service page, location page, patient guide, comparison, FAQ, or original-data asset should map to a demonstrated question or evidence gap. Reject a plan built around generic publishing volume. More pages do not help if they repeat the same claims or blur the boundary between services you do and do not provide.
    4. A structured-data map. Ask the agency to connect each machine-readable fact to visible, approved page content and to document how markup will be validated. JSON-LD can clarify entities, relationships, locations, and services, but it cannot manufacture authority or rescue unsupported claims. The map should also state who maintains the markup after templates, providers, locations, or services change.
    5. An external corroboration plan. The agency should identify which business profiles, citations, publications, professional references, and other third-party signals need correction or development. Ask it to separate controllable profile work from earned references it cannot guarantee. Vague promises of authority building are not enough.
    6. An action and measurement specification. Define the calls, forms, estimate requests, appointment requests, bookings, and qualified-lead states that will be tracked. Require action-path testing and a correction process for inaccurate AI answers. For dental, keep clinical decisions and sensitive patient information outside ordinary marketing workflows unless your practice has approved the necessary privacy and compliance controls.

    These artifacts also solve a common ownership problem. If the relationship ends, you should still possess the question set, fact ledger, content, structured-data documentation, reporting history, and access credentials. Without them, changing agencies can mean rebuilding the strategic foundation rather than simply changing the team executing it.

    Use the interview to expose generic SEO in AI clothing

    Do not spend the interview asking an agency to predict the future of AI search. Ask it to work through your current decision path. Strong operators become more specific when the discussion reaches services, locations, evidence, approval, and measurement. Weak ones retreat to traffic, content volume, or platform buzzwords.

    Ask thisA credible answer includesA weak answer sounds like
    How will you build our monitored question set?Segmentation by service or treatment, geography, intent, suitability, and action, with an explanation of why each segment mattersA generic keyword export or a secret proprietary list you cannot inspect
    How do you separate retrieval from evaluation?A distinction between appearing in the candidate set and being described as a suitable choice for the specific needOne visibility score with no answer-level evidence
    Show us a vertical-relevant example.The original problem, the facts and assets changed, representative AI outputs, and a business result or clearly stated limitationA screenshot of a favorable branded query with no baseline or conversion data
    What operating information do you need from us?Service boundaries, locations, exclusions, capacity, provider or technician facts, approvals, and change notificationsLittle or no involvement from your operations or clinical team
    How do you handle variable AI answers?A repeatable prompt protocol with platform, date, geography assumptions, answer capture, and trend reportingA promise that one answer or ranking position will remain stable
    How will you connect visibility to business outcomes?Defined conversion events, qualified-lead rules, source capture, and separation of mentions from calls, appointments, or bookingsImpressions, citations, or estimated visibility presented as revenue
    Who approves factual claims?Named business owners for operating facts and clinician review for dental treatment contentThe agency publishes from general web research without a documented approval route
    What happens when an AI answer is wrong?A triage process that checks owned pages, structured data, profiles, conflicting third-party information, and action pathsNo process beyond publishing another blog post

    Ask to see the artifacts on screen. A polished pitch can hide whether the agency has a real query taxonomy, fact-control process, or answer-level reporting system. Redacted examples are reasonable when client confidentiality applies, but the team should still be able to demonstrate its method.

    Measure the path from AI answer to booked business

    An icon-based path leads from an AI-style phone interface through a call and calendar to a home service visit and a dental appointment.

    AI visibility is an intermediate result. A useful report shows whether visibility is increasing, whether the recommendation is accurate, and whether the right person can complete the next step.

    Require four reporting layers

    LayerWhat to recordWhat it tells youWhat it does not prove
    RetrievalCandidate inclusion, mentions, citations, and visibility across the agreed question setWhether AI systems can retrieve and associate your business with relevant demandThat the system prefers you or that a customer will contact you
    EvaluationRecommendation language, stated reasons, suitability, and accuracy of service, treatment, provider, and location factsWhether your positioning survives comparison with alternativesThat the recommendation generated a qualified lead
    ActionCalls, forms, estimate requests, appointment requests, booked jobs, and the agreed qualified-lead statesWhether the discovery path produces usable demandThat every conversion is incremental or profitable
    IntegrityIncorrect facts, obsolete pages, conflicting profiles, broken booking paths, and correction statusWhether visibility is being gained without creating operational or patient riskThat the wider web contains no conflicting information

    Establish the baseline with the same controlled questions the agency will use later. Preserve the question wording, platform, date, location assumption, returned answer, citations, and recommended businesses. AI outputs can vary, so one favorable capture is evidence of an occurrence, not evidence of a durable trend.

    Then keep the commercial metrics vertical-specific. A home-services dashboard should distinguish an irrelevant call, an eligible estimate request, a booked visit, and completed work. A dental dashboard should distinguish a general inquiry, a new-patient appointment request, a scheduled appointment, and the practice’s approved downstream outcome. Do not let a growing mention count conceal poor suitability or an unusable booking path.

    Protect accuracy, access, and exit before signing

    Your contract should state who owns the content, structured data, dashboards, prompt history, and underlying accounts. It should name the people allowed to approve business and clinical facts, define how corrections are handled, and explain what you receive when the engagement ends.

    • Reject guaranteed placement in ChatGPT, Gemini, Claude, or any other AI answer surface.
    • Reject reporting that relies on unexplained proprietary scores without answer-level evidence.
    • Reject a content quota that is not mapped to a retrieval, evaluation, or action gap.
    • Reject schema-only positioning. Machine-readable markup is one part of the system, not the whole strategy.
    • Reject home-services plans that ignore coverage, capacity, exclusions, and the actual estimate or dispatch path.
    • Reject dental plans that permit unreviewed treatment claims or confuse marketing automation with clinical guidance.
    • Reject account structures that prevent you from accessing your analytics, content, profiles, markup, or conversion history.

    Send the same operating facts, question set, scope requirements, and reporting expectations to a small shortlist. The agency that gives you the clearest boundaries, evidence, and ownership model is usually a safer choice than the one offering the boldest visibility promise. Your next move is not to buy a ranking. It is to make each candidate show exactly how your business will be retrieved, evaluated, and chosen.

    References


  • How to Choose AI Search Optimization and Query Analytics Tools

    How to Choose AI Search Optimization and Query Analytics Tools

    You’re looking at an AI visibility dashboard that says your brand is being cited more often. The line is moving in the right direction, but it still doesn’t tell you whether new buyers discovered you, existing demand simply used your name, or any cited page contributed to a useful business outcome.

    That is the real tool-selection problem. You don’t need another score with an upward arrow. You need a system that preserves the chain from query to citation to page to outcome, then shows you what to change.

    Start with the decision your tool must support

    AI search optimization tools often combine monitoring, query analysis, content recommendations, competitive tracking, and attribution. Those functions may appear in one interface, but they answer different questions. Treating them as one category makes it easy to buy broad coverage without gaining a usable workflow.

    Write down the decisions you expect the tool to improve before you review its features:

    1. Where are we absent? Identify the topics, questions, platforms, markets, and answer types where your brand or pages are missing.
    2. Why are we absent? Determine whether the likely gap concerns content relevance, factual clarity, source eligibility, entity representation, authority, technical accessibility, or a weak match between the query and the page.
    3. What should we change? Turn the observation into a specific action on a specific URL, entity record, content brief, internal link, or structured-data implementation.
    4. Did the change matter? Compare the same query set and conditions after the change, then connect improved visibility to visits, leads, transactions, or another outcome that matters to your organization.

    The underlying measurement chain contains several distinct objects:

    • Audience intent: the problem or decision a person is trying to resolve.
    • User prompt: the words the person enters into an AI interface, when that information is actually available.
    • Grounding query: a lookup an AI system uses to find supporting information for its response. This is not necessarily the user’s verbatim prompt. Microsoft Clarity’s AI reporting, for example, surfaces grounding queries used to retrieve supporting information.
    • Citation: the page or domain selected as support.
    • Answer inclusion: whether the answer mentions, describes, compares, or recommends the brand.
    • Outcome: what happens after exposure, such as a visit, signup, qualified lead, assisted conversion, or transaction.

    A tool that observes only one layer cannot explain the whole chain. Citation tracking doesn’t automatically reveal the original prompt. A brand mention doesn’t prove that your page was cited. Referral traffic doesn’t show every answer that influenced a person without producing a click. Revenue attribution doesn’t become trustworthy merely because a dashboard attaches currency to an AI channel.

    Define each metric before accepting it. Record its numerator, denominator, platforms, markets, languages, query set, brand rules, reporting window, and treatment of missing observations. A citation rate calculated from a monitored query set describes that set; it is not a census of your visibility across every possible AI answer.

    Separate branded demand from non-branded discovery

    Two separate streams of abstract search signals represent existing brand demand and broader discovery before entering an analytics system.

    An aggregate visibility score can rise while your ability to reach unfamiliar buyers remains flat. That happens when branded questions and generic category questions are blended into one total.

    A branded query contains your company, product, domain, or another deliberate brand identifier. A non-branded query expresses a problem, category, use case, comparison criterion, or desired outcome without naming you. The first group usually tells you about retrieval around existing awareness. The second gives you a clearer view of discovery and consideration beyond that awareness.

    Microsoft Clarity can now label individual AI queries as branded, filter by branded or non-branded status, and break Share of Authority out by query type. The important lesson is broader than one product: any query analytics workflow should preserve this distinction rather than bury it inside a blended score.

    Observed patternWorking interpretationWhat to inspect next
    Branded visibility improves while non-branded visibility is flatExisting brand retrieval may be strengthening without broader category discoveryReview missing generic intents, competitor citations, and whether you have a suitable page for each important problem or category query
    Non-branded citations improve but brand inclusion does notYour pages may be useful as evidence without creating a strong connection to the brandInspect how clearly the cited page identifies the organization, product, expertise, and relationship between the evidence and the brand
    Citations improve but downstream outcomes remain flatThe new exposure may be informational, poorly matched to the intended audience, or disconnected from a useful next stepCheck the cited URLs, query intent, landing-page path, calls to action, and whether the outcome is measurable at all
    Branded visibility declines while non-branded visibility is stableGeneral topical relevance may be intact while brand-specific retrieval or representation has weakenedCheck name variants, product facts, changed URLs, outdated pages, inconsistent entity details, and competing pages that may have replaced the intended citation

    These are diagnostic hypotheses, not proof of causation. Use them to choose the next inspection, not to declare why an AI system behaved as it did.

    Your brand classification rules also need to be explicit. Build a controlled dictionary containing the company name, product names, domains, accepted abbreviations, former names that still matter, and common variants. Keep competitor-only queries out of your branded segment. Put queries that contain both your brand and a competitor into a separate brand-plus-competitor segment if comparisons matter to you.

    Preserve the raw query beside the assigned label. When the dictionary changes, record the change and reprocess historical data consistently where possible. Otherwise, a reporting shift caused by classification can look like a visibility shift caused by the market.

    Turn query analytics into an optimization queue

    Abstract query signals are sorted into groups and condensed into a short stack of prioritized optimization cards.

    A query report becomes useful when every important observation has an owner, a target page, a proposed change, and a validation method. Without those fields, the dashboard produces interesting meetings rather than better search assets.

    Use this operating loop:

    1. Capture the evidence. Keep the raw query, platform, observation time, market and language where available, branded status, cited URL, brand inclusion, answer evidence, and any connected outcome identifier. A screenshot can help with review, but retain exportable text or structured records as well.
    2. Cluster by intent. Group wording variants around the same underlying job, such as learning, evaluating, comparing, troubleshooting, or buying. Do not force ambiguous queries into a convenient category; an unknown bucket is more honest than false precision.
    3. Map each cluster to the page that should win. Record the preferred URL even when it is not currently cited. If several internal pages compete for the same intent, decide which one should be canonical for the task before producing more content.
    4. Write a testable diagnosis. Replace vague notes such as improve authority with statements such as the preferred page does not answer the comparison criterion present in the query, or the cited page contains an outdated product description.
    5. Make the smallest defensible change. Clarify the direct answer, add missing evidence, update obsolete facts, improve the heading and page structure, strengthen relevant internal links, or repair structured data that inaccurately expresses visible page content.
    6. Recheck under comparable conditions. Use the same defined query set, platforms, markets, and classification rules. Preserve before-and-after evidence and treat a single changed answer as an observation, not conclusive proof.
    7. Connect the result to an outcome. Determine whether the change affected only citation presence or also brand inclusion, qualified visits, assisted conversions, leads, transactions, or another declared objective.

    The diagnosis step prevents a common failure: applying the same content tactic to every visibility gap. Different observations call for different checks.

    • The relevant query appears, but your domain is not cited: inspect the pages that are cited, the kind of evidence they provide, and whether you have an eligible page that directly satisfies the intent.
    • Your domain is cited through the wrong page: inspect internal competition, redirects, canonical signals, page purpose, and whether the preferred page is actually the better answer.
    • Your page is cited, but the brand is not meaningfully included: examine whether the page supplies a fact without establishing a clear relationship between that fact, your entity, and the reader’s decision.
    • The brand appears, but a material fact is wrong: prioritize factual correction over visibility growth. Audit the current page, structured data, consistent entity details, and any outdated content that could support the error.
    • Visibility and traffic improve, but conversions do not: inspect intent fit and the path after arrival. The cited content may answer an early-stage question while the page asks for a late-stage commitment.

    Structured data belongs inside this workflow, but it isn’t a substitute for the page. JSON-LD should express accurate, visible, supported facts and relationships. Adding markup for information the reader cannot verify on the page creates a data-quality problem rather than an optimization advantage.

    Keep the queue prioritized by consequence as well as visibility. An inaccurate product claim deserves attention even if it appears in a small query cluster. A high-volume-looking theme may deserve less attention if it has no suitable audience, page, or business path. The tool should help you retain those distinctions instead of sorting every task by a single proprietary score.

    Choose the tool by the evidence it can preserve

    AI platform coverage, optimization actions, agentic commerce, and revenue attribution form a useful buying frame. They are not interchangeable, and a long feature list in one area does not compensate for missing evidence in another.

    Buying criterionEvidence to requestWarning sign
    Platform coverageA precise list of answer experiences, markets, languages, collection methods, refresh behavior, and historical availability, plus raw evidence behind each observationA platform logo is shown without explaining which surface, geography, or data-collection method it represents
    Query analyticsRaw query export, a clear distinction between user prompts and grounding queries, editable brand rules, intent grouping, page mapping, and traceable metric definitionsAll observations are collapsed into a visibility score whose denominator and monitored universe are unclear
    Optimization actionsA recommendation that identifies the query, diagnosis, target URL, proposed change, supporting evidence, owner, status, and validation signalGeneric instructions to add authority, improve quality, or write more content without showing the affected query and page
    Agentic commerceA concrete explanation of the agent action being observed or enabled, the product data required, the supported transaction path, and the event record available for verificationThe term agentic is used for ordinary content generation, chatbot interaction, or product monitoring without an observable commerce action
    Revenue attributionThe identifiers and rules that connect exposure, citation, visit, conversion, and revenue; documented attribution logic; accessible underlying records; and a path for unresolved or unattributed casesRevenue appears beside an AI channel without a reproducible connection between the visibility event and the business event
    Data portabilityExports for raw observations, labels, evidence, URLs, recommendations, status history, and outcome joins in a format your team can use elsewhereYour history, classifications, and evidence disappear when the subscription ends or cannot be independently audited

    Agentic commerce should carry substantial weight only when it matches your business model. If you sell structured products and expect agents to participate in discovery or transactions, ask exactly which part of that path the tool measures. If you publish advice, generate leads, or sell a service through a considered sales process, query coverage, citation evidence, content actionability, and attribution may deserve more weight.

    Do not evaluate attribution from the dashboard label. Ask the vendor to walk through one record from the observed AI event to the business outcome. You should be able to see what was directly measured, what was joined, what was modeled, which window and rules were applied, and where uncertainty remains. If that chain cannot be reproduced, treat the revenue figure as directional.

    Run a bounded pilot with your own query set before making a long-term commitment. Include branded, non-branded, comparison, factual, and action-oriented intents that matter to your audience. Define the preferred page and expected outcome for each cluster in advance. Then inspect whether the tool:

    • captures the platforms and markets you actually care about;
    • shows raw evidence behind its classifications and scores;
    • distinguishes prompts, grounding queries, citations, mentions, and outcomes;
    • lets you correct brand labels and query clusters without losing the original record;
    • turns a visibility gap into a page-level action your team can assign;
    • preserves before-and-after evidence after a change;
    • exports the data required for independent analysis; and
    • explains attribution without hiding the join logic.

    Treat missing raw evidence, unclear denominators, or unusable exports as gating failures when auditability matters. A polished interface can save reporting time, but it cannot repair an unverifiable measurement model.

    Key takeaways

    • Choose an AI search tool for the decisions it improves, not the number of charts it contains.
    • Keep audience intent, user prompts, grounding queries, citations, answer inclusion, visits, and outcomes as separate measurement layers.
    • Split branded retrieval from non-branded discovery before interpreting any aggregate visibility trend.
    • Require every optimization recommendation to name the affected query, target page, diagnosis, proposed change, and validation signal.
    • Judge platform coverage by precise surfaces, markets, collection methods, and raw evidence rather than platform logos.
    • Accept revenue attribution only when you can inspect the chain connecting an AI observation to the business event.

    Your next move can be small. Take one important non-branded query cluster, identify the page that should answer it, and trace the available evidence from grounding query to citation to brand inclusion to outcome. Make one defensible change and preserve the before-and-after record.

    If your current tool cannot support that chain, you now know the capability to look for. If it can, stop watching the aggregate score and start using the evidence to run an optimization queue.

    References


  • How Brands Earn Visibility and Citations in AI Search

    How Brands Earn Visibility and Citations in AI Search

    Your brand can rank well in conventional search and still disappear from an AI-generated shortlist. When that happens, publishing another broadly optimized article may not solve the problem. The failure could occur before the system searches, while it retrieves evidence, or when it chooses which sources to cite.

    You need to identify that stage before deciding whether to invest in brand building, content, digital PR, technical optimization, or structured data. Treating every visibility problem as a citation problem wastes effort at the wrong end of the process.

    AI visibility passes through three separate gates

    Brand visibility and citation visibility overlap, but they are not interchangeable. A generated answer can mention a brand from prior model knowledge, discover it through live search, cite its own website, or support the recommendation with an independent source. Each outcome reflects a different path.

    • Consideration: Does the brand enter the model’s candidate set when it interprets the question?
    • Retrieval: Does live search find the brand, its content, or independent evidence about it?
    • Citation: Does the system select that evidence to support the answer it ultimately presents?

    The first gate matters more than many content teams assume. Across 3,960 responses to 66 U.S. buyer questions, models searched for brands they were already familiar with 3.2 times as often as unfamiliar brands. Familiar brands appeared in 55.7% of brand searches, compared with 17.4% for brands outside each model’s measured top 10.

    That advantage did not turn every retrieval query into a branded query. Only 31% of 13,281 fan-out searches named a company. When a query did name one, however, 63% involved one of the model’s five most familiar brands. Familiarity therefore appears to shape which companies receive direct investigation, while most of the wider research process still runs through unbranded questions.

    Use those figures as a directional signal, not a universal benchmark. The tests covered a defined set of U.S. buyer prompts and 1,416 brand-level observations. They found a relationship between measured familiarity and search behavior, but did not establish that familiarity caused each search. Some industry slices were based on as few as six prompts.

    This distinction gives you a practical diagnostic. If your brand is never mentioned, work on consideration and external recognition. If it appears but its evidence is not retrieved, improve discoverability and question coverage. If relevant pages are retrieved but competitors receive the citations, improve source fit, specificity, and corroboration.

    Win unbranded fan-out searches before chasing citations

    A glowing sphere branches into many paths leading to clusters of generic products and evidence tiles, with a blue marker appearing in several clusters.

    A buyer may ask for the best platform for a particular workflow, but an AI system can break that request into narrower searches about features, integrations, pricing structure, implementation, risks, alternatives, or suitability. Most of those searches will describe the need rather than name a vendor.

    This creates an opening for a less familiar brand. Live retrieval is not completely confined by model memory. In one documented example, Gemini searched for Lemon Squeezy while evaluating online payment providers even though the company was not present in its measured familiarity set. An unfamiliar brand can still enter through a relevant live search.

    Build your content map from those generic research needs, not from a list of product keywords alone:

    1. Choose a real buyer decision. Define the audience, use case, constraints, and consequence of choosing poorly. A prompt such as “Which platform is best?” is too broad to guide useful coverage.
    2. Break the decision into verifiable subquestions. Include fit, requirements, comparisons, limitations, implementation, and evidence. Keep each question narrow enough that a page can answer it directly.
    3. Inspect the sources that AI answers currently cite. Record the domain, page type, claim supported, and whether the brand behind the source is also recommended. This shows which evidence surfaces are actually entering the answer.
    4. Assign one source of truth to each important claim. Use an owned page for facts you control and seek independent corroboration where a self-published assertion would be weak.

    Do not force the brand name into every heading. A useful unbranded page should answer the generic question even if the reader has never heard of you. Introduce your product only where it genuinely satisfies the stated criteria, and make the connection explicit enough to verify.

    This approach serves both discovery and citation. It gives retrieval systems a relevant page for the unbranded query, while giving the answer generator a bounded claim it can use. A generic thought-leadership page may mention the topic repeatedly without doing either job.

    Segment citation patterns by model, market, and prompt

    There is no dependable universal list of domains that every AI system prefers. Citation behavior changes with the model and the category being researched. A large observational analysis covering 12 billion citations, 29 industries, and eight consumer LLMs found that source preferences differed across model-and-industry combinations.

    Brand familiarity also varied sharply by category. In the tested industries, models searched for familiar brands between 41% and 82% of the time, while unfamiliar brands appeared in 9% to 23% of searches. The small prompt counts in some categories make those ranges unsuitable as targets, but the variation is still a warning against managing AI visibility through one blended score.

    Separate your analysis at three levels:

    LevelWhat to recordDecision it supports
    ModelMentions, cited domains, cited URLs, and answer language for each tested systemWhere visibility is weak and whether one model is distorting the overall result
    Prompt classDiscovery, comparison, implementation, risk, and branded questionsWhich part of the buyer decision your evidence fails to cover
    Market or categoryRelevant publishers, directories, communities, review surfaces, and first-party sitesWhere credible evidence needs to exist outside your own domain
    ClaimThe exact statement supported by each citationWhether the source is helping your brand, merely discussing the category, or contradicting you

    The claim-level view is crucial. A domain may be cited frequently without ever supporting a recommendation for your brand. Conversely, an independent page may improve brand visibility even when your own site receives no link. Count the mention, the cited source, and the supported claim separately.

    Look for repeatable patterns inside each segment. If a model repeatedly cites product documentation for implementation questions, strengthen the relevant documentation. If independent comparisons dominate evaluation prompts, improve the accuracy and availability of third-party information. The point is not to copy a competitor’s backlink profile. It is to place verifiable evidence on the surfaces selected for the decision you want to influence.

    Publish evidence that can survive citation selection

    Verified evidence objects pass through a glowing selection aperture while vague and duplicate source fragments remain outside.

    Retrieval only earns your page an audition. Citation selection still depends on whether the page supplies a clear answer that fits the prompt. Repetition, word count, and schema volume cannot compensate for a claim that is vague, unsupported, or difficult to locate.

    Give every important page a citation-ready core

    A citation-ready passage is not a block written for bots. It is a self-contained answer that a buyer can understand and verify without reconstructing your argument from several pages.

    • Answer the question immediately. Put the direct answer near the relevant heading, then explain the reasoning and exceptions.
    • Name the entity precisely. Use consistent brand, product, and company names. Distinguish similarly named products and explain the relationship between a parent company, platform, and individual offering.
    • State the scope. Identify the audience, plan, product version, location, or use case to which the claim applies.
    • Expose the evidence. Put material facts in accessible page text. Do not make a video, image, downloadable file, or interactive widget the only place where the answer appears.
    • Separate facts from positioning. Replace unsupported superlatives with capabilities, constraints, methodology, and evidence a third party can check.
    • Maintain the claim. Show the relevant date or version when information can change, and update or retire pages that no longer describe the current product.

    These choices do not guarantee a citation. They reduce ambiguity and make it easier for both people and machines to determine what the page actually supports.

    Use JSON-LD to clarify, not manufacture, authority

    Structured data should describe the entity and content already visible on the page. Use the most accurate applicable types, such as Organization for the company, Product or SoftwareApplication for an offering when appropriate, Article for editorial content, and Person for a real author. Keep names, URLs, and relationships consistent with the page.

    Do not mark up claims that readers cannot see, and do not fill sameAs with loosely related profiles. JSON-LD can reduce entity ambiguity. It cannot make an unsupported claim credible, create brand familiarity by itself, or guarantee inclusion in an AI answer.

    Build corroboration beyond your own website

    Your website is the right source for documentation, specifications, policies, and other facts you control. It is not automatically the strongest source for comparative claims about quality, leadership, or market position.

    Compare the independent domains cited for your priority prompts with the places where your brand has an accurate presence. Correct stale descriptions. Supply partners, directories, reviewers, and publishers with verifiable information when there is a legitimate editorial reason to do so. Do not manufacture consensus through duplicate contributed content; repeated wording across low-value pages is not independent corroboration.

    This is where AI visibility connects with brand building and digital PR. Familiarity may help a brand enter consideration, while independent evidence gives retrieval systems something credible to find. Neither replaces the other.

    Measure the visibility funnel and fix its weakest gate

    Key takeaways

    • Measure consideration, retrieval, and citation separately; a failure at one stage calls for a different fix.
    • Test unbranded buyer questions because most observed fan-out searches did not name a company.
    • Segment results by model, prompt class, market, source, and claim instead of trusting one visibility score.
    • Make important answers direct, scoped, accessible, and verifiable before adding more markup.
    • Track third-party citations as brand visibility even when they do not produce a link to your domain.

    A useful measurement system preserves the path from prompt to claim. Without that path, a rising citation count can hide the fact that citations are supporting competitors, irrelevant topics, or outdated descriptions of your product.

    1. Freeze a representative prompt set. Cover the important buyer decisions with both unbranded and branded wording. Keep the wording stable so changes in output are not confused with changes in the test.
    2. Record the full answer. Capture the model, prompt, date, brand mentions, recommendation order, cited URLs, cited domains, and the claim attached to each citation.
    3. Capture retrieval only when it is observable. If a platform exposes fan-out searches, save them. If it does not, mark retrieval as unknown rather than inferring hidden queries from the final citations.
    4. Repeat prompts. Generated answers vary. A single appearance or omission is an observation, not a stable visibility pattern.
    5. Classify the bottleneck. Decide whether the next intervention belongs to entity recognition, unbranded content coverage, technical accessibility, independent corroboration, or citation-page quality.

    Use a simple decision rule when reviewing the results:

    • Never mentioned: strengthen entity clarity, relevant distribution, independent coverage, and category association.
    • Mentioned but absent from observable searches: determine whether the brand is being recalled without current evidence and whether generic fan-out queries expose a content gap.
    • Found but not cited: compare your page with the selected source at the claim level. Check directness, scope, evidence, accessibility, and freshness.
    • Cited through a third party: count the visibility, verify that the description is accurate, and decide whether an owned source should also exist for the underlying fact.
    • Cited with an incorrect claim: correct the source of truth and any external listings you can legitimately update. More mentions of the same error will deepen the problem.

    Start with one commercially important decision, establish its prompt and citation baseline, and identify the first gate where your brand consistently disappears. Fix that gate before expanding the program. The goal is not to accumulate citations in the abstract. It is to make your brand a credible, retrievable answer when a buyer asks the question that leads to a decision.

    References


  • How to Improve AI Search Visibility Without Hurting SEO

    How to Improve AI Search Visibility Without Hurting SEO

    Your pages rank, your product information is accurate, and your team publishes regularly. Yet when a buyer asks ChatGPT, Gemini, Claude, or Perplexity for a shortlist, your brand is missing or described in language you wouldn’t use.

    The fix isn’t to manufacture a page for every prompt. You need to make your strongest knowledge easy to retrieve, extract, verify, and reuse. That improves your eligibility for AI-generated answers while protecting the SEO authority you already have.

    Key takeaways

    • Measure presence, accuracy, evidence, and cited domains separately. A brand mention can still be wrong, unsupported, or irrelevant.
    • Fix crawl barriers and conflicting facts before creating more content. AI visibility cannot compensate for an inaccessible or internally inconsistent website.
    • Give each important question a direct, qualified answer that still makes sense when extracted from the surrounding page.
    • Build reusable content from an approved fact record, then adapt it for the format and context your audience needs.
    • Treat prompt gaps as hypotheses. Publish only when a distinct buyer need, useful evidence, and an appropriate destination justify a new URL.

    Start with an AI visibility baseline

    An analyst studies four unlabeled visual panels showing markers, evidence tokens, source documents, and connected pathways.

    AI visibility isn’t a single ranking. A system can mention your brand but misstate a feature. It can describe you accurately but omit you from the recommendation that matters. It can use your information without displaying your URL. You need a scorecard that preserves those differences.

    DimensionQuestion to answerWhat to record
    PresenceDoes the brand appear for the buyer’s prompt?Mention, omission, shortlist position, and context
    FramingIs the brand described as intended?Category, audience, use case, strengths, and limitations
    AccuracyAre the material claims current and correct?Stale features, conflicting descriptions, and unsupported statements
    EvidenceWhat appears to support the answer?Displayed URLs, named domains, quoted facts, or no visible citation

    Begin by writing the version of the answer you want a qualified buyer to receive. Define your category, intended audience, primary use cases, differentiators, limitations, and strongest proof points. This isn’t advertising copy. It is the reference against which you can identify omissions and factual drift.

    Next, build prompts from real buying decisions rather than keyword variants. Include category discovery, constrained recommendations, use-case questions, comparisons, and objections. A useful set might include prompts shaped like these:

    • Which products help [audience] complete [job]?
    • What should I look for when choosing a [category] for [use case]?
    • Which options meet [meaningful constraint]?
    • Compare [brand] and [competitor] for [specific use case].
    • Is [brand] suitable for [audience or condition]?

    Ask the same buyer questions across ChatGPT, Gemini, Claude, and Perplexity. Save the exact prompt, response, date, system or model shown in the interface, brand framing, factual errors, and displayed citations. If an answer shows no citations, record that instead of inferring where it came from.

    Treat one generated answer as an observation, not a universal rank. Preserve the wording of your prompts and repeat the same method on a consistent schedule and after meaningful changes. Otherwise, you won’t know whether the result changed or the test did.

    Your baseline should produce a gap with a destination:

    • If you appear with stale facts, correct the conflicting information on properties you control.
    • If a competitor appears because an external comparison page is repeatedly surfaced, investigate that domain and the evidence it uses.
    • If your relevant page is accessible but its answer is buried, restructure that page before commissioning another one.
    • If no existing page satisfies a distinct buyer need, consider a new page only after defining what unique information it will add.

    This turns a vague concern about AI into a repair queue. It also prevents the most expensive mistake in AI SEO: producing content before you know whether the gap is technical, editorial, reputational, or external.

    Make your best information retrievable

    Strong Google performance remains useful, but it is no longer the whole retrieval environment. Major AI systems can use search tools to find current pages; Gemini remains shaped by Google Search, while other systems use different search tools and crawlers. The practical question is whether the retrieval systems you care about can reach and understand the page that contains your best answer.

    Audit the URLs that represent your brand, products, categories, and priority use cases:

    1. Confirm that each important page is crawlable by the search engines and AI crawlers your policy allows. Inspect robots.txt and any page-level indexing directives rather than assuming all bots receive the same access.
    2. Put material claims in readable page text. Don’t leave a differentiator, price condition, product limitation, or proof point only inside an image or an interaction that a crawler may not extract.
    3. Use descriptive titles and plain headings. A heading such as “Data retention and deletion” gives readers and retrieval systems more context than “Your information.”
    4. Make product and category pages explicit about the audience, job, constraints, and current capabilities. Clever slogans are poor substitutes for factual descriptions.
    5. Link related pages where the relationship helps a reader continue the task. An implementation page should lead to prerequisites; a comparison should lead to the underlying feature or policy evidence.
    6. Remove or update statements that conflict across product pages, help documentation, company profiles, and other properties you control.

    Resolve contradictions before adding detail

    Conflicting facts create a selection problem. If one page uses an old category, another describes a discontinued feature, and a third targets a different audience, an AI system has several plausible versions of your brand. Adding another polished page doesn’t settle the conflict.

    Create a controlled fact record for statements that affect selection: official name, category, intended users, supported use cases, meaningful limitations, availability, and evidence. Give each fact an owner and a page that should be treated as its maintained destination. When a fact changes, update dependent pages and formats from that record.

    Use schema as clarification, not camouflage

    Structured data should describe what the visible page actually contains. Choose the schema type that matches the page and keep its names, dates, entities, and claims aligned with the human-readable content. For reported news, NewsArticle structured data is a relevant part of the publishing pattern.

    JSON-LD cannot rescue a blocked page, reconcile contradictory claims, or make generic copy authoritative. If markup and visible text disagree, you have created another inconsistency. Fix the content model first, then use schema to make that model explicit.

    Build answers that survive extraction and reuse

    A layered source document passes through a transparent chamber and becomes modular tiles that remain linked to evidence before fitting into several blank answer containers.

    An AI system rarely needs every paragraph on a page to answer a narrow question. It needs the relevant statement, its meaning, its qualifiers, and enough evidence to trust the selection. Your job is to make those parts clear without reducing the page to robotic fragments.

    Give each important question a complete answer unit

    For each priority question, create a passage that remains accurate when lifted out of context:

    • State the answer early, ideally in the opening sentence of the relevant section.
    • Name the subject instead of relying on vague pronouns such as “it” or “this solution.”
    • Carry the important qualifier with the claim. If a capability applies only to a particular plan, region, integration, audience, or workflow, say so in the same passage.
    • Place proof near the claim it supports. Don’t make a reader hunt through an unrelated resource to understand why the statement is credible.
    • Link to the maintained destination for deeper detail, prerequisites, or exceptions.

    This is answer-first writing, not answer-only writing. The direct response helps a busy reader decide whether to continue. The surrounding explanation helps them judge scope, trade-offs, and evidence.

    For long-form material, use an inverted-pyramid structure, an informative summary near the top, descriptive subheadings, highlighted lessons or quotes, and purposeful internal links. These elements make important information easier for people and AI systems to locate. A summary should reveal the useful facts, not tease them.

    Separate the knowledge from its page container

    A durable content operation doesn’t treat the finished page as the only copy of what the organization knows. Keep an inventory of reusable knowledge objects behind it:

    • The approved claim in plain language
    • The entity or product the claim describes
    • The conditions and exceptions that limit it
    • The evidence, quotation, data, or maintained URL that supports it
    • The owner responsible for changes
    • The pages and formats that currently reuse it

    This is the operational value of liquid content. Verified facts, quotations, data, and resources remain intact, but they are no longer locked inside one rigid presentation. The same approved knowledge can support a detailed page, an audio explanation, a video script, an infographic, a slide deck, a briefing, or a social asset.

    Choose the format from the audience’s situation

    Repurposing is useful when the format changes access or comprehension. An audio version can serve someone who cannot read at that moment; a text version can serve someone who cannot listen. A diagram can clarify a relationship that prose makes cumbersome. A short video can demonstrate a process, while a maintained page carries the full qualifications and links.

    AI tools can accelerate conversion into briefings, infographics, quizzes, podcasts, and presentations, but human review remains essential. A polished derivative can still omit a condition, distort a comparison, mismatch a label, or place the wrong value in a visual.

    Treat every transformation as a publication that requires editorial control:

    • Verify names, quotations, figures, labels, and links against the approved fact record.
    • Check that qualifications survived compression.
    • Keep important claims available as text, even when the primary experience is visual or audio.
    • Send corrections back to the shared fact record so the next format doesn’t repeat an error.
    • Retire or update derivatives when the underlying claim changes.

    Scale only what adds evidence or access

    A prompt audit can expose many missing queries. That doesn’t mean you need the same number of new pages. Several prompts may express one underlying need, and your strongest existing URL may already be the right destination.

    The relevant risk isn’t AI-assisted drafting by itself. It is publishing large amounts of thin, repetitive content that offers retrieval systems and readers no compelling reason to select one page over another. Overlapping URLs can also divide internal links, create maintenance conflicts, and blur which page represents the topic.

    Put every proposed page through a decision gate

    • Which buyer decision or task does this page resolve?
    • Can an existing page satisfy that need with a focused update?
    • What information, evidence, or utility will be genuinely new?
    • Which claim makes this page more useful than the material already available?
    • Does this subject belong on your domain, or is an independent industry, review, community, or reference destination more useful to the buyer?
    • Who will maintain the facts when the product, policy, or market changes?
    • How will the page connect to your existing topic structure without competing with a stronger URL?

    If you cannot answer those questions, keep the idea out of production. If the need is real but the information belongs on an established page, update that page. Create a new URL only when it has a distinct purpose and enough substance to remain useful on its own.

    Work on the external evidence AI systems already surface

    Your website is only one part of your AI visibility. When another brand wins a recommendation, record the domains and pages associated with that answer. A competitor may dominate a comparison because a relevant review destination is visible for the question, not because the competitor published more posts.

    Review recurring external destinations for relevance, editorial legitimacy, freshness, and fit with the buyer’s decision. Correct inaccurate profiles you are authorized to manage. Where you do not control publication, pursue inclusion by offering verifiable information or genuinely useful evidence. Don’t fabricate consensus, manipulate community pages, or copy the structure of a cited page without adding value.

    Measure whether the narrative improved

    Use the same prompt portfolio and score each observation against the baseline:

    • Presence: the share of tracked prompts in which your brand appears in a relevant context
    • Accurate framing: the share of appearances that use the intended category, audience, and use case
    • Factual integrity: the number and severity of stale, conflicting, or unsupported claims
    • Recommendation fit: whether you appear when your documented capabilities satisfy the stated constraints
    • Source coverage: which owned and external domains are repeatedly displayed or associated with the answer
    • Content reuse: which maintained pages or knowledge objects support several valuable prompts without spawning duplicate URLs

    Do not collapse these measures into a vanity score too early. An increase in mentions is not a win if the descriptions are inaccurate. A missing mention is not necessarily a failure if the prompt asks for a capability you do not provide. The goal is qualified visibility: being selected for the questions you can answer truthfully and supported by evidence that a buyer can inspect.

    You also cannot force an AI system to cite, phrase, or recommend your brand in a particular way. Optimization improves retrieval eligibility and reduces ambiguity; it does not create editorial control over generated answers.

    For your next working session, capture the baseline before changing a page. Then choose the clearest gap with an addressable cause: a crawl barrier, a contradiction, a buried answer, weak supporting evidence, or an absent external reference. Fix that gap, repeat the same test, and expand only when the result shows what the next investment should be.

    References


  • AI Search Visibility in 2026: A Practical Operating System

    AI Search Visibility in 2026: A Practical Operating System

    You can keep your blue-link rankings and still lose the moment that matters. If an AI answer resolves the question before a click, the customer may never see your result, visit your site, or encounter the message you worked to rank.

    The 2026 response is not to discard SEO for a new acronym. It is to manage visibility at the answer level: where your brand appears, what role it is given, which claims are cited, and whether the answer moves a qualified buyer toward you. Here is how to turn that into a repeatable operating process.

    Key takeaways

    • Keep technical SEO and organic rank tracking, but add measurement for mentions, citations, recommendations, accuracy, and downstream action.
    • Monitor a fixed portfolio of decision-oriented prompts instead of checking a few flattering questions whenever someone asks for an AI visibility update.
    • Build pages around clear claims, evidence, scope, comparisons, and next steps. Generic prose gives an answer engine little reason to select or cite you.
    • Test across the AI experiences your customers use. A strong result in one engine does not establish visibility in the others.
    • Treat structured data as a machine-readable description of visible facts, not as a switch that guarantees inclusion in an AI answer.

    Reset your definition of search visibility

    AI search is no longer a side experiment that can be represented by one chatbot screenshot. Reported mid-2026 figures put ChatGPT at 900 million weekly active users, Gemini at 900 million monthly active users, and the share of consumers starting searches with AI at 37%. The weekly and monthly figures describe different windows, so they should not be compared as if they were the same metric. The consumer figure is also better treated as directional market evidence than as a forecast for your own audience.

    Google’s AI interfaces add another layer of scale. Reported 2026 reach put AI Mode at 1 billion users and AI Overviews at 2.5 billion. Do not convert those headline counts into a traffic projection. Their practical value is showing that synthesized answers have become an interface you need to manage, not merely a feature to watch.

    A ranking tells you that a page is eligible to be found in a conventional result set. AI visibility asks several additional questions: Was your brand selected for the answer? Was your site cited? Was the description accurate? Were you recommended, merely mentioned, or used as background evidence? Did the answer create a measurable business response?

    Visibility layerQuestion to answerEvidence to capture
    EligibilityCan the relevant page be accessed, rendered, indexed, and understood?Indexing state, canonical URL, rendered content, internal links, and structured data
    SelectionDoes the engine use your brand or page when constructing the answer?Brand mentions, linked citations, quoted claims, and the prompts that triggered them
    RepresentationDoes the answer describe your brand, product, and limitations correctly?Accurate claims, unsupported claims, omitted qualifiers, and conflicting facts
    ConsiderationAre you presented as a relevant option for the user’s decision?Recommendation position, comparison context, alternatives named, and reasons given
    ResponseDoes visibility produce a useful next action?Qualified visits, branded searches, assisted conversions, leads, and sales outcomes

    Your existing SEO dashboard covers part of the eligibility layer. Keep it. Then add the other layers instead of forcing mentions, citations, traffic, and conversions into the familiar language of keyword positions.

    Build a prompt portfolio around real decisions

    Blank symbol-marked cards are grouped around a faceted decision node and connected by colored threads on a studio table.

    A keyword list records phrases. A useful AI visibility program records decisions. The same broad subject can produce very different answers when the user adds a budget, audience, constraint, location, use case, or comparison. That context affects whether your brand is relevant at all.

    Choose prompts from the buyer’s work

    Begin with one product line or service area. Pull recurring questions from sales calls, support tickets, on-site search, paid-search terms, community discussions, and customer research. Convert them into the kinds of decisions a person delegates to an answer engine:

    • Learn: What is the problem, how does it work, and what terminology does the buyer need before evaluating options?
    • Compare: Which approaches or products fit a stated use case, and what trade-offs separate them?
    • Verify: Does a named option support a required feature, integration, market, policy, or technical constraint?
    • Choose: Which options should a buyer shortlist for a specific situation, and why?
    • Act: What should the buyer check, prepare, calculate, or ask before purchasing or implementing?

    Include branded and unbranded prompts, but report them separately. An unbranded prompt tests discovery and consideration. A branded prompt usually tests representation: whether the engine understands what you do, who you serve, how you differ, and where your limits are. Combining the two can make visibility look healthy even when new buyers never encounter you.

    Give every monitored prompt a durable record. Capture the exact wording, target audience, market, decision stage, intended fact, relevant page, engine, account state, location context when applicable, test date, answer, citations, competitors mentioned, and your brand’s role. If you change the wording, save it as a new prompt version. Otherwise, you cannot tell whether the answer changed or the question did.

    Test the environments that can change the answer

    ChatGPT-only monitoring is now an incomplete view of the market. Statcounter’s March 2026 data placed Gemini ahead of Perplexity as the second-largest source of AI chatbot referrals. That movement matters less as a league table than as a warning: engine mix changes, and visibility does not transfer automatically from one answer system to another.

    Track ChatGPT, Gemini, Perplexity, Google AI Mode or AI Overviews where available, and any other answer environment that produces meaningful discovery in your category. Use the same core prompts in each one. Then retain engine-specific prompts only when a platform supports a distinct customer behavior you actually need to measure.

    Account context also matters. Google’s Personal Intelligence reached all U.S. users in 2026, making a single signed-in result especially unsuitable as a universal view of what the market sees. When possible, compare a clean or minimally personalized session with a normal signed-in session. Log the difference instead of averaging it away.

    Do not call one favorable answer a win or one absence a loss. Answers can vary across runs, contexts, and product changes. Your fixed prompt portfolio is what turns those unstable observations into evidence: the same questions, checked under documented conditions, over time.

    Create pages an answer engine can use without guessing

    A page can be comprehensive and still be difficult to use in an answer. The problem is often not word count. It is that the key claim is buried, the subject is unnamed, the scope is unclear, or the evidence sits far from the sentence it supports.

    Build an answer asset, not a keyword container

    Give each important page a primary decision to resolve. Then make its answer inspectable:

    • State the answer early. Name the product, method, audience, or problem directly. Do not make a crawler or a reader infer the subject from pronouns and slogans.
    • Define the scope. Add the market, product version, eligibility rule, date, or use-case qualifier that determines when the claim is true.
    • Attach evidence to the claim. Place the methodology, primary documentation, calculation, policy, or clearly labeled first-party data near the statement it supports.
    • Expose the trade-off. Explain when another approach is more suitable. A bounded claim is easier to trust than a universal claim that collapses under scrutiny.
    • Resolve the next question. Link to the specification, comparison, implementation instructions, pricing context, or contact path that moves the reader forward.

    Write important facts as atomic statements. A reusable fact names its subject and predicate clearly: the product supports a named task; the service is available in a named market; the policy applies under stated conditions. Keep promotional adjectives out of these claim units. An engine cannot verify that something is transformative, seamless, or best-in-class unless you supply a defined comparison and defensible evidence.

    Comparison pages need particular discipline. Use consistent criteria, disclose where an option does not fit, show the date or version when capabilities can change, and link each consequential claim to its evidence. Do not create a matrix merely to insert your brand into every category. A comparison that hides constraints can produce the wrong kind of AI visibility: confident misrepresentation.

    Align structured data, technical access, and entity facts

    JSON-LD can make the page’s declared meaning easier to parse, but it must agree with the visible content. Use the most specific Schema.org type that truthfully describes the page and entity. Organization markup should carry stable identity fields. Article markup should match the visible headline, author, and dates. Product or Service markup should describe attributes actually presented to users. FAQPage markup should represent real, visible questions and answers rather than hidden keyword variations.

    Schema does not create authority, repair weak evidence, or guarantee a citation. Think of it as a consistency layer. If the copy says one thing and the JSON-LD says another, fix the underlying content model instead of adding more properties.

    Run a technical check on every page attached to a high-value prompt. Confirm that the intended URL returns normally, carries the right canonical, is not excluded by a noindex directive, exposes the important content in the rendered page, appears in the appropriate sitemap, and receives descriptive internal links. Review robots policies for search crawlers and AI agents separately. Changing those policies can affect security, infrastructure load, and content-licensing choices, so coordinate with the appropriate technical and legal owners before opening access broadly.

    Then reconcile the facts beyond the page. Your site, company profiles, product documentation, press materials, partner listings, and other maintained public records should agree on the brand name, category, offering, audience, availability, and current capabilities. Remove obsolete claims where you control them. When conflicts cannot be removed, publish a clear, dated statement on the canonical page so the current position is unambiguous.

    Use a scorecard that shows what to fix next

    A hand adjusts an unlabeled modular control console with lenses, evidence links, indicator lights, and decision-path components.

    AI visibility is not one percentage. A composite score can be useful for an executive trend line, but it should never replace the underlying measures. Presence, citation, accuracy, consideration, and business response fail for different reasons and require different owners.

    Keep the underlying measures separate

    • Presence rate: the share of eligible monitored prompts whose answers mention your brand. Report it by engine, intent, market, and branded versus unbranded prompt.
    • Owned citation rate: the share of checked answers that link to a page you control. Also record when your brand is mentioned but a third party receives the citation.
    • Representation accuracy: the share of captured brand claims that are supported, current, and correctly qualified. Flag harmful errors separately so they are not diluted by many harmless statements.
    • Consideration rate: the share of relevant choice or comparison prompts where your brand is recommended or shortlisted, not merely named in passing.
    • Qualified response: the visits, branded searches, assisted conversions, leads, or revenue events connected to AI discovery. Keep unattributed traffic separate rather than assuming that every direct visit came from an answer engine.

    Save the answer itself alongside the score. A mention classified as positive can still contain an outdated limitation. A citation can support a competitor rather than you. A recommendation can target the wrong audience. The captured language is what lets a content, product, PR, or legal owner understand the actual failure.

    Diagnose the failure before editing the page

    • If you are absent across engines, first check relevance, access, entity clarity, and whether you have a page that directly resolves the monitored decision.
    • If you are mentioned without an owned citation, improve the page that should substantiate the claim. Make its answer, evidence, scope, and identity clearer.
    • If the answer is wrong, locate conflicting public facts before adding new copy. More content will not resolve a contradiction if the obsolete version remains prominent.
    • If you are cited but not considered, inspect the role your page plays. Informational authority does not automatically establish product fit; a comparison or use-case gap may remain.
    • If visibility produces visits but no useful action, check prompt intent, landing-page continuity, and the next step. The engine may be sending curious researchers rather than qualified buyers.
    • If results swing between checks, expand the run history and segment by environment. Do not present volatility as a durable gain or loss.

    Turn monitoring into an operating cadence

    Run the fixed prompt portfolio on a regular schedule and preserve exact outputs. Review misses in a recurring working session. Group them by failure layer, assign an owner, change the smallest relevant asset, and rerun the affected prompts after the update is available. Revisit the portfolio when customer questions, products, markets, or engine interfaces materially change.

    Ownership should follow the failure. SEO owns crawlability, indexation, internal discovery, and page targeting. Content owns answer structure and claim clarity. Product and legal owners validate changing capabilities, restrictions, and policies. PR and reputation teams address contradictory or weak external representation. Analytics connects exposure to qualified response.

    This cross-functional model is already becoming part of mainstream marketing operations. More than 750 marketing leaders gathered for 13 sessions in April 2026 focused on strategy, team structure, and measurement in the AI era, with companies including OpenAI, LinkedIn, Figma, Webflow, Reddit, Expedia, Stripe, G2, and others represented. The useful signal is organizational: AI visibility touches too many systems to remain an occasional SEO report.

    Start with one commercially important product line, a stable prompt sheet, and one accountable owner for the evidence log. Repair the highest-intent inaccurate or absent answer first, then verify whether the change affected selection, representation, and response. That gives you a working AI visibility loop instead of another dashboard nobody knows how to act on.

    References