You want Google Ads automation to remove repetitive work, not remove your control over spend. The problem is that an automated campaign can look efficient inside the platform while attracting weak leads, claiming conversions that would have happened anyway, or scaling a creative idea that has never proved incremental value.
The answer is not to choose between manual management and full autonomy. Build a control system in which machines execute within explicit boundaries, experiments establish causality, and a person remains accountable for the objective, economics and exceptions.
Key takeaways
Automate repeatable execution, but keep conversion definitions, economic thresholds, exclusions and stop conditions under human control.
Fix the conversion signal before optimizing against it. Faster optimization only magnifies a bad definition.
Treat attributed conversions and incremental conversions as different measures. Attribution assigns credit; incrementality tests whether advertising caused an additional result.
For a Demand Gen asset uplift experiment, isolate one creative variable, use a 50/50 cookie-based split, protect the budget for at least four weeks and aim for at least 50 conversions across the test groups.
Scale only when a change passes two gates: it produces acceptable business economics and it operates without violating your controls.
Choose exactly what automation is allowed to control
Automation is not one switch. Bidding, budgets, keyword or query expansion, audiences, creative, campaign construction and landing-page testing are separate control layers. Give each layer its own permission, boundary and owner.
Your dashboard says advertising is working. ROAS is up, automated campaigns are claiming conversions, and conversational AI is opening new inventory. But the decision in front of you is harder: which spending actually created revenue that would not have happened otherwise?
You can answer that question without waiting for perfect attribution. Separate platform-reported performance from incremental lift, measure the return on the next dollar rather than the average dollar, and treat new AI placements as controlled learning investments. That gives you a practical basis for scaling, holding, or cutting spend.
A high ROAS can still describe demand capture
Platform ROAS answers a narrow question: how much revenue did the platform attribute to ads relative to their cost? It does not tell you how many of those purchases required the ads.
That distinction becomes important when automated systems can concentrate spending around branded searches, repeat visitors, existing customers, and people already close to buying. The platform may be accurately recording its involvement while claiming revenue that would have arrived through direct, organic, or another channel. The number is useful for optimizing activity inside the platform, but it is not causal proof of growth.
Before you increase a campaign budget, ask three separate questions:
Did the platform influence conversions? Platform attribution, CPA, and ROAS can help answer this.
Did advertising cause additional conversions? A controlled incrementality test is needed to estimate this.
Will the next block of spending remain profitable? Marginal return and contribution economics answer this better than average ROAS.
Use the right calculation for each decision
Attributed ROAS equals platform-attributed revenue divided by ad spend. Use it to compare campaigns under the same attribution rules and improve execution within a platform.
Incremental revenue is the difference between the outcome for an exposed group and the estimated outcome for a comparable unexposed group, after accounting for relevant baseline differences.
Incremental ROAS equals incremental revenue divided by the advertising cost required to produce that lift. Use it to decide whether the campaign adds enough business value to keep funding.
Marginal ROAS equals the change in incremental revenue divided by the change in spend. Use it to decide whether an additional budget block is worth buying.
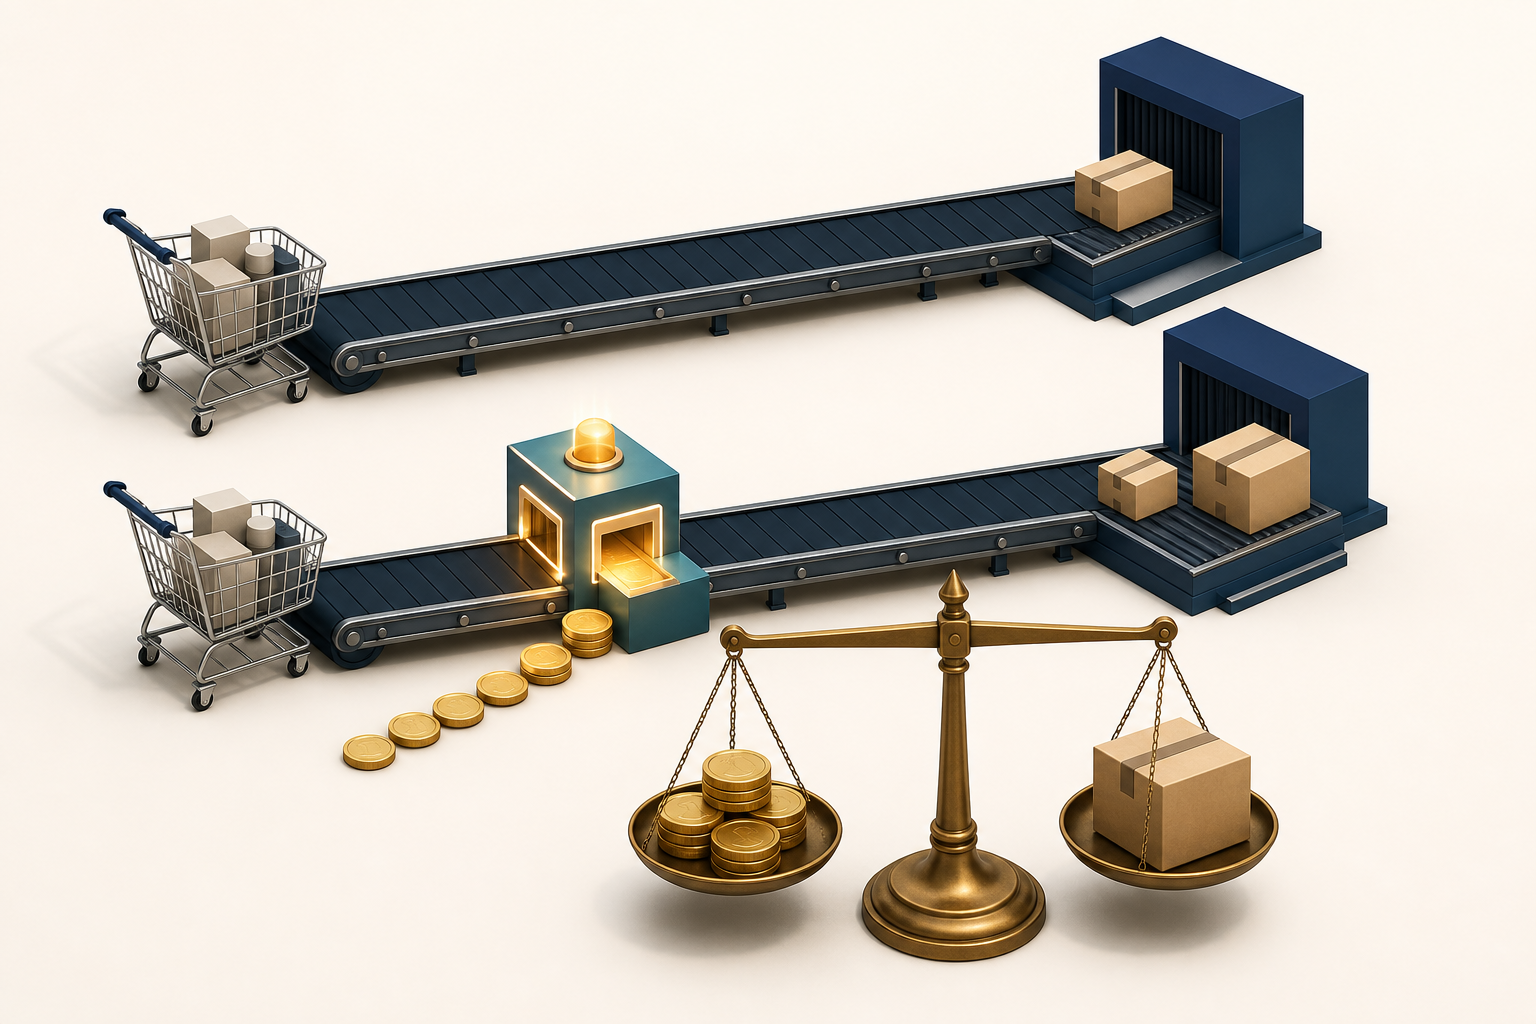
The average and marginal numbers can point in opposite directions. A campaign that produces $50,000 from its first $10,000 has a 500% average ROAS. If another $5,000 produces only $5,000 more revenue, the combined average still looks respectable at roughly 366%, but the marginal ROAS on the added spend is only 100%.
Do not call that final dollar break-even merely because one dollar of spend returned one dollar of revenue. Product costs, fulfillment, payment fees, returns, sales commissions, and other variable costs can make a 100% revenue ROAS unprofitable. Convert incremental revenue into incremental contribution before approving more budget. If margins differ by product or customer segment, calculate contribution at that level instead of applying one blended percentage to everything.
Build a measurement ladder instead of one master metric
No single metric can optimize campaigns, prove causality, and allocate the next dollar. A measurement ladder gives each metric a specific job and prevents a familiar dashboard number from being stretched beyond what it can establish.
Decision
Primary evidence
What that evidence cannot prove alone
Which bid, audience, or creative should run?
Platform conversions, CPA, and attributed ROAS
Whether the advertising caused the conversion
Should the campaign keep receiving money?
Incremental lift, incremental ROAS, and contribution
Whether a larger budget will perform at the same rate
Where should the next budget block go?
Marginal incremental revenue or contribution
How performance will change after a major market or product shift
Is the brand gaining visibility in AI answers?
Paid exposure and unpaid AI mentions measured separately
That either form of visibility caused profitable demand
Run an incrementality test that matches the business question
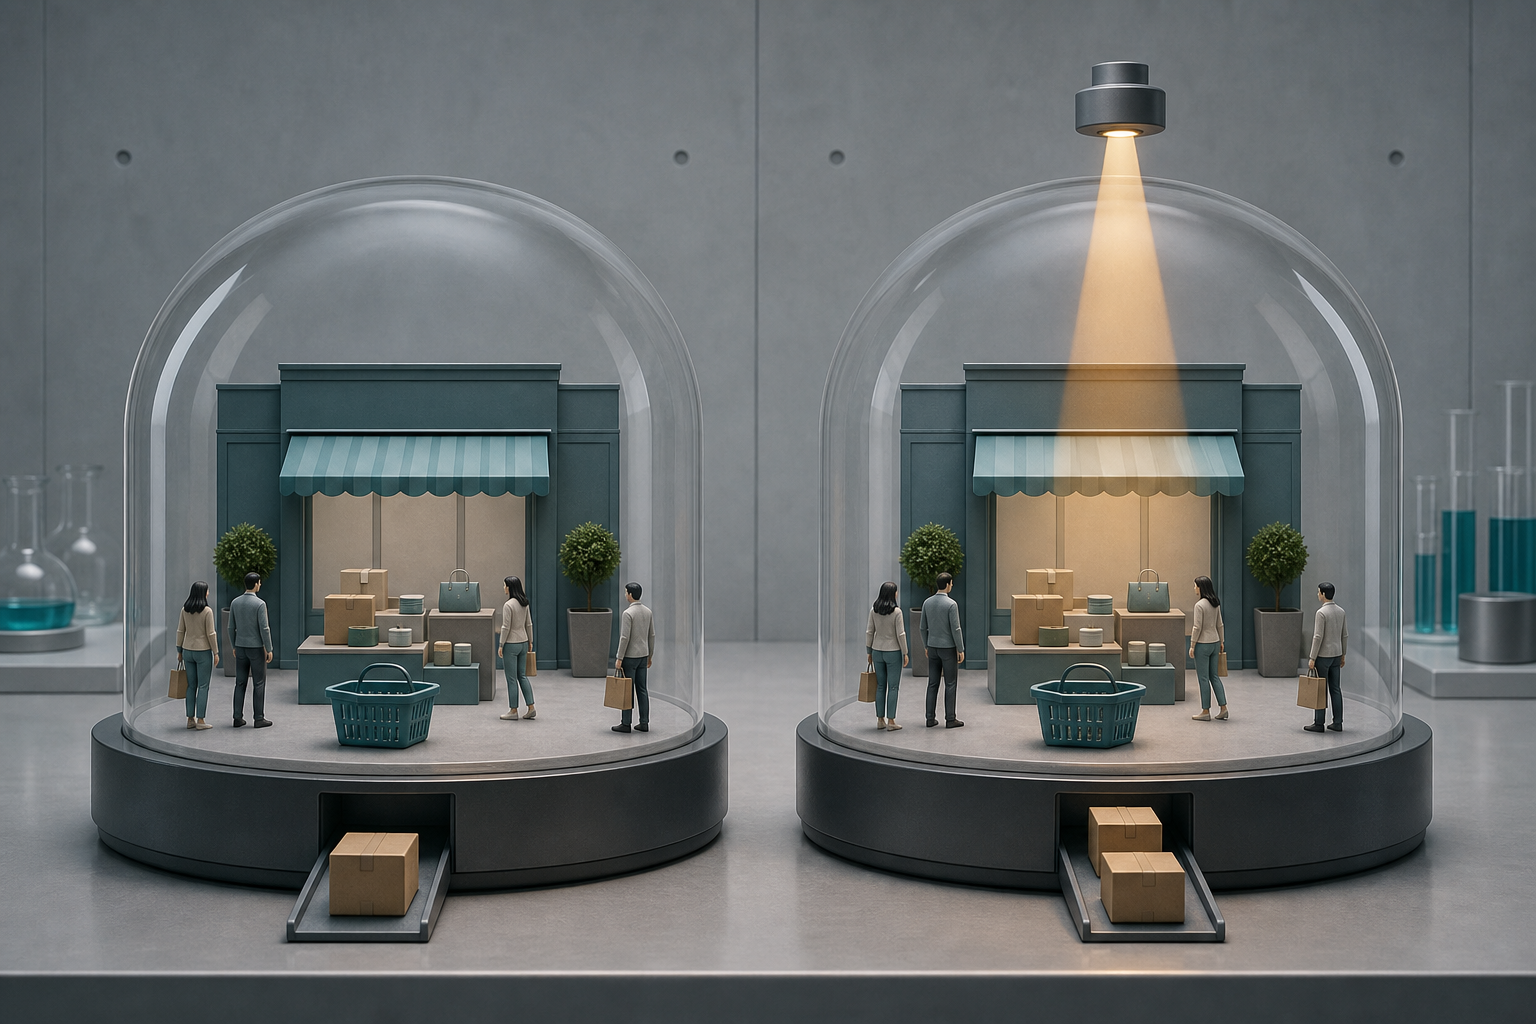
You do not need a perfect measurement laboratory. You do need a credible counterfactual: an estimate of what would have happened without the advertising.
Choose one business outcome before launch. Use completed revenue, gross contribution, qualified pipeline, new customers, or another outcome tied to the decision. Do not replace it mid-test with whichever platform metric looks strongest.
Choose a control design. Comparable geographic markets, randomized audience holdouts, platform lift tests, audience exclusions, and controlled spend reductions can all create evidence beyond ordinary attribution. Geo splits and audience holdouts are especially useful when user-level journeys cannot be observed cleanly.
Protect the contrast. Record which campaigns, markets, audiences, promotions, and prices differ between treatment and control. A large promotion in only one group can look like advertising lift even when the ad had little effect.
Record the exposure rules. Preserve campaign settings, eligibility, placement types, creative versions, market coverage, and any platform product changes. This matters more in AI inventory, where formats and reporting can change while the channel is still maturing.
Let the test cover the decision cycle. A test that ends before delayed purchases or qualified leads can mature will favor channels with short feedback loops. Set the observation window from the actual buying process, not from a convenient reporting date.
Report uncertainty with the result. A positive point estimate from a small or volatile control group is not automatically a scalable win. If the result is too noisy to distinguish lift from normal variation, enlarge the test unit, repeat it, or classify the conclusion as unresolved.
Maintain a test ledger with the hypothesis, primary outcome, treatment and control definitions, launch and end conditions, known confounders, result range, and budget decision. That record stops teams from remembering only successful tests and makes later retesting much faster.
Write the pilot brief before negotiating inventory
State the user moment. Name the conversational situation you expect to influence, such as category comparison, product research, retailer selection, or troubleshooting. A generic awareness objective is too broad to diagnose.
Define an exposure. Establish whether the platform reports a served impression, visible placement, interaction, click, conversation, or another unit. Do not compare CPMs until you know what the impression represents.
Name one primary outcome. Choose incremental qualified visits, incremental orders, incremental contribution, or qualified pipeline. Treat impressions and clicks as diagnostic signals rather than proof of growth.
Set the economic boundary in advance. Calculate the maximum acceptable acquisition cost or minimum contribution return from your own unit economics. If the required commitment would displace a proven campaign or consume the budget needed for a valid control, wait.
Specify the control. Use an unexposed geography, audience, eligible period, or other comparable unit where the placement will not run. If the seller cannot support or tolerate a credible comparison, classify the investment as exploratory rather than performance-proven.
Preserve evidence. Export the available delivery, market, tier, placement, creative, billing, and outcome data. Note reporting-definition changes so a product update is not mistaken for a performance change.
Set a stop rule. Decide what level of economic loss, reporting failure, brand-safety concern, or control contamination ends the test. The novelty of the format is not a reason to ignore an invalid experiment.
Keep paid presence separate from earned AI visibility
A sponsored brand appearing near a recommendation is not the same as a model selecting, citing, or mentioning that brand without payment. Early placements may influence the journey indirectly by making a sponsored retailer more prominent among recommendations, even when the underlying answer is presented as independent from the ad.
Measure three lanes separately:
Paid AI delivery: eligible exposure, served placements, interactions, clicks, cost, and available conversion signals.
Earned AI visibility: unaided brand mentions, citations, recommendation presence, and factual accuracy across a fixed set of representative prompts.
Business effect: incremental visits, qualified leads, new customers, revenue, and contribution against a control or credible baseline.
This separation protects your AEO and GEO work from a false success signal. Paid exposure can increase while unpaid recommendation visibility falls, or an AI system can mention the brand more often without creating profitable demand. Neither outcome should be credited to the other without a test.
Move budget according to marginal contribution
The AI shift does not make established channels irrelevant. IAB/PwC figures put U.S. search advertising revenue at $114.2 billion in 2025 within a $294.6 billion digital advertising market. Digital video reached $78 billion after 25.4% growth, while social reached $117.7 billion after 32.6% growth. The ten largest companies controlled 84.1% of the market.
Those market totals describe where money went, not where your next dollar belongs. A rapidly growing channel can be unprofitable for your offer, while a slower-growing channel can still produce strong incremental contribution. Concentration also means the same large platforms often control inventory, optimization, and attribution. Use their reporting to manage campaigns, but require independent business outcomes or controlled lift before treating claimed conversions as proof.
Use a repeatable capital-allocation cycle
Rank current channels by marginal contribution. Use the most recent credible spend change or controlled test, not lifetime average ROAS.
Choose the next observable budget block. It should be large enough to create a measurable change but small enough that a weak result does not materially damage the plan.
Estimate the expected range. Record a low, central, and high outcome using evidence from your tests and unit economics. Do not convert an uncertain pilot into a single precise forecast.
Move one block from the weakest expected marginal use to the strongest. Keep major promotions, pricing changes, and other confounders visible so they do not receive advertising credit.
Remeasure after the change. Marginal returns usually change with spend. A channel that deserved the previous increase does not automatically deserve the next one.
It also helps to classify spending by purpose. Core campaigns have repeatable causal and economic evidence. Experimental campaigns buy information about new inventory, audiences, or creative. Verification spending retests old assumptions after platform, product, or market changes. A brand-defense campaign may remain strategically valuable despite low measured incrementality, but label it as protection rather than presenting it as growth. That makes the trade-off explicit.
Key takeaways
Platform ROAS measures attributed performance; it does not establish how much revenue advertising caused.
Incrementality tells you whether a campaign created an outcome that would not otherwise have occurred.
Marginal contribution, not blended ROAS, should determine whether the next budget increase is economically sound.
Conversational AI ads need a defined exposure unit, control, business outcome, economic limit, and stop rule before a substantial commitment.
Paid AI placements, earned AI visibility, and business impact belong in separate measurement lanes.
Market growth identifies where advertisers are moving, but your own causal evidence and unit economics should determine where you move.
For your next budget review, replace the single ROAS column with six fields: attributed return, incremental lift, incremental contribution, marginal return, confidence level, and next test. Mark an untested channel as unproven rather than successful or failed. Then fund the next measurable budget block where the expected marginal contribution is strongest. AI formats will keep changing; that decision discipline will remain useful even when the placements do not.
Your PPC dashboard says conversions are up. Revenue, order value, or sales quality says otherwise. That gap usually means the account is optimizing for the easiest recorded action, not the outcome your business actually needs.
A conversion-focused PPC strategy fixes the problem in a specific order: define the valuable outcome, improve the signals sent to the platform, separate different kinds of intent, and test changes against business value. Automation can then help you pursue the right result instead of efficiently producing the wrong one.
Start with the conversion signal you actually want
A conversion is whatever your tracking setup labels as a conversion. It isn’t automatically a sale, a qualified lead, or a profitable customer.
This distinction matters because automated bidding learns from the outcomes you feed it. If a content download, an unqualified form submission, a valuable phone call, and a completed purchase all look equivalent, the system can favor whichever action is easiest to generate. Weighting conversion actions by their likelihood of producing value gives the platform a better representation of what the business wants.
Begin with a one-sentence campaign objective:
Acquire the right customer for this offer at an allowable cost, measured by the most reliable purchase, qualified-lead, revenue, or repeat-value signal available.
Then audit every conversion action against that objective:
List every action currently counted in campaign reporting and bidding.
Identify the business outcome that happens after each action: qualification, sale, revenue, retention, or no meaningful progress.
Classify the action as a primary outcome, a useful secondary signal, or a diagnostic event.
Assign relative values only where you can defend the differences with business logic or downstream data.
Remove weak proxy actions from optimization when they compete with stronger outcomes.
Observed action
How to treat it
Question to answer first
Purchase with recorded revenue
Use as a primary value signal when the revenue is reliable
Does revenue reflect the full order without duplicates or missing transactions?
Qualified phone call or sales-ready lead
Weight according to its downstream likelihood of becoming a customer
Can you distinguish a qualified inquiry from support, spam, or a poor-fit prospect?
Unqualified form submission
Keep secondary until qualification data proves its value
What share reaches the next meaningful sales stage?
Page view, content download, or other micro-conversion
Use for diagnosis or audience building, not as a substitute for revenue
Does this action predict a valuable outcome, or is it merely easy to complete?
A phone call isn’t inherently more valuable than a form submission. It deserves more weight only when your own qualification and sales data show that it is more likely to create value. The same rule applies to any conversion hierarchy: evidence should determine the weight, not a generic PPC convention.
Google’s planning direction reinforces the need for clear outcome signals. Performance Planner has stopped supporting Display and Video planning as well as impression-share-based plans, while its supported scope centers on conversion-oriented campaign types such as Search, Shopping, App, Demand Gen, Local, and Performance Max. That doesn’t make awareness activity worthless. It does mean you need your own explanation of what upper-funnel spend contributes instead of treating impressions as sufficient proof.
Don’t invent precise values merely to satisfy an automated system. False precision can redirect real budget. If the downstream value is unknown, preserve the action for reporting, investigate its relationship to sales, and keep the uncertainty visible until you have a defensible signal.
Route each kind of intent to the right campaign treatment
Conversion-focused targeting begins before you select a match type or audience. You need to know what the person is trying to accomplish and how close that intent is to a decision.
For every meaningful query or audience, ask three questions:
Who has a present problem and is likely to act now?
Who could become a buyer after an objection is answered?
Who is unlikely to buy because the offer, use case, price, or customer profile doesn’t fit?
This classification should change the ad, landing page, bidding signal, and degree of structural control. It shouldn’t remain a persona exercise in a planning document.
Use precision where the intent justifies it
High-intent, high-value terms can merit dedicated control. Selective single-keyword ad groups may improve message relevance and query precision where one term represents commercially important demand. That doesn’t justify rebuilding an entire account around single-keyword structures. Reserve the added maintenance for cases in which the intent and potential value make it worthwhile.
Competitor searches can also represent developed purchase intent. The person already understands the category and may be evaluating alternatives. A competitor campaign therefore needs a clear reason to choose your offer and a relevant landing page; a generic page wastes the intent you paid to capture.
Target Impression Share is another deliberate exception. It may support brand defense or visibility on strategically important non-branded terms, but it pursues presence rather than conversion efficiency. Use it only when visibility itself is the stated objective and the business accepts the possible efficiency tradeoff. Don’t present the result as a conventional acquisition win if cost per valuable outcome deteriorates.
Let automation explore inside visible boundaries
Broad match can discover demand you didn’t anticipate, but exploration needs a feedback loop. Combining it with assertive negative-keyword management lets the platform search broadly while you continually shape what qualifies. Several useful PPC tactics, including selective SKAGs, controlled broad match, competitor bidding, conversion weighting, and feed refinement, work because they improve the signals or boundaries around automation rather than rejecting automation outright.
Use this query-review loop:
Inspect the actual search query, not just the keyword that matched it.
Label its intent, customer fit, likely value, and relationship to the offer.
Exclude irrelevant or consistently poor-fit themes with negative keywords.
Move commercially important themes into a more controlled treatment when dedicated ads, bids, or landing pages would change the outcome.
Feed useful language from real queries back into ad copy and landing-page messaging.
Top-of-funnel queries require a different scorecard. They may contribute by building remarketing pools or strengthening audience signals even when their direct conversion rate is weak. Keep that spend identifiable, state the support role in advance, and don’t allow upper-funnel activity to hide inside the economics of high-intent acquisition.
Retargeting audiences can serve as a controlled environment for message and creative tests because those users already have some familiarity with the offer. A winning message can then be tested with colder audiences. Familiarity still changes behavior, so treat the retargeting result as a promising hypothesis rather than proof that the same creative will work everywhere.
Diagnose performance from revenue backward
When performance weakens, broad questions such as why did ROAS fall tend to produce broad answers. Diagnose the chain from the business result backward:
Spend to click to conversion to qualified outcome to sale to revenue to repeat value.
The first broken relationship is usually more actionable than the loudest metric in the interface. Use the following patterns as hypotheses to investigate, not automatic verdicts:
If conversion volume rises while Value/Conv. falls, the account may be finding easier but lower-value customers. Inspect audience, query, product, and order-value mix before celebrating the extra conversions.
If raw leads increase while qualified leads do not, improve the conversion hierarchy and customer filters before buying more traffic.
If qualified lead quality remains stable but sales decline, inspect the landing-to-sales handoff, offer, and downstream process rather than forcing a media-only explanation.
If relevant queries decline, examine match behavior and negatives before rewriting every ad.
If click-through performance improves without a better business result, the new message may be attracting attention without improving buying intent.
This is especially important when B2B and B2C demand overlaps. A campaign may collect many inexpensive consumer conversions while losing the higher-value business buyers it was meant to acquire. In that situation, stronger first-party audience inputs, specific audience segments, and value rules can emphasize B2B intent. That approach has been used to address lagging average order value reflected in Google Ads Value/Conv., but it still requires measurement: targeting a supposedly valuable group doesn’t guarantee valuable orders.
Evaluate economics at the deepest reliable level you possess. For ecommerce, revenue per order is more informative than order count, while contribution after variable costs is more useful than revenue alone when the necessary financial data is available. For lead generation, an expected value model can combine qualification likelihood, close likelihood, and customer economics. Use definitions approved by the people responsible for finance and sales rather than creating a parallel PPC version of profitability.
Customer lifetime value can justify a different acquisition decision from first-order revenue, but only when retention and repeat purchases are observable. Ask why customers stay, what causes another purchase, and which segments actually retain. Don’t raise allowable acquisition costs because an AI tool or a planning assumption produced an attractive lifetime-value story.
When you alter conversion values, audience rules, targeting, or campaign structure, log the change and the intended effect. Avoid simultaneously changing so many decision variables that you can’t tell whether performance moved because of better traffic, a different signal, a new message, or a changed offer.
Use AI to produce testable hypotheses, not synthetic certainty
Use prompts as structured briefs. Supply the offer, intended customer, price context, conversion action, observed performance pattern, and any known constraints. Then ask for hypotheses that can be checked against real query, CRM, sales, or order data.
Purchase intent prompt: Separate the audience into people likely to act now, people who need persuasion, and people who are poor fits. For each group, identify the observable evidence that would confirm or reject the classification.
Emotional context prompt: Identify the fears, frustrations, ambitions, and desired relief that could influence this customer. Distinguish plausible motivations from claims requiring customer evidence.
Objection prompt: Generate three to five credible objections to this offer. For each one, propose a response based on logic, emotion, and proof, but flag any proof the business must substantiate.
Value diagnosis prompt: Given rising conversion volume and falling Value/Conv., propose segment, query, audience, product-mix, and order-value explanations. Rank them by what can be checked with the available data.
Lifetime-value prompt: Explain why a customer might stay, buy again, or expand the relationship. Convert each idea into a retention hypothesis and specify what data would demonstrate that it is real.
The output is not customer evidence. AI can make an unsupported psychological profile sound convincing, invent proof, or favor a neat explanation for a messy performance change. Check proposed motivations against search terms, customer language, objections heard by sales, and observed buying behavior. Delete claims you can’t substantiate.
Turn each surviving idea into a compact experiment card:
Hypothesis: what you believe will change and why.
Audience: the specific intent or customer group being tested.
Variable: the message, creative, landing page, query treatment, audience input, or value signal you will change.
Primary measure: the valuable outcome that determines success.
Guardrails: the quality, cost, average-value, or downstream metrics that must not deteriorate unnoticed.
Decision: what you will scale, revise, or stop after interpreting the result.
A test is useful even when it loses, provided it isolates a meaningful decision. A higher click-through rate with weaker lead quality tells you the message attracted the wrong kind of attention. More conversions with lower order value tells you the platform responded to the signal but the signal didn’t represent enough value. Those are findings you can act on.
Key takeaways
Optimize for the deepest reliable business outcome, not the largest conversion count.
Give different conversion actions different treatment when their downstream value differs.
Apply tight control to commercially important intent and give automated discovery explicit boundaries.
Keep upper-funnel activity visible and judge it by its defined support role, not by impressions alone.
When results weaken, trace the path from revenue backward until you find the first relationship that changed.
Use AI to generate and rank hypotheses, then validate them with customer and performance data.
Start with one campaign, not an account-wide rebuild. Write its economic objective, audit the conversion actions influencing bidding, and inspect which queries or audiences produce the valuable outcome. Make the smallest signal or routing change that addresses the gap, record the expected effect, and let the next decision follow from business results rather than interface activity.
Your paid search account can look healthier while the business behind it gets worse. Cost per conversion falls, the dashboard fills with activity, and automation appears to be working – yet purchases weaken, qualified leads become rarer, or the sales team spends more time rejecting inquiries.
That usually isn’t an automation failure. It is an instruction failure. Automated bidding, targeting, and testing follow the goals you make visible to them. If those goals reward easy actions rather than valuable outcomes, the system can become highly efficient at acquiring the wrong conversions.
Make the business outcome the strongest conversion signal
A bidding system doesn’t independently decide which website action matters to your company. It learns from the conversion actions, values, and campaign goals you provide. When purchases, qualified leads, pageviews, button clicks, and form starts are all treated as optimization targets, frequent low-friction actions can overwhelm the events that produce revenue.
This is the central conversion-quality problem: more conversion data is not automatically better conversion data. A pageview is easier to generate than a sale. A form start is easier to generate than a qualified submission. If the system receives no meaningful value hierarchy, it has a strong incentive to find the predictable action rather than the commercially important one.
Too few signals can also slow learning, so the answer is not to delete every intermediate event. The answer is to distinguish observation from optimization. Keep useful micro-conversions for analysis, audience understanding, and funnel diagnosis, but do not automatically make every event a primary campaign goal.
Build a conversion hierarchy before changing bids
Name the final business outcome. For ecommerce, that will normally be a completed purchase. For lead generation, it may be a qualified lead, an accepted opportunity, or another offline stage that represents genuine commercial intent.
Identify the earliest event that reliably predicts that outcome. A submitted form might be useful if nearly every submission is legitimate. If submissions vary sharply in quality, the stronger signal sits later in the sales process.
Separate primary and secondary actions. Use the commercially meaningful action for bidding. Retain form starts, calls below your qualification standard, page engagement, and similar events as diagnostic signals unless they have demonstrated business value.
Send offline outcomes back to the ad platform. When value is established after a call, review, consultation, or sales conversation, online form tracking alone gives automation an incomplete picture. Offline conversion tracking lets the system learn which clicks created real outcomes.
Use values to express meaningful differences. If two outcomes have materially different business value, representing them as equal conversions hides that distinction. Value-based bidding only helps when the values reflect the hierarchy you actually care about.
Validate the data path. Check that each event fires at the intended stage, is not duplicated, carries the right value, and can be connected to its originating campaign. A sophisticated bidding strategy cannot repair a mislabeled or duplicated conversion.
Do not compensate for sparse final conversions by promoting every available event into the primary goal set. First check whether delayed or offline outcomes are missing. Adding weak signals may increase reported volume while moving optimization farther away from revenue.
Use intent and creative to qualify traffic before the click
Conversion quality starts before someone reaches the landing page. Your keywords, product feed, campaign structure, and ad language determine which searches can enter the funnel. The more freedom you give automated targeting, the clearer those inputs need to be.
This becomes especially important in housing, employment, credit, healthcare, and legal services. Google Ads can restrict website and app remarketing, Customer Match, YouTube interaction audiences, and custom segments in sensitive-interest categories. Housing campaigns may face additional demographic limitations. Even with those controls unavailable, advertisers can still work with keywords, feeds, permitted Google audiences, content targeting, conversion tracking, and certain forms of automated targeting.
When audience history cannot do the qualifying, search intent and creative have to carry more of the load:
Start with the problem expressed in the query. Organize keywords around what the searcher needs, not just the service name your company uses internally.
Use phrase or broad match deliberately. Exact match may miss different ways of expressing the same need, particularly in restricted categories. Broader matching can recover that demand, but it should be paired with meaningful conversion signals and regular query review.
Make the offer specific in the ad. State who the service is for, what is being offered, and any important eligibility boundary that can be communicated lawfully. Clear creative discourages unsuitable clicks before they consume budget.
Keep feeds accurate. For Shopping and feed-led campaigns, titles, categories, prices, availability, and other product attributes shape which searches can surface an item. Feed quality is part of targeting quality.
Separate genuinely different services. If a company offers both sensitive and non-sensitive services, distinct sites or domains can preserve a clean operational boundary. That separation should reflect a real difference in the business and user journey, not an attempt to disguise a restricted service.
Placement changes can complicate the picture. Microsoft has tested a larger, double-row sponsored product carousel in Bing Shopping results, although the format was not visible to every user and should be treated as an experiment rather than a universal layout. More sponsored inventory can increase impressions and clicks without improving the intent of those clicks.
If Shopping traffic rises abruptly, do not assume the campaign has found a better audience. Compare product-level conversion quality, revenue, query composition, and final outcomes before raising budgets. A larger ad surface is an inventory change; it is not evidence that the additional traffic is valuable.
Put automated experiments behind business guardrails
Experiments are valuable because they isolate a proposed change from the existing campaign. The risk appears at the handoff from test result to live account. Google Ads includes an experiment setting that can apply a winning result automatically and is enabled by default. That can shorten the testing cycle, but it also removes the review point where downstream quality problems are often discovered.
The experiment interface allows directional evaluation or statistical-significance thresholds of 80%, 85%, or 95%. It also prevents automatic application when a selected success metric performs significantly worse. The limitation is just as important: an experiment can use only two success metrics, so an unselected third metric can deteriorate without stopping the rollout.
Before launching a test, write down three things outside the platform: the result that would count as a win, the business metric that must not fall below an acceptable level, and the conditions that require manual review. This prevents a visually convincing dashboard from redefining success after the test ends.
When automatic application is reasonable
The change is easy to reverse and has limited reach.
The primary success metric represents a final or strongly qualified outcome.
The second metric protects the most important cost, value, or quality constraint.
No critical business measure sits outside those two metrics.
Conversion tracking has been validated before the experiment starts.
When to require manual review
The test changes the conversion goal, assigned values, or bidding strategy.
The change expands traffic through broader matching, automated targeting, new inventory, or a substantially different feed.
Lead quality is determined offline or only after a meaningful delay.
The campaign operates in a regulated or sensitive category.
The commercial downside of a false winner is larger than the operational cost of reviewing it.
For a manual review, look beyond the two headline metrics. Inspect the conversion-action mix, qualified-lead or purchase rate, revenue or assigned value, search-query and product composition, spend distribution, and any delayed offline outcomes. If the experiment appears to win only because it generated more low-value actions, it has not passed a conversion-quality test.
Diagnose quality loss from the symptom, not the dashboard score
Automation problems leave recognizable patterns. Use the visible symptom to identify which instruction the system may be following, then correct the signal or boundary before making another bid adjustment.
What you notice
Likely mechanism
What to inspect
What to change
Reported CPA falls while qualified-lead or purchase rate falls
An easy micro-conversion is dominating optimization
Primary goals, conversion-action mix, duplicate events, and assigned values
Move weak actions to observation, correct duplication, and optimize toward the final or qualified outcome
Form volume rises but the sales team rejects more leads
The platform sees submission volume but not downstream qualification
Offline outcome imports, attribution identifiers, and the delay between submission and review
Import qualified stages and use them as the stronger bidding signal
Shopping impressions and clicks jump without comparable revenue
More prominent or expanded ad inventory is creating extra exposure
Product-level revenue, query composition, conversion rate, and average order value
Hold budget decisions until final conversion quality is clear; refine products and feed inputs where needed
A sensitive-category campaign has very little eligible traffic
Audience restrictions and narrow matching are constraining reach
Policy status, prohibited audience dependencies, keyword coverage, feeds, and ad specificity
Use compliant intent targeting, permitted audiences, phrase or broad match where appropriate, and clearer qualifying creative
An experiment wins but downstream revenue weakens
The deteriorating business metric was not one of the two protected success metrics
The complete funnel, not only the experiment summary
Reverse or withhold the rollout, redesign the metrics, and keep automatic application off for that test class
Smart bidding has too little useful data
Final outcomes are sparse, delayed, or missing from the platform
Tracking completeness, offline imports, attribution matching, and conversion lag
Repair the final-outcome data path before adding low-intent events as optimization goals
Resist the urge to solve every symptom by loosening targets or increasing budget. Those changes may give the system more room to pursue the same incorrect objective. Fix the definition of success first, then decide how aggressively to scale it.
Key takeaways
Automated bidding optimizes the conversions and values you expose; it does not independently know which actions create revenue.
Keep micro-conversions available for funnel analysis, but make them primary goals only when they are reliable proxies for business value.
For lead generation, send qualified offline outcomes back to the platform instead of asking form submissions to stand in for lead quality.
When remarketing or audience controls are restricted, use search intent, accurate feeds, and self-qualifying creative to shape traffic.
Treat increases caused by new or expanded ad inventory as exposure gains until purchase or lead-quality data proves otherwise.
Review auto-applied experiment settings before launch, especially when an important business metric cannot fit among the two success metrics.
Start your next optimization session in the conversion-goal settings, not the bidding controls. Confirm which actions are primary, trace them to a real business outcome, and identify the quality metric that could deteriorate unnoticed. Once those instructions are sound, automation has something worth scaling.
Your TikTok ad opened strongly, then the cost per acquisition began to climb. Now you have an expensive decision to make: replace the creative, leave it alone, or change the campaign around it.
If you replace the ad too quickly, you can discard a message that still works. If you wait too long, you keep paying for a response that is fading. The better approach is to diagnose which part of the system weakened, refresh only that part, and have the next challenger ready before the decision becomes urgent.
Creative freshness is a performance state, not an age
TikTok ad creative can have a short shelf life, but that does not give every ad the same expiration date. A creative is fresh while it continues to earn the attention and action you bought it to produce. It is tired when its ability to do that deteriorates under reasonably comparable conditions.
That distinction matters because a rising CPA is not, by itself, proof of creative fatigue. Several different problems can produce the same headline result:
Creative fatigue: The audience is responding less strongly to an execution it has repeatedly encountered.
Audience saturation: Delivery is cycling through a limited pool of people, so additional impressions become less productive.
Message exhaustion: The underlying promise or angle no longer creates enough interest, even when it is packaged differently.
Post-click friction: The ad still earns clicks, but the landing page, form, checkout, availability, pricing, or message continuity reduces conversion.
Campaign or measurement disruption: A change in delivery conditions, tracking, optimization, bidding, budget, attribution, or conversion reporting makes the apparent decline difficult to attribute to the ad.
Do not refresh on a calendar simply because an ad has been live for a certain length of time. Use the ad’s own stable performance as the baseline. Compare periods with the same objective, conversion event, market, audience definition, offer, landing page, metric definitions, and material campaign settings. If one of those inputs changed, mark the comparison as contaminated rather than forcing a creative conclusion.
This also prevents a common waste pattern: producing an entirely new batch of videos to solve a problem that actually sits on the website or in campaign delivery. Freshness is useful only when it is attached to a diagnosis.
Diagnose the decline before you retire the ad
Read performance as a sequence. CPM describes the cost of obtaining impressions. Your chosen opening-view or hold metric shows whether the beginning keeps people watching. Click-through rate shows whether the message creates enough intent to click. Conversion rate shows what happens after that click. CPA or ROAS tells you whether the full chain works economically.
No single metric establishes the cause. The pattern across them tells you where to investigate first.
Performance pattern
What it may indicate
What to check next
CPM rises while CTR and conversion rate remain stable
Delivery has become more expensive, but the creative response is not clearly weaker
Review audience, market, placement, bidding, budget, competition, and other delivery changes before commissioning a reshoot
Opening retention and CTR weaken while conversion rate remains stable
The opening execution may be losing its ability to stop and qualify viewers
Test a new opening line, first visual, pacing choice, or problem frame while preserving the body, proof, offer, and landing page
Opening retention remains stable while CTR falls
People continue watching, but the promise, proof, or call to action creates less click intent
Test the benefit, demonstration, objection handling, evidence, and CTA as separate hypotheses
CTR remains stable while conversion rate falls
The main weakness is probably after the click or in the match between ad and page
Audit page availability, speed, form or checkout function, pricing, inventory, offer continuity, and conversion tracking
Frequency rises while CTR falls in the same audience
Repeated exposure is a plausible contributor
Inspect audience overlap and delivery, then introduce a meaningfully different concept rather than a cosmetic edit
CPA deteriorates across many unrelated creatives at once
A shared campaign, auction, audience, site, offer, or tracking issue is more plausible than simultaneous fatigue in every ad
Find the common dependency before judging individual creatives
Likes or comments weaken while CPA remains acceptable
A visible engagement signal changed without evidence that the business result did
Keep the ad eligible and monitor the primary outcome instead of optimizing to a vanity metric
Start the diagnosis with measurement. Confirm that the conversion event still fires, reporting definitions have not changed, and the destination works on the devices and markets receiving traffic. Then check the change log for budget, bid, audience, placement, optimization, offer, page, and attribution changes. A performance chart without that context invites false certainty.
Next, compare the ad with a control and with other live creatives exposed to similar conditions. If only one execution weakens, a creative-specific explanation becomes more credible. If everything declines together, investigate the shared system first. Breakdowns by audience, market, placement, and creative can help you see whether the decline is concentrated or widespread.
Comments can add context, especially when viewers repeat the same objection, misunderstand the promise, or indicate familiarity with the execution. Treat those comments as clues, not as a substitute for performance data.
Avoid universal fatigue thresholds. The amount of evidence you need depends on conversion volume, reporting lag, normal volatility, and the cost of a wrong decision. Define an account-specific comparison window and minimum evidence requirement before the campaign runs. That keeps an isolated bad period from becoming an emergency production brief.
Refresh the layer that has actually lost its pull
A refresh does not have to mean a new concept, creator, script, edit, offer, and landing page all at once. Creative has layers, and each layer answers a different viewer question:
Concept: What situation, problem, or desired outcome is the ad about?
Angle: Which reason should make that outcome matter now?
Hook: What earns attention and identifies the relevant viewer?
Execution: How is the idea expressed through a demonstration, explanation, story, reaction, comparison, or creator-led delivery?
Proof: What makes the promise credible or concrete?
Call to action: What should the viewer do next, and what expectation does the ad set for the destination?
Use the smallest viable refresh
When the opening weakens but downstream conversion remains healthy, start with hook variants. Change the opening line, initial visual, entry point, or pace while keeping the proven promise and destination intact. You are trying to restore attention without discarding the part that still converts.
When people keep watching but fewer click, work deeper in the message. Test a clearer benefit, a more concrete demonstration, stronger proof, a different objection, or a CTA that better matches the next step. A new first frame will not repair a weak reason to act.
When multiple executions of the same idea weaken, stop repainting the concept. Move to a different problem frame, use case, desired outcome, or reason to believe. A new background, caption treatment, soundtrack, crop, or shirt may make a file technically new without giving the viewer a new reason to care.
When CTR holds and conversion rate falls, do not send the problem straight to the editor. Check the destination and the promise-to-page handoff. A more persuasive ad can make the economics worse if it sends additional people into a broken or mismatched conversion path.
Preserve the causal core of a winner
Before changing a successful ad, write down why you believe it works. The answer should name a mechanism, not an aesthetic preference. For example: the problem is recognized immediately, the product is demonstrated without delay, a specific objection is answered, or the ad and landing page make the same promise.
Build adjacent versions around that core. If a demonstration appears to be doing the persuasive work, keep the demonstration while testing new openings or proof. If a particular audience situation drives qualified clicks, keep that situation while changing the format. This gives each replacement a clear inheritance from the winner instead of asking an unrelated idea to reproduce the same result by chance.
Native-looking creative should still be intentional. It can feel appropriate to the feed while maintaining readable captions, audible speech, a visible subject, truthful proof, and a clear next step. Freshness is not an excuse to weaken brand accuracy or make claims the destination cannot support.
Build a creative pipeline that makes replacement routine
Plan the next asset before the current one declines
The worst time to invent a TikTok concept is after a winner has already deteriorated. Maintain a backlog with distinct states: ideas awaiting evidence, concepts ready to script, assets in production, challengers ready to launch, live controls, and retired ads. Every live control should have a next test attached to it.
Use a short concept card for each idea. Record the audience situation, problem, promise, proof, objection, format, CTA, landing page, and the reason the concept should work. This keeps production focused on strategic differences instead of accumulating visually different videos that all say the same thing.
During production, capture modular components: alternative openings, demonstrations, proof elements, objection responses, transitions, and end cards. Keep the raw material and map each component to its concept. Modular production lets you create interpretable challengers without rebuilding every asset from the beginning.
Use names that expose the creative logic. A useful naming structure includes the concept, audience or situation, hook, proof, format, and version. The exact syntax matters less than consistency. Anyone reviewing the account should be able to tell whether two ads represent different concepts or merely different edits.
Test challengers without erasing the signal
Choose the control. Use a relevant live winner or a clearly documented baseline.
Name the hypothesis. State which layer is weakening and why the proposed change should improve it.
Limit the difference. Change the layer under investigation while preserving the parts that still appear healthy.
Keep conditions comparable. Avoid mixing a creative test with major audience, offer, destination, budget, optimization, or measurement changes.
Read the full metric chain. Check attention, click response, post-click conversion, and the primary business outcome using consistent definitions.
Record the result. Log what changed, what remained fixed, the comparison period, relevant delivery context, and the decision.
Turn the result into the next brief. Extend a supported mechanism, challenge an uncertain one, or leave the creative alone when the evidence points elsewhere.
Do not demand that every challenger beat the control on every metric. A hook that attracts more viewers but lowers conversion quality is not automatically better. A less engaging ad can still be commercially useful if it filters for the right people and improves the primary outcome. Decide which metric is the goal and which metrics are guardrails before seeing the result.
Write replacement rules before performance slips
Your operating rule should identify the primary KPI, acceptable guardrails, comparison window, minimum evidence requirement, and action attached to each pattern. Use relative movement against a valid baseline and the account’s normal variation rather than importing a universal percentage from someone else’s campaign.
Keep: The primary business result remains acceptable, even if a secondary engagement metric has softened.
Refresh: The primary result shows sustained deterioration and the metric chain identifies a specific creative layer that is weakening.
Replace the concept: Multiple targeted variants fail to restore the response, or the message itself no longer creates sufficient intent.
Investigate the system: Unrelated ads decline together, conversion tracking becomes uncertain, or post-click performance breaks while click response holds.
Archive: Retire the asset without deleting its history. Preserve the concept, hypothesis, results, and reason for retirement so the same failed test is not unknowingly repeated.
A compact freshness dashboard can make these rules operational. Track the ad and concept IDs, audience, launch date, spend, CPM, selected opening metric, CTR definition, conversion-rate definition, CPA or ROAS, frequency where relevant, status, diagnosed weak layer, and next challenger. Add notes for changes to the offer, page, tracking, or campaign setup. The dashboard should explain the decision, not merely display the decline.
Allocate production capacity across extensions of proven concepts, genuinely new concepts, and ready-to-launch reserves. The right allocation depends on how concentrated your results are and how quickly your team can produce credible replacements. The important part is that exploration continues while a winner is still working.
Key takeaways
A rising CPA is a symptom, not a creative-fatigue diagnosis.
Compare performance only after accounting for changes in delivery, audience, offer, destination, tracking, and metric definitions.
Use the metric chain to locate the weak layer: delivery cost, opening attention, click intent, post-click conversion, or business outcome.
Refresh hooks when the opening weakens, refresh persuasion when click intent weakens, and replace the concept when repeated executions of the same message stop working.
Keep the control stable enough to make challenger results interpretable.
Define keep, refresh, replace, investigate, and archive rules before campaign noise puts the team under pressure.
Before your next TikTok launch, document the control’s working hypothesis and queue a challenger for one identifiable layer. Then write the decision rule before spend begins. That turns creative freshness from emergency churn into a repeatable optimization system.
Your ecommerce dashboard can show that an affiliate, content page, or campaign touched an order. It cannot tell you, by itself, whether that activity created the order. That gap is where apparently healthy revenue can conceal discounts, commissions, and production costs that bought little or no new demand.
If you need to decide what to keep, pause, or scale, ask a harder question: what changed because this investment existed? Answering it turns incrementality from a reporting label into a practical way to allocate your budget.
Key takeaways
Attribution records a touchpoint. Incrementality estimates the sales, customer value, or profit caused by that touchpoint.
A credible ROI calculation needs a counterfactual: what comparable customers, products, or markets did without the investment.
Measure incremental profit after product costs, discounts, commissions, fees, returns, fulfillment, and the investment itself. Attributed revenue is not ROI.
Judge each affiliate by the job it performs. Discovery, comparison, trust, conversion assistance, and checkout interception do not deserve the same commission merely because they appear in the same report.
Organic content should remove a specific buyer uncertainty, express its evidence clearly for machines, and work across search, AI, social, and other discovery environments.
Start with profit that would not exist otherwise
Attribution and incrementality answer different questions. Attribution asks which recorded interaction receives credit. Incrementality asks whether the business outcome would have happened without that interaction.
This distinction produces four useful categories:
Attributed sale: an order assigned to a channel under your reporting rules.
Incremental value: additional value created even when the underlying order might still have happened, such as a larger basket or a conversion enabled by trust the brand could not create alone.
Cannibalized sale: an order credited to a paid touchpoint even though the customer was already likely to buy through an unpaid or less expensive path.
Consider a shopper who reaches checkout and then searches for your brand plus the word “coupon.” A coupon publisher appears, the shopper clicks, and the affiliate platform credits the sale. The touchpoint had high intent, but the brand may have created that intent before the affiliate appeared. If comparable shoppers complete their purchases without the affiliate, the commission is paying for interception rather than growth.
That does not make every coupon or deal publisher unhelpful. A partner may reach an audience you cannot reach, distribute an exclusive offer, increase the basket, or rescue purchases that would otherwise be abandoned. The important point is that high intent is not evidence of incremental value. You still have to test what changes when the partner is absent.
Revenue alone also gives you the wrong economic answer. Use a profit bridge that both marketing and finance accept before the test begins:
Incremental revenue equals revenue from the exposed group minus the revenue you would expect without the intervention.
Incremental operating gain equals incremental revenue minus the product, discount, return, payment, fulfillment, and other variable costs attached to those orders.
Net incremental profit equals that operating gain minus commissions, network fees, media, content production, distribution, and other investment costs.
Incremental ROI equals net incremental profit divided by the investment cost used in the calculation.
Agree on the cost boundary and evaluation period first. Otherwise, one team can present gross revenue while another includes commissions and production costs, leaving both with different versions of “ROI.” For a reusable content asset, document how you will treat its creation cost and future maintenance. For an affiliate campaign, include the commission, discount, platform costs, and any placement fee.
Build a counterfactual before opening the dashboard
You cannot observe the same customer both receiving and not receiving an intervention at the same moment. An incrementality test solves that problem by creating a comparison that estimates the missing outcome.
Name the intervention precisely. Test a specific partner, offer, content asset, or distribution method. “Affiliate” and “organic content” are too broad because they combine activities with different jobs and economics.
Choose the eligible unit. Depending on what you can control, this may be a customer, audience, product group, category, or geographic market. The treatment and comparison groups must be similar enough for the difference to be meaningful.
Choose the business outcome before viewing results. Completed orders, incremental revenue, contribution profit, new-customer profit, or basket value can all be valid. Pick the one connected to the investment’s intended job.
Define the counterfactual. A randomized holdout is the cleanest option when it is operationally possible. Otherwise, use comparable markets, audiences, or product groups. A temporary pause can help, but a simple before-and-after comparison is more vulnerable to promotions, seasonality, inventory changes, and other events occurring at the same time.
Protect the comparison. Keep pricing, inventory, promotions, tracking rules, and other material conditions aligned. Record contamination, such as a coupon leaking into the holdout group or customers moving between exposed and unexposed devices.
Calculate the net difference and apply a prewritten decision rule. Decide in advance what evidence would justify scaling, modifying, retesting, or stopping the investment. Do not move the rule after seeing a favorable revenue number.
When a randomized holdout is not feasible, be candid about the limitation. A matched comparison can inform a decision without proving perfect causality. Record what else could explain the result and reduce your commitment until stronger evidence is available.
Do not switch off a large revenue partner across the whole business merely to satisfy curiosity. That can create avoidable financial exposure if the partner is genuinely incremental. Use the smallest bounded holdout that can answer the decision, preserve a rollback path, and monitor operational effects while the test runs.
Watch for measurement shortcuts that inflate ROI
Treating attributed sales as the baseline: this assumes causation instead of testing it.
Comparing unlike periods: a promotional treatment period and a quiet comparison period cannot isolate the effect of the channel.
Pooling unlike partners: a creator introducing the brand and a coupon page appearing at checkout may average into a respectable channel result while having opposite incremental effects.
Stopping at revenue: a lift can disappear after discounts, commissions, returns, and fulfillment costs.
Judging content only by last-click sessions: content that resolves uncertainty earlier in the journey may influence a sale without owning the final recorded visit.
Ending a test when the result looks convenient: define the stopping condition before launch and avoid making a large decision from sparse or unstable observations.
Judge affiliate partners by the customer decision they change
An affiliate program is not one behavior. Its partners can introduce an unknown brand, shape a comparison, lend trust, distribute an offer, answer a product question, or appear after the customer has already decided to buy. Start your audit by assigning each partner a role.
Partner role
Evidence worth testing
Main measurement risk
Discovery
Additional qualified customers or sales in an exposed audience
Crediting demand created elsewhere
Comparison and evaluation
A change in which product or brand customers choose
Counting shoppers who had already selected your brand
Trust and recommendation
Higher conversion among a comparable audience exposed to the recommendation
Confusing audience affinity with the effect of the endorsement
Exclusive distribution
Sales or customer value unavailable through your owned channels
Paying for an offer the brand could distribute directly
Checkout assistance
Recovered orders, additional basket value, or reduced purchase friction
Paying commission on customers who would have completed anyway
Review and comparison publishers can create real value because they influence which seller receives the order. For a smaller brand, appearing beside established alternatives can provide context and credibility while introducing the brand to another company’s potential customers. Useful formats include comparison sites, listicles, YouTube reviews, communities, forums, and shopping guides.
Creators can play a similar role even when they do not publish a formal review. A trusted recommendation or distinctive presentation can expose the product to an audience the brand does not already own. The right test compares outcomes among eligible people who did and did not receive that exposure; the creator’s tracked clicks alone do not establish the difference.
For every partner, ask:
Where does the partner usually enter the buyer journey?
What customer uncertainty or distribution gap can it resolve that your brand cannot resolve as effectively on its own?
Would the same offer, recommendation, or product information exist without the partnership?
Does the partner change the probability of purchase, the selected product, the basket value, or the customer acquired?
What happens to completed orders and profit when a comparable group cannot use the partner?
Does the incremental profit remain positive after commissions, discounts, placement fees, and network costs?
Do not use a “new customer” label as automatic proof. A first-time buyer may already be at checkout before encountering the affiliate. Conversely, an existing customer can still represent incremental value if a partner causes an additional purchase or a more valuable order that would not otherwise occur. The counterfactual, not the customer label, settles the question.
Also compare the commercial model with realistic alternatives. A one-time placement in an independent comparison may cost less over its useful life than recurring commissions on every referred order. That does not make fixed-fee coverage universally better; it means you should compare the full cost of ongoing commissions with the cost and durability of a non-affiliate placement.
Fund organic assets that change a purchase decision
Organic content has the same incrementality burden, even though its cost structure is different. Publishing more URLs is not a business outcome. The asset has to change what a potential customer knows, trusts, compares, or chooses.
That matters because discovery now happens across AI experiences, social platforms, and search engines. AI summaries and shopping features can answer part of a customer’s question before a website visit occurs. Clicks therefore remain useful, but they do not capture every valuable discovery touch.
Start with a blocked decision. Choose a real question that prevents the customer from selecting or trusting a product. Product comparisons, fit questions, use-case constraints, offer eligibility, and evidence behind a claim are stronger starting points than a broad keyword with no clear purchase decision attached.
Build the evidence before the prose. Gather the product facts, comparison criteria, limitations, examples, and offer terms required to resolve the question. If the page cannot support its answer, polished wording will not create durable trust.
Make the answer explicit. Use descriptive headings, stable product names, direct answers, visible tables where a comparison is genuinely tabular, and internal links that expose the relationship between products and supporting evidence.
Keep structured data faithful to the page. JSON-LD and other machine-readable markup should restate visible, accurate facts. Markup is packaging for evidence, not a substitute for it.
Adapt the evidence to the discovery environment. A comparison page, creator brief, shopping guide, short video, and community answer may express the same verified facts differently. Preserve the substance while fitting the format and audience.
Test the business effect. A staggered rollout across comparable product groups or markets can provide a counterfactual. Evaluate the outcome at the eligible-group level rather than requiring the content URL to receive the last click on every influenced order.
Assign the content costs before evaluating it: research, writing, design, expert review, technical implementation, distribution, and updates. Then select an evaluation period that matches how long you expect the asset to remain useful. Changing that period after results arrive is another way to manufacture a favorable ROI.
Use one decision record for every growth investment
Affiliate, content, paid media, and other channels become easier to compare when every owner completes the same short record:
Hypothesis: which customer behavior should change, and why?
Counterfactual: what represents the outcome without the investment?
Primary outcome: which business metric decides the result?
Cost basis: which variable and investment costs are included?
Result: what changed in revenue, operating gain, and net profit?
Evidence quality: what contamination, imbalance, or outside event could explain the difference?
Action: scale, modify, renegotiate, retest, or stop.
The action should follow the combination of economics and evidence. Strong attributed revenue with no measurable lift is a reason to change the arrangement, not celebrate the dashboard. Incremental sales with negative net profit call for a lower commission, smaller discount, cheaper distribution, or better margin. A promising but inconclusive result calls for a cleaner test, not an unrestricted rollout.
Start with the investment making the largest revenue claim and offering the weakest causal proof. Define a bounded holdout before the next promotion or rollout, agree on the profit calculation with finance, and write the decision rule before results appear. Your next growth decision will then be based on value the business actually gained, not credit a platform happened to assign.
Your paid dashboard says efficiency is acceptable, your SEO and AEO reports show visibility moving, and the CRM says revenue is flat. You do not need another chart. You need to determine whether demand is weakening, conversion is breaking, or the measurement itself is misleading you.
AI can shorten that investigation and help you choose the next experiment. It cannot rescue disconnected definitions, overlapping tests, or a team that has not agreed on what evidence would change a decision. The practical goal is a governed measurement loop: connect signals across the customer journey, expose uncertainty, run the least disruptive useful test, and preserve what you learn.
Start with the decision your measurement must support
A measurement system should begin with a decision, not a collection of available metrics. Before you connect an AI model to your dashboards, write one sentence that names the choice in front of you:
"Should we increase, hold, redirect, or reduce this investment, and what evidence would make us change our current position?"
That sentence forces useful specificity. It identifies the intervention, the person who owns the decision, the business outcome, the acceptable risk, and the uncertainty that needs to be resolved. Without it, AI will produce an intelligent-sounding tour of your metrics. With it, AI has an analytical job.
Map the decision to a measurement chain rather than a single conversion number. For SEO, GEO, paid media, content, and brand campaigns, that chain usually moves through four distinct stages:
Measurement stage
Question it answers
Useful evidence
What it does not prove
Demand formation
Are more relevant people becoming aware of the problem and your brand?
Non-brand discovery, visibility in relevant AI answers, brand mentions, branded search interest, and engagement from the intended audience
That marketing caused revenue
Demand capture
Are interested people entering and progressing through an owned journey?
Relevant landing-page visits, return visits, form starts, content progression, and response to calls to action
That the captured demand is incremental
Commercial progression
Are the right prospects becoming viable sales opportunities?
That a particular platform deserves all the credit
Business outcome
Is the activity producing commercial value?
Pipeline, revenue, retention, margin, or another agreed business result
Which intervention caused the difference
This separation matters when the lower funnel looks weak. A decline in remarketing conversion may appear to justify a budget cut. But if non-brand acquisition has slowed, competitors are gaining visibility, and fewer new qualified visitors are entering the journey, remarketing may be displaying an upstream demand problem rather than causing it. Looking across systems can reveal that the apparent channel failure is really a missing layer of demand creation.
Use four evidence labels consistently: observed, attributed, associated, and incremental. An observed change is simply present in the data. An attributed result received credit under a platform or analytics rule. An associated result moved alongside another signal. An incremental result is the difference that would not have occurred without the intervention, supported by a suitable experimental comparison. AI should never silently promote evidence from one level to another.
This is especially important for AI-search measurement. A citation or brand mention in a relevant answer is an upstream visibility signal. Branded search, direct visits, and assisted engagement can provide additional evidence. CRM outcomes show commercial progression. These signals belong in the same chain, but placing them next to one another does not make the first one the proven cause of the last one.
Build a measurement spine before adding an AI agent
AI does not remove data silos merely because it can read several exports. If web analytics, Google Search Console, brand monitoring, advertising platforms, and the CRM use different campaign names, conversion definitions, timestamps, and identity rules, the model will automate the disagreement.
A measurement spine is the small set of shared definitions and identifiers that connects those systems. It does not require every tool to become one giant database. It requires each system to describe the same business events consistently enough that evidence can be reconciled.
Create a measurement contract for every metric that can affect a budget or campaign decision. Record:
The canonical metric name and plain-language definition.
The business question the metric is allowed to answer.
The system of record when platforms disagree.
The unit represented by each row, such as a person, account, session, campaign, opportunity, or transaction.
The event timestamp, reporting timestamp, timezone, and currency rules.
The identifiers used to join campaign, content, account, and revenue data.
Inclusion and exclusion rules, including internal traffic, duplicates, test records, and disqualified leads.
The expected update cadence and how stale data is marked.
Known coverage gaps and changes in tracking.
The experiment identifier and exposure status when a test is active.
Keep the original channel-native value alongside the canonical value. A platform conversion can still be useful for platform optimization even when finance uses a different revenue definition. Preserving both prevents a clean warehouse field from erasing the context needed to explain a discrepancy.
Identity resolution also needs restraint. Join data at the least sensitive level that can answer the decision. An account-level key may be sufficient for a B2B pipeline question; a campaign or content identifier may be sufficient for a visibility question. Do not send raw personal information, credentials, or unrestricted customer records to an AI system. Use an approved environment, restrict access, and provide only the fields required for the analysis.
Put a data-quality gate in front of every AI analysis. The gate should ask:
Did all expected systems update for the reporting period?
Do totals reconcile with the designated systems of record?
Are joins dropping or duplicating campaigns, accounts, opportunities, or revenue?
Are timestamps, currencies, attribution windows, and conversion definitions aligned?
Did a tag, consent rule, CRM stage, platform setting, budget, or campaign structure change?
Did another experiment expose the same audience during the same period?
If a check fails, the correct AI output is "analysis blocked" or "result qualified," not a plausible estimate inserted into the gap. Missing data is a measurement state. Hiding it turns uncertainty into false precision.
Use AI as a governed analyst, not the final judge
Once the measurement spine is reliable, AI is useful for work that is tedious, cross-channel, and easy to perform inconsistently. Give it bounded analytical jobs:
Reconcile channel, site, search, brand, CRM, and revenue signals around one decision.
Flag divergences, such as improving click efficiency alongside declining new-audience reach or qualified pipeline.
Audit experiment history for repeated variables, inconclusive tests, audience collisions, platform resets, and unexamined failures.
Convert a business question into candidate hypotheses with an explicit mechanism and predicted direction.
Rank proposed tests by risk, learning value, and operational feasibility.
Monitor declared primary and guardrail metrics without changing the test autonomously.
Draft a result summary that distinguishes measured facts, interpretations, data gaps, and recommended follow-up.
Require a fixed response structure from the model. Each analysis should return the decision being supported, evidence for and against the current hypothesis, conflicting signals, data-quality limitations, plausible alternative explanations, the smallest useful next test, operational risk, and a confidence label. This makes the output reviewable and discourages a polished narrative built around whichever metric happened to move.
Keep human approval at three boundaries: choosing what the business is willing to risk, authorizing changes to live campaigns, and deciding whether evidence is strong enough to scale. Start with read-only AI access. A model that detects a CPA spike can recommend an interruption review; it should not rewrite budgets unless you have deliberately built and validated that authority.
AI also needs explicit causal limits. Attribution models distribute credit according to configured rules. Cross-system analysis identifies patterns and likely failure points. A controlled experiment estimates what changed because of an intervention. These are different jobs. A model can help design or analyze the experiment, but it cannot manufacture the missing counterfactual from an ordinary dashboard.
Synthetic audiences can screen messaging before real-world exposure. Use them to identify confusing language, obvious positioning conflicts, or persona-specific objections. Do not use simulated preference as proof of demand, conversion lift, or market response. It is a filter for weak candidates, not a substitute for observed behavior.
Run fewer experiments with cleaner isolation
The best next experiment is not the most creative one. It is the test that resolves an important uncertainty without exposing the business, the brand, or the platform algorithm to unnecessary disruption.
Write the hypothesis before producing variants. Use this structure:
"Among the eligible audience, changing this defined variable should move this primary outcome in the predicted direction because of this mechanism. We will advance, reject, or classify the result as inconclusive under the prewritten decision rule, provided the guardrail metrics remain acceptable."
The mechanism is the most valuable part. "Test a new headline" names an activity. "Emphasize faster time-to-value because the intended buyer appears to prioritize speed over ease of use" names an idea that can be supported, weakened, or refined. Even a losing test can improve future decisions when the mechanism is explicit.
Every test card should identify the decision owner, eligible population, assignment unit, control and treatment, variable being changed, primary outcome, guardrail metrics, planned analysis window, completion rule, interruption rule, conflicting campaigns, and platform changes that could invalidate interpretation. If one of these fields cannot be filled in, the test is not ready.
Your guardrail document should cover the testing budget, maximum acceptable performance deterioration, platform-specific reset conditions, tracking failures, audience contamination, early warning signals, and brand boundaries that cannot be crossed. Give the same document to the AI system that proposes and monitors experiments. Otherwise, the model is optimizing without knowing what the business considers unacceptable.
Sequence tests so that each one answers a recognizable question. If you change the audience, creative concept, offer, landing page, and budget together, a better result does not reveal which change mattered. Start with the lowest-risk environment that can reject a weak idea. A positioning claim might be screened with synthetic personas, then observed in an organic setting, then tested in a controlled paid environment. Evidence from each stage determines whether the next exposure is justified.
When a live test begins, protect its isolation. Avoid overlapping experiments on the same eligible audience. Hold the major variable families steady. If simultaneous changes are unavoidable, preserve a credible control group and record every collision. Do not let an AI agent quietly "improve" a weak variant halfway through the run; that creates a new treatment and compromises the original comparison.
Platform stability is part of experiment cost. Significant changes to creative, audience, campaign structure, or budget can restart learning and cloud the result. Ad sets that remain in a learning phase have been associated with CPAs 20%-40% above those of stable ad sets, though the effect in your account may differ. Multiple overlapping resets can therefore make the whole account look worse, even when none of the ideas being tested is inherently bad.
Prewrite both completion and interruption rules. Do not stop merely because an early reading looks attractive or uncomfortable. Interrupt when a declared safety, brand, tracking, or financial boundary is crossed. Otherwise, allow the planned evidence to accumulate and classify the outcome honestly as a supported win, supported loss, inconclusive result, or invalidated test.
Turn every result into reusable measurement memory
A completed experiment should change more than the current campaign. It should improve the quality of the next hypothesis, reduce repeated mistakes, and help a future analyst understand why a decision was made.
Store one durable record for every launched test, including:
An immutable experiment identifier and the decision it supported.
The hypothesis, proposed mechanism, and expected direction.
The audience, channel, content, creative, offer, and landing experience involved.
The assignment method, control, treatment, and exposure rules.
The primary outcome and guardrail metrics.
Tracking changes, platform resets, audience overlap, and other anomalies.
The result, evidence label, confidence assessment, and unresolved uncertainty.
The decision made, responsible owner, and next test if one is warranted.
Any later check showing whether the effect persisted, weakened, or disappeared.
Link every AI-generated interpretation back to the underlying experiment record, query, or dashboard view. The summary is a navigation layer, not the evidence itself. A future reviewer should be able to trace "speed messaging worked" to the precise audience, outcome, comparison, and limitations. Otherwise, a narrow result will gradually become an unsupported company-wide belief.
Before approving a new test, ask AI to search this memory for similar mechanisms, audiences, and variables. It should identify repeated low-value ideas, apparent failures that were actually inconclusive, results compromised by volatility, and interactions worth examining. The output should recommend the smallest remaining uncertainty, not simply generate another batch of variants.
This memory also helps you respond intelligently when leading and commercial indicators move at different speeds. If upstream visibility and qualified engagement improve while pipeline remains flat, keep the claims narrow: demand signals are strengthening, but commercial impact is unproven. Check the next handoff and any expected reporting lag before scaling. If every stage suddenly declines, verify tracking and joins before rewriting strategy. If only the platform deteriorates during several overlapping tests, investigate resets and audience contamination before declaring that demand has vanished.
Integrated measurement is valuable because it shows where momentum may be forming and where the chain is breaking. It is not a license to claim causality from a synchronized chart. The discipline is to act on leading evidence with bounded exposure, then require stronger evidence before making a larger commitment.
Key takeaways
Begin with a budget, campaign, or positioning decision and define what evidence would change it.
Connect demand, capture, commercial, and revenue signals through shared definitions and identifiers.
Use AI to reconcile evidence, expose uncertainty, audit test history, and propose the smallest useful experiment.
Keep causality labels, live-campaign authority, sensitive data, and acceptable risk under human control.
Sequence experiments, protect controls, record platform resets, and reject tests whose disruption exceeds their learning value.
Preserve every result in a traceable knowledge base so future tests start from accumulated evidence rather than memory.
Your next move is to choose one live marketing decision and build its measurement chain. Give AI the definitions, guardrails, historical tests, and permission to identify the single uncertainty blocking that decision. Then run the cleanest affordable experiment that can resolve it. If the proposed test cannot explain what you will do differently after each possible result, do not launch it.
You have a campaign brief, not an afternoon to spend rerolling images. The asset needs readable copy, stable people and products, multiple formats, and localized versions. Someone also needs to know exactly what changed between creative variants.
Google Nano Banana 2 can carry more of that production workload, but only if you treat it as part of a controlled creative system. The useful shift is not simply better-looking output. It is the ability to move from a structured brief to a consistent family of assets with fewer compromises between speed, detail, text, and continuity.
What Nano Banana 2 changes in an image workflow
Nano Banana 2 is the informal name for Gemini 3.1 Flash Image. Google DeepMind has positioned it as a combination of Nano Banana Pro’s image intelligence and Gemini Flash’s faster generation. For a marketing team, that combination matters because image quality and iteration speed normally pull the workflow in opposite directions.
The model’s improvements map to four practical jobs:
Knowledge-heavy visuals: Real-time web grounding can bring current context into infographics and data-oriented images. Treat that as assistance with generation, not proof that a visual is factually correct.
Images containing words: Improved text rendering and translation make social graphics, diagrams, promotional cards, and localized creative more viable. Every visible word still needs human proofreading.
Scenes that must remain recognizable: Stronger instruction adherence and subject consistency make it easier to preserve the same cast, objects, visual hierarchy, and art direction during revisions.
Assets for different placements: Supported output extends from 512px through 4K, so the same workflow can cover lightweight concepts and high-resolution deliverables.
The documented consistency envelope reaches up to five characters and 14 objects in one workflow. Read that as an upper capability boundary, not a guarantee that a crowded scene will remain perfect. The closer your composition gets to the limit, the more deliberate your naming, placement, and review need to be.
Key takeaways
Use Nano Banana 2 for repeatable asset families, not just isolated image generation.
Write prompts as production briefs with explicit priorities, subjects, composition, copy, and output requirements.
Approve one master image before generating formats, languages, or test variants.
Verify every word, number, label, and data point even when web grounding is involved.
Keep important page meaning in HTML and metadata rather than leaving it trapped inside an image.
Turn the prompt into a production brief
Stronger instruction adherence is only useful when the instructions have a clear hierarchy. A loose collection of adjectives leaves the model to decide what matters. A production brief tells it what the asset must accomplish, what cannot change, and where it has room to interpret.
Start with the asset’s job. Name the destination and the action the visual should support: a landing-page hero, an ad variant, a report cover, a diagram, or a localized social card. This gives the composition a reason to exist.
Define the required subjects. List each person, product, interface, or meaningful object. Give recurring subjects short, stable labels so later instructions can refer to them without ambiguity.
Specify spatial relationships. State what belongs in the foreground, where the main subject sits, which direction a person faces, and where clear space is required for external copy or controls.
Describe the visual system. Set the palette, lighting, texture, level of realism, camera perspective, and overall mood. Use concrete visual properties rather than piling up subjective terms such as premium, bold, or modern.
Supply text as exact copy. Separate the headline, labels, supporting text, and language. If a phrase must not be translated, say so. Do not bury critical wording inside a long paragraph of art direction.
Name the output requirements. Include the intended aspect ratio, supported resolution, crop needs, and any areas that must remain uncluttered. Request 4K when the approved asset actually needs it, not by default for every concept.
Declare the invariants. Say which identities, objects, colors, text, and layout relationships must remain unchanged across revisions.
A reusable prompt pattern
Goal: Create a 4K landscape hero image for a landing page promoting a search visibility report. Subjects: Show one analyst at a desk and one dashboard object displaying a clean line chart. Composition: Place the analyst and dashboard on the right, with the left third uncluttered for an HTML headline. Visual direction: Use deep navy, off-white, and restrained cyan accents, with soft directional lighting and realistic textures. Restrictions: Do not add logos, watermarks, interface labels, extra screens, or text inside the image. Continuity: Keep the analyst’s appearance, dashboard layout, palette, and lighting unchanged in later variants.
This example deliberately reserves the headline for HTML. That is usually the cleaner choice for a web hero because the copy remains editable, selectable, responsive, and available to assistive technology. Use embedded text when the words are part of the artifact itself, such as a social card, diagram label, poster, or standalone ad creative.
For an image that needs embedded copy, add a separate instruction such as On-image copy: Q3 Search Visibility Report. Then identify the exact location, hierarchy, and language. Keeping copy in its own instruction makes proofreading and localization easier.
Follow-up prompts should be smaller than the original brief. Ask to change one controlled element while restating the invariants: replace the background environment, change the accent color, translate the approved copy, or adapt the crop while preserving the subjects. Rewriting the entire prompt for every revision invites unplanned changes.
Build variants without losing control of the experiment
Fast generation can create a false sense of progress. Twenty visually different outputs are not a useful test if the headline, palette, composition, subject, and offer all changed together. You will know which image performed better, but not why.
Use a master-and-variant workflow instead:
Generate a baseline. Produce the first complete interpretation of the brief before requesting alternatives.
Review against the brief. Separate objective misses, such as incorrect text or a missing object, from subjective preferences, such as wanting warmer lighting.
Correct the baseline. Do not build variants from an image that already violates the required composition, copy, or identity.
Approve a master. Record the accepted prompt, output, invariants, language, and intended placement.
Create one-variable variants. Change one meaningful family of attributes at a time, such as the background, focal framing, callout treatment, or color emphasis.
Localize after visual approval. Preserve the master composition while changing the language-specific copy, then allow only the layout adjustments required by the translated text.
Your review should use explicit gates rather than a general looks-good decision:
Brief compliance: Are all required subjects present, and are unwanted additions absent?
Continuity: Do recurring people, products, and objects remain recognizable across versions?
Copy: Does every character match the approved wording, including punctuation, capitalization, and product terms?
Factual content: Do chart labels, values, dates, maps, and explanatory elements match the information you intend to publish?
Visual integrity: Are faces, hands, object boundaries, reflections, lighting, and small details internally coherent?
Placement safety: Will important content survive the real crop, overlay, and responsive layout?
Delivery: Does the final file have the resolution and aspect ratio required by its actual destination?
Web grounding does not remove the factual review gate. It can help the model reason about the requested subject, but it cannot approve a statistic, establish which date your campaign should use, or decide whether a generated chart supports your claim. Keep the underlying facts in a separate, human-reviewed content sheet and compare the rendered visual against it.
The same discipline applies to translation. Generate the localized version, copy the visible wording out of the image, and compare it with approved language line by line. Check line breaks and hierarchy as well as meaning; a correct translation can still become unreadable when it is forced into the original layout.
Nano Banana 2 is integrated into Google Ads as well as the broader Gemini ecosystem, which makes rapid campaign variation an obvious use case. Keep the creative test interpretable: hold the audience, offer, and measurement setup steady when the purpose is to learn whether a visual change affected performance.
Finish the asset for SEO, AEO, and GEO
A production-quality image is not automatically a search-ready asset. Image generation creates pixels. Your publishing workflow must connect those pixels to the page’s subject, the user’s task, and machine-readable context.
Keep the meaning outside the pixels
Match the search intent. Use the image to clarify the answer, process, entity, comparison, or result the page is actually about. A polished but generic visual adds little retrieval value.
Write functional alt text. Describe the information or purpose the image contributes in its context. Do not paste the generation prompt or turn the attribute into a keyword list.
Use descriptive filenames. Name the finished asset for its actual subject and role rather than preserving a generator’s default filename.
Publish essential facts as HTML. If an infographic contains a process, statistic, or comparison that the reader needs, provide the same core information in nearby page text. Do not make people or search systems depend on reading pixels.
Add a useful caption when context is needed. A caption should explain why the visual matters, not merely repeat what it depicts.
Create delivery derivatives. Keep a high-resolution master, but serve a file sized and compressed for the placement. Sending a 4K image everywhere can add page weight without improving the reader’s experience.
Localize the surrounding context. When you translate text inside an image, update the filename, alt text, caption, nearby explanation, and linked destination for the same audience.
Treat structured data as a record
If your page’s structured data references the image, the markup should describe the asset that is visibly published at the live URL. Keep the image URL, dimensions, caption, creator information, and licensing information aligned with what you can substantiate. Do not manufacture metadata simply to fill properties.
JSON-LD does not rescue a weak relationship between the visual and the page. The image, headline, body copy, captions, internal links, and structured data should all describe the same primary subject. That consistency gives search engines and answer systems a clearer entity-and-context relationship to interpret, although it cannot guarantee rankings, citations, or inclusion in an AI-generated response.
This is also where subject consistency becomes strategically useful. Reusing a recognizable product, character, diagram language, or branded visual system across a related content cluster can make the collection feel coherent. Keep each asset specific to its page, however; duplicating one generic image across every URL does not explain what makes those pages different.
Choose a pilot that exposes the model’s real value
Do not judge Nano Banana 2 by asking it for a single decorative image. That tests whether it can produce an attractive picture, not whether it can improve your production system.
Our rule of thumb is to choose a pilot that needs at least two of the model’s differentiating capabilities:
A recurring person, product, or object that must remain consistent.
Exact words or labels inside the visual.
Several controlled creative variants for a campaign.
Localization into more than one language.
A knowledge-heavy infographic or data visualization.
Outputs ranging from smaller concept images to a 4K master.
A strong pilot might be a report launch that needs a hero image, a labeled social card, ad variants, and localized editions. One approved visual system can then be carried through each placement while the team measures generation time, correction cycles, consistency, proofreading effort, and final usability.
Begin concepts at the smallest supported resolution that lets your team judge composition. Move to 4K after the direction is approved. This keeps reviewers focused on the idea before they spend time inspecting final-level detail.
The model is available across Google Ads, the Gemini app, Search AI Mode, Lens, and other parts of Google’s ecosystem. That reach makes shared governance more important than platform-specific habits. Store the master brief, approved copy, invariants, final asset, localization decisions, and QA result together so the next person can reproduce the workflow.
Pick one recurring campaign asset this week. Define its invariants, create one approved master, and generate a single controlled variant. If the model preserves the subject, copy, composition, and visual system through that cycle, you have evidence for expanding the workflow. If it does not, the QA record will show whether the problem came from the brief, the generation, or the review process.
Your paid search ad can be relevant, accurate, and polished yet disappear into a row of near-identical promises. When every advertiser uses the category term, a broad benefit, and Learn more, the problem is not grammar. It is contrast.
If you are deciding what to change, stop judging each headline in a spreadsheet. The useful unit of review is the complete ad as it appears beside competing ads. That shift turns copywriting from wordsmithing into a practical positioning exercise.
Start with the search results, not a blank document
Choose the queries that represent the clearest commercial intent in the campaign. For each query, record what the visible ads actually communicate. You are looking for patterns, not trying to imitate individual phrases.
Intent match: What product, service, or problem does the ad name?
Main promise: What outcome is the advertiser leading with?
Proof: Does the ad use a number, award, named recognition, or another verifiable detail?
Effort: Does it explain how quickly or easily the customer can act?
Commercial offer: Is there a free trial, free quote, or visible price?
Qualification: Does the message specify a location, price level, audience, or other boundary?
Call to action: What does the advertiser ask the searcher to do next?
Now mark the ideas that recur across the result. If every visible ad leads with the category name and a vague claim about simplicity, another variation of those words will not create a meaningful difference. Keep the category term where it helps confirm intent, but use the remaining space for a reason to choose you.
Do not confuse different wording with different positioning. Fast setup, get started quickly, and easy onboarding may all occupy the same competitive territory. A genuine differentiator changes the decision: verified adoption, a named award, a real completion time, an accessible starting offer, a clear price, or specific local availability.
For every proposed differentiator, ask three questions: Can you prove it? Does it answer a concern that matters at this point in the search? Is it meaningfully different from what appears around it? If the answer to any of those questions is no, the line is not ready.
Build responsive search ads as a message system
A Responsive Search Ad gives you room for 15 headline options and four descriptions. Filling every field is not the same as creating a versatile ad. If most assets repeat the same noun and benefit, the platform has many combinations but very little real choice.
Assign every asset a job before you write it:
Intent anchor: Confirms what the product or service is.
Outcome: Names what the customer can accomplish.
Proof: Supports the promise with something verifiable.
Effort reducer: Addresses time, complexity, or inconvenience.
Offer: Gives the searcher a low-friction next step.
Qualifier: Uses price, location, or another useful boundary to attract a better fit.
Action: Tells the searcher what to do next.
This role-based structure makes combinations easier to inspect. An intent anchor can sit beside proof and an action without sounding repetitive. Three assets that all say the product is easy will compete for the same job and may appear together as a weak, monotonous message.
Read plausible headline and description combinations as complete ads. Check for repeated claims, awkward transitions, contradictory qualifiers, and calls to action that do not match the landing page. An asset can be strong by itself and still create a poor ad when paired with another asset.
When several headlines are alternatives for the same role, you can pin them to the same position. That allows those alternatives to rotate without appearing beside one another. Pinning can reduce the platform’s ad-strength rating, so use it deliberately when it protects meaning, prevents repetition, or preserves an approved message. The rating is feedback; a coherent customer-facing ad is the goal.
Replace broad claims with proof, effort, and useful boundaries
Competitive copy does not become persuasive by choosing a louder adjective. A claim such as Best Local Contractor asks the searcher to accept your opinion. Attaching that claim to named, verifiable recognition gives the person a reason to believe it.
Run each important claim through the appropriate check:
Superiority: Replace an unsupported claim such as best with the specific evidence behind it. If there is no evidence, choose a benefit you can defend.
Speed and ease: Describe a real action and a real timeframe. Open an account in 10 minutes is useful only when the customer can reasonably expect that experience.
Free offer: State what is free. A free trial and a free quote solve different kinds of hesitation, so do not reduce both to a vague mention of savings.
Pricing: Show price when it helps someone compare or qualify themselves. A higher price can also filter out poorly matched prospects, provided the amount and any necessary qualification are accurate.
Location: Name the actual place served in a regional campaign. A relevant county, city, or service area is more useful than a generic claim about being local.
Action: Name the next meaningful step, such as requesting a quote, starting a trial, or scheduling an appointment.
Before publishing, compare every promise with the landing page and the operating reality behind it. Can the business fulfill the stated timeframe? Is the recognition named correctly? Does the free offer have a scope the ad should clarify? Does a displayed price need a starting qualifier? If the destination cannot confirm the promise immediately, revise the ad or the page before paying for traffic.
The most useful copy often does two jobs at once: it attracts the right person and gives the wrong person enough information to opt out. Price, geography, availability, and the exact nature of an offer can reduce raw appeal while improving message fit. That is not a copy failure. It is qualification.
Use AI to widen the options without surrendering control
AI is useful for exploring angles, spotting repetition, and producing alternative wording. It should work from an approved fact set, not fill gaps with plausible claims. Treat AI-generated assets as drafts that require human review.
A practical prompt starts with the competitor message map and a fact bank. Ask for headline and description options grouped by role: intent, outcome, proof, effort, offer, price, location, and action. Tell the model to use only the supplied facts, keep necessary qualifiers, avoid unsupported rankings, and make each group communicate a genuinely different idea.
Review the output with a stricter standard than fluency:
Delete numbers, awards, rankings, and time claims that are not in the approved fact set.
Reject assets that restate an existing claim with synonyms.
Restore any eligibility, pricing, availability, or geographic qualifier the draft omitted.
Check the wording against brand voice and relevant industry requirements.
Render the assets in combinations and read them as a searcher would.
Confirm that every call to action leads to a page where that action is available.
Account-level automation needs the same ownership. If every message and link must pass an accuracy or compliance review, disable automatically generated assets rather than allowing unapproved copy or destinations to appear. Automation can help assemble and vary approved material; it cannot take responsibility for whether a claim is true.
Test the competitive idea, not just the wording
Do not let an ad-strength score decide which copy deserves to run. A high rating may indicate that the platform has a varied asset inventory, but it does not answer the strategic question: does your ad give this searcher a credible reason to choose you over the alternatives?
Write a test hypothesis before changing the assets. It should name the competitive problem and the proposed answer. For example: an independently verifiable proof point will create a clearer reason to choose the brand than an unsupported superiority claim. That is more useful than testing whether one adjective beats another.
Choose one message dimension. Test proof, effort, offer, price, location, or action without rebuilding every part of the ad at once.
Protect the comparison. Keep unrelated messaging stable where the setup permits, and prevent duplicate or conflicting assets from muddying the test.
Inspect combinations before launch. Make sure the intended contrast survives assembly and the landing page fulfills both versions.
Judge the business outcome. Use the campaign result that reflects the action you actually value, not an interface score alone.
Return to the result page. Performance data tells you what happened inside the campaign; a fresh competitive review shows whether the message is still distinctive in context.
Record the decision. Keep the query, competitive pattern, hypothesis, assets, outcome, and next action together so the campaign does not drift back toward generic copy.
Key takeaways
Review paid search copy beside competitor ads, because distinctiveness cannot be judged in isolation.
Give every Responsive Search Ad asset a defined role instead of filling the inventory with paraphrases.
Support superiority claims with evidence, and use truthful details about effort, offers, price, and location to help people decide.
Pin alternative assets when necessary to prevent repetition or protect an approved message.
Use AI to explore approved facts, then review every claim, qualifier, link, and assembled combination.
Test a competitive proposition with a written hypothesis, not merely a different set of words.
Start with one commercially important query and one live ad. Map the competing promises, remove assets that do the same job, and strengthen the least-supported claim. Your next test will then have a clear reason to exist and a result you can use.
Your Demand Gen campaign is spending, but the results do not resemble Search. The cost per lead looks high, the audience feels difficult to control, and every adjustment seems less precise than adding a keyword or exclusion. Before you pause the campaign, check whether you are asking discovery traffic to behave like declared search intent.
A workable Demand Gen strategy aligns the buyer’s stage, the audience, the offer, the creative and the conversion signal. When those elements describe different moments in the journey, bidding changes cannot repair the campaign. When they reinforce one another, you can diagnose performance without guessing.
Reset the campaign around discovery, not search intent
Search advertising responds to an action the prospect has already taken: entering a query. Demand Gen reaches people while they are browsing environments such as YouTube, Gmail and discovery feeds. They may fit your market without actively looking for your product at that moment.
That difference changes the campaign’s job. You are not simply capturing intent. You are interrupting someone, making a relevant problem recognizable and earning the next appropriate action. Visual assets must perform much of the work that keywords perform in Search: establishing context, selecting for the right problem and showing why the offer deserves attention.
The most common strategic mismatch is a mid-funnel campaign judged against a bottom-of-funnel acquisition target. A cold prospect who downloads an educational resource is not equivalent to a prospect who requests a demo. Treating both actions as if they should carry the same cost or immediate revenue expectation obscures what the campaign is actually producing.
Define two outcomes before you build:
The optimization conversion: the action Google Ads should seek for this campaign, such as a qualified resource registration, webinar registration, demo request or purchase.
The business outcome: the downstream result that makes the optimization conversion worthwhile, such as a sales-qualified opportunity, new customer or completed order.
The optimization conversion gives the campaign a learnable signal. The business outcome keeps you from celebrating inexpensive actions that never become valuable. For lead generation, inspect lead quality and downstream progress as well as the reported cost per conversion. For ecommerce, keep the purchase outcome visible even when a discovery campaign is designed to create an earlier interaction.
This is not permission to ignore economics. It is a way to evaluate the correct part of the funnel. If a mid-funnel action rarely advances, improve or replace it. If it reliably creates qualified demand, judge its cost in relation to that progression rather than demanding the same immediate return as high-intent Search traffic.
Match each buyer stage to one credible next step
Start with the next decision the prospect is ready to make. Cold audiences need a reason to care. Warm audiences need help evaluating the problem and possible solution. Hot audiences need a clear path to a demo, quote or purchase. An offer becomes ineffective when it asks for more commitment than the creative has earned.
Buyer stage
Likely situation
Creative job
Suitable offer
Conversion signal
Cold
Fits the market but has little or no prior engagement
Make a specific problem recognizable and useful
Educational content, explainer or practical resource
Meaningful engagement with that resource
Warm
Understands the problem or has engaged with related material
Build confidence and make the solution concrete
Case study, webinar or deeper evaluation content
Registration or another evaluation-stage action
Hot
Is ready to evaluate a provider or complete a purchase
Reduce uncertainty and clarify the action
Demo, consultation, quote or purchase offer
Qualified request or transaction
Write a one-sentence brief for every campaign or ad group:
For this audience at this stage, we will lead with this problem, offer this next step and optimize for this conversion.
If you cannot complete that sentence without adding several unrelated problems or actions, the strategy is not yet focused enough.
Consider a B2B campaign aimed at small businesses concerned about cybersecurity. A cold ad can identify a specific security gap and offer a practical educational resource. A warm ad can use a relevant case study or webinar to help the buyer evaluate an approach. A hot ad can invite an appropriate prospect to request a demo. The underlying product may be unchanged, but the message and commitment move with the buyer.
The same principle applies to ecommerce. Cold creative can explain the problem, use case or product category. Warm creative can help a shopper evaluate fit. Hot creative can present the purchase offer directly. Sending every stage to the same product page with the same message removes the strategic distinction the campaign needs.
Choose the campaign conversion only after choosing the offer. A cold educational campaign optimized solely for a scarce bottom-of-funnel action may not produce enough signal for useful learning. When purchase or demo volume is limited, a genuine mid-funnel action can provide a more workable optimization goal, provided you continue measuring whether those conversions progress toward revenue.
Do not combine actions merely to make the conversion count look larger. A brief page visit, a resource registration and a demo request do not carry the same intent. If the bidding goal treats weak and strong actions as interchangeable, the campaign may find the easiest action rather than the one that advances the buyer.
Use campaign and ad-group boundaries to preserve meaning
Demand Gen has two important steering layers. The campaign carries broad decisions such as the bidding strategy and conversion goal. Ad groups define audience choices, and each ad group develops its own learning. Your structure should make those layers easier to interpret.
Create a separate campaign when the conversion goal, bidding logic or journey stage needs to differ. Create a separate ad group when you have a distinct audience hypothesis that deserves its own message. Do not split audiences simply because the interface allows it. Every additional ad group divides the available activity and creates another unit you must evaluate.
Assign one journey stage to the campaign. This keeps the offer and conversion goal coherent.
Build ad groups around audience hypotheses. Custom segments, lookalike-based audiences and warmer groups can be separated when each represents a meaningfully different route to the same stage.
Give each audience suitable creative. The offer may remain consistent across the campaign, but the problem language and visual treatment should reflect why that audience is relevant.
Apply exclusions for a journey reason. Remove people when their status makes the message inappropriate, not simply to make the audience look more precise.
Name the structure so someone else can audit it. Include the stage, audience thesis and offer in the campaign or ad-group name.
The goal is neither maximum reach nor microscopic segmentation. An audience that is too broad forces generic messaging and makes performance difficult to interpret. An audience that is too narrow may not create enough activity for its ad group to learn. Aim for an audience that is broad enough to operate but specific enough to share a recognizable problem and respond to the same offer.
Custom segments can express a clear market or problem hypothesis. Lookalike data can extend reach from a useful seed. Warmer audiences can support later-stage messages. Treat these as different strategic ideas, then let performance determine where expansion is justified. Do not start with one undifferentiated audience and assume the platform will discover your entire customer journey on its own.
Exclusions deserve the same discipline. A recent converter generally should not keep receiving the acquisition message that produced the conversion. An existing customer may be inappropriate for a new-customer offer but relevant to a separate cross-sell journey. A warm prospect should not remain in a cold educational track when you have intentionally created a warm track with a more appropriate next step.
Avoid blanket exclusions designed to imitate negative-keyword control. Discovery advertising needs room to find potential buyers. Exclude identifiable journey conflicts and genuinely ineligible groups; use creative, audience definitions and the offer to do the rest of the steering.
Make creative carry the targeting strategy
A Demand Gen ad competes with the content a person chose to browse. A polished brand montage can still fail if it does not quickly establish relevance. The opening needs to communicate a recognizable problem or payoff within the first three to four seconds. The viewer should not have to wait for the logo reveal to understand why the ad concerns them.
Build each creative brief from these components:
Audience: the specific person or business situation the ad is meant to interrupt.
Problem: the concrete issue that makes the message relevant.
Consequence or payoff: why the issue deserves attention now.
Offer: the useful next step available at this stage.
Visual idea: an image, demonstration or contrast that communicates the point without depending on a long explanation.
Call to action: wording that accurately describes what happens after the click.
Specificity matters more than theatrical language. A cold cybersecurity ad for small businesses should look and sound as if it concerns security challenges in a small organization. A generic promise such as better protection forces the viewer to work out whether the message applies. A practical resource framed around a recognizable small-business problem gives that viewer a faster reason to continue.
Do not stretch one asset across the entire funnel. Cold creative should teach or clarify. Warm creative can present evidence, a use case, a case study or an event. Hot creative should make the commercial action unmistakable. Reusing the same visual is acceptable only when the message still fits the audience’s stage; visual consistency is not a substitute for journey alignment.
Organize creative testing around decisions you can act on:
Problem angle: Which customer problem produces relevant attention?
Opening hook: Does the audience respond better to the problem, consequence or desired outcome?
Visual treatment: Which available format and visual concept make the message easiest to understand?
Offer: Is the audience more willing to take an educational, evaluative or commercial next step?
Call to action: Does it set the right expectation for the destination?
Post-click experience: Does the page continue the same promise with appropriate friction?
Change one major strategic variable at a time when practical. If you replace the audience, creative, offer and landing page together, improved performance will not tell you which decision worked. You can still launch multiple assets within a test, but define the question first and keep enough of the experience consistent to interpret the result.
The destination is part of the creative system. Repeat the ad’s problem and promise near the top of the page. Deliver the offer named in the call to action. Match the form or checkout commitment to the buyer’s stage. A cold educational ad that lands on an aggressive demo page breaks the agreement created by the click, even if the page is well designed.
Budget for learning, then optimize the whole path
Automated bidding needs conversion activity from the goal you selected. Budget planning should therefore begin with the action the campaign is expected to generate, not with an arbitrary amount left over after Search. If the available budget cannot plausibly support meaningful volume for a rare bottom-of-funnel conversion, the campaign-goal combination is the problem.
You have several responsible ways to address thin conversion volume: consolidate unnecessary ad groups, focus on the audiences most closely matched to the offer, improve the offer, or optimize toward a legitimate mid-funnel action that occurs more often. A smaller budget can still be useful when it is concentrated around a focused mid-funnel objective. Spreading it across many stages, offers and audience fragments makes each result harder to learn from.
Once the campaign is running, diagnose it in funnel order. Demand Gen does not give you the same negative-keyword workflow used to refine Search, so the main optimization controls are the conversion goal, audience, exclusions, creative, offer and post-click experience.
Verify measurement. Confirm that the primary conversion fires only when the intended action occurs and that weaker actions are not being counted as equivalent outcomes.
Check stage and goal alignment. Make sure the audience’s likely readiness, the offer and the optimization conversion describe the same moment.
Review audience coherence. Ask whether each ad group represents a clear hypothesis or an accidental collection of loosely related people.
Inspect the creative opening. Confirm that the problem or payoff is understandable in the first three to four seconds and that the visual supports it.
Evaluate the offer. If relevant people engage but resist the next step, the commitment may be too high or the value too vague.
Follow the click. Check whether the landing page preserves the message, supplies the promised value and makes the action clear.
Validate downstream quality. Determine whether reported conversions become qualified leads, sales opportunities or orders worth acquiring.
Use performance patterns as diagnostic clues, not automatic verdicts. Reach with little meaningful engagement points you toward the audience hypothesis, creative or offer. Engagement followed by weak conversion points you toward the offer, call to action or landing page. Reported conversions with poor business quality point you toward the conversion definition, audience qualification or downstream follow-up. Fix the earliest broken handoff before adjusting everything below it.
Keep a simple decision log for every meaningful change. Record the problem you observed, the hypothesis, the variable changed and the result you will use to judge it. This prevents an account from becoming a sequence of undocumented reactions and gives creative testing a cumulative purpose.
Key takeaways
Treat Demand Gen as discovery advertising. It must create and develop attention, not merely capture a declared query.
Align the buyer stage, audience, offer, creative and conversion goal before choosing bidding settings.
Use campaigns to separate conversion goals or journey stages, and ad groups to test distinct audience hypotheses.
Make the problem or payoff clear in the first three to four seconds, then use a call to action that accurately describes the next step.
Concentrate limited budgets around a goal capable of producing useful conversion activity rather than fragmenting spend across the entire funnel.
Optimize the complete path from impression to downstream business quality instead of relying on reported cost per conversion alone.
Open your current campaign and write the buyer stage, audience problem, offer and primary conversion beside every ad group. If one row contains competing stages or unrelated offers, separate them. If a cold audience is being sent directly to a high-commitment action, repair the offer before changing the bid strategy. If the opening cannot establish relevance within three to four seconds, rebuild the creative before narrowing the audience. Those checks will turn the next optimization from a guess into a decision you can evaluate.