Tag: A/B Testing

  • Paid Search Incrementality Testing: A Practical Framework

    Paid Search Incrementality Testing: A Practical Framework

    You may know exactly how much revenue Google Ads claims and still not know how much revenue the ads created. That gap matters most when branded campaigns, strong organic rankings, and direct traffic all reach the same customer.

    A paid search incrementality test replaces that ambiguity with a controlled absence. You pause a defined slice of advertising, measure what actually disappears and what moves elsewhere, then compare the incremental loss with the spend you avoided. The goal isn’t to prove that paid search works or doesn’t. It is to identify where it acquires demand, where it supports another channel, and where it charges you for demand you already own.

    Attribution records a route; incrementality measures an effect

    Platform attribution answers, “Which tracked interaction received credit?” Incrementality answers, “What would have happened without this interaction?” Only the second question tells you whether removing or reducing spend would materially change the business outcome.

    Suppose a customer searches your company name, clicks an ad above your top organic result, and buys. The advertising platform can correctly record the ad click while still overstating the ad’s causal value. The unresolved question is whether that same customer would have clicked the organic listing and bought anyway.

    You can’t settle that question with last-click, first-click, data-driven, or multi-touch attribution alone. Changing the credit rule redistributes recorded value among observed touches. It doesn’t create the missing counterfactual.

    The prior evidence is genuinely mixed. Google’s pause experiments across more than 400 advertisers estimated that 89% of ad clicks were incremental on average, while eBay’s branded-search experiment found that almost all missing paid clicks and sales moved to organic. Google’s result is platform-supplied evidence, and neither finding is a universal rule. The difference is the point: brand strength, organic visibility, query type, competition, and account structure can produce very different answers.

    For a useful diagnosis, classify paid search at the query or campaign level:

    ClassificationWhat it meansWhat you should test or decide
    IncrementalPaid search reaches customers or produces outcomes that your other channels would not have captured.Keep it when incremental contribution exceeds its cost; test expansion separately.
    DependentOrganic or another channel performs worse when paid support disappears.Measure the combined channel effect and avoid treating paid and organic as isolated budgets.
    CannibalizedThe ad captures a click or conversion that a strong unpaid result was already positioned to win.Reduce or pause the affected slice while monitoring total revenue, query clicks, and competitive pressure.

    These aren’t permanent labels. A branded query can be largely cannibalized while you rank first, then become more incremental if organic visibility falls or a competitor changes the search results. Your test should therefore support a budget rule with conditions, not a timeless verdict about the channel.

    Key takeaways

    • Test a material but reversible slice of spend instead of switching off the entire account by default.
    • Judge the test on total business outcomes, not on the revenue that disappears from the advertising platform’s report.
    • Separate branded search, non-brand search, Shopping, and Performance Max because their substitution patterns can differ.
    • Join paid search-term data with organic query data before the pause so you know where paid and organic already overlap.
    • Allow for delayed substitution. A short test can make paid search look more incremental than it is if customers and reporting take time to move.
    • Make the final decision with incremental contribution or profit, not attributed ROAS.

    Design the pause around one budget decision
    Matched groups of campaign tiles arranged for a controlled experiment, with one bounded set removed beside a stack of budget tokens.

    A broad question such as “Does paid search work?” cannot produce a clean action. Define the decision first: whether to keep branded ads in a particular market, reduce spend on terms where you already rank strongly, or retain a non-brand campaign that appears to introduce new customers.

    Then write the test plan before changing the campaigns:

    1. State the counterfactual. Write what you expect customers to do when the selected ads disappear. For example, they may move to organic listings, arrive directly, choose a competitor, or not visit at all. This forces you to measure the channels where substitution should appear.
    2. Choose one testable slice. Isolate branded search from non-brand search, Shopping, and Performance Max. A result from brand terms should not be used to cut prospecting campaigns whose job and audience are different.
    3. Select the test unit. A campaign, coherent query group, or market can be paused while a comparable unit remains active. A credible control helps distinguish the pause from seasonality, promotions, or a general change in demand. If no good control exists, be explicit that a pre-versus-post result carries more uncertainty.
    4. Lock the primary outcome. Use total revenue, qualified leads, purchases, or another business result that exists outside the ad platform. Record paid-attributed revenue, organic revenue, direct revenue, organic clicks, and total query clicks as diagnostic measures rather than competing versions of success.
    5. Define the economic rule. Decide in advance how you will compare the incremental outcome with avoided media cost. Where margin data is available, use contribution rather than revenue; otherwise a high-revenue, low-margin campaign can appear more valuable than it is.
    6. Record known disruptions. Promotions, price changes, inventory constraints, site outages, tracking changes, SEO releases, and brand publicity can alter the same metrics as the pause. Log them during the test and exclude or qualify affected periods instead of explaining them away after seeing the result.
    7. Set exposure and rollback conditions. Specify the largest acceptable business loss before launch. If the downside could be material, stage the pause or use a narrower market. Don’t invent the rollback threshold after an uncomfortable result appears.
    8. Declare the observation window. Include enough time for buying cycles, channel switching, and revenue reporting to settle. One documented pause recovered 30% of paid-attributed revenue through organic and direct within six weeks, but that figure rose to 65% by week 13. That is evidence that substitution can lag, not a universal thirteen-week minimum.

    Build the overlap baseline before you pause

    Export Google Ads search terms with their spend and outcomes, then export matching Google Search Console queries and organic clicks for the same dates. Normalize obvious differences such as capitalization and whitespace, but preserve query intent. A brand name, a brand-plus-product query, and a generic category query shouldn’t be collapsed into one row merely because all three contain the company name.

    For each matched query, record paid clicks, paid spend, paid outcomes, organic clicks, and whether a meaningful organic result is present. This gives you a map of expensive overlap. It does not prove cannibalization on its own: customers can still respond differently when both listings appear. The pause provides the causal evidence; the query join tells you where to look and how to interpret the movement.

    Protect the business without protecting the assumption

    A total-account blackout can create unnecessary financial exposure. Choose the largest coherent slice whose potential loss the business can tolerate, while retaining enough volume to produce a useful signal. If a small unit cannot distinguish normal variation from a real effect, acknowledge that limitation or have an analyst assess the design before increasing exposure.

    Monitor competitor activity on branded results during the pause, but don’t treat a competitor impression as proof that your ad is incremental. The relevant outcome is whether the changed results cause a measurable loss in total clicks, conversions, revenue, or contribution. Brand protection can be a legitimate job for paid search; it should be named and valued as protection rather than reported as customer acquisition.

    Measure substitution outside the advertising dashboard
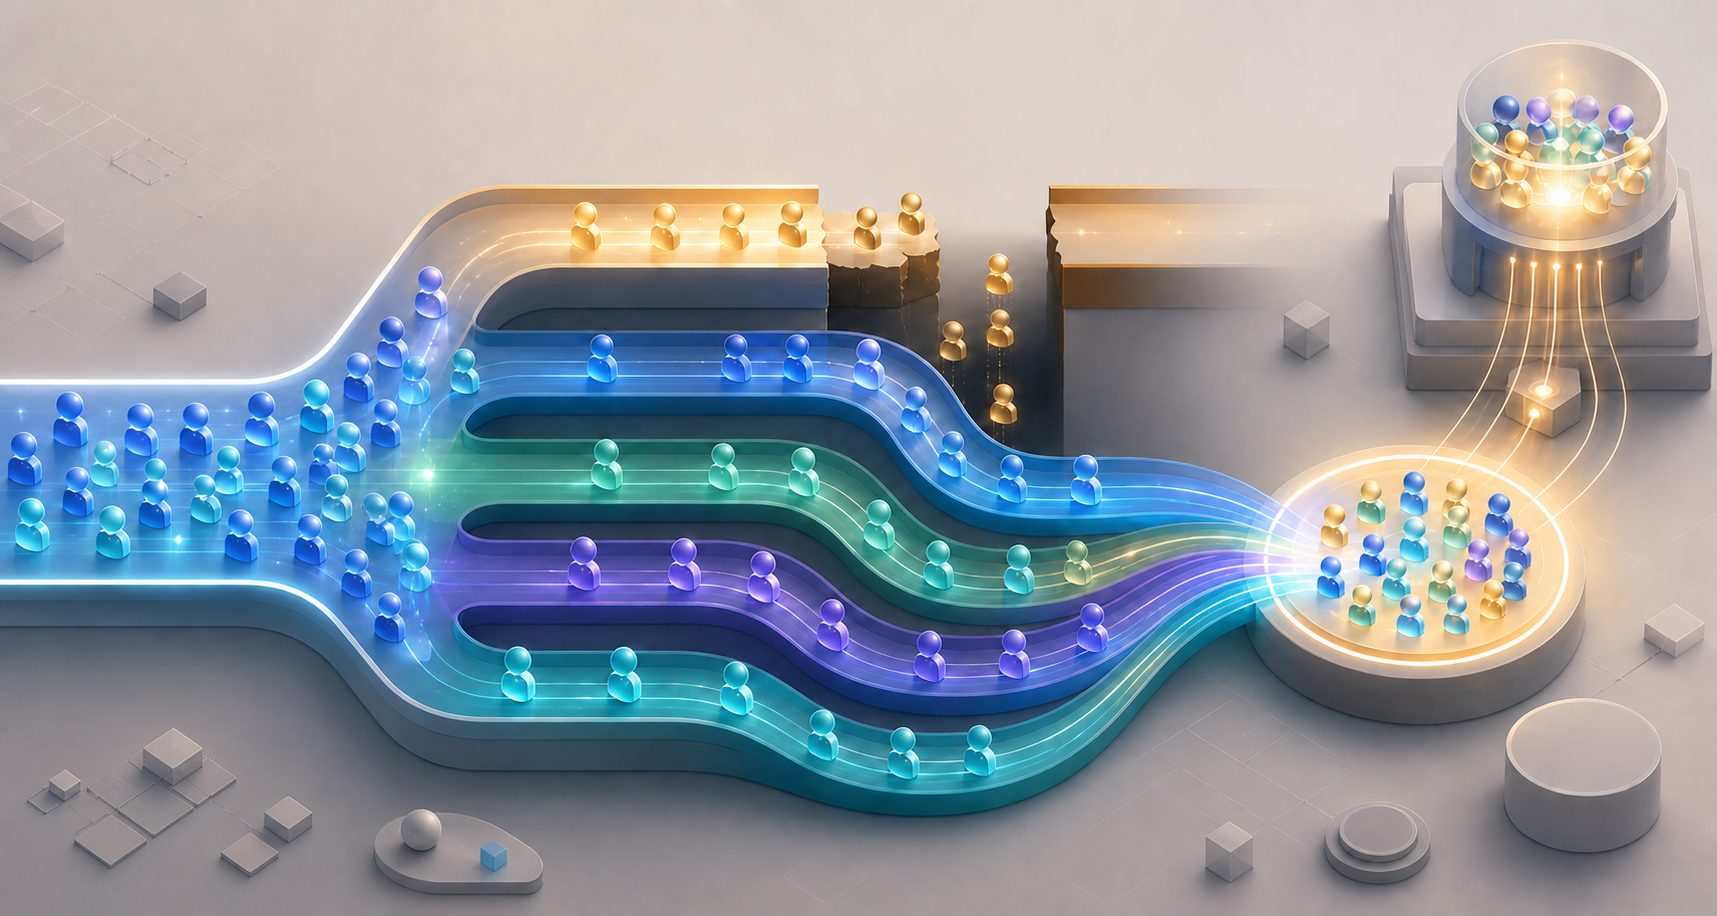
    Customer tokens reroute from a paused paid channel into several other acquisition paths, while some demand disappears before reaching the shared sales destination.

    The moment you pause ads, paid clicks and paid-attributed revenue will fall. That is an implementation check, not the test result. The result is the difference between the total outcome you observed and the total outcome you would reasonably have expected with the ads still running.

    Use a comparable control market or campaign when you have one. Measure how the control changed over the same period, then apply that movement to the test unit’s baseline. This is more defensible than assuming the week before the pause would otherwise have repeated exactly. Without a control, compare against a predeclared baseline and carry the added uncertainty into the decision.

    Calculate the readout in this order:

    1. Estimate the paid-on counterfactual. Determine the total revenue, purchases, or qualified leads you would have expected in the test unit if ads had remained active.
    2. Measure the total incremental loss. Subtract the observed total outcome during the pause from the paid-on counterfactual. This is the business effect attributable to removing the ads, subject to the design’s uncertainty.
    3. Measure channel substitution. Compare organic, direct, and any other plausible substitute channels with their counterfactual levels. Use these movements to explain where demand went, not to override the total-outcome calculation.
    4. Calculate recapture. Divide verified substitute-channel lift by the paid-attributed revenue that disappeared. State clearly which channels were counted and how their counterfactuals were estimated.
    5. Compare incremental value with avoided cost. For a revenue-based view, divide the incremental revenue preserved by the ad spend required to preserve it. For the economic decision, apply the relevant contribution margin and subtract media cost.

    Direct traffic deserves special care. A rise in direct revenue may represent people who saw no ad and typed the address, customers returning through bookmarks, or a change in how analytics classified the visit. The first two can be genuine substitution; the third is measurement reclassification. Look for timing, market specificity, and corresponding stability in total business outcomes before counting the entire increase as recaptured demand.

    The same caution applies to organic traffic. More organic clicks after a pause are persuasive when they occur on the affected queries, in the affected market, during the declared window, and alongside the expected loss of paid clicks. A sitewide organic increase caused by an unrelated SEO release shouldn’t be credited to paid-search substitution.

    What a delayed recapture looks like in practice

    One company paused branded search in the United States, United Kingdom, Australia, and Canada, then paused most non-brand paid search by the end of the month. Its prior spend across branded search, non-brand search, Shopping, and Performance Max averaged $113,000 per month. In one branded campaign, organic already held 71% of overlapping clicks while ads were active, and only $3,945 of $36,129 in spend appeared to purchase clicks that organic could not capture. The remaining $32,184, or 89.1%, functioned as brand defense in that analysis.

    Time after the pauseMonthly organic revenue changeMonthly direct revenue changePaid-attributed revenue recaptured
    Weeks 1-6+$17,800+$14,50030%
    Weeks 7-12+$28,100+$14,10039%
    Week 13 onward+$15,800+$54,00065%

    The important pattern is the delay, not a benchmark you should copy. A six-week read would have made the ads appear much more incremental than the later observation did. The shift toward direct revenue also shows why a paid-versus-organic traffic comparison is too narrow: substitution can cross both channel and attribution boundaries.

    Don’t treat the remaining 35% as automatically incremental. Some of it may be a real paid-search effect, but the strength of that conclusion depends on the counterfactual, controls, tracking, and outside events. Report the observed total loss, the estimated substitute lift, the avoided spend, and the uncertainty separately. A single blended percentage hides the assumptions leadership needs to judge.

    Turn the result into campaign-level budget rules

    An incrementality test should end with a rule someone can execute in the account. “Paid search is incremental” and “brand ads are wasteful” are both too broad.

    • High incremental contribution: retain the tested campaign when the contribution it protects exceeds media cost. Treat expansion as a new hypothesis; the next dollar may not perform like the current dollar.
    • Low incrementality with strong organic substitution: keep the slice paused or reduce it, then monitor organic visibility, total query clicks, revenue, and competitor pressure. Define the conditions that would trigger a retest or restart.
    • Dependent organic performance: manage paid and organic as a combined search system. Investigate which queries lost total clicks or outcomes rather than assuming that an organic ranking alone guarantees replacement.
    • Primarily defensive value: label the budget as brand protection. Decide whether the measured conversion or revenue loss justifies that protection instead of letting attributed ROAS disguise it as acquisition.
    • Uncertain result: don’t force a binary decision. Restore only what is required by the predeclared guardrail, improve the control or measurement, and run a better-bounded test.

    Keep a permanent test record containing the hypothesis, test and control units, campaign changes, baseline dates, primary outcome, rollback rule, exclusions, calculation method, and final decision. Revisit the rule when organic visibility changes, competitors become more aggressive, margins shift, tracking changes, or the campaign begins serving a materially different mix of queries.

    Your next step is to choose one material but reversible slice of paid search. Write its counterfactual, export the paid-organic overlap, lock the business guardrail, and schedule the readout far enough beyond the pause to observe substitution. If the spend returns, it should return with a clear job description: acquisition, channel support, or brand defense. If it doesn’t, you can redirect the budget toward demand you weren’t already positioned to capture.

    References


  • Google’s Mobile Search Ad Test: A Practical Response Plan

    Google’s Mobile Search Ad Test: A Practical Response Plan

    If you manage paid search, Google’s mobile ad presentation test creates an awkward question: should you change campaigns now, or wait until the format becomes more than an isolated experiment? The right answer is to prepare the brand elements the layout exposes, preserve your measurement baseline, and avoid auction-level changes that the available evidence cannot justify.

    The test changes what a mobile searcher may notice first. That could matter for recognition and trust, but it does not yet establish a new campaign rule. Your immediate job is to separate the visible interface change from the performance effects you can actually demonstrate.

    The test adds an identity layer before the ad copy

    In the observed mobile layout, Google places a list of advertisers, including their favicons and domain names, at the top of a sponsored-results block. The individual ads appear below that list. A searcher therefore encounters the participating companies before reaching the first complete ad.

    That is more than a cosmetic rearrangement. The standard ad-reading sequence starts with a specific advertiser’s message. This test inserts a preliminary identity check: which companies are present, which ones look familiar, and which domains appear credible enough to consider.

    Three practical implications follow, although none has been proven as a performance outcome:

    • Recognition may arrive before relevance. A familiar favicon or domain could attract attention before the searcher compares headlines and descriptions.
    • Unfamiliar advertisers may face a sharper trust test. If your domain does not clearly map to your brand, the user may have little reason to remember you when the full ad appears.
    • Ad copy remains important, but it may no longer make the first impression. The advertiser list can frame the choice set before any individual value proposition is read.

    Do not turn those possibilities into conclusions. The test does not show that recognized brands will necessarily gain clicks, that unfamiliar brands will lose them, or that inclusion in the list conveys an endorsement. It only gives you a credible set of hypotheses to examine.

    Treat this as a presentation test, not a new campaign rule

    Google has not publicly explained the experiment, and it remains unclear whether the layout will move beyond limited testing. That uncertainty should govern your response. A screenshot is evidence that a format exists; it is not evidence that your account is consistently exposed to it or that the format changed your results.

    Use this response sequence if someone on your team encounters the layout:

    1. Capture the entire mobile results block. A cropped advertiser row is not enough to understand its position relative to the Sponsored results label, individual ads, and nearby organic results.
    2. Record the observation context. Save the query, date and time, market, device type, browser, and whether the search was performed while signed in. These details will not reveal Google’s test assignment, but they make repeated observations comparable.
    3. Check whether the layout appears again under controlled conditions. Look for a pattern across relevant queries and devices. Do not treat one person’s result as universal.
    4. Annotate the observation in your reporting. Keep it separate from campaign launches, budget changes, promotional periods, landing-page releases, and other events that could affect performance.
    5. Delay structural campaign changes. Bids, budgets, match types, targeting, and creative rotation all introduce new variables. Changing them in response to an unconfirmed interface test makes later diagnosis harder.

    The distinction is simple: prepare for the format where preparation is low-risk, but require performance evidence before altering how you buy traffic.

    Audit the two brand assets users may see first

    A specialist compares a circular identity mark and a rectangular brand image in small mobile interface previews.

    The observed advertiser list emphasizes two compact identity cues: the favicon and the domain. You can review both without rebuilding a campaign or assuming the experiment will become permanent.

    • Inspect the favicon at a genuinely small size. A detailed logo can become an indistinct shape when reduced. Look for strong contrast, a recognizable silhouette, and freedom from tiny text that disappears on a phone.
    • Check the domain as a brand signal. Read the domain without the surrounding ad. It should be easy to associate with the company a user expects to find. Document confusing abbreviations, legacy names, unexpected subdomains, or other mismatches before deciding whether any change is warranted.
    • Compare identity across the journey. The favicon, domain, ad language, and landing-page branding should feel like parts of the same company. A mismatch can be especially costly when a compact advertiser list prompts users to evaluate identity before the offer.
    • Review ad differentiation after the identity check. Once the user reaches the full ads, your message still needs to explain why your option fits the query. Brand recognition cannot substitute for a relevant proposition.
    • Make landing-page verification immediate. An unfamiliar advertiser should not force visitors to hunt for the company name, product relationship, or reason to trust that they reached the intended destination.

    Keep this audit within its proper scope. Nothing disclosed about the experiment establishes that JSON-LD, organic structured data, or an SEO schema change controls the advertiser list. Do not modify markup merely because the interface displays a favicon and domain. That would connect two systems without supporting evidence.

    Measure the effect without confusing visibility with causality

    Two identical smartphones display generic ad layouts with and without an identity layer, separated for controlled comparison.

    The central measurement problem is exposure. Unless Google identifies test participation in reporting, you may know that the layout was observed without knowing which impressions used it. Any account-level analysis is therefore directional, not a clean experiment.

    Build the analysis around the part of the journey the layout can plausibly influence:

    1. Preserve a baseline. Retain mobile performance from a comparable period before the first confirmed observation. Use a window long enough to reflect your normal buying cycle rather than selecting dates because they produce a convenient result.
    2. Separate mobile from desktop. The observed format is a mobile Search test. A blended device report can hide a mobile movement or incorrectly attribute an account-wide change to the layout.
    3. Split branded and non-branded intent. Brand recognition is one of the clearest hypotheses created by the advertiser-first presentation. If branded and non-branded queries move differently, that difference deserves investigation.
    4. Start with click-through rate, then follow the click. Presentation acts before the visit, so CTR is the nearest directional signal. Conversion rate, cost per acquisition, return on ad spend, and lead quality tell you whether any additional clicks were commercially useful.
    5. Use stable comparisons where possible. Compare query groups, markets, or campaigns with similar conditions rather than placing all traffic in one before-and-after total. A comparison is useful only if it was not changed by a different promotion, bid strategy adjustment, budget constraint, or creative release.
    6. Keep a confounder log. Record every material account and site change during the observation period. Without that log, a mobile CTR shift can easily be credited to the interface when a new ad, offer, competitor, or landing page changed at the same time.

    Interpret patterns conservatively. A mobile CTR increase while desktop remains stable would be consistent with a mobile presentation effect, but it would not prove one. A larger branded than non-branded shift would fit the recognition hypothesis, but other brand activity could produce the same pattern. If clicks rise while conversion quality weakens, the format may be attracting attention without improving intent. If nothing meaningful changes, the correct action may be no action at all.

    Only consider campaign changes after you can state the decision rule in advance. For example: if a repeatable mobile-only movement persists while comparable traffic remains stable, review creative or budget allocation in the affected segment. Defining the rule first prevents ordinary volatility from becoming a story after the fact.

    Key takeaways for paid search teams

    • Google’s test places advertiser favicons and domains before the individual mobile Search ads, potentially changing the first cue a user evaluates.
    • The format remains a limited experiment with no confirmed broad rollout, so one sighting should not trigger changes to bids, budgets, targeting, or campaign structure.
    • Audit favicon legibility, domain recognition, ad-to-landing-page consistency, and message differentiation now because those checks are useful even if the test ends.
    • Measure mobile separately, preserve branded and non-branded segments, and treat CTR as an early signal rather than the final business result.
    • Do not assume structured data or schema markup controls the paid advertiser list; no such connection has been established.
    • Without impression-level test identification, performance analysis can support a hypothesis but cannot cleanly prove causation.

    Your next move should be small and reversible: document any sightings, complete the favicon-and-domain audit, and protect a clean performance baseline. If the presentation expands, you will be ready to measure it. If it disappears, you will not have disrupted a working account in pursuit of a temporary interface.

    References

  • Technical SEO Experiment Design: A Practical Framework

    Technical SEO Experiment Design: A Practical Framework

    You shipped a technical SEO change, watched the graph move, and now someone wants to know whether the change caused it. A before-and-after screenshot cannot answer that question. Demand, competitors, algorithm updates and overlapping site changes keep moving, whether your deployment works or not.

    A useful experiment gives you a defensible rollout decision. It identifies the pages that actually received the treatment, compares them with pages facing the same outside conditions, waits for search engines to encounter the change, and defines what success means before anyone sees the result.

    Start with the rollout decision, not the dashboard

    Do not begin with a broad question such as, "Do internal links help SEO?" You cannot turn the answer into a clean implementation decision. Begin with the exact change under consideration and the scope of the possible rollout.

    Suppose you manage a multi-location site. Location pages are reachable mainly through a central locator and state pages, and you want to add contextual links. A testable intervention would be: add one consistently placed module to selected location pages, with links to three nearby locations and two relevant service pages. The design, placement, link count and selection logic stay fixed throughout the treatment group.

    That definition is narrow enough to reproduce. It also prevents the test from quietly becoming a bundle of internal links, rewritten copy, new navigation and a redesigned template. If all four change together, you may learn that the bundle performed differently, but you will not know which part deserves the rollout.

    Write a one-page test charter

    Your test charter should settle the following points before implementation:

    1. Decision: State what you will roll out, reject or revise after the test.
    2. Eligible population: List the templates, directories or page types to which the decision could apply. Record exclusions such as newly launched pages, unstable markets or pages scheduled for another change.
    3. Treatment: Describe the implementation precisely enough that another developer could reproduce it without filling in missing choices.
    4. Unit of assignment: Decide whether you are assigning individual pages, page clusters, markets, categories or templates.
    5. Expected mechanism: Explain the step between the implementation and the desired outcome.
    6. Primary outcome: Choose the metric that will determine the decision. Treat other metrics as diagnostic or protective guardrails.
    7. Decision rules: Define success, failure and inconclusive results before the data arrives.

    A useful hypothesis connects the treatment, mechanism, affected pages and comparison. For the location-page example, it could be: "Adding contextual links from selected location pages to related location and service pages will strengthen crawl paths and internal signals, improving the organic visibility of those destinations relative to comparable pages that retain the existing structure."

    Notice that the receiving pages are central to the hypothesis. The pages displaying the module are not necessarily where the benefit will appear. If your implementation changes how authority and crawlers reach other URLs, those destination URLs belong in the measurement plan.

    Replace vague decision language with operational definitions. "Meaningful improvement" should refer to a minimum effect worth the engineering effort and rollout risk. "Enough data" should require verified implementation, adequate crawl exposure and a stable comparison. Set those standards now. Choosing them after seeing the graph invites the team to move the goalposts.

    Choose the strongest counterfactual your site can support

    Two matched rows of abstract web-page modules travel through the same environment, while a precision device changes one component in only one row.

    The central design question is not what happened after launch. It is what would probably have happened to the treated pages during the same period without the change. Your control or comparison group is an attempt to estimate that missing outcome.

    No SEO control is perfect. Pages differ in age, authority, search intent, link history, demand, competition and seasonality. They also interact through shared templates and internal links. Your job is to build the strongest comparison the site genuinely supports, then state where it remains weak.

    DesignUse it whenWhat it improvesMain limitation
    Concurrent split testYou have a large, stable set of sufficiently similar pages and can safely withhold the change from part of it.Treatment and control experience the same calendar period, helping account for demand shifts, seasonality and broad search changes.A nominally random split can still be imbalanced when markets, categories or page histories differ sharply.
    Matched page groupsA clean split is impractical, but you can identify pages or sections with similar historical behavior.Matching can account for baseline trajectory, demand, crawl frequency, indexing, page age or market characteristics.Unmeasured differences can still explain part of the result.
    Phased rolloutThe change is intended for the whole site, but it can be introduced across markets, categories or templates in stages.Untreated phases provide temporary concurrent controls while delivery continues.The control disappears as rollout advances, and later phases may face different conditions.
    Before-and-after observationNo credible concurrent control is available.It can reveal direction and surface implementation problems.It cannot reliably separate the change from external events, so conclusions must remain limited.

    Do not assume a 50/50 split creates comparable groups. A location-page template can cover major cities, small markets, mature pages and recent launches. If the stronger markets land disproportionately in one group, random assignment has not rescued the design.

    Build the groups in this order:

    1. Create the eligible page pool using the exclusions in your test charter.
    2. Collect pre-test behavior for the metrics connected to the hypothesis, including clicks, impressions, rankings, crawl activity or indexing where relevant.
    3. Describe structural differences such as page age, market size, branded demand, template subtype and known seasonal behavior.
    4. Pair, stratify or match pages using characteristics that could plausibly affect the outcome.
    5. Inspect the historical trajectories of the proposed groups. Similar current totals are less useful when one group has been rising and the other declining.
    6. Lock the assigned URLs before launch and preserve that list. Do not move inconvenient pages between groups after results begin to appear.

    Historical co-movement often matters more than equal starting values. A higher-traffic treatment group can still be informative when it has moved like the comparison group over time. Conversely, two groups with matching traffic on launch day may be poor controls if their preceding trends point in opposite directions.

    When the page pool is small or highly varied, honest matching may produce a stronger test than a ceremonial random split. The method should reflect the control you possess, not the certainty you want to present.

    Protect the treatment from contamination and spillover

    A strong comparison will not save a test whose implementation keeps changing. Freeze the feature being tested, record unrelated releases and make ownership explicit. If a critical production fix must alter the affected template, document the date, affected URLs and expected influence instead of pretending the test remained untouched.

    Use an implementation checklist before examining outcomes:

    • Confirm that every assigned treatment page received the intended feature and every control page remained untreated.
    • Check the production output a crawler can encounter, not only a component preview or staging screenshot.
    • Validate the destination URLs, link selection logic, canonical targets and status behavior relevant to the change.
    • Record partial deployments, rollbacks, rendering failures and pages added or removed during the test.
    • Keep a dated change log for migrations, template releases, navigation changes, content programs and other work that could affect either group.
    • Preserve the original page assignments even if some URLs later need to be excluded from the final analysis. Record exclusions and their reasons separately.

    Internal-link experiments need an additional check: treatment can spill beyond the page carrying the new module. If treatment page A links to control page B, page B may receive part of the intervention. Comparing A with B as though only A were exposed would misstate what the test changed.

    Map the link graph created by the feature before assigning groups. When pages are tightly connected, assign coherent clusters, markets or sections rather than individual URLs. If cross-group links cannot be avoided, label the affected destinations and interpret the comparison as partially contaminated.

    Contamination also works in the opposite direction. A shared template update, global navigation change or sitewide indexing problem can reach both groups. A concurrent control may help absorb the common movement, but only if you know the event occurred and can verify that it affected the groups similarly.

    Measure exposure before judging the SEO outcome

    A glowing probe scans a network of web-page tiles, illuminating encountered treated pages while other pages and blocked routes remain dim.

    A deployment timestamp is not proof that the search system has encountered your treatment. Search engines have to revisit the relevant pages, process what they find and propagate any downstream effects. Calling a test early because a fixed number of calendar weeks has passed can turn an exposure failure into an apparent SEO failure.

    Think in three clocks. The development clock starts when the release reaches production. The exposure clock advances as the affected source and destination pages are crawled and processed. The outcome clock covers the period in which the hypothesized search effects have a reasonable opportunity to appear. These clocks rarely start together.

    Build the measurement stack in layers:

    • Deployment: How many assigned pages contain the correct treatment? How many controls were accidentally changed?
    • Exposure: Which treated source pages and affected destination pages have been recrawled since deployment? Is crawl coverage broad enough to evaluate the group?
    • Mechanism: Did the signals closest to the intervention move, such as crawl activity, discovery or indexing where those are part of the hypothesis?
    • Primary outcome: Did the predefined visibility, ranking, impression, click or traffic measure improve relative to the comparison?
    • Guardrails: Did the change create declines, crawl waste, indexing problems or regressions elsewhere in the eligible population?

    Report coverage, not just elapsed time. If only a limited portion of affected pages has been revisited, the result is not yet a fair test of the implementation. Insufficient recrawling can make an otherwise valid change look ineffective.

    Match every metric to a place in the causal chain. For an internal-linking test, crawl behavior is closer to the implementation than organic clicks. That makes crawl data useful diagnostic evidence, but it does not automatically make it the business outcome. If crawl activity improves while visibility does not, you have evidence for one step of the mechanism, not proof that the full hypothesis succeeded.

    Measure both sides of a transfer. Track the pages carrying the new links to verify implementation and the pages receiving them to test the expected benefit. Aggregating the whole site can hide the effect by mixing exposed destinations with thousands of unaffected URLs.

    Use the launch date as an annotation, not as an automatic verdict date. The stopping rule should depend on verified exposure, usable outcome data and the continued validity of the comparison. If those conditions are not met, classify the result as inconclusive rather than extending or ending the test until the graph tells the preferred story.

    Turn the result into a rollout, rejection or retest decision

    Start with the comparison, not the treatment group’s raw chart. At minimum, calculate how the treatment changed from its baseline and how the control changed over the same period. The difference between those changes is the incremental estimate you care about. Use the metric transformation and aggregation method you selected before launch; switching between totals, averages and percentages after seeing the data is another way to manufacture a favorable reading.

    Then classify the result against the prewritten rules:

    • Success: The implementation and exposure checks pass, the primary outcome improves relative to the comparison by a practically worthwhile amount, and guardrails remain acceptable. Roll out to the population represented by the test, not automatically to unrelated templates or markets.
    • Failure: Exposure and comparison quality are adequate, but the primary outcome shows no meaningful incremental benefit or declines. Do not rescue the test by promoting a secondary metric that happened to move.
    • Inconclusive: Crawl exposure is insufficient, treatment integrity failed, the groups stopped being comparable, contamination was material or the available signal cannot support a decision. Fix the design and retest if the decision remains valuable.

    Mixed results need a causal reading. If crawl activity improves but rankings do not, the change may have influenced the early mechanism without producing the intended visibility outcome. That can justify further investigation, but it is not a ranking win. If both treatment and control rise together by similar amounts, the movement is evidence of a shared condition, not an incremental treatment effect. If only a narrow page subtype benefits, consider a targeted rollout rather than averaging the subtype away or extending the feature everywhere.

    Write the final decision with its boundary conditions. Name the tested page population, intervention, exposure status, comparison method, primary result, important guardrails and known weaknesses. A result from established location pages does not automatically establish the same effect for editorial articles, product pages or newly launched markets.

    Key takeaways

    • Define the rollout decision, treatment, mechanism, affected pages and primary outcome before implementation.
    • Use a concurrent split when page volume and comparability permit it; otherwise use matched groups, a phased rollout or a carefully qualified before-and-after observation.
    • Compare historical trajectories, not just launch-day traffic, when building treatment and control groups.
    • Prevent overlapping releases and cross-group links from contaminating the intervention.
    • Verify deployment and crawl exposure before interpreting rankings, clicks or traffic.
    • Predefine success, failure and inconclusive states, then keep secondary metrics in their diagnostic roles.

    Your next step is small: choose one pending technical change and write its test charter before the implementation ticket is finalized. If you cannot name the decision, comparison, affected URLs, exposure check and stopping rule on one page, the experiment is not ready to launch.

    References

  • How to Make Evidence-Based SEO Investments Under Uncertainty

    How to Make Evidence-Based SEO Investments Under Uncertainty

    Your leadership team wants a yes-or-no answer: keep funding SEO while AI answers reshape discovery, or wait until the channel becomes predictable. That is the wrong decision frame. Uncertainty increases the value of protecting durable assets and buying useful information through controlled tests. It does not make inactivity free.

    You do not need to predict the final form of search. You need an investment system that distinguishes essential maintenance from speculative work, contains downside risk, and gives every experiment a clear path to scale, stop, or further investigation.

    A pause is a position, not a neutral baseline

    A budget freeze can feel reversible because no new campaign has been launched and no visible loss appears on day one. Organic visibility does not behave that way. Content freshness, technical health, trust, and authority develop over time. When that work stops, competitors can occupy the space while your recovery becomes slower and potentially more expensive. The resulting costs can appear as lost share of voice, weaker pipelines, and a longer route back to your previous position.

    That means “spend nothing” belongs in the same investment analysis as any proposed initiative. Make the pause defend itself. For each important site segment, document what would stop, what would probably deteriorate, how you would notice the deterioration, and what would have to be rebuilt when funding returned.

    • Maintain: What recurring work protects discoverability, accuracy, technical reliability, and commercially important pages?
    • Reduce: Which assets will still be maintained, and which slower deterioration are you consciously accepting?
    • Pause: What signals will warn you that the decision is damaging visibility or demand, and who has authority to restart work?

    Assess those consequences by page group, product line, audience, or market rather than relying on one sitewide average. A healthy brand section can hide a weakening non-brand category. Stable total traffic can conceal lost visibility on the queries that introduce new buyers. The investment decision should follow the exposed asset, not the reassuring aggregate.

    This does not mean every SEO budget should stay untouched. It means that reducing investment should be an explicit trade: a known saving now in exchange for defined maintenance risk, lost learning, and uncertain recovery later.

    Give every SEO dollar one of three jobs

    A stream of metallic tokens divides among crews maintaining a digital library, testing a module in a laboratory, and expanding a modular structure.

    An evidence-based budget becomes easier to defend when every line item has a distinct job. Separate foundation work, market observation, and experimentation instead of placing all three in a single “SEO growth” bucket.

    1. Protect the foundation. Keep commercially important content current, maintain technical accessibility, audit the site, preserve authority-building activity, and continue producing original information that helps people make decisions. These are durable inputs to visibility across traditional and AI-mediated search, even when individual interfaces and tactics change.
    2. Observe the environment. Monitor the parts of search that could change the return on your work: audience priorities, product strategy, competitor movement, algorithms, and LLM behavior. Observation earns its budget by producing a decision, not by producing another dashboard.
    3. Buy information through experiments. Test uncertain changes on a controlled scope, measure their incremental effect, and expand only when the evidence supports expansion. Experiments are a learning mechanism within the strategy, not a substitute for the foundation.

    Fund the maintenance floor before funding speculative tactics. If the budget cannot support the whole site, narrow the protected scope deliberately. Start with assets that combine commercial importance, evidence of existing demand, and meaningful consequences if they deteriorate. Do not spread cuts evenly merely because an even reduction is administratively simple.

    Then rank discretionary proposals with a consistent filter:

    • Expected value: What business outcome could improve if the idea works?
    • Evidence strength: Is the proposal based on your own relevant data, a credible external pattern, or an untested assumption?
    • Reversibility: Can the change be removed quickly without damaging valuable pages, revenue, or measurement?
    • Learning value: Would the result guide decisions across a meaningful group of pages, or answer only a narrow question?
    • Measurement readiness: Are the affected pages, success metric, guardrails, comparison group, and tracking already available?

    Keep expected return and learning value separate. A low-risk test can deserve funding even when its immediate upside is uncertain if the answer will improve many later decisions. A sweeping change to high-revenue pages needs stronger prior evidence because the cost of being wrong is higher.

    Turn an uncertain tactic into a decision-grade test

    A modular tile passes through a transparent two-lane testing apparatus and reaches routes for scaling, further inspection, or stopping.

    “Add more schema,” “refresh the content,” and “optimize for AI” are activities, not hypotheses. None specifies where the change applies, what should move, what must not get worse, or what you will do with the result.

    Write a hypothesis that can lose

    Use this structure: For this eligible group of pages, making this consistent change should improve this primary outcome over this measurement period, compared with this control, without causing an unacceptable decline in these guardrail metrics.

    A useful hypothesis must be actionable, consistently implemented, measurable, and allowed enough time and exposure to reveal an effect. Tiny edits on a few low-traffic pages rarely justify formal experimentation because the result is unlikely to resolve the decision. As an illustration of test scale rather than a universal benchmark, changing a word in the H1 across 30 pages receiving more than 100 monthly sessions and observing them for four weeks is more testable than changing a word buried in the body copy of a few quiet pages.

    Before approval, put the hypothesis on a one-page test record with the affected page set, excluded pages, implementation owner, launch window, primary metric, business guardrails, control group, known confounders, monitoring cadence, rollback condition, and decision owner. If the team cannot fill those fields, the proposal is not ready to consume an experimentation budget.

    Match the method to the question

    MethodQuestion it can answerMain limitation
    User-level A/B testDoes one experience improve engagement, interaction, or conversion for users who see it?Splitting visitors between versions does not isolate the ranking effect of changing the page for search engines.
    Pre/post testDid performance change after an update to the same page or page group?Seasonality, algorithm changes, competitors, and other outside factors can create the apparent difference.
    Incrementality testDid changed pages outperform comparable unchanged pages during the same period?It requires a sufficiently similar control group and clean implementation across both groups.

    Use A/B testing for user experience or conversion questions. Use pre/post analysis when a credible control is unavailable and you need directional evidence. For rankings, visibility, or organic traffic, a concurrent comparison between changed and unchanged page groups provides the strongest isolation of the three methods because both groups experience the same period while only the test group receives the intervention.

    If you must use pre/post analysis, lower the confidence of the conclusion. Check sitewide movement, seasonal patterns, other campaigns, algorithm changes, and competitor activity before assigning the difference to your change. A later staged rollout across more eligible pages can show whether the pattern repeats.

    Contain the downside before launch

    Risk planning belongs in the test design, not in the incident response. A conservative rollout can use cross-browser and device QA, a lower-value pilot page, a tracking check after three days, weekly monitoring, and a prepared rollback plan. Avoid launching immediately before a weekend or another period when nobody can respond.

    • Confirm that pages load, render, link, and report analytics as expected.
    • Test on lower-value eligible pages before exposing the pages responsible for the most leads or revenue.
    • Record the original state and the exact reversal procedure before publishing the change.
    • Increase monitoring frequency when the possible impact on revenue, conversions, or site function is high.
    • Leave enough time to complete the test and any rollout before a busy season complicates measurement or raises the cost of failure.

    Reversibility should affect test scope. A cheap, easily reversed change can justify a broader initial test. A technically risky or revenue-sensitive change should begin small even when the projected upside looks attractive.

    Read the result as a business decision, not a traffic result

    An organic sessions increase is not automatically a win. Sessions can rise while conversion rate falls, or visibility can expand around queries that do not match the audience you intended to attract. That is why result analysis must check the full data set, validate surprising numbers, and look beneath the headline metric.

    Read every completed test in the same order:

    1. Verify implementation and tracking. Confirm that the intended pages received the intended change, the control did not, and both groups produced reliable data.
    2. Inspect the before-and-after movement. Establish what changed in the test group after launch.
    3. Compare the control. Determine whether similar unchanged pages moved in the same direction during the same period.
    4. Check the site context. Look for sitewide shifts that could indicate an algorithm event, demand change, tracking problem, or another marketing campaign.
    5. Check seasonality. Compare with the relevant prior seasonal period where that context is available rather than treating every temporal pattern as a test effect.
    6. Inspect quality and business impact. Review query intent, qualified traffic, conversion behavior, leads, revenue, or the closest valid downstream outcome.

    Decide the response before stakeholders debate the most flattering chart:

    • Scale: The primary metric improves against the control, the data checks out, and important business guardrails remain acceptable. Expand in stages so the rollout continues to confirm the effect.
    • Hold: The result is inconclusive but the implementation and measurement are valid. Record what remains unknown, then decide whether more exposure or a redesigned test is worth the cost.
    • Investigate: Visibility improves while conversion quality deteriorates. Examine query and landing-page intent before calling the change successful.
    • Stop or roll back: A guardrail deteriorates, the page malfunctions, tracking becomes unreliable, or the downside exceeds the value of additional learning.

    Do not keep extending a weak test until the chart finally looks favorable. An inconclusive result is evidence about the design, exposure, or effect size; it is not permission to declare a win. Preserve the record so the next proposal starts with what you already learned.

    A winning result is not permanent law either. Search systems, competitors, content, and user behavior continue to change, so a tactic that works during one period may not retain the same value indefinitely. Monitor scaled changes as part of the maintained foundation.

    Finally, define trigger events that require the portfolio to be reviewed. Relevant triggers include a shift in products, services, audiences, internal goals, competitor behavior, major algorithms, or LLM behavior. A trigger should prompt a fresh assessment, not an automatic budget increase or shutdown. Recheck the original assumptions, then choose whether to maintain the course, expand an experiment, reduce exposure, or move resources.

    Key takeaways

    • Treat pausing SEO as an investment scenario with its own costs, risks, warning signals, and recovery requirements.
    • Protect foundational work first, fund monitoring that can trigger decisions, and isolate speculative tactics inside experiments.
    • Require every experiment to name its page set, intervention, primary metric, guardrails, comparison group, measurement period, and decision rule.
    • Use user-level A/B tests for experience and conversion questions, pre/post tests for directional evidence, and concurrent test-control groups for stronger ranking evidence.
    • Scale only when the incremental result survives data validation and business guardrails; hold, investigate, or reverse the rest.
    • Revisit the portfolio when meaningful internal, competitive, algorithmic, or LLM changes invalidate its assumptions.

    At your next budget review, bring the portfolio rather than a prediction. Approve the maintenance floor, name the next controlled bet, document its scale and rollback rules, and identify the events that would change your allocation. You may not remove uncertainty from search, but you can stop paying for it blindly.

    References

  • Curiosity-Driven Social Ads: A Practical Creative System

    Curiosity-Driven Social Ads: A Practical Creative System

    Your ad stops the thumb, but viewers leave as soon as the opening gives way to a familiar product pitch. The hook worked. The rest of the ad did not give them a reason to stay.

    The fix is not a louder opening or more frantic editing. You need a controlled sequence of questions, partial answers, proof, and payoff. That sequence turns a moment of attention into enough interest for someone to understand the offer and decide whether it is relevant.

    Key takeaways

    • A hook earns a pause. Curiosity earns the next few seconds by creating a question the viewer genuinely wants answered.
    • Build one primary information gap, then close it through a sequence of useful revelations rather than withholding the answer until the final frame.
    • Give creators a planned beat sheet but room to choose their own words. Natural delivery and deliberate structure can coexist.
    • Judge creative with retention, completion, replay, save, share, click, and conversion signals. No single metric tells you whether the ad is commercially effective.
    • Test the opening, revelation sequence, demonstration, and product transition separately so you can identify the part that changed performance.
    • Curiosity must repay attention. If the resolution is vague, irrelevant, or weaker than the promise, the ad becomes clickbait and trust falls with it.

    Build a curiosity chain, not a single hook

    Four connected tabletop scenes progressively reveal, demonstrate, and show the use of an unbranded product.

    Attention is an event: someone notices an unusual visual, a sharp line, or an unexpected result. Curiosity is a continuing state: the viewer notices that something remains unresolved and chooses to follow it.

    That distinction matters because Meta and TikTok increasingly use AI-powered delivery systems that respond to engagement, watch time, and downstream conversion behavior. An opening that produces a brief pause but immediate abandonment gives those systems less evidence of sustained interest than an ad people actively choose to finish, replay, save, share, or click.

    A curiosity gap is the distance between what the viewer knows and what they now want to know. It might be the cause of an unexpected result, the missing step in a demonstration, or whether a solution worked under a condition that resembles their own. It should not be a random mystery pasted onto an unrelated offer.

    Write the curiosity brief before the script

    Before anyone records, answer the following in plain language:

    1. What should the viewer understand by the end? Write the commercial conclusion without slogans. If you cannot state it clearly, the creative will wander.
    2. What question will carry the ad? Choose one primary question, such as why a familiar approach failed, what caused a surprising outcome, or whether a particular method can solve the viewer’s problem.
    3. Why does that question matter to this audience? Connect it to a recognizable frustration, risk, desire, or decision. Curiosity without relevance produces empty viewing.
    4. What evidence will resolve it? Select the demonstration, observation, comparison, explanation, or experience that makes the answer credible.
    5. Where does the product belong? Introduce it when the viewer can understand its role, not merely because the logo is due to appear.
    6. What is the complete payoff? State the answer you owe the viewer. The ending must satisfy the question created at the beginning.
    7. What should happen next? Match the call to action to the level of intent the ad has earned.

    This brief prevents a common mistake: opening with a compelling problem and then abandoning it for a feature list. Every beat should either advance the answer, provide proof, or help the viewer decide whether the answer applies to them.

    Use a question-and-answer ladder

    Do not keep one answer locked away while padding the middle. Give the viewer useful progress. Each beat can close a small question while opening the next logical one:

    • Opening tension: What happened, and why is it unexpected?
    • Relevant context: Why was the outcome a problem worth solving?
    • First revelation: What obvious explanation turned out to be incomplete?
    • Mechanism or demonstration: What was actually happening?
    • Product connection: How did the product change the process or result?
    • Resolution: What should the viewer conclude from what they have seen?
    • Next step: What can an interested viewer do now?

    The sequence should feel inevitable. If you remove the product and the opening story still reaches the same conclusion, the connection is probably too weak. If the product appears before the problem has meaning, the ad will feel like a disguised sales pitch.

    Make creator ads sound natural without leaving them to chance

    Conversational creator ads work differently from compressed brand spots. Longer, less polished creator videos are sometimes called yapper ads. They may move through a personal experience, an explanation, or a demonstration before naming the product. Their apparent looseness can make them feel like content someone chose to share rather than a commercial recited at them.

    That does not mean you should ask a creator to improvise the strategy. Most people will either disclose the conclusion too early, drift away from the main question, or remember the selling points and forget the promised payoff.

    Give the creator a beat sheet rather than a word-for-word script. Specify what each beat must accomplish, the evidence that must appear, any claim boundaries, and the final action. Let the creator choose the connective language, pauses, examples, and conversational rhythm.

    A reusable creator beat sheet

    1. Start inside the problem. Open with the moment the creator noticed something was wrong, surprising, or inconsistent with what they expected.
    2. Make the consequence concrete. Explain why the situation mattered without inflating the stakes.
    3. Show the first attempt. A failed assumption or incomplete fix gives the eventual answer context.
    4. Reveal the missing mechanism. Explain what changed the creator’s understanding of the problem.
    5. Demonstrate the product’s role. Show the action, process, or result instead of substituting adjectives for evidence.
    6. Close the original question. Return to the tension from the opening and provide a definite resolution.
    7. Invite the next step. Use a call to action that follows naturally from the resolved problem.

    A useful opening pattern is: I thought the obvious fix would solve this problem, but it made this specific symptom worse. The next beat must explain what happened. It cannot jump directly to a product name and leave the contradiction unresolved.

    Another workable pattern begins with a visible result, then asks what produced it. The demonstration supplies the answer in stages. This is especially useful when the product has a behavior viewers can see, because the proof becomes part of the story rather than a claim delivered over unrelated footage.

    During recording, capture complete thoughts and natural pauses. In editing, remove repetition but preserve the cause-and-effect chain. A jump cut should move the explanation forward, not create artificial urgency. The goal is not to make a conversational ad slow; it is to give each second a clear job.

    Protect the line between curiosity and clickbait

    Every open loop creates a debt. The viewer gives you time because the ad implies that an answer is coming. Honest curiosity repays that debt with an explanation, result, or demonstration that is useful even if the viewer does not buy.

    Clickbait uses the same surface mechanics but breaks the exchange. It exaggerates the opening, delays a simple answer without adding value, or resolves the story with information that has little to do with the promise. The problem is not merely tone. A disappointed viewer can abandon the video, ignore the call to action, or carry their distrust to the brand.

    Run a promise-payoff check

    Review the finished ad without sound first, then read its transcript without the visuals. In both passes, ask:

    • Can you state the opening promise in one sentence?
    • Does the middle provide meaningful progress, or does it merely postpone the answer?
    • Is the final answer specific enough to satisfy the opening?
    • Does the proof support the conclusion the viewer is asked to draw?
    • Is the product essential to the resolution, or has it been attached to an unrelated story?
    • Would a reasonable viewer feel that the time spent watching was respected?
    • Does the call to action follow from the evidence, or does it demand more confidence than the ad earned?

    Also inspect every transition. A strong transition answers one question and introduces the next. A weak transition changes the subject. When the ad jumps from a personal problem to a generic feature montage, curiosity collapses because the viewer can already predict the rest.

    Do not manufacture uncertainty around information the audience needs to evaluate the offer. The mystery should concern the story or mechanism, not whether the ad will eventually disclose a meaningful condition. The more consequential a fact is to the buying decision, the less useful it is as a tease.

    Measure the whole attention-to-action sequence

    A smartphone projects a path of glowing steps through a lens and doorway toward a hand reaching for a product.

    The traditional focus on the first three seconds is still useful, but it answers only whether the opening earned a chance. It does not tell you whether the story sustained interest, the proof created confidence, or the offer produced action.

    Read performance as a sequence of signals:

    • Initial attention: Did viewers stay beyond the opening instead of leaving immediately?
    • Sustained interest: Did watch time and completion behavior indicate that the middle held attention?
    • Active value: Did viewers replay, save, or share the video, including sharing it through direct messages?
    • Commercial interest: Did clicks occur after viewers had enough context to understand the offer?
    • Business outcome: Did the resulting visits produce the downstream conversion the campaign was built to generate?

    Watch time, completion, replays, saves, shares, post-view clicks, and conversions provide different evidence of chosen attention. Read them together. A long watch with no commercial response may mean the story entertained but did not qualify the viewer. A strong opening followed by weak completion points toward a middle that became predictable, repetitive, or disconnected from the hook. Completed views without clicks can indicate that the payoff was satisfying but the product transition or call to action was not persuasive.

    These patterns are diagnostic prompts, not automatic verdicts. Placement, audience delivery, offer, landing experience, and campaign objective can also shape the result. Use the creative signals to identify the next question, then isolate that question in the next test.

    Test one part of the curiosity system at a time

    Begin with a control ad and create variants around a single creative decision. Keep the offer, core message, and other controllable campaign conditions stable where possible.

    1. Test the opening. Keep the body and payoff unchanged while changing the initial tension, visual, or question. This tells you which version earns the strongest entry into the same story.
    2. Test the revelation sequence. Keep the opening constant while changing how the explanation unfolds. Compare direct explanation with demonstration, personal experience, or a problem-and-discovery progression.
    3. Test the proof. Preserve the promise and product role while changing the evidence used to resolve the question.
    4. Test product timing. Introduce the product at different logical points, but do not change the ending. Look for the point at which its appearance feels informative rather than interruptive.
    5. Test the payoff and call to action. Keep the preceding story stable while changing how explicitly the conclusion connects the result to the next step.

    Do not select a winner from the opening signal alone. The variant that stops more people can still attract poorly matched attention or fail to hold it. Compare retention behavior with clicks and downstream conversions, then choose the creative that advances the campaign’s actual objective.

    Keep a simple test record containing the hypothesis, the element changed, the control, the observed retention pattern, and the business outcome. This turns individual ads into reusable knowledge. Without that record, teams often repeat the same hook test while the real weakness sits in the middle of the story.

    Start with one active ad. Print its transcript, underline the question created in the opening, and label the exact line that resolves it. Then mark what new reason to continue appears between those points. If the middle contains no useful progress, rewrite that sequence before producing another hook.

    Automated delivery can decide who receives the next impression. Your controllable advantage is making that impression worth following. Build an honest question, reward each additional second, and let the sale follow from a conclusion the viewer was given enough evidence to reach.

    References

  • How to Measure and Test Google Ads Without False Winners

    How to Measure and Test Google Ads Without False Winners

    Your Google Ads experiment produced a lift, but you still can’t answer the question that matters: should you change the account? That usually happens when the platform reports movement without proving what caused it, whether it will persist, or whether the measured conversion was valuable in the first place.

    You need a measurement system that can survive automated bidding, responsive creative, uneven audience delivery, and pressure to declare a winner. The framework below helps you define the decision before launch, protect the test from weak tracking, interpret conditional results, and report what the evidence actually supports.

    Key takeaways for reliable Google Ads experiments

    • Define the business decision before the metric. A test should tell you whether to adopt, reject, extend, or refine a specific change. It should not merely produce a dashboard comparison.
    • Separate primary outcomes from diagnostic actions. Purchases, qualified leads, calls, chats, and video engagement do not carry the same business value and should not be flattened into one conversion total.
    • Test strategic inputs while holding the operating environment as stable as practical. Creative propositions, landing pages, offers, and first-party signals are useful inputs to test. Simultaneous budget, bidding, tracking, and promotion changes make the result difficult to interpret.
    • Expect performance to vary by context. A creative asset can be valuable for one audience or situation without becoming the account-wide winner. Evaluate the role it plays before removing it.
    • Report counts, percentages, quality, and value together. No single metric explains performance. A transparent report shows what happened, what composed the result, what remains uncertain, and what decision follows.

    Define conversion truth before you design the test

    Glowing signal particles pass through transparent filters that remove duplicates and low-quality events before verified tokens reach a value balance.

    A conversion is whatever the account configuration counts as a conversion. It is not automatically a customer, revenue event, or profitable outcome. A form submission, marketing-qualified lead, and closed sale represent different stages of the business, even when all three appear under a conversion heading.

    Start with a measurement contract. This is a short written agreement between the people running the campaign and the people using its results. Complete it before anyone builds an experiment:

    1. Name the decision. State exactly what you will change if the evidence is favorable. Examples include replacing a landing page, introducing a new value proposition, expanding an audience signal, or changing the allocation between campaign types.
    2. Select one primary business outcome. Use the deepest dependable event available at sufficient volume, such as a purchase, qualified lead, or imported sale. If the final sale arrives later, record the delay rather than quietly substituting a faster but weaker action.
    3. Classify secondary actions. Calls, chats, form starts, page engagement, and video views can help diagnose behavior. Mark them as secondary unless the business has explicitly established their value.
    4. Define the population. Record the campaigns, locations, devices, customer types, products, and dates included. Decide how you will handle existing customers, branded demand, and other traffic that could answer a different question.
    5. Set guardrails. Identify outcomes that must not deteriorate even if the primary metric improves. Lead quality, total acquisition volume, cost, order value, and downstream revenue are common guardrails when they are available.
    6. Write the decision rules. Specify what would justify adoption, extension, iteration, or rejection. Do not invent the rule after seeing which interpretation makes the test look best.

    Audit the composition of the conversion column

    Open the conversion-action breakdown rather than trusting the headline total. For every action, record its name, trigger, inclusion status, assigned value, source, and relationship to revenue. If a video-engagement event and a purchase are both included, the aggregate conversion count cannot serve as an unqualified business result.

    This audit also protects automated bidding. When weak actions sit beside valuable ones without an appropriate distinction, the bidding system can pursue the easier event while the report celebrates a rising total. The number may be technically accurate and strategically misleading at the same time.

    Automation can build tags, but it cannot validate meaning

    If Google Tag Manager displays the Google Ads Purchase Conversions Guided Setup card, the beta can create the required tags, triggers, and variables automatically. Availability is not universal, and generated configuration should still go through the same quality checks as a manual implementation.

    Complete a real test transaction before launching the experiment. Confirm that the expected action fires once, reaches the intended Google Ads conversion action, and carries the correct value and currency when those fields are part of your setup. Check any order identifier or deduplication mechanism your implementation uses. Then compare the platform record with the commerce or lead system that represents business truth.

    Do not launch new tracking and a strategic campaign test at the same time. If the numbers move, you will not know whether user behavior changed or measurement changed. Stabilize and verify the instrumentation first; start the experiment afterward.

    Design the experiment for an automated auction

    A randomized split feeds two protected experiment lanes with matching bidding machines while uneven audience signals flow through an automated auction environment.

    Modern Google Ads delivery is already adaptive. Bidding changes auction participation, responsive formats assemble different assets, and audience signals influence where the system searches for demand. Your experiment therefore sits inside another optimization system. A clean plan isolates the strategic input you control without pretending that every impression is otherwise identical.

    Write a hypothesis with a mechanism

    Use this structure: For a defined audience and context, changing a specific input should improve the primary business outcome because of a stated mechanism, without breaching named guardrails.

    The mechanism matters. Improving a headline because it makes the offer clearer is a hypothesis. Improving performance because the new headline is better is circular. A mechanism tells you what to inspect when the aggregate result is mixed and what to carry into the next creative iteration.

    Choose one strategic variable at the experiment-arm level whenever practical. If you test a new offer, new landing page, new audience signal, and new bidding target together, you may learn whether the package performed differently, but you will not know which input deserved the credit. A package test can still be valid when the decision is whether to adopt the entire package; label it that way from the start.

    Screen creative before spending money on it

    Letting the platform rotate every submitted idea is not a substitute for creative judgment. Use the MOCA framework as a preflight check:

    • Magnetic: Does the message attract the intended buyer while helping an unsuitable visitor decide not to click? Good qualification can reduce wasted traffic even when it does not maximize click-through rate.
    • Obvious: Can someone identify the offer, category, and payoff without decoding the ad? Every text, image, and video asset should reinforce the same central idea.
    • Congruent: Does the promise fit the user’s likely intent, and does the landing page fulfill that promise? Message match is necessary, but the offer must also make sense for the stage of demand.
    • Actionable: Is the next step clear, specific, and appropriate to the commitment being requested?

    Reject assets that fail this screen before the test. The purpose is not to predetermine the winning execution. It is to ensure the experiment compares ideas that are coherent enough to deserve budget.

    Build useful variety, not cosmetic variation

    Responsive creative needs assets with distinct jobs. One message might qualify a price-conscious buyer, another might emphasize speed, and another might address risk or governance. That variety gives the system options for different users. Rewriting the same claim with minor punctuation or capitalization changes produces little strategic information.

    This is the practical meaning of testing for asset liquidity rather than one universal champion. A headline with weaker aggregate reporting may still be the strongest match for a smaller, valuable audience. Before pausing it, ask whether it supplies a proposition that no remaining asset covers.

    Set stopping rules that do not reward volatility

    There is no defensible universal test duration. Conversion volume, sales delay, demand patterns, budget, and delivery behavior differ too much. A single week is especially weak evidence when automated bidding is still finding where to allocate spend and a short-lived auction opportunity can dominate the result.

    Before launch, schedule review points and define what must be true before a decision is allowed:

    • Tracking has remained stable and reconciliation checks have passed.
    • The test has covered the demand patterns relevant to the business rather than one unusual day or promotion.
    • The primary outcome has accumulated enough evidence for the size and consequence of the decision. If it has not, report the result as inconclusive instead of promoting a secondary metric.
    • Recent conversions have had enough time to mature through the normal reporting or sales delay.
    • No material budget, bid, targeting, site, inventory, pricing, or promotional change has compromised the comparison.
    • The result persists beyond an isolated performance spike.

    Maintain a change log while the experiment runs. Record the date, affected arm, change, reason, and likely direction of impact. This gives you a defensible explanation when a stakeholder asks why the test was extended or why a period was treated cautiously.

    Interpret and report results without manufacturing certainty

    Read the result in three passes: validity, business outcome, and context. Reversing that order encourages a common mistake: finding an attractive number first and looking for a story that supports it.

    Pass one: decide whether the comparison is trustworthy

    Check tracking health, conversion delay, exposure, budget constraints, and the change log. Look for promotions, outages, inventory shifts, or other conditions that affected only part of the test. If validity is compromised, do not rescue the result with a longer explanation. Mark the experiment inconclusive and state what must change before it can answer the question.

    Pass two: evaluate the business outcome before diagnostics

    Lead with the primary outcome named in the measurement contract. Show its raw count, rate, cost, and value where available. Then show downstream quality and the guardrails. CTR, CPC, impression volume, and engagement can help explain movement, but they do not replace the outcome the business funded.

    A universal CTR benchmark does not establish account health in an environment where algorithms can find audiences that are easier to click. A higher CPC is not automatically deterioration either; more expensive traffic can produce a lower acquisition cost when it carries stronger intent. Judge diagnostic metrics by their relationship to the agreed business result.

    Pass three: inspect context without rewriting the hypothesis

    Break the result down by audience, device, timing, query or theme, and creative proposition when the available reporting supports it. Treat those intersections as explanations and future hypotheses, not automatic proof that a small subgroup should become the new account strategy.

    A sudden device or weekday gain may mean the bidding system found a temporary pocket of efficient inventory, not that user preferences permanently changed. Competitor absence, auction prices, and budget allocation can all affect where delivery lands. Performance volatility should not be mistaken for a durable testing conclusion.

    Unexpected audience segments are useful for discovery. If a segment over-indexes, translate the observation into a customer hypothesis, develop creative that speaks to the implied need, and test it deliberately. Do not immediately narrow targeting around a segment that the system may have reached under a specific, temporary set of auction conditions.

    Use decision language that matches the evidence

    • Adopt: The primary outcome supports the change, tracking is valid, and guardrails remain acceptable.
    • Reject: The change harms the business outcome or violates a guardrail without a credible compensating benefit.
    • Iterate: The aggregate result is insufficient, but a clear mechanism or contextual signal justifies a narrower follow-up test.
    • Extend: The setup remains valid, but conversion maturity or evidence volume is not yet adequate for the planned decision.
    • Inconclusive: The experiment cannot answer the original question because of weak evidence, contamination, or measurement failure.

    Inconclusive is an honest result, not a failed presentation. It prevents a weak test from turning into an expensive account-wide change.

    Give stakeholders the whole denominator

    Show raw numbers and percentages together. Counts explain scale; percentages explain composition; rates explain efficiency; value and downstream quality explain business consequence. Choosing only the representation that looks favorable changes the story, even when every displayed number is technically correct.

    A useful test report can fit into seven blocks:

    1. Decision: Adopt, reject, iterate, extend, or mark inconclusive.
    2. Question: The original hypothesis and business action under consideration.
    3. Validity: Tracking status, material account changes, conversion maturity, and known limitations.
    4. Primary result: Raw outcomes, rate, cost, and value for each arm.
    5. Composition and quality: Conversion types, their shares, and downstream qualification or sales data.
    6. Context: Audience, device, timing, and creative patterns that may explain the aggregate result.
    7. Next action: The owner, exact change, and next measurement point.

    Keep observations separate from interpretations. Then label interpretations by confidence. That small discipline makes it much harder for a temporary spike, flattering denominator, or secondary conversion to masquerade as a business win.

    Match the measurement method and budget to the decision

    Not every question belongs in the same experiment. Choose the method based on the decision and the outcome you can credibly observe.

    Decision questionUseful approachDo not call this success
    Did a change improve purchase or lead economics?Use the deepest reliable conversion outcome, reconcile it with business records, and evaluate cost, value, and quality.More interactions or a larger blended conversion total when sales quality did not improve.
    Which creative direction deserves more investment?Pre-screen assets with MOCA, test distinct propositions, and inspect conditional audience and placement patterns.A global asset label or click-through rate viewed without business outcomes and context.
    Did broad delivery reveal a new audience opportunity?Treat the segment as discovery, write a customer-need hypothesis, and run a focused follow-up with relevant creative.A temporary over-index as permanent proof that the segment should be isolated or scaled.
    Did an upper-funnel campaign change brand perception?Use a Brand Lift option when the campaign has sufficient scale and the detectable difference would change a real budget decision.Clicks or attributed conversions as a complete measure of awareness or consideration.

    Pay for greater Brand Lift sensitivity only when it matters

    Google Ads offers Standard and Enhanced Brand Lift options. Google’s reported product specifications position Standard Brand Lift to measure lifts of 2% or more, while Enhanced Brand Lift can detect lifts as low as 1.2%. The enhanced option requires approximately three times the budget, and Google estimates that it raises the likelihood of detecting a positive lift by 60%.

    Those figures describe vendor-reported study sensitivity and budget requirements, not a guarantee that your campaign will create lift. The practical question is whether distinguishing a modest effect from no detectable effect would change your decision. If a result between 1.2% and 2% would not affect investment, the additional sensitivity may not justify roughly tripling the required budget. If that distinction would determine a substantial upper-funnel allocation, the enhanced option can be relevant when the campaign has enough scale.

    For your next experiment, write the measurement contract and the empty seven-block report before building the campaign. Validate one complete conversion path, record the stopping rules, and reject creative that fails the preflight screen. Once the test begins, your job is to protect that decision structure from mid-test improvisation. The result may be adopt, iterate, or inconclusive; any of those is useful when it is tied to a clear next action.

    References

  • Performance Max Placement Controls Enter an Early Alpha

    Performance Max Placement Controls Enter an Early Alpha

    A limited Performance Max alpha could give selected advertisers a consequential new choice: whether a campaign includes Search Partners and the Google Display Network. The reported setting does not dismantle campaign automation, but it may let advertisers define two important boundaries around the inventory that automation can use.

    The distinction matters for both expectations and testing. This is a reported network-level control, not evidence of comprehensive placement management, and its value will depend on whether advertisers can measure the effects of each configuration reliably.

    Key takeaways

    • CrushPress.AI reported that a Partners (Alpha) setting is appearing in some Performance Max campaigns.
    • The reported interface provides separate inclusion choices for Search Partners and the Google Display Network.
    • Because the setting is labelled Alpha and has limited availability, it should be treated as an experiment rather than an established campaign feature.
    • The most useful evaluation is a controlled comparison based on business outcomes such as cost per acquisition or return on ad spend.
    • The reported controls apply to networks; they should not be interpreted as proof of granular control over individual websites, apps, searches or placements.

    The alpha changes the boundary of automation

    According to CrushPress.AI’s report, advertisers with access can use checkboxes to include or exclude Search Partners and the Google Display Network. The publication said both networks had previously been included automatically in Performance Max without a corresponding exclusion option.

    That makes the test notable without making Performance Max a manually managed campaign type. Google would still automate decisions within the inventory available to the campaign; the advertiser would gain a higher-level choice about whether two sources of inventory are available at all. In practical terms, the control changes the perimeter in which the system operates rather than replacing automated delivery.

    The terminology also deserves care. Although network selection affects where ads may appear, the reported setting is broader than a conventional placement exclusion. It does not, based on the available report, establish controls for selecting particular sites, apps, pages or search contexts.

    Why network choice could improve campaign diagnosis

    An analyst compares two separated streams of generic advertising inventory connected to one automated campaign engine.

    When several inventory sources contribute to one automated campaign, an aggregate result can show whether the campaign succeeded without fully explaining which environments helped or hurt. An option to remove Search Partners or the Google Display Network creates a clearer diagnostic question: does the campaign produce stronger business results when either network is unavailable?

    That question should be framed around the campaign’s actual objective. CrushPress.AI identified return on ad spend and cost per acquisition as relevant measures for evaluating the setting. Advertisers may also need to examine whether changes in those outcomes accompany changes in conversion volume, reach or delivery stability. A lower cost per acquisition is less useful if the configuration can no longer produce the required volume, while additional reach is not automatically valuable if it fails to support the campaign goal.

    The setting may also help separate an inventory concern from a broader campaign problem. If excluding a network does not materially improve the chosen outcome, attention may be better directed toward inputs such as creative, offers, audience signals, conversion measurement or landing-page experience. If performance changes consistently, the result supplies a more focused basis for deciding which inventory belongs in the campaign.

    A useful test requires more than toggling a checkbox

    Two matched campaign pathways use different switch settings in a controlled side-by-side testing setup.

    A credible comparison begins with a decision rule established before the configuration changes. The advertiser should specify the primary business metric, the acceptable trade-off between efficiency and volume, and the conditions that would justify retaining or reversing the exclusion. This reduces the risk of choosing whichever metric looks most favorable afterward.

    The comparison should also avoid unnecessary simultaneous changes. Major adjustments to budgets, conversion definitions, creative assets or landing pages can make it difficult to attribute a result to network selection. Normal volatility and automated learning further argue against drawing a conclusion from a brief movement in performance.

    Interpretation should account for interaction effects. Excluding inventory can change the opportunities available to the campaign, which may alter how automation distributes delivery elsewhere. The meaningful comparison is therefore the campaign’s total outcome under each configuration, not an assumption that removed activity would have transferred unchanged to another network.

    What remains unresolved while access is limited

    The available evidence is preliminary. CrushPress.AI described the control as an Alpha available to a limited group and reported that Google had not announced whether or when it would become more broadly available. The report attributed the discovery to PPC Growth Strategist Saquib Syed, who shared the setting on LinkedIn.

    The report does not establish how eligibility is determined, whether the interface will remain unchanged, or whether Google will add related reporting and controls. Those omissions are especially important because a network toggle is most actionable when advertisers can clearly evaluate the inventory affected by it.

    The next meaningful signal will be broader availability accompanied by documented behavior and sufficient reporting to support sound comparisons. Until then, advertisers with access can treat the alpha as a structured learning opportunity, while those without it should avoid planning around a control that has not been confirmed as a general release.

    References

  • A Framework for Technical SEO Risk, ROI and Indexing

    A Framework for Technical SEO Risk, ROI and Indexing

    Technical SEO decisions become difficult when the highest-impact changes also create the widest failure surface. URL structures, canonical rules, robots.txt directives, internal links and migrations can improve discovery and indexing, yet an error in any of them can affect large parts of a site.

    The measurement environment is equally imperfect. Benefits may emerge only after recrawling and reindexing, avoided losses leave no clean counterfactual, and even a primary diagnostic such as Google Search Console can be delayed. A useful operating model must therefore connect three disciplines: risk-based prioritization, layered indexing diagnosis and evidence-based ROI reporting.

    Technical SEO combines implementation risk with measurement uncertainty

    The implementation challenge and the measurement challenge are closely related. The changes most likely to affect organic performance are often sitewide or template-level changes, which makes them difficult to isolate and dangerous to test carelessly.

    One Search Engine Land contributor identified URL updates, canonical changes, robots.txt edits, internal linking work and migrations as initiatives that deserve extra caution. Their common characteristic is scale: a rule or template change can alter how search engines encounter, interpret or prioritize many URLs at once. A small configuration mistake can consequently have a much larger effect than an isolated metadata edit.

    A separate Search Engine Land analysis explains why the return from this work can be hard to prove. Technical changes rarely occur in a closed system, search engines recrawl and reindex on their own schedules, and multiple teams may release changes together. Sitewide work can also remove the possibility of an untreated control group. The result is an inference problem, not merely a reporting gap.

    This distinction matters for funding. Some technical SEO work seeks measurable growth, while some maintains access, resolves technical debt or reduces the probability and cost of a future loss. A migration that preserves traffic may be successful even if its performance chart is flat. Treating every project as a short-term acquisition campaign undervalues resilience and encourages false precision.

    Prioritize changes by exposure, value and failure cost

    An audit finding is not automatically an implementation priority. Automated crawlers are effective at finding patterns, but a warning may represent a serious defect, an intentional configuration, a platform limitation or a low-value imperfection. Manual validation and business context should come before a development ticket.

    A practical prioritization decision can be organized around five questions:

    1. Is the issue real? Confirm representative examples and determine whether the observed behavior is intentional.
    2. What is exposed? Establish how many URLs, templates or sections could be affected, with extra weight given to commercially or strategically important pages.
    3. What outcome is expected? State whether the work is intended to improve discovery, consolidate signals, preserve existing visibility, reduce wasted crawling or prevent a known failure mode.
    4. What does implementation require? Account for engineering effort, platform constraints, cross-team dependencies and the testing needed before release.
    5. What happens if the change is wrong? Consider the scale of lost crawl access, unintended consolidation, broken discovery paths or migration-related visibility loss.

    This framework prevents easily counted issues from crowding out consequential work. For example, an automated report may flag metadata on low-priority pages, while a canonical rule affecting an important template could receive less attention because it requires manual investigation. The number of warnings is not a reliable measure of business impact.

    Different changes also require different controls. URL moves need explicit redirect mappings, updated internal links and refreshed XML sitemaps. Canonical changes require validation of both the emitting template and its targets. Robots.txt edits should be checked against intended URL patterns and the production environment. Navigation changes need checks for orphaned pages, removed pathways and links pointing to non-public locations. A migration needs all of these controls coordinated because it can combine several high-risk changes in one release.

    Indexing diagnosis should start by testing the evidence itself

    Hands examine layered website pages and crawl paths with a magnifying lens, revealing a broken route and conflicting signal.

    An indexing chart can look authoritative while describing an older state of the site. One source reported that the Google Search Console page indexing report was more than two weeks behind, with June 11, 2026 shown as its latest timestamp. The report normally helps distinguish indexed from non-indexed pages, presents reasons for exclusion and can overlay impressions, but delayed processing limits its value for investigating recent events.

    The first diagnostic question should therefore be whether the evidence is current enough for the period under investigation. A stale report is not proof of a new indexing loss, nor does it prove that a recent fix failed. It establishes an observation boundary: aggregate conclusions about the missing period must remain provisional.

    When aggregate reporting is delayed, diagnosis can move through a layered sequence:

    1. Record report freshness. Note the visible processing date before comparing deployments with indexed-page totals or exclusion reasons.
    2. Inspect representative URLs. Use Search Console’s URL inspection capability for important examples, recognizing that this is a page-by-page investigation rather than a fresh sitewide report.
    3. Trace the technical signal chain. Check whether the URL can be reached through intended internal links, whether redirects lead to the expected destination, and whether canonical or noindex signals point elsewhere.
    4. Review crawl controls. Compare robots.txt rules with the affected URL patterns, particularly after a deployment or migration.
    5. Check discovery sources. Confirm that internal links and XML sitemaps contain the intended current URLs rather than old, redirected or non-public versions.
    6. Segment the pattern. Determine whether examples share a template, directory, parameter pattern or release. A common boundary can identify a systemic cause without treating every exclusion as the same problem.
    7. Separate visibility from index status. Use impressions and other available performance evidence as supporting context, not as a substitute for current indexing data.

    This sequence connects the indexing report’s categories with the implementation risks highlighted in the rollout guidance. Duplication, redirects, canonical choices, crawl restrictions and internal discovery are not independent dashboard labels; they are interacting signals. Conflicts between them can produce a symptom that looks like a single indexing problem even when the cause sits in a template or release process.

    Deployment controls create better evidence as well as safer releases

    Website components pass through staged safety gates while a defective module is diverted before reaching the production network.

    Testing is not only a safeguard. It also improves attribution by documenting what changed, where it changed and what successful behavior should look like. Without that record, a later movement in crawling, indexing or visibility is difficult to connect to a release.

    Before launch, teams should define the affected templates and priority sections, preserve a set of representative URLs, specify expected signals and agree on rollback criteria. Redirect mappings, canonical destinations, robots.txt patterns, internal links and sitemap entries should be validated in an appropriate test environment when the platform permits it. Early alignment with developers, content teams, product owners and other stakeholders is especially important when a change spans systems.

    After launch, the same examples should be checked again in production. Redirect destinations, canonical outputs, crawl directives, internal links and sitemap contents should match the approved plan. Monitoring should distinguish release timing from Search Console’s data timestamp so that reporting latency is not mistaken for implementation failure.

    Measurement can then be matched to the type of return:

    • Enhancement: evidence that a targeted change improved discovery, indexing or search visibility in the intended segment.
    • Maintenance: evidence that known technical defects or inefficient processes were removed and the expected technical state was restored.
    • Resilience: evidence that important pages retained access, signals and visibility through a migration, platform change or external search disruption.

    Where segmentation is feasible, the ROI source recommends a proof of concept resembling an SEO A/B test: apply a change to one segment, leave a comparable segment untreated and evaluate the relative result before expanding it. Sitewide infrastructure work may make that impossible. In those cases, relative trends, competitor movement around shared external events and longer-term performance can support an inference, but they should be labeled as proxies rather than causal proof.

    Funding discussions become more credible when the claim matches the evidence. Growth work can be evaluated against an expected improvement, while maintenance and resilience work can be framed in the language used for infrastructure, security and insurance: exposure, likelihood, consequence and cost of control. Scenario assumptions should remain visible instead of being converted into a single guaranteed revenue figure.

    Key takeaways

    • Audit counts do not determine priority; validate the issue, affected scope, business importance, effort and failure cost.
    • URL, canonical, robots.txt, internal linking and migration changes require controls proportionate to their sitewide exposure.
    • Check the processing date before using Search Console’s page indexing report to judge a recent release or indexing event.
    • When aggregate data is stale, inspect representative URLs and trace redirects, canonical signals, crawl controls, discovery paths and sitemap entries.
    • Report technical SEO as a mix of enhancement, maintenance and resilience, using experiments where possible and clearly labeled proxies where they are not.

    As search behavior and site platforms continue to change, technical SEO programs will need stronger release records and more explicit uncertainty, not more confident-looking dashboards. Teams that connect engineering controls with indexing evidence and financial framing will be better equipped to pursue meaningful gains without hiding the risk required to achieve them.

    References

  • How AI Advertising Changes Measurement and Experimentation

    How AI Advertising Changes Measurement and Experimentation

    AI-driven advertising is making campaign delivery more adaptive while making performance harder to interpret. When platforms choose audiences, placements and combinations of creative, a conversion report can show what happened without revealing whether automation created additional demand, captured demand that already existed or simply shifted credit between channels.

    The useful response is not another all-purpose attribution metric. Advertisers need a layered measurement system that combines behavioral signals, downstream outcomes, controlled experiments and creative-quality checks. The source reports collectively show platforms moving in that direction, although each covers a different part of the problem.

    AI shifts the question from attribution to evidence

    Traditional attribution asks which interaction receives credit for a result. AI-driven campaigns create a broader question: what evidence shows that the campaign changed customer behavior? That distinction matters because an automated system may optimize successfully against its assigned conversion signal while producing little incremental value for the wider business.

    The reported expansion of YouTube measurement illustrates the shift. CrushPress.AI’s article on YouTube measurement said Google added Shorts Ad Actions to the budget optimization and reporting available for eligible Video View Campaigns. It also reported the global availability of Attributed Branded Searches, a Google Ads metric intended to identify branded Google searches following exposure to or a view of a YouTube ad.

    Those signals occupy different positions in the customer journey. A Shorts interaction describes behavior around the ad itself, while a subsequent branded search suggests that exposure may have influenced active interest. Neither is equivalent to a sale, but together they can provide a more informative path from attention to intent.

    The article relayed Google’s claim that Shorts ads associated with more than 10 seconds of watch time and a like delivered 15% higher brand consideration and 20% higher brand favourability. It also relayed Google’s statement that each additional branded search generated was associated, on average, with a $31 sales increase. These are reported platform findings and associations, not universal forecasts or proof that every additional search causes the stated sales gain.

    Signals form a measurement ladder, not a single score

    Four connected translucent platforms rise from behavioral signals to outcomes, a controlled test apparatus, and a verified decision beacon.

    AI advertising environments increasingly expose early indicators that are useful before a direct conversion occurs. The appropriate interpretation depends on how close each signal sits to the desired business outcome.

    Interaction signals diagnose relevance

    Ad dismissal is one example. CrushPress.AI’s report on ChatGPT advertising said OpenAI reported a 50% decline in dismissals after launching its advertising business and presented that change as evidence of improving relevance. A lower dismissal rate may indicate that ads feel less intrusive or more useful in a conversational setting, but it does not by itself establish incremental sales, profit or retention.

    This makes dismissal a diagnostic metric rather than a final business verdict. It can help determine whether an ad fits the user’s task and context. The same principle applies to watch time, likes and other engagement actions: they can reveal whether the experience is resonating, while stronger evidence is still required to justify budget.

    Intent and cross-channel outcomes strengthen the case

    Branded search can bridge the gap between engagement and conversion because people do not always respond through the channel that introduced them to a brand. The paid-social measurement article described a common pattern in which social advertising creates awareness and paid search later captures the visit or conversion. It recommended examining branded search activity, search click-through rate, conversion rate, lead quality, cost per acquisition and revenue-related outcomes before, during and after meaningful social changes.

    These comparisons are directional because public relations, email, influencers, product launches, seasonality and organic activity can also affect search behavior. Their value is in identifying a plausible relationship that deserves stronger testing. When branded search, search engagement and conversion efficiency move together after a campaign change, the combined pattern is more informative than any one metric viewed alone.

    Experiments are becoming the control plane for automation

    Two matched campaign environments run in parallel with one controlled variation, and their results feed back into an automation engine.

    Controlled experiments address the central weakness of observational reporting: the absence of a credible counterfactual. Instead of asking only how an AI campaign performed, an experiment asks what would likely have happened without the campaign or without the proposed change.

    Microsoft’s reported Performance Max experiment expansion separates two useful decisions. Uplift experiments compare Performance Max activity with a control group to assess incremental impact. Upgrade experiments compare an existing campaign with an upgraded Performance Max version before a broader rollout. The first tests whether the automated campaign adds value; the second tests whether changing the operating model improves results.

    Google’s Ads API v24.2 adds another level of experimental granularity. According to the source article, its COMPARE_CAMPAIGNS workflow can compare multiple campaigns or campaign types across as many as five experiment arms, including custom Performance Max experiments. A separate experiment can divide traffic within one Performance Max campaign to test text customization and final URL expansion.

    Together, these options point to three distinct testing jobs. Incrementality tests evaluate whether advertising creates additional outcomes. Upgrade tests evaluate whether a new automated campaign structure outperforms the current approach. Component tests isolate a feature or configuration inside the system. Treating these as separate questions prevents a successful feature test from being mistaken for proof that the entire campaign is incremental.

    Where platform-native experiments are unavailable, the cross-channel measurement article proposed geotargeted holdouts: paid social runs in selected test markets and is withheld from comparable control markets, with search and business outcomes compared across the groups. It also noted that this approach generally requires suitable markets, sufficient budget and enough time, while smaller advertisers may need to begin with carefully controlled pre- and post-campaign analysis.

    Creative and delivery must be measured as one system

    Automation changes what creative does. In broad-targeting systems such as Performance Max, Advantage+ and TikTok’s automated expansion, the creative does more than persuade a predefined audience. Its language, visuals, opening hook and call to action help people self-select and generate behavioral signals that influence future delivery.

    The source on creative qualification argued that specificity is therefore a performance control. A message that clearly states the relevant need, prerequisite or use case can discourage unqualified engagement while attracting people for whom the offer is appropriate. That can improve lead quality and reduce the noisy conversion data fed back into an automated system. A generic message may achieve inexpensive engagement while teaching the system to find more of the wrong response.

    Measurement should consequently connect asset-level engagement with qualified outcomes. High watch time or click-through rate is encouraging only when the same creative also contributes to appropriate leads, sales or other defined business results. Creative tests should preserve the qualifying elements that identify the intended customer, rather than optimizing hooks in isolation.

    Placement visibility is part of the same diagnosis. The Google Ads API v24.2 article reported that Performance Max placement views can be segmented by ad_network_type, providing more visibility into where performance occurs across Search, Display and partner networks. That does not remove every limitation of automated delivery, but it can help teams determine whether an apparent creative result is actually concentrated in a particular network or context.

    Build decisions around an evidence hierarchy

    A practical operating model begins by assigning each metric a job. Interaction metrics diagnose relevance, branded search and cross-channel efficiency indicate possible demand creation, and holdouts or platform experiments provide the strongest available evidence of incrementality. Business outcomes remain the decision target against which the other layers are judged.

    Key takeaways

    • Define the business outcome before choosing the platform optimization signal; the two should be connected but should not be treated as interchangeable.
    • Use dismissals, watch time, likes and clicks to diagnose relevance, not as stand-alone proof of commercial value.
    • Monitor branded search and paid-search efficiency to detect demand that an upper-funnel or social campaign may have created elsewhere.
    • Match the experiment to the decision: uplift for incrementality, upgrade tests for campaign migration and component tests for individual automation features.
    • Evaluate creative as both a persuasion mechanism and an audience qualifier, with lead quality or customer value checked alongside engagement.
    • Document delivery context, placement mix and AI-generated asset status so that experiment results remain interpretable and governable.

    The final point extends beyond performance reporting. The Google Ads API article also reported new fields for synthetic-content information and attestation. Such disclosures do not measure effectiveness, but they become important experiment metadata: teams need to know which assets were AI-generated, which controls were active and what changed between variants if they want results that can be audited and repeated.

    As automated platforms assume more control over delivery, measurement will need to become more deliberate rather than more passive. The teams best positioned for the next generation of ad products will be those that can connect useful early signals to cross-channel behavior, then challenge the apparent result with a credible control.

    References

  • SEO Expertise in the AI Era: From Output to Prioritization

    SEO Expertise in the AI Era: From Output to Prioritization

    AI is making many familiar SEO outputs faster and cheaper to produce, but it is not making the underlying decisions easier. The emerging premium is on expertise that can distinguish plausible advice from worthwhile action, connect search work to business outcomes, and carry priorities through implementation.

    Across technical SEO, content, and AI visibility, the practical question is therefore no longer how many recommendations a team can generate. It is which intervention deserves scarce time, what evidence supports it, and how success should be measured.

    Recommendation volume is becoming a weak proxy for expertise

    The career analysis in Search Engine Land argues that AI is changing the value of SEO skills more than it is directly targeting the profession. Audits, briefs, keyword work, and optimization suggestions remain useful, but AI can produce versions of them quickly. If recommendations become inexpensive, a long report is less persuasive evidence of expertise than the judgment used to select, sequence, and implement its best ideas.

    The same pressure is visible in content. Search Engine Land’s article on firsthand experience describes a web crowded with interchangeable advice and says AI has made generic production still easier. Its proposed differentiators are concrete examples, test results, candid opinions, client outcomes, and lessons from failed work. That is the content equivalent of the career shift: readily generated output loses relative value, while evidence rooted in actual decisions and consequences gains it.

    Together, these accounts suggest a more demanding definition of SEO expertise. Knowledge remains the foundation, but the differentiating layer is the ability to challenge an answer, identify the assumptions behind it, and convert a recommendation into an outcome. AI can accelerate analysis and drafting without deciding which organizational constraint, commercial objective, or uncertain premise matters most.

    Prioritization should operate as a portfolio discipline

    A hand allocates a limited number of glowing tokens among abstract website, content, audience, and AI-system models on a circular table.

    A backlog cannot be prioritized credibly when every item is labeled urgent. Search Engine Land’s forecasting framework contrasts a minor schema issue with a title-tag problem affecting thousands of pages to show why technical seriousness and business impact are not necessarily the same. It recommends estimating likely traffic impact before work begins, while acknowledging that traffic is not the only objective when brand visibility or user experience is at stake.

    Estimate the opportunity that is actually exposed

    The first distinction is scope: a sitewide change, a template-level repair, and a single-page optimization create different opportunity sizes. The forecasting source recommends filtering affected URLs in Google Search Console and examining current clicks, impressions, ranking positions, and the surrounding search-result features. It identifies pages ranking from positions 8 through 15 as potential near wins, but also warns that an improvement can produce very different click gains depending on the result layout and the presence of AI experiences.

    Replace a precise promise with explicit scenarios

    Potential lift can then be grounded in outcomes from similar past changes, competitor and search-result analysis, and assumptions appropriate to AI-influenced click behavior. Rather than presenting one apparently certain number, the source recommends conservative, expected, and aggressive scenarios. That approach makes uncertainty visible: partial implementation and competitive responses can be represented separately from stronger execution and faster indexing.

    Compare expected value with delivery cost

    The forecast becomes useful only when it changes the roadmap. Comparing the expected effect with effort through a framework such as RICE can expose large, scalable opportunities that would otherwise lose attention to smaller and more appealing technical tasks. For initiatives whose primary outcome is not traffic, the same discipline still applies: define the intended result, select an observable measure, state the uncertainty, and compare the opportunity cost with competing work.

    Evidence must cover both execution and search context

    The sources point to two complementary forms of evidence. Internal evidence comes from implementation: previous fixes, controlled tests, client work, failures, and observed results. External evidence comes from the environment in which a brand or page must compete: result layouts, competitors, third-party coverage, and the associations AI systems appear to use.

    This distinction helps explain why AI fluency alone is insufficient. The career article recommends evaluating how an SEO handled a disagreement, responded to a failed test, or caught an AI mistake. Those questions test whether the candidate can reason under uncertainty and continue after an initial plan breaks down. The content article makes a parallel case for publishing details that could come only from real practice rather than another summary of established advice.

    A useful workflow therefore treats AI output as a hypothesis generator. An audit suggestion, content angle, or visibility diagnosis should be checked against the site’s data, the actual search environment, and relevant operational experience. When evidence is incomplete, the appropriate response is a bounded test or a qualified forecast, not greater confidence in the wording of the recommendation.

    AI visibility requires separating recognition from recommendation

    A network of web sources passes through two transparent filtering chambers before a small selection reaches a human silhouette.

    Prioritization becomes more complicated when the objective extends beyond conventional rankings and clicks. A Search Engine Land study conducted through Friction AI examined 12 activewear brands across more than 14,000 API tests. The researchers reported that strong Knowledge Graph recognition did not consistently translate into recommendations for related prompts, describing the difference as a framing gap.

    The study’s co-mention analysis suggests why those outcomes may diverge. It found that brands could become associated with particular competitors and category leaders through the contexts in which they appeared together. Nike, for example, was reported to appear prominently in recommendation prompts despite sharing a broad company description with other footwear brands; the researchers connected that result to its recurring association with category leaders.

    This was an exploratory study in the UK athleisure sector, and its authors said additional categories and regions would need examination. It should not be treated as a universal ranking formula. It does, however, identify an important planning distinction: improving the clarity of a brand’s own pages may support recognition, while earning relevant third-party coverage and category associations may support recommendation. Those are related objectives, but they call for different actions and should not be collapsed into a single visibility score.

    The distinction also changes content strategy. Firsthand case studies and specific results can make owned content more credible, as the experience-focused source argues. Yet the co-mention research indicates that a brand’s self-description is only part of its AI-visible context. A mature plan must consider both what the brand demonstrates directly and how independent sources position it within the market.

    Key takeaways

    • Judge SEO work by the quality of decisions and delivered outcomes, not the number of recommendations produced.
    • Estimate scope, exposed traffic, potential lift, uncertainty, and implementation effort before assigning roadmap priority.
    • Use AI to accelerate hypotheses and production, then validate its output against data, search context, and firsthand experience.
    • Preserve real examples, failed tests, observed results, and informed opinions because generic information is increasingly easy to reproduce.
    • Measure brand recognition and AI recommendation separately; owned-page clarity and third-party category associations may require different investments.

    As AI lowers the cost of producing SEO artifacts, teams will need clearer decision records, stronger testing habits, and measures tied to the outcome each initiative is meant to change. The durable advantage will belong to practitioners who can make uncertainty legible and direct limited resources toward work that survives contact with real users, search systems, and organizational constraints.

    References