Category: Technical optimization

  • How to Build Reliable SEO Agents That Verify Their Work

    How to Build Reliable SEO Agents That Verify Their Work

    You ask an SEO agent to audit a site, and minutes later it returns a polished list of problems. The real question is not whether the report sounds expert. It is whether every claim came from a page the agent retrieved, evidence it preserved, and a rule it can explain.

    If you cannot trace a finding from recommendation back to observation, you do not have a reliable SEO agent yet. You have a text generator with access to SEO vocabulary. The way forward is to build a small inspection system around the model: tools to collect facts, rules to classify them, tests to expose failure, memory to preserve lessons, and a deployment gate that blocks unsupported conclusions.

    Reliability begins with an evidence contract, not a longer prompt

    A role prompt can tell a model to act like an SEO expert. It cannot prove that the model fetched a URL, received the expected response, inspected the relevant HTML, or distinguished a real defect from an intentional configuration.

    This distinction matters because confident language can hide incomplete inspection. In one documented build, an agent returned 20 findings, eight of which described problems that did not exist. It had not actually visited many of the URLs behind those claims. Better wording would not have corrected that failure. The agent needed tools, evidence requirements, and a way to reject its own unverified findings.

    Before choosing a model or writing detailed instructions, define an evidence contract. It should answer five questions:

    • What may the agent inspect? Name the permitted inputs, such as XML sitemaps, robots.txt, HTTP responses, raw HTML, rendered page output, and crawl data.
    • What counts as proof? Require the requested URL, final URL, retrieval result, inspected representation, observed value, and applicable rule for every finding.
    • What can the agent conclude? Limit conclusions to issue types supported by its tools and reference criteria.
    • What happens when evidence is unavailable? Require an explicit unknown or unverified state instead of allowing the agent to guess.
    • What must appear in the deliverable? Define the fields, evidence excerpts, coverage totals, confidence state, and recommendation format before the run begins.

    Suppose the agent wants to report a missing canonical element. It must first show that the page was fetched successfully and that it inspected the intended representation. A redirect, authentication screen, bot challenge, blocked request, empty response, or tool failure does not prove that the canonical is missing. It proves that the check was not completed.

    The same discipline applies to indexability. Finding a noindex directive is an observation. Declaring it an SEO problem is a classification that depends on the page’s intended role. If the agent does not have that context, it should report the directive and request confirmation rather than inventing intent.

    Make the agent separate each result into three layers:

    • Observation: what the tool found, including the URL, response, element, value, and retrieval method.
    • Classification: the rule that turns the observation into confirmed issue, acceptable state, rejected candidate, or unknown.
    • Recommendation: the action justified by that classification, with any required human decision stated plainly.

    This separation makes review faster. A human can challenge the rule without disputing the collected fact, or rerun the collection step without rewriting the recommendation. It also prevents a plausible recommendation from disguising a weak observation.

    Give every SEO agent a workspace it can operate from
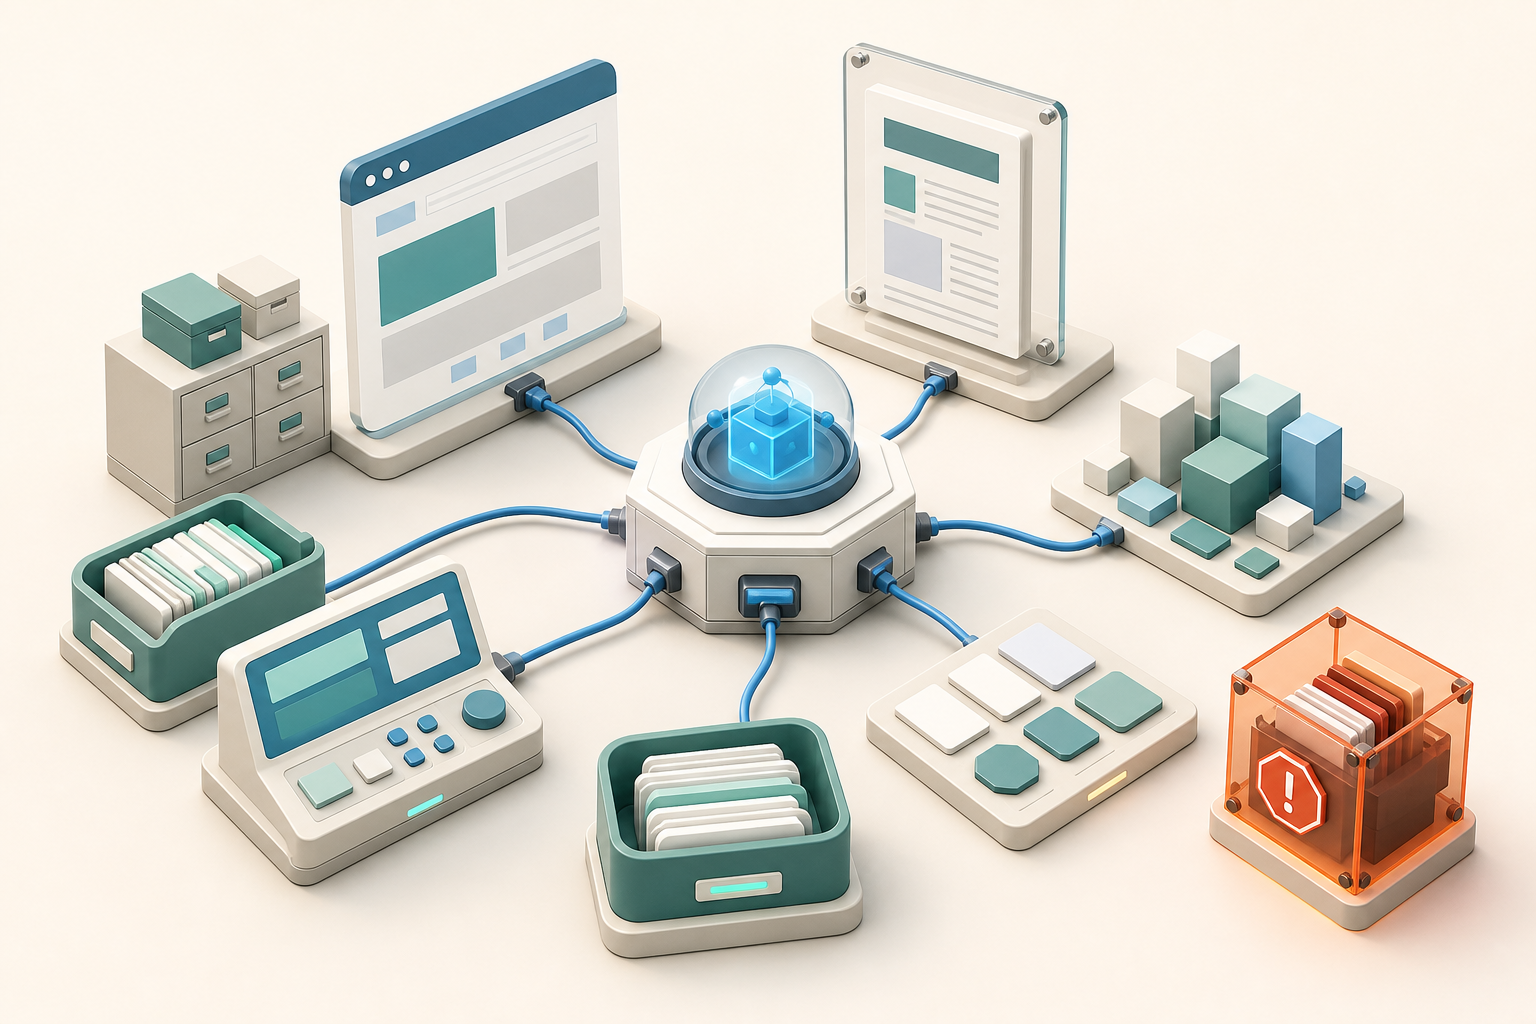
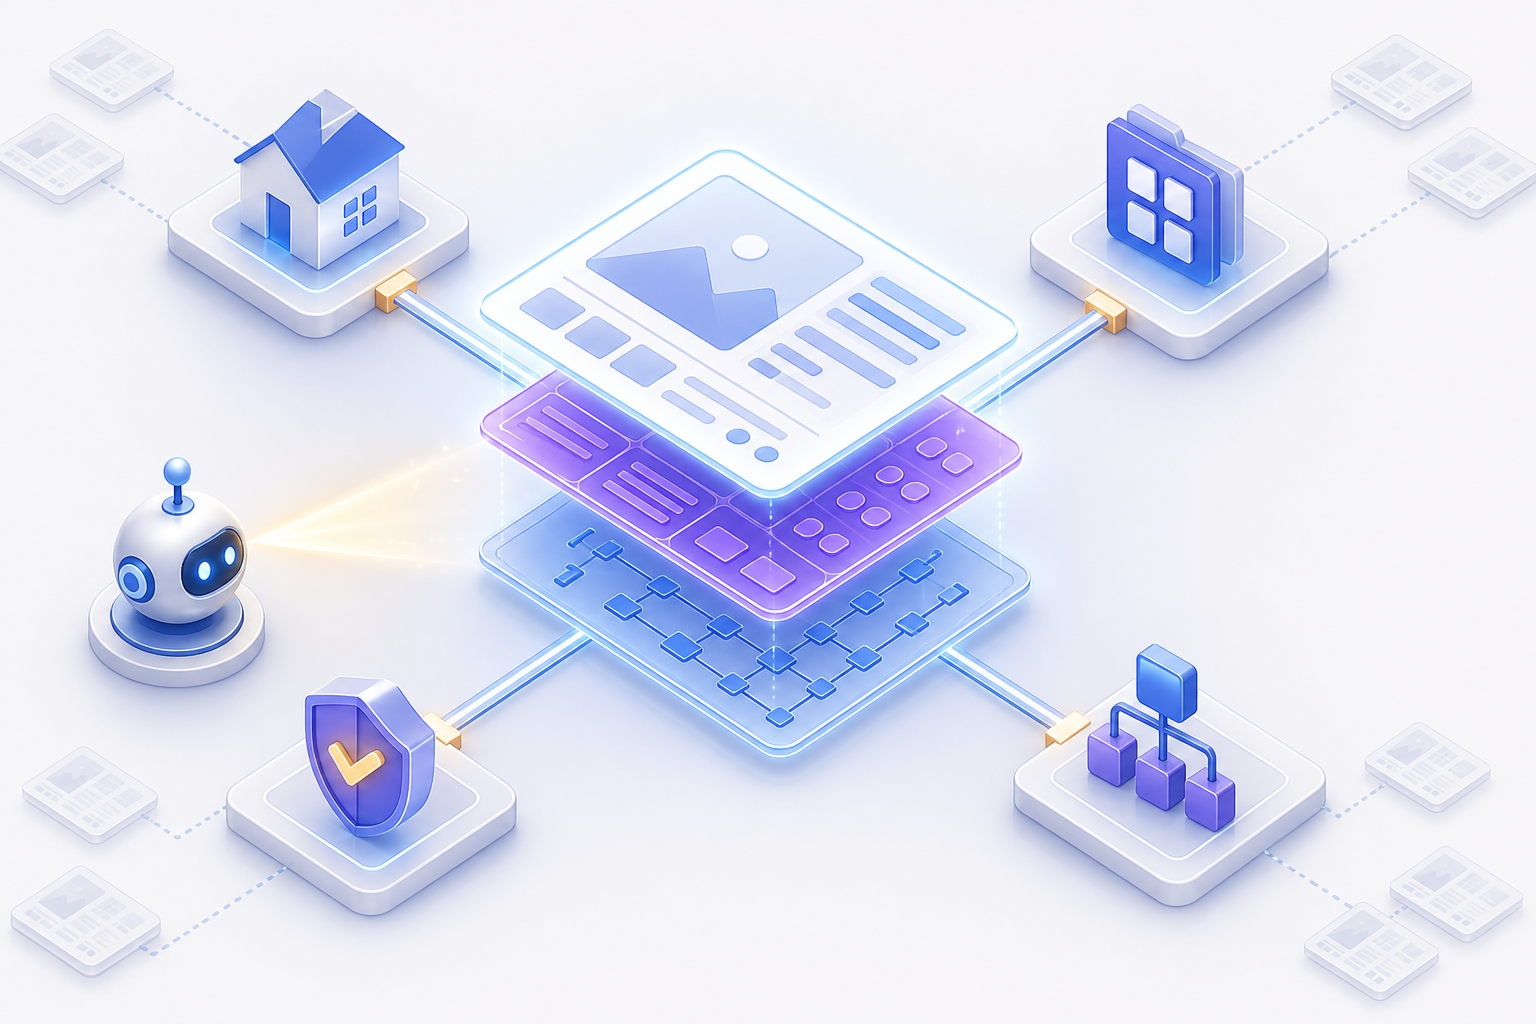
    An isometric workspace connects a central robotic agent to abstract page snapshots, structured records, rules, tests, an archive, and an error tray.

    A standalone prompt has nowhere to put operating procedures, executable tools, false-positive rules, previous failures, and output contracts. A dedicated workspace gives each of those concerns a stable home.

    Workspace componentWhat belongs thereReliability job
    AGENTS.mdOrdered methodology, allowed tools, stop conditions, escalation rules, and required outputKeeps the agent on the same operating procedure across runs
    SOUL.mdJudgment principles, skepticism rules, quality bar, and communication standardsDefines how the agent behaves when instructions do not cover an edge case
    scripts/Reusable crawlers, sitemap parsers, extractors, validators, and renderersCollects facts through repeatable operations instead of improvised commands
    references/Issue criteria, severity definitions, exceptions, and known false positivesSeparates real problems from noise
    memory/Run manifests, failure logs, rule changes, and regression historyPreserves lessons and exposes changes between executions
    templates/Finding records, summaries, evidence fields, and final report structurePrevents important fields from disappearing when prose varies

    The filenames are less important than the boundaries. Instructions should explain the workflow. Scripts should perform deterministic collection and validation where possible. References should define judgment. Memory should record what happened. Templates should constrain what can be published.

    Write AGENTS.md as an operating procedure, not a persona paragraph. An instruction such as “check the sitemap” leaves too much unspecified. A useful procedure tells the agent to look for sitemap declarations in robots.txt, try expected locations such as /sitemap.xml and /sitemap_index.xml, parse discovered sitemap indexes, record failed retrievals, and switch to an approved discovery method when no sitemap can be found.

    Give scripts equally clear contracts. A crawler should return structured records rather than a narrative. At minimum, each record should distinguish the requested URL from the final URL, record whether retrieval succeeded, preserve the response status, identify the collection method, and expose tool errors as data. The agent can explain those records later, but it should not have to reconstruct them from terminal prose.

    References need operational definitions. Do not write “flag bad canonicals.” Define the observable condition, the exceptions that suppress it, the evidence required for confirmation, and the severity rule. Put recurring traps in a separate gotchas file so they remain visible: intentional noindex pages, redirected URLs, blocked resources, duplicate URLs that resolve to one destination, and pages whose useful output requires rendering are examples of cases your test environment may need to cover.

    The output template should make unsupported findings difficult to express. Give every finding mandatory fields for evidence, rule ID, verification state, and affected URL. Reserve a visible section for unknowns and crawl failures. If the template offers only “issue” and “no issue,” the agent will be pushed toward false certainty whenever collection fails.

    Turn the audit into a collection and verification pipeline

    A reliable SEO audit is not one model call. It is a pipeline in which each stage produces an inspectable artifact for the next stage. The following sequence gives you a practical starting point.

    1. Create a run manifest. Record the target host, allowed scope, enabled checks, agent version, rule version, script versions, and any crawl constraints. This lets you explain why two runs differ.
    2. Discover the URL set. Start with declared sitemaps. Check robots.txt for references, then expected routes such as /sitemap.xml and /sitemap_index.xml. If none are available, use the approved crawl or supplied URL inventory and record that fallback.
    3. Collect responses without interpreting them. Apply configured rate limits, follow the approved redirect policy, and store requested URL, final URL, response result, and retrieval failure. A collection error belongs in the data, not in a discarded console message.
    4. Capture the representation required by each check. Preserve raw HTML for server responses. Use rendering when the initial response does not contain the elements a supported check needs. Label the representation so reviewers know what was inspected.
    5. Generate candidate observations. Extract canonical elements, robots directives, status behavior, titles, descriptions, links, or other in-scope signals without calling them defects yet.
    6. Verify every candidate. Recheck the relevant page and element through the appropriate tool. Reject stale, contradictory, duplicated, or unsupported candidates. If verification cannot finish, change the state to unknown.
    7. Classify against explicit criteria. Apply the relevant rule and its exceptions. Preserve the rule identifier and reason so a reviewer can reproduce the decision.
    8. Build the report from verified records. Let the model prioritize and explain confirmed findings, but do not let it introduce new URLs, counts, or diagnoses that are absent from the records.

    The pipeline should retain rejected candidates as internal run data. They tell you where the agent almost produced a false positive. If a rule repeatedly rejects the same pattern, you may be able to move that exception earlier in the workflow and save verification work.

    Coverage also needs to be explicit. Report separate totals for URLs discovered, retrievals attempted, pages fetched, pages inspected for each enabled check, and pages left unknown. “Crawled 500 URLs” is not useful if only part of that set reached the check that produced the recommendation. The denominator for a claim must be the set actually inspected for that claim.

    Do not collapse access failure into site failure. A CDN response, rate limit, robots restriction, timeout, or rendering error can stop the agent from observing the page. None of those outcomes proves that the suspected on-page issue exists. After the configured retry and fallback paths are exhausted, publish the limitation as a limitation.

    A compact finding record can carry the chain of evidence:

    • Run ID and rule version
    • Requested URL and final URL
    • Retrieval state and inspection method
    • Observed element or response value
    • Rule ID and applied exception
    • Verification state: confirmed, rejected, or unknown
    • Recommended action and any decision that still needs a person

    Once those fields exist, the model’s job becomes narrower and safer. It can group related findings, explain likely consequences, and make the report readable. It no longer needs to invent the factual substrate underneath the prose.

    Make every failure a regression test and a permanent lesson
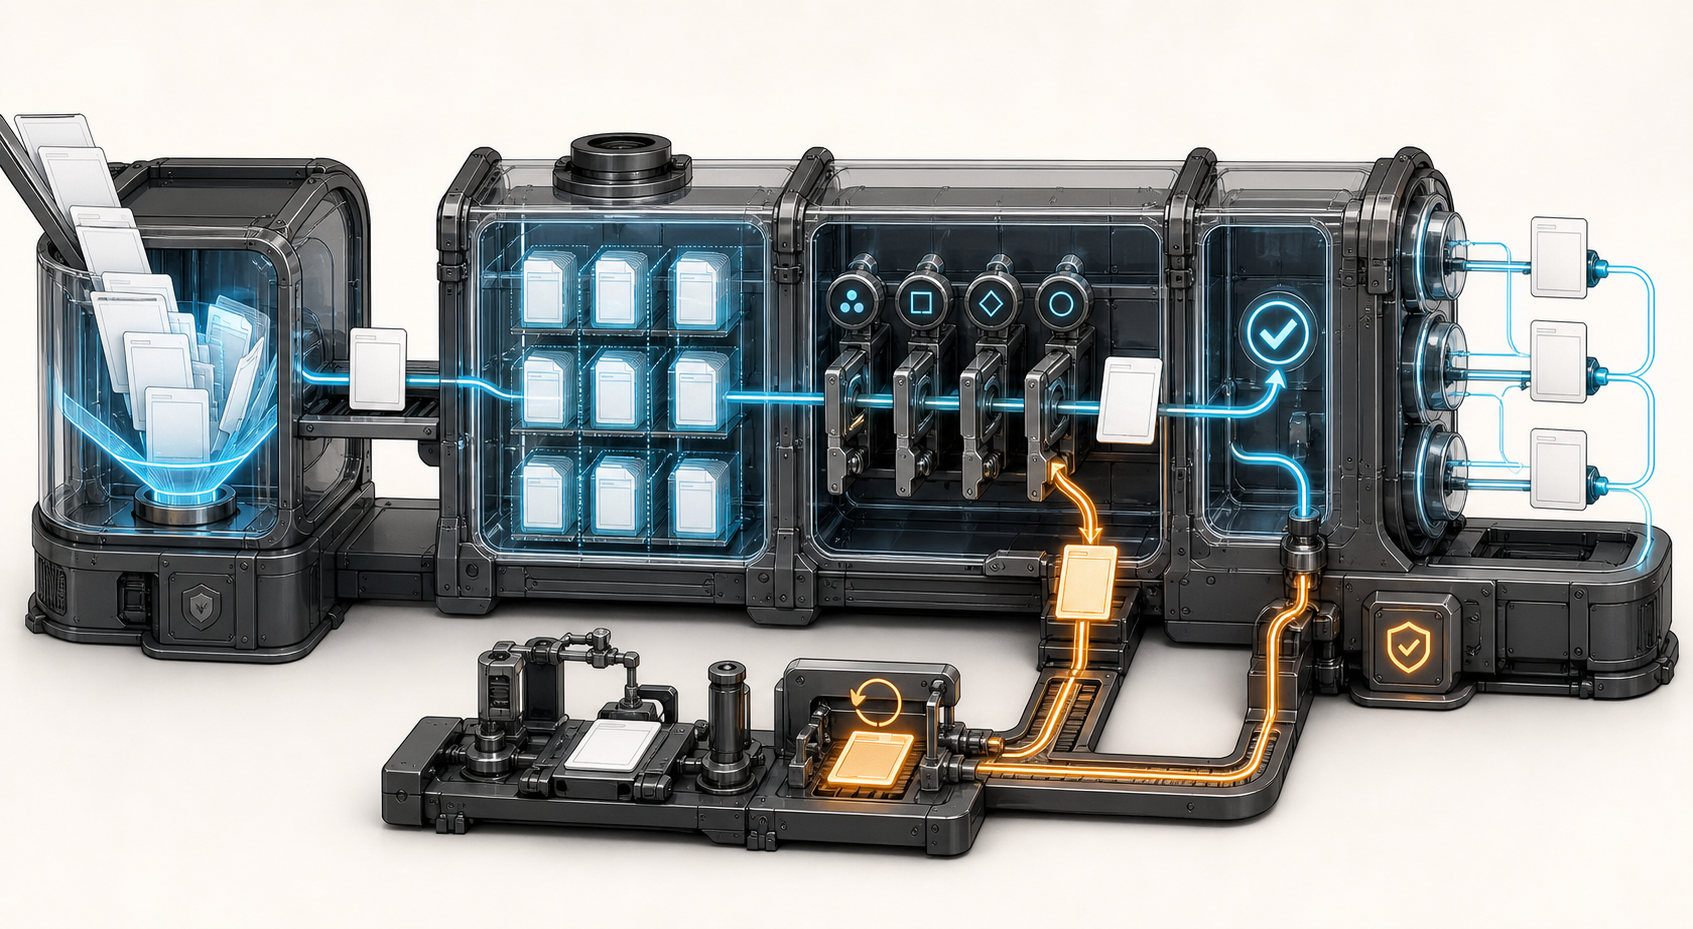
    A transparent audit machine collects abstract web pages, preserves evidence, checks rules, and routes a failed item through a test bench into a new checkpoint.

    You cannot establish reliability by running the agent once on a cooperative site. Build a small fixture set in which the expected observations and classifications are already known. It should include clean pages as well as failures, because an agent that finds seeded defects may still produce unacceptable noise on valid configurations.

    Your fixture set should exercise the conditions your agent claims to handle:

    • A static page with all required elements present
    • A page with a deliberately missing in-scope element
    • A page with a canonical element that should not be flagged
    • An intentionally noindexed page whose intent is supplied to the test
    • A redirect and its final destination
    • A nonexistent URL
    • A blocked, challenged, or rate-limited response
    • A route whose supported checks require rendered output
    • A standard sitemap, a sitemap index, a robots.txt sitemap declaration, and a site with no discoverable sitemap

    For each fixture, store the expected collection result, extracted observation, classification, and output state. Run the suite whenever you change instructions, scripts, issue criteria, templates, or model configuration. Review both misses and false positives. A report that catches every seeded problem but invents several more is not ready.

    When a live run fails, convert the failure into four artifacts:

    1. A minimal fixture that reproduces the condition
    2. A test that fails before the correction
    3. A change to the appropriate script, instruction, or reference rule
    4. A run-log entry that explains the symptom, cause, correction, and affected version

    This is how iteration creates an accumulating reliability advantage. Problems involving modern CDNs, rate limiting, JavaScript rendering, sitemap discovery, and noisy classifications stop being isolated surprises once their fixes are preserved in the workspace and exercised on every later change. The architecture becomes measurably better as failures become reusable lessons.

    Memory must not become a substitute for current evidence. A previous run may tell the agent that a URL once lacked a meta description, but it cannot prove the page still lacks one. Use memory to retain operating knowledge, compare changes, and select regression checks. Require a fresh observation before making a current-site claim.

    A useful run log records the run ID, workspace version, scope, discovery method, coverage totals, confirmed findings, rejected candidates, unknown checks, tool failures, and rule changes. Keep links to retained evidence where your data-handling rules allow it. This gives you a basis for comparing runs without asking the model to remember what happened.

    Repeatability does not mean every sentence must be identical. It means the same collected facts and rule versions should produce the same classifications. Keep factual extraction and rule evaluation structured; allow the model more freedom only when it turns those stable records into reader-friendly explanations.

    Key takeaways before you deploy

    Use this as the release gate for an SEO agent that will influence audits, tickets, or client recommendations:

    • Require evidence for every finding. A published issue must identify the inspected URL, observed value, retrieval method, verification state, and rule that supports it.
    • Keep observation separate from judgment. The tool collects the fact, the criteria classify it, and the final layer recommends an action.
    • Treat inaccessible as unknown. A failed request, blocked page, rendering problem, or exhausted retry path must never be translated into a missing element.
    • Expose coverage. Show how many URLs were discovered, fetched, inspected for each check, and left unresolved so readers can interpret the scope correctly.
    • Test valid and invalid configurations. Your regression set must prove that the agent can stay quiet on acceptable pages as well as detect seeded problems.
    • Preserve every correction. A false positive should result in a fixture, regression test, rule or tool change, and versioned run-log entry.
    • Keep memory subordinate to fresh inspection. Previous runs can guide comparisons and testing, but current claims require current evidence.
    • Block unsupported prose. The report generator may explain and prioritize verified records; it may not add facts, URLs, counts, or issue types that the pipeline did not produce.

    Your next move should be deliberately narrow. Build a URL inventory agent that records discovery, redirects, response results, indexability signals, and canonical observations. Give it known fixtures, force it to show unknowns, and manually inspect a sample of its evidence on a site you control. Add another issue class only after the first one survives the same gate across repeated runs.

    That pace may feel slower than asking for a comprehensive audit in one prompt. It is also how you end up with an agent whose conclusions deserve to be acted on.
    References

  • Technical SEO Foundations for Search in the AI Era

    Technical SEO Foundations for Search in the AI Era

    You can publish excellent answers, add structured data, and track dozens of AI prompts, yet still remain invisible because the underlying site sends mixed signals about which pages exist, which URLs matter, and what each page is actually about.

    The remedy is less exotic than the problem sounds. Build a site that can be discovered, fetched, interpreted, and trusted without guesswork. That foundation serves conventional search engines, retrieval systems, and the people who eventually land on your pages.

    Key takeaways

    • AI search optimization starts with ordinary technical access: clean URLs, crawlable links, indexable pages, and content that exposes its main answer clearly.
    • Give each important intent one preferred URL, then make internal links, redirects, canonical signals, navigation, and structured data agree with that choice.
    • Remove campaign tracking parameters from internal destinations. Measure the click without creating another version of the destination URL.
    • Write pages as extractable answer systems: state the answer, define the subject, support the claim, preserve its qualifiers, and cover the natural follow-up questions.
    • Structured data can confirm visible meaning, but it cannot repair inaccessible content, contradictory facts, weak architecture, or an unclear page purpose.
    • Measure discovery, URL selection, extraction, corroboration, and AI answer visibility separately. A missing citation does not identify which layer failed.

    Audit the complete retrieval chain before rewriting content

    A cutaway sequence shows a page moving through discovery, server access, rendering, indexing, and retrieval, with one connection visibly inactive.

    An AI-generated answer may look different from a page of blue links, but much of the upstream work is familiar. Retrieval, page quality, speed, and intent matching remain durable foundations. If a system cannot reliably reach or interpret a page, polishing its answer format will not solve the real problem.

    Retrieval-augmented generation, usually shortened to RAG, gives you a useful model for thinking about this process. Instead of relying only on information learned during model training, a RAG system can retrieve external material to help construct an answer. Your technical job is to make the right page a strong retrieval candidate.

    Work through the chain in order. Each step depends on the one before it:

    1. Discovery: Can a crawler reach the page through ordinary internal links from an indexable part of the site? A sitemap can support discovery, but it should not be the page’s only connection to the site.
    2. Access: Does the preferred URL return a successful response and expose the primary content without a login, consent dead end, redirect loop, or permanent loading failure?
    3. Eligibility: Do robots controls, page-level indexing directives, canonical tags, and other technical signals permit the page to be considered?
    4. URL selection: Do all signals identify the same preferred URL, or do internal links point to parameters and redirects while the canonical tag names something else?
    5. Extraction: Can a machine identify the subject, main answer, supporting details, and important qualifiers from the page itself?
    6. Corroboration: Is the claim consistent with the rest of your site, and does the page offer evidence or references appropriate to the question?

    Do not collapse these checks into a single question such as, “Is the page indexed?” Indexing does not prove that the preferred URL was selected, that the decisive passage was extracted, or that the page was judged useful for a particular prompt.

    Start the audit with pages tied to real decisions: a service page, a product category, an important comparison, a technical explanation, or a support page that resolves a costly problem. For each one, begin at the home page or its nearest topic hub and follow the path a crawler would take. Record every redirect, parameterized destination, blocked step, and conflicting canonical signal. You are testing the route, not merely inspecting the destination.

    Run the same check in your templates. A clean link added manually to one page does not compensate for a navigation component, related-content module, or call-to-action block that generates messy URLs across the site. Template defects multiply; template fixes do too.

    Use one stable URL per intent, then make every link agree

    A canonical tag is not a substitute for coherent architecture. It is one signal describing your preferred version. If navigation, breadcrumbs, content links, redirects, sitemaps, and structured data repeatedly point elsewhere, you force retrieval systems to reconcile a disagreement you created.

    Choose the preferred page before changing tags

    For every important topic or task, decide which page should own the intent. That decision should be based on the page’s purpose, not on which URL happens to rank at the moment.

    • Write one sentence describing the question or decision the page owns.
    • Identify overlapping pages that answer substantially the same need.
    • Decide whether each overlapping page has a distinct job, should be consolidated, or should point readers toward the preferred page.
    • Update internal links so their destination is the final preferred URL, not a redirecting or parameterized variation.
    • Align canonical tags, sitemap entries, structured-data URLs, navigation, and alternate versions with that same choice.

    Do not merge pages merely because they share a keyword. A setup tutorial, pricing explanation, troubleshooting page, and buyer comparison can mention the same product while serving different decisions. Consolidate only when the pages compete for essentially the same purpose and neither needs to exist independently.

    Remove tracking parameters from internal destinations

    Campaign parameters are useful when a link crosses from a campaign into your site. They become a liability when your own pages keep appending them to internal destinations. Tracking parameters in internal links can undermine otherwise useful internal linking by creating discoverable URL variants and making the site’s preferred paths less consistent.

    The clean pattern is simple: link internally to the canonical destination and record the interaction separately. Use an analytics event, the referring page, or another measurement method that does not alter the destination URL. The user reaches the same content, while crawlers receive one stable address.

    Audit parameter use as a controlled cleanup:

    1. Export or crawl all internal links, including links produced by headers, footers, cards, related-content blocks, banners, and reusable calls to action.
    2. Group destinations that resolve to the same underlying page but contain different query strings, fragments, protocols, hostnames, or path formats.
    3. Classify each query parameter as tracking, decorative, or functional before changing anything.
    4. Replace tracking variants in templates and page content with the preferred clean URL.
    5. Keep redirects for legacy or externally linked variants when they are still needed, but stop producing those variants internally.
    6. Recrawl the affected paths and confirm that new internal links now point directly to the final destination.

    Do not delete query parameters indiscriminately. Search filters, pagination, account flows, carts, localization, and other features may rely on them. Removing a functional parameter can break the experience or change the content being requested. Classify first; clean second.

    Make internal links explain the site’s knowledge structure

    Internal links do more than move authority around. They describe relationships. A broad topic hub should lead to its detailed explanations; a comparison should link to the products or methods it evaluates; a troubleshooting page should link to the relevant setup instructions; and a supporting definition should point back to the page where the larger decision is made.

    Use anchor text that names what the reader will find. Repeated “learn more” links make the relationship less explicit. You do not need to force the same exact phrase everywhere, but the wording should make sense without relying on the surrounding design.

    Watch for orphaned expertise. A strong technical explanation buried in an old resource directory may be technically indexable yet disconnected from the pages that establish its relevance. Link it from the appropriate hub and from related pages where it resolves a genuine follow-up question.

    Design pages for fan-out, extraction, and corroboration

    A bright central web page receives converging internal links and branches into retrievable fragments that connect with several corroborating source nodes.

    A conversational prompt often contains more than one information need. A person asking which platform fits a regulated team may implicitly need definitions, feature differences, limitations, implementation requirements, and evidence of reliability. AI systems can respond through query fan-out and related prompt intents, retrieving material for those component questions.

    You do not need a separate page for every wording of every prompt. You need a page with one clear primary job and enough well-organized support to answer the natural questions surrounding that job.

    Put the answer where it can be extracted intact

    Open the main content with a direct response to the page’s primary question. Follow it with the mechanism, conditions, evidence, and exceptions. If the answer depends on a product version, user type, location, or implementation state, keep that qualifier beside the claim. A technically correct caveat buried far away can be lost when a passage is retrieved on its own.

    • Use a descriptive page title and heading that identify the subject and task.
    • Give each major follow-up question a descriptive subheading.
    • State important nouns explicitly instead of making long sections depend on vague pronouns such as “it” or “this solution.”
    • Keep definitions near the terms they define.
    • Place evidence, limitations, and applicability conditions near the claim they qualify.
    • Use lists for procedures or criteria, prose for reasoning, and tables only when readers need to compare the same fields across several options.
    • Remove introductions that delay the answer without adding context the reader needs.

    This structure is not an invitation to write in disconnected fragments. A page still needs a coherent argument. The goal is for each important section to remain accurate and useful when encountered independently.

    Keep entity facts consistent across the site

    Machines have a harder job when your own pages disagree about basic identity. Product names, organization names, service areas, feature labels, relationships, and current availability should not change casually between a landing page, documentation, an author profile, and structured data.

    Create a small factual inventory for the entities that matter most. Record the preferred name, concise description, relationship to the organization, and the canonical page that represents each entity. Use that inventory when updating templates and content. This is especially valuable after rebranding, product consolidation, acquisitions, URL migrations, or changes in terminology.

    Consistency does not mean copying the same marketing paragraph everywhere. It means that factual identity remains stable while each page explains the entity in the context of its own task.

    Use structured data to confirm visible meaning

    Structured data should describe what the page visibly communicates. It can make entities, page roles, and relationships more explicit, but it cannot make a blocked page retrievable or turn contradictory copy into a reliable fact.

    • Use the preferred canonical URL wherever the markup identifies the page or its main entity.
    • Keep names, descriptions, relationships, and other properties consistent with visible content.
    • Remove markup left behind by deleted templates, expired offers, or repurposed pages.
    • Validate syntax after template changes, then inspect the rendered page to confirm that the intended markup is actually present.
    • Treat eligibility for a search feature as separate from guaranteed visibility. Valid markup is an input, not an outcome.

    Support claims with appropriate corroboration

    AI optimization is not confined to your own domain. Quality backlinks and third-party visibility remain relevant because retrieval systems need reasons to treat one candidate as more dependable than another.

    On the page, cite primary material when a claim depends on a standard, regulation, official specification, dataset, or named research result. Outside the page, make sure reputable profiles, directories, partners, and industry references use the same core identity. Do not manufacture mentions or fill the web with duplicated descriptions. The useful signal is independent, contextually relevant corroboration.

    Measure the failed layer, not just the missing mention

    AI visibility is tempting to reduce to a yes-or-no brand check. That hides the diagnosis. Your site may be absent because the page was not discovered, the wrong URL was selected, the relevant passage was difficult to extract, another page answered the intent better, or the system produced an answer without showing its external inputs.

    That last case matters: AI tools may provide an answer without displaying external sources. A visible citation is useful evidence, but the lack of one does not prove that no retrieval occurred. Treat AI answer monitoring as directional evidence, not as a conventional rank report with a fixed position.

    Build a prompt set around real user decisions

    Group prompts by intent instead of generating superficial keyword variations. Include the questions people ask when defining a problem, comparing approaches, checking suitability, planning implementation, and resolving failure. Preserve the exact wording so you can rerun the same prompt after a change.

    For every observation, record the system used, the exact prompt, the date, the answer’s main claims, any cited domains, the cited page URL, and whether the answer represented your entity accurately. Reviewing responses in systems such as Google AI Mode and ChatGPT can reveal which external pages are being selected and which prompt intents your coverage misses.

    Do not interpret one generated response as permanent. Retrieval inputs and generated wording can vary. Look for repeated patterns across your stable prompt set, then connect those patterns to technical evidence from crawling, indexing inspection, analytics, and server data where available.

    Use the symptom to choose the next check

    • The preferred page is not discoverable through the site: repair navigation, hub links, orphaning, and template-generated destinations before rewriting the copy.
    • A parameterized or redirected URL appears instead of the preferred page: align internal links, canonical signals, redirects, sitemaps, and structured-data URLs.
    • The page is accessible, but the extracted answer is incomplete: move the direct answer and its qualifiers into a coherent section under a descriptive heading.
    • The wrong page answers the prompt: clarify the purpose of overlapping pages, consolidate true duplicates, and strengthen links to the intended owner.
    • The entity appears with incorrect facts: locate contradictions across landing pages, documentation, profiles, structured data, and relevant third-party references.
    • Competitors are repeatedly cited for a subtopic you barely cover: decide whether that subtopic belongs on the existing page or deserves a distinct page with its own purpose and evidence.
    • Your answer appears without a visible citation: record the mention, but do not claim attribution you cannot observe. Continue checking retrievability, accuracy, and independent corroboration.

    Ship improvements in dependency order

    1. Restore discovery and access for the preferred page.
    2. Resolve conflicting URL and indexability signals.
    3. Clean internal destinations and repair the path from relevant hubs.
    4. Clarify the page’s primary intent and reorganize its answer.
    5. Align entity facts and structured data with visible content.
    6. Strengthen evidence and relevant third-party corroboration.
    7. Rerun the same prompt set and document what changed.

    Your next move is not another isolated AI tactic. Pick one important path through your site, audit it from discovery to extraction, fix the first broken layer, and verify the same prompts again. Once that path is coherent, repeat the process on the next decision that matters to your audience.

    References

  • SEO Under Constraints: Rendering and Restricted Keywords

    SEO Under Constraints: Rendering and Restricted Keywords

    Your page can fail search visibility in two places at once. The content a crawler needs may not exist until JavaScript runs, while the phrase customers actually search may be prohibited by legal, trademark or brand rules.

    Treat those as separate failure modes. First, make the page understandable without waiting for client-side rendering. Then build relevance around the intent you are allowed to express. That order matters: stronger copy cannot rescue content a crawler never receives.

    Separate retrieval problems from relevance problems

    A rendering constraint affects retrieval. The server returns a thin document, and JavaScript later inserts the main copy, navigation, product details or internal links. A wording constraint affects relevance. The page is available, but the language that connects it to a valuable query is weak, indirect or deliberately absent.

    When both occur on the same page, teams often misread the symptoms. An editor adds more synonyms when the copy is missing from the initial response. A developer improves rendering while the approved vocabulary still fails to describe the searcher’s need. Neither change closes both gaps.

    QuestionWhat to inspectWhat the result means
    Can a crawler understand the page before JavaScript runs?The raw HTML response, including the title, main heading, essential copy and linksIf the page’s purpose is missing, you have a retrieval problem.
    Can a visitor understand the offer without the restricted phrase?Headings, body copy, definitions, attributes, use cases and related terminologyIf the offer remains vague, you have a relevance problem.
    Is the phrase legally prohibited or merely discouraged?The written rule for body copy, metadata, links, comparisons, questions and definitionsThe permitted tactics depend on the actual boundary, not an informal preference.
    Does the approved vocabulary match how people express the need?Query data grouped by intent rather than one isolated keywordA large demand gap may justify revisiting the policy or creating a stronger semantic route.

    Run these checks before changing templates or copy. They tell you whether the next ticket belongs with engineering, content, legal or all three. They also give each team a testable acceptance criterion instead of the vague instruction to improve SEO.

    Put the essential answer in the initial HTML

    Solid core page panels emerge first from a server while translucent secondary modules assemble behind them.

    Google can execute JavaScript, but execution is not the same as immediate, complete discovery. Pages can be queued until rendering resources are available, after which a headless browser processes the client-side code. That extra stage creates another opportunity for delayed or incomplete discovery.

    The dependency is even riskier outside Google. Many AI crawlers and other non-Google bots do not consistently execute JavaScript. If the useful answer exists only inside a client-rendered component, those systems may receive a shell rather than a document they can quote, classify or follow.

    You do not need to rebuild every interaction as a no-JavaScript application. You do need an HTML-first discovery path for anything that establishes what the page is, what it offers and where its important links lead.

    • Return a unique, meaningful page title and a clear main heading in the server response.
    • Include the primary explanation, answer, product description or service description before client-side code runs.
    • Expose essential facts that determine whether the result satisfies the visitor’s need. Do not hide the only useful details behind tabs, filters or event handlers.
    • Render primary navigation, breadcrumbs and contextual internal links as ordinary anchors with real destinations.
    • Deliver structured information needed to identify the page and its subject in the initial document where practical.
    • Add JavaScript for filtering, personalization, live calculations and other interactions after the discoverable foundation is present.

    Server-side rendering, static generation and pre-rendering can all provide that foundation. The right choice depends on how often the content changes and how much of the interface is truly dynamic. A stable service page may suit static generation. A frequently updated catalogue may need server-side rendering. A client-rendered application can selectively pre-render its public discovery pages while keeping authenticated workflows dynamic.

    A <noscript> block can be a safety net, but it should not become a second, neglected version of the page. If you use one, keep it concise and aligned with the visible experience. The safer architectural target is meaningful server-delivered HTML that JavaScript enhances rather than replaces.

    Test the response, not just the finished screen

    A browser screenshot with JavaScript enabled proves that a visitor can see the interface. It does not prove that a crawler received the content or that the links are discoverable. Use this sequence on every important template:

    1. Open the raw server response or page source. Find the title, main heading, first useful answer and primary links.
    2. Load the page with JavaScript disabled. Confirm that its subject and next step remain understandable.
    3. Inspect critical links. They should have crawlable destinations rather than relying only on click handlers.
    4. Compare the initial and enhanced versions. They can differ in presentation, but they should not contradict each other or describe different offers.
    5. Repeat the check while logged out and without stored browser state. Public discovery must not depend on a previous session.
    6. Test a sample from every shared template. Passing one editorial page says little about a product, location or category template built through a different rendering path.

    Prioritize pages by consequence. Start with the homepage, high-demand landing pages, major categories, locations and pages that supply internal links to deeper content. A missing decorative widget is inconvenient. A missing product description or category link changes what the crawler can understand and reach.

    Map the search intent before working around a restricted term

    Hands arrange groups of pictorial tokens along illuminated paths around a locked central tile.

    Do not treat every keyword restriction as the same instruction. A trademark concern, an absolute legal prohibition, a brand preference and a rule against making one phrase the primary focus create different boundaries. Get the rule in writing before anyone places the term in a heading, title, image description or link.

    The first question is not, “How can we hide this keyword?” It is, “What is the searcher trying to identify, compare or accomplish?” That change of frame gives you legitimate language to work with even when the familiar label is unavailable.

    Demand data can also reveal whether an internal naming preference carries a substantial visibility cost. In one senior-living comparison, “skilled nursing near me” showed 4,400 monthly searches while “nursing home near me” showed 27,100. Those figures do not create permission to use a prohibited phrase. They do show why legal, brand and search teams should make the decision with the same evidence in front of them.

    Build an intent map around the restricted query. Include:

    • The approved category: the clearest accurate name you are allowed to use.
    • The underlying job: what the person wants to buy, arrange, learn, compare or solve.
    • Defining attributes: materials, features, level of support, location, compatibility or other characteristics that make the offering identifiable.
    • Use contexts: the occasions, environments and situations in which the need appears.
    • Audience language: natural questions, synonyms, spelling variants and adjacent terms that people use for the same intent.
    • Necessary distinctions: what the offering is, what it is not and how nearby categories differ.

    For a beverage-insulation product, for example, the semantic field might include can cooler, insulated drink sleeve, beer, cold drinks, party favors and occasions such as a bachelorette party. No single substitute has to impersonate the restricted name. Together, accurate category, attribute and context language can make the page’s subject clear.

    Use the exact term only where permission is explicit

    Some policies allow a term in a factual definition, comparison, question or combined product label but prohibit presenting it as the brand’s preferred category. If legal or brand reviewers approve that boundary, a limited contextual mention can clarify the relationship between the common query and the approved offering.

    If the phrase is prohibited everywhere, do not smuggle it into metadata, alternative text or anchor text. Those fields are still published content. Search engines can process them, users may encounter them, and moving a term out of the visible body does not remove a trademark or compliance concern.

    Apply the same rule to each element:

    • Title and main heading: lead with the approved category and the page’s actual promise.
    • Introduction: answer the underlying need immediately. Do not force awkward synonyms into a sentence that becomes harder to understand.
    • Definitions: explain unfamiliar approved terminology and its boundaries. Use the restricted label only if that explanatory use has been cleared.
    • Internal links: choose descriptive anchor text that truthfully identifies the destination. An approved common term can be useful; an unapproved one remains unapproved.
    • Alternative text: describe the image and its purpose. It is not a storage area for keywords that copy reviewers rejected.
    • External links: do not build an artificial exact-match pattern. Use language that is accurate, natural and permitted in that context.

    You may still earn visibility without the exact phrase because relevance can be established through related concepts and intent. It is not a guarantee, especially when competitors can use the dominant wording directly. Set expectations accordingly: the goal is the strongest truthful signal set available under the constraint, not a loophole that makes the constraint disappear.

    Use one launch gate for code, copy and compliance

    A constrained page should not move through engineering, editorial and legal as three disconnected deliverables. Give it one acceptance checklist. That prevents a technically crawlable page from shipping with vague language, or approved copy from disappearing behind client-side rendering.

    1. Define the page’s job. Write one sentence stating who the page helps, what they need and what action the page should enable.
    2. Name the query family. Group the restricted term, approved synonyms, questions, category language, attributes and use cases by shared intent.
    3. Record the wording boundary. Specify whether the term is banned everywhere, allowed only in named contexts or merely excluded as the primary label. Cover headings, body copy, metadata, links and image descriptions separately.
    4. Draft the minimum complete answer. Before designing interactive elements, write the heading, concise explanation, essential facts and next-step links that must exist in the initial HTML.
    5. Place approved relevance signals. Use the approved category prominently, then add useful attributes, applications, distinctions and definitions. Each addition should improve understanding, not just keyword coverage.
    6. Render the foundation on the server. Choose static generation, server-side rendering or pre-rendering for the public content. Hydrate interactive features on top of it.
    7. Run two reviews. Technical QA verifies the raw response and crawlable links. Editorial and legal review verify that every published field follows the wording policy.
    8. Measure by query group and template. Watch whether the intended family of searches reaches the page and whether affected templates are discoverable. Do not judge the work from one exact keyword or one successfully rendered URL.

    Write the acceptance criteria so failure is obvious. “Improve crawlability” is not testable. “The service description and links to all primary locations appear in the initial HTML” is. “Use related keywords” is equally weak. “The title names the approved category, and the body explains its use, defining attributes and difference from adjacent categories” gives an editor something concrete to deliver.

    When a page still underperforms, return to the two failure modes. If the content is absent from the response, fix retrieval. If it is present but does not clearly resolve the intent, fix relevance. If the exact phrase would materially change the opportunity but remains prohibited, take the demand evidence back to the decision-maker rather than quietly violating the rule.

    Key takeaways

    • Rendering and keyword restrictions are independent constraints: one limits retrieval, while the other limits relevance signals.
    • Put the page’s heading, essential answer, core facts and important links in server-delivered HTML.
    • Use JavaScript to enhance the experience, not as the only delivery mechanism for content that must be discovered.
    • Clarify whether a restricted term is legally banned, contextually permitted or simply discouraged before placing it anywhere.
    • Build relevance through approved category language, intent, attributes, use cases, definitions and natural internal links.
    • Make raw-HTML validation and wording compliance part of the same launch gate.

    Start with one high-value template this week. Capture its raw HTML, mark the essential content that is missing, document the exact wording boundary and rebuild the smallest complete answer that satisfies both. Once that page passes, turn the checks into requirements for every template that follows.

    References


  • Google Back-Button Hijacking: What to Audit and Fix Now

    Google Back-Button Hijacking: What to Audit and Fix Now

    If your site changes browser history to stop visitors from leaving, the grace period is over. Google’s enforcement date was June 15, 2026, so any remaining back-button trap is now an active search compliance problem rather than a future development task.

    The remedy is not to disguise the behavior or move it into another script. You need to restore the navigation outcome users expect: after arriving from another page, one press of the Back button should take them back to that page unless they have deliberately navigated through a meaningful intermediate state.

    Key takeaways

    • Google made back-button hijacking an explicit malicious-practices violation, with enforcement beginning June 15, 2026.
    • Possible consequences include a manual spam action or an automated demotion in Google Search.
    • The deciding issue is the visitor’s navigation outcome, not whether your implementation uses a particular JavaScript API.
    • Audit first-party code, tag-manager deployments, advertising scripts, affiliate tools, themes, plugins, and experimentation platforms.
    • Do not delete every History API call blindly. Legitimate routers and interface states still need coherent browser history.
    • A passing test requires more than the disappearance of a popup: Back must return users through the places they actually visited, in the expected order.

    The policy judges the navigation outcome, not the API

    Back-button hijacking occurs when a page interferes with normal browser navigation. A visitor tries to return to the page they came from but is redirected somewhere they never chose, shown an unsolicited advertisement or recommendation, or otherwise prevented from leaving normally.

    That distinction matters during an engineering audit. Methods such as history.pushState, history.replaceState, and the popstate event are not inherently abusive. Single-page applications, tabs, filters, multi-step forms, and user-opened overlays can use browser history for legitimate reasons. The problem begins when the history stack no longer represents states the user knowingly entered.

    Use an outcome test instead of treating the presence of an API call as proof. A page needs remediation when you can reproduce behavior such as:

    • The visitor arrives from Google, presses Back, and lands on another site page, advertisement, or recommendation that they never visited.
    • The page adds invisible or meaningless history entries on load, forcing the visitor to press Back repeatedly before reaching the actual previous page.
    • A popstate handler immediately pushes the current page back into history, sends the visitor forward again, or routes them to an unrelated destination.
    • An exit overlay appears because the visitor pressed Back, and dismissing it still does not restore the expected previous page.
    • A third-party script changes the Back destination only for certain campaigns, referrers, devices, or consent states.

    A legitimate interface state has a different shape. The user takes a visible action, the URL or interface meaningfully changes, and Back reverses that action. For example, a user-opened modal may be represented in history if Back closes that modal once. A visitor who never opened it should not inherit a synthetic modal state merely because the page loaded.

    Intent does not make a broken flow acceptable. A conversion team may call the behavior an exit offer, while an advertising vendor may describe it as retention. If the user cannot immediately return through their real browsing path, rename-and-retain is not a remediation strategy.

    Audit every landing-page path, not just the homepage

    A magnifying glass examines multiple routes into a generic website, including one route that loops back on itself.

    Back-button behavior often depends on how someone entered the site. Testing the homepage from a bookmark can therefore miss a trap that runs only on search landings, paid campaigns, content templates, affiliate pages, or pages with a particular tag-manager trigger.

    Run the audit as a reproducible navigation test:

    1. Inventory entry templates. Group URLs by the code and commercial stack they use: articles, product pages, category pages, lead-generation landers, comparison pages, and any separate mobile or campaign experiences. Start with templates that receive external entrances rather than selecting URLs at random.
    2. Create a real predecessor page. Begin on a Google results page or another controlled page, then open the target in the same tab. This gives Back a known destination. Typing a URL into an empty tab is not an adequate test because there may be no previous document to return to.
    3. Test before interacting. After the landing page finishes loading, press Back once. Record the destination, any intermediate screen, any overlay, and whether the site appears to reload or push you forward.
    4. Repeat after relevant states. Test after making a consent choice, opening and closing site controls, following an internal link, returning to the landing page, and triggering any advertising or recommendation component the template normally displays.
    5. Vary the environment. Repeat in clean sessions across the browser and device families your site supports. Include logged-in and logged-out states where applicable, as well as the consent choices that determine which third-party tags execute.
    6. Trace the responsible code. When a test fails, isolate first-party bundles, tag-manager containers, plugins, themes, advertising tags, affiliate scripts, and experimentation tools. Disable candidates in a safe test environment until the normal Back destination returns.

    Keep the findings in a small test ledger. It turns a vague sitewide concern into an assignable release plan:

    FieldWhat to recordWhy it matters
    Landing URL and templateThe tested URL plus the shared page typeLets you determine whether one failure affects a larger URL family
    Entry routeThe exact page visited immediately before the landing pageDefines the destination Back should restore
    Pre-Back actionsConsent choices, clicks, overlays, internal navigation, or no interactionExposes state-dependent triggers
    Observed resultThe first destination, intermediate states, redirects, ads, or loopsSeparates an expected state reversal from interference
    Code ownerBundle, tag, plugin, vendor, or team responsibleGives the remediation a clear owner
    Fix and verificationRelease identifier, test environment, production result, and date checkedPrevents an unverified configuration change from being marked complete

    A code search can accelerate the investigation. Look for uses of pushState, replaceState, popstate, location.assign, location.replace, meta refresh, and handlers attached to exit-related events. Treat each match as a lead, not a conviction. Removing a router’s legitimate state management without understanding it can break internal navigation, filters, deep links, or form recovery while leaving the actual third-party trap untouched.

    Fix the history model instead of masking the symptom

    Hands remove duplicate page layers from a tangled browser-history stack, leaving a clear sequence back to the original page.

    The correct fix depends on why the history stack was changed, but the acceptance criterion stays constant: browser history should reflect the visitor’s real journey.

    Remove deliberate retention traps

    If code adds dummy history entries when a landing page loads, remove that insertion. If a Back event triggers an advertisement, recommendation, interstitial, or unchosen redirect, remove the handler that causes it. Do not replace several dummy entries with one dummy entry; the first Back press would still fail the user’s expectation.

    Move legitimate retention content into the page. An inline recommendation, a clearly labeled link, or a user-invoked offer lets the visitor choose whether to continue. The browser’s navigation control should not become an undisclosed conversion mechanism.

    Preserve meaningful application states

    For a single-page application, map history to visible, reversible states. Push a new entry when the user deliberately moves to a meaningful view. Replace the current entry when you are correcting or normalizing the same state. When popstate fires, render the state it represents instead of immediately creating another entry that defeats the Back action.

    Check deep links and the Forward button after making this change. A repair that lets users escape but leaves URLs pointing at the wrong content is still a broken navigation model, even if it no longer resembles a retention trap.

    Contain third-party behavior you cannot verify

    When the behavior belongs to an ad network, affiliate script, conversion tool, plugin, or tag-manager template, identify the exact configuration that enables it. Turn that feature off and retest with the vendor code still present. If the feature cannot be isolated or its behavior changes outside your control, keeping the integration live means keeping the navigation risk live. Pause the responsible script until its Back behavior is predictable.

    Do not assume that a vendor-side setting changed production. Cached bundles, container versions, consent branches, and campaign-specific rules can preserve an older path. Confirm the rendered production experience after deployment.

    Treat the passed deadline as a release gate

    Google’s advance-notice period ended on June 15, 2026. From that date, the stated enforcement paths included manual spam actions and automated Search demotions. Those are distinct paths, so the absence of a known manual action does not prove that a site is unaffected or compliant.

    Do not read stable rankings immediately after the date as permission to leave the code in place. An enforcement start date is not a promise that every affected URL will show a visible change at the same moment. The reliable compliance signal is a clean navigation test, not a lack of obvious ranking movement.

    Before closing the remediation ticket, require these production results:

    • After a fresh external landing with no interaction, the first Back press returns to the immediate predecessor page.
    • After meaningful user-initiated navigation, repeated Back presses unwind those states in the order the user entered them.
    • No Back action opens an unrequested advertisement, recommendation, overlay, or destination.
    • The page does not insert a replacement history entry that sends the visitor forward again.
    • Forward navigation, deep links, filters, authentication flows, and multi-step interfaces still work where the affected code participates in them.
    • The test passes on production under the campaign, consent, device, and account states that control script execution.

    If search visibility declined around the enforcement date, do not declare back-button hijacking the cause from timing alone. First confirm whether the behavior existed, which templates contained it, when it was removed, and whether the same URLs pass now. That evidence gives you a defensible diagnosis while avoiding an unrelated rewrite.

    Schema, content expansion, and AI-search optimization do not remove a navigation trap. Put the work in the right order: contain the offending behavior, repair the history model, verify every affected template, and then return to broader optimization. Assign an engineering owner and an SEO owner now, and do not close the issue until one press of Back does what the visitor intended.

    References


  • How to Build an AI-Era SEO Stack That Improves Visibility

    How to Build an AI-Era SEO Stack That Improves Visibility

    You are probably not short of AI SEO tools to evaluate. The harder problem is deciding which ones deserve a place in your stack when several products generate briefs, audit pages, track prompts, suggest schema, and summarize reports in slightly different ways.

    The answer is not to buy the platform with the longest AI feature list. Build a system in which every tool produces evidence, that evidence leads to a named decision, and a person verifies the result before it changes a page. That gives you a stack that can support conventional search, answer engines, and generative search without paying for three versions of the same dashboard.

    Choose tools by the decision they improve

    Tool consolidation and AI adoption are happening at the same time. In the 2025 MarTech Replacement Survey’s cohort of 154 marketers who had replaced an application in the preceding year, 43.8% cited cost reduction, while 37.1% considered AI capabilities crucial and 33.9% wanted AI features in a new tool. Those figures describe one survey cohort, not the entire market, but they expose the decision most SEO teams now face: add AI capability without adding another layer of overlapping cost.

    Start by inventorying decisions rather than products. Your working stack needs to cover these jobs:

    • Technical discovery: identify crawling, indexing, rendering, internal-linking, response-code, and metadata problems that block or weaken discovery.
    • Demand and intent: connect queries and audience questions to the page that should answer them.
    • Content evaluation: find omissions, ambiguity, outdated information, weak evidence, and intent mismatches.
    • Entity and structured-data management: make the people, organizations, products, topics, and relationships on a page explicit and internally consistent.
    • Search and AI visibility monitoring: record rankings, impressions, mentions, linked citations, cited URLs, and the accuracy of generated descriptions.
    • Workflow and reporting: turn findings into tickets, briefs, annotations, summaries, and accountable next actions.

    One platform may cover several jobs. That is useful only when the outputs remain specific enough to act on. A single interface filled with generic scores is not an integrated stack; it is a consolidated reporting problem.

    Use a keep, replace, remove, or build audit

    Assign every current tool to one of four buckets:

    • Keep it when it produces evidence you use, fits the workflow, and has a clear owner.
    • Replace it when an important requirement is missing, the data cannot be exported, or another product can remove genuine duplication.
    • Remove it when nobody can name a recent decision that changed because of its output.
    • Build a narrow utility when your process, data model, or reporting logic is genuinely specific to your business.

    For each product, complete this sentence: “When the tool shows ______, the owner does ______, and success is checked with ______.” A blank in any position reveals the real gap. You may have a data problem, an ownership problem, or a validation problem rather than a software problem.

    Do not accept “AI-powered” as a requirement. Translate it into an observable capability. For example: classify a crawl export by likely impact; preserve citations when summarizing evidence; identify the URL cited in an answer; generate JSON-LD from approved fields; or turn approved metrics into a report narrative without changing the underlying numbers.

    Custom software has become more plausible for these narrow jobs. Homegrown applications accounted for 8.1% of replacements in the 2025 survey, up from 3.4% in 2024. That is evidence of renewed interest, not proof that building is automatically cheaper. Buy common infrastructure such as crawling when a mature product already solves the problem. Consider building the small connector, classification rule, or reporting layer that reflects how your organization actually works.

    Make vendors demonstrate the evidence trail

    A useful evaluation should begin with your data and end with your decision. Give each shortlisted tool the same representative input, then inspect the complete path from evidence to recommendation.

    • Can you see the page, query, answer, citation, crawl row, or measurement behind a recommendation?
    • Can you export the raw evidence and the processed result in a usable format?
    • Can you distinguish observed facts from the tool’s interpretation?
    • Can you segment results by page type, intent, market, language, or another dimension that matters to your decisions?
    • Can a reviewer correct the output without rebuilding the workflow outside the product?
    • Can you connect the finding to an owner, ticket, brief, or content update?
    • Does the tool replace an existing cost, or does it merely add a new dashboard?

    If a vendor can show a polished recommendation but not the evidence behind it, treat the output as a hypothesis. That distinction matters more in AI search because an answer can change across prompts and contexts. A tool that preserves the prompt, response, cited URL, date, and evaluation conditions gives you something you can audit. A visibility score without those components is much harder to interpret.

    Put AI on high-friction work, not final judgment

    AI earns its place in an SEO workflow when it reduces the effort between raw input and a reviewable result. It should not quietly become the authority that decides whether a claim is true, a page satisfies intent, or code is safe to deploy.

    Use a repeatable prompt specification rather than an improvised request. Give the model the page’s purpose, audience, target query or task, approved evidence, constraints, required output format, and review criteria. Tell it how to mark uncertainty and what it must not invent. The last instruction is especially important when the input does not contain enough evidence to complete every field.

    Accelerate content work without outsourcing expertise

    Several practical AI-assisted SEO workflows share the same pattern: the model creates options or performs a first pass, while a person supplies expertise and approves what gets published.

    • First drafts: provide a real brief, audience, intended angle, target query, source material, and exclusions. Ask for a structure before a full draft. The editor must then add original reasoning, examples supported by evidence, and the publication’s voice.
    • Content refreshes: give the model the existing page, its target intent, performance context, and current approved facts. Ask it to separate missing coverage, stale material, unsupported claims, structural problems, and optional expansion ideas. Verify each proposed change rather than accepting a rewritten page wholesale.
    • Titles and descriptions: generate variations within your supplied constraints, then choose or combine them manually. Check that each option accurately describes the page; an enticing promise that the page does not fulfill is not optimization.
    • FAQ development: use AI to organize questions found in query research and audience conversations. Remove duplicates, verify that each question belongs on the page, and write answers from approved evidence. Do not manufacture an FAQ merely to create schema.
    • Alt text: supply the image and its function in the surrounding page, not just a filename. Review the result for accessibility and accuracy. A target keyword belongs only when it naturally helps describe the image.

    The quality check is simple: can the reviewer identify what was supplied by the evidence, what was inferred by the model, and what was added by an expert? If those layers are blended together, the workflow is too opaque for reliable publishing.

    Use AI as a technical interpreter and code assistant

    Technical SEO often contains small, high-friction tasks that suit supervised generation:

    • Translate an error message or log excerpt into plain language, possible causes, evidence needed, and reversible diagnostic steps.
    • Generate a regular expression for a clearly described Google Search Console filter, then test it against examples that should and should not match.
    • Classify a crawl export into issue types and propose an order of investigation, while preserving the original rows used for each recommendation.
    • Generate JSON-LD from approved page facts and a named schema type, then compare every value with the visible page before validation.

    AI-generated code can be syntactically tidy and still be wrong. Test regular expressions on a limited dataset. Validate structured data before deployment. Treat suggested fixes to templates, redirects, canonical tags, robots directives, or rendering behavior as code changes that require review and a rollback path.

    Separate reporting observations from explanations

    AI can help scan performance exports for anomalies, compress a long report into an executive summary, or draft the narrative connecting several approved metrics. The model should never be allowed to turn correlation into a confident cause.

    Require reporting output in four labeled parts:

    • Observation: what changed in the supplied data.
    • Possible explanations: hypotheses that could account for the change.
    • Evidence still needed: data required to distinguish those explanations.
    • Next action: the check, experiment, or decision an owner should make.

    This structure makes AI useful without hiding uncertainty. It also creates prompts worth saving. A maintained prompt library for recurring briefs, crawl analysis, metadata, reporting, and schema tasks is more valuable than repeatedly improvising requests, because the inputs, constraints, and review standard become part of the operating process.

    Optimize pages for retrieval, comprehension, and citation

    A modular webpage with organized content and source cards is scanned, and one relevant passage is retrieved into an answer sphere.

    An AI visibility tool cannot compensate for a page that is inaccessible, unfocused, internally inconsistent, or difficult to support with a citation. Conventional SEO remains the retrieval layer. Answer engine optimization and generative engine optimization add a comprehension and representation layer on top of it.

    Build each important page around a clear evidence path:

    1. Assign one dominant intent. Decide which real question, comparison, task, or decision the page should resolve.
    2. State the direct answer early. Do not make a reader or retrieval system work through several paragraphs before discovering the page’s position.
    3. Break complex material into answerable units. Use descriptive headings, a direct explanation, applicable conditions, necessary caveats, and the supporting detail needed to act.
    4. Keep entity names and attributes consistent. A product, organization, person, date, or feature should not acquire different names or conflicting descriptions across the title, body, metadata, structured data, and linked pages.
    5. Support important claims where they appear. Link the words carrying the fact, and distinguish evidence from your interpretation.
    6. Connect related pages deliberately. Internal links should tell a reader what the destination adds, not rely on vague anchor text.
    7. Confirm technical availability. The intended canonical page must be crawlable, indexable where appropriate, renderable, and free from contradictory directives.

    This approach also makes editorial review easier. A reviewer can inspect one answer unit at a time and ask whether it is clear, supported, current, and useful. That is a better quality control mechanism than chasing an aggregate optimization score.

    Treat schema as a translation layer, not a ranking switch

    Structured data gives machines explicit labels for information that may otherwise be expressed only in prose. It can clarify what a page and its entities represent, but it does not repair weak content, establish that an unsupported claim is true, or guarantee a citation in an AI answer.

    Use this schema workflow:

    1. Extract the facts that are visibly present on the page.
    2. Select a schema type that accurately represents that page, such as Article for an editorial page or FAQ when genuine questions and answers appear in the visible content.
    3. Generate or author the JSON-LD from those approved facts.
    4. Compare every populated property with the visible page, including names, descriptions, dates, relationships, and URLs.
    5. Validate the markup. AI can generate Article or FAQ JSON-LD quickly, but the resulting code should still be checked with Google’s Rich Results Test where applicable.
    6. Publish through a controlled template or field mapping so later page edits do not leave stale values in the markup.
    7. Recheck the rendered page and structured data after deployment.

    Validation proves that a parser can understand the code and may surface eligibility issues. It does not prove that the data is accurate, that a search feature will appear, or that a language model will cite the page. Those remain separate checks.

    Schema also should not become an isolated technical project. AI-search strategy increasingly connects technical foundations, content, social activity, public relations, mentions, and citations. The practical lesson is not that every channel needs another tool. It is that your content and reporting systems need a shared view of the entities, claims, questions, and pages the organization wants to be known for.

    Measure AI visibility without disguising it as rank tracking

    An analyst compares how identical glowing inputs produce different webpage fragments and citation markers across several answer portals.

    Rank tracking records an ordered search result under defined conditions. AI answer monitoring records a generated response that may vary with wording, context, system behavior, market, and time. Putting both into one visibility score may be convenient, but it can hide what actually changed.

    Keep the layers separate in your scorecard:

    Measurement layerRecordDecision it supports
    Technical availabilityCrawl state, indexability, canonical target, rendering result, structured-data validityWhether the page can participate as intended
    Conventional searchQuery, landing page, impressions, clicks, position context, conversion outcomeWhere discoverability or intent alignment needs work
    Generated answersExact prompt, engine, date, answer, brand mention, linked citation, cited URL, factual accuracyWhether the brand is represented, supported, and described correctly
    Content operationsAI-assisted task, reviewer changes, rejection reason, approved output, workflow ownerWhere automation saves effort or creates rework
    Stack economicsLicense cost, active use, duplicated output, integration burden, maintenance ownerWhether to keep, replace, remove, or build

    Clicks remain useful, but they cannot describe every zero-click or AI-generated experience. That is one reason teams now seek tools that can measure visibility beyond traditional rankings and clicks. Do not solve that limitation by treating every brand mention as equivalent. An unlinked mention, a citation to your page, a citation to someone else’s page, and an inaccurate description are four different outcomes.

    Create a repeatable AI-answer benchmark

    Build the benchmark from questions that matter to the business, not prompts chosen because the brand already performs well. Include the informational questions, comparisons, objections, and decision-stage tasks that your priority pages are meant to resolve.

    1. Freeze the wording of each benchmark prompt and document its intended user intent.
    2. Record the engine, market or language conditions, date, complete response, citations, and cited URLs.
    3. Capture a baseline before changing content, templates, structured data, internal links, or external promotion.
    4. Change a single meaningful variable where the workflow allows it, and annotate every other known change.
    5. Run the same benchmark on a planned cadence rather than testing only when you expect a favorable answer.
    6. Look for repeated patterns across relevant prompts before claiming that an optimization caused the outcome.

    A mention is not automatically a success. Review whether the answer gives the correct name, category, attributes, limitations, and relationship to the user’s question. Also record which URL earned the citation. If an outdated page or a third-party page is repeatedly cited, that finding should lead to a different action than a simple absence from the answer.

    Measurement should also expose automation failures. Record which AI suggestions were rejected and why. Repeated factual corrections point to an evidence or prompting problem. Repeated voice corrections point to an editorial specification problem. Repeated technical corrections point to a workflow that needs stronger tests, not a model that needs more freedom.

    Key takeaways and your first move

    • Choose an AI SEO tool only when you can name the decision it improves, the evidence it preserves, the owner who acts, and the way the result will be checked.
    • Keep conventional crawling, indexing, intent, and content quality at the base of the stack. AI visibility monitoring adds a measurement layer; it does not replace the retrieval layer.
    • Use AI for first passes, classification, variants, interpretation, and formatting. Keep factual approval, strategic judgment, and deployment control with a qualified reviewer.
    • Make pages easier to retrieve and cite by answering a defined question, using consistent entities, supporting claims in place, and connecting related pages clearly.
    • Use schema only when it matches visible content. Validate the code and verify the facts separately.
    • Track generated answers with their exact prompts, citations, cited URLs, conditions, and accuracy. Do not compress unlike outcomes into one unexplained visibility score.

    Your first move does not require a new subscription. Open the current stack inventory and complete the evidence-action-validation sentence for every tool. Remove the entries nobody can complete. Then choose one recurring workflow with visible friction, such as turning a crawl export into reviewed tickets or turning an approved brief into a review-ready draft. Define its inputs, output, owner, and checks before testing automation.

    Once that workflow is reliable, extend the same operating model to structured data and AI-answer monitoring. You will know what to buy because the missing capability will be explicit, and you will know whether it worked because the evidence trail already exists.

    References


  • Is Your Website Ready for AI Agents? A Practical Audit

    Is Your Website Ready for AI Agents? A Practical Audit

    You can have a fast, attractive website that still leaves an AI system guessing. A person may work around a price that appears late, two conflicting policy pages, an unlabeled button, or a confirmation shown only through a visual change. A machine may stop, cite the wrong fact, or repeat an action because it cannot tell whether the first attempt worked.

    The goal is not to rebuild your site for bots at the expense of people. It is to make public information retrievable, meaning explicit, and actions safely bounded. That is the practical response to the shift toward machine-led website visits. This audit shows you where to look and what a passing result should look like.

    Audit the journey, not the bot name

    Agent readiness is broader than allowing a particular crawler through robots.txt. An AI search system may retrieve a page to answer a question, compare facts across pages, send a person to a landing page, or help a signed-in user complete a task. Each journey fails differently.

    Start with the intent that matters, then follow it from request to outcome. Choose priority journeys from three groups: finding an answer, making a decision, and taking an action. Write the expected result before you test so that a plausible but incorrect response does not pass by accident.

    JourneyWhat the machine needsWhat failure looks like
    Answer or citeA public, stable page with a direct answer and enough context to interpret itThe answer is absent from the retrieved HTML, buried in an image, or contradicted elsewhere
    Compare and decideConsistent names, identifiers, attributes, prices, conditions, and limitationsThe same offer has different facts across the page, structured data, and linked policies
    Act and confirmClearly labeled controls, explicit prerequisites, bounded permissions, and a machine-readable resultThe agent cannot identify the correct control, understand an error, or confirm whether the action succeeded

    For each journey, name the authoritative page, the facts that must be preserved, the actions that are permitted, and the state that proves completion. This turns an abstract AI-readiness project into a set of testable requirements.

    Make important pages retrievable without guesswork

    A page is not agent-ready merely because it looks correct in your browser. Your browser may have cookies, cached scripts, a logged-in session, and enough processing time to assemble the page after the initial response. A fresh machine client may have none of those advantages.

    Test every priority URL from a clean, logged-out session. Inspect the returned HTML as well as the rendered screen. The page title, primary heading, main answer, relevant entity name, and essential links should be available without requiring a person to reveal them through hover effects, tabs, or visual-only controls. When a fact is central to the page, do not assume every client will execute and wait for the same JavaScript path as a full browser.

    • Confirm that the preferred URL returns a successful response and does not enter a redirect loop, soft-error state, consent loop, or challenge page.
    • Review robots.txt, meta robots directives, and the X-Robots-Tag together. An accidental conflict can make an otherwise public page unavailable. Robots directives are discovery instructions, not security controls, so private information still belongs behind real authentication.
    • Use one canonical URL for each primary resource. Internal links, canonical tags, redirects, and the XML sitemap should agree on that URL.
    • Keep the sitemap focused on live, canonical pages that you actually want discovered. Remove obsolete, redirected, private, and erroring URLs rather than asking machines to sort through them.
    • Link important pages through ordinary crawlable navigation. Descriptive link text such as “Enterprise pricing” carries more meaning than repeated links labeled “Learn more.”
    • Provide an HTML version of essential facts that otherwise live only in an image, video, downloadable document, or interactive widget.
    • Test firewall, bot-management, content-delivery, and rate-limit rules with a fresh client. Record whether a failure comes from the application or from an infrastructure layer in front of it.
    • Never weaken authentication to make an agent test pass. Keep protected data protected and expose only the public information or authorized interface the task genuinely requires.

    A useful retrieval record includes the requested URL, response status, final URL after redirects, declared canonical, applicable robots directives, and whether the required facts appeared in the response. A screenshot can confirm appearance, but it cannot replace those checks.

    Make the page’s meaning explicit in content and JSON-LD

    An abstract machine agent connects directly to a central web page shown in visible-content, semantic, and linked-data layers within an orderly site structure.

    Once a machine can retrieve a page, it still has to identify what the page describes and which claims belong together. Ambiguity usually enters through inconsistent naming, missing qualifiers, stale duplicates, and structured data that says something different from the visible page.

    Give each priority page a clear job. Put the direct answer near the point where the page establishes the question or offer, then supply the evidence, conditions, and alternatives a reader needs. Do not force the machine to combine fragments from a feature grid, tooltip, footer, and separate policy page just to understand the basic proposition.

    • Name the entity in full before relying on abbreviations or pronouns. If two products, locations, plans, or organizations have similar names, state the distinction on the page.
    • Attach qualifiers to the claim they modify. Geography, currency, billing period, eligibility, availability, effective date, tax treatment, shipping limits, and plan restrictions should not be left to implication.
    • Use stable identifiers where your operation already has them, such as a product code, plan name, location identifier, or internal service name. Keep the same identifier across templates, feeds, and structured data.
    • Choose an authoritative home for reusable facts such as the legal organization name, support contact, returns policy, or service-area definition. Other pages should link to or consistently reproduce that truth.
    • Update, redirect, remove, or clearly label stale pages. Two accessible pages that make incompatible claims create an interpretation problem even when only one appears in navigation.
    • Show ownership and maintenance information where it helps a reader judge the claim, such as an author, responsible team, publication date, or last reviewed date. Do not add decorative dates that are unrelated to a substantive review.

    Use JSON-LD to restate and connect meaning that is already visible. Select the most specific appropriate schema type for the resource, such as Organization, Product, Service, Article, or BreadcrumbList. Treat the type as a description of the actual page, not as a keyword target.

    • Make names, URLs, prices, availability, dates, and identifiers agree with the visible content.
    • Give important entities stable @id values and reuse those identifiers when another object refers to the same entity.
    • Connect related objects deliberately. An article’s publisher, a product’s brand, and a service’s provider should resolve to the organization you actually mean.
    • Include only properties you can support and maintain. An empty or guessed field adds ambiguity rather than clarity.
    • Validate syntax after template changes, then inspect the generated object for meaning. Syntactically valid markup can still describe the wrong entity or carry stale values.
    • Do not use structured data to make claims that a person cannot verify on the page. Markup cannot repair inaccessible, contradictory, or inaccurate content, and it does not guarantee inclusion in an AI answer.

    The final check is simple: read the visible page and the JSON-LD side by side. If they would lead a careful reader to different conclusions, the page is not ready.

    Treat agent actions as controlled transactions

    A transaction object passes through guarded verification, review, execution, and confirmation chambers while a duplicate action token is diverted into a holding loop.

    Retrieving a shipping policy is a read. Changing an address, booking an appointment, placing an order, publishing content, or deleting data is a write. Your design should preserve that boundary even when the same assistant handles both parts of the journey.

    Public facts should not require authentication without a business reason. Actions that expose personal data or change state should require an authenticated, authorized user. Do not create a machine-only shortcut around the permission model used by your human interface.

    • Use real links, buttons, and form controls with persistent programmatic names. An icon, color change, or visual position alone is not a dependable instruction.
    • Give every field a label and every validation failure an actionable message. State what is missing or invalid and preserve valid input so the task can continue.
    • Show prerequisites and consequences before submission. Required documents, inventory constraints, cancellation terms, units, time zones, and final charges belong before the committing action.
    • Require review or explicit user confirmation before consequential actions involving payment, publication, deletion, cancellation, or a binding reservation. Automation is not a reason to remove a safety boundary.
    • Make retries safe. If a client repeats a request after a timeout, the system should not silently create duplicate orders, bookings, messages, or records.
    • Return an unambiguous result after submission. The response should state whether the action succeeded, failed, remains pending, or requires another step, along with the relevant record or transaction identifier.
    • Keep errors distinct from success states. A generic page refresh, disappearing modal, or disabled button does not prove what happened.
    • Apply the least privilege needed for the requested task. Scope credentials, sessions, and connected tools so that a narrow action does not grant unrelated access.
    • Log enough context to investigate a failure or duplicate action, while avoiding unnecessary capture of personal data, credentials, or sensitive form contents.

    Test consequential paths in a staging environment or with a non-destructive mode whenever possible. If a production check could charge money, delete data, publish material, or create a real reservation, use an authorized test path rather than discovering the guardrails through a live transaction.

    Measure readiness from fetch to business outcome

    Referral traffic is useful, but it is not a complete AI-search scorecard. A system may use your information without sending a click, while a detected visit may still land on an inaccurate or unusable page. Keep the stages separate so you know which problem you are fixing.

    • Availability: Can a clean client retrieve the preferred page, and are canonical and robots signals aligned?
    • Comprehension: Can the required answer and its qualifiers be extracted from the visible content? Do the structured data and page agree?
    • Representation: Does a fixed set of relevant prompts produce an accurate description, mention, or citation on the AI surfaces you monitor? Record the prompt, surface, location or account context, date, output, and cited URL so later checks are comparable.
    • Referral: Which detectable AI referrals reach the site, where do they land, and do they engage with the intended next step? Treat missing referral data as unknown, not as proof that your content was never used.
    • Outcome: Do those visits or assisted journeys produce the qualified lead, completed task, sale, subscription, support resolution, or other result the page exists to support?

    Create a worksheet with a row for each priority intent. Include the authoritative URL, approved answer, required fields, expected entity, permitted action, passing condition, owner, last test date, observed output, and remediation status. A useful AEO system of record should show where performance is strong and why, not merely accumulate screenshots and isolated visibility scores.

    Establish a baseline before changing templates or access rules. Rerun affected journeys after changes to navigation, rendering, structured data, robots directives, authentication, forms, firewall policy, or core content. Keep the prompt and acceptance criteria fixed when you want a meaningful comparison; create a new test when the underlying intent changes.

    Key takeaways

    • AI-agent readiness has four practical layers: retrieval, interpretation, safe action, and measurement.
    • A passing visual check is not enough. Inspect the response, redirects, canonical, robots directives, rendered content, and required facts.
    • Visible content and JSON-LD must describe the same entity with the same claims, identifiers, and qualifiers.
    • Read access and write access need different controls. Consequential actions require authorization, confirmation, retry protection, and an explicit final state.
    • Measure fixed intents across availability, comprehension, representation, referral, and outcome instead of treating traffic as the whole result.
    • Technical readiness improves eligibility and reduces ambiguity, but it cannot guarantee ranking, citation, recommendation, or agent selection.

    Start with a revenue page, a policy page, and a consequential conversion path. Fetch them logged out, compare their visible facts with their JSON-LD, complete the permitted action in a safe environment, and record every point where the result becomes ambiguous. Fix those failures before expanding the audit across the rest of the site.

    References


  • How to Build Search Visibility for AI Agents and Answers

    How to Build Search Visibility for AI Agents and Answers

    You can rank in conventional search and still be absent when an AI system assembles an answer. The missing piece is often not another keyword. An agent has to reach your content, isolate the relevant passage, connect it to the right entity and decide that the claim is clear enough to reuse.

    Treat that sequence as a visibility pipeline. When you control access, extraction, delivery and measurement separately, you can diagnose why a page is missing instead of making broad content changes and hoping one of them works.

    Key takeaways

    • Set separate policies for model-training crawlers and agents that retrieve information for live answers. Blocking a vendor name broadly can block the function you actually want.
    • Make the core answer understandable in raw HTML, then use semantic sections and accurate structured data to reduce extraction ambiguity.
    • Keep titles, canonicals, essential metadata and critical structured data early in the HTML response. A page that renders correctly in your browser can still present an incomplete document to a crawler.
    • Use pull crawling for durable pages, push discovery for important updates, machine-readable delivery for structured facts and MCP access when an agent genuinely needs current data.
    • Measure bot access, extracted content, citation share and business outcomes as separate signals. Referral traffic alone cannot tell you whether generative visibility improved.

    Build a five-entry visibility pipeline

    Traditional search workflows often compress discovery, indexing and ranking into one mental model. Generative systems add retrieval, passage extraction, entity annotation and answer assembly. Your content can enter that process through five distinct routes.

    Entry routeWhat it doesWhere it fits
    Pull crawlingA crawler discovers and fetches a public URL on its own schedule.Evergreen pages, documentation, category hubs and other durable web content.
    Push discoveryYou notify a participating system that a URL is new or has changed.Pages whose value depends on being discovered soon after publication or revision.
    Push dataMachine-readable facts are delivered directly instead of relying only on page extraction.Structured catalogs, feeds and other data with a defined receiving system.
    MCP accessAn agent requests current information through a Model Context Protocol connection.Data that changes too quickly to be represented reliably by an occasional crawl.
    Ambient entryA system recommends or introduces information without a conventional explicit search query.Brand and entity discovery influenced by consistent, well-annotated information.

    These routes are complementary, not maturity levels. An evergreen explainer usually needs a clean crawl path more than an MCP server. A changing first-party dataset may need a direct machine interface because a cached page can become stale between fetches. Map each important content type to the least complicated route that preserves its accuracy.

    All five routes eventually depend on annotation: the system has to associate a fact with the correct organization, product, person, place or topic. That is why delivery alone is insufficient. Conflicting names, unclear ownership, inconsistent dates or schema that disagrees with visible copy can weaken the content after it has been successfully fetched.

    Separate training permission from live-answer retrieval

    The label AI bot hides several different jobs. The same provider may use one user agent for model training and another for retrieval or search. Current crawler distinctions include separate training, crawling and live-search identities:

    • OpenAI: GPTBot is associated with training, while OAI-SearchBot is associated with search and retrieval.
    • Anthropic: ClaudeBot is associated with training; Claude-User and Claude-SearchBot serve retrieval or search functions.
    • Perplexity: PerplexityBot is the crawler identity, while Perplexity-User is associated with user-driven searching.

    Decide what you want before editing robots.txt. For each user agent, record whether public editorial pages, product information, support documentation and downloadable resources should be accessible. Make the training decision independently from the retrieval decision. A company can decline training access while still choosing to make public pages available to a search-oriented agent.

    A narrowly scoped rule can look like this:

    User-agent: GPTBot
    Allow: /public/
    Disallow: /private/

    Do not use robots.txt to protect confidential information. It is a crawler directive, not an authentication system. Private, customer-specific and administrative content needs server-side access control whether a path is disallowed or not.

    After deployment, inspect server logs by user agent. Confirm that the intended crawler reaches the intended URLs, receives a successful response and can fetch resources needed to interpret the page. A syntactically tidy policy is not evidence that the access path works.

    Use llms.txt as a map, not a dependency

    The emerging llms.txt convention can give agents a concise map of important links, while llms-full.txt can aggregate larger amounts of text into one machine-oriented resource. Adoption is not universal, so neither file should be the only way to discover or understand your content.

    If you publish llms.txt, generate it from the same canonical content inventory used by your sitemap and navigation. Include public, authoritative URLs rather than every filtered, duplicated or campaign-specific variation. Keep the file synchronized when pages move or claims change. It does not override robots.txt, authentication, canonical signals or the content of the page itself.

    Make each page fragment-ready

    A digital page separates into modular content cards while an AI lens selects one card and links it to a network of entities.

    An agent rarely needs every sentence on a long page. It needs a passage that answers the current question without losing essential qualifications. Your job is to make that passage easy to locate and safe to reuse.

    Build each important section in this order: state the answer, name the entity it applies to, add the condition or limitation, then provide the supporting explanation. Put exceptions beside the claim they qualify. If a warning appears several sections later, extraction can separate it from the advice it was meant to constrain.

    • Use a descriptive heading that reflects the question or decision addressed by the section.
    • Answer immediately beneath that heading instead of opening with scene-setting copy.
    • Name the product, organization, method or audience inside the passage. Avoid relying on vague references such as it, they or this solution when the fragment could be retrieved alone.
    • Keep definitions stable. Do not alternate between near-synonyms if they could make one entity look like several unrelated entities.
    • Use lists for steps and criteria, and tables only when rows and columns express a real comparison.
    • Link supporting detail close to the claim it supports rather than collecting all evidence in an unrelated footer.

    Semantic HTML helps establish those boundaries. Use <article> for the primary work, <section> for coherent subtopics and <aside> for genuinely supplementary material. This does not guarantee selection, but it gives crawlers a clearer representation than a page composed entirely of generic containers.

    Structured data should agree with the visible page. Use the schema type that matches the content, identify the same entities named in the copy and omit properties you cannot support on the page. JSON-LD can reduce ambiguity; it cannot repair an unclear claim or turn unsupported markup into trustworthy information.

    Put critical information within the fetched bytes

    Payload order matters when a crawler stops before the document ends. Googlebot fetches up to 2MB for an individual non-PDF URL, with the HTTP response headers included in that limit. When an HTML response exceeds the threshold, the downloaded portion is passed to indexing and the Web Rendering Service as though it were the complete file. Bytes after the cutoff are not fetched, rendered or indexed. PDFs have a higher 64MB limit.

    The Web Rendering Service can fetch referenced resources separately and execute JavaScript like a modern browser, so external scripts and styles do not consume the parent HTML document’s byte allowance. That is a reason to remove oversized inline payloads, not a reason to hide the central answer behind unnecessary client-side execution.

    Do not generalize Google’s exact limits to every AI crawler. Use them as a concrete reminder that a page visible in your browser is not necessarily the same document a bot received or completed.

    • Inspect the raw server response as well as the rendered page.
    • Place the title, canonical link, essential meta tags and critical structured data early in the HTML.
    • Move large CSS and JavaScript payloads into external resources where appropriate.
    • Remove duplicated navigation, serialized application state and other bulky inline material that delays the primary content.
    • Verify that the central answer appears without requiring a click, expansion control or user-specific session.
    • Compare raw and rendered text so you know what depends on JavaScript.

    Response performance belongs in the same audit. When a server cannot deliver resources efficiently, fetchers may slow their activity to avoid adding load, which can reduce crawl frequency. Review latency alongside status and crawl counts instead of interpreting fewer requests as a content-quality judgment.

    Add push paths where freshness changes the answer

    Publishing and waiting remains reasonable for stable content, but it is incomplete when discovery speed or data freshness affects whether an answer is useful. Add proactive delivery in layers, after the public URL and its canonical content are sound.

    1. Preserve the pull foundation. Give every durable page a crawlable canonical URL, sensible internal links and an accurate sitemap entry. Push mechanisms should supplement this foundation.
    2. Notify systems about meaningful URL changes. Bing’s IndexNow can accelerate discovery by telling participating systems that content is new or updated. Treat the notification as an entry signal, not a substitute for a fetchable and interpretable page.
    3. Provide machine-readable data when a receiver supports it. Use a structured feed or direct data connection for facts that should not depend on extracting prose. Define one authoritative source so the feed and public page do not contradict each other.
    4. Use MCP for genuinely current interactions. An MCP connection is justified when an agent needs information that could become stale between crawls. Specify what each tool exposes, which fields are authoritative, how errors are represented and who may call it. Do not create an MCP layer merely to duplicate static editorial pages.
    5. Strengthen the inputs to ambient discovery. Keep names, descriptions and relationships consistent across your first-party content and machine-readable outputs. Ambient recommendations are not a submission box you can force; they depend on whether systems can confidently recognize and contextualize the entity.

    Use a freshness test when choosing the route: if an older value would make the answer materially wrong, evaluate direct data or MCP access. If the information remains accurate until the next normal crawl, keep the architecture simple and focus on extraction quality.

    Centralize the underlying data before adding several delivery methods. Otherwise a page, feed and agent tool can expose three different versions of the same fact. Faster delivery only makes that inconsistency spread sooner.

    Measure access, citations and outcomes separately

    Three parallel visual channels depict content access, citation connections, and human outcomes using abstract gateways, fragments, and symbols.

    A click-only dashboard cannot explain generative visibility. An answer may cite you without sending a visit, retrieve your page without using it or mention your brand while linking elsewhere. A practical GEO technical audit combines citation share, log analysis and zero-click behavior rather than collapsing them into one traffic number.

    • Access: Group server requests by user agent. Record which important URLs were requested, whether they were allowed, how the server responded and whether latency changed.
    • Extraction: Compare the raw response with the rendered page. Confirm that the answer, entity name, qualifications, canonical and structured data are present and mutually consistent.
    • Interpretation: Check whether headings, visible copy, schema and linked canonical resources describe the same entity and claim. Flag conflicting names, dates, ownership or status.
    • Visibility: Maintain a fixed set of representative questions. Citation share is the portion of checked answers that cite your domain or a tracked URL. Record the engine, model, query, cited page and claim so later checks remain interpretable.
    • Outcome: Track identifiable AI referrals and their business actions, but keep citations as a separate measure. No referral does not prove that the system ignored you; the generated answer may have satisfied the user without a click.
    • SEO context: Compare changes in AI visibility with domain metrics, backlink profiles, keyword research and organic-search data. This helps distinguish an agent-access problem from a broader authority, demand or search-performance problem.

    The combination of signals points to the next action. No crawler requests usually directs you toward discovery or access controls. Successful fetching with no usable passage points toward rendering or extraction. Clear extraction with weak citation presence points toward annotation, relevance or authority. More citations without more referrals may reflect zero-click use rather than failure.

    Keep the prompt set and measurement method stable while evaluating a change. If you replace the questions, engines and success definition at the same time, the before-and-after comparison cannot tell you which intervention mattered.

    Start with one content cluster tied to a real business or reputation goal. Verify crawler policy, raw HTML, semantic sections and structured data; then add IndexNow, a structured feed or MCP only where the content’s freshness requires it. Record access and citations before and after the change. Once that evidence chain works, make it part of the publishing workflow for every similar page.

    References


  • TurboQuant Search Acceleration: An SEO and GEO Action Plan

    TurboQuant Search Acceleration: An SEO and GEO Action Plan

    You may be wondering whether TurboQuant requires an immediate SEO response. The short answer is no: it is not an announced ranking update, and there is no disclosed evidence that Google Search is using it in production.

    It still matters. TurboQuant targets a constraint that shapes semantic search, retrieval-augmented generation, and AI answer systems: how much meaning a system can search within a limited memory and response-time budget. If that constraint loosens, more content can become practical to retrieve. Your job is to make sure your content remains understandable, competitive, and worth citing when the candidate pool grows.

    TurboQuant changes retrieval economics, not your ranking brief

    Semantic search systems commonly convert documents, passages, products, images, or other objects into vectors. A vector is a numerical representation that places related meanings near one another. When someone asks a question, the system can retrieve nearby vectors even when the wording in the query does not exactly match the wording in the content.

    The difficulty is scale. Detailed vectors consume memory, moving them through processors takes time, and building or updating large searchable indexes can be expensive. A system may therefore search only a restricted candidate set before another model ranks, filters, or summarizes the results.

    TurboQuant addresses that infrastructure problem by compressing vectors while preserving a close approximation of their original relationships. It mathematically rotates the data to make it easier to pack efficiently, then carries a 1-bit error-correction signal intended to reduce mistakes introduced by compression. Google also associates the approach with substantially lower memory requirements and nearly zero indexing time.

    That is important, but it is not the same as a new ranking factor. TurboQuant does not tell a search engine which page is trustworthy, which claim is current, which source deserves a citation, or which answer best satisfies a user. It makes one stage of the pipeline more efficient: locating semantically similar candidates.

    Keep the distinction clear in planning meetings. Retrieval asks, “Which items might be relevant?” Ranking and answer generation ask, “Which of those items should be used, in what order, and for what purpose?” Faster retrieval can affect the first decision without replacing the others.

    A larger candidate pool changes what can be discovered

    Scanning beams illuminate relevant capsules and document-like tiles across a vast abstract archive, with selected items grouped in the foreground.

    A search or AI system operates inside practical limits. It has finite memory, compute capacity, and time to produce a response. If vectors become cheaper to store and faster to search, the system could examine a broader collection of candidates within those limits. That could include more documents, more passages within each document, or more specialized material that would otherwise sit outside an economical retrieval set.

    This does not guarantee that AI answers will cite more websites. A larger candidate pool can increase opportunity and competition at the same time. Your page may become easier to retrieve, but so may a more precise product manual, a better-supported explanation, or a specialist page that previously sat too deep in the corpus.

    The likely strategic shift is from winning inside a narrow set of obvious pages to surviving comparison against a deeper set of semantically related passages. Thin content becomes more exposed in that environment. Repeating the target phrase does little when the system can find pages that answer the underlying question with clearer entities, stronger evidence, and better-qualified claims.

    Nearly zero indexing time could also make rapid ingestion more practical for systems built around TurboQuant. Do not turn that possibility into a claim about Google Search freshness. Crawling, rendering, canonicalization, quality assessment, and index-selection policies remain separate processes. Faster vector indexing cannot make an uncrawled or rejected page searchable.

    The same logic applies outside public search. An organization operating a large retrieval-augmented generation system could use aggressive vector compression to reduce memory pressure or update a knowledge index more quickly. If you own that system, TurboQuant is an engineering option to evaluate. If you publish content that such systems may ingest, the more durable task is to improve the material being represented by those vectors.

    Optimize the passage before you optimize the embedding

    Disordered translucent fragments are reorganized into clear modular content blocks before becoming compact glowing vectors.

    You usually cannot control which embedding model, quantization method, retrieval threshold, reranker, or answer model a third-party search system uses. You can control whether a passage contains enough information to be correctly interpreted after it is separated from the rest of the page.

    Start with answer-bearing passages. A useful passage names the subject, resolves the question, and carries the qualification that prevents the answer from becoming misleading. Avoid openings that rely on nearby headings or pronouns to supply all the context. “It depends on the plan” is fragile. “Indexing frequency depends on the crawler, the site’s change rate, and whether the URL remains eligible for indexing” retains meaning when retrieved alone.

    Do not force every paragraph into a rigid template. The goal is semantic completeness, not robotic prose. Use the following checks where a passage contains a definition, recommendation, comparison, process, limitation, or factual answer:

    • Name the entity. Use the full product, organization, method, or standard name before relying on shorthand. This reduces ambiguity between similarly named entities.
    • State the relationship. Make it explicit whether the entity creates, supports, replaces, depends on, conflicts with, or applies to something else.
    • Carry the qualifier. Keep version, platform, audience, condition, and scope close to the claim they limit.
    • Put evidence beside the claim. A citation attached to a vague paragraph is less useful than a link on the specific statement it supports.
    • Separate fact from inference. Use direct language for documented behavior and conditional language for plausible consequences. TurboQuant could support broader retrieval; that does not establish its use in Google Search.

    Next, cover the relationships around the central entity. A page about TurboQuant should not merely repeat that it accelerates vector search. A useful treatment connects compression to memory use, index construction, similarity accuracy, candidate retrieval, reranking, and downstream answer generation. Those relationships help a system match the page to different formulations of the same underlying problem.

    This is semantic breadth, not permission to inflate word count. Add a section only when it resolves a real adjacent question. Remove a section when it paraphrases a claim already made. Efficient retrieval can expose comprehensive content, but it can also expose padding.

    Make structured data support the same meaning

    JSON-LD and schema markup can reinforce entity identity and relationships, but they do not rescue unclear visible content. Treat structured data as a machine-readable restatement of the page, not a hidden layer where you make claims the reader cannot see.

    For each important page, compare the visible content with its structured data. The page title, main entity, author or organization, publication information, and any explicitly marked questions or steps should agree. If the markup identifies one subject while the body drifts into several loosely related topics, compression is not the problem. The underlying document is ambiguous.

    Internal links deserve the same discipline. Use anchor text that describes the destination’s role rather than generic commands such as “learn more.” Link from a broad concept to the page that resolves its important subtopic, and link back where the relationship helps the reader. This creates navigable context for crawlers and people without pretending that internal links directly control vector proximity.

    Technical eligibility remains the floor. Confirm that the canonical URL is crawlable, the primary answer appears in rendered HTML, internal links reach the page, and structured data matches the visible material. A brilliantly written passage cannot enter a retrieval pipeline that never receives or accepts the page.

    Run a retrieval-readiness audit you can repeat

    Do not create a TurboQuant-specific score. You have no public implementation details that would make such a score credible. Audit the properties that remain useful across embedding models and compression methods.

    1. Select a representative page from each important topic cluster. Include the pages that answer commercial, informational, troubleshooting, and comparison questions rather than auditing only your highest-traffic URLs.
    2. Build query families around user intent. For each page, write the direct question, a paraphrase, a problem-first version, and a version that names a competing approach. This reveals whether the page answers the concept or merely repeats one keyword pattern.
    3. Locate the passage that should satisfy each query. If you cannot point to a self-contained answer, rewrite the relevant section. Do not assume the title or surrounding page will repair an incomplete paragraph.
    4. Check entities and qualifiers. Mark unclear pronouns, unexplained abbreviations, missing versions, unsupported superlatives, and conditions placed far away from the claims they govern.
    5. Verify evidence and provenance. Link important claims to their originating authority when available. Remove assertions whose confidence exceeds the evidence.
    6. Compare visible content, metadata, and JSON-LD. Resolve conflicts in names, dates, page purpose, authorship, and entity type. Consistency makes the page easier to interpret; markup volume does not.
    7. Record answer-surface outcomes. For the query families you monitor, note whether your URL appeared, whether it was cited, which passage was used, and which alternative sources won. Ordinary rank position alone cannot show how an AI answer assembled its response.

    When a competing page is selected, diagnose the difference at the passage level. Ask whether it gave a more direct answer, named the relevant entity more clearly, carried a necessary qualification, supplied stronger evidence, or addressed an adjacent intent you omitted. Those observations produce useful editorial work. Guessing at an undisclosed quantization configuration does not.

    Keep infrastructure tests separate from content tests if you operate your own vector search system. Engineering teams can compare memory use, indexing cost, latency, and retrieval quality under compression. Editorial teams should evaluate answer completeness, ambiguity, evidence, and citation suitability. Combining both into one vague “AI optimization” metric makes it impossible to tell which layer improved.

    Key takeaways

    • TurboQuant compresses vectors to reduce memory pressure and accelerate similarity search, with a 1-bit signal designed to correct small compression errors.
    • It is retrieval infrastructure, not a disclosed Google Search ranking factor or confirmed production deployment.
    • Cheaper retrieval could let an AI system search a broader candidate set, but broader access also exposes your content to more competitors.
    • Your durable advantage is a crawlable page with self-contained passages, unambiguous entities, nearby qualifications, and evidence attached to specific claims.
    • Use JSON-LD to reinforce visible meaning. Do not use it to compensate for vague writing or to introduce claims absent from the page.
    • Measure citation and passage selection across query families, not just traditional rankings for one exact keyword.

    Your next move is modest: choose one important topic cluster and run the retrieval-readiness audit before rewriting the entire site. Fix the places where meaning breaks when a paragraph stands alone. That work remains valuable whether TurboQuant reaches public search, stays inside other AI systems, or inspires a different compression method.

    References


  • How to Make Content Machine-Readable for AI Search

    How to Make Content Machine-Readable for AI Search

    You can publish a technically clean page, answer the right question, and still give an AI search system a passage it cannot safely reuse. The problem often appears after retrieval: the extracted sentence no longer identifies its subject, a price loses its billing condition, or a claim depends on context several paragraphs away.

    The fix is not more copy or a larger pile of schema. You need answer blocks that retain their meaning when separated from the page, plus structured data that identifies the same entities and relationships without contradiction.

    Key takeaways

    • Open each important section with a direct answer of roughly 40 to 60 words, then add qualifications, evidence, and next steps.
    • Name the entity inside important claims. Do not make a retriever resolve vague references such as “it,” “they,” “this service,” or “the platform.”
    • Keep scope, units, eligibility, geography, billing terms, and time periods in the same sentence as the fact they qualify.
    • Use JSON-LD to connect Organization, Person, Article or BlogPosting, Product, and Service entities through stable @id values.
    • Treat schema as comprehension infrastructure. Schema can reduce ambiguity, but schema alone does not guarantee an AI citation.
    • Test the live, rendered URL. Perfect prose and valid markup cannot help a system that receives an empty shell, blocked response, or incomplete page.

    Design the passage an AI system needs to retrieve

    Machine-readable content states who or what a fact concerns, how the relevant entities relate, and which conditions limit the claim. It uses descriptive headings, self-contained sentences, accessible HTML, and consistent structured data. The objective is not robotic writing. The objective is preserving meaning when a useful passage is extracted from its original layout.

    An AI search pipeline does not need every word on your page to answer every query. A retrieval stage selects a limited amount of relevant material before a model composes its response. A rough working estimate of about 380 words from a page illustrates the pressure this places on information density. That estimate is not a universal page-length limit, and you should not cut a useful page to 380 words. It is a reason to make every answer block earn its place.

    Build each answer block in this order:

    1. Use a query-shaped heading. “How long does migration take?” gives the passage more retrieval context than “Migration overview.”
    2. Answer before explaining. Put the conclusion, entity, and main condition in the first paragraph. Do not spend the opening on category history or a broad market trend.
    3. Add the conditions that could change the answer. Identify the affected plan, customer type, location, version, time period, or eligibility rule.
    4. Provide extractable support. Use a short list or a genuine comparison table when the evidence contains several distinct fields.
    5. End with the decision or next action. Restate the practical implication without copying the opening sentence word for word.

    A strong opening paragraph should answer one question completely enough to quote, but not pretend the answer has no qualifications. For example, a software migration section should identify what is being migrated, which starting environment the estimate covers, what the estimate includes, and which dependency can extend it. Moving those conditions into a distant note makes the opening easier to read but less safe to extract.

    Front-loading does not mean repeating the target phrase or turning every heading into a minor variation of the same question. Give each section a distinct retrieval job. One section can define the service, another can establish eligibility, another can explain cost, and another can describe implementation. If two sections would return the same answer, merge them.

    Write portable claims, not context-dependent fragments

    A complete information module and its linked condition, unit, time, and source symbols travel together inside a transparent capsule as incomplete fragments dissolve behind it.

    AI retrieval breaks a page into passages. A sentence that feels clear after three introductory paragraphs may become ambiguous when it is the only sentence returned. The most important facts therefore need to work as portable assertions.

    The practical language pattern is a semantic relationship: subject, predicate, and object, followed by any conditions that control the claim. “The Atlas Enterprise plan supports SAML single sign-on for accounts managed through the enterprise console” identifies the plan, states the relationship, names the capability, and preserves the relevant scope.

    The following examples illustrate editing patterns rather than claims about real products or performance:

    ProblemFragile wordingMore extractable wording
    Missing subjectIt also supports SSO.The Atlas Enterprise plan supports SAML single sign-on.
    Entities without a relationshipSEO, paid search, content marketing.The agency uses paid-search query data to select topics for SEO landing pages.
    Detached conditionDelivery takes two business days. Restrictions apply.Metro delivery takes two business days for orders placed before the daily cutoff.
    Unsupported evaluationOur process is more reliable.The migration process requires a crawl export, redirect map, and post-launch validation.

    You do not need to remove every pronoun from the page. That would make the writing repetitive and unnatural. Apply the isolation rule to sentences carrying a definition, number, comparison, product attribute, policy, recommendation, or other claim that a search system might quote. Supporting transitions can still use normal prose.

    Use this editing sequence on every important claim:

    1. Name the subject. Replace “it,” “this,” or “our solution” with the brand, product, plan, person, process, or policy that owns the fact.
    2. Choose a relationship verb. Prefer precise verbs such as includes, costs, requires, supports, applies to, publishes, authors, or is offered by.
    3. Name the object or value. State the feature, amount, requirement, organization, audience, or outcome connected to the subject.
    4. Attach the boundary. Keep the unit, currency, billing period, location, version, audience, and time frame beside the claim.
    5. Remove unproved decoration. Words such as leading, seamless, robust, revolutionary, and best-in-class add confidence without adding a retrievable fact.

    Then run the isolation test. Copy a sentence from the middle of the section into a blank document. Ask whether a reader can identify the subject, relationship, object, and applicable conditions without seeing the preceding sentence. If any answer is no, repair the sentence rather than assuming the heading will always travel with it.

    Read the repaired paragraph aloud as a final check. Machine clarity should come from explicit relationships, not from repeating the full product name in every line. Once the key claim is anchored, nearby explanatory sentences can vary their rhythm.

    Build a connected entity graph instead of isolated schema

    A webpage plane connects to several symbolic entities, with a matching layer of structured-data nodes aligned beneath the same network.

    JSON-LD gives machines a second representation of facts that people can already see on the page. Its most useful role in AI search is disambiguation: identifying which organization published the page, which person wrote it, which product owns a price or feature, and how those entities connect.

    Google Search confirmed in April 2025 and Microsoft Bing confirmed in March 2025 that structured data helps their search and AI systems understand content. The position is less certain for ChatGPT, Perplexity, and other AI search products because their public crawling and extraction descriptions have not established whether page-level JSON-LD is preserved and used throughout retrieval.

    That uncertainty matters. Sites with extensive schema did not consistently earn more citations in a December 2024 citation comparison. A separate February 2024 extraction experiment found that LLMs handled defined, structured fields more accurately than open-ended input. The defensible conclusion is narrow: structure can improve interpretation and extraction accuracy when a system uses it, but schema presence is not a citation switch.

    Connect the entities that establish identity and responsibility

    A page-by-page schema object often repeats names without proving that the “Jane Doe” on one page is the same person elsewhere. Stable @id values let multiple pages refer to one persistent entity. Build the graph in this order:

    1. Create one Organization node. Give the brand a permanent @id, such as the canonical domain followed by #organization, and reuse that identifier across the site.
    2. Create one Person node per author. Give each author a stable @id and connect the Person to the Organization through worksFor when that relationship is accurate.
    3. Create an Article or BlogPosting node for the page. Connect author to the Person @id and publisher to the Organization @id. Keep the headline and other properties consistent with the visible page.
    4. Connect commercial entities to their owner. Use Product or Service where appropriate, and connect the offer or service to the responsible Organization rather than repeating an unlinked organization name.
    5. Use FAQPage only for genuine visible questions and answers. Markup should describe content available to the reader, not create a hidden answer layer that says something different.

    Maintain a small entity registry outside individual page drafts. Record each entity’s canonical name, @type, @id, owner, and the templates that reference it. This prevents an author from acquiring a new identifier on every article and stops a brand from being represented as several anonymous Organization objects.

    Keep prose, visible data, and JSON-LD in agreement

    Machine readability fails when the page contains several competing versions of the same fact. A product name in the heading, a shorter name in the body, a legacy name in JSON-LD, and a different name in navigation create an entity-resolution problem that more markup will not solve.

    • Use the same canonical entity name in visible copy and structured data, while reserving abbreviations for clearly introduced aliases.
    • Assign one stable @id to each real entity and reference that ID instead of recreating nested anonymous copies.
    • Make each attribute belong to the correct node. A price belongs to an offer or product context; authorship belongs to the content item and Person; publishing responsibility belongs to the Organization.
    • Update visible content and JSON-LD together when a price, plan name, author relationship, or product status changes.

    Schema cannot compensate for an unsupported claim, weak topical coverage, or an inaccessible page. It can make a good page less ambiguous. That narrower job is still valuable because it is controllable and useful to platforms that consume structured data.

    Run a machine-readability audit before publishing

    Do not stop at a schema validator. Validation can show that the syntax fits a vocabulary, but it cannot tell you whether an extracted paragraph remains accurate or whether the live URL exposes the content an AI system needs.

    1. Test URL access. Open the live URL through an LLM agent or another crawler-like reader. Confirm that the primary answer, headings, author, and important attributes are present without a click, login, or client-side interaction.
    2. Test the page without its hero. Scroll until the banner and introductory layout disappear, then begin reading. Mid-page sections should identify their own topic instead of relying on the page title for all context.
    3. Test the opening answer. Read only the first paragraph under each important heading. Verify that it answers the heading and contains the primary entity and decisive condition.
    4. Test sentence isolation. Copy a factual sentence from the middle of each core section. Repair any missing subject, dangling pronoun, detached qualifier, or unexplained abbreviation.
    5. Test entity relationships. Identify the subject, relationship verb, and object in every claim you want quoted. A list of related keywords does not establish how those entities interact.
    6. Test structured-data continuity. Check that Organization, Person, content, Product, and Service nodes reuse their registered @id values and point to one another correctly.
    7. Test factual parity. Compare names, relationships, prices, eligibility rules, dates, and other attributes across visible copy and JSON-LD. Resolve conflicts before publication.

    Use a five-point editorial scorecard

    Give the page one point for each passing lens in this five-part utility check. A zero identifies an editing task; the total is not a predicted citation rate.

    • Structural fitness: Do headings create a clear hierarchy in which each section answers a distinct question?
    • Information density: Does each paragraph contribute a fact, condition, explanation, example, or decision rather than repeating a broad benefit?
    • Extractability: Can important statements survive without the preceding paragraph, visual layout, or an unresolved pronoun?
    • Entity completeness: Are the relevant people, organizations, products, services, attributes, and relationships explicitly named?
    • Natural language quality: Does the page remain clear and pleasant for a person after the entities and conditions have been made explicit?

    Separate this quality-assurance score from visibility measurement. URL access, sentence isolation, entity consistency, and markup continuity are conditions you can inspect directly. AI citations are non-deterministic outcomes. Measure them with a fixed set of real audience questions, and record the engine, prompt, date, cited URL, and answer context. A single appearance or disappearance is not enough to prove that one edit caused the change.

    We’d start with one page that already contains genuine expertise but buries its answer. Rewrite the first answer block, repair its portable claims, connect its entity graph, and load the live URL as an agent would. Once that page passes the audit, turn the successful structure into an editorial and schema template for the rest of the site.

    References


  • Essential Checks for a Seamless Website Migration

    Essential Checks for a Seamless Website Migration

    I’ve learned that website migrations often fail due to small oversights. That’s why I focus on reducing risks with thorough pre-launch, launch-day, and post-launch SEO checks.

    Website migrations can notoriously go awry, even with the best planning. I’ve seen rankings slip, traffic drop, and tracking break. Surprisingly, it’s usually the small oversights rather than complex technical issues that cause these problems.

    I approach website migrations with a staging process. The checks I perform during staging, on launch day, and in the few weeks following the launch are crucial. They often determine whether a migration stabilizes quickly or spirals into a long recovery project.

    Before Launch: Catch Issues on Staging

    I’ve found that most migration problems should be identified and resolved on the staging site. If issues make it to the live site, recovery tends to be slower and more uncertain. Here’s how I set myself up for success:

    Keep the Staging Site Private (Even from Crawlers)

    A common mistake I’ve encountered is making the staging site publicly indexable. Google crawling a staging environment can lead to duplicate content in search results, causing rankings to fluctuate and unfinished pages to be indexed.

    I make it a point to block crawlers from the staging site or protect it with a password to ensure it stays invisible to search engines until the live launch.

    It’s not just about the crawlers. I’ve seen ecommerce sites where customers found the staging site and tried to place orders, creating confusion and frustration internally.

    Take Benchmarks

    To help identify real issues rather than reacting to normal shifts, I always take a baseline. I record organic sessions, rankings, top landing pages, indexed pages, conversions, and site speed before moving to the new site.

    Identify Priority Pages

    For me, it’s crucial to focus on pages that drive traffic, revenue, or attract links. These need extra care during redirect mapping, content review, and testing, with special attention to internal links, redirects, and URL rules.

    Review Templates and Content Continuity

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    Templates are the backbone of a website, controlling titles, headings, metadata, and more. If templates break, similar problems can spread across countless pages. Here’s what I check:

    • Presence and accuracy of titles and headings.
    • Canonical tags that use full URLs and point to live pages.
    • Correctly transferred structured data.
    • Intact copy, images, and internal links.

    Launch Day: Verify Everything Works on the Live Site

    On launch day, preparation meets reality. I join my SEO, developer, and design teams to make sure what worked on staging works on the live site as well. Even small oversights can immediately impact rankings, traffic, and user experience.

    Test Redirects at Scale

    It’s not enough to spot-check. Every mapped URL should redirect correctly, without chains or loops, as they can slow down crawling and delay signal consolidation.

    Crawl the Live Site

    Immediately after the site goes live, I run a full crawl and compare the results to the staging crawl to spot any differences. I’m on the lookout for broken links, redirected internal links, missing pages, and server errors.

    Menüs, breadcrumbs, and in-content links should directly point to live URLs. Allowing internal links to rely on redirects adds unnecessary load and risk.

    After Launch: Monitor and Stabilize Performance

    I know that even with the best planning, surprises can emerge once search engines and real users start interacting with the site. Small errors missed on staging can suddenly affect rankings or traffic.

    Structured monitoring in the days and weeks post-launch is crucial. By catching issues early, I can ensure they don’t impact performance or user experience.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot