Have you ever wondered why your site isn’t getting the attention it deserves from AI crawlers? I know how frustrating it can be to feel overlooked in the digital world. Often, Cloudflare might be the culprit blocking access.
Let me guide you through diagnosing these issues, providing solutions, and optimizing your site for better LLM (Large Language Model) visibility. Together, we’ll ensure your site is primed for the AI-age and ready to capture its rightful place in search rankings.
An important URL is missing from Google, but Search Console isn’t giving you a clean explanation. Before you resubmit the page, rewrite it, or change sitewide settings, identify exactly where its visibility chain broke.
The useful question isn’t simply, “Is this page indexed?” You need to know whether Google discovered the URL, whether Googlebot could fetch it, whether the page was eligible for indexing, whether Google selected it for the index, and whether the data you’re reading is current. Those are different conditions with different fixes.
Google crawling and indexing: key takeaways
Crawling, indexing, and ranking are separate stages. Evidence from one stage doesn’t prove that the next stage succeeded.
Check the Page Indexing report’s last update before interpreting a change. The report normally trails activity by a few days and can experience longer reporting delays.
Diagnose one exact URL from the server response upward: access, robots rules, indexing directives, canonical signals, discovery paths, and Search Console status.
Use server logs and Search Console together. Logs tell you whether a request reached your server; Search Console tells you how Google classified the URL.
More bot requests do not automatically produce more indexed pages, rankings, referral traffic, or AI visibility.
Find the broken stage in the visibility chain
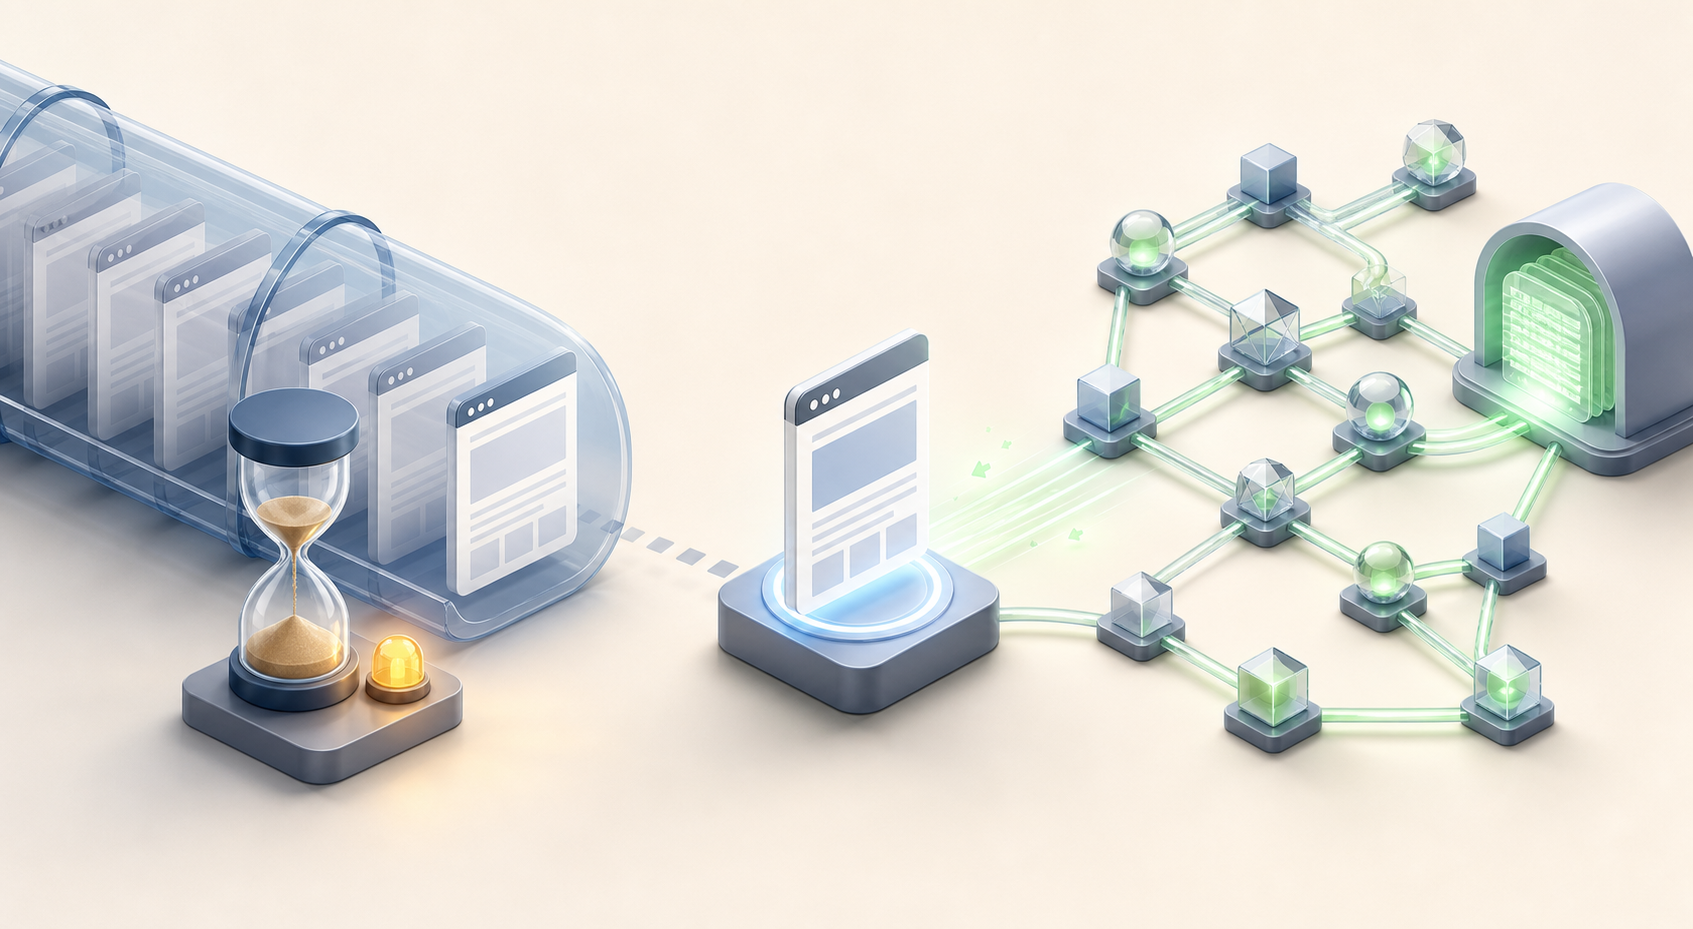
A page doesn’t move directly from publication to search results. It passes through a sequence, and a failure early in that sequence makes later optimization irrelevant. Work through these stages in order.
Discovery: Google needs a route to the URL. Internal links and XML sitemaps can provide that route. A URL that exists only in your CMS, an orphaned landing page, or a malformed link may never enter the normal discovery path.
Crawl permission: Googlebot must be allowed to request the URL and the resources needed to understand it. Check the applicable robots.txt user-agent group, authentication, firewall rules, CDN controls, and bot-protection settings.
Fetch success: Your server must return the intended content reliably. Inspect the response that a crawler receives, not merely what an administrator sees while logged into the CMS. Redirect loops, error responses, empty output, and challenge pages can all interrupt this stage.
Index eligibility: The fetched response must not contain an unintended noindex directive. Check both the HTML meta robots tag and the X-Robots-Tag HTTP header. Also verify that the page isn’t presenting a canonical URL that points somewhere else.
Index selection: An eligible page is a candidate, not a guaranteed index entry. Google may select another canonical, treat several URLs as duplicates, or decide not to retain the page. Repeated submission doesn’t resolve contradictory page-level signals.
Search visibility: Indexing makes a URL eligible to appear; it doesn’t guarantee impressions or rankings. If the URL is indexed, move the investigation to query relevance, content usefulness, internal prominence, competitive strength, and search-result presentation.
This sequence prevents a common diagnostic mistake: trying to improve content when Googlebot is blocked, or changing crawl settings when the page is already indexed and simply isn’t ranking. Label the failed stage before choosing the intervention.
Keep robots.txt and noindex conceptually separate. Robots.txt controls crawling. A meta robots or X-Robots-Tag noindex directive controls index eligibility after the directive is fetched. If you block a URL in robots.txt while also relying on a page-level noindex directive, Google may be unable to revisit the page and read that directive. Choose the control that matches the outcome you actually want.
Audit one URL in an order that preserves the evidence
Start with a specific URL, not a sitewide theory. Record the result of each check before changing anything. If you alter robots rules, canonicals, internal links, and content simultaneously, you lose the ability to tell which condition mattered.
Define the URL that should be visible. Write down its exact protocol, hostname, path, parameters, and expected canonical. Test the final destination rather than a shortened URL, tracking link, or redirecting variant.
Inspect the delivered HTTP response. Confirm that an anonymous request can reach the intended page and receives the expected successful response. Follow redirects and make sure they terminate on the correct URL. Check whether a CDN, consent layer, security product, or login requirement serves different content to automated requests.
Match the URL against robots.txt. Evaluate the rules for Googlebot, including the most specific applicable path. Don’t assume that a rule written for another crawler applies to Googlebot, or that a global rule is harmless because the page loads in your browser.
Read every indexing directive. Inspect the HTML and HTTP headers for noindex or conflicting robots instructions. CMS dashboards can describe an intended setting while plugins, templates, caching layers, or edge rules deliver something different.
Trace the canonical signals. Compare the declared canonical with the final URL, redirects, sitemap entry, internal links, and alternate versions. If those signals nominate different URLs, decide which one should win and align them. A canonical tag isn’t a substitute for a coherent URL policy.
Verify discovery paths. Link the page from an indexable, relevant page using a normal crawlable link. Include the preferred URL in the appropriate XML sitemap. Sitemap inclusion helps discovery and monitoring, but it doesn’t override noindex directives, access failures, or canonical conflicts.
Compare Google’s view with your server evidence. Review the URL-level information available in Search Console, the Page Indexing category, and your server logs. Note whether Googlebot requested the URL, which response it received, and whether Search Console is describing a crawl problem, an indexing directive, a canonical decision, or a reporting state.
Fix the narrowest confirmed cause. Correct the response, rule, directive, canonical, or discovery path that failed. Then use Search Console’s validation or submission workflow where appropriate and wait for new evidence instead of repeatedly changing unrelated parts of the page.
Run the same checks on a healthy sibling URL that uses the same template. If both URLs fail in the same way, investigate the shared template, plugin, CDN rule, or server configuration. If only one fails, stay focused on its directives, links, canonical target, and content relationship to other URLs.
The Page Indexing report is designed to show which pages Google can find and index, identify exclusion or error patterns, and let you monitor whether submitted fixes were accepted. That makes it valuable for pattern detection, but it doesn’t replace inspection of the actual response or the logs generated when Googlebot visits.
Separate stale Search Console data from a real SEO failure
Search Console reporting is not a live event stream. Before treating a count increase, count decrease, or unchanged category as a new technical problem, read the report’s last-updated date. A fresh deployment and an older report can both be accurate within their own time frames.
Read the timestamp first. Compare the report’s last update with the publication date, deployment time, and date of your fix. Don’t expect a snapshot that predates the change to confirm it.
Check the scope of the lag. Look at unrelated URLs and other Search Console views. If many sections stop advancing at the same date, reporting freshness is a stronger explanation than a simultaneous sitewide indexing failure.
Inspect the URL directly. A URL-level inspection can provide evidence that differs from an older aggregate report. Record both results with their dates rather than forcing them into a single conclusion.
Read server logs. A recent Googlebot request proves that the request reached your infrastructure, even if an aggregate report hasn’t incorporated it. The status code, redirect destination, response size, and requested resources provide clues about what happened next.
Preserve the before-and-after state. Record the directive, canonical, response, report category, and report date at the time of the fix. When the report updates, you can evaluate the change against evidence instead of memory.
Email alerts are useful prompts, but silence isn’t proof that indexing is healthy. Alerts can be interrupted, and not every URL-level issue becomes an email. Your monitoring process should still include report freshness, representative URL checks, and server-side crawl evidence.
If the report date is current and Google has recrawled the corrected URL, an unchanged exclusion deserves investigation. If the report predates the fix, wait for a newer snapshot while checking live evidence. That distinction can save you from reverting a correct implementation because the dashboard hadn’t caught up.
Read bot activity without mistaking it for visibility
Those figures explain why a Google-specific crawl problem can have a disproportionate visibility cost. They do not mean that every Googlebot request creates an index entry, or that a higher request count improves rankings. A crawler can revisit redirects, error pages, duplicate URLs, resources, or pages that remain excluded.
Separate Google Search access from access granted to other AI crawlers. AI crawlers were among the user agents most frequently disallowed in robots.txt, while AI user-action crawling grew sharply. Your policy may reasonably differ by crawler and business objective. What matters diagnostically is that an increase from an AI bot doesn’t prove Googlebot access, Google indexing, AI citation, or referral traffic.
What you observe
What the evidence supports
What to check next
No Googlebot request appears within your retained log window
You don’t yet have server-side evidence of a Googlebot visit
Check internal discovery, sitemap inclusion, robots.txt, DNS and CDN access, security rules, and whether log coverage includes the correct host
Googlebot requests receive redirects, blocked responses, or server errors
Google reached the infrastructure, but fetching the intended page failed or took a different path
Follow the complete response chain and correct the redirect, origin, firewall, authentication, or availability problem
Googlebot receives the intended successful response, but the URL isn’t indexed
At least one fetch succeeded; crawl access alone isn’t the remaining question
Inspect noindex directives, X-Robots-Tag headers, canonical selection, duplicate variants, and the Page Indexing reason
The Page Indexing date is old across unrelated URL groups
The dashboard may not yet represent recent crawling or fixes
Use URL-level inspection and logs while waiting for a newer aggregate snapshot
The URL is indexed but receives no meaningful impressions
The investigation has moved beyond basic crawl and index eligibility
Evaluate query alignment, search intent, internal prominence, content usefulness, competing results, and result presentation
Requests from other AI bots rise while Googlebot activity does not
Non-Google crawl activity increased
Review user-agent-specific access rules and measure each visibility surface separately
Maintain a simple incident ledger for important URL groups. Record the preferred URL, page purpose, HTTP response, robots.txt result, page-level directive, canonical target, discovery path, latest Googlebot request in your retained logs, current Search Console category, report date, and next action. This turns an ambiguous visibility complaint into a set of testable conditions.
Start with your highest-value missing URL and one healthy peer that uses the same template. Complete the ledger before changing the site. Once a repeatable cause appears, fix it at the narrowest shared layer, validate the delivered output, and then watch for new crawl and indexing evidence.
When Google adds an extra route from a search result into the middle of your page, the visitor may never see your title, introduction, or opening explanation. Your technical SEO job is no longer limited to improving the description beneath a blue link. You also need useful section-level entry points and a stable preferred URL.
You cannot force Google to show a particular snippet enhancement. You can make the page ready for one, prevent JavaScript from sending conflicting canonical signals, and verify what Google can recognize. That is the practical standard this guide will help you apply.
Build sections that work when the introduction is skipped
Read an important section as if everything above it were hidden. If its opening depends on context from the introduction, a search visitor can land in the right place and still feel lost. The fix is not to repeat the entire page. It is to put the minimum orientation at the point of arrival.
Use a heading that names the question, decision, or task the section resolves. Replace labels such as “More details” or “Other considerations” with headings such as “When JavaScript should set the canonical URL.”
Answer the heading immediately. Put the direct answer in the opening sentence, then add qualifications and implementation detail.
Remove unexplained backward references. Phrases such as “as described above” fail when the visitor has bypassed the earlier material.
Define any term or acronym the reader needs to use the section. Do not make the visitor search upward for a definition that could fit in a short clause.
Keep the relevant example, warning, or next action with the explanation it belongs to. A section-level visitor should not have to reconstruct the procedure from disconnected parts of the page.
Use stable section IDs when they help your internal navigation or make sections easier to share. Treat those IDs as useful site architecture, not as a guarantee that Google will display a read-more link.
Run the mid-page landing test
Open the page at each important heading instead of starting at the top. Read only the heading, its opening paragraph, and the nearby action. You should be able to identify the subject, understand the answer, and know what to do next without consulting the introduction.
This test also exposes content problems that a meta description cannot repair. Search-result copy may persuade someone to click, but only the destination can fulfill the promise. If the section is vague, fixing metadata leaves the actual landing experience unchanged.
Treat snippet enhancements as outputs, not settings
Read-more links have appeared in many results, but they are not included in every search snippet. Their absence is therefore not proof of a technical defect, and their presence is not proof that every section of the page is well optimized.
The additional link creates another clickable route from a result and may give the page another opportunity to satisfy the searcher. It does not guarantee more traffic. The query, the wording Google presents, the selected destination, and the usefulness of that destination still shape what happens after the result is shown.
Keep the control boundary clear. You control the page’s headings, section order, explanations, initial HTML, rendered HTML, canonical declaration, and indexability instructions. Google decides whether a result receives an additional link and which relevant section it exposes.
That distinction prevents two common overreactions. Do not rewrite a canonical URL merely because an extra link did not appear. A canonical identifies the preferred page-level URL; it is not a switch for selecting a section. Likewise, do not assume that a visible enhancement makes the underlying technical setup correct. The result can look useful while JavaScript is still changing a critical signal behind the scenes.
Use the symptom to choose the audit. If no read-more link appears, review section clarity and basic indexability without treating the absence as an error. If the link reaches a confusing passage, rewrite that section as an independent entry point. If Google surfaces an unexpected page URL, move your attention to canonical consistency.
Make the canonical URL identical before and after JavaScript
The canonical link tells Google which page-level URL you want treated as the preferred version. The cleanest implementation places that URL in the original HTML. If JavaScript also manages the document head, it should preserve the same canonical rather than changing it.
A straightforward HTML declaration looks like <link rel="canonical" href="https://example.com/technical-seo/">. If that exact URL is present in the original response, the rendered document should retain it. Do not publish one value as a placeholder and depend on client-side JavaScript to replace it with another.
Original HTML
After JavaScript runs
What to do
Canonical A
Canonical A
Keep this consistent pattern.
Canonical A
Canonical B
Resolve the conflict so both layers use the intended preferred URL.
No canonical
JavaScript sets canonical A
Use this only when the canonical cannot be emitted in the original HTML, then verify that Google recognizes it.
In the table, “canonical A” means the exact preferred URL you intended to declare. During an audit, record the complete string from both layers. Compare the protocol, hostname, path, trailing slash, and query string. Even when two variants eventually reach the same content, a difference tells you that separate parts of the rendering system disagree about the page’s identity.
If your framework genuinely cannot place the canonical in the original HTML, leave it out there and let JavaScript set the intended value. That is safer than publishing a provisional canonical and changing it after rendering. The JavaScript-only pattern is a fallback to verify, not a reason to move a working HTML canonical into client-side code.
Trace any mismatch to the component that owns the document head. Common architectural pressure points include a server-rendered template supplying one URL while a client-side router or SEO component calculates another. You do not need two canonical systems competing for control. Establish one preferred URL and make every rendering layer produce the same answer.
Keep section navigation separate from canonicalization. A search result may send someone into a particular passage, but the canonical still describes the page as a whole. Do not change the canonical to represent whichever section Google happened to expose for a query.
Audit the original HTML, rendered page, and Google view
A browser can show you a functioning page while concealing a disagreement between the response Google first receives and the document JavaScript eventually creates. A useful audit therefore checks both states and then confirms Google’s interpretation.
Choose a page that uses the same template and rendering path as the pages you care about. If multiple templates manage metadata differently, audit each template rather than assuming the homepage represents the whole site.
Open the original page source. Record the canonical URL exactly as delivered and check whether an index-blocking instruction is present.
Inspect the document after JavaScript has completed its normal rendering. Record the rendered canonical and check for duplicate canonical elements.
Compare the initial and rendered values character by character. If JavaScript changes the value, fix the component producing the disagreement instead of accepting the rendered value as “close enough.”
If a live search result contains a read-more link, follow that actual link. Check whether the selected heading and opening explanation make sense without the top of the page.
Repeat the check after changes to routing, templates, head-management components, or deployment logic. Those are the layers most capable of altering the original-versus-rendered relationship.
Do not rely on JavaScript to undo an initial noindex
This matters when staging controls leak into production or when a rendering system starts with restrictive metadata and relaxes it on the client. Resolve the deployment state before the page is served. An indexable production page should not begin by telling a crawler not to index it.
Canonical and noindex also answer different questions. The canonical identifies the preferred URL among versions; noindex asks that a page not appear in the index. Do not use one as a substitute for the other, and do not expect an attractive snippet treatment to compensate for contradictory indexability instructions.
Key takeaways
A Google read-more link may bypass the top of your page, so every important section should make sense as an entry point.
The enhancement is not universal and cannot be treated as a setting, technical entitlement, or guaranteed traffic increase.
Put the canonical URL in the original HTML when possible. If JavaScript also touches it, the value should remain identical.
If the original HTML cannot contain a canonical, omit it there, set the intended value with JavaScript, and verify Google’s recognition in URL Inspection.
Do not ship an initial noindex on a page you want indexed and depend on client-side code to remove it.
Audit search presentation and page identity separately: section quality affects the landing experience, while canonical consistency protects the preferred page-level URL.
Start with one JavaScript-rendered template. Place its original source beside the rendered document, compare the canonical values, and then open its major sections without reading the introduction. That small audit will tell you whether the next fix belongs in your content structure, rendering system, or indexability controls.
You’re deciding whether to shut out AI crawlers, but the cost of a mistake is lopsided. Allow too much and you may give away valuable access while absorbing the infrastructure cost. Block too broadly and you may cut off search discovery that still brings readers, customers, and subscribers.
The workable approach is to stop treating “AI” as one access category. Decide which systems may retrieve which content, for which purpose, under which conditions. Then enforce that policy in layers and measure the result.
Separate discovery, retrieval, training, and licensing
A crawler request is a technical event, not a complete explanation of intent. The same public page can have several distinct uses, and your business may benefit from some while rejecting others.
Conventional search discovery: A search crawler retrieves a page so the page can be considered for a search index. Access makes discovery possible; it does not guarantee indexing or rankings.
Live AI retrieval: A system fetches current information to help answer a user’s request. You may value the resulting visibility, but allowing retrieval does not guarantee a citation or referral visit.
Model development: An operator collects content for training or related model-improvement work. This can involve a different value exchange from answering a current query.
Licensed access: A publisher deliberately supplies content under agreed technical and commercial terms, potentially through authentication, metering, or a dedicated feed.
These purposes are strategically separate even when a platform does not give you separate crawler controls. That limitation matters: you can only implement distinctions that the operator exposes and your infrastructure can verify. Where an operator combines purposes, record the exception and make the resulting trade deliberately.
Key takeaways
Preserve conventional search access unless you have consciously decided that its discovery value no longer justifies it.
Set policy by crawler identity, declared purpose, and content class rather than using one domain-wide rule for every automated request.
Use robots.txt to communicate crawl preferences, but use server-side controls or authentication when access must actually be prevented.
Roll out narrow, reversible rules and compare infrastructure savings with changes in discovery, revenue, and AI visibility.
A blanket block creates an asymmetric business risk
The volume is large enough to justify active management. Cloudflare reported that, following the July 1 launch of its pay-per-crawl initiative, customers had blocked 416 billion AI-bot requests. That figure demonstrates the scale of crawler demand on participating sites. It does not establish that every blocked request would have harmed a publisher or that blocking is the right default for every site.
This is why “block all AI” can be a misleading objective. If the platform connects conventional search crawling with AI use, the technical setting may force a wider business decision than you intended. Before deploying a rule, write down which benefit you are prepared to lose. If the answer is “none of our organic search discovery,” a domain-wide crawler block is too blunt.
The reverse is also true. “Allow everything for visibility” is not a strategy. An allowed request may generate no referral, citation, subscription, or licensing opportunity. Access should remain open because it serves a defined outcome, not because the crawler includes “AI” in its name.
Build an access matrix your engineers can enforce
Turn the policy into a small matrix before touching robots.txt or a firewall rule. Start with four access tiers and assign each content class to one of them.
Access tier
Use it for
Technical default
Business condition
Open discovery
Public pages intended for broad distribution
Allow verified search crawlers and selected AI access; monitor usage
Reach and discoverability outweigh reuse concerns
Search-preserved
Public pages that should remain searchable but are not offered for wider AI collection
Allow conventional search where the operator exposes a separate identity; deny or throttle named AI crawlers
The technical identities can be separated reliably
Metered or licensed
Original archives, structured collections, or other material with concentrated reuse value
Require authentication, rate limits, or a controlled delivery channel
Access is granted under recorded operational and commercial terms
Closed
Subscriber-only, internal, personal, or otherwise non-public material
Require authentication and enforce denial at the server or application layer
Public crawler access is unnecessary or inappropriate
Do not classify the whole site by its most valuable page. A public news story, an evergreen guide, a subscriber archive, an image library, and an internal search endpoint can justify different rules. URL groups make the policy more precise and make mistakes easier to reverse.
For every crawler-policy combination, record the operator, declared purpose, method used to verify identity, allowed URL groups, rate limit if any, enforcement layer, policy owner, and review date. If you cannot verify the operator or purpose, classify the traffic according to your risk tolerance rather than guessing from a friendly-looking user-agent string.
Keep the technical policy separate from the legal permission. A crawler being able to retrieve a page does not by itself define the terms under which the content may be reused. If you intend to sell or contractually license access, have appropriate legal counsel establish the rights, attribution, payment, update, termination, and enforcement terms.
Enforce the policy in layers, not with one bot rule
Robots.txt is useful for expressing crawl instructions to compliant operators. It is not authentication, and it does not prevent an unidentified or non-compliant client from requesting a public URL. Use the control that matches the consequence of failure.
Capture a baseline. Before changing access, record crawler requests, transferred bytes, cache misses, origin load, requested URL groups, response codes, search crawl health, search traffic, observable AI referrals, and conversions. Note campaigns or publishing spikes that could distort the comparison.
Inventory and verify identities. Group requests by claimed user agent, network identity, paths requested, rate, and behavior. A user-agent string can be copied, so do not approve or block high-impact access solely because a request claims a recognizable name. Use verification information supplied by the relevant operator where it is available.
Publish the intended crawl rules. Add crawler-specific robots.txt instructions only after confirming that the rule preserves the search access you want. Test the deployed file, including rules inherited from broader user-agent groups.
Enforce consequential restrictions upstream. Use your CDN, web application firewall, origin, or application to throttle or deny matching requests. Keep each rule narrow, log its matches, return a consistent response, name an owner, and document the rollback procedure.
Put valuable non-public material behind authentication. Do not rely on robots.txt to protect subscriber content, private files, customer information, unpublished drafts, or licensed datasets. If anonymous visitors can retrieve a URL, an automated client may be able to retrieve it too.
Stage the rollout. Begin with one verified crawler identity or one low-risk URL group. Review false positives and business metrics before extending the rule. This limits the damage if a shared identity, proxy, or overly broad path pattern catches traffic you meant to preserve.
Blocking only affects requests that reach your controls and match your rules. It does not prove that a model lacks the content, and allowing a crawler does not prove that the content will appear in an answer. Describe the operational outcome accurately: you allowed, throttled, or denied a particular access path.
Measure whether blocking improved your position
A successful block is not merely a rising denial count. The useful question is whether the policy improved the exchange between access granted and value received. Review the same scorecard before and after each staged change.
Infrastructure: Requests, bandwidth, cache misses, origin work, and load associated with each verified crawler and content class.
Search discovery: Crawl errors, accessible pages, index coverage, organic impressions, clicks, and landing-page conversions. Investigate changes that coincide with a rule deployment before expanding it.
AI visibility: Observable AI referrals, cited pages found through a consistent sample of relevant prompts, brand mentions, and resulting conversions. Referral logs measure visits, not every unseen citation or model use, so do not treat zero referrals as proof of zero exposure.
Content value: Subscriptions, leads, revenue, partnership requests, and licensing discussions associated with the affected material.
Policy quality: False positives, unidentified automation, repeated requests against denied paths, operator verification failures, and rules that no longer match your content structure.
Set the decision rule before examining the result. Retain a restriction when it materially reduces unwanted access or resource use without damaging the outcomes you chose to preserve. Roll it back when search discovery or legitimate partner access declines because the match was too broad. Move valuable, persistent demand toward authenticated or licensed access when the opportunity justifies the operational and legal work.
Your first action can be small: write one policy sentence for conventional search, one for live AI retrieval, one for model-development access, and one for premium content. Compare those sentences with the controls your platforms actually expose. Where policy and tooling do not line up, start with the narrowest reversible restriction and preserve the baseline you will need to judge it.
You are looking at robots.txt because crawlers are spending time on the wrong URLs, a migration introduced unfamiliar rules, or someone wants to block a page from search. The risky part is that all three problems can look similar while requiring different controls.
A good configuration is usually short. It limits crawl waste without hiding pages, resources, or signals that search engines need. Here is how to decide what belongs in the file, write the narrowest workable rules, and test them before they affect valuable content.
Give each SEO objective the right control
The Robots Exclusion Protocol has coordinated crawler access since 1994, but robots.txt still has one primary job: requesting that compliant crawlers avoid particular URL paths. It does not protect content, guarantee deindexing, consolidate duplicates, or redirect visitors.
That distinction prevents the most damaging configuration error. A crawler can discover a blocked URL through links even though it cannot fetch the page. The URL may therefore remain known to the search engine without its current content being crawled. If you need a crawler to process a noindex directive, canonical tag, redirect, or rendered page, robots.txt must not prevent that fetch.
What you need to accomplish
Appropriate control
Why
Reduce requests to a verified crawl trap or low-value URL space
A narrow robots.txt rule
The crawler does not need to fetch those matching paths.
Keep a crawlable page out of search results
A robots meta noindex directive or equivalent response header
The crawler must fetch the URL to see and process the indexing instruction.
Consolidate duplicate pages
Consistent internal links, an appropriate redirect, or a canonical signal
Blocking a duplicate can prevent the crawler from seeing the signal intended to consolidate it.
Protect private, preview, administrative, or staging content
Authentication and access controls
Robots.txt is public and voluntary; it is not a security boundary.
Retire a page or move it elsewhere
An appropriate redirect or not-found response
The response communicates the URL’s actual state instead of merely suppressing crawling.
Anyone can open /robots.txt. Do not put confidential paths, credentials, internal hostnames, or explanations of sensitive systems in it. A bot that does not honor the protocol can ignore every line. If unauthorized access would create a problem, secure the resource at the server or application layer.
Build rules from URL evidence, not page labels
Robots rules match URLs. They do not understand concepts such as “thin content,” “member area,” or “filter page.” Before writing a directive, translate the business label into an exact, observable path pattern.
Inspect actual crawler requests. Use server logs, crawl reports, and your site architecture to identify paths that bots are requesting repeatedly. A large theoretical URL space is not automatically a crawl problem; confirm that crawlers are entering it.
Classify the URLs by desired behavior. Decide whether each group should be crawled and indexed, crawled but not indexed, redirected, removed, or protected. Only the first decision is directly managed through robots.txt.
Find a stable URL boundary. Prefer a dedicated directory or unmistakable prefix over fragments that can also occur in valuable URLs. If the unwanted set cannot be isolated safely, fix URL generation or navigation instead of forcing a broad exclusion.
Collect boundary examples. Include known URLs that should match, known URLs that must remain crawlable, paths with and without trailing slashes, mixed-case variants that actually exist, and representative query strings.
Assign a reason and owner to every rule. Record why it exists, what evidence justified it, and who should review it after migrations or routing changes. Keep confidential operational detail outside the public file.
Internal search results, sorting paths, faceted navigation, tracking variants, generated calendars, and duplicate utility views can be candidates for crawl restrictions. None should be blocked merely because it belongs to that class. First check whether the URLs receive organic traffic, serve as landing pages, carry useful links, or need to expose indexing and canonical signals.
Keep the scope of each robots file in view. The file belongs at the root of the origin it governs. A rule on the main host does not automatically control a shop, help center, asset host, or other subdomain. Protocol and port differences can create separate origins as well. Audit the exact locations from which search engines request content rather than assuming one file covers the entire brand.
Write the smallest configuration that expresses the intent
A group begins with User-agent and is followed by directives for that crawler or crawler family. Disallow identifies paths you do not want fetched. Allow can preserve a narrower path inside a broader exclusion when the target crawler supports that logic.
This illustrative configuration asks compatible crawlers to avoid an internal search directory while preserving a useful help path inside it:
Do not paste that example into production unchanged. It is safe only if your site’s valuable URLs and routing behavior match the stated intent. In particular, test both /search and /search/. The trailing slash changes what the pattern can match.
Use separate user-agent groups only when you have a deliberate crawler-specific policy. That may matter when search crawlers, archive crawlers, commercial bots, and AI bots serve different purposes. Keep each group complete and unambiguous, because directive support and group handling are not identical across every crawler.
Wildcards such as * and end-of-URL matching with $ can express patterns that plain prefixes cannot. They also increase the chance of an unintended match, and support can vary. If a rule depends on either character, verify the syntax for every crawler that matters and test representative URLs through that crawler’s parser or testing facility.
Keep comments brief and operational. A # comment can document a rule’s purpose, but the public file is the wrong place for sensitive notes. In most configurations, readable path-based rules are easier to audit than dense wildcard expressions.
Reject these common configurations during review:
Disallow: / in a production-wide group. It requests that the affected crawler avoid the whole site. Treat it as a release-blocking change unless complete exclusion is the explicit objective.
A noindex instruction placed in robots.txt. Use a supported page-level meta directive or response header and leave the URL crawlable long enough for the crawler to process it.
Rules that expose private locations. Remove the path from the public file if secrecy matters, then protect it with authentication or authorization.
Broad blocks on scripts, styles, images, or API responses needed for rendering. Search engines may need those resources to understand the visible page. Test rendered output before excluding asset paths.
Parameter rules copied from a different URL structure. A generic pattern for filters or sorting can also catch category pages, pagination, campaign landing pages, or other valuable combinations.
A robots file copied from staging. Staging should be protected by access controls, while production should have an independently reviewed configuration. Deployment automation must not transfer an environment-wide block accidentally.
Crawl-delay treated as a universal throttle. Support is not consistent across crawlers. Verify crawler-specific controls and address server capacity directly instead of assuming one directive will regulate every bot.
Rules added solely to “improve crawl budget.” A directive cannot save meaningful requests if crawlers were not visiting the affected space. Establish a log-based baseline and confirm that the change alters the intended behavior.
Test matching, deployment, and crawler response separately
A syntax check is necessary, but it is not enough. A technically valid rule can still block the wrong URLs. Treat the change as a routing change with an explicit test set and a rollback path.
Save the current file. Put the proposed version under version control or otherwise preserve an immediately deployable rollback copy.
Fetch the real endpoint. Confirm that /robots.txt is reachable without authentication from the exact production origin and returns the intended plain-text content. Check each relevant subdomain separately.
Run positive and negative URL tests. Test known blocked URLs, known allowed URLs, boundary cases, trailing-slash variants, letter-case variants that your server recognizes, and URLs containing representative parameters.
Test each important crawler identity. Do not assume a wildcard group behaves identically to a crawler-specific group or that every bot supports the same pattern extensions.
Crawl the site as a user would navigate it. Check that indexable pages, canonical destinations, structured-data resources, images, scripts, and styles remain accessible where search engines need them.
Deploy the narrowest change first. Avoid combining a robots rewrite with unrelated routing, canonical, sitemap, or template changes. Isolation makes an unexpected result easier to diagnose and reverse.
Watch requests and search diagnostics. Compare server logs and crawl reports with the pre-change baseline. Look for reduced requests in the targeted space and any new blocks affecting valuable URLs.
Do not judge the result from an immediate manual fetch alone. Compliant crawlers can cache robots.txt and revisit known URL spaces on their own schedules. Keep monitoring through subsequent crawl activity, and retain the rollback until the logs show the intended request pattern without losses elsewhere.
Recheck the file after a redesign, domain migration, subdomain launch, routing change, faceted-navigation update, or content-management migration. Those events can change URL boundaries even when robots.txt itself remains untouched.
Key takeaways
Use robots.txt to manage crawler access, not as a security, removal, redirect, canonicalization, or guaranteed indexing control.
Keep pages crawlable when search engines need to process noindex, canonical, redirect, rendering, or structured-data signals.
Base exclusions on observed crawler requests and stable URL patterns, then use the narrowest rule that isolates the unwanted space.
Treat each origin separately and verify every relevant host, subdomain, protocol, and crawler group.
Assume wildcard, end-anchor, exception, and crawl-rate behavior can vary until you confirm support for the target crawler.
Test URLs that should match and URLs that must not match, then verify the result in server logs after deployment.
Start with your current file and a compact set of real URLs. For every directive, write down the crawler, the matching URL space, the desired behavior, and the evidence that the rule is needed. If you cannot do that cleanly, narrow the rule or leave it out until the underlying URL problem is understood.
You deploy an indexing fix, open Google Search Console, and find that the Page Indexing report still shows the old problem. Before you reopen tickets or change the site again, check the report’s data date. You may be looking at a stale measurement rather than a failed fix.
A reporting delay changes what you can verify, not necessarily what Google is doing. The right response is to separate the age of the report from the state of the site, validate what you can independently, and give stakeholders an honest status without turning old counts into current facts.
Read the report’s cutoff date before reading its numbers
The Page Indexing report, also known by the older Index Coverage name, is a historical view. It shows which pages Google has found and indexed, identifies indexing problems, and lets you follow whether submitted fixes are recognized. When its processing is delayed, the interface can remain available while the newest underlying observations are missing.
That makes the report’s last-updated date part of every conclusion. A current-looking chart with an old cutoff is still old evidence.
Record the report date. Copy the last-updated date before exporting counts, taking screenshots, or comparing periods.
Record the change date. Note when the fix became publicly available, which templates or URLs changed, and what condition you expected to disappear.
Put the dates in order. If the report stops before the deployment, it cannot tell you whether the deployment worked.
Limit the conclusion. Say that validation is pending because the reporting window has not reached the change. Do not label the fix successful or unsuccessful yet.
In one confirmed incident, the Page Indexing data was delayed by about two weeks. That is an example, not a normal service-level expectation or a waiting rule for every future delay. Let the displayed cutoff, rather than an assumed timetable, determine what the report can support.
Separate stale reporting from an actual indexing problem
A delayed report and an indexing problem are different conditions. They can also occur at the same time. You therefore need to identify what each observation proves instead of choosing the most reassuring explanation.
Keep the fix in place, validate the live implementation, and wait for the cutoff to advance
The Page Indexing report remains stale across the property
The aggregate view is not current
Document the cutoff and avoid presenting its totals as current-period results
The cutoff advances beyond the fix, but the affected URLs still show the same exclusion
Fresh reporting still detects the condition
Reopen the technical diagnosis using representative URLs
A live URL has an unintended response, directive, canonical, or page state
A site-side issue exists independently of the reporting delay
Correct that implementation without waiting for the aggregate report
Search visibility is not a clean substitute for the missing report. Rankings can change for reasons unrelated to indexing, and the absence of a result for one query does not isolate the cause. Use visibility as a separate performance signal, not as proof that the reporting pipeline is current.
Use a verification workflow that does not depend on the stale chart
You cannot force an aggregate report to catch up, but you can determine whether the intended technical state is live. Work from a small set of representative URLs: one or more that received the fix, an unaffected control URL, and examples from each materially different template.
Preserve the original evidence. Save the affected URL set, exclusion label, report cutoff, and pre-fix state. Without that baseline, it becomes difficult to tell whether a later change reflects your work or a different site change.
Check the public response. Confirm that each representative URL loads as intended and that redirects or error responses are not sending Google somewhere unexpected.
Check indexability controls. Review the rendered page and relevant directives for an unintended noindex instruction, robots restriction, or canonical target. Confirm that the live output, not merely the CMS setting, contains the intended value.
Check discoverability where it matters. Verify that internal links and any relevant sitemap entries point to the preferred URL. A corrected page that is isolated from the site’s discovery paths can remain a separate technical problem.
Use URL-level diagnostics carefully. Search Console’s URL Inspection tools can help you examine individual examples. Treat their findings as URL-level evidence, not proof that the aggregate Page Indexing report has refreshed.
Stop changing the implementation if it is correct. Repeated edits made only to move a stale chart can introduce conflicting canonicals, directives, redirects, or deployment states. Preserve a technically sound fix until newer evidence justifies another change.
Recheck when the data date advances. Once the report covers a period after deployment, review the affected group separately from the rest of the site. That is the first point at which the aggregate report can meaningfully validate the change.
This workflow gives you two separate answers. The live checks tell you whether the implementation is currently correct. The refreshed Page Indexing report later tells you whether Google’s aggregate reporting recognizes the outcome. Do not collapse those answers into one status.
Report the delay without turning stale data into a current KPI
Reporting delays become most disruptive when a dashboard or client report expects a fresh number on a fixed date. The tempting shortcut is to copy the latest visible count into the current period. That makes the report look complete, but it silently changes an old observation into a new claim.
If the data has not caught up, label it as pending. If a reporting template requires a value, carry forward the prior observation only with its original as-of date. Never place a stale count under the current period without a visible qualifier.
A useful status update contains five elements:
Affected surface: Name the Page Indexing report rather than saying that all of Search Console is broken.
Data cutoff: State the last date represented in the report.
Change timing: State whether the cutoff falls before or after your deployment.
Independent checks: Summarize what you verified on the live URLs without claiming that those checks replace Google’s aggregate data.
Decision: Say what will remain unchanged and what event will trigger the next review, such as the report date advancing beyond deployment.
Example status wording: The Search Console Page Indexing report is delayed, and its newest data predates our deployment. The intended response, canonical, and indexability directives are live on the sampled URLs. Aggregate validation remains pending until the report’s cutoff advances beyond the change date. We are keeping the current implementation in place and will reassess when newer data is available.
This wording does not promise that every URL is indexed. It tells the reader what is known, what is not yet observable, and why waiting is a controlled decision rather than inaction.
Key takeaways
Check the Page Indexing report’s last-updated date before interpreting any count, chart, or validation state.
If the report stops before your deployment, it cannot confirm or reject the fix.
A confirmed reporting delay is not evidence that crawling, indexing, or ranking has stopped.
Validate the live technical state with representative URLs while keeping aggregate validation marked as pending.
Do not repeat or reverse a correct implementation merely to make a stale chart change.
When the cutoff advances beyond deployment and the same exclusion remains, move from waiting back to technical investigation.
Your next action is simple: put the report cutoff beside your deployment timestamp. If the data is older than the change, preserve the fix, document the gap, and set the next review for when Search Console finally shows post-change data.
If your pages perform in conventional search but rarely surface in AI-generated answers, publishing more copy is unlikely to solve the underlying problem. A machine may reach the page yet still struggle to identify its main subject, separate the answer from supporting detail, verify important claims, or determine what it is allowed to do next.
An AI-ready site makes that chain explicit. Because AI systems can draw on inputs ranging from web crawls to licensed datasets, no single optimization can guarantee inclusion or citation. What you can control is whether your site is accessible, understandable, internally consistent, and useful. That means coordinating content, structured data, machine-readable context, controlled actions, and APIs instead of treating each as an isolated project.
Key takeaways for an AI-ready website
Give every important page one clearly stated job, such as answering a question, explaining an entity, supporting a decision, or enabling an action.
Put the direct answer and its important qualifications in visible page content. Structured data should describe those facts, not introduce a second version of them.
Reduce ambiguity with stable names, explicit relationships, descriptive headings, canonical URLs, and links to supporting evidence.
Separate content readiness from action readiness. A page can be understandable without being safe for an AI agent to transact through.
Prioritize blocked access, incorrect claims, content-schema conflicts, and unsafe actions before cosmetic metadata or additional copy.
Design each page around one answerable job
AI optimization starts before schema. It starts with deciding what the page is supposed to help someone understand or accomplish.
A page titled around a broad topic often tries to define a term, promote a service, answer several unrelated questions, compare alternatives, and capture a lead at the same time. A human can sometimes infer the intended path from the design. Automated systems have to resolve competing signals in the title, headings, navigation, body copy, metadata, and structured data.
Write a plain-language page job before editing anything: “This page helps a qualified buyer determine whether this service supports their use case.” That sentence does not need to appear on the page, but the published content should fulfill it without making the reader assemble the answer from several sections.
For an answer-oriented page, use this sequence:
Name the subject. Use the full, consistent name of the product, organization, person, service, location, or concept being described.
Answer the central question. Put the useful answer near the beginning rather than delaying it behind a promotional introduction.
State the scope. Identify the audience, use case, region, plan, prerequisites, or other conditions that determine when the answer applies.
Support the answer. Add definitions, evidence, examples, limitations, and links that let a reader verify or interpret the claim.
Resolve the next decision. Tell the reader what to compare, check, read, or do next.
Sentence construction matters as well. “It supports integrations” forces the reader and the machine to recover both the subject and the meaning of “integrations” from nearby text. “The service accepts customer records through its documented API” identifies the subject, capability, object, and mechanism. If authentication, account level, geography, or supported data format changes that claim, put the qualification in the same passage.
This does not mean every sentence must sound mechanical. It means consequential claims should survive extraction from the surrounding design. A useful editing test is to copy the sentence into an empty document. If its subject, meaning, or scope disappears, rewrite it or keep the necessary qualifier attached.
Do not turn this advice into a collection of thin question-and-answer pages. Create a separate URL when the question represents a distinct intent that deserves its own complete answer. Keep closely related questions on one page when they share the same subject, evidence, and next step.
Use JSON-LD to clarify identity and relationships
Structured data is a translation layer between the visible page and a machine-readable representation of it. It is not a substitute for the page, a place to hide extra keywords, or a ranking coupon.
Start by identifying the main entity. An organization page should primarily describe the organization. A service page should describe the service and connect it to its provider. A profile should distinguish the person from the organization that employs or publishes them. An informational page should make its subject, author or publisher, and relationship to the rest of the site clear.
Then build the smallest accurate JSON-LD graph that represents what a visitor can verify. More properties do not automatically create more meaning. Every additional property creates another fact that can become stale, conflict with visible copy, or imply a relationship the page does not establish.
Use these rules when reviewing the graph:
Keep identity stable. Use the same name and persistent identifier for the same entity across templates. Do not create what appear to be several unrelated entities merely because different pages generate their markup independently.
Connect related entities explicitly. Represent the relationship between a service and its provider, a person and an organization, or a page and its publisher when that relationship is real and relevant.
Match visible facts. Names, descriptions, eligibility conditions, important values, dates, and other material details should agree with the content a visitor sees.
Choose types by meaning. Select the type that describes the real object on the page, not the type that appears to offer the most fields or the most attractive search treatment.
Omit unsupported claims. If a fact cannot be confirmed from the page or a connected authoritative page, do not add it only to make the markup look complete.
Validate meaning as well as syntax. Markup can be syntactically valid while identifying the wrong main entity, reversing a relationship, or carrying obsolete information.
The most important review is a parity check between what people read and what machines receive. Ask who or what the page is about, what it claims, who is responsible for it, which conditions limit those claims, and where the supporting detail lives. The answers should be the same whether you inspect the rendered content or the JSON-LD.
Template ownership is essential here. If an editorial team updates a page while a developer, plugin, or feed controls its schema, the two versions can drift. Assign one owner for each underlying fact and generate both representations from that maintained value where your publishing system permits it.
Make important evidence easy to crawl and verify
A clear answer is useful only if an automated visitor can reach it in a dependable form. Review the published page as an anonymous visitor, not only through the content-management preview.
Put the essential answer, qualifications, and entity names in accessible page text. If a critical fact appears only after a click, inside a stateful widget, behind an account prompt, or after a personalization step, treat it as less dependable for automated extraction. Interactive features can still improve the experience, but they should not be the only location of information needed to understand the page.
Check the technical path as well:
Confirm that the preferred URL returns the intended page to an unauthenticated request and does not resolve to a soft error, challenge screen, or unrelated fallback.
Use one canonical destination for materially identical versions instead of making systems choose among conflicting URLs.
Make titles and headings describe the page content. A clever label that omits the subject creates avoidable ambiguity.
Link important pages from relevant navigation or body content. Do not rely on an internal search box as their only route of discovery.
Review robots controls, page-level indexing directives, authentication rules, and content-delivery protections together. A page can be public in the browser yet unavailable to a particular automated request.
Keep essential assets available when they are required to render or interpret the content, while preserving appropriate security controls.
Do not respond to an access problem by allowing every bot through every layer of the site. Administrative areas, personal information, unpublished material, expensive dynamic endpoints, and account-specific pages need protection. The goal is deliberate access to publishable information, not indiscriminate exposure.
Verification is the next layer. Give substantive claims enough context that another system can distinguish a fact from promotional language. Name the responsible organization or person where it matters. Explain the basis of a claim. Link to the page that defines a policy, method, limitation, or data point. If an important statement is conditional, attach the condition to the statement rather than burying it elsewhere.
Dates deserve particular care. Updating a displayed date without materially reviewing the content creates a freshness signal that the page cannot support. When something changes, revise the affected claim, its visible date where appropriate, its structured representation, and any dependent pages. When nothing changed, leave cosmetic freshness alone.
Discovery, live retrieval, and inclusion in model data should not be treated as the same event. Making a page crawlable does not guarantee that an AI service will select, quote, cite, or learn from it. Build for dependable access and interpretation because those are necessary qualities you can inspect, not because they promise a placement you cannot control.
Treat agent actions as a controlled product surface
Answer engines mainly need to understand information. Agents may also attempt to complete a task. That changes the optimization problem from “Can the system interpret this?” to “Can the system perform the intended operation without creating unacceptable risk?”
Separate read operations from write operations. Looking up availability, retrieving documentation, or checking status generally has a different risk profile from placing an order, sending a message, changing an account, booking an appointment, or deleting a record. Do not expose a broad administrative function when a narrowly scoped operation would satisfy the user’s intent.
For every supported action, define:
The intent: what the action does, and what it explicitly does not do.
The required inputs: which fields are mandatory, which formats are accepted, and which values are rejected.
The authorization boundary: who may invoke the action and which records or capabilities that identity may access.
The preview: what will change, what it will cost, and which destination or account is affected before a consequential operation is committed.
The confirmation rule: which paid, destructive, externally visible, or difficult-to-reverse actions require explicit approval.
The response contract: how success, partial completion, validation failure, denial, and temporary failure are represented.
The recovery path: whether a request can be retried safely, cancelled, reversed, or handed to a person.
The audit trail: what was requested, which identity authorized it, what changed, and how access can be revoked.
Validate all inputs on the server side even when the interface already constrains them. Apply rate controls and abuse protections according to the operation’s cost and sensitivity. Use request identifiers or another duplicate-handling mechanism for actions that could be repeated after a timeout. Otherwise, a harmless retry can become a second purchase, message, or booking.
A public API is not automatically an agent-ready API. The interface still needs a clear contract, appropriately scoped authentication, predictable errors, and a supported integration path. Conversely, you do not need to expose an action API merely to claim that your site is AI-ready. If safe execution is not part of the user journey, accurate machine-readable information is the correct boundary.
Audit AI readiness in the order that reduces risk
Do not begin with an unrestricted site-wide rewrite. Start with the page templates tied to your most important questions, decisions, and transactions. A focused audit makes it easier to find the recurring defect and correct it at the template or data-model level.
For each selected page, mark every checkpoint as pass, partial, or fail:
Page job: Can you state in one sentence what the page helps a visitor understand or do?
Direct answer: Does the visible content answer that job early, with its important scope and limitations attached?
Entity clarity: Are the main subject, responsible organization, related entities, and their relationships unambiguous?
Structured-data parity: Does the JSON-LD represent the same facts as the visible page without hidden, stale, or conflicting claims?
Access: Can an anonymous request reach the preferred URL and the information needed to interpret it?
Evidence: Can a reader follow the definitions, supporting pages, policies, or other context behind consequential claims?
Action safety: If the page supports an operation, are permission, validation, confirmation, failure, retry, and recovery behavior defined?
Ownership: Is someone responsible for updating the visible content, structured representation, and connected interfaces when a fact changes?
Fix failures in consequence order. Blocked public content, factually wrong pages, schema-content conflicts, leaked private information, and unsafe write operations come first. Ambiguous subjects, hidden qualifications, and inaccessible evidence come next. Redundant wording and optional markup fields can wait.
When the same problem appears across several pages, stop editing URLs individually. Trace the defect to the template, shared content field, entity record, plugin configuration, or API contract that generated it. A durable fix should make the correct state easier to maintain than the incorrect one.
Begin with one high-value template this week. Define its job, rewrite the direct answer, align its JSON-LD, inspect anonymous access, and document who owns each important fact. Once that template passes, apply the same model to the next page family and turn the checks into part of publishing rather than an occasional cleanup.