I’m thrilled to share that Microsoft is simplifying the process of expanding Google PMax campaigns into Microsoft, allowing us to enjoy greater visibility and control over our campaign performance.
Microsoft Advertising is launching several updates to make managing, measuring, and migrating Performance Max campaigns more straightforward, especially for those of us already familiar with Google Ads.
Driving the news. Microsoft now allows us to import Google PMax campaigns with new customer acquisition (NCA) goals, a feature that’s been part of Microsoft since earlier this year.
The update is live for all advertisers now, enabling us to transfer campaigns focused on first-time buyers more seamlessly, without having to start from scratch.
What’s new. Microsoft ensures that when we import Google PMax campaigns with NCA goals, they will be retained if they don’t already exist in our account. Our existing settings won’t be overwritten.
Regarding audience lists:
Google website visitor segments transform into Microsoft remarketing lists.
Google’s “all visitors” and “all converters” lists map to similar lists on Microsoft.
For unsupported lists like Customer Match, we may need to use alternate options.
I’ve also noticed that Microsoft takes a cautious approach with “unknown” customers, categorizing them as existing customers to avoid inflating new customer conversion counts.
Why we care. This initiative could streamline cross-platform campaign expansion and reduce the hassle of rebuilding, making it simpler to test Microsoft’s PMax inventory. Plus, enhanced landing page reporting and search term insights offer a clearer picture of campaign performance, aiding our optimization and budget decisions.
More visibility for PMax. Microsoft is integrating landing page (Final URL) reporting for PMax campaigns, allowing us to review spend, clicks, impressions, conversion value, and ROAS by landing page.
We can also break this information down by campaign, asset group, and other dimensions.
Additionally, Microsoft stated that search term reporting will become more apparent by default, with more transparency updates such as auction insights and publisher URL metrics rolling out soon.
Other key updates:
Seasonality adjustments now support portfolio bid strategies, aiding short-term promotions.
Campaign name limits have increased, enabling up to 400 characters for easier management.
Autogenerated assets are improving ad relevance and performance by filling in underused Responsive Search Ads.
Merchant Center users can directly update store names and domains without needing support.
The bottom line.These updates simplify scaling across platforms, save time on campaign setups, and enhance our visibility into campaign performance, giving us greater control over efficiency and outcomes.
I’ve noticed that Google Ads tends to produce the same results repeatedly, no matter how much money I invest. This pattern stems from the system being trained by my consistent actions over time.
Previously, achieving success in paid searches was all about optimizing. I would adjust bids, restructure campaigns, refine match types, and add negatives, directly impacting performance.
While this method remains standard for many, during audits, these accounts often appear well-managed on paper—active management, matched targets, proper ROAS. Yet, their performance seems stuck.
Google Ads now builds upon the signals I’ve reinforced. Hearing phrases like “That didn’t work” usually indicates that minor changes didn’t override the ingrained patterns.
What many advertisers call optimization is actually training, and if I’m not careful, I might teach it the wrong lessons.
Why Isolated Optimizations Don’t Work Anymore
The current environment features Smart Bidding, Performance Max, and modeled conversions. These systems learn cumulatively rather than resetting at each change.
If I change my ROAS target today, it won’t wipe away months of established patterns. Shutting down a new campaign prematurely can mark such volatility as something to avoid.
It’s about optimizing for survival—behaviors that get funded, hit targets, and aren’t paused are what the platform focuses on.
When accounts plateau, especially under strong management, it often indicates that the system has been trained to avoid unpredictability—while that’s precisely where growth occurs.
What Training Looks Like in Google Ads
On the backend, Google Ads consistently evaluates the concept of success based on factors like conversion inclusion, valuation, and how I handle volatility.
Over time, these become the signals shaping its behavior, influencing queries, audience priorities, auction strategies, and demand exploration.
For example, if repeat customers easily hit ROAS targets but prospecting fluctuates, the system learns to prioritize what’s safe over what’s incremental.
Common Mistakes in Google Ads Training
These errors often pass for good management, but recognizing them is crucial. Here are a few I’ve noticed:
Mistake 1: Leaning on Easiest Revenue
Encouraging branded searches and repeat customers seems logical, but Google learns that predictable revenue is the ideal.
Shouldering this strategy makes incremental demand suffer as the account conservatively emphasizes what works, causing stagnation.
Mistake 2: Punishing Volatility
Responding to short-term inefficiency quickly by tightening targets or pulling budgets can send a message that exploration isn’t allowed.
This results in prioritizing stability, which eventually limits expansion and innovation, as the account simply recycles existing demand.
Mistake 3: Treating All Purchases the Same
Not all purchases are equal. When everything sends the same signal, Google defaults to what’s easiest to replicate—typically repeat purchases.
This can hinder new customer acquisition, a vital component of sustainable growth.
Intentional Training for Optimal Google Ads
Aligning Google Ads with business goals rather than just ROAS is key. Here’s my approach to intentional training that I’ve found effective:
Maintaining Efficiency Lanes
These are my accounts’ baseline revenue protectors. They include brand campaigns and high-intent terms with stable performance. These are not my growth engines.
Building Growth Lanes
Growth campaigns have broader match types and looser targets, aimed at demand expansion and new customer acquisition.
By separating growth lanes with realistic expectations, I allow them to learn even when fluctuations arise.
Changing Signals Slowly
Constantly adjusting ROAS targets can disrupt the system. I avoid weekly changes to let the data compound for broader query expansion and improved share.
Overall, it’s about accepting gradual growth rather than seeking overnight success.
Managing a Trained Google Ads System
Reflect on your management approach. If you’ve answered “yes” to questions about tightening targets quickly or pausing exploratory campaigns, it indicates your system is merely following the training it’s received.
The focus should shift from speed to thoughtful teaching, constantly evaluating what behaviors I’m reinforcing and how they align with my bigger picture goals.
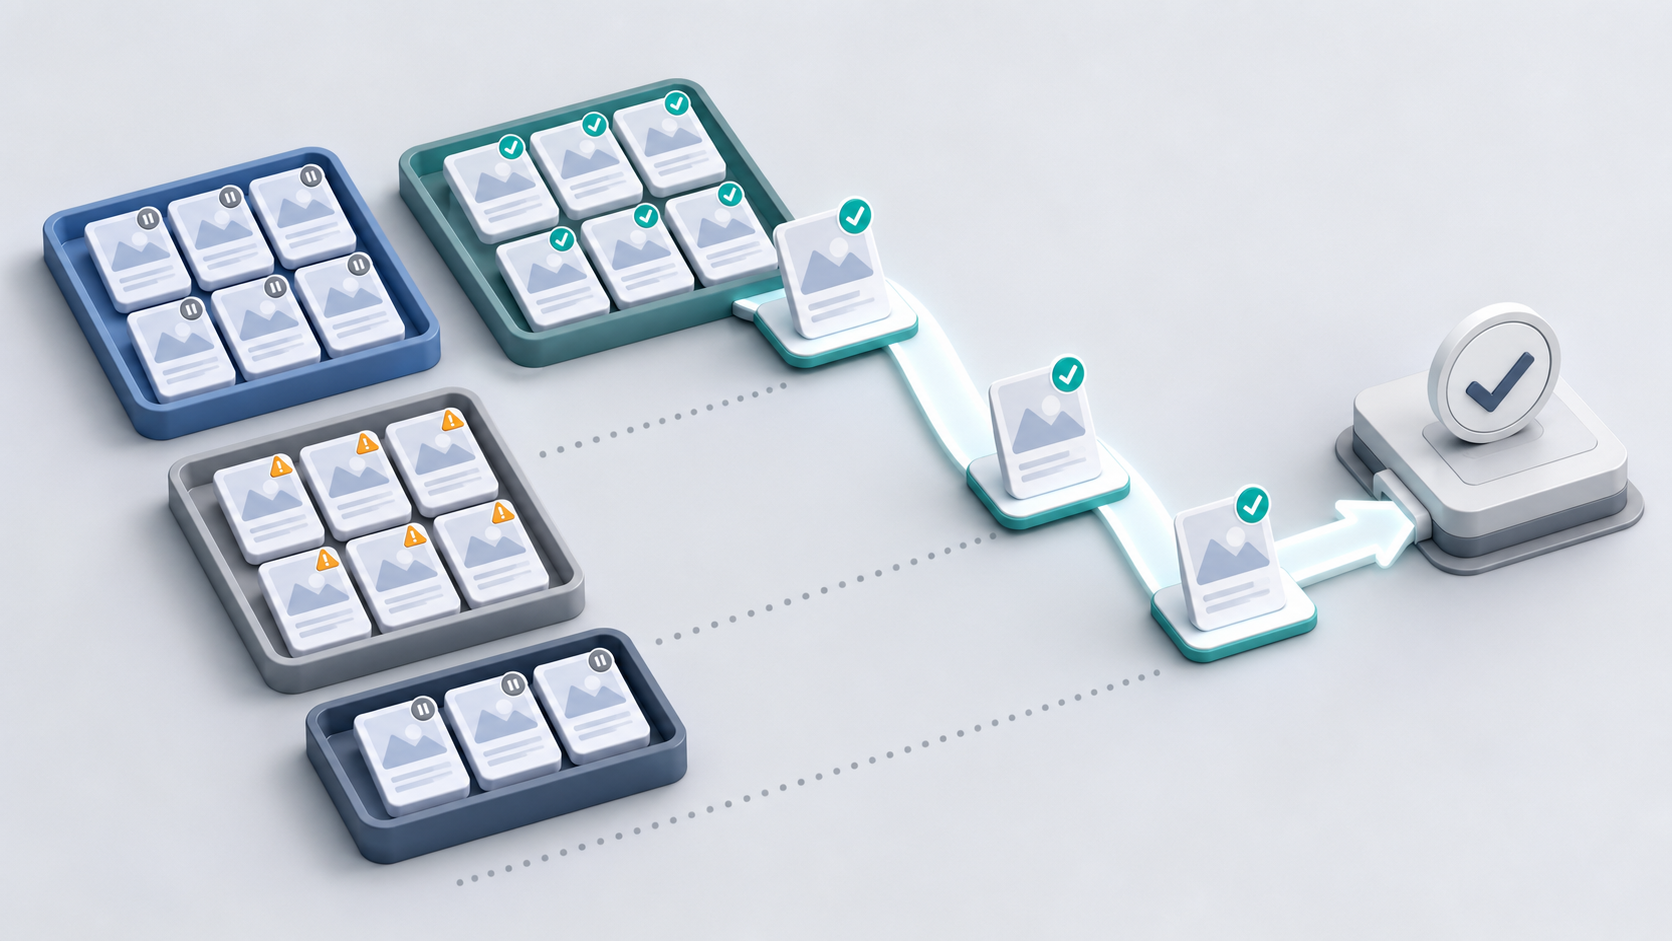
A policy issue has affected several ads, but only some belong to campaigns you still intend to run. Sending every eligible ad back through review can pull dormant campaigns, unfinished corrections, and unrelated account history into a request that should have been narrowly focused.
Campaign-level filtering gives you a cleaner way to control that scope. The payoff is operational: you can appeal the ads that are ready now, leave stale work out, and preserve a clear queue for anything that still needs attention.
The wording can create the wrong impression. This is not a special policy ruling for a campaign as a single object. The ads remain the items being submitted for re-review; the campaign is the filter used to build the batch.
That distinction matters in a large account. A campaign can contain ads in different states: one may have been corrected, another may still need work, and an older variation may no longer serve a business purpose. Selecting a campaign is therefore a scoping decision, not proof that everything inside it is ready.
The control also does not make a weak appeal stronger or guarantee a faster policy decision. It removes unnecessary submissions from your batch. You still need to resolve the underlying policy issue and verify what you are sending.
Build an appeal batch around readiness
The safest workflow starts before you open the appeal interface. Decide which ads are ready, which campaigns matter, and what remains unresolved. That prevents the platform’s list of eligible items from becoming your de facto work plan.
Identify the policy issue you are handling. Record the displayed policy category and the affected campaigns. If several policy issues are present, keep them separate in your working notes so that one correction does not get mistaken for another.
Classify each affected ad. Mark it as corrected and ready, believed compliant and ready to contest, still under investigation, or no longer relevant. “Eligible” is a platform state; “ready” is your operational decision.
Confirm the business scope. Prioritize campaigns that are active, scheduled to return, or otherwise important. A dormant campaign should not enter the batch merely because Google permits it to be selected.
Complete the necessary corrections. Check the ad and any connected experience involved in the issue. Do not use an appeal as a substitute for an unfinished change.
Select only the ready campaigns. Use “Select eligible campaigns” to exclude legacy or unfinished campaign groups from the bulk request.
Inspect the resulting batch. Look for older variations, mixed readiness inside a selected campaign, or ads that were changed after your internal review. Campaign filtering narrows the candidates; it does not replace this final check.
Log what you submitted. Keep the policy issue, campaign names or identifiers, submission date, correction status, and owner together. Your record should make it possible to reconstruct the batch without relying on memory.
Retain an excluded-work queue. List the campaigns you intentionally left out and the action each one needs. Exclusion should mean “not ready for this batch,” not “forgotten.”
This process is especially useful when one policy issue appears across many campaigns. Instead of waiting until every historical ad is repaired, you can prepare a coherent set of current campaigns and deal with lower-priority inventory separately.
Decide which campaigns belong in the appeal
Campaign status alone is not enough. A paused campaign might be scheduled to return soon, while an enabled campaign might contain obsolete creative. Base the decision on readiness and business intent together.
Include a campaign when all of the following are true:
You still intend to use the campaign or need its affected ads reviewed.
The relevant ads have been examined against the displayed policy issue.
Required corrections are complete, or you have a clear basis for believing the ads already comply.
The person submitting the appeal can explain why this campaign is in the batch.
You have checked for older ad variations that should not be resubmitted yet.
Leave a campaign out of the current batch when any of these conditions applies:
Its ads are obsolete, experimental, or attached to an offer you no longer use.
The corrective work is incomplete or has not been verified.
The campaign contains a mixture of resolved and unresolved ads that you have not yet sorted.
You cannot tell whether the campaign has an owner or a future purpose.
It belongs to an older account structure that you do not want to reactivate or revisit now.
Do not delete historical campaigns simply to make the appeal screen easier to manage. Deletion or removal can damage the account record you may later need. The campaign selector already gives you the less destructive option: leave irrelevant campaigns outside this request and document why.
When readiness varies widely, use waves. Submit the current, verified campaigns first. Move the next group only after its corrections and internal checks are complete. This makes the scope of each request easier to understand and prevents unfinished ads from riding along with urgent work.
Avoid the mistakes that recreate account-wide clutter
Campaign filtering is useful only if you resist turning it into another version of “select everything.” Watch for these failure modes.
Treating eligibility as approval readiness. An ad appearing in the eligible set does not tell you whether your team finished the correction or whether the campaign still matters. Apply your own readiness check.
Selecting a campaign without checking its ads. Campaigns can contain old variations alongside updated ones. Inspect the batch after applying the filter.
Mixing cleanup with policy reasoning. “We edited something” is not a complete explanation of readiness. Record what issue was addressed and whether the ad was changed or is being contested as compliant.
Resubmitting dormant inventory by habit. Older campaigns add noise when their ads have not been updated. Exclude them until someone deliberately reviews them.
Assuming a smaller batch guarantees a favorable or immediate result. Filtering improves scope control. It does not change the applicable policy or determine the outcome.
Keeping no record of exclusions. A clean appeal today can create a forgotten backlog tomorrow. Give every excluded campaign a reason, owner, and next action.
Account naming conventions can make this process easier. If campaign names clearly indicate market, offer, lifecycle, or status, you can scope a request with more confidence. If they do not, use campaign identifiers and a separate appeal log rather than guessing from similar names.
Key takeaways
Campaign-level appeals are a filter for selecting eligible ads, not a campaign-wide policy judgment.
Build the batch from ads and campaigns that are operationally ready, not from everything the interface marks eligible.
Exclude stale, unfinished, and low-priority campaigns from the current request without deleting their history.
Check the selected ads after filtering because a chosen campaign can still contain mixed states.
Record both submitted and excluded campaigns so that the next appeal starts from a reliable queue.
Before your next bulk appeal, create four working labels: ready after correction, ready to contest, still investigating, and no longer relevant. Select campaigns only after every affected ad has one. That small gate turns campaign filtering from a convenient button into a dependable policy workflow.
If conversions are rising while lead quality, margin, or inventory health is falling, do not start by tightening bids. Your PPC system may be doing exactly what you asked it to do, just not what the business needs.
That gap can be dramatic. A 417% surge in reported conversions can still conceal automation drift. The way back to control is not more manual bidding. It is a better definition of success, stronger conversion signals, explicit boundaries, and a review process that catches drift before the platform spends heavily against the wrong outcome.
Turn the business outcome into an optimization contract
An automated campaign cannot infer profit from a conversion count. It sees the objective, conversion actions, assigned values, targeting permissions, and creative options you provide. If those inputs reward cheap form fills, the system will find people who fill out forms. It will not independently discover that sales rejects most of them.
Before changing a bid strategy, write a short optimization contract for the campaign. It should answer seven questions:
What commercial result matters? Name the actual outcome: qualified pipeline, closed revenue, gross profit, profitable new customers, or another business result.
Which observable event best represents that result? A purchase may be sufficient for one store. A lead-generation campaign may need a marketing-qualified lead, accepted opportunity, or closed deal rather than a submitted form.
How is the event valued? Use actual value when it is available. When it is not, use a documented proxy based on historical progression and business economics.
How long does validation take? Record the delay between the ad interaction, the initial conversion, and the downstream business result. This stops the team from judging a slow sales cycle solely through immediate form counts.
What must the system avoid? Identify excluded locations, unsuitable queries, low-value products, unavailable inventory, restricted pages, and claims the ads must not make.
Which metric authorizes more spend? Specify the combination of volume, efficiency, quality, and value that justifies expansion. A platform conversion total alone should not be enough.
What evidence triggers intervention? Define the business-level warning signs that require a signal audit, reach restriction, budget change, or pause. Set these from your own economics rather than copying generic benchmarks.
This contract should shape the account architecture. A high-volume, low-margin product should not automatically share a target with a smaller, high-margin offer. When financially different outcomes are treated as equivalent conversions, automation can improve account-level revenue while weakening profit.
A practical profit-oriented structure separates campaigns or asset groups where the business needs independent budgets, target CPA settings, target ROAS settings, or eligibility controls. Useful dividing lines include margin tier, lead value, acquisition capacity, inventory condition, return rate, and new-versus-returning customer status.
Do not create a separate campaign merely because a category has a different name on the website. Create separation when the business would bid differently, cap spending differently, or evaluate success differently. Where independent control is unnecessary, labels and reporting dimensions may provide enough visibility without fragmenting the learning data.
Target CPA answers how much the system may spend to obtain the conversion you defined. Target ROAS answers how much reported value it should return for the spend. Neither setting can repair a weak conversion definition. They make the supplied definition more operational.
Engineer signals that represent quality and profit
Signal engineering is the central control function in AI-driven PPC. The bidding system needs timely, consistent, and economically meaningful feedback. More conversion data is not automatically better data. A smaller set of validated outcomes can be more useful than a large stream of actions that mix intent, quality, and accidental activity.
For lead generation, move beyond the form fill
A submitted form proves that someone completed a form. It does not prove that the person met your qualification criteria, entered the sales process, or generated revenue. If the initial submission is the only primary bidding signal, the algorithm has no reason to distinguish a high-potential prospect from a low-quality response.
Build the signal chain from the CRM backward:
Select the downstream stages that are defined consistently enough to guide bidding, such as marketing-qualified lead, sales-accepted opportunity, and closed/won.
Import those stages through offline conversion tracking or a direct CRM integration. HubSpot and Salesforce are common examples, while larger programs may use Search Ads 360 for cross-engine data management.
Assign values using historical progression and deal economics. An illustrative hierarchy of $10 for a raw lead, $50 for an MQL, and $500 for a closed deal demonstrates the principle, but your values must come from your own close rates and economics.
Decide whether stage values are cumulative or incremental. If one lead can generate several counted actions, a cumulative value at every stage can overstate its total contribution.
Keep stage definitions stable. If sales changes what qualifies as an opportunity, update the ad-platform mapping and annotate the change before comparing performance across the boundary.
Validate identifiers, timestamps, currency, values, and import status before allowing the downstream event to control meaningful spend.
A simple proxy calculation is historical probability of reaching the sale multiplied by the usable value of that sale. The usable value might be revenue, gross profit, or another approved measure. The important point is consistency: the value passed to the platform should represent the business objective in the optimization contract.
Do not remove the raw-lead action if the team still needs it for diagnostics. Keep it available for observation while making the deeper, validated event the bidding priority when data quality and volume permit. This preserves visibility without teaching the algorithm that every submission has equal value.
For ecommerce, make the feed carry business context
Revenue tracking is the baseline for ecommerce, not the final form of control. Two products can produce the same sale value while contributing very different profit after cost, returns, and inventory constraints.
Use custom labels to group products by margin tier, stock position, return behavior, or another factor that changes their commercial value.
Pass profit or margin information through the available conversion-value fields and variables when the implementation supports it.
Exclude or constrain products that cannot support additional demand, even if they have historically produced attractive platform ROAS.
Use first-party customer lists to distinguish new buyers from returning customers when acquisition strategy requires different values or bidding behavior.
Check whether feed titles, attributes, landing pages, and availability still represent what the business can sell profitably. The feed is part of the bidding system, not just a product catalog.
A product with a 40% return rate is a useful stress test. Revenue-based ROAS may look healthy when the initial sale is reported, while the underlying economics deteriorate after returns. If margin and return behavior never reach the bidding system, the system cannot account for them.
Separate new-customer acquisition from retention economics as well. An algorithm often finds the easiest available conversion, which may be an existing customer who already knows the brand. That can be efficient while overstating incremental growth. Give the platform a reliable way to identify customer status, then set values and targets that reflect what each type of order is worth.
Reported conversions rise while qualified leads, closed sales, or profit weaken.
Primary and secondary conversion actions, duplicate firing, CRM stage definitions, imported values, attribution changes, and missing offline events.
Stop using a corrupted action for bidding, preserve it for diagnosis if useful, repair the mapping, and validate the replacement before scaling.
Query drift
Spend moves toward broader or adjacent intent that converts cheaply but rarely produces the desired business result.
Search terms, brand versus non-brand mix, intent categories, match behavior, location intent, and downstream quality by query group.
Add exclusions, separate economically different intent, refine brand and location controls, or limit expansion that is not producing qualified value.
Inventory drift
Ads increasingly send traffic to pages or products that are available to the platform but unsuitable for the business objective.
Landing-page reports, URL expansion, stock status, margin labels, return behavior, service eligibility, and page-level conversion quality.
Exclude unsuitable URLs or products, correct feed labels, constrain expansion, and route traffic only to inventory that can satisfy the optimization contract.
Creative drift
Automated assets increase response by changing the promise, emphasis, or audience attracted by the ad.
Asset-level messaging, text customization, offer accuracy, landing-page continuity, legal or brand restrictions, and lead quality by message theme.
Remove misleading assets, tighten text controls, supply stronger approved alternatives, and ensure the landing page fulfills the ad’s promise.
We would inspect these in that order. Signal drift contaminates the evidence used to judge everything else. If the conversion action is wrong, changing bids or excluding queries can make the account look more controlled while the underlying measurement error remains.
Your review view should place three layers side by side:
The comparison matters more than any isolated metric. Rising conversion volume alongside falling qualification points first toward signal or query drift. Stable query quality with deteriorating margin points toward inventory mix. A sudden shift in respondent expectations can point toward creative drift.
Run this review after any material change to tracking, CRM stages, feeds, inventory, targets, landing pages, or automation settings. Also set a recurring review interval that matches your spending pace and sales-cycle delay. The interval should be short enough to limit financial exposure but long enough to include meaningful downstream outcomes.
Move to AI Max as a controlled change, not a blind handoff
AI Max combines search-term matching, text customization, and URL expansion, with controls involving brands, locations, and text. Those capabilities can discover demand that a narrow keyword-and-page structure misses. They can also widen three surfaces at once: who qualifies for the auction, what the ad says, and where the click lands.
Treat the migration like a measurement and eligibility change. Use this sequence:
Capture a stable baseline. Save the current conversion actions, assigned values, bidding targets, budgets, search-term mix, landing pages, asset set, brand settings, location settings, and downstream business results. Use a representative period rather than a period distorted by a promotion, outage, or tracking incident.
Reconcile conversion signals first. Confirm that the action controlling bids still matches the optimization contract. Fixing this after reach expands means the learning period was based on the wrong outcome.
Define reach boundaries. List brands, locations, query themes, URLs, product groups, and customer types that should or should not be eligible. Translate those decisions into the controls available in the account.
Audit the destination set. URL expansion should not have access to pages that are irrelevant, unavailable, low margin, or incapable of fulfilling the ad’s promise.
Prepare approved creative inputs. Give text customization accurate assets and landing-page language to work from. Document claims or themes that must remain off-limits.
Upgrade a controlled cohort before broad adoption where account options permit. Choose a campaign whose economics and downstream outcomes are well understood. Avoid mixing the migration with unrelated tracking, feed, landing-page, and budget changes.
Judge both efficiency and composition. Compare not only CPA or ROAS, but also query intent, landing-page mix, product margin, lead quality, customer status, and profit contribution.
Document the resulting state. Record which AI Max features and safeguards are active. Preserve the prior configuration and note which expansion settings can be reversed, even if returning to the retired campaign type will not remain possible.
Google says AI Max could produce an average 7% improvement in conversions or conversion value at similar efficiency. Treat that as a vendor-supplied directional claim, not a forecast for your account. An unchanged CPA or ROAS can still hide a worse commercial mix if the system shifts toward low-margin products, returning customers, or leads that never progress.
Early adoption is valuable when it gives you time to observe the new reach and tighten controls before an automatic migration. It is not valuable merely because it happens early. The test is whether the account produces more of the business outcome in the contract without violating its boundaries.
Key takeaways for keeping PPC automation accountable
Define the commercial outcome before selecting the bidding strategy. Conversion count is an input, not a substitute for profit or qualified growth.
Feed the system the deepest reliable outcome you can measure. For lead generation, connect CRM stages; for ecommerce, add margin, inventory, return, and customer-status context.
Separate campaigns when outcomes need different budgets, targets, or eligibility controls, not simply because the website has different categories.
Audit signal drift before changing bids. Bad measurement can make every downstream optimization decision look reasonable and still be wrong.
Review query, inventory, and creative composition alongside CPA and ROAS. Automation controls more than the auction price.
Treat AI Max migration as a controlled expansion of matching, messaging, and landing-page selection. Baseline the account, set boundaries, and test business outcomes before scaling.
Keep a change log that connects platform settings to downstream results. Human oversight works when it is a repeatable control process, not an occasional account check.
Your next move does not need to be a full account rebuild. Choose one campaign where platform success and business success have started to diverge. Complete its optimization contract, validate its deepest conversion signal, and run the four-part drift audit. Then stage any AI expansion against that clean baseline.
Let automation own auction speed and pattern detection. You should retain control of what counts as success, which opportunities are eligible, what the ads are allowed to promise, and when the evidence justifies more spend.
Your expensive search campaign may look weak for exactly the wrong reason. A buyer searches a high-intent term, spends several days validating options on Reddit, and clicks your ad only after forming an opinion. Your PPC platform sees the costly click and the conversion that did or did not follow. It usually cannot see the research that made the click valuable.
Reddit can influence a conversion without receiving credit
PPC reporting works best when the path from click to outcome is short and observable. Reddit makes that path harder to interpret because buyers can move between search results, community discussions, vendor pages, internal conversations, and later searches before they submit a form or make a purchase.
Smart Bidding does not know that someone spent three evenings comparing recommendations, reading complaints, or checking whether a product works in a particular situation. It learns from the events you send back: clicks, on-site conversions, imported lead stages, and conversion values. If the valuable business outcome arrives late or never returns to the ad platform, automation has an incomplete training signal.
That creates three related problems. They can happen at the same time, but each requires a different response.
Problem
What you observe
What to do
Organic displacement
A Reddit discussion appears where buyers might otherwise discover your educational content.
Improve the content that answers the query and participate in relevant discussions transparently.
Journey invisibility
The buyer researches elsewhere and returns later, leaving no clean connection between the research and the conversion.
Use CRM evidence and lightweight self-reported attribution to supplement platform reports.
Bidding distortion
An expensive click looks unproductive because qualification, pipeline, or revenue arrives after the platform’s shallow conversion signal.
Import downstream conversion events and values through the original ad click identifier.
There may also be a search-side effect. A Reddit result that repeatedly satisfies a query can reinforce its perceived relevance, although advertisers cannot inspect that mechanism or calculate its causal weight. Treat that as a reason to strengthen your presence around the topic, not as a metric you can place in a forecast.
The practical consequence is clearest in legal, finance, insurance, and premium home services, where high CPCs make a delayed or misclassified conversion especially expensive. The same mechanism can affect other industries whenever the purchase involves risk, comparison, or a long evaluation period.
Diagnose the Reddit effect before cutting a keyword
Do not begin by assuming that Reddit caused a performance problem. Begin with a cohort analysis that can distinguish weak intent from incomplete measurement. You want to know whether mature clicks produce better business outcomes than the current PPC dashboard implies.
Select one meaningful campaign. Start with a high-intent campaign that has material spend, costly search terms, and a sales process long enough for research to occur. A narrow test is easier to reconcile than an account-wide audit.
Use a mature click cohort. Choose clicks old enough to have passed through your normal sales cycle. A current-period report excludes deals that have not had time to close, so it cannot answer whether those clicks were economically sound.
Join ad and CRM records. Where your access and privacy controls allow it, connect the supported ad click identifier to the lead, qualification date, opportunity stage, close date, and realized value. Keep unsuccessful leads in the dataset; otherwise, you will inflate performance.
Classify Reddit visibility. Review a representative set of important queries under consistent market, device, and location conditions. Record whether a Reddit result is prominent, merely present, or absent. Search results can vary, so retain the date and conditions instead of treating one check as permanent.
Compare downstream economics. For the Reddit-visible and comparison cohorts, calculate qualified-lead rate, close rate, time to qualification, time to close, and value per click. CTR and immediate conversion rate are useful operational metrics, but they do not tell you whether a click ultimately created revenue.
Add customer evidence. Search sales notes for references to Reddit, forums, peer recommendations, or online research. If those notes are inconsistent, add a short post-conversion question asking what influenced the decision. Self-reported attribution will be incomplete, so use it as directional evidence rather than a replacement for click-level data.
What the patterns actually mean
Weak immediate results but healthy mature revenue: The keyword may be attracting research-heavy buyers. Fix conversion feedback before reducing bids.
Plenty of leads but poor qualification and close rates: The issue is more likely query intent, targeting, offer fit, or lead quality. Reddit research does not excuse bad economics.
A long sales lag with profitable mature cohorts: Your reporting window and bidding inputs are too shallow for the actual journey.
No material difference when Reddit is visible: Do not force the hypothesis. Reddit may be present in the search results without meaningfully changing that campaign’s performance.
Strong closes from only a few isolated deals: Do not redesign bidding around a tiny sample. Keep collecting downstream outcomes until the pattern is stable enough to guide budget.
This analysis prevents a common mistake: cutting a costly keyword because its short-window cost per lead looks poor even though its mature customers are valuable. It also protects you from the opposite mistake of defending an expensive keyword with an attractive story that the CRM cannot support.
Give Smart Bidding the outcomes that matter to the business
Offline conversion tracking closes part of the gap between PPC activity and the sales process. Its purpose is not merely to produce a richer report. It tells the bidding system which clicks generated qualified demand and what those outcomes were worth.
Capture the click connection at lead creation. Store the ad platform’s supported click identifier with the form submission or other lead record. Preserve campaign parameters as secondary context, but do not rely on manually typed source fields as the only connection.
Define unambiguous lifecycle events. Choose milestones that represent real progress, such as an accepted qualified lead, a completed sales appointment, an approved application, a signed agreement, or a closed sale. A stage should mean the same thing across salespeople and campaigns.
Return more than the first form fill. Send the relevant qualification and revenue events back when the CRM status changes. If the platform receives only form submissions, it will optimize toward people who fill out forms rather than people who become valuable customers.
Use defensible values. Import realized value for completed transactions when it is available. For earlier stages, use a proxy only if the business can explain how it was derived and updates it when close rates or economics change.
Reconcile before changing bid strategy. Compare imported counts and values with the CRM, check that repeat updates are handled correctly, and investigate missing identifiers. An unreliable offline feed can teach automation the wrong lesson faster than no feed at all.
Optimize to the deepest reliable event with sufficient volume. A closed sale is closest to business truth, but it may be too rare or delayed to guide bidding by itself. A consistently defined qualified-lead event can be a more practical optimization input while closed revenue remains the final evaluation metric.
Do not switch bidding goals on the day you start importing data. First confirm that the feed is complete, the stage definitions are stable, and enough valid events are arriving for the chosen campaign. Otherwise, a measurement repair can become an abrupt targeting change with an unclear cause.
Compete for the research moment, not just the ad click
Measurement can reveal Reddit’s influence, but it cannot remove the buyer’s need for candid information. If community discussions rank because they answer questions that vendor pages avoid, another bid adjustment will not solve the underlying problem.
Build an owned answer for each recurring uncertainty you find in search results and community discussions. Useful formats include a plain-language glossary, a balanced alternatives page, an explanation of cost drivers, implementation requirements, common failure modes, limitations, and a clear account of who the offer is not for. The standard is not more copy. It is fewer unanswered questions.
For every expensive, high-intent term, maintain a simple research map:
The query and the decision it represents.
Whether Reddit appears prominently for that query.
The questions, objections, and trade-offs visible in the discussion.
The owned page that answers those points directly.
The ad and landing page that continue the same line of thought.
The on-site and offline conversions used to evaluate the term.
The date when enough sales-cycle time has passed for a fair review.
You can also participate where the discussion occurs. Answer the question being asked, disclose a relevant affiliation, separate facts from opinion, and link only when the destination genuinely helps. Undisclosed promotion and manufactured recommendations are especially damaging in a channel whose value comes from perceived peer candor.
Keep PPC copy aligned with what buyers are trying to verify. If the recurring concern is implementation complexity, eligibility, pricing structure, or a known limitation, generic claims will feel evasive after a detailed community discussion. Address the decision factor directly and make sure the landing page supplies the promised evidence.
Key takeaways
Reddit can be a meaningful pre-click research touchpoint even when it receives no credit in your PPC attribution.
Do not judge an expensive keyword solely on recent clicks or first-stage conversions; evaluate a cohort that has had time to qualify and close.
Compare Reddit-visible queries with other queries using qualified-lead rate, close rate, sales lag, and value per click.
Capture supported ad click identifiers and import downstream outcomes so bidding can distinguish form volume from valuable demand.
Use the deepest stable conversion event that occurs often enough to guide automation, while retaining closed revenue as the business truth.
Answer the questions that make buyers choose Reddit in the first place, both through useful owned content and transparent community participation.
Start with one campaign where high CPCs and a long sales process make bad decisions costly. Reconcile its last fully matured click cohort with CRM outcomes, label the queries where Reddit is visible, and repair the offline feedback loop before changing bids. If the economics improve as later outcomes arrive, measurement is the first problem to fix.
If Claude gives you a strong search-term analysis only after you paste the same instructions and CSV into a new chat, you have improved the task, not automated it. You still have to assemble the context, request the analysis, normalize the output, and move each approved change into Google Ads.
Claude-powered PPC automation becomes useful when you design those handoffs once. The practical system has three separate parts: decision logic, access to current campaign data, and controls over what the AI may change. Get those parts right and Claude can take recurring work off your desk without taking campaign authority away from you.
The three parts of a reliable Claude PPC system
The model is only one layer of the system. A dependable workflow also needs a stable playbook and an explicit operating boundary.
System part
What it does
The question you must answer
Claude Skill
Encodes the task, decision rules, required inputs, exceptions, and output structure.
What should happen every time this PPC job runs?
Data and tools
Supply campaign context and, when authorized, provide a way to execute an approved action.
Which data may Claude read, and which operations may it call?
Workflow controls
Define scope, approval requirements, stop conditions, and records of proposed or completed changes.
What is Claude allowed to decide, recommend, and change?
A Claude Skill is a task-specific playbook, not a general preference about tone or behavior. It can tell Claude how to audit an account, evaluate search terms, generate ad assets, or compare budget opportunities. The instructions can be stored in a Markdown file, kept locally, or shared through a repository so the team uses the same method.
The main benefit is procedural consistency. Without a fixed contract, one run might return letter grades while another uses percentages or an unrelated numerical scale. That is more than a presentation problem. A person, spreadsheet, script, or approval workflow cannot reliably consume an output whose structure changes between runs.
A Skill should make the process predictable, but it should not pretend every PPC judgment is deterministic. Campaign evidence changes, and some cases will remain ambiguous. Your playbook therefore needs both decision rules and an explicit way to return insufficient evidence, conflicting signals, or required human review.
The data layer solves a different problem. A Skill can know how to evaluate a search query report while knowing nothing about the queries currently appearing in your account. A Model Context Protocol connection can bridge that gap: MCP can connect Skill logic to live data sources and account tools. That turns a static playbook into an operating workflow, but it also makes permissions and approval gates essential.
Build the first workflow around one recurring decision
Start with a bounded job rather than asking Claude to optimize an account. Search-term mining is a practical first candidate because you can define the input, inspect every recommendation, and test the logic without granting write access.
Define the job in one sentence. For example: review search terms from the requested 14-day window, identify waste and opportunity using the account’s approved criteria, and return proposed actions for review. The 14-day period is an input to this workflow, not a universal recommendation for every account.
Write down the judgment currently living in the operator’s head. Include the evidence Claude must consider, the conditions that support each recommendation, the exceptions that require escalation, and anything it must never infer from missing data.
Lock the output contract. Name every required field, its allowed values, and what a stopped run looks like. Do not let Claude invent a new scoring system or column set each time.
Convert the SOP into a Skill. A useful instruction is: Convert this SOP into a task-specific Claude Skill. Preserve the decision rules, define required inputs, return a fixed schema, stop when required fields are missing, and do not take write actions without approval.
Run the Skill against a known CSV before connecting an account. Confirm that it covers the intended records, follows the rubric, flags exceptions, and returns the exact structure your reviewer or downstream tool expects.
Connect live data in read-only mode. Compare the live run with the CSV-based process. Add write capabilities only after the connected workflow passes the same acceptance checks.
A useful output contract for this workflow can require:
The account, campaign, and reporting window included in the run.
A completion status that distinguishes a finished analysis from a stopped or incomplete run.
The item reviewed, the evidence used, and the applicable decision rule.
The proposed action and a concise reason for it.
An exception field for missing inputs, conflicting signals, or cases outside the Skill’s authority.
An authorization state such as proposal, approved, executed, or rejected.
The output contract is what turns a clever response into a component another person or system can trust. Claude should never quietly substitute a plausible answer when a required campaign field is unavailable. A stopped run with a precise error is safer and more useful than a polished recommendation built on incomplete context.
Put money-changing actions behind explicit gates
Access and authority are not the same thing. An MCP-enabled tool may make an account change technically possible, but your workflow still decides whether Claude may propose it, prepare it, or execute it. That distinction matters whenever an action can change spend, targeting, messaging, or delivery.
Operating mode
Claude’s role
Human role
Manual-context assistant
Analyzes an uploaded report and returns structured recommendations.
Exports data, checks the result, and implements every change.
Connected analyst
Pulls permitted live data and prepares account-specific proposals.
Reviews and approves each proposed action before execution.
Controlled operator
Executes only approved action types within the defined scope and constraints.
Sets policy, handles exceptions, reviews logs, and can stop the workflow.
Most teams should move through these modes in order. Live read access removes manual report handling without immediately exposing the account to automated edits. Proposal-only operation then shows whether the logic behaves well under current conditions. Controlled execution comes last, after the team knows which exceptions appear in real runs.
Before enabling any write action, add these controls to the workflow:
Default-deny permissions. Claude may read or modify only the accounts, campaigns, objects, and action types explicitly included in scope.
Action-specific approval. Treat applying an existing extension, creating an ad experiment, changing a search-term response, and reallocating budget as separate permissions.
User-defined financial boundaries. A budget workflow must operate inside limits set by the account owner rather than deciding its own acceptable spend change.
Fail-closed behavior. Missing data, an invalid schema, an unavailable tool, or an out-of-scope request should stop the run instead of triggering a best guess.
A preview of the exact modification. The reviewer should see what object will change, its current state, the proposed state, and the reason before approving it.
An audit trail. Preserve the input scope, Skill version, findings, approval state, tool response, and execution result so a later reviewer can reconstruct what happened.
A conflict rule. Give each task one canonical Skill, because overlapping audit or optimization Skills can reintroduce the inconsistency the system was built to remove.
A recovery plan. Document how an executed change will be reversed when reversal is available. Keep irreversible or poorly understood actions manual.
Budget reallocation deserves the tightest gate because it moves money between campaigns. A recommendation can still be automated: Claude can compare the permitted data, explain the proposed shift, and prepare the action. Execution should remain subject to the account owner’s constraints and approval until the workflow has demonstrated reliable behavior in proposal-only mode.
Use acceptance checks rather than impressions when deciding whether a workflow is ready. The run should always return the required fields, stop on missing inputs, stay inside its declared scope, expose the evidence behind each proposal, and show the planned modification before execution. If any of those checks fail, improve the Skill or connection before expanding its authority.
Choose PPC tasks by controllability, not novelty
The best first automation is not necessarily the task consuming the largest budget or producing the most visible output. It is the task whose rules can be written clearly, whose evidence can be inspected, and whose mistakes can be contained.
PPC workflow
What the Skill should standardize
First safe deployment
Expanded deployment
Search-term mining
The evaluation rubric, required evidence, exception handling, and recommendation format.
Analyze an uploaded report and return proposals for review.
Pull live search-term data and implement only separately approved actions.
Ad copy generation
How landing-page information, keywords, user intent, and value propositions become proposed ad assets.
Generate structured drafts for human review.
Identify underperforming ads, prepare alternatives, and create an approved experiment.
Account auditing
The checklist, severity logic, supporting evidence, and distinction between findings and remedies.
Return a consistent audit with no account changes.
Use live account data and apply permitted remedies, such as attaching an existing extension where appropriate.
Budget reallocation
The comparison method, constraints, explanation, and escalation conditions.
Produce proposed reallocations with no write access.
Execute approved shifts inside account-owner limits and record every result.
Score a candidate workflow against five practical questions before building it:
Does the task recur often enough that removing handoffs will matter?
Can an experienced operator state the decision rules without relying on unexplained instinct?
Are the required inputs available in a stable, inspectable form?
Can a reviewer verify the recommendation before the account changes?
Can the impact of an error be contained to a narrow scope?
If the answers are weak, connecting more tools will not improve the workflow. Clarify the SOP first. Automation magnifies whatever is encoded: good judgment becomes repeatable, while an ambiguous process becomes ambiguous at greater speed.
For a first deployment, we would favor a proposal-only search-term or account-audit workflow. Both make it easy to compare Claude’s output with an existing human process. Ad experiments can follow once asset review is defined. Budget execution belongs later because its consequences reach spend directly.
Frequently asked questions
What is Claude-powered PPC automation?
It is a workflow in which a Claude Skill applies a repeatable PPC playbook, data connections supply the required campaign context, and explicit permissions determine whether Claude analyzes, proposes, or executes an action. A chat response alone is assistance; automation also handles the recurring context and handoffs.
Do you need MCP to use a Claude Skill for PPC?
No. You can run a Skill against a manually uploaded CSV and implement its recommendations yourself. MCP becomes relevant when you want Claude to retrieve live data or use connected account tools. Start with manual or read-only data if the Skill’s decision logic has not yet been validated.
Which PPC workflow should you automate first?
Choose a recurring workflow with written rules, inspectable inputs, a fixed output, and limited consequences when something goes wrong. Search-term mining or a checklist-based audit is usually easier to validate than autonomous budget reallocation. Keep the first version proposal-only so you can judge the logic before granting execution authority.
How do you prevent inconsistent Claude outputs?
Use one canonical Skill for the task, define required fields and allowed values, state how exceptions must be returned, and stop the run when required data is missing. Remove or narrow competing Skills that could handle the same request. Test structural consistency before connecting the output to another tool.
Take the next recurring search-term review or account audit and write down its rubric, output contract, and stop conditions. Test that process on a CSV, connect live data in read-only mode, and grant write access only after the workflow passes explicit acceptance checks. That sequence turns Claude from another prompt window into a PPC system you can supervise.
If you are six to 15 years into PPC and your pay has barely moved, adding another platform badge probably will not solve the problem. The market is not discounting every paid search professional equally. It is separating people who execute campaigns from people who influence revenue, margin, budgets and business decisions.
That distinction gives you something useful to work with. You can benchmark the role you actually hold, identify the work keeping you in the compressed middle and build evidence for a better-paid agency, in-house or independent position.
Your employment model matters. In-house medians exceeded agency medians in every U.S. experience band reported for 2026, although the unusually high six-to-nine-year in-house figure was influenced by outliers.
AI fluency is becoming an expected capability rather than a separate reason to pay more. The valuable question is what decisions you make with the time automation gives back.
The strongest promotion case connects campaign choices to the commercial metrics your company uses, while stating attribution limits honestly.
Salary medians are market signals, not promises. Compare the same country, city, employment model, scope and compensation structure before judging an offer.
The salary curve starts branching after five years
The three-to-five-year rebound matters: employable early-to-mid-career practitioners are not simply being pushed toward lower pay. The pressure is more concentrated. The six-to-nine-year median returned to its 2022 level, while the 10-to-15-year median stayed between $133,500 and $136,000 for three consecutive years. That is nominal stagnation before you consider any loss of purchasing power.
Experience still matters, but years alone no longer explain the result. U.S. practitioners in the 10-to-15-year band included top salaries above $300,000 alongside a $135,000 median. That spread is salary polarization in practical terms: people with similar time in the field can occupy very different economic roles.
Do not turn the median into the salary you believe you are owed. The 2026 figures came from 445 practitioners across more than 50 countries, so smaller slices can move with the respondent mix. Use the numbers to ask why your role sits where it does, then compare your responsibilities with positions on the other side of the divide.
Do not import a U.S. benchmark into another market
Country and city can change the benchmark substantially. In the U.K., the 10-to-15-year median fell from £60,000 in 2025 to £50,000 in 2026. Across Europe, the corresponding median rose from €50,000 in 2024 to €65,625 in 2026, while the three-to-five-year median fell to €37,200, below its 2022 level. Berlin sat higher than the broader European figure, at approximately €76,000 for the 10-to-15-year band.
Your benchmark should therefore match the market in which the employer sets pay, not merely the market in which its customers live. Compare currency, location, employment type and experience band before you use any figure in a negotiation. A global median may be interesting, but a local role with comparable scope is the more relevant reference.
Those medians identify a disparity; they do not establish a single cause. Negotiation, promotion paths and access to high-value commercial relationships may contribute, but the aggregate numbers cannot isolate their effects.
If you are assessing your own position, look beyond title and tenure. Record the accounts, budgets, revenue decisions and executive forums you are trusted to influence. Ask for the compensation band, the criteria for its upper end and the scope required for the next level. If you manage a team, compare pay and opportunity across people doing genuinely comparable work, then inspect who receives strategic accounts, client exposure, sponsorship and revenue ownership. A pay-equity review that ignores access to those career-making assignments will miss part of the mechanism.
Your employment model is part of your compensation
A job title does not tell you how close the role sits to a commercial decision. The 2026 U.S. agency and in-house medians make that difference visible:
Experience
Agency median
In-house median
In-house difference
3-5 years
$80,000
$89,000
+$9,000
6-9 years
$90,000
$170,000
+$80,000
10-15 years
$123,545
$140,000
+$16,455
15+ years
$120,000
$140,000
+$20,000
The $170,000 in-house median for six to nine years was affected by outliers, so it should not be treated as a dependable offer target. The broader pattern is more useful: every in-house median exceeded the agency equivalent, and the 10-to-15-year difference was $16,455. The agency median also slipped from $123,545 at 10 to 15 years to $120,000 at 15 or more years. Seniority without a material change in scope did not produce a higher median in that slice.
Agency experience can still build broad category knowledge, rapid diagnostic skill and exposure to many business models. The compensation problem appears when the role remains packaged as campaign delivery. Automation makes repeatable execution harder to bill as scarce expertise, and an agency cannot sustainably pay high salaries from work clients perceive as interchangeable.
In-house roles can place paid media closer to forecasting, finance, product, inventory, sales and customer economics. That proximity creates an opportunity to influence decisions larger than the media account. It does not happen automatically. An in-house specialist who only receives a budget and returns a dashboard can remain execution-bound even with a better title.
Independence creates a different ceiling. U.S. freelancers with comparable senior experience had median income of $202,895, compared with an agency median of $123,545, a difference of roughly $79,000 in the available data. Do not interpret that difference as an automatic raise. Freelance income and employee salary are not equivalent: benefits, taxes, business expenses, unpaid selling time, demand volatility and time off can all change what reaches you and how predictable it is.
Treat employment model as a strategic variable rather than an identity. You do not need to leave agency work merely because an in-house median is higher. You do need to know whether your current environment can give you commercial ownership, high-value relationships and evidence that another employer or client will recognize.
AI fluency is the floor, not the compensation case
AI can make you faster without making your role more valuable. PPC professionals were saving approximately 5.2 hours per week with AI, yet corporate compensation practices point in the same direction: 61% of companies required AI skills while 55% offered no additional benefits for having them.
The message is not that AI is unimportant. It is that tool access and basic fluency are becoming normal job requirements. A prompt library, automated analysis or faster draft is useful operational evidence, but it does not by itself prove that you should occupy the upper end of a salary band.
Separate three kinds of value when you describe your work:
Task speed: You produce queries, briefs, summaries, variants or first-pass analyses faster.
Decision quality: You verify the output, identify missing context, reject weak recommendations and choose an appropriate action.
Commercial ownership: You connect that action to revenue, margin, forecast risk, customer quality or another metric the business uses to allocate money.
The first layer can save time. The second protects the business from confident but incomplete output. The third gives leaders a reason to expand your scope and compensation.
Reinvest the time AI saves in work that is difficult to commoditize. Meet the people who own finance, sales or product assumptions. Learn which conversions become profitable customers and which merely make the dashboard look healthy. Document where attribution is uncertain. Turn a recurring performance update into a recommendation that states the decision, expected business effect, risk and next check.
When an AI-generated report arrives, the valuable person is not the one who can restate it most quickly. It is the person who can explain what is credible, what is missing and what the company should do next.
Build evidence that you own outcomes, not just campaigns
A vague claim that you are strategic will not move a compensation discussion. Build a small body of evidence that lets a hiring manager, client or executive see how you think. You can do this inside your current job before changing roles.
Start with a real decision. Choose a budget allocation, measurement dispute, audience change, channel trade-off or forecast question you influenced. Routine optimizations are less persuasive unless they changed a larger decision.
Name the business constraint. State what limited the choice: margin, inventory, lead quality, sales capacity, brand rules, measurement reliability or another genuine constraint. This demonstrates that you were not optimizing an account in isolation.
Show your reasoning. Record the alternatives you considered, why you rejected them and what evidence changed your view. A result without reasoning can look accidental and is difficult for another employer to generalize.
Follow the metric beyond the platform. Connect the paid-media signal to the furthest reliable business outcome available. Stop where the evidence stops instead of claiming credit for revenue you cannot support.
Include uncertainty and downside. Explain attribution limitations, external factors and what could have invalidated the decision. Senior judgment includes knowing when the data cannot carry a confident conclusion.
State what happened next. Record the action taken, the observed result and how the result influenced a subsequent budget or strategy decision. Remove confidential names and figures before using the case outside the company.
A useful case-study sentence follows this structure: Because [business constraint], we chose [decision] over [alternative], which affected [business metric] during [relevant period]; [limitation] means the result should be interpreted as [appropriate level of confidence].
Translate the metric ladder for your business model
ROAS and CTR can be useful diagnostic metrics, but they are not interchangeable with profit. Your evidence should show that you understand the chain between an ad-platform result and the economic outcome the company values.
For ecommerce, follow reported conversion value toward realized revenue, gross margin or contribution margin where those figures are available. Call out returns, discounts or product-mix effects when they change the interpretation.
For lead generation, distinguish a form submission from a qualified opportunity and a qualified opportunity from closed revenue. If sales feedback is missing, identify that gap rather than presenting lead volume as the final outcome.
For subscriptions, separate initial acquisition from activation, retention and customer economics. A cheaper signup is not necessarily a more valuable customer.
You do not need to own every downstream function. You need to understand how paid media enters the system, which handoffs can break and what evidence is required before the company increases or withdraws investment.
Change the questions in your performance meetings
The questions you ask reveal whether you are operating at campaign or business level. Bring questions that can change an allocation decision:
Which conversion event is most closely connected to realized revenue?
Which costs or downstream losses are absent from the current ROAS calculation?
What would make us reduce spend even if platform efficiency improved?
Where does sales, finance or product data disagree with the ad-platform view?
What decision will leadership make from this dashboard?
What evidence would justify moving more budget, and what evidence would stop us?
Capture the answers and incorporate them into the next recommendation. That creates a visible record of scope expansion instead of waiting for a title change to prove you are ready.
Choose the lane you are actually preparing for
The right next move depends on the kind of risk, access and responsibility you want. Use the salary data to identify possibilities, then test whether the role gives you the conditions needed to create higher-value evidence.
Lane
What to seek
Evidence to build
Main risk to examine
Agency
Commercial strategy, executive client access, measurement ownership and influence over account direction
Decisions that improve client economics, resolve strategic uncertainty or expand trusted scope
A senior title that still consists mainly of repeatable campaign delivery
In-house
Access to finance, product, sales, inventory and forecasting decisions
Budget recommendations connected to unit economics and company priorities
A channel silo that receives targets but cannot influence the assumptions behind them
Freelance or consultancy
A differentiated problem, identifiable buyers, pricing power and a repeatable way to win work
Credible outcome cases, a clear offer and proof that clients value your judgment
Treating business income as employee-equivalent pay without accounting for costs and volatility
Before applying or negotiating, audit a representative period of your calendar. Label each substantial task as execution, decision support or business-outcome work. Then inspect the evidence, not just the time spent. If nearly every artifact is a build sheet, optimization log or platform dashboard, your strategic contribution may be real but invisible. Replace one recurring status report with a decision memo that links performance to a commercial choice.
Use that memo in a scope conversation. Explain the decisions you already influence, show the evidence and ask what additional ownership is required for the target role and compensation band. If the employer cannot define that path or provide access to the necessary work, you have learned something more useful than a generic promise about future progression.
Your next move does not have to begin with a resignation. Begin by changing the unit of value you present: from campaigns completed to decisions improved. That shift will tell you whether your current role can grow with you or whether it is time to take your evidence somewhere that prices it differently.
Your PPC account may already use automated bidding, AI-assisted targeting, and generative tools, yet still leave you unsure whether the system is making good decisions. That uncertainty usually isn’t a reason to abandon AI. It is a reason to tighten the operating system around it.
A dependable AI-assisted PPC strategy has a clear order: verify the business data, simplify the account around meaningful decisions, constrain automation where failure would be expensive, and turn every recommendation into a test. Follow that order and AI becomes easier to trust because its work remains visible, measurable, and reversible.
Start by proving that your ROAS means what you think
Your first AI decision isn’t which model, campaign type, or bidding strategy to use. It is whether the conversion value entering the system represents the business result you intend to optimize.
ROAS is calculated by dividing attributed conversion value by advertising cost. The calculation is simple, but the inputs can be misleading. A dashboard may produce a precise ratio even when its currencies, conversion actions, or imported revenue values are inconsistent.
Currency errors are particularly dangerous because they can affect reporting without producing an obvious technical failure. In one paid-media account, a mismatch between an Australian billing setup and reporting in GBP distorted conversion values so severely that CRM reconciliation showed actual performance was twice the reported level. An optimization decision made from the advertising dashboard alone would have started from the wrong diagnosis.
Before changing bids, budgets, or account structure, audit the measurement chain:
Confirm the account billing currency, conversion-value currency, and reporting currency. Document every intentional conversion between them.
Compare advertising-platform revenue with CRM, order-management, or finance data over equivalent reporting periods.
Verify which conversion actions are included in bidding. Remove duplicate or secondary actions from the primary optimization signal unless they represent genuine incremental value.
Check whether cancellations, refunds, offline sales, and qualified leads are handled consistently.
Record the attribution view and normal conversion delay so that the team does not compare numbers built on different rules.
Name the system that decides the final business outcome. The ad platform may guide bidding while the CRM remains the authority for lead quality or realized revenue.
Treat disagreement between systems as a diagnostic signal, not an inconvenience to average away. If the platform and CRM both decline, the performance problem may be real. If platform revenue falls while CRM revenue remains stable, investigate tracking, attribution, currency, and reporting logic before rebuilding campaigns. If platform ROAS rises while qualified revenue stays flat, the bidding system may be optimizing toward a convenient but weak proxy.
This audit protects more than reporting accuracy. Automated bidding learns from the values you send it. A corrupt value is therefore both a measurement problem and an instruction to spend money in the wrong places.
Build an account structure AI can learn from
Many legacy PPC structures were designed when control meant separating almost every keyword, product, market, or match type. That granularity made sense when practitioners performed more decisions manually. It can work against automated systems when it fragments related data and creates thousands of campaign-level boundaries.
Keep campaigns separate when the boundary changes a real decision, such as:
A distinct business objective or conversion action.
A materially different margin, customer value, or acceptable acquisition cost.
A budget that must be protected or controlled independently.
A geographic, language, regulatory, inventory, or landing-page difference that changes eligibility or performance.
A brand-protection requirement or an exclusion that cannot safely be shared.
Consider combining structures when the only distinction is an inherited naming convention, a reporting preference that can be handled with labels, or a keyword taxonomy that does not change bidding economics. The goal is not the fewest possible campaigns. It is the fewest boundaries needed to express genuine business constraints.
Restructure in stages rather than replacing the account in one irreversible move:
Map every existing campaign to its objective, budget owner, conversion signal, audience, destination, and economic target.
Mark the boundaries that affect business decisions and the ones that exist only because of account history.
Capture a clean performance baseline and annotate known tracking or seasonal issues.
Migrate a representative, lower-risk portion first. Check query routing, budgets, conversion recording, and lead or revenue quality.
Expand only after the new structure behaves as intended. Retain a documented rollback path while the change is being evaluated.
Timing matters as much as architecture. A peak trading period is a poor moment for a sweeping rebuild, but indefinite postponement creates its own risk. One delayed restructuring effort had to be accelerated after performance weakened in January, creating the pressure the delay was meant to avoid. Choose a lower-risk implementation window with enough runway to validate the new structure before the next commercially critical period.
Put guardrails around automated bidding
Using automation does not require giving the platform unlimited freedom. Your job is to define the objective, provide trustworthy signals, decide which decisions the system may make, and set boundaries around outcomes the business cannot tolerate.
Useful controls can include campaign budgets, portfolio boundaries, eligible locations, audience exclusions, conversion-action selection, inventory rules, and bid limits where the chosen platform and strategy support them. Pick the control that addresses the observed failure mode. Do not add constraints merely to make an automated campaign feel more manual.
A max CPC cap applied within portfolio bidding once reduced click costs without damaging performance. That is evidence that a well-chosen boundary can improve an automated system, not proof that every account needs the same cap. A cap set below the price of useful auctions can suppress traffic, conversion volume, and access to high-value prospects.
Use a guardrail protocol whenever you intervene:
Name the failure precisely. Runaway CPC, weak lead quality, overspending in one segment, and volatile total spend are different problems.
Capture the baseline. Record CPC, click volume, conversion volume, attributed value, and the CRM outcome that matters to the business.
Change one meaningful control. If you alter the cap, budget, targeting, and conversion setup together, you will not know which change produced the result.
Allow for the normal conversion cycle. A constraint can look efficient immediately because it reduced traffic, while its effect on qualified revenue appears later.
Judge the business result. Lower CPC is not a win if profitable volume, lead quality, or realized revenue also falls.
Keep the decision reversible. Define in advance which outcome means keep, loosen, or remove the constraint.
This is the practical middle ground between blind automation and constant manual interference. The algorithm keeps enough freedom to respond to auctions, while you retain control over the economics and risk.
Prompt generative AI like an analyst with a proper brief
A request such as analyze this campaign gives the model no reliable definition of success. It does not know whether you care about revenue, qualified leads, margin, new customers, market coverage, or budget stability. It also does not know which fields are facts, which are calculated metrics, or which constraints it must respect.
Build PPC prompts from seven parts:
Context: Describe the business model, campaign type, funnel stage, audience, and decision you face.
Objective: State the business outcome and the advertising metric being used as its proxy.
Data definitions: Explain the reporting period, currency, attribution view, conversion delay, and meaning of each important field.
Evidence: Supply only the relevant account, CRM, and historical information. Label missing or unreliable fields.
Constraints: Include budget limits, brand rules, geographic boundaries, minimum volume requirements, and changes that are off limits.
Task: Ask for a specific deliverable, such as ranked hypotheses, an anomaly check, or a test plan.
Output rules: Require the model to separate observations from inferences, identify missing evidence, and state what would disprove each recommendation.
A reusable prompt frame can be short: Review the supplied PPC and CRM data to explain the change in qualified revenue. Use the definitions and constraints below. Separate measured facts, plausible causes, and unsupported possibilities. Rank the hypotheses by evidence strength. For each one, give the confirming evidence, conflicting evidence, next check, and safest reversible test. Mark missing information as unknown rather than filling the gap.
That last instruction matters. Fluent output can conceal uncertainty. Asking for competing explanations and disconfirming evidence makes it easier to spot a recommendation that merely sounds plausible.
Protect client and customer data as you work. Remove customer-level identifiers, avoid pasting credentials or confidential commercial details into unapproved tools, and follow the data-use rules that apply to your organization. AI assistance does not change your responsibility for access control or final decisions.
Turn every change into a controlled learning loop
A test-and-learn culture is not permission to make a stream of undocumented changes. It is a discipline for converting uncertainty into evidence without putting the whole account at risk.
For every material test, create a decision record containing:
The problem being addressed and the evidence that it exists.
The hypothesis linking the proposed change to the expected outcome.
The primary business metric and the secondary indicators that guard against a hollow win.
The account segment affected and what remains unchanged for comparison.
The expected conversion delay and the condition for making a decision.
The owner, approval, annotation, and rollback procedure.
Match the evaluation cadence to the account’s conversion volume and sales cycle. A low-volume campaign should not be judged with the same rhythm as a high-volume retail account, and a lead-generation campaign should not be declared successful before downstream quality becomes visible.
When performance falls, resist the urge to stack speculative fixes. Validate tracking and currency first. Review recent account and site changes. Locate whether the decline is concentrated by campaign, query class, audience, location, device, or conversion action. Reconcile platform outcomes with CRM results. Then decide whether the evidence supports a rollback, a targeted constraint, or continued observation.
Small mistakes still happen: an incorrect report is sent, a setting is misunderstood, or a change produces an unexpected effect. Fast acknowledgement protects the account better than defensive explanation. Correct the immediate problem, document the cause, add the missing check, and return the team’s attention to the business outcome.
Key takeaways
Reconcile platform reporting with CRM or realized revenue before treating ROAS as an optimization signal.
Separate campaigns for real business constraints, not inherited naming or reporting habits.
Use automation guardrails to address a defined failure mode, and evaluate their effect on profitable volume rather than CPC alone.
Give generative AI the objective, definitions, evidence, constraints, and uncertainty rules an analyst would need.
Record each material change as a reversible test with a hypothesis, decision condition, and rollback path.
Your next move should be small and diagnostic. Before launching another bid-strategy change, reconcile one important revenue view from ad click to CRM outcome. That check will tell you whether the account needs better automation, better structure, or simply better data.
I’ve discovered that measurement is truly the cornerstone for all we achieve in performance marketing. Without precise measurement, everything I recommend, implement, and optimize becomes mere speculation. Today, maintaining accurate measurement is more challenging than ever—and it’s only getting more difficult.
With regulatory crackdowns and growing privacy concerns, paired with elongated multi-touch journeys, we face a measurement crisis. Brands that still rely on outdated tactics are missing the mark when it comes to modern measurement challenges.
If your brand falls into this category, it’s time I help you rebuild your measurement foundation—from integrating first-party data (crawl), to creating cross-channel reporting for actionable insights (walk), to advanced media mix modeling (MMM) and incrementality testing for true media lift (run).
The crawl: Building a first-party data foundation
By integrating first-party data into our performance marketing channels, I can move beyond reliance on third-party signals. While those metrics offer surface-level insights, they don’t reveal how channels impact our business goals.
Audience integration
The first step involves integrating CRM data into our paid media platforms. This includes:
Remarketing to abandoners.
Creating exclusion lists for current subscribers or recent purchasers.
Compiling priority contact lists.
I might be uploading lists today, but integration enhances targeting by connecting to up-to-date audience lists for media platform targeting.
Offline-conversion tracking
For lead-gen businesses like ours, setting up offline conversion tracking (OCT) is crucial. It reveals the bottom-line impact of our media on sales, passing sales data back to platforms for campaign attribution.
Once OCT is in place, we can optimize for lower-funnel, higher-quality conversion steps in the sales cycle or even begin optimizing toward revenue to enhance our return on ad spend.
Server-side tracking and consent mode
To progress from crawl to walk, I need to move from client-side to server-side tracking.
By adopting server-side tracking, we bypass browser-based tracking and instead rely on our first-party data. This approach ensures data accuracy and resilience as privacy restrictions increase and cookies become obsolete.
Partner integration uses pre-built connectors for setup through platforms like Shopify or Google Tag Manager.
Direct API requires a development team to handle complex data or custom backends.
The walk: Cross-channel reporting integration
With a robust measurement foundation, my next step is breaking down platform silos to understand the full ecosystem.
Going beyond last click
After implementing server-side tracking, I created a clean data pipeline. Yet, traditional attribution models neglect the full-funnel customer journey.
To address this, I recommend using data warehousing solutions like BigQuery to centralize your data and apply custom logic, thereby gaining insights across the ecosystem.
Unified reporting dashboards
Integrating evolved attribution with unified reporting dashboards, like Looker Studio, allows me to visualize data across the funnel and obtain actionable insights into what platforms are truly driving volume and conversions.
The run: Media mix modeling and incrementality testing
With a comprehensive, everyday view of performance, significant questions persist about growth potential and offline performance measurement.
By employing media mix modeling and incrementality testing, I can discern the full impact of media investments at a macro level to make informed decisions.
The holistic view through MMM
I view MMM as my compass, providing a holistic, quantitative guide for paid media investments, helping me analyze the relationship between inputs and business outcomes.
Pulse checks with incrementality testing
Incrementality testing offers validation for MMM and helps evaluate if specific tactics or channels are driving true incremental lift by comparing test and control groups.
The sprint: Clean, integrated, and validated first-party data
With first-party data integrated through server-side tracking and cross-channel reporting, I’ve built a robust measurement foundation. Guided by MMM and validated by incrementality testing, I’m now ready to sprint towards a more informed and successful marketing strategy.
Your PPC dashboard says conversions are up. Revenue, order value, or sales quality says otherwise. That gap usually means the account is optimizing for the easiest recorded action, not the outcome your business actually needs.
A conversion-focused PPC strategy fixes the problem in a specific order: define the valuable outcome, improve the signals sent to the platform, separate different kinds of intent, and test changes against business value. Automation can then help you pursue the right result instead of efficiently producing the wrong one.
Start with the conversion signal you actually want
A conversion is whatever your tracking setup labels as a conversion. It isn’t automatically a sale, a qualified lead, or a profitable customer.
This distinction matters because automated bidding learns from the outcomes you feed it. If a content download, an unqualified form submission, a valuable phone call, and a completed purchase all look equivalent, the system can favor whichever action is easiest to generate. Weighting conversion actions by their likelihood of producing value gives the platform a better representation of what the business wants.
Begin with a one-sentence campaign objective:
Acquire the right customer for this offer at an allowable cost, measured by the most reliable purchase, qualified-lead, revenue, or repeat-value signal available.
Then audit every conversion action against that objective:
List every action currently counted in campaign reporting and bidding.
Identify the business outcome that happens after each action: qualification, sale, revenue, retention, or no meaningful progress.
Classify the action as a primary outcome, a useful secondary signal, or a diagnostic event.
Assign relative values only where you can defend the differences with business logic or downstream data.
Remove weak proxy actions from optimization when they compete with stronger outcomes.
Observed action
How to treat it
Question to answer first
Purchase with recorded revenue
Use as a primary value signal when the revenue is reliable
Does revenue reflect the full order without duplicates or missing transactions?
Qualified phone call or sales-ready lead
Weight according to its downstream likelihood of becoming a customer
Can you distinguish a qualified inquiry from support, spam, or a poor-fit prospect?
Unqualified form submission
Keep secondary until qualification data proves its value
What share reaches the next meaningful sales stage?
Page view, content download, or other micro-conversion
Use for diagnosis or audience building, not as a substitute for revenue
Does this action predict a valuable outcome, or is it merely easy to complete?
A phone call isn’t inherently more valuable than a form submission. It deserves more weight only when your own qualification and sales data show that it is more likely to create value. The same rule applies to any conversion hierarchy: evidence should determine the weight, not a generic PPC convention.
Google’s planning direction reinforces the need for clear outcome signals. Performance Planner has stopped supporting Display and Video planning as well as impression-share-based plans, while its supported scope centers on conversion-oriented campaign types such as Search, Shopping, App, Demand Gen, Local, and Performance Max. That doesn’t make awareness activity worthless. It does mean you need your own explanation of what upper-funnel spend contributes instead of treating impressions as sufficient proof.
Don’t invent precise values merely to satisfy an automated system. False precision can redirect real budget. If the downstream value is unknown, preserve the action for reporting, investigate its relationship to sales, and keep the uncertainty visible until you have a defensible signal.
Route each kind of intent to the right campaign treatment
Conversion-focused targeting begins before you select a match type or audience. You need to know what the person is trying to accomplish and how close that intent is to a decision.
For every meaningful query or audience, ask three questions:
Who has a present problem and is likely to act now?
Who could become a buyer after an objection is answered?
Who is unlikely to buy because the offer, use case, price, or customer profile doesn’t fit?
This classification should change the ad, landing page, bidding signal, and degree of structural control. It shouldn’t remain a persona exercise in a planning document.
Use precision where the intent justifies it
High-intent, high-value terms can merit dedicated control. Selective single-keyword ad groups may improve message relevance and query precision where one term represents commercially important demand. That doesn’t justify rebuilding an entire account around single-keyword structures. Reserve the added maintenance for cases in which the intent and potential value make it worthwhile.
Competitor searches can also represent developed purchase intent. The person already understands the category and may be evaluating alternatives. A competitor campaign therefore needs a clear reason to choose your offer and a relevant landing page; a generic page wastes the intent you paid to capture.
Target Impression Share is another deliberate exception. It may support brand defense or visibility on strategically important non-branded terms, but it pursues presence rather than conversion efficiency. Use it only when visibility itself is the stated objective and the business accepts the possible efficiency tradeoff. Don’t present the result as a conventional acquisition win if cost per valuable outcome deteriorates.
Let automation explore inside visible boundaries
Broad match can discover demand you didn’t anticipate, but exploration needs a feedback loop. Combining it with assertive negative-keyword management lets the platform search broadly while you continually shape what qualifies. Several useful PPC tactics, including selective SKAGs, controlled broad match, competitor bidding, conversion weighting, and feed refinement, work because they improve the signals or boundaries around automation rather than rejecting automation outright.
Use this query-review loop:
Inspect the actual search query, not just the keyword that matched it.
Label its intent, customer fit, likely value, and relationship to the offer.
Exclude irrelevant or consistently poor-fit themes with negative keywords.
Move commercially important themes into a more controlled treatment when dedicated ads, bids, or landing pages would change the outcome.
Feed useful language from real queries back into ad copy and landing-page messaging.
Top-of-funnel queries require a different scorecard. They may contribute by building remarketing pools or strengthening audience signals even when their direct conversion rate is weak. Keep that spend identifiable, state the support role in advance, and don’t allow upper-funnel activity to hide inside the economics of high-intent acquisition.
Retargeting audiences can serve as a controlled environment for message and creative tests because those users already have some familiarity with the offer. A winning message can then be tested with colder audiences. Familiarity still changes behavior, so treat the retargeting result as a promising hypothesis rather than proof that the same creative will work everywhere.
Diagnose performance from revenue backward
When performance weakens, broad questions such as why did ROAS fall tend to produce broad answers. Diagnose the chain from the business result backward:
Spend to click to conversion to qualified outcome to sale to revenue to repeat value.
The first broken relationship is usually more actionable than the loudest metric in the interface. Use the following patterns as hypotheses to investigate, not automatic verdicts:
If conversion volume rises while Value/Conv. falls, the account may be finding easier but lower-value customers. Inspect audience, query, product, and order-value mix before celebrating the extra conversions.
If raw leads increase while qualified leads do not, improve the conversion hierarchy and customer filters before buying more traffic.
If qualified lead quality remains stable but sales decline, inspect the landing-to-sales handoff, offer, and downstream process rather than forcing a media-only explanation.
If relevant queries decline, examine match behavior and negatives before rewriting every ad.
If click-through performance improves without a better business result, the new message may be attracting attention without improving buying intent.
This is especially important when B2B and B2C demand overlaps. A campaign may collect many inexpensive consumer conversions while losing the higher-value business buyers it was meant to acquire. In that situation, stronger first-party audience inputs, specific audience segments, and value rules can emphasize B2B intent. That approach has been used to address lagging average order value reflected in Google Ads Value/Conv., but it still requires measurement: targeting a supposedly valuable group doesn’t guarantee valuable orders.
Evaluate economics at the deepest reliable level you possess. For ecommerce, revenue per order is more informative than order count, while contribution after variable costs is more useful than revenue alone when the necessary financial data is available. For lead generation, an expected value model can combine qualification likelihood, close likelihood, and customer economics. Use definitions approved by the people responsible for finance and sales rather than creating a parallel PPC version of profitability.
Customer lifetime value can justify a different acquisition decision from first-order revenue, but only when retention and repeat purchases are observable. Ask why customers stay, what causes another purchase, and which segments actually retain. Don’t raise allowable acquisition costs because an AI tool or a planning assumption produced an attractive lifetime-value story.
When you alter conversion values, audience rules, targeting, or campaign structure, log the change and the intended effect. Avoid simultaneously changing so many decision variables that you can’t tell whether performance moved because of better traffic, a different signal, a new message, or a changed offer.
Use AI to produce testable hypotheses, not synthetic certainty
Use prompts as structured briefs. Supply the offer, intended customer, price context, conversion action, observed performance pattern, and any known constraints. Then ask for hypotheses that can be checked against real query, CRM, sales, or order data.
Purchase intent prompt: Separate the audience into people likely to act now, people who need persuasion, and people who are poor fits. For each group, identify the observable evidence that would confirm or reject the classification.
Emotional context prompt: Identify the fears, frustrations, ambitions, and desired relief that could influence this customer. Distinguish plausible motivations from claims requiring customer evidence.
Objection prompt: Generate three to five credible objections to this offer. For each one, propose a response based on logic, emotion, and proof, but flag any proof the business must substantiate.
Value diagnosis prompt: Given rising conversion volume and falling Value/Conv., propose segment, query, audience, product-mix, and order-value explanations. Rank them by what can be checked with the available data.
Lifetime-value prompt: Explain why a customer might stay, buy again, or expand the relationship. Convert each idea into a retention hypothesis and specify what data would demonstrate that it is real.
The output is not customer evidence. AI can make an unsupported psychological profile sound convincing, invent proof, or favor a neat explanation for a messy performance change. Check proposed motivations against search terms, customer language, objections heard by sales, and observed buying behavior. Delete claims you can’t substantiate.
Turn each surviving idea into a compact experiment card:
Hypothesis: what you believe will change and why.
Audience: the specific intent or customer group being tested.
Variable: the message, creative, landing page, query treatment, audience input, or value signal you will change.
Primary measure: the valuable outcome that determines success.
Guardrails: the quality, cost, average-value, or downstream metrics that must not deteriorate unnoticed.
Decision: what you will scale, revise, or stop after interpreting the result.
A test is useful even when it loses, provided it isolates a meaningful decision. A higher click-through rate with weaker lead quality tells you the message attracted the wrong kind of attention. More conversions with lower order value tells you the platform responded to the signal but the signal didn’t represent enough value. Those are findings you can act on.
Key takeaways
Optimize for the deepest reliable business outcome, not the largest conversion count.
Give different conversion actions different treatment when their downstream value differs.
Apply tight control to commercially important intent and give automated discovery explicit boundaries.
Keep upper-funnel activity visible and judge it by its defined support role, not by impressions alone.
When results weaken, trace the path from revenue backward until you find the first relationship that changed.
Use AI to generate and rank hypotheses, then validate them with customer and performance data.
Start with one campaign, not an account-wide rebuild. Write its economic objective, audit the conversion actions influencing bidding, and inspect which queries or audiences produce the valuable outcome. Make the smallest signal or routing change that addresses the gap, record the expected effect, and let the next decision follow from business results rather than interface activity.