Category: PPC

  • Google Ads API v20 Sunset: Upgrade Before June 10, 2026

    Google Ads API v20 Sunset: Upgrade Before June 10, 2026

    If any reporting, bidding, or campaign-management workflow still calls Google Ads API v20, June 10, 2026 is a hard failure boundary. Any request sent to v20 after the cutoff will fail, so a healthy dashboard or successful scheduled job on June 9 does not prove that you are ready for June 10.

    Your job is to find every remaining v20 request, move each affected workflow to a newer version, and produce evidence that the replacement works in production. That requires more than changing a version string. It requires an inventory, representative testing, a staged cutover, and monitoring that can distinguish fresh data from stale output.

    Know exactly what will fail at the cutoff

    The sunset applies at the API request boundary. It does not, by itself, mean that a Google Ads account or campaign disappears. It means a workflow loses access whenever the request it needs still targets v20.

    The business consequence depends on what that request does:

    • Reporting and data pipelines can stop collecting new data, leaving dashboards, attribution processes, or client reports with gaps.
    • Campaign automation can stop reading or applying intended changes, including workflows connected to bidding and campaign management.
    • Internal tools can fail when a user opens a screen, requests a report, or submits a change that depends on v20.
    • Third-party platforms can break even when your own code is current, because the version choice may live inside the vendor’s backend.

    A failed reporting job is not always visually obvious. A dashboard may continue showing its last successful dataset unless it also displays data freshness. A failed write does not necessarily leave an account in a safe or paused state; it may simply leave the previous campaign settings in place. Review each workflow’s retry, alerting, and failure behavior so that an API error cannot masquerade as a successful run.

    Translate every technical dependency into an operational consequence. Instead of recording only “reporting service uses v20,” document which report stops, who consumes it, how quickly stale data becomes harmful, and who owns recovery. That mapping tells you which migrations must move first.

    Key takeaways

    • Google Ads API v20 requests will fail after June 10, 2026; the deadline is not a warning-only deprecation milestone.
    • Inventory observed API traffic and stored configuration. Either view alone can miss a dependency.
    • Test complete workflows on a newer API version, not merely authentication or one sample request.
    • Run read-only comparisons in parallel where useful, but do not duplicate campaign-changing requests across versions.
    • Cut over early enough to observe a full operating cycle and restore v20 temporarily if the new implementation fails before the sunset.

    Build an inventory that includes hidden and dormant calls
    An isometric enterprise system shows visible services and faint hidden connections to legacy jobs, dormant components, and recovery infrastructure.

    Start with actual traffic, then reconcile it against code, configuration, schedules, and vendor dependencies. An application list assembled from memory will miss old scripts, shared services, and jobs owned by teams that no longer think of themselves as Google Ads API users.

    Recent API activity in Google Cloud Console can help identify the methods and versions used by your projects. Review every relevant project rather than only the one associated with your main campaign application.

    1. List the environments and projects. Include production, staging, reporting infrastructure, serverless jobs, shared integration projects, and systems managed by another team.
    2. Inspect recent activity. Record which projects still produce v20 traffic and which methods they call.
    3. Cover the complete job cadence. Your observation period must include infrequent workloads such as weekly, monthly, or manually triggered jobs. Zero traffic during an idle period proves nothing.
    4. Search stored configuration. Look for literal v20 references, version selectors, client-library dependencies, deployment variables, request builders, infrastructure definitions, and copied scripts.
    5. Attach an owner to every dependency. An unidentified service is not ready merely because it appears inactive. Someone must decide whether it should be migrated, retired, or verified as unused.

    Traffic inspection and configuration inspection answer different questions. Traffic tells you what ran. Configuration tells you what may run later. Keep both in the migration register.

    Dependency surfaceWhat to locateUseful readiness evidence
    Custom applicationsVersion settings, client dependencies, request construction, and deployment configurationRepresentative requests succeed on the target version and production activity no longer shows v20
    Scheduled data pipelinesJob definitions, orchestration schedules, exports, and downstream consumersA complete scheduled run finishes with fresh, complete output
    Campaign automationRead and write paths, retry behavior, approval controls, and alertsA controlled test produces the intended state once and failures reach an owner
    Third-party platformsVendor-owned connectors, reporting modules, and automation featuresThe vendor confirms the production version and you verify your own affected workflows
    Dormant or manual toolsOccasional scripts, archived repositories, runbooks, and analyst utilitiesThe tool is migrated, formally retired, or blocked from future v20 use

    Ask vendors for feature-level confirmation

    A generic claim that a platform “supports the Google Ads API” is not enough. One module may be current while a less visible exporter or automation feature still uses v20. Ask the provider:

    • Which API version does each feature used by your account call in production?
    • Has every v20 workload been migrated, or only the primary integration?
    • When will the production cutover occur?
    • How can you verify that your tenant is using the newer version?
    • What happens to queued jobs, retries, and cached reports if a request fails?

    Keep the response with your migration record, then test the feature yourself. Vendor confirmation transfers information, not operational responsibility.

    Migrate the workflow, not just the version label

    Choose a newer supported API version that works with your client stack and the capabilities your workflows need. Use Google’s release notes and upgrade guides to identify required changes. Do not assume that editing a version constant is sufficient: client dependencies, available fields, request structures, generated types, and response handling may also need attention.

    A practical migration sequence looks like this:

    1. Capture a baseline. Record representative inputs, expected outputs, normal completion signals, and current error behavior for each workflow. Use stable comparisons where possible because live campaign data can change during testing.
    2. Update the client and application together. Change the supported client dependency, version configuration, request construction, and any code affected by the official upgrade guidance. Check deployment manifests and runtime variables as well as the repository.
    3. Test authentication and simple reads. Confirm that the application can connect using the credentials and account scope it will use in production. Connectivity is only the first gate, not the completion criterion.
    4. Exercise representative read workflows. Run the same account scope, date range, filters, pagination path, and downstream transformation used by the real job. Compare required fields, completeness, row-level invariants, and freshness rather than relying on a single successful response.
    5. Test writes under controlled conditions. Do not change live spend merely to prove connectivity. Use an approved test environment, test account, or non-spend-altering path where your setup supports one. Verify that the intended resource changes once and that retries cannot duplicate an action.
    6. Validate downstream consumers. A successful API response does not prove that a dashboard, warehouse load, bid process, notification, or internal interface can consume the new output correctly.
    7. Release in stages. Move a bounded set of workloads first, watch their results, and expand only after the expected operating signals remain healthy.

    Parallel validation is useful for read-only workloads. You can run equivalent reporting requests on v20 and the target version, then compare the resulting datasets while v20 remains available. Avoid sending campaign-changing requests through both versions: duplicate writes can produce real account changes and financial consequences. For write paths, use a controlled test followed by a staged production rollout.

    Preserve a temporary rollback path during the early cutover, but recognize its expiration date. Before June 10, a rollback to v20 may buy time to fix a problem. After the sunset, v20 is no longer a viable recovery plan because its requests will fail. Your post-cutoff contingency must keep the newer version in place, disable the affected workflow safely if necessary, and route the failure to a named owner.

    Define readiness with production evidence
    Engineers monitor abstract requests moving through a replacement processing lane with checkpoints, a separated legacy lane, and a rollback route.

    “The code was upgraded” is a progress update. It is not a definition of done. Close the migration only when you have evidence across configuration, runtime traffic, workflow output, and ownership.

    • Every known application, script, scheduled job, and integration has an owner and an explicit migrate-or-retire decision.
    • Each active workflow completes successfully on the selected newer API version using representative accounts and request types.
    • Production configuration and deployed client dependencies point to the intended version.
    • No v20 activity appears across the relevant Cloud projects during a period that covers the full operating cadence of the workflows.
    • Reporting outputs expose freshness and completeness, so stale data cannot look current.
    • Campaign-changing automation has controlled retry behavior and a human receives actionable failure alerts.
    • Third-party features have been confirmed by the provider and verified through your own account-level test.
    • The rollback plan works before the cutoff, and the post-cutoff contingency does not depend on v20.
    • Campaign owners, analysts, engineers, and support staff know when the cutover occurred and where failures will be reported.

    Be careful with negative evidence. Seeing no v20 requests is meaningful only if every relevant workload had an opportunity to run. A monthly exporter that has not reached its schedule can remain invisible until after the deadline. Pair runtime inspection with the dependency register, then record the last successful target-version execution for every retained workflow.

    Set your internal cutover early enough to run a complete operating cycle while v20 can still serve as a temporary fallback. Name the owner, start the inventory, and schedule the target-version validation now. The date that matters internally should be the day you can prove v20 is gone, not June 10 itself.
    References

  • Performance Max Reporting for B2B: An Optimization Plan

    Performance Max Reporting for B2B: An Optimization Plan

    Your Performance Max campaign can look efficient while your sales team rejects nearly every lead. That isn’t a contradiction. It means the campaign is succeeding against a conversion signal that doesn’t represent the business outcome you actually need.

    You don’t need complete visibility into every automated bid to fix that problem. You need a reporting chain that connects platform activity to qualified pipeline, plus a disciplined way to intervene when the chain breaks. Here is how to build it.

    Start with the business outcome, not the campaign CPL

    Cost per lead is only useful when the word lead has a stable business meaning. A form submission, sales-accepted lead, opportunity and closed deal are not interchangeable outcomes. If PMax counts the first while your team values the third, a falling CPL can hide deteriorating performance.

    Begin with a conversion inventory. List every action available to the campaign, then write down what each action proves. A form submission proves that someone completed a form. It does not prove that the person fits your market, has buying authority or represents a real organization. Treating those facts as equivalent gives automation an easy target and gives you misleading reporting.

    1. Define the funnel stages your team can verify. Use the stages already applied consistently in your CRM, such as inquiry, accepted lead, opportunity and won business. Don’t create a more elaborate taxonomy than sales can maintain.
    2. Choose the deepest dependable optimization signal. The ideal event is close to revenue, recorded consistently and available often enough to guide the campaign. If closed business is too sparse or delayed, use the nearest reliably graded stage rather than pretending a raw form fill is equally valuable.
    3. Keep earlier actions for diagnosis. An inquiry can still reveal landing-page or creative behavior. It simply shouldn’t be allowed to masquerade as qualified demand in your business reporting.
    4. Connect platform records to later CRM outcomes. For B2B campaigns, offline conversion tracking and enhanced conversions for leads help carry information from the initial interaction into the later stages that matter.
    5. Remove obvious form abuse before asking the algorithm to learn. Controls such as reCAPTCHA can reduce low-quality submissions. They don’t replace qualification, but they prevent some worthless activity from being treated as useful training data.

    No tracking configuration can rescue an undefined lead. Sales and marketing must agree on the rule for accepting or rejecting one, and that rule must be applied consistently. Otherwise, imported outcomes encode internal inconsistency rather than buyer quality.

    This also changes how you evaluate cost. A campaign with a higher form-fill CPL may be the better investment if more of those forms become accepted leads or opportunities. Compare cost at the deepest mature stage available, not merely at the fastest stage the ad platform can report.

    Build a reporting chain that answers five different questions

    Five connected transparent chambers show a stream of marketing activity narrowing into leads, qualified prospects, and valuable pipeline outcomes.

    No single PMax report can tell you whether a campaign is working. Placement data explains where ads appeared. Channel data shows how automated delivery was distributed. Intent reports add search context. Asset reporting helps you inspect messages and formats. Your CRM determines whether any of that activity produced business value.

    Reporting layerQuestion it answersEvidence to inspectDecision it can support
    Business outcomeDid the lead progress?CRM qualification, opportunities, won business and imported offline outcomesChange the optimization signal, qualification process or lead controls
    Campaign and channelWhere did automated delivery produce recorded conversions?Campaign results, segmented conversion metrics and account-level channel reportingInvestigate channel mix and decide where a more focused follow-up test belongs
    Publisher placementWhich inventory received spend and recorded conversions?Microsoft’s Website Publisher URL report with spend and conversion dataIdentify inventory worth studying, protect brand safety or add a justified URL exclusion
    Intent and competitionWhat demand patterns surrounded performance?Google search term insights, auction insights, search themes and brand controlsRefine intent guidance, separate branded demand or investigate a competitive change
    Creative assetWhich messages and formats appear to attract response?Asset-level reporting and controlled creative testsRetire weak messages, add qualification or develop a stronger variant

    Microsoft’s PMax reporting makes the placement layer more actionable by adding conversion and spend metrics to the Website Publisher URL report. That is materially better than a list of domains with no economic context. You can see which placements consumed budget and which were associated with recorded conversions.

    But recorded conversions are still only as trustworthy as the conversion definition. A publisher with several form fills is not automatically a strong B2B placement if none of those people survive qualification. Conversely, a publisher with spend and no immediate conversion is not automatically waste if your evaluation window closes before leads mature. Join placement evidence to the CRM before making an efficiency judgment.

    Google’s channel, search-term, auction and asset reporting answers different questions. Channel reporting can expose where reported results originate, while search term insights add context about demand. Auction insights help you notice competitive conditions. Asset reporting shows how creative components are being evaluated. None of these views, by itself, proves incremental revenue.

    The practical rule is simple: use platform reporting to locate a pattern, then use downstream data to decide whether that pattern deserves action. A report is diagnostic evidence, not a verdict.

    Apply PMax controls in the order that reduces uncertainty

    When lead quality is poor, it is tempting to change audience signals, creative, themes and exclusions at once. That creates activity without producing a clear lesson. Apply controls from the bottom of the measurement chain upward.

    1. Repair the conversion signal and form hygiene

    First confirm that legitimate leads can be connected to later CRM stages and that obvious spam is filtered. If the campaign is rewarded for an event your business doesn’t value, every targeting adjustment rests on a faulty objective.

    Inspect conversion metrics separately rather than blending every action into one total. A campaign that produces many shallow actions and few qualified outcomes should not receive the same interpretation as one that advances prospects through the funnel. Segmented conversion reporting and offline outcomes give you the distinction needed to see that difference.

    2. Feed the system a clean first-party audience signal

    A large CRM export is not automatically a useful audience input. It may mix customers, unqualified inquiries, inactive records, students, vendors and prospects at unrelated stages. That teaches the system that all records deserve equal attention.

    Clean and segment the data before using it. Start with groups closest to a verified revenue event, provided each group has a consistent business definition. A list of accepted leads or opportunities usually carries clearer intent than an undifferentiated list of everyone who has ever completed a form. The value comes from the label, not the file size.

    Treat audience signals as guidance to be validated. After launch, compare the resulting leads with the segment characteristics you intended to emphasize. If the campaign finds cheap conversions outside your real customer profile, the CRM outcome should overrule the attractive platform metric.

    3. Use search themes and brand exclusions to clarify intent

    Search themes can guide Google PMax toward the demand you want it to explore. Build them around the problems, use cases and buying situations your qualified prospects actually express. Avoid turning themes into a loose catalogue of every phrase related to your industry.

    Brand exclusions solve a separate problem. If your objective is to assess incremental acquisition, branded demand can make an automated campaign look more efficient than its prospecting work really is. Search themes and brand exclusions provide useful control over those inputs and costs. Decide explicitly whether a campaign should capture existing brand demand or discover new demand, then configure and judge it against that purpose.

    Review search term insights after the campaign has produced meaningful evidence. Look for patterns that indicate the wrong buyer, job seeker, student, consumer use case or research intent. Those patterns should lead to a specific hypothesis about themes, messaging or conversion quality. They shouldn’t trigger an indiscriminate attempt to block anything unfamiliar.

    4. Treat placement exclusions as a precise control

    Microsoft’s placement spend and conversion data can expose publishers that are clearly unsuitable for the brand or economically unproductive after downstream outcomes are considered. High-performing inventory can also inform a separate Audience Ads or remarketing strategy, while unsuitable inventory can be added to an account-level URL exclusion list.

    Account-level exclusions have a wider blast radius than a campaign-specific observation. Before adding one, verify the exact domain, the reason for exclusion and the other campaigns that may rely on it. A clear brand-safety conflict can justify immediate action. An apparent performance problem needs more context: adequate spend relative to your economics, a review window long enough for lead grading and evidence that the recorded conversions did not progress.

    Do not turn the placement report into a manual bidding console. Its best use is to find material exceptions: unsafe environments, obvious mismatch, persistent waste or inventory that deserves a focused follow-up strategy.

    5. Make creative qualify the prospect

    B2B creative should do more than generate attention. It should help the right buyer recognize relevance and help the wrong visitor recognize a mismatch. State the use case, intended role, business context or other genuine qualifier that distinguishes your offer. Vague creative may attract more interactions while making lead quality harder to control.

    Video deserves deliberate treatment because YouTube is an important part of PMax inventory. Google also provides AI-assisted asset creation, creative testing and asset-level reporting. Use those capabilities to test a defined message difference, not merely to produce more variations. A useful test might compare problem-led positioning with outcome-led positioning, or broad language with a clear buyer qualifier.

    Read asset results alongside lead quality. An asset that attracts many conversions but disproportionately weak prospects may be doing its job badly, even if the platform labels it positively. The next variation should address the mismatch in the message rather than simply changing the visual treatment.

    Run a decision loop that sales can audit

    Marketing and sales professionals work at a circular table where campaign controls, lead reviews, feedback, and opportunity markers form a connected loop.

    PMax optimization becomes safer when every change starts with an observed business problem. Use the table below as a diagnostic map. The first column is a symptom, not a conclusion.

    What you noticeWhat to verifyWhat to do next
    Platform conversions rise while accepted leads stay flatWhich conversion actions increased, whether form abuse changed and whether offline outcomes are returning correctlyCorrect the optimization signal or lead-quality controls before changing audience inputs
    Form-fill CPL rises while opportunity creation improvesCost per accepted lead and opportunity for a fully graded cohortJudge the campaign on the deeper outcome rather than cutting it solely because the shallow CPL increased
    A publisher consumes spend without qualified progressionPlacement spend, recorded conversions, CRM outcomes, evaluation lag and brand suitabilityExclude a verified unsafe or persistently wasteful URL; otherwise gather enough context to distinguish delay from failure
    One channel appears to overperformConversion mix and lead quality by channelUse the pattern to design a focused channel or audience test instead of assuming every reported conversion has equal value
    An asset attracts response but weak prospectsThe CRM quality of leads associated with its message and offerAdd a buyer, use-case or business-context qualifier and test the revised message
    Branded demand dominates the visible intent patternWhether the campaign’s job is brand capture or incremental acquisitionUse brand controls where appropriate and report branded and non-branded intent against separate expectations
    Auction conditions change near a performance shiftWhether conversion quality, creative, landing experience or campaign inputs changed at the same timeTreat auction data as context and test the most plausible cause rather than declaring competition the cause automatically

    Make the review window match your buying process. If sales has not yet graded the leads in a cohort, that cohort cannot support a final quality conclusion. Label it incomplete instead of filling the gap with the platform’s faster metrics.

    Keep a short decision log for every material intervention. Record the observed problem, the evidence from each reporting layer, the change made, the downstream metric expected to move and the point at which the affected leads will be mature enough to review. This prevents the team from repeating tests or crediting an unrelated performance swing to the latest edit.

    Change one major layer at a time where practical. If you replace the audience signal, add themes, exclude publishers and rewrite every asset together, you may improve results but learn very little about why. Sequencing changes turns automation from an opaque system into a set of testable business decisions.

    Key takeaways

    • PMax optimizes the conversion definition you provide, so a cheap form submission is not evidence of efficient B2B growth.
    • Use offline outcomes and consistent CRM stages to evaluate cost per qualified result, not just cost per initial lead.
    • Placement, channel, intent, auction and asset reports answer different questions. Join them to downstream outcomes before acting.
    • Clean first-party audience segments, focused search themes and qualifying creative give automation better guidance.
    • Use URL and brand exclusions deliberately. Confirm the scope, business purpose and downstream evidence before restricting delivery.
    • Log each material change and wait until the affected lead cohort is mature enough to judge.

    Start with the latest lead cohort that sales has completely graded. Compare its CRM outcomes with the campaign, channel, intent, placement and asset evidence available on your platform. Find the largest break in that chain and change that layer first. The goal is not to control every automated decision. It is to make sure automation is learning from, and being judged by, the same definition of value your business uses.

    References

  • A Practical Paid Media and Cross-Channel Measurement Plan

    A Practical Paid Media and Cross-Channel Measurement Plan

    Your paid social dashboard says the campaign worked. Paid search gets credit for the eventual conversion. Direct traffic also rises. If you evaluate each channel in isolation, you can end up paying three platforms for the same story or cutting the channel that started it.

    You need an execution plan that separates platform-reported performance from incremental business impact. That means assigning each channel a job, preserving a measurable journey, testing a specific causal claim, and deciding in advance what evidence will change the budget. AI-driven changes have made paid media platforms more complex, but they haven’t removed the need for this discipline.

    Measure the customer journey, not a stack of channel totals

    A platform conversion total answers a narrow question: which conversions can this platform claim under its attribution rules? It does not tell you how many conversions would have disappeared without the campaign. That second question is incrementality, and it is the one that should guide a material budget decision.

    Cross-channel journeys make the distinction important. A paid social impression may introduce the brand. The person may later search for it, click a paid search ad, and convert on the site. In that journey, social created or accelerated demand, search captured it, and the website closed it. Giving the entire outcome to the last interaction understates social. Adding every platform’s claimed conversions overstates the total.

    Paid social can build familiarity that later appears in branded search volume, paid search click-through rates, and conversion rates. Those effects are plausible hypotheses, not universal laws. Some businesses will see a meaningful relationship; others will see little or none. Your measurement design has to distinguish the two.

    Start by assigning a role to every campaign. Use roles such as demand creation, demand capture, remarketing, registration, or conversion. Do not let every channel claim to be a direct-response closer merely because its interface reports conversions. The role determines which signals deserve attention and which signals are only diagnostic.

    Key takeaways

    • Platform attribution shows claimed credit; an incrementality test estimates what the advertising caused.
    • Do not add channel-reported conversions together unless you have deduplicated the underlying business events.
    • Give each campaign a defined job in the journey before selecting its success metrics.
    • Judge an awareness campaign partly by downstream demand signals, not only by its last-click conversions.
    • Use a control whenever the budget decision depends on causality rather than reporting convenience.

    Define the decision and hypothesis before changing spend

    A useful paid media test begins with a budget decision, not a dashboard. Write down what you might do differently after the result: increase social investment, reduce it, move money between audiences, protect branded search coverage, or change the registration journey. If no possible result would alter an action, you are monitoring rather than testing.

    Next, turn the decision into a falsifiable hypothesis. A practical format is: changing a named campaign variable for a defined audience or geography will change a specified business or downstream channel outcome relative to a control.

    For example: increasing paid social exposure in selected markets will increase branded paid search demand relative to comparable markets where social spend remains unchanged. The mechanism is greater brand familiarity. The primary signals are branded search impression and click volume. Search click-through rate and conversion rate are supporting signals because familiarity may affect both, but they should not quietly replace the primary outcome after the test begins.

    Your campaign brief should record the following before launch:

    • Business decision: the budget or execution choice the result will inform.
    • Intervention: the exact variable you will change, such as social spend, audience exposure, creative, or destination.
    • Expected mechanism: why that change should affect customer behavior.
    • Primary outcome: the business or downstream channel signal that directly tests the hypothesis.
    • Supporting metrics: signals that help explain the result without redefining success.
    • Guardrails: delivery, cost, lead quality, or customer-experience indicators that could make an apparent win unacceptable.
    • Control: the audience, geography, or other comparable group that will not receive the change.
    • Decision rule: what pattern of evidence would justify scaling, stopping, or running a narrower follow-up test.

    This record prevents a common failure: finding an attractive metric after launch and treating it as the goal. Engagement can explain delivery. It cannot substitute for registrations when registrations were the reason for the campaign.

    Build one observable journey across channels and destinations

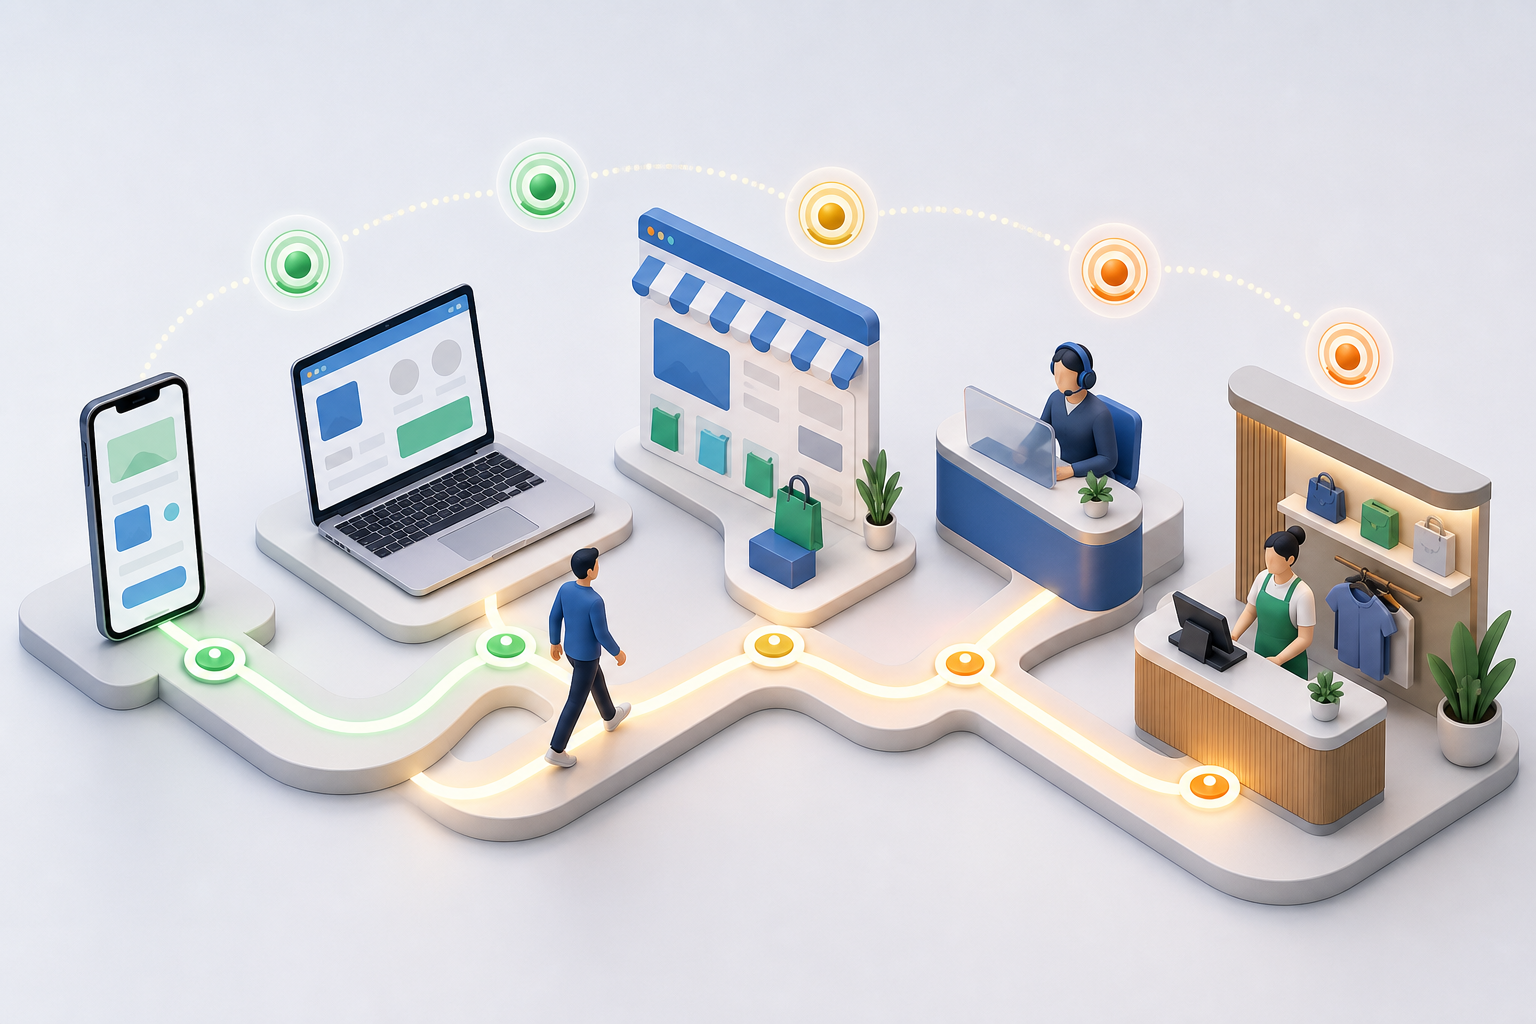
    An isometric customer journey connects a phone, laptop, online store, call center, and retail counter with one illuminated path.

    Cross-channel measurement breaks when execution creates different definitions of the same customer action. If paid social counts a form submission, paid search counts a confirmation page, and the CRM counts an accepted lead, the totals are not comparable. Establish the business event first, then map each platform signal to it.

    Use a shared campaign taxonomy across ad platforms, analytics, landing pages, and downstream reporting. The taxonomy should let you identify the channel, campaign, audience, geography, creative, offer, and test group without decoding inconsistent names. Preserve those values through the conversion path where your systems allow it. The aim is not a longer campaign name; it is a reliable join between spend, exposure, site behavior, and the final business event.

    Off-platform destinations give you more control over that join. LinkedIn’s off-platform Event Ads can direct clicks to an external webinar platform, landing page, or livestream site while Campaign Manager retains platform performance reporting. The format can support awareness, engagement, traffic, or lead-generation objectives and includes event details such as its date and format.

    That flexibility does not make measurement automatic. Before sending event traffic to your site, verify the complete path:

    1. Open the live ad destination and confirm that campaign and test identifiers survive the redirect.
    2. Complete a test registration and verify that analytics records the same completion event used in business reporting.
    3. Confirm that duplicate page loads or repeated form submissions do not create multiple business conversions.
    4. Check that the registration reaches the system where lead quality or attendance will eventually be evaluated.
    5. Separate campaign clicks, landing-page sessions, completed registrations, qualified registrations, and attendance. Each represents a different stage and should not be relabeled as another.
    6. Document any platform-reported conversion window or modeled result that differs from your analytics definition so stakeholders do not compare unlike totals.

    If you compare a native platform experience with an external destination, treat the destination as part of the intervention. A difference in registration rate may reflect page speed, form length, trust, tracking loss, or the handoff itself rather than the ad format alone. Keep the audience, offer, and conversion definition as stable as the platform permits, then examine the full path from click to qualified outcome.

    Use a geographic split when channels influence one another

    Two similar miniature city regions sit on opposite sides of a river, with media signals illuminating only one region.

    A simple before-and-after comparison is weak evidence for a cross-channel effect. Seasonality, promotions, news, competitor activity, and changes in search demand can move at the same time as your spend. A geographic split improves the comparison by exposing selected markets to the change while comparable markets act as controls during the same period.

    A defensible geographic paid social test requires more than dividing a map. Match treatment and control markets on factors that could affect the outcome, including income characteristics and region type. Check for local television campaigns, televised sports activity, regional promotions, distribution differences, or other events that reach one group but not the other. Either redesign around a major imbalance or document it before interpreting the result.

    Then protect the test from delivery constraints:

    • Confirm that the treatment budget can create a real difference in social exposure. A nominal budget increase that does not change delivery is not a meaningful intervention.
    • Keep the non-tested parts of the media plan as stable as practical across treatment and control markets.
    • Inspect paid search impression share before and during the test. If search is capped by budget or rank, added demand may not produce more paid search clicks.
    • Use the same conversion definition and reporting window in both groups.
    • Record campaign edits, outages, landing-page changes, promotions, and regional anomalies while the test runs.
    • Compare the change in treatment markets with the change in control markets. Do not infer lift merely because treatment improved from its own earlier level.

    Testing a reduction in spend can be valid when social investment is already substantial, but the financial consequence is real: you may suppress demand in the treatment markets. Define the exposure change, affected markets, stopping conditions, and recovery plan before launch. If you cannot tolerate the downside, test an increase in selected markets instead.

    If you lack comparable geographies, sufficient delivery, or trustworthy outcome data, say that the test is inconclusive. An attribution model can help describe journeys, but changing the model does not create a control group and should not be presented as proof of incrementality.

    Read the result as a system, then make one budget move

    Begin evaluation with the primary outcome written into the brief. Then use supporting metrics to explain why it moved or why it did not. This order matters. It stops an improvement in an easy platform metric from masking a flat business result.

    QuestionUseful signalMisreading to avoid
    Did social create more brand demand?Change in branded paid search impressions and clicks in treatment versus control marketsJudging the effect only by social last-click conversions
    Did familiarity change search response?Brand and non-brand paid search click-through and conversion ratesCalling every rate change causal without a control
    Could paid search capture added demand?Impression share and budget statusReading flat search clicks as proof that demand did not change when delivery was constrained
    Did the path between channels change?Visitor overlap, conversion touchpoints, and attribution-model comparisonsTreating descriptive journey data as an incrementality test
    Did an external event journey work?Campaign clicks, site sessions, registrations, qualified registrations, and attendanceOptimizing to engagement while losing registration quality after the click

    Expect the supporting metrics to disagree occasionally. Reducing social spend can produce mixed conversion-rate changes across regions even when overall conversions decline. A decline in branded search volume may strengthen the case that social supported demand, while a rising conversion rate may simply show that the remaining visitors had stronger intent. The conversion rate alone would tell the wrong story.

    When the result looks unusually large, investigate before scaling. Check tracking releases, site changes, inventory, promotions, search budgets, regional events, and changes to platform delivery. An anomaly is a reason to inspect the mechanism, not an invitation to replace the original hypothesis.

    Finish with one of four decisions: scale the tested change, reverse it, keep the current allocation, or run a narrower follow-up test. State which evidence drove the choice and which uncertainty remains. Avoid changing audiences, creative, bids, destination, and budget simultaneously after a test; you will lose the ability to learn which adjustment mattered.

    For your next planning cycle, choose one disputed budget question and write its hypothesis before opening an ad platform. Lock the conversion definition, identify a credible control, verify the end-to-end path, and agree on the decision rule. That turns cross-channel measurement from a reporting exercise into a repeatable way to allocate spend.

    References

  • Paid Search Optimization Beyond Keywords: A Signal Playbook

    Paid Search Optimization Beyond Keywords: A Signal Playbook

    You can have tidy ad groups, extensive negative-keyword lists, and a busy search-term report while still training paid search toward the wrong business outcome. If traffic looks healthy but qualified leads, sales, or revenue do not, adding more keywords will rarely solve the underlying problem.

    Keywords still help you read intent. They just no longer control the whole match. Your larger job is to give the platform reliable evidence about who should see the offer, what the offer is for, which stage of the journey matters, and what a valuable outcome looks like.

    Optimize the customer need state, not just the query

    A query tells you what someone typed. It rarely tells you, by itself, whether that person fits your market, why the problem matters to them, how close they are to buying, or what the eventual conversion could be worth.

    A need state combines those dimensions: the right type of customer, experiencing a relevant problem, at a meaningful point in the buying journey. A vague search such as “scaling infrastructure” can carry commercial value when first-party signals indicate that the person is an IT decision-maker investigating SOC 2 compliance. Modern matching systems can infer that intent from a collection of signals rather than waiting for one perfectly phrased keyword.

    This does not make search terms useless. Use them to learn the language customers use, identify irrelevant themes, protect the brand, and detect changes in demand. Just do not treat the query list as the only control surface in the account.

    Control surfaceWhat you are optimizingWarning sign
    Queries and themesProblem language, intent patterns, exclusions, and brand boundariesRelevant-looking terms produce the wrong type of inquiry
    Audience dataCustomer fit, lifecycle status, known value, and verified interestsTraffic converts, but sales repeatedly rejects the leads
    Landing pages and creativeOffer meaning, customer context, qualification, and message fitClicks rise while conversion quality or revenue falls
    Conversion feedbackThe outcomes and values that bidding should pursueCheap actions attract budget even though they do not predict revenue
    Measurement infrastructureThe integrity of data moving between ads, the site, the CRM, and salesPlatform results diverge from the system where the business records outcomes

    Build a signal stack the bidding system can understand

    Translucent layers containing audience, context, product, time, location, device, and transaction symbols feed into a central bidding engine.

    The strongest paid search accounts do not depend on one perfect signal. They combine first-party audience truth, clear page context, qualifying creative, and journey-aware conversion data. Each layer should confirm the same commercial hypothesis.

    Start with first-party truth, not a broad persona

    Do not feed every contact to the platform as if every contact represented success. Separate records that mean different things to the business: strong customers, qualified opportunities, early inquiries, rejected leads, existing customers, and people who are ineligible for the offer.

    Google increasingly uses Customer Match and other first-party inputs to help identify relevant people in an auction. B2B matching can be difficult, so the practical response is to improve the quality and organization of the data, not to collapse every record into one oversized list. Clustering people by a shared pain point and verified behavior can give the system a clearer signal than a loose job-title persona.

    For every audience group, document five things before using it:

    • Who is in the group and what qualifies them for inclusion.
    • Which observed action, CRM stage, or customer attribute supports that classification.
    • Which business outcome the group has historically represented.
    • Which problem and offer should be shown to it.
    • Whether the group should be acquired, retained, cross-sold, observed, or excluded.

    This prevents an audience label such as “high intent” from becoming an unsupported opinion. If you cannot explain the evidence behind the label, the bidding system cannot repair that ambiguity for you.

    Turn the landing page into a targeting brief

    Your landing page is not merely the place a click arrives. Automated systems use its content to interpret the offer and decide where it fits. A page that clearly says “mid-market manufacturing” provides a more useful market signal than a page promising generic solutions for every organization. That makes landing-page context part of campaign targeting.

    Read the page without the campaign open. A qualified visitor and a matching system should both be able to answer these questions from the visible content:

    • What category of product or service is this?
    • Who is it designed for?
    • Which specific problem or need does it address?
    • What requirements, limitations, or use cases define a good fit?
    • What should a suitable visitor do next?

    If the answers exist only in your keyword list, the page is withholding context from both the visitor and the machine. Rewrite vague headings, name the customer and use case plainly, and keep the ad, page, and conversion action aligned around the same need state.

    Use creative to qualify, not merely attract

    Creative assets also help define the audience. An ad that names the user, problem, outcome, and relevant constraint gives the system and the prospect more information than a generic promise designed only to win the click.

    Build creative around distinct need states rather than producing cosmetic variations of the same claim. One asset set might address a compliance-driven buyer, while another addresses an operational-efficiency problem. Send each to a page that continues the same argument. Then evaluate the combination using qualified outcomes, not click-through rate alone.

    Close the click-to-revenue feedback loop before scaling

    A circular pathway links an ad click, landing page, qualified customer, and completed sale back to an optimization engine, while an incomplete click path fades away.

    Automated bidding learns from the conversion events you return. If a form submission is marked as success but most submissions are irrelevant, the system is being asked to find more people who resemble poor leads. The campaign may be performing exactly as instructed while failing the business.

    Define a conversion hierarchy instead of treating every measurable action as equal:

    <!– wp:list {
  • Resolving Delays in Google Ads Demand Gen Reviews

    Resolving Delays in Google Ads Demand Gen Reviews

    Google Local Services Ads vs. Search Ads- Which drives better local leads?

    I’ve recently experienced frustrations with Google Ads as there’s a known issue causing Demand Gen ads to face review delays of over a week. Google acknowledges this problem and assures us that they’re working on a solution.

    Some of us advertising on Google have noticed our ads are lingering in review, taking more than seven days—something that deviates from normal review timelines.

    What’s happening. Matthew Skelton, a senior PPC specialist I follow, has pointed out a trending issue: Demand Gen campaigns stuck in review for an unexpectedly long time. This delay is noticeable across various accounts and industries, seemingly without any policy breaches causing it.

    Interestingly, other campaign types, like Search and Performance Max, aren’t affected and continue processing as usual, which suggests the problem is isolated to Demand Gen ads.

    Why we care. For those of us using Demand Gen to test creatives and drive top-of-funnel results, speed is crucial. Long review times hinder our ability to iterate swiftly, delay launches, and make it challenging to respond to seasonal trends or time-sensitive opportunities.

    A delay lasting a week can disrupt our pacing and diminish the effectiveness of campaigns relying on rapid optimization.

    The response. Ginny Marvin, a Google Ads Liaison, acknowledged this issue specifically impacting Demand Gen image ads, admitting reviews are taking longer than anticipated. She assured us that Google’s team is actively seeking a solution, but no clear timeline has been provided yet.

    Bottom line. If you’re experiencing delays with your Demand Gen ads, know that it’s a widespread issue acknowledged by Google rather than something you can directly address.

    First seen. This situation was first reported by Matthew Skelton, who shared his insights on LinkedIn.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Test Google Ads Acquisition Tools Without Skewing ROAS

    How to Test Google Ads Acquisition Tools Without Skewing ROAS

    You have more ways than ever to tell Google Ads what kind of customer to pursue. The difficult part is knowing whether a performance lift came from acquiring better customers, adding extra value to those customers, counting conversions after ad views, or testing an unfinished feature.

    If those signals are mixed together, an improving ROAS can hide unchanged revenue. The safer approach is to separate customer economics, attribution, and experimentation before you let automated bidding act on them.

    Start with the acquisition decision, not the campaign type

    A campaign cannot repair an undefined customer strategy. Before choosing Demand Gen, Performance Max, a customer acquisition goal, or an experimental app feature, write down the business decision the campaign is supposed to make.

    1. High-value acquisition: Find new customers who resemble the people your business considers valuable.
    2. Retention: Re-engage customers who meet your definition of lapsed, with a separate distinction for high-value lapsed customers when the data supports it.
    3. Demand creation: Reach people in discovery-oriented environments where an ad view may influence a later conversion even when no click occurs.
    4. Product experimentation: Test an early Google Ads capability without making the business dependent on a feature that may disappear.

    These are different jobs. In particular, customer acquisition and retention bidding goals cannot both be applied to the same campaign. That restriction is useful: it forces you to decide whether a campaign should spend more to acquire a certain new customer or spend to win back an existing one.

    Do not use “new customer” as shorthand for “good customer.” A first-time buyer with a small, one-off order may be less valuable than an existing customer ready for a premium service. Define value using evidence your business already understands, such as order value, repeat purchasing, margin, or interest in a premium offering. Then decide which of those attributes can be represented reliably in a customer list.

    A clean campaign map usually has one lane for high-value new-customer acquisition, another for lapsed-customer retention, and a separate learning lane for experimental features. Demand Gen can support acquisition, but it should still inherit one clearly defined customer objective. The campaign type is the delivery mechanism; the customer decision comes first.

    Make customer states usable before Smart Bidding sees them

    Anonymous customer figures are sorted into separate lifecycle chambers before individual signal cables connect them to an automated decision engine.

    Define high value and lapsed in your own data

    Google’s predictive bidding can look for likely high-value customers, but your Customer Match list supplies the examples. If the list contains a mixture of loyal buyers, discount-only buyers, recent customers, and stale records, the label “high value” carries little usable meaning.

    Create a short data definition before creating the audience. It should answer four questions:

    • What observable behavior makes a customer high value?
    • How does that definition differ from merely having a large first order?
    • What period without an eligible purchase or action makes a customer lapsed?
    • Which condition takes precedence when someone qualifies for more than one list?

    There is no universal lapse window. A sensible definition follows your buying cycle, not an arbitrary calendar interval. Document the rule so that a future list refresh classifies customers the same way.

    List scale matters as well. High-value Customer Match audiences need at least 1,000 active members on YouTube or Search networks to serve effectively. Treat that as an operational floor, not proof that the audience is representative. If only a narrow or unusual slice of high-value customers matches, bidding can still learn from a distorted picture.

    Include eligible identifiers such as phone numbers and addresses alongside the other customer data you upload; richer records can improve match rates. Direct audience integrations, including Klaviyo, can reduce the manual work of keeping lists current. Automation only solves the transfer, however. It will reproduce a bad definition just as efficiently as a good one.

    Treat additional customer value as a bidding instruction

    Lifecycle settings are managed in the customer lifecycle optimization area under Goals > Summary, followed by Edit Goal. For a high-value acquisition campaign, you can assign an additional new-customer value so bidding is more aggressive when Google predicts that a conversion will come from the desired customer type.

    That additional value is not money collected at checkout. It is a bidding adjustment layered onto the sale or lead value. If a conversion has an actual value and the lifecycle setting adds another amount, the value used in reporting and optimization can include both.

    Google may suggest an adjustment based on higher lifetime value, but the suggestion still needs to be reconciled with your own economics. A value that is too small will barely change bidding. A value that is too large can cause the campaign to overpay for customers who merely look like the uploaded audience.

    The reporting consequence is especially important under a ROAS strategy. Additional customer value increases the conversion-value numerator even though it does not increase booked revenue at the moment of conversion. The discrepancy is less influential when decisions are based on cost per conversion, but it can materially change the interpretation of ROAS. Use the reporting column that separates true conversion value from additional lifecycle value, and keep all three figures visible in your working report:

    • Actual sale or lead value.
    • Additional value assigned for the customer state.
    • Total value presented to the bidding and reporting system.

    If stakeholders see only the total, label it as optimization value rather than revenue. Otherwise, a campaign can appear to produce more economic value when the account has simply changed how much value it assigns to the same type of conversion.

    Choose click, view, and lifecycle signals for different jobs

    Customer lifecycle and attribution answer different questions. Lifecycle data asks who converted: new, existing, lapsed, or high value. Attribution asks how the advertising interaction receives credit: through a click, a view, or another eligible touchpoint. Combining those dimensions is useful, but only if you continue to report them separately.

    Demand Gen extends acquisition beyond click-heavy intent capture. Its Commerce Media Suite integration can use retailers’ first-party catalog and conversion data across YouTube, Discover, and Gmail. This is most relevant when you have commerce data capable of identifying products and outcomes, not merely a broad audience label.

    View-through conversion optimization gives the system another signal. It can focus on conversions that occur after someone views an ad, even when that person does not click at the time. That fits discovery environments such as YouTube, where exposure may precede a later visit or purchase.

    A view-through conversion is still an attributed conversion, not automatic proof of incremental demand. It tells you that an eligible view occurred before the conversion under the account’s attribution rules. It does not establish that the conversion would have been lost without the ad.

    That distinction should change how you evaluate a Demand Gen test. Keep click-associated and view-through outcomes visible as separate paths. Then compare actual customer and revenue outcomes, not just the total number of attributed conversions. If view-through volume grows while qualified new customers and true conversion value remain flat, the campaign has changed how credit is assigned more clearly than it has demonstrated business growth.

    Creative must follow the same separation. High-value acquisition messaging should make sense to someone who has not bought from you. Retention messaging should acknowledge the reason a lapsed customer might return. In Performance Max, lapsed customers may encounter several ads across the campaign, so a generic asset mix can undermine an otherwise well-configured retention goal.

    Before launch, inspect each eligible asset from the perspective of the customer state attached to the campaign. If the ad would be confusing to that person, targeting precision will not rescue it.

    Run App Labs as a reversible test, not a permanent dependency

    An analyst monitors a removable experimental module connected to a campaign machine beside separate control and test pathways.

    App Labs is narrower than its name may imply. It is a tested hub inside the app advertising area for limited-time experimental campaign features, not a general replacement for every Google Ads experiment. If the tab appears in your account, it offers app advertisers a chance to try features still in development and provide feedback.

    Early access can produce useful learning before a capability becomes widely available. It also carries product risk: an App Labs feature is not guaranteed to become permanent. Build the test so that losing access would remove an option, not break your acquisition program.

    Use this protocol for an App Labs test or any other early acquisition feature:

    1. Write one hypothesis. State which customer behavior or business outcome the feature is expected to change and why.
    2. Freeze the customer definitions. Do not change high-value or lapsed-list rules while evaluating a campaign feature.
    3. Select one primary business measure. Prefer true conversion value, qualified new customers, or another observed outcome over adjusted ROAS alone.
    4. Record the feature state. Note the settings, audience lists, attribution configuration, creative, and eligibility present when the test begins.
    5. Keep a stable comparison. Where the interface supports a control, use it. If it does not, document the limitations of the nearest comparable stable campaign rather than presenting the comparison as causal proof.
    6. Cap the learning spend. Put only an amount you are prepared to spend on uncertain learning at risk, and define the condition that will stop the test.
    7. Wait for the normal conversion lag. Reading the result before delayed conversions arrive will favor whichever path reports fastest, not necessarily the one that creates more value.

    Avoid changing the lifecycle value, attribution treatment, audience definition, and experimental feature at the same time. If the result moves, you will not know whether customers changed, credit changed, or bidding changed. Sequence the changes so each test resolves one decision.

    An experimental feature can still teach you something even if Google later removes it. Preserve the customer insight, creative finding, or measurement lesson in your test log. Do not build an essential workflow around the beta’s exact interface or availability.

    Key takeaways for your next campaign cycle

    • Define high value and lapsed status from your business data before uploading Customer Match lists.
    • Keep customer acquisition and retention goals in separate campaigns because both bidding goals cannot run on the same campaign.
    • Separate actual conversion value from the additional lifecycle value used to influence bidding, especially when evaluating ROAS.
    • Use view-through optimization for discovery journeys, but do not treat attributed views as proof of incremental conversions.
    • Match creative to the customer state; acquisition and reactivation messages have different jobs.
    • Test App Labs features in a bounded learning lane because limited-time experiments may never become permanent products.

    Your first move does not need to be a new campaign. Open Goals > Summary and identify every lifecycle adjustment currently affecting reported value. Then verify the attached customer lists, their definitions, and whether your report separates real conversion value from added bidding value.

    Once those numbers reconcile, choose one next experiment: a high-value acquisition goal, a retention goal, view-through optimization, or an App Labs feature. One clear change will teach you more than four simultaneous upgrades and a better-looking ROAS you cannot explain.

    References


  • Discover How OpenAI is Revolutionizing Ads with ChatGPT CPC

    Discover How OpenAI is Revolutionizing Ads with ChatGPT CPC

    Have you heard the news that OpenAI has introduced CPC ads to ChatGPT? This strategic shift has transformed it into a performance-driven channel, offering advertisers new avenues for engaging intent-driven audiences and tracking ROI.

    OpenAI is moving away from a focus purely on impressions in ChatGPT to prioritize performance. This change places OpenAI in direct competition with giants like Google by adopting cost-per-click (CPC) ads, allowing advertisers to pay only when users click on their ads.

    What’s happening? OpenAI has started testing CPC ads within ChatGPT, where advertisers only pay when their ads receive clicks. Initial reports highlight that these clicks are priced between $3 to $5. They’re rolling out this feature through a limited ads manager, alongside their existing CPM-based model.

    Why now? The main catalyst seems to be pricing pressure. Since its launch, ChatGPT’s CPMs have significantly decreased from around $60 to approximately $25. Switching to CPC helps mitigate this decline by connecting revenue to tangible outcomes rather than mere impressions.

    Why do we care? With its evolution into a performance channel, ChatGPT is now not just a branding space. The CPC pricing model makes it easier for us to connect budgets directly to measurable actions, test ROI, and compare these results with channels like Google Search.

    I’m excited about the opportunity for advertisers to access what could be a high-intent audience in a new format. This presents a first-mover advantage before competition—and the associated costs—escalate.

    The bigger picture: This isn’t just a pricing change; it’s a strategic pivot. By embracing CPC advertising, OpenAI challenges Google’s dominance in the market, thereby positioning ChatGPT as a contender for performance marketing budgets.

    Reading between the lines: A major challenge lies in proving user intent. While search advertising is effective because it captures users actively searching for something, ChatGPT’s conversational context needs to generate clicks with equal value. Advertisers will likely compare these results directly with Google, setting a high standard for quality and conversion.

    Zoom out: Advertising is becoming integral to OpenAI’s long-term revenue plan, supported by investments in ad infrastructure, measurement tools, and a wider self-serve platform.

    Bottom line: By implementing CPC ads, OpenAI is vying for the performance-driven ad dollars that have long supported traditional search platforms.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Audit Campaign Controls Before You Optimize Spend

    How to Audit Campaign Controls Before You Optimize Spend

    Your campaign can look more efficient while becoming harder to control. Spend may be compressed into fewer active days, conversion signals may be incomplete, and a polished dashboard may show activity without giving you the controls needed to explain or stop it.

    If performance changes without a clear bid, audience, or creative change, audit the control layer first. You need to know what the platform is allowed to do, what data its optimizer can see, and whether your reports describe the same system you configured.

    Key takeaways

    • Budget, schedule, consent, optimization, and reporting are separate controls. Changing or validating one does not validate the others.
    • A restricted ad schedule may concentrate spending rather than reduce the campaign’s monthly spending limit.
    • Consent diagnostics should help you locate missing or inconsistent signals. A consent rate is not a target to maximize at the expense of genuine user choice.
    • A dashboard is not a mature control system unless you can inspect state, enforce changes, verify their effects, and reconstruct who changed what.
    • Paid placement in an AI interface and earned visibility in a generated answer require separate attribution and reporting.

    Audit the whole control chain before touching bids

    Campaign optimization is usually treated as a bidding problem. In practice, bidding is only one link in a chain. The platform first determines whether an ad is eligible, then how much it may spend, which signals it can use, what decision automation should make, and what evidence you get afterward.

    A weakness anywhere in that chain can produce a misleading result. A schedule can alter the concentration of spend. A consent implementation can reduce observable conversions. A reporting delay can make a stable campaign appear volatile. Raising or lowering a bid before resolving those conditions adds another variable without answering the original question.

    Control layerQuestion to answerEvidence to record
    Business constraintWhat outcome, total cost, or operational load can you accept?Approved spending ceiling, capacity limit, and stop condition
    EligibilityWhen is the campaign allowed to enter auctions?Active days and hours, plus the business reason for each restriction
    DeliveryHow may the platform allocate spend while the campaign is eligible?Budget values, bidding mode, spending caps, and documented pacing behavior
    SignalWhich conversions and consent states can the optimizer observe?Conversion definitions, consent diagnostics, and coverage by relevant dimension
    ObservationCan you explain what happened after delivery?Reporting latency, available breakdowns, exports, attribution settings, and change history

    Run the audit in that order. Starting with reports is tempting, but a report cannot tell you whether the configured business constraint was correct. Starting with bidding is worse because the optimizer may be responding rationally to a budget, schedule, or signal state you did not intend.

    1. Write down the campaign’s intended result and its hard constraint. Separate a performance target from a limit the platform must not cross.
    2. Capture the current schedule, budget, bidding mode, conversion actions, consent state, targeting, and exclusions. Use actual settings, not what the launch plan says should be configured.
    3. Translate settings into effective exposure. For example, calculate the monthly spending ceiling and inspect how much delivery could be compressed into eligible periods.
    4. Check whether the optimizer receives the signals you expect across apps, platforms, regions, and traffic sources. Treat gaps as unresolved until you have distinguished user choice from an implementation problem.
    5. Verify that important controls are enforceable. A pause button, budget edit, or exclusion is useful only if you can confirm its scope, timing, and effect.
    6. Record each change with the old value, new value, timestamp, reason, expected effect, evaluation window, and stop condition. Where practical, avoid changing another layer before the first change can be evaluated.

    This gives you a baseline that optimization can build on. Without it, every performance movement invites a new theory, and several contradictory theories may fit the same aggregate chart.

    Scheduled campaigns need a spend-concentration audit

    A hand adjusts a scheduling gate above a blank calendar grid where glowing budget tokens are concentrated into only a few active tiles.

    A budget limits spending; a schedule limits eligibility. Those settings may feel interchangeable when a campaign runs only on selected days or hours, but they answer different questions.

    Under Google’s scheduled-campaign pacing model, a campaign can pace toward its full monthly spending limit even when its ads are not eligible every day. Disabled days remain disabled, but the system has more reason to capture available demand during the periods that remain open.

    The stated limits make the exposure calculable: the monthly spending cap remains 30.4 times the average daily budget, while spending on an individual day can reach up to twice that daily budget. These are ceilings, not promises about what the campaign will spend.

    The practical correction is simple: do not assume that fewer eligible days will produce a proportionally smaller monthly bill. If you intend to reduce total exposure, set the budget to reflect that intention. Keep the schedule focused on when the business can serve demand or when traffic is valuable.

    • Find every non-continuous schedule. Include campaigns limited to particular weekdays as well as those restricted to certain hours.
    • Write down why the restriction exists. A schedule tied to staffing, inventory, response time, or lead quality is an operational guardrail. Do not remove it merely to smooth a spending chart.
    • Calculate the monthly ceiling. Multiply the average daily budget by 30.4, then compare that amount with the total monthly exposure you actually approved.
    • Check the active-day boundary. Ask whether spending up to twice the average daily budget on an eligible day would create a cash-flow, inventory, or service-capacity problem.
    • Review eligible periods directly. Monthly averages can hide concentrated delivery. Inspect spend, conversions, and downstream quality during the windows when ads were allowed to run.
    • Change the correct control. Lower the budget when the total amount is too high. Narrow or widen the schedule only when eligibility itself is wrong.

    This distinction also improves diagnosis. Faster spending during active periods does not automatically mean bidding has become more aggressive or demand has improved. It may be the predictable result of the pacing system trying to use the same monthly allowance within fewer opportunities.

    Consent diagnostics tell you whether the optimizer can learn

    An analyst examines anonymous data signals passing through transparent consent gates toward an unbranded optimization engine, with some signals blocked or fading.

    An optimizer cannot act on a conversion it cannot observe. That makes consent signal quality part of campaign operations, not a separate technical housekeeping task.

    Google Ads’ App Consent Insights exposes consent diagnostics across apps, platforms, regions, and traffic sources. The view includes an overall rating of Excellent, Good, or Poor, a live count of apps sending consented data, and conversion consent rates with EEA and non-EEA differences.

    Use those dimensions to localize a gap. Do not interpret the account-level rating as a complete diagnosis. A lower rate could reflect genuine user choices, traffic composition, a deployment inconsistency, or missing signal transmission. Those possibilities need different responses.

    1. List the apps and platforms that should be sending consent information. Compare that inventory with the live count shown in the diagnostic.
    2. Locate the narrowest break. Determine whether the difference belongs to one app, one platform, one region, one traffic source, or a wider implementation.
    3. Compare EEA and non-EEA results without assuming geography is the cause. Review the regional consent implementation and the underlying traffic mix separately.
    4. Validate the technical path from the consent choice to the advertising platform. Confirm that the relevant state is collected, transmitted, and associated with the intended conversion setup.
    5. Annotate the release or configuration change that corrected a gap. Keep unrelated budget and bidding edits out of the same evaluation window where possible.
    6. Reassess campaign performance only after the corrected signal flow has had an appropriate observation period for your normal conversion lag.

    The overall rating is a diagnostic indicator, not an optimization objective. Do not make a consent experience more coercive just to lift a platform metric. Changes to consent language or interaction design should remain under the appropriate privacy and legal review. The campaign team’s job is to make sure a valid choice is transmitted accurately and that missing instrumentation is not mistaken for user behavior.

    This protects decision quality in both directions. You avoid blaming creative when measurement is incomplete, and you avoid treating every consent-rate difference as a tagging failure. Once signal coverage is understood, bidding and conversion reports become easier to interpret.

    Prove an AI ads manager can control delivery before scaling it

    New advertising interfaces can improve access long before their control systems become mature. OpenAI is testing a ChatGPT Ads Manager that moves beyond weekly CSV reporting toward real-time campaign management, monitoring, and optimization. That is meaningful progress, but testing an interface is not evidence that every targeting, reporting, governance, or automation capability is complete or broadly available.

    Evaluate an emerging ad manager by what you can verify, not by how familiar its dashboard looks. For every requirement, distinguish between a control that is promised, a control visible in the interface, and a control whose effect you have confirmed.

    • Authority: Can the authorized operator pause delivery, edit budgets, and reverse a change at the required account or campaign scope?
    • Budget semantics: Is the budget daily, monthly, lifetime, or another form? How is pacing described, and what prevents an unexpected concentration of spend?
    • Eligibility and exclusions: Which scheduling, targeting, placement, brand-safety, and exclusion controls actually exist? Do not assume parity with Google Ads or Meta because the navigation feels familiar.
    • Measurement: Which event counts as a conversion, what attribution rules apply, how quickly do results appear, and can reported totals be reconciled with your analytics?
    • Diagnostic depth: Can you break performance down far enough to separate delivery, audience, creative, placement, and signal problems?
    • Auditability: Is there a change history showing who changed a setting, when it changed, and what the previous value was?
    • Portability: Can you export campaign, delivery, and conversion data in a form your reporting system can retain and compare?
    • Governance: Can access be limited by role, and can a second operator review high-impact changes before they affect delivery?

    If a required control is missing or unverified, limit the test to exposure your organization can tolerate and define a manual stop path before launch. A report that arrives quickly is helpful, but speed does not replace enforcement, audit history, or the ability to reconcile results.

    Keep paid AI advertising separate from GEO and earned AI visibility as well. An ad impression purchased inside an AI experience is not proof that the brand was selected, cited, or recommended organically by a model. Give paid campaigns their own attribution labels, landing-page tracking, and reporting view so an increase in paid traffic cannot be presented as improved generative visibility.

    Before your next optimization cycle, open one consequential campaign and record its monthly spending ceiling, the reason for its schedule, its maximum active-day exposure, its consent-signal coverage, the controls that can stop delivery, and the delay in its reporting. Resolve any unknown that could change the meaning of the results. Once those controls are observable and enforceable, bid and creative changes can produce evidence you can actually use.

    References


  • Discover Why ‘Ugly’ Ads Could Boost Your Marketing Success

    Discover Why ‘Ugly’ Ads Could Boost Your Marketing Success

    For years, I’ve been told to stick to a set of guidelines: always use top-notch creatives, maintain a polished brand, follow scripts, and adhere to platform-recommended formats.

    Lately, while navigating ad accounts or simply scrolling through feeds, I’ve noticed something intriguing. The ads that grab my attention often defy these rules. They’re less polished, scrappier, and sometimes referred to as ‘ugly ads.’ What’s fascinating is that they’re outperforming the traditional, polished ones.

    More brands are deliberately breaking so-called best practices to stand out. It’s important to remember that these practices represent an average of what worked for others in the past. By the time a strategy becomes a platform-recommended rule, it might have already lost its edge.

    This is why defying best practices can lead to success — but only if you understand the reasons behind them.

    Why Breaking Best Practices Enhances Ad Performance

    Before diving into what to change, it’s crucial to understand the rationale behind existing rules. Platforms like Meta and TikTok have dual objectives:

    • They aim for you to spend money on ads.
    • They want to keep users engaged on their platforms.

    The best practices they promote are designed to ensure a seamless experience, encouraging ads to resemble others. The issue is that familiarity eventually breeds invisibility. When I adhere too closely to the rules, my ads risk blending into the background noise, overlooked by users.

    ```json
{
  "alt": "Person holding a dumbbell at the gym, with text saying 'Your AirPods died at the gym' and emoji expressions.",
  "caption": "When your motivation gets heavy! A classic gym moment – your AirPods gave up, but you didn’t. Feel the silence and lift on!",
  "description": "Image shows a close-up of a person’s hand gripping a black dumbbell at the gym. The text overlay humorously reads 'POV: Your AirPods died at the gym' with laughing emojis, depicting the common scenario of exercising without music due to AirPods losing charge. This relatable gym scene captures the blend of determination and humor. Keywords: gym, dumbbell, AirPods, workout, humor."
}
```

    Highly-produced ads often scream ‘this is an ad,’ prompting users to skip them before my message hits home. In contrast, when my ad resembles something a friend might share, users’ defenses remain down longer, potentially transforming a scroll into a conversion.

    This is why many top-performing ads today don’t appear traditionally polished or on-brand. They break patterns instead. Consider:

    • Grainy phone footage.
    • Notes app screenshots.
    • Green-screened reactions or commentary videos.
    • Other lo-fi formats that outperform studio-quality creatives.
    A screenshot of a TikTok video ad featuring POV overlay text, a hand grabbing a dumbbell, and AirPods
    Source: TikTok Ads Manager

    To implement this, I started intentionally reducing my production value and experimented with formats like point-of-view (POV) shots tailored to various personas.

    Dig deeper: TikTok ad creative has a shorter shelf life. Here’s how to keep up

    Founder-Led Ads: Reviving the Human Touch

    Many brands have adopted guidelines that make them seem faceless and untouchable. They refrain from showing a messy office, an unpolished founder, or anything that challenges their corporate script. However, others are discarding that playbook, embracing founder-led ads that deviate from the polished executive version.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    There’s a catch.

    Breaking the rules works only when it’s genuine. I’ve learned that faking authenticity is easy to spot and can backfire. This was evident in a viral series of videos where McDonald’s CEO appeared to present a new burger, but his execution was criticized for being stiff and unconvincing.

    As shown in a Dineline video, his performance appeared staged. Contrarily, Burger King’s president presented their burger with no hesitation, offering a genuine and relatable moment.

    The distinction was evident: One was a product pitch, and the other felt authentic.

    If my leadership doesn’t genuinely believe in the product, neither will my customers. Rule-breaking should allow us to be real, rather than simply appear unpolished.

    ```json
{
  "alt": "A man in a light sweater speaks in a video with McDonald's fries and drink in front of him.",
  "caption": "A promotional video featuring a man discussing while enjoying McDonald's fries and a drink, set against a vibrant yellow background.",
  "description": "The image shows a man seated in an office setting, wearing a light sweater, speaking in a promotional video. In front of him is a McDonald's meal, including a box of fries and a cup with a plastic straw. The background is bright yellow, adding vibrancy to the scene. This promotional video appears designed to emphasize McDonald's offerings in a casual yet professional manner. Keywords: McDonald's, promotional video, fast food, marketing."
}
```
    A screenshot of a YouTube video of theMcDonald’s CEO with their new burger
    Source: Dineline on YouTube

    The Comment Hook Hijack

    You’ve probably encountered video hook best practices like ‘show the product in the first two seconds and state the value prop clearly.’ Sound familiar?

    Imagine my ad starting with a screenshot of a negative comment, like one for a skincare product stating, ‘This probably smells like old socks, and does it even work?’ My ad would then show the founder confidently disproving this in an unscripted manner, applying the product.

    Though this breaks the positive-association rule, it leverages viewers’ curiosity about digital conflicts. By the time they realize it’s an ad, they might already be engaged.

    A screenshot of a TikTok video ad with a comment bubble that a person is addressing
    Source: TikTok Creative Center

    The Rebel’s Safety Net

    I learned not to abandon all polished assets just yet.

    Rule-breaking is strategic, and often misunderstood when the ’80/20 rule’ is ignored.

    ```json
{
  "alt": "Man in a black hoodie answers a question about the game Survivor.io",
  "caption": "Exploring the unbeatable myth of Survivor.io, this video provides insights and tips.",
  "description": "A man in a black hoodie, marked with a logo, responds to a comment asking if Survivor.io is unbeatable. The background shows a two-toned wall with wood paneling. The video aims to address a common inquiry among players, sharing personal experiences and strategies related to the game. Keywords: Survivor.io, unbeatable, gaming tips, strategy."
}
```

    Switching completely to shaky phone footage isn’t wise. Keeping 80% of the budget in traditional ads while using 20% for testing unconventional ones can be effective.

    Next testing campaign, I plan to try:

    • The silent test: Running a silent ad with bold captions to stand out in a noisy feed.
    • The UI ghost: Using static images resembling platform notifications to pause scrolling.
    • The algorithmic trust fall: Disabling auto-optimizations in a campaign to test creative performance without constraints.

    Don’t Follow the Rules; Understand Them

    Best practices are a guide, not a strategy. To move beyond them, I do it systematically.

    I start by questioning the rule’s existence, evaluating its current relevance, and testing its opposite in a structured manner. Comparing traditional and lo-fi approaches helps me understand user engagement better.

    In an environment where brands play it safe, those who understand and strategically break the rules will capture attention and conversions. My goal is to learn faster than the competition, skipping guesswork.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Google Ads Automation: A Practical Optimization Framework

    Google Ads Automation: A Practical Optimization Framework

    You want Google Ads automation to remove repetitive work, not remove your control over spend. The problem is that an automated campaign can look efficient inside the platform while attracting weak leads, claiming conversions that would have happened anyway, or scaling a creative idea that has never proved incremental value.

    The answer is not to choose between manual management and full autonomy. Build a control system in which machines execute within explicit boundaries, experiments establish causality, and a person remains accountable for the objective, economics and exceptions.

    Key takeaways

    • Automate repeatable execution, but keep conversion definitions, economic thresholds, exclusions and stop conditions under human control.
    • Fix the conversion signal before optimizing against it. Faster optimization only magnifies a bad definition.
    • Treat attributed conversions and incremental conversions as different measures. Attribution assigns credit; incrementality tests whether advertising caused an additional result.
    • For a Demand Gen asset uplift experiment, isolate one creative variable, use a 50/50 cookie-based split, protect the budget for at least four weeks and aim for at least 50 conversions across the test groups.
    • Scale only when a change passes two gates: it produces acceptable business economics and it operates without violating your controls.

    Choose exactly what automation is allowed to control

    A modular control console shows separate guarded mechanisms for budget, audiences, bidding, creative selection, and conversion quality.

    Automation is not one switch. Bidding, budgets, keyword or query expansion, audiences, creative, campaign construction and landing-page testing are separate control layers. Give each layer its own permission, boundary and owner.

    Some commercial platforms are marketed as handling campaign builds, bids, ad copy, keyword expansion, landing-page experiments and reporting. That feature scope is a vendor claim, not independent evidence that full autonomy will improve profit or generate incremental demand in your account. Evaluate the decision rights behind the feature list.

    Control layerWhat automation may doWhat you must defineWhen to pause it
    Conversion measurementReceive events and values used for optimizationWhich event represents a real business outcome and how its value is calculatedTracking breaks, duplicates appear or the mix of conversion events changes unexpectedly
    Bidding and budgetAdjust bids and allocate spend within approved campaignsMaximum acceptable acquisition cost, minimum acceptable return and hard spending limitsSpend or unit economics moves outside the approved boundary
    Queries and audiencesExplore demand patterns and expand reachMarkets, exclusions, customer fit and intent boundariesTraffic drifts toward irrelevant intent, excluded regions or low-value prospects
    CreativeAssemble, rotate or test approved assetsClaims, tone, brand rules and the hypothesis being testedA policy or brand risk appears, or simultaneous changes make the test uninterpretable
    Landing pagesRoute traffic or test approved variationsPermitted page elements, data handling and the required user journeyForms, tracking, consent mechanisms or essential page functions fail

    Write these boundaries before connecting a tool that can make changes. At minimum, your operating brief should contain:

    <!– wp:list {