Category: Content

  • AI Search Visibility and the New Publisher Control Layer

    AI Search Visibility and the New Publisher Control Layer

    AI search creates a consequential choice for publishers: content must be accessible enough to be discovered, but unrestricted crawler access may weaken control over valuable archives. Visibility strategy and content governance can no longer be treated as separate concerns.

    Two reports illustrate the emerging trade-off. One describes the factors associated with citations across prominent AI platforms; the other describes publisher tools for deciding which AI crawlers may access content. Together, they suggest a practical operating model built around influence, access, measurement, and deliberate rights decisions.

    AI visibility extends beyond the published page

    CrushPress.AI’s account of Goodie’s fourth AEO Periodic Table says the research examined 1.13 million prompts across ChatGPT, Claude, Perplexity, Grok, Gemini, and Google AI Mode. The reported framework assigns explicit weights to 14 factors and adds Search & Fan-Out Rank and Originality & Information Gain as new factors.

    The most strategically important finding may be the reported weight of external validation. According to the article, off-site earned and social citations represent 22% of total citation leverage, exceeding the contribution of any single on-page content factor in the framework. This does not establish that mentions automatically cause AI citations, but it does challenge a page-only approach to AI search optimization.

    For publishers, the implication is that accessibility is only one condition of visibility. Original material, conventional search prominence, references from other sites, and social discussion may all help an AI system encounter or evaluate a publisher’s work. Opening a site to crawlers cannot compensate for weak information value or a lack of recognition elsewhere.

    Crawler access is a policy decision, not a visibility guarantee
    Digital crawler devices approach an online archive through open, restricted, and closed access gates.

    The second report addresses the access side of the equation. CrushPress.AI reported that beehiiv integrated Cloudflare’s Crawl Control technology so newsletter publishers can monitor, permit, or restrict AI bots from the beehiiv dashboard. The interface reportedly shows attempted crawler access, blocked activity, and referral traffic attributed to AI interactions.

    That distinction matters because crawling, citation, and referral traffic are different events. A bot may access a page without citing it; an AI service may mention a publisher without producing a measurable visit; and a referral may arrive without revealing how extensively content was used. Crawler logs therefore describe access behavior, not the full value exchange between a publisher and an AI platform.

    The reported integration lets publishers allow or block specific AI models through simplified permissions, while Cloudflare is expected to update coverage as new crawlers appear. The article says beta access to activity insights is available to every beehiiv user, whereas blocking is available to beehiiv Max subscribers. These are platform-reported capabilities rather than evidence that a particular permission setting will improve revenue, citations, or audience growth.

    The core trade-off is distribution versus optionality

    The two choices described in the Cloudflare and beehiiv announcement are maximum discovery and content protection. Maximum discovery permits AI search engines and agents to crawl more freely in pursuit of broader distribution. Content protection blocks scraping to preserve archives for possible monetization or licensing.

    Policy posturePrimary objectiveEvidence to monitorMain limitation
    Broader accessIncrease the opportunity for AI discoveryCrawler activity, referrals, and observed citationsAccess does not guarantee attribution or traffic
    Stricter protectionRetain control over potentially licensable archivesBlocked requests and changes in discovery or referralsProtection may reduce opportunities to be found
    Model-specific accessBalance distribution and protection by crawlerResults associated with each permission decisionRequires continuing review as crawlers and services change

    The appropriate posture may differ by publishing model. A publication that depends on reach may place more value on discoverability, while one with a differentiated paid archive may place more value on preserving licensing options. A model-specific approach can sit between those positions when the available controls support it.

    A practical framework connects permissions to outcomes
    People gather around a table where four symbolic tools connect to a protected digital content archive.

    Define the objective first. A crawler setting should serve an explicit goal, such as brand visibility, qualified referrals, subscription growth, archive protection, or future licensing. Without that goal, access decisions risk becoming symbolic rather than operational.

    Separate access metrics from visibility metrics. Crawler attempts and blocked requests indicate demand for access. Referral traffic indicates one form of audience return. Citations and brand mentions indicate representation inside AI answers. These measurements answer different questions and should not be collapsed into a single AI traffic number.

    Invest beyond crawler permissions. The AEO research summary points to originality, search and fan-out rank, and off-site earned and social citations. Publishers seeking AI visibility therefore need useful source material and external recognition as well as technically accessible pages.

    Review policies by crawler. The beehiiv integration reportedly supports permissions for specific AI models. Publishers can use that granularity to compare access activity and referrals before applying one rule to every bot, while recognizing that the supplied reports do not establish the commercial value of any individual crawler.

    Preserve uncertainty in evaluation. Neither source proves that allowing a crawler causes citations or that blocking one preserves a future licensing opportunity. Decisions should be treated as revisable policies informed by observed results, not permanent conclusions drawn from a single dashboard or ranking study.

    Key takeaways

    • AI search visibility combines content quality, conventional discoverability, external recognition, and crawler access.
    • Goodie’s reported framework gives off-site earned and social citations 22% of total citation leverage, highlighting the importance of signals beyond a publisher’s own pages.
    • Cloudflare and beehiiv reportedly give newsletter publishers visibility into crawler activity and controls for permitting or blocking specific AI models.
    • Crawling, citation, and referral traffic are distinct outcomes and should be measured separately.
    • Publisher controls work best when they are tied to a declared distribution, subscription, protection, or licensing objective.

    Visibility strategy will become a governance discipline

    As access controls become easier to operate, the difficult work will shift from implementation to judgment. Publishers will need to decide which forms of AI discovery create value, what evidence supports that conclusion, and which content rights they are unwilling to exchange for uncertain exposure. The strongest strategy will keep those decisions measurable and reversible as both crawler behavior and citation patterns evolve.
    References

  • AI-Assisted SEO Content Operations: A Scalable Framework

    AI-Assisted SEO Content Operations: A Scalable Framework

    AI can make SEO production faster, but speed does not resolve the central challenge of content operations: ensuring that business economics, workflow systems and editorial judgment continue to support the same goal. If those elements drift apart, greater output can simply multiply weak decisions.

    A durable AI-assisted operation therefore begins with the publishing model, not the model prompt. The practical objective is to encode useful expertise into repeatable workflows while preserving human control over strategy, evidence, quality and investment.

    Key takeaways

    • Content volume should follow audience demand and unit economics rather than the availability of inexpensive AI production.
    • Generic AI output becomes more useful when an organization supplies its own customers, priorities, standards and SEO process as context.
    • Custom assistants are best treated as workflow infrastructure: they can apply a defined method repeatedly, but they do not replace editorial judgment.
    • Quality controls and performance feedback must be designed into the operation before production expands.

    Scalability starts with economic and editorial fit

    The first source describes a structural problem that appears when content businesses grow: economic objectives, operating systems and editorial decisions can become disconnected. A small team may coordinate through experience and close working relationships, while a large network needs explicit systems and data to keep production coherent. AI increases the importance of that distinction because it makes additional drafts easier to create without proving that additional publishing is warranted.

    Volume is also category-dependent. The scaling article contrasts a niche B2B product, where very high output could waste resources, with sports publishing, where games, teams, players and continuing developments can support frequent coverage. Its example of The Athletic reports $54 million in revenue during one quarter and says direct consumer subscriptions provided most of that revenue. In that model, editorial quality is closely connected to the value customers are purchasing.

    The same source presents a more fragile equation for advertising-supported publishing: revenue equals pageviews divided by 1,000, multiplied by revenue per thousand impressions, while profit subtracts production cost. It illustrates the pressure with an article receiving 4,000 pageviews at a $16 RPM, producing $64 before production costs. These figures are an example reported by the source, not a universal benchmark. Their operational lesson is broader: when expected value per article is constrained, producing more content can magnify both small efficiencies and small quality failures.

    DecisionQuestion to resolve before scalingOperational consequence
    DemandDoes the audience have enough distinct, continuing needs to justify more pages?Sets a defensible ceiling for publishing volume.
    RevenueHow is each content type expected to contribute to the business?Determines what production cost and quality level the model can support.
    DifferentiationWhat knowledge, evidence or perspective makes the content worth choosing?Defines what must remain intact when AI assists production.
    GovernanceWho can approve, revise, pause or retire content?Prevents workflow speed from becoming uncontrolled publication.

    AI is most useful when it carries a specific SEO process

    The second source examines the workflow side of the problem. It reports that general-purpose tools such as ChatGPT and Google’s Gemini can perform standard on-page reviews, but their initial recommendations often remain generic because they lack the organization’s business context. Broad advice about improving content or acquiring links may be reasonable in the abstract while still failing to identify the best action for a particular company.

    That limitation points to the appropriate role for AI in content operations. The model should not be expected to discover the business strategy from a bare keyword or URL. It should receive a defined method: who the customer is, what the page is meant to accomplish, which competitive conditions matter, how evidence should be handled and what an acceptable deliverable contains.

    The workflow article highlights GPTs, Gems and Claude Projects as accessible ways to package such context without extensive coding. Its central claim is that the organization’s expertise is the valuable input; the assistant helps apply that expertise repeatedly. Combined with the scaling article, this suggests a clear division of labor: systems preserve and distribute an approved process, while editors decide whether that process is appropriate for a particular topic and business objective.

    A controlled operating loop connects strategy to publication

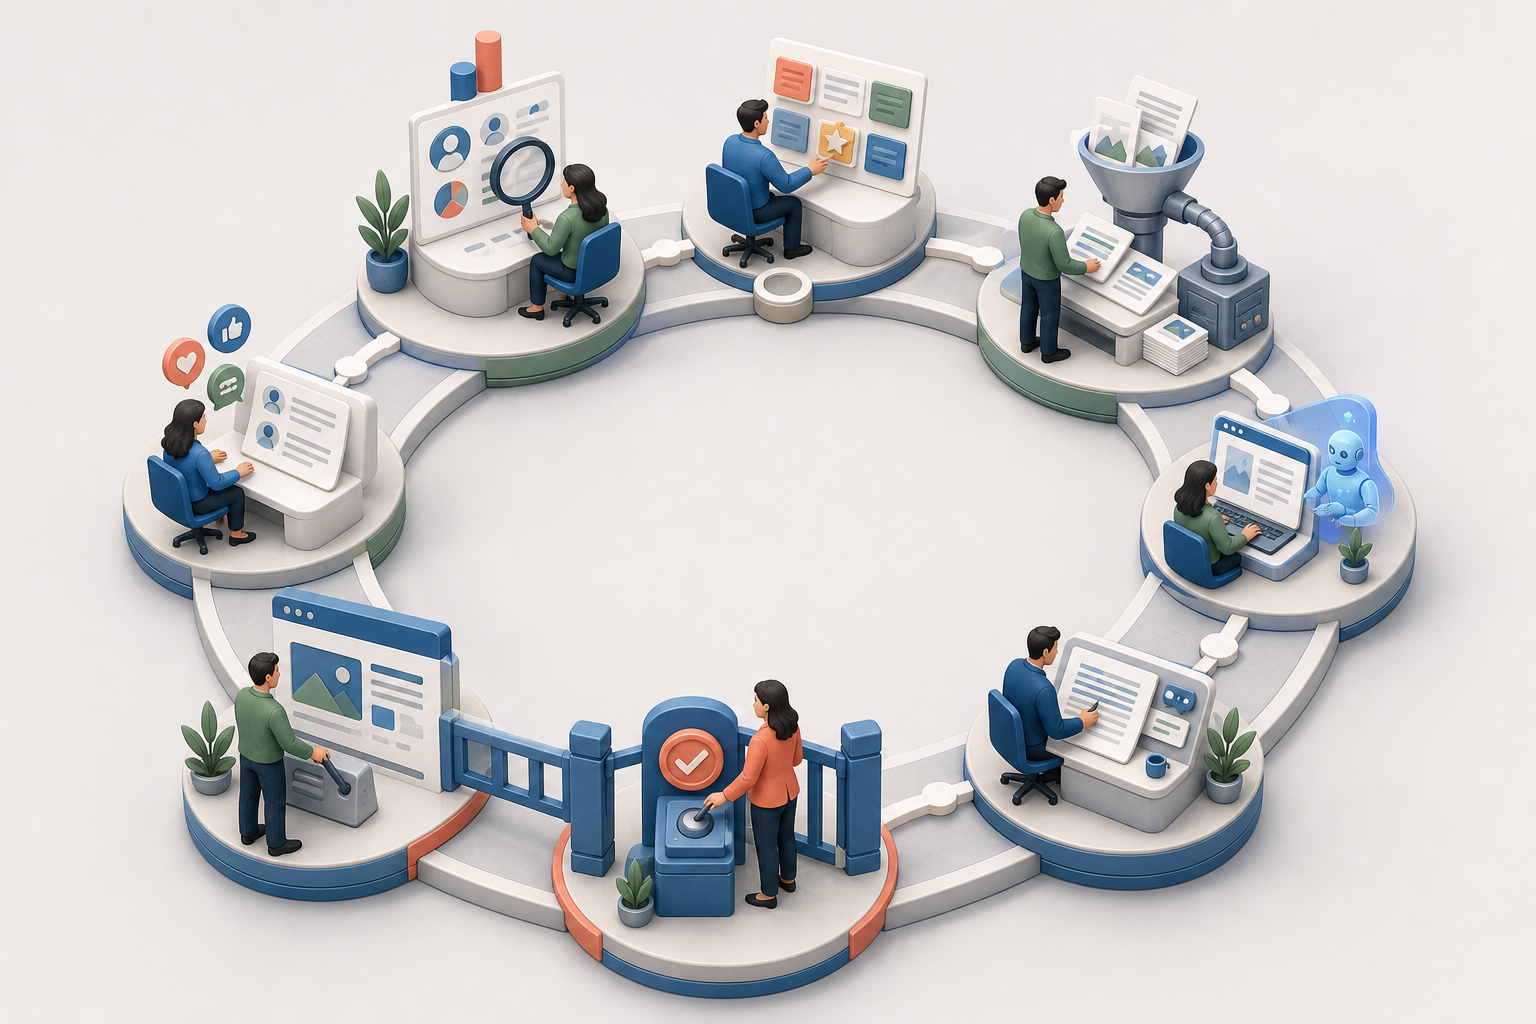
    An isometric circular workspace shows people guiding content through research, drafting, editing, approval, publication and feedback stages.

    Define the assignment before invoking AI

    Each assignment needs a business purpose, intended audience, search need, content type and success criterion. This brief is the bridge between economics and execution: it prevents a production system from treating every keyword as equally valuable and gives the assistant enough context to apply the organization’s method.

    Encode the repeatable method

    A custom assistant can carry reusable instructions for research organization, page analysis, outlines, optimization checks and editorial formatting. Stable standards can be embedded in the workflow, while changing inputs such as the audience, offer, competitors and source material should be supplied with each assignment. This separates institutional knowledge from task-specific evidence.

    Place human judgment at consequential gates

    Editorial review should concentrate on decisions with business or reputational consequences: whether the premise deserves publication, whether claims are supported, whether the page adds something useful, whether it matches the intended voice and whether optimization compromises clarity. The goal is not human intervention in every mechanical step; it is accountable control where errors would matter most.

    Return outcomes to the system

    Publication completes a production cycle, not a learning cycle. Performance observations, recurring editorial corrections and failed assumptions should inform briefs, assistant instructions and topic selection. Otherwise, an organization may automate the same avoidable weakness across an expanding library.

    Measure the operation at three connected levels

    Three connected scenes show an editor assessing an article, a team monitoring a content workflow and a leader observing business outcomes.

    Production metrics reveal whether work moves efficiently, but they cannot establish whether the work was worth producing. Editorial indicators examine accuracy, usefulness, distinctiveness and the amount of correction required. Business outcomes then show whether the content contributes to the economic model, whether that contribution comes from subscriptions, advertising, leads or another defined purpose.

    These levels should be interpreted together. Faster drafting with heavier editorial repair is not an unqualified efficiency gain. Higher traffic with production costs that exceed the resulting value is not sustainable growth. Strong individual pages in a category with insufficient demand do not justify unlimited expansion. The two source articles approach the issue from different directions, but they converge here: scalable content requires operational systems and contextual expertise, not output capacity alone.

    The next stage of AI-assisted SEO will belong to organizations that can make their judgment explicit, test it against business outcomes and revise the system without lowering the editorial standard that gives the content value.

    References

  • What Google Content Visibility Signals Really Tell Publishers

    What Google Content Visibility Signals Really Tell Publishers

    Google visibility is often discussed as if it could be improved through a single tactical change: choose a more successful headline pattern, add a machine-readable file, or imitate whatever appears to perform best across a large dataset. The source reporting points to a more demanding conclusion.

    A study of Google Discover headlines shows how an apparent format advantage can be driven by publisher and audience differences, while Google’s reported guidance on llms.txt says the file has no effect on Search rankings. Together, these accounts offer a practical way to distinguish an observable characteristic from a credible visibility lever.

    Visibility is not one outcome or one mechanism

    The two source articles address different Google environments. The Discover analysis concerns how often editorial articles appeared across the 1492.vision fleet. Its metric was hits per article, which the source described as a proxy for visibility rather than a count of Discover clicks. The llms.txt article, by contrast, concerns whether a site-level file affects visibility in Google Search.

    That distinction matters because a feature associated with frequent appearances on one surface is not automatically a ranking factor, a cause of traffic, or a general rule for Google visibility. A Discover headline can be correlated with exposure without causing it. A file can help another service understand a site while remaining irrelevant to Google Search. The surface, measured outcome, and proposed mechanism must therefore be identified before a result becomes actionable.

    Headline format looks powerful until publisher context is added

    Two contrasting publisher environments show different content-card styles, audience sizes, and distribution conditions around a central magnifying lens.

    The Discover report described an analysis of 1,674,518 English articles and 1,690,295 French articles from the 1492.vision corpus. When publishers were pooled, quote-led headlines produced 37% more hits per article than statements in English and 48% more in French. Questions also exceeded statements in the aggregate, by 7% in English and 16% in French.

    Those figures appear to support a simple editorial prescription. Yet the report argued that the aggregate comparison mixed together publishers with different audiences, subject matter, editorial styles, and patterns of Discover exposure. Celebrity publications, regional news organizations, and outlets focused on trending topics were among the types said to use quotations more often. Their underlying visibility could therefore make the quotation format look more effective than it was.

    The source identified this as an example of Simpson’s paradox: a relationship visible in pooled data can weaken, disappear, or reverse after the data is separated into meaningful groups. In this case, the relevant test is not simply whether all quote headlines outperform all statements. It is whether the formats perform differently within comparable publishers and contexts, with each publisher serving as its own baseline.

    This does not make headline construction irrelevant. It changes the claim that the evidence can support. The reported aggregate results describe where visibility occurred across a mixed population; on their own, they do not establish that converting a statement into a quotation will create the same lift for an individual publisher.

    Google’s llms.txt position removes a different false lever

    The second source reported that Google updated its AI Search optimization guidance to say that llms.txt files do not affect Search rankings. According to that account, Google Search does not use the files, and publishers do not need to create new AI-oriented text or Markdown files to qualify for inclusion in Search experiences involving generative AI.

    The reported guidance includes an important qualification: Google may still discover, crawl, and index various file types. That general ability does not mean llms.txt receives special ranking treatment. The source also noted that a site may maintain the file for other services without improving or damaging its Google Search visibility.

    This is a more direct finding than the Discover correlation. The headline analysis asks whether an apparent advantage survives contextual controls. The llms.txt guidance says the proposed mechanism is not used for the claimed Google Search benefit. One tactic requires better causal analysis; the other has been explicitly ruled out as a Google ranking aid in the source’s account.

    A stronger test for proposed visibility signals

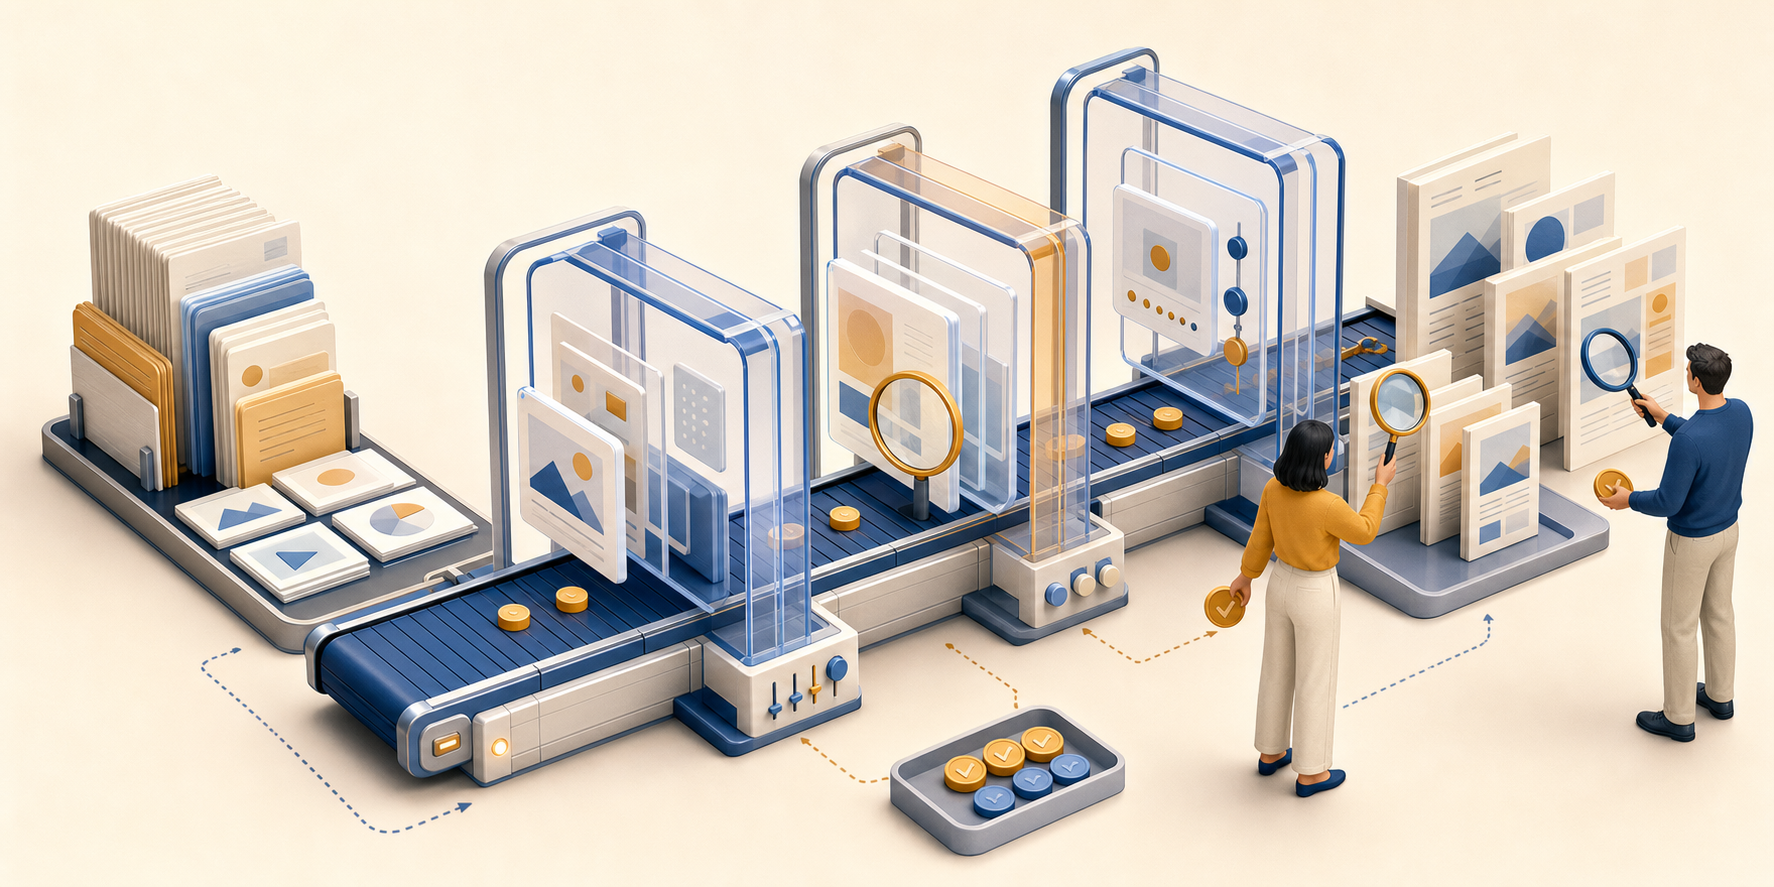
    Glowing signal tokens move through a sequence of evidence checkpoints, with weaker signals diverted and stronger signals reaching an illuminated content card.

    The synthesis suggests that publishers should evaluate any claimed signal along three dimensions. First, the claimed outcome should be precise: ranking position, impressions, Discover appearances, clicks, or another measure. Second, comparisons should account for publisher, audience, topic, language, and surface whenever those factors could influence both the tactic and the outcome. Third, the proposed mechanism should be checked against Google’s stated use of the feature when relevant guidance exists.

    For headline decisions, the most informative evidence would come from comparisons within the same publication and from controlled editorial tests that keep topic and distribution conditions as comparable as possible. Hits per article can reveal exposure patterns, but it should not be presented as click performance or as proof that punctuation and syntax independently caused the result.

    For machine-readable files, the decision can be separated by beneficiary. An llms.txt file may be maintained for a non-Google service that uses it, but the reported Google guidance provides no basis for treating its creation as a Search ranking project. This prevents an implementation task from being justified with an unsupported visibility promise.

    Key takeaways

    • Google visibility claims must name the surface and metric; Discover hits, clicks, and Search rankings are not interchangeable outcomes.
    • The reported quote-headline advantage appeared in pooled English and French data, but publisher and audience differences made a simple format-based explanation unreliable.
    • Within-publisher comparisons are more useful than global averages when editorial conventions and baseline visibility vary across outlets.
    • According to the llms.txt source, Google Search does not use the file as a ranking aid, although sites may keep it for other services.
    • An observable pattern becomes actionable only after plausible confounders and the proposed mechanism have been examined.

    As new visibility tactics emerge, the durable editorial advantage will come from asking what was measured, what else could explain it, and whether the platform recognizes the proposed mechanism. That discipline leaves room for experimentation while keeping correlation, platform guidance, and causal claims in their proper roles.

    References

  • Instagram Empowers Users with Personalized Feed Controls

    Instagram Empowers Users with Personalized Feed Controls

    I’ve got exciting news for all Instagram enthusiasts! Instagram has now rolled out an update that allows us to tailor the Your Algorithm controls directly into our main feed experience. This means we have more power to manage the topics influencing our recommendations across Feed, Reels, and Explore.

    About Your Algorithm. This feature is designed to allow me to view the topics Instagram thinks I’m interested in. It gives me the option to remove topics I’m not keen on and add those I want to see more frequently. Although Instagram first introduced Your Algorithm for Reels last December, it has since broadened these controls across more recommendation surfaces.

    Feed joins Reels and Explore. Now, with this update, I can manage topic-level controls on my main feed. This change means the recommended posts I see—often from accounts I don’t follow—can be more aligned with my true interests.

    Instagram generates a list of topics based on my activity, and any tweaks I make to this list help the system fine-tune future recommendations.

    More user control. Adam Mosseri, the head of Instagram, mentions that this update addresses how we often feel out of control in recommendation-driven feeds.

    “Our system learns from what I tap, watch, and share, but there hasn’t been a clear way for me to tell it what I truly want,” Mosseri explained. With the help of large language models, Instagram can now describe content clusters in simple language, offering me a clearer way to shape the system’s understanding of my preferences.

    Interest media. As Gary Vaynerchuk brilliantly put it, there’s a shift happening from follower-based feeds, which he called social media, to interest-based discovery, or interest media. Insights show that platforms like Instagram are focusing on engagement-driven content rather than purely the accounts I follow. With this update, Instagram is transparent about the interests behind my recommendations.

    Why we care. Matching user interests has become a priority in Instagram’s discovery process. If you’re creating content, it’s crucial to signal specific topics and audience intent to increase visibility in recommendations.

    More controls are planned. Topics are just the beginning! Mosseri assured us that Instagram is also working on controls for people, moods, content types, and other signals.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Build Reusable AI Content Skills That Stay Useful

    How to Build Reusable AI Content Skills That Stay Useful

    You probably have a prompt that everyone on your team is supposed to use. It may be buried in a document, copied from an old chat, or rewritten from memory whenever someone starts a draft. That works until the prompt changes, a rule gets dropped, or two people interpret it differently.

    A reusable AI content skill gives those recurring instructions a stable home. Build it well, and you can spend less time rebuilding prompts while keeping voice, quality, and answer-engine requirements consistent across projects.

    Move durable decisions out of individual prompts

    The first decision is what deserves to become a skill. A useful candidate appears repeatedly, applies across multiple assignments, and should produce a consistent result regardless of who starts the workflow. Saving recurring instructions for reuse can reduce repetition while helping teams apply the same writing style, AEO practices, and content standards.

    Do not turn every long prompt into a permanent asset. Campaign facts, temporary offers, target keywords, product claims, and assignment-specific angles belong in the content brief. If you embed them in a reusable skill, they can quietly leak into unrelated work or become outdated.

    Put in the reusable skillKeep in the content brief
    Brand voice and prohibited languageThe audience for this specific page
    Required content structureThe query, topic, and search intent
    AEO and editorial quality checksApproved facts, claims, and references
    Citation and uncertainty rulesCampaign messaging and calls to action
    Standard output formatDeadlines, owners, and publishing details

    Use a simple test before promoting an instruction: would you want it applied to the next unrelated assignment? If the answer depends on the topic, client, campaign, or date, leave it in the brief.

    Write the skill as an operating contract

    A skill should tell the AI what job it is doing, what information it needs, which rules are mandatory, and how to recognize an acceptable result. Vague instructions such as “write high-quality SEO content” leave too much room for interpretation. Replace them with observable requirements.

    Skill fieldWhat to write
    PurposeThe narrow outcome this skill produces, such as an answer-first educational page.
    Use whenThe assignments that should trigger it, plus cases where it should not be used.
    Required inputsThe audience, intent, approved facts, desired action, and output destination.
    Non-negotiable rulesVoice, claim boundaries, citation requirements, prohibited language, and compliance constraints.
    MethodThe sequence for interpreting the brief, drafting, checking, and revising.
    Output contractThe required headings, markup, metadata, fields, or schema-ready information.
    Quality checksConditions the result must meet before it can be returned.
    Escalation ruleWhat the AI must flag instead of guessing when information is missing or contradictory.

    Write rules so an editor can verify them. “Use a direct answer near the opening” is testable. “Make it engaging” is not. “Link factual claims to approved references” is testable. “Sound authoritative” is not.

    Define priorities before instructions conflict

    Reusable defaults will eventually collide with a project brief. State the order of precedence inside the skill. A practical hierarchy is mandatory legal and brand policy first, assignment requirements next, skill defaults after that, and model discretion last. Adjust that hierarchy to match your organization, but do not leave it implicit.

    Add an escalation rule for unresolved conflicts. The AI should identify the clashing instructions and request a decision rather than quietly choosing whichever wording appeared most recently.

    Separate writing, optimization, and validation

    Three separate workstations represent writing, optimization, and final content validation in a staged workflow.

    One giant skill may look efficient, but it becomes difficult to maintain. A change to your brand voice should not require rewriting your structured-data rules. A new citation policy should not disturb the way product pages are organized.

    Use a small set of focused layers. A voice skill can control tone, sentence style, terminology, and banned phrasing. A content-type skill can define the structure for an explainer, comparison, landing page, or documentation page. An AEO skill can require a direct response to the main question, intent-aligned headings, clear entities, useful follow-up coverage, and supported claims. A validation skill can check the finished draft for omissions and violations.

    Keep validation separate from generation when possible. Asking the same instruction block to draft and approve its own output can hide errors. A dedicated check should compare the result with the brief and return specific failures: an unsupported claim, a missing answer, an inconsistent term, or an invalid output field.

    This separation also makes ownership clearer. Brand teams can maintain voice rules, search teams can maintain AEO requirements, subject experts can maintain claim boundaries, and content operations can maintain formatting. Each group can update its layer without reopening the entire workflow.

    Test the skill against real editorial failures

    A technician tests a modular content system against abstract obstacles representing common editorial failures.

    A skill is not ready because it worked on the prompt used to create it. Test it with representative briefs: a straightforward assignment, an incomplete one, a request that conflicts with brand policy, and a topic where the supplied evidence does not support a confident claim.

    Review the outputs by failure type. Check whether the voice drifted, the answer arrived too late, unsupported details appeared, mandatory fields were omitted, or the AI followed a lower-priority instruction. Record the failure and revise the smallest instruction that caused it.

    Change a single rule at a time when practical. Otherwise, you will not know which revision fixed the problem or introduced a new one. Preserve previous versions and note why each update was made. That turns the skill into a managed editorial asset instead of an anonymous prompt that gradually accumulates exceptions.

    Watch for rules that belong elsewhere

    Repeated exceptions are diagnostic. If editors constantly override the same voice rule for product pages, you may need a separate product-page skill. If factual corrections recur, the problem may be the approved material supplied with the brief rather than the writing instructions. If output fields disappear, strengthen the output contract and validation layer.

    Do not solve every failure by adding more words. Remove duplicated rules, merge instructions that mean the same thing, and replace subjective adjectives with checks an editor can observe. A shorter skill with clear boundaries is easier to trust than a long one full of overlapping advice.

    Key takeaways

    • Save stable, recurring editorial decisions as skills; keep assignment-specific facts and goals in the brief.
    • Define the skill’s purpose, trigger, inputs, mandatory rules, output contract, checks, and escalation behavior.
    • Use focused layers for voice, content type, AEO requirements, and validation so each can be maintained independently.
    • Make every instruction observable enough for an editor to verify.
    • Test against incomplete and conflicting briefs, then revise the smallest rule responsible for each failure.
    • Version skills and record why they changed so teams know which standard is active.

    Start with the instruction block your team copies most often. Remove anything tied to a single assignment, give the remaining rules a clear output contract, and test the skill on work your editors already know well. Once that first skill performs reliably, use the same pattern for the next recurring workflow.

    References

  • How to Align Claude With Your Brand Voice Consistently

    How to Align Claude With Your Brand Voice Consistently

    You ask Claude for a polished draft, but the result sounds like polished AI: competent, smooth, and interchangeable with everyone else’s content. Repeating your preferred tone or asking it to sound more human rarely fixes the underlying problem.

    You need to turn brand voice from a subjective impression into instructions Claude can apply and your team can review. With clear rules, representative examples, and a repeatable editing loop, Claude can reflect your brand voice without merely copying an old draft.

    Translate your brand voice into observable choices

    An editor's hands organize unlabeled sliders, dials, colored tokens, and differently sized blocks on a neutral workspace.

    Words such as friendly, authoritative, bold, and conversational are too open to interpretation. A financial adviser and a fitness coach can both sound friendly while using completely different language, pacing, evidence, and calls to action.

    Build a compact voice card that describes what a writer should do on the page. Cover these areas:

    • Audience: Name the reader, what they already understand, and the decision they are trying to make.
    • Relationship: Decide whether the brand acts as a specialist, teacher, peer, challenger, or reassuring adviser.
    • Sentence behavior: Describe the preferred pace, paragraph length, use of contractions, and tolerance for jargon.
    • Vocabulary: List preferred terms, words that require explanation, and language the brand avoids.
    • Evidence: Explain when claims need examples, data, citations, qualifications, or practical next steps.
    • Point of view: Specify when to use you, we, the company name, or a neutral construction.
    • Formatting: Define how headings, lists, calls to action, and emphasized text should work.
    • Boundaries: Identify tones the brand must never adopt, such as smug, alarmist, vague, or overly promotional.

    Make every rule testable. Replace be clear with explain technical terms on first use. Replace sound confident with state the recommendation directly, then explain its limits. Replace avoid hype with remove unsupported superlatives, urgency, and promises of guaranteed results.

    Add contrast when a rule could be misunderstood. For example: direct, not abrupt; informed, not academic; warm, not chatty; persuasive, not pushy. These boundaries help Claude distinguish your intended voice from a nearby but unsuitable one.

    Choose examples that teach judgment, not imitation

    Examples show Claude how your rules interact in real writing. Use approved material that still represents the brand. A rushed email, an outdated landing page, and an executive’s personal writing style can introduce conflicting signals.

    Label why each example belongs

    Do not paste examples into the prompt without explanation. Mark the behavior Claude should learn from each one:

    • This opening names the reader’s problem before introducing the company.
    • This explanation defines the technical term without talking down to the reader.
    • This transition moves from evidence to a recommendation without overstating certainty.
    • This call to action describes the next step without manufacturing urgency.

    Also distinguish voice from content. Tell Claude that names, claims, prices, dates, product details, and recommendations in an example are not facts for the new draft. They are reference material only for language, structure, and tone.

    Include useful negative examples

    A rejected line becomes valuable when you explain the rejection. Pair it with an approved rewrite and a reason. The reason might be that the original buries the answer, uses an empty superlative, assumes too much knowledge, or turns a measured claim into a guarantee.

    Negative examples work best when they are close to acceptable. Obvious failures teach little. A plausible sentence that misses your voice reveals the boundary Claude needs to recognize.

    Give Claude a prompt with clear layers

    A reliable brand prompt separates permanent voice rules from the current assignment. This prevents campaign details from being mistaken for lasting brand principles and makes the setup easier to reuse.

    Use this sequence when assembling the prompt:

    1. Set the role. Identify the brand, the type of writer Claude should act as, and the responsibility it has to the reader.
    2. Define the reader and outcome. State who the content serves, what brought that person to the page, and what they should understand or do afterward.
    3. Insert the voice card. Include observable language rules, preferred vocabulary, formatting conventions, and prohibited tendencies.
    4. Add annotated examples. Explain which behaviors to reproduce and which factual details not to carry into the new work.
    5. Provide task facts. Supply the brief, approved claims, required links, product information, and any material that must appear.
    6. Set hard constraints. Name the required format, scope, compliance boundaries, and anything Claude must not infer.
    7. Request a self-check. Ask Claude to identify any voice rule it could not satisfy and flag missing facts instead of filling gaps.

    Keep priorities explicit. Accuracy and legal or editorial constraints come before style. Voice rules come before decorative flourishes. Examples demonstrate delivery but do not override the approved facts in the brief.

    If the assignment is complex, ask for an outline before the full draft. Review whether the planned argument suits the reader and brand posture. Fixing a structural mismatch at that stage is easier than polishing an entire draft built on the wrong approach.

    Review voice alignment with evidence

    Do not approve a draft because it feels roughly on-brand. Review it against the voice card and point to the language that passes or fails each rule.

    • Does the opening address the reader’s actual concern, or does it begin with background they did not ask for?
    • Are recommendations stated directly and supported at the level your brand expects?
    • Would the intended reader understand every technical term without leaving the page?
    • Does the draft preserve uncertainty where the available facts are limited?
    • Are paragraphs, headings, and lists consistent with your publishing conventions?
    • Does the call to action offer a relevant next step rather than switching into sales language?
    • Could a competitor publish the draft unchanged? If so, which brand-specific judgment or vocabulary is missing?

    When something fails, give Claude a diagnostic correction. Instead of make this warmer, identify the behavior: the paragraph sounds distant because it uses abstract nouns and never addresses the reader. Ask for a revision that speaks to you, keeps the technical meaning, and removes the abstract phrasing.

    Save recurring corrections as new voice rules. If editors repeatedly remove inflated claims, add an explicit rule about claim strength. If introductions repeatedly take too long to reach the answer, define what the opening must accomplish. Your editing history should improve the system, not disappear into individual drafts.

    Turn a successful prompt into a content workflow

    Two team members inspect content pages moving through a modular workflow of transparent frames, review lenses, and adjustment controls.

    Brand alignment breaks when every writer maintains a different prompt. Store the approved voice card, examples, exclusions, and review checklist in one controlled location. Give the material an owner and update it when the brand changes.

    Separate the workflow into clear responsibilities:

    • Brand owner: Approves voice rules, terminology, and representative examples.
    • Subject specialist: Supplies facts, qualifications, and claims that may be made.
    • Prompt owner: Maintains the reusable instructions and resolves conflicts between them.
    • Editor: Checks the draft against the brief, voice card, and publishing requirements.
    • Approver: Accepts the final communication risk rather than assuming the model has done so.

    Track failures by type. Voice drift, unsupported claims, weak structure, missing context, and formatting errors need different fixes. A voice rule will not repair a thin brief, and another example will not resolve contradictory product facts.

    Test revisions with the same assignment whenever possible. If you change the voice card and the brief at once, you cannot tell which change improved the result. Keep approved outputs as benchmarks, but continue reviewing new drafts; consistency is a managed process, not a one-time prompt.

    Key takeaways

    • Replace broad adjectives with observable rules about wording, structure, evidence, and reader treatment.
    • Use current, approved examples and label the behavior Claude should learn from each one.
    • Keep voice instructions, task facts, examples, and hard constraints in separate prompt layers.
    • Review drafts against explicit criteria and turn repeated editorial corrections into reusable rules.
    • Assign ownership for the voice system so every writer works from the same approved standard.

    Start with one approved asset and extract the decisions that make it sound like your brand. Build the voice card, run a real assignment through it, and record every correction. That gives you something more durable than a good draft: a system your team can improve each time it publishes.

    References

  • Harnessing Psychology: Create Persuasive Content That Converts

    Harnessing Psychology: Create Persuasive Content That Converts

    How persuasive content taps into human psychology

    I’ve noticed that TikTok Shop creators excel by tapping into the psychology that drives people to act. Let me share how we can leverage these persuasive principles in our writing.

    SEO content is often designed to rank, but conversion can sometimes fall by the wayside when we’re caught up in the technical checklist. In light of AI Overviews and falling click-through rates making visibility more challenging, I believe it’s time to focus on whether our content encourages action once someone engages with it.

    Take a cue from TikTok Shop creators—they don’t just thrive because of large followings. They master persuasion by understanding consumer psychology and scaling actions. This insight can transform how we approach our written content.

    The formula that successful TikTok Shop creators follow isn’t random. It relies on consumer psychology principles, not on celebrity status or follower count. I’ve realized that 99% of my own video views come from non-followers. Therefore, it’s the understanding of the psychology behind actions that matters.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

    By focusing on visual hooks, psychological triggers, storytelling, and relentless experimentation, we can apply these elements to written content to drive similar results.

    People often buy based on emotions, justifying their decisions rationally later. It’s crucial to connect with their motivations rather than just presenting facts.

    Persuasive content succeeds because it targets human desires like protecting loved ones, enjoying life, feeling safe, and seeking social approval.

    Understanding these motivations allows me to craft content that resonates more deeply with my audience, ultimately leading to better engagement and conversion rates.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Build an SEO Strategy for AI Buyer Journeys

    How to Build an SEO Strategy for AI Buyer Journeys

    If your SEO plan ends at “answer the query,” you may win a ranking and still lose the buyer. People often search with a solution already in mind, even when they have not fully examined the problem or the alternatives.

    Your content needs to do two jobs: satisfy the immediate intent and help the reader make a better decision. That combination is especially important when an AI-generated answer can handle the basic summary before anyone visits your site.

    Key takeaways

    • Map the buyer’s problem, assumed solution, and credible alternatives instead of targeting isolated keywords.
    • Answer the stated query before introducing a different path; otherwise, the page feels evasive or promotional.
    • Build depth with decision criteria, trade-offs, firsthand experience, and next-step guidance rather than extra word count.
    • Match calls to action to the reader’s stage, from a diagnostic tool for early research to a consultation or purchase for late-stage demand.
    • Measure assisted journeys and qualified outcomes, not rankings and last-click conversions alone.

    Map the decision behind each search query

    A buyer stands at a three-way junction connecting an obvious solution with alternative routes and symbols of deeper investigation.

    A keyword tells you what someone typed. A journey map tells you what they are trying to change, what solution they currently believe in, and what uncertainty is keeping them from acting.

    Start with one commercially important problem. Then collect the searches that can appear before, during, and after the obvious product comparison. These journey-adjacent queries often look unrelated in a keyword tool, but they belong to the same decision.

    Query signalWhat the buyer may be thinkingUseful content response
    Problem-led: “How do I reduce lawn maintenance?”I want an outcome, but I have not chosen a solution.Explain the available paths, their trade-offs, and who each one suits.
    Operational: “How often should I cut grass?”I may still be trying to solve the problem myself.Answer the task, then show when a tool or service becomes worthwhile.
    Category-led: “Robot lawnmower price”I recognize a solution and need help evaluating it.Cover total decision criteria, limitations, and alternatives to ownership.
    Comparison-led: “Robot mower vs. lawn service”I am actively weighing different approaches.Use a balanced comparison tied to property, effort, control, and support needs.
    Branded research: “[Brand] reviews” or “[Brand] competitors”I know the brand but remain open to evidence or another option.Provide verifiable proof, candid constraints, and a clear fit assessment.
    Branded transaction: “[Brand] buy”I have probably made the decision.Remove friction and keep alternative messaging secondary.

    The opportunity is usually greatest before the final branded transaction. Someone researching reviews, costs, methods, or competitors is still testing assumptions. A useful page can introduce an option the buyer had not considered without ignoring the question that brought them there.

    For each priority problem, write down three statements: “The buyer wants…,” “The buyer currently assumes…,” and “The buyer may not know….” Those statements give your content team a stronger brief than a primary keyword and target word count.

    Build a content system that can redirect the journey

    Interconnected content modules guide several buyers from broad discovery through deeper resources toward a decision point.

    Journey-aware SEO is not one oversized guide. It is a connected set of pages that serve different levels of awareness while moving the reader toward the next useful question.

    1. Create a problem hub. Explain the outcome the reader wants, the main causes or constraints, and the broad solution categories. Keep it neutral enough to earn trust.
    2. Publish intent-matching pages. Build focused pages for the searches you already know matter: costs, reviews, comparisons, implementation questions, and product use cases.
    3. Add alternative-path pages. Compare approaches the buyer may not yet view as competitors. A service can compete with software, ownership can compete with rental, and a paid offer can compete with a do-it-yourself process.
    4. Connect the pages deliberately. Link from the direct answer to the relevant alternative, then from the comparison to evidence, tools, case examples, and commercial pages.
    5. Assign one next step to each page. Decide what the reader should do after learning: diagnose the problem, compare options, calculate cost, read an experience, request help, or buy.

    The order matters. A page targeting “how often to cut grass” should answer that question before presenting a robot mower or lawn service. Once the reader has the answer, you can explain the conditions under which doing the work personally becomes inconvenient. The offer then appears as a relevant decision path rather than an interruption disguised as advice.

    Use internal-link language that describes the decision waiting on the next page. “Compare the cost of a mower with a recurring service” is more useful than “learn more.” It sets an expectation for the reader and makes the relationship between the pages explicit.

    Go deeper than the answer an AI can summarize

    AI summaries can cover the first layer of a question. Search behavior is also becoming more conversational, with people supplying more context in longer, more detailed queries. A page that merely defines the topic or repeats common advice gives the reader little reason to visit, trust, or cite your brand.

    Depth is not length. A deep page removes uncertainty that a short answer leaves behind. After the direct answer, add the information a person needs to make or defend a decision:

    • Decision criteria: the conditions that should change the recommendation.
    • Trade-offs: what the reader gains, gives up, pays for, or must maintain.
    • Fit and non-fit: who benefits from an option and who should choose something else.
    • Experience: what happened during implementation, what was unexpectedly difficult, and what changed after use.
    • Evidence: named methods, transparent examples, attributable claims, and limitations.
    • Next questions: the issues a careful buyer should investigate before acting.

    Human experience is particularly valuable in purchase decisions because buyers want to know what using a product or service was actually like. Capture that experience with structured interviews, customer stories, screenshots, demonstrations, expert commentary, or original analysis. Do not turn a testimonial into universal proof. Keep the context that explains why the outcome occurred.

    Make the resulting page easy to parse. Use a descriptive heading for each decision, answer it directly in the opening sentence, and keep supporting detail close to the claim. Define ambiguous terms. Name the compared options consistently. A person should be able to scan the page and understand the decision path without reconstructing it from scattered paragraphs.

    Structured data comes after this editorial work. Mark up information that is genuinely present and visible, such as organization details, breadcrumbs, product information, or a real question-and-answer section. JSON-LD can clarify entities and relationships; it cannot turn generic content into original expertise.

    Turn broader discovery into a measurable, ethical path

    A journey-interrupting page should not force every reader toward the same conversion. Match the offer to the amount of commitment the query implies. Early problem research may call for a checklist, assessment, template, calculator, webinar, or email course. A comparison page can lead to a detailed case example or fit guide. A late-stage product page can ask for a demo, consultation, trial, or purchase.

    Measure the system at three levels. First, check whether the content is being discovered for problem-led, comparison, and branded research queries. Second, inspect whether readers continue to the intended decision page or use the supporting tool. Third, connect those journeys to qualified leads, trials, sales, or another business outcome. Assisted conversions matter because the page that changes the buyer’s frame may not be the final page visited.

    Review weak pages by asking a diagnostic question rather than adding more copy. If impressions are low, the query set or internal linking may be incomplete. If people arrive but do not continue, the alternative may appear too early, feel irrelevant, or lack evidence. If engagement is healthy but commercial outcomes are poor, the call to action may ask for more commitment than the reader is ready to give.

    Use stricter guardrails when the decision affects health, finance, education, or a career. Present alternatives in proportion to the evidence. State meaningful risks and limitations. Do not position a product as a substitute for professional care or imply that one path fits everyone. Health-related promotions also need appropriate legal and subject-matter review, including attention to FDA and FTC requirements. Responsible journey expansion gives the reader more agency; it does not exploit uncertainty.

    Start with one product line and one problem this week. Map the assumed solution, identify one credible alternative, and upgrade the relevant page with a direct answer, decision criteria, honest trade-offs, and a stage-appropriate next step. That small cluster will show you where a broader AI-search content strategy deserves investment.

    References

  • Why Quality Content Often Fails to Rank on Google

    Why Quality Content Often Fails to Rank on Google

    I find it intriguing how, despite creating stellar content, it often doesn’t make it to the top of Google’s search results. What holds it back isn’t necessarily quality—there are usually other roadblocks in play. Let me break down how to identify what’s hindering your content’s rankings.

    The common advice has always been to create helpful, high-quality content to rank well. However, this piece of advice doesn’t cover the full story of Google’s search algorithm mechanics.

    Even if your content is well-researched and aligned with search intent, technical barriers and competition may still impede its visibility. Identifying these barriers is crucial before deciding to rewrite any piece of content.

    Before blaming your content’s positioning, it’s essential to assess its quality. I often observe pages that don’t stand out, sometimes being autogenerated with minimal editorial input. Google’s guidelines on helpful content underscore the significance of experience and trust.

    Ask yourself: Does your content deliver unique insights, adhere to Google’s preferred format, and offer value beyond the current top results? A ‘yes’ suggests positioning issues; otherwise, focus on enhancing your content’s quality first.

    ```json
{
  "alt": "The CapmatchOne logo with a gradient circle and bold text.",
  "caption": "Discover innovation with the CapmatchOne logo, featuring sleek typography and a modern gradient circle.",
  "description": "The CapmatchOne logo features bold, modern typography coupled with a gradient circle, symbolizing connection and innovation. The sleek design conveys a sense of progress and creativity. This image can be used for branding or promotional purposes, appealing to audiences interested in innovative solutions and forward-thinking designs."
}
```

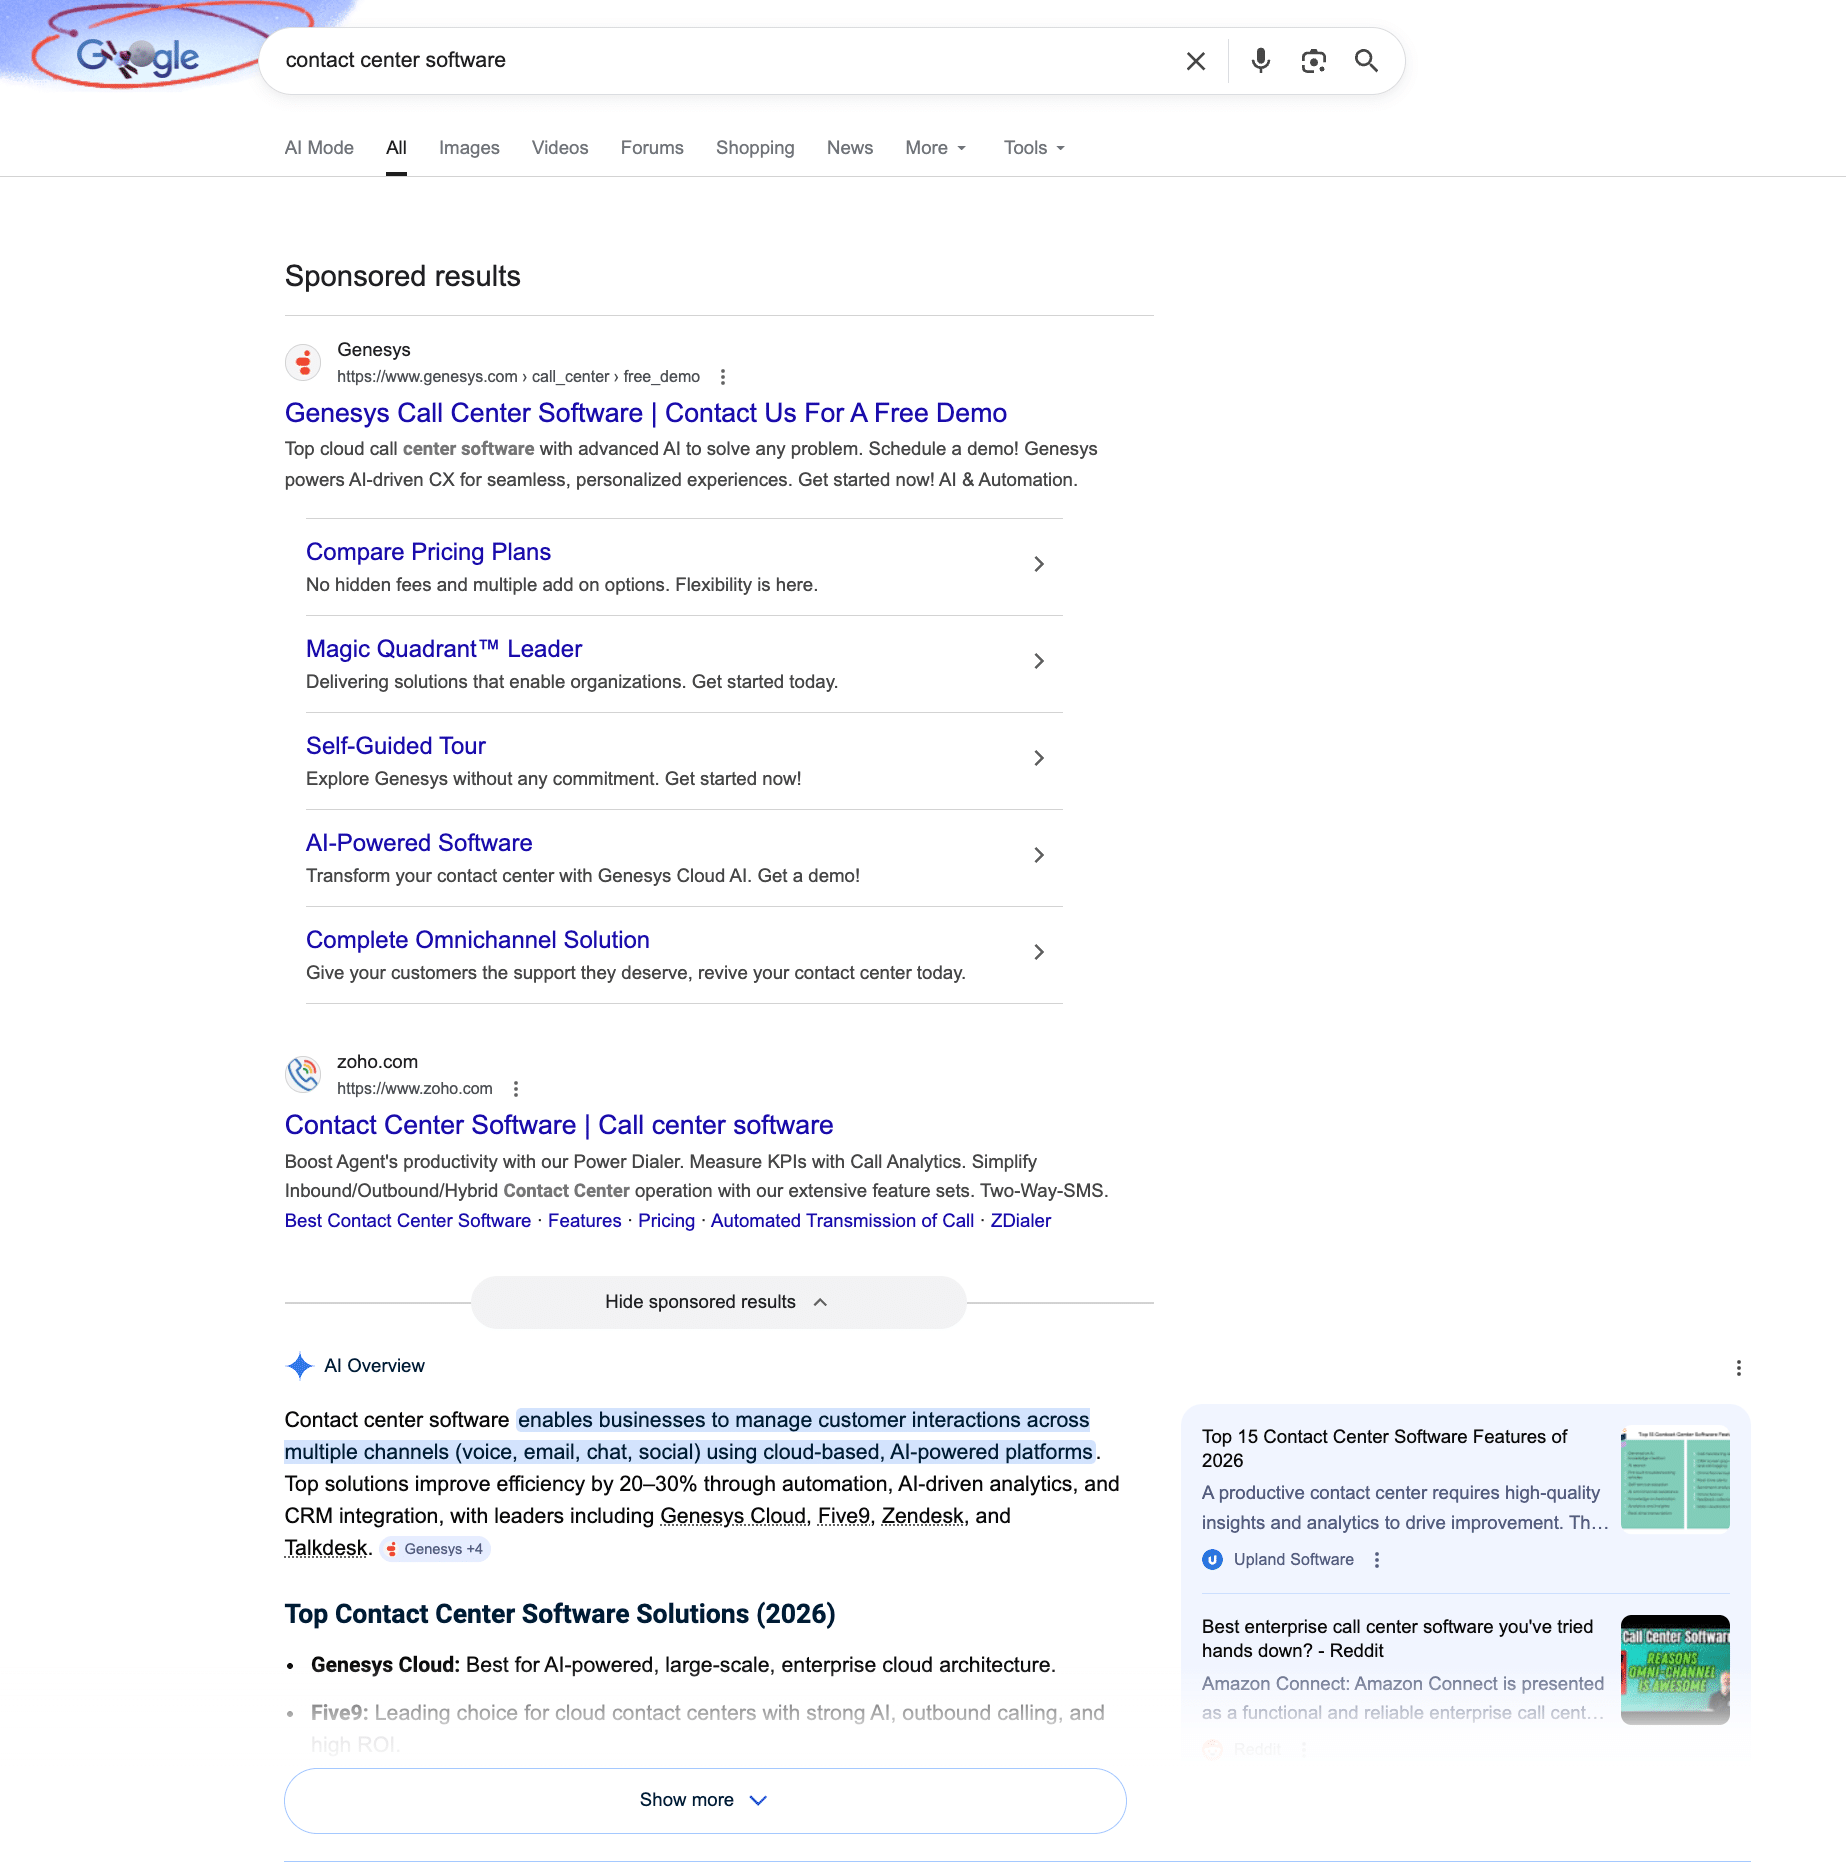
    In the competitive 2026 search landscape, various factors such as AI summaries and an increased ad presence are reshaping search results pages, making it harder for organic content to achieve visibility.

    Understanding what your content is truly competing against is key. If these external factors push your content down the page, adjustments are necessary to remain competitive.

    When questioning why good content isn’t ranking, I employ a diagnostic framework that prioritizes technical issues. Ensuring that your page is indexed and free from technological hurdles is the first and simplest step to address.

    Matching search intent with your content’s format is also critical. If your content is misaligned, improving it won’t suffice unless you address the fundamental disconnect.

    ```json
{
  "alt": "Google search results page for contact center software, showing sponsored listings for Genesys and Zoho.",
  "caption": "Exploring contact center software options? This Google search results page highlights sponsored listings from Genesys and Zoho, offering AI-powered solutions.",
  "description": "This image shows a Google search results page for 'contact center software'. Two prominent sponsored listings from Genesys and Zoho are displayed. Genesys offers AI-driven solutions for seamless, personalized contact center experiences, while Zoho promotes call analytics and multi-channel interaction management. The page provides further insights into contact center solutions with links and detailed descriptions. Keywords: contact center software, Genesys, Zoho, AI-powered, solutions."
}
```

    If a large trust signal gap exists between your domain and your competitors’, repositioning is often necessary to focus on less competitive keywords where you can compete effectively.

    The type of website you manage affects which barriers are most significant. For example, SaaS platforms typically face challenges concerning authority more than technical issues, while ecommerce sites contend with technical constraints.

    Understanding and applying this diagnostic sequence helps identify and address potential bottlenecks, ultimately allowing your content to rank better by focusing on what truly matters.

    In 2026, as the ease of generating good content continues to grow due to AI, positioning becomes crucial. Differentiated, experience-driven content is what stands out and captures attention.

    Your strategic question isn’t just about creating good content. It’s about understanding the landscape: What else is required for your content to achieve outstanding results in the search arena?


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Unlock Seamless Integration with Google Drive and Notion

    Unlock Seamless Integration with Google Drive and Notion

    As I delve deeper into enhancing my workflow, I realize that effective agents thrive on comprehensive context. Thanks to Profound’s Knowledge Bases, I empower my agents with my unique brand voice, product intricacies, and messaging guidelines.

    Now, I’m excited to share that integrating these knowledge bases with Notion and Google Drive is easier than ever. This integration allows me to streamline my processes and maintain consistency.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot