Category: AI

  • Profound MCP Connectors: What the Integration Really Means

    Profound MCP Connectors: What the Integration Really Means

    Profound’s External MCP Connectors are presented as a way to bring outside work systems into Profound through a shared integration layer. The practical promise is less tool switching: information and actions associated with content management, project tracking, and team communication could become accessible from a more centralized workflow.

    The available source is a short, vendor-authored announcement rather than independent testing or detailed technical documentation. Its claims therefore establish Profound’s intended direction, but not the connector catalog, supported operations, security model, or measurable productivity gains.

    What Profound says its external connectors enable

    According to the Profound post, External MCP Connectors can link the platform with CMS tools, project trackers, and team communication platforms. The announcement describes these connections as a way to manage projects, streamline workflows, improve collaboration, and access important tools from a central hub.

    Those statements should be read as product positioning. The source does not identify particular supported services, distinguish between read-only access and write actions, or demonstrate a complete workflow. It also offers no comparative results showing how much time or effort the connectors save. Consequently, the meaningful takeaway is the proposed integration model, not a verified performance outcome.

    Why MCP changes the integration conversation
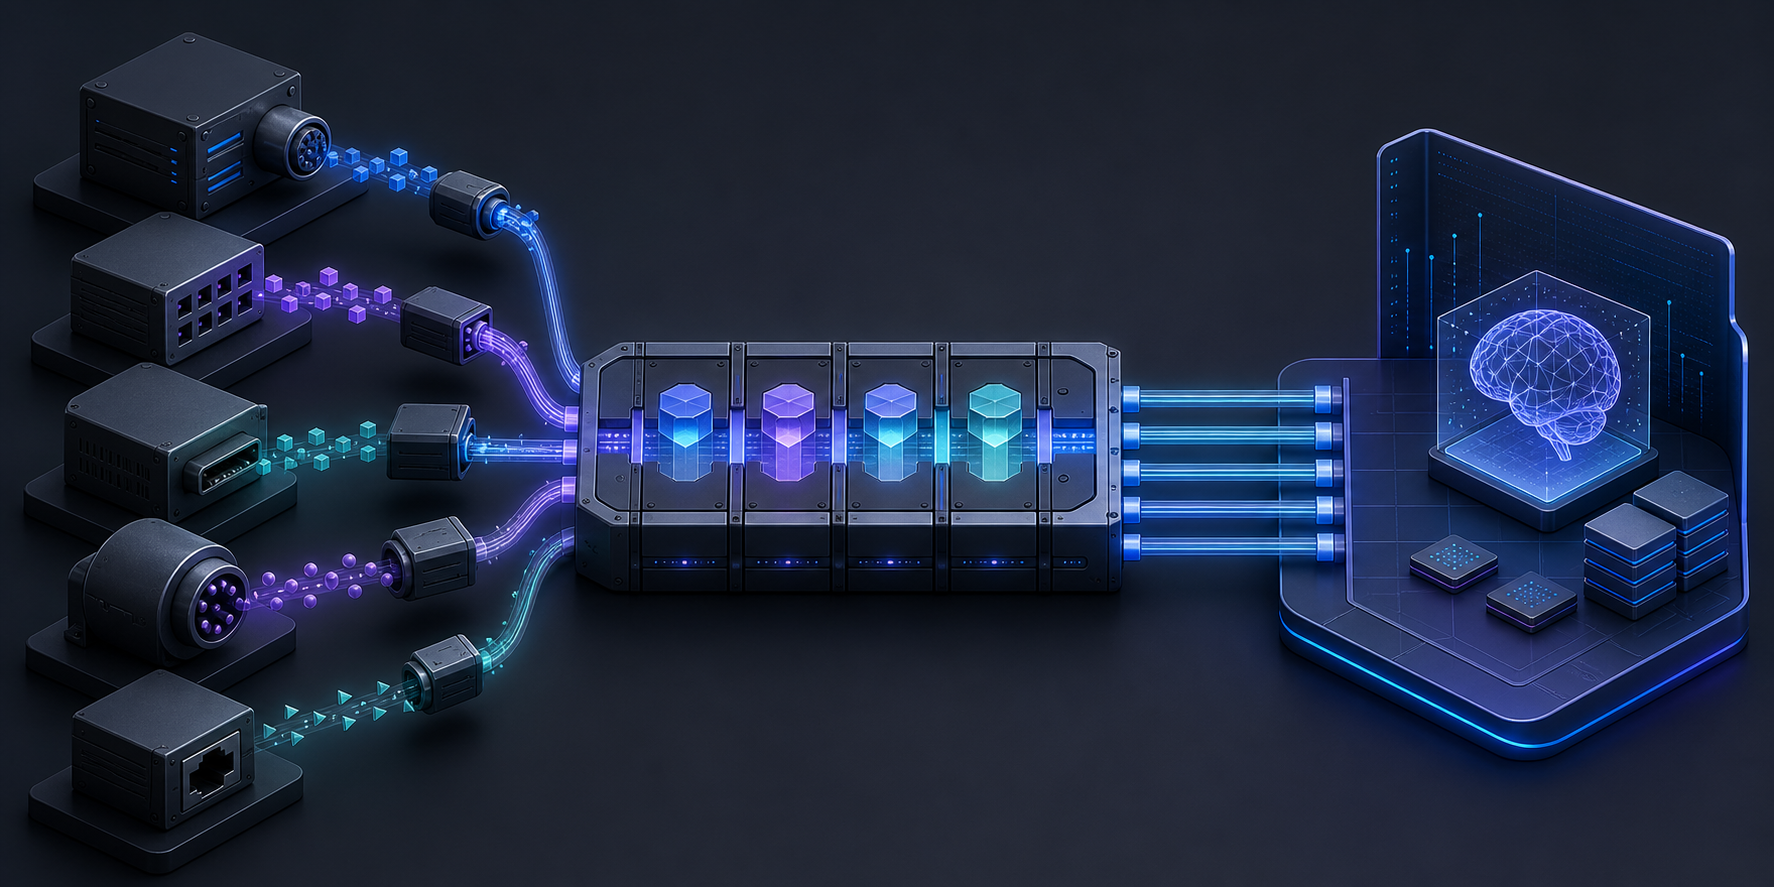
    Different digital systems connect through a standardized bridge to a single AI workspace.

    In general terms, the Model Context Protocol provides a standardized way for an AI-enabled application to interact with external sources and tools. Instead of treating every connection as an entirely separate product integration, an MCP-based approach can give compatible systems a common interface for exposing permitted context or actions.

    For Profound users, the architectural implication may matter more than the phrase “central hub.” A common interface can make it easier to assemble workflows spanning several systems, but it does not automatically make those systems interchangeable. Each connector can still differ in authentication, available functions, data structure, reliability, and administrative controls.

    Key takeaways

    • Profound reports that External MCP Connectors can connect CMS, project-tracking, and team-communication tools with its platform.
    • The central value proposition is workflow consolidation, although the source provides no independent evidence or quantified results.
    • MCP standardizes the connection pattern; it does not guarantee identical capabilities, permissions, or data quality across external tools.
    • Teams should evaluate each connector at the level of actual tasks, accessible data, permitted actions, and operational controls.

    The questions teams should answer before adoption
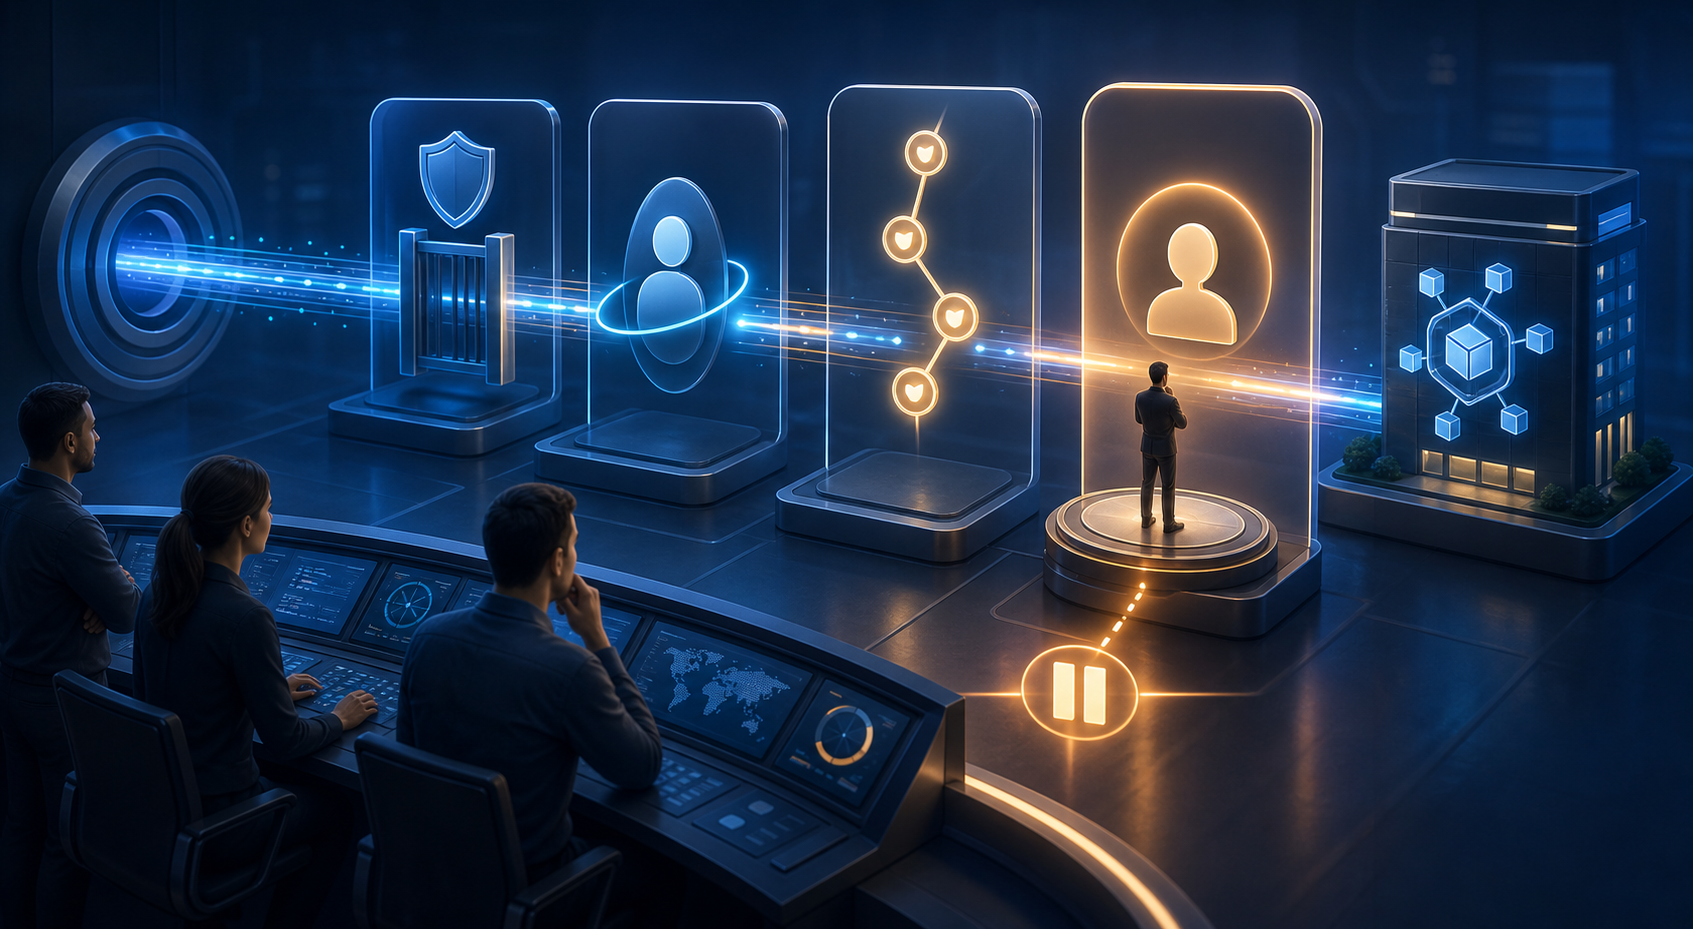
    A digital connector workflow passes through permission, identity, audit, and human approval checkpoints while a team monitors it.

    A useful evaluation starts with the workflow rather than the number of available connections. A team might examine where information currently moves between its CMS, project tracker, and communication system, then identify which transfers are repetitive, slow, or prone to inconsistency. The connector is valuable only if its available operations match those specific handoffs.

    Access boundaries also require scrutiny. Evaluators should determine which data Profound can retrieve, which actions it can initiate, how users authenticate, and whether permissions from the connected service remain enforceable. Logging, error handling, approval requirements, and procedures for revoking access are similarly important wherever a connector can change external records.

    Finally, teams should test the quality of the resulting context. Centralized access is not necessarily coherent access: duplicated records, inconsistent naming, stale project statuses, or ambiguous ownership can still undermine an integrated workflow. A limited pilot built around one repeatable task can reveal whether the connector reduces friction without obscuring accountability.

    From connectivity to dependable workflows

    Profound’s announcement points toward a platform that can sit closer to the systems where teams already plan, communicate, and manage content. Whether that direction produces meaningful efficiency will depend on the depth of individual connectors and the governance surrounding them. Future documentation and hands-on evaluation will be needed to establish which workflows are genuinely supported and how reliably they operate.
    References

  • How AI Recommendations Reshape Referrals and Buyer Intent

    How AI Recommendations Reshape Referrals and Buyer Intent

    AI-driven discovery is creating a two-stage customer journey: an assistant first narrows the choices, then a referred visitor decides whether a website confirms the recommendation. The available reporting suggests that these stages are closely connected, but they should not be measured as one channel.

    A product’s inclusion in an AI answer can change when web search is enabled, while the people who click through may behave differently from conventional visitors. Understanding both effects helps brands distinguish recommendation visibility from referral performance.

    Key takeaways

    • AI recommendation visibility can be highly variable: one reported ChatGPT study found that enabling search changed the products appearing in 80.2% of responses.
    • AI referrals can bring unusually engaged visitors without guaranteeing stronger conversion. Adobe’s reported travel data showed more time on site and lower bounce rates, but a remaining conversion deficit.
    • Category context matters. The same Adobe reporting found that AI-referred retail visitors converted substantially better than non-AI traffic, in contrast with travel.
    • Readable, well-structured content may support discovery, but the cited evidence does not prove that improving AI readability directly causes more recommendations or sales.

    Recommendation visibility depends on how the AI gathers evidence

    Abstract AI workspace comparing a closed evidence network with an expanded web search network that produces different selections.

    An AI assistant does not necessarily produce a stable shortlist from a fixed body of knowledge. A study by Visibility Labs founder and CEO Jeff Oxford, summarized in the second source, ran 1,000 product-recommendation prompts ten times with search enabled and ten times without it, producing 20,000 interactions. Only 19.8% of products suggested without search reappeared when search was active. In other words, the retrieval method altered much more than the wording of the answer; it changed the choice set presented to users.

    The most frequently suggested products were not insulated from that change. Of the products consistently recommended in search-disabled responses, the source reported that only 15.8% appeared after search was enabled. Search-enabled answers were also somewhat narrower, averaging 5.2 products per response compared with 6.2 without search. Across ten runs of each prompt, search produced an average of 19 unique products, versus 21.8 without it.

    This volatility complicates the idea of a single, permanent AI ranking. A brand can be prominent in an assistant’s model-based answer and absent when the assistant consults the web, or vice versa. Visibility therefore needs to be evaluated across repeated prompts and different answer modes rather than inferred from one favorable result.

    The study also found a reported Pearson correlation of 0.4 between how often products appeared in cited sources and how frequently they were recommended. That is useful directional evidence, but the observational design did not establish that source mentions caused inclusion. Citations may reflect broader web prominence, product suitability, accessible information or several factors operating together.

    Referral quality reveals intent after the recommendation

    The first source, reporting Adobe data, examines what happens after an AI user reaches a website. It said AI-driven traffic to U.S. travel sites increased 194% year over year in May 2026 and 2,215% from the beginning of Adobe’s monitoring in October 2024. The research drew on more than 8 million visits to U.S. travel sites and a March survey of more than 5,000 U.S. consumers.

    These visitors displayed stronger engagement than non-AI visitors: Adobe reportedly measured 70% more time per visit, a 41% lower bounce rate and 21% higher engagement. The source interpreted the pattern as consistent with more deliberate, higher-intent browsing. That interpretation is plausible because an assistant can help a traveler compare destinations, hotel features, itineraries and promotions before the click, leaving the destination site to validate details or support a booking.

    Engagement did not translate into an immediate travel conversion advantage. AI-referred visitors converted 28% less often than non-AI visitors, although the source said that gap had narrowed by nearly 70% since October 2024. Travel decisions can involve additional comparison and coordination, so time on site should not be treated as a substitute for completed transactions.

    Retail produced a different outcome in the same Adobe reporting. AI-driven visits to U.S. retail sites rose 138% year over year in May and 1,324% from October 2024. AI-referred retail visitors converted 54% better than non-AI visitors, reversing the earlier pattern described by the source, when their conversion rate had been nearly half as high. Adobe’s retail analysis covered more than 1 trillion visits and over 100 million SKUs.

    The contrast is important: AI referral traffic is not inherently high- or low-converting. Its commercial value depends on the category, the decision cycle and what remains unresolved when the visitor arrives. The recommendation stage may substantially reduce uncertainty for a specifications-led retail purchase while leaving a traveler with dates, availability, policies and other booking details still to settle.

    Readable content links discovery with the landing experience

    The two reports meet at content accessibility. The product study indicates that activating web search can substantially reshape recommendations and that cited-source mentions have a modest association with product visibility. Adobe’s travel analysis, meanwhile, suggests that a meaningful share of website content cannot be processed effectively by AI systems. Together, they point to an operational dependency: useful information must be available to the system before it can help form or substantiate a recommendation.

    Using its AI Content Visibility Checker, Adobe reportedly found that hotel homepages had 63% AI readability and car-rental homepages 59%. Product pages scored higher, at 73% for hotels and 71% for car rentals. Even so, the source said more than one-third of the content on leading travel pages remained unreadable to AI systems.

    Performance also varied by page type and sector. Hotels led in areas including destination guides, activities, search results, customer service and promotions. Car-rental companies performed best on FAQ pages, while cruise companies led in blog and news content. Airlines trailed the other major travel segments across the page types Adobe assessed. In retail, cosmetics and electronics benefited from detailed material such as ingredients, tutorials, specifications and how-to information, whereas grocery and furniture lagged.

    These findings do not justify writing pages solely for machines. They support a more durable principle: important facts should be explicit, consistently named and placed in accessible page content. Detailed descriptions, amenities, specifications, policies and practical guidance can serve an assistant’s evidence gathering while also helping the referred visitor verify the recommendation.

    Measurement must connect exposure, visits and outcomes

    Three linked visual stages show an AI recommendation, a visitor arriving at a website, and a completed outcome.

    A useful measurement model separates three questions. First, how often does the brand or product appear across repeated recommendation prompts, with and without search? Second, which cited pages and on-site facts are associated with those appearances? Third, what do referred visitors do after arrival, including engagement, progression and conversion?

    Each layer prevents a misleading conclusion. A single recommendation screenshot cannot establish durable visibility. A citation does not prove that the cited mention caused a recommendation. Strong engagement does not necessarily mean strong conversion, as the travel results demonstrate. Conversely, a lower volume of AI referrals may still be commercially meaningful when visitors arrive with a well-defined need, as the retail results suggest.

    The next competitive advantage is likely to come from joining these measurements rather than optimizing them independently. Brands that monitor recommendation variability, expose decision-critical information and evaluate post-click behavior by category will be better positioned to learn whether AI is merely mentioning them or delivering customers who can act.

    References

  • How Meta AI Mode Changes Search and Discovery on Facebook

    How Meta AI Mode Changes Search and Discovery on Facebook

    Meta AI Mode changes Facebook Search from a results-finding tool into an answer-generating experience. According to CrushPress.AI’s report, Meta AI can respond to broad or specific queries using public material from Groups, Reels and other parts of Meta’s ecosystem.

    The immediate benefit is a faster route to community knowledge. The larger consequence is that an AI system now mediates which experiences, recommendations and brand discussions become visible, while important details about selection and attribution remain undisclosed.

    Facebook Search is moving from retrieval to synthesis

    The supplied report describes a departure from the familiar list of search results. Instead of requiring people to open and compare multiple items, AI Mode can assemble a direct response from relevant public content.

    This distinction matters. A conventional search interface leaves much of the evaluation to the user: results are displayed, sources can be inspected and conclusions are formed afterward. An answer interface performs some of that work before the user sees the output. Source selection, interpretation and presentation therefore become part of the search experience rather than steps taken entirely by the searcher.

    CrushPress.AI also reported that Meta AI can surface relevant public content as people navigate Facebook, extending discovery beyond a single results page. That suggests a closer connection between intentional search and recommendations encountered elsewhere in the product, although the report does not provide performance data showing how often this occurs.

    The feature shares the AI Mode name used by Google, as the report notes. The common label should not be treated as evidence that the two products use the same sources, ranking systems or answer-generation methods.

    Community experience is the central search asset

    A diverse group shares posts and videos that flow through a central AI lens.

    Facebook’s distinctive contribution is not simply an AI-written summary. It is the underlying pool of public conversations and creator material. The report positions Groups and Reels as sources of experience-based information about products, places, hobbies and everyday questions.

    This can make Facebook Search particularly relevant when a query benefits from practical opinions rather than a single canonical answer. A discussion may reveal how different people approached a problem, while a Reel may demonstrate an activity or product in context. AI Mode can potentially connect those formats in one response instead of making the user search each surface separately.

    The same strength creates an editorial challenge. Community posts can contain conflicting perspectives, incomplete context or highly individual experiences. An AI-generated answer necessarily decides which material to foreground and how to reconcile it. The usefulness of the response therefore depends not only on the available conversations but also on selection and synthesis decisions that the supplied report says Meta has not explained.

    Key takeaways

    • Meta AI Mode provides generated answers instead of relying solely on a conventional list of Facebook search results.
    • The reported source material includes public content from Groups, Reels and other surfaces within Meta’s ecosystem.
    • The feature could reshape discovery for recommendations, local information, hobbies, products and brand conversations.
    • Meta has not disclosed enough detail to establish how sources are selected, ranked or credited.
    • Brands and publishers should treat AI Mode as an emerging discovery layer, not as a channel with proven optimization rules.

    The visibility question has three unresolved layers

    A user observes social content passing through three translucent filtering layers before reaching an AI answer.

    The first unknown is eligibility. The report repeatedly identifies public content as the foundation for answers, but it does not define the complete eligible corpus or explain whether every type of public post is treated similarly.

    The second is selection. CrushPress.AI reported that Meta has not explained how particular posts, Groups or Reels earn inclusion. This leaves brands, creators and community administrators without a documented way to distinguish content that is merely available from content likely to influence an answer.

    The third is attribution. The report says it is unclear whether brands, creators or publishers will be informed when their content is used. That gap affects more than recognition. Without consistent source visibility or reporting, content owners may struggle to connect participation in Facebook conversations with AI-mediated exposure.

    CrushPress.AI further reported that the experience uses Meta AI and Muse Spark, while noting that Meta has not disclosed how Muse Spark affects ranking, source selection or answer generation. Until those roles are clarified, claims about a reliable Facebook AI optimization formula would be speculative.

    A practical response without invented ranking tactics

    Organizations can begin by separating content quality from presumed algorithmic influence. Public posts that clearly identify the subject, explain the circumstances and provide useful context are easier for people to understand regardless of whether AI Mode selects them. Specificity is a sound communication practice, but the supplied reporting does not establish it as a ranking factor.

    Brands can also examine the public discussions that already surround their products, locations or services. The goal is to understand the questions and language used by communities, not to flood those spaces with promotional material. Because AI Mode draws on public social interactions, genuine community participation may become more consequential even when a brand does not control the eventual summary.

    Where the feature is available, teams can document representative queries, the answers displayed, the content formats surfaced and any visible attribution. Repeating the same checks over time can reveal changes in presentation or source patterns. Such observations remain local tests, however, and should not be generalized into universal ranking rules without broader evidence.

    The decisive next development will be greater clarity about selection, attribution and measurement. Until Meta supplies it, the most defensible approach is to treat AI Mode as a new interface between public conversation and discovery: important enough to monitor, but too opaque for confident optimization promises.

    References

  • Claude Code as an Agency Knowledge and Action Layer

    Claude Code as an Agency Knowledge and Action Layer

    Claude Code can give an agency more than another place to store information. When local memory, searchable history, connected work systems and focused automations are combined, agency knowledge can move directly from retrieval to a reviewed deliverable or next action.

    The supplied case study describes this as a second brain, but its results should be read as one practitioner’s experience rather than a general benchmark. The author reported that, after rebuilding the workflow over roughly six months, a Monday catch-up that previously involved several applications could be completed in about a minute.

    Key takeaways

    • The useful unit is not a saved note but a decision-ready packet of context that can support a draft or action.
    • Durable memory should remain small and curated, while detailed history can live in a separate search layer.
    • Focused skills turn retrieved knowledge into outputs such as briefs, proposals, meeting summaries and draft replies.
    • Monitoring becomes valuable only after memory, retrieval and task execution work reliably.
    • Read access, drafting authority and permission to act should be treated as separate stages of deployment.

    Treat the system as a decision pipeline, not a notebook

    Agency information moves through a staged pipeline while a strategist reviews a deliverable before release.

    Traditional second-brain systems are good at capture, but capture alone does not resolve the agency’s underlying workflow problem. Information may be preserved in meeting notes, email, messaging tools, a CRM and project files, yet a team member must still remember where it lives, find it, reconstruct the surrounding context and convert it into useful work.

    The source identifies three related failure modes: passive storage that depends on manual recall, context switching between applications, and the absence of an action layer. Claude Code changes that pattern in the reported setup through access to local project files, structured Markdown memory, MCP connections to services such as Gmail, Slack, Google Drive, HubSpot and Scoro, and the ability to draft or analyze material inside a working context.

    Viewed as an operating model, the source’s four layers form a pipeline in which each component answers a different question:

    LayerRole in the workflowQuestion it answers
    MemoryLoads a small set of curated Markdown files covering stable business context, client preferences and working conventions.What should consistently shape the response?
    SearchRetrieves detail from indexed daily logs without placing the entire history in permanent memory.What happened previously?
    SkillsApplies focused procedures for tasks such as drafting a brief, preparing a proposal or summarizing a meeting.What should be produced from the context?
    HeartbeatChecks connected systems on a schedule and surfaces situations that may require attention.What needs intervention now?

    The separation is important. A compact memory layer provides durable guidance, search restores case-specific detail, and a skill transforms both into an output. The heartbeat sits above that foundation: in the reported implementation, it checked email, calendars, Slack and pipeline activity hourly, then delivered a summarized Slack notification and a draft when intervention appeared necessary.

    Design around moments when context must become a deliverable

    The strongest agency use cases begin with a recurring moment of friction, not with a broad goal to automate knowledge work. The source highlights three moments in which scattered context normally has to be assembled before useful work can begin.

    Preparing a client update

    A request for an update may depend on call transcripts, internal notes and recent message threads. The reported system gathers those materials before drafting, reducing the preparation burden and the likelihood that an important discussion is missed. The practical value comes from combining sources around the client question rather than merely returning a list of search results.

    Interpreting performance data

    Analytics and rank-tracking data become more useful when reviewed alongside the decisions, expectations and previous observations that give them meaning. According to the source, the second-brain workflow compiles the needed context for analysis. This illustrates a broader design principle: retrieval should be scoped to the decision being made, so the system supplies relevant history without flooding the task with every stored note.

    Moving from discovery to scope

    Scoping a new engagement often requires translating discovery conversations into requirements and deliverables. The source reports using accumulated discovery context to formulate a scope, reducing repeated exchanges. Here, the skill is not simply summarization. It is a structured transformation from conversational evidence into a draft that a responsible team member can assess.

    These examples share a closed loop: collect the relevant evidence, apply stable business context, produce a defined artifact and place that artifact in front of a human reviewer. A narrow loop is easier to test and improve than an all-purpose agency agent because the expected inputs and acceptable output are clearer.

    Separate knowledge quality from permission level

    Two agency team members review an output within a layered system of knowledge access, drafting and controlled actions.

    An assistant can fail because it lacks the right context or because it has too much authority. Those are different risks and should be managed separately. Better retrieval may improve a draft, but it does not justify allowing the system to send that draft, alter a record or commit a decision without review.

    The source recommends beginning with read-only integrations. In that mode, the system can inspect connected services and prepare material without sending messages or committing changes. Write access is introduced selectively only after its behavior has been evaluated. This creates a practical progression from visibility, to recommendation, to drafting and finally to narrowly bounded execution where appropriate.

    Memory needs a similar constraint. The reported workflow does not treat every daily detail as permanent context. Daily logs can be searched, while only information likely to affect future behavior, such as pricing considerations, client preferences or established working methods, is distilled into long-term memory. This helps prevent outdated or incidental facts from silently steering later work.

    Human review remains the final control for consequential communication. The source’s rule is effectively to trust the drafting advantage while verifying the action. For agencies, that preserves professional judgment over tone, commercial commitments and client-facing claims while still removing much of the mechanical work that precedes a decision.

    Roll out by proving one closed knowledge loop

    A useful implementation sequence follows the flow of information rather than the number of available integrations:

    1. Map the systems that contain decision-relevant material, including email, calendars, messaging, CRM and task management.
    2. Add a transcript source where calls contain context that is not captured elsewhere.
    3. Create a small foundation of durable memory, beginning with business identity, working preferences and carefully distilled daily knowledge.
    4. Keep detailed history searchable so it can be retrieved when relevant without expanding permanent memory indefinitely.
    5. Build one focused skill around a repetitive, reviewable output such as a meeting summary, brief, proposal or draft reply.
    6. Add monitoring only after retrieval and output quality are dependable, beginning with notifications and introducing write permissions cautiously.

    The source presents the heartbeat as the final layer for good reason: proactive monitoring magnifies whatever sits beneath it. If retrieval is noisy or memory is poorly curated, more frequent alerts create more distraction. Once a single loop consistently produces relevant, reviewable work, the same pattern can be extended to another agency process without turning the system into an unrestricted general agent.

    The next stage for agency knowledge workflows is therefore likely to be controlled expansion rather than maximum autonomy: more well-defined loops, better-curated context and permissions that grow only as evidence of reliable performance accumulates.

    References

  • How AI Platforms Are Reshaping Commerce Advertising

    How AI Platforms Are Reshaping Commerce Advertising

    AI-powered commerce is not emerging as a single ad format. Across the supplied reports, four related shifts are taking shape: structured product data is becoming ad creative, retailer audiences are moving into broader media channels, conversational assistants are becoming shopping environments, and transaction data is being used to connect advertising with business outcomes.

    For advertisers, the useful distinction is not simply between search, retail media and conversational AI. It is between platforms that help people discover an offering, platforms that support a buying decision, and platforms that can also complete or measure the resulting action.

    The ad is moving into the transaction interface

    Amazon’s reported Alexa for Shopping experience represents the most complete version of this transition. According to the supplied report, Amazon combined Rufus with Alexa+ to support product research, comparisons, price tracking, cart building and automated purchases. Sponsored products, Sponsored Brands and conversational ad formats can appear within that journey, placing advertising in the same environment where a customer expresses preferences and moves toward a purchase.

    OpenAI’s reported approach begins at a different layer. Its Ads Manager beta reportedly lets retail advertisers upload product feeds and generate ads from individual catalog items. Rather than building every product campaign manually, participating retailers can use structured catalog data to match products with purchase-oriented conversations in ChatGPT. The supplied report characterizes early beta performance as strong, but it does not provide a methodology or numerical results.

    Google’s richer Local Services Ads for Home Listings show that the same reduction in friction is not limited to conversational assistants. The supplied real estate report says these ads can display property photos, prices and home features using data provided through a collaboration with HouseCanary. Prospective buyers can then call, message or book an appointment with an agent from the ad experience. This is a lead-generation model rather than an automated purchase flow, but it similarly brings evaluation and action closer to the initial discovery surface.

    The Walmart Connect and Display & Video 360 integration addresses another part of the system: extending retailer audiences and sales measurement into media that the retailer does not own. The supplied report says advertisers can activate Walmart Connect audiences for YouTube campaigns through DV360 and relate ad exposure to purchases at Walmart, including online and in-store transactions. Taken together, the reports describe commerce advertising expanding both inward, deeper into shopping interfaces, and outward, across off-site media.

    Four models create different kinds of advertiser value

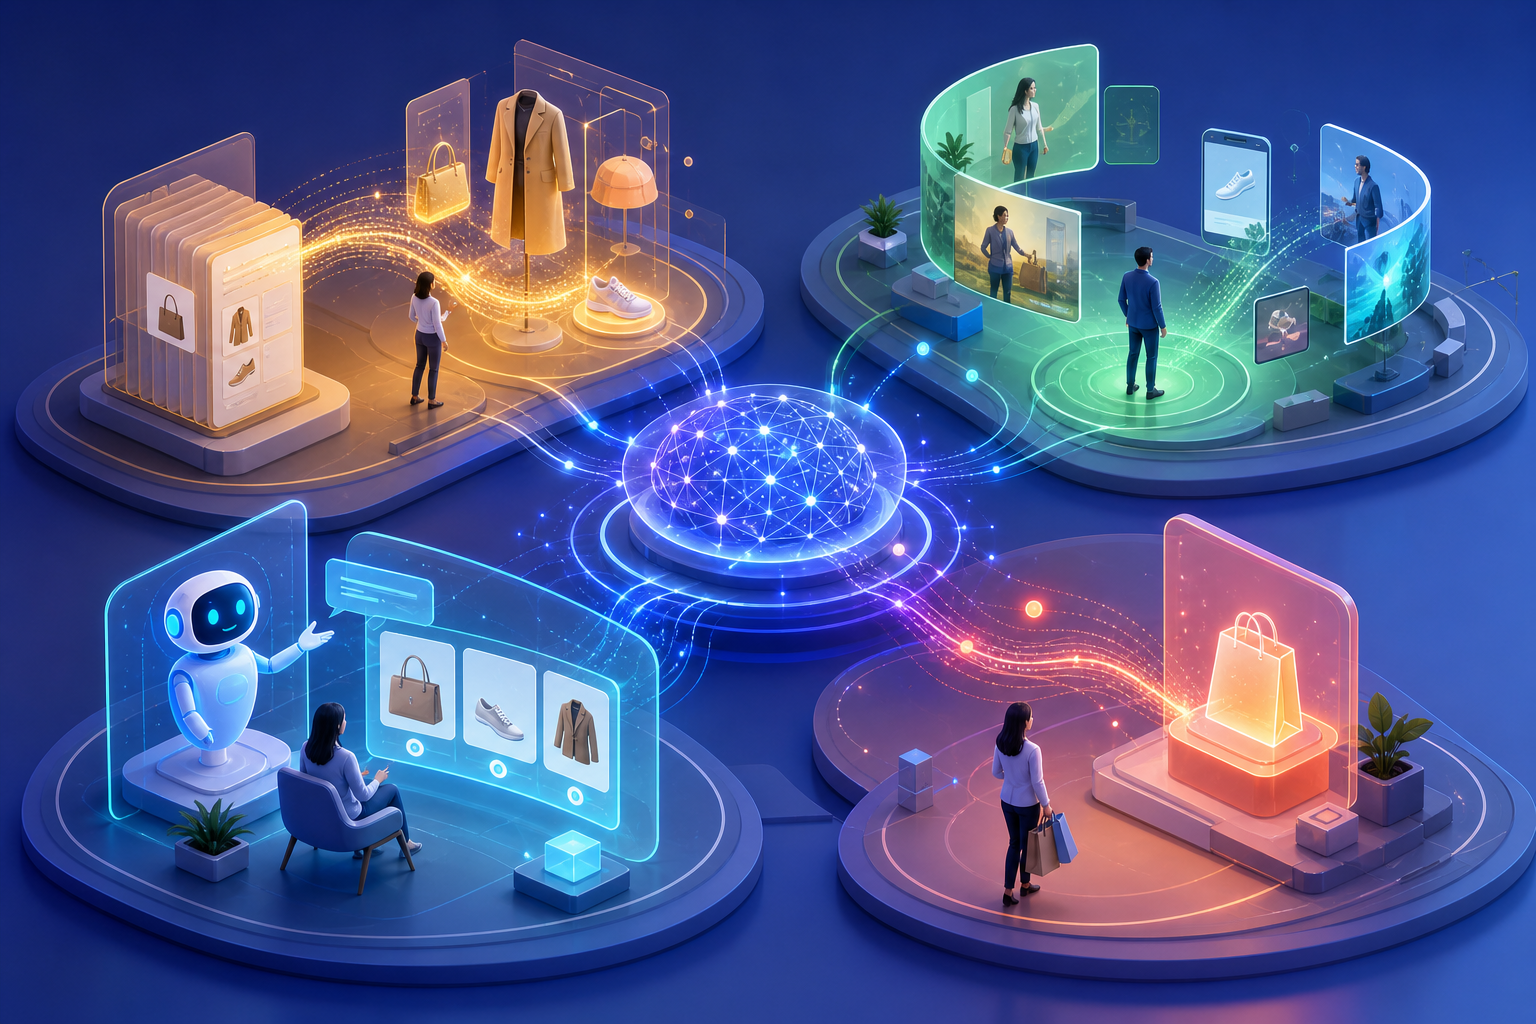
    Four connected miniature scenes depict product data, retailer audiences, conversational shopping, and purchase measurement around a central network.
    Reported platform moveWhere intent or action appearsPrimary advertiser valueImportant scope detail
    Walmart Connect audiences in Google DV360YouTube media followed by Walmart purchasesRetailer audience activation and sales attributionThe supplied report describes YouTube as the initial focus
    Google Home Listings in Local Services AdsProperty evaluation and agent contact within SearchRicher information for high-intent lead generationThe enhanced experience is reported as available nationwide in the U.S., with existing LSA advertisers automatically included
    OpenAI product-feed adsPurchase-focused conversations in ChatGPTCatalog-scale ad generation and product relevanceThe capability is described as an Ads Manager beta
    Amazon Alexa for ShoppingConversational research, comparison, cart building and purchaseAdvertising across a more complete shopping journeyThe report says existing sponsored ad campaigns are automatically eligible for the experience

    These are complementary models, not interchangeable products. Google Home Listings is oriented toward connecting a buyer with a service provider. OpenAI’s beta emphasizes scalable product-ad creation. Walmart and Google combine off-site reach with retailer transaction data. Amazon is placing discovery, advertising and commerce functions inside a single assistant. Comparing them by their position in the customer journey is more informative than grouping all four under a broad AI advertising label.

    The competitive stack is data, automation and proof

    Intent data is becoming more explicit

    Traditional targeting commonly relies on observable proxies such as searches, page visits or prior transactions. The Amazon report argues that conversational shopping can add direct expressions of needs, preferences and purchase goals. Walmart’s reported advantage is different but related: its shopper audiences are based on retail behavior and can be activated in YouTube campaigns. One source supplies language-rich intent, while the other supplies transaction-informed audience data.

    Those signals serve different purposes. A conversation can clarify what a shopper wants at a particular moment, while retailer data can help identify or evaluate audiences using past shopping behavior. Platforms capable of combining contextual intent with dependable commerce data may offer more precise decision inputs, although the supplied reports do not establish how the platforms compare on accuracy, privacy safeguards or incremental performance.

    Automation is changing the unit of campaign work

    OpenAI’s feed-based model shifts campaign preparation from constructing an ad for every item toward maintaining a catalog that can supply product-level ads. Amazon reportedly makes existing sponsored campaigns available in Alexa for Shopping and offers AI-driven campaign optimization tools. Google’s real estate update automatically brings existing LSA advertisers into the enriched listing experience.

    These examples automate different tasks. Product-feed ingestion automates ad assembly at catalog scale; campaign eligibility extends existing advertising into another surface; and optimization systems help determine how campaigns operate. Advertisers should therefore evaluate what a platform actually automates rather than treating every automated feature as equivalent. Less manual assembly does not remove the need for accurate data, suitable creative, inventory governance or campaign oversight.

    Measurement separates exposure from commercial evidence

    The Walmart-DV360 and Amazon reports place closed-loop measurement at the center of their advertiser propositions. Walmart’s integration reportedly links YouTube exposure with Walmart transactions. Amazon’s reported offering combines advertising, first-party signals and measurement inside an environment that can extend through purchase.

    The other two models require different interpretations. Google’s enriched real estate ads produce direct contacts with agents, but the supplied report does not describe transaction-level attribution for completed home sales. The OpenAI report says feed-based ads have performed well during the beta without disclosing the measurement framework. Consequently, a lead, a reported ad-performance result and an attributed retail sale should not be treated as the same outcome.

    Key takeaways

    • Commerce ads are moving closer to evaluation and action, whether that action is contacting an agent, adding a product to a cart or completing a purchase.
    • Structured feeds are becoming operating infrastructure for advertising, not merely back-office catalog records.
    • Conversational platforms can capture explicitly stated preferences, while retail platforms contribute audiences and transaction signals derived from shopping behavior.
    • Closed-loop attribution is a meaningful differentiator, but it is not described consistently across all four reports.
    • Platform maturity varies: the supplied material describes a beta at OpenAI, an initial YouTube focus for Walmart’s DV360 integration, a nationwide Google LSA experience and a broader shopping-assistant model at Amazon.

    Advertisers need a surface-by-surface operating plan

    Two marketing professionals view connected mobile, retail, media, search, and checkout environments coordinated by shared data flows.

    Treat structured data as a media asset

    When ads are assembled from feeds or enriched with listing information, data quality directly affects what a prospective customer sees. Retailers need reliable product names, availability and other relevant catalog fields; real estate advertisers depend on accurate property information and visuals. This is a general operating implication of feed-driven advertising, not a performance claim about any one platform.

    Define the outcome before comparing platforms

    A useful measurement plan should distinguish among media engagement, a conversation, an agent inquiry, a cart action and an attributed sale. The reports show why a single efficiency metric cannot explain every model. Each platform should be evaluated against the business action it can observe and the evidence it provides for connecting advertising to that action.

    Separate convenience from control

    Automatic enrollment and feed-generated ads can reduce setup work, but advertisers still need to understand where campaigns may appear, how products are selected and which reporting is available. Existing campaign portability, audience portability and measurement access are separate capabilities. A platform that offers one does not necessarily offer all three.

    Evaluate the customer experience alongside performance

    Advertising inside product research or a conversational exchange can shorten the path to action, but it also places greater weight on relevance and clear commercial context. As assistants take on more shopping tasks, advertisers and platforms will need to balance monetization with an experience that remains useful enough for customers to continue relying on it.

    The next stage of commerce advertising will likely be shaped less by the novelty of an AI interface than by how well each system connects dependable data, useful recommendations, controlled activation and credible measurement. Advertisers prepared to assess those components separately will be better positioned as these reported integrations expand and mature.

    References

  • AI Platforms Face Publisher Accountability on Two Fronts

    AI Platforms Face Publisher Accountability on Two Fronts

    Publisher accountability disputes are converging on two different stages of the AI supply chain: how platforms acquire protected material and what they say after processing it. One dispute challenges the collection and distribution of publisher content through Common Crawl; another treats false statements in Google’s AI Overviews as content for which Google may be directly responsible.

    Together, the reports suggest that platforms may find it harder to rely on a single intermediary defense. Publishers are pressing for control before their work enters AI systems and for meaningful remedies when those systems generate unsupported claims.

    Key takeaways

    • AI accountability is developing at both the input layer, where publisher content is collected, and the output layer, where generated answers can affect publishers.
    • Digital Content Next argues that copyright requires permission rather than a publisher opt-out, while Common Crawl disputes allegations that it bypasses paywalls or misleads publishers.
    • The reported Munich ruling treated disputed AI Overview statements as Google’s own content because they presented standalone claims rather than merely directing users to sources.
    • Links and removal procedures do not resolve the same problem: attribution cannot correct an unsupported generated accusation, while output accuracy does not answer whether source material was authorized.

    One accountability debate begins before generation

    Unmarked documents move toward an AI intake portal through a transparent gate that separates controlled pathways and preserves glowing provenance links.

    The Common Crawl dispute concerns the material available to AI developers before a model produces any answer. According to the source report, Digital Content Next sent the Common Crawl Foundation a cease-and-desist letter demanding that it stop collecting and distributing protected content belonging to its members. The organization also sought removal of member content already present in datasets, including paywalled and subscriber-only articles.

    The report identifies Digital Content Next as representing publishers including the Associated Press, The New York Times, NBC Universal, Bloomberg, NPR and Fox. Its position is that copyright is not an opt-out regime and that making protected material available for AI development without authorization or compensation constitutes infringement. These remain claims advanced by the publisher group, not findings reported as having been resolved by a court.

    Common Crawl presents a different account. Executive Director Rich Skrenta denied bypassing paywalls or misleading publishers and said the foundation responds to requests to remove previously collected material within the constraints of its dataset architecture. The source also notes that Common Crawl maintains a registry of sites that have opted out, while Digital Content Next questions whether the organization’s stated compliance has been adequate.

    The practical importance extends beyond one crawler. The report describes Common Crawl, established in 2008, as a repository containing billions of webpages and as an important source of AI training material. It also relays two indicators of that role: The New York Times’ 2023 lawsuit against OpenAI reportedly said Common Crawl supplied 60% of GPT-3’s training data, and a 2024 Mozilla Foundation paper reportedly concluded that generative AI would scarcely exist in its current form without the repository. Those figures and characterizations are source-reported rather than independently verified here.

    A second debate begins when an AI answer causes harm

    Readers face information tiles projected by an AI terminal while one warped tile casts a fractured shadow on a publisher's desk.

    The reported German ruling addresses a later stage: responsibility for claims generated after information has been collected and processed. The Regional Court of Munich reportedly considered false AI Overview statements that connected two Munich publishers with scams and questionable practices even though the linked pages did not support those allegations.

    According to the account, the misinformation resulted from the system conflating information about other entities with information about the publishers. That detail matters because the disputed allegations apparently could not be traced to the cited pages. If Google were treated only as a conduit, the affected publishers would have no obvious third-party author to pursue for the newly assembled claim.

    The court reportedly rejected that characterization. It viewed AI Overviews as processing material and presenting it in a distinct form, not simply listing third-party pages. Because the accusations appeared as complete answers and were created through a feature and algorithms controlled by Google, the court treated them as Google’s own content. Traditional protections for search engines acting as indirect intermediaries therefore did not apply in the same way.

    The presence of links did not shift the burden back to users. The ruling account says the court rejected the argument that readers could verify the claims by opening the cited pages, reasoning that the Overview presented assertions that stood on their own. The resulting injunction required Google to refrain from repeating the disputed allegations. The court also reportedly considered comparison against primary sources technically possible, at least in analogous circumstances.

    Permission, provenance and accuracy require separate controls

    The two disputes are related, but they should not be collapsed into a single copyright or misinformation issue. The Common Crawl conflict asks whether material may be copied, retained and redistributed for AI development. The Munich case asks who owns the consequences when a platform transforms information into a new, unsupported statement. A platform could improve its answer verification without resolving a publisher’s rights objection, just as it could license every source and still generate a false claim.

    Provenance also has different functions at each stage. During collection, it can identify where material came from, what access conditions applied and whether a removal request covers stored copies. At the answer stage, citations can help users inspect supporting material, but they do not establish that the generated wording is supported. The Munich report illustrates the gap: the pages were linked, yet the allegations attributed to them were reportedly absent.

    This distinction changes what meaningful platform accountability looks like. Input governance concerns authorization, access controls, opt-out or consent signals, retention and downstream distribution. Output governance concerns entity matching, faithful synthesis, verification against cited material, correction and prevention of repeated harmful claims. Treating either set of controls as a substitute for the other leaves publishers exposed at a different point in the system.

    What publishers can learn from the two disputes

    For publishers, evidence should be organized around the stage at which the alleged failure occurred. A collection dispute depends on records such as ownership, access conditions, crawler instructions, removal correspondence and the continued presence or distribution of material. A generated-answer dispute instead depends on preserving the exact output, its citations, the underlying pages and the differences between what those pages say and what the platform asserted.

    The reported cases also make platform promises worth examining at an operational level. A stated opt-out policy is not the same as confirmed removal from existing datasets. A cited answer is not necessarily a supported answer. A correction mechanism is not necessarily protection against repetition. Publishers evaluating an AI platform’s accountability can therefore ask whether its controls cover historical data as well as future collection, and whether answer citations are checked for actual support rather than merely attached.

    Legal conclusions will depend on jurisdiction and the facts of each dispute, so the German ruling should not be treated as a universal rule and Digital Content Next’s allegations should not be treated as adjudicated findings. Their combined significance is narrower but still substantial: AI systems are prompting separate challenges to assumptions that web access implies permission and that automated synthesis remains neutral intermediation.

    If consent requirements become stronger, the Common Crawl report suggests that licensed sources could gain importance relative to broadly collected web content. If courts continue to distinguish generated answers from conventional search results, platforms may also need more rigorous source validation and remedies at publication time. The durable accountability model will have to govern both directions of the exchange: what AI platforms take from publishers and what they publish about them.

    References

  • Google AI Search Ads: Access, Control and Measurement

    Google AI Search Ads: Access, Control and Measurement

    Google’s AI-enhanced search experiences are changing more than ad placement. They are separating campaign management into three distinct questions: how advertisers gain access to AI Search inventory, how they guide automated decisions, and how they measure results when reporting remains incomplete.

    The supplied CrushPress.AI report, based on a discussion involving Google Ads Liaison Ginny Marvin and the PPC Chat community, offers useful answers across those questions. Viewed together, its details point to a system in which participation remains relatively open, but effective optimization increasingly depends on strong data and carefully defined instructions.

    Key takeaways

    • AI Max is not reported to be a prerequisite for ads to appear in AI Overviews or AI Mode.
    • Broad match can provide a route into AI Search inventory, while AI Max can extend matching beyond the advertiser’s explicit keyword set.
    • AI Search ads do not yet have a distinct reporting breakdown, limiting advertisers’ ability to isolate their contribution.
    • Google’s direction combines automated matching with advertiser guidance, first-party data and measurement designed for longer conversion cycles.

    AI Search eligibility is broader than AI Max

    One of the most consequential distinctions in the report is between eligibility and expansion. According to CrushPress.AI’s account of Marvin’s comments, advertisers do not need to enable AI Max merely to participate in Google’s AI-driven search experiences. Search campaigns using broad match keywords can still be eligible for AI Overviews and AI Mode.

    AI Max instead appears to widen the matching opportunity. The report says it can apply broad-match behavior to phrase and exact match keywords while also enabling keywordless matching. That makes AI Max less of an admission ticket and more of an additional discovery mechanism.

    This distinction should shape campaign decisions. An advertiser can evaluate AI Search exposure separately from the decision to grant Google more latitude in matching queries. The relevant question is therefore not simply whether to adopt AI Max, but whether its broader reach fits the campaign’s economics, message constraints and tolerance for automation.

    Reporting has not caught up with the new inventory

    An analyst examines fragmented advertising signals as some data paths vanish behind translucent blank reporting panels.

    Access to AI Search inventory does not currently come with equivalent visibility. The source reports that ads appearing in AI Overviews and AI Mode are recorded like other top-of-page ads, without a separate reporting breakdown. It also says Google was still determining what dedicated reporting should eventually look like.

    That creates an important analytical limitation. Advertisers may participate in AI Search without being able to isolate its traffic, conversion performance or incremental value from standard search placements. A campaign-level improvement cannot automatically be attributed to AI inventory, while a weak result does not reveal whether the problem arose from an AI placement, another top-of-page impression or a broader campaign setting.

    Until reporting becomes more granular, AI Search should be treated as part of the campaign’s combined delivery environment. Conclusions about its standalone effectiveness would go beyond the evidence available in the reported interface.

    AI Brief and first-party data serve different roles

    The report describes AI Brief as a forthcoming control layer for AI Max. Advertisers are expected to be able to supply guidance covering matters such as target audiences, preferred message themes, priority search intents and prohibitions including instructions not to mention prices. CrushPress.AI says the rollout was planned to begin with English-language Search campaigns before extending to Performance Max and Shopping campaigns.

    Those instructions and an advertiser’s data are complementary rather than interchangeable. AI Brief can communicate strategic boundaries: whom a campaign should address, which ideas it should emphasize and what it should avoid. First-party data provides signals about actual customer and conversion outcomes.

    CrushPress.AI reports that Google emphasized data quality through a concept called Data Strength and pointed to Enhanced Conversions and Google Tag Gateway as important tools. The broader implication is that automation does not eliminate foundational measurement work. If the underlying signals are incomplete or unreliable, more sophisticated matching and creative guidance cannot supply the missing business evidence.

    Measurement is moving toward longer customer journeys

    A shopper follows a winding path across several digital touchpoints while interaction signals converge into a measurement lens and a secure data vault supports the journey.

    Qualified Future Conversions, or QFC, represents another part of Google’s reported direction. The source describes it as a metric that estimates potential conversions occurring within 180 days after an ad interaction. It was reportedly being tested with selected advertisers and was presented as especially relevant to B2B and lead-generation businesses with lengthy sales cycles.

    QFC addresses a different measurement problem from the missing AI Search breakdown. Dedicated placement reporting would help advertisers understand where an interaction occurred; a future-conversion estimate is intended to help evaluate what that interaction may eventually produce. Neither capability substitutes for the other.

    The report also identifies new AI Search ad formats, QFC and YouTube Creator Partnerships as three areas Marvin highlighted after Google Marketing Live. Together, those priorities suggest attention to discovery, delayed outcomes and creator-led reach. For search advertisers, the immediate challenge is to prepare reliable inputs and explicit campaign guidance while avoiding stronger claims about AI-specific performance than the available reporting can support.

    What advertisers should prepare next

    The most durable preparation is not adoption of every automation feature. It is a campaign structure that can accommodate wider matching without losing strategic intent, supported by dependable conversion signals and documented messaging boundaries. As AI-specific controls and reporting develop, advertisers with those foundations will be better positioned to test new inventory and interpret the results responsibly.

    References

  • Exciting Support for Claude Fable Now in Profound

    Exciting Support for Claude Fable Now in Profound

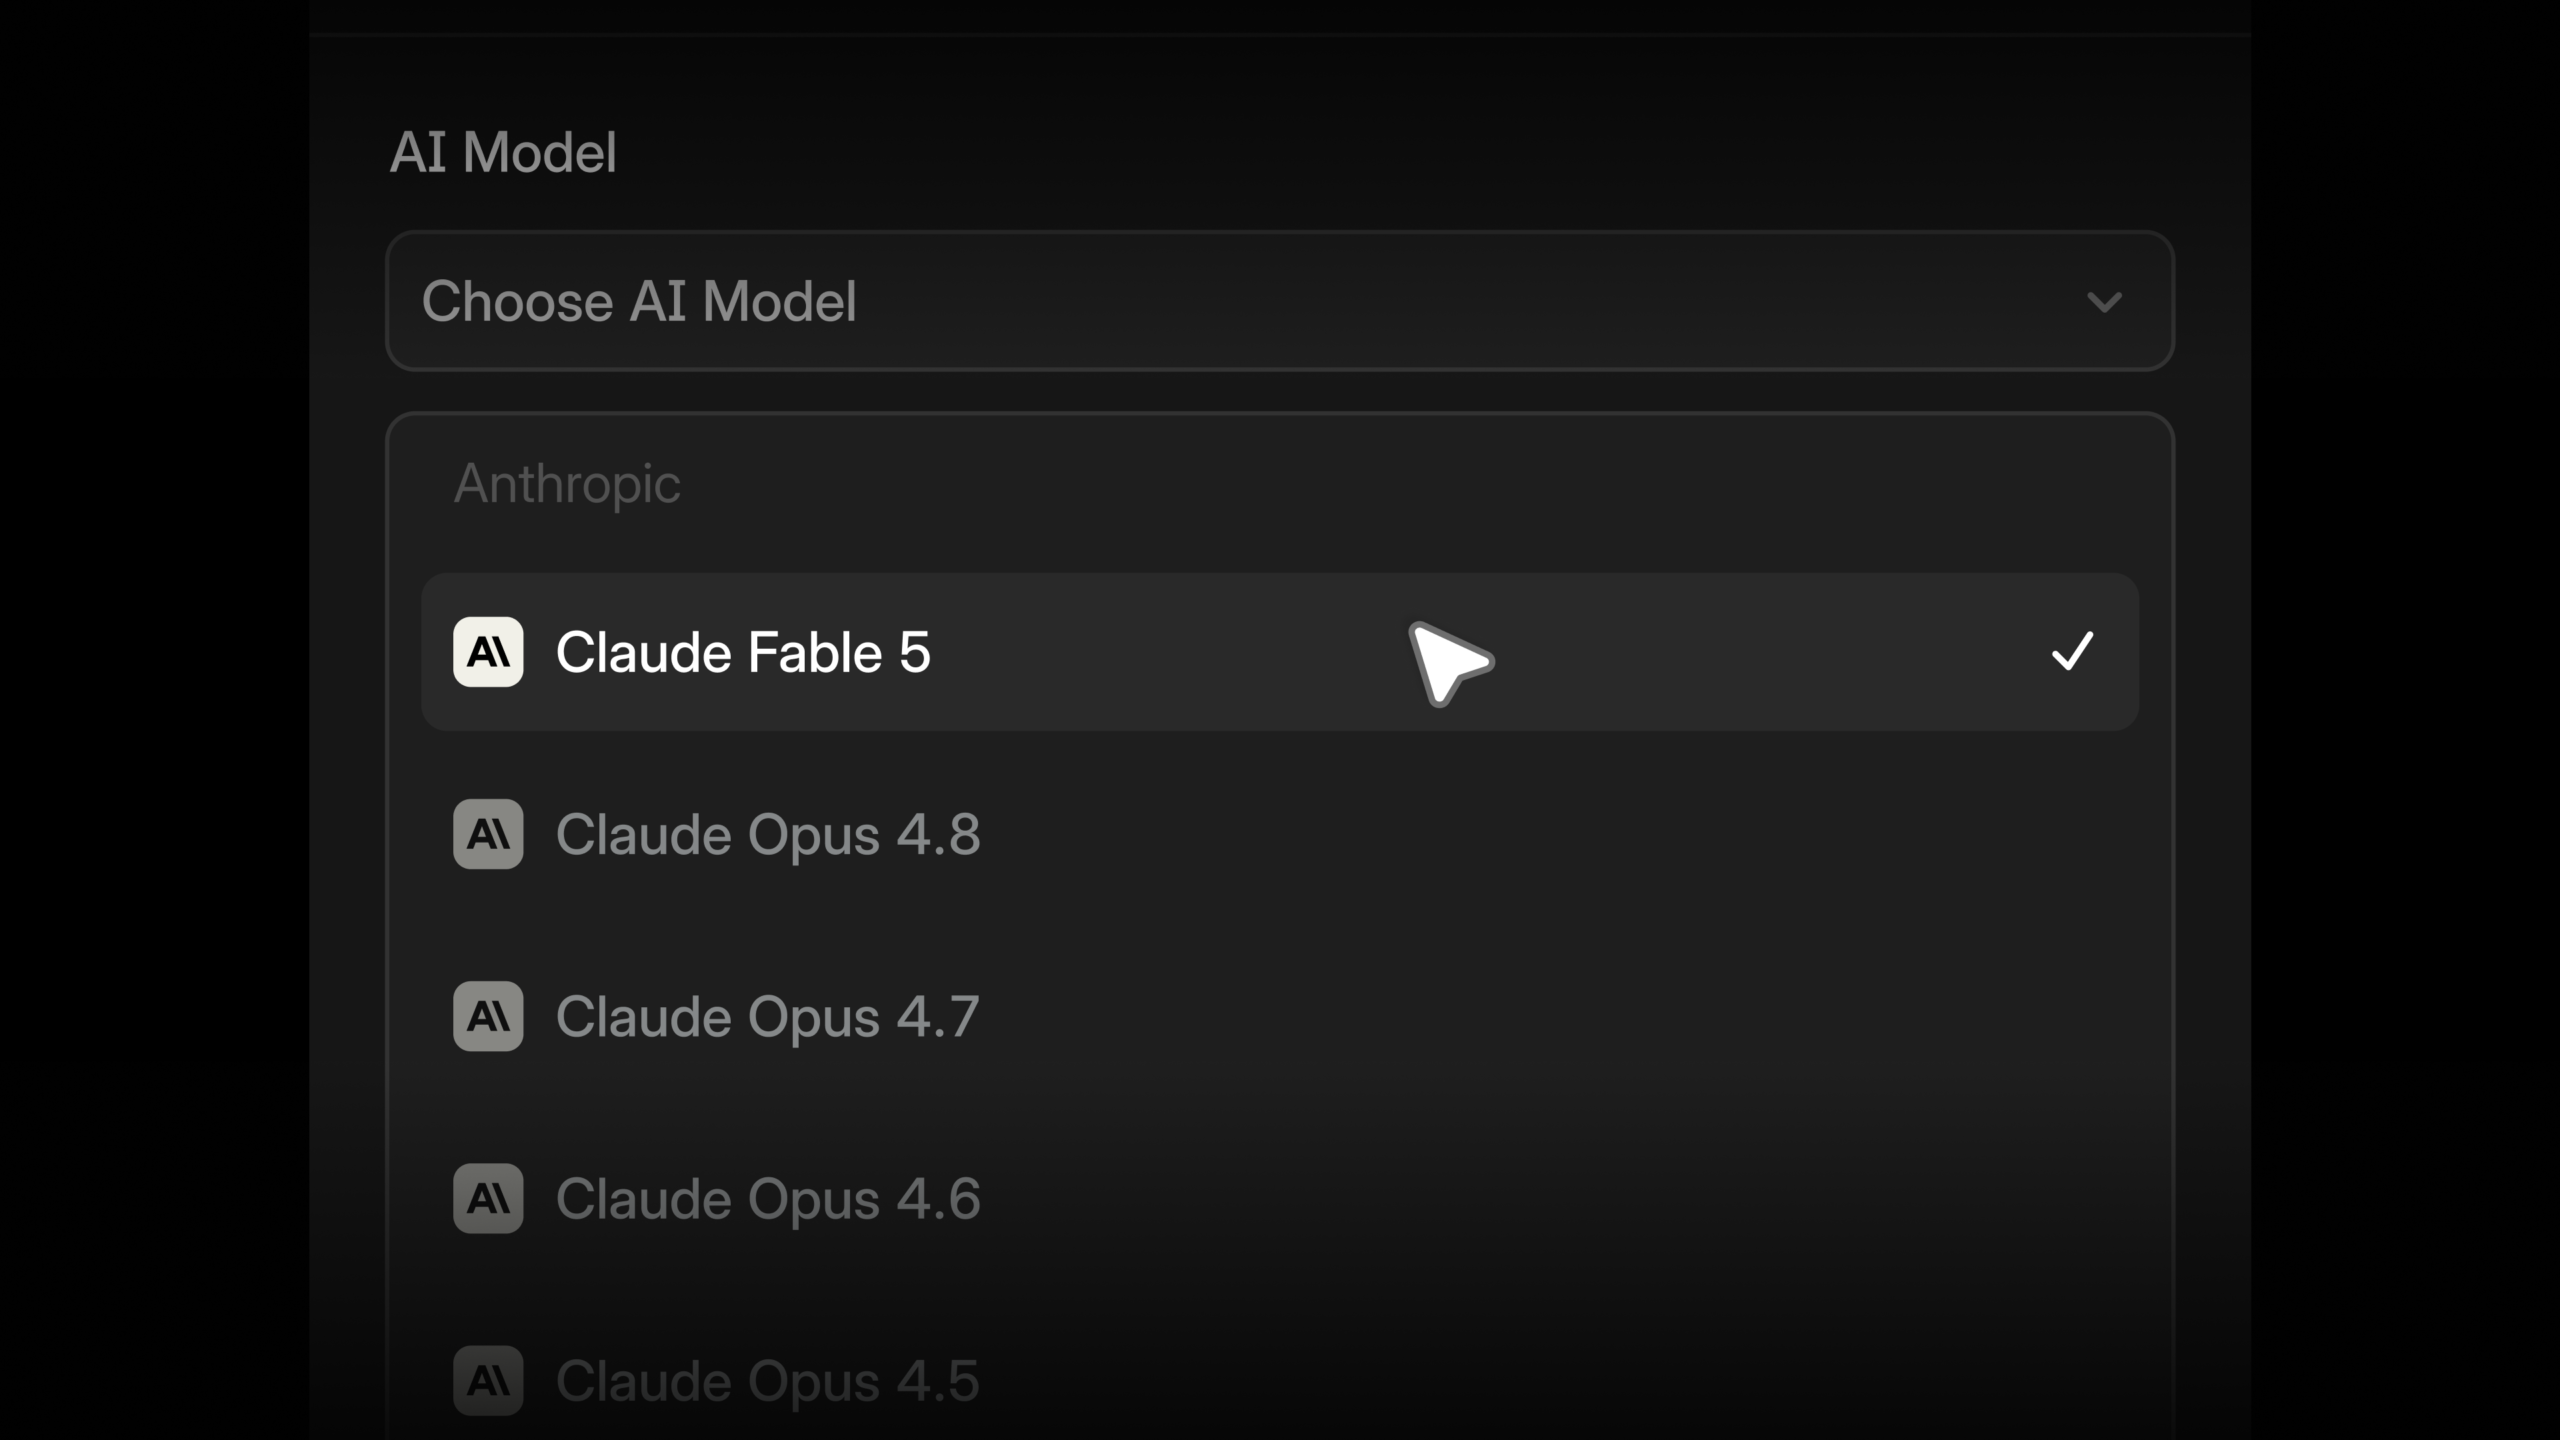
    I’m thrilled to share some fantastic news with you. We’ve just launched support for Claude Fable within Profound, and it’s an upgrade that I’m genuinely excited about.

    Incorporating Claude Fable into our system not only enhances user experience but also brings a new level of efficiency to our platform. This integration is designed to provide seamless functionality and improve overall productivity.

    I’m confident that this addition will greatly benefit all users by offering enhanced capabilities and features that are both intuitive and powerful. Stay tuned for more updates as we continue to innovate and evolve.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • Unlock Competitor Insights with Adthena’s ChatGPT Ad Analysis

    Unlock Competitor Insights with Adthena’s ChatGPT Ad Analysis

    I recently dove deep into the fascinating world of ChatGPT Ads with insights from Adthena. It turns out, the advertising space on ChatGPT is a treasure trove of competitive information that many search teams are missing out on.

    Your competitors are running stealth campaigns via ChatGPT, and the frustrating part is that it’s not immediately visible what they’re bidding on or what creative strategies they’re adopting. Unlike Google Ads, there’s no native way—yet—to get a behind-the-scenes look at this in ChatGPT.

    When OpenAI launched advertising within AI-generated responses, brands jumped on board quickly. With the Ads Manager and lowered spending thresholds, this new ad channel grew rapidly. And with plans to expand to U.K. markets soon, there’s a quickly closing window for early adopters to gain a significant advantage.

    From the start, we’ve been closely monitoring these developments, and what we’ve found is eye-opening.

    ```json
{
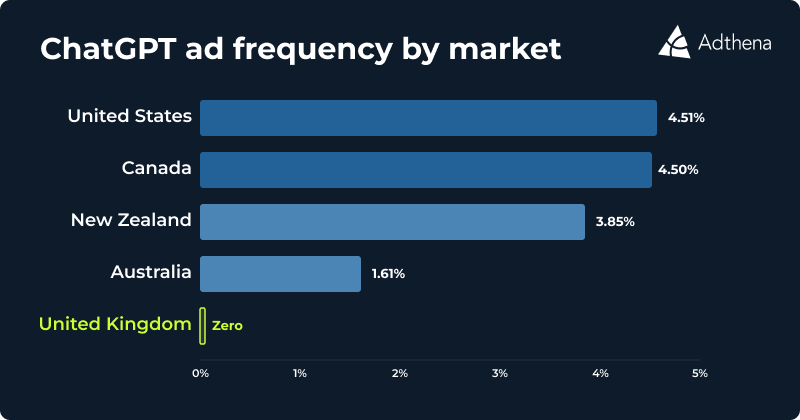
  "alt": "Bar chart showing ChatGPT ad frequency by market. U.S. at 4.51%, Canada 4.50%, New Zealand 3.85%, Australia 1.61%, U.K. Zero.",
  "caption": "Exploring ChatGPT ad presence globally: U.S. and Canada lead with over 4%, while the U.K. notes zero activity. Discover market trends in AI advertising.",
  "description": "This image is a bar chart illustrating ChatGPT ad frequency across different markets. The data shows the United States at 4.51%, Canada at 4.50%, New Zealand at 3.85%, and Australia at 1.61%. Notably, the United Kingdom registers zero ad frequency. The chart is presented on a dark blue background, emphasizing the data collected by Adthena."
}
```

    What Does the Current ChatGPT Ads Landscape Look Like?

    Our analysis spans nearly a million queries across 20 industries in five markets, telling a clear story of the current landscape.

    It’s Primarily a U.S. Channel—Other Markets are Catching Up

    In the U.S., ads are run on about 4.5% of queries. In contrast, during the same period, the U.K. had none. The U.S. dominates, accounting for 90% of ChatGPT ad placements in our dataset, with Canada and New Zealand also active and Australia at 1.6%.

    For U.K. teams, it means while the channel isn’t live yet, U.S. competitors are already fine-tuning prompts and creative strategies, placing them at a strategic advantage when the U.K. market opens.

    ```json
{
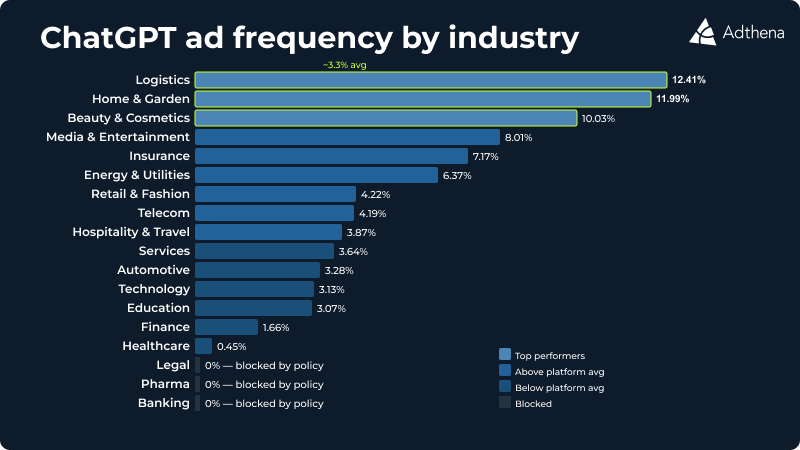
  "alt": "Bar chart showing ChatGPT ad frequency by industry, with Logistics having the highest percentage.",
  "caption": "Explore how ChatGPT ads perform across industries, with Logistics leading the charge at 12.41% and sectors like Legal and Pharma blocked.",
  "description": "This image is a bar chart from Adthena, illustrating ChatGPT ad frequency across various industries. Logistics tops the list at 12.41%, followed by Home & Garden at 11.99%. Categories such as Legal and Pharma have 0% due to policy blocks. The chart categorizes industries into top performers, above platform average, below average, and blocked, offering insight into advertising trends."
}
```

    The Majority of Responses Contain Just One Ad

    On average, ChatGPT presents only 1.06 ad items per response in the U.S., implying a single sponsored slot per query. This level of exclusivity changes the game completely compared to multi-slot Google Ads.

    Industry Restrictions Still Apply

    Certain sectors, like Legal and Pharma, show no ad activity due to what seems to be OpenAI’s deliberate restrictions, although this could change, providing proactive teams an edge.

    Unexpected Hot Categories

    Logistics, Home & Garden, and Beauty & Cosmetics are leading in ad frequency, indicating high potential for growth in these sectors.

    ```json
{
  "alt": "Bar chart showing US market shares for retail, automotive, hospitality, media, and others.",
  "caption": "Retail and fashion dominate the US market, leading ahead in both search queries and ad presence.",
  "description": "This bar chart compares the US market shares of various industries: retail & fashion, automotive, hospitality & travel, media & entertainment, and others. Retail & fashion is the leader with 24.1% share of queries and even higher ad items share at 38.9%, showing an over-index of +14.8pp. Automotive follows with 8.5% in queries. The chart, presented by Adthena, emphasizes the commercial gravity of retail in the US market."
}
```

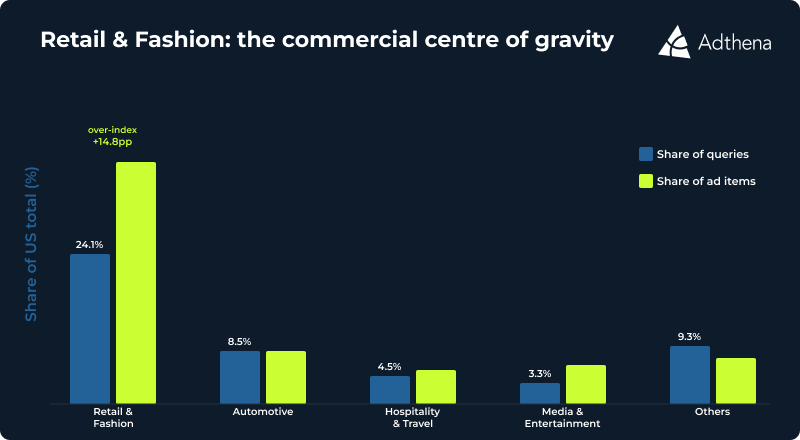
    Retail Leads in Ad Spend

    Retail & Fashion accounts for a vast share of U.S. ad items, indicating robust advertiser demand, far surpassing the national average. This suggests the significant investments made by retail brands in this space.

    Current Challenges in Competitive Intelligence

    Without tools like Auction Insights, understanding your competitive landscape on ChatGPT is practically impossible. You’re spending budget where you can barely track competitor activity. It’s a gap that Adthena aims to close.

    Achieving Full Market Visibility with Adthena

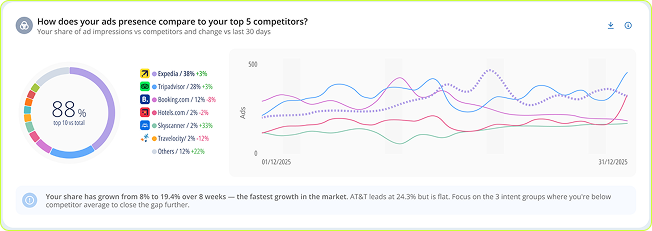
    Adthena’s ChatGPT Ads Intelligence offers broader insights by monitoring a plethora of prompts daily, providing a competitive overview previously unavailable.

    ```json
{
  "alt": "Ad impressions comparison chart with competitors and line graph analysis.",
  "caption": "Dynamic visualization of ad presence over time, comparing performance with top competitors.",
  "description": "The image displays a data chart comparing ad impressions among top competitors over 30 days. A pie chart shows a 38% share, while a line graph tracks different competitors' trends from 01/12/2025 to 31/12/2025. A note highlights the fastest growth from 8% to 19.4% in 8 weeks, advising focus on areas where competitors outperform."
}
```

    You can now see who bids on your prompts, track share of voice, and spot open prompts ripe for targeting before competitors do.

    In a new and rapidly evolving channel, being an early mover is an opportunity that shouldn’t be missed. Try ChatGPT Ads Intelligence free for 21 days and unlock the full potential of your advertising strategy.

    Beyond Just ChatGPT: Expanding Your Search Horizons

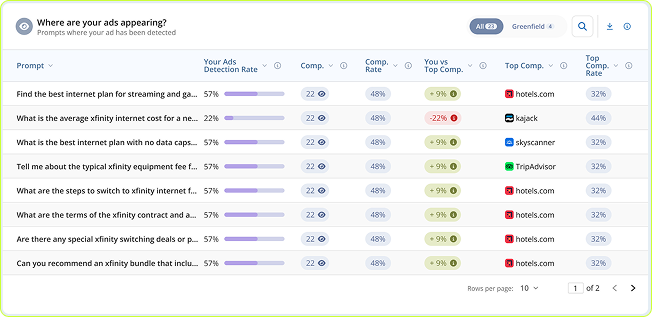
    As users move towards AI-driven searches for high-intent queries, such as product recommendations, it’s essential for search practitioners to adapt. Simply put, the game is changing.

    ```json
{
  "alt": "Chart showing ad detection rates for Xfinity-related queries with competitors' comparison and top competitor sites.",
  "caption": "Explore where your ads stand in the competitive landscape with detailed detection rates and comparisons against top competitors like hotels.com and kajack.",
  "description": "This image displays a chart analyzing ad detection rates for various Xfinity-related queries. It highlights your detection rate alongside competitors and compares it to top competitors like hotels.com. The table details 'Prompt', 'Your Ads Detection Rate', 'Comparison Rate', 'Top Competitor', and more. Ideal for advertisers seeking insights into ad performance and competitor strategy."
}
```

    If you’re attentive to ChatGPT Ads now, you’ll be hard to budge later. Our data shows a window of opportunity open now, similar to the early days of Google Ads. Capitalize on this before it closes.

    Start your free 21-day trial of Adthena’s ChatGPT Ads Intelligence today to discover what’s unfolding in the ChatGPT ad space.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Harnessing the Power of Profound for AI-Driven Marketing Success

    Harnessing the Power of Profound for AI-Driven Marketing Success

    I’ve discovered that Profound is the ultimate hub for marketers aiming to excel in the AI-driven landscape. It’s where I run my visibility, sentiment, and accuracy analyses.

    This platform is my go-to for building marketing Agents and uncovering new opportunities. It’s here that I generate innovative content and take action based on deep insights.

    Given all these functions, it’s only natural that Documents have found a home here too. Profound seamlessly integrates document management into my existing marketing workflow.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot