Category: AI

  • Claude Chat Privacy: When Shared Links Enter Search Results

    Claude Chat Privacy: When Shared Links Enter Search Results

    If you’ve used Claude for something sensitive, hearing that Claude chats appeared in search results can make it sound as though every private prompt is searchable. That isn’t what the documented exposure established.

    The affected pages were chat snapshots made available through user-created public share URLs. The practical lesson is still serious: once you turn a conversation into a shareable web page, you should treat that page as public unless access control proves otherwise.

    A shared Claude link is a web page, not a private message
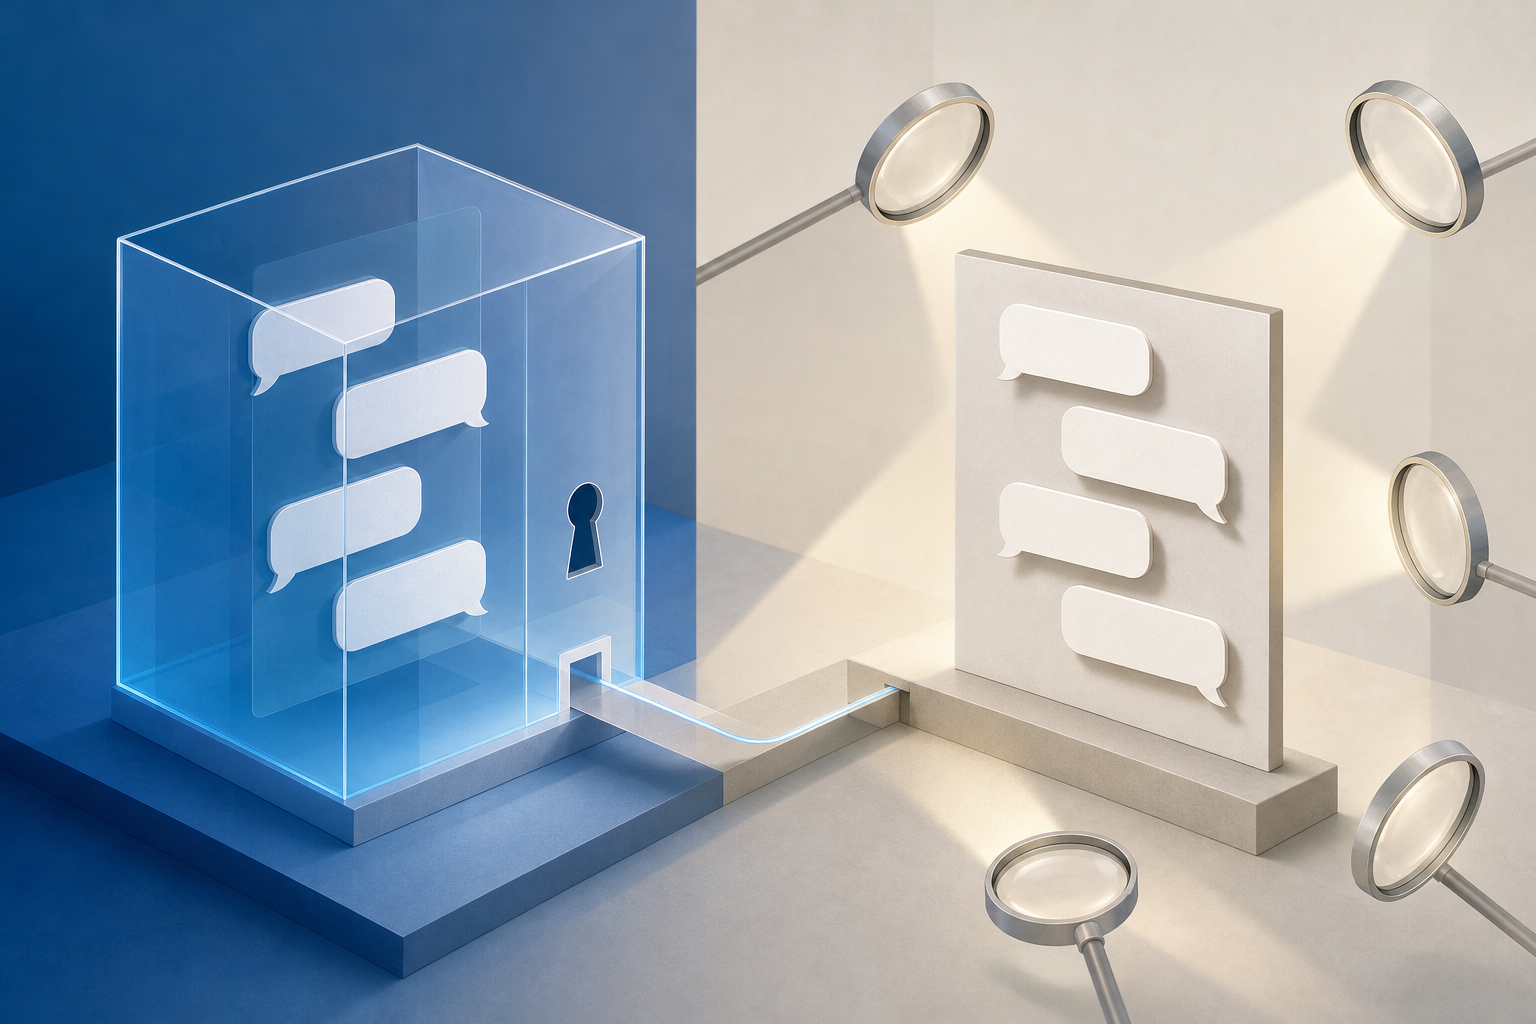
    Blank chat bubbles sit inside a secured chamber while a copied conversation page outside is illuminated by magnifying lenses.

    A conversation inside your authenticated Claude account and a snapshot exposed through a share URL occupy different privacy states. The first sits behind your account session. The second is designed to be opened outside that session, which means the URL can be forwarded, linked from another page, collected by automated systems, or discovered by a search crawler.

    Creating the share URL does not guarantee that Google or Bing will index it. It does, however, create the conditions under which indexing can happen. There are three separate stages:

    1. Public access: A person who has the URL can load the page without signing in.
    2. Discovery and crawling: A search engine finds the URL, often through a link or another crawlable source, and requests the page.
    3. Indexing: The search engine decides that the URL or its contents can appear in search results.

    The first stage is the privacy boundary. Indexing increases discoverability, but a page was already exposed before it appeared in search. An unindexed URL is therefore not the same thing as a private URL.

    This also separates search exposure from other questions about AI services, such as conversation retention or model training. Those issues depend on the service’s policies and settings. The incident at issue concerned public share pages reaching search indexes; it does not, by itself, establish that ordinary unshared chats were searchable.

    At one point, a site:claude.ai/share query surfaced hundreds of shared conversations, including sensitive health and political discussions. Those results were later removed. Removal from a search index reduces discovery, but it cannot establish that nobody opened, copied, forwarded, or captured a page while it was accessible.

    Key takeaways

    • An ordinary Claude conversation and a user-created share page are not the same privacy state.
    • A public page can be accessed before a search engine indexes it, so no search result does not mean no exposure.
    • If a shared conversation contains sensitive material, remove or revoke the page at its host before concentrating on search-result removal.
    • Robots.txt is a crawler-management file, not an access-control or privacy system.
    • A noindex instruction must remain visible to crawlers; blocking the same page in robots.txt can prevent them from seeing it.

    What to do if you created a Claude share link
    A person reviews a generic shared chat page while closing a link icon and placing a message card in a locked drawer.

    Start at the original page, not at Google. Search results are a downstream copy of a more important condition: whether the conversation is still publicly accessible.

    1. Inventory the links you created. Check any sharing controls currently available in your Claude account, then review places where you may have pasted links: email, chat messages, tickets, documents, notes, social posts, or team workspaces. Do not assume you created only one snapshot.
    2. Test each link while signed out. Open it in a private browser window where you are not logged into Claude. If the conversation loads without authentication or another access check, treat it as public. Avoid submitting the URL to unrelated scanning sites or public forums, because that creates additional copies and routes of discovery.
    3. Revoke or remove access at Claude. Use the platform’s current sharing controls to disable the link. If no self-service control is available, contact Anthropic through its support process and identify the exact share URL. Search delisting alone is not enough while the original page remains open.
    4. Record the minimum evidence you need. Keep the URL, when you noticed the exposure, and a private screenshot of any relevant search result if you may need an organizational incident record. Do not republish the conversation merely to document it.
    5. Respond to the contents, not just the page. Revoke exposed API keys, access tokens, invitation links, or session credentials. Change any exposed password wherever it was reused. If the chat contains client records, employee information, regulated data, or confidential business material, notify the appropriate security, privacy, or legal owner through your organization’s incident process. Removing a page does not make a disclosed credential safe again.
    6. Check search visibility after access is closed. Search for the exact URL, a distinctive non-sensitive phrase, and the site:claude.ai/share pattern in the relevant search engines. Treat these as spot checks rather than a complete audit. If a result remains, use the search engine’s webmaster or personal-information removal process, but keep the origin page disabled.

    If the page contained no identifying information, credentials, confidential records, or material tied to another person, revoking the link and checking for residual results may be proportionate. If any of those elements were present, escalation matters more than repeatedly searching your own name. The consequence comes from what was exposed and who could act on it, not merely from whether a result still ranks.

    For site owners, robots.txt is not a privacy control

    The technical failure behind this kind of exposure is easy to repeat. A team wants to keep pages out of search, so it disallows their paths in robots.txt and adds a noindex directive to the pages. That combination looks cautious, but the two instructions can work against each other.

    A noindex directive works only after a crawler retrieves the page and reads the directive in its HTML or HTTP response. When robots.txt prevents that retrieval, the crawler cannot see noindex. Google explicitly warns that a robots-blocked URL can still appear in results when the engine learns about it elsewhere, such as through links.

    The right configuration depends on the access policy you actually intend:

    • Private conversation: Require authentication and verify that the signed-in user is authorized to access that specific conversation. Add noindex as defense in depth, not as the lock on the door.
    • Public share page that should not appear in search: Allow compliant crawlers to request the page, then serve a noindex meta directive or X-Robots-Tag response header. Do not disallow the same URL in robots.txt while depending on noindex.
    • Public and indexable publication: Make the publishing consequence explicit before the user creates the URL. Let the user preview and redact the content, identify what metadata will be visible, and provide a reliable revocation control.
    • Revoked or deleted share: Remove public access at the origin. Require authorization again or return a genuine not-found or gone response. Search-removal requests can accelerate cleanup, but they should follow the access change.

    Noindex does not encrypt content, restrict direct visitors, stop forwarding, or prevent every scraper and archive from collecting a page. Robots.txt does none of those things either. If viewing the content would itself be a privacy failure, the content belongs behind authentication and server-side authorization.

    Test the privacy boundary as a stranger would

    A logged-in product test can hide the most important failure. Include these checks in every release that affects chat sharing:

    • Open a newly shared link in a clean, signed-out browser session.
    • Confirm whether the user made an explicit public-sharing choice before the URL was created.
    • Inspect the rendered meta robots value and response headers on the actual share template.
    • Verify that robots.txt does not block crawlers from reading a noindex directive you expect them to obey.
    • Revoke the link and confirm that the same signed-out request no longer reveals the conversation.
    • Maintain a server-side inventory of active share URLs instead of relying on site: searches, which are useful for discovery but incomplete as an audit.

    Before your next sensitive Claude session, decide whether the content should remain inside an authenticated conversation or become a shareable web page. If you choose to share, redact first and act as though the link may travel. For product teams, make that same distinction structural: private content needs access control, public-but-unlisted content needs a crawlable noindex directive, and revoked content needs to stop loading.

    References


  • How to Build a Self-Improving AI Content Workflow

    How to Build a Self-Improving AI Content Workflow

    You keep correcting the same AI output: a vague heading, an unsupported claim, a generic opening, a conclusion that says nothing. The draft improves after you edit it, but the workflow that produced it stays exactly the same.

    A self-improving content workflow preserves those corrections, finds recurring patterns, and changes the next run under controlled conditions. The goal is not an agent that rewrites its own rules without supervision. It is a system that turns editorial judgment into reviewable improvements to briefs, evidence retrieval, writing instructions, quality gates, and routing.

    A workflow improves only when feedback changes the next run

    Generating a draft, editing it, and publishing it is a production process. It becomes a feedback loop only when the correction affects a reusable part of the process. Unless you persist that correction somewhere, a new model run has no reason to avoid the same failure.

    The reusable change does not have to be a prompt edit. Feedback can change the criteria used to approve an angle, the queries used to retrieve evidence, the material included in a writing packet, the rubric applied by an editorial agent, or the route taken when a check fails. This distinction matters because many apparent writing problems originate before the writer receives the task.

    Every useful loop needs the same basic components:

    • An observable failure, recorded in specific terms.
    • A classification that identifies where the failure entered the workflow.
    • A proposed change to a reusable instruction, criterion, example, query, or routing rule.
    • An evaluation that checks whether the change fixes the target problem without damaging other requirements.
    • A human-controlled decision to approve, reject, revise, or roll back the change.

    That last component is what makes the system governable. Production agents can record feedback and propose patches, but they should not silently promote every correction into permanent operating memory. A rushed edit, an individual preference, or an unusual brief can otherwise become a global rule.

    Key takeaways

    • Begin with a quality gate around existing drafts; it creates useful feedback without requiring you to rebuild the whole pipeline.
    • Cap revision at two rounds. A draft that still fails usually needs better evidence, a narrower claim, or a stronger angle.
    • Separate editorial review from citation checking so each agent has a clear job and an appropriate context packet.
    • Stop weak angles and evidence gaps before writing. Upstream failures become more expensive after a full draft exists.
    • Use recurring edits as evidence for an instruction change, but require a proposal, evaluation, version record, and human approval.

    Start with a quality gate and a firm revision cap

    Blank manuscript sheets move through a quality gate, with one approved, one sent through a limited revision loop, and one routed to a human editor.

    The smallest practical self-improving workflow places an independent reviewer after the writer. The reviewer does more than declare that a draft feels weak. It evaluates explicit acceptance criteria, identifies the class of failure, and returns a bounded revision request.

    Build that loop in this order:

    1. Write an acceptance contract for the content type. Define the intended reader, the decision or task the content must support, the required evidence standard, the voice constraints, and the structural requirements.
    2. Give the writer a bounded packet containing the approved brief, outline, evidence, brand instructions, and output format. Do not make the writer infer which requirements matter most from a large repository of loosely related material.
    3. Send the resulting draft to an editorial reviewer in a separate context window. The reviewer should receive the acceptance contract and the draft, not the writer’s internal deliberation.
    4. Send factual claims and cited evidence to a dedicated fact-checker. Its job is to verify that the evidence supports the wording in the draft, not merely that a cited link exists.
    5. Classify the result as pass, flag, or escalate. Attach a precise diagnosis to every flag.
    6. Return fixable defects to the writer. The revision request should name the affected passage, failed criterion, reason for failure, and required result.
    7. Stop after two revision rounds. Route the draft and its review history to a person who can change the angle, evidence plan, or brief.

    The three verdicts need operational definitions. Pass means the draft meets the acceptance contract and its factual claims survive checking. Flag means the defect can be corrected within the existing brief and evidence set. An undefined term, an indirect opening, or a poorly ordered section can usually be flagged. Escalate means rewriting alone cannot solve the problem. Missing evidence, an unworkable thesis, contradictory requirements, and an angle with no defensible point of view belong here.

    The revision cap prevents an agent pair from polishing around a structural defect. If specificity remains weak after two rewrites, the evidence packet may not contain the concrete material the writer needs. Another instruction to be more specific will not create that material. The correct route is back to research or strategy.

    Keep editorial review and fact-checking separate even if both happen after drafting. An editorial reviewer asks whether the structure serves the argument, the language fits the audience, and the answer is useful. A fact-checker compares each factual statement with the evidence attached to it. Combining those responsibilities makes it easier for fluent prose to distract from weak support, or for citation work to crowd out substantive editing.

    Add a direct entry point to the gate as well. A draft written by a colleague, contractor, or older system should be reviewable without rerunning ideation, retrieval, and drafting. This makes the gate useful across the content operation and gives you a more representative record of recurring failures.

    Catch weak angles and evidence gaps before drafting

    A downstream reviewer can detect an unsupported claim, but it cannot manufacture the missing proof. It can identify a generic thesis, but by then you have already paid for research, drafting, and review. Two upstream checks prevent those failures from entering the expensive part of the workflow.

    Filter the brief with pass, revise, and kill decisions

    Evaluate each proposed angle against criteria you define before generation. Useful criteria include audience fit, thesis strength, original point of view, distance from existing coverage, and whether the necessary proof appears obtainable. The evaluator must choose an action, not simply assign a vague confidence score.

    VerdictMeaningNext action
    PassThe angle has a defensible thesis, fits the intended audience, and can be supported.Release the brief to evidence retrieval and outlining.
    ReviseThe idea is viable, but its scope, audience, differentiation, or evidence requirement is wrong.Return a specific change request, then evaluate the revised brief again.
    KillThe angle lacks a meaningful point of view or depends on proof that is not available.Stop the run and record the reason. Do not ask the writer to rescue it with phrasing.

    The kill log is not a graveyard for ideas. It is training data for strategy rules. Record the intended audience, thesis, decision, reason code, missing requirement, evaluator, and rule version. You can then see whether the same pattern keeps failing: duplicate angles, claims that require unavailable data, topics aimed at the wrong buyer stage, or briefs too broad to support a useful answer.

    Keep revise and kill distinct. Revise means a known change can make the brief viable. Kill means the core proposition does not survive the criteria. If evaluators use kill merely to avoid difficult research, tighten the definition. If they send fundamentally empty ideas through repeated revisions, tighten it in the other direction.

    Map planned claims to evidence section by section

    Once the angle passes, place a checkpoint between retrieval and writing. For every planned section, record the claim it needs to establish, the evidence intended to support it, and the gap that would remain if the writer used only that material.

    A practical evidence map contains:

    • The section heading and its purpose in the argument.
    • The exact factual or analytical claim the section must support.
    • The relevant evidence URL or document identifier.
    • A support score on a 1-10 scale, using a definition that stays consistent across runs.
    • The unsupported part of the planned claim.
    • A follow-up query, narrower claim, or deletion recommendation.

    Choose the passing threshold before evaluating the packet. When a section falls below it, the mapping agent should not hand the gap to the writer. It should produce the follow-up query itself, narrow the planned statement to match the available evidence, recommend removing the section, or escalate the gap to a person.

    This checkpoint is especially useful for SEO, AEO, and GEO content. A fluent answer can still be unusable if its strongest sentence outruns its citation. Mapping claims before drafting gives the writer permission to be specific where the evidence is strong and forces a deliberate decision where it is not. It also gives the fact-checker a clean chain from planned claim to evidence to published wording.

    Turn repeated edits into controlled instruction updates

    An editor groups recurring changes from blank drafts, approves one pattern, and adjusts an instruction module for the next content cycle.

    Do not update a shared prompt every time someone changes a sentence. Many edits are local: a legal qualification for a particular market, a preference from one stakeholder, or an exception created by an unusual format. Promoting them immediately makes the workflow unstable.

    A useful operating rule is to wait until the same edit pattern appears across three separate content assets. That is not a universal law or proof that the proposed fix is correct. It is a practical trigger for asking whether a reusable instruction has failed. The system should propose a change at that point, not apply one automatically.

    Capture each meaningful edit as a structured event:

    • Asset type and workflow version.
    • Original passage and approved revision.
    • Defect category, such as weak specificity, unsupported claim, indirect answer, voice mismatch, repetition, or poor section order.
    • The workflow stage most likely to own the defect.
    • The requirement that the original output failed.
    • Whether the edit is local to the asset, specific to a channel, or potentially global.
    • The reviewer who approved the final correction.

    Classification is more important than raw edit distance. Replacing an entire paragraph may reflect a minor tone preference, while changing a short factual qualifier may correct a serious accuracy problem. The system needs to know why the edit happened before it can recommend where to intervene.

    Route the proposed fix to the earliest stage that can prevent recurrence. A repeated unsupported claim belongs in evidence mapping or fact-checking. A repeated mismatch between topic and audience belongs in the brief filter. A buried direct answer belongs in the outline or structural rubric. Only a failure that genuinely originates in drafting belongs in the writer instructions.

    Make every instruction proposal reviewable. It should contain the observed pattern, the affected assets, the proposed wording, the expected change, the evaluation criterion, the scope of application, and the current instruction version. Replace abstract directives such as improve clarity with testable behavior. For example: define a technical term when it first appears, then state the implementation consequence in the same section. A reviewer can inspect that requirement in an output; improve clarity cannot be evaluated consistently.

    Evaluate the patch on representative briefs before promoting it. Check the target defect and the rest of the acceptance contract. An instruction that produces sharper openings but removes necessary qualifications is not an improvement. Preserve the earlier version so you can roll back the change if a wider set of runs reveals a regression.

    Scope memory by format. The correction that improves a landing page may make a technical explainer too abrupt. A rule for a LinkedIn post may be inappropriate for a video script. Maintain shared brand requirements where they are genuinely universal, then place format-specific instructions closer to the relevant writer and reviewer.

    Use rubric scores to diagnose the system, not flatter it

    A pass-or-fail gate tells you whether content can move forward. A rubric tells you which capability is holding it back. Score each criterion separately and require a concrete diagnosis whenever a score falls below its threshold. A total score alone is dangerous because strong voice and clean structure can conceal weak evidence.

    Rubric dimensionQuestion to evaluateLikely route when it fails
    Audience and intent fitDoes the content resolve the decision or task named in the brief?Brief filter
    Original point of viewDoes the thesis make a defensible contribution rather than restating the topic?Angle evaluation
    SpecificityDo important recommendations include the mechanism and an actionable consequence?Evidence mapping or writer
    Claim supportDoes the evidence establish the claim at the strength used in the draft?Retrieval checkpoint
    Citation fidelityDoes each cited item support the exact sentence attached to it?Fact-checker
    StructureDoes each section advance the argument or help the reader complete the task?Outline or editorial reviewer
    VoiceDoes the wording follow the applicable brand and format rules?Writer instructions
    Answer usabilityAre core answers direct, self-contained, and explicit about the entities and conditions involved?Outline or writer

    A diagnosis must describe the gap, not merely repeat the criterion. Specificity is low is not useful feedback. The recommendation names actions but omits the condition that determines which action applies is useful. It tells the writer what to repair and gives the reviewer something concrete to check on the next pass.

    You can also apply the same rubric to competing briefs, outlines, or openings. Compare candidates criterion by criterion, preserve any hard acceptance requirements, and select the option that best serves the task. Do not let a high average compensate for a fatal weakness such as an unsupported central claim.

    Track workflow health alongside content scores. Useful operating measures include first-pass acceptance, flags by defect category, revision rounds per asset, escalation reasons, evidence gaps caught before drafting, instruction patches proposed and approved, and patches later rolled back. These measures show whether the system is preventing defects or merely moving them between agents.

    Post-publication outcomes can trigger investigation, but they should not rewrite instructions by themselves. Search visibility, AI citations, engagement, and conversion depend on more than wording. Associate each asset with its intended outcome, review performance within a predefined measurement window, and compare the result with the editorial record. Then decide whether the signal points to content quality, distribution, technical implementation, audience fit, or a changed search environment.

    Implement the system in layers. Put the capped reviewer and fact-checker around the draft currently waiting for approval. Log every verdict and escalation. When those logs expose upstream failures, add the angle and evidence checkpoints. When recurring edits become visible across separate assets, enable instruction proposals with approval and rollback. Your workflow will then improve from evidence of its own failures without giving up editorial control.

    References
  • How to Use Profound Aim Brainstorm Mode Productively

    How to Use Profound Aim Brainstorm Mode Productively

    You can have useful AI Search data and still face a blank next step. The data may expose several promising directions, but it cannot choose which uncertainty your team should resolve first.

    Brainstorm Mode within Profound Aim is designed for that handoff: it guides a broad goal toward scoped, ready-to-run Agents. The practical value is not producing more ideas. It is reducing the distance between an ambition and a task that can inform a real decision. To get that value, you need to give Brainstorm Mode strategic direction without prematurely prescribing the analysis.

    Use Brainstorm Mode to close a decision gap

    Brainstorm Mode is most useful when you know the outcome you want but do not yet know what an Agent should investigate. That is a decision gap: your team has a business objective and relevant data, but the next analytical question remains unclear.

    Good reasons to start in Brainstorm Mode include:

    • You can describe the business outcome, but several parts of the AI Search data could be relevant.
    • You have noticed a visibility pattern and need to decide which part deserves deeper investigation.
    • Different teams are proposing different explanations for the same result.
    • You need to turn a broad AI visibility priority into work that has a clear boundary.
    • You know someone can act on the answer, but you have not yet defined the question that would produce it.

    Brainstorming adds less value when the task is already precise. If you know the exact question, scope, evidence and required output, you may already have an Agent brief. Starting another ideation cycle can introduce ambiguity that was not there before.

    There is a simple readiness test: complete the sentence, “When this Agent finishes, we will decide whether to ______.” If you cannot fill the blank with a decision your team is prepared to make, the problem is not Agent scope yet. You still need alignment on the purpose of the work.

    Give Aim a broad goal without giving it an empty one

    A glowing sphere and several streams of abstract evidence pass through an open funnel and become three distinct research capsules.

    Broad and vague are not the same. A broad goal leaves room to discover the right investigation. A vague goal hides the decision, audience and boundary that make an investigation useful.

    “Improve our AI visibility” is vague. It does not say which part of the business matters, what kind of visibility problem is in scope or what anyone will do with the result. Brainstorm Mode may still be able to propose work, but you will have no strong basis for judging whether that work matters.

    A useful goal normally contains these ingredients:

    • Outcome: the change you want to support, such as choosing a content priority or understanding a visibility weakness.
    • Business scope: the brand, offering, product area or customer problem that matters.
    • Audience scope: the market, language, geography or buyer context that should govern relevance.
    • Decision: what the team expects to choose after seeing the evidence.
    • Evidence boundary: what the available AI Search data can reasonably help examine.
    • Constraint: what should remain outside the first investigation so the Agent does not become an entire strategy project.

    You can assemble those ingredients with this reusable structure:

    Help us decide [decision] for [brand, offering or audience] by using our AI Search data to investigate [uncertainty]. Keep the first Agent focused on [scope], and produce evidence we can use to [next action].

    Goal-framing template

    For example, replace “Improve our AI visibility” with: “Help us decide which content area should receive the next optimization effort. Use our AI Search data to investigate where visibility is weakest within the product area we plan to grow, and keep the first Agent focused on identifying and characterizing the gap rather than recommending a complete content strategy.”

    The improved version is still broad enough for Brainstorm Mode to shape the work. It also supplies a decision, a business boundary and a stopping point. That stopping point matters. Without it, one Agent can easily become responsible for finding a problem, explaining it, designing a strategy, writing content and evaluating results. Those are different jobs with different evidence requirements.

    Review every proposed Agent as a research brief

    “Ready to run” describes an operational state, not automatic strategic importance. Before running a proposed Agent, make sure its result could actually change what you do. A technically valid investigation can still be too broad, unanswerable from the available data or disconnected from the decision owner.

    Use this pre-run check:

    • One primary question: Can you express the Agent’s job as one question without joining several assignments with “and”?
    • Defined boundary: Does the brief identify the relevant brand, topic, audience or market while excluding unrelated areas?
    • Available evidence: Can the AI Search data support the requested analysis, or is the Agent being asked to infer facts the data does not contain?
    • Usable output: Will the result help someone choose, prioritize, approve, reject or investigate something specific?
    • Inference discipline: Does the brief distinguish observed patterns from possible explanations?
    • Named owner: Is there a person or team prepared to use the result?

    Break apart bundled Agents

    A bundled Agent might be asked to find every visibility gap, explain every cause, compare all relevant competitors, build a content strategy and produce implementation briefs. It sounds comprehensive, but each stage depends on choices made in the previous one. If the first interpretation is weak, every later deliverable inherits the problem.

    Start with the smallest question that can change the next action. An initial Agent might identify and characterize an in-scope visibility gap. A later Agent can investigate evidence-linked explanations for the selected gap. Content planning should begin only after you decide that the gap is important enough to address.

    This sequence also makes poor outputs easier to diagnose. You can tell whether the difficulty came from the goal, the data boundary, the interpretation or the proposed action instead of debugging one oversized deliverable.

    Separate observations from explanations

    AI Search data can reveal a pattern. A pattern does not, by itself, prove why that pattern exists. “The brand appears less often for this topic” is an observation. “The brand appears less often because of a particular content weakness” is an explanation that still needs support.

    If a proposed Agent asks why something is happening, require it to distinguish direct evidence from inference. The useful output is not an unsupported diagnosis stated confidently. It is a set of plausible explanations connected to the available evidence, with the remaining uncertainty made visible. That gives your team something it can test instead of a conclusion it can only accept or reject.

    Turn the first Agent into a controlled decision loop

    A research capsule moves around a circular track with four abstract review stations while a person oversees the final branching gate.

    The fastest way to create a pile of unused analysis is to run every plausible Agent at once. The outputs arrive without an order of operations, overlap in scope and often answer questions that no longer matter after the first decision.

    Use Brainstorm Mode as the beginning of a controlled sequence:

    1. Write the decision sentence: “When this Agent finishes, we will decide whether to ______.”
    2. Frame the broad goal around that decision and the relevant AI Search data.
    3. Use Brainstorm Mode to translate the goal into a proposed Agent or set of Agents.
    4. Apply the pre-run check and select the smallest Agent whose result could change the decision.
    5. Run that Agent before commissioning downstream analysis.
    6. Record the finding, the interpretation and the decision as separate items.
    7. Create another Agent only when the decision exposes a new uncertainty that must be resolved.

    A working note for each completed Agent can remain short:

    • Finding: What is directly supported by the output and underlying data?
    • Interpretation: What might the finding mean, and which part remains an inference?
    • Decision: What will the team do, defer or reject because of the finding?
    • Owner: Who is responsible for the next action?
    • Validation: What later AI Search signal would help determine whether the action had the intended effect?

    Consider a team deciding which product area deserves its next content investment. The first Agent could identify which in-scope topic area shows the most decision-relevant visibility weakness in the available data. The team then selects a topic based on business importance, not merely the size of the gap. A second Agent, if needed, can examine answer patterns for that topic and organize evidence-linked hypotheses. Only then does the team choose a content intervention and define how it will evaluate the result.

    That order preserves human judgment at the points where data cannot make the business choice. Brainstorm Mode helps structure the investigation; it does not remove the need to decide which market, audience, risk and opportunity matter.

    Key takeaways

    • Use Brainstorm Mode when you have a meaningful AI Search goal but have not yet converted it into an answerable investigation.
    • Frame the goal around a decision, business boundary, audience and evidence source instead of asking generally for better visibility.
    • Reject proposed Agents that combine discovery, diagnosis, strategy, production and measurement in one assignment.
    • Make every Agent distinguish data-backed observations from explanations that remain hypotheses.
    • Run the smallest useful Agent first, make a decision and generate follow-up work only when a new uncertainty appears.

    Before you open Brainstorm Mode, write one sentence: “When the first Agent finishes, we will decide whether to ______.” Use that decision to frame the goal you bring into Aim. If the blank is still empty, pause the Agent design and settle the business question first.

    References
  • Choosing an AI Model in 2026: Performance, Cost and Fit

    Choosing an AI Model in 2026: Performance, Cost and Fit

    The strongest AI model on a leaderboard is not automatically the right model for a product, research program or engineering team. Cost, latency, deployment control and input formats can matter as much as raw reasoning performance.

    A comparison reported by First Page Sage Blog evaluated 42 large language models and ranked 15 of them using benchmark, pricing and technical data available in June 2026. Its findings offer a useful starting point, provided buyers treat the ranking as a decision aid rather than a universal purchasing order.

    How the source built its model ranking

    The source weighted eight factors: the Artificial Analysis Intelligence Index at 25%, SWE-bench Verified at 20%, GPQA Diamond at 15%, and context window, output speed and blended API cost at 10% each. Supported modalities and open-weight availability each accounted for the remaining 5%.

    Those measures address different questions. SWE-bench Verified tests the resolution of real GitHub issues in a standardized environment, while GPQA Diamond focuses on graduate-level science questions. Context size indicates how much material a model can accept in one call; it does not, by itself, prove that the model will use every part of a long prompt effectively. Speed affects interactive experiences, and open weights can support self-hosting or fine-tuning without dependence on a single API vendor.

    When public data was missing, the source applied a conservative below-average score. That choice makes a complete ranking possible, but it can also push models with incomplete reporting below models with more extensive published results.

    Key takeaways

    • Claude Fable 5 led the composite ranking. First Page Sage reported an Intelligence Index score of 60, 95.0% on its standardized SWE-bench source and a blended price of $7.70 per million tokens.
    • GLM-5.2 stood out among open-weight choices. It was reported at 82.8% on SWE-bench Verified, with a $0.90 blended cost and an MIT license.
    • Qwen 3.7 Max was the speed leader. Its reported output rate of 198 tokens per second makes it especially relevant to interactive products.
    • DeepSeek V4 Flash had the lowest estimated blended price. The source listed it at about $0.15 per million tokens, while noting that its Intelligence Index score was unavailable.
    • No single benchmark settles the decision. Capability, latency, price, modalities, context and deployment requirements need to be considered together.

    Match the model to the workload

    The most useful way to read the reported results is by operating constraint. A team paying for failed reasoning has different priorities from one serving millions of short customer interactions.

    Primary needModel highlighted by the sourceReported reason to consider it
    Maximum overall capabilityClaude Fable 5Highest composite and standardized coding scores in the dataset
    Long-running software agentsClaude Opus 4.8Strong coding and command-line results at a lower price than Fable 5
    One multimodal platformGPT-5.5Text, vision, audio and image generation in one model
    Low-cost open-weight codingGLM-5.2Strong reported SWE-bench performance, MIT licensing and a $0.90 blended price
    High-speed user interfacesQwen 3.7 MaxFastest confirmed output rate in the comparison
    Scientific and multimodal researchGemini 3.1 Pro94.1% reported GPQA Diamond performance and support for text, vision, audio and video
    Lowest API costDeepSeek V4 FlashLowest estimated blended price in the dataset
    Self-hosted multimodal deploymentLlama 4 MaverickOpen weights and compatibility with major inference frameworks

    Where benchmark comparisons need caution

    The source explicitly warned that SWE-bench Verified results above roughly 80% should be interpreted carefully because of debate about saturation and practical utility. It also noted that standardized harness results may differ from developer-published figures produced with proprietary tools.

    Several entries carry additional uncertainty. MiniMax-M3’s 80.5% SWE-bench result was flagged for possible training-data contamination. Grok 4’s Intelligence Index was estimated rather than officially confirmed, while Llama 4 Maverick lacked published SWE-bench Verified and GPQA Diamond figures in the materials reviewed. GPT-5.3 Codex also lacked a standardized SWE-bench Verified result, and the listed Intelligence Index figure was preliminary.

    Pricing deserves similar scrutiny. A blended figure depends on the assumed balance of input and output tokens, while self-hosting introduces infrastructure and operational costs that an API price does not capture. Latency can also vary by provider even when the underlying model is the same.

    A practical way to make the final choice

    1. Define the task and the cost of an incorrect result.
    2. Eliminate models that fail hard requirements such as data residency, modalities, context capacity or licensing.
    3. Shortlist options using benchmark results that resemble the actual workload.
    4. Run the same representative test set against every shortlisted model.
    5. Measure quality, latency and total cost together, including retries and human review.

    Model rankings will continue to move, but a repeatable evaluation process is more durable than any leaderboard position. The best deployment is the one that meets a clearly defined quality threshold at an acceptable operational cost.


    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot
  • Meta Business Agents Shift Commerce Into Messaging

    Meta Business Agents Shift Commerce Into Messaging

    Meta is positioning business messaging as more than a support channel. Its new Business Agent is designed to help companies handle discovery, sales and service inside conversations on WhatsApp and Instagram Direct.

    For marketers, the important question is not whether this is a better chatbot. It is how customer journeys change when product research, lead qualification and checkout can happen without a visit to the company website.

    What Meta Business Agent is designed to do

    Search Engine Land reported on the launch announcement from Meta Conversations 2026 in London. The article describes an autonomous AI agent that can interpret context, continue multi-turn conversations and follow a company’s brand voice across languages.

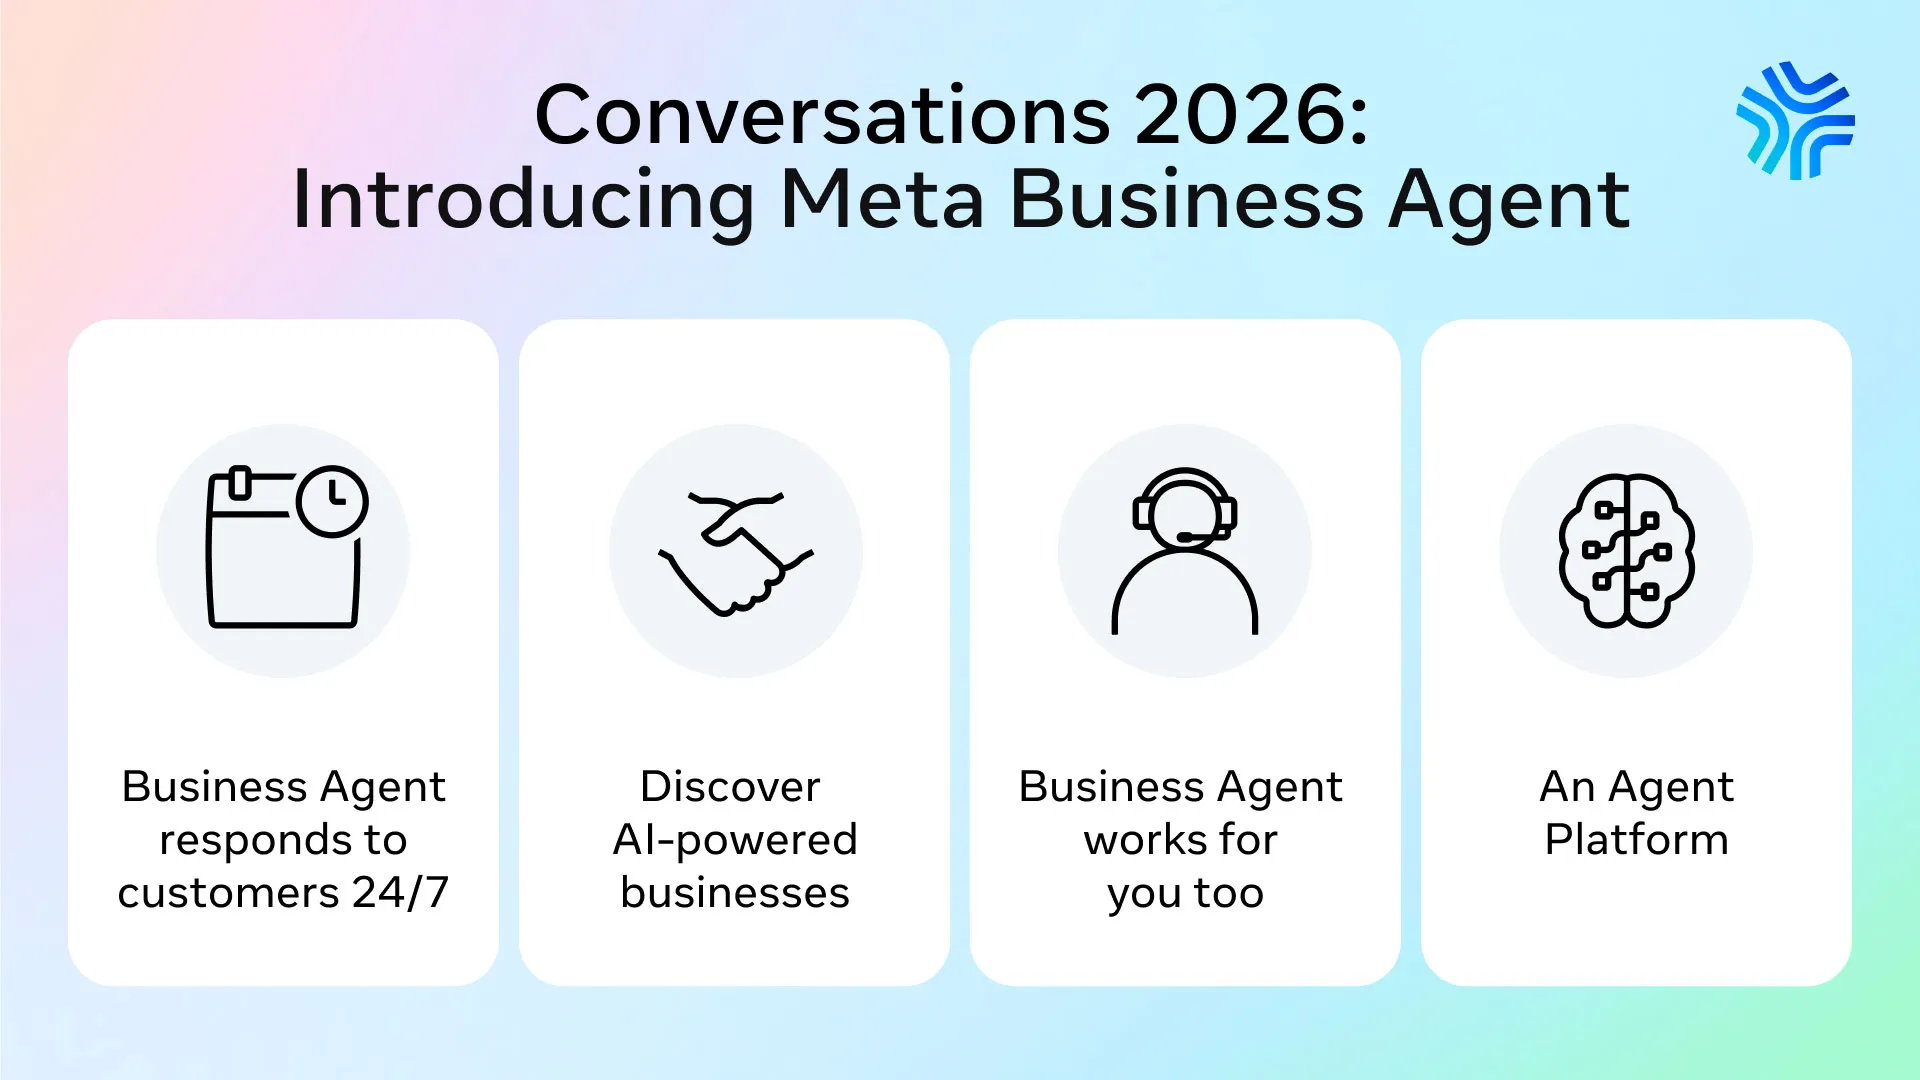
    Conversations 2026 slide introducing Meta Business Agent with four feature cards and icons.
    A Conversations 2026 slide introduces Meta Business Agent through four cards covering 24/7 customer response, AI business discovery, agent support, and an agent platform.

    In demonstrations observed by the publication’s contributor, agents answered support requests, qualified leads, retrieved current inventory through API connections and guided customers through checkout in one WhatsApp thread. Those demonstrations illustrate the intended workflow, but they should not be treated as independent evidence that every deployment will perform equally well.

    The agent can reportedly learn from a business’s Meta channels and website. Companies can also supply operational information such as prices and inventory, then add instructions covering tone, availability and how products should be represented.

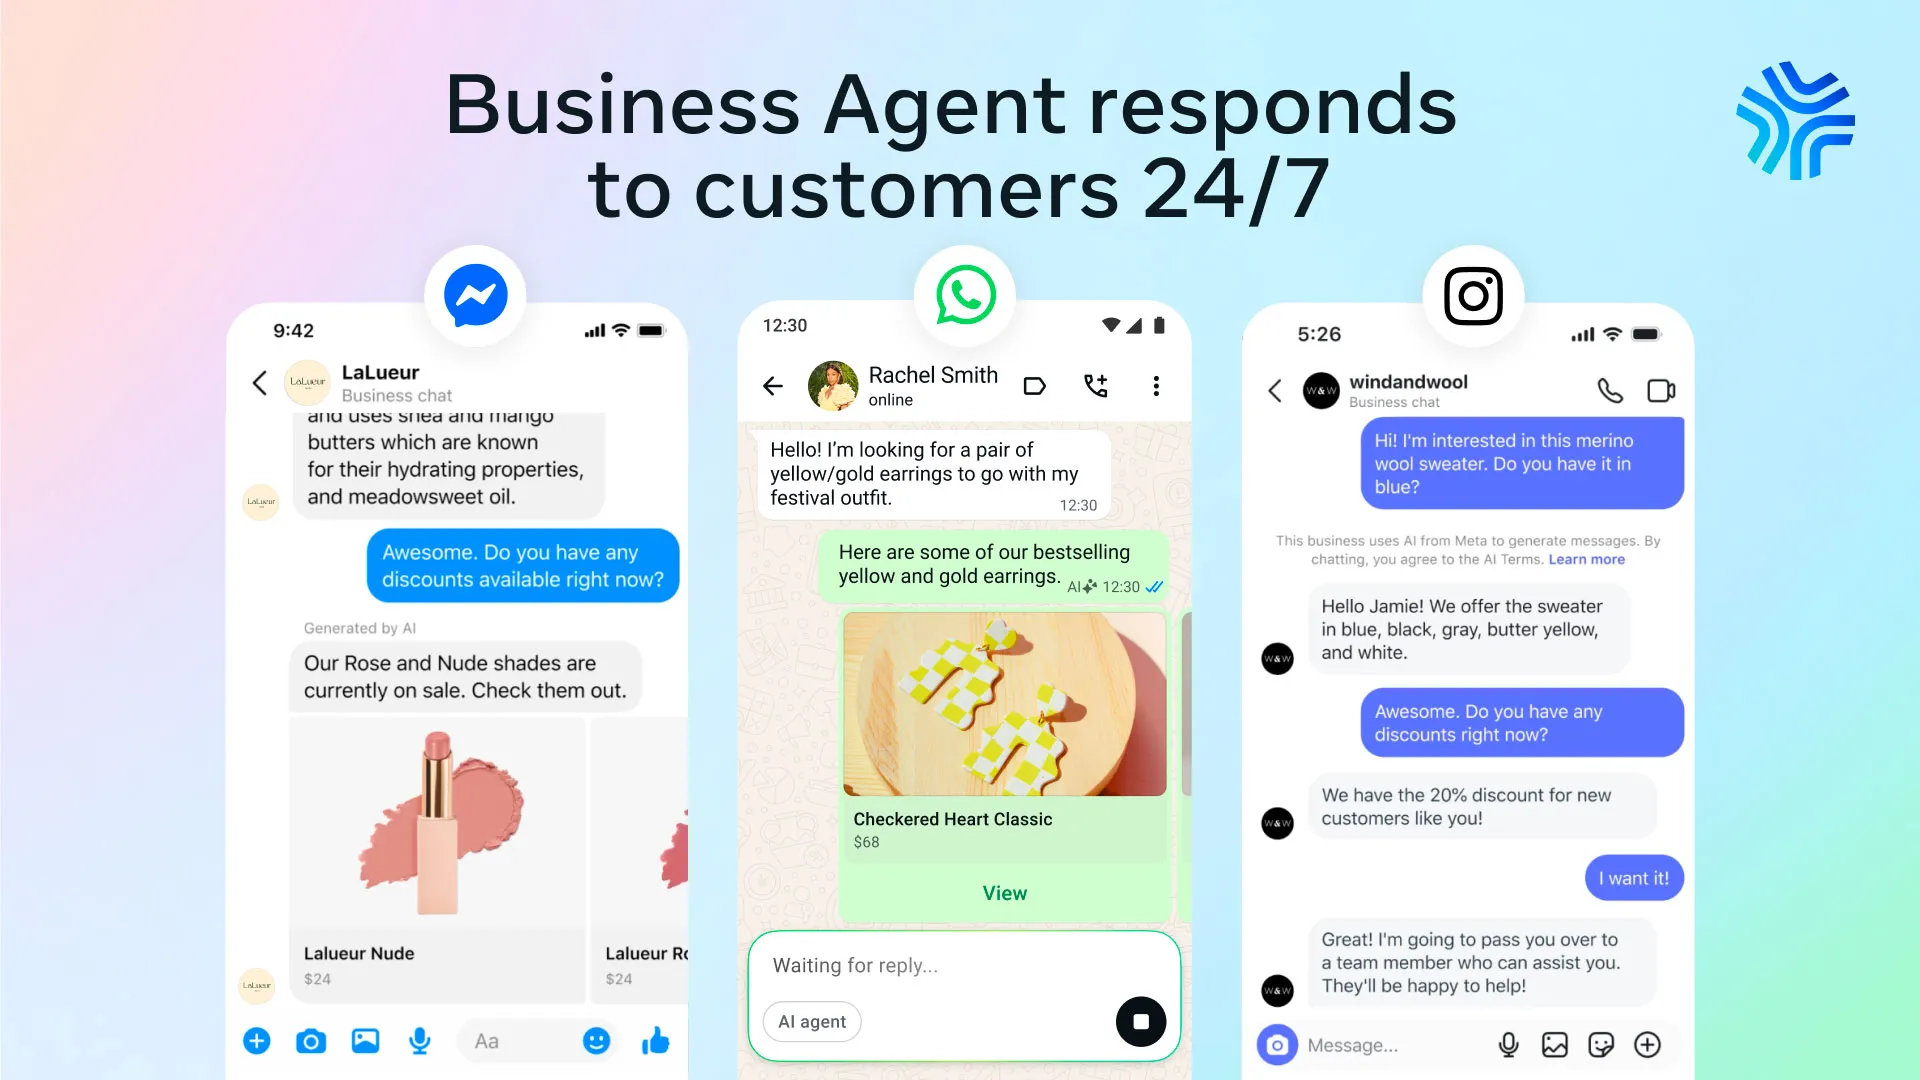
    Three phone chat screens beneath the headline "Business Agent responds to customers 24/7," with messaging app icons.
    Three mobile chat examples show customers asking businesses about products and discounts through Messenger, WhatsApp, and Instagram beneath a 24/7 agent headline.

    Key takeaways for marketers

    • Business messaging can cover several stages of the journey, from initial questions and lead qualification to order updates and purchases.
    • Meta is adding business discovery within WhatsApp search, creating another surface where accurate business information may influence visibility.
    • Product feeds can be browsed within WhatsApp or Instagram Direct, reducing the need to send every shopper to a website.
    • The system can support non-ecommerce goals, including appointment scheduling and other lead-generation tasks.
    • Reliable data, clear operating instructions and human supervision will be central to useful customer interactions.

    The website may no longer anchor every conversion

    A conventional digital funnel often directs an ad, social post or search result toward a landing page. Meta’s model compresses that journey: a person may discover a business, ask questions, browse products and complete a transaction within messaging.

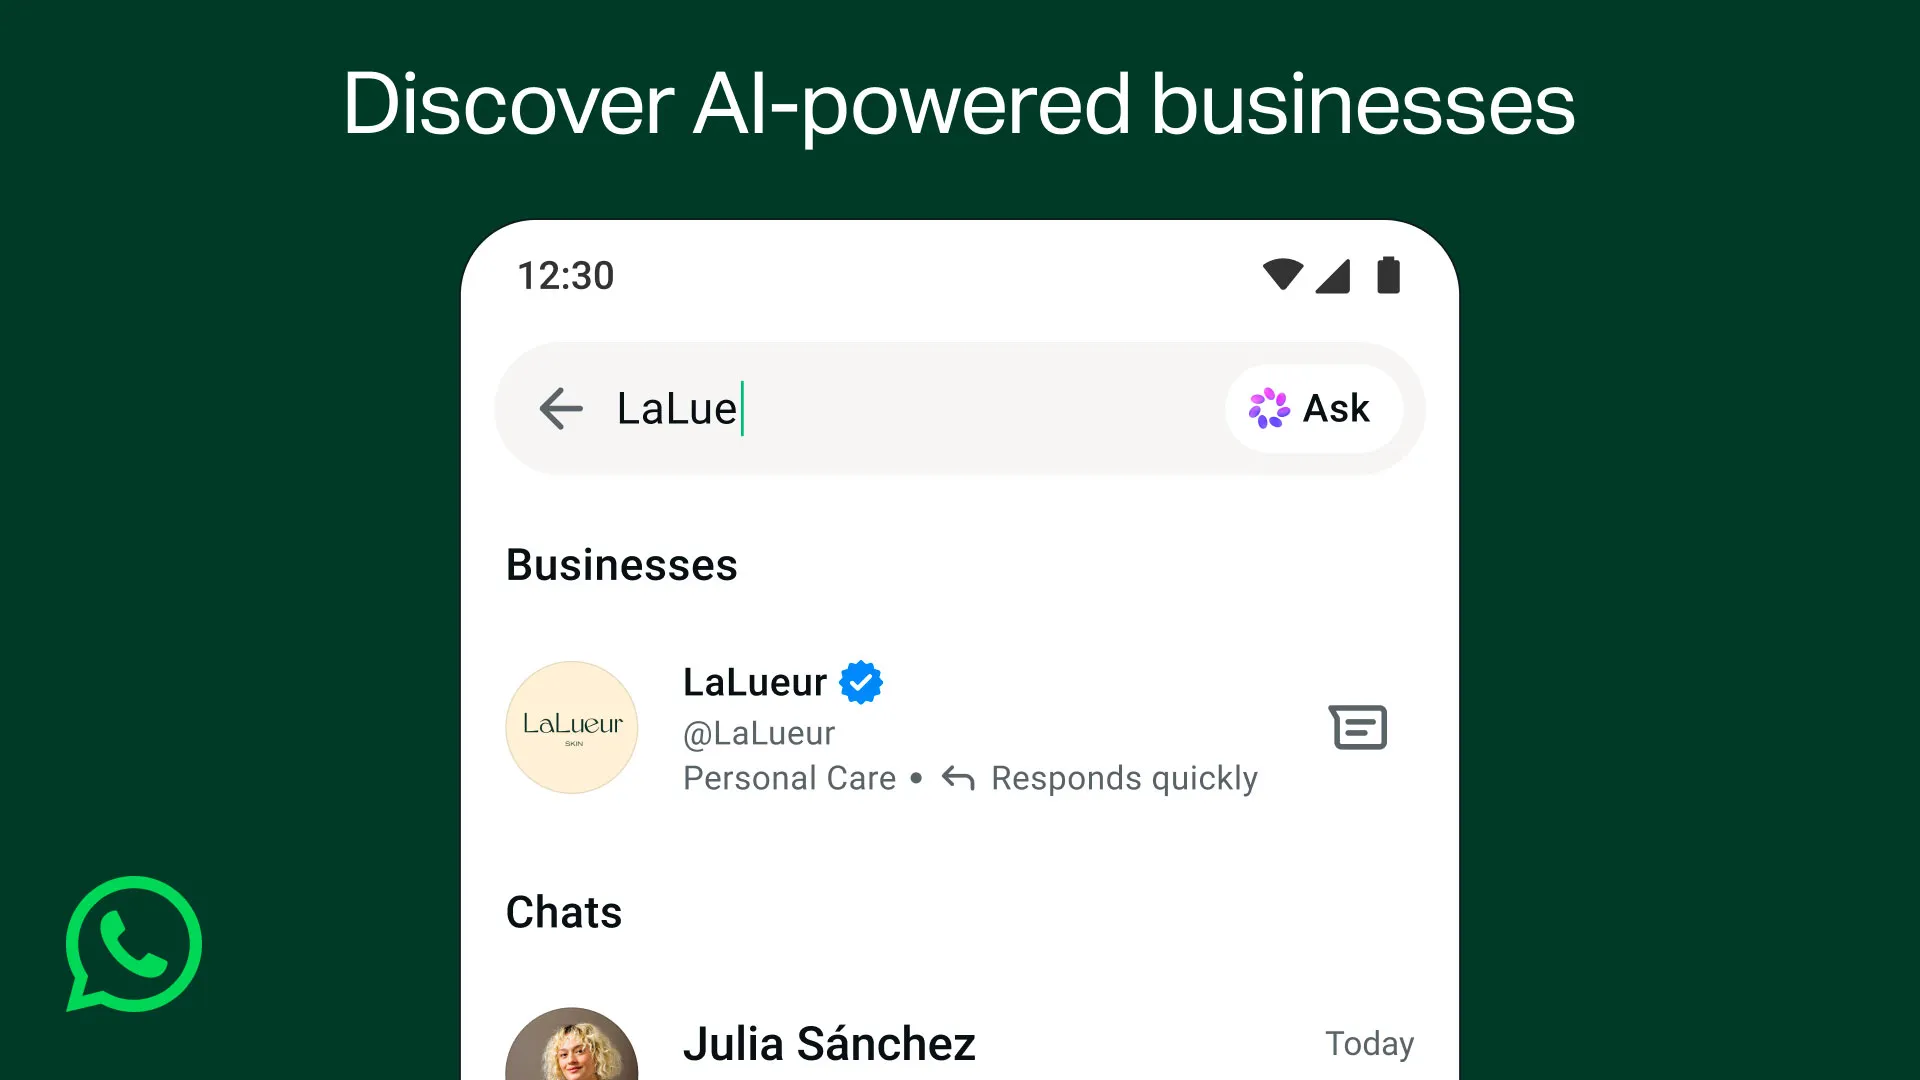
    Search Engine Land also says enhanced discovery features will allow people to find businesses through the WhatsApp search bar. A shared business can become a conversation with a tap when it uses the feature, while a shared restaurant can lead to a directions request within the chat.

    Phone mockup showing an AI-powered business search for LaLueur, with a business result and chat list.
    A phone interface under the heading Discover AI-powered businesses shows a search for LaLue, a verified LaLueur profile, and the start of a chat list.

    This does not make websites irrelevant. Sites can still provide detailed information and support other acquisition channels. The practical change is that website sessions may capture a smaller portion of the customer journey, making channel-level measurement less complete unless messaging interactions are incorporated into reporting.

    Data quality and escalation will determine the experience

    An agent cannot give dependable answers about availability, pricing or policies when its source information is incomplete or stale. Connecting an AI interface to operational systems therefore creates a data-management responsibility as well as a marketing opportunity.

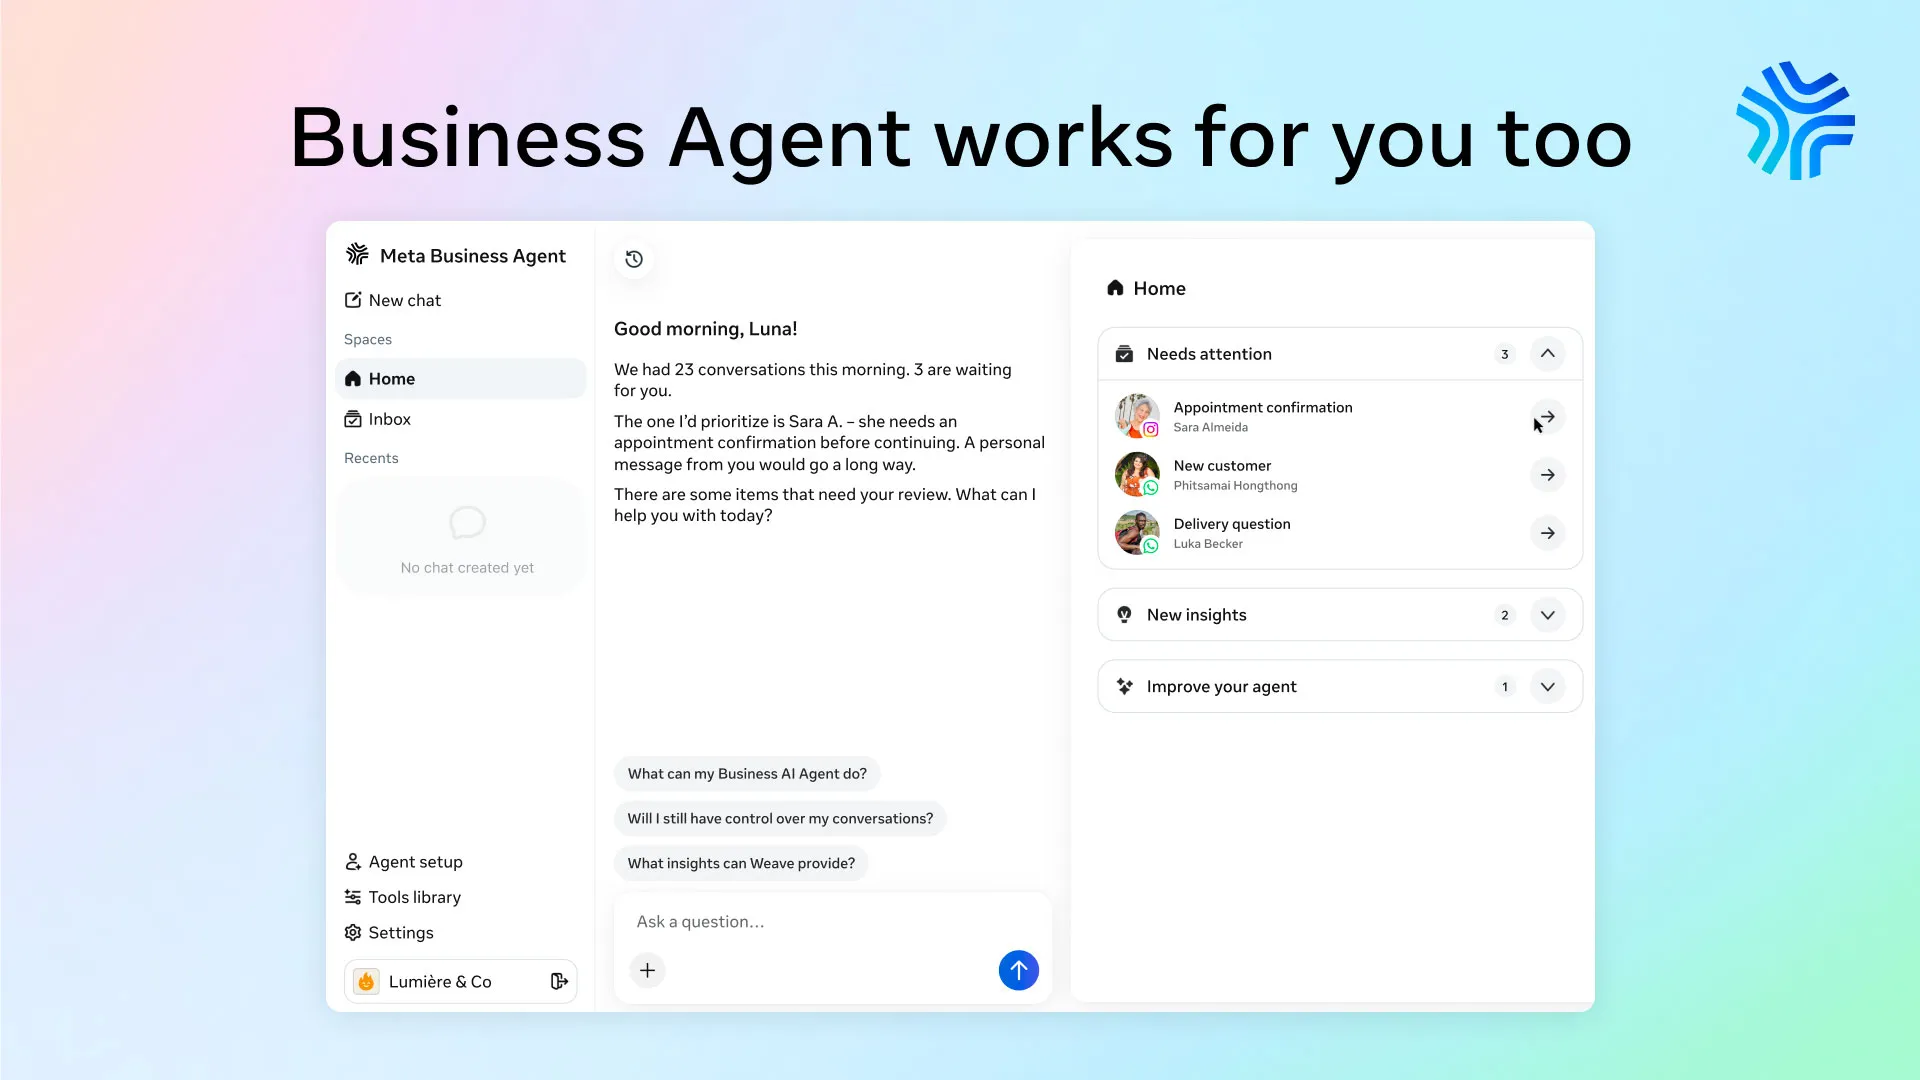
    Business Agent works for you too headline above a Meta Business Agent dashboard with chat and task panels.
    A Meta Business Agent interface shows navigation, a morning conversation summary, suggested questions, and a Home panel listing items that need attention.

    Meta’s control environment, as described in the source, lets a business monitor active conversations, transfer selected chats to a person and provide feedback based on those interactions. That human handoff is important for unusual requests, sensitive cases and conversations where the agent lacks enough information.

    Teams evaluating the product should define which information the agent may use, who owns updates to that information and which situations require escalation. They should also review whether its language reflects the brand accurately instead of assuming that initial instructions will cover every customer scenario.

    Futuristic web browser and analytics dashboard overlap amid neon data streams, illustrating the convergence of SEO, PPC and AI-driven search marketing.
    Organic visibility, paid media and artificial intelligence merge into one connected search ecosystem, where vivid data streams link a creative website with a powerful analytics dashboard.

    A practical way to assess the channel

    The strongest starting point is a narrow customer task with clear source data and an obvious success condition, such as answering routine product questions or scheduling an appointment. Marketers can then examine conversation quality, handoff frequency and the effect on the wider customer journey before expanding the agent’s responsibilities.

    The report does not provide detailed rollout, eligibility or performance information, so planning should remain conditional on what Meta makes available to each business. Even so, the strategic direction is clear: discovery and commerce are moving deeper into messaging, and marketing teams will need to treat those conversations as managed customer experiences rather than isolated chatbot exchanges.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • AI Agent Website Accessibility: A Practical Framework

    AI Agent Website Accessibility: A Practical Framework

    AI agent website accessibility is the ability of an automated assistant to discover a page, retrieve its contents, identify the relevant facts, and cite the business as the source. A site can work well for a human visitor yet fail this sequence when important information is hidden, dynamically rendered, ambiguous, or difficult to fetch.

    The practical goal is not to redesign every page for bots. It is to ensure that decision-critical facts survive the agent’s path from search to answer, especially when a prospective buyer asks about pricing, features, integrations, security, or compliance.

    Agent accessibility is a chain, not a page feature

    An agent typically starts with a task rather than a preferred website. It searches for relevant pages, fetches their contents, extracts an answer, and identifies sources it can cite. Failure at any stage can remove the vendor from the resulting answer even if the information appears somewhere on its site.

    This makes agent accessibility broader than visual presentation. A polished pricing grid offers little machine value if its values appear only after client-side code runs. A detailed PDF may contain the answer but make individual plan terms difficult to isolate. A contact-sales page may be accessible and accurate, but it cannot support a numeric answer that the company has chosen not to publish.

    This operational definition should not be confused with, or used as a replacement for, accessibility for people with disabilities. Human accessibility and agent accessibility address different users and failure modes, even though clear structure and understandable content can benefit both.

    Pricing exposes weaknesses that other product facts do not

    A geometric AI assistant faces layered website panels where pricing symbols are visible on one panel but obscured behind a modal and fragmented elements on others.

    A CrushPress.AI analysis conducted with Siteline founder David Kaufman examined three buyer tasks across 100 B2B products. The agent had to find each official vendor site without being given a starting URL, and each task was run five times to account for variable model behavior.

    Buyer taskFirst-party answer rateFirst-party citation share
    Pricing and features79%84%
    Integrations93%99%
    Security and compliance92%99%

    According to the analysis, pricing and feature research generated 77% of all third-party citations in the study. The contrast matters because pricing is both commercially sensitive and central to comparison. Integrations and security information can often be stated as straightforward facts; pricing may depend on plans, billing periods, usage, optional services, negotiated terms, or eligibility rules.

    Non-disclosure was only part of the problem. When a vendor did not publish a real price, 45% of pricing runs cited at least one third-party source. When a numeric public price was present, third-party sources still appeared in 18% of runs. Publishing information therefore improves the opportunity for first-party attribution, but does not guarantee that an agent can extract or trust it.

    Three failure gates determine whether the vendor remains the source

    Disclosure: is there a direct answer?

    The first gate is whether the company states the requested fact. If a price is unavailable, the page can still give an authoritative first-party answer by clearly saying that pricing is customized or requires sales contact. Vague packaging language creates a larger information gap, which third parties may fill without the vendor controlling the context.

    Extraction: can the fact be separated from the interface?

    The second gate is machine-readability. The source identified JavaScript interfaces, calculators, toggles, screenshots, PDFs, and ambiguous tables as potential obstacles. Its Zendesk example described a pricing grid that loaded for people but left the agent without usable plan data, leading to a 53-second process involving six tool calls before the agent turned to third-party blogs.

    The underlying editorial requirement is precision. A price needs an associated plan, unit, billing period, qualification rule, and any material condition. If those relationships are conveyed mainly through layout or interactive state, an agent may retrieve the values without understanding what they mean.

    Reachability: can the page be fetched consistently?

    The third gate is access. Fetch failures, blocking, rate limits, or unreachable pages appeared in 7% of all runs reported by CrushPress.AI, but their effect was disproportionate. Within pricing runs, an access error was associated with third-party fallback in 77% of cases, compared with 17% when no access error occurred.

    The study also compared high- and low-friction runs at the 90th and 10th percentiles. It reported a 4.4-fold cost difference, a 4.7-fold token difference, and a twofold time difference. Those costs are borne by the agent operator rather than the website, but they indicate how quickly retrieval friction can make an alternative source more attractive.

    A practical audit should follow the agent’s full journey

    A luminous AI agent travels through search, web document, fact extraction, and source-link stations along a pathway with three gateways and one blocked side route.

    Start with buyer questions, not page templates

    An audit can begin with the questions a buyer would delegate: What does the product cost? What is included? Which systems does it integrate with? Which security or compliance claims does the vendor make? Testing should begin from external discovery rather than a supplied page URL, mirroring the study’s method and revealing whether the intended first-party page can be found at all.

    Separate essential facts from interactive presentation

    Core plan and product facts should appear as clear page text that a fetcher can retrieve, even when the human experience also uses toggles or calculators. Labels should make relationships explicit: which plan a value belongs to, what the billing basis is, and which conditions change the amount. Complex pricing can remain complex, but its methodology should be explained in a form that can be quoted and cited without reconstructing the interface.

    Evaluate the answer and the citation separately

    A successful audit asks two different questions: did the agent produce an accurate answer, and did it support that answer with the vendor’s page? An answer sourced from a directory or editorial site may appear satisfactory while still showing that the vendor has lost control of attribution. In the reported pricing fallbacks, editorial pages accounted for 52.2% of fallback citations, directories for 45.7%, and ecosystem pages for 2.1%.

    Repeated testing is important because one successful retrieval does not establish reliable access. Results should be checked across multiple attempts, with special attention to blocked fetches, empty dynamic components, inconsistent plan labels, and facts that change when an interface control is activated.

    Key takeaways

    • Agent accessibility depends on discovery, retrieval, extraction, interpretation, and citation; a failure at any gate can push the answer to another source.
    • Pricing is a demanding test because disclosure choices and technical presentation can both prevent first-party attribution.
    • Publishing a number is insufficient when its plan, billing basis, conditions, or surrounding methodology remain ambiguous.
    • Access errors were uncommon in the reported study but sharply increased third-party fallback when they occurred.
    • Audits should test realistic buyer questions from search, repeat the attempts, and score answer accuracy separately from first-party citation.

    As agents assume more research and comparison work, the most resilient sites will treat machine access as part of publishing quality. The priority is a first-party record that remains understandable and citable after the interface itself is removed.

    References
  • Why AI Assistant Usage Follows Different Daily Rhythms

    Why AI Assistant Usage Follows Different Daily Rhythms

    AI assistants may be software, but the people using them still follow schedules. That creates patterns in when AI tools attract attention, answer questions, and influence decisions.

    Try Profound Blog offers one central observation: every AI assistant has a daily and weekly rhythm, but that rhythm varies by platform, region, and user. The source does not provide supporting measurements, so the useful takeaway is a framework for investigation rather than a universal timetable.

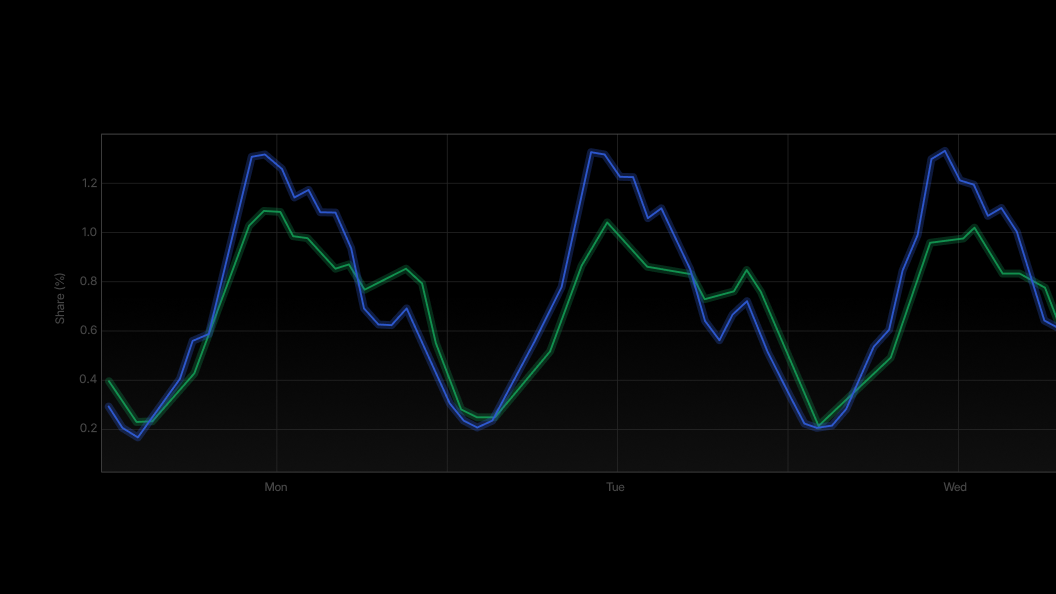
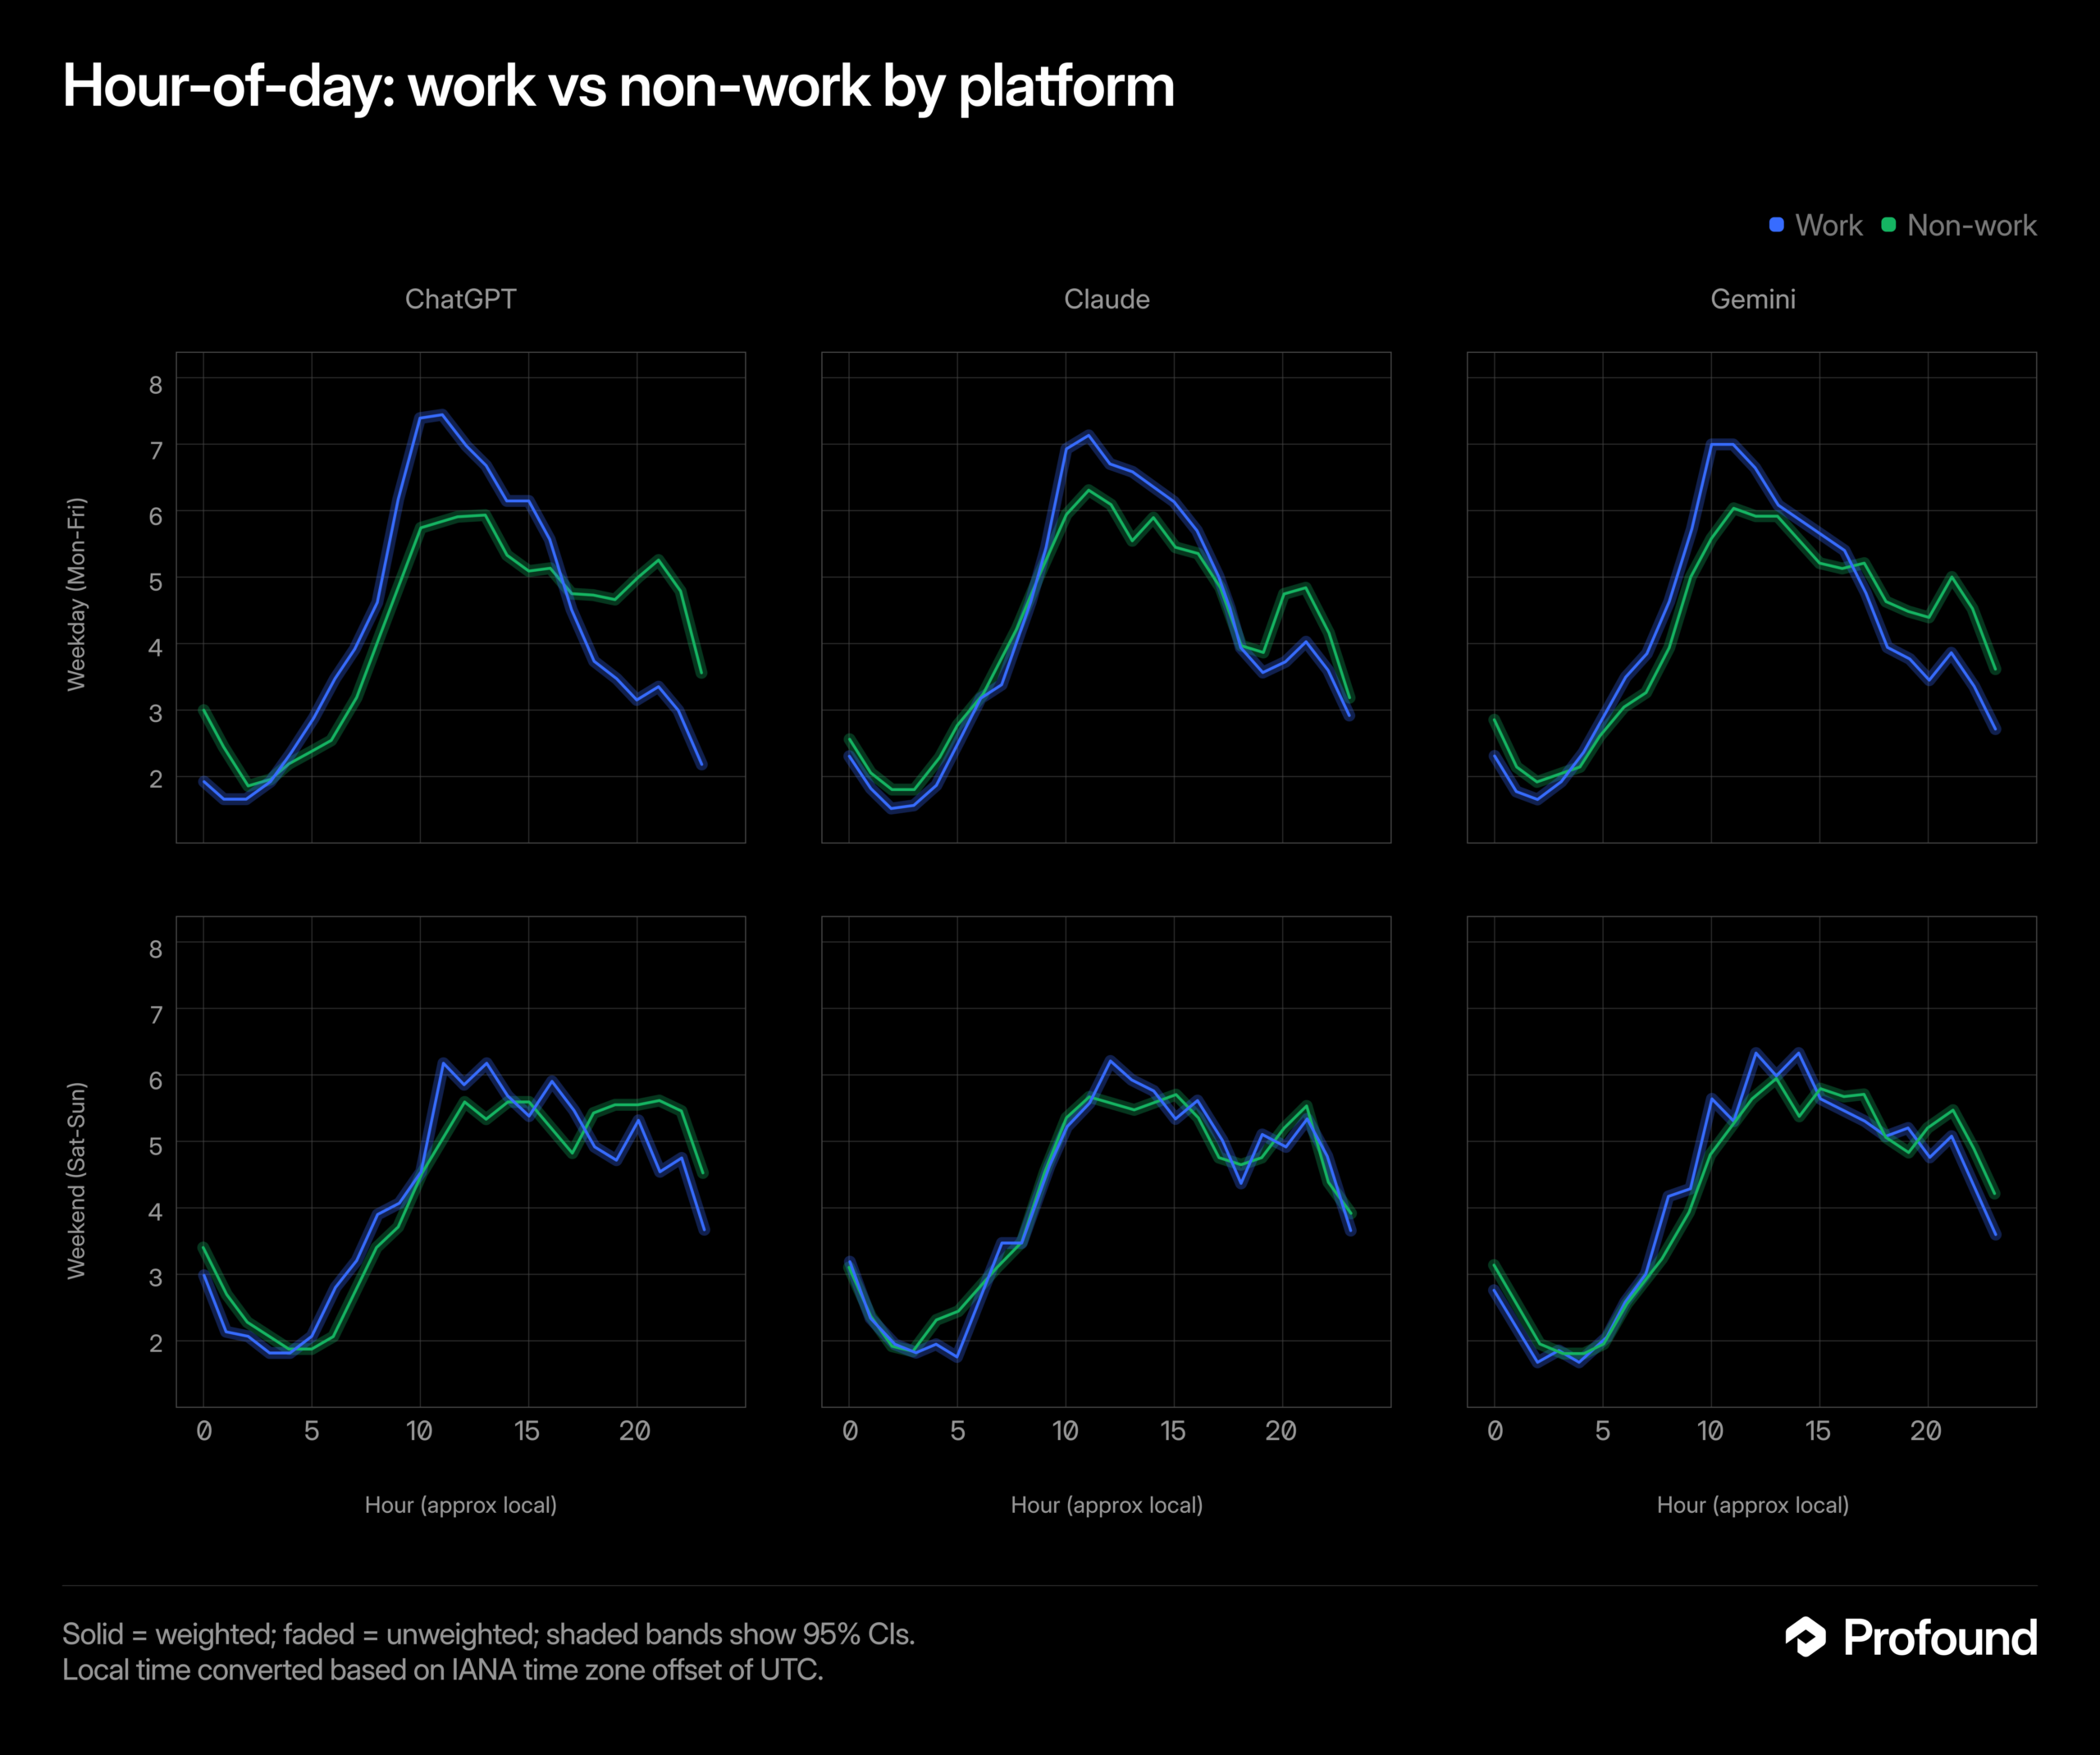
    Six line charts compare work and non-work hourly patterns for ChatGPT, Claude, and Gemini on weekdays and weekends.
    Blue work and green non-work lines show hourly patterns for ChatGPT, Claude, and Gemini, split into weekday and weekend rows, with most curves highest around late morning to afternoon.

    The rhythm belongs to usage, not the assistant

    An AI system does not begin a workday in the human sense. Any apparent schedule is more likely to reflect when people open a platform, what they use it for, and how it fits into their routines.

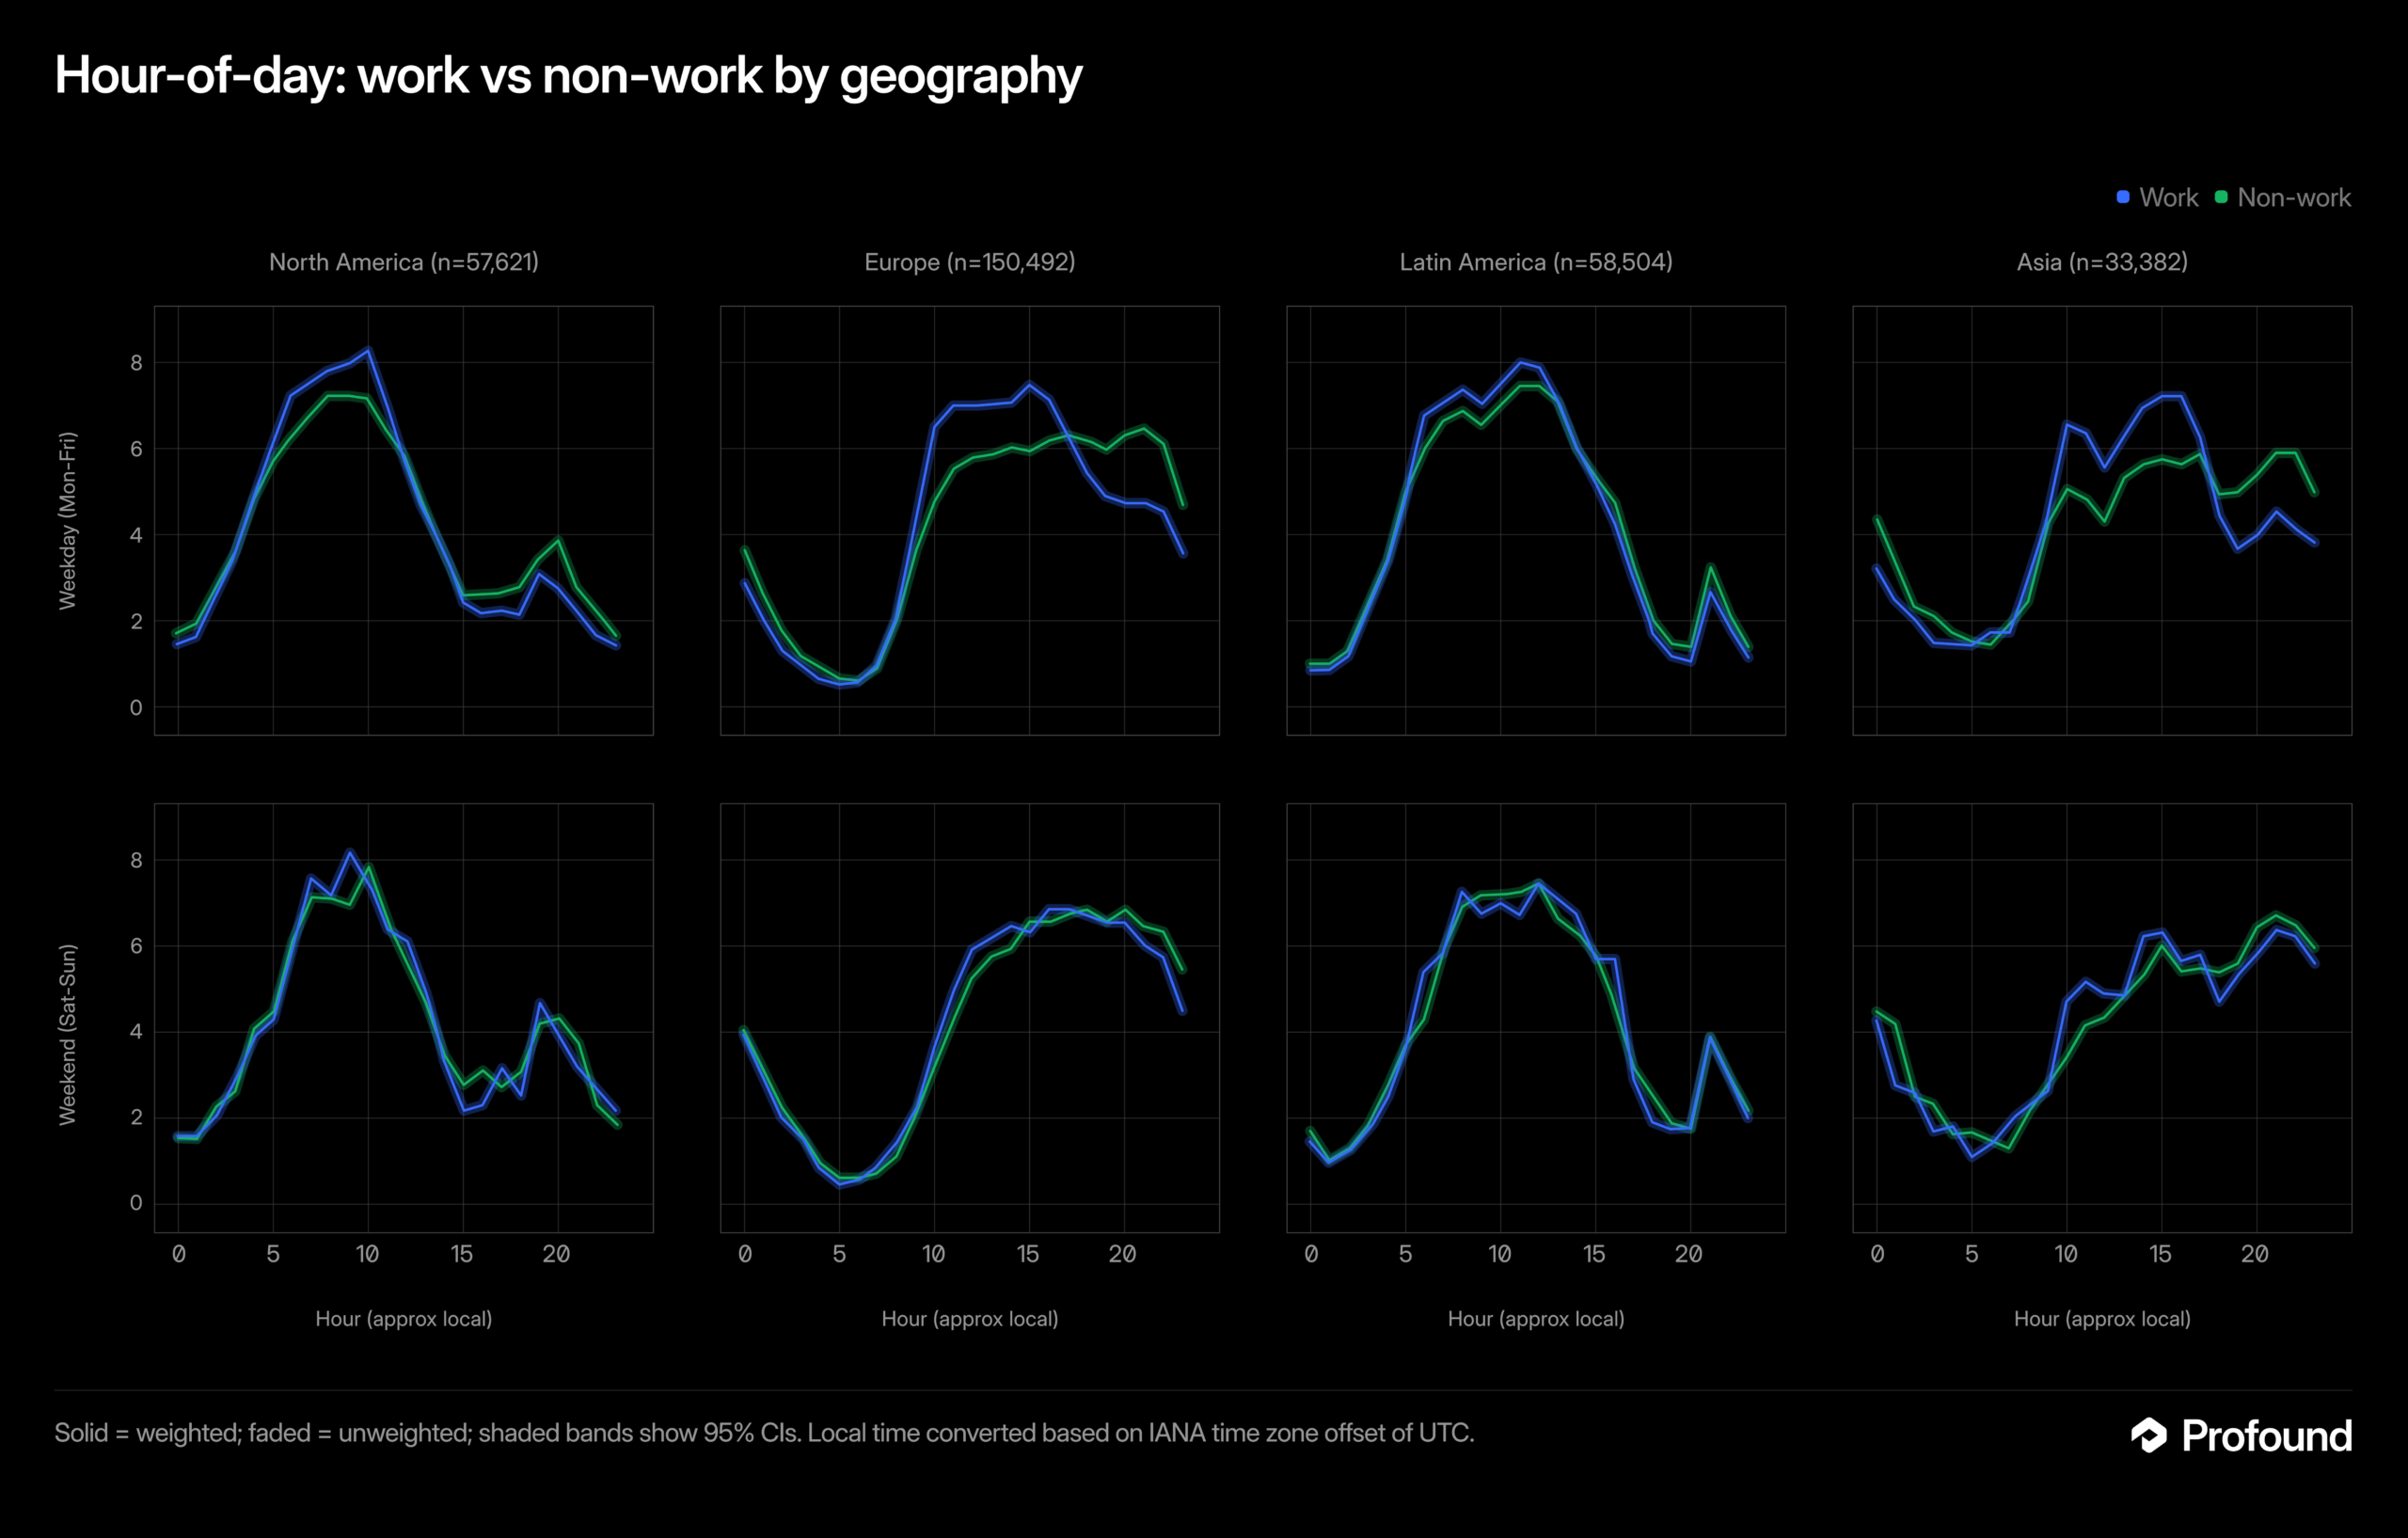
    Eight line charts compare hourly work and non-work patterns across four regions on weekdays and weekends.
    Blue work and green non-work lines trace hour-of-day patterns for North America, Europe, Latin America and Asia, split into weekday and weekend rows.

    A tool associated with professional tasks may see a different pattern from one used for personal questions. The distinction matters because a broad label such as “AI traffic” can hide meaningful differences among audiences and use cases.

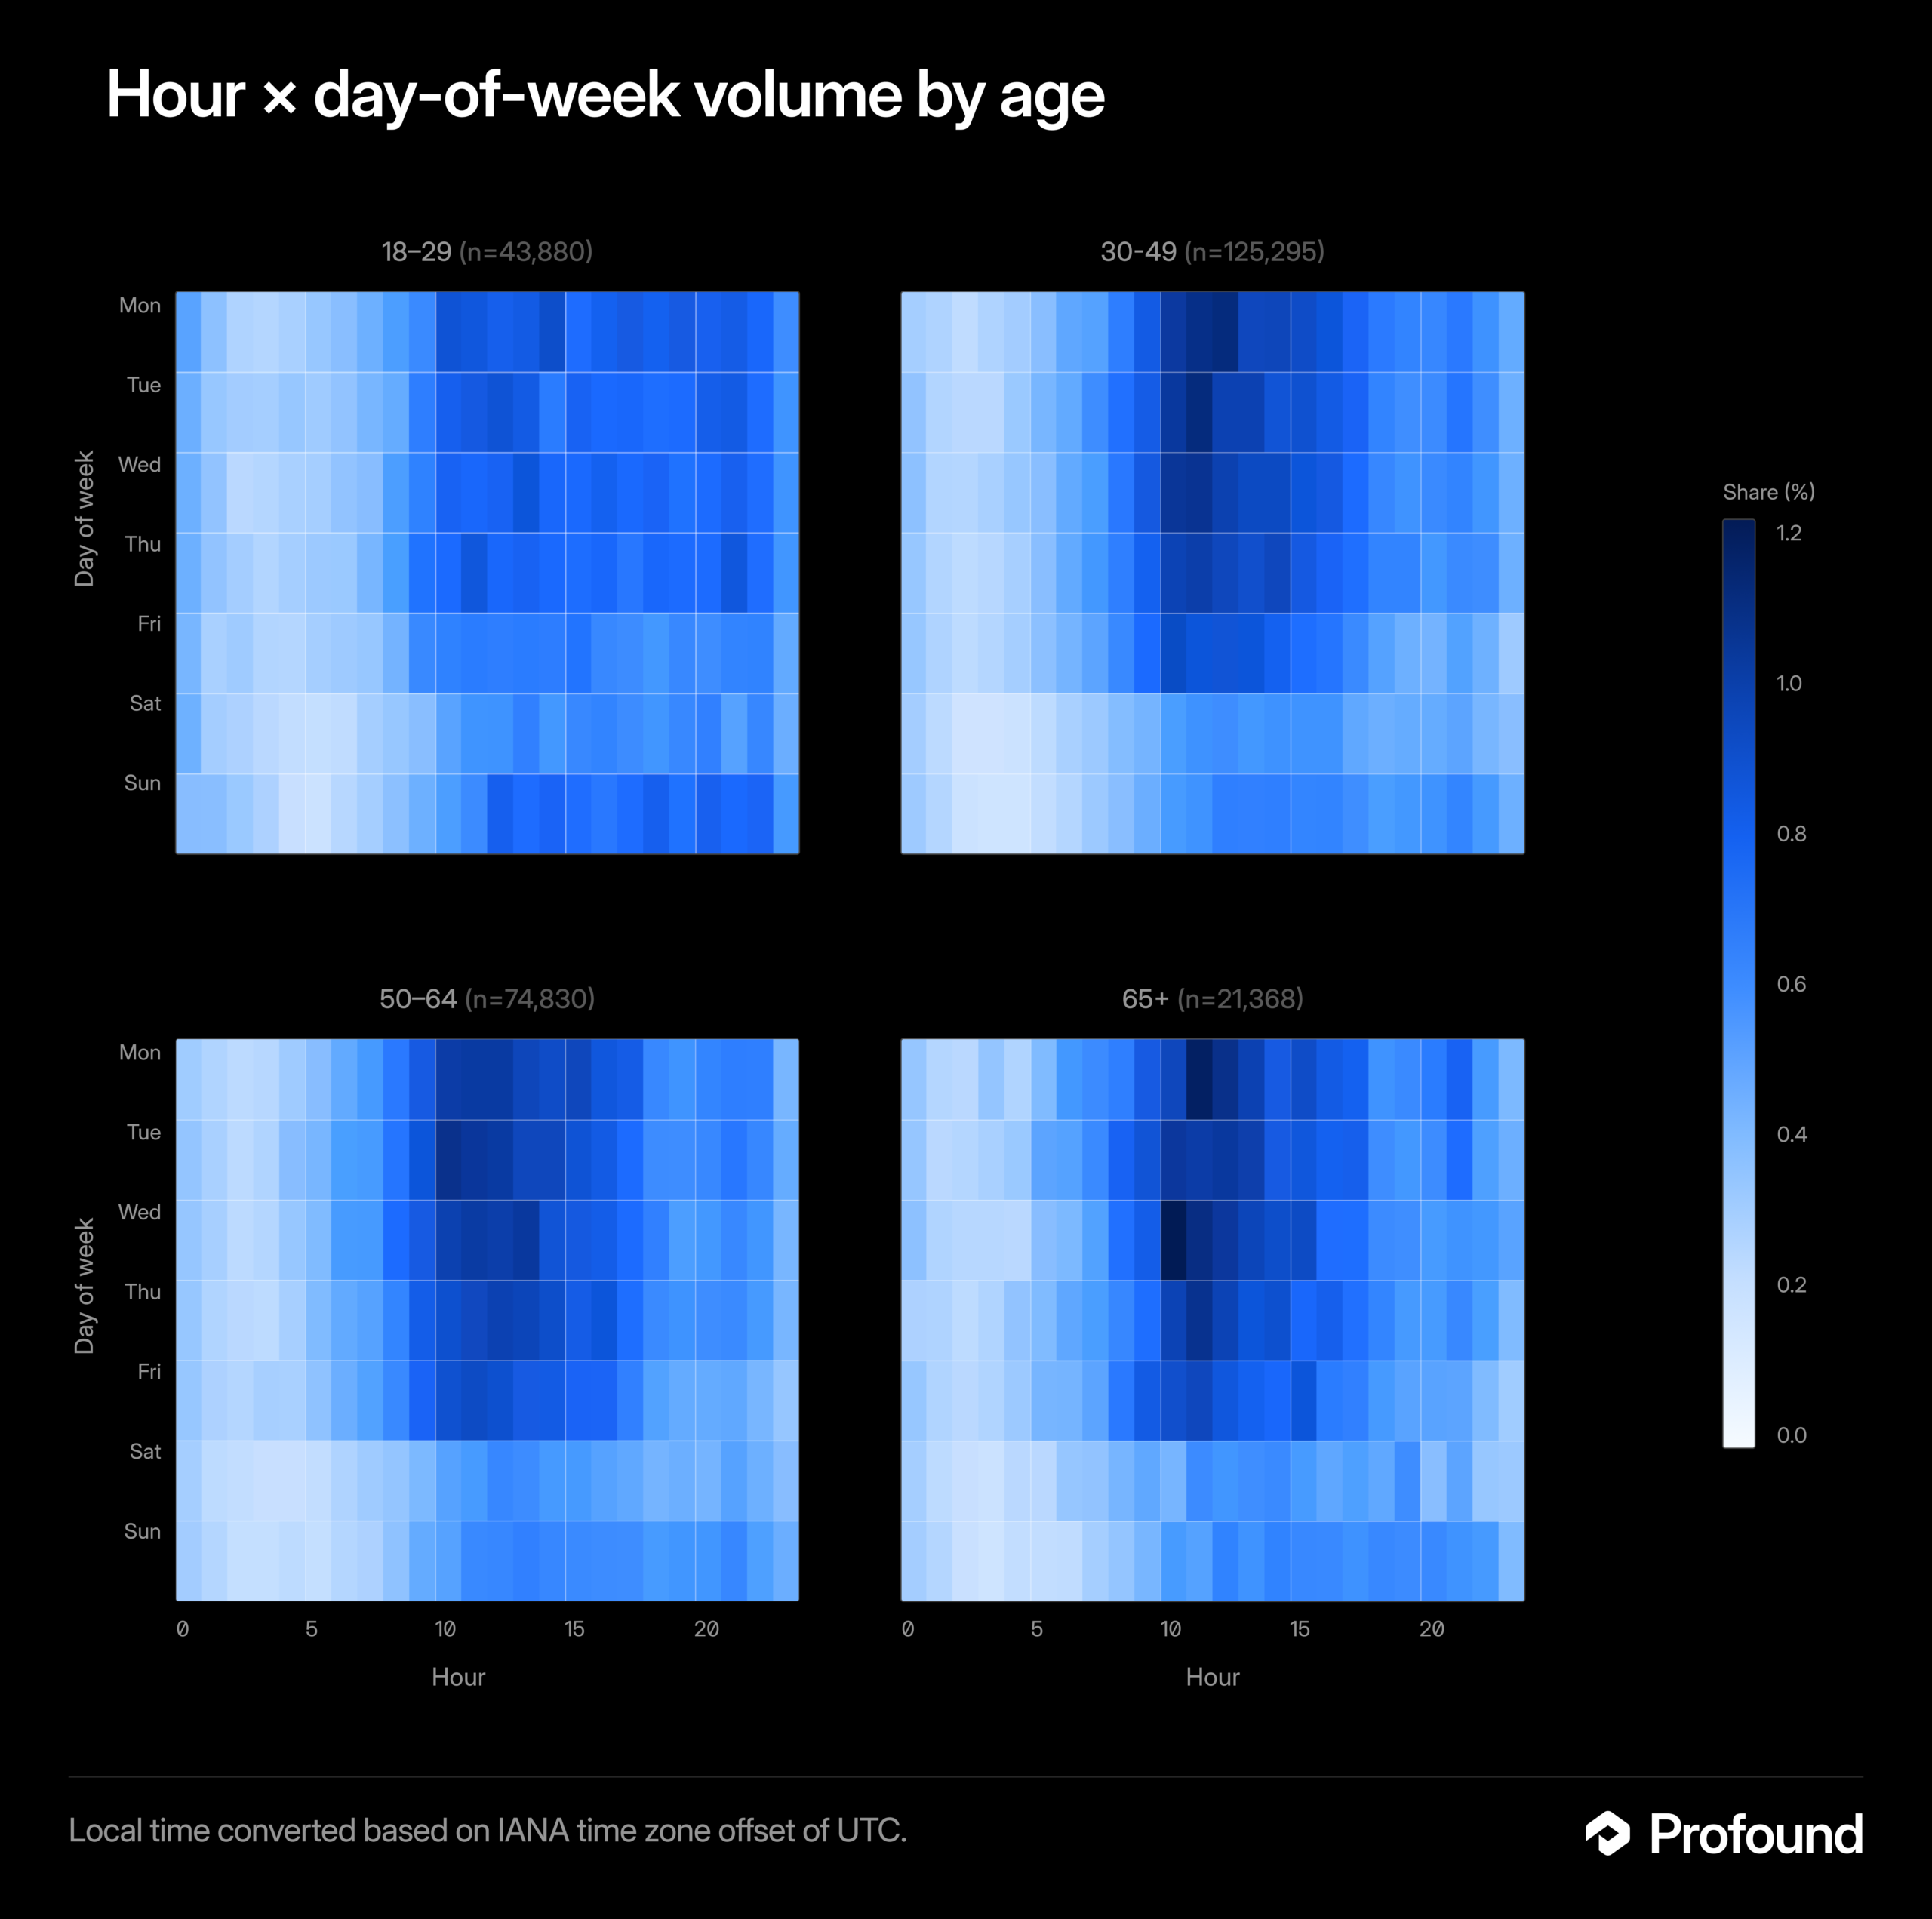
    Four blue heatmaps compare hourly, weekday volume shares across age groups from 18-29 to 65+.
    Four heatmaps plot share by hour and day of week for ages 18-29, 30-49, 50-64 and 65+, with the darkest weekday bands around late morning.

    Why one schedule cannot describe every audience

    The source specifically cautions that timing is not consistent across platforms, regions, or users. Each dimension can change how an observed pattern should be interpreted:

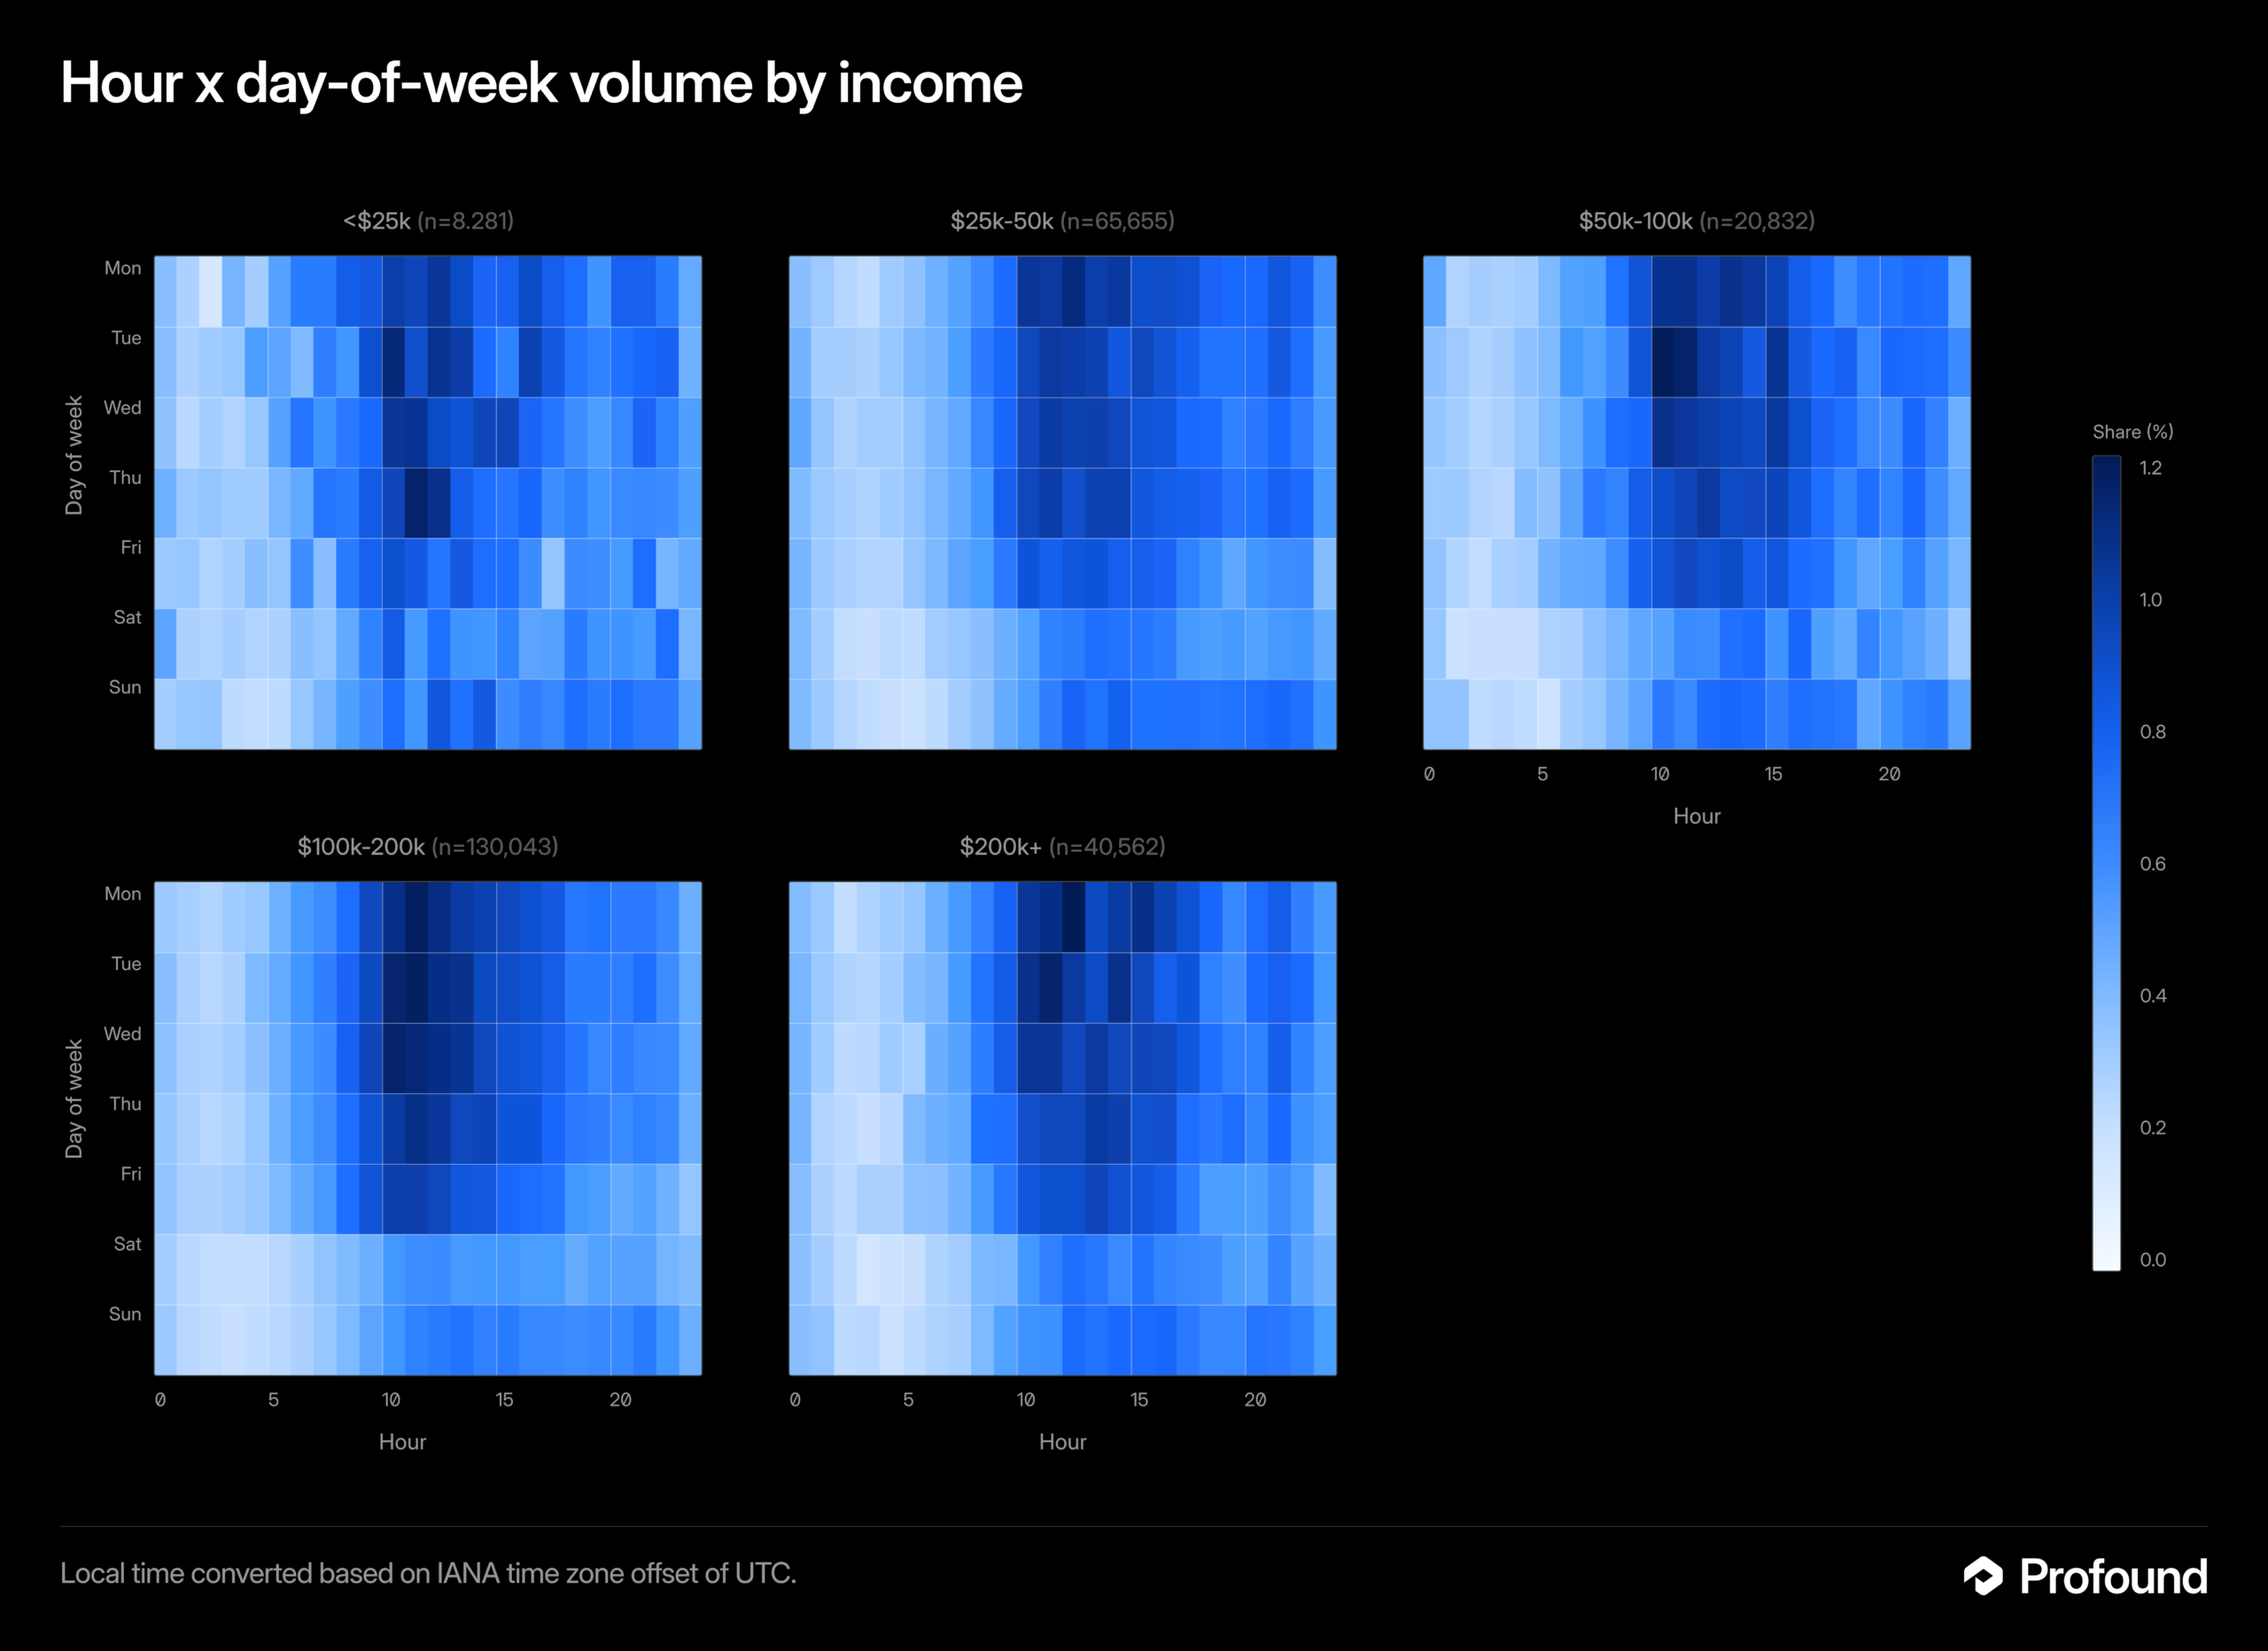
    Five heatmaps compare hourly, weekday volume shares across income brackets from under $25k to $200k+.
    The five blue heatmaps show share percentages by hour and day of week for income groups, with many darker cells appearing from late morning through afternoon.
    • Platform: Different products can serve different purposes and attract different usage habits.
    • Region: Local time, working patterns, and audience location can shift periods of activity.
    • User: Individual needs determine whether an assistant is used for work, study, research, planning, or another task.

    These variables make a single global “best time” an unreliable assumption. A pattern found in one segment should not automatically be applied to another.

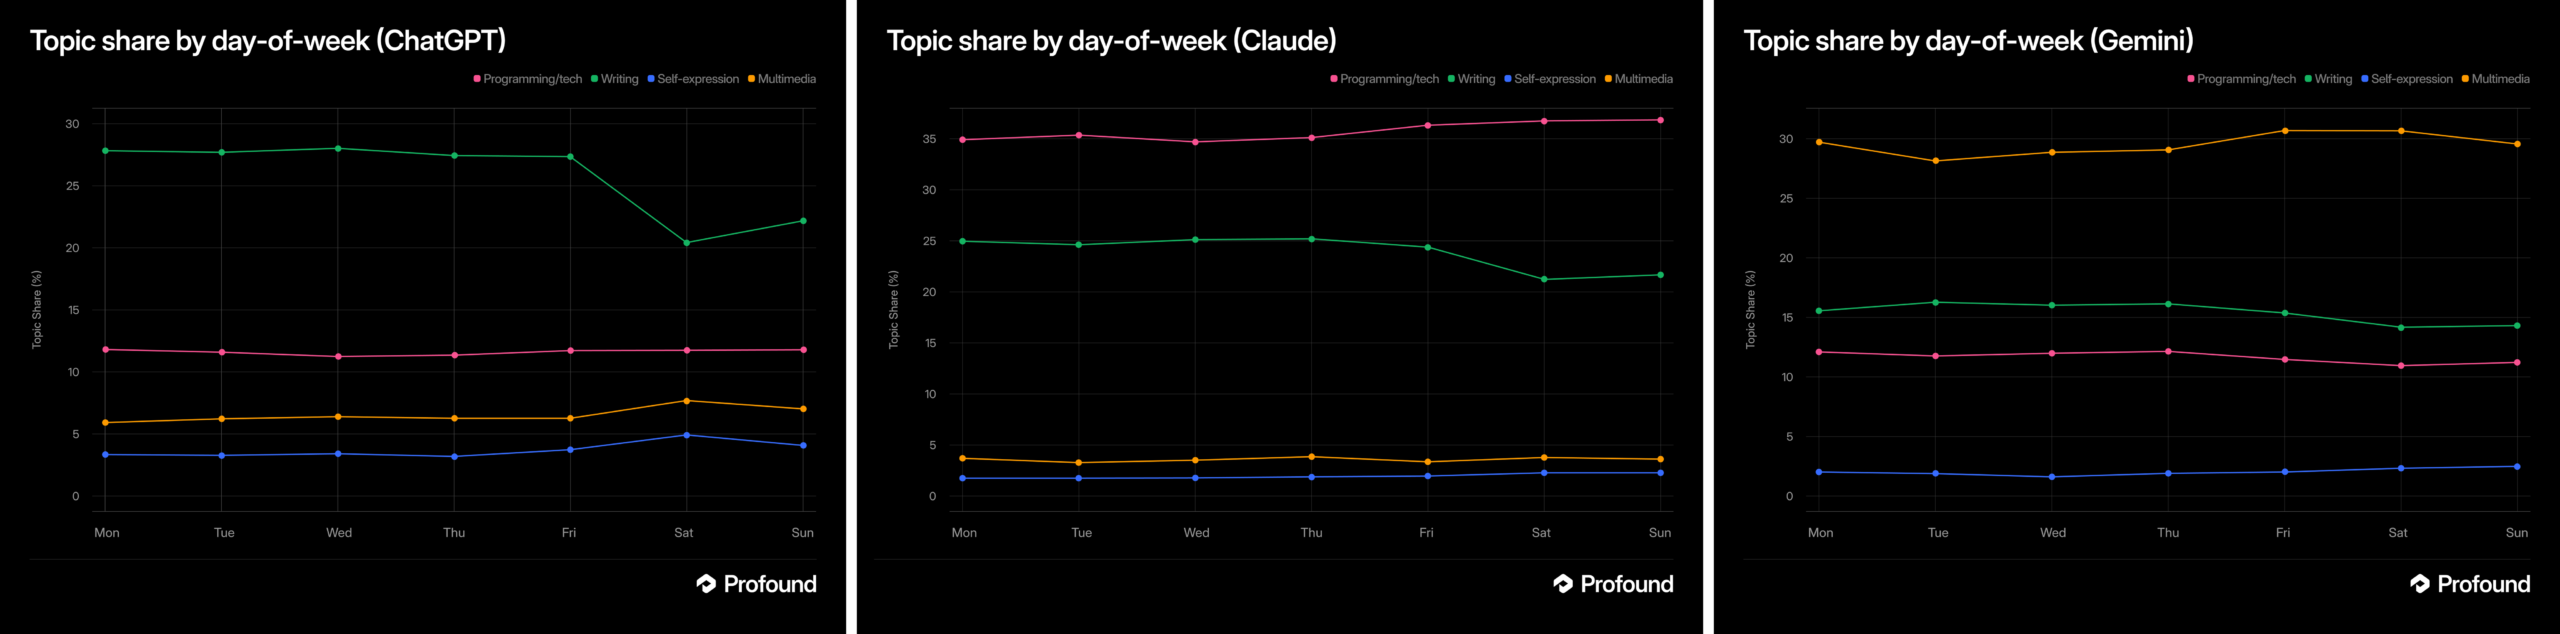
    Three line charts compare topic share by weekday for ChatGPT, Claude, and Gemini across four categories.
    Side-by-side weekday charts show writing highest for ChatGPT, programming/tech highest for Claude, and multimedia highest for Gemini, with weekend shifts.

    Key takeaways

    • AI assistant activity can form recurring daily and weekly patterns.
    • Those patterns may differ across platforms, regions, and individual users.
    • Timing should be evaluated within a defined audience and use case.
    • The source states the principle but does not supply data for specific hours or days.

    How teams can evaluate timing responsibly

    For marketers, publishers, and product teams, the practical response is to examine their own evidence. Analysis should begin with a clear question: which platform, audience, region, and outcome are being measured?

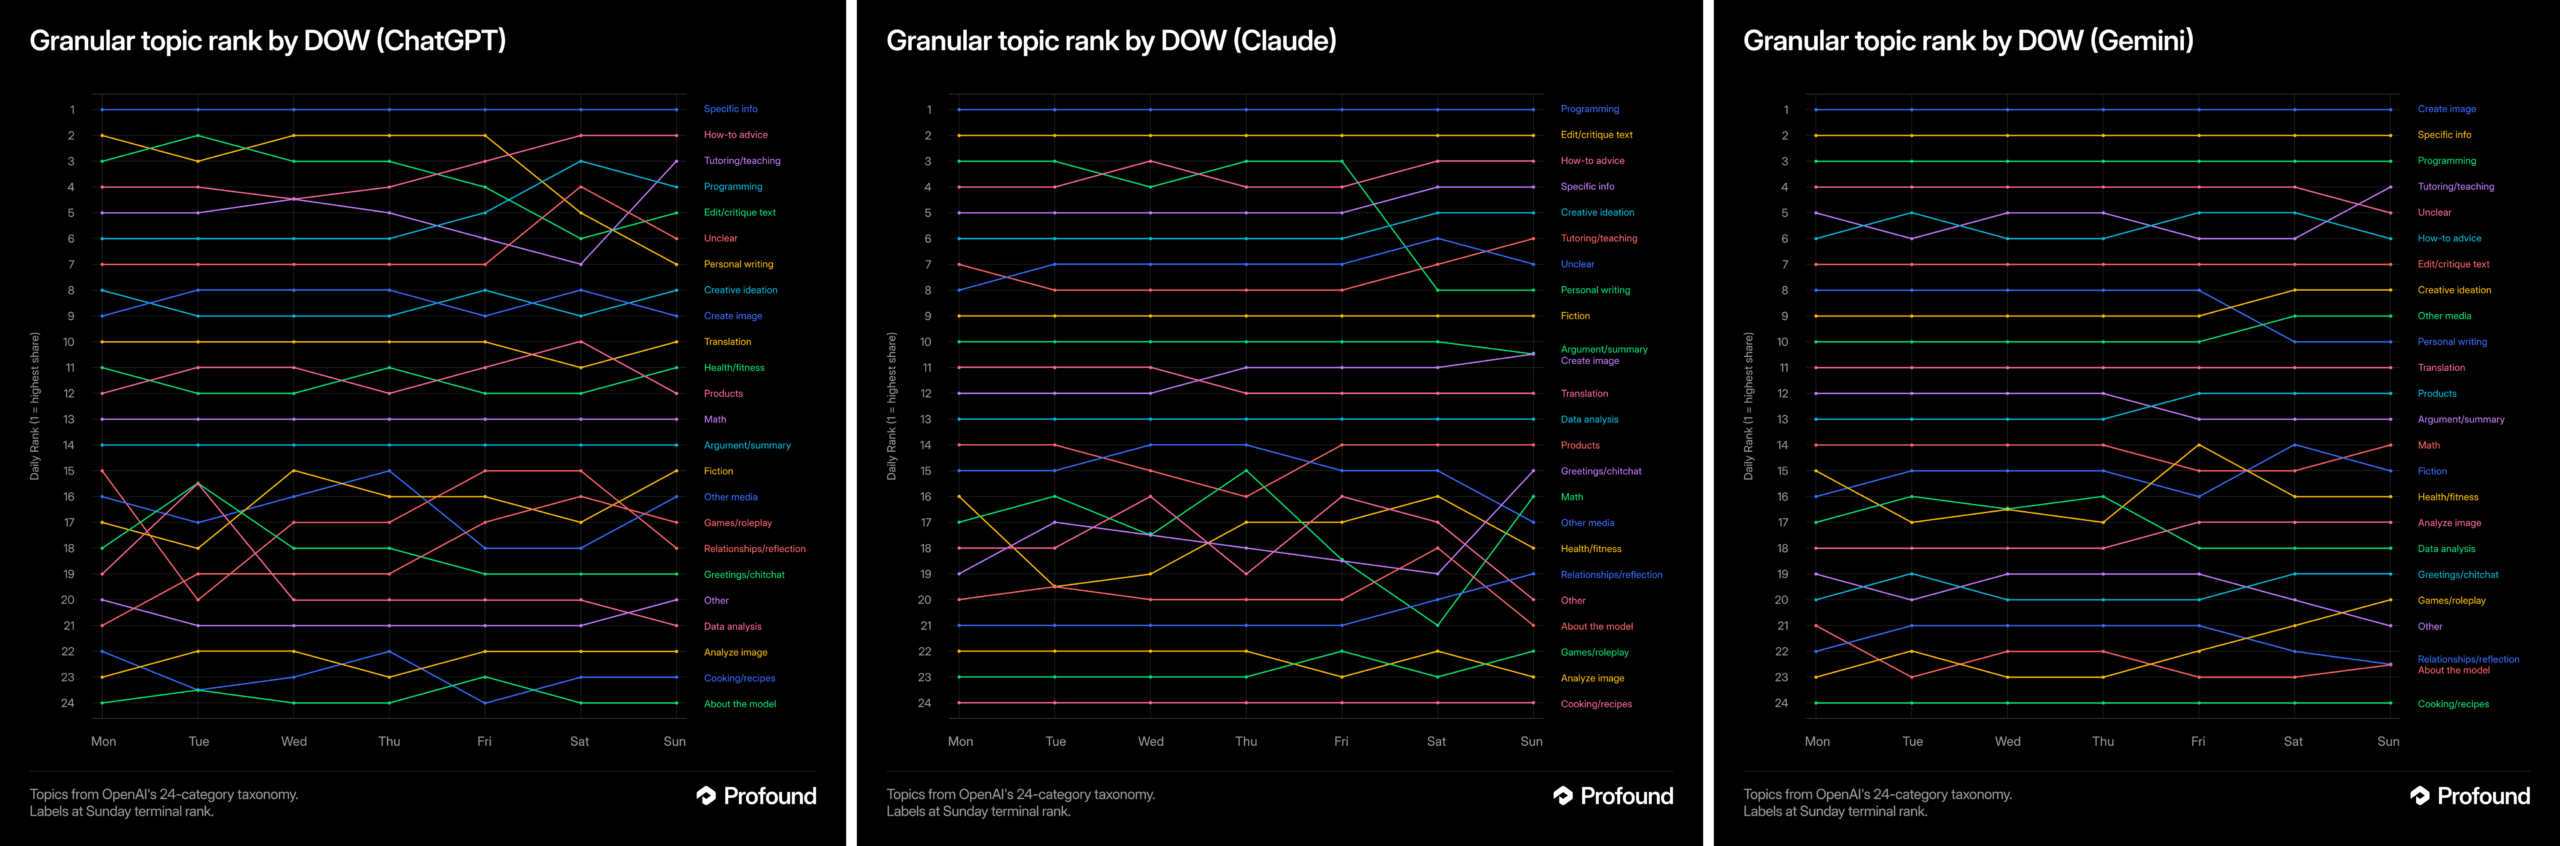
    Three dark line charts compare 24 topic rankings by day of week for ChatGPT, Claude, and Gemini.
    Side-by-side charts titled "Granular topic rank by DOW" trace colored topic rankings from Monday through Sunday for ChatGPT, Claude, and Gemini.

    Teams can then compare consistent time periods, use the relevant local time zone, and separate audience segments where possible. They should also distinguish between activity and impact. A busy period does not necessarily produce the most valuable visits, recommendations, conversions, or customer outcomes.

    Any apparent rhythm should be treated as a working pattern rather than a permanent rule. User behavior, product design, and the mix of use cases can change, so conclusions need periodic review.

    What the source does not establish

    Try Profound Blog does not identify peak hours, preferred weekdays, regional differences, or platform-specific results in the supplied material. It also does not describe a study or methodology. Claims about exact schedules would therefore go beyond the available evidence.

    The defensible conclusion is narrower: AI usage has timing patterns, and context determines what those patterns mean. Organizations that want actionable answers will need to measure the audiences and outcomes that matter to them.


    Inspired by this post on Try Profound Blog.


    crushpress.ai community screenshot
  • GPT-5.6 in Profound: Tiers and Workflow Implications

    GPT-5.6 in Profound: Tiers and Workflow Implications

    Profound has announced support for GPT-5.6, giving its users access to the model family through the platform’s existing AI workflows. The announcement emphasizes a choice among Sol, Terra, and Luna tiers rather than presenting GPT-5.6 as a single configuration for every task.

    The practical significance is workload matching: teams can consider different tiers for demanding reasoning and production-scale activity while evaluating whether the reported gains in capability, reliability, and efficiency hold for their own use cases.

    What GPT-5.6 support changes in Profound

    According to Profound’s announcement, GPT-5.6 is now available directly within the workflows supported by the platform. Profound characterizes it as OpenAI’s newest flagship model family and identifies advanced AI performance as the central reason for adding it.

    This is an integration announcement, not an independent benchmark. The source reports improvements in capability, reliability, and efficiency, but it does not provide test results, pricing, latency figures, context limits, or comparisons with earlier models. Those omissions matter when deciding whether the new option should replace an existing model or serve only selected workloads.

    Sol, Terra, and Luna introduce a tier-selection decision

    Profound says its GPT-5.6 support spans the Sol, Terra, and Luna tiers. It presents this range as a way to cover work extending from frontier reasoning to high-throughput production workloads, although the announcement does not assign detailed specifications or a fixed use case to each named tier.

    For teams, the important shift is therefore operational: model selection can be treated as a workload decision. A demanding research or reasoning task may call for a different balance than a repeatable, high-volume process. Without tier-level measurements in the source, however, buyers should avoid assuming which option will deliver the best quality, speed, or cost for a particular application.

    The workflows Profound expects to benefit

    Abstract task objects travel along branching illuminated paths through three differently scaled processing chambers before converging into organized outputs.

    The announcement highlights four areas: agentic workflows, coding, research, and enterprise knowledge work. These categories share a need for dependable handling of instructions and context, but they create different evaluation requirements.

    • Agentic workflows: Evaluate whether the selected tier follows multi-step instructions consistently and handles failure conditions appropriately.
    • Coding: Test against the languages, repositories, review practices, and validation tools used by the organization.
    • Research: Check source handling, factual accuracy, uncertainty, and the usefulness of generated synthesis.
    • Enterprise knowledge work: Examine performance with internal terminology, access controls, document retrieval, and required approval processes.

    These checks are general implementation practices rather than performance claims about GPT-5.6. Profound’s post identifies the target workflow categories but does not publish evidence for individual tasks within them.

    Key takeaways

    • Profound reports that GPT-5.6 is supported within its AI workflows.
    • The integration includes the Sol, Terra, and Luna tiers.
    • Profound positions the model family for uses ranging from advanced reasoning to high-throughput production.
    • Agentic systems, coding, research, and enterprise knowledge work are the principal use cases named in the announcement.
    • The post reports capability, reliability, and efficiency improvements but supplies no benchmarks or tier-level specifications.

    How teams can evaluate the integration responsibly

    A sensible evaluation begins with representative tasks rather than a broad platform-wide switch. Teams can define the required output quality, acceptable error patterns, response-time needs, and operating constraints for each workflow, then compare the available tiers under the same conditions.

    1. Select a small set of real tasks from each intended workflow.
    2. Define pass criteria before comparing model outputs.
    3. Record quality, consistency, failure modes, and human-review effort.
    4. Compare tiers without presuming that the same option will suit every workload.
    5. Expand adoption only where the results support Profound’s reported benefits.

    GPT-5.6 support broadens the choices available inside Profound, but the integration’s value will ultimately depend on how clearly organizations match those choices to their own work. More detailed tier documentation and workload-specific evidence would make that decision easier.

    References
  • AI Shopping Visibility: A Retailer’s Operating Framework

    AI Shopping Visibility: A Retailer’s Operating Framework

    AI shopping visibility is becoming a distinct retail discipline: the goal is not merely to rank a page, but to make a product understandable, credible and recommendable when an answer engine helps someone choose what to buy.

    The two supplied articles frame this change through holiday shopping and Profound’s evolving technology. Taken together, they point toward a practical operating model for retailers: identify the questions that shape a purchase, strengthen the product evidence available to answer engines, monitor the resulting recommendations and act before seasonal demand peaks.

    The AI shelf sits upstream of the product page

    Both articles argue that answer engines can influence discovery, comparison and purchase decisions before a shopper reaches a retailer’s website. Their shared concern is funnel compression: an AI-generated response may narrow a broad category to a shortlist, so the retailer enters the conventional website journey only after some options have already been filtered out.

    This makes the “AI shelf” a useful strategic concept. It is not a literal results page or a single ranking. It is the changing set of products, brands, retailers and supporting sources that an answer engine mentions or cites in response to a shopping question. Visibility can therefore vary with the prompt, use case, audience constraint and stage of consideration.

    Traditional search optimization remains relevant because clear, accessible product information can support discovery in multiple channels. The broader requirement, however, is recommendation readiness. Retail teams need to ask whether an answer engine can determine what a product is, whom it suits, why it differs and whether the supporting information is sufficiently clear to use in an answer.

    Holiday behavior and agent infrastructure reveal different layers

    A cutaway illustration shows seasonal shoppers above a connected layer of product, inventory and AI agent signals.

    The holiday-focused article concentrates on customer behavior. It says its report draws on Christmas 2025 shopper behavior examined through Profound’s AI visibility lens, with the aim of helping retailers prepare before the 2026 holiday season. Its central recommendation is to optimize early enough to appear in AI-assisted gifting research, product comparisons and buying decisions.

    The MCP-focused article reaches a similar commercial conclusion from a technology angle. It reports that Profound’s MCP evolution connects agents with a knowledge graph and adds 15 capabilities designed around marketing workflows. That suggests AI visibility work may increasingly be handled as an ongoing system of research, analysis and action rather than as a periodic content exercise.

    The distinction matters. One article describes the demand-side problem: shoppers may use answer engines while forming preferences. The other describes an emerging supply-side response: marketing agents connected to structured organizational knowledge and specialized capabilities. Together, they imply that retailers need both shopper insight and operational infrastructure.

    The supplied articles do not disclose prompt samples, product-level findings, measurement methodology or performance outcomes. Their references to real shopper behavior should therefore be treated as source-reported framing, not as independently verifiable evidence that a particular optimization tactic will increase sales.
    Key takeaways

    • Manage AI visibility around shopping questions and recommendation contexts, not only brand or category keywords.
    • Separate being mentioned from being cited, accurately represented, shortlisted and ultimately selected; each reflects a different outcome.
    • Coordinate product, content, merchandising, search and analytics work because no single page or team controls the full AI-assisted journey.
    • Begin seasonal analysis before merchandising decisions and content production are locked, especially when the objective is holiday visibility.
    • Treat visibility-platform findings as diagnostic signals and validate commercial value with retailer-owned behavioral and conversion data.

    Turn AI visibility into a repeatable retail workflow

    A retail team works around a circular process connecting question research, product evidence, recommendation monitoring and action.

    Map the decisions behind shopping prompts

    A useful prompt map should follow decisions rather than isolated phrases. Discovery questions express a need; comparison questions test trade-offs; validation questions look for reassurance; and purchase-oriented questions introduce constraints such as availability, suitability or budget. Retailers can use these families to examine where their products enter, survive or disappear from consideration.

    Build a dependable product evidence layer

    Each priority product should have a consistent factual identity across the retailer’s product pages and other controlled materials. Names, variants, intended uses, differentiators, limitations and policies should not contradict one another. Comparison content should clarify meaningful choices rather than manufacture unsupported superiority claims. The objective is to reduce ambiguity while giving recommendation systems usable reasons to distinguish one option from another.

    Measure the recommendation, not just the mention

    A practical scorecard can distinguish several analytical states: whether the retailer appears, whether a product is described correctly, whether the response cites a relevant source, whether the product reaches the shortlist and whether the recommendation remains stable across repeated checks. Those observations can then be segmented by prompt family, product category and journey stage.

    AI visibility should not automatically be treated as revenue attribution. It is better used as an upstream indicator alongside retailer-owned measures such as qualified visits, product engagement and completed purchases. Where direct referral data is limited, controlled changes to priority product content can help teams determine whether representation and recommendation patterns improve after the evidence changes.

    Create an accountable improvement loop

    The workflow should connect observed gaps to named actions. An inaccurate description may require product-content correction; weak differentiation may expose a merchandising or positioning problem; absence from a relevant comparison may call for better explanatory content; and inconsistent answers may justify broader monitoring. Clear ownership prevents an AI visibility report from becoming a dashboard that no team can act upon.

    For seasonal retail, the immediate opportunity is to establish this loop while teams can still improve product evidence and test important shopping contexts. Retailers that approach the AI shelf as a measurable cross-functional system will be better prepared to adapt as answer engines and agent capabilities evolve.

    References

  • AI Ad Products Are Expanding Faster Than Disclosure Rules

    AI Ad Products Are Expanding Faster Than Disclosure Rules

    AI advertising is developing along two connected tracks: platforms are adding tools that make campaigns easier to create and manage, while also deciding how much people should be told about the technology behind an ad.

    Google’s creative-origin disclosures and OpenAI’s expanding ChatGPT Ads product show why transparency cannot be reduced to a single label. Users need to recognize paid placements, understand when AI shaped the creative, and know who remains responsible for the resulting claims.

    Key takeaways

    • Google is adding a “How this ad was made” section to My Ad Center for ads across Search, YouTube, and Discover, according to CrushPress.AI’s coverage.
    • Google will automatically disclose the use of its own generative AI ad tools, but advertisers using third-party AI tools will have control over disclosure, subject to local requirements.
    • ChatGPT Ads is adding audience, reporting, draft, and format capabilities, while its suggested ad drafts reportedly reuse website metadata rather than generating new copy or images with AI.
    • Effective transparency needs to distinguish the presence of an ad, the origin of its creative assets, and responsibility for its content.

    Advertising transparency now has two separate jobs

    A digital ad card is shown between symbols for paid placement and AI-assisted creation, with a human advertiser standing behind it.

    The first job is placement transparency: making it apparent that a recommendation, card, or other interface element is advertising. CrushPress.AI reported that OpenAI’s refreshed static ChatGPT ad card uses a clearer “Ad” badge, a more readable presentation, and larger visuals. That addresses the commercial status of the content rather than how it was produced.

    The second job is production transparency: explaining whether generative AI created or modified the ad creative. According to CrushPress.AI’s Google coverage, users will be able to open the three-dot menu or information icon on an ad and find a dedicated “How this ad was made” section inside My Ad Center. The disclosure is expected to cover ads on Search, YouTube, and Discover.

    These signals answer different questions. An ad badge tells a person why content is being shown commercially. A creative-origin disclosure explains something about how that content came into existence. A platform can provide one without fully providing the other, so treating either signal as complete transparency would leave an important gap.

    Google’s disclosure model mixes automation and advertiser choice

    Google’s reported approach creates two disclosure paths. When an advertiser uses Google’s own generative AI advertising tools, Google will automatically place the relevant information in My Ad Center. Because the platform can observe the use of its own creation tools directly, disclosure can be built into the workflow.

    The process is less uniform when creative comes from elsewhere. CrushPress.AI reported that advertisers using third-party AI tools will control whether to disclose that use. Depending on local requirements, an AI label may also appear on the ad itself, either automatically or after the advertiser uses the available control.

    This split reveals a central difficulty for AI ad governance: platforms have stronger evidence about activity within their own systems than about assets imported from outside. A dependable program therefore needs both technical detection or provenance signals and accurate declarations from advertisers.

    Google already embeds imperceptible signals, including SynthID, in material created with its generative AI tools, according to the same coverage. The source also noted that Google has required election advertisers to disclose synthetic or digitally altered content in political ads under a policy introduced in 2023. Those measures offer context for the new My Ad Center information, but they do not make all disclosure scenarios identical.

    Product automation does not always mean generative creation

    OpenAI’s reported suggested-ad workflow illustrates why precise language matters. When a campaign needs broader content coverage, ChatGPT Ads Manager may offer an “Add new ad” option that prefills an image, title, and description from existing website metadata. The advertiser can then review, edit, and assign the draft to a campaign and ad group.

    CrushPress.AI emphasized OpenAI’s statement that this feature does not generate new copy or imagery with AI. It is automated assembly, according to the description, rather than generative production. Labeling every automated advertising workflow as “AI-generated” would therefore obscure meaningful differences in how assets are sourced and transformed.

    That distinction becomes more important as the product develops. The reported ChatGPT Ads updates also include an overview tab for account health, recommended tasks and performance trends; audience-list uploads containing at least 25,000 users; audience inclusion or suppression; and ad-group bid multipliers. These are campaign-management capabilities, not evidence that the visible creative was generated by AI.

    The same report said ChatGPT Ads had expanded to Japan and South Korea. As an advertising system reaches more markets and adds targeting and optimization controls, transparency must cover the entire experience without collapsing targeting, workflow automation, generative creation, and sponsored placement into one ambiguous category.

    A practical transparency standard for advertisers

    A marketing professional reviews an advertisement through transparent layers representing sponsorship, AI involvement, and human approval.

    Advertisers can prepare for this environment by maintaining an internal record of where each asset originated, which tools materially changed it, who approved it, and which platform disclosures were selected. That record is a general operational safeguard rather than a platform-specific requirement, but it can support consistent decisions when rules differ by market, format, or creation tool.

    Teams should also separate three reviews. The first confirms that a placement is visibly identified as an ad. The second determines whether the creative requires an AI-origin disclosure. The third checks the underlying claims, identity, and offer for accuracy. Google’s existing prohibition on misleading or deceptive advertising still applies regardless of whether AI was involved, according to CrushPress.AI’s report; provenance information does not validate an ad’s message.

    Clear terminology will be as important as the controls themselves. “AI-assisted,” “AI-generated,” “AI-modified,” and “assembled from existing metadata” describe different processes. Platforms that make those distinctions understandable can give users useful context without implying that automation alone determines whether an advertisement is trustworthy.

    As AI advertising products mature, the strongest transparency systems will connect visible ad identification, reliable creative provenance, and continuing advertiser accountability. The next test is whether those elements remain coherent as more creation tools, formats, and markets enter the workflow.

    References