Author: shivamcrushpressai

  • Google Ads Original Conversion Value: A Practical Guide

    Google Ads Original Conversion Value: A Practical Guide

    Your Google Ads return can appear to improve even when the underlying value of your conversions has not. If value rules or lifecycle goals are active, the Conversion Value column can include adjustments intended to guide automated bidding.

    Original Conversion Value gives you a cleaner baseline. The point is not to replace adjusted value, but to stop using one number for two different jobs: steering Google Ads and measuring the value your conversion tracking originally recorded.

    What Original Conversion Value actually removes
    Two parallel channels of value tokens, with one unchanged and the other gaining colored rings after passing through translucent filters.

    Google Ads provides an Original Conversion Value column that separates the starting value from rule and lifecycle adjustments. The relationship is:

    Conversion Value – Value Rule Adjustments – Lifecycle Goal Adjustments = Original Conversion Value

    Value rules can change the value Google Ads assigns for optimization purposes. Lifecycle goals can add strategic value as well, including a bonus associated with new customer acquisition. Those adjustments may be entirely intentional. They still make the resulting Conversion Value unsuitable as a direct stand-in for unadjusted value.

    • Original Conversion Value answers: What value was present before these Google Ads adjustments?
    • Conversion Value answers: What value remains after Google Ads applies the relevant value rules and lifecycle goal adjustments?
    • The difference between them answers: How much of the reported value comes from the optimization layer rather than the original value layer?

    The word “original” needs one important qualification. This metric does not independently verify your sales, margins, customer lifetime value, or recognized revenue. It inherits the quality of the conversion values entering Google Ads. If those values are incomplete, duplicated, outdated, or based on an unsuitable proxy, removing adjustments will not repair the underlying measurement.

    It also does not tell you whether the number of conversions increased. A campaign can show more adjusted value without producing more conversion events. Check conversion volume separately when your question is about acquisition volume rather than value.

    Compare the gap before you trust reported ROAS

    The useful insight is rarely in either value column by itself. It is in the relationship between them. Build that comparison into your campaign audit instead of waiting for a mismatch between Google Ads and an internal report.

    1. Choose one reporting scope. Use the same account or campaign rows, conversion scope, and date range for every value you compare.
    2. Place the columns side by side. Include Cost, Conversion Value, and Original Conversion Value. Add conversion volume when you also need to determine whether the number of outcomes changed.
    3. Calculate the adjustment gap. Subtract Original Conversion Value from Conversion Value. Treat this as a diagnostic calculation, not as another revenue measure.
    4. Calculate both ROAS views. Divide Original Conversion Value by Cost for an unadjusted, ads-side view. Divide Conversion Value by Cost for the adjusted view that reflects optimization priorities.
    5. Break the comparison down by campaign. An account-level total can hide a large adjustment in one campaign behind an unadjusted result somewhere else.
    6. Map each meaningful gap to a setting. Check whether an active value rule or lifecycle goal explains it. An unexplained gap should be resolved before you use the adjusted result to defend a budget decision.

    You can read the resulting patterns quickly:

    • The two values match: the selected slice has no net difference from the value-rule and lifecycle adjustments represented by the formula.
    • Both values move together: the underlying conversion value is likely contributing to the change. Check the gap as well, because adjustments may still amplify or reduce it.
    • Conversion Value rises while Original Conversion Value stays flat: the apparent gain is adjustment-driven, not growth in the baseline value.
    • Original Conversion Value falls while Conversion Value holds steady or rises: adjustments may be masking deterioration in the baseline.
    • The gap changes sharply: investigate a rule, lifecycle goal, or change in the mix of conversions eligible for those adjustments before attributing the movement to campaign execution.

    This comparison is especially important across campaigns. If one campaign receives a new-customer bonus and another does not, their adjusted Conversion Values do not represent the same measurement policy. Original Conversion Value removes that particular source of distortion and gives you a more consistent starting point for comparison.

    Keep bidding value and business value in separate lanes

    Adjusted value is not automatically false or useless. Its purpose can be strategic. If acquiring a new customer matters more to the business than recording an otherwise similar conversion, a lifecycle adjustment can communicate that preference to Smart Bidding.

    The reporting problem begins when that strategic preference is presented as money already generated. A new-customer bonus can represent additional value you want bidding to recognize without being an amount paid during the conversion. Calling the entire adjusted total “revenue” erases that distinction.

    A practical performance report should therefore show separate lines for separate questions:

    • Cost: what you spent.
    • Original Conversion Value: the baseline value before the covered Google Ads adjustments.
    • Original-value ROAS: Original Conversion Value divided by Cost. Label this as your own calculated view rather than implying it is a different official metric.
    • Adjusted Conversion Value: the value after rules and lifecycle goals have shaped it.
    • Adjusted-value ROAS: Conversion Value divided by Cost.
    • Adjustment gap: the difference between the two value columns, accompanied by the rule or goal responsible for it.

    Use the original-value view when you need to assess unadjusted campaign output, compare campaigns operating under different value strategies, or explain why platform ROAS does not match a less adjusted report. Use the adjusted view when you need to understand the priorities being supplied to automated bidding.

    Neither view should be silently relabeled as booked revenue. If revenue accuracy matters to a financial decision, reconcile the ads-side numbers with the system your business uses to validate transactions and customers. Until that reconciliation exists, keep the platform’s own metric name in stakeholder reports.

    Audit the automation before changing budgets or rules
    A magnifying glass examines connected switches, gates, and value tokens in a miniature automation control system.

    An attractive adjusted ROAS is not enough reason to expand spending. It may reflect stronger underlying performance, a larger adjustment, or both. Diagnose those components before you change the budget.

    1. Confirm whether the improvement exists in Original Conversion Value. If it does, the baseline moved. If it does not, isolate the adjustment responsible for the reported improvement.
    2. Verify that the adjustment is intentional. A value rule or lifecycle bonus should express a current business priority, not survive merely because nobody revisited it.
    3. Separate the optimization decision from the investment decision. Ask whether the bidding system should continue favoring the adjusted outcome, then ask whether the baseline value justifies more spend. Those questions can have different answers.
    4. Compare campaigns on a consistent basis. Use Original Conversion Value when differing adjustment policies would otherwise make adjusted values misleading.
    5. Document the reason for the gap. A short reporting note identifying the applicable rule or lifecycle goal prevents a strategic bonus from being mistaken for unexplained revenue growth later.

    Do not remove an intentional value rule solely to make the dashboard resemble a revenue report. Value adjustments help steer Smart Bidding. If the strategy is sound, preserve the signal and fix the reporting presentation by showing the original and adjusted views separately.

    Conversely, do not defend a campaign solely with adjusted ROAS when Original Conversion Value is weakening. The adjustment may explain why automation still favors the campaign, but it does not erase the decline in its baseline value. That is a commercial issue to investigate, not a reporting inconvenience.

    Key takeaways

    • Original Conversion Value is the conversion value before value-rule and lifecycle-goal adjustments covered by the metric.
    • The gap between Conversion Value and Original Conversion Value shows how much adjusted value separates your optimization view from the baseline.
    • Original Conversion Value divided by Cost provides a cleaner ads-side ROAS for analysis, but it is not automatically the same as validated business revenue.
    • Adjusted Conversion Value remains useful for understanding the priorities supplied to Smart Bidding.
    • If adjusted value improves without a corresponding improvement in original value, investigate the adjustment before crediting campaign performance.
    • Campaign reports should label original value, adjusted value, both ROAS calculations, and the reason for any material gap.

    Before your next budget review, add Original Conversion Value beside Conversion Value and Cost, calculate the gap, and annotate the rule or lifecycle goal behind it. You will leave the meeting knowing whether you are discussing stronger conversion value, a stronger bidding preference, or a mixture of both.
    References

  • How to Adapt Your SEO Strategy for Google’s AI-Driven Search

    How to Adapt Your SEO Strategy for Google’s AI-Driven Search

    You can still rank well in Google’s conventional results and lose the moment that matters: when a prospective customer asks AI Mode to explain the problem, compare the options, and recommend what to do next. The risk is no longer limited to losing a click. Your brand may be omitted from the answer before the user ever sees a list of links.

    The practical response is not to abandon SEO or chase every new AI feature. It is to make your brand easier to identify, your expertise easier to verify, and your offer easier to select. That requires a strategy for the generated answer as well as the ranked page.

    Google AI Mode changes the unit of competition

    A traditional search result usually asks you to compete for a position and earn a click. An AI-generated result can absorb more of the journey. It may explain an unfamiliar concept, evaluate alternatives, present information in a generated layout, and help the user move toward a decision without following the path you designed on your website.

    That change is visible in Gemini 3’s role in AI Mode. Its reasoning, multimodal understanding, generative layouts, interactive simulations, and agentic capabilities allow Google to produce something closer to a purpose-built experience than a static set of blue links.

    Your pages still matter, but their job is broader. They need to supply clear facts, credible evidence, useful explanations, and an unambiguous path to action. A high ranking can create eligibility for discovery; it does not guarantee that your brand will be included in a generated comparison or selected as the recommended option.

    This gives you four separate questions to answer during an AI search audit:

    • Identity: Can Google reliably determine who you are, what you offer, and who you serve?
    • Relevance: Can it connect your brand to the problem, category, use case, and decision criteria in the query?
    • Credibility: Can it find evidence that supports the claims you want repeated?
    • Deliverability: If the user wants to act, are the next step, requirements, limitations, and contact or purchase path clear?

    If one of those layers is weak, publishing more loosely related content will not necessarily repair it. Diagnose the missing layer first. An inaccurate brand description is an identity problem. Exclusion from category shortlists is more likely a relevance or credibility problem. A recommendation that produces no qualified action points to deliverability.

    Plan for explicit, implicit, and ambient research

    A person using a laptop, behavioral content trails, and ambient device signals converge on a central AI search orb with visual answer cards.

    A useful model separates AI discovery into explicit, implicit, and ambient research. These modes describe different moments in the decision journey, so they should not be collapsed into one visibility score.

    Research modeWhat triggers itWhat success looks likeFirst audit
    ExplicitThe user names your brandGoogle describes the brand accurately and handles reviews or comparisons fairlyBrand, review, and brand-versus-competitor queries
    ImplicitThe user names a problem, category, or requirementYour brand appears as a credible answer or candidate without being promptedProblem, best-option, and category-comparison queries
    AmbientSoftware identifies a relevant need without a direct searchYour brand is surfaced as a contextually appropriate recommendationSituations in which an assistant could reasonably introduce or act on your offer

    Secure explicit research first

    Explicit research is the closest point to a decision. Test the brand name on its own, common review questions, and comparisons with alternatives that customers genuinely consider. Record what the response says about your category, audience, differentiators, reputation, and next step.

    Do not score this as a simple mention check. A prominent but inaccurate description can be worse than a weak mention because it teaches the user the wrong thing. Flag stale positioning, merged product names, unsupported superlatives, missing limitations, and statements that conflict with your canonical pages. Then repair the clearest public version of the fact and the pages or profiles that contradict it.

    Earn inclusion during implicit research

    Implicit research happens when the user has not supplied your name. Queries such as who is best for a particular use case, how to solve a specific problem, or which option fits a constraint force Google to construct its own candidate set.

    Build your implicit query set from customer decisions, not from isolated keywords. For each commercial problem, document the audience, situation, constraints, comparison criteria, objections, and required proof. Your content should show where your offer fits and where it does not. Repeating a category term across many pages may create topical noise; answering the decisions inside that category creates usable evidence.

    Also separate informational inclusion from commercial selection. A page can be useful enough to support an explanation while leaving Google with no reason to associate the solution with your brand. Connect the explanation to a clearly identified author or organization, relevant offering, supporting evidence, and appropriate next step.

    Prepare for ambient research without pretending it is fully measurable

    Ambient research begins before a conventional query. An assistant could surface a relevant provider while someone evaluates return on investment in a spreadsheet, summarize a brand as a possible solution inside email, or identify it during a meeting workflow. If assistive agents progress from recommending to executing, the eligible set may narrow further because an action can require one concrete choice rather than a long list.

    This is the least directly testable mode. Treat it as a design target, not as a channel for which anyone can promise reliable coverage. Define the contexts in which a recommendation would be appropriate, then make the underlying facts operationally clear: what you provide, who qualifies, where it is available, what constraints apply, and how someone or an authorized agent can proceed.

    The order matters. Fix explicit inaccuracies before trying to dominate implicit discovery. Build credible implicit coverage before expecting ambient recommendations. Otherwise, you are asking an AI system to advocate for a brand it cannot consistently describe.

    Build an AI resume that keeps the brand record coherent

    Your AI resume is the compact, evidence-backed record you want search and assistive systems to learn about the brand. It does not need to be a single public page. It should begin as an internal source of truth that controls how important facts appear across your website, structured data, public profiles, executive biographies, product materials, and earned coverage.

    Create the record before editing individual pages. At minimum, settle these fields:

    • The canonical brand name and any legitimate alternate names.
    • The plain-language category in which the brand operates.
    • The products or services it actually provides.
    • The audiences, use cases, and locations it serves.
    • The meaningful constraints, exclusions, or eligibility rules.
    • The differentiating claims you are prepared to substantiate.
    • The strongest available evidence for each important claim.
    • The correct action path for a qualified user.

    Turn those fields into a claims-and-evidence ledger. Each row should contain the canonical claim, the page where it is stated most clearly, the evidence supporting it, any qualifying language, and the public locations that need to agree. This converts a vague brand-consistency exercise into an editorial queue.

    Start with contradictions, not cosmetic wording differences. A company can use varied language and remain understandable. It becomes difficult to interpret when its homepage, organization description, product page, and executive profile assign it different categories or make incompatible promises.

    JSON-LD should reinforce this record, not invent a second version of it. Mark up the entity and relationships that the visible page genuinely supports. Keep names, descriptions, URLs, offers, and organizational relationships aligned with the copy a visitor can read. Schema can reduce ambiguity; it cannot make an unsupported claim credible or repair a contradiction elsewhere.

    Assign ownership as well. Brand facts tend to drift when marketing, product, public relations, and leadership pages are updated independently. Someone needs authority to approve canonical changes and identify every public surface affected by them. Without that control, each campaign can quietly create a new version of the brand.

    Make important pages usable inside a generated answer

    Unlabeled modules from a structured webpage are extracted into translucent answer cards that remain connected to their original page sections.

    AI Mode’s ability to create dynamic layouts changes how you should evaluate a page. A polished narrative may work for a linear visit but remain difficult to reuse when Google needs a definition, a comparison criterion, a limitation, and a supporting fact for different parts of a generated response.

    Give each high-value page a clear information structure:

    <!– wp:list {
  • How Positionless Marketing Can Solve AI Adoption Challenges

    How Positionless Marketing Can Solve AI Adoption Challenges

    Research from Forrester and insights from Blain’s Farm & Fleet have shown me that the real obstacle in AI adoption isn’t the technology itself; it’s how we approach marketing tasks.

    Imagine a chocolate company with a cherished, decades-old recipe. They ask an AI tool to identify cost-cutting measures. After several ingredient eliminations and promising margins, sales plummet. Finally, someone tastes the product: “This isn’t even chocolate anymore.”

    Aly Blawat from Blain’s Farm & Fleet shared this during a MarTech webinar to highlight why 82% of marketing teams struggle with AI: automation devoid of human insight often exacerbates failure.

    According to a Forrester study for Optimove, just 18% of marketers feel at the vanguard of AI adoption, despite 80% anticipating enhanced targeting through AI. Only a quarter have active AI use cases in production.

    As Forrester’s Rusty Warner explains, many await software with built-in safeguards before fully embracing AI. Currently, marketing runs like an assembly line, ill-suited for AI’s potential to overhaul workflows.

    Positionless Marketing could be the answer. Here, marketers manage everything from data to campaign launches independently, allowing swift action and reserved teamwork for larger initiatives.

    Blain’s Farm & Fleet trialed AI for their brand’s cohesive tone across platforms, utilizing Jasper, a protected system. Warner suggests starting small to build confidence, ensuring data integrity for effective AI outcomes.

    Successful marketing teams centralize critical data definitions, providing essential signals directly to marketers. Adoption lags not due to the technology, but because organizations aren’t structured to exploit it effectively.

    Balancing automation with authentic customer engagement means deploying AI where it can be most beneficial while maintaining a genuine brand experience. At Blain’s Farm & Fleet, human oversight ensures alignment with customer expectations.

    The future points toward AI in execution, allowing unique, personalized customer journeys. This shift demands organizations to enhance customer experience expertise across all channels.

    For effective AI integration, restructuring marketing workflows and focusing on measurable outcomes are key. The vision includes less manual effort, fewer illustrative meetings, and more tangible customer impact.

    By 2026, AI adoption is expected to soar with more vendors providing embedded, coherent AI solutions. Brands like Blain’s Farm & Fleet illustrate the transformation—the right AI application fosters growth, far beyond superficial changes.

    Ultimately, AI can’t repair broken systems but amplifies existing conditions. Successful teams must adapt modern workflows and mindset shifts to harness AI’s full potential.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Revolutionize Your Google Ads with Journey Aware Bidding

    Revolutionize Your Google Ads with Journey Aware Bidding

    I’ve recently come across an exciting development from Google that could change the way we approach Google Ads. It’s called Journey Aware Bidding, and it’s designed to optimize Search campaigns by utilizing signals from every step of the customer journey. This aims to provide a smarter and more efficient way of managing campaigns.

    Google has rolled out this new Search bidding model to enhance prediction accuracy and improve campaign performance. The idea is to consider the entire customer journey, not just the final conversion point.

    How it works: Journey Aware Bidding learns not only from your primary conversion goal but also from non-biddable journey stages. If you’re someone who tracks and defines each step of your purchase funnel meticulously, this model could be particularly beneficial.

    Google advises mapping out the entire process—from lead submission to final purchase—and labeling all critical touchpoints as conversions within standard goals. This method promises to integrate more of the conversion funnel into Google’s prediction models, potentially streamlining lengthy, complex journeys such as lead generation.

    Why it matters: As someone who’s worked extensively with fragmented signals in conversion funnels, I’m intrigued by how Journey Aware Bidding could bring greater efficiency to our campaigns. It emphasizes learning from all key touchpoints, leading to smarter bidding strategies.

    What you should know: To get the most out of this feature, align your optimizations to a single KPI-driven stage, such as purchases or qualified leads. While other journey stages should be marked as primary conversions, they should be excluded from campaign-level or account-default bidding optimization.

    ```json
{
  "alt": "Infographic on Journey Aware Bidding for advertisers with key benefits and pilot information.",
  "caption": "Discover Journey Aware Bidding: A strategy that embraces the whole customer journey, promising improved ad performance for informed advertisers.",
  "description": "This infographic presents 'Journey Aware Bidding', a strategic initiative aimed at enhancing ad performance by monitoring the full customer journey. Key benefits include improved prediction accuracy and performance by leveraging conversion goals. The pilot program allows select advertisers to implement these strategies ahead of a wider rollout. Elements include icons of a magnifying glass and shopping bag, signifying search and commerce. Keywords: Journey Aware Bidding, advertisement strategy, customer journey, pilot program."
}
```

    Ensure that all tracking and categorization are accurate to achieve the best results.

    Pilot phase: Google is launching a closed pilot this year for select advertisers, with plans to expand after refining the model. This could be a game-changer in how we approach Search optimization.

    The bottom line: If you’re ready to rethink how you optimize your campaigns, Journey Aware Bidding might be the innovative approach you’ve been waiting for. By understanding not just what converts, but how users get there, we could see significant improvements.

    First seen: Senior Consultant Georgi Zayakov shared insights about this new bidding model on LinkedIn during Think Week 2025, alongside other intriguing products.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Google’s EU Ad-Tech Remedies: A Publisher and Buyer Playbook

    Google’s EU Ad-Tech Remedies: A Publisher and Buyer Playbook

    If you operate programmatic campaigns or publisher inventory in Europe, the wrong move is to treat Google’s EU ad-tech case as either business as usual or an imminent breakup. The practical question is narrower: which parts of your auction setup, measurement, and vendor dependencies could change if the proposed remedies are accepted?

    Google has submitted a compliance plan rather than agreeing to structural separation. That plan is not yet a settled operating model. You can still prepare without guessing the regulatory outcome: establish an auction baseline, locate single-vendor dependencies, and design tests that are easy to reverse.

    What Google has proposed – and what remains unresolved

    The proposal centers on two product-level remedies:

    • Publishers would be able to set different minimum prices for different bidders in Google Ad Manager.
    • Google’s advertising tools would work more readily with competing tools, giving publishers and advertisers more flexibility in how they assemble their ad-tech stacks.

    Those remedies target different kinds of control. Bidder-specific minimum prices change the rules governing participation in individual auctions. Greater interoperability changes how inventory, demand, workflows, and reporting can move across tool boundaries. Neither remedy, by itself, separates the ownership of Google’s integrated ad-tech operations.

    Google’s position is that technical changes can address the European Commission’s concerns without the disruption of a breakup. Critics question whether product adjustments can change the underlying power relationships while the integrated business remains intact. The Commission still has to decide whether the proposed changes are sufficient or whether a structural remedy should remain on the table.

    That uncertainty matters operationally. Do not plan as though bidder-level floors are already available in their final form, interoperability has a settled technical definition, or a breakup has been ordered. Treat each as a separate scenario with its own trigger.

    Bidder-specific price floors need controlled testing

    Two transparent auction test chambers use adjustable gates to evaluate identical streams of colored bid tokens under controlled conditions.

    A price floor is the minimum bid a publisher will accept for an impression. A bid below the applicable floor cannot win. If publishers can assign different floors to different bidders, a single pricing control becomes a bidder-level policy.

    That creates more control, but it does not guarantee more revenue. Raising one bidder’s floor can increase the price of the impressions that bidder wins while also reducing the number of eligible bids. The resulting loss of competition or fill can outweigh the higher price on the remaining wins. Average clearing price, viewed alone, can therefore make a poor change look successful.

    If the proposed control becomes available, use this test sequence:

    1. Preserve the existing state. Export or record current floors, bidder configuration, inventory groupings, and relevant auction settings before changing anything.
    2. Write one testable hypothesis. State which bidder, inventory class, format, and market the rule covers, as well as the behavior you expect to change. Avoid a stack-wide policy based only on a bidder’s brand or market reputation.
    3. Keep a comparable holdout. Leave similar inventory on the existing rule. Without a control, changes in demand, campaign mix, or seasonality can be mistaken for a floor effect.
    4. Measure the whole auction outcome. Track bid rate, win rate, fill, revenue per thousand ad requests, average clearing price, buyer concentration, and latency. The remedy is useful only if the combined result improves the publisher’s objective.
    5. Define stop conditions before launch. Decide which movement in fill, total revenue, latency, or demand diversity requires a rollback. Use thresholds based on your own established baseline rather than an unsupported industry benchmark.
    6. Record every change. Store the rule, affected inventory, start and end points, owner, rationale, and result in the same change log used for campaign and platform changes.

    Because bidder-specific rules treat demand sources differently, they can also create contractual and competition-law questions. Do not turn a pending regulatory proposal into a new pricing policy without checking existing agreements. Where a rule could create legal exposure in an EU market, have qualified competition counsel review it before it is scaled.

    What media buyers should monitor

    Advertisers will not control a publisher’s price floors, but they may see the effects in delivery. Segment reporting by exchange or supply path, publisher, market, device, and format. Watch for changes in win rate, eligible reach, delivery pace, cost, and the concentration of spend among supply paths.

    Do not diagnose a floor change from a higher CPM alone. A cost increase can also come from demand pressure, inventory mix, targeting, campaign edits, or a change in the route used to reach the impression. Compare cost with placement quality and campaign outcomes, then check whether the same inventory remains reachable through alternative authorized paths.

    Interoperability must be tested as a workflow, not a promise

    A modular workbench links publisher inventory, auction, buyer, delivery, and measurement stations through removable adapters and fallback routes.

    Greater interoperability between Google and competing ad-tech tools could expand choice for publishers and advertisers. Its actual value will depend on implementation details. A connector, export, or documented interface is not automatically equivalent to a complete working alternative.

    Turn the broad word interoperability into acceptance criteria your team can verify:

    • Scope: Identify the inventory, auction objects, campaign controls, and reports that can cross the boundary. List exclusions explicitly.
    • Direction: Determine whether the competing tool can only read information, can write or update settings, or can support a complete transaction workflow.
    • Field parity: Compare the fields, dimensions, controls, and levels of detail available through the integrated workflow with those available inside Google’s own tools.
    • Timing: Establish whether the exchange is real time, delayed, or batch-based. A delay that is harmless for reporting may make an auction or optimization workflow unusable.
    • Access: Document permissions, account relationships, authentication requirements, and any commercial conditions that determine who can use the connection.
    • Reconciliation: Verify whether requests, bids, impressions, costs, revenue, and adjustments can be reconciled across both systems.
    • Failure behavior: Test what happens when the connection times out, returns incomplete data, or becomes unavailable. A workable integration needs an observable error state and a safe fallback.

    Build a repeatable acceptance test before evaluating any implementation. Route a defined sample of eligible activity through the competing workflow. Confirm that inventory is available, bidder participation is visible, required controls work, reports reconcile, and failures can be detected. Keep the original route as a control until the replacement has passed those checks.

    This distinction prevents a common procurement error: counting the existence of an integration as evidence of effective choice. The operational question is not whether two products can connect. It is whether your team can complete the required workflow without losing material control, visibility, performance, or the ability to recover from a failure.

    Build one readiness file for every regulatory outcome

    You do not need to predict the Commission’s decision. You need a compact evidence package that lets you respond when a decision or documented product change creates an operational trigger.

    1. Map the stack. Record the ad server, exchanges, supply-side and demand-side platforms, buying interfaces, reporting systems, and the direction in which data or auction activity moves between them.
    2. Mark Google-dependent workflows. Identify where a Google product is required for setup, demand access, auction execution, optimization, reporting, or reconciliation. Distinguish a preference from a genuine technical dependency.
    3. Capture performance baselines. Preserve publisher auction metrics and buyer delivery metrics at the level needed to detect a change. Aggregated account totals can hide a material shift in one market, format, bidder, or supply path.
    4. Review portability and exit terms. Locate contract renewal dates, notice periods, data-export provisions, integration ownership, and any switching costs. Do not terminate or rewrite agreements merely because a remedy has been proposed.
    5. Assign decision owners. Name the person responsible for legal interpretation, platform configuration, measurement, vendor communication, and rollback. A regulatory update should not trigger an uncoordinated production change.

    Use three planning branches rather than one forecast:

    Possible outcomeImmediate actionWhat to avoid
    Product remedies are accepted substantially as proposedRead the final platform requirements, validate access, and run controlled floor or interoperability tests.Assuming the new controls improve yield or competition before measuring them.
    Stronger or structural remedies are requiredUpdate the dependency map, test continuity options, and review migration sequencing when operational terms are known.Rushing into an irreversible stack migration based on a headline rather than an enforceable plan.
    The proposal is changed, delayed, or remains under reviewKeep baselines, contracts, and vendor-path documentation current while continuing normal optimization.Freezing useful work while waiting for a regulatory outcome with no settled implementation.

    The event that should release a production change is not speculation about the case. It is a documented requirement, enforceable decision, contract change, or platform capability that your legal and technical owners have reviewed.

    Key takeaways for your next planning cycle

    • Google’s compliance plan is a proposal. The European Commission still has to determine whether product-level changes resolve its concerns.
    • Bidder-specific price floors affect auction participation as well as price. Evaluate net revenue, fill, competition, and latency instead of optimizing for clearing price alone.
    • Advertisers should monitor delivery by supply path and inventory segment because aggregate CPM and spend cannot identify the cause of an auction change.
    • Interoperability is useful only when the complete workflow preserves necessary access, controls, reporting, reconciliation, and failure recovery.
    • A dependency map, configuration record, performance baseline, and named rollback owner are useful under every regulatory scenario.

    Your most useful next step is a one-page readiness file. Put your current floors, bidder and vendor paths, baseline metrics, contract checkpoints, decision owners, and release triggers in one place. When the Commission decides or the products change, you will be able to test the actual remedy against evidence instead of rebuilding your operating picture under pressure.

    References

  • Google AI Travel Planning: An Action Plan for Travel Brands

    Google AI Travel Planning: An Action Plan for Travel Brands

    If you market a hotel, airline, restaurant, destination, or travel platform, the uncomfortable question is not whether travelers will use AI to brainstorm trips. It is whether your offer will remain visible when the same interface can compare the options and move the traveler toward a reservation.

    Google is connecting discovery, itinerary planning, deal-finding, and booking inside AI Mode. You do not need to chase every new feature. You need to separate live capabilities from planned ones, make your inventory easy to compare, and test whether a traveler can move from a conversational request to a correct booking without hitting conflicting information.

    Separate the live travel tools from planned booking features

    Google’s travel rollout is not one feature with one availability date. Some capabilities are already rolling out in particular markets and devices. Others describe the direction of flight and hotel booking but should not yet be treated as universally available. That distinction should determine what your team fixes now and what it prepares for next.

    CapabilityDocumented availabilityWhat your business should do
    Dinner reservations in AI ModeAgentic dinner reservations are rolling out in the U.S. through services including OpenTable and Resy, without being confined to a Google Labs opt-in.Check that your restaurant name, location, availability, party rules, and booking destination agree across your website, Google presence, and reservation provider.
    Canvas for trip planningCanvas is available for travel planning on desktop in the U.S.Publish information that remains useful within an itinerary, including location context, operating constraints, policies, and what must be reserved in advance.
    Flight DealsFlight Deals is expanding to more than 200 countries and multiple languages, and it accepts travel requests written in conversational terms.Make route, schedule, price, and eligibility information unambiguous. Review localized content as operational data, not merely translated marketing copy.
    Agentic flight and hotel bookingGoogle plans to help travelers compare flights and hotels by schedule, price, and reviews before completing a booking with a selected partner. Booking.com, Expedia, and Marriott are among the companies working with Google on the experience.Prepare your content, inventory, and distribution handoffs, but do not tell customers that universal AI Mode flight or hotel booking is already available.

    This prevents two expensive mistakes. The first is postponing all work because flight and hotel transactions are still developing, even though restaurant reservations and conversational deal discovery already create practical work. The second is promising a booking experience that a traveler cannot access in their market, device, or category.

    Label every internal project as live optimization, rollout monitoring, or future readiness. A U.S. restaurant connected to a supported reservation service belongs in the first group. A hotel preparing its distribution data for agentic booking belongs in the third. Flight offers shown across languages need both optimization and monitoring because geographic expansion does not guarantee that every offer is eligible or represented correctly.

    Optimize for a travel brief, not just a destination keyword

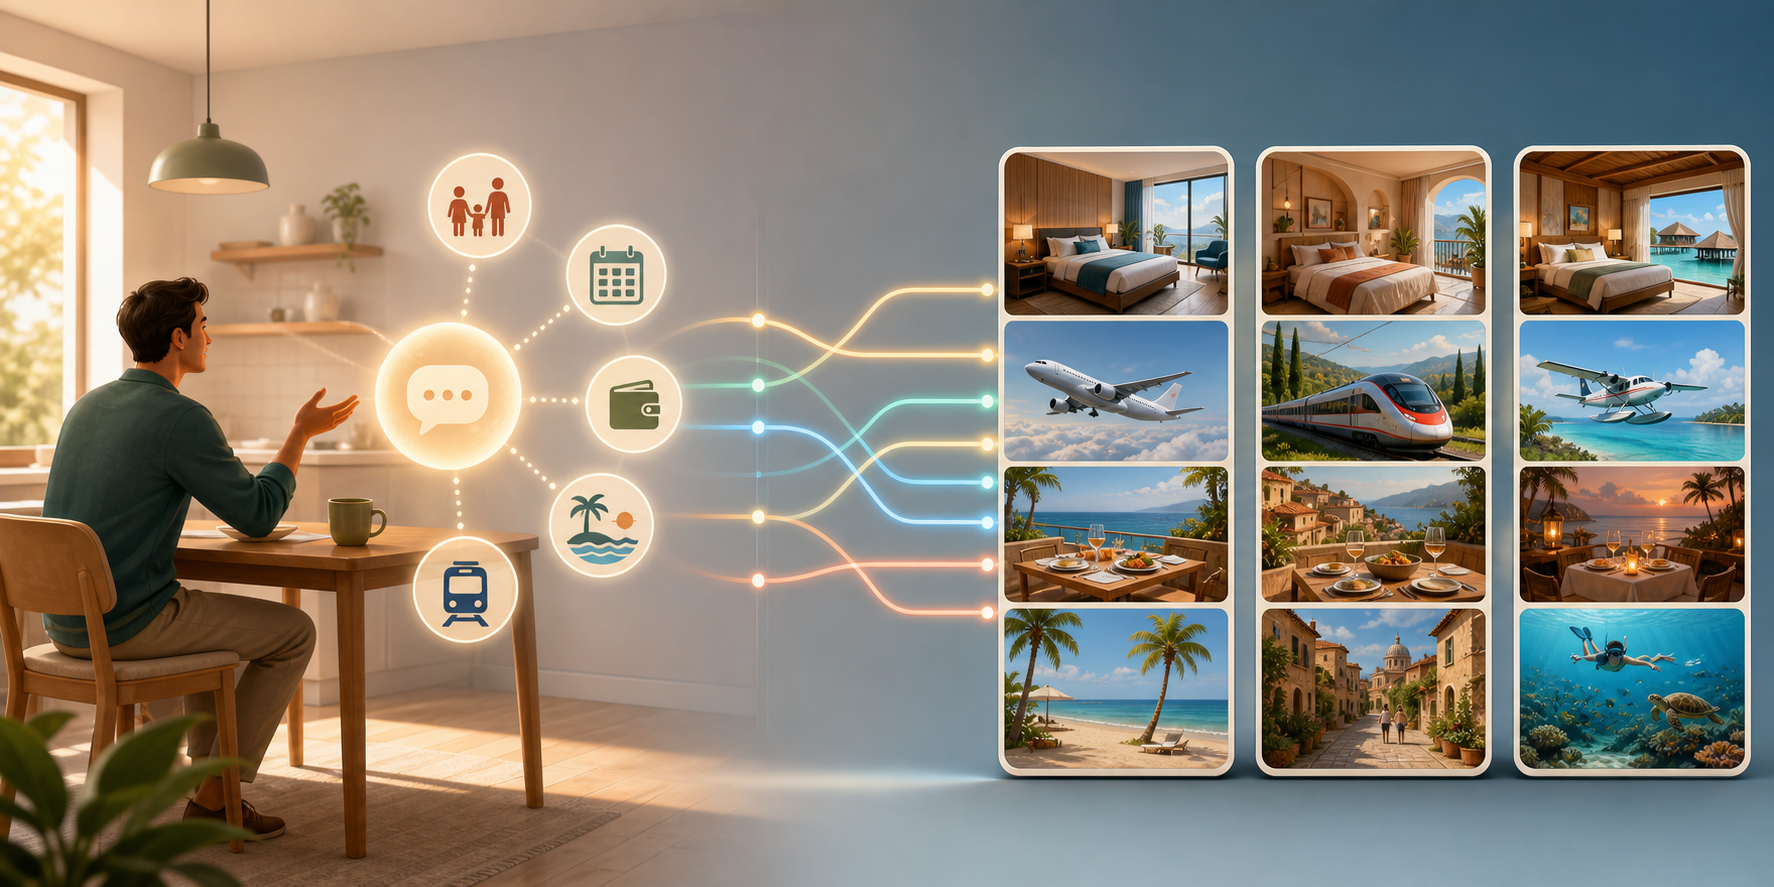
    A traveler's preferences for family, timing, budget, dining, and transportation flow into three consistently arranged trip options.

    A conventional travel query often looks like a destination plus a category. A conversational request can contain the whole decision: origin, timing, budget, preferred pace, who is traveling, acceptable connections, desired amenities, and conditions the traveler wants to avoid. Google is explicitly letting people describe the flight deal they want as they would describe it to another person.

    That changes the useful unit of content. A page that repeats a broad phrase such as “city hotel” may match a category, but it does not resolve whether the property fits a particular trip. Your page should help a planning system answer selection questions without inventing the missing context.

    1. State the fit. Say which traveler, occasion, route, or itinerary the offer serves. Avoid claiming that every product is ideal for everyone.
    2. Expose the constraints. Put operating days, stay requirements, connection rules, age or party restrictions, accessibility details, and booking conditions where they are relevant and visible.
    3. Explain the tradeoff. If an option is cheaper because it is less flexible, farther away, indirect, or limited to particular inventory, make that distinction explicit.
    4. Define the price context. Identify what the displayed amount covers, what may change it, what is excluded, and where the traveler must confirm the current total.
    5. Give the next action. Link the exact offer to the matching availability or booking step instead of sending every traveler to a generic homepage.

    Use that sequence as a content brief. Start with the travel need, answer the constraints, present the tradeoffs, supply evidence, and expose the booking path. It works better than manufacturing a separate page for every conversational variation because the underlying offer stays canonical while its decision facts become clearer.

    Do the same with destination content. A useful neighborhood page should explain what the location makes convenient, what remains inconvenient, which transport assumptions matter, and how the property or experience fits into a realistic itinerary. Generic inspiration can attract attention, but comparison-ready facts help a traveler make a choice.

    Make every offer comparable, verifiable, and machine-readable

    Google’s planned flight and hotel experience centers on schedules, prices, and reviews. Those are not decorative content fields. They are decision inputs. If your website, feed, booking engine, and distribution partners describe them differently, an AI interface has no reliable version to carry into the traveler’s plan.

    Audit each bookable offer as a record with the following components:

    • A stable identity: the exact property, route, room, fare, table, package, or experience being offered.
    • A precise location or operating area: not just a destination label, but the information needed to place the offer in an itinerary.
    • Availability context: the dates, times, operating pattern, inventory status, or conditions that control whether the offer can actually be selected.
    • Price context: currency, inclusions, exclusions, mandatory charges, variability, and the point at which the traveler receives the final amount.
    • Policies: cancellation, changes, refunds, deposits, check-in or arrival rules, and any restriction that could reverse the decision.
    • Fit attributes: the amenities, service conditions, accessibility information, traveler requirements, and limitations that distinguish the option.
    • Review evidence: ratings or review summaries that are genuine, attributable, current enough to use, and consistent with what the visitor can see.
    • A specific booking destination: the page or provider that can act on the offer without making the traveler reconstruct the search.

    Then compare the record across every system that publishes it. Begin with the visible page, continue through your structured data and feeds, and finish in the booking flow. A price that is correct in a feed but stale on the page is still a problem. So is an amenity marked up in JSON-LD that the visible content does not support.

    Use structured data as a consistency layer. Choose the narrowest valid type and properties supported by the page, connect records with stable identifiers, and make the marked-up values agree with the content a visitor can read. Do not use markup to assert unavailable inventory, hidden reviews, or an offer that the linked booking page cannot reproduce. Schema can reduce ambiguity; it cannot compensate for contradictory business data or guarantee inclusion in an AI response.

    Keep critical decision facts in readable page text rather than only inside promotional images or an interaction that reveals nothing until checkout. You should not require a person or a machine to infer whether breakfast is included, whether the rate can be canceled, or whether a venue accepts the requested party. If a fact materially changes the booking decision, publish it before the handoff.

    Test the booking handoff as carefully as the search result

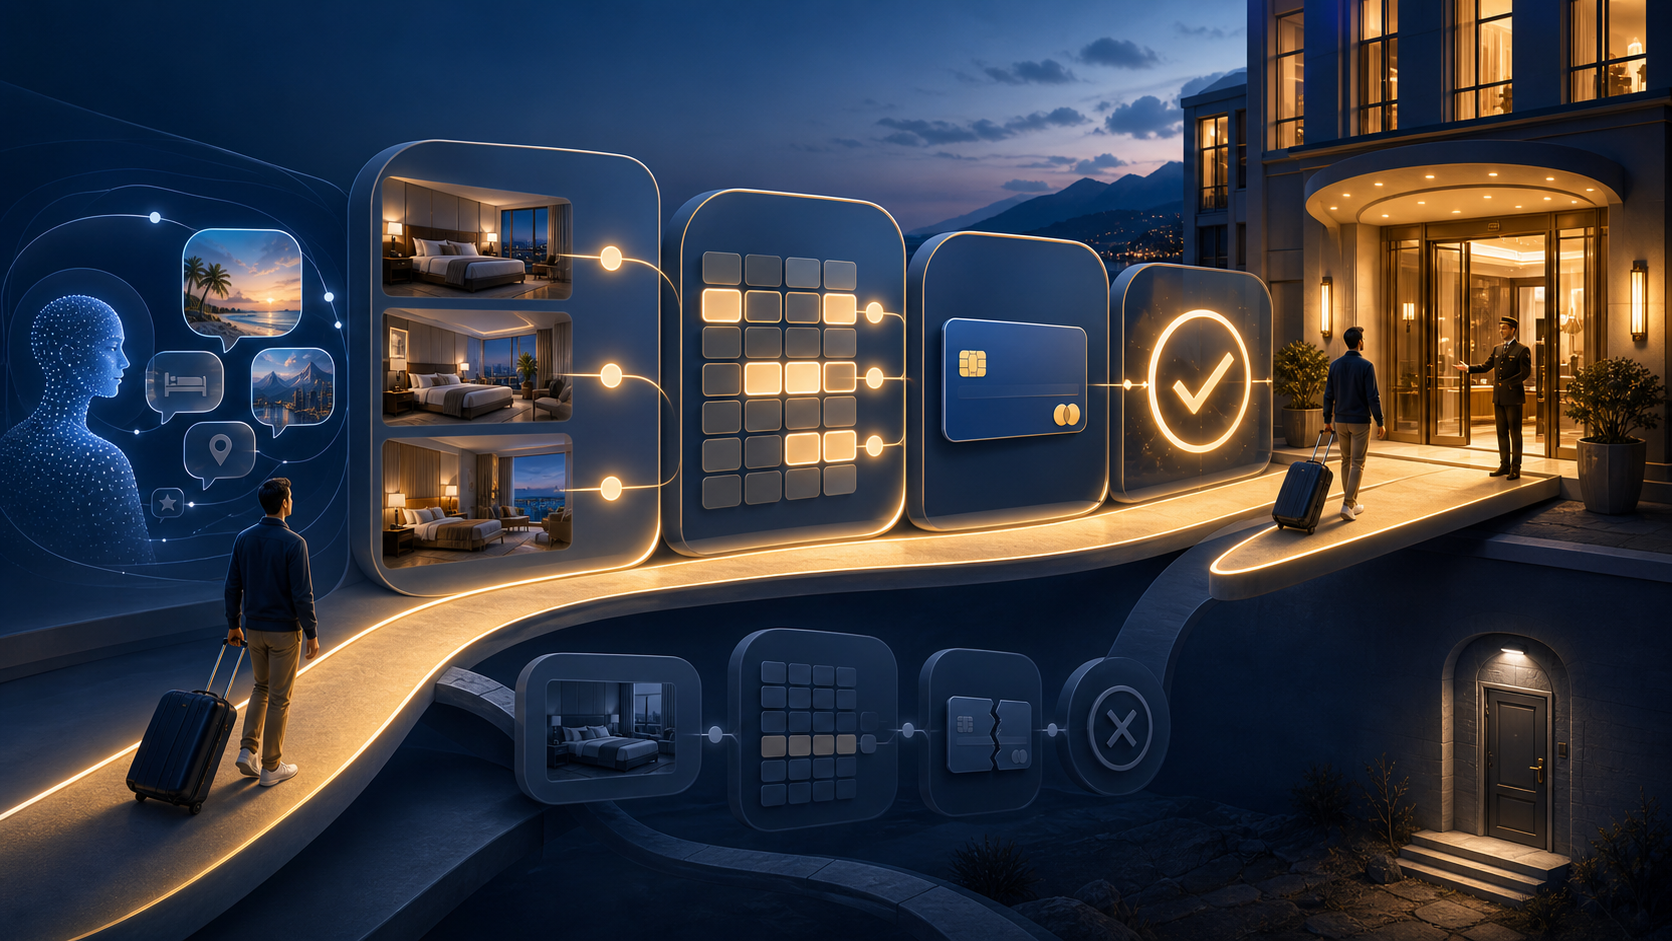
    A traveler follows a connected path from trip planning through room selection and payment to a hotel reservation, beside a second path that ends at a disconnected doorway.

    Agentic booking does not remove the rest of the travel stack. Google is working with reservation and travel partners, and its planned flow still ends with a chosen booking partner. Your visibility can therefore depend on information and transaction paths that your own marketing site does not fully control.

    Run a complete journey for each priority offer:

    1. Start with a realistic conversational request that includes the constraints your customers actually use.
    2. Check whether your business or offer appears, whether it is described accurately, and which page or provider is attached to it.
    3. Select the offer and compare the displayed schedule, price, availability, review information, and policy with your authoritative records.
    4. Continue to the reservation provider. Confirm that dates, party details, route, room, fare, or package context survives the handoff.
    5. Proceed far enough to see the payable amount and essential terms. Stop before creating a charge unless the test booking is authorized and can be safely reversed.
    6. Test an unavailable option and a changed option. The experience should return a clear alternative or current status rather than a dead end or misleading confirmation.
    7. Verify the confirmation path. The traveler should know who holds the reservation, where support comes from, and which rules govern changes or cancellation.

    For a U.S. restaurant, include the reservation provider you actually use when checking the live dinner-booking path. For a hotel or airline, start with existing distribution relationships and monitor Google’s flight and hotel rollout. The fact that Booking.com, Expedia, and Marriott are named collaborators is not evidence that every supplier, property, or rate connected to them will automatically qualify.

    Do not move inventory to a new channel solely because its company appears in a product rollout. A change in distribution can alter commissions, contract terms, customer ownership, support obligations, and margin. First ask your existing provider what data it sends, which identifiers it preserves, how corrections propagate, and whether your inventory is eligible for the relevant Google experience. Review the commercial terms before changing the channel mix.

    Assign ownership for mismatches. Marketing can maintain descriptive content, but pricing, inventory, distribution, and reservation failures often sit elsewhere. Give each field an authoritative system and an escalation path. Otherwise, the first person to discover the inconsistency will be the traveler attempting to book.

    Measure the full prompt-to-reservation journey

    Organic clicks alone cannot tell you whether Google AI travel planning is helping or displacing your business. If more comparison happens inside the planning interface, a visitor may arrive later in the decision process, transact through a partner, or remember the brand and return directly. None of those possibilities makes a click unimportant; they make it incomplete as a standalone measure.

    Build a repeatable prompt set from real customer questions and group the observations by market, language, device, and travel category. Record the prompt, test conditions, options shown, facts attributed to your offer, linked destination, booking provider, and result of the handoff. Keep the conditions with the result so that a desktop Canvas observation in the U.S. is not silently treated as evidence of identical availability everywhere.

    Use operational measures that point to a fix:

    • Discovery rate: the share of applicable test prompts in which the business or eligible offer appears.
    • Fact accuracy rate: the share of checked decision fields that agree with the authoritative record.
    • Price parity rate: the share of tested offers whose displayed price context matches the booking destination.
    • Handoff success rate: the share of selections that reach the correct bookable inventory with the important context preserved.
    • Confirmation rate: the share of authorized test or customer journeys that produce a valid reservation rather than an error, unavailable result, or abandoned mismatch.
    • Correction time: how long it takes an updated schedule, policy, price, or availability status to become consistent across the systems you control.

    Do not collapse all of this into one AI visibility score. An appearance with the wrong cancellation policy is not a success. Neither is an accurate citation that sends the traveler to an unrelated booking page. Diagnose the failing stage: discovery, comparison, handoff, or transaction. Then fix the system responsible for that stage.

    Key takeaways

    • Treat U.S. dinner reservations, desktop Canvas, international Flight Deals, and planned flight or hotel booking as different rollouts with different actions.
    • Write for the complete travel brief by exposing fit, constraints, tradeoffs, price context, policies, and the exact next step.
    • Keep visible content, structured data, feeds, provider records, and checkout information consistent.
    • Test whether offer context survives the move from an AI recommendation to the reservation provider.
    • Measure accurate discovery and successful booking separately; visibility with incorrect facts is a failure, not a partial win.

    Start with the journey tied to your most important bookable offer. Reproduce it from a realistic prompt to the final reservation step, find the first fact or handoff that fails, and correct its authoritative record. Repeat that process across the markets and languages you actually serve. That work will remain useful as Google’s travel features expand because it improves the same thing every planning interface needs: an offer that can be understood, compared, and booked without surprises.

    References

  • Microsoft AI-Generated Video Ads: A Practical Testing Plan

    Microsoft AI-Generated Video Ads: A Practical Testing Plan

    You already have image ads that communicate the offer. The problem is turning them into credible video creative without waiting for another full production cycle.

    Microsoft’s AI image animation can close part of that gap, but generating motion is only the production step. You still need to choose the right source image, protect the message, control the test, and decide whether the resulting video deserves more spend.

    What Microsoft’s image animation changes

    Microsoft Advertising’s Copilot-powered Image Animation feature turns static creative into video through Ads Studio’s video templates. It was introduced as a global pilot available outside mainland China, so account access should be verified before you make it part of a campaign deadline.

    The practical benefit is asset extension. Instead of beginning every video concept with a script, shoot, edit, and new approval cycle, you can give an existing image a motion treatment and make it eligible for more video opportunities across Microsoft’s publisher network.

    That does not make an animated image equivalent to a purpose-built video. It does not create a stronger offer, repair weak positioning, or prove that video will outperform the original image. The feature reduces production friction; it does not remove the need for creative judgment.

    This distinction should shape your first decision. Use image animation when the static asset already contains a complete, intelligible idea and motion could make that idea easier to notice. Commission purpose-built video when the message depends on a demonstration, a sequence of claims, a spokesperson, a detailed explanation, or a narrative change over time.

    Choose a source image that can survive motion

    A hand selects a clean, spacious running-shoe image from three unbranded advertising compositions on a design table.

    Your most attractive image is not automatically your best animation candidate. Motion directs attention, which means it can amplify either a clear hierarchy or a confused one. Start with assets that pass these checks before animation is added:

    • The image has one obvious focal point. A person, product, interface, or result should command attention without competing with several equally prominent elements.
    • The offer works as a still image. A viewer should understand the basic promise even if the animation fails to add meaning.
    • The text is readable without depending on motion. Animation should support the message rather than move essential words through the frame or make them harder to follow.
    • The brand is identifiable. A logo alone is not enough if the colors, product, offer, and landing-page experience feel unrelated.
    • The composition has room to move. A crowded collage, dense screenshot, or image packed with disclaimers gives the animation little freedom without creating distraction.
    • The asset has a reason to be tested. Prior engagement or conversion performance is useful evidence, but a strategically important new image can also qualify if you define the hypothesis clearly.

    Be especially cautious with comparison charts, multi-product grids, small interface screenshots, and images whose meaning depends on fine print. These can be effective static ads because viewers can pause and inspect them. Added motion may reduce that advantage.

    Do not choose an image merely because it is available. Write one sentence explaining what the motion is supposed to improve: make the product easier to notice, reveal a benefit, create depth around the focal point, or refresh a proven concept for video inventory. If you cannot finish that sentence precisely, you do not yet have a testable reason to animate the asset.

    Build a controlled image-to-video workflow

    The fastest route from image to video is not necessarily the fastest route to a usable ad. Put a short decision process around generation so that reviewers evaluate the output against the same objective.

    Define the test before generating variants

    1. Name the source asset. Record the exact image, its message, and why it was selected.
    2. State the motion hypothesis. Describe the viewer behavior you expect the animation to influence, not simply that the video should be more engaging.
    3. Set the non-negotiables. Identify the product details, logo treatment, claims, price information, and required disclosures that must remain accurate and legible.
    4. Generate a small, meaningfully different set. Do not keep numerous near-identical outputs. Retain only variants that create distinct attention paths or motion treatments.
    5. Choose against the hypothesis. Select the version that best serves the intended message, even if another version looks more dramatic.
    6. Preserve the static control. Keep the original image and its performance context so the video result can be judged as an extension of known creative rather than an isolated asset.

    Keep campaign variables stable wherever the platform and inventory permit it. The audience, offer, landing page, bidding approach, and measurement window should not all change at the same time as the format. Otherwise, a result cannot tell you whether animation helped or whether another variable produced the difference.

    Apply a quality gate before the ad reaches review

    AI-generated motion can be technically valid and still be commercially unusable. Watch the complete output repeatedly, including without audio, and stop the asset if any of these checks fail:

    • Object integrity: Products, hands, faces, packaging, interfaces, and logos remain visually coherent throughout the motion.
    • Claim integrity: Movement does not imply a product function, transformation, or result that the offer cannot support.
    • Message order: The first thing motion emphasizes is also the first thing the viewer needs to understand.
    • Text stability: Essential copy remains readable and is not obscured, distorted, or pulled away from its intended context.
    • Brand continuity: The animation still looks like the brand and still leads naturally into the landing page.
    • Ending clarity: The final state leaves the viewer with a recognizable product, offer, and next action instead of ending on decorative movement.

    Reviewers should also compare the video directly with the source image. The right question is not, “Does this move?” It is, “What became clearer because it moves?” Reject output that adds activity but weakens comprehension.

    Keep the approved source image, generated output, final exported asset, approval record, and campaign label connected in your asset library. That lineage matters when a price changes, a claim expires, or a product image is replaced. Without it, an efficient production process can create a larger cleanup problem later.

    Measure whether motion improves the business outcome

    A marketing analyst compares matched static and animated versions of the same bottle advertisement on two displays.

    Video metrics can make weak creative look busy. Views, starts, and completion behavior tell you how people consumed the format, but they do not automatically tell you whether the ad attracted the right audience or advanced the campaign goal.

    Select the primary metric from the campaign objective before launch. A response campaign should ultimately be judged by the valuable action it is designed to produce. An awareness campaign can use video-consumption and reach signals, but it still needs a defined outcome rather than a collection of whichever metrics improved.

    Read the result as a sequence rather than a single total:

    • Delivery changed: If the animated asset receives different inventory or substantially different exposure, separate the effect of access from the effect of creative quality.
    • Video engagement improved but clicks did not: The movement may hold attention without communicating a sufficiently relevant offer.
    • Clicks improved but post-click performance weakened: The animation may be creating curiosity that the landing page does not satisfy, or it may be attracting less-qualified traffic.
    • Downstream performance improved: Check whether the gain is consistent enough to justify producing more animations from the same creative pattern.
    • Nothing meaningful changed: Do not add more motion by default. Revisit the source image, the hypothesis, and whether animation is the appropriate format for the message.

    These patterns are diagnostic clues, not proof of a cause. Campaign delivery, inventory, audience composition, and normal variation can affect them. The cleaner your setup and asset labeling, the less likely you are to scale a false winner.

    When a test wins, scale the principle before you scale the production volume. Identify what appears to have worked: focal-point movement, a clearer product reveal, stronger brand presence, or access to useful video inventory. Apply that lesson to the next suitable image and test again. Generating a large batch from every asset would replace a production bottleneck with a measurement bottleneck.

    Key takeaways

    • Microsoft’s Copilot-powered feature converts static images into video through Ads Studio templates and can extend existing creative into more video inventory.
    • Account availability should be confirmed because the documented rollout was a pilot rather than an unconditional promise of access.
    • The strongest source image already communicates one clear idea; motion should reinforce that hierarchy rather than invent it.
    • A useful test changes the format while keeping the offer, audience, landing page, and measurement approach as stable as practical.
    • Generated motion needs human review for distorted objects, altered claims, unstable text, weak endings, and brand discontinuity.
    • Scale only when the video improves the metric tied to the campaign objective, not merely because it collects more video activity.

    Start with one image whose role you understand. Write the motion hypothesis, generate a restrained set of options, pass the winner through a strict quality check, and test it against a preserved control. If the downstream result improves, you have found a repeatable creative direction rather than merely a faster way to make files.

    References

  • ChatGPT Referral Traffic: What Publishers Should Measure

    ChatGPT Referral Traffic: What Publishers Should Measure

    You’ve earned the citation. Your page appears in ChatGPT, perhaps even inside the main answer, but analytics barely moves. That isn’t a contradiction. A citation can help complete the user’s task without giving that person a reason to visit you.

    If you publish for traffic, subscriptions, advertising inventory, or leads, the practical question isn’t whether AI visibility exists. It is which parts of that visibility can become measurable business value. The answer starts by separating exposure, acquisition, and outcomes.

    Visibility and referral traffic are different outcomes

    A three-part illustration shows broad attention narrowing into website visits and then branching toward subscription, advertising, and lead outcomes.

    A conventional search result usually asks the user to choose a page before getting the full answer. ChatGPT can reverse that sequence: it presents an answer first and uses links to support, verify, or extend it. The link may be useful even when nobody opens it.

    That creates three distinct layers of performance:

    • Exposure: Your brand, page, or domain appears in an answer, citation, sidebar, or search result.
    • Acquisition: The user clicks and reaches your site.
    • Outcome: The visit produces something valuable, such as another pageview, a registration, a newsletter signup, a subscription, a lead, or revenue.

    Give each layer its own metric. A citation count is not a visit count, and a visit is not a business result. If you combine all three under a label such as “AI performance,” a rising citation graph can hide flat acquisition while a small but productive referral channel can look insignificant.

    Choose the layer you are trying to improve before changing content. If the objective is exposure, track citations and mentions. If it is acquisition, track referral visits and landing pages. If it is revenue or audience development, judge those visits by their downstream behavior. This distinction keeps a GEO win from being mistaken for a traffic win.

    What the available ChatGPT CTR figures actually mean

    In one leaked slice of OpenAI interaction data, a top-performing URL accumulated 610,775 link impressions and 4,238 clicks, producing a 0.69% overall click-through rate. The strongest individual-page CTR was 1.68%, while many other pages recorded 0.1%, 0.01%, or no clicks.

    Placement also changed the relationship between exposure and action:

    ChatGPT link locationRelative impression volumeObserved click behaviorWhat a publisher should infer
    Main responseMassiveMinimal CTRTreat visibility here primarily as exposure unless your own referrals prove otherwise.
    Sidebar and citationsLowerApproximately 6% to 10% CTRThe context may produce more clicks per impression, but its smaller reach limits total traffic.
    Search resultsNegligibleNo clicks in the observed sliceDo not build a traffic forecast around this surface without materially more evidence.

    Do not mix these figures. The 6% to 10% range belongs to particular display areas; it cannot be applied to the much larger main-response impression count. Page-level CTR and placement-level CTR also answer different questions. Combining their numerators or denominators would produce a metric with no clear meaning.

    The scale becomes clearer through simple arithmetic: at the observed 0.69% rate, 100,000 impressions would produce 690 clicks. That is an illustration, not a forecast. The underlying material was leaked, limited, and not established as a representative platform-wide benchmark. Your topics, link placements, audience intent, and page types may behave differently.

    Use the figures to set expectations, not targets. They support a cautious operating assumption: high ChatGPT visibility may coexist with low referral volume. They do not establish the CTR your publication should expect.

    Build a referral report that answers a business question

    Your site analytics can count visits that arrive with an identifiable ChatGPT referrer. They cannot calculate a true ChatGPT CTR from those visits alone. CTR requires both clicks and impressions measured across the same pages, surfaces, and reporting period. If you do not have the impression denominator, label the metric “referral visits,” not CTR.

    Set up the report in this order:

    1. Preserve the raw referral values. Create a ChatGPT segment from the referrer values your analytics actually records, while retaining source, landing-page URL, device, and date. Keeping the raw fields lets you revise the grouping without losing the original evidence.
    2. Assign an outcome to each page type. A news page may be judged by additional pageviews or registrations. A research page may support newsletter subscriptions. A commercial explainer may support qualified leads. Do not force every landing page into one conversion definition.
    3. Group landing pages by function. Separate news, evergreen explainers, tools, datasets, opinion, and commercial pages. A channel-wide average can conceal the page types that attract the few useful visits.
    4. Measure visit quality after arrival. Record the next page, return visit, registration, subscription start, lead, advertising pageviews, or other outcome that matters to your publishing model. Raw sessions tell you how much traffic arrived, not what it was worth.
    5. Compare ChatGPT with your own baseline. Evaluate referral quality against other channels and against previous reporting periods using the same definitions. Do not grade your publication against a leaked CTR from an unknown mix of publishers and surfaces.

    A useful dashboard therefore has landing pages as rows and separates exposure, acquisition, and outcome columns. Add citation or impression counts only when you have a defensible source for them. Then show ChatGPT visits, the chosen page-level outcome, outcome rate, and any revenue measure you can reliably attribute.

    This structure also prevents a common strategic error. ChatGPT does not need to replace Google-scale traffic to be useful, but a small channel must earn its place through audience quality or business value. If it delivers neither scale nor valuable actions, call it visibility rather than acquisition.

    Give the cited reader a reason to leave the answer

    A reader moves from a compact answer panel toward a publisher site offering a calculator, map, document, comparison grid, and research archive.

    When ChatGPT has already supplied the summary, repeating that summary on your landing page creates little additional value. The click needs to continue the task. Your page should offer something the answer could not conveniently contain or personalize.

    Useful continuation points include:

    • Evidence: the complete dataset, methodology, source trail, definitions, or limitations behind a claim.
    • Application: a calculator, worksheet, template, checklist, filter, or other tool that helps the reader act.
    • Freshness: a maintained table, status page, version-specific instruction, or dated update that the reader can verify.
    • Depth: edge cases, implementation details, worked examples, and tradeoffs that would make an answer unwieldy.
    • Personal relevance: paths organized by role, use case, location, product, or decision stage.

    Treat these as hypotheses to test, not guaranteed click tactics. Start with pages that already receive ChatGPT referrals and inspect the exact task each page serves. Then make the continuation obvious near the beginning of the page.

    Audit each landing page with five questions:

    1. Does the opening immediately confirm that the visitor reached the promised topic?
    2. Can the visitor see the next layer of value without searching through a generic introduction?
    3. Does the primary call to action match the likely intent behind this page, rather than using the same CTA across the entire site?
    4. Are the author, publication date, scope, and supporting evidence clear enough for a verification-minded visitor?
    5. Do pop-ups, registration walls, or slow page elements obstruct the value that justified the click?

    Do not turn a complete answer into a thin teaser just to manufacture a click. The cited material still needs to answer its question clearly. The landing-page offer should extend that answer through evidence, utility, depth, or personalization rather than withholding the basic fact.

    Key takeaways for publisher teams

    • ChatGPT citation visibility, referral acquisition, and business outcomes are three separate performance layers.
    • A leaked interaction sample recorded 0.69% overall CTR for a top-performing URL, with much higher CTR in lower-volume sidebar and citation placements.
    • Those figures are directional evidence, not a universal publisher benchmark or a traffic forecast.
    • You cannot calculate ChatGPT CTR from site visits alone; you need a matching impression denominator.
    • Evaluate referral traffic by landing page and downstream value, not just by its share of total sessions.
    • Give cited users a concrete continuation such as evidence, a tool, current data, implementation depth, or a personalized path.
    • Treat ChatGPT referrals as incremental until your own analytics demonstrate enough scale and value to justify a larger acquisition role.

    Take the landing pages already receiving ChatGPT visits, assign one meaningful outcome to each page type, and add one continuation worth the click. Compare the same metrics before and after the change over consistent reporting periods. Let your own referral and outcome data decide whether ChatGPT is a visibility channel, an acquisition channel, or both.

    References

  • How to Measure AI Search Visibility and Track What Changed

    How to Measure AI Search Visibility and Track What Changed

    You changed a template, rewrote an important page, added structured data, or earned a prominent mention. Two weeks later, a visibility graph moved. The tempting conclusion is that your work caused it. The honest answer is that a graph alone cannot tell you.

    You need two connected records: a repeatable visibility baseline and an event log that shows exactly what changed, where, when, and why. Build those records before the next launch and you can separate a durable gain from sampling noise, an engine-specific shift, seasonal demand, or an unrelated platform change.

    Measure visibility as a set of signals, not one score

    A single visibility score is convenient for reporting, but it hides the mechanism behind a change. Your brand can gain mentions while losing citations. An owned page can attract more citations while traditional search clicks remain flat. One AI engine can improve while another moves in the opposite direction.

    Start with the decision you need the data to support. If you want to know whether an entity-focused content update improved AI discovery, brand mentions and citations are primary measures. If you want to know whether a technical fix restored organic performance, query- and page-level Search Console trends matter more. Business outcomes belong in the system too, but they should not replace the visibility signal you are trying to diagnose.

    Measurement layerQuestion it answersMinimum useful measure
    Brand presenceHow often does the engine include you?Valid answers mentioning your brand divided by all valid answers in the tracked prompt set
    Owned citation visibilityHow often does an answer use one of your pages as evidence?Valid answers citing your domain, plus the exact cited URLs
    Third-party representationWhich external domains connect your brand to the subject?Domains and URLs that mention or support your brand in cited answers
    Competitive inclusionAre you considered alongside the alternatives buyers see?Prompt-level mentions of you and the named competitors you track
    Traditional search discoveryAre relevant pages and queries gaining exposure?Search Console impressions, clicks, click-through rate, and average position by page-query cluster
    Business responseDid the added visibility produce a useful action?Qualified visits, conversions, leads, or another preselected outcome

    Keep the numerator and denominator with every rate. A report that says brand visibility rose from one collection to the next is incomplete if the second collection contained more prompts, fewer valid answers, or a different mix of intents. Store raw counts beside percentages so someone can audit the movement without reconstructing the dataset.

    Build a fixed prompt panel before watching the trend

    An AI visibility series is only comparable when the questions remain comparable. Treat your core prompt panel like a measurement instrument, not a running list of interesting queries.

    1. Group prompts by a decision-relevant intent such as learning, evaluating options, comparing vendors, solving a problem, or choosing a product.
    2. Save the exact wording. Small wording changes can change the brands, sources, and recommendation frame that appear.
    3. Record the engine and surface separately. Include the visible model or mode label, collection time and time zone, locale, and any account conditions you can identify.
    4. Define a valid run. Timeouts, empty responses, blocked answers, and collection errors should not silently enter the denominator.
    5. Store the complete answer, every citation URL, and the scored fields. A summary score cannot answer a later question about why the result changed.
    6. Keep the core panel frozen. Put new questions in an exploratory panel until you deliberately version the baseline.

    Generative answers can vary even when the prompt does not. If your collection budget allows repeated runs, report how often a result occurs rather than selecting the most favorable answer. When repeated runs are not practical, keep the collection conditions stable and avoid treating a one-run change as proof.

    Do not blend every prompt into an unweighted average by default. A high-intent comparison prompt may matter more to your business than a broad informational prompt, but any weighting should be declared before you inspect the result. Otherwise the score becomes adjustable after the fact.

    Keep a separate time series for every search surface

    Four separate transparent channels carry colored signal pulses through matching circular measuring gates.

    AI engines do not use interchangeable recommendation or citation systems. In a three-month Semrush sample of 2,500 real-world prompts across five sectors, ChatGPT’s cited-source count grew by 80% in October, while Google AI Mode’s source diversity rose by 13% from August to October. Those are sampled platform movements, not universal benchmarks, but they show how much the environment around your own result can change.

    The same sample recorded 67% agreement on brand mentions but only 30% agreement on sources between ChatGPT and Google AI Mode. A brand-level total can therefore look stable while the pages and external authorities producing that visibility change substantially.

    Your dashboard should preserve those differences rather than averaging them away:

    • Give each engine and search surface its own series. Add a cross-platform total only as a secondary view.
    • Segment by prompt intent, market, language, product line, and audience when those dimensions affect the decision. Do not compare segments with materially different prompt counts as if they were equivalent.
    • Track brand mentions and citations separately. A mention tells you that the entity appeared; a citation tells you which page or domain helped support the answer.
    • Show source diversity beside your own citation rate. Your citation count can stay level while your share of a widening source pool falls.
    • Preserve the answer text and citation list for every collection. When a line moves, you need evidence you can inspect rather than only a score you can chart.
    • Display valid runs, failed runs, and total scheduled runs. A collection failure should look like a data-quality problem, not a visibility loss.

    Choose a collection cadence that matches the decision. Before a migration, redesign, structured-data deployment, or major content release, take a frozen baseline. Repeat the same panel on a consistent schedule afterward. A slower schedule can work during steady-state monitoring, but changing the interval whenever results become interesting makes the time series harder to interpret.

    Do not overwrite history when you change the prompt panel or scoring rules. Create a new version, record its start date, and show a break in the series. Otherwise a methodological change can masquerade as a search-performance change.

    Use an event log that records scope, mechanism, and ownership

    Blank event tiles and change-related objects lead toward a glass prism separating a bright signal from scattered particles.

    In this measurement system, an event is a change that could affect visibility. It is not the same thing as a user interaction event such as a click, form submission, or purchase. Interaction events measure outcomes. Change events explain why the conditions around those outcomes may have shifted.

    A useful event log includes more than a launch date and a vague note. Give every material change a durable event ID and record these fields:

    FieldWhat to recordWhy it matters
    Event IDA unique, permanent identifierConnects chart annotations, tickets, deployments, and analysis
    Effective timeDate, time, and time zone when the change reached users or crawlersPrevents a ticket-creation date from being mistaken for a release date
    Event typeTechnical, content, structured data, authority, measurement, external, or platformSupports filtering and reveals overlapping changes
    ScopeExact URLs, templates, directories, query clusters, prompt cohorts, markets, and languages affectedCreates a testable boundary for the expected movement
    DescriptionWhat changed, using concrete before-and-after languageMakes the record understandable months later
    HypothesisExpected metric, direction, affected segment, and mechanismStops the success definition from changing after results arrive
    OwnerPerson or team responsible for the changeProvides a route to implementation details when the graph moves
    Evidence linksTicket, deployment, content brief, crawl, test, or release recordPreserves the detail that will not fit in a chart annotation
    ConfoundersOther launches, outages, campaigns, holidays, or known platform events in the same periodPrevents an overlapping event from receiving all the credit or blame
    StatusPlanned, deployed, rolled back, or supersededSeparates intended work from what actually remained live

    Scope is the field most teams under-document. “Updated product content” is not testable. “Rewrote comparison copy on /product-a/ and /product-b/ for the vendor-selection prompt cohort” gives you affected pages, an affected intent, and an unaffected group you can use for context.

    Use a controlled event vocabulary so similar work can be filtered together. Technical events can include migrations, template releases, rendering changes, internal-link changes, outages, and bug fixes. Content events can include new pages, consolidations, intent shifts, title changes, and factual updates. Representation events can include structured-data changes, third-party coverage, new citations, and material changes to brand or product naming. Measurement events include prompt-panel revisions, tracking-code changes, scoring-rule changes, and data-collection failures.

    Use Search Console annotations as pointers, not the master record

    Google Search Console can place a change note directly on a Performance chart: right-click the relevant date, select the date, enter the note, and add it. That is useful when someone investigating a spike or decline needs immediate context.

    The built-in annotation should not be your only event store. Search Console notes are limited to 120 characters and 200 annotations per property, cannot be edited, and are automatically removed after 500 days. They are also visible to everyone with access to the property, so confidential details do not belong there.

    Put the event ID, scope, short change description, and owner in the annotation. Keep the complete record in your durable change log. A compact note can follow this pattern: “EVT-142 | /pricing/* | FAQ schema removed | owner: SEO.” If the note is wrong, delete it and add a corrected one; editing is not available.

    Add annotations for measurement changes too. If you revise the prompt panel, change a dashboard formula, fix missing tracking, or alter a page-query grouping, the apparent trend may change even when search behavior does not. A measurement event makes that discontinuity visible.

    Turn a graph movement into a defensible decision

    An event marker shows coincidence, not causation. The change becomes more credible when timing, scope, mechanism, and independent signals line up. Use the same review sequence every time so a desirable result does not receive a lower standard of proof than an undesirable one.

    1. Validate collection integrity. Confirm that prompt-panel version, engine, locale, scoring rules, denominators, and failure handling match the comparison period.
    2. Inspect the raw evidence. Read changed answers, open changed citations, and verify that the brand or page was scored correctly.
    3. Locate the movement. Identify the engine, prompt cohort, query cluster, page group, market, and metric responsible for the aggregate change.
    4. Match the scope. Ask whether the movement occurred where the logged event could reasonably have had an effect. A change to one directory should not automatically receive credit for a sitewide rise.
    5. Check the timing without demanding an instant response. Crawling, indexing, search evaluation, and generative citation behavior do not share one universal delay. Record when movement first appears rather than inventing a standard lag.
    6. Compare an unaffected group. Unchanged pages, prompt cohorts, markets, or competitors can show whether the movement was specific to your change or part of a wider shift.
    7. Triangulate signals. Look for a compatible pattern across mentions, owned citations, third-party citations, Search Console visibility, site visits, and the intended business outcome.
    8. Assign an evidence status. Use labels such as supported, plausible but inconclusive, contradicted, or not yet observable. Reserve causal language for cases in which the evidence genuinely supports it.

    The combination of signals often tells you what to inspect next:

    • If brand mentions fall on one engine while citations remain stable, inspect the changed recommendation language and competing brands before rewriting cited pages.
    • If citations to your domain fall while total source diversity rises, calculate whether you lost absolute citations or were diluted by a larger pool. Those lead to different responses.
    • If Search Console impressions fall only in the page-query cluster touched by a technical release, the release deserves closer inspection. Check an unaffected cluster before calling it the cause.
    • If several engines and traditional search move together without a scoped site event, investigate demand, seasonality, outages, campaigns, and platform-level changes before crediting routine content work.
    • If AI mentions improve but qualified visits and conversions do not, record a discovery gain rather than declaring a business win. The visibility may still matter, but the outcome has not been demonstrated.

    Do not judge every event by an immediate conversion change. A structured-data fix might first affect eligibility or interpretation. An entity-focused content update might first change mentions or citations. The primary metric should match the proposed mechanism, while downstream metrics show whether the effect eventually became commercially useful.

    When the evidence remains mixed, keep the result inconclusive and continue collecting. Reversing a safe, isolated change can sometimes provide a stronger test, but do not use a rollback when it risks data loss, breaks a migration, removes required information, or creates avoidable business exposure. In those cases, compare affected and unaffected scopes instead.

    Key takeaways

    • Keep brand mentions, citations, traditional search visibility, and business outcomes as separate measures before considering a blended score.
    • Use a fixed, versioned prompt panel and preserve exact prompts, full answers, citation URLs, collection conditions, valid runs, and failures.
    • Measure every AI engine and search surface independently because brand and source behavior can diverge.
    • Give every material site, content, schema, authority, platform, or measurement change a permanent event ID with exact scope and a predeclared hypothesis.
    • Use Search Console annotations to point to a durable event record; their character, volume, editing, retention, and access limits make them unsuitable as the only log.
    • Call a result supported only when timing, scope, mechanism, and multiple relevant signals align.

    Freeze your core prompt panel, define the denominator for each metric, and create the event log before your next release. Then backfill the few recent changes most likely to affect the pages and prompts you track. The next time visibility moves, you will have a specific explanation to test and a clear decision about what to keep, investigate, or change.

    References

  • How to Choose a Generative Engine Optimization Agency

    How to Choose a Generative Engine Optimization Agency

    If you’re comparing generative engine optimization agencies, the difficult part isn’t finding one that talks about AI visibility. It’s determining whether the agency can improve the evidence surrounding your brand, observe how generative systems use that evidence and connect the work to a business result you care about.

    You need a selection process that exposes the difference between a renamed SEO package and a genuine cross-functional GEO program. The right questions will also protect you from paying for an impressive dashboard that never changes what ChatGPT, Google Gemini, Perplexity or their users actually see.

    Define the failure before you make a shortlist

    Do not begin with a goal such as improve our AI visibility. It gives an agency too much room to choose an easy metric after the work begins. Start with the failure a customer can observe.

    • Your brand is absent when buyers ask for suitable providers in your category.
    • The brand appears, but the description is inaccurate or outdated.
    • Your company is mentioned as background information but omitted from recommendations.
    • A competitor is repeatedly cited for a topic on which your organization has stronger expertise.
    • Your pages receive citations or referral visits, but those visitors do not find a useful next step.
    • Your visibility is acceptable for broad informational questions but weak for buying, comparison or implementation questions.

    These are different problems. An inaccurate company description may point to inconsistent entity information across your site and third-party profiles. Missing citations may expose a content, accessibility or authority gap. Weak recommendations may reflect thin proof, limited independent validation or an unclear fit between your offer and the user’s criteria. Poor conversion after a referral is primarily a landing-page and offer problem.

    Give every prospective agency the same written brief. Include the audience, product or service, markets, languages, customer questions, named competitors, target generative engines and current failure. Add the business action you want after discovery, such as a qualified enquiry, trial, purchase or sales conversation. The agency should be able to challenge the brief, but it should not be allowed to replace your commercial objective with its preferred visibility score.

    You may not need a broad GEO agency if the problem is narrow. A technical SEO specialist can address a clearly diagnosed crawling, rendering or structured-data defect. An editorial team may be enough when useful pages simply do not exist. A reputation or public-relations specialist may be a better lead when credible third-party information is the main gap. A GEO agency earns its broader remit when these problems overlap and one accountable team must coordinate them.

    Match the agency model to the work you actually need

    Three differently structured agency teams work with research materials, technical systems and editorial assets around a shared glowing hub.

    A credible GEO program usually has to coordinate SEO, content creation, technical optimization, review management, social media and public relations. That does not mean every provider must perform every task internally. It does mean someone must explain how the workstreams reinforce one another, who owns each one and where handoffs occur.

    Look for inspectable deliverables in each relevant workstream:

    • Discovery and query mapping: A defined set of real customer questions grouped by intent, audience and stage of decision. The map should identify the answers, brands and citations that currently appear, not merely list search keywords.
    • Technical and entity clarity: Corrections to crawlability, canonicalization, rendering, internal linking and contradictory organization or product facts. Structured data should represent information visible on the page and validate correctly. Installing schema is an implementation task, not a guarantee that an AI system will cite or recommend the entity.
    • Content improvement: Pages that answer the exact questions buyers ask, state important limitations, support claims and make authorship or organizational responsibility clear. A publication calendar without a documented information gap is not a GEO strategy.
    • Independent corroboration: A plan for legitimate reviews, relevant media coverage, expert participation and accurate third-party profiles. The objective is a stronger public evidence trail, not artificial mentions or fabricated consensus.
    • Distribution: A reasoned choice of channels that can put useful material in front of customers, journalists, communities and other publishers. Social posting volume by itself is not evidence of greater generative visibility.
    • Observation and iteration: A repeatable method for capturing answers, mentions, recommendations, citations, factual errors and referral behavior. The method should preserve enough context to make one observation comparable with the next.

    Agency positioning recorded in 2025 ranged from full-service GEO to small-business, technical, paid-media, analytics-led, niche-market, retail and industry-specific offerings. That breadth is a warning against buying the category label. Choose the operating model that matches the diagnosed constraint.

    Agency modelBest fitWhat to verify
    Integrated or full serviceYour gaps span technical SEO, content, reputation and authority buildingNamed owners, handoff rules and evidence that the disciplines share one plan
    Technical-ledYour site has indexing, rendering, architecture, entity or structured-data problemsWhether the team can also diagnose content and offsite evidence gaps instead of treating every problem as code
    Content-ledYour organization has expertise but has not published clear, decision-useful answersEditorial standards, claim substantiation, subject-matter review and a distribution plan
    Authority or reputation-ledYour owned content is strong but independent corroboration is weak or inconsistentPlacement disclosure, review integrity, relevance and how factual corrections are handled
    Vertical specialistTerminology, regulation, buyer behavior or trusted publications are unusually specific to your marketDirect evidence of relevant work rather than a generic client logo from the same industry
    Paid-media hybridPaid acquisition is a separate part of the commercial planClear separation between purchased exposure and observed organic inclusion in generative answers

    Client names can establish that an agency has operated at a certain level, but a logo does not prove GEO experience. Ask which service the client bought, what the team changed and which evidence can be discussed. An SEO, advertising or reputation-management relationship should not quietly become a GEO case study during the sales process.

    Leadership experience, independent customer reviews, employee tenure, founder involvement and credible media references are useful secondary checks. Interpret them carefully. Founder access can speed decisions but does not prove delivery capacity. Longer employee tenure can reduce handoff risk but does not establish technical skill. Media attention establishes visibility, not client performance. Third-party reviews are most useful when they describe communication, execution and the kind of engagement you are considering.

    Make every contender prove how the work will operate

    An agency team demonstrates how source documents move through research, technical review and editing while clients observe the workflow.

    Send the same evidence request to every shortlisted firm before a presentation. Comparable answers reveal more than a polished custom pitch. Ask for written responses to these questions:

    1. What do you believe our actual visibility problem is? The answer should distinguish discovery, citation, recommendation, factual accuracy, referral and conversion problems.
    2. How will you establish the baseline? Ask what prompts will be used, how they will be grouped, which engines will be observed and how language, geography, date and other relevant context will be recorded.
    3. Which changes can you make directly? Separate work on your website from editorial recommendations, review programs, outreach, public relations and changes that require another team.
    4. What will we receive? Request examples of an audit, query map, technical specification, content brief, reporting view and change log. A list of activities is not the same as a set of usable deliverables.
    5. Which claimed clients purchased GEO work? Ask for the problem, deliverables, observation method and result that can be substantiated. If confidentiality prevents disclosure, the firm should still be able to explain its method without exposing client information.
    6. How do you separate a mention, citation and recommendation? These are not interchangeable. A brand can appear in an answer without being endorsed, and a cited page can supply background information without generating a qualified visit.
    7. How do you handle variable outputs? Generative answers can change across prompts and repeated observations. The agency should retain the underlying answer evidence and discuss patterns, not turn an isolated favorable response into a performance claim.
    8. Who will perform each part of the work? Get the names or roles of the strategist, technical lead, editor, outreach or PR owner and analyst. Clarify which work is outsourced and who reviews it.
    9. What cannot be guaranteed? A trustworthy answer acknowledges that the agency does not control a generative model, its retrieval systems or its final response.
    10. How will success connect to our business? The firm should explain how visibility observations will be considered alongside referrals, engaged visits, conversions, qualified demand and other commercial signals relevant to your brief.

    Reject claims that cannot survive inspection

    You can shorten the process by rejecting a proposal when its central promise depends on any of these:

    • A guaranteed ranking, citation or recommendation inside a system the agency does not control.
    • A proprietary visibility score with no access to the prompts, captured answers, citations or scoring rules underneath it.
    • A one-time schema installation presented as the complete GEO program.
    • High-volume AI-generated content without subject-matter review, claim verification or a documented audience need.
    • A case result that omits the baseline, work performed or definition of success.
    • SEO, public-relations or advertising clients presented as GEO clients without confirmation that they bought GEO services.
    • Paid placements blended into an organic AI visibility result.
    • Review generation, community posting or media outreach that depends on fabricated identities, concealed incentives or undisclosed placements.

    Also pay attention to what happens when you challenge a metric. A capable team should welcome precise definitions because those definitions protect its work from being misread. Evasion at the proposal stage will become ambiguity in the performance report.

    Contract for evidence, ownership and an honest measurement model

    GEO measurement works best as a chain. Implementation shows what was changed. Answer observation shows whether your presence changed for a defined set of questions. Audience data shows what people did when a trackable visit occurred. Commercial data shows whether those interactions contributed to the outcome in your brief. No single layer can prove the entire chain.

    Measurement layerUseful evidenceWhat it cannot prove alone
    ImplementationTechnical fixes, corrected entity facts, published pages, earned coverage and completed profile updatesThat a generative system used or trusted the change
    Observed visibilityMentions, recommendation inclusion, citations and factual accuracy across the defined query setA permanent rank or visibility outside the observed questions and conditions
    Audience responseReferral sessions, landing-page engagement, conversions and later branded interactions where measurableThe full influence of answers that produced no direct click
    Commercial contributionQualified enquiries, pipeline, purchases or another agreed business outcome under a stated attribution methodCausation when several marketing and sales activities influenced the same decision

    Require the baseline and follow-up observations to use the same core query set and recording protocol. The agency may add newly discovered questions, but it should label them as additions rather than mixing them into the original comparison. Preserve captured answers and cited URLs. A trend line without the underlying evidence is difficult to audit and easy to overinterpret.

    Do not treat referral traffic as a complete GEO metric. A recommendation may influence a later branded search, a direct visit or a conversation with sales rather than produce an immediate click. At the same time, do not accept that measurement difficulty makes business accountability optional. Agree in advance which direct and assisted signals will be reviewed and what each signal can reasonably demonstrate.

    The statement of work should settle the operational questions before execution begins:

    • Phasing: Put diagnosis, baseline creation and roadmap approval before broad production. Include an off-ramp if the diagnosis does not support the proposed retainer.
    • Deliverables: Name the artifacts, channels and responsible parties. Replace vague promises such as ongoing optimization with specific work products and approval points.
    • Measurement protocol: Define the target engines, query set, captured evidence, metric definitions and treatment of newly added prompts.
    • Publishing controls: Require your approval for factual, legal, medical, financial, product or performance claims relevant to your organization. The agency should not create authority by publishing claims your business cannot substantiate.
    • Account access: Use the minimum access needed for the work and document who can publish, change technical settings or connect analytics. Remove access as part of the exit process.
    • Asset ownership: Ensure your organization can export and retain audits, prompt libraries, content briefs, schemas, dashboards, captured answers, outreach records and final creative work. Ambiguous ownership can force you to rebuild the operating system when the relationship ends.
    • Dependencies: Record what your developers, subject-matter experts, legal reviewers, sales team and executives must provide. Otherwise, an agency can attribute missed delivery to an approval bottleneck that was never planned.
    • Change log: Connect observed movement to dated technical, editorial and offsite work. This does not prove causation, but it makes analysis more disciplined.
    • Exit and handoff: Specify final exports, access removal, open-work status and the person responsible for transferring knowledge.

    If intellectual-property, data-use, indemnity or publishing terms create material exposure, have the contract reviewed by qualified counsel. The practical safeguard is simple: do not assume that paying for an asset means you own it or can reuse it. Put the answer in the agreement.

    Key takeaways

    • Define the visible failure and business outcome before asking an agency for a strategy.
    • Choose a broad GEO agency only when your problem genuinely crosses technical, content, reputation, distribution and measurement workstreams.
    • Verify that client examples involved GEO services; a recognizable logo from unrelated SEO or advertising work is not enough.
    • Demand access to the prompts, captured answers, citations and scoring definitions behind every visibility metric.
    • Measure implementation, observed visibility, audience response and commercial contribution as separate layers.
    • Phase the engagement, preserve an off-ramp and keep ownership of the data, accounts and reusable assets created for your organization.

    Your next move is to write the brief before booking another agency demonstration. Send each contender the same problem statement and evidence questions. The firm that can define the limits of its method, expose its working evidence and connect deliverables to your commercial goal is giving you far more useful information than the firm promising to make your brand the answer everywhere.

    References