Author: shivamcrushpressai

  • AI Search Visibility Optimization: An Actionable Framework

    AI Search Visibility Optimization: An Actionable Framework

    If your pages rank in Google but disappear when a buyer asks ChatGPT, Gemini, or Perplexity what to choose, you do not have a conventional ranking problem. You have a chain-of-trust problem. The assistant must be able to reach your information, understand what it means, reconcile it with information elsewhere, and decide that it is relevant and credible enough to use.

    That changes where you should start. Publishing more content or adding AI-related keywords will not repair a blocked crawler, a confused business identity, or conflicting location data. Audit the full path to an AI answer, then fix the earliest point at which your visibility breaks.

    AI visibility is a connected system, not a single ranking

    Traditional rank tracking asks where a page appears for a query. AI search visibility covers several different outcomes: whether an assistant mentions your brand, uses your content, links to your site, states your facts accurately, or recommends you as a suitable choice. A brand can succeed at one outcome and fail at another.

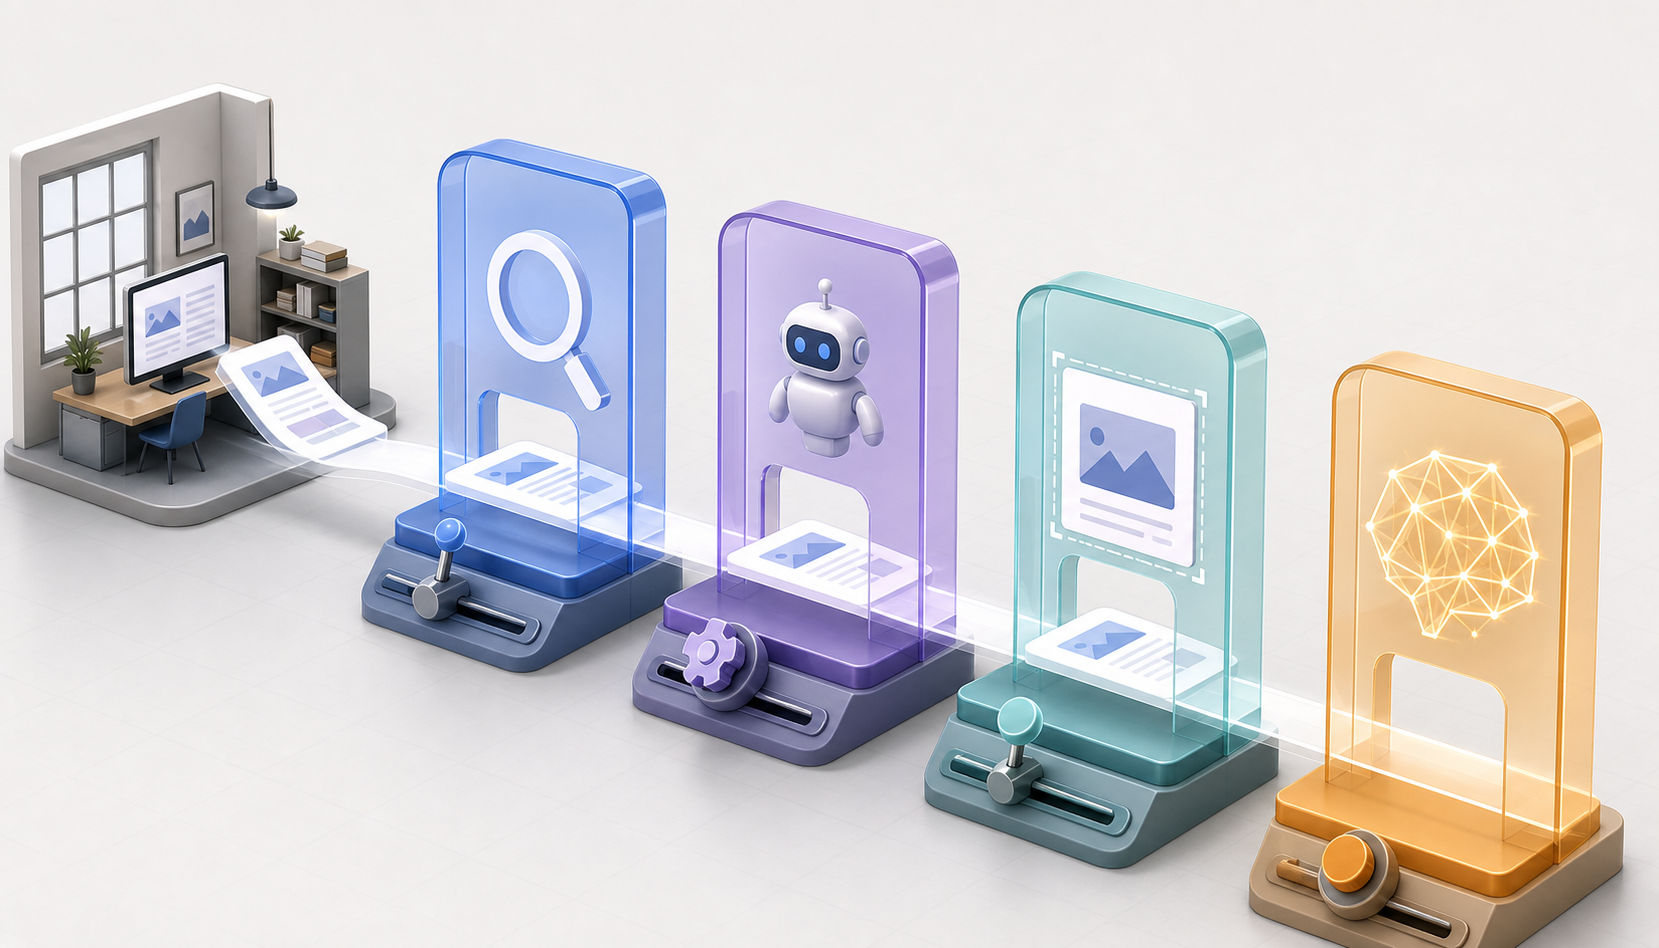
    A practical audit separates the system into these stages:

    • Access: Can retrieval systems and permitted bots reach the important public pages without being blocked by robots rules, authentication, a firewall, or a challenge page?
    • Interpretation: Does each page make the subject, claim, location, product, and relationship between entities explicit?
    • Corroboration: Do your website, business profiles, reviews, and other public records agree on the facts that matter?
    • Selection: Does your information answer the user’s actual task well enough to be cited or recommended?

    The order matters. Better copy cannot compensate for a page that cannot be retrieved. Perfect crawl access cannot resolve two different addresses for the same location. Consistent facts do not guarantee selection when the page never answers the question behind the prompt.

    What you observeLikely bottleneckFirst check
    Important public pages are absent from retrieval or crawler logsAccessRobots rules, authentication, CDN controls, and firewall challenges
    Assistants state an old address, name, or service detailInterpretation or corroborationThe canonical page and every prominent public profile carrying that fact
    Your pages are cited for facts, but your brand is not recommendedConfidence or task fitReputation signals, comparative evidence, and whether the offer fits the prompt
    Google visibility is strong while assistant visibility is weakSelectionA separate prompt-level baseline for each assistant

    Do not label every absence a crawl problem. If an assistant accurately summarizes a page but does not mention your brand, it obtained the information through some path. Your next work belongs farther down the chain, usually in attribution, corroboration, or selection.

    Prove access before you rewrite the content
    A glowing crawler-like orb follows an open route through a cutaway website structure while other routes are blocked by barriers.

    Start with the pages closest to discovery, evaluation, and conversion. These are usually your main service or product pages, location pages, comparison resources, original research, documentation, pricing explanations, and pages that answer recurring pre-sale questions. The goal is not to make every URL equally prominent. It is to ensure that your most useful public information is technically reachable.

    1. Fetch each priority URL without a login. Confirm that the response contains the intended page, not a consent wall, security challenge, empty shell, or error message.
    2. Read robots.txt as a set of instructions. Look for broad disallow rules, overlapping bot-specific directives, and stale rules left by a migration or staging environment.
    3. Inspect controls outside robots.txt. A CDN, web application firewall, rate limit, or bot-management product can reject a request even when the robots file allows it.
    4. Follow redirects to the final page. The destination should remain public, load the substantive content, and identify the stable canonical version of the URL.
    5. Review server and security logs. Look for successful requests, repeated rejections, redirects, and challenge responses associated with the crawlers you intend to permit.
    6. Retest after changing a rule. A configuration edit is not proof that the final URL is reachable through the full delivery stack.

    Refining robots.txt and maintaining a useful llms.txt file can improve the conditions under which AI bots discover your content. The files serve different jobs. Robots.txt communicates crawl permissions. An llms.txt file can act as a concise map to important, canonical resources.

    If you publish llms.txt, keep it selective. Point to pages that explain who you are, what you offer, and where your strongest reference material lives. Remove redirected, duplicated, expired, and thin URLs. Update the file when important destinations change. A stale directory creates another version of your site for machines to reconcile.

    Treat llms.txt as a signpost, not an access-control system or a visibility guarantee. It does not override robots.txt, authentication, firewall rules, or a broken page. It also does not replace ordinary internal links and crawlable site architecture. Do not expose private, administrative, customer, or staging URLs merely to make a crawler test pass.

    Your access audit passes when a priority public URL can be retrieved without credentials, returns the intended substantive content, survives the redirect path, identifies a stable canonical destination, and is not rejected by a rule or security control you meant to allow.

    Make your identity, evidence, and suitability easy to resolve

    Build pages around complete, extractable answers

    An extractable page does not need robotic prose. It needs explicit relationships. A reader and a retrieval system should both be able to identify what the page answers, which entity the answer concerns, where the claim applies, and what supports it.

    • Use a descriptive heading that matches a real question or decision rather than a vague slogan.
    • Name the company, product, service, or location before relying on pronouns such as it, this, or we.
    • Give the direct answer first, then add conditions, exceptions, evidence, and next steps.
    • Keep supporting evidence close to the claim it supports. Do not make a reader hunt through unrelated pages to understand the basis of an important statement.
    • Distinguish facts from positioning. Availability, location, compatibility, and eligibility should not be buried inside promotional language.
    • Use internal links with descriptive anchor text so the relationship between an overview, supporting evidence, and a detailed resource is apparent.
    • Keep structured data, including JSON-LD, aligned with the visible page. Markup should clarify information that users can verify on the page, not introduce a separate set of claims.

    Page structure is especially important when a fact has a limited scope. If a service is available only in a particular region, a feature applies only to one plan, or a result depends on stated conditions, carry that qualifier into the answer itself. A technically accurate sentence can still create a wrong AI answer when its limiting context is several paragraphs away.

    Give every team one record of core business facts

    Create an internal fact sheet for the details that assistants and customers must not get wrong. Include the official brand and location names, canonical URLs, contact details, addresses, operating hours, service areas, categories, and current descriptions of the main products or services. Assign an owner to each field so an operational change has somewhere to go before conflicting versions spread.

    Audit those facts across your own site and the external platforms likely to carry them, including Google Maps, Yelp, and Facebook. Check each location separately. A correct corporate address does not repair an incorrect branch profile, and a correct branch page does not erase stale hours elsewhere.

    Consistency does not require identical marketing copy on every platform. It requires agreement on verifiable facts. Preserve platform-appropriate descriptions, but remove conflicts in identity, location, availability, and contact information. When you find a discrepancy, correct the system that owns the bad record rather than merely publishing another page with the right answer.

    Treat reputation as a confidence signal, not decoration

    AI recommendations are markedly selective in the local context measured by SOCi’s 2026 Local Visibility Index. Across nearly 350,000 locations belonging to 2,751 multi-location brands, ChatGPT recommended 1.2% of locations, Gemini recommended 11%, and Perplexity recommended 7.4%. Brands appeared in Google’s local three-pack 35.9% of the time. The resulting gap ranged from about three to 30 times within that dataset.

    Those percentages describe a particular multi-location sample, not a universal multiplier for every query, industry, or business. They still expose a costly assumption: strong local Google performance is not a dependable proxy for AI recommendations.

    Profile accuracy also differed by assistant in the same dataset. Gemini returned accurate business information in 100% of the measured cases, while ChatGPT and Perplexity reached 68%. That variation is a reason to inspect individual answers and platforms, not to calculate one blended visibility score that hides factual errors.

    Ratings appeared to work more like a confidence filter than a simple ranking boost. Locations recommended by ChatGPT averaged 4.3 stars, with slightly lower averages for Gemini and Perplexity. Do not turn 4.3 into a supposed eligibility threshold; it is an observed average, not a published cutoff. Use it as a prompt to examine the underlying customer experience, recurring complaints, unresolved listing errors, and whether your public reputation supports the recommendation you want an assistant to make.

    Measure mentions, citations, accuracy, and recommendations separately
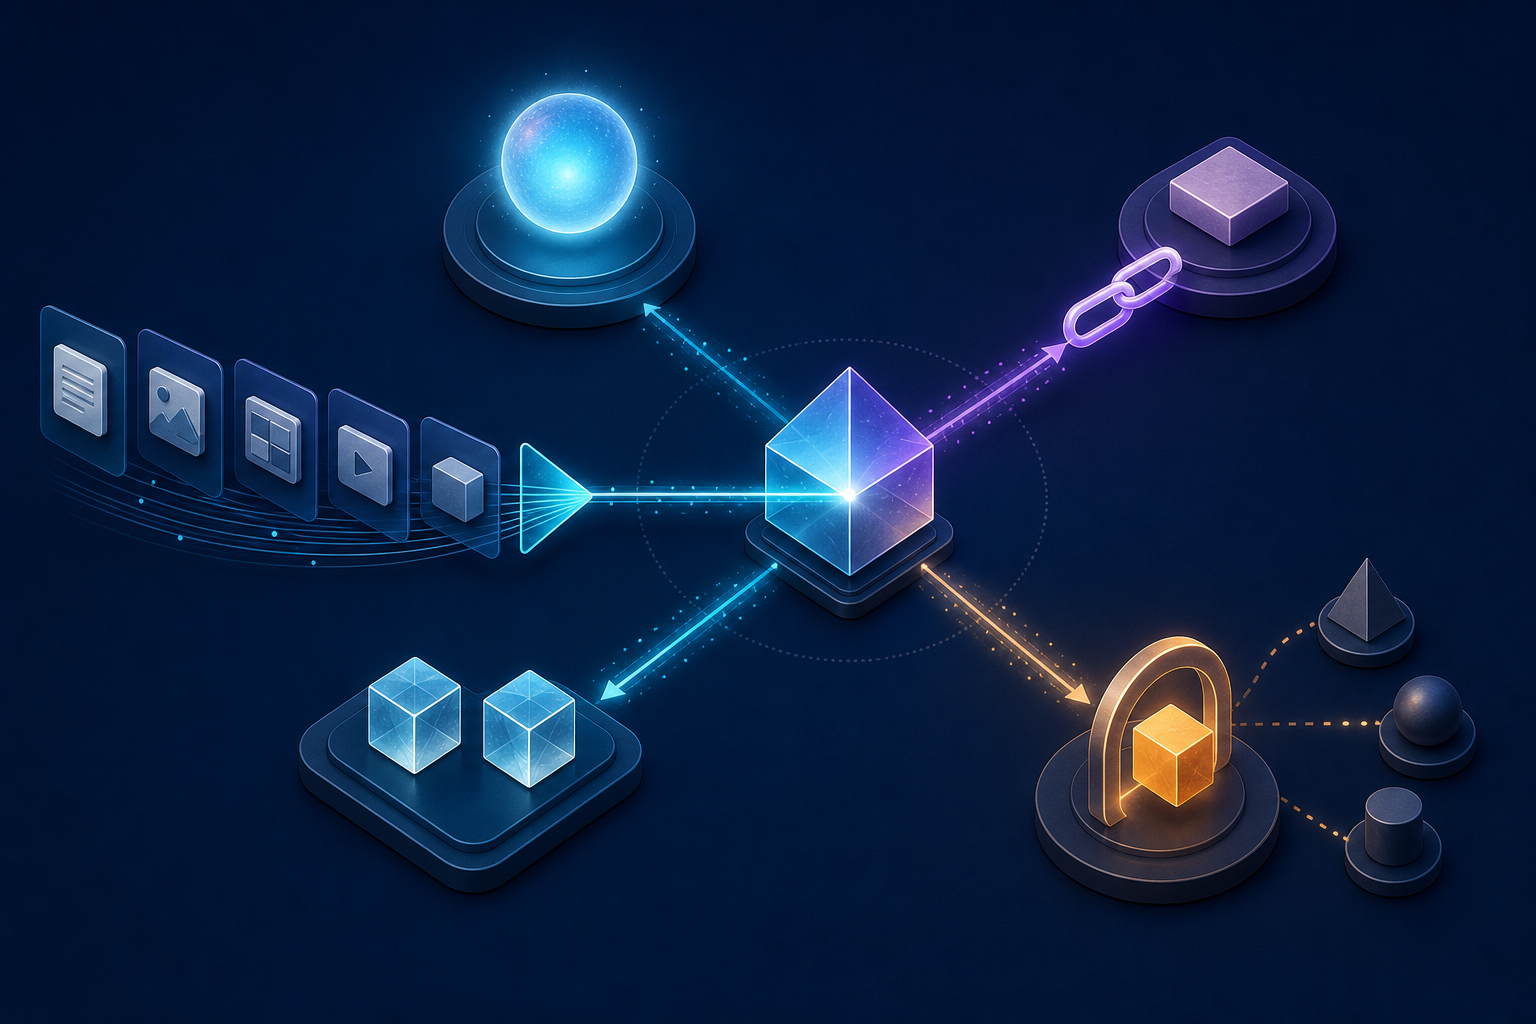
    A central AI prism connects to four abstract outcomes represented by a presence orb, source link, matching objects, and a selected object passing through a gateway.

    A conventional position report cannot show whether an assistant named your brand, recommended it, cited it, or repeated an incorrect fact. Build a prompt-level measurement set around the tasks your audience actually performs.

    • Discovery prompts: The user is identifying possible approaches, providers, products, or locations.
    • Comparison prompts: The user is weighing alternatives against explicit requirements.
    • Suitability prompts: The user wants to know what fits a particular situation, industry, location, or constraint.
    • Factual prompts: The user needs an address, capability, policy, compatibility detail, operating hour, or other verifiable fact.
    • Branded prompts: The user already knows your name and expects an accurate explanation.
    • Non-branded prompts: The user describes the need without giving the assistant your brand as a hint.

    For every test, record the exact prompt, platform, model or product surface when identifiable, location context, account state, test date, complete answer, cited URLs, brand mentions, recommendation status, and factual errors. Preserve the response itself. AI answers can vary, and a result you did not save cannot be audited later.

    Keep the core metrics separate:

    • Visibility rate: the share of eligible responses that mention your brand.
    • Recommendation rate: the share that present your brand as a suitable option, not merely as background.
    • Citation rate: the share that link to or explicitly identify your owned content.
    • Factual accuracy: whether the material facts stated about your brand are correct and current.
    • Cross-platform consistency: whether different assistants produce materially compatible descriptions of the same entity.

    A single answer is an observation, not a trend. Retest the same prompt set under documented conditions and look for direction across repeated runs. Change a small, named group of inputs, log the change, and then use the same prompts again. Otherwise, you will not know whether an apparent improvement came from your work, answer variability, or a different testing context.

    Keep Google and AI results side by side, but never substitute one for the other. Fewer than half of the brands leading local Google visibility also led their sectors in AI outcomes. In retail, only 45% of the top 20 local-search brands also reached the leading group for AI recommendations. That is dataset-specific evidence for maintaining separate dashboards and separate diagnoses.

    Use the following sequence to turn the audit into work:

    1. Baseline the prompts connected to your highest-value customer decisions.
    2. Resolve access failures on the pages that should answer those prompts.
    3. Correct conflicting identity, location, product, and availability facts.
    4. Rewrite weak pages so the direct answer, scope, evidence, and entity relationships are explicit.
    5. Repair inaccurate external profiles and address the operational causes of recurring negative sentiment.
    6. Retest the same prompt set and classify each remaining failure as an access, interpretation, corroboration, or selection problem.

    Key takeaways

    • Google rankings are useful context, but they do not predict whether an AI assistant will cite or recommend you.
    • Fix the earliest broken stage: access, interpretation, corroboration, or selection.
    • Robots.txt and llms.txt can support discovery, but neither repairs firewall blocks, private pages, weak answers, or conflicting facts.
    • Your site, Google Maps, Yelp, Facebook, and other prominent profiles should agree on verifiable business details.
    • Structured data should reinforce visible content, not create claims that users cannot verify on the page.
    • Measure mentions, recommendations, citations, and factual accuracy separately for each assistant.
    • Review averages from a multi-location dataset are diagnostic context, not universal eligibility thresholds.

    Start with one high-value query cluster rather than a site-wide rewrite. Confirm that its best pages are reachable, align the facts across your public presence, strengthen the direct answers and supporting evidence, and capture a baseline in the assistants your audience uses. That gives you a controlled unit of work and a result you can actually diagnose.
    References

  • Meta Paid Subscriptions: A Decision Guide for Marketers

    Meta Paid Subscriptions: A Decision Guide for Marketers

    If Meta offers you a paid tier inside Instagram, Facebook, or WhatsApp, don’t start with the length of the feature list. Start with the recurring problem you need the subscription to solve. A premium control is valuable only when it changes a decision, removes meaningful work, or produces a measurable business result.

    That distinction matters because Meta is experimenting with several kinds of value at once: audience controls, deeper insights, AI creation capacity, and AI-assisted productivity. You need a way to evaluate each capability without assuming that payment automatically buys attention.

    What Meta is actually testing across its apps

    Meta is testing paid subscriptions on Instagram, Facebook, and WhatsApp. The core experiences are expected to remain free, and the experiments are being developed as app-specific offerings rather than one universal bundle.

    These subscriptions are also separate from Meta Verified. That is an important purchasing distinction. Verification-related value and access to premium creation, productivity, or audience tools should be evaluated as different products, even if they eventually appear next to each other in an account.

    Instagram’s initial candidates may include unlimited audience lists, information about non-followers, and stealth Story viewing. Treat those as provisional examples, not a promised package. A feature displayed in another account, market, or test does not belong in your business case until it appears in the offer available to you.

    AI is a larger part of the direction. Meta intends to give paying users greater access to its Vibes AI video generator through a freemium model. It also plans to embed the Manus AI agent in its apps and offer separate Manus subscriptions to businesses. Meta acquired Manus for $2 billion, and an Instagram shortcut has been reported as part of the prospective integration. The investment shows that AI is not merely a decorative subscription extra, but it still does not tell you which workflows the final products will support.

    Put every proposed feature into one of four practical buckets:

    • Control: who can see something, how an audience is organized, or how you interact with content.
    • Intelligence: information that can improve a content, audience, or campaign decision.
    • Production: tools or capacity that help create more usable assets.
    • Productivity: assistance that removes steps from a repeatable workflow.

    This classification gives each feature an owner and a measurement plan. It also exposes vague offers. If your team cannot identify the bucket, the recurring job, and the expected result, the feature is not ready for a budget.

    Paid access does not automatically mean greater reach

    An unbranded phone unlocks a set of premium tools while a distant audience remains the same size and distance away.

    Nothing in the subscription test description establishes that paying will give posts preferential ranking or guaranteed distribution. Do not build a forecast around an algorithmic advantage that Meta has not explicitly offered.

    A subscription could improve results indirectly. Better non-follower information might change what you publish. More AI video capacity might let you test additional creative ideas. Audience lists might make a recurring sharing workflow easier. In each case, however, the paid feature is only the first link in a longer chain:

    • Entitlement: your account receives access to the feature.
    • Adoption: someone uses it in a defined workflow.
    • Audience effect: the resulting content or interaction produces a different response.
    • Business effect: that response contributes to a qualified visit, lead, sale, retention outcome, or documented cost saving.

    Only entitlement follows directly from the transaction. You have to demonstrate the other three. This is why impressions, generation counts, and time spent inside a premium interface are weak success measures on their own.

    The same discipline applies to SEO, answer engine optimization, and generative engine optimization. A paid Meta tool may help you create or adapt content, but it does not by itself produce a durable, crawlable, well-supported answer on your website. It also does not guarantee that a search engine or frontier model will cite your brand. Keep social production and owned-content visibility as connected but separately measured systems.

    If reach is your goal, write the hypothesis in mechanism terms. For example: non-follower insights will reveal a recurring topic gap; the team will use that gap to revise its content plan; the revised content should increase qualified actions from people outside the existing audience. That can be tested. “Premium will increase reach” cannot.

    Decide whether a feature solves a paid-worthy problem

    A long menu makes an offer feel valuable even when most of its features will never enter your workflow. Replace feature counting with a written decision gate.

    Answer five questions before checkout

    1. What recurring job is difficult now? Name the work, the person doing it, and where the friction occurs.
    2. Does the available tier support that job today? Verify the in-account offer. Do not pay for a roadmap, a reported test, or a feature available only to someone else.
    3. What action will change? More data is not an outcome. Identify the content, audience, or operating decision that the new information will alter.
    4. What evidence will establish value? Choose a workflow metric and a downstream metric before activating the tier.
    5. What is the exit rule? Set the minimum result required for renewal and the condition that will trigger cancellation or another controlled test.

    If you cannot answer the third question, wait. A dashboard that creates no decision is another reporting obligation, not an intelligence advantage.

    Translate candidate features into proof

    Candidate capabilityProblem it could solveEvidence worth collectingCommon purchasing mistake
    Non-follower insightsUnderstanding how people beyond the current audience respondA documented content decision followed by qualified actions from the relevant audience segmentPaying for more charts without changing the content plan
    Unlimited audience listsManaging repeated sharing to distinct groupsLess list-maintenance work and better response from the intended groupCreating segments that nobody owns or uses
    Additional Vibes capacityProducing more usable video variations from a defined conceptApproved assets per production hour and outcomes per published assetCounting generated clips instead of publishable, effective clips
    Stealth Story viewingA specific personal or research preferenceA clearly stated utility that justifies the recurring expenseInventing a growth case for a feature with no growth mechanism
    Manus integrationA workflow the available agent can demonstrably completeCompletion time, error rate, review work, and avoided tool costSubscribing because of the acquisition or future integration plan

    For a business, calculate a maximum defensible recurring price before the actual price influences your judgment. Use this structure: verified labor saved, plus attributable incremental contribution, plus the cost of any tool you can genuinely retire, minus added review and governance costs. If the subscription is mainly for personal utility, compare it with a fixed discretionary budget instead of manufacturing a commercial return.

    Because Meta intends to develop different offerings for its apps, run that calculation separately for Instagram, Facebook, and WhatsApp. An Instagram production benefit does not justify a WhatsApp fee unless the WhatsApp tier independently improves a workflow you use.

    Test the workflow before making the subscription permanent

    A marketer tests an unbranded phone feature through a tabletop workflow that compares time, remaining work, results, and recurring cost.

    A new tool often receives extra attention during its first use. That novelty can look like productivity. A useful pilot captures all the work around the feature and holds unrelated variables steady.

    1. Capture a baseline. Use one complete, representative content or operating cycle. Record time, output, review work, and the downstream result with exact metric definitions.
    2. Choose one primary hypothesis. Tie one premium capability to one workflow change and one main result.
    3. Hold major confounders steady. Avoid changing publishing cadence, paid-media spend, offer, audience, and creative process at the same time.
    4. Log actual use. Record who used the feature, for which task, what failed, and how much correction or manual work followed.
    5. Inspect the full chain. Check entitlement, adoption, audience response, and business effect instead of stopping at platform activity.
    6. Apply the exit rule before the next billing decision. Renew, cancel, or run a narrower follow-up based on the threshold set before the test.

    A simple before-and-after pilot is not a true A/B test unless comparable users or outputs are assigned concurrently and other meaningful conditions are controlled. Call the method what it is. The goal is a decision-grade result, not a more impressive label.

    Measure AI output as a production system

    Generation speed alone will overstate the value of Vibes or any future AI feature. Include prompt preparation, source gathering, factual review, brand review, revisions, and publishing work. Useful operational measures include:

    • Approved assets per production hour: approved assets divided by the team’s total production and review time.
    • First-pass acceptance rate: assets approved without revision divided by all assets reviewed.
    • Publication rate: generated assets that were actually published divided by all generated assets.
    • Outcome per published asset: the chosen qualified action divided by the number of assets published.
    • Correction burden: review and revision time added because of factual, brand, or quality problems.

    These measures prevent cheap generation from hiding expensive review. They also let you compare an integrated Meta tool with your existing workflow without pretending that every generated variation has equal value.

    Keep your website as the factual source of truth

    If premium AI tools increase your social output, anchor that output in owned content. Publish the durable explanation, product information, evidence, or answer on your website first. Then derive platform-native clips and captions from the approved source.

    • Keep names, product details, definitions, and claims consistent between the web page and its social derivatives.
    • Give each substantive page a clear purpose, visible authorship where relevant, and a review process for material changes.
    • Use structured data only when it accurately represents content visitors can see on the page.
    • Link from social content when the page provides the useful next step, not merely to manufacture a click.
    • Measure social referrals, branded discovery, leads, and assisted outcomes separately; do not claim search or AI visibility from social activity alone.

    This arrangement gives AI production a controlled input and gives your audience a stable place to verify details. It also protects the content program from becoming dependent on a feature package Meta may change after testing.

    Key takeaways

    • Meta is testing separate paid offerings for Instagram, Facebook, and WhatsApp while keeping the core experiences free.
    • The proposed subscriptions are distinct from Meta Verified and may combine audience controls, insights, AI creation, and productivity features.
    • No described feature establishes that subscribers will receive automatic ranking or distribution priority.
    • Subscribe only when a capability changes a recurring workflow, has a measurable downstream result, and clears a pre-set renewal threshold.
    • Evaluate each app independently and include review, governance, and correction work in the cost of AI output.
    • Use premium social tools to derive and distribute content from an accurate owned source, not as a substitute for one.

    When an offer reaches your account, take a screenshot of the exact features and terms, choose one paid-worthy problem, and write the success and exit criteria before activating it. If you cannot define the changed action and the evidence it should produce, keep the free experience and revisit the decision when the product is clearer.

    References

  • Google Performance Max Ad Previews: A Practical QA Guide

    Google Performance Max Ad Previews: A Practical QA Guide

    You’ve refreshed a Performance Max asset group and need a clear answer before approving it: will the creative still look deliberate when it appears across different placements? Until now, getting that answer could take more navigation than the review itself.

    The one-click preview makes the mechanical part faster. Its real value, however, depends on what you do after opening it. With a fixed review sequence, you can turn a convenient interface shortcut into a reliable quality-control step.

    Where the one-click PMax preview lives

    Google Ads has shortened the path between the asset list and the rendered ad. From the Asset Groups table, clicking an image or video now opens previews for different Performance Max placements without requiring you to leave the page.

    That is a workflow change, not a new campaign strategy. The preview does not, by itself, add targeting control, supply performance evidence, or explain why PMax gives one asset more delivery than another. It puts the creative closer to the surface so you can inspect it with less friction.

    The time saving matters most when you manage a large asset library or replace creative frequently. Instead of treating previews as a separate destination that you visit only when something looks wrong, you can use the Asset Groups table as a review queue: open an asset, inspect the available presentations, record the decision, and move to the next one.

    Do not assume that opening one image validates the entire asset group. A preview answers a narrow question about the creative in front of you. If several images or videos changed, each changed asset needs its own review.

    A repeatable workflow for reviewing PMax creative

    Hands arranging abstract ad-preview cards through visual checks for first impression, cropping, contrast, and consistency across devices.

    Random clicking is quick but unreliable. Use the same sequence every time so that a busy reviewer does not approve the first attractive rendering and miss a problem elsewhere.

    1. Define the scope before opening previews. Identify which asset groups changed and whether the change involved an image, a video, the surrounding message, or several elements. If the message changed, include older assets in the review because a previously acceptable visual may no longer fit the new offer.
    2. Set the blocking criteria. Decide what requires revision before approval: an unclear focal point, unreadable embedded text, a hidden logo, a conflicting offer, an awkward crop, or a mismatch with the destination. This keeps personal taste from becoming the approval standard.
    3. Open each image and video from the Asset Groups table. Review every placement presentation the interface makes available. Do not stop after the first version simply because it looks acceptable.
    4. Inspect in a fixed order. Check composition first, legibility second, brand and product recognition third, and message consistency last. A fixed order reduces the chance that a strong headline distracts you from a weak crop.
    5. Record an asset-level decision. Use simple statuses such as Pass, Revise, and Block. Include the asset identifier, the placement or rendering where the issue appeared, the reason for the decision, the required change, and the person responsible for it.
    6. Reopen the preview after revision. A corrected source asset can solve one problem while creating another presentation issue. Approval should apply to the revised rendering, not to the intention behind the revision.

    This process also makes team reviews easier to resolve. “The creative feels off” gives a designer little direction. “The product is no longer recognizable in the narrow rendering” identifies the visible failure and the condition the next version must satisfy.

    What to inspect across the available placements

    Image composition and legibility

    An image can be strong as a standalone file and weak once placed inside an ad layout. Review the displayed creative as a user would encounter it, not as the designer saw it on a full-size canvas.

    • Focal point: Confirm that the product, person, or action remains immediately understandable in each displayed presentation.
    • Embedded text: Check whether words inside the image remain readable. If the message depends on enlarging the preview, it is not doing its job in the ad.
    • Logo and product recognition: Make sure the identifying elements are visible without crowding the composition.
    • Edges: Look for important details that sit too close to the boundary or appear cut off in a displayed rendering.
    • Visual hierarchy: The main subject should win attention before decorative elements, badges, or background details.

    A useful test is to ignore the surrounding copy for a moment. If you cannot tell what the image is trying to communicate, the text is being asked to rescue the creative.

    Video clarity and continuity

    Review a video as a sequence, not merely as a valid uploaded file. The opening should establish enough context for the viewer to understand what follows. Watch on-screen text, scene changes, product visibility, logos, and the ending. Important information should not become hard to read or appear crowded by the displayed layout.

    Then compare the video’s promise with the rest of the ad. A polished video can still fail review if it promotes a different product, audience, offer, or next step from the copy presented with it.

    Asset pairing and destination consistency

    PMax creative should be reviewed both as individual assets and as an assembled message. When copy appears with the selected image or video, read the combination from beginning to end.

    • Confirm that the visual and copy refer to the same product, service, or action.
    • Remove accidental repetition when an image already contains the same wording shown beside it.
    • Check that a specific offer in the creative agrees with the current campaign message.
    • Make sure the requested action is a sensible next step for the user.
    • Compare the approved ad message with the destination page separately. The preview can show the ad side of the experience, but it cannot perform that destination review for you.

    This is where the preview earns more than a quick visual check. Assets that look acceptable in isolation can become confusing when presented together. Reviewing the assembled message helps you catch that problem before treating it as a performance mystery.

    What a PMax preview can and cannot prove

    Split illustration showing a controlled ad preview beside the same creative appearing in varied real-world screen contexts.

    The most important distinction is between visual evidence and performance evidence. A preview lets you examine what is displayed in the preview. It does not tell you whether that presentation will receive meaningful delivery or produce better campaign results.

    DecisionWhat the preview establishesWhat you should do
    Visual approvalWhether the displayed examples meet your creative standard.Inspect every available placement presentation for each asset in scope.
    Actual deliveryIt does not guarantee which asset combination will receive impressions.Use campaign reporting to evaluate delivery after the ads run.
    PerformanceIt does not show which asset will generate stronger results.Base performance decisions on relevant campaign data, not appearance alone.
    Destination consistencyIt shows the ad side of the message, not the full landing-page experience.Compare the creative, offer, and requested action with the destination manually.
    Root causeIt can expose a visible flaw but cannot prove that the flaw caused a performance change.Treat the preview as diagnostic evidence and investigate other campaign factors before assigning cause.

    This boundary prevents two common errors. First, an attractive preview is not proof that an ad will perform well. Second, weak results do not automatically prove that the crop, image, or video is responsible. Use previews to remove visible defects; use delivery and outcome data to make performance calls.

    The update also does not eliminate the broader transparency limits associated with Performance Max. It makes creative inspection easier, but it should not be mistaken for a complete view of the system’s selection and delivery decisions.

    Key takeaways

    • You can open placement previews by clicking an image or video directly in the Performance Max Asset Groups table.
    • Review every changed asset and every presentation available to you; one acceptable rendering does not validate the whole asset group.
    • Check composition, legibility, brand recognition, message consistency, and destination alignment in the same order every time.
    • Record Pass, Revise, or Block at the asset level, with the visible reason and required correction.
    • Use previews for creative quality assurance, not as proof of delivery, performance, or causation.

    For your next creative refresh, make preview review a release gate: no changed image or video leaves QA without a recorded pass or revision. The interface saves the clicks. A consistent checklist turns those saved clicks into fewer preventable creative mistakes.

    References

  • How AI Search Is Changing Visibility and What to Measure

    How AI Search Is Changing Visibility and What to Measure

    If your average positions look steady while organic growth feels weaker, you may be measuring a journey that no longer happens in the same number of steps. A person can express a fuller need in one query, receive a synthesized answer, and skip follow-up searches that once gave you several chances to earn a click.

    That changes visibility in two ways. Search sessions are becoming more compressed, and AI recommendations are less stable than conventional rankings. Your response should be an intent-based system that measures repeated presence, gives machines unambiguous evidence, and still helps a person make the decision in front of them.

    Search demand can persist while the journey loses steps

    Datos/SparkToro behavioral data from millions of users found that desktop Google searches per U.S. user fell by nearly 20% year over year. The decline in the EU and U.K. was much smaller, at roughly 2% to 3%. This is a per-user change, not proof that Google suddenly lost its audience.

    The surrounding numbers make that distinction important. Traditional search remained about 10% of U.S. desktop activity through 2025. Dedicated AI tools accounted for only 0.77%, while Google AI Mode represented about 0.06% of U.S. desktop events by December. AI adoption is growing, but those shares are too small to support a simple story in which everyone abandoned Google for a chatbot.

    These figures do not prove that AI caused every missing search. They are consistent with a more practical mechanism: AI answers and instant results can resolve part of a need before a person performs a second, third, or fourth query. Search remains central, but each session may generate fewer opportunities for publishers.

    Query shape is changing at the same time. Six-to-nine-word searches are increasing rapidly in the U.S. Very long queries of 15 words or more remain uncommon and volatile, but they show that people are experimenting with more complete descriptions of what they need. You should therefore plan around the decision contained in a query, not just the keyword string that introduces it.

    1. Choose one commercially meaningful decision. Examples include selecting a product for a constrained use case, deciding whether a service fits a particular situation, or comparing two approaches.
    2. List the modifiers that change the answer. Audience, budget, compatibility, location, urgency, skill level, risk tolerance, and intended use can turn superficially similar prompts into different decisions.
    3. Write down the facts required to answer each version. Include suitability, exclusions, specifications, limitations, evidence, availability, and the next action.
    4. Map every important fact to a crawlable location. A claim should have a clear home on a page, not exist only in an image, sales call, private document, or advertising campaign.
    5. Consolidate wording variants, but split genuinely different intents. If ten phrasings lead to the same criteria and answer, one strong resource can serve them. If the criteria change, create a distinct section or page rather than forcing every audience into generic copy.

    This exercise gives you an intent map rather than another keyword list. It also exposes a common visibility gap: the page may mention the right topic while failing to provide the specific facts a search engine or AI system needs to answer the actual decision.

    Measure AI visibility as repeated presence, not a fixed rank

    Several translucent answer surfaces contain changing source arrangements, with the same blue and amber source object recurring in different positions.

    An AI recommendation is generated for a particular request and context. It is not a stored, universally ordered result. Across nearly 3,000 executions of 12 identical prompts by more than 600 volunteers, an identical recommendation list appeared fewer than once in 100 responses. Getting the same list in the same order was rarer still, at fewer than once in 1,000.

    A single screenshot therefore cannot tell you that your brand ranks third in AI search. It tells you that your brand appeared third in one response. Running the same prompt once more and reporting the better result is no more defensible; it replaces one anecdote with another.

    The more useful signal is visibility percentage: how often your brand appears across a defined set of valid responses. Presence proved more stable than exact order, even when the lists themselves changed. Smaller niche categories tended to produce more consistent answers than large markets, so you should not compare percentages across unrelated categories as though they shared the same competitive conditions.

    1. Define the prompt universe before collecting results. Select the audience, decision, market, language, and meaningful constraints. Do not add favorable prompts after seeing the outcome.
    2. Create wording variants that preserve intent. Natural prompts can differ substantially in phrasing while expressing the same underlying need. Keep these in one family.
    3. Separate prompts when the purpose changes. A general product recommendation and a recommendation for gaming, accessibility, enterprise security, or noise cancellation are different intent families if their selection criteria differ.
    4. Repeat tests under documented conditions. Record the product or model, interface, date, locale, login or personalization state when known, exact prompt, and complete response.
    5. Classify the outcome before calculating a rate. A passing mention, a direct recommendation, a citation, and an accurate description are not interchangeable forms of visibility.
    6. Aggregate by intent family. Calculate repeated presence within each decision context before combining anything into an overall number.

    There is not yet a validated universal minimum number of runs, and API output may not reproduce what a person sees in a consumer interface. Treat a small sample as directional. Keep the protocol consistent, retain the underlying responses, and widen the sample before making an expensive content or positioning decision.

    You can still record list order for diagnosis. A persistent pattern may lead you to inspect what distinguishes frequently preferred brands. But exact position should not become the executive KPI, agency guarantee, or performance bonus when the output is inherently variable.

    Make every important claim retrievable, specific, and verifiable

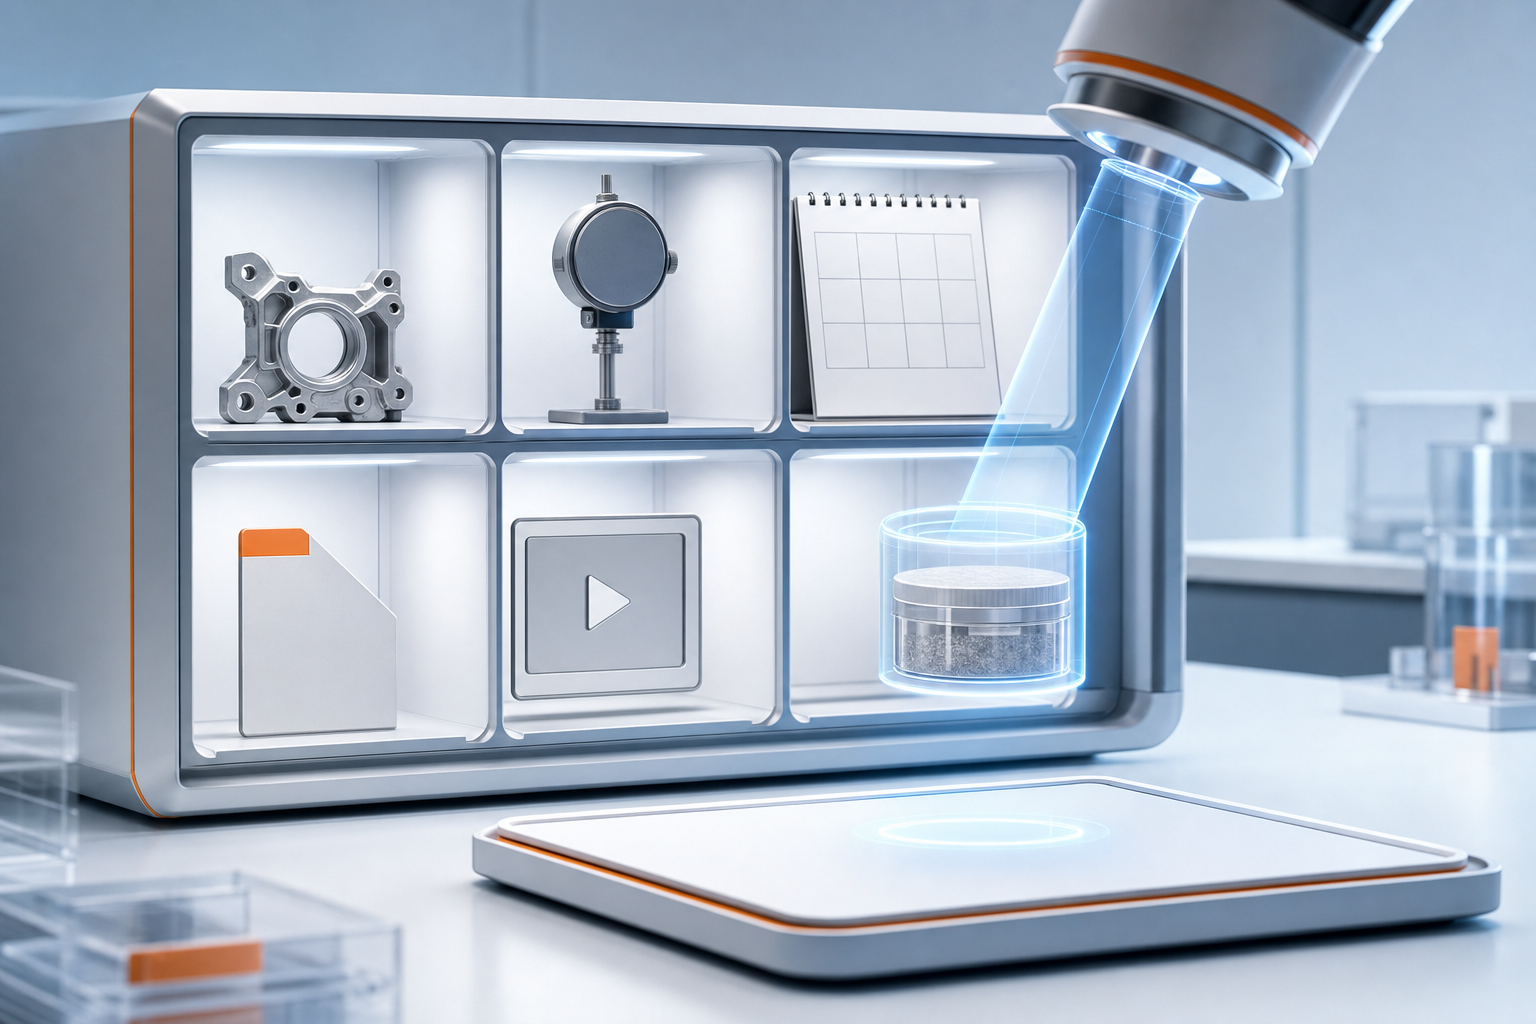
    An illuminated knowledge cabinet organizes documents, a product part, a measuring tool, a video frame, and a sample while a search beam selects one evidence module.

    The next visibility problem is eligibility: can a system identify your entity, retrieve the relevant facts, and determine whether your offer fits the user’s constraints? A page can be persuasive to a person while remaining ambiguous to a machine because the product name changes between sections, limitations are missing, specifications live in images, or structured data conflicts with visible copy.

    Moving from discovery to transaction inside one AI conversation is still a forecast rather than established behavior at scale. It is nevertheless sensible to make product and service information machine-readable now. The same cleanup also helps conventional search, feeds, internal search, accessibility, and human comparison.

    Use this content pattern for each important decision page:

    • Entity: State the exact product, service, organization, person, or location being described. Use the same canonical naming across headings, copy, metadata, and structured data.
    • Direct answer: Address the central decision early. Say who or what the option is for, rather than making the reader assemble an answer from feature copy.
    • Qualifiers: State compatibility requirements, exclusions, prerequisites, geographic limits, and material tradeoffs. Missing limits invite incorrect assumptions.
    • Comparable facts: Present specifications, capabilities, availability, and policies in labeled text or tables where a comparison genuinely helps.
    • Evidence: Add original measurements, first-party data, expert explanation, examples, or a documented method. Include enough context for someone to judge what the evidence does and does not establish.
    • Freshness: Show when time-sensitive facts were reviewed, and correct outdated pages instead of allowing contradictory versions to coexist.
    • Structured data: Apply the most specific relevant schema types and properties, using the same facts shown to the reader. Markup labels evidence; it does not replace evidence or make an unsupported claim true.

    Generic summaries are easy to reproduce and hard to distinguish. Proprietary data and distinctive first-party content give other sites and AI systems information they cannot obtain from another lightly rewritten overview. The useful part is not merely owning data. You need to publish the method, scope, date, definitions, and limitations that make the result interpretable.

    Specificity also protects brand accuracy. When your trial policy, service boundary, compatibility, or availability is unclear, a generative system may fill the gap with a category-level pattern that applies to competitors but not to you. Put the correction on the canonical page, align related pages and schema, and make the wording explicit enough to quote without reconstruction.

    Do not create a separate thin page for every prompt variation. Build around meaning. A strong resource can answer several phrasings when the intended decision is the same, while modular sections can address the qualifiers that materially change the answer.

    Treat video as visual, audio, text, and metadata

    Video can supply evidence that prose struggles to carry: a product in use, a software workflow, a physical dimension, an expert’s explanation, or the exact state of an interface. AI systems can process visual frames, speech, on-screen text, and relationships between them. Some handle these streams together; others depend on separate recognition and transcription components. Either way, clarity determines how much useful information survives.

    Optimize all four layers rather than uploading a polished file and relying on its title:

    • Visual layer: Publish crisp 1080p video where practical. OCR can struggle with footage below 360p, and enhancement cannot reliably restore text that was never captured clearly. Use high contrast, bold readable type, and close enough framing for labels and interface states to be legible.
    • Temporal layer: Keep a key object, label, or action on screen long enough to appear in sampled frames. Rapid cuts may look energetic to a person while causing an automated system to miss the one frame that establishes the fact.
    • Audio layer: Use clear speech, identify speakers, reduce competing noise, and align narration with the action on screen. Deliberate pauses can separate important statements and reduce ambiguity.
    • Text layer: Provide human-verified captions and a transcript. A transcript gives text-dependent systems access to the substance and reduces errors introduced by automatic speech recognition.
    • Metadata layer: Use accurate titles and descriptions, then add applicable VideoObject markup. Properties such as hasPart, transcript, and interactionStatistic should describe real, visible content and verified data.

    Review the finished video without sound, then review only the audio and transcript. If either version loses the core claim, the layers are not reinforcing one another. Fix the asset itself before adding schema; metadata cannot rescue an unreadable demonstration, an incorrect caption, or a missing limitation.

    Use a scorecard that separates exposure, accuracy, and value

    Traffic remains useful, but it no longer describes the whole journey. An answer can mention your brand without linking to it, cite you without recommending you, recommend you inaccurately, or send a visitor who converts. Those are different outcomes and should occupy different rows in your reporting.

    Key takeaways

    • Fewer searches per person do not mean Google has become irrelevant; they mean each journey may contain fewer opportunities.
    • An AI list position is an observation from one response, not a durable rank.
    • Measure repeated brand presence across defined intent families and documented conditions.
    • Separate mentions, recommendations, citations, accuracy, and business outcomes.
    • Improve visibility eligibility with explicit facts, distinctive evidence, consistent structured data, and machine-readable media.

    A practical scorecard can use the following definitions. Set the inclusion rules before testing, and keep the denominator visible beside every percentage.

    MetricHow to calculate itWhat it helps you decide
    AI visibility rateValid responses that mention your brand divided by all valid responses in the defined prompt setWhether you enter the answer set for that intent
    Recommendation rateValid responses that present your brand as a suitable option divided by all valid responsesWhether appearances are incidental or decision-relevant
    First-party citation rateResponses that cite a page you control divided by valid responses on citation-capable surfacesWhether your own evidence is being used, rather than only third-party descriptions
    Accuracy rateReviewed appearances with all predefined material claims correct divided by appearances reviewedWhether greater exposure is reinforcing the right brand facts
    Intent coverageIntent families in which the brand appears divided by all intent families testedWhich audiences or use cases have evidence gaps
    Human search performanceImpressions, clicks, landing-page behavior, and conversions reported by page and intent groupWhether conventional discovery and on-site usefulness are improving
    Business outcomeQualified actions, leads, sales, or other agreed outcomes from attributable journeysWhether visibility work is connected to value rather than exposure alone

    Store the prompt and complete response behind every AI observation. Also retain the model or product, interface, collection date, locale, and personalization state when known. Compare like with like. If a platform changes, preserve the old series and label a new baseline instead of hiding the discontinuity inside a blended average.

    Do not force no-click visibility into a revenue number you cannot defend. Report correlation as correlation, keep attributable conversions separate, and use brand visibility trends to decide where to investigate. The purpose of the scorecard is to improve decisions, not manufacture certainty from a probabilistic system.

    On your next reporting cycle, start with one high-value customer decision. Build its prompt family, collect a documented baseline, identify the most obvious evidence or accuracy gap, and correct that gap on the canonical page. Then rerun the same protocol. That gives you a repeatable visibility practice while the interfaces, models, and search journeys continue to change.

    References

  • Meta Andromeda and GEM: A Practical Ads Strategy for 2026

    Meta Andromeda and GEM: A Practical Ads Strategy for 2026

    If your old Meta Ads playbook depended on narrow interest stacks, duplicated ad sets, and frequent bid or budget adjustments, Andromeda and GEM create an uncomfortable question: which controls still help, and which ones now obstruct the system?

    The practical answer is not to hand everything to automation. It is to move your effort upstream. Use targeting to define genuine eligibility, give Meta a stronger range of creative choices, consolidate avoidable fragmentation, and judge performance at planned checkpoints instead of reacting to every short-term movement.

    What Andromeda and GEM actually change

    A useful operating model begins by separating retrieval from recommendation. Andromeda, introduced in 2024, retrieves ads that may be relevant to a person by using past interactions and creative-level signals. GEM then applies broader predictive intelligence to ad selection and sequencing. In simple terms, Andromeda helps assemble the viable candidates; GEM helps determine which candidate should be delivered and what interaction may make sense next.

    That distinction matters because neither system can rescue weak inputs. Retrieval cannot surface a useful creative concept that does not exist in your account. Recommendation cannot optimize toward a business outcome that is poorly measured or represented by the wrong campaign objective.

    LayerOperational roleYour strongest leverCommon mistake
    AndromedaRetrieves potentially relevant ads for an individual opportunityDistinct creative concepts and enough eligible reachDividing the audience so narrowly that each campaign sees only a thin slice of demand
    GEMPredicts which ad and sequence may produce the desired responseClear objectives, dependable measurement, stable delivery, and coherent offersChanging campaigns so often that the system has to optimize around a moving setup
    Combined systemMatches available ads to people and outcomes across Meta’s ecosystemHigh-quality inputs, useful creative variety, and disciplined evaluationTreating automation as a substitute for positioning, economics, or conversion experience

    This is why broad targeting and creative-first planning often belong together. A broader eligible audience gives the system more opportunities to find response patterns. Distinct creative concepts give it meaningful choices within that audience. Broad groups have been able to outperform elaborate interest-based setups as Meta’s retrieval became more creative-centric, but that is a strategic direction, not a promise that every broad campaign will win.

    Creative-first also does not mean targeting has become irrelevant. Targeting should still enforce real constraints: where you can sell, who is legally eligible, which existing customers should be included or excluded, and which regions can receive the offer. What has weakened is the case for using speculative audience slices as the main way to express relevance. When the difference is a motivation, pain point, use case, or level of awareness, express it in the ad before creating another audience partition.

    Consolidate campaigns without erasing business controls

    Many tangled campaign pathways merge into a few organized channels while several distinct control gates remain separate.

    The goal of simplification is signal concentration, not the smallest possible account. Before merging anything, ask whether the campaigns can genuinely share an objective, conversion event, offer, geographic eligibility, and economic target. If they cannot, separation may still be necessary. If they can, duplicated structures may only be dividing delivery data and forcing Meta to relearn similar patterns in several places.

    Use this consolidation test on every campaign and ad-set boundary:

    • Keep the boundary when the business outcome differs. A lead campaign and a purchase campaign are not interchangeable merely because they advertise the same brand.
    • Keep it when eligibility differs. Regional availability, language-dependent destinations, legal restrictions, and customer exclusions can justify separate delivery rules.
    • Keep it when economics require independent control. Offers with materially different margins, sales capacity, or acceptable acquisition costs may need their own budgets.
    • Question it when the only difference is a guessed persona or interest. If both groups can buy the same offer under the same economics, let persona-specific creative carry more of the distinction.
    • Question it when the split exists only for reporting convenience. Naming conventions, asset labels, and downstream reporting can often provide visibility without creating another delivery silo.

    After consolidation, do not judge success by whether every creative or audience receives equal spend. The system is designed to allocate delivery unevenly when it predicts unequal opportunity. Your decision metric should remain the campaign’s business outcome. Asset-level delivery is diagnostic evidence, not a fairness requirement.

    Budget belongs in the same discussion. Larger, consistent budgets can accelerate learning by producing a steadier flow of data. That does not make a budget increase an automatic cure. More spend can simply purchase more weak traffic when the offer, measurement, or creative is wrong. Scale only when the resulting acquisition cost and conversion quality remain acceptable to the business.

    A more useful budget question is: can this campaign run long enough to reach a planned decision point without a rescue edit? If the answer is no, reduce structural fragmentation, narrow the number of simultaneous tests, or revise the expected volume. A budget that forces constant intervention is not giving either system a stable problem to solve.

    Build creative coverage, not a pile of cosmetic variants

    Six distinct advertising concepts surround a central product pedestal, including demonstration, lifestyle, close-up, creator-style, problem-focused, and promotional scenes.

    Andromeda can retrieve only from the ads you supply. If every asset makes the same promise to the same implied buyer in nearly the same format, a large creative count can still represent very little strategic variety. Changing a background color, trimming a caption, or moving the logo produces a variant. Changing the buyer problem, promise, proof, objection, or presentation creates a new concept.

    Plan the creative library as a coverage map. For each concept, record:

    • Buyer context: the situation that makes the offer relevant, such as an urgent problem, a recurring task, or a planned upgrade.
    • Primary promise: the outcome the ad asks the buyer to value.
    • Reason to believe: the demonstration, mechanism, evidence, or explanation supporting that promise.
    • Objection addressed: the concern that could prevent action, such as effort, fit, complexity, or switching cost.
    • Format: the way the idea is experienced, including a demonstration, direct explanation, customer perspective, static visual, or short-form video.
    • Destination: the page or conversion path that continues the same message after the click.

    This map exposes false diversity quickly. If several ads have different thumbnails but identical entries in every other field, you have executional variation rather than broad conceptual coverage. That can still be useful for refining a proven idea, but it should not be mistaken for a portfolio capable of matching several motivations.

    A hypothetical analytics product illustrates the difference. One concept could focus on the reporting backlog and demonstrate an automated workflow. Another could focus on uncertainty in decision-making and show how an executive sees the underlying evidence. A third could address implementation anxiety with a clear explanation of the setup. The product is unchanged, but the reason to care, the proof, and the implied buyer situation are genuinely different.

    Meta’s AI-driven setup benefits from creative tailored to different personas and delivered through varied media formats. Treat that as a portfolio requirement, not permission to publish ungoverned volume. Every concept still needs an accurate claim, recognizable brand voice, and a landing experience that fulfills the promise.

    GEM’s role in sequencing also changes how you should think about a winner. The account does not necessarily need one universal ad that performs every communication job. It needs useful material for different interaction contexts: introducing the problem, explaining the solution, supplying proof, handling an objection, and stating the offer. You cannot dictate the exact sequence for every person, but you can make sure the available library contains coherent next steps.

    Use labels that preserve this strategic information. A useful asset name identifies the concept, promise, proof type, format, and version. That lets you see whether Meta is finding repeatable demand for a message or merely concentrating delivery on one execution. Without concept-level labels, creative analysis collapses into filenames and superficial format comparisons.

    Test with stable inputs and diagnose the right layer

    Stability does not mean leaving a campaign untouched indefinitely. It means deciding in advance what evidence will justify a change. Short-lived performance peaks and daily fluctuations are weak foundations for structural decisions. Longer engagement patterns, continuous creative renewal, and fewer hasty modifications fit the way Andromeda and GEM learn.

    Run a deliberate operating loop:

    1. Define the question. State whether you are testing a new buyer problem, promise, proof type, format, offer, or destination. Do not call an undefined batch of new ads a test.
    2. Set the decision rule before launch. Name the primary business outcome, any quality or profitability guardrail, and a review point that accounts for your normal conversion delay and data volume.
    3. Hold avoidable inputs stable. Keep the objective, measurement, offer, and destination consistent when the purpose is to compare creative concepts.
    4. Intervene only for a clear exception. A broken destination, rejected asset, invalid tracking setup, material pacing risk, or incorrect offer deserves immediate action. Ordinary movement does not.
    5. Review campaign outcomes and creative patterns separately. Decide whether the campaign is economically viable first. Then use asset patterns to brief the next round of concepts.
    6. Document the decision. Record what changed and why, so a later performance shift is not misattributed to the newest creative when budget, tracking, or structure changed at the same time.

    If you need causal certainty, use a controlled experiment that isolates the variable. Normal AI-optimized delivery is not an even creative rotation, so comparing two ads that received different audiences, spend, and timing does not produce a clean causal answer. Routine campaign reporting can identify promising patterns; it cannot automatically explain why they occurred.

    When results disappoint, diagnose the layer before rebuilding the account:

    • The campaign cannot spend: check eligibility, approvals, budget, bid or cost controls, audience restrictions, and delivery settings before blaming creative matching.
    • Ads receive delivery but little meaningful response: examine the hook, buyer problem, format, and clarity of the promise. More audience slicing will not repair an irrelevant message.
    • People engage but do not complete the next step: check whether the destination continues the ad’s promise, whether the offer is clear, and whether the conversion path adds avoidable friction.
    • Reported conversions change after measurement edits: separate the tracking change from the media conclusion. A reporting shift is not automatically a change in buyer behavior.
    • One concept absorbs most delivery: do not force equal allocation solely to make the report look balanced. Examine what buyer problem or proof it represents, then develop materially distinct ways to serve the same underlying demand.
    • Performance weakens after a previously productive run: refresh the concept portfolio and inspect the offer and destination. Recreating old audience complexity is unlikely to solve creative exhaustion.

    This diagnostic order protects you from a common failure mode: using targeting changes to solve a message problem, using new creative to solve a broken conversion path, or using more budget to solve weak economics. Andromeda and GEM can optimize delivery choices. They cannot decide which business problem you actually have.

    Key takeaways

    • Andromeda retrieves potentially relevant ads; GEM adds predictive selection and sequencing across broader interaction data.
    • Use targeting for genuine eligibility and control. Express motivations, use cases, and objections through creative before building another speculative audience slice.
    • Consolidate campaigns that share the same outcome, measurement, eligibility, offer, and economics, but retain boundaries that protect real business constraints.
    • Build distinct creative concepts around different problems, promises, proof, objections, and formats. Cosmetic variations are not strategic diversity.
    • Keep budgets and campaign inputs stable until a planned review point unless an operational problem requires immediate intervention.
    • Judge automation by profitable business outcomes, then use delivery patterns as evidence for the next creative brief.

    Start with one account audit. Mark every campaign boundary that exists only because of an assumed audience distinction, label each live ad by its actual concept, and choose the next review point based on your conversion delay. Those three actions will show whether you are giving Andromeda and GEM a clear optimization problem or a maze of competing instructions.

    References

  • Publisher Opt-Outs From Google AI Search: A Practical Plan

    Publisher Opt-Outs From Google AI Search: A Practical Plan

    You want Google Search to keep finding your work, but you may not want that work used to produce answers in AI Overviews or AI Mode. The problem is that changing the wrong control could limit ordinary Search visibility without giving you the AI-specific choice you intended.

    Don’t add a guessed directive or treat every Google AI control as interchangeable. Google has confirmed that it is exploring updates that would let sites opt out of Search generative AI features, but it did not provide a launch date, directive name, implementation syntax, or final description of the consequences. Your useful work now is to separate the controls, define your decision criteria, and prepare a reversible rollout.

    The proposed opt-out is not an implementation instruction

    Google identified AI Overviews and AI Mode as the Search generative experiences at issue. It also said any new publisher control must preserve the usefulness of core Search and avoid creating a fragmented or confusing experience. That tells you why the problem is difficult, but not how the eventual mechanism will behave.

    Until Google publishes the actual specification, nobody can responsibly tell you what token to add, whether the setting will work at the domain, directory, or page level, how quickly a change will take effect, or whether opting out will alter links, previews, rankings, or eligibility elsewhere in Search. Those are unresolved product questions, not details you should fill in by analogy.

    Key takeaways

    • Google is exploring a dedicated opt-out for Search generative features; the disclosed proposal did not include deployable syntax or a release date.
    • Google-Extended addresses how site content helps train Gemini models. It should not be treated as a confirmed AI Overviews or AI Mode opt-out.
    • Robots controls, preview controls, model-training controls, and Search generative controls answer different questions.
    • Do not precommit to opting in or out until you know the final control’s scope and its relationship with ordinary Google Search.
    • Prepare an inventory, measurement baseline, approval owner, and rollback plan before the mechanism arrives.

    Separate four control layers before changing anything

    An isometric publishing system sends a page through four separate adjustable gates representing discovery, crawler access, previews, and generative processing.

    The phrase “AI opt-out” is too broad to drive a technical change. It can refer to training a model, generating a search answer, displaying an extract, or accessing a page for core Search. Write down which use you mean before evaluating any directive.

    Control layerWhat Google has describedThe decision it addresses
    Core Search access and appearanceLong-standing publisher controls based on standards such as robots.txtHow Google may access and handle content for ordinary Search
    Search-result presentationControls for Featured Snippets and image previews, which can also be relevant to AI OverviewsHow much content Google may show as a preview or extract
    Gemini model trainingGoogle-ExtendedWhether site content may help train Gemini models
    Search generative useA proposed, not yet specified, opt-out for AI Overviews and AI ModeWhether content may be used in Google’s generative Search experiences

    The most important distinction is between model training and generation at search time. Google discussed Google-Extended as a Gemini training control and then described a separate control under consideration for Search generative features. That separate treatment means the presence of Google-Extended does not establish that a page is excluded from AI Overviews or AI Mode.

    If an audit, policy, or vendor report labels your site “opted out of Google AI” solely because Google-Extended is present, ask for product-specific evidence. The accurate statement is narrower: the setting concerns Gemini training. Keep the Search generative status marked as unresolved until Google publishes a dedicated mechanism and its scope.

    Structured data is separate as well. Schema markup helps machines interpret entities, attributes, and relationships on a page; it is not a consent or exclusion directive. Continue improving useful structured data for discoverability, but do not represent it internally as a way to grant or deny generative use.

    Decide what you are protecting and what you depend on

    Google’s stated position is that AI Overviews help people discover content and explore more topics. That is the platform’s case for generative Search, not a guarantee that your pages will receive qualified visits, conversions, subscriptions, or revenue. Your decision has to reflect how each part of your publishing business creates value.

    Start with two questions: how important is Google discovery to this content, and how strict is your policy on generative reuse? Those answers may differ across a single domain. A public help center, subscriber analysis, licensed database, product catalog, and evergreen editorial library do not necessarily need the same rule.

    • If discovery is the priority and reuse concerns are limited: do not promise an opt-out in advance. Preserve the current configuration, establish a baseline, and evaluate the documented effects when the control is released.
    • If control is the priority and Search discovery is secondary: prepare the internal approval to opt out, but make deployment conditional on confirmation that the mechanism does what your policy requires.
    • If your content portfolio is mixed: make granularity a go-or-no-go criterion. A path-level or page-level option could support different policies; a domain-wide switch could force a much larger business decision.
    • If you cannot quantify the tradeoff: plan a limited, reversible test if the final mechanism supports one. Do not turn uncertainty into a sitewide default.

    For every content family, record the outcome that matters on your own site: advertising consumption, a lead, a sale, a subscription, a download, account usage, or support deflection. Then record the competing concern: licensing limits, exclusivity, editorial policy, brand representation, or a general preference against generative use. This turns an abstract argument about AI into an explicit operating decision.

    Do not assume that the future opt-out will remove your words from a generated answer while preserving a citation, or that it will leave ordinary Search performance untouched. Do not assume the opposite either. Google has said it wants new controls to avoid breaking Search, but the final interaction has not been specified.

    If third-party licenses or contracts limit machine use, have the person responsible for those rights review the final specification before deployment. A technical setting can support a rights policy, but the mere presence of a setting does not establish that contractual obligations have been satisfied.

    Build a publisher decision package before launch

    Four publishing professionals review blank documents, a server model, abstract dashboard shapes, and two color-coded pathways around a meeting table.

    The fastest safe response to a new control will come from work that does not depend on its syntax. Build one compact decision package now so your SEO, editorial, legal, product, and engineering teams are not debating first principles after a release.

    1. Assign one accountable owner. Name the person who will confirm the final documentation, collect stakeholder approval, authorize production changes, and own rollback. Consultation can be broad; deployment authority should not be ambiguous.
    2. Inventory content by policy-relevant group. Use hostnames, directories, templates, or content types rather than starting with individual URLs. Record the business owner, discovery goal, onsite outcome, third-party rights, and desired AI policy for each group.
    3. Document the controls already in production. Capture your current robots.txt rules, Featured Snippet and image-preview choices, Google-Extended configuration, relevant page-level directives, and the systems that generate them. Label each control by its actual purpose.
    4. Save a pre-change baseline. Export organic Search impressions and clicks, important landing-page actions, conversion or subscription outcomes, and a representative record of crawl and index status. Preserve the reporting definitions so the later comparison uses the same measurements.
    5. Write a conditional decision. Use language such as: “Opt out for this section only if the final control covers AI Overviews and AI Mode, supports directory-level scope, and does not remove the section from core Search.” A condition is useful before launch; guessed syntax is not.
    6. Prepare change and rollback records. Your deployment entry should capture the exact directive, affected properties, implementation location, approver, release time, validation result, monitoring owner, and reversal procedure.

    A useful inventory can be a single sheet with columns for hostname, path or template, content owner, revenue or user outcome, Search dependency, rights constraints, existing Google controls, preferred generative policy, required granularity, approver, and rollback owner. The point is not to score every URL. It is to expose where one sitewide setting would combine content with different needs.

    Keep the measurement claim modest. A before-and-after change can show whether important site outcomes moved, but it may not prove that the opt-out caused the movement. Search demand, rankings, publishing volume, and product changes can move at the same time. Log other releases and compare equivalent content groups where the final control makes that possible.

    Require clear answers before production deployment

    When Google releases a control, read its final documentation as a specification. A headline saying that publishers can opt out is not enough. Your owner should be able to answer every question below with product documentation before approving a change.

    • Product coverage: Does the control apply to AI Overviews, AI Mode, or both? Does it cover every content format you publish?
    • Prohibited use: Does it prevent content from contributing to generated text, or does it also change links, citations, extracts, images, and previews?
    • Scope: Can you configure it by domain, subdomain, directory, template, page, or asset?
    • Core Search interaction: What happens to crawling, indexing, ranking eligibility, result links, Featured Snippets, and image previews?
    • Relationship with existing controls: Which rule wins when robots, preview, Google-Extended, page-level, and Search generative settings differ?
    • Processing: How does Google discover a change, how long may processing take, and what happens to content processed before the change?
    • Verification: Is there a testing tool, status report, inspection result, or other way to confirm that Google recognized the setting?
    • Reversibility: How do you restore eligibility, and is restoration processed on the same timetable as exclusion?

    If the mechanism is delivered through robots.txt, validate the public production file rather than only the CMS setting that is supposed to generate it. Check the response status, exact user-agent grouping, syntax, and the version served through your CDN. Confirm that an automated deployment cannot overwrite it. A misplaced rule in robots.txt can affect more than the feature you intended to control.

    If Google uses a page-level meta directive or HTTP response header instead, inspect the server-rendered HTML and live headers across representative templates. Check canonical and alternate versions, cached pages, and any CMS plugin that can emit competing directives. These are conditional validation steps; Google has not specified which delivery method the proposed control will use.

    For now, document your existing settings, correct any internal claim that Google-Extended already excludes AI Overviews, and set a release trigger. When Google publishes the final scope and syntax, your owner can compare them with the decision package, approve a narrow rollout where possible, and monitor the outcomes that matter to your business. Until that trigger is met, the right preparation is governance and measurement, not speculative code.

    References

  • How to Choose a 2026 SEO Agency for a Specialized Market

    How to Choose a 2026 SEO Agency for a Specialized Market

    You do not need the agency with the longest service list. You need one that understands the constraint most likely to derail your growth: a difficult website, a regulated approval process, local-market competition, a narrow buyer group, or a team with little time to implement recommendations.

    That changes how you should build a shortlist. Instead of beginning with agency rankings, start with your operating reality, define the evidence each candidate must provide, and make every contender answer the same questions. The result is a decision you can defend after the sales presentation is over.

    Choose for the constraint that can break the engagement

    “Specialized SEO” is not one service. A telecom company may need JavaScript troubleshooting, mobile-first technical work, Core Web Vitals improvements, lead generation, and a reliable compliance workflow. A pharmaceutical business may have medical, legal, and regulatory review requirements that determine what can be published. A contractor usually depends more heavily on geographically specific demand, calls, map visibility, and service-area pages. A small business may have a sound strategy but no spare team to execute it.

    An agency’s industry label is therefore only a filter. A relevant client logo shows that the agency entered the market before; it does not show what the team diagnosed, changed, or measured. Even a firm featured among small-business SEO agencies still has to prove that its delivery model fits your staff, margins, geography, and sales process.

    Write a short constraint brief before contacting candidates. Include:

    • The business event SEO should influence, such as a qualified inquiry, booked consultation, application, purchase, or sales opportunity.
    • The buyer and the problem that brings that person to search.
    • The geographic market you can actually serve.
    • The technical environment the agency will inherit, including the CMS, JavaScript dependencies, analytics setup, and development resources.
    • The people who can approve content, technical work, and regulated claims.
    • The capacity available for writing, subject-matter review, design, development, and sales follow-up.
    • The search surfaces that matter to you, including conventional results, local results, answer engines, and generative AI systems.

    This brief prevents a common procurement error: buying a strategy that assumes resources you do not have. If every recommendation will wait for an unavailable developer or subject-matter expert, the agency’s theoretical sophistication will not rescue the engagement.

    Build the scorecard before you see the pitches

    Three proposal folders, blank question cards, scoring tokens, and a magnifying glass are arranged for a consistent agency evaluation.

    For a telecom shortlist, one useful 2026 weighting assigns 20% to technical SEO, 15% each to industry experience and team composition, 12% to leadership, 10% each to geography and reviews, client satisfaction and results, and future-readiness, and 8% to recognition. The categories total 100%, but the mix is not a universal law. It is a starting point for deciding what deserves scrutiny.

    Set or adjust the criteria before you know which agency scores well. Otherwise, an impressive presenter can quietly redefine what “best” means during the meeting. A pharmaceutical buyer might elevate governance and compliance evidence. A contractor might place more emphasis on local execution and lead attribution. A resource-constrained business might value prioritization and implementation support more than awards.

    CriterionTelecom starting weightEvidence to request
    Technical SEO competency20%An anonymized audit excerpt, the affected templates, the proposed fix, implementation responsibility, and the validation method.
    Industry experience and track record15%A relevant engagement with a similar buyer, business model, search problem, and operational constraint.
    Team composition15%The named strategist, technical specialist, writer or editor, analyst, and day-to-day account lead who would do the work.
    Leadership experience12%Who makes strategic decisions, when senior specialists participate, and how an escalation reaches them.
    Geographic presence and reviews10%Evidence that the team understands the target market, plus review patterns rather than a single testimonial.
    Client satisfaction and results10%Baseline, measurement window, intervention, business outcome, and a clear explanation of what the agency can substantiate.
    Innovation and future-readiness10%A practical AEO or GEO workflow covering query selection, source-page improvement, entity clarity, citations, monitoring, and limitations.
    Media recognition and industry awards8%Recognition relevant to the work you are buying, separated from paid placements and general promotional visibility.

    Do not award points for a capability merely because it appears on a slide. Define what earns full, partial, or no credit. For example, “technical SEO” should not receive full credit for a generic site-audit screenshot. The candidate should be able to explain a real diagnosis, the implementation path, the dependency that made it difficult, and the evidence used to verify the result.

    Future-readiness deserves the same discipline. AEO and GEO are not synonyms for publishing more AI-generated copy. Ask how the agency identifies questions worth answering, strengthens the underlying page, clarifies entities and claims, uses structured data where appropriate, and observes whether the brand appears accurately in answer systems. No agency controls whether a frontier model cites or recommends a page, so guaranteed inclusion should reduce confidence rather than increase it.

    Make every proof point survive a follow-up question

    A polished case study can conceal the information you need most. Traffic may have grown while qualified inquiries remained flat. A ranking increase may concern a low-value query. A chart may begin after a migration problem was already corrected. A client may also have supplied writers, developers, and public-relations support that you will not have.

    Use the same evidence ladder for every claim:

    1. Relevance: Was the client similar in buyer, geography, sales motion, platform, and operating constraint?
    2. Baseline: What was happening before the work, and which measurement defined the problem?
    3. Intervention: What did the agency actually change, as distinct from work performed by the client or another vendor?
    4. Mechanism: Why was that change expected to affect discovery, evaluation, or conversion?
    5. Verification: Which analytics, search, local, CRM, or sales records supported the claimed outcome?
    6. Transferability: Which conditions made the result possible, and which of those conditions are absent in your business?

    If a candidate cannot answer the baseline and intervention questions, you cannot tell whether its work caused the result. If it cannot answer the transferability question, you cannot tell whether the example applies to you.

    For telecom, request technical and compliance evidence

    A credible telecom SEO team should be able to discuss rendering, crawl paths, mobile templates, Core Web Vitals, product architecture, lead journeys, and the review of regulated or sensitive claims. Ask for an anonymized technical finding and follow it from diagnosis through implementation and validation. You are testing whether the agency can move from an audit to a shipped fix, not whether it owns an auditing tool.

    For pharmaceuticals, inspect the publishing controls

    When comparing pharmaceutical SEO agencies, ask who separates search recommendations from medical or legal approval, how claim-supporting material is recorded, how reviewers receive context, and what happens when an approved statement changes. A content calendar is not enough. The agency needs a workflow that preserves accuracy and approval status from briefing through publication and later revision.

    For contractors, trace visibility to serviceable demand

    A contractor SEO agency should explain how it handles Google Business Profile ownership, service-area relevance, location and service-page architecture, duplicate or thin pages, reviews, calls, forms, and lead quality. Ask it to distinguish increased visibility from increased demand inside the area you can serve. Traffic from the wrong location is not a business win.

    For a small business, test prioritization under constraint

    A small-business engagement often fails at the handoff between recommendation and implementation. Give each candidate the same hypothetical constraint: limited writing capacity, limited development help, or a narrow service area. Ask what it would do first, what it would defer, what it needs from you, and what would invalidate its initial plan. The quality of those trade-offs tells you more than the length of the proposed deliverable list.

    Also ask who will write and review specialist content. A general copywriter can organize information, but your business still needs a defined subject-matter review path. The agency should identify where expert input enters the workflow, how factual changes are resolved, and who owns the final approval.

    Protect access, accountability, and exit rights before signing

    A business leader and agency representative place access keys, a folder, and a drive into a transparent lockbox during a meeting.

    An SEO proposal mixes three different things: work the agency controls, work your team controls, and outcomes neither party can guarantee. Separate them in the agreement. The agency can control whether it delivers an audit, brief, page, schema recommendation, implementation, or report. It cannot guarantee a particular ranking, AI citation, lead volume, or revenue result.

    Resolve these operating terms before work begins:

    • Account ownership: analytics, Search Console, Google Business Profile, tag management, advertising, CMS, call tracking, and reporting accounts should be created or retained in your business’s name where the platforms allow it.
    • Access level: give each person the permissions needed for the work, document who has administrative access, and include a revocation process for the end of the engagement.
    • Implementation responsibility: state whether the agency, your team, or another vendor edits templates, publishes pages, adds structured data, redirects URLs, and validates releases.
    • Approvals: name the person responsible for brand, factual, medical, legal, security, and technical sign-off where those controls apply.
    • Measurement definitions: define a qualified lead, branded versus non-branded demand, the reporting data set, attribution limitations, and how CRM outcomes will be reconciled with web analytics.
    • Change records: require a useful record of material content, technical, schema, and tracking changes so later performance shifts can be investigated.
    • AI use: document where generative tools may be used, what human review follows, and whether confidential business or customer information may enter an external model.
    • Exit package: specify the files, briefs, content, credentials, dashboards, change records, and unresolved recommendations you receive when the relationship ends.

    Account and data ownership are not administrative trivia. If a vendor controls a critical profile, tracking number, dashboard, or analytics property, changing agencies can interrupt reporting or customer contact. Resolve ownership in writing and have appropriate legal or security reviewers examine any term that creates material exposure for your business.

    Use the sales call to test how the working relationship will behave under pressure. Ask:

    1. Which part of our constraint brief changes your usual process?
    2. What would you investigate before recommending new content?
    3. Show us a recommendation that required development, compliance, or subject-matter approval. How did it reach production?
    4. Who performs each part of our work, and which responsibilities would be subcontracted?
    5. Which result in your proposal is a deliverable, which is a forecast, and which is outside your control?
    6. How would you connect search visibility to qualified opportunities in our sales process?
    7. What would cause you to change the strategy?
    8. What will we still own and be able to use if the engagement ends?

    Listen for boundaries as well as confidence. A trustworthy answer names assumptions, dependencies, and uncertainty. Be cautious when a candidate guarantees rankings or AI citations, avoids naming the delivery team, presents traffic as the only business measure, recommends large content volume before understanding the market, or makes essential data available only through a proprietary dashboard you lose on exit.

    Key takeaways for your shortlist

    • Choose around the constraint that can block results, not around the broadest service menu.
    • Define and weight the scorecard before meeting agencies so presentation quality cannot rewrite your criteria.
    • Require every result claim to identify the baseline, intervention, verification method, and conditions needed to repeat it.
    • Match the proof to the market: technical and compliance depth for telecom, controlled review for pharmaceuticals, serviceable local demand for contractors, and realistic prioritization for small businesses.
    • Treat AEO and GEO as measurable discovery work, not as a promise that an AI system will cite or recommend you.
    • Keep business accounts, data, implementation records, and reusable deliverables under terms that survive the agency relationship.

    Before you book another sales call, finish the constraint brief and scorecard. Send both to every contender and require evidence in the same format. That small piece of procurement discipline will make the pitches comparable and expose the gaps while you can still walk away.

    References

  • Top SEO Firms Elevating Law Practices in 2026

    Top SEO Firms Elevating Law Practices in 2026

    n

    Last updated: January 27, 2025.

    nnnn

    I dove headfirst into exploring 73 different law firm SEO companies from March 2024 to January 2026. It was an adventurous dive into the world of legal search engine optimization, meticulously evaluating the top 8 firms with a specific set of criteria.

    nnnn

    The adventure involved considering factors like location (12%), which, while less critical, still signals an agency’s capability to excel in local markets. Years in business (8%) demonstrated a firm’s stability through algorithm changes. I placed a heavier weight on average client review score (20%) because client satisfaction speaks volumes. Moreover, examining the number of law firm clients (18%) revealed a firm’s legal expertise. I also evaluated their GEO/AIO experience score (15%), a necessary gauge as AI-driven optimization grows in importance.

    nnnn

    The assessments continued with leadership experience (10%), based on expertise, and media references (9%), which indicated industry acknowledgment. Lastly, median employee tenure (8%) was a consideration, reflecting the workplace culture


    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot
  • Discover 2026’s Top SEO Agencies for Investment Banks

    Discover 2026’s Top SEO Agencies for Investment Banks

    n

    Last updated: January 26, 2026

    n nnn

    I’m excited to share with you a comprehensive analysis of the leading investment banking SEO agencies for 2026. Through a methodical evaluation of approximately 50 agencies, I

    ```json
{
  "alt": "Night sky with stars and text advertising SEO services for medium and large organizations.",
  "caption": "Explore the wonders of data-driven SEO solutions under a starry night sky. Tailored for medium and large businesses, discover SEO expertise redefined.",
  "description": "The image showcases a starry night sky, serving as a backdrop for text promoting data-driven SEO solutions for medium and large organizations. The website header reads 'assertive' with options like Organic, Paid, Industries, and more. A 'Discover More' button invites further exploration. This visually appealing setting blends tranquility with technological expertise, positioning the company as a leader in SEO services."
}
```

    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot
  • Explore the Best SEO Agencies for Private Equity in 2026

    Explore the Best SEO Agencies for Private Equity in 2026

    n

    Last updated: January 27, 2026

    n nnn

    Recently, I

    ```json
{
  "alt": "Bold text on dark background states, 'We use creativity and technology to elevate brands and deliver business growth.'",
  "caption": "Harness the power of creativity and technology to transform brands and drive business growth with innovative solutions.",
  "description": "This image features a modern design with bold text against a dark background. It reads, 'We use creativity and technology to elevate brands and deliver business growth,' emphasizing the integration of creative strategies and technological advancements. The image reflects a focus on brand enhancement and business development, ideal for marketing and design contexts."
}
```

    Inspired by this post on First Page Sage Blog.


    crushpress.ai community screenshot