Author: shivamcrushpressai

  • How to Build an AI Search Citation Strategy That Compounds

    How to Build an AI Search Citation Strategy That Compounds

    Your organic rankings can hold steady while the visibility those rankings used to create quietly disappears. On parts of LinkedIn’s B2B marketing sites, non-brand awareness traffic fell by as much as 60% across specific topics even though rankings remained stable. The answer itself had started absorbing the discovery that once required a click.

    You now need a strategy for being retrieved, understood, trusted, mentioned, and cited before a prospect reaches your site. This is not a replacement for SEO. It is a way to make your SEO, content, digital PR, structured data, and measurement work together around the answers people receive from ChatGPT, AI Overviews, Bing, and other answer interfaces.

    Key takeaways

    • Optimize for the questions that shape a decision, not every prompt that happens to mention your category.
    • Treat the initial question and its follow-ups as one journey. The first answer often establishes the sources that later turns build upon.
    • Make every important page easy to extract and verify: state the answer early, define entities clearly, qualify claims, and place evidence beside the claim it supports.
    • Combine owned content with credible external corroboration. A page can be accurate and still lose citations if the wider information environment does not support it.
    • Measure answer presence, citation quality, accuracy, and business response separately. Referral traffic alone cannot show how much influence AI answers created.

    Build a citation map before producing more content
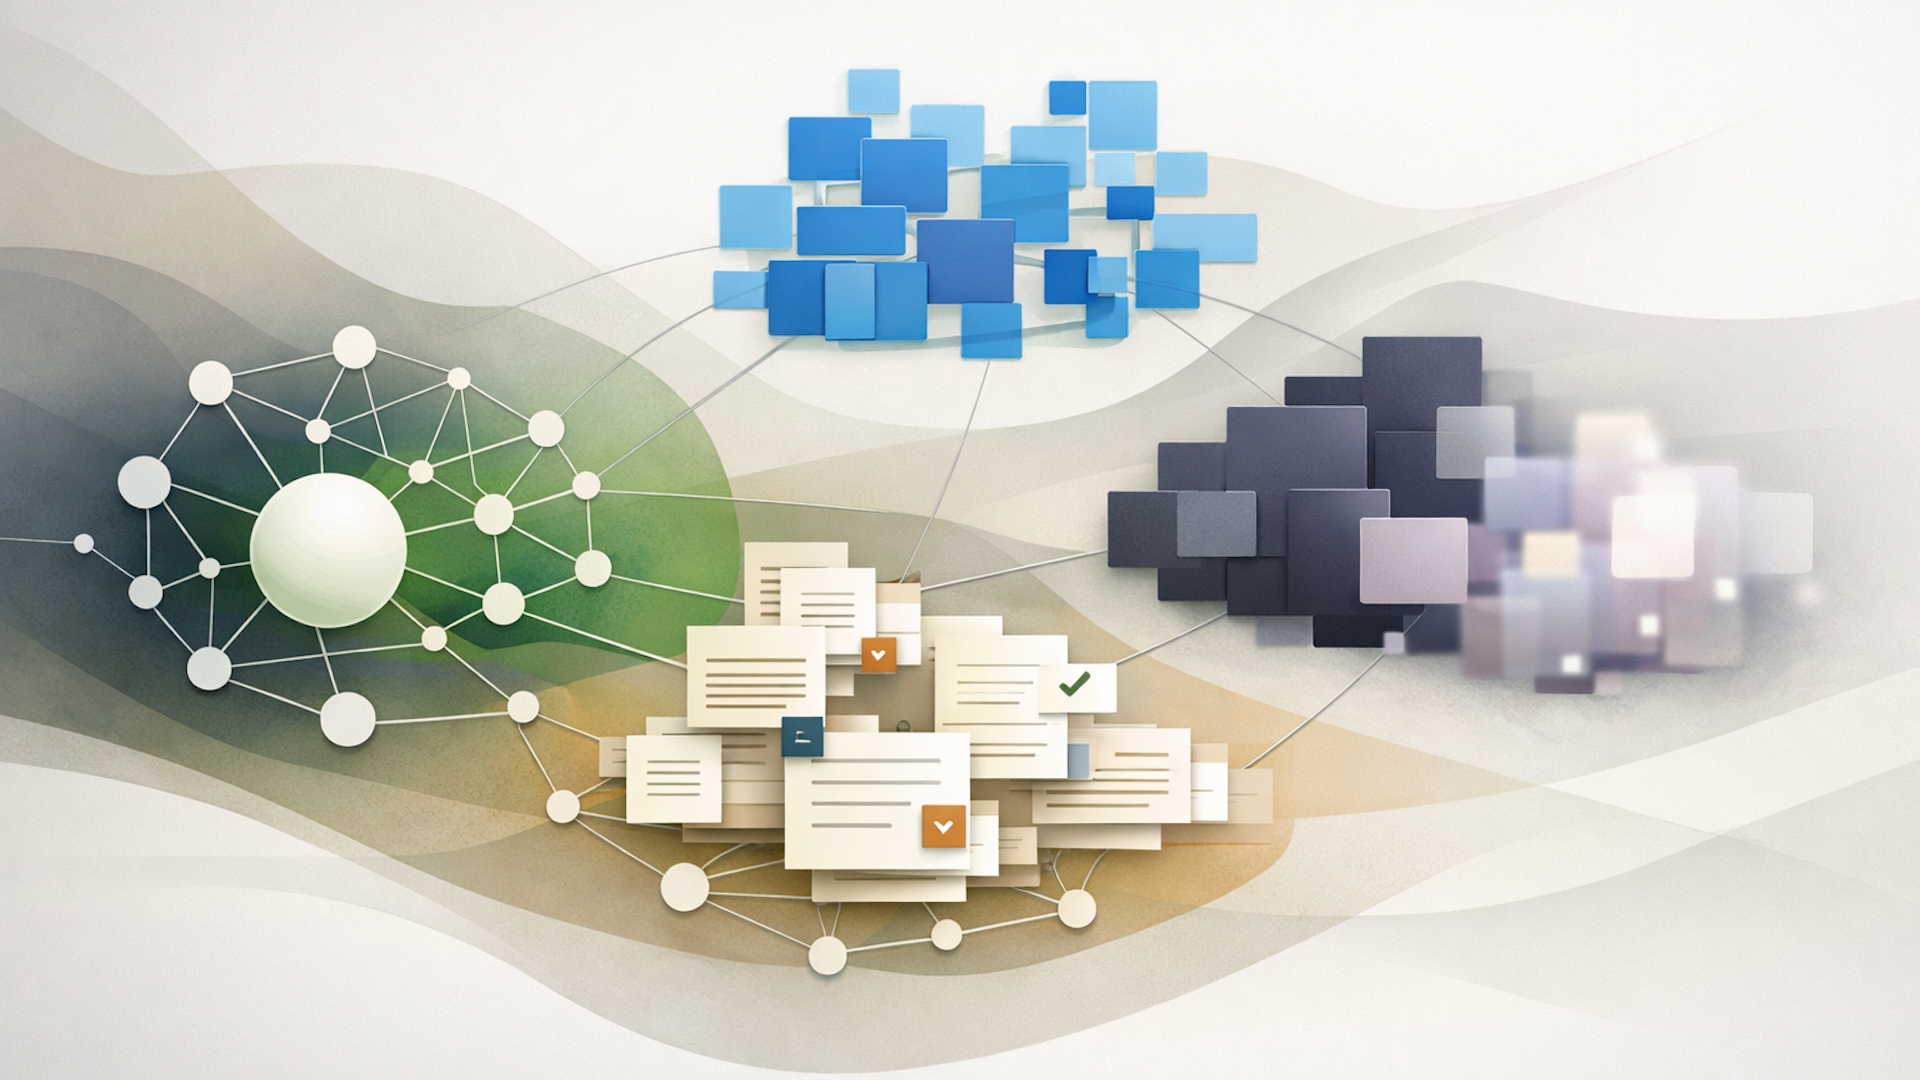
    An isometric network of blank document tiles, source pillars, topic spheres, and verification markers sits on a planning table.

    A keyword list tells you what people search. A citation map tells you what an answer engine needs in order to answer, which claims require support, and where your brand deserves to appear. That distinction prevents a common failure: publishing more broadly while leaving the commercially important questions unanswered.

    Start with the decision, not the query volume

    Choose questions by the decision they influence. A high-volume definition may create awareness, but a lower-volume question about suitability, implementation, risk, or cost may determine whether your company enters the consideration set. The right target is the intersection of audience need, business relevance, and evidence you can genuinely provide.

    For each topic, record:

    • The audience: who is asking and what they already understand.
    • The decision: what they are trying to choose, approve, reject, or do next.
    • The opening question: the broad request likely to begin the session.
    • The follow-up questions: the constraints, comparisons, objections, and requests for proof that narrow the answer.
    • The claims required: definitions, criteria, trade-offs, facts, limitations, and procedures needed for a complete response.
    • The best evidence: first-party documentation, original data, an official definition, a transparent method, or independent corroboration.
    • The current citation candidates: your relevant URL and the external domains already associated with the topic.
    • The gap: what is missing, ambiguous, unsupported, outdated, or difficult to extract.

    This becomes your operating document. Content teams can see what to publish, PR teams can see which claims need external validation, technical teams can see which entities need clearer markup, and analysts can see which answer journeys to monitor.

    Plan for the first answer and the follow-up chain

    Across 700,000 ChatGPT conversations containing web citations in the fourth quarter of 2025, most citations were captured in the first turn. Wikipedia was prominent for general knowledge, while other cited domains tended to cluster around particular topics. That dataset is directional rather than a universal rule, but it makes the opening answer too important to treat as a generic awareness prompt.

    The opening page should establish the core definition, entities, framing, and evidence. Supporting pages can then handle comparisons, exceptions, implementation details, and objections. Link them through descriptive anchor text so the relationship is legible to readers and machines. Do not force one oversized page to answer every possible branch.

    At the same time, do not optimize for an isolated prompt. Bing’s worldwide multi-turn search can retain context for follow-up questions, reflecting a broader move from disconnected searches to continuing conversations. Test whether your brand remains relevant when the user adds a budget, industry, location, compatibility requirement, risk concern, or alternative. A citation won on a broad question is weak if your evidence disappears as soon as the decision becomes specific.

    Prioritize citation-map gaps using three judgments: the consequence of being absent or wrong, the quality of evidence available, and your realistic ability to become a credible source. Work first where all three are strong. A topic with business value but no defensible evidence is not ready for content production; it needs product documentation, data, expert input, or independent validation first.

    Make each page easy to extract, verify, and reuse

    Answer engines do not cite a page merely because it ranks or repeats the right phrase. The page has to contain a passage that can survive extraction: the meaning must remain clear when the passage is separated from the title, surrounding copy, navigation, and brand context.

    Build citation-ready answer units

    Put the direct answer immediately after a descriptive heading. Then provide the reason, evidence, qualifier, and next action. This gives an answer engine a concise passage to retrieve without stripping away the conditions that make the claim accurate.

    A citation-ready unit usually contains:

    • A named subject: identify the product, organization, process, standard, audience, or platform instead of relying on vague pronouns.
    • A direct claim: answer the heading before adding history, scene-setting, or promotional language.
    • A boundary: state the version, market, audience, situation, or limitation when the answer is not universal.
    • Adjacent evidence: place the supporting method, data, documentation, or link beside the claim rather than in a distant resources page.
    • A freshness signal: show when material was published or materially reviewed, and explain version-dependent changes in the body.
    • Clear ownership: identify the organization and, where relevant, the qualified person responsible for the content.

    Read the passage without its page title. If you cannot tell what is being discussed, who the advice applies to, or why the statement should be trusted, the passage is not ready to serve as evidence.

    Separate readability, retrievability, and credibility

    These are related but different jobs. A well-written page can still be difficult to retrieve if its headings are generic. A well-structured page can still be untrustworthy if its claims have no evidence. An authoritative page can still be unusable if the answer is buried inside a long narrative.

    • Readability: use plain language, short paragraphs, descriptive headings, and lists only where the material is genuinely sequential or categorical.
    • Retrievability: keep each section focused on one recognizable question, name entities consistently, and use internal links that explain the relationship between pages.
    • Credibility: show methods, limitations, accountable authorship, primary evidence, and corrections. Remove claims that exist only because competitors repeat them.

    Clear headings, semantic hierarchy, accessibility, fresh expert content, and strong information structure remain useful in AI-led discovery. These practices sound familiar because they are extensions of durable SEO and content-quality work. Their value now reaches beyond rankings into whether a passage can be understood and reused inside an answer.

    Use JSON-LD to clarify, not to compensate

    Use JSON-LD to describe entities and content that are already visible on the page. Connect the organization, author, article, product, and other relevant entities consistently across your site. Choose schema types that match the page rather than the search feature you hope to obtain.

    Structured data cannot turn a vague assertion into evidence, make an anonymous page authoritative, or guarantee an AI citation. It is a clarification layer. If the visible copy and markup disagree, fix the copy and data model instead of adding more markup. The strongest implementation makes the same entity relationships clear in the prose, internal links, metadata, and JSON-LD.

    Build corroboration, correction, and budget into one workflow
    A transparent modular workflow turns blank source pages and evidence objects into reusable information blocks connected to reference nodes.

    Owned content is essential because it gives you a canonical place to define your products, policies, evidence, and terminology. It is not sufficient for every kind of claim. Answer engines may rely on broad reference sites for general knowledge and topic-specific domains for specialized questions. Your citation strategy therefore needs both a strong canonical page and an accurate external information environment.

    Earn corroboration where it has a legitimate reason to exist

    Start by classifying each important claim. Product specifications and company policies belong in first-party documentation. Claims about market importance, comparative performance, or category leadership usually need transparent evidence or independent support. Definitions may be better anchored to an originating standard, institution, or primary text than to your marketing page.

    Then pursue the external format that fits the claim: expert commentary, documented partnerships, reputable profiles, original research with a disclosed method, or coverage that adds independent analysis. The objective is not to scatter identical brand language across domains. It is to make accurate facts available in places that have their own editorial reason to mention them.

    Do not treat Wikipedia prominence as permission to manufacture a presence there. A reference page is valuable only when the subject meets its standards and independent citations support the material. Promotional editing creates a fragile signal and a reputation risk. If the evidence is not strong enough for independent editors to verify, improve the evidence rather than the entry.

    Run an explicit misinformation correction loop

    When an AI answer is wrong, save enough context to reproduce the problem: the platform, mode, exact prompt, relevant prior turns, market, answer text, citations, and observation date. A screenshot alone is useful for evidence but poor for diagnosis because it may omit the conversational context that shaped the response.

    1. Classify the error. Determine whether the answer is outdated, factually false, attributed to the wrong entity, missing a limitation, or merely absent.
    2. Trace the claim. Open the cited URLs and find the wording or ambiguity that could have produced the answer.
    3. Repair the canonical record. Update the appropriate owned page with a direct correction, clear entity names, supporting evidence, and the relevant qualifier. Preserve a stable URL where practical.
    4. Repair corroborating pages. Ask legitimate publishers, partners, directories, or profile owners to correct inaccurate information they control. Do not request language their evidence cannot support.
    5. Retest the journey. Repeat the opening question and the important follow-ups. Record whether the answer, mention, and cited URL changed.
    6. Keep the case open until accuracy stabilizes. An immediate retest can show whether the problem persists, but retrieval and model updates do not follow a schedule you control.

    This work crosses organizational boundaries. LinkedIn organized AI-search work across SEO, PR, editorial, product marketing, and other teams, including efforts to correct misinformation and publish content designed for AI visibility. You may not need a formal task force, but every tracked issue needs a named owner and a route to the team that can fix the underlying fact.

    Fund the workstream, not the AEO label

    AEO pricing models affect both the budget and where resources can be applied. Compare proposals by the work they actually fund rather than by a single visibility promise. A complete program may need diagnosis, evidence creation, content editing, technical presentation, authority development, monitoring, correction, and measurement. Paying for only the dashboard tells you where you are absent but does not create a credible reason to include you.

    Before approving an internal budget or vendor proposal, ask:

    • Does prompt monitoring include opening questions and contextual follow-ups?
    • Will you receive the answer text, cited domains, exact cited URLs, and observation context?
    • Does content work include implementation and editorial review, or only recommendations?
    • Who supplies and validates the evidence behind new claims?
    • What does authority development mean in practice, and which placements or outreach activities are excluded?
    • Who owns misinformation cases from discovery through correction and retesting?
    • How will AI visibility data connect to web analytics, branded demand, sales conversations, and conversions?

    Budget first for the bottleneck. If your pages are vague and unsupported, monitoring more prompts will document the same weakness in greater detail. If your canonical content is already clear and authoritative, the next constraint may be external corroboration or measurement. Reassess the bottleneck as the program develops instead of locking every workstream into the same level of spending.

    Measure influence without pretending every answer produces a click

    AI visibility and referral traffic are not interchangeable. A user can see your brand, accept a cited claim, ask several follow-ups, and visit later through a branded search or direct navigation. Another user can click immediately. Standard analytics can observe the second path more easily than the first.

    The imbalance is already visible in practice. LinkedIn reported triple-digit growth in LLM-referred visits to its B2B marketing sites while the channel remained a small portion of overall traffic. That is one company’s experience, not a universal benchmark. It illustrates why a fast-growing referral segment can still understate the influence of answer-led discovery.

    Build a scorecard with separate layers:

    • Answer coverage: whether the monitored answer addresses the topic accurately and completely enough to support the user’s decision.
    • Brand presence: whether your organization, product, expert, or terminology appears, and what role it plays in the answer.
    • Citation presence: whether a citation supports the passage where your brand or claim appears, rather than merely appearing elsewhere in the response.
    • Citation ownership: whether the cited URL is owned, earned, neutral, or controlled by another commercial party.
    • Accuracy: whether the answer preserves material conditions, limitations, version details, and entity relationships.
    • Journey depth: whether your visibility survives the follow-ups that move the user from orientation to evaluation and action.
    • Business response: LLM referrals, engagement, conversions, branded-search movement, direct demand, and qualitative evidence from sales or support conversations.

    Store the platform, search mode, prompt, conversational context, market, observation date, response, and citations with every evaluation. AI answers can vary, so a single manual query should be treated as an observation, not a performance trend. Use a stable prompt set for comparison, but review it when customer questions or product conditions change.

    Read combinations of metrics instead of chasing one visibility score:

    • Rankings stable, clicks down, answer mentions up: the answer interface may be satisfying more awareness demand before the click. Improve downstream calls to action, but do not describe the visibility as an SEO loss without examining the answer.
    • Mentions up, citations flat: the brand may be recognized without being selected as evidence. Strengthen claim-level proof and legitimate corroboration.
    • Owned citations up, accuracy weak: inspect the exact cited passage. Ambiguous wording, missing qualifiers, or entity confusion may be making the page easy to retrieve but unsafe to reuse.
    • Referral growth high, total volume small: treat it as a directional signal. Evaluate visit quality and conversions without presenting the channel as a replacement for established acquisition sources.
    • Visibility unchanged after a content refresh: check retrieval, internal linking, technical accessibility, evidence quality, and external corroboration before repeatedly rewriting the same page.

    Start with the commercially important question for which an inaccurate or absent answer carries the greatest consequence. Map its conversation, repair the canonical page, add defensible corroboration, and monitor the whole path through follow-up questions. Once that loop works, extend it to the next decision. That is how AI-search visibility becomes a repeatable operating capability instead of a collection of prompt screenshots.

    References

  • Overcoming Google’s Biggest Crawling Challenges: A Personal Review

    Overcoming Google’s Biggest Crawling Challenges: A Personal Review

    Managing my website’s URLs efficiently is crucial to prevent crawlers from slowing it down. If you’re like me, you want your site to load fast, ensuring both visitors and search engines have a seamless experience.

    Just the other day, I listened to Google’s latest insights on their year-end report for 2025. It was fascinating to hear Gary Illyes discuss on the Search Off the Record podcast about the major crawling challenges Google faces, like faceted navigation and action parameters, which make up a whopping 75% of the issues.

    What’s the issue? Well, I’ve learned that crawling problems can seriously impact site performance, potentially making it unusable or inaccessible. Crawlers can sometimes get stuck in an infinite loop on a site, wreaking havoc on server performance.

    According to Gary, once a set of URLs is discovered, the crawler has to check a significant portion to determine its quality. By the time this is done, the damage is done—your site slows down dramatically.

    The Biggest Crawling Challenges Here’s what caught my attention as the major issues from the report:

    • 50% relate to faceted navigation. These are very common in e-commerce sites where endless filtering options exist for products based on size, color, price, etc.
    • 25% pertain to action parameters. These come from URL parameters that trigger actions instead of significantly changing page content.
    • 10% involve irrelevant parameters like session IDs or UTMs.
    • 5% are due to plugins or widgets that cause confusion by creating problematic URLs.
    • 2% encapsulate other “weird stuff”, which includes strange issues like double-encoded URLs.

    Why this matters to me is simple. A well-structured URL strategy keeps my server healthy, ensures quick page loads, and prevents search engines from misunderstanding which URLs should be indexed as canonical.

    The Podcast: Here’s where you can listen to the discussion yourself:


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Target Google Ads and See Where PMax Performs

    How to Target Google Ads and See Where PMax Performs

    Your Search campaigns can be well built and still leave growth on the table. Keywords meet people after they express intent; they do not automatically reach every suitable buyer who has not started searching. If you answer that gap by handing more work to Performance Max, you inherit a second problem: knowing which Google channel produced the result.

    You can solve both problems without pretending automation is transparent. Define targeting as a two-part decision – where relevant intent appears and who qualifies – then use Google Ads API v23 channel reporting to inspect how Performance Max distributed and converted traffic. That gives you a practical operating loop: targeting hypothesis, channel evidence, focused correction, and cost-per-acquisition review.

    Separate where an ad can appear from who should see it

    A targeting plan becomes much easier to audit when you stop treating every setting as interchangeable. Google Ads targeting falls into two functional groups: content targeting and audience targeting.

    DecisionContent targetingAudience targeting
    Question it answersIn what query or content environment can the ad appear?What kind of person should be eligible to see the ad?
    Main optionsKeywords, topics and placementsGoogle data, your data, custom segments and automated targeting
    Best useCapturing a relevant moment or contextImproving the fit between the person, message and offer
    Common mistakeAssuming a relevant query always identifies the right buyerAssuming a plausible audience is ready for the same offer at the same time

    Keyword targeting reaches people through searches and also extends into dynamic ad groups and Performance Max. Topic targeting places ads alongside content about a selected subject in display and video campaigns. Placement targeting lets you choose particular websites, apps, YouTube channels or videos.

    Audience targeting works on a different axis. Google’s prebuilt options include detailed demographics, affinity segments, in-market segments and life events. Your own data can include website visitors, app users, people who engaged with your Google content and eligible Customer Match data. Custom segments can be based on relevant searches, interests, websites or apps. Automated options can expand from the signals and data you provide, although their names and exact behavior vary by campaign type.

    The distinction matters because a keyword can reveal intent without identifying the buyer. Someone searching for vacation packages could be planning a family trip, honeymoon or retirement holiday. The query is the same, but the useful message, proof and offer can be completely different. Treat the keyword as evidence of a moment, not as a complete persona.

    Build the targeting stack before automation expands it

    An isometric targeting system shows layers for intent, context, audience qualification, and controlled automated expansion.

    Before changing campaign settings, write down the answers to two separate questions: How can Google Ads promote this offer, and how can Google Ads reach this particular audience? If you can answer only the first, you have a distribution plan without an audience strategy. If you can answer only the second, you have a persona without a reliable way to reach it.

    1. Define the action that creates business value. Name the conversion you actually want, the offer attached to it and the page where it happens. This prevents cheap but irrelevant traffic from becoming the campaign’s de facto objective.
    2. Describe audience fit independently of search behavior. State who has the problem, what makes the offer relevant and what language that person would immediately recognize. Do this before selecting a Google segment.
    3. Choose the content signals that reveal a useful moment. Use keywords for expressed search intent, topics for subject context and placements when you know the specific sites, apps, channels or videos where the audience spends attention.
    4. Add the audience data you can legitimately use. Consider Google’s segments, eligible first-party data and custom segments. Treat automated expansion as another layer of reach, not as a substitute for defining the audience yourself.
    5. Make the creative perform a targeting job. Use the buyer’s vocabulary, problem, context and expected outcome. A broad audience paired with precise creative can filter attention more effectively than generic creative placed in a narrowly named segment.
    6. Set the success hierarchy before launch. Put conversions and cost per acquisition ahead of click volume and cost per click. Otherwise, an apparent traffic improvement can move the campaign away from qualified demand.

    For example, lead-generation software intended for Google Ads professionals could use custom segments informed by searches for terms such as Performance Max, visits to relevant industry sites or use of the Google Ads app. Content targeting could add placements on industry education channels and topics around search marketing. The creative should then speak in the terminology of campaign management rather than generic business-software language.

    This is a coordinated stack, not necessarily an instruction to combine every setting as a restrictive intersection. Campaign types interpret signals differently. Your planning document should show what each input contributes: context, identity, prior relationship, expansion or creative qualification.

    When remarketing or custom segments are restricted

    Some sensitive-interest campaigns, including certain legal or healthcare advertising, may not be eligible for custom segments or remarketing. When those options are unavailable, do not treat the restriction as a technical obstacle to work around. Start with an eligible Google data audience that has plausible overlap, then let the creative filter for relevance.

    Industry terminology, recognizable acronyms and specialist visuals can make the intended audience pay attention while other people move on. That approach is especially useful when you can target a broad eligible group but cannot encode the sensitive trait directly. Confirm which options are available in the account and campaign you are actually running before finalizing the plan.

    Use API v23 to turn PMax delivery into channel evidence

    An analyst observes one automated advertising stream separated into visible paths for search, video, shopping, web, and map channels.

    Older Google Ads API versions returned MIXED for the Performance Max ad_network_type segment. API v23 can instead break results out across Search, YouTube, Display, Discover, Gmail, Maps and Search Partners. That changes Performance Max reporting from a single blended row into a view of where delivery occurred.

    The visibility is available at three useful levels:

    • Campaign level: See the overall channel mix and identify which channels deserve a closer look.
    • Asset group level: Determine whether a channel pattern belongs to the whole campaign or is concentrated in one audience-and-creative grouping. This channel breakdown is available through the API, not the Google Ads interface.
    • Individual asset level: Connect channel delivery to particular creative assets instead of judging every asset against one blended campaign result.

    There are three implementation constraints you should record in the reporting specification. Channel-specific data is available only for dates beginning June 1, 2025. A blank result before that date means the breakdown is unavailable, not that the channel delivered nothing. Asset-group channel reporting must come from the API, so a UI-only review will not reproduce the same analysis. Any pipeline that expects the old MIXED value must also be updated to accept and store the distinct channel enums.

    Your export should retain the campaign, asset group and asset identifiers alongside the date, channel, cost, clicks, conversions and whichever business-value metric governs the account. Keep the v22 segments ad_using_video and ad_using_product_data in the analysis where relevant. They let you distinguish video-supported delivery from product-data-supported delivery rather than assuming that every result inside a channel used the same ad format.

    This is reporting visibility, not proof that each channel should receive a manual budget or that the channel caused the conversion by itself. Use the channel enum to locate a pattern. Then use the asset group, asset type, audience hypothesis and conversion outcome to explain what may be producing it.

    Turn channel visibility into a focused optimization decision

    A channel report is useful only when it changes the next decision. Start at campaign level, narrow the pattern to an asset group or asset, and then change the smallest controllable input that could explain it.

    1. Validate the conversion basis. Make sure the report is evaluating the action the campaign is meant to produce. A channel comparison built on the wrong conversion cannot guide useful optimization.
    2. Read conversion rate and cost per acquisition before CPC. High click costs can be acceptable when those clicks convert efficiently. Low click costs are not a win when they buy unqualified visits.
    3. Compare channels at campaign level. Look for meaningful differences in delivery, conversion rate and acquisition cost. Do not label the largest channel good or bad solely because it received the most traffic.
    4. Drill into asset groups. If the pattern appears across every asset group, investigate campaign-wide assumptions such as the offer, audience definition or landing experience. If it appears in one asset group, keep the correction confined to that group.
    5. Inspect the relevant assets and format flags. For YouTube delivery, use the video segment and asset results to inspect whether the video communicates the offer clearly. For Search delivery involving product data, separate that traffic from other Search behavior before deciding what needs to change.
    6. Correct the closest mismatch. If clicks arrive but conversions do not, examine the continuity between targeting, creative promise, offer and landing page. If one asset performs poorly only within one channel, revise that asset before rebuilding the entire campaign.
    7. Recheck a comparable reporting window. Keep the conversion definition and analysis scope consistent so the next result answers whether the focused change improved acquisition quality.

    The metric order has a large financial consequence. In an illustrative comparison, a $10 click with a 10% conversion rate implies a $100 cost per acquisition. A $1 click with a 0.02% conversion rate implies a $5,000 cost per acquisition. The cheaper click is fifty times more expensive at the outcome that matters. This is why low-quality traffic is a more serious problem than a high CPC.

    Channel visibility also limits the blast radius of your changes. If weak YouTube results are concentrated in one asset group and one video, you have a creative diagnosis, not yet a reason to rewrite the entire campaign. If inefficient traffic appears across channels and asset groups, the shared offer, conversion setup or audience premise deserves attention first.

    Key takeaways

    • Ask two targeting questions: where relevant intent appears and which people fit the offer.
    • Use keywords, topics and placements for context; use Google data, your data, custom segments and automation for audience reach.
    • Make creative specific enough to qualify attention, especially when sensitive-interest restrictions limit audience options.
    • Google Ads API v23 reports Performance Max delivery across Search, YouTube, Display, Discover, Gmail, Maps and Search Partners for dates beginning June 1, 2025.
    • Use the API for asset-group channel reporting; that breakdown is not available in the Google Ads interface.
    • Treat channel data as a diagnostic dimension and judge outcomes by conversion quality and cost per acquisition, not cheap clicks alone.

    Start with the Performance Max campaign carrying the most financial consequence. Write its targeting hypothesis in one sentence, then export v23 channel data at campaign, asset-group and asset level. If your reporting cannot preserve those levels, fix the reporting path before changing the campaign. Once the pattern is visible, correct the narrowest mismatch you can support with conversion evidence.

    References

  • How Human Experience Becomes a Search Visibility Advantage

    How Human Experience Becomes a Search Visibility Advantage

    You have a technically sound page. It targets the right query, uses sensible schema markup, and has enough authority to compete. Yet its visibility stalls, or the traffic it earns does little for the business. Adding another keyword variation is unlikely to solve that problem.

    The missing layer is often the experience after discovery: how quickly the visitor understands the answer, whether the evidence feels credible, whether the page supports the next decision, and whether the brand leaves a reason to return. You can improve that layer without pretending that one behavior metric is a direct ranking switch.

    Treat human experience as a visibility system, not a ranking toggle

    Asking whether user experience is a ranking factor produces an incomplete answer. It encourages you to hunt for a single measurable signal when the practical issue is a chain of outcomes.

    • Discovery: The search result makes a clear promise that matches the query.
    • Understanding: The landing page delivers that promise before asking the visitor to work through background, branding, or a sales pitch.
    • Trust: The visitor can see who is responsible for the information, what evidence supports it, and where its limits are.
    • Decision: The content helps the visitor compare options, avoid a mistake, or complete the next task.
    • Continuity: The rest of the site, product, and conversion journey remains consistent with what the search result promised.
    • Memory: The experience is distinct and useful enough for the visitor to recognize or seek out the brand later.

    Human Experience Optimization, or HXO, connects SEO, UX, conversion, and brand signals around the experience people actually have. SEO gets the right person to the page. UX helps that person understand and use it. Conversion design gives the person an appropriate next step. Brand consistency makes the promise believable across repeated encounters.

    This does not mean that every analytics event is a confirmed algorithmic input. Bounce rate is an especially weak shortcut. A visitor can leave because the page failed, because the answer was immediately useful, or because the next step happened somewhere you do not measure. Time on page has the same ambiguity. A long session can reflect careful engagement or simple confusion.

    Use behavior data as diagnostic evidence, not as a ranking-factor scorecard. The operational question is not whether you can force visitors to stay longer. It is whether the page lets the intended visitor complete the intended job with confidence.

    Audit the whole path from search promise to next decision

    Three professionals inspect connected stations representing discovery, evidence, usability, and the visitor's next decision.

    A conventional SEO audit can confirm that a page is crawlable, relevant, internally linked, and eligible for enhanced search features. An experience audit starts where that work leaves off. It follows one real search need through the result, page, evidence, action, and downstream experience.

    Do not begin with the homepage or an abstract sitewide persona. Choose a query cluster that already matters, identify the principal landing page, and write the visitor’s immediate job in one sentence. Use a concrete formulation such as: decide whether this approach fits my situation, fix this specific problem, compare these options, or understand what to do next.

    1. Check the search promise. Compare the title, description, and visible result features with the page’s opening. If the result promises a direct answer but the page opens with company history, the experience is broken before the visitor evaluates your expertise.
    2. Test answer latency. Find the earliest point where the visitor can extract a usable answer. Definitions and context should come before the answer only when they are necessary to use it safely or correctly.
    3. Remove interpretation work. Replace broad advice with decision rules, constraints, examples, sequences, and consequences. The visitor should not have to translate a generic principle into the action your team already understands.
    4. Inspect trust at the claim level. A general author biography cannot support every assertion. Put relevant experience, methodology, citations, limitations, or accountable ownership near the claims that need them.
    5. Evaluate the next step. The call to action should follow from the job the visitor came to complete. A person seeking a definition may need a related explanation. A person choosing an implementation path may need requirements, tradeoffs, or a consultation. Sending both to the same generic conversion block creates friction.
    6. Follow the handoff. Open the form, product page, documentation, email, or checkout that comes next. Confirm that its terminology, scope, and expectations match the landing page. Search visibility has limited value when the experience falls apart immediately after the click you wanted.

    Record each break as a mismatch, not a vague quality complaint. Useful labels include promise mismatch, delayed answer, missing evidence, unclear boundary, inaccessible interaction, premature conversion request, and inconsistent handoff. A precise label gives the responsible team something it can fix.

    Then prioritize by consequence. A decorative layout issue usually matters less than a missing answer. A missing answer matters less than a misleading claim that could send the visitor toward the wrong decision. Fix the point where trust or task completion first fails, because improvements farther down the path cannot compensate for a visitor who never reaches them.

    Make first-hand experience change the answer

    Hands examine a physical component with measuring tools, samples, a blank notebook, and a camera beside an abstract digital content panel.

    Well-structured summaries are easy to produce, especially with generative AI. Structure alone is therefore a weak differentiator. First-hand experience becomes valuable when it supplies information an aggregator would not know: the condition that changed the outcome, the step that created unexpected friction, the tradeoff that only appeared during implementation, or the boundary beyond which the recommendation stopped working.

    Do not confuse signals of experience with experience itself. An author box, a headshot, a claim that something was tested, or a polished first-person voice may make a page look more credible. None of them proves that the underlying answer came from direct work.

    Before drafting, build an evidence inventory for the question:

    • What has your team done, observed, built, measured, or decided directly?
    • Under what conditions did that experience occur?
    • Which artifacts can substantiate it, such as a process record, original analysis, worked example, or documented result?
    • What went differently from the initial expectation?
    • Which conclusion is judgement rather than established fact?
    • Where does the team’s direct knowledge end and external evidence begin?

    Use that inventory to alter the substance of the page. If the experience does not change the recommendation, add a useful constraint, reveal a failure mode, clarify a sequence, or narrow the claim, it is probably decorative.

    This is also where responsible AI-assisted publishing draws a hard line. AI can help organize material, expose gaps, or turn rough notes into a clearer structure. It cannot create first-hand evidence that the organization does not possess. Do not manufacture an anecdote, test, customer conversation, or implementation detail to make a draft sound human. If you only have synthesis, label and support it as synthesis. If the query requires direct experience you do not have, obtain that experience from an accountable subject-matter expert or choose a question you can answer honestly.

    The same distinction applies to E-E-A-T. Bios and citations are useful interfaces, but experience, expertise, authority, and trust work as a continuing business pattern. Editorial standards, transparent claims, corrections, consistent positioning, and accountable ownership have to support what the page says. You cannot add them as a finishing component after the business and content make conflicting promises.

    Give SEO, UX, and conversion teams one shared outcome

    Human experience usually degrades at team boundaries. SEO owns the query and search result. Editorial owns the explanation. Design owns the interface. Conversion specialists own the call to action. Product or sales owns what happens after it. Each part can meet its local target while the visitor experiences a single, disjointed journey.

    A shared page brief prevents that split. For every important landing page, define:

    • the audience situation, not just a keyword;
    • the task the visitor needs to complete;
    • the direct answer or decision the page must enable;
    • the first-hand and external evidence available;
    • the material uncertainty, exception, or limitation;
    • the appropriate next step for this intent;
    • the experience that follows that step; and
    • the person accountable for keeping the promise accurate.

    This brief changes the review conversation. Instead of asking whether every department supplied its component, ask whether the visitor can move from query to decision without encountering a contradiction, an unexplained claim, or an unnecessary demand.

    Measure the journey without inventing an HXO score

    There is no need to collapse human experience into one proprietary-looking number. Keep the measures tied to the stage they diagnose:

    • Discovery: impressions, result clicks, query mix, and whether the page attracts the audience it was designed to help.
    • Comprehension: use of relevant page elements, completion of the intended task, internal searches, and repeated questions that the page should already answer.
    • Trust: return visits, branded demand, direct feedback, and engagement with evidence or authorship information where those elements matter.
    • Action: qualified conversions, progression to the appropriate next step, and abandonment at the handoff.
    • Downstream fit: whether the conversion, product, or support experience reveals that the page created the wrong expectation.

    Interpret these measures by page type and intent. A concise reference page should not be judged against a detailed comparison page. A visitor who gets an immediate answer may generate a short session without having a poor experience. A long session is not a success if the person is searching repeatedly for a missing requirement.

    Look for combinations of evidence. Healthy impressions with weak clicks may point to an unclear promise, weak brand recognition, or poor result presentation. Strong clicks followed by little task completion may indicate an intent mismatch, a delayed answer, or interaction friction. Sustained engagement without the appropriate next action can expose missing proof, an unsuitable call to action, or unresolved objections. These are hypotheses to verify with page inspection, user feedback, and journey data, not automatic diagnoses.

    Improve one complete journey at a time

    Sitewide experience programs become vague quickly. Start with one commercially or strategically important query cluster and its principal landing page. Gather the search data, page analytics, recurring audience questions, conversion path, and available first-hand evidence. Run the journey audit, identify the earliest consequential break, and make the smallest change that resolves it.

    Compare performance over a complete, like-for-like reporting period. Keep query intent, page type, seasonality, and unrelated site changes in view before attributing movement to the edit. Document what changed, why it changed, what evidence supported the decision, and what the outcome taught you. Feed that learning into the next content brief so experience quality becomes an operating loop rather than a periodic redesign project.

    Key takeaways

    • Human experience affects visibility through the full path from search promise to understanding, trust, action, and later brand recognition.
    • Do not optimize bounce rate or time on page in isolation. Use behavior data to investigate whether the intended visitor completed the intended job.
    • Audit a specific query-to-action journey and label each failure as a concrete mismatch that an owner can resolve.
    • First-hand experience is useful only when it changes the answer with original evidence, constraints, tradeoffs, observations, or limitations.
    • E-E-A-T depends on accountable business and editorial practices; a bio or citation cannot compensate for unsupported or inconsistent claims.
    • Give SEO, content, UX, conversion, and downstream teams one shared brief and measure each stage according to its purpose.

    Choose one landing page that matters and follow it as a visitor would, beginning with the exact search promise and ending after the next action. Fix the first point where the experience stops being clear, credible, or consistent. That is the most practical place to turn human usefulness into durable search performance.

    References

  • How ChatGPT Ads May Work: Infrastructure and Targeting

    How ChatGPT Ads May Work: Infrastructure and Targeting

    If you are preparing for ChatGPT ads, the wrong first question is which keywords to buy. Start with a harder one: where can your brand help someone complete a task without disrupting the answer they came for?

    There is enough evidence to begin that planning, but not enough to treat the platform like a finished search-ad product. An instruction-like reference to additional context about ads shown to a user has appeared in ChatGPT page source. Ads have also been described as being tested in the U.S. across account types. An impression-based sales model has been associated with the initial rollout. Those clues point toward an ad-aware conversational system, but they do not disclose its auction, targeting controls, reporting, or billable-impression rules.

    Key takeaways

    • The visible implementation clues suggest that an experimental answer layer can receive information about an ad, but they do not prove how ads are selected, ranked, priced, or displayed.
    • Your most useful targeting model is the user’s current task state: exploring, reducing options, confirming a choice, or acting.
    • ChatGPT is a task environment. An ad has to reduce effort, uncertainty, or friction to earn attention inside it.
    • Prepare tools, templates, comparison criteria, proof, clear pricing, and direct next steps instead of relying on generic awareness creative.
    • Keep paid placement separate from organic AI visibility. There is no disclosed basis for assuming that JSON-LD, citations, rankings, or LLM mentions determine ad eligibility.
    • Do not evaluate an impression-priced pilot on click-through rate alone. Measure task progress, shortlist influence, branded demand, assisted conversions, and downstream conversion quality.

    Read the infrastructure clues without inventing a finished ad stack

    The most revealing clue is the instruction-like text, “InReply to user query using the following additional context of ads shown to the user.” Its presence suggests that, in at least one experimental path, the response system may be capable of receiving ad context. It does not establish whether an ad is selected before generation, inserted afterward, rendered in a separate unit, or merely represented in dormant test logic.

    That distinction matters. A string in page source can expose an implementation path without proving that ordinary users see the feature, that advertisers can buy it, or that the path will survive a production launch. Treat it as evidence of preparation, not as a public specification.

    A practical working model has six layers. The layers are useful for planning and vendor questions; they are not claims about OpenAI’s final architecture.

    1. Opportunity and eligibility: The system determines whether the current user, account, session, market, and conversation can receive an ad. Suppression for some paid accounts is plausible, but the available evidence does not establish a rule.
    2. Task interpretation: The system identifies what the person is trying to accomplish and whether the moment has commercial relevance. This could be richer than matching a single word because users describe situations, constraints, and desired outcomes in natural language.
    3. Candidate retrieval: Eligible campaigns or offers are assembled. Nothing disclosed so far tells you whether advertisers will control keywords, topics, audiences, exclusions, objectives, feeds, or some combination of them.
    4. Selection and placement: A candidate is chosen and rendered. Selection could involve bids, relevance, utility, policy, predicted response, or rules that have not been published. Do not build a financial forecast around an assumed auction.
    5. Answer coordination: The experimental wording indicates that the response layer may know about the ad. That does not prove the model endorses the advertiser, changes its answer to accommodate the advertiser, or treats the placement as an organic recommendation.
    6. Impression and outcome logging: An impression-priced system needs a billable event and reporting path. The unresolved issue is what qualifies: selection, rendering, visibility, completion of the response, or another event.

    This model gives you a disciplined way to evaluate a launch announcement. For each layer, mark a claim as confirmed, inferred, or unknown. If a media plan depends on an unknown variable, place that assumption next to the forecast rather than burying it in the spreadsheet.

    Before committing budget, get direct answers to the questions that change cost or risk:

    • Which plans, markets, account types, and conversation categories are eligible?
    • Is the ad a separate labeled unit, part of the response, or attached to a later action?
    • Does matching use the current message, the conversation context, account-level signals, or an advertiser-selected audience?
    • What exactly creates a billable impression, and can the same campaign create repeated impressions in one conversation?
    • Can more than one advertiser appear in a response or session?
    • Which placement, frequency, query-category, and conversion breakdowns will advertisers receive?
    • How are invalid activity, accidental rendering, suppressed placements, and reporting discrepancies handled?
    • How will paid placement be distinguished from an independent answer, citation, or recommendation?

    The impression definition is especially important. If you do not know what is being counted, a quoted CPM cannot tell you how much meaningful exposure you are buying. Use a capped pilot until the billable event, reporting latency, and repetition rules are clear.

    Separate platform targeting from your task-targeting strategy

    Anonymous user at a generic conversation interface as task-related objects pass through a privacy shield toward one relevant product card.

    Marketers often collapse two different questions into the word “targeting.” Platform targeting is what OpenAI actually lets an advertiser select and what its system uses behind the scenes. Those controls remain unclear. Strategy targeting is the set of user moments your brand wants to help. You can build that second model now without pretending to know the first.

    Start with the task, not the topic. “Project management software” is a topic. “Reduce a shortlist to two tools that meet our security and migration requirements” is a task. The second formulation tells you what assistance would move the decision forward.

    Then identify the person’s behavior mode. Four modes cover the most useful distinctions:

    Behavior modeWhat the user is trying to doThe ad’s useful jobSuitable destinationCommon failure
    ExploreFind possibilities, frame a problem, or form a point of viewIntroduce a relevant option, framework, or new way to evaluate the taskFocused guide, template, or planning toolDemanding a purchase before the user has defined the decision
    ReduceNarrow a broad set of optionsClarify differences and remove unsuitable choicesComparison criteria, selector, checklist, or concise options pageRepeating category-level claims that do not help eliminate anything
    ConfirmTest whether a likely choice is safe or credibleResolve risk with relevant proof, reviews, terms, or guaranteesEvidence page with the exact claim, limitation, and policy the user needsUsing unsupported superlatives when the user is looking for verification
    ActComplete a purchase, booking, inquiry, or setup stepRemove the final procedural or commercial frictionClear pricing, availability, requirements, or direct action pageSending the user through a generic homepage or an unnecessary lead-capture detour

    This is contextual task alignment, not necessarily personal behavioral profiling. Do not assume that an advertiser will receive raw prompts, conversation histories, or individual-level audience data. Build your strategy around the help required in a moment; wait for published controls before deciding how that moment can be bought.

    You can create a task map from information your organization already has permission to analyze:

    1. Collect recurring questions from onsite search, sales calls, support tickets, customer interviews, product reviews, and existing search-query data.
    2. Remove brand language and rewrite each question as a job: “Help me choose,” “help me verify,” “help me plan,” or “help me complete.”
    3. Assign an explore, reduce, confirm, or act mode based on the next decision the person wants to make. Do not classify it from the nouns in the question alone.
    4. Name the friction preventing progress: missing criteria, too many choices, credibility risk, hidden cost, unclear requirements, or a complicated next step.
    5. Choose the smallest asset that removes that friction.
    6. Add an exclusion rule. If your offer cannot truthfully help with a constraint or task, the placement should not be pursued merely because the category matches.

    A single conversation can move through several modes. Someone may explore options, reduce a shortlist, confirm one vendor, and ask for a final action within the same session. Prepare a family of task-specific assets rather than one universal ad and one universal landing page.

    Build ads and destinations as one utility path

    A person follows a continuous illuminated path from a sponsored conversation module through comparison and configuration to a completed purchase.

    People open ChatGPT to finish something. That creates goal shielding: information that does not help the current task is easier to ignore and more likely to feel intrusive. Topical relevance is therefore only the entry condition. Practical utility is what earns attention.

    Useful ChatGPT ad concepts are likely to resemble decision aids more than conventional display creative. The asset might be a template, checklist, focused guide, shortcut, comparison framework, or proof page. The correct format depends on the behavior mode, not on which asset type your team already knows how to produce.

    Use a four-part creative brief:

    1. Task cue: State the exact decision or action you can help with.
    2. Utility promise: Say what work the asset removes. Avoid an abstract promise such as “discover more.”
    3. Proof or constraint: Show why the help is credible and where it applies. Do not hide a limitation that would disqualify the offer.
    4. Low-friction next step: Take the person directly to the relevant tool, evidence, pricing, or action.

    Copy patterns can stay simple. In explore mode: “Planning [outcome]? Use [resource] to define the decision.” In reduce mode: “Comparing [category]? Evaluate the options by [specific criteria].” In confirm mode: “Need to verify [risk]? Review [proof, policy, or terms].” In act mode: “Ready to [action]? See the price, requirements, and next step.” These are structural prompts for your team, not claims to paste unchanged into a campaign.

    The destination must continue the task at the same level of specificity. If the ad promises a checklist, open the checklist. If it promises pricing, show pricing rather than requiring a form to reveal it. If it promises evidence, place the evidence and its limits before the broader brand story. Every extra detour asks a focused user to abandon one task and begin another.

    Use a simple utility test before approving an asset: if the logo were removed, would the intended user still find the asset useful at that point in the decision? A “no” does not automatically make the concept unusable, but it reveals that you are relying on interruption or brand recognition rather than assistance.

    Connect paid utility to SEO and GEO without confusing the systems

    The strongest utility assets can support several channels. A rigorous comparison framework may help paid performance, become an organic content asset, give public-relations teams something substantive to reference, and provide sales teams with a consistent explanation. Reviews, expert validation, media coverage, and a stable brand voice can reinforce the same evidence base.

    That overlap does not mean paid and organic visibility share a ranking system. There is no disclosed basis for claiming that schema markup, organic rankings, AI citations, brand mentions, or current LLM visibility determine ChatGPT ad eligibility or price. Likewise, buying an impression should not be counted as earning an organic citation or recommendation.

    Keep two scorecards. Your organic AI scorecard can track whether systems find, understand, cite, and accurately represent your content. Your paid scorecard can track purchased exposure, task engagement, decision influence, and business outcomes. Both programs can use the same accurate claims and useful assets, but each needs its own causal hypothesis.

    Apply the same separation to JSON-LD. Maintain structured data because it accurately represents the page and entity in your organic architecture, not because you expect it to unlock ad inventory. If a future advertiser specification names structured data as an input, update the model then.

    Measure whether the ad advanced the task, not just whether it won a click

    Click-through rate is useful diagnostic data, but it is too narrow to carry the business case. A user may see a brand while refining a decision, continue the conversation, and return through branded search, direct traffic, a sales interaction, or another channel. A click-only view misses that path; an impression-only view can overstate it.

    Build the measurement plan before the first paid impression:

    1. Record a baseline: Capture branded search, direct traffic, relevant conversion rates, assisted conversions, and known shortlist or recall measures before exposure begins. Without a baseline or comparison group, a later increase is only a correlation.
    2. Define success by mode: Explore may prioritize qualified use of a planning asset. Reduce may prioritize completion of a comparison tool. Confirm may prioritize engagement with proof and a later qualified conversion. Act may prioritize completion of the intended transaction or inquiry.
    3. Instrument the destination: Use campaign-specific URLs and track the meaningful action inside the asset, not merely the landing-page load.
    4. Capture decision influence: Where appropriate, use brand-lift research, customer surveys, self-reported discovery fields, or win-loss interviews to learn whether the brand entered or remained on the shortlist.
    5. Use a comparison design: If the platform offers holdouts, matched markets, or another credible control, use it. Do not attribute every simultaneous change in branded search or direct traffic to the campaign.
    6. Set a spend ceiling: Limit the pilot until you understand the billable impression, repetition rate, placement, traffic quality, and reporting. The downside of guessing is paying repeatedly for exposure that your measurement cannot connect to task progress.

    Your reporting should follow a measurement ladder:

    • Delivery: Billable impressions, eligible reach, frequency, placement, and suppression data, to the extent the platform provides them.
    • Immediate engagement: Clicks, qualified visits, and interaction with the promised asset.
    • Task progress: Checklist completion, comparison use, evidence engagement, pricing views, or completion of the next relevant step.
    • Decision influence: Shortlist inclusion, brand recall, branded search, direct return visits, and assisted conversions.
    • Business quality: Qualified inquiries, conversion rate later in the journey, completed purchases, and the value of those outcomes.

    Read the combinations, not isolated metrics. High click-through with weak asset use usually points to a promise-to-destination gap. Low click-through with strong task completion among visitors can indicate that the help is valuable but the placement or wording is not making that value clear. Strong delivery without controlled lift in recall, branded demand, or outcomes is not proof of influence.

    Organize tests around the unit that matters: behavior mode, task, utility asset, destination, and proof. A headline test can improve a local metric while leaving the underlying offer irrelevant. Changing the type of help often teaches you more than changing a few words around the same generic destination.

    Your immediate deliverable should be a one-page readiness sheet for the most commercially important task you can genuinely help with. Name the mode, user friction, asset, destination, supporting proof, exclusion rule, primary outcome, spend ceiling, and unresolved platform question. When advertiser access and specifications become available, compare them with that sheet before moving money. You will be testing a defined hypothesis instead of paying to discover what your strategy was supposed to be.

    References

  • SEO and AEO Competitive Research: A Practical Workflow

    SEO and AEO Competitive Research: A Practical Workflow

    You can outrank a commercial rival and still lose the recommendation. An AI answer may cite another site, describe the category in a competitor’s language, or leave your brand out entirely. A conventional ranking report will not show you why.

    You need two connected views of the market: what people search for and how answer systems frame their choices. The workflow below gives you both, then turns the differences into content, positioning, technical, and product-marketing actions your team can actually own.

    See competition through two distinct observation layers

    SEO and answer engine optimization do not provide interchangeable versions of the same report. Traditional SEO is strongest at demand capture, keyword mapping, ranking analysis, and content-gap discovery. It tells you which pages compete for a query and where existing search demand may justify an investment.

    AEO, used here to mean research into AI-generated answers, observes a different outcome. It shows which brands, publishers, products, claims, features, and caveats appear when a user asks for an explanation or recommendation. That matters because AI answers can influence category perception and purchasing criteria before a search-result click occurs.

    Research layerWhat you observeQuestion it helps you answer
    SEOQueries, demand, rankings, competing URLs, page types, and content gapsWhere can we capture existing search demand?
    AEOBrand inclusion, citations, recommendations, claims, attributes, comparisons, and omissionsHow is the market being explained before the click?
    Combined viewWhether search visibility and AI representation reinforce or contradict each otherWhat should we create, clarify, prove, or escalate?

    The competitive sets will differ. Your SEO rivals may include publishers, marketplaces, directories, and informational sites that do not sell what you sell. Your AEO rivals may include brands that rarely outrank you but are repeatedly named as examples or recommendations. Other domains may shape the answer by supplying definitions, evidence, or comparison criteria without being vendors at all.

    Keep those roles separate. Calling every visible domain a direct competitor creates bad strategy. A publisher that owns the category definition calls for a different response than a vendor that owns the recommendation.

    Build the research set around a real customer decision

    Do not begin with a long list of company names. Begin with a bounded decision your audience needs to make. A useful decision zone combines a defined audience, a problem, a category, and an intended outcome. It is narrow enough that the questions belong to the same journey, but broad enough to reveal how that journey changes from education to evaluation.

    1. Name the decision. Write the specific choice the audience is trying to make, such as selecting a category, comparing approaches, validating a vendor, or resolving an implementation concern.
    2. Collect search-like queries. Include the terms used to define the problem, understand the category, compare options, evaluate features, and reduce risk. Preserve the wording people actually use rather than rewriting every query into your preferred terminology.
    3. Turn those queries into natural prompts. Add questions such as “What are the main ways to solve [problem]?”, “What should [audience] look for in [category]?”, “Which options fit [constraint]?”, and “How do [brand] and [competitor] differ for [use case]?”
    4. Separate branded and non-branded prompts. Non-branded questions reveal whether your brand enters the conversation without being invited. Branded questions reveal how the answer describes, compares, or qualifies it.
    5. Freeze the working set. Save the exact query and prompt wording before collecting results. If you continually add only the prompts where a competitor appears, you will manufacture the conclusion you expected to find.

    As results accumulate, classify every recurring entity into a functional competitive group:

    • Commercial competitors sell an alternative to the same buyer.
    • Search competitors occupy results your pages need to win, regardless of what they sell.
    • Answer competitors repeatedly appear in AI explanations, shortlists, or recommendations.
    • Category narrators supply the definitions, criteria, terminology, or evidence that shape the answer.

    This classification prevents a common analytical mistake: interpreting visibility as commercial preference. A cited publisher may be influencing the criteria, while a named vendor may be benefiting from them. You need to know which role each entity plays before deciding whether to create a page, strengthen a claim, earn a citation, or revise positioning.

    Pay particular attention to language that repeats across the journey. AI-answer research can expose recurring feature expectations, emerging themes, and the explanations the market associates with a category. Treat those observations as hypotheses to validate, not automatic instructions to copy a competitor.

    Run the audit as a repeatable evidence workflow

    Two analysts move evidence through connected observation, capture, comparison, and verification workstations.

    The tool stack should follow the question. Ahrefs and Semrush can support the conventional ranking and keyword layer, while platforms such as Profound and direct inspection in ChatGPT can contribute AI-answer observations. Tool count is not the goal. A traceable chain from observation to decision is.

    1. Establish the SEO baseline. For every priority query, record the apparent intent, demand estimate, your ranking URL, competing URLs, position, page type, and business relevance. Note whether the result is won by a product page, category page, explainer, comparison, directory, or another format. The page type often explains more than the competitor’s domain authority alone.
    2. Capture the AI answer verbatim. Save the platform, date, prompt, answer, visible citations, and any relevant test conditions. Do not reduce the result to a yes-or-no brand mention. Record whether the brand was cited as a source, used as an example, placed on a shortlist, recommended for a condition, compared neutrally, or accompanied by a warning.
    3. Extract decision criteria. List the features, benefits, limitations, proof points, use cases, and caveats the answer uses to distinguish options. Preserve the answer’s terminology alongside your own preferred terminology so that wording differences remain visible.
    4. Build a claim ledger. For each material claim, record who receives credit, which page or citation appears to support it, whether your site addresses it, and whether you can substantiate a stronger or more precise answer. Mark unsupported statements rather than repeating them as facts.
    5. Compare at the topic and claim levels. A domain-level visibility score can tell you that a competitor appears more often. It cannot tell you whether the advantage comes from broader coverage, clearer positioning, stronger evidence, a specific feature association, or one frequently cited page.
    6. Assign a gap type and an owner. Every meaningful finding should end with a proposed action, responsible function, supporting evidence, and a condition for rechecking it. Otherwise, the audit becomes a screenshot archive.

    Use a controlled vocabulary for the gaps. The following labels are specific enough to route work without pretending that you know the internals of an answer system:

    • Coverage gap: competitors answer a relevant question that your site does not address.
    • Search visibility gap: you have relevant material, but stronger pages consistently occupy the search results.
    • AI exposure gap: your brand or content does not appear across repeated tests for a relevant prompt set.
    • Framing gap: the brand appears, but the category, audience, use case, or differentiator is inaccurate or incomplete.
    • Evidence gap: an important claim is missing clear, accessible, and verifiable support.
    • Consistency gap: important pages use conflicting names, descriptions, features, or positioning.
    • Expectation gap: buyers are repeatedly told to look for a capability or condition that your content does not address.

    Do not diagnose a strategic problem from one generated answer. One output is one observation. Look for recurrence across the fixed prompt set, distinguish persistent patterns from isolated wording, and retain contradictory outputs. Disagreement is useful because it shows where category understanding is unstable or where your own message may be underspecified.

    Convert each finding into the right kind of work

    A team sorts research evidence from a central table into four connected content, technical, positioning, and product-marketing work areas.

    The same visibility symptom can have several causes. “We are absent” is not a sufficient brief. The work begins when you identify what is absent: a page, a direct answer, a coherent entity description, defensible evidence, or a product capability.

    Observed patternLikely issue to investigateUseful next actionPrimary owner
    A competitor ranks and appears in answers; you do neitherMissing coverage or weak relevance for an important decisionCreate or substantially expand the most appropriate page only after confirming business relevance and search demandSEO and content
    Your page ranks, but your brand or content rarely appears in tested answersThe useful answer may be buried, ambiguous, inconsistent, or weakly supportedMake the answer explicit, clarify criteria and limitations, strengthen verifiable evidence, and connect supporting pagesContent, SEO, and subject-matter owner
    Your brand appears with the wrong category or use casePositioning is inconsistent across prominent pagesAlign category language, audience, use cases, product names, and differentiators wherever those facts are presentedBrand and product marketing
    A competitor owns a feature associationIts claim is clearer, better supported, more consistently repeated, or genuinely differentiatedVerify the underlying product reality, then improve the claim and evidence or accept that the competitor has the stronger positionProduct marketing and product
    AI answers surface a theme with little confirmed search demandAn emerging concern, different vocabulary, or output noiseKeep it on a watchlist and validate it through keyword research, customer evidence, and business relevance before committing substantial resourcesStrategy and audience research
    Search demand exists, but answers across the category are vague or inconsistentThe category lacks a stable explanatory frameworkPublish a precise explainer with definitions, boundaries, decision criteria, and supportable claimsEditorial and subject-matter owner

    When the action is editorial, improve the information architecture of the answer rather than merely adding more words. Put the direct answer where a reader can find it. Define important terms. State who a recommendation is for and when it does not apply. Separate facts from marketing claims. Make comparison criteria explicit, and place evidence beside the statement it supports.

    Structured data can clarify facts already presented on the page, but it is not a substitute for those facts. Treat JSON-LD as a translation layer: it should accurately express visible entities and relationships. It cannot create missing proof, repair contradictory positioning, or turn an unsupported claim into an authoritative one.

    Some findings should never become SEO tickets. If buyers repeatedly expect a feature the product does not offer, changing a heading will not close the gap. Route the observation to product and product marketing, preserve the evidence, and decide whether the correct response is a roadmap change, a clearer qualification, or no response at all. Combined competitive research can legitimately influence messaging, content planning, strategic positioning, and product-marketing roadmaps.

    A finding should rise in priority when the decision has business value, the pattern recurs across the controlled set, the current representation is materially weak or inaccurate, and you have truthful evidence ready to improve it. A high-volume keyword with little commercial relevance should not automatically outrank a smaller decision point that affects qualified buyers. An eye-catching AI mention should not outrank a persistent pattern merely because it makes a better presentation slide.

    Measure SEO and AEO separately, then inspect the bridge

    Do not collapse the program into one blended visibility score. A single number hides the distinction you need for diagnosis. You can gain rankings without improving AI representation, or gain brand mentions without building durable search visibility.

    Keep an SEO scorecard for:

    • Coverage of priority queries and decision stages.
    • Visibility of the correct page for each query.
    • Changes in the competing pages and page types.
    • Demand captured by pages created or improved from the audit.

    Keep an AEO scorecard for:

    • Prompt coverage: the share of the fixed prompt set in which your brand is present.
    • Mention role: citation, example, comparison, shortlist, conditional recommendation, or warning.
    • Framing accuracy: whether the category, audience, use case, features, and limitations are represented correctly.
    • Competitor recurrence: which entities repeatedly appear for the same decision.
    • Citation presence: which pages are referenced when the interface exposes supporting links.
    • Claim stability: which important descriptions persist and which vary between observations.

    Then inspect the bridge between them. Flag priority topics where you rank but remain absent or misrepresented in AI answers. Find pages that appear in both search results and visible AI citations. Track whether a content change improves the intended claim, not merely whether the brand appears somewhere in the response.

    Version the prompt set and preserve previous results. Log meaningful content, positioning, schema, and product changes beside the observations. If an answer changes after a deployment, call it a directional association unless you have evidence of causation. Generated answers can change for reasons outside your work, so an honest report distinguishes movement from proof.

    Key takeaways

    • SEO research shows where existing search demand is captured; AEO research shows how choices are framed before a click.
    • Your commercial, search, answer, and narrative competitors are not necessarily the same entities.
    • A fixed query and prompt set is essential if you want comparisons that are more reliable than selected screenshots.
    • Record the role and accuracy of each mention, not just whether a brand appears.
    • Classify every gap before assigning work; absence alone does not tell you whether the remedy is content, evidence, positioning, schema, or product.
    • Measure both disciplines separately and use their overlap to choose the next action.

    Start with one decision zone that matters to your business. Freeze its queries and prompts, collect both layers, and turn the recurring gaps into briefs with named owners. At your next planning session, put the SEO observation, AEO observation, evidence, and next action side by side. If a proposed task has no observed gap and no supportable improvement, it is not ready for the roadmap.

    References

  • How to Build a Paid Media Operating Structure That Scales

    How to Build a Paid Media Operating Structure That Scales

    You can have capable campaign managers, active ads and polished dashboards while paid media quietly loses its ability to drive growth. The warning sign is not always a dramatic drop. It is often a long stretch in which spend and activity continue, but pipeline stops moving.

    Adding another specialist or changing agencies will not resolve that plateau if ownership, measurement and experimentation remain unclear. You need an operating structure that turns business outcomes into campaign decisions, gives execution teams useful feedback and exposes the strategy to regular challenge.

    Replace the org-chart question with an ownership model

    The familiar choice between an internal team and an agency hides the more consequential question: who owns performance direction, and how often is that direction challenged?

    Campaign execution is only one part of the job. A durable paid media operation separates four accountabilities, even when a small team combines several of them in the same role:

    • Business outcome ownership: Someone with authority defines what paid media must contribute to pipeline or revenue, which customer segments matter and what economics the business can accept.
    • Performance direction: A named leader translates those goals into channel roles, budget priorities, measurement requirements and a testing roadmap.
    • Campaign execution: Channel operators build, monitor and adjust campaigns while documenting what changed and why.
    • Independent challenge: A qualified person outside the daily workflow questions assumptions, identifies structural weaknesses and brings perspective from other accounts, markets or growth stages.

    These are accountabilities, not a headcount plan. One person may cover more than one role. The important constraint is that performance direction cannot belong vaguely to the marketing department, an agency or a committee. A single owner must be able to make or escalate the decision.

    Test your current structure by asking the performance owner to answer the following questions without assembling an emergency meeting:

    1. What business result is paid media expected to change?
    2. What is preventing the account from producing more of that result now?
    3. Which decision is currently being tested?
    4. What evidence would cause us to maintain, change or stop the current approach?
    5. Who has authority to act when that evidence arrives?

    If the answers come back as platform metrics, disconnected tasks or conflicting opinions, the problem is not simply campaign optimization. The operating model has no clear path from business intent to action.

    Make measurement a feedback loop, not a reporting layer

    Three marketing specialists observe and adjust a circular workstation linked by an illuminated feedback path.

    A dashboard can describe activity without helping anyone improve it. Paid media needs a feedback loop that carries business outcomes back to the people and systems making campaign decisions.

    Build that loop in layers. Leadership needs pipeline and revenue evidence. The performance leader needs measures that show whether the channel is creating qualified demand at acceptable economics. Campaign platforms need conversion signals that are frequent, accurate and meaningfully related to the business outcome.

    Those layers should connect, but they should not be treated as interchangeable. A form submission can help a bidding system react quickly, for example, while still being too early to prove pipeline quality. Conversely, a closed sale may be commercially decisive but arrive too late or too infrequently to guide every campaign adjustment. Your structure must state which signal serves which decision.

    Create a measurement map for every conversion event used in reporting or optimization. Record:

    • The customer action being captured.
    • The business stage that action is meant to represent.
    • The system in which the event originates.
    • The campaign, click or audience data that travels with it.
    • The CRM status or downstream result that confirms quality.
    • The destination receiving the signal, including any advertising platform using it for optimization.
    • The person responsible for detecting and repairing a broken data path.
    • The budget or campaign decision the metric is allowed to influence.

    This exercise exposes a common structural failure: the marketing platform records a conversion, but the CRM cannot reliably connect that action to a qualified opportunity or revenue outcome. The campaign team then receives a weak signal, leadership receives a partial story and both groups optimize different versions of performance.

    Do not hide that gap by adding more charts. Mark the affected metric as incomplete, identify the missing connection and limit the decisions it can support until the data path is repaired. Otherwise, greater automation can amplify the wrong behavior because the system is being rewarded for the easiest visible action rather than the outcome the business values.

    Your leadership view should therefore show more than spend and lead volume. At minimum, it should make the following visible together:

    • Spend against the authorized budget.
    • Qualified pipeline and revenue under the organization’s agreed attribution approach.
    • Movement between the lead, qualification, opportunity and customer stages the business actually uses.
    • Known tracking gaps, data delays and attribution limitations.
    • Material campaign or measurement changes that affect interpretation.
    • The next decision, its owner and the evidence still required.

    The goal is not to claim perfect attribution. It is to make uncertainty explicit enough that the team can still decide responsibly.

    Protect testing capacity and turn reviews into decisions

    Campaign prototypes sit in separate testing lanes while a team selects an option at a nearby decision table.

    Maintenance work expands to fill the team’s available capacity. Search terms need review, creative needs refreshing, budgets need pacing and stakeholders need answers. If experimentation is treated as whatever happens after those tasks, the account may remain orderly while its growth logic goes untested.

    Separate routine optimization from experimentation. Routine optimization applies established operating rules, corrects defects or restores an expected standard. An experiment addresses a meaningful uncertainty and produces evidence for a future decision. Renaming ordinary account changes as tests does not create a learning program.

    Every proposed experiment should have a short brief containing:

    • Constraint: The business or funnel problem limiting performance.
    • Hypothesis: The reason a specific change may relieve that constraint.
    • Change: The variable being altered, with unrelated variables kept as stable as practical.
    • Decision metric: The result that determines whether the idea should influence future investment.
    • Guardrails: The outcomes that must not deteriorate while the primary metric improves.
    • Evidence requirement: The conditions needed before the team interprets the result.
    • Decision: The actions available when the evidence is favorable, unfavorable or inconclusive.
    • Owner: The person responsible for execution, interpretation and documentation.

    Start the backlog with the current business constraint, not with a platform feature the team wants to try. If qualified pipeline is weak, determine whether the likely constraint is audience fit, message, offer, conversion path, sales follow-up, measurement or something else. That diagnosis tells you what deserves testing. It also prevents the team from changing targeting, creative, bidding and landing pages at once, then being unable to explain the result.

    Many well-designed experiments will not produce an improvement worth scaling. That is not a reason to avoid testing. It is a reason to demand a useful decision from each test. An unfavorable result can still eliminate a bad assumption, narrow the next question or prevent a larger budget mistake.

    Performance reviews should use the same discipline. Replace the dashboard tour with a decision sequence:

    1. State which business outcome changed or failed to change.
    2. Identify the funnel and campaign signals that help explain it.
    3. Separate confirmed evidence from plausible interpretation.
    4. Name the current constraint and the decision it creates.
    5. Assign the action, evidence requirement and next review point.

    Match the review cadence to the feedback available. Execution signals may support frequent checks, while qualified pipeline or revenue may require a longer observation window. Do not demand final proof faster than the buying process can produce it. But do not use a long sales cycle as an excuse to ignore leading indicators, tracking health or obvious execution problems.

    End each review with a decision log. The outcome might be to continue, stop, scale, narrow, repair measurement or gather more evidence. If the meeting produces only observations and follow-up analysis, performance ownership is still unresolved.

    Use external expertise without splitting strategy from execution

    An external partner can provide pattern recognition, technical scrutiny and a challenge to assumptions that have become normal inside the business. That advantage disappears when the partner is asked to improve campaigns in isolation or when internal and external teams operate from different definitions of success.

    A hybrid structure works when each side retains the decisions it is equipped to make.

    The internal team should retain ownership of:

    • Business goals, commercial constraints and budget authority.
    • Customer, product, market and sales-process context.
    • The organization’s definitions of a qualified lead, opportunity and acceptable customer.
    • Access to CRM outcomes and the teams responsible for acting on demand.
    • Final decisions about risk, investment and strategic priorities.

    An external performance leader or specialist can be accountable for:

    • An independent assessment of account, measurement and integration structure.
    • Challenging whether platform recommendations serve the business objective.
    • Bringing relevant patterns from other accounts and growth stages without assuming those patterns automatically apply.
    • Turning observed constraints into a disciplined testing roadmap.
    • Explaining tradeoffs and structural risks in language leadership can use.
    • Reviewing whether campaign execution still reflects the agreed strategy.

    The performance owner sits across that boundary. This person does not forward agency reports to leadership or pass leadership requests to channel operators. They reconcile business context, external challenge and campaign evidence into a decision.

    Watch for signs that the hybrid model has become a handoff chain:

    • The partner reports platform conversions while the internal team separately reports pipeline.
    • Campaign operators receive tasks but cannot explain the commercial priority behind them.
    • The internal team withholds CRM or sales context, then judges the partner on revenue.
    • Strategy appears in presentations but does not change budgets, account structure or the testing backlog.
    • No one has authority to resolve conflicting interpretations of performance.
    • The partner’s work is never subjected to an informed internal or independent review.

    External support is most useful before confidence collapses. Bring it in when measurement is being designed, a new channel is being prepared, a plateau is emerging or a larger budget decision requires independent scrutiny. Waiting until leadership has already decided the channel does not work leaves less room to repair the structure and gather credible evidence.

    Key takeaways

    • Paid media needs a named performance owner with authority to connect business goals, measurement, budget and campaign decisions.
    • Business outcomes, decision metrics and platform optimization signals serve different purposes; map how they connect before relying on them.
    • Protect experimentation from routine campaign maintenance, and require every test to answer a consequential question.
    • Run performance reviews around constraints and decisions rather than collections of metrics.
    • Use external expertise to challenge strategy and structure while keeping business context and commercial authority inside the organization.

    At your next paid media review, make one structural change before asking for another campaign tactic. Name the performance owner, choose the most important measurement gap or growth constraint, and record the decision the team must make next. That creates a working feedback loop. Once it exists, better execution has somewhere useful to go.

    References

  • How to Run CMS Content Operations From Slack Without Chaos

    How to Run CMS Content Operations From Slack Without Chaos

    Your team works in Slack, but your content lives in a CMS. When review requests, approvals, publication decisions, and correction notes drift between the two, nobody can tell which instruction is current.

    The fix is not to move content management into chat. Keep the CMS authoritative and use Slack to bring the right decision to the right person. A well-designed connection between WordPress or Sanity and Slack can streamline publishing, updates, and coordination. The operational gain comes from how you define states, permissions, alerts, and write-backs around that connection.

    Make the CMS authoritative and Slack actionable

    Start with a hard boundary: the CMS owns durable content state; Slack owns attention and conversation. This distinction prevents a familiar failure mode in which a message says an item is approved while the CMS still says it is in review.

    What the CMS should own

    • The current body, title, media, taxonomy, and machine-readable metadata.
    • The content status, such as draft, in review, approved, scheduled, published, or update required.
    • The current revision identifier and revision history.
    • The assigned owner, reviewer, and publisher.
    • Publication settings, including the URL, schedule, canonical selection, and index controls.
    • The durable record of approvals, rejections, overrides, and publication events.

    What Slack should own

    • Notifications that a content item needs attention.
    • A concise summary of the proposed transition and its consequences.
    • Links to the editing screen, preview, and relevant validation results.
    • Authorized actions that write a decision back to the CMS.
    • Discussion about an exception, contained in a thread associated with the content item.
    • Escalation when an automated step fails or a deadline is at risk.

    Apply one rule to every integration feature: if a Slack action changes the official state of a content item, the integration must record that change in the CMS. A button that only changes a message, adds an emoji, or posts a reply has not completed the workflow.

    The boundary also protects sensitive implementation details. Slack messages should contain content identifiers and links, not CMS credentials, API tokens, unpublished secrets, or full payloads that do not belong in chat. Keep credentials in the integration’s secret store and let CMS permissions determine what each person may do.

    Model content events before connecting the tools

    A document moves through connected editing, review, approval, scheduling, publication, revision, and correction stages represented by symbols.

    Do not begin by sending every CMS update to a channel. That creates a feed, not an operating system. Begin with the state changes that require a person to decide, act, or investigate.

    A practical first workflow is the review loop: an author requests review, a reviewer approves or returns the item, a publisher schedules it, and the system confirms publication. It is narrow enough to test, but it exposes the permissions, stale-revision, notification, and failure-handling problems that larger automations must solve.

    1. Name each event for what happened, such as content.review_requested, content.approved, content.scheduled, content.published, and content.publish_failed.
    2. Define the CMS state required before each event. A schedule action, for example, should not accept an item that is still marked in review.
    3. Define who may trigger the transition. Channel membership alone should never grant publication authority.
    4. Specify the write-back. Record the actor, decision, relevant revision, timestamp, and reason where one is required.
    5. Specify the failure path. Decide who is notified, what remains unchanged, and how the action can be retried safely.

    Put enough context in every actionable message

    A reviewer should not have to search several systems just to understand the request. Each actionable Slack message should identify:

    • The content title and stable CMS identifier.
    • The content type, site, locale, and environment when your operation has more than one.
    • The current state and requested next state.
    • The owner and requested reviewer.
    • The revision being reviewed.
    • A preview link and an edit link with visibly different labels.
    • The requested action and any deadline already stored in the workflow.
    • Validation failures or missing fields that could block the transition.

    Include the revision identifier even if people rarely read it. Without it, someone can approve an earlier preview after another editor has changed the content. The integration should reject or re-request an approval when the underlying revision no longer matches.

    Engineer for duplicate and delayed events

    CMS events can be retried, delivered late, or received more than once. Give each event a stable identifier, retain the content and revision identifiers, and make handlers idempotent so a retry cannot schedule or publish the same revision again. When event order matters, compare the incoming revision and state with the current CMS record before changing anything.

    A failed delivery also needs an explicit destination. Send operational failures to a channel monitored by the people who can resolve them, with the content identifier, attempted action, error category, and safe retry path. Do not report success until the CMS has accepted the mutation.

    Route by responsibility rather than broadcasting everything. Review requests belong where reviewers work; release confirmations belong where publishers monitor launches; integration failures belong with the workflow owner. Batch low-priority activity into a digest if nobody needs to act immediately. Notification volume is part of the design because an alert that is routinely ignored is not a control.

    Make approvals durable, scoped, and revision-aware

    An isometric workflow shows two document revisions, with the latest connected to an approval seal and archive while the older approval path is locked.

    Approval is a state transition, not a reaction. An emoji can communicate sentiment, but it should not be the only evidence that a specific person approved a specific revision for publication.

    Use separate roles even when one person fills more than one of them:

    • The author prepares the item and requests review.
    • The reviewer approves the current revision or returns it with a reason.
    • The publisher confirms the destination and schedule.
    • The integration verifies the transition, writes it to the CMS, and reports the resulting state.

    Keeping the actions distinct makes handoffs visible. It also lets you change permissions later without redesigning the entire workflow.

    Validate every action at the moment it is taken

    • Authenticate the Slack user and map that identity to an authorized CMS user or role.
    • Confirm that the content remains in the expected state.
    • Confirm that the revision still matches the one shown in the message.
    • Require a reason when content is rejected, sent back, or moved through an override path.
    • Write the result to the CMS before updating the Slack message.
    • Replace the actionable controls with the final outcome so an old button cannot be used later.

    If any check fails, leave the CMS state unchanged and explain what the person should do next. A stale approval should lead to a fresh preview and review request, not a best-effort approval of whatever revision happens to be current.

    Plan the exception path before you need it

    Urgent corrections will eventually bypass a normal queue. Give that path tighter controls rather than no controls: limit who can use it, require a reason, identify the revision, record the override, and notify the content owner. For destructive actions, prefer unpublishing or archiving with revision history intact over deleting content from a Slack control. A mistaken chat action should not erase the recovery path.

    Threads are useful for discussion, but the final decision must still return to the CMS. Summarize the resolution in a structured field or audit entry rather than expecting a future editor to reconstruct it from channel history.

    Tie the workflow to AI-search quality, then measure it

    Connecting Slack to a CMS does not, by itself, make a page more visible in AI search. The connection supports visibility when it helps your team publish accurate, accessible, well-structured content and correct problems without losing ownership or context.

    Turn high-risk quality checks into publication gates

    Store these checks in the CMS or validation service and surface their results in Slack. Do not ask reviewers to type machine-readable values into chat.

    • Confirm that the title, summary, headings, and visible answer agree about the page’s subject.
    • Confirm that the intended public URL, canonical selection, and index controls are set for the correct environment.
    • Validate that structured data describes the content a visitor can actually see rather than an earlier draft or a different page type.
    • Require the relevant author, organization, product, service, date, and taxonomy fields for the content type.
    • Check that important claims, citations, and destination links survived the latest revision.
    • Assign an owner for future corrections so a published item does not become operationally anonymous.

    The Slack notification should report pass, fail, or needs review for each gate and link to the field that needs work. It should not bury a blocking error in a long log. If a check is advisory rather than mandatory, label it that way so reviewers know whether they can proceed.

    After publication, send a separate confirmation containing the public URL, CMS identifier, published revision, responsible user, and validation outcome. A publication request and a successful publication are different events. Treating them separately keeps a timeout or platform error from looking like a completed launch.

    Measure the handoffs, not the message count

    Slack activity is not a useful success metric on its own. Join workflow events by content identifier and track the points where work waits, returns, or fails:

    • Review queue age: time from review request to the first reviewer action.
    • Approval cycle time: time from review request to approval of the accepted revision.
    • Revision loops: how often an item returns to the author before approval.
    • Stale actions: attempted decisions against a revision or state that has already changed.
    • Metadata completeness: required fields present when review or publication is requested.
    • Publication reliability: successful confirmations compared with failed or unresolved publication attempts.
    • Post-publication corrections: items that require an avoidable fix after release.

    Establish the baseline before adding more automation, then compare the same content type and workflow stage. If review time remains high but routing delay falls, the integration is doing its job and the remaining constraint is editorial capacity or decision quality. If correction volume rises, faster publishing has exposed a weak gate rather than solved the operation.

    Keep operational measures separate from AI-search outcomes. Visibility, mentions, citations, and referral traffic can change for many reasons outside Slack. Use the integration to preserve a reliable record of what changed and when, then evaluate search outcomes against that record without assigning the entire movement to one tool connection.

    Key takeaways

    • Keep content, metadata, permissions, revisions, and final state in the CMS; use Slack to route attention and authorized actions.
    • Automate named state transitions rather than forwarding every update into a channel.
    • Attach every approval to a specific content item and revision, then write the decision back to the CMS.
    • Design for duplicate events, delayed events, stale buttons, permission failures, and publication errors from the beginning.
    • Surface SEO, structured-data, and content-quality gates in Slack while retaining their values and validation logic outside chat.
    • Measure queue age, revision loops, stale actions, failed publications, metadata completeness, and corrections before expanding the workflow.

    Start with one transition that currently causes visible friction, usually the move from ready for review to approved. Make that loop authoritative, revision-aware, and recoverable. Once it works without manual reconciliation, extend the same event model to scheduling, publication, updates, and post-publication quality checks.

    References

  • 2 Million LLM Sessions: AI Discovery Insights Revealed

    2 Million LLM Sessions: AI Discovery Insights Revealed

    Analyzing nearly two million LLM sessions across nine industries throughout 2025 was a fascinating journey for me. I began with the assumption that ChatGPT would dominate and that AI usage patterns would be relatively uniform with minimal impact.

    The findings, however, were surprising.

    While ChatGPT does indeed control 84.1% of the trackable AI discovery traffic, it’s primarily serving as a broad-market tool. This discovery significantly impacts strategic approaches.

    In today’s landscape, relying solely on a single discovery strategy is not viable. A multi-platform approach that aligns with how and where users find productivity is essential.

    Brands must now discern which platforms are empowering productivity rather than merely supporting initial discovery phases.

    Various LLMs are excelling in different sectors, often with stark differences. The key takeaway for 2026 is more complex than simply focusing on ChatGPT.

    Here’s what I’ve discovered from the data.

    The Growth Rate Divergence: ChatGPT vs. Competitors

    Throughout 2025, major LLM platforms exhibited significant growth discrepancies:

    • ChatGPT: 3x growth
    • Copilot: 25x growth
    • Claude: 13x growth
    • Perplexity: 1x growth
    • Gemini: 1x growth

    Although ChatGPT grew, Copilot and Claude experienced much more rapid growth. Platforms like Perplexity and Gemini remained steady, reinforcing specific workflows.

    These numbers highlight strategic priorities:

    • Satya Nadella celebrated Copilot reaching 100 million monthly users.
    • Dario Amodei revealed that Anthropic’s revenue grew from $100 million to $8–10 billion in under two years.
    • Aravind Srinivas noted significant interest in Perplexity Finance.

    The focus on growth is crucial because it signals true user value:

    • Copilot excels in the Microsoft ecosystem.
    • Claude appeals to developers.
    • Perplexity thrives among finance professionals.

    Different LLMs are thriving in various industries at markedly different rates.

    Pattern 1: Copilot’s Striking Growth

    Copilot’s remarkable 25x growth is indicative of its premier position in B2B environments reliant on Microsoft tools.

    SaaS

    • ChatGPT: 2x growth
    • Copilot: 21x growth
    • The rapid adoption mirrors modern SaaS practices, embedding LLMs directly into workflows.

    Education

    • ChatGPT: 6x growth
    • Copilot: 27x growth
    • Copilot benefits from educational settings fostering knowledge sharing and synthesis.

    Finance

    • ChatGPT: 4.2x growth
    • Copilot: 23x growth
    • Finance aligns with Copilot due to automation needs and context dependency.

    Copilot’s growth is most pronounced in industries where professionals are deeply integrated with Microsoft tools.

    Instruments like Excel transform into data interpretation powerhouses with Copilot, eliminating the need for external searches.

    ```json
{
  "alt": "Screenshot of stock news headlines from Perplexity Finance with a search bar at the top.",
  "caption": "Stay updated with the latest financial headlines on Perplexity Finance. Track market shifts, tech advancements, and industry changes in real-time.",
  "description": "The image displays a screenshot from Perplexity Finance featuring a list of news headlines related to the stock market and financial sectors. The headlines cover topics like JPMorgan's credit card dominance, Apple's competitive challenges, Tesla's AI developments, and more. A search bar at the top allows users to explore stocks, cryptocurrencies, and other financial topics. The layout is clean and organized, catering to users seeking quick updates and insights into financial markets. Keywords: finance, stocks, market news, Perplexity Finance."
}
```

    Implications

    For work-centric audiences like SaaS, finance, and education specialists, AI discovery is shifting into LLMs embedded in workflows.

    Pattern 2: Perplexity Shines in Finance

    While Perplexity has flat growth overall, it stands strong in finance with a 24% market share, unlike in other sectors where it has diminished.

    • SaaS: down to 7.3%
    • E-commerce: down to 3.4%
    • Education: down to 5.2%
    • Publishers: down to 3.6%

    Finance demands accuracy; thus, traceable sources make Perplexity vital in this sector.

    Partnering with Benzinga, FactSet, and others, Perplexity offers in-depth data vital for financial decisions.

    Trust and verifiability are crucial in finance, and that’s where Perplexity excels.

    Implications

    In finance, selection of platforms that integrate with licensed data and credible sources is critical. Success hinges on being part of these authoritative ecosystems.

    Pattern 3: Claude’s Dominance in Analysis

    With just a 0.6% share, Claude might appear to be an underdog, but it thrives in specialist sectors like publishing and finance.

    • Publishers: 49x growth
    • Education: 25x growth
    • Finance: 38x growth
    • SaaS: 10.3x growth

    Claude’s strength lies in standalone, strategic thinking rather than integrated tools like Copilot.

    • Publishing professionals and financial analysts use Claude for its substantial context window, enabling complex and strategic queries.

    Implications

    Target audiences that require in-depth analysis should focus on creating structured and detailed content. Claude’s user base is smaller but highly influential.

    Pattern 4: Challenges in Tracking Gemini

    The data concerning Gemini is puzzling, showing both growth and declines. This could be attributed to issues with attribution rather than an actual decline in users.

    • Education: −67% tracked traffic
    • SaaS: +1.4x growth
    • Finance: +1.3x growth
    • E-commerce: +2.7x growth

    Gemini’s interaction model keeps users within its ecosystem, making measurement challenging.

    The reality is that usage might still be robust, but the tracking systems need to catch up with user behaviors.

    Implications

    As AI-assisted conversions increasingly occur, traditional last-click attribution models need reconsideration.

    Monitor brand search performance and invest in broader visibility strategies.

    Strategizing Your LLM Approach

    AI discovery is diversifying rather than converging. Tailoring strategies based on your audience’s preferences and behaviors is crucial.

    • Enterprise Audiences: Focus on Copilot integration for SaaS and B2B environments.
    • High-Stakes Decisions: Consider Perplexity’s reliability in providing traceable data.
    • Technical Evaluations: Claude’s detailed analysis capabilities require rich, structured content.
    • Emerging Sectors: Initiate with ChatGPT, monitor for evolving platform preferences.
    • Measurement Challenges: Adjust strategies to accommodate for gaps in tracking.

    Success in AI discovery is rooted in understanding your audience’s platform preferences and their specific needs.

    Read the full study: 2025 State of AI Discovery Report: What 1.96 Million LLM Sessions Tell Us About the Future of Search


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot