Author: shivamcrushpressai

  • Third-Party Endorsements in Google Search Ads: What to Do

    Third-Party Endorsements in Google Search Ads: What to Do

    If you buy Google Search ads, the immediate question is whether you can get a publisher quote into your own ad. For now, there is no disclosed setup path, eligibility rule, or request process. Rebuilding a campaign around this feature would be premature.

    You can still prepare intelligently. The useful work is to organize the independent evidence behind your brand, decide how you would measure an endorsement if one appeared, and avoid confusing an experimental ad treatment with an advertiser-controlled asset.

    What the endorsement test actually changes

    The experimental format places a short statement from an external publisher directly beneath the advertiser’s description. The treatment can include the publisher’s name, logo, and favicon, visually separating the statement from the copy supplied by the advertiser.

    One observed ad displayed the line “Best for Frequent Travelers” and attributed it to PCMag. That example matters because it shows the kind of claim involved: a concise editorial judgment about whom a product suits, rather than a generic customer rating or another promotional sentence written by the advertiser.

    This distinction changes how you should evaluate the feature. Your headline and description present your own proposition. A recognizable external endorsement could add a different kind of evidence at the moment someone is deciding which result deserves a click. It may make the ad resemble an editorial recommendation more closely, but that possible effect has not yet been established through disclosed performance data.

    Google has confirmed only that it is running a “small experiment” involving third-party endorsement content. Several operational questions remain unanswered:

    • Which advertisers, products, queries, or publishers are eligible.
    • Whether an advertiser can opt in or opt out.
    • Whether an advertiser can request, select, approve, or reject an endorsement.
    • How Google finds the content and decides which statement to display.
    • How old, changed, disputed, or removed publisher content would be handled.
    • Whether the experiment is connected to review-extension concepts, publisher partnerships, or broader trust-and-safety systems.

    Until those questions are answered, treat the endorsement as a possible search-result treatment, not as a new asset type you can add to a campaign. There is no documented basis for changing bids, budgets, campaign structure, or creative solely to obtain it.

    Prepare your brand without trying to game the experiment
    Hands organize blank press materials, a neutral medallion, and research documents beside a separate tray of generic ad cards.

    You cannot configure an undisclosed feature, but you can make your external reputation easier to understand and manage. Start with an endorsement inventory. A simple worksheet should contain the publisher, URL, covered brand or product, exact wording, publication date, current status, and the person responsible for checking it.

    1. Record exact claims, not flattering paraphrases. “Best for frequent travelers” is materially different from “best travel product.” Preserve the original wording and context internally so your team does not turn a narrow judgment into a broader claim.
    2. Classify the evidence correctly. Keep editorial endorsements separate from customer reviews, testimonials, awards, certifications, affiliate roundups, and paid placements. They may all support trust, but they are not interchangeable.
    3. Check the product and audience match. An endorsement for one plan, model, or use case should not be treated as validation for an entire company. Map each statement to the exact landing page and offer it describes.
    4. Make brand and product names consistent. If a product has several informal names across your site, campaign, and public coverage, document which names refer to the same thing. Clear naming helps your own team avoid attaching the wrong evidence to an ad or landing page.
    5. Create a correction route. Assign an owner who can contact a publisher when a factual detail is outdated or inaccurate. You may not be able to control what Google displays, but you can keep the underlying public information accurate.

    Do not copy publisher quotations or logos into your creative merely because Google displayed them in an experiment. A platform-generated treatment does not automatically give an advertiser permission to reuse editorial language or branding elsewhere. Keep the inventory as an evidence and monitoring tool unless your organization has the appropriate permission for direct reuse.

    It is also too early to commission coverage for the purpose of triggering this format. You do not know whether Google considers a particular publisher, whether paid or affiliate relationships affect selection, or whether advertisers will ever receive controls. Earn credible coverage because the coverage itself helps buyers evaluate you, not because you expect it to become an ad decoration.

    Measure an appearance without inventing causality
    A magnifying lens examines a blank search-ad card surrounded by separate contextual layers, while a broken link separates the observation from an outcome token.

    If an endorsement appears beneath one of your ads, a screenshot proves that the treatment rendered. It does not prove that the treatment improved performance. Queries, competitors, auction conditions, audience mix, devices, and campaign changes can all affect the same metrics.

    1. Capture the context. Save the screenshot along with the query, date, time, country, device type, displayed endorsement, publisher, ad copy, and destination URL.
    2. Annotate your reporting. Record when the first appearance was observed and note any simultaneous changes to bids, budgets, targeting, creative, landing pages, offers, or conversion tracking.
    3. Look for repeated exposure. Do not make a budget decision after one observation. Establish whether the treatment appears repeatedly and whether its wording stays consistent.
    4. Use business metrics in sequence. Examine click-through rate first, then conversion rate and the cost or return metric your campaign actually uses. A higher click-through rate with lower post-click quality is not automatically an improvement.
    5. Use the closest valid comparison. Compare similar queries, ads, audiences, and periods where possible. If Google does not provide an exposure field or experiment control, label any apparent difference as directional rather than causal.

    Avoid rewriting your description to imitate the endorsement. Repetition can waste limited ad space, and a line that looks independent loses its meaning when the advertiser makes the same claim about itself. Your copy should explain the offer; the external statement, if shown, should remain clearly external.

    Keep paid search, SEO, AEO, GEO, and schema in their proper lanes

    Third-party validation can support a broader visibility strategy, but this experiment does not establish a technical connection between Search ads and organic or AI-generated results. The selection process and its relationship to other Google systems remain undisclosed.

    • For paid search: the observed endorsement is an experimental element displayed with an ad. It is not currently a documented advertiser asset.
    • For SEO: there is no disclosed evidence that appearing in this treatment changes organic rankings.
    • For AEO and GEO: independent coverage can give people and answer systems public material with which to understand a brand, but this ad experiment does not prove that the same selection mechanism powers AI answers or citations.
    • For structured data: there is no disclosed evidence that JSON-LD or another schema type triggers the endorsement.

    Your safest cross-channel strategy is therefore straightforward: keep product facts precise, use consistent entity names, maintain the pages that substantiate your claims, and organize legitimate independent coverage. Those actions make your brand easier to verify even if this particular ad format never expands.

    Use a simple decision rule. If an activity makes your public evidence clearer, more accurate, or more useful to a prospective buyer, it is worth considering on its own merits. If its only purpose is to trigger an undocumented ad feature, defer it until Google publishes eligibility rules and advertiser controls.

    Key takeaways

    • Google is testing publisher quotations, names, logos, and favicons beneath some Search ad descriptions.
    • The confirmed example is part of a small experiment, not a generally available ad feature.
    • No public setup path, eligibility rule, opt-in mechanism, selection method, or performance reporting has been disclosed.
    • An endorsement inventory can help you manage external claims without assuming that you can submit them to Google.
    • If the treatment appears, document the exposure and assess the entire path from click to conversion before changing spend.
    • Do not treat SEO, AEO, GEO, or schema work as a shortcut into the experiment without evidence of a connection.

    Build the inventory now, add a place for endorsement observations to your campaign log, and leave campaign economics unchanged until repeated data or official controls give you something reliable to act on.

    References

  • 7 Creative GPT Automations to Boost Your SEO Workflow

    7 Creative GPT Automations to Boost Your SEO Workflow

    I’ve discovered how custom GPTs can revolutionize how we handle SEO, transforming repetitive tasks into efficient workflows. By leveraging AI, we can speed up our processes, from planning and analysis to reporting and technical work.

    If you don’t have access to paid ChatGPT, don’t worry. You can still utilize these prompts by saving them as standalone references in your notes. Remember, they’re just starting points, so modify them to fit your team’s requirements.

    Working with AI requires trial and error. My advice is to start with small tasks to practice writing prompts. Iterate on them and take notes on what produces good outputs.

    AI can sometimes be verbose, so it’s helpful to set strict formatting guidelines and clear context. Upload resources and articles to guide AI results, and always define the role and audience upfront.

    Let’s dive into seven prompts that I’ve found incredibly useful for developing custom GPTs dedicated to planning, analysis, and ongoing SEO tasks:

    1. Project plan GPT

    By analyzing previous project plans, I can create a GPT that assists in drafting this year’s focus areas.

    How to set it up

    • Input project plans from previous years.
    • Specify a format for consistency.
    • Determine the number of items or sections to include.
    • Include specific details unique to your team.
    • Optionally, integrate team feedback and retrospectives.

    Example prompt

    Based on last year’s project plan, outline this year’s focus. List three critical items for each quarter, ensuring at least one covers link building.

    Include a one-sentence summary for each recommended item and at least two KPIs to measure success.

    [Insert last year’s plan.]

    Now critique the plan. Offer three reasons against focusing on these items, providing sources for your notes.

    Dig deeper: How to use ChatGPT Tasks for SEO

    2. Site performance GPT

    By connecting performance dashboards or custom GA reports to ChatGPT, it can handle initial issue identification. This allows me to focus on investigating critical trends.

    How to set it up

    • Hook up reporting tools or upload data directly.
    • Direct AI on specific aspects to investigate.
    • Set frequency for data review, such as daily or weekly.
    • Provide examples of pages or categories to analyze.

    Example prompt

    Here’s the weekly site report. Analyze this week’s performance against last week’s data, summarizing sessions, conversions, and engagement.

    Highlight three successes and three areas needing improvement, color-coded by significance.

    [Insert report doc.]

    3. Competitor analysis GPT

    I’ve found it invaluable to scrutinize what works on competitor sites. This often involves tools like Semrush or Ahrefs.

    How to set it up

    • Integrate Ahrefs, Semrush, or upload relevant reports.
    • Select competitors and identify top-performing pages.
    • List key metrics for evaluation.
    • Create unique prompts for various levels of analysis.
    • Optionally, document metrics requiring deeper scrutiny.

    Example prompt

    As an SEO analyst, compare these URLs. Present a table detailing backlinks, average rank, top keyword, sessions, and value for each URL.

    Provide a concise summary of category leaders, referencing this link for criteria and citing sources.

    URL 1:
    URL 2:
    URL 3:
    Article reference:

    Dig deeper: Advanced SEO competitor analysis for better rankings

    Now, more than ever, custom GPTs are making a significant impact alongside existing SEO tools and workflows. They’re not about replacing the tools we use, but about making initial tasks smoother so that we can focus on insightful and strategic actions. By integrating them into our everyday processes, from planning to technical checks, we can really enhance our productivity.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • SEO as a Brand and Performance Channel: The New Reality

    SEO as a Brand and Performance Channel: The New Reality

    I’ve come to realize that SEO now serves as both a brand and performance channel. The traditional traffic model has been disrupted by AI Overviews and zero-click SERPs, making brand strength crucial for SEO ROI.

    For years, SEO was straightforward: rank higher, get more traffic, then boost the sales pipeline. However, this simple equation is rapidly evolving, much to the frustration of marketing leaders.

    With AI Overviews and users getting answers directly from LLMs, the idea of “rank and receive traffic and leads” is less effective now. Even top keyword positions don’t guarantee the clicks they once did.

    This shift has sparked challenging discussions in boardrooms. Executives often question, “If traffic is down, how can we measure SEO success?”

    It’s obvious now: the traffic model has changed, yet the demand for ROI remains. We must treat SEO as a brand-dependent performance channel, not just a traffic provider.

    Why traffic and pipeline are no longer in lockstep

    Linear attribution has never fully reflected the dynamic nature of organic search. While ChatGPT isn’t replacing Google, it’s augmenting it.

    Users now verify information across platforms due to skepticism of search and LLM results. Where research once happened solely within Google’s ecosystem, it has become more scattered.

    Today’s organic search is akin to a pinball machine, with buyers bouncing across channels unpredictably. This introduces complexity that traditional attribution software struggles to follow.

    Such complexity has broken the linearity executives crave. Traffic and pipeline charts, once aligned, now often diverge.

    Across B2B SaaS portfolios, a common pattern emerges: organic sessions may be flat or declining, yet rankings for high-intent terms stay stable, and the pipeline from organic search grows.

    This mismatch doesn’t indicate SEO failure. Rather, it shows that traffic is no longer a reliable business impact measure.

    The traffic lost to zero-click searches often consists of informational, low-intent content. What remains is higher-intent traffic, closer to conversion.

    We’re seeing the “atomization” of search demand. Short-head, broad keywords are declining, while specific, long-tail queries with higher intent are rising.

    Many leaders mistakenly react to dropping sessions by pushing for quantity, aiming to regain the lost numbers through top-of-funnel content. This often inflates vanity metrics without delivering qualified leads.

    ```json
{
  "alt": "Metrics table showing increases in demo requests, pipelines, and other areas, but a 2% decrease in organic traffic highlighted.",
  "caption": "Despite organic traffic slightly dipping by 2%, other key metrics like demo requests and conversion rates soar, showcasing business growth.",
  "description": "This image displays a metrics table with a focus on conversion and pipeline metrics. It indicates substantial increases in demo requests (up 130%) and other areas, despite a highlighted 2% decrease in organic traffic. The data suggests overall positive performance with significant growth in multiple areas, emphasizing the message 'Traffic Flat → Revenue Up!' SEO, performance metrics, and business analytics keywords are relevant."
}
```

    SEO ROI is now the downstream outcome of brand traction

    For years, SEO was viewed as a pure performance channel. We believed optimizing some keywords would suffice.

    In reality, SEO has always depended on brand strength. The rise of AI-driven engines highlights this, expecting reputations, not just keywords.

    If your brand lacks authority, technical optimizations alone won’t elevate your status. Brand strength determines organic performance limits. Search engines seek web-wide consensus, and weak associations hinder results.

    Brand strength for LLMs means owning topical authority, aligning with customer queries, being validated by trusted sources, and having clear positioning.

    SEO captures pre-existing demand validated by your brand, not creating it from nothing.

    The new defensibility metrics for SEO

    As traffic no longer headlines KPIs, new defensibility metrics are necessary. Successful teams focus on revenue and reputation impact, not just volume.

    Metrics proving business impact include stable top-10 rankings for commercial keywords, increased Ahrefs traffic value, stable solution page traffic, growing homepage traffic, and developing LLM referral traffic.

    When pipeline per organic visitor rises, even with falling sessions, the dialogue shifts from “SEO is broken” to recognizing SEO’s evolution.

    Modern SEO is moving from acquisition to influence

    Successful SEO isn’t about recovering traffic but influencing buyer decisions and enhancing organic visibility. In an AI-first context, zero-click doesn’t imply zero-value.

    SEO remains key in building market readiness, positioning brands as authorities even before buyers enter the funnel.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Unlocking the Secrets of Query Fan-Out in AI SEO

    Unlocking the Secrets of Query Fan-Out in AI SEO

    When I first stumbled upon the concept of query fan-out, I realized how misunderstood it often is in the world of AEO and SEO. It’s fascinating how AI searches can take a single prompt and transform it into numerous sub-queries, expanding the scope of search in unimaginable ways.

    Understanding this process opened my eyes to the hidden potential these sub-queries hold. By leveraging the data generated from them, I discovered new strategies to enhance SEO effectiveness, making my digital marketing efforts more robust.


    Inspired by this post on HiGoodie Blog.


    crushpress.ai community screenshot
  • Publisher Controls for Google AI Overviews and AI Mode

    Publisher Controls for Google AI Overviews and AI Mode

    You have a decision to prepare for, but not yet a reliable switch to flip. Google has discussed letting publishers opt out of AI Overviews and AI Mode, yet it has not disclosed a clear, feature-specific implementation. Adding a guessed crawler rule or sitewide directive now could affect more than the AI feature you meant to control.

    Do the policy work first. Decide which content you would exclude, what outcome would justify exclusion, how you would detect collateral damage, and what would trigger a rollback. Then, if Google releases a documented control, you can test it as an operating decision instead of reacting with a blanket yes or no.

    The opt-out question is ahead of the actual control

    Google has been exploring ways for websites to opt out of AI-generated search features. What publishers still need is the operational detail: whether a control would apply to AI Overviews, AI Mode, or both; whether it could be used on individual URLs or only an entire site; how quickly a change would take effect; and whether it would alter eligibility for traditional search.

    Until those questions have documented answers, nobody can responsibly give you an exact implementation recipe. A directive intended for an AI training crawler is not automatically a control for an AI-generated search result. A general search restriction is not automatically limited to AI. The names may sound related, but the scope and business consequences are different.

    Publishers are already divided on the underlying choice. In an X poll with more than 350 responses, 33.2% said they would block Google, 41.9% said they would not, and 24.9% were unsure. Treat that as evidence of a real strategic disagreement, not as a representative estimate of the entire publishing market.

    The disagreement makes sense because “block AI” is not a business objective. One publisher may prioritize broad discovery. Another may place more value on controlling the reuse of expensive original work. A third may want visibility in AI results but only when those appearances send qualified readers or reinforce the brand. You cannot resolve those positions with a technical toggle alone.

    Keep three decisions separate in every internal discussion:

    • AI training access: whether a named crawler may collect content for a training-related purpose.
    • Traditional search access: whether Google can crawl, index, and present a page in established search results.
    • AI search presentation: whether content can contribute to or appear in AI Overviews and AI Mode.

    That distinction matters because 79% of nearly 100 leading UK and US news websites were blocking at least one AI training crawler. That shows publishers are actively managing training access. It does not establish that the same sites have opted out of Google AI search features, or that a training-crawler block would produce that result.

    Build the policy around content classes, not one domain-wide answer

    Different types of unlabeled publishing materials are sorted into compartments and routed separately toward or away from an abstract AI portal.

    A sitewide decision is simple to announce and difficult to evaluate. Your domain probably contains pages with different economics and different jobs: original reporting, evergreen reference material, product or service pages, subscriber content, documentation, archives, and pages built primarily to acquire search visitors. A future control may or may not support URL-level rules, but your policy should be ready for that possibility.

    Create an inventory by template or content class. You do not need to classify every URL manually. Start with the groups that account for most of your search traffic, revenue, subscriptions, leads, or editorial investment.

    1. Name the page class. Use a stable label such as original news, analysis, evergreen guide, product page, documentation, archive, or subscriber-only content.
    2. State its primary job. Choose one: attract new readers, convert demand, retain subscribers, establish authority, support customers, or generate direct revenue.
    3. Record its dependency on Google discovery. Use your own impressions, clicks, landing sessions, conversions, and revenue rather than an editorial assumption.
    4. Identify the use you want to control. Say “AI Overviews and AI Mode” if that is the target. Do not write only “AI,” because that leaves training, search presentation, and other uses mixed together.
    5. Assign a provisional status: allow, exclude when a verified control exists, or include in the first test.
    6. Name the owner who can approve implementation and the owner who can order a rollback.

    The three provisional statuses keep uncertainty visible without forcing a premature technical change:

    • Allow: discovery is the dominant objective, so the current state remains in place unless measured harm changes the decision.
    • Exclude when possible: the content conflicts with a declared reuse or rights policy, but implementation waits for a documented control whose scope is understood.
    • Test: the trade-off is uncertain, so the content becomes a candidate for a limited, reversible experiment.

    Add the reason beside every status. “Editorial leadership requested it” is an approval trail, not a decision rule. A usable reason sounds like this: “These pages depend on search acquisition, so exclusion will be retained only if targeted AI use declines without pushing qualified organic visits or conversions below our predeclared guardrails.”

    If Google ultimately offers only a domain-wide setting, your classification work still matters. It shows which page groups carry the benefit and which carry the cost. That gives leadership a defensible basis for accepting or rejecting the broader control.

    Decide what success and failure look like before changing anything

    A publisher test fails when the team changes a setting first and chooses the interpretation later. Traffic can move for many reasons. If your success criteria remain unwritten, almost any result can be used to defend the decision someone already preferred.

    Build a measurement sheet with four layers:

    • Business outcome: qualified leads, purchases, subscriptions, advertising value, or another result tied to the selected page class.
    • Search referral outcome: impressions, clicks, click-through rate, landing sessions, and the queries sending those visits.
    • AI feature observation: whether the chosen URLs or brand appear for a fixed set of queries in AI Overviews or AI Mode.
    • Technical guardrails: continued crawling, indexation, and appearance in the traditional search surfaces you intended to preserve.

    Do not assume your normal analytics can isolate every AI feature appearance. If they cannot, create a manual observation set. Select queries before the test, record the page and feature being checked, keep the location, account state, and device conditions as consistent as practical, and save dated evidence. The purpose is not to estimate all AI visibility from a small sample. It is to check whether the behavior of known query-URL pairs changed after the control.

    Use queries where the page had previously appeared in the targeted feature whenever possible. If an AI Overview does not appear for a query on a later check, that single absence does not prove the exclusion worked; the feature itself may not have appeared. Verification needs to distinguish “the feature was present without our content” from “the feature was not present at all.”

    Write the retention rule in advance. A practical template is:

    We will retain exclusion for [content class] only if the targeted use declines in our logged sample, organic search outcomes remain above our chosen floor, the primary business metric stays within its guardrail, and traditional search eligibility shows no unintended change.

    Publisher decision template

    Choose the floors from your own historical volatility and business tolerance. There is no credible universal percentage that tells every publisher when loss of reach is worth greater content control. A subscription publisher, a lead-generation site, and an advertising-funded newsroom can assign very different values to the same traffic movement.

    Test a documented control with the smallest reversible scope

    A single article tile is tested in a transparent chamber while an operator monitors indicator lights beside a rollback lever.

    When Google publishes an actual control, verify what it governs before deploying it. The label is not enough. Read for its target feature, supported scope, interaction with traditional search, activation behavior, verification method, and rollback procedure. If the documentation does not answer one of those questions, record it as an unresolved risk rather than filling the gap with an assumption.

    Then run the test in this order:

    1. Choose a narrow cohort. Prefer one content class or template over the entire site when the documented control permits it.
    2. Select a comparison cohort. Match pages as closely as practical on purpose, query demand, historical performance, update pattern, and publication timing.
    3. Capture a baseline. Include a period that reflects your normal publishing or business cycle, and note promotions, seasonal events, migrations, algorithm changes, or major editorial updates that could distort it.
    4. Freeze avoidable confounders. Do not simultaneously rewrite titles, change internal links, redesign templates, or move URLs unless those changes are part of the test.
    5. Apply one documented control. Log the exact setting, scope, time, implementer, approver, and expected outcome.
    6. Verify the target behavior. Check the tracked query-URL pairs and confirm that any observed change concerns AI Overviews or AI Mode rather than a broader loss of search access.
    7. Compare business results and guardrails. Use the predeclared rule, not a newly chosen metric that happens to support the preferred conclusion.
    8. Roll back if the blast radius is larger than intended. Preserve the implementation log so the team can separate recovery from later unrelated changes.

    If the control is sitewide only, you lose the cleanest form of an internal comparison. Do not pretend a before-and-after chart proves causation. Keep a dated change log, use the same tracked query set, document concurrent events, and require stronger evidence before making the setting permanent.

    Operational cost belongs in the result as well. A page-level control that must be maintained across several publishing systems creates a different burden from a stable sitewide setting. Record implementation time, quality-assurance failures, ownership gaps, and rollback effort. A policy that cannot be maintained reliably is not an effective control, even when its strategic intent is sound.

    Key takeaways

    • Google has discussed publisher opt-outs for AI Overviews and AI Mode, but a clear feature-specific implementation has not been established here.
    • Blocking an AI training crawler is not the same as opting out of an AI-generated search feature.
    • Classify content by business purpose and Google dependency before choosing allow, exclude, or test.
    • Predeclare the target behavior, primary business metric, search guardrails, technical checks, and rollback condition.
    • When a documented control arrives, begin with the smallest reversible cohort its scope permits.

    Your useful next step is a one-page control brief, not a speculative configuration change. Assign an owner, classify the page groups that matter, capture their baseline, and list the documentation questions Google must answer. When a real control becomes available, you will be ready to evaluate it with evidence instead of making a domain-wide bet under deadline pressure.

    References

  • Google Ads API v23: A Practical Upgrade Plan for 2026

    Google Ads API v23: A Practical Upgrade Plan for 2026

    Your Google Ads integration may be stable, but that does not make the v23 decision automatic. You need to know whether upgrading will close a real operational gap: opaque Performance Max reporting, difficult invoice reconciliation, date-only scheduling, fragmented store data or an audience workflow that still depends on manual interpretation.

    Google Ads API v23 brings those changes into the same release, while also beginning a faster API release cycle for 2026. The practical response is not to adopt every feature at once. It is to connect each capability to a decision, migrate the safest read paths first and put tighter controls around anything that can change targeting, schedules or spend.

    Choose the upgrade scope from the decisions you need to improve

    Start with the workflow that consumes the data, not the endpoint that exposes it. A feature has upgrade value only when someone can name the decision it will improve, the current workaround it will replace and the failure you need to prevent.

    v23 capabilityDecision or workflow it can improveFirst acceptance test
    Performance Max breakdown by ad network typeExplaining where campaign results are occurringSegmented values reconcile with the unsplit control query for every additive metric you publish
    Campaign-level invoice details, regulatory fees and adjustmentsBilling reconciliation and client cost allocationEvery amount remains traceable to its original charge type instead of being forced into media spend
    Campaign start and end date-timesPrecise launch, promotion and shutdown schedulingA controlled write-read test preserves the intended date, time and governing timezone convention
    PerStoreView location detailsStore-level reporting and local performance analysisThe account and location scope agrees with the corresponding Stores report
    LIFE_EVENT_USER_INTERESTLife-event dimensions in audience insight workflowsThe new dimension survives extraction, storage and review without being collapsed into a generic interest label
    Surface-specific Demand Gen conversion-rate forecastsPlanning separately for placements such as Gmail and ShortsSurface remains part of the forecast key through the planning layer
    Free-text descriptions converted into structured audience attributesDrafting audience definitions from a strategist’s briefThe generated attributes are visible, validated and approved before downstream use
    Additional Shopping competitive and conversion-date metricsCompetitive analysis and conversion reportingEvery metric carries its date basis and aggregation rule into the dashboard

    This map also exposes ownership. Performance Max and Shopping changes usually begin with analytics engineering. Invoice changes require a finance or billing consumer. Date-time scheduling belongs to the team that owns campaign mutations. Audience generation needs both a technical owner and the person accountable for targeting decisions.

    A low-risk migration sequence starts on the read side. Capture representative outputs from your existing integration, upgrade the required client libraries and code in an isolated path, add one v23 capability, and compare its result with your control data. Move write operations only after your storage, validation and monitoring layers understand the new values.

    1. List every query, scheduled job, report, billing export and campaign writer affected by the upgrade.
    2. Record the account scope, selectors, reporting window and downstream consumer for each path.
    3. Capture baseline responses and the totals currently shown to users.
    4. Upgrade the client dependency and generated types without changing business logic in the same step.
    5. Add one v23 capability behind a separately testable query or writer.
    6. Define a reconciliation rule, an owner and a rollback condition before releasing it.
    7. Keep the old output available until the new consumer passes both data and operational checks.

    Rebuild reporting around the new data grain

    An analyst examines an opaque campaign object as it passes through a prism and separates into distinct reporting components.

    The reporting additions are useful because they expose distinctions that were previously difficult to retrieve. They can also break a pipeline that assumes one row per campaign, one meaning for a date or one reporting grain across every metric.

    Performance Max network breakdowns need a new row key

    Google Ads API v23 adds an ad-network-type breakdown for Performance Max reporting. Once that segment enters a result, a campaign can occupy more than one row. Any transformation keyed only by campaign can overwrite rows, duplicate joined values or accidentally recombine the split before an analyst sees it.

    Add the network dimension to the unique key at ingestion. Then run a paired query: one result at the original campaign grain and one with the network split. Reconcile metrics that your reporting contract treats as additive. For ratios and calculated metrics, recompute from their underlying components where your data model supports that; do not sum percentages merely because they arrived in separate rows.

    Label the output narrowly. A network breakdown provides a more useful view of distribution, but it should not be presented as complete Performance Max transparency. That wording matters because analysts will otherwise infer visibility into decisions the field does not actually expose.

    Shopping conversion-date metrics need an explicit time basis

    Expanded Shopping reporting includes new competitive and conversion metrics organized by conversion date. A conversion-date series answers a different question from a series organized around the ad interaction. If your warehouse stores both under an undifferentiated date column, a dashboard can produce a plausible trend with the wrong meaning.

    Give every affected metric a semantic contract. At minimum, record its metric name, date basis, source grain and permitted aggregation behavior. Carry the date basis into the BI model and display label. If you show conversion-date and interaction-date views together, identify them explicitly instead of blending them into one unlabeled total.

    Competitive metrics deserve the same discipline. Do not assume a newly available value can be summed across products, campaigns or dates. Preserve the returned grain first, then implement only the aggregation behavior your reporting definition supports.

    Use PerStoreView as a controlled local-data migration

    PerStoreView exposes store location details aligned with the Stores report. That alignment gives you a practical acceptance test. Select a known account and location scope, retrieve both views, and compare the location set and identifying details before replacing an existing store feed.

    Preserve the identifiers exposed by the API instead of matching stores only by display name. Names can be formatted inconsistently in downstream systems, while a durable identifier gives you a defensible join. Keep store attributes separate from campaign measures as well; duplicating a location attribute across performance rows does not make it an additive metric.

    Your exception report should show missing locations, duplicate mappings and conflicting attributes. Do not hide those cases inside an inner join. A clean-looking dashboard that silently drops an unmatched store is harder to repair than a visible migration exception.

    Keep billing detail and scheduling precision from creating new errors

    Two v23 features move beyond analytical convenience. More detailed invoices affect financial reconciliation, while precise campaign date-times affect when ads can run. Both deserve stronger controls than a new reporting column.

    Model invoice charges by type before calculating totals

    InvoiceService can now return campaign-specific costs, regulatory fees and adjustments. Those amounts may contribute to the same billing reconciliation, but they do not mean the same thing. Putting all of them into an internal field named spend destroys the distinction that makes the new detail valuable.

    Retain the raw response, then normalize each amount into a typed financial record. Your internal model should distinguish campaign cost, regulatory fee and adjustment, preserve the campaign association when supplied, and record the sign convention used by your system. Never change the raw value to make a reconciliation pass.

    • Reconcile typed amounts to the billing total your finance workflow expects.
    • Flag an adjustment whose sign cannot be interpreted confidently instead of silently treating it as a cost.
    • Keep fees visible as fees in client and internal reports.
    • Surface campaign references that cannot be mapped to your internal campaign table.
    • Make repeated ingestion idempotent so rerunning a billing job does not duplicate a charge.

    Release the richer invoice feed beside the existing reconciliation for at least one normal billing run in your own workflow. The purpose is not merely to reach the same final number. Finance should be able to explain which campaign costs, fees and adjustments produced it.

    Treat date-time scheduling as a write-path migration

    Campaigns can use precise start and end date-times rather than date-only boundaries. That is an operational change, not just a more detailed field. A database column, serializer or form built around dates can strip the time and still produce a syntactically valid value with the wrong schedule.

    Trace the value from the user’s input through storage, request construction and the returned campaign state. Confirm the timezone or normalization convention required by the API and your client library rather than guessing. Keep the user’s intended local time available for audit even if your integration also stores a normalized representation.

    • Test a same-day start and end.
    • Test a boundary near midnight.
    • Test a date affected by a daylight-saving transition when the campaign’s market uses one.
    • Test that an end earlier than the start is stopped by your own validation.
    • Read the campaign back after writing and compare the returned schedule with the submitted intent.
    • Verify that legacy date-only jobs do not overwrite the newer time values on their next run.

    Do not move this writer into production while the timezone or end-boundary behavior remains ambiguous. An incorrect boundary can allow spend outside the intended promotion window or stop a campaign while it should still be active. Use a controlled, low-risk campaign for the final lifecycle check and require an explicit rollback path.

    Put human review between AI assistance and campaign changes

    A campaign manager reviews AI-generated adjustment modules before allowing one to pass through an approval gate into an advertising system.

    Google Ads API v23 expands AI-assisted audience and planning workflows in three different ways: a new life-event dimension, free-text audience generation and surface-specific Demand Gen forecasting. They should not be merged into one opaque automation step. Each produces a different kind of planning input and needs a different validation rule.

    Preserve LIFE_EVENT_USER_INTEREST as its own dimension

    The new LIFE_EVENT_USER_INTEREST audience dimension gives Insights workflows a structured way to work with life-event interests. Store the dimension type separately from its returned value. Mapping it immediately into a generic interest bucket removes the distinction before a strategist can use it.

    Add explicit handling for unknown or newly returned values. A resilient integration should retain a value it does not recognize, route it for review and continue processing the rest of the response. Hard-coded mappings that discard an unfamiliar value make API evolution look like missing audience demand.

    Handle generated audience attributes as a proposal

    Generative audience tooling can translate a free-text audience description into structured attributes. That can reduce manual setup, but the structured result is still the consequential output. The input may sound reasonable while the generated attribute set is broader, narrower or simply different from what the strategist intended.

    Make generation a reviewable draft. Store the original description, the complete structured result, the version of your internal mapping logic, the reviewer decision and the eventual change applied downstream. Show the strategist a diff between the current audience definition and the proposed one. Empty attributes, unsupported values and unexpectedly broad additions should block automatic application.

    This audit trail is also how you make the feature debuggable. If campaign behavior later raises a question, you can distinguish the user’s brief, the generated interpretation and the approved configuration instead of treating them as one decision.

    Keep Demand Gen forecasts separated by surface

    Demand Gen conversion-rate forecasts can now vary across surfaces such as Gmail and Shorts. Include surface in the storage key, API-to-warehouse mapping and planning view. Otherwise, one surface can overwrite another or an early average can erase the difference the feature was designed to expose.

    Use each forecast as a planning input, not a guaranteed outcome. Retrieve the forecast without automatically changing budget or targeting, show the surface-level values to the planner, record the decision they support and compare eventual performance using the same surface distinction where your measurement data permits it.

    Key takeaways for your v23 upgrade sequence

    • Adopt v23 by workflow value, not by feature count. Tie every capability to a named decision and consumer.
    • Move read-only reporting first. Baseline, dual-run and reconcile before replacing an existing output.
    • Add the new dimension to your data key. Network, store, surface and date-basis distinctions must survive ingestion.
    • Keep financial meanings separate. Campaign costs, regulatory fees and adjustments should remain typed and traceable.
    • Test scheduling end to end. Database precision, serialization, timezone handling and legacy writers can all alter the intended date-time.
    • Keep AI-generated audience attributes behind validation and human approval.
    • Build reusable migration checks now. A faster 2026 release cadence makes a repeatable test harness more valuable than a one-off v23 patch.

    Your next step is to create one migration ticket for each capability you intend to use. Give it an owner, affected consumer, baseline sample, reconciliation rule, failure alert and rollback condition. Start with the highest-value read-only gap. Move invoice and scheduling changes only when the teams responsible for billing and campaign operations have approved the acceptance tests.

    That approach lets you capture v23’s useful reporting and planning gains without turning the upgrade into an uncontrolled rewrite. It also leaves you with a migration pattern you can reuse as the Google Ads API release pace increases.

    References

  • How to Align SEO Traffic With Your Sales Funnel and Revenue

    How to Align SEO Traffic With Your Sales Funnel and Revenue

    Your rankings are up. Organic visits are rising. Form submissions may even look healthy. Yet the sales pipeline is flat, and nobody can explain where the apparent success disappears.

    That doesn’t automatically mean SEO failed or attribution hid the value. It means you need to trace what happens after the click. The useful question is no longer, “Is SEO working?” It is, “At which transition does commercially relevant demand stop moving?”

    Key takeaways

    • Segment organic traffic by search need and likely buying stage before judging its commercial value.
    • Give every important landing page one stage-appropriate job instead of asking every visitor to book a call.
    • Trace the funnel from organic entry to conversion, qualification, sales acceptance, opportunity, and revenue.
    • Preserve the visitor’s original problem and conversion context when the lead moves into the CRM.
    • Fix the first weak or unmeasured transition before scaling content, redesigning forms, or debating attribution models.

    Map search intent to an actual buying stage

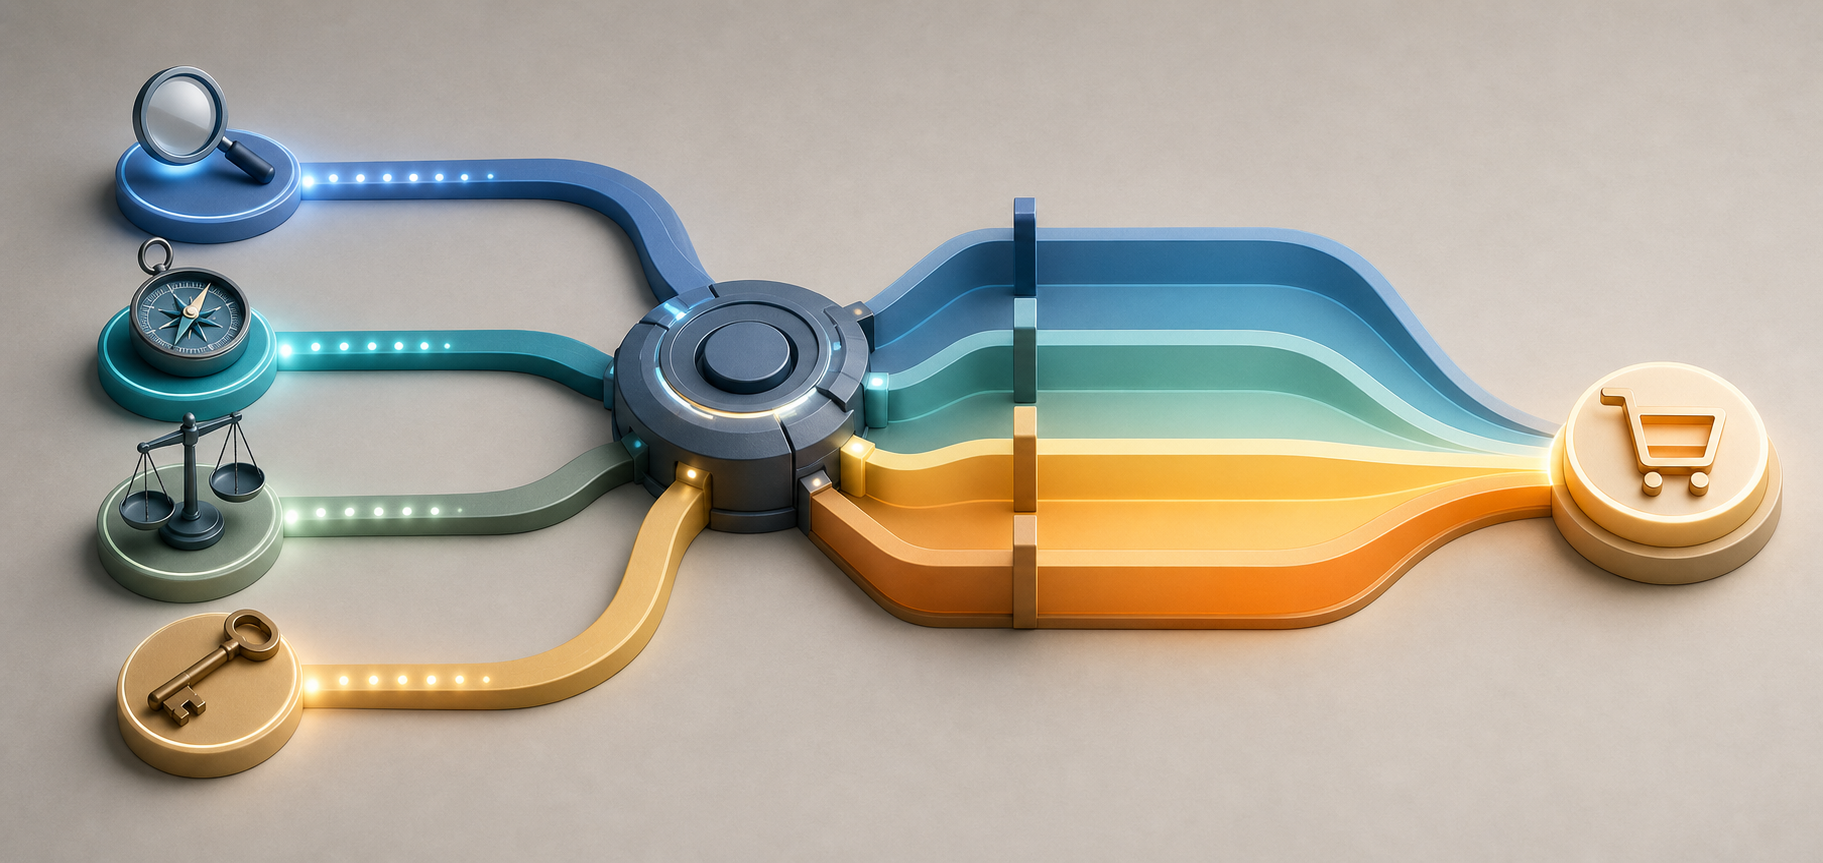
    A magnifying lens, compass, balance, and key are sorted into four colored pathways that progress from cool blue to warm amber.

    Search intent and buying readiness are related, but they are not interchangeable. A person can be an excellent fit for your product while still exploring the problem. Another can use a highly specific query because a purchase decision is already underway. If you judge both visitors by immediate demo requests, the first group looks worthless and the second can be obscured by the average.

    Intent also has dimensions that a keyword label rarely captures on its own: urgency, familiarity with the problem, authority to buy, preferred solution, and timing. A query can match your offer while remaining out of step with the sales motion or the buyer’s current priority.

    Start by grouping important landing pages around the problem they solve, not merely their ranking keywords. For each page or topic cluster, complete this map:

    Work itemQuestion to answerRequired output
    Search needWhat problem does the visitor expect this page to solve?A one-sentence promise in the visitor’s language
    Buying stageWhat can you reasonably infer about readiness, and what remains unknown?A stage hypothesis, not a declaration of purchase intent
    Page jobWhat is the next useful movement from this stage?One primary journey step
    Call to actionIs the requested commitment proportionate to the visitor’s readiness?A stage-appropriate primary CTA
    Decision supportWhat must the visitor understand or believe before moving?The proof, comparison, detail, or reassurance the page must supply
    Sales contextWhat would a seller need to continue this conversation coherently?The context that must pass into the lead record

    An early-stage page may need to move a reader into a more specific diagnostic, comparison, or use-case path. An evaluation page may need to clarify fit, implementation, limitations, or proof. A page serving someone ready to act should make product details and contact routes easy to find. These are starting hypotheses. Validate them against the paths and outcomes of your own visitors.

    This distinction protects you from two common mistakes. The first is forcing a sales conversation onto every informational visit. The second is celebrating traffic that has no credible route toward a business outcome. Top-of-funnel content does not need to close the sale, but it does need a defined role in the journey.

    A useful test is to ask whether a new visitor could explain what to do after getting the answer they came for. If the page ends with a generic contact button, an unrelated newsletter form, or no relevant next step, the content may satisfy the query while abandoning the funnel.

    Inspect conversion and sales handoff as one continuous chain

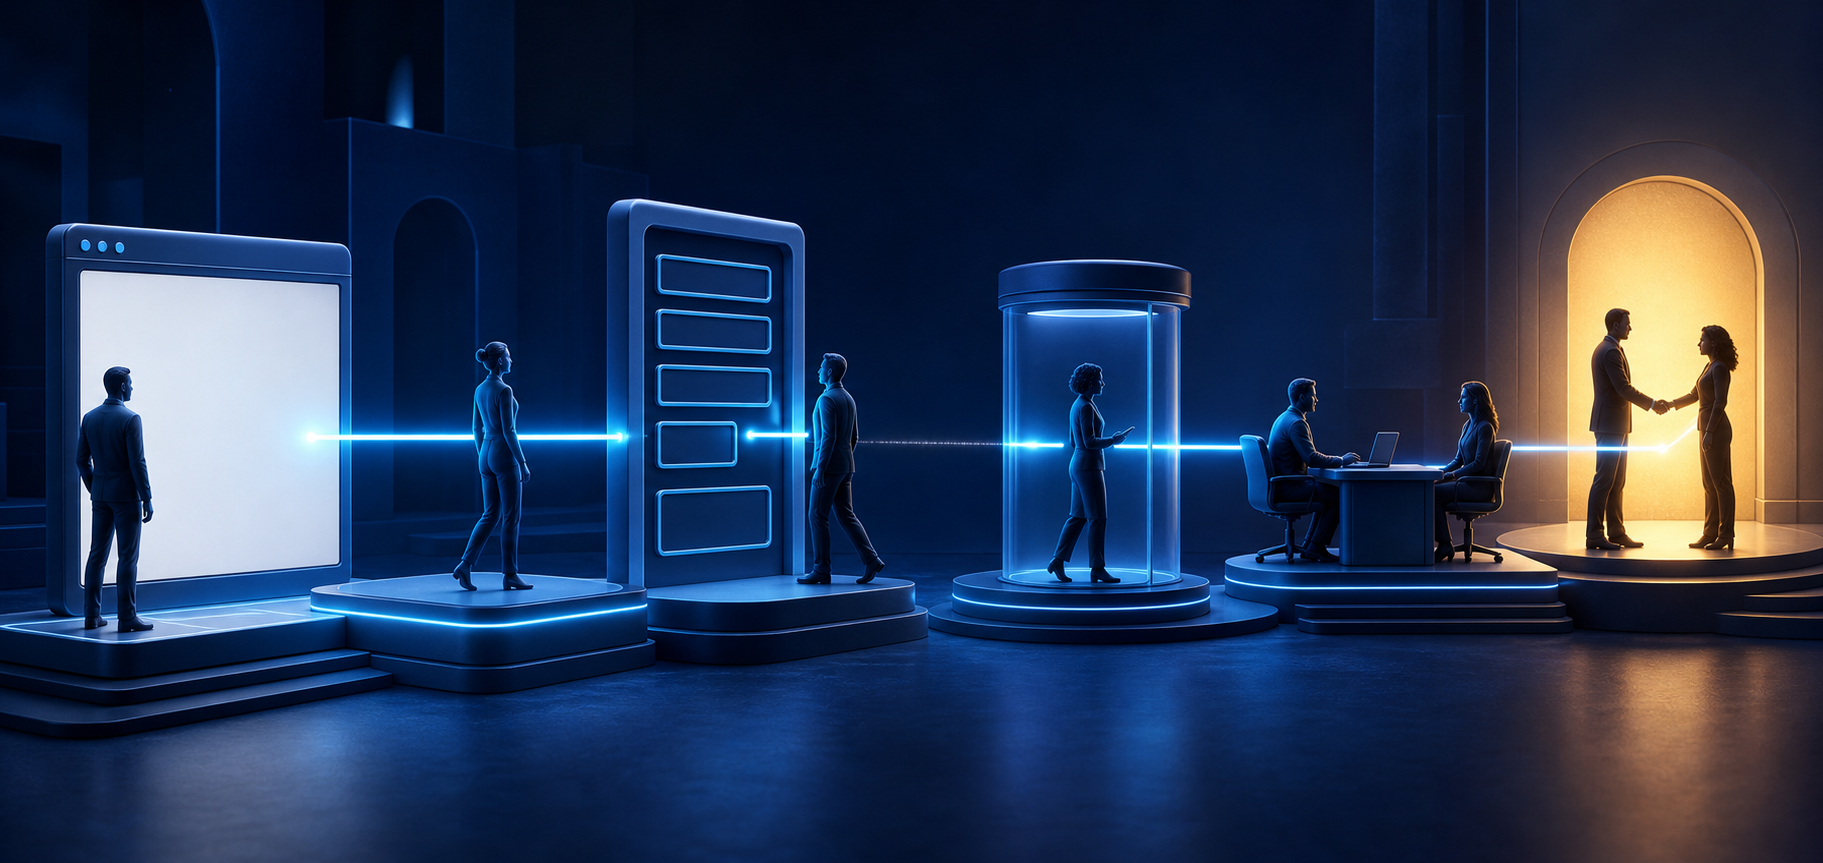
    A glowing line connects a blank web portal, landing platform, form gate, qualification checkpoint, sales desk, and customer handshake, with one dim gap in the middle.

    The commercial gap often opens after the search click, across intent, conversion, qualification, handoff, and measurement. Those transitions may belong to different teams, but the visitor experiences one continuous journey.

    Do not begin with the sitewide organic conversion rate. It blends visitors with different needs and can hide the exact transition you need to repair. Choose one commercially relevant topic, landing-page group, or offer and trace its cohort through the funnel.

    1. Write down the search promise. State what the visitor expected to accomplish when choosing the result.
    2. Identify the intended next action. Make it specific enough to observe, such as viewing a relevant solution path, starting an assessment, requesting information, or contacting sales.
    3. Count movement through each available transition: organic entry to meaningful action, action to valid inquiry, inquiry to accepted lead, accepted lead to sales contact, contact to opportunity, and opportunity to closed outcome.
    4. Segment the results by intent cluster, landing page, offer, and qualification outcome. Keep cohorts with materially different readiness separate.
    5. Read form records, routing outcomes, disqualification reasons, and follow-up activity for the affected cohort. Aggregate rates tell you where to look; individual records show what the process actually did.
    6. Mark the first transition that is weak, inconsistent, or unknown. That is the initial breakpoint to investigate.

    The first breakpoint matters because later metrics inherit earlier failures. If relevant visitors rarely see or understand the CTA, changing the lead-scoring model will not repair the journey. If qualified inquiries enter the CRM but sit without an owner, publishing more content increases volume into a broken handoff.

    Check message continuity before redesigning the page

    Conversion friction is not limited to button color, form length, or layout. It often begins when the experience changes its promise. Compare these elements in sequence:

    • The need implied by the query and search result
    • The landing-page headline and opening explanation
    • The primary CTA and the commitment it requests
    • The form questions and qualification language
    • The confirmation message and stated next step
    • The first automated or human follow-up

    Each step should continue the same conversation. A visitor who asks for an assessment should not receive a generic product pitch. Someone requesting a quote should not land in an educational sequence that avoids the requested commercial answer. A page promising help with a specific problem should not switch to broad corporate language at the form.

    Also inspect the commitment level. A CTA can be relevant to the product and still be wrong for the stage. If the only option on an exploratory page is a sales call, low conversion does not necessarily indicate poor traffic. It may indicate that the page asks the visitor to skip several decisions.

    Use a smaller next step only when it advances the buying journey. An ungated related explanation, a fit-checking tool, a focused comparison, or a route to a relevant solution page can do that. A generic content download that collects an email without clarifying intent merely creates another number for marketing to defend.

    Carry the original intent into the sales conversation

    A technically valid lead can still be mishandled when its context disappears. The CRM record should preserve the original organic channel, landing page or topic, converting page, selected offer, form answers, routing result, and relevant timestamps. Capture the search query only when it is legitimately available; do not make the workflow depend on visitor-level keyword data that you do not have.

    Translate those fields into something a seller can use. A raw URL is less helpful than a short description of the problem the person was researching, the action requested, the information already provided, and the likely stage that still needs confirmation.

    The first sales response should acknowledge that context. If the visitor requested information about a specific use case, the response should continue there rather than opening with a broad introduction to the company. Context makes the handoff feel like the next step the visitor chose, not an unrelated interruption.

    Measure the time from submission to ownership and from ownership to the first meaningful action. There is no universal response-time target that fits every sales model, so set an internal expectation your team can actually meet, make exceptions explicit, and track whether the agreed process occurred. A nominal SLA that nobody can operationalize will only add another green metric with no explanatory value.

    Define qualification and measurement before debating credit

    Marketing and sales cannot evaluate SEO together if the same funnel label means different things to each team. One person may call any submitted form a qualified lead. Another may require confirmed fit, a current need, and a real sales next step. Both can produce internally consistent reports that contradict each other.

    Turn funnel stages into observable contracts

    For every stage your organization uses, document five things: entry criteria, exit criteria, owner, clock-starting event, and allowed rejection or loss reasons. The labels themselves are less important than the shared rules.

    • Inquiry: a person or account has created a record through an identified action. This confirms capture, not quality.
    • Marketing-qualified lead, if used: the record meets explicit fit and intent criteria that marketing and sales have agreed to. A download or form completion alone should not silently become qualification.
    • Sales-accepted lead: a named sales owner has reviewed the record, accepted responsibility, and either confirmed the entry criteria or recorded a permitted rejection reason.
    • Sales-qualified lead or opportunity: the seller has verified the conditions your business requires for an active sales process and recorded a concrete next step.
    • Closed outcome: the result is recorded consistently, including the reason when the opportunity does not become revenue.

    If you use lead scoring, let the score automate parts of this contract rather than replace it. A score that combines unrelated activities into an unexplained threshold can make low-readiness activity appear sales-ready. Keep the underlying fit and behavior signals visible, and check whether higher-scored records actually progress.

    Rejection codes need the same discipline. “Bad lead” is not diagnostic. Reasons such as outside the served market, wrong use case, insufficient information, duplicate record, no response, or no current need point to different remedies. Use only the categories relevant to your business, define them clearly, and prevent free-text variations from fragmenting the report.

    Build one reporting view from demand to revenue

    Your shared view should preserve several layers instead of compressing SEO into one return-on-investment number:

    • Demand: organic entrances, landing-page groups, and intent clusters
    • Action: completion of the next step assigned to each page or stage
    • Quality: valid inquiries, qualification rate, sales acceptance, and disqualification reasons
    • Progress: sales contact, opportunity creation, pipeline movement, and stage age
    • Outcome: closed results and revenue where the CRM can support them
    • Operations: routing success, ownership, time to first meaningful action, and records with missing status

    Rankings and traffic remain useful. They diagnose whether search visibility and demand capture are changing. They simply cannot answer whether the rest of the commercial system converted that demand.

    Revenue also matures later than traffic. Compare cohorts at equivalent stages of maturity instead of treating the newest traffic period as if every lead has already completed the sales cycle. Keep the original cohort definition stable so later CRM updates can be connected to the same group.

    Resolve missing lifecycle data before arguing over first-touch, last-touch, or multi-touch attribution. Attribution distributes credit among recorded interactions. It cannot explain a lead that was never routed, an acceptance decision that was not logged, or an opportunity whose origin was overwritten.

    This does not require SEO to own the entire funnel. It requires an owner for every transition and a shared system of record. SEO can own the accuracy of the search promise and intent map. The appropriate web or conversion team can own the on-page transition. Revenue operations can own routing and lifecycle data. Sales can own acceptance, follow-up, and opportunity progression. Adapt the boundaries to your organization, but do not leave a boundary unowned.

    Turn each funnel pattern into a specific decision

    A funnel report should change what someone does next. Treat the patterns below as investigation starting points, not proof of a single cause:

    Observed patternInvestigate firstPractical next action
    Organic entrances rise while stage-appropriate actions fallIntent mix, landing-page promise, CTA relevance, and page pathSegment the new traffic and repair the affected page-to-next-step transition
    Inquiries rise while sales acceptance fallsQualification criteria, form inputs, routing rules, and rejection reasonsCompare accepted and rejected records, then revise the definition or capture process
    Accepted leads hold steady while opportunities declineOwnership, follow-up timing, message continuity, and missing sales contextAudit the handoff records and first responses for the affected cohort
    Opportunities rise while pipeline value stays flatOffer mix, account fit, expected deal value, and opportunity classificationSeparate volume from value and identify which search cohorts create commercially relevant opportunities
    CRM outcomes are blank or inconsistentRequired fields, stage rules, integrations, and process complianceRepair lifecycle recording before making a scaling or budget claim

    Once you identify the first credible breakpoint, write a compact action brief. Name the affected cohort, the evidence, the transition owner, the proposed change, the success measure, and the metric that must not deteriorate. Set the review point based on when enough of that cohort can reasonably mature through the relevant stage.

    Do not respond to a flat pipeline by changing content, forms, scoring, routing, attribution, and sales messaging at once. When several changes are unavoidable, record them so you do not later assign the result to whichever team presents the most persuasive chart.

    The most dangerous state is not an obvious decline. It is a dashboard full of improving metrics with no agreed explanation of how they connect to revenue. That uncertainty makes it impossible to scale the right work or stop the wrong work with confidence.

    For your next review, choose one important organic cohort and follow it from landing promise to recorded sales outcome. Find the first unowned, weak, or invisible transition. Give that transition an explicit definition, an owner, and a measurable next step before you commission another wave of traffic.

    References

  • AI Search Visibility: A Practical Plan to Earn Citations

    AI Search Visibility: A Practical Plan to Earn Citations

    If you are responsible for search and your brand rarely appears in AI answers, another optimization file is unlikely to solve the problem. Look for the break in a longer chain: the system cannot reliably retrieve the right page, understand the offer, corroborate the claim, or extract a useful answer.

    Your strategy should strengthen every link in that chain. That means clearer audience pages, citation-ready answers, consistent brand language, credible mentions beyond your domain, meaningful updates, and measurement built around AI responses rather than rankings alone.

    Start with an audience-and-use-case visibility map

    A broad services page often asks an AI system to infer too much. It must decide who the offer is for, which problem it solves, which industries it fits, and whether it applies to the user’s situation. Create clearly defined pages for the audiences, industries, and use cases you actually serve so those relationships are stated rather than implied.

    Key takeaways

    • SEO makes a page eligible for retrieval; answer design makes its content usable in an AI response.
    • Give each important audience-and-use-case combination a clear destination instead of forcing one generic page to cover everything.
    • State who you serve and what you do in homepage copy, not only in navigation labels.
    • Use reputable third-party coverage to corroborate your brand’s positioning across the web.
    • Refresh content only when the substance changes, then distribute the updated answer in formats your audience already uses.
    • Keep llms.txt behind crawlability, page clarity, content quality, authority, and measurement in your priority list.

    Build the map before commissioning more content:

    1. List the audiences that affect buying or adoption decisions. Use the labels those people use for themselves, not just your internal segments.
    2. List the problems, jobs, and situations that bring each audience to search.
    3. Turn each important intersection into a prompt cluster. Include the question, the desired outcome, relevant constraints, and the category of solution.
    4. Assign the best existing page to each cluster. Mark an intersection as a gap when no page answers it directly.
    5. Decide whether the gap needs a dedicated page, a substantial section on an existing page, or a visible FAQ answer.

    Do not create a thin page for every wording variation. A dedicated page is justified when the audience’s requirements, decision criteria, examples, or next step are materially different. If the answer would be nearly identical, keep one stronger page and address the variation within it.

    Then perform a homepage clarity test. Ignore the navigation and read only the body copy. An unfamiliar visitor should be able to complete this sentence without guessing: the brand helps this audience perform this job through this category of product or service. Homepage text is especially important because AI systems may extract brand and service meaning from the page more effectively than from navigation labels alone.

    Apply the same discipline to the footer. Use a compact, natural description of the business and link to priority audience or use-case pages. Footer copy can reinforce brand and service signals, but a block of repeated keywords will not repair an unclear site.

    Make every priority page retrievable, interpretable, and quotable

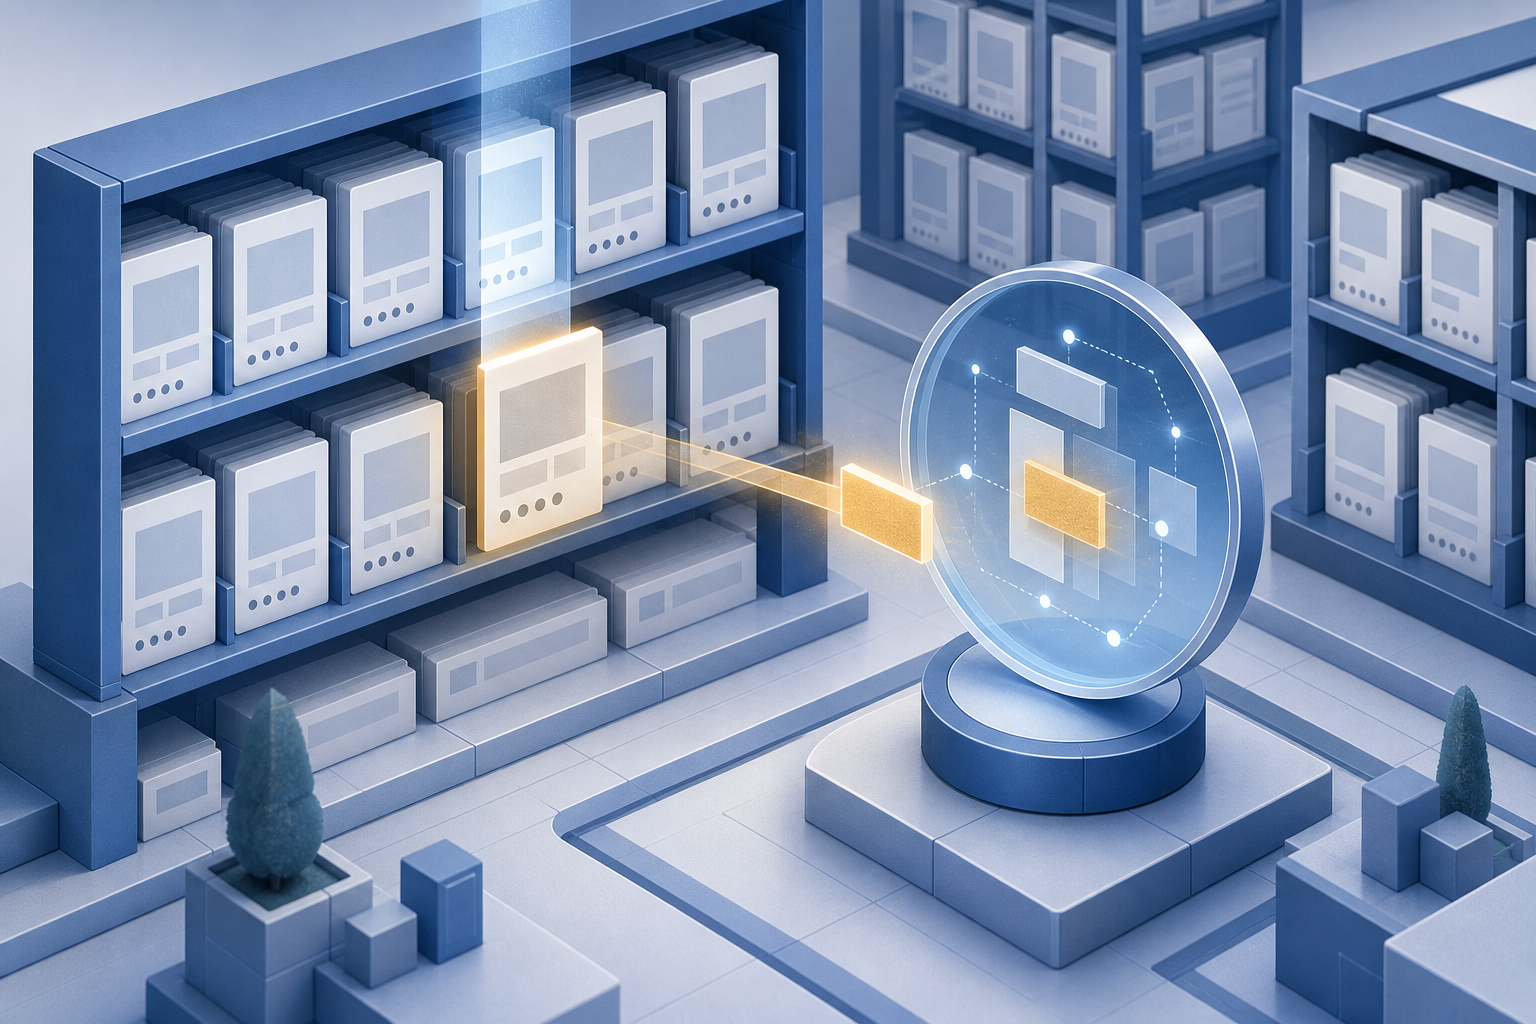
    An isometric digital library shows a beam retrieving one structured document card and extracting a highlighted fragment.

    Retrieval comes before citation. Systems such as GPT-5 can use retrieval-augmented generation to query current information, so visibility in conventional search remains an important route into AI-generated answers. SEO earns eligibility. AEO or GEO improves the chance that the retrieved page will be selected, represented accurately, and cited.

    Audit each priority page in that order:

    • Retrievable: The page is crawlable, indexable, internally linked, canonically consistent, and not dependent on an interface state that prevents its main answer from appearing in the rendered content.
    • Clearly scoped: The title, heading, opening copy, and supporting sections agree about the audience, problem, and use case.
    • Direct: The first useful paragraph answers the primary question before expanding into background, qualifications, examples, or process.
    • Explicit: The page names the brand, category, audience, and relevant use case where those facts matter. It does not rely on the reader or model to infer them from slogans.
    • Supportable: Important claims include the conditions, limitations, dates, or evidence needed to interpret them correctly.
    • Extractable: Each important section contains a self-contained answer that still makes sense when separated from the paragraphs around it.
    • Connected: Internal links point to the next relevant detail rather than sending every visitor back to the homepage.

    A citation-ready passage has a simple anatomy: a specific question or descriptive heading, a direct answer, the conditions under which it applies, supporting detail, and a sensible next action. A page can be topically relevant and still be hard to cite when its conclusion remains implicit. Treat clear, reusable answers as an editorial requirement for AI visibility, not as a layer to add after publication.

    Structured data should describe facts that are already clear and visible on the page. It can make relationships more explicit, but it cannot supply a missing answer, establish unsupported authority, or rescue vague positioning. Validate the markup, keep it consistent with the visible content, and fix the underlying page before expanding the schema.

    FAQs are useful when they resolve distinct questions rather than restating the sales copy. When the topic naturally supports enough depth, publish eight to ten well-developed questions and answers. Put the direct response at the start of each answer. Cover the relevant qualification or exception, then link to a deeper page when one exists.

    Do not make a closed accordion the only place where a crucial fact appears. If the interface must collapse secondary detail, keep the concise answer visible in the main page copy. The goal is not to ban accordions; it is to prevent essential meaning from depending on a click.

    Keep llms.txt in perspective. No major LLM provider has confirmed broad reliance on it, and Google has said it does not use the file. That makes llms.txt a low-priority experiment rather than a visibility foundation. It cannot compensate for blocked crawling, weak search performance, ambiguous pages, or a lack of credible corroboration.

    Build external corroboration without sacrificing trust

    Your site supplies the preferred description of your business. Independent, relevant websites help establish that the description exists beyond your own claims. This is why digital PR, expert contributions, reputable directories, industry coverage, and carefully chosen syndication belong in an AI visibility plan.

    Evaluate every prospective placement with the same questions:

    • Does the publication reach the audience represented by the target prompt?
    • Does it regularly cover the category with enough depth to make the mention contextually credible?
    • Will the brand appear in a complete, factual sentence that explains what it does and for whom?
    • Can the coverage point readers to the most relevant use-case page instead of defaulting to the homepage?
    • Is the page public, durable, readable, and governed by recognizable editorial standards?
    • Would you still want the placement if no AI system ever cited it?

    The last question prevents a visibility tactic from becoming a reputation problem. Current observations indicate that LLMs may not reliably distinguish paid advertorials from organic editorial coverage, so well-placed advertorials can influence brand visibility. That is not a reason to disguise sponsorship. Disclose paid content, follow the publication’s rules, and judge the placement by its usefulness and credibility rather than by the possibility that a model will ingest it.

    Syndication follows the same quality rule. Wider distribution can create more opportunities for discovery, but repetition across low-quality or irrelevant sites is not equivalent to independent authority. Favor a smaller set of respected publications with real topical and audience alignment over indiscriminate volume.

    Authority can also affect speed. Coverage on a respected niche site has appeared in AI responses within hours in documented examples, but rapid inclusion should be treated as a possibility, not a service-level guarantee. The model, query, retrieval system, publication, and timing can all change the outcome.

    The scale required to change an established brand narrative may be larger than expected: one estimate puts meaningful influence at about 250 documents. Treat that figure as directional, not as a quota. It does not establish that any collection of 250 pages will work, and it says nothing by itself about relevance, authority, consistency, or retrieval.

    The operational lesson is that brand representation is a corpus problem, not a homepage-editing task. Maintain a short narrative brief that defines the category, primary audiences, important use cases, substantiated differentiators, facts that must remain consistent, and claims that should not be made. Use it when preparing owned content, contributed material, press outreach, partner profiles, and paid placements. Consistency should apply to the facts; the prose should still fit each publication and audience.

    Use meaningful freshness and native formats to widen discovery

    Freshness can carry disproportionate weight in AI search, but changing a date is not a content update. A useful refresh changes what a reader can learn, decide, or do. Otherwise, the new timestamp creates an expectation the page cannot satisfy.

    Refresh a page when you can make at least one substantive improvement:

    • Replace an outdated fact, process, capability, recommendation, or example.
    • Add a newly important audience question or use case.
    • Clarify a qualification that changes when the answer applies.
    • Strengthen weak support for an important claim.
    • Remove obsolete sections that obscure the current answer.
    • Reorganize the page so the direct answer appears before secondary background.

    Document what changed and update the visible date only when the revision is real. This gives editors a defensible maintenance process and prevents a freshness program from becoming a schedule of cosmetic touches. The practical advantage comes from genuinely current information, not artificial refreshing.

    After updating the canonical page, adapt its core answer for other formats. A video can demonstrate a process. Audio can support an interview or detailed explanation. An image can make a framework or sequence easier to grasp. A native social post can state the conclusion for people who will not open a long page. Keep the category, audience, use case, and important facts consistent so every format reinforces the same entity relationships.

    Use one publishing workflow:

    1. Make the owned page the complete, maintained version of the answer.
    2. Select formats according to what each can explain better, not merely according to what can be copied fastest.
    3. Preserve important terminology and qualifications across the adaptations.
    4. Publish enough native context for each version to make sense on its own.
    5. Return to the canonical page when the audience needs the complete answer or evidence.

    Distribution speed varies. LinkedIn posts and Pulse articles can appear in AI search quickly, and Reddit and YouTube have shown similar behavior; in some observations, discovery has happened within hours or even minutes. Use fast-moving platforms as additional retrieval paths, not as guaranteed or permanent coverage.

    Multimodal publishing is useful when every version contributes something. A stock-footage video that reads the page aloud adds little for the user. A demonstration, visual breakdown, expert discussion, or focused question-and-answer session gives the format a reason to exist while reinforcing the underlying topic.

    Measure AI answers as a visibility system, not a rank

    An analyst observes multiple translucent AI answer panels connected to changing groups of source nodes over time.

    A conventional rank tracker cannot tell you whether an AI answer mentioned the brand correctly, cited the intended page, or adopted a competitor’s framing. Build the measurement set from the audience-and-use-case map so the prompts reflect business relevance rather than a random collection of popular questions.

    Include several kinds of intent: category discovery, problem diagnosis, use-case fit, comparison, and branded fact checking. Keep a stable core set so changes remain interpretable, but retain natural variants because AI responses are not fixed search listings.

    For every check, record:

    • The AI surface or model, date, prompt, and any account or location context that could affect the result.
    • Whether the brand appeared.
    • Whether the answer included a citation or link.
    • Which URL was cited and whether it was the page assigned in the visibility map.
    • How the answer described the brand, audience, category, and use case.
    • Whether the description was accurate, incomplete, or wrong.
    • Which competitors appeared and which pages supported them.
    • Which owned-page, distribution, or authority-building changes preceded the check.

    Turn those observations into four simple measures. Mention rate is the share of tracked prompts in which the brand appears. Citation rate is the share in which the brand or its content receives a supporting link. Accuracy rate is the share of mentions that state the essential facts correctly. Intended-page rate is the share of citations that lead to the page assigned to that prompt cluster. None should be treated as a universal benchmark; their value is in showing movement within your own tracked set.

    Use response patterns as diagnostic hypotheses:

    • No mention: inspect retrieval, audience fit, topical coverage, and external authority.
    • A mention without a citation: inspect whether the page contains a self-contained answer and whether independent coverage supports the claim.
    • An inaccurate description: compare the language used across the homepage, priority pages, profiles, partner pages, and recent coverage.
    • A competitor cited instead: compare the specificity of its answer, the relevance of its cited page, and the authority of the websites corroborating it.
    • Social content appears while the owned page does not: rapid distribution may be working while canonical-page retrieval remains weak.
    • The homepage is cited for every intent: the audience and use-case pages may not be sufficiently distinct, discoverable, or internally connected.

    These patterns do not prove causation. Change a single layer where practical, annotate the change, and watch the full prompt set rather than celebrating one favorable response. AI visibility is variable; a durable strategy improves retrieval, representation, and corroboration together.

    Begin with the highest-value gap in your audience-and-use-case map. Give it a clear destination, make the homepage and footer state the same fit, publish visible answers to the questions that affect the decision, and pursue credible coverage around those facts. Define the prompts and measures before publication so success means more than finding a flattering answer after the fact.

    Once that operating loop is in place, AI search stops being a collection of speculative tricks. It becomes a disciplined extension of SEO, content design, brand management, distribution, and measurement.

    References

  • Mastering the Art of Finding Exceptional Content Writers

    Mastering the Art of Finding Exceptional Content Writers

    How to find great writers (and other content marketing struggles)

    I’ve realized that when it comes to content, you truly get what you pay for. In 2026, I’m constantly exploring new ways to locate outstanding writers, from job boards to LinkedIn and more.

    As a marketer, I find myself spoiled for choice when it comes to sources for stellar content. Nowadays, there are more tools and job boards available, making it simpler to locate talented writers and generate compelling content.

    However, this abundance also brings challenges, such as prioritizing speed and cost over quality.

    If I’m aiming for great (not just good) content, I know some sources are more reliable than others.

    This guide will help me find top-tier writers and build a content strategy that ensures quality without sacrificing speed.

    Struggle 1: What qualifies as a ‘great’ content writer?

    Identifying a great writer can feel a lot like evaluating a new love interest. They may look good on paper and make a strong first impression, but how can I be sure they’re the right fit?

    Just like a love interest, I need to invest time to truly know the writer. But that doesn’t mean I go in blindly. Here’s what I focus on to find the perfect match without wasting time.

    Evaluate the fundamentals

    I look for writers with a strong grasp of grammar, spelling, clarity, and structure. Instead of formal tests, I examine their portfolios and content samples for quality.

    A few email exchanges during the hiring process can also reveal their communication skills and confidence.

    Make sure they know how to write for people, not bots

    Great writers understand that search engines favor content crafted for people rather than formulas. When evaluating samples, I keep an eye out for readability and SEO expertise.

    I try to read through and ask myself, “Would this content be useful and engaging for my target audience?” If the answer is no, I know search engines won’t favor it either.

    Choose effective copywriters

    For a solid return on investment, I prefer writers who possess SEO copywriting skills beyond basic SEO tactics.

    While driving traffic is essential, skilled copywriters guide readers toward action, be it signing up, clicking through, or making a purchase.

    Assess how easily understandable their work is

    I put importance on checking readability scores for potential writers. Sometimes, an article may appear well-written but holds a low score for readability, signaling a lack of clarity.

    Find writers that adapt to the audience

    My ideal writer not only understands the product or target demographic but deeply connects with the audience’s mindset. I ask for niche-specific samples to ensure they understand my audience’s needs and frustrations.

    Dig deeper: How SEO can collaborate with content teams

    Struggle 2: Where can I find great content writers?

    In my experience, you can find “good” writers almost anywhere. However, I notice a difference between choosing Fiverr and more selective platforms offering better screening opportunities.

    Blogging sites

    I often look for SEO content writers on blogging sites like Medium, Substack, and LinkedIn. These platforms allow me to see real-time writing and communication styles.

    Google and other search engines

    Google is a resourceful tool for finding high-quality writers. Those who maintain their own websites often showcase their understanding of SEO through their content marketing efforts.

    LinkedIn and Facebook groups

    By joining writer and freelancer groups on LinkedIn and Facebook, I observe conversations and discover writers who share their work and thoughts.

    Peer recommendations

    I don’t shy away from asking for recommendations. Strong writers often get referrals in their communities. Business owners frequently suggest top performers known for real-world project success.

    Dig deeper: How to build an effective content strategy for 2026

    Struggle 3: Do I need an ‘SOP’ for my writers?

    Absolutely. Even when working with experienced writers who manage multiple clients, each has unique preferences and styles. I use standard operating procedures (SOPs) to minimize guesswork and enhance clarity.

    Many businesses misinterpret the struggle to find writers with the challenge of retaining them. Without clear directions and SOPs, there’s room for confusion. I’ve found that SOPs save time and keep everyone on the same page.

    If writing SOPs feels overwhelming, I consult with operations specialists who can streamline the process, boosting my ROI and ensuring writer satisfaction.

    Dig deeper: How to document your content strategy

    Get the newsletter search marketers rely on.

    MktoForms2.loadForm(“https://app-sj02.marketo.com”, “727-ZQE-044”, 16298, function(form) { // form.onSubmit(function(){ // }); // form.onSuccess(function (values, followUpUrl) { // }); });

    Struggle 4: How much should I pay for content?

    The allure of low-cost content is tempting, especially with quick turnaround promises. But I question the time needed to revise or rewrite it.

    If I don’t have editors on hand, this might mean more time editing than crafting it myself. Investing in inexpensive writers isn’t wise without adequate training resources.

    In 2026, I’m preparing to pay at least $0.20 per word for premium content. Rates vary, depending on a writer’s expertise and accolades. Ultimately, I look for writing that truly converts.

    Dig deeper: Mastering content quality: The ultimate guide

    Struggle 5: Should I use freelance writers or build a team?

    Choosing between freelancers and an in-house team hinges on my objectives and budget. Freelancers provide flexibility, scaling content as needed without heavy resources.

    Conversely, an in-house team offers consistency and deep brand knowledge. While creating more content or operating in complex niches, this consistency becomes invaluable.

    For many, a hybrid model is effective: blend an internal team for editorial control with freelancers for scaling. Tailoring the content system to resources can fit any business stage.

    Dig deeper: 5 SEO content pitfalls that could be hurting your traffic

    Struggle 6: Is ‘great content’ worth the investment?

    From my perspective, optimized content, just like anything else, yields returns based on investment.

    By working with top-quality writers, I see an increase in traffic and rankings, making the investment worthwhile. The benefits of high-quality content amplify over time.

    I find well-researched content draws qualified visitors long after it’s published, and builds trust with audiences, ultimately fostering more sales.

    Great content supports the entire customer journey by answering queries and positioning the brand as credible, providing value throughout their experience.

    A skilled writer attracts the right audience, making each investment worthwhile.

    Great writers come from clear standards, not lucky hires

    I’ve learned that finding exceptional writers isn’t about luck, but about maintaining clear standards.

    Understanding what quality looks like and where to look transforms the process into a predictable and less frustrating experience.

    The most successful content programs approach writing as a sustainable investment, pairing writers with clear expectations, fair pay, and repeatable systems for long-term value.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How AI Highlights the Vital Role of Human Connections in Agencies

    How AI Highlights the Vital Role of Human Connections in Agencies

    Working as an office manager in my early 20s, I discovered Dale Carnegie’s “How to Win Friends and Influence People.”

    The timeless principles in that book have been my guiding compass through various career shifts. I’ve realized that success in most professions hinges on how we interact with others—be they clients or colleagues.

    For many years, combining human touch with technical skills has been a winning formula for digital marketers. It was this ability to demystify complex machines coupled with strong relationship-building that allowed agencies to retain clients.

    But now, this model is under scrutiny as AI becomes integral to PPC platforms, raising a pertinent question: why shouldn’t clients dive into an entirely AI-driven approach?

    What agencies have an edge on is their relational strength—their ability to communicate effectively and understand what business owners genuinely need.

    1. Ask questions

    I’ve learned that one of the most effective ways to understand people and what makes them tick is by asking questions. Though it seems straightforward, communication often becomes lost in translation or obscured by assumptions.

    Whenever I walk into a sales call, I arm myself with a list of questions. How much can I uncover about this potential client in a brief half-hour conversation?

    Similarly, during strategy discussions, I prepare a comprehensive set of queries—some for myself, and some for the client. What are they aiming to achieve? What aspects of their current strategy need refinement? How can we enhance it?

    To this day, AI can’t fulfill this role—not yet, at least. Our exchanges with AI remain predominantly one-sided.

    AI doesn’t actively seek to understand us as individuals or identify our unique challenges. These discoveries only come from asking questions and actively listening, which leads to the next point.

    Dig deeper: 6 tips to build PPC client relationships

    2. Talk less, listen more

    How often do I find myself in conversations, impatiently waiting for a pause to insert my thoughts? I’m guilty of this, but I’ve found that clients crave the opportunity to be heard.

    Allow them to express themselves fully, encourage them with more clarifying questions, and just keep listening. It’s remarkable what you can learn about someone when you enter a conversation with no other agenda but to understand the other person.

    Fill the silences only if they become awkward, and if you have valuable agenda points to address based on what you’ve learned. This approach fosters collaboration and generates ideas more swiftly than dominating the conversation could. It solidifies agreement, which is foundational in building relationships.

    Dig deeper: 8 questions to ask your new PPC clients

    3. Find common ground

    Whenever possible, I aim to discover commonalities between myself and new acquaintances. By doing so, I build rapport, enriching both personal and professional relationships.

    Being personal and specific, whether dealing with a friend or a client, is key. I love recalling little details about people and bringing them up in future conversations. People appreciate being remembered and valued.

    Though AI is beginning to develop memory, finding shared experiences with others is a uniquely human skill that, fortunately, remains beyond AI’s reach.

    Dig deeper: When and how to fire PPC clients

    4. Smile, be less serious (when it’s appropriate)

    In the fast-paced marketing realm, it’s easy to succumb to the all-consuming cycle of data analysis and testing. Remember, though, not to take ourselves too seriously.

    After all, this profession is relatively new, and its evolution is unpredictable. Let’s not forget why we ventured into marketing—to help and connect with people. Let’s embrace opportunities to be less serious and inject humor when it fits.

    We’re human, and it’s vital for those we work for to recognize this humanity as an integral part of any relationship.

    Dig deeper: How to set and manage PPC expectations for teams and stakeholders

    What differentiates a partner from an algorithm

    In a world increasingly dominated by AI, the focus is shifting from technical prowess to personal connection. AI excels at data and analysis, available at a moment’s notice, but knowledge alone isn’t sufficient anymore.

    Empathy, shared experiences, and true rapport are beyond AI’s capability to replicate. These human principles, combined with expertise, are what enabled agencies to decode machines for clients and nurture enduring relationships.

    By returning to relational basics—posing insightful questions, practicing active listening, and establishing common ground—agencies can affirm their indispensable value.

    These relational skills are vital in distinguishing a partner from an algorithm, ensuring that the work of agencies remains not just relevant but essential.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot