Month: October 2026

  • Retail Media Audience Sharing in Google Ads: A Practical Guide

    Retail Media Audience Sharing in Google Ads: A Practical Guide

    If you sell through a retailer, some of the most useful shopper signals may sit in the retailer’s account while your campaign sits in yours. Google Ads commerce audience sharing creates a bridge between those two positions. That bridge is useful, but narrow: it is limited to eligible commerce media network campaigns.

    Before you build a media plan around it, you need to know what can be shared, where the resulting audiences can be used, what each partner can see and how you will judge the outcome. Getting those decisions in writing before activation prevents an audience opportunity from turning into an account, measurement or expectations problem.

    The feature is useful, but its lane is narrow

    Commerce audience sharing lets a retailer or marketplace make selected first-party audience segments available to a brand or seller through Google Ads. That gives an advertising partner access to audiences grounded in the commerce partner’s own customer relationships and shopping activity, rather than requiring the advertiser to build the same relationship independently.

    The roles are straightforward:

    • The commerce partner is the retailer or marketplace that owns and shares the eligible first-party segments.
    • The advertising partner is the brand or seller that can use those shared segments in an eligible retail media campaign.
    • Google Ads supplies the campaign infrastructure through which the collaboration operates.

    The most important limitation is also the easiest to miss. Shared commerce audiences are available for commerce media network campaigns, not for automatic use across regular Search, Shopping or Performance Max campaigns. Operationally, you should treat this as audience access for a qualifying retail media program, not as a portable audience asset that can be reused throughout your Google Ads account.

    That boundary should shape your go-or-no-go decision. The feature is a plausible fit when your immediate goal is to reach a retailer’s existing customers, high-intent shoppers or another retailer-defined customer group inside an eligible commerce media network campaign. It is not the answer when your plan depends on carrying the same segment into ordinary Search, Shopping or Performance Max activity.

    It is also a paid media capability, not an organic visibility tactic. Activating a retailer audience does not change how your pages are indexed, cited in AI answers or surfaced through SEO, AEO or GEO. Keep retail media activation and organic search optimization as separate workstreams, even when they support the same commercial objective.

    Prove the account and campaign path before planning creative
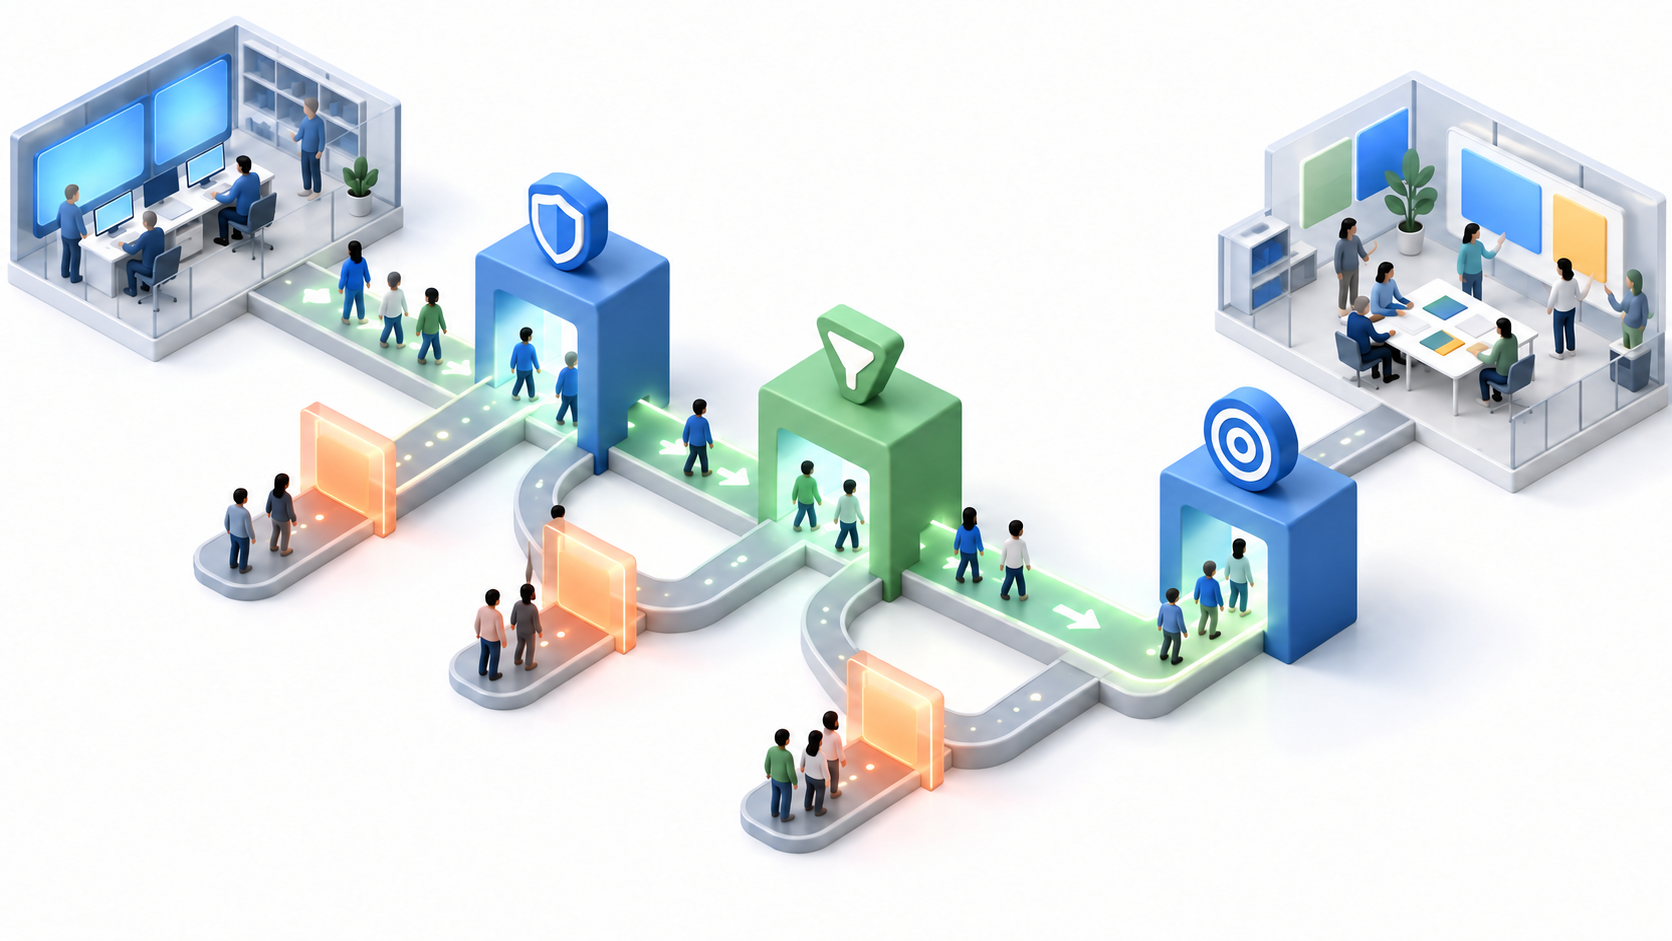
    An isometric account-to-campaign pathway connects retailer and advertiser workspaces through eligibility and access checkpoints, while incompatible routes are blocked.

    A promising audience idea has no value if the required accounts, eligibility and campaign type are not in place. Validate the operating path before you assign budget or ask a creative team to produce segment-specific ads.

    1. Identify the commerce partner. Name the retailer or marketplace that will make the segment available. Do not leave ownership implied between a brand, agency, seller and retailer.
    2. Confirm eligibility on both sides. The commerce partner and advertising partner must each satisfy Google’s eligibility requirements. One eligible account does not make the other eligible.
    3. Confirm the campaign type. Write down that the intended activation is an eligible commerce media network campaign. If the media plan only contains regular Search, Shopping or Performance Max campaigns, stop and redesign the audience plan.
    4. Map the required account relationships. The retailer’s sharing setup involves linking its Google Ads account with the relevant Google Merchant Center and data-sharing accounts. Assign an owner for each account and identify who can approve each link.
    5. Inventory the segments that will actually be shared. Availability is a commerce-partner decision. Build the campaign around confirmed segments, not around audience names that you hope the retailer can provide.
    6. Agree on the handoff. Record who publishes the segment, who confirms that it is available, who attaches it to the campaign and who resolves access problems.

    This sequence matters because audience strategy and account setup are different jobs. The advertiser may know which shoppers it wants, while the retailer controls which first-party segments are made available. A short activation brief should join those responsibilities instead of allowing each side to assume the other has handled them.

    Your brief should name the commerce partner, advertising partner, Google Ads account, relevant Merchant Center and data-sharing relationships, eligible campaign type, approved audience segments, primary conversion and approval owners. If any one of those fields is unresolved, the campaign is not ready for an audience-dependent launch date.

    Build the audience plan around a decision, not a label

    A segment called high intent sounds useful, but the label alone does not tell you what action to take. Ask what business decision becomes different because that audience is available.

    • Existing customers: Use this type of retailer-defined segment when the campaign has a clear relationship objective, such as presenting a relevant next purchase or a distinct customer message. Decide in advance whether existing customers are the target, a separate reporting group or outside the acquisition objective.
    • High-intent shoppers: Use this type only after the retailer explains what makes a shopper high intent. The campaign message should reflect the next action you want that shopper to take, not merely repeat a broad awareness message.
    • Specific customer segments: Request a segment when a meaningful difference in customer type changes the offer, product emphasis, creative or measurement plan. If every segment will receive the same treatment, extra segmentation may add operational complexity without improving the decision.

    For every requested segment, document the following questions:

    • What customer type does the segment represent?
    • Which behavior or relationship qualifies a person for it?
    • How recent must that qualifying behavior be?
    • How is the segment refreshed?
    • Can customers belong to more than one shared segment?
    • Which eligible campaigns may use it?
    • Which conversion will determine whether using it was worthwhile?

    Those operational definitions may require a direct agreement with the retailer. The information visible to an advertising partner includes segment names, customer types and conversion data, but a usable campaign brief often needs more context than a segment name can carry.

    Naming deserves care as well. A segment name should be clear enough for the advertiser to select and report on correctly. It should not contain customer-level information or encode details that are inappropriate to expose to a partner. Use a stable naming pattern that distinguishes the customer type, intended use and any version the partners need to recognize.

    The governing principle is simple: request the smallest meaningful set of audiences that can change a campaign decision. A long list of vaguely differentiated segments makes implementation and interpretation harder. A clearly defined segment tied to a specific message and conversion creates something both partners can evaluate.

    Measure value without calling every conversion incremental
    An analyst separates a mixed stream of conversion symbols into distinct groups to distinguish observed results from possible incremental effects.

    Audience sharing gives both sides visibility, but not identical visibility. Advertising partners can see shared audience information and conversion data. Commerce partners can access performance metrics showing how their audiences are being used and how the campaigns perform. Agree on a shared scorecard before launch so that each side does not reach a different conclusion from its own view.

    Separate four measurement questions:

    1. Was the intended audience available and used? Confirm that the correct shared segment was attached to the correct eligible campaign.
    2. Did the campaign produce the selected conversion? Define the conversion before launch and use the conversion data available to the advertising partner consistently.
    3. Was performance better than a relevant comparison? Where practical, compare the audience strategy with a campaign or audience treatment that is similar enough to inform the decision. Avoid changing the audience, creative, offer and optimization objective simultaneously if you want to understand which choice mattered.
    4. What can you honestly claim? Strong performance within a high-intent audience shows that the campaign reached and converted valuable shoppers. It does not, by itself, prove that every conversion was caused by audience sharing or that those purchases would not otherwise have happened.

    The distinction between efficiency and incrementality is important. A retailer’s high-intent audience may naturally contain people who are already close to buying. That can make the segment commercially useful, but a strong conversion result is still a performance observation unless the measurement design supports a causal lift claim. Label the result accurately: performance, comparative performance or incremental lift should not be treated as interchangeable terms.

    Set the decision rule before the campaign runs. State which conversion matters, which comparison you will use, which campaign variables must remain consistent and what result would lead you to expand, revise or stop the activation. The rule does not need an invented universal benchmark. It needs to match your economics and be agreed by the people who will act on it.

    Audience collaboration also needs a governance check. Document the approved campaign purpose, the people who can access the relevant accounts, the audience naming convention and the performance information each partner expects to review. Platform eligibility answers whether the feature can be used; it does not replace the commercial, privacy or contractual review appropriate to the partners’ relationship. Involve the responsible internal teams before sharing or activating customer-based segments.

    Key takeaways

    • Commerce audience sharing lets eligible retailers and marketplaces make first-party segments available to eligible brands and sellers through Google Ads.
    • The shared segments are limited to commerce media network campaigns; they do not automatically extend to regular Search, Shopping or Performance Max campaigns.
    • The retailer’s setup depends on the relevant Google Ads, Google Merchant Center and data-sharing account relationships.
    • Advertisers can see segment names, customer types and conversion data, while commerce partners can review performance information about audience use and campaign results.
    • A useful segment needs an operational definition, a distinct campaign decision and a named conversion. A persuasive label is not enough.
    • Campaign performance and incremental impact are different claims. Use comparison-based or causal language only when the measurement design supports it.

    If the campaign qualifies, begin with one documented audience, one campaign objective, one primary conversion and one agreed comparison plan. Resolve account ownership and eligibility before creative production begins. If your strategy requires the audience in standard Search, Shopping or Performance Max campaigns, choose another audience path instead of building a plan around access this feature does not provide.

    References


  • How to Read Google Ads Experiments and Funnel Reports

    How to Read Google Ads Experiments and Funnel Reports

    You open Google Ads and see two persuasive narratives. The funnel view shows campaigns contributing across the customer journey, while an AI-generated experiment summary points toward a recommended action. Both can help you make a decision. Neither should make that decision for you.

    The practical job is to separate three questions: Where did campaign activity appear in the journey? Did it cause an incremental result? What exactly will happen if you apply the experiment outcome? Once you keep those questions separate, the reporting becomes far more useful.

    Use funnel reporting to decide where to investigate

    The Performance by stage card on the Google Ads Overview page organizes campaign reporting around awareness, consideration, and action. It brings impressions, CPM, frequency, views, video completion rate, and conversion insights into a journey-oriented view.

    That structure is most useful when you treat each stage as a different decision question. An awareness campaign should not be judged only by the immediate conversions visible at the end of the journey. An action-focused campaign should not receive credit merely because it generated a large number of impressions. Start with the job the campaign was meant to do, then select the evidence that fits that job.

    Funnel stageDecision questionSignals to examine togetherWhat to do next
    AwarenessAre you reaching people at an acceptable exposure pattern?Impressions, CPM, frequency, and Brand Lift when configuredInvestigate reach, repetition, and whether exposure is changing brand outcomes before expanding delivery.
    ConsiderationAre people engaging deeply enough to warrant further investment?Views, video completion rate, and Search Lift when configuredIdentify which campaigns or creative approaches deserve a controlled follow-up test.
    ActionIs campaign activity connected with business outcomes?Conversion insights and Conversion Lift when configuredValidate measurement coverage, incremental impact, and economic value before changing budget or settings.

    Read these signals in pairs rather than isolation. Impressions without frequency do not tell you whether delivery is broad or repetitive. Views without completion rate do not reveal how much of the video people consumed. Conversion totals without knowing which conversion actions are eligible can produce a false comparison.

    The funnel card can also incorporate insights from Brand Lift, Search Lift, and Conversion Lift studies when they are configured. That distinction matters. Routine delivery and engagement metrics tell you what happened inside the reporting system; lift measurement is designed to address whether exposure changed an outcome.

    Do not turn a conversion path into a causal claim

    Branching customer touchpoints converge on an outcome beside two matched groups arranged for a controlled experiment.

    Video impressions can now appear in conversion paths, marked with an eye icon. This gives you visibility into exposure that was previously missing when the path showed video views but not impressions. It does not prove that the impression caused the eventual conversion.

    A conversion path is descriptive. It tells you that an eligible exposure or interaction appeared in the recorded sequence associated with a conversion. Incrementality is a different question: would the conversion have happened without that campaign exposure? A path alone cannot answer it.

    • Use the path to identify patterns worth investigating, not to declare that every recorded touchpoint deserves causal credit.
    • When the decision involves additional spend, use an incrementality method such as Conversion Lift when it is available and appropriately configured.
    • Keep observational language in your internal reporting. Say that video impressions appeared in conversion paths, not that those impressions generated every conversion in those paths.
    • Compare campaigns only after confirming that their conversion coverage is comparable.

    That last check is essential because the added video-impression visibility currently covers eligible web conversions but excludes conversions imported from Google Analytics 4. If your account relies on GA4-imported conversions, a missing video impression may reflect the reporting boundary rather than the absence of an earlier exposure.

    Before presenting a funnel report, label the conversion setup behind it. Note which actions are eligible web conversions, which are imported from GA4, and whether different campaigns are being evaluated against the same set. Without that note, an apparent gap between campaigns may be a measurement-coverage gap.

    Treat the AI experiment summary as triage, not a verdict

    The Summary tab for Google Ads experiments now includes an AI-generated panel covering the experiment goal, key findings, and recommended actions. This can reduce the time required to scan several test scorecards, particularly when you manage multiple experiments.

    Use that panel to find the decision you need to inspect. Then return to the underlying scorecard and run a consistent decision gate. The summary can condense the reported pattern, but it cannot replace the business context that determines whether the pattern is valuable.

    1. Restate the hypothesis. Write the specific change and the result it was expected to improve. If you cannot state both in one sentence, the experiment is not ready for a winner declaration.
    2. Confirm the primary outcome. Use the business outcome selected for the decision, not whichever metric happens to show the most attractive movement.
    3. Check duration and conversion volume. A promising direction based on limited observation is still limited evidence. Do not end a test merely because the automated summary sounds decisive.
    4. Inspect statistical significance. A visible difference is not automatically a reliable difference. If the evidence is inconclusive, record it as inconclusive rather than relabeling it as a tie or a failure.
    5. Test practical significance. A statistically credible change may still be too small, too costly, or too poorly aligned with the business objective to apply.
    6. Review trade-offs. Check whether improvement in the primary metric came with deterioration in a metric that protects cost, lead quality, conversion quality, or another business constraint.
    7. Evaluate the recommendation. Treat the suggested action as a candidate decision that has passed through the preceding checks, not as an instruction that bypasses them.

    This order prevents a common analytical mistake: reading the recommendation first and then searching for evidence that supports it. Decide what would count as success before you let the generated narrative frame the result.

    Statistical significance and business significance should also remain separate. Statistical significance addresses whether an observed difference is likely to be more than random variation under the test assumptions. Business significance asks whether the difference is worth the cost, risk, and operational change. You need both questions, even when the interface emphasizes only one of them.

    Check the consequence before applying a Performance Max result

    An analyst inspects a glowing recommendation at a decision gate connected to several downstream resource channels.

    The word “apply” does not have one universal effect across Performance Max experiments. The outcome depends on the experiment type, so confirm the type before accepting any recommendation.

    Performance Max experimentWhat applying the result doesDecision you must make first
    Migration experimentMoves traffic fully to Performance MaxConfirm that you intend to move all relevant traffic, not merely acknowledge the reported winner.
    Optimization experimentPermanently applies the tested settingsConfirm that every tested setting is acceptable as an ongoing campaign configuration.
    Custom experimentLets you manually select the winning versionCompare the versions against the predefined business outcome and choose deliberately.

    This is the point where a reporting interpretation becomes an account change with spending consequences. Before applying a result, record the control configuration, the tested difference, the experiment type, the selected winner, the expected platform behavior, and the person responsible for the decision. Also write down how you would respond if post-change performance no longer supports the choice.

    A compact decision record keeps the funnel view, the experiment, and the account change connected without pretending they are the same kind of evidence:

    • Business question: What decision are you trying to make?
    • Funnel stage: Is the campaign intended to influence awareness, consideration, or action?
    • Measurement coverage: Which conversion actions and exposure types are represented, and which are excluded?
    • Evidence type: Is the finding descriptive path evidence, an experiment result, or a lift result?
    • Validity check: Were duration, conversion volume, statistical significance, and business objectives considered?
    • Platform consequence: What will applying this experiment type actually change?
    • Decision: Apply, continue collecting evidence, revise the test, or stop without declaring a winner.

    The resulting workflow is straightforward. Use funnel reporting to spot the stage and signal that needs attention. Turn that observation into a specific hypothesis. Choose an experiment when you need to compare a controlled campaign change, or an appropriate lift study when the question is incrementality. Read the AI summary to orient yourself, validate it against the scorecard and business objective, then apply only after confirming the consequence.

    Key takeaways

    • The Performance by stage card is a diagnostic map across awareness, consideration, and action; it is not automatic proof of campaign impact.
    • A video impression in a conversion path shows recorded exposure, not causation.
    • Video-impression paths cover eligible web conversions and exclude GA4-imported conversions, so check coverage before comparing results.
    • AI-generated experiment summaries can speed up review, but duration, volume, statistical significance, practical value, and business objectives still determine the decision.
    • Applying a Performance Max result has different consequences for migration, optimization, and custom experiments.

    At your next review, put one sentence above the dashboard: “We are deciding whether to…” Finish that sentence before opening the AI recommendation. It will tell you which funnel evidence matters, what still needs validation, and whether pressing Apply is justified.

    References


  • Search Marketing Attribution: Measure Incremental Revenue

    Search Marketing Attribution: Measure Incremental Revenue

    Your search dashboard can look healthy while the budget decision remains unresolved. Paid search claims conversions, organic search receives assisted credit, and AI-search referrals appear in GA4 when referral data survives. Then finance asks the question the dashboard cannot answer: how much revenue would disappear if you stopped?

    Choosing another attribution model will not settle that question. You need two connected systems: an evidence chain that follows search activity into realized revenue, and a causal test that estimates what search created rather than merely touched. Here is how to build both without pretending the data is cleaner than it is.

    Attribution assigns credit; incrementality tests causation

    Attribution asks which observed touchpoints should receive credit for a conversion. Incrementality asks whether the conversion happened because of the marketing activity. Those are different questions, and they support different decisions.

    Consider a customer who already intends to buy, searches for your brand, clicks a paid result, and completes the purchase. An attribution model may give the ad full or partial credit because the click is visible. An incrementality test asks how many comparable customers would have purchased without being eligible to see that campaign.

    This distinction matters most when a channel sits close to conversion. Branded Search can collect a large amount of credited revenue without necessarily creating an equally large amount of new demand. Performance Max can span several Google properties, making channel-by-channel paths harder to interpret. For eligible Search and Performance Max campaigns, user-based Conversion Lift creates an unexposed holdout and compares its behavior with that of users who can be exposed. The difference estimates incremental conversions.

    That does not make attribution useless. Attribution helps you reconcile customer journeys, diagnose tracking, allocate observed credit, and identify where conversions are being captured. It becomes misleading only when credited revenue is presented as revenue caused.

    Key takeaways

    • Use attribution to describe observed paths and allocate credit; use incrementality to make causal budget claims.
    • Connect search activity to realized revenue before debating which attribution model deserves the final click.
    • Keep unknown and unattributed revenue visible instead of forcing every conversion into a channel.
    • Run a controlled test when the causal answer could change a meaningful spending decision.
    • Report attributed and incremental results side by side. Never substitute one for the other.

    Build the revenue trail from the business outcome backward

    A continuous illuminated path connects search touchpoints, a conversion gateway, a customer record, a contract, a payment, and gold revenue tokens.

    A reliable measurement plan begins with the outcome your organization recognizes as revenue. It does not begin with the easiest event in GA4 or the conversion a media platform happens to optimize.

    1. Define the commercial outcome. For ecommerce, decide whether the recognized value is the completed order, collected payment, or revenue after refunds and cancellations. For lead generation, distinguish a submitted form, qualified lead, opportunity, and closed-won sale. Write down the event, its valuation method, and the point at which it becomes reportable revenue.
    2. Capture acquisition evidence. Store campaign parameters for links you control, along with the landing page, referrer when available, and timestamp. Add a self-reported discovery question when the buying journey can begin in an AI answer, an untagged result, or another environment that may not pass referral data. Keep the self-reported answer separate from the machine-captured source.
    3. Preserve the first and subsequent touches. Do not overwrite the original source every time a person returns. Retain the initial discovery evidence, the most recent measurable interaction, and relevant intermediate touches so that later analysis can distinguish demand creation from conversion capture.
    4. Carry a stable record into the revenue system. Use an approved internal transaction or lead identifier to connect analytics activity with the order platform or CRM. Avoid relying on names or email addresses as analytical keys when a privacy-safe internal identifier is available.
    5. Reconcile to realized value. Join the record to the value finance recognizes. Document how you treat duplicates, reopened opportunities, cancellations, refunds, repeat purchases, and records that never match.
    6. Measure coverage. Report the share of conversions with a known acquisition source, the share of revenue successfully matched to a transaction or CRM record, and the amount left unknown. A visible unknown bucket is more trustworthy than invented precision.

    AI search makes this discipline especially important. When an AI answer does not pass a referrer or tracked link, a later direct visit cannot reveal the earlier discovery by itself. Self-reported discovery can provide supporting evidence, but it should not silently replace behavioral data. Treat agreement between the two as corroboration and disagreement as a reason to inspect the journey.

    A workable AI-search revenue program puts GA4 setup, a five-level attribution ladder, and a board-ready scorecard in the same measurement system. Traffic collection without revenue reconciliation stops too early. A revenue total without source coverage hides too much.

    Use a five-level ladder to prevent signal inflation

    Search teams often mix visibility, visits, conversions, and revenue in one report even though each represents a different level of evidence. A five-level ladder keeps those claims separate.

    1. Visibility. Rankings, impressions, mentions, citations, or other forms of search presence show that your brand or content can be discovered. They do not establish that a person visited or bought.
    2. Visits. Sessions, referral data, campaign parameters, and landing-page activity show measurable traffic. They still do not prove that the visit produced a qualified outcome.
    3. Qualified outcomes. A business-defined action such as a qualified lead or valid purchase separates meaningful demand from raw activity. The definition must be stable enough to compare across channels.
    4. Attributed revenue. Transactions or closed-won revenue matched to observed search interactions show where measurable credit appears. The attribution model determines how that credit is distributed.
    5. Incremental value. A controlled comparison estimates the additional conversions or revenue caused by the marketing activity. This is the level needed for a causal return claim.

    Apply one rule throughout the report: a metric keeps the label of the highest level its evidence actually supports. Do not multiply AI-search visibility by an average conversion rate and present the result as measured revenue. That calculation may be useful as a forecast or scenario, but it remains modeled value and should be labeled accordingly.

    The same rule applies when you change attribution models. Moving from one credit-allocation method to another can redistribute attributed revenue among touchpoints. It cannot promote the result from attributed revenue to incremental value. A different model changes the accounting view, not the counterfactual.

    For each channel, ask what prevents the evidence from moving to the next level. Missing campaign parameters block clean visit classification. An analytics-to-CRM gap blocks revenue matching. A lack of controlled variation blocks causal inference. This turns the ladder into a measurement backlog rather than a decorative maturity score.

    Run an incrementality test when the answer can change spend

    Two matched miniature markets are separated into treatment and control groups, with a search-marketing beam and additional revenue tokens appearing only in the treatment group.

    Incrementality testing has a real cost. A holdout withholds campaign exposure from some users, and those users may generate fewer conversions. Use the method when the result can change a material decision: whether to retain, reduce, expand, or restructure a campaign.

    Self-serve Google Ads Conversion Lift has explicit eligibility gates for Search and Performance Max. An advertiser needs at least 1,000 observed conversions, excluding conversions that use supplementary data; participating campaigns need a minimum budget of $5,000; and the account needs at least one compatible conversion action. Availability can still vary by account, and alpha or beta campaign types may require assistance from a Google representative.

    Meeting those gates does not guarantee a decisive result. The selected action must occur frequently enough to be statistically useful. Purchases, leads, website activity, and other eligible actions can be evaluated, but the action you choose should correspond as closely as possible to the decision you need to make.

    1. Write the decision first. State which campaign and budget choice the result will inform. A test without a decision attached tends to become an interesting chart rather than an operating tool.
    2. Choose one primary outcome before launch. Define the eligible conversion action and how it maps to revenue. If the action is a lead rather than a sale, keep the test result in incremental leads until you have a defensible lead-to-revenue mapping.
    3. Set the campaign scope. Include the campaigns needed to answer the question and avoid mixing unrelated budget decisions into the same test.
    4. Accept the holdout tradeoff explicitly. A larger holdout can improve the comparison sample, but it also withholds ads from more users. Record who accepted that opportunity cost and why it is proportionate to the decision.
    5. Keep the plan stable. Avoid changing the primary outcome, campaign scope, or interpretation rule after seeing an early result. If operations force a material change, document it rather than presenting the test as untouched.
    6. Translate the output only as far as the evidence allows. Report incremental conversions directly. Convert them to incremental revenue only through an agreed value mapping, then connect that revenue to margin if the budget decision is based on profit.

    Keep two efficiency calculations distinct:

    • Attributed ROAS = attributed revenue divided by advertising spend.
    • Incremental ROAS = incremental revenue caused by the advertising divided by advertising spend.

    Attributed ROAS can be much higher than incremental ROAS when a campaign captures conversions that were likely to happen anyway. That does not automatically mean the campaign has no value. It means its budget case should be made with incremental economics rather than the full amount of credited revenue.

    If you are not eligible for the platform test, do not turn a before-and-after chart into causal proof. A carefully designed geographic or phased-rollout test may provide a comparison when you can maintain a credible control and consistent measurement. If you cannot create that comparison, report attributed performance and state plainly that the incremental effect has not been measured.

    A board-ready scorecard shows the decision, not just the dashboard

    Executives do not need every touchpoint row. They need to see what is observed, what is inferred, what is causal, how much of the revenue trail is covered, and what decision follows.

    Scorecard lineWhat to showQuestion it answersRequired label or caveat
    Attributed revenueRealized revenue allocated to measurable search interactionsWhere did observed credit appear?Name the attribution method and reporting scope
    Incremental outcomeAdditional conversions or revenue estimated by a valid control comparisonWhat did the campaign cause?Show the tested campaigns, primary outcome, and uncertainty provided by the test
    Measurement coverageSource-known conversions, revenue-matched records, and unknown revenueHow complete is the evidence chain?Do not redistribute the unknown bucket
    EconomicsSpend, attributed ROAS, incremental ROAS when available, and the finance-approved value basisIs the activity economically useful?Keep attributed and incremental returns separate
    DecisionScale, retain, reduce, retest, or repair measurementWhat changes because of this result?Name the owner and the condition that would reverse the decision

    Read the combinations, not just the largest number:

    • High attributed revenue and credible positive lift: the channel is receiving credit and creating additional outcomes. Evaluate whether incremental economics support more investment.
    • High attributed revenue and weak or uncertain lift: the channel may be capturing existing demand. Do not use the credited total as proof that the same revenue would vanish with the spend.
    • Low attributed revenue and poor measurement coverage: the result is inconclusive. Repair source capture and revenue matching before treating the channel as ineffective.
    • Attribution changes sharply when the model changes, while experimental lift remains stable: the disagreement is primarily about credit allocation, not whether the campaign caused additional outcomes.
    • No credible control comparison: keep the causal field marked as not measured. A blank causal result is more useful than a confident answer produced by the wrong method.

    In your next reporting cycle, add two lines to every search performance review: “What revenue can we trace?” and “What revenue did we cause?” If the second answer is unavailable, do not replace it with modeled certainty. Mark it as not yet measured, identify the live budget decision it affects, and plan the smallest credible control test around that decision. This prevents credited revenue from being mistaken for created demand.

    References


  • Google Ads AI Max Reporting and Direct Offers: A Control Plan

    Google Ads AI Max Reporting and Direct Offers: A Control Plan

    When Google Ads makes automation easier to deploy, your reporting has to get stricter. AI Max can expand targeting and apply brand or location-related controls, while Direct Offers can put a context-selected incentive in front of a shopper inside AI Mode. Those capabilities can help, but they also blend media optimization with commercial policy.

    Your job is to answer two separate questions: what was the automation allowed to do, and did it create profitable demand that would not otherwise have existed? A campaign can improve on an in-platform metric while quietly reaching a different audience, relaxing a targeting boundary, or discounting orders you could have won at full price. The control plan below is designed to expose those differences before you scale them.

    Start with permission reporting, not performance reporting

    Google Ads is adding AI Max reporting columns for Locations of interest, Optimized targeting and Brand inclusions. Add them to the campaign-level view before investigating a performance change. They tell you which controls are present, which is the first layer of any useful audit.

    Think of these fields as permission reporting. They describe what a campaign is configured to use; they do not prove that a setting caused an outcome. A conversion increase beside an enabled setting is a lead for investigation, not a causal conclusion.

    Reporting columnWhat it makes visibleWhat you should check
    Locations of interestWhich campaigns use location-of-interest settingsWhether campaigns being compared use the same geographic-intent configuration
    Optimized targetingWhere automated audience expansion is enabledWhether broader reach is intentional and whether it coincides with a change in traffic quality
    Brand inclusionsWhere brand inclusion settings are appliedWhether each campaign has the brand scope your strategy requires

    The columns are still rolling out and may not be visible in every account. If you cannot find one, do not treat its absence from the interface as evidence that the underlying behavior is disabled. Confirm the campaign settings directly until the reporting fields reach your account.

    Once the columns are available, build a repeatable campaign view:

    1. Add all three AI Max columns to the same view as the outcome metrics your team actually uses.
    2. Keep campaign identity, status and commercial objective visible so campaigns with different jobs are not compared as if they were interchangeable.
    3. Save a dated export or configuration record. That gives you a snapshot of the permissions in place when results were measured.
    4. Flag unexpected combinations, such as an expansion setting enabled on one campaign but not on otherwise comparable campaigns.
    5. Resolve configuration mistakes before interpreting performance. Analysis built on unintended settings only explains the wrong experiment more precisely.

    This view should let you scan from configuration to outcome in one row. If an analyst has to open every campaign individually to discover the relevant settings, setup differences are too easy to miss and too slow to audit.

    Compare configuration cohorts before explaining a performance gap

    Three parallel campaign pathways pass through different permission controls before reaching comparable shopper groups.

    Campaign averages become misleading when they combine different automation permissions. Create configuration cohorts instead. One cohort might contain campaigns with Optimized targeting enabled; another might contain campaigns without it. You can then subdivide them by Locations of interest and Brand inclusions when those distinctions matter to the question.

    Do not automatically call one cohort a control group. A credible comparison also needs a similar commercial objective, market, offer, audience opportunity and measurement setup. A branded campaign and a prospecting campaign remain different even if their three AI Max columns match exactly.

    Use this sequence when a campaign begins outperforming or underperforming its peers:

    1. Define the business symptom. State whether the issue is lead quality, sales volume, acquisition cost, conversion value or profit. Avoid the vague diagnosis that performance changed.
    2. Map the permission state. Record the values of Locations of interest, Optimized targeting and Brand inclusions for the affected campaign and its intended comparators.
    3. Separate mismatched campaigns. Compare like configurations first. If the difference disappears, the blended average was hiding a setup distinction.
    4. Check timing. Place the first visible performance change beside the dated configuration record and other campaign changes. A setting that was already stable before the change is a weaker explanation than one altered at the same time.
    5. Change one decision at a time where practical. If targeting, bidding, creative and promotion all change together, you may improve the result but lose the ability to explain why.
    6. Write down the interpretation. Record the setting, expected mechanism, primary metric and condition that would disprove your explanation.

    The last step is important. A statement such as “Optimized targeting improved the campaign” is too broad to test. A useful interpretation is narrower: enabling expansion was followed by more qualified conversions in comparable campaigns while cost and downstream quality stayed within the team’s accepted limits. That claim can be monitored and challenged.

    Also look for configuration drift. Two campaigns that were launched from the same template can stop being comparable after later edits. The new columns make that drift easier to spot, but only if somebody owns the exception review. Assign that check to a named role and run it on the same cadence as your normal campaign review.

    Build Direct Offers as governed promotions

    Direct Offers add a second kind of automation: Google can decide not only when an offer is relevant, but also which incentive to present. The beta-labeled asset can be created at the account or campaign level, and it is limited to campaigns using AI Max or text customization.

    The setup asks for an internal offer name, final URL and short description. Google AI uses the description to judge relevance and can generate the customer-facing offer text. If you provide multiple incentives, the system can select among them using the shopper’s behavior and context. That makes the description and incentive set part of your targeting logic, not just administrative copy.

    Start with a campaign-level pilot unless you have a clear reason to expose the offer across the account. A campaign-level asset narrows the commercial blast radius and makes it easier to connect claims and redemptions to a defined test population.

    Use the following launch checklist:

    • Name the offer for analysis. Include the campaign or product scope, incentive and intended run period in the internal name. Someone reviewing an export later should not have to decode Offer 1.
    • Send traffic to the exact destination. The final URL should land where the promoted product, service or eligibility conditions can be understood and the incentive can actually be redeemed.
    • Write the description as an AI instruction. State what is being offered and the context in which it is relevant. Do not rely on clever promotional language to carry eligibility rules.
    • Begin with one incentive. Multiple incentives are supported, but allowing AI to choose among them immediately makes the first result harder to interpret. Establish a baseline before testing an incentive set.
    • Use a dedicated code batch. Single-use promotional codes can be uploaded by CSV. Keep the pilot’s codes separate so a redemption can be reconciled to the offer rather than mixed with codes from email, affiliates or customer support.
    • Set the contractual boundaries. Add the applicable terms and conditions, terms URL, start date and end date. Make sure the landing page and checkout enforce the same promise the shopper sees.
    • Cap the exposure. Direct Offers support daily limits based on total offer value or number of claims. Select the type that controls your real constraint, then set it before activation.

    A claim-count limit is useful when code inventory or fulfillment capacity is scarce. A total-value limit gives you a closer control on financial exposure, especially when incentives have different values. Neither replaces a complete promotional budget because a claim is not necessarily a redemption and a redemption is not necessarily an incremental sale.

    The shopper can see an eligible promotion beneath a sponsored result in AI Mode as a Claim one-time code option. Opening it reveals the offer details and code, along with a button to visit the advertiser’s website. Review the entire handoff from that promise to the landing page and checkout. If the displayed terms and the site experience disagree, pause the offer rather than asking support staff to repair the mismatch after purchase.

    Promotional terms can also create financial and legal exposure. If eligibility, expiry, exclusions or consumer rights require formal review in your market, put the Direct Offer through the same legal and operational approval process as any other public promotion. AI-selected delivery does not make the underlying promise less binding.

    Measure discount economics beyond claims and conversions

    A promotional tag, shopping basket, cost layers, approval gate, and branching purchase paths form a visual model of discount economics.

    A Direct Offer has at least six commercially distinct events: the offer is shown, its details are opened, a code is claimed, the shopper reaches the site, the code is redeemed and an order is completed. Do not collapse that chain into a single conversion number. Each transition answers a different question.

    DecisionMeasurementWhat a problem can mean
    Is the offer attracting attention?Claims or detail opens relative to observable offer exposureThe incentive, relevance decision or presentation is not compelling enough to prompt action
    Can shoppers use it?Redeemed codes relative to claimed codesThe site journey, eligibility rules, expiry or checkout process is creating friction
    Does it produce completed business?Completed orders and revenue tied to redeemed codesClaims are not progressing to purchases, or order tracking is incomplete
    Is the promotion affordable?Realized discount cost and contribution after the discountAdditional sales may still be eroding margin
    Is the result incremental?Difference versus a credible unoffered comparisonThe offer may be subsidizing orders that would have occurred at full price

    Use the denominator you can actually observe, and label it precisely. Claims divided by offer views is not the same metric as claims divided by sponsored-result impressions. If a required exposure event is not available in your account, report the narrower metric rather than manufacturing a rate from incompatible events.

    Reconcile the advertising record with your commerce or lead system. The promotional code is the bridge: it lets you distinguish a code that was claimed from one that was redeemed, and a redemption from an order that remained valid after returns, cancellations or lead qualification. Do not assume the Google Ads interface contains every downstream business outcome you need.

    Track the realized discount separately from media spend. A promotion can improve conversion efficiency inside an ad platform while the associated margin reduction appears only in the order system. Your decision table should therefore place ad cost, discount cost and contribution in the same review, even if the data originates in different systems.

    Redemption alone cannot establish incrementality. Some shoppers who use a code would have purchased without one. The cleanest test is a randomized unoffered group when your setup supports it. If it does not, use the closest comparable campaign or audience cohort you can maintain, keep other meaningful changes stable and document the limitations. A simple before-and-after comparison is weaker because seasonality, demand shifts and other campaign edits can move at the same time.

    Set decision rules before the pilot starts:

    • The maximum daily offer value or claim count you will permit.
    • The minimum contribution the promoted orders must retain.
    • The comparison you will use to judge incremental orders or leads.
    • The code redemption and completed-order events that must reconcile.
    • The conditions that trigger a pause, such as exhausted code inventory, a checkout failure, incorrect terms or unacceptable margin.
    • The evidence required before you add more incentives or move from campaign-level to account-level deployment.

    Read the failure pattern, not just the final total. Many claims with few redemptions points toward a broken or confusing handoff. Many redemptions without incremental growth points toward cannibalization. Few claims followed by strong purchase quality may indicate narrow relevance or limited exposure; it does not automatically justify a larger discount. Each pattern calls for a different response.

    Key takeaways

    • The new AI Max columns expose campaign permissions; they do not prove why performance changed.
    • Compare campaigns in configuration cohorts before attributing a result to Locations of interest, Optimized targeting or Brand inclusions.
    • Start a Direct Offer at campaign level with one incentive when you need a test that is easier to interpret and contain.
    • Treat the offer description as an input to AI relevance and generated copy, not as a private note.
    • Use claim limits for operational scarcity and value limits for financial exposure, then track the full promotional budget outside the asset.
    • Judge success through redemptions, completed outcomes, realized discount cost, contribution and incrementality – not claim volume alone.

    When the new columns appear in your account, export the current permission state before changing anything. Then choose one eligible campaign, document its baseline, connect a dedicated code batch to completed-order data and launch only with a hard exposure limit. That gives Google room to optimize while preserving your ability to explain what happened and decide whether it deserves to scale.

    References

  • AI Search Investment: Attribution Across the Buyer Journey

    AI Search Investment: Attribution Across the Buyer Journey

    You have enough evidence to test AI search, but probably not enough to promise a clean last-click return. A recommendation may create the shortlist while Google, YouTube, a retailer, or a direct visit records the next step.

    The decision is not whether AI deserves a blind budget. It is how much to invest, which customer handoff you expect to improve, and what evidence will unlock the next tranche. Set those conditions before the work begins, and attribution becomes a decision system instead of an argument at the end of the quarter.

    AI search influences a journey; it rarely owns the whole journey

    An AI answer can introduce a brand, narrow a longlist, explain a product, or reduce perceived risk. It may produce a click, but it does not have to. The person could remember the name, search for it later, watch a demonstration, compare alternatives, and then convert through a different channel.

    A last-click report will credit the final visit. A first-touch model may over-credit the initial discovery. A screenshot showing that an AI system cited your page proves exposure, but not commercial intent. None of these views is useless; each answers a different question.

    Cross-platform behavior is already visible outside AI search. In a survey of 511 beauty consumers, whose average age was 47, 43% named Google as their first stop, while Instagram accounted for 11.9%, YouTube 11.2%, TikTok 10.6%, and AI tools 9.8%. When respondents discovered a beauty product on TikTok, 72% searched for it on Google and only 7% bought directly through TikTok at that moment. When TikTok or YouTube did not provide the answer, 61% fell back to Google.

    Those percentages belong to one consumer survey in one category. Do not paste them into a B2B forecast or treat them as universal market shares. Use the behavior they expose: discovery, validation, evaluation, and transaction can happen on different platforms, even within one purchase.

    • Discovery answers: What is this, and which options should enter my consideration set?
    • Validation answers: Is this claim credible, safe, relevant, and supported by enough detail?
    • Evaluation answers: How does this option compare with alternatives for my situation?
    • Transaction answers: What does it cost, what happens next, and where can I buy, subscribe, or speak to someone?

    Your investment case should name the journey job you expect AI search to perform. If the objective is discovery, evaluate qualified visibility and subsequent demand. If it is evaluation, inspect whether comparison and proof content move people toward a commercial action. If it is transaction, require stronger evidence from referrals, leads, pipeline, or revenue.

    Map the handoffs before you decide what to fund

    Small figures pass a glowing signal between an AI orb, a search panel, a video display, a storefront, and a purchase pedestal connected by branching paths.

    Begin with the questions that matter to the business, not a list of AI platforms. A useful journey map can live in one worksheet, provided every row connects a customer question to an intended next step.

    1. Choose a commercially important topic cluster. Include problem questions, option questions, trust questions, comparisons, and action-oriented queries such as pricing, availability, buying, or booking.
    2. Record where customers are likely to ask each question: an AI assistant, Google, social search, YouTube, a marketplace, a review site, or your own website. Validate this with analytics, customer interviews, sales-call notes, and on-site search data where available.
    3. Write down the job of each touchpoint. One may create awareness, another may provide proof, and another may capture the transaction.
    4. Name the destination that should receive the next visit. It might be an evidence page, comparison, product page, calculator, store locator, pricing page, or lead form.
    5. Define one observable signal for the handoff and one likely failure mode. A referral session is observable; a remembered brand mention may not be. A citation to an irrelevant page is visibility with a broken destination.

    Format should follow the job. In the beauty survey, TikTok searches were most often based on a product name, a skin or hair concern, a brand name, or a full question; only 7% searched by ingredient. YouTube creators also received a higher “very trustworthy” rating than TikTok creators, 14.1% versus 8.6%. That does not establish a universal hierarchy of platforms. It shows why the same buyer may use a short demonstration for discovery, a longer video for reassurance, and a detailed page for ingredient or product validation.

    For every important query family, keep these fields together:

    • Customer question and journey stage
    • Platform or surface where the question is asked
    • Brand answer, content asset, or proof required
    • Page or property that should receive the next visit
    • Expected customer action
    • Observable analytics or CRM signal
    • Owner responsible for repairing the handoff

    Then test the relay manually. Can someone move from an AI recommendation to the exact evidence needed to validate it? Does the cited or discovered page match the question? Is the brand, product, author, and organization information consistent across the relevant properties? Does the destination offer a sensible next action?

    Structured data can help machines interpret entities and page content when the markup truthfully represents what a visitor can see. It is not a guarantee of an AI citation or recommendation. Fund schema implementation as part of a clear content and entity system, not as a substitute for useful evidence.

    Use an attribution ladder instead of forcing one perfect number

    The strongest measurement system separates what you observed from what you inferred. A practical architecture combines GA4, a five-level attribution ladder, and a board-ready scorecard. Each level supports a different decision, and no level should be presented as stronger evidence than it is.

    Evidence levelWhat to measureWhat it can supportWhat it cannot prove
    1. VisibilityPresence, mentions, citations, linked citations, and answer accuracy across a defined prompt setWhether the brand is eligible and visible for the questions you choseThat anyone visited, considered, or bought
    2. Referred demandSessions, landing pages, and clicks from identifiable AI referrers when referral data survivesThat a measurable AI surface sent a visitInfluence that resulted in a later direct or search visit
    3. On-site intentCommercial page views and key events such as account creation, a pricing action, a tool completion, a store-locator use, or a qualified form submissionWhether referred visitors performed meaningful actionsClosed revenue or causality
    4. Commercial outcomesQualified leads, opportunities, purchases, revenue, and repeat value connected to observable journeys or declared influenceHow much measurable business value is associated with the programAll invisible assists or the value that would have occurred anyway
    5. Incremental effectPredefined holdouts, staggered rollouts, or credible comparisons between exposed and unexposed topics, markets, or periodsWhether the intervention probably created additional valuePerfect certainty when other variables changed at the same time

    Configure analytics so the ladder remains auditable. Preserve the original source, medium, landing page, and campaign fields. You can create a reporting group for known AI referrers, but keep the underlying values because referrer hosts and product behavior can change. Use UTM parameters on links you control; do not pretend you can add them to third-party citations you do not control.

    Mark key events that reflect actual business progress rather than convenient activity. A page view is not equivalent to a qualified enquiry. If your buying cycle continues offline, connect consent-appropriate analytics and CRM records so you can distinguish a submitted lead from an accepted opportunity and a closed sale.

    Add declared influence as a separate evidence stream. A “How did you hear about us?” field can include AI assistants or AI search, plus a free-text option. Sales teams can record unsolicited mentions during qualification. These responses are useful precisely because referral data can disappear, but self-reported memory is imperfect. Label it as declared influence and never overwrite observed acquisition with it.

    Use explicit confidence labels in reporting:

    • Observed: a visible referral, event, or transaction was recorded directly.
    • Connected: analytics and CRM identifiers linked the visit to a later commercial stage.
    • Declared: the customer named an AI system or answer as an influence.
    • Inferred: changes in visibility and demand moved together, but the individual journey was not connected.
    • Incremental: a predefined comparison provides evidence that the program caused additional results.

    Keep attributed revenue and influenced revenue in separate columns. The same opportunity may appear in both, so adding them can double-count the deal. Your board scorecard should show investment, coverage of priority questions, visibility, referred demand, commercial actions, qualified pipeline, revenue, confidence level, and the next decision. Include a baseline and a target; a growing cumulative total without either is difficult to interpret.

    Visibility tracking also needs controls. Use a stable set of commercially relevant prompts, record the model or surface, market, language, date, and test conditions, and repeat the process consistently. A single generated answer is an observation, not a durable ranking.

    Release the budget through gates, not a long leap of faith

    Metallic tokens move through a sequence of transparent gates beside visual evidence objects, with additional tokens waiting at each stage.

    GEO and AEO pricing spans radically different scopes. A vendor-compiled dataset covering 1,146 quotes from 214 agencies between July 6 and October 2, 2026 put the median monthly retainer at $6,850. Its reported tier medians ranged from $2,950 for Starter work to $7,400 for Growth, $14,600 for Advanced, and $31,500 for Enterprise. Sixty-eight percent of agencies primarily used a custom or tiered monthly retainer.

    Treat those figures as directional negotiating context, not a universal price sheet. The dataset was assembled and published by an agency, and proposals differ by market coverage, senior staffing, digital PR, technical work, content volume, and commitment length. Its $6,850 GEO/AEO median was 45% above the $4,740 traditional SEO median, so a buyer should require a clear explanation of what the premium adds.

    Before signing, ask the provider or internal program owner to specify:

    • The countries, languages, products, audiences, and query families included
    • The baseline that will be captured before optimization begins
    • How mentions, citations, linked citations, accuracy, traffic, leads, and revenue are defined
    • Which technical, schema, content, analytics, authority-building, and digital PR activities are included
    • Who owns the accounts, prompt sets, dashboards, content, structured data, and historical exports
    • What constitutes a qualified lead or opportunity
    • How duplicated, declared, and inferred revenue will be handled
    • The minimum term, review points, exit conditions, and work that remains usable after termination

    A three-stage, 90-day pilot can create decision evidence without pretending that every buying cycle will produce revenue in 90 days.

    1. Days 1-30: establish the prompt, visibility, traffic, conversion, and pipeline baselines. Repair analytics and CRM gaps. Map one or two high-value customer journeys and identify their weakest handoffs.
    2. Days 31-60: improve a deliberately limited set of pages and supporting assets. Correct factual ambiguity, strengthen evidence, connect related entities, implement accurate structured data where appropriate, and make the next action unmistakable.
    3. Days 61-90: repeat the visibility tests under consistent conditions, inspect referral and declared-influence data, review commercial events and pipeline, and classify the result as scale, repair, continue observing, or stop.

    Negotiate this review even when the commercial agreement runs longer. A six- or twelve-month commitment without definitions, data ownership, and intermediate decision gates creates avoidable financial exposure.

    Use the pattern of results to decide what happens next. If priority visibility and qualified commercial signals both improve, expand carefully. If visibility improves but the next step does not, repair the handoff or destination. If referred visits rise but meaningful actions do not, investigate intent mismatch, page experience, offer clarity, and conversion friction. If a provider ships deliverables but cannot show movement at any agreed evidence level, do not renew solely on citation screenshots.

    Key takeaways

    • Budget AI search for a defined journey job: discovery, validation, evaluation, or transaction.
    • Map the handoff between platforms before producing more content. A visible answer with no relevant destination is an incomplete investment.
    • Report visibility, referred demand, on-site intent, commercial outcomes, and incrementality as separate evidence levels.
    • Keep attributed, declared, and inferred influence distinct so stakeholders can see both value and uncertainty.
    • Use market pricing as directional context, then tie your actual spend to scope, ownership, baselines, and pre-agreed decision gates.

    Start with one commercially important topic cluster this week. Map its discovery, validation, destination, and conversion steps; instrument the signals you can observe; and fund the smallest program capable of moving them. At the review point, let the evidence tell you whether to scale the work, repair the relay, or redirect the budget.

    References

  • Human Accountability in AI-Assisted Marketing Decisions

    Human Accountability in AI-Assisted Marketing Decisions

    An AI assistant has given your team a confident plan: publish more pages, change the message, and redirect resources toward the tactics it predicts will work. The output is polished enough to put into a deck. The hard question is whether anyone can explain why it fits your customers, constraints, and sales process – and who will answer for the result.

    Human accountability does not mean doing every marketing task manually. It means a qualified person owns the decision, verifies the supporting evidence, controls what gets released, and follows the outcome. That operating discipline lets you use AI for speed without quietly allowing it to become the decision-maker.

    Draw the line between AI assistance and decision authority

    AI can propose options, organize information, expose questions, transform approved material, and accelerate production. A person should retain authority over positioning, priorities, investment, customer promises, and the criteria used to judge success. Those decisions depend on context a generic model response may not contain. A recommendation can sound sensible while omitting something as basic as how customers buy.

    Use consequences, not content format, to decide how much oversight is required. A short tagline can be consequential if it changes the promise your brand makes. A long set of ad variations can be relatively contained if every option stays within an approved offer, audience, and call to action.

    • Execution support: AI formats approved information, groups data, creates variants, or produces a first-pass outline. The task owner checks accuracy and adherence to the brief.
    • Recommendation support: AI diagnoses a problem, ranks opportunities, or proposes a campaign change. A subject-matter owner inspects the evidence, assumptions, business fit, and test design before acting.
    • Consequential decisions: The work changes positioning, budget, material claims, customer experience, or a large part of the website. An experienced marketer explicitly approves, modifies, or rejects the recommendation.

    Accountability includes more than final approval. The human owner must define the problem, set the constraints, decide what evidence counts, and remain responsible after launch. If the only explanation for a choice is that AI recommended it, no accountable marketing decision has actually been made.

    Assign AI work only to people who can evaluate it

    Before assigning a task to AI, ask whether the designated reviewer could evaluate the result without the tool. They do not need to produce it at the same speed. They do need enough knowledge to detect a missing assumption, an unsupported claim, an unsuitable tactic, or a recommendation that conflicts with how the business operates. Access to a tool is not a substitute for understanding the work it performs.

    Consider a recommendation to increase website traffic. A competent reviewer will ask who currently visits, which visitors are relevant, what they do after arriving, and whether the offer is clear. More traffic will not repair a weak explanation, attract the right buyer automatically, or make an unclear next step easier to find.

    The same test applies when AI proposes a large SEO or GEO content program. The reviewer must be able to distinguish a genuine information gap from a request to produce more pages. If nobody can explain which audience needs each page, what decision it helps them make, and why existing content cannot do the job, the team is not ready to approve the plan.

    Give every AI assignment a review brief before prompting. At minimum, record:

    • The business problem the work is meant to solve.
    • The intended audience and the relevant stage of its buying journey.
    • The approved facts, offer, positioning, and operational constraints.
    • The outcome that would count as an improvement.
    • The claims, promises, or changes that are outside the assignment.
    • The person qualified to review and release the work.

    If you cannot name a qualified reviewer, narrow the assignment, obtain the missing expertise, or keep the work out of production. A more elaborate prompt does not repair a missing accountability structure.

    Put every AI recommendation through a human review gate

    Hands verify AI-assisted campaign materials against research before one item passes through a physical review gate.

    A consistent gate prevents fluent output from slipping directly into campaigns, content, or site changes. Use the following sequence for recommendations that affect performance, spend, public claims, or customer-facing experiences.

    1. Name the owner before reviewing the answer. Identify the person who can approve, modify, or reject the recommendation. The AI system is a contributor, not the owner.
    2. Restate the business problem. Write it without mentioning AI or the proposed tactic. There is an important difference between users not understanding a service and a perceived need to publish more content. The first is a problem; the second is only one possible response.
    3. Expose the missing context. Check the target customer, sales cycle, available budget, team capacity, current performance, brand position, and delivery constraints. A valid tactic can still be wrong for the organization expected to carry it out.
    4. Inspect the evidence. Ask AI to identify the basis for its recommendation and disclose important assumptions. Open the cited material and determine whether it supports the specific advice. A citation must be read and checked for relevance; the presence of a link is not proof.
    5. Check operational truth. Reject copy that promises something the business cannot deliver. Confirm product facts, audience fit, availability, approval requirements, and any regulated or contractual language with the appropriate human owner.
    6. Convert the recommendation into a bounded test. State the expected effect, the measurement, the review point, and the smallest reversible scope that can produce useful evidence. Do not make a site-wide change when a limited set of pages can test the same premise.
    7. Record the decision and follow-up. Note whether the recommendation was approved, modified, or rejected; why that choice was made; what changed; and who will review the result. This keeps later analysis from turning into guesswork.

    Timing must reflect the actual buying process. If a service typically takes six months to purchase, judging a campaign after several weeks only by closed sales would ignore how that business wins customers. Early evaluation should examine the relevant conversations and buying activity while preserving a defined point at which the investment will be reconsidered. Patience is not permission to spend indefinitely.

    A compact decision record

    The record can live beside the campaign brief, content ticket, or website change log. A short, specific entry in each field is more useful than a long narrative nobody will revisit.

    FieldWhat to record
    OwnerThe person accountable for approval and follow-up.
    Business problemThe customer or performance problem, stated independently of the proposed tactic.
    AI contributionWhat the system generated, analyzed, summarized, or recommended.
    Context and assumptionsThe audience, sales process, resources, constraints, and uncertain premises that affect the decision.
    Evidence checkedThe material a human opened and reviewed, plus any gaps that remain.
    DecisionApproved, modified, or rejected, with a concise reason.
    Test and measureThe change being tested, expected effect, metric, and bounded scope.
    Review pointWhen the result will be assessed and who will assess it.

    Match the control to the marketing assignment

    Three marketing assignments receive progressively stronger human oversight as their potential risk increases.

    Not every task needs the same process. The useful question is what the model can contribute safely and what judgment must remain with a person who understands the subject and the consequences.

    AssignmentUseful AI roleRequired human release check
    Ad and tagline variationsGenerate alternatives within an approved offer, audience, and action.Reject inaccurate claims, off-brand language, and promises the business cannot deliver.
    Expert or thought-leadership contentDevelop questions, organize an outline, expose gaps, or improve readability.A subject-matter reviewer owns the reasoning, factual accuracy, citations, usefulness, and voice.
    SEO or GEO content planningGroup themes, propose hypotheses, and identify possible information gaps.Confirm a real audience need, a distinct purpose for each page, and a connection to the business problem.
    JSON-LD and schema generationDraft markup from approved page information and a defined entity model.Confirm that every entity, relationship, and claim matches the visible content and the real business, then validate the markup before deployment.
    Positioning, priorities, and budgetOrganize evidence, surface assumptions, and compare scenarios.An experienced marketer makes and signs off on the decision after considering customer knowledge, resources, sales process, and consequences.

    Generation and approval should be separate acts even when the same person performs them. First ask the model for possibilities. Then review those possibilities against the brief and evidence. You do not owe an AI-generated option a place in the final work merely because it is fluent.

    Substantive content needs more than a readability pass. An editor can improve a sentence without knowing whether its conclusion is true, distinctive, or useful. Someone familiar with the subject must evaluate the substance and stand behind what is published.

    Search recommendations deserve the same discipline because a weak premise can create work across an entire site. When AI proposes more pages, require an intended reader, a missing question, a reason the existing site cannot answer it, and a useful next step. Investigate whether relevant visitors already lack a clear service explanation or path to contact before committing the team to a larger publishing schedule.

    For structured data, technical validity is only one part of approval. Perfectly formatted markup can still describe the wrong entity or repeat an unsupported claim. The accountable reviewer must check semantic truth as well as syntax. That is the difference between automating production and automating judgment.

    Key takeaways

    • Let AI generate, organize, and challenge ideas, but give a named person authority over consequential marketing decisions.
    • Do not assign AI work unless someone with relevant knowledge can evaluate its substance, not merely its tone or formatting.
    • Treat model confidence as presentation, not evidence. Check cited material, assumptions, and business fit yourself.
    • Test consequential recommendations within the smallest useful, reversible scope before applying them across campaigns or websites.
    • Keep a decision record that states the problem, owner, evidence, choice, change, measurement, and review point.
    • Judge performance against the real sales cycle and customer journey, not the speed with which AI produced its recommendation.

    For your next AI-assisted task, start before the prompt. Name the owner, write the business problem, define the release check, and decide how the result will be tested. Then let AI work inside those boundaries. If your team cannot fill in those fields, pause the assignment: the missing input is not another prompt but accountable human judgment.

    References


  • How to Choose an Enterprise eCommerce Development Partner

    How to Choose an Enterprise eCommerce Development Partner

    You are not choosing an agency to build a nicer storefront. You are choosing the team that will connect pricing, inventory, customer, product, order, payment, and fulfilment systems without turning your own staff into the missing systems integrator.

    That distinction makes the shortlist much easier to manage. Start with the systems and workflows that can break the programme, require evidence from comparable implementations, and evaluate the people who will actually do the work. Platform badges and impressive client logos come later.

    Start with the system most likely to break the programme

    The commerce platform is the visible part of an enterprise implementation, but it is rarely the only system of record. Your ERP may control prices, credit limits, inventory, invoices, and account terms. A PIM may own product attributes and media. An OMS may decide where an order is fulfilled. The storefront has to present a coherent customer experience while those systems exchange data reliably.

    Among seven leading providers assessed in 2026, five documented at least one specific ERP integration. ERP integration depth and B2B functionality were the clearest points of separation, even though most of the firms covered several major commerce platforms. If your programme is ERP-connected, match the agency to the ERP family and workflow before giving much weight to its general platform credentials.

    The distinction is practical. Atwix has documented connectors for industrial distribution systems including Prophet 21, Infor, Kodaris, and Expertek. Elogic Commerce has documented work involving SAP S/4HANA, Microsoft Dynamics 365, NetSuite, and Visma Business. Scandiweb shows considerable Adobe Commerce scale, but its documented position is stronger for high-volume platform delivery than for industrial B2B and ERP work. All three can be credible enterprise firms while fitting very different system landscapes.

    Draw the system map before you issue the RFP

    Create a one-page map covering every data flow that matters to launch. It does not need to be a finished architecture diagram. It does need to show enough detail to stop vendors from answering a precise integration problem with a generic capability claim.

    • Business object: products, inventory, prices, customer accounts, credit limits, quotes, orders, returns, shipments, invoices, and tax data.
    • System of record: the application allowed to create or change each object.
    • Direction: which system publishes the data and which systems consume it.
    • Timing: whether the workflow is synchronous, event-driven, scheduled, or manually triggered.
    • Failure behaviour: what the customer sees when a dependency is delayed or unavailable.
    • Operational owner: the team responsible for detecting, triaging, correcting, and replaying a failed transaction.
    • Launch dependency: whether the flow is mandatory for go-live or can be delivered later without creating duplicate work.

    Ask each agency to classify every flow as native platform functionality, configuration, an existing connector, new custom development, or a manual process. The dangerous answer is simply supported. It hides whether the capability already exists, requires modification, or has only appeared in a sales presentation.

    For a B2B programme, map workflows as well as systems. Company accounts, customer-specific catalogues and prices, approval chains, quote management, PunchOut, EDI, and credit terms can change the entire design. A team with strong direct-to-consumer experience does not automatically have the data model or operational knowledge to implement them.

    Score fit instead of counting logos and partner badges

    Platform partnerships matter, but they stop differentiating firms once every serious candidate has them. In one Adobe Commerce field, five of the six qualifying agencies held Gold Solution Partner status. The stronger distinctions were contribution history, review volume, integration evidence, and relevant B2B case work.

    If you need a neutral starting structure, a 100-point provider model distributes attention as follows. The weights are not universal requirements. They are a prompt to make your own priorities explicit before a persuasive pitch changes them.

    CriterionStarting weightEvidence worth requesting
    Platform expertise20%Credentials, contribution history, upgrade experience, and work on the edition and architecture you will use
    ERP integration17%Comparable production integrations, data-flow designs, failure handling, and references involving your ERP family
    Recognition and delivery evidence15%Named implementations, quantified outcomes, verified reviews, and clearly defined agency scope
    Migration and replatforming12%Source-to-target migrations, data reconciliation, cutover planning, rollback design, and post-launch validation
    B2B feature depth10%Working examples of company accounts, negotiated pricing, approvals, quotes, PunchOut, EDI, and portals
    Custom development and proprietary IP10%Architecture, maintenance obligations, portability, licensing terms, documentation, and exit options
    Enterprise scale and complexity8%Comparable traffic, catalogue, order, brand, market, language, currency, and organisational complexity
    Ongoing management and support8%Service levels, coverage hours, escalation paths, named roles, release management, and incident reporting

    Change the model once, before reviewing proposals. If an integration, B2B workflow, security requirement, region, or support window is mandatory, make it a pass-or-fail gate rather than one more weighted row. A vendor should not be able to compensate for missing a launch-critical capability by scoring highly on design, awards, or presentation quality.

    For the remaining criteria, label the evidence consistently:

    • Unproven: no relevant evidence was supplied.
    • Claimed: the proposal asserts the capability but gives no named implementation or artefact.
    • Proven: a production example, client reference, or inspectable deliverable supports the claim.
    • Matched: the evidence involves a similar business model, platform, integration family, scale, and delivery responsibility.

    This prevents unlike signals from being treated as interchangeable. Atwix’s sustained position as the leading Magento Open Source contributor from 2018 through 2025 signals unusual codebase familiarity. Scandiweb’s 894 or more Adobe certifications signal broad organisational coverage. Elogic Commerce’s 5.0 rating across 64 verified Clutch reviews signals consistency across a substantial review set. Each is useful, but none proves that the proposed delivery team has implemented your combination of workflows and systems.

    Review averages need their denominator for the same reason. Within the Adobe Commerce field, a 5.0 rating across 64 verified reviews carried more evidence than the same rating across 15. Read the recurring strengths and criticisms, then test them during discovery. A high company-wide score cannot tell you whether the architect assigned to your account communicates clearly or whether the proposed onboarding process fits your team.

    Verify current certifications, partner status, and named personnel directly during procurement. These details can change, and an agency-level credential may belong to someone who will not work on your programme.

    Make every finalist prove the hard parts before selection

    A client and agency team test a prototype order flow linking product, pricing, payment, inventory, fulfilment, and delivery modules.

    A conventional RFP makes it easy to return polished answers. A better process asks each finalist for the same compact proof package. You can then compare the substance without rewarding the agency with the largest proposal team.

    • A closest-match implementation: require the platform, ERP or PIM, business model, agency scope, launch status, and client reference. A famous retailer on an unrelated stack is not a match.
    • An interface design: select one critical flow and request the objects, endpoints, direction, authentication, validation, expected timing, retry logic, monitoring, reconciliation, and ownership model.
    • A B2B workflow demonstration: use your real sequence from sign-in through price resolution, approval, order submission, and ERP acknowledgement. Slides are not a substitute for a working example or detailed walkthrough.
    • A migration approach: ask how the team profiles legacy data, maps identifiers, handles transformations, rehearses cutover, reconciles records, freezes changes, and decides whether to roll back.
    • Non-functional evidence: require the method used to establish performance, security, availability, accessibility, privacy, and operational acceptance criteria.
    • The proposed team: obtain names or role profiles, allocation assumptions, location, time-zone overlap, relevant credentials, and responsibility for architecture, engineering, quality assurance, delivery, and support.
    • The support model: request severity definitions, response and restoration commitments, coverage hours, escalation paths, monitoring responsibility, maintenance boundaries, and reporting cadence.

    Replace broad questions such as Have you integrated SAP? with scenarios that reveal how the team thinks:

    • A contract price changes in the ERP while a buyer has the product in a saved cart. Walk us through propagation, cache invalidation, display, checkout validation, and audit history.
    • The storefront accepts an order, but the ERP rejects it because the account is on credit hold. What state does each system enter, what does the customer see, and who resolves it?
    • A product update contains an invalid attribute. Show how it is quarantined, reported, corrected, and replayed without blocking valid updates.
    • The ERP is temporarily unavailable during checkout. Explain which functions degrade, which transactions queue, how duplicates are prevented, and how recovery is verified.
    • A platform upgrade changes an API used by custom middleware. Who detects the change, owns regression testing, and approves the production release?

    Good answers name states, decisions, and owners. Weak answers jump immediately to a product name or promise real-time integration without defining acceptable delay, error recovery, or reconciliation.

    Interrogate outcomes instead of borrowing them

    Quantified case work is useful because it gives you something concrete to examine. Atwix reports that PowerPak launched in three months and recorded 230% revenue growth in the first year. Elogic Commerce reports that Armacell achieved five-times-faster order approvals and that PetHQ generated $1.1 million in new B2B revenue after a launch completed in 2.5 months. Those results do not forecast your outcome. They are vendor-attributed examples that should trigger better questions.

    • What was the baseline and measurement window?
    • Which systems, markets, channels, and workflows were included?
    • Which parts did the agency own, and which were delivered by the client or another integrator?
    • What else changed during the period, including assortment, pricing, media, sales coverage, or operations?
    • Which reusable components shortened delivery, and what custom work was still required?
    • What failed, changed scope, or took longer than expected?

    A case study becomes decision evidence only when you understand the mechanism behind the result. Revenue growth alone cannot tell you whether the integration was stable, whether adoption required manual work, or whether the implementation is economical to maintain.

    Use discovery and the contract to test life after launch

    Client and agency teams plan responsibilities at a table that leads into a shared post-launch commerce operations workspace.

    Run paid discovery as a delivery audition

    A proposal tests sales and solutioning. A bounded discovery engagement tests how the actual team asks questions, resolves disagreement, records decisions, and exposes uncertainty. This matters most when legacy data, undocumented integrations, or cross-department ownership make a fixed estimate unreliable.

    Define the discovery outputs in the statement of work. At minimum, require:

    • A validated current-state system and ownership map.
    • A target architecture with material alternatives and decision records.
    • An inventory of interfaces, data objects, dependencies, and failure modes.
    • A representative data profile or migration sample, including reconciliation rules.
    • A workflow catalogue with standard, configured, custom, and deferred capabilities identified.
    • A delivery plan that names assumptions, client dependencies, decision deadlines, environments, testing stages, and release gates.
    • A risk register with owners and proposed mitigations.
    • A staffing plan showing the proposed delivery roles and expected allocation.
    • A support and knowledge-transfer plan rather than a placeholder for later negotiation.

    Do not judge discovery by the number of slides. Judge whether another qualified team could understand the proposed system, the unresolved choices, and the basis of the estimate. Make the required file formats, documentation handover, and ownership or licence rights explicit. Proprietary accelerators may be valuable, but you need to know what happens if the partnership ends or the component is discontinued.

    Have procurement or legal counsel review intellectual-property, data-processing, termination, transition-assistance, and liability language. A technical assumption can become an expensive contractual gap when neither party is clearly responsible for a failed interface or an unsupported component.

    Contract the operating model, not only the build

    The launch date is a transition between delivery modes, not the end of the programme. Put the post-launch model into the agreement while the implementation is still being negotiated.

    • Acceptance: connect payment milestones to testable business and technical criteria, including data reconciliation and operational readiness.
    • Interface ownership: identify who monitors each integration, handles incidents, replays transactions, and coordinates with third-party vendors.
    • Service levels: define severity, measurement windows, response, communication, restoration, exclusions, and escalation rather than relying on a general support promise.
    • Security and compliance: specify access controls, vulnerability handling, logging, incident notification, evidence retention, and responsibility for applicable compliance work.
    • Release governance: document environments, approval gates, emergency changes, regression testing, rollback, and responsibility for platform upgrades.
    • Knowledge transfer: require architecture records, code and configuration documentation, operational runbooks, credentials handover, and training for the people who will own the system.
    • Change control: distinguish clarification, defect, dependency change, and new scope so that every disagreement does not become a commercial negotiation.
    • Exit: cover repository access, infrastructure access, documentation, open incidents, licences, data export, and transition support.

    Security certifications are useful screening signals, but scope matters. Scandiweb lists ISO 27001 and PCI DSS credentials, while Elogic Commerce lists ISO 27001, ISO 9001, and SOC 2 Type II. Ask which legal entity, locations, services, people, and systems are covered. A certificate at company level does not automatically validate your proposed hosting architecture or remove your own compliance responsibilities.

    Make the final decision in two stages

    First, apply the technical and operational gates. Eliminate candidates that cannot demonstrate a launch-critical integration, workflow, security requirement, delivery role, or support obligation. Then score the remaining firms on matched evidence, team quality, delivery approach, commercial terms, and working fit.

    Compare total cost across discovery, implementation, licences, middleware, cloud services, data migration, testing, launch support, managed service, upgrades, and transition. Hourly rates are difficult to compare when one proposal includes architecture and quality assurance while another leaves them as client responsibilities. Normalize scope and assumptions before treating price differences as savings.

    Keep the commercial discussion from reopening a failed technical gate. A discount does not make an unproven order flow, missing ERP capability, or vague support model less risky.

    Key takeaways

    • Choose around your hardest system and workflow dependencies, not the storefront platform alone.
    • Make mandatory integrations, B2B functions, security controls, and support coverage pass-or-fail conditions.
    • Treat partner tiers, certifications, reviews, and client logos as signals to investigate, not substitutes for matched implementation evidence.
    • Ask finalists to solve the same integration and failure scenarios so you can compare their reasoning directly.
    • Use paid discovery to evaluate the proposed delivery team and produce portable architecture, migration, risk, and operating artefacts.
    • Contract acceptance, interface ownership, support, knowledge transfer, change control, and exit terms before implementation begins.

    Before your next agency call, draw the one-page system map and select three failure scenarios that would materially disrupt revenue or operations. Send the same map and scenarios to every finalist, then require written answers tied to named people and comparable production work.

    The partner that deserves the next step is not the one that promises every capability. It is the one that makes boundaries visible, explains how failure will be handled, and gives you evidence that the assigned team can operate the system after the launch presentation is over.

    References


  • How to Build an SEO Career Without Waiting to Be Hired

    How to Build an SEO Career Without Waiting to Be Hired

    If you have been learning SEO but keep meeting the same barrier — no job without experience, no experience without a job — stop treating an offer letter as permission to begin. A certificate can show that you studied the subject. It cannot show how you make decisions when the audience, budget, traffic, and outcome are real.

    Build a small project with a real audience and a useful offer. Use it to practise SEO, GEO, content, measurement, and responsible AI use as connected disciplines. The project does not need to become a large business. It needs to produce credible evidence of how you identify a problem, choose an action, measure the result, and learn from what happened.

    Stop optimizing for permission and start producing evidence

    The conventional entry route is harder to navigate when businesses can automate tasks that once gave junior employees their initial experience. Economic pressure and uncertainty around search add to the problem. Sending applications still matters, but it cannot be your only career strategy.

    Learning and evidence are different things. Learning tells you what a canonical tag does. Evidence shows that you found a canonicalization problem, understood its effect, chose a safe correction, and checked the result. Learning explains search intent. Evidence shows how you mapped a real customer’s questions to pages and calls to action.

    CapabilityWeak career signalStronger project evidence
    Audience researchYou say that you understand search intent.You show how customer questions shaped an offer, query map, and page plan.
    Technical SEOYou list an auditing tool on your CV.You document an indexing, internal-linking, canonical, or rendering issue and the reasoning behind your response.
    ContentYou publish generic advice about SEO.You create content that helps a defined audience evaluate or use something, then examine what visitors do next.
    GEO and AI visibilityYou describe yourself as an AI search expert.You keep a dated record of how relevant AI systems represent the project, where answers are inaccurate, and what you changed.
    Commercial judgmentYou claim to be strategic.You explain why one task deserved limited time or money while another did not.

    Your project gives an employer or client something concrete to question. Why did you target that audience? Why did you create that page before another one? What evidence changed your mind? What failed? Strong answers reveal judgment more reliably than a collection of tool badges.

    You also do not need to create financial pressure for the sake of appearing committed. If you need the income from your current job, keep it. An SEO career can begin alongside the work and responsibilities you already have. Choose a project small enough to maintain consistently rather than planning a second full-time job that you will abandon.

    Choose a project with a real audience and a real action

    A creator photographs a handmade planter at a community market while two visitors examine the product and use a phone.

    A practice website about SEO may help you learn a content management system, but it often removes the hard part of the job: understanding somebody else’s customer. It also encourages a weak success metric — publishing articles and waiting for traffic.

    A better project gives people something useful to do, request, join, download, book, or buy. It might be a small app, service, product, or other offer in a field you understand. Content then supports the offer instead of becoming the entire business model.

    Use these filters before committing:

    • Audience access: You can observe where the intended users ask questions and how they describe the problem. If you cannot reach or listen to them, your assumptions will be hard to correct.
    • A recognizable need: The project solves a specific problem rather than serving a vague interest. The need does not have to be large, but a real person should be able to recognize it as their own.
    • A meaningful action: Visitors can do more than read. Give them a clear next step that creates a measurable signal of interest.
    • Manageable production: You can build and support the offer with the time, skills, and money available to you. A narrower live project is more useful than an ambitious concept that never launches.
    • Room for discovery work: Potential users look for answers, recommendations, providers, products, or comparisons through search, AI assistants, communities, or relevant publications.
    • Safe subject matter: Avoid a field in which useful advice would require professional credentials or access to sensitive information you do not have.

    Write a short opportunity brief before building anything. It should name the audience, the problem, the offer, the intended user action, the places where discovery may happen, and the constraints under which you will work. Add what you currently believe and what evidence could prove you wrong. This turns the project from an open-ended hobby into a series of decisions.

    Do not define success as becoming a large business. That outcome is outside your control and unnecessary for the career goal. Define success as producing an honest body of evidence: a live offer, observable user behavior, documented interventions, technical decisions, and conclusions that respect the limits of the data.

    A project that receives little interest can still teach you something valuable. Perhaps the need was weak, the positioning was unclear, the audience was difficult to reach, or the offer asked for too much commitment. Your task is not to disguise that result. It is to work out which explanations the evidence supports and what you would test next.

    Run the project like a small SEO and GEO account

    The project becomes career evidence only when you can reconstruct what happened. Keep a decision log from the beginning. Memory turns experiments into neat stories; a dated record preserves the uncertainty, alternatives, and inconvenient results that demonstrate how you actually think.

    Capture a baseline before making changes

    Record the condition you are starting from, even if the initial values are empty. Depending on the project, the baseline may include:

    • The pages you intend search engines to access and the pages currently indexed.
    • The queries, impressions, clicks, and landing pages visible in Google Search Console.
    • The actions you count as meaningful, such as an inquiry, signup, download, booking request, or purchase.
    • Existing brand mentions, links, directory entries, referrals, and community visibility.
    • How relevant AI systems answer discovery and comparison questions connected to the project.
    • Errors, omissions, inconsistent facts, missing citations, or competitor recommendations in those AI answers.

    For AI observations, save the exact question, the system or model used, the date, the answer, any cited pages, and your interpretation. Treat that record as an observation of a changing interface, not as a universal ranking report. A later answer may differ for reasons unrelated to your work.

    Make each change answer a defined question

    Start with access and comprehension. Check response status, robots directives, canonical signals, internal links, sitemaps, page templates, and whether important content is available without a fragile interaction. If you add structured data, it should describe information that is genuinely present and visible on the page. Passing a validator does not repair a weak or misleading page.

    Then connect demand to the offer. Group queries and audience questions by the task behind them: learning, comparing, evaluating suitability, resolving an objection, or taking action. Map each meaningful task to the page best equipped to satisfy it. This prevents the common habit of producing disconnected articles merely because a keyword tool returned a phrase.

    For every substantial intervention, record:

    • Observation: What did you notice, and where did the evidence come from?
    • Hypothesis: What do you think is happening, and what alternative explanation remains plausible?
    • Decision: What will you change, postpone, or deliberately leave alone?
    • Expected signal: What behavior or search signal would support the hypothesis?
    • Result: What happened after the change, including a null or negative outcome?
    • Confounders: What else changed that could have affected the result?
    • Next action: What will you do because of what you learned?

    Where practical, avoid changing several major variables at once. Allow an observation period that makes sense for the project’s traffic and the type of change, and choose that period before seeing the outcome. Sparse data may not justify a firm conclusion. Say so. Causal restraint is a strength in a case study, not an admission of weakness.

    Use AI to increase your capacity, not to impersonate expertise

    AI can help you prototype an interface, organize audience language, classify information, draft test cases, or automate repetitive work. It can also produce plausible errors. The useful professional skill is not collecting prompts; it is knowing enough about the underlying task to recognize and correct bad output.

    Keep the review step visible. Note what AI helped produce, what you verified, what you rejected, and why. If it drafts structured data, compare every property with the visible page and the vocabulary you intend to use. If it clusters queries, inspect ambiguous terms and outliers. If it summarizes customer comments, return to the original language before deciding what customers need.

    Apply the same discipline to tools. You do not need an agency-sized stack to prove that you can do SEO. Every paid subscription should answer a practical question: Did it reveal information you could not obtain another way? Did that information change a decision? Did the resulting action contribute to a useful outcome? Working without somebody else’s software budget can sharpen the commercial judgment future employers need.

    Traffic alone is not the outcome. Connect discovery to behavior. A page can gain impressions without attracting the right visitors, and visits can grow without producing interest in the offer. Report the chain honestly: visibility, visits, meaningful actions, and any evidence of commercial value. If the chain breaks, the break is the problem to investigate.

    Turn the decision trail into a portfolio and relationships

    Hands review a portfolio case containing research cards, content thumbnails, interface mockups, and a finished product photograph arranged in sequence.

    A portfolio should not be a gallery of screenshots or a list of services you hope to sell. It should let another practitioner inspect your reasoning. Publish the work while it is still in progress, with enough context that a reader can distinguish evidence from interpretation.

    Write case studies as decisions, not victory laps

    Use a consistent case-study structure:

    • Context: What is the project, who is it for, and what constraint mattered?
    • Problem: What specific condition required a decision?
    • Evidence: What did you observe before acting?
    • Options: What credible alternatives did you consider?
    • Choice: What did you do, and why was it the best use of limited resources?
    • Implementation: What changed on the site, in the content, or in distribution?
    • Outcome: What moved, what did not, and over what recorded observation period?
    • Limits: What prevents a stronger causal claim?
    • Next decision: What will you preserve, reverse, or test next?

    Show relevant absolute values when you can do so safely, not just favorable percentages. Explain whether the baseline was small and whether seasonality, another campaign, a platform change, or simultaneous site work could have contributed. Never convert correlation into certainty merely because certainty makes the headline stronger.

    Publish failures too. A careful account of an unsuccessful experiment can demonstrate diagnosis, accountability, and adaptability better than recycled advice. The useful question is not whether every idea worked. It is whether you noticed the result, updated your understanding, and made a better next decision.

    Let communities see work that is already in motion

    Use an owned home for complete case studies and a social profile or community presence for shorter updates. Start with a channel you can maintain. Publishing creates visibility for both the project and the person learning how to grow it: potential users can discover the offer, while practitioners can see the decisions behind it.

    Join communities where people are doing the work: relevant forums, Slack groups, local meetups, or a paid community when it provides access or support you genuinely need. Do not arrive with a broad request for somebody to mentor you. Bring a specific artifact and a narrow question. Show the baseline, what you changed, what happened, and the part of your interpretation you want challenged.

    • Answer questions when your project gives you relevant evidence, and state the limits of that evidence.
    • Share a useful template, diagnostic process, or failed test without turning every interaction into self-promotion.
    • Ask for criticism of a particular decision rather than general approval of your career plan.
    • Return after acting on feedback and explain what changed in your thinking.
    • Protect private information and obtain permission before discussing work that belongs to somebody else.

    If you work on another person’s business, agree on scope, access, data handling, ownership, and expectations before touching the site. Do not imply that rankings or revenue are guaranteed. A project you own is often simpler because you control the asset, can publish the process, and do not expose somebody else to an inexperienced change.

    Use the portfolio to make applications and outreach more precise. When a role emphasizes technical diagnosis, link to the case that shows your diagnosis. When it emphasizes content growth, show how audience research became pages and measurable actions. When it mentions AI search, share your dated observation method and the limits you placed on the conclusions. You are giving the reader a reason to discuss your work rather than asking them to infer ability from enthusiasm.

    The same evidence can open several routes: an employed role, a bounded freelance assignment, a collaboration, or an introduction to somebody with a harder problem. None is guaranteed. The point is to create more ways for useful work to encounter opportunity than a CV inside a crowded recruitment system.

    Key takeaways and your next move

    • You do not need an SEO job before you can begin producing SEO evidence.
    • A small live offer with a defined audience teaches more than a practice blog built only to attract traffic.
    • Your strongest portfolio material is the full reasoning chain: baseline, hypothesis, decision, implementation, outcome, limitations, and next action.
    • SEO, GEO, content, conversion, and AI-assisted work should meet inside the same project because real businesses experience them as connected problems.
    • Responsible AI use includes verification, rejection of weak output, and enough subject knowledge to explain both.
    • Publishing honest work gives potential users a way to find the project and practitioners a way to assess your judgment.

    At your next work session, write down the audience, problem, offer, intended action, discovery surfaces, and current baseline for one manageable idea. If you cannot fill those fields without vague language, narrow the project. If you can, put the smallest useful version in front of real people and begin the decision log. Your next application can then lead with work somebody can inspect, question, and remember.

    References


  • How to Win Visibility in Agent-Driven Search

    How to Win Visibility in Agent-Driven Search

    Your page can rank first and still lose the customer. In agent-driven discovery, a person can ask an AI assistant to find, compare, book, buy, or contact a provider. The agent may evaluate several businesses and complete the task without sending that person through a familiar results page.

    That changes the visibility problem. You still need to be found, but you also need to survive qualification, support verification, and offer a safe path to action. The practical goal is not merely to appear in an answer. It is to remain the best eligible choice all the way through the agent’s workflow.

    Search visibility now has four separate gates

    An agent commonly turns a delegated request into requirements, searches for possible candidates, evaluates each candidate against those requirements, checks important claims, and then attempts the requested action. A conventional ranking affects the candidate-gathering stage, but it does not settle the final decision.

    GateQuestion the agent must resolveWhat your site needs to provideUseful metric
    RetrievalCan I find this business for the delegated task?Indexable pages, unambiguous entities, relevant task language, and clear topical coverageCandidate appearance rate
    QualificationDoes it satisfy every non-negotiable requirement?Explicit capabilities, limits, prices, locations, eligibility rules, integrations, and availabilityHard-requirement pass rate
    SelectionIs it the best fit among the eligible choices?Suitability guidance, evidence, differentiators, and independently verifiable claimsSelection share when retrieved
    CompletionCan I safely perform the requested action?A usable form, booking flow, checkout, approved API, or clearly defined human handoffSuccessful action rate

    Ranking remains important because it helps a brand enter the candidate set. It is no longer a reliable proxy for winning the decision. First Page Sage reported that, in its vendor-led analysis of 2,417 agentic commands issued from March 4 through June 10, 2026, the first-ranked result was selected 44.6% of the time, while a result ranked fourth or lower was selected 38.2% of the time. Those figures are directional rather than universal benchmarks: they come from one commercial analysis, and agent behavior can differ by platform, category, request, and user context.

    The useful conclusion is narrower and more durable: rank and selection are different outcomes. If your reporting stops at impressions, positions, and clicks, you cannot tell whether an agent failed to retrieve your brand, rejected it on a requirement, distrusted a claim, or could not complete the transaction.

    Give each gate its own metric. Candidate appearance rate tells you whether discovery is working. Hard-requirement pass rate exposes missing or disqualifying facts. Selection share tells you whether the agent prefers you after finding you. Successful action rate reveals whether your conversion path works for an automated assistant. A single visibility score hides all four failure modes.

    Publish the facts agents need to qualify you

    A central business model is connected to visual modules for location, hours, price, availability, services, accessibility, and verification.

    A broad category page may rank for “payroll software,” “family hotel,” or “commercial electrician” while giving an agent too little information to answer a constrained request. Real delegated tasks include conditions: company size, location, budget, dates, integrations, accessibility needs, service area, cancellation terms, or regulatory requirements.

    Agents can treat those conditions differently. A hard requirement eliminates a candidate. An important requirement carries substantial weight. A nice-to-have breaks a close comparison. An optional feature may add only a small advantage. Your first content job is to discover which facts occupy each tier for the buying tasks that matter to your business.

    1. Choose a delegated commercial task. Use a task tied to revenue, such as booking a service, selecting a product, requesting a proposal, or arranging a demonstration. Commercial requests deserve priority because delegated agent activity is more concentrated around buying, booking, and hiring than around general informational searches.
    2. Write down the complete requirement set. Use actual sales questions, support tickets, requests for proposals, on-site searches, form responses, and objections. Separate non-negotiable conditions from preferences instead of treating every feature as equally important.
    3. Map every hard requirement to a canonical page. The answer should be stated directly, not buried in a brochure, image, unsupported comparison chart, or sales-only conversation.
    4. Add suitability content. Explain who the offer is for, who it is not for, which situations it supports, what prerequisites apply, and where its limits begin.
    5. Keep consequential facts synchronized. Prices, regions, availability, policies, product names, and eligibility rules should not conflict across product pages, help content, structured data, directories, and partner profiles.

    Use a suitability page pattern that answers the whole decision

    A useful suitability page is not another generic “why choose us” page. It should let a machine or a person decide whether your offer fits a specific situation. A practical structure is:

    • Best fit: the customer, use case, location, scale, or conditions the offer is designed for.
    • Required conditions: prerequisites the customer must meet before buying, booking, or applying.
    • Supported requirements: the capabilities, integrations, service areas, configurations, or policies that satisfy common constraints.
    • Limitations: unsupported scenarios, exclusions, capacity boundaries, dependencies, and cases that require a different offer.
    • Commercial facts: visible pricing where possible, or a precise explanation of what determines price; availability; fees; cancellation terms; and what happens after submission.
    • Evidence: links to documentation, policies, certifications, product details, or independent material that substantiates consequential claims.
    • Next action: a clear route to buy, book, request a quote, schedule a demonstration, or move to a human review.

    Dedicated suitability content is worth testing even if it attracts little conventional search volume. In the same vendor analysis, businesses with this kind of content were selected 2.7 times as often as equally ranked businesses without it. That multiplier should not be treated as a guaranteed result, but the mechanism is sensible: explicit fit information reduces the inference an agent must make.

    Make proof machine-readable without hiding caveats

    Relevant JSON-LD can express your organization, offer, product or service, availability, and other supported attributes in a consistent format. Use it to clarify facts already visible on the page. Do not use markup to introduce claims, prices, ratings, availability, or capabilities that a visitor cannot confirm in the page content.

    Structured data reduces ambiguity; it does not establish truth. Agents may compare a site’s claims with what they already know and with independent material before choosing a candidate. Make important assertions easy to verify by identifying what the claim applies to, where it applies, and under which conditions. A sentence such as “integrates with accounting software” is weak. A maintained integration page that names the supported systems, required plan, setup path, and current limitations is decision-grade evidence.

    Consistency matters here. Use the same business name, canonical URL, product names, locations, and core offer descriptions wherever you control the information. When a third-party profile is outdated, correct it. When a claim changes, update the visible page and its markup together. Contradictory facts force an agent to decide which version to trust, and the safest decision may be to exclude the candidate.

    Remove the blockers between selection and completion

    A glowing agent pathway moves through verification, availability, selection, payment, and completion while alternate routes end at digital obstacles.

    A recommendation has limited commercial value if the agent cannot finish the requested job. The operational difference is whether a page is machine-actionable: can an approved agent use the interface to submit the inquiry, reserve the time, add the product, complete the purchase, or reach a defined handoff?

    The vendor-led command analysis recorded 78.3% of conversions on machine-actionable pages, compared with 9.6% on pages where the agent could not act. This is not a promise that making a form accessible will produce a particular conversion rate. It is evidence that transactional usability can become a selection constraint rather than a minor conversion optimization.

    Audit the complete transaction, not just the landing page

    • Use visible, specific field labels. “Work email,” “arrival date,” and “number of employees” are easier to interpret than placeholder-only or context-dependent fields.
    • State required inputs before submission. If a quote needs a postal code, account identifier, property type, budget range, or document, disclose that requirement before the agent enters the flow.
    • Explain validation failures precisely. Identify the affected field, preserve valid entries, and say what an acceptable value looks like.
    • Expose material terms before commitment. Price, fees, renewal terms, cancellation conditions, availability, and approval dependencies should not appear only after the decisive click.
    • Use conventional controls and stable destinations. Buttons should have meaningful labels, links should resolve predictably, and essential actions should not depend on unexplained gestures or decorative interface elements.
    • Return an actionable confirmation. Show what was submitted, whether it succeeded, what happens next, and any reference number or next step the user needs.
    • Define the human handoff. If the task cannot be automated, say which step requires a person, what information that person needs, and how the customer will be contacted.

    Test the flow from a clean session using the same facts a customer would give an agent. Check every branch: unavailable dates, unsupported locations, invalid entries, expired inventory, payment failure, authentication, and confirmation. A form that works only on the happy path is not reliably actionable.

    Agent-friendly does not mean unguarded. Keep authentication, fraud controls, consent, privacy safeguards, and human approval wherever the risk requires them. Do not weaken a security control to make automation easier. If automated action is allowed, provide an approved route; if it is not, provide a clear and honest handoff instead of a hidden bypass.

    Use audience preference where the platform supports it

    Retrieval is not driven only by topical relevance. Google Preferred Sources gives readers an explicit way to star publications in the Top Stories area so that stories from those outlets can appear more often for those readers. This is a narrow feature with a precise scope: it concerns publications and Top Stories, not every business listing, organic result, or AI-agent decision.

    The feature has nevertheless become large enough for publishers to treat it as a real retention channel. Google reported that people had selected more than 600,000 unique sources, up from 200,000 in May 2026. Google has also said that users who select a preferred source are twice as likely to click. Those figures describe this specific feature; they do not establish a general ranking advantage across search or AI platforms.

    If you publish news and participate in Top Stories, the implementation is straightforward:

    1. Install Google’s Preferred Sources button using the supported implementation.
    2. Place the prompt near a moment when the reader has received value, such as the end of a substantive story, rather than interrupting the opening.
    3. Explain the result accurately: starring the publication can make its stories appear more often in that reader’s Top Stories experience.
    4. Record the preferred-source user count with its reporting date so you can measure growth instead of relying on an undated total.
    5. Compare that growth with returning readership and engagement, while keeping correlation separate from proof of causation.

    Some site owners received Search Console emails showing a Preferred Source user count as of October 5, 2026. Google also surveyed recipients about future reporting methods, frequency, and metrics. Until regular reporting is established, keep your own dated record of any counts you receive.

    If you are not a relevant publication, do not imitate the button or describe ordinary follows as Preferred Sources. Apply the underlying principle without inventing a platform signal: give satisfied readers a clear way to return, subscribe, follow, or search for your brand again. Explicit preference can support a durable audience, but it should not be presented as proof that an unrelated agent will select you.

    Measure agent visibility as a decision path

    You do not need access to an agent’s private logs to build a useful diagnostic. You need a repeatable set of realistic tasks and a disciplined record of what can be observed. Start with the commercial requests that matter most, because “explain this topic” and “choose a provider and submit an inquiry” test very different kinds of visibility.

    1. Define the task exactly. Include the hard constraints a real buyer would provide: location, budget, timing, compatibility, eligibility, scale, or required terms.
    2. Preserve the test context. Record the platform, date, locale, sign-in state, exact command, and any files or preferences supplied. Keep the command unchanged when comparing runs.
    3. Capture the candidate set. Note whether your brand appeared, which page supported the appearance, what claims were surfaced, and which competing options were considered.
    4. Score each requirement. Mark hard requirements as confirmed, failed, contradictory, or unknown. An unknown should not be counted as a pass merely because you know the answer internally.
    5. Separate selection from retrieval. Record whether the brand was found, whether it remained eligible, whether it was selected, and the observable reasons given. Do not present an inferred reason as if the agent disclosed it.
    6. Test the action. Where authorized, follow the process through the form, booking, cart, checkout, or handoff. Record the exact field, policy, authentication step, or interface state that prevents completion.
    7. Fix the earliest failed gate. More suitability copy will not solve an indexing failure. More authority will not repair an unusable booking flow. Diagnose before choosing the optimization.
    8. Repeat on a fixed cadence. Agent outputs can change, so compare patterns across repeated observations rather than treating one response as a permanent ranking.

    Keep conventional SEO and analytics beside this testing. Search rankings still influence retrieval, human visitors still use results pages, and agent-driven commercial activity remains only part of search. The measurement upgrade is additive: it connects rankings and mentions to qualification, selection, and completed work.

    Key takeaways

    • A ranking can earn entry into an agent’s candidate set without earning the final selection.
    • Publish explicit requirements, supported scenarios, limitations, commercial terms, and suitability guidance so the agent does not have to guess.
    • Use JSON-LD to clarify visible facts, not to make unsupported claims or conceal qualifications.
    • Make consequential claims consistent and independently verifiable.
    • Treat forms, booking systems, checkout, APIs, and human handoffs as part of search visibility.
    • Measure retrieval, qualification, selection, and completion separately so each failure receives the right fix.
    • Use Google Preferred Sources if its Top Stories scope fits your publication, but do not mistake it for a universal agent-ranking signal.

    Choose your highest-value delegated task and trace it from discovery to completion. If your brand is absent, repair retrieval. If it appears but is rejected, expose the missing fit or proof. If it is selected but the task stalls, fix the transaction. That sequence keeps you from buying more visibility when the real leak is qualification, trust, or action.

    References