Month: October 2026

  • How to Hire Senior SEO Talent for Judgment, Not Tasks

    How to Hire Senior SEO Talent for Judgment, Not Tasks

    You are not hiring a human backlog. You are hiring someone to decide which search problem is real, which evidence deserves trust, and which work should win scarce support.

    A polished candidate can discuss crawling, content, links, reporting, and AI visibility. The harder test begins when those signals disagree. Organic clicks can fall while conversion and quality indicators improve. Visibility can grow in a market the business cannot serve. An impressive AI score can have no demonstrated relationship to revenue. Your hiring process needs to reveal who can navigate those conflicts without retreating into a generic checklist.

    Start with the decision this person must improve

    Before writing the job description, finish this sentence: We need this person to help us decide and execute…

    The words that follow should describe a business problem, not an SEO department. You may need more qualified demand in a particular industry, better conversion from existing traffic, clearer priorities for a neglected backlog, or someone who can move discovery work through engineering, content, product, PR, and legal. You may need to learn whether visibility in ChatGPT and other AI experiences produces valuable customer behavior. Those are different mandates.

    Build a short role charter before listing responsibilities. It should define:

    • The business problem: What is currently underperforming, uncertain, or blocked?
    • The outcome: What should improve for customers or the business if the hire succeeds?
    • The constraints: Which budgets, markets, technical limits, compliance requirements, or capacity limits are real?
    • The dependencies: Which teams must approve, build, publish, measure, or support the work?
    • The decision rights: What can this person prioritize directly, and where must they persuade others?
    • The non-goals: Which adjacent responsibilities belong to other people?

    The non-goals matter. A description that combines technical SEO, content strategy, AI discovery, analytics, conversion optimization, link acquisition, reporting, and project management may conceal several jobs inside one salary. It also makes evaluation incoherent: one interviewer rewards technical depth, another expects an editorial strategist, and a third wants a cross-functional program leader.

    Decide whether you primarily need a specialist who will complete defined work or a leader who will determine what the work should be. A senior discovery leader may not personally execute every migration ticket or content brief. They should be able to diagnose the system, select a defensible sequence, obtain support, and keep the work connected to a business outcome.

    Build a scorecard that rewards judgment

    Five symbolic assessment objects form a balanced structure while an unnecessary metallic piece is set aside.

    Technical competence remains a threshold requirement. A senior SEO leader must recognize technically plausible explanations, interrogate the right systems, and understand the consequences of a recommendation. But technical fluency should not consume the entire scorecard. One useful hiring model treats SEO- and AI-specific knowledge as roughly 25% of what makes a senior discovery hire effective, with the rest carried by critical thinking, communication, persuasion, prioritization, and business judgment. That percentage is not a universal formula. It is a practical guardrail against hiring the candidate with the largest vocabulary.

    Use evidence-based dimensions instead of adjectives such as strategic, data-driven, or collaborative. Those words are too easy to claim and too difficult to score consistently.

    DimensionWhat to ask the candidate to doStrong evidenceRisk signal
    Problem framingInterpret a situation in which search and business metrics disagreeSeparates the observed symptom from the decision the business must makeAccepts the prompt’s framing and immediately recommends familiar tactics
    Measurement judgmentIdentify what must be validated before comparing performanceQuestions tracking, consent, definitions, time comparisons, and the relationship between proxy and outcome metricsTreats every dashboard value as equally reliable and meaningful
    PrioritizationChoose work under a real resource constraintNames what will be deferred, explains the opportunity cost, and states what could change the orderLabels most of the backlog urgent or critical
    Business connectionMap search demand to capacity, conversion, and revenueDistinguishes available demand from demand the business can profitably serveTreats rankings, traffic, or AI mentions as the final objective
    InfluenceExplain the same recommendation to technical and commercial stakeholdersChanges the language and level of detail while preserving the reasoningUses channel jargon in place of a business case
    Technical and AI literacyDevelop and test plausible causes across conventional and AI-mediated discoveryKnows what evidence would support or falsify each explanationRepeats platform announcements or best practices without connecting them to the case

    Listen for causal reasoning. A candidate should be able to say: this observation could have several causes; this is the evidence that would separate them; this decision is safe while we investigate; and this is the point at which we would change course. Memorized recommendations rarely contain that structure.

    Do not penalize a candidate for challenging the premise. Senior judgment often appears as "I need more information." The phrase becomes useful only when the candidate identifies the missing information, explains why it changes the decision, and offers a provisional path instead of stopping the conversation.

    Use an ambiguous work sample instead of a trivia test

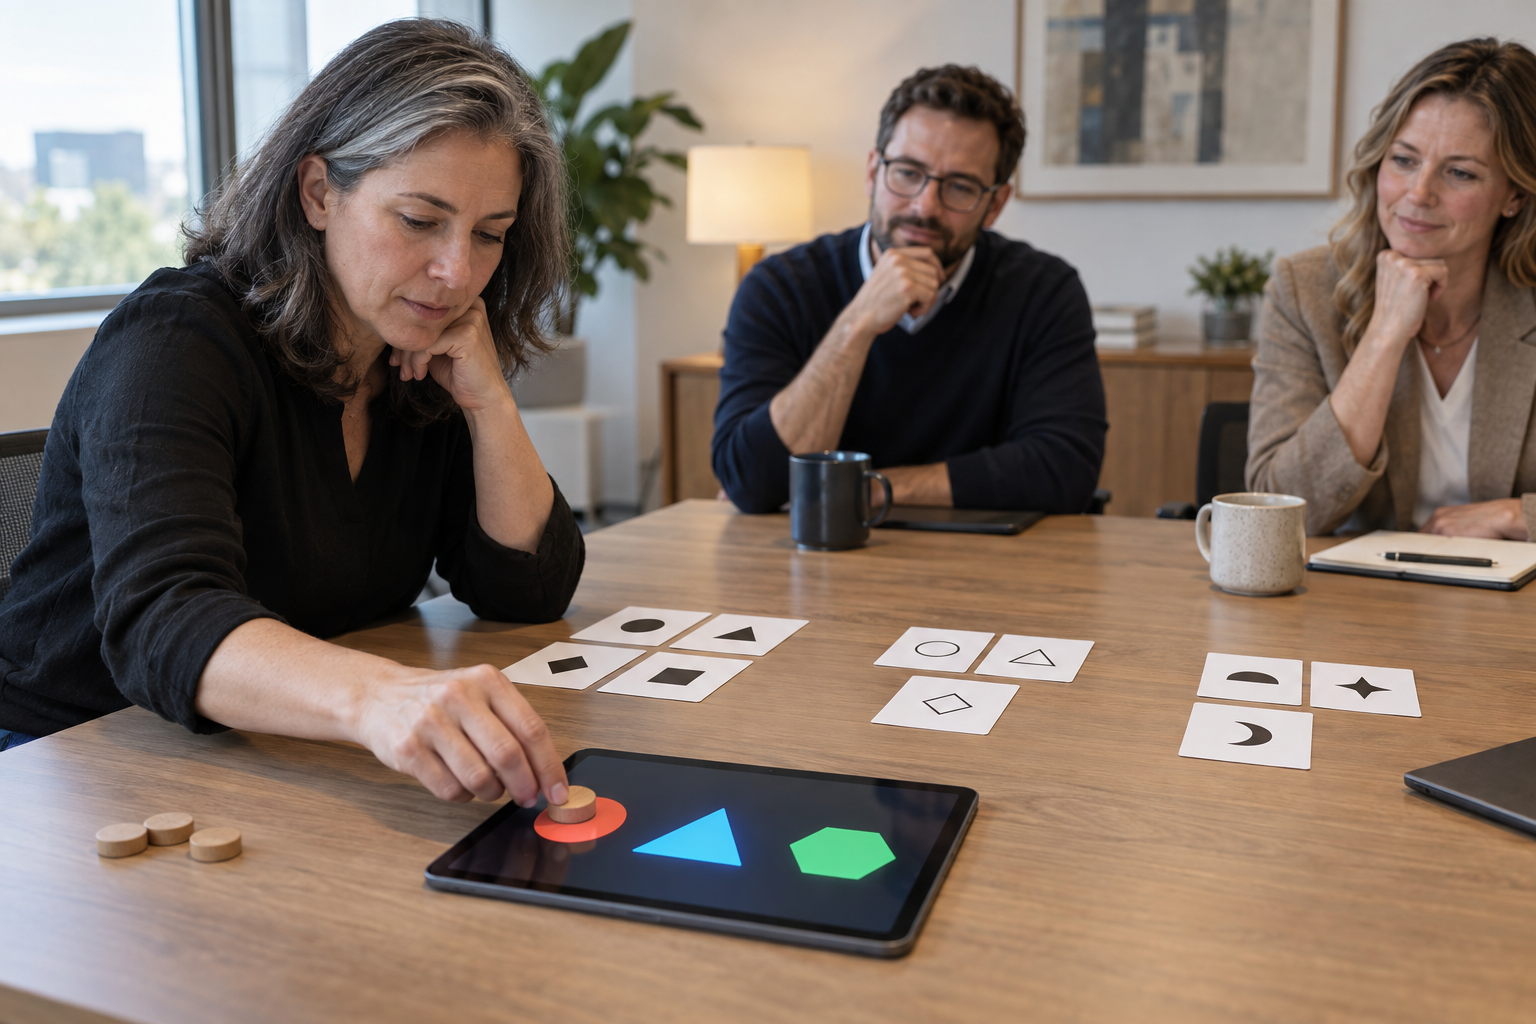
    A candidate sorts ambiguous evidence cards and selects one resource token while two interviewers observe.

    A realistic exercise should contain enough evidence for a recommendation and enough ambiguity to make a checklist inadequate. Keep it close to your operating environment, but fictionalize sensitive data so every candidate receives the same case.

    A useful brief could contain these conditions:

    • Organic clicks are down, while conversion and customer-quality indicators are up.
    • Keyword trends and an AI visibility score are available, but neither has been connected conclusively to the business outcome.
    • Some markets have unused service capacity, while others cannot absorb much more demand.
    • An analytics or cookie-consent change may have affected the year-over-year comparison.
    • Engineering can contribute only 40 hours during the quarter.

    Ask the candidate to make a recommendation, not produce an audit. The deliverable should require them to:

    1. Define the decision the business actually needs to make.
    2. Identify the assumptions and measurement questions that could materially change that decision.
    3. Offer a working recommendation while those questions are being resolved.
    4. Allocate the constrained engineering capacity and state what will not be done.
    5. Choose outcome measures that distinguish commercial progress from visibility alone.
    6. Explain what new evidence would cause the plan to change.

    A weaker response usually expands the scope. It proposes a technical audit, content refresh, cleanup program, link initiative, and AI visibility project at the same time. Every tactic may be legitimate in isolation, but the candidate has not shown why any of them deserves priority in this situation.

    A stronger response first tests whether the apparent decline is a problem. If conversions and customer quality are improving, the lost clicks may include less valuable demand, the measurement may have changed, or another part of the journey may be performing better. The candidate should not assume which explanation is correct. They should specify how to tell them apart.

    Market capacity creates another revealing choice. Improving visibility where the business cannot serve more customers may produce attractive charts and operational frustration. A candidate with business judgment will examine where additional demand can become a completed sale, appointment, subscription, or other real outcome. They may prioritize a market with unused capacity even when its search opportunity looks less glamorous.

    Treat the AI visibility metric the same way. It is a hypothesis-generating signal until the candidate can show a credible relationship to customer discovery and business results. The right next step may be a bounded test, better attribution, or closer analysis of the queries and citations involved. It is not automatically a mandate to maximize the score.

    Use a short panel discussion after the exercise. Grade the candidate’s reasoning, questions, tradeoffs, and communication – not whether the final recommendation matches an answer your team decided in advance. If there is only one answer you will accept, you are testing compliance rather than judgment.

    Interview for tradeoffs, influence, and restraint

    The best interview questions make the candidate choose. Broad prompts such as "How would you improve our SEO?" reward confident improvisation. Constrained prompts reveal whether the person can protect the business from low-value work.

    Questions that reveal diagnosis

    • Organic traffic has declined while qualified conversions have improved. Under what conditions is that good news, bad news, or a measurement problem?
    • Which data would you validate before comparing this period with the previous one, and why?
    • What finding would make you decide not to run a broad technical audit?
    • One market has a visibility gap but no service capacity. Another has spare capacity but lower apparent search demand. How would you choose where to work?
    • Our AI visibility score increased. What would you need to see before treating that increase as business progress?
    • Which recommendation would you make now, and which decision would you deliberately postpone?

    Do not judge the candidate by the number of questions asked. Judge whether each question can change the decision. Asking about a consent implementation that may invalidate a trend is valuable. Asking for every report the company owns may simply delay commitment.

    Questions that reveal leadership

    • Engineering gives you 40 hours this quarter, while the proposed work would take six months. What ships, what waits, and what do you tell the executive team?
    • Explain your recommendation first to a CFO and then to a CTO. What changes in the explanation, and what remains constant?
    • A technically sound recommendation is blocked by product or legal. How do you determine whether to modify it, build a stronger case, or stop pursuing it?
    • When can conversion, inventory, follow-up, reputation, or product preference be a more important discovery constraint than crawlability?
    • Tell us about a recommendation you would reject even if it increased rankings or visibility. What makes the tradeoff unattractive?

    A senior leader should be able to operate outside the SEO silo. Search performance connects to product experience, customer support, paid landing pages, brand reputation, conversion paths, operational capacity, and revenue. That does not mean the SEO leader owns every function. It means they can recognize when the limiting factor sits elsewhere and bring the right owner into the decision.

    Restraint is part of the job. If the candidate describes six months of work as critical despite a narrow engineering allowance, they have not prioritized. They have reformatted the backlog. Look for explicit deferrals, sequencing logic, reversible first moves, and thresholds that would justify further investment.

    During the debrief, record evidence before discussing overall impressions. Ask what assumption the candidate challenged, what they chose not to do, how they connected discovery to business capacity, and whether a non-specialist could follow the logic. A charismatic presentation should not compensate for an undefined problem or an unbounded plan.

    Key takeaways and your next move

    • Define the business decision before defining the SEO role.
    • Treat technical and AI fluency as essential foundations, not the whole senior-level scorecard.
    • Use conflicting metrics and real constraints to expose how a candidate thinks.
    • Reward requests for more information when they identify decision-changing evidence and still produce a provisional recommendation.
    • Make candidates connect search and AI visibility to capacity, conversion, customer quality, and revenue.
    • Grade tradeoffs, communication, and restraint rather than agreement with a predetermined answer.

    Before you publish the role, replace its opening list of channel responsibilities with the decision this person must improve. Then replace the generic take-home audit with an ambiguous case drawn from that decision. The candidate who clarifies the problem, makes a choice, and earns support for it is showing the judgment you are actually hiring.

    References


  • Microsoft Ads and HubSpot: A Revenue Integration Playbook

    Microsoft Ads and HubSpot: A Revenue Integration Playbook

    If Microsoft Ads reports clicks and leads while HubSpot holds qualification, deals and revenue, you have two partial views of the same buyer journey. That gap makes a basic budget question unnecessarily hard: which campaigns are producing commercially useful demand?

    The Microsoft Ads and HubSpot integration can connect advertising activity with CRM records, activate CRM-based audiences and automate the handoff from marketing to sales. The connector creates the path, but trustworthy revenue reporting still depends on the definitions, associations and workflows you put around it.

    What the integration changes – and what it does not

    The integration brings Microsoft Advertising into HubSpot so you can use CRM data to build audiences and connect advertising activity with contacts and deals. Those audiences can support campaigns across Bing, Copilot, Outlook, Xbox and other Microsoft properties. Advertisers also gain access to LinkedIn professional audiences.

    Operationally, that creates a more useful chain:

    • A Microsoft campaign generates or influences a contact.
    • HubSpot records the contact’s lifecycle movement and sales ownership.
    • The contact is associated with a deal when an opportunity is created.
    • The deal moves through pipeline stages and eventually becomes won, lost or inactive.
    • Marketing compares campaign investment with qualified demand, pipeline and credited revenue.

    That is a large improvement over judging campaigns only by click-through rate or cost per lead. It does not, however, turn every CRM record into reliable attribution. The integration cannot decide what your company means by a qualified lead, repair missing contact-to-deal associations or settle whether a campaign sourced a sale or merely appeared somewhere in the journey.

    Key takeaways

    • Use the integration to connect Microsoft campaign activity with contacts and deals, not simply to duplicate ad-platform metrics inside HubSpot.
    • Define lifecycle stages, pipeline rules and revenue credit before treating the resulting dashboard as a source of truth.
    • Automate rep assignment and nurture sequences, but route incomplete or ambiguous records to an exception queue.
    • Separate lead volume, qualified demand, pipeline creation and won revenue so one strong top-of-funnel metric cannot hide a weak commercial result.
    • Use revenue reporting to find promising patterns and controlled experiments to test whether a campaign change actually improves performance.

    Define revenue truth before connecting the accounts

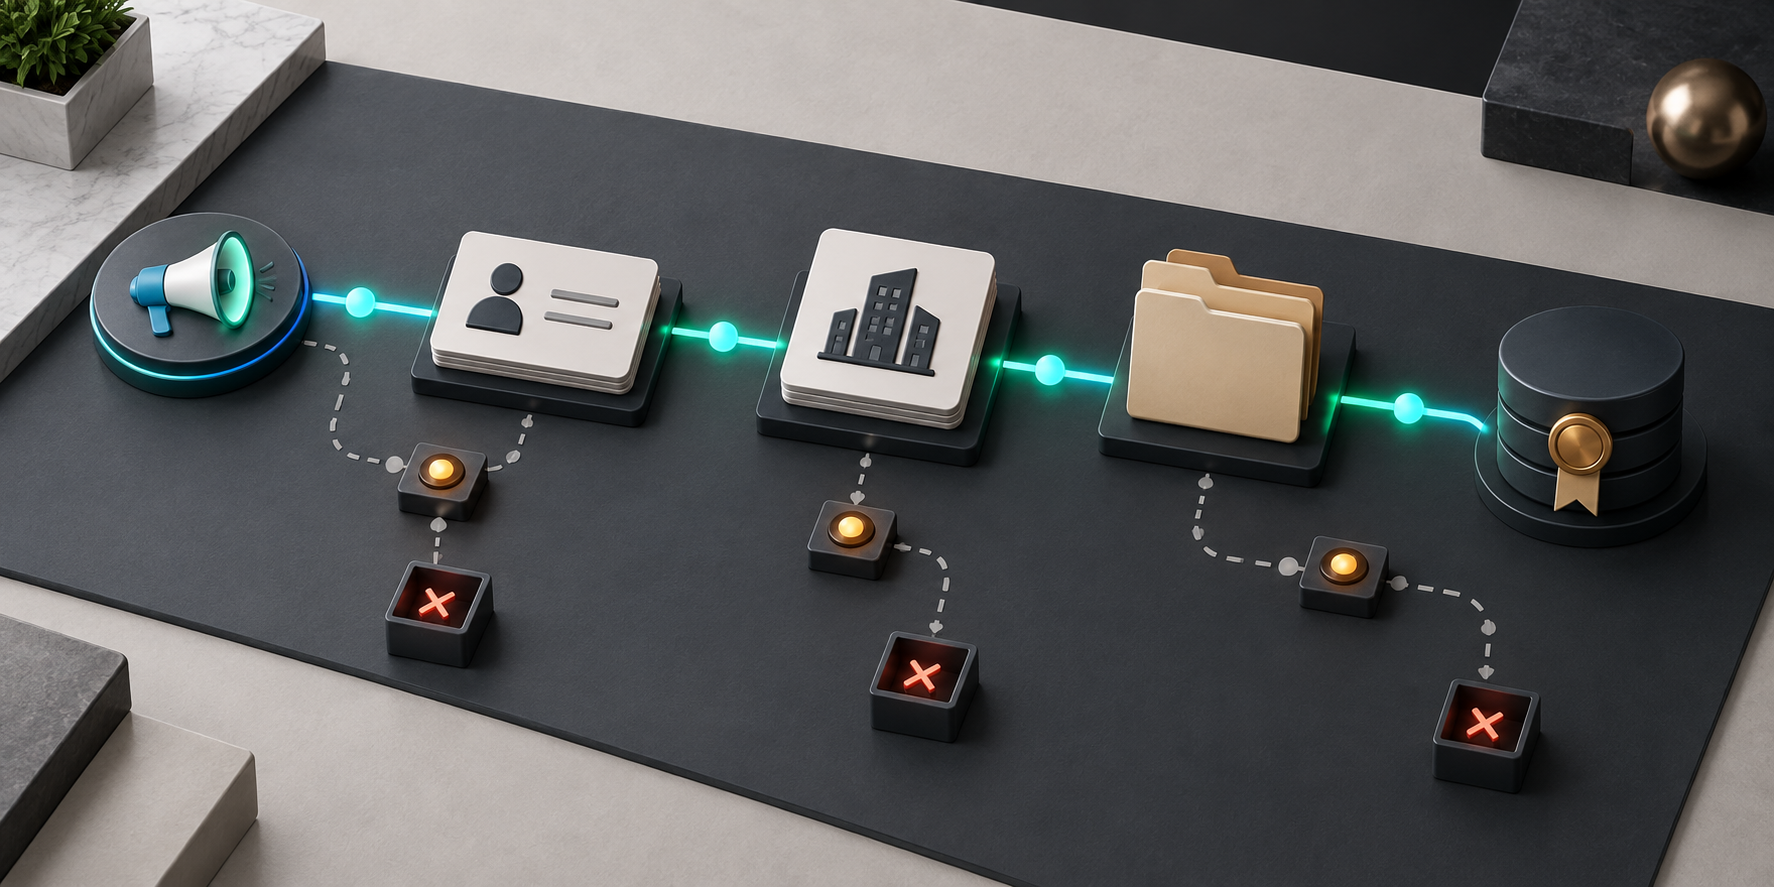
    Unlabeled contact, company, opportunity, and revenue objects connected in sequence by a highlighted data path with validation checkpoints.

    Your first deliverable should be a one-page measurement contract. It is not a technical specification. It is a set of business rules that marketing, sales and revenue operations agree to use when interpreting the integration.

    Write down these decisions before anyone builds a revenue dashboard:

    • Lead: Identify the event that creates a reportable lead. A form submission, imported record and existing contact returning to the site should not become interchangeable by accident.
    • Qualified lead: Name the fields or review step that indicate fit and intent. Do not let the mere presence of a CRM record count as qualification.
    • Pipeline: Specify the deal stage at which an opportunity enters pipeline reporting. If early, unverified deals count, label that value accordingly.
    • Revenue: Decide whether reports use the full closed-won amount, another approved amount stored on the deal or a weighted value. Use one definition consistently.
    • Date: Choose whether campaign reports group results by lead creation, deal creation or close date. These answer different questions.
    • Credit: Distinguish sourced revenue from influenced revenue. A campaign credited under an agreed acquisition model is not the same as a campaign that appeared somewhere in the recorded journey.
    • Associations: State which contact-to-company and contact-to-deal links must exist before pipeline or revenue can be attributed.
    • Exclusions: Document how employees, tests, duplicates, spam, invalid deals and other non-commercial records are removed.

    This prevents the most common reporting failure: a technically correct dashboard answering a question nobody defined. For example, a report grouped by close date tells you what revenue finished in a period. It does not necessarily tell you whether the campaigns launched in that period worked, because many of those leads may not have had time to mature.

    Keep campaign naming equally disciplined. Use a stable structure that identifies the channel, market, campaign purpose and audience without relying on a person’s memory. If names change midstream, record the change instead of silently merging unlike activity. Consistency is what lets the Microsoft-to-HubSpot relationship survive staff changes and dashboard rebuilds.

    Build and validate one complete revenue path first

    Do not begin by connecting every campaign, audience and workflow. Choose one campaign family with a clear conversion path and follow it from advertising activity to a HubSpot contact, a qualified outcome and a deal. A narrow pilot makes broken associations visible before they contaminate a larger report.

    A practical implementation sequence

    1. Confirm account scope and ownership. Record which Microsoft Advertising account and HubSpot portal belong in the connection. Assign one owner for advertising configuration, one for CRM data and one person who approves the shared measurement rules.
    2. Audit the pilot records. Inspect the fields used for lifecycle stage, source, owner, company, deal association, pipeline stage and revenue. Fix obvious duplicates and missing values before using those records as validation evidence.
    3. Connect the approved accounts. Use the Microsoft Advertising integration available in HubSpot and grant only the access required for the planned use. Record who authorized it and how your team will review access later.
    4. Select a controlled audience and campaign scope. Start with a segment whose business meaning is easy to explain. Avoid uploading the entire CRM simply because the connection makes broader activation possible.
    5. Create the minimum handoff workflow. Use the integration’s ability to assign a generated lead to a sales representative or start a nurture email sequence. Keep the first workflow simple enough to audit record by record.
    6. Run an end-to-end validation. Follow a controlled test record or policy-compliant live submission through contact creation, campaign association, lifecycle processing, ownership, workflow enrollment and deal association. Record the expected value and the actual value at each checkpoint.
    7. Reconcile before expanding. Compare the pilot’s contact and deal records with the corresponding campaign activity. Investigate unexplained records rather than forcing totals to match through manual edits.

    A successful connection should be observable. If a marketer cannot open a contact and explain why it entered a workflow, or a sales operator cannot explain why a deal carries campaign credit, the setup is not ready to drive a budget decision.

    Design workflows with an exception path

    A lead handoff should have at least three branches:

    • Ready for sales: The record meets your agreed fit-and-intent rule, contains the information needed for routing and is assigned to the appropriate sales owner.
    • Ready for nurture: The record is legitimate but does not yet meet the sales threshold, so it enters the appropriate email sequence rather than being treated as an immediate opportunity.
    • Needs review: Ownership, market, consent status, company association or another required value is missing or contradictory. The record enters a visible queue with a named person responsible for resolving it.

    That third branch matters. Automation usually fails quietly when every record is forced down a happy path. An exception queue turns a hidden data-quality problem into a manageable operating task.

    Close the loop with sales feedback as well. Use consistent reasons when a lead is accepted, rejected or returned for nurture. Marketing can then see whether a high-volume campaign is reaching the wrong companies, attracting weak intent or simply handing records to sales before enough information exists.

    Measure the funnel without overstating attribution

    Several illuminated marketing and sales paths converge around a business buyer before reaching a completed deal, with a transparent lens examining the junction.

    The integration can show which Microsoft campaigns are contributing to pipeline and revenue and support comparisons with other advertising channels. Treat that visibility as decision support, not automatic proof that an ad caused every credited sale.

    Your working dashboard should keep the funnel layers separate:

    Measurement layerQuestion it answersWhat to inspect when it weakens
    Spend and trafficDid the campaign buy the intended exposure and visits?Delivery, targeting, bidding and creative response
    LeadsDid visitors complete the defined lead action?Offer, landing-page path and tracking continuity
    Qualified leadsDid the campaign attract people who met the fit-and-intent rule?Audience composition, search intent and qualification criteria
    Pipeline createdDid qualified demand become recognized sales opportunities?Sales acceptance, follow-up, deal creation and CRM associations
    Closed-won revenueDid opportunities become revenue under the agreed reporting model?Sales-cycle maturity, deal progression, losses and revenue fields

    Calculate rates between adjacent stages as well as totals. If leads rise while the qualified-lead rate falls, cheaper acquisition may simply be moving the quality problem downstream. If qualified demand is healthy but pipeline creation is weak, inspect the sales handoff and deal-creation process before changing ads. If pipeline looks strong but won revenue lags, separate recent opportunities that still need time from older opportunities that stalled or closed lost.

    Use cohort views when the sales cycle extends beyond the reporting period. Group contacts by the period in which they entered through the campaign, then observe how that cohort progresses. Keep a separate close-date view for financial reporting. Combining those views into one number makes recent campaigns look artificially weak and older campaigns difficult to diagnose.

    Use experiments to test the next decision

    Revenue reporting can reveal an association worth investigating. A controlled test is better suited to deciding whether a change should receive more budget. Microsoft Advertising’s optimization experiments are generally available for Search, Shopping, Audience and Performance Max campaigns, with tests covering bidding, targeting, creative and other changes.

    For each experiment, change one decision you can act on and name the primary outcome before looking at results. If revenue takes too long to mature, use the closest CRM stage that has an agreed connection to commercial value, such as a qualified lead or accepted opportunity. Continue to inspect later pipeline and revenue rather than declaring success from an early-stage improvement alone.

    Keep the original campaign as the comparison, document the tested change and apply a successful variation only after it has met the decision rule your team set in advance. This protects you from promoting a variation merely because its early lead count looks attractive.

    Scale B2B activation with the platform limits in view

    The audience connection is especially useful for B2B teams because Microsoft has expanded LinkedIn company lists from 1,000 to 10,000 companies. Advertisers can upload the companies together and combine those lists with LinkedIn profile targeting in Search and Audience campaigns.

    Do not turn that larger ceiling into one undifferentiated account list. Segment companies according to the decision you need to make. For example, keep priority accounts separate from broader expansion accounts, and separate active opportunities from earlier-stage prospects when your permitted data use and available controls support that plan. Distinct segments let you compare message, response and pipeline quality instead of averaging unlike accounts together.

    Check geographic eligibility before promising reach. The company-list feature is available in supported markets globally, but the underlying consumer data excludes users in the EEA, the United Kingdom and Switzerland. Treat that as a planning constraint for audience design and regional reporting, not as a data problem the HubSpot connection can solve.

    There is also a separate technical deadline for teams maintaining custom Microsoft Advertising integrations. Developers have until January 31, 2027, to migrate from SOAP to REST. SOAP support for new features and enhancements was extended through that deprecation date. This matters to custom API work; it should not be confused with the business process of configuring the standard HubSpot integration. Inventory any custom jobs, middleware and reporting scripts now so the migration does not arrive as an attribution outage later.

    Start with one campaign family, one CRM audience, one handoff workflow and one agreed revenue view. Let that path run long enough to expose association gaps and sales-cycle lag, correct the exceptions, and only then extend the model to more campaigns. The fastest route to credible revenue reporting is a small chain your marketing and sales teams can both explain.

    References


  • AI Search Visibility Is Not Value: How to Measure the Gap

    AI Search Visibility Is Not Value: How to Measure the Gap

    You can be cited by an AI answer and still lose the customer. Your product details may help construct the response while a better-known competitor gets the recommendation, click, and sale. If you publish content, the split can happen further upstream: an AI system can use your work while the economic return remains negligible or impossible to predict.

    That is the practical problem behind unequal value distribution in AI search. You will not solve it by tracking mentions alone. You need to measure each handoff from citation to recommendation, action, and compensation, then work on the point where value stops moving toward you.

    AI search value passes through five separate gates

    Visibility is not one outcome. From your point of view, it is a chain of increasingly valuable outcomes. A business can succeed at one gate and fail at the next.

    GateQuestion to answerMeasure
    CitationDid the response name or link to your site as supporting material?Citation share across eligible responses
    Candidate inclusionDid the response name your brand, store, product, or publication as an option?Mention or shortlist share
    RecommendationDid the system endorse you, especially as its first choice?Recommendation rate and top-choice rate
    ActionDid the exposure produce a visit, inquiry, subscription, or purchase?Traceable visits, leads, and conversions
    Value captureDid the commercial return justify the content, inventory, and operational cost?Attributed revenue, direct payment, and contribution margin

    The distinction matters because an AI answer can use one company as an information source and send the buyer to another company. For publishers, even a direct contribution payment can be too small or volatile to support the work that produced the material.

    Do not combine these gates into a single AI visibility score. A blended score can improve while commercial performance deteriorates. If citations rise but top recommendations fall, the headline number will hide the loss that matters.

    The largest value losses occur after retrieval

    Glowing information particles emerge from a repository and enter a central prism, then split into pathways that narrow sharply before reaching product, interaction, and value symbols.

    Shopping responses show the citation-recommendation gap clearly. Large and small retailers each represented roughly 38% of the stores cited, yet large retailers appeared about 2.5 times as often as small retailers in the top recommendation. Smaller merchants were visible to the systems. They were much less likely to receive the most commercially valuable placement.

    Web access reduced the imbalance without removing it. When search was unavailable, large national chains received 63% to 70% of recommendations, while small and local retailers appeared about 10% of the time. With live search, large retailers still took 46% to 58% of top recommendations across ChatGPT, Google AI Mode, and Google AI Overviews.

    The gap cannot be dismissed as a simple failure to find smaller stores. When an AI system was presented with one large retailer and one smaller store without explicit size labels, it selected the larger retailer in 90% to 94% of responses. This establishes a behavioral pattern, not its cause. It does not prove that any model contains an explicit rule favoring chains, so your audit should measure outcomes rather than speculate about an undisclosed ranking factor.

    Query specificity widened the difference. Small retailers secured roughly one-third of top recommendations for broad requests, but only about 10% when the shopper specified a product. Over the same shift, large retailers moved from roughly 40% to 60% of top recommendations. If you sell specific products, a healthy citation count can therefore coexist with weak purchase-intent visibility.

    Publishers face a second distribution problem: content use does not necessarily produce proportionate compensation. Google’s limited AI Contribution pilot reportedly includes about 100 publishers, but several small and midsize participants received less than 0.1% of their advertising revenue from it. Smaller sites received less than $1,000 over several months, while individual participants were reported at approximately $50,000 to $60,000 after joining and more than $1 million a year in another case.

    Those absolute payouts do not reveal a dependable market rate. Publisher scale, content contribution, eligibility, and the calculation behind monthly changes are not disclosed clearly enough to normalize the figures. The pilot is also too limited to support a conclusion about what most publishers will earn if it expands. Treat it as preliminary evidence of a payment mechanism, not as a forecast you can put into a budget.

    Build an audit that finds the exact value leak

    A transparent five-chamber system carries glowing particles toward a reservoir while a magnifier and inspection light reveal a leak at one connection.

    Your audit should connect controlled prompt testing with real business outcomes. Prompt testing shows what happens before a click; analytics and commercial records show what happens afterward. Neither view is sufficient on its own.

    1. Define the entity and outcome. Choose the brand, product line, location, or publication you are assessing. Then name the desired result: a top recommendation, store visit, qualified lead, sale, subscription, or content payment. Do not substitute citations for that result.
    2. Create separate prompt cohorts. Test broad category requests, specific product requests, requests using local or near me, and requests explicitly asking for an independent business. Keep the commercial intent consistent enough that differences remain interpretable.
    3. Separate platform conditions. Record the platform, product mode, whether live web search is active where that condition is controllable, the displayed model or version when available, the target market, and the test date. Do not merge searched and non-searched responses into one rate.
    4. Grade placement, not merely presence. For each response, record whether you were cited, named as a candidate, recommended, and placed first. Also record the wording: being mentioned as one option is not equivalent to being called the best fit.
    5. Inspect the destination. If a link appears, record its landing page and whether that page can complete the user’s task. A product recommendation that lands on a generic homepage may create visibility without usable demand.
    6. Join the prompt record to downstream evidence. Track attributable referral traffic where it is available, relevant landing-page conversions, assisted conversions you can substantiate, and direct platform payments. Label untraceable exposure as untraceable rather than assigning it an invented monetary value.

    Use separate rates so you can see where performance changes:

    • Citation share: responses citing you divided by eligible responses.
    • Candidate share: responses naming you as an option divided by eligible responses.
    • Top-choice rate: responses placing you first divided by eligible responses.
    • Citation-to-top-choice conversion: responses that both cite you and place you first divided by responses citing you.
    • Action rate: measurable visits, leads, subscriptions, or purchases divided by the relevant exposure measure available to you.
    • Value capture: substantiated revenue or platform compensation compared with the cost of producing and maintaining the underlying content or commerce experience.

    The citation-to-top-choice calculation is especially useful. If citation share rises while that conversion rate falls, your information is becoming more useful to the answer without your business becoming more likely to receive the decision.

    Do not use one undifferentiated prompt average. A retailer can perform adequately on broad discovery prompts and disappear when a shopper names a product. Segmenting by specificity exposes that loss. Segmenting independent separately from local also prevents a nearby branch of a national chain from being counted as evidence that independent businesses are winning.

    Improve the handoff that is failing

    The appropriate intervention depends on the failed gate. More content is not the automatic answer. If you are already cited frequently, producing another page that earns citations may deepen the same imbalance.

    For retailers and service businesses

    The strongest prompt-level change came from the word independent. Adding it more than doubled the share of small and local businesses named, moving their share from roughly one-third to nearly four-fifths in a randomized prompt sample. On Google’s platforms, large-chain sources fell from about 44% under neutral wording to as little as 9%.

    That result changed the user’s request, not the merchant’s website. It does not prove that adding independent to a page will produce the same lift. The responsible action is narrower: if independent ownership is accurate and relevant, state it plainly in visible business descriptions and keep the fact consistent wherever your identity is represented. Then retest. Do not imply independent ownership merely to chase a recommendation pattern.

    Treat local and independent as different attributes. Requests using local or near me had much less effect because an AI system can legitimately interpret a nearby national-chain branch as local. If your advantage is ownership rather than distance, a local-only measurement set will answer the wrong question.

    For specific-product prompts, inspect the facts a system and a shopper need to make a decision: the precise product, current availability, service area or delivery coverage, purchase path, and differentiators relevant to that request. Publish only details you can keep accurate. The available evidence does not prove that any one field improves AI selection, but reducing factual ambiguity gives you a cleaner test and a better destination if a recommendation does occur.

    Use structured data, including JSON-LD, to clarify facts that also appear on the page. Do not present schema as a way to force a recommendation. Machine-readable information can support understanding; it cannot guarantee that an AI system will prefer your business over a larger competitor.

    For publishers and content-led businesses

    Separate audience value from content-use value. Audience value includes visits, subscriptions, leads, and purchases you can substantiate. Content-use value includes contribution payments or licensing income. A citation can contribute to either, both, or neither.

    If you participate in a contribution program, maintain a monthly ledger containing the payment, any available citation or usage information, AI referral traffic, revenue linked to that traffic, and the cost of the eligible content. Do not infer that the payment is impression-based, click-based, or proportional to the amount of content used. Participants in Google’s pilot reportedly do not receive enough explanation to determine why their payouts change from month to month.

    Set your investment rule before an attractive payout anecdote changes your expectations. Continue or expand work only when substantiated direct revenue, defensible assisted value, and disclosed contribution payments together justify your own cost threshold. There is no supported industry benchmark in the available pilot data, so the threshold must come from your economics.

    When payments are opaque and unstable, classify them as uncertain supplemental revenue. Do not hire, commission a content program, or abandon a working traffic channel on the assumption that the pilot will expand on comparable terms. The safe planning case is the amount you can defend from your own records, not another publisher’s headline payout.

    Use the following diagnosis to decide where the next unit of work belongs:

    Observed patternLikely value leakNext action
    Low citation and low recommendation ratesDiscovery or factual clarityCheck accessibility, identity consistency, and whether relevant pages answer the tested request.
    High citation rate but low top-choice rateSelectionClarify truthful differentiators and decision-relevant facts, then rerun the same prompt cohorts.
    High recommendation rate but weak measurable actionDestination or attributionInspect links, landing pages, calls to action, and gaps in analytics before producing more content.
    Strong AI referral traffic but poor conversionOffer or on-site experienceTreat it as a conversion problem and analyze the landing experience by intent.
    Frequent content use but opaque or negligible paymentValue captureLimit financial dependence, document the economics, and treat undisclosed payments as uncertain.

    Key takeaways

    • A citation proves visibility or use. It does not prove recommendation, traffic, or commercial value.
    • Track top-choice rate separately from citation share because the largest loss can occur between those two events.
    • Segment broad and specific-product prompts. Smaller retailers can lose substantial recommendation share as a request becomes more specific.
    • Do not treat local as a substitute for independent; the two words encode different customer preferences.
    • Do not budget around preliminary publisher-payment anecdotes when eligibility, calculation methods, and monthly changes remain opaque.

    On your next AI visibility report, add two columns beside citations: top-recommendation share and attributable business outcome. If you publish content, add compensation and content cost as well. The first empty or underperforming column is where your next investigation belongs.

    References


  • How to Measure AI Search Visibility When Attribution Breaks

    How to Measure AI Search Visibility When Attribution Breaks

    You can win visibility in an AI answer and still see nothing obvious in your analytics. The answer may remove the need for a click, or the prospect may remember your brand and return later through search or a direct visit. In either case, a last-click report can make useful work look unproductive.

    The answer is not to invent AI-generated revenue or abandon attribution. You need a measurement system that separates exposure, observable behavior, and business outcomes. Then you can use the three together to decide what to improve, even when no single platform reveals the full journey.

    The customer journey has moved outside your analytics

    Attribution is an accounting rule, not a camera. It assigns credit among the interactions your systems can observe. It cannot assign reliable credit to an answer that influenced someone without producing a trackable visit.

    The familiar search-to-click-to-conversion path is especially incomplete in AI search. Discovery can now follow a prompt-to-synthesis-to-direct-visit journey: a buyer asks a question, an AI assistant combines information from several places, and the buyer later searches for a company, types its address, asks a colleague about it, or converts on another device. Conventional analytics may record only the final interaction.

    AI referral traffic still matters because it is directly observable. It proves that at least some people moved from an AI interface to your site. But it is a floor, not a complete measure of influence. It excludes people who received a sufficient answer without clicking and people who returned through an unconnected route.

    This leaves you with three separate questions:

    • Did your brand, product, or content appear in the answers that matter?
    • Did audience behavior change after that exposure?
    • Did a commercially meaningful outcome change?

    No one metric can answer all three. A defensible measurement program keeps them separate and looks for agreement across them.

    Key takeaways

    • Treat AI referral sessions as observed traffic, not the total value of AI discovery.
    • Measure brand mentions, recommendations, and citations separately. Being named is not the same as being recommended, and being cited is not the same as owning the answer.
    • Triangulate an exposure metric, a behavioral signal, and a business outcome instead of forcing every interaction into a last-click model.
    • Collect visibility data frequently enough to see short citation cycles. A monthly snapshot can miss both a gain and the subsequent loss.
    • Report what is observed, what is supported by several signals, and what remains inferred. That distinction is more useful than a precise-looking AI ROI number built on missing data.

    Build a three-layer AI measurement system

    Three transparent stacked platforms depict exposure signals, observable behavior, and business outcomes connected by partly broken paths.

    Your dashboard should preserve the boundary between visibility and value. Combining everything into one proprietary score may make the chart simpler, but it hides which part of the system actually changed.

    Measurement layerQuestionUseful signalsMain blind spot
    ExposureWere you present in relevant AI answers?Visibility rate, recommendation rate, citation rate, citation share, AI share of voiceExposure does not prove that a person noticed, trusted, or acted on the answer
    BehaviorDid people do something consistent with that exposure?AI referrals, engaged visits, branded search trends, direct-visit trends, self-reported discoveryMost signals have other possible causes, and many journeys remain disconnected
    OutcomeDid the business result improve?Qualified leads, activated accounts, pipeline, sales, subscriptions, retentionAn outcome can change for reasons unrelated to AI visibility

    Define exposure with a stable prompt set

    An AI visibility program starts with prompts, not keywords. Build the set around decisions your audience is trying to make: diagnosing a problem, understanding possible approaches, comparing options, shortlisting providers, evaluating risk, or planning implementation. A prompt that contains your brand name tests brand representation; it does not tell you whether you are discoverable before the buyer knows you.

    For each observation, record enough context to reproduce or interpret it:

    • The exact prompt and its intent cluster.
    • The AI engine, observation date, and market or language when those factors are relevant.
    • Whether the brand appeared at all.
    • Whether it was recommended, described neutrally, or mentioned negatively.
    • Whether an owned page was cited and which URL received the citation.
    • Which competitors appeared in the same answer.
    • Whether the response failed, refused the request, or was otherwise invalid.

    Keep the denominator visible when you calculate a rate. A result such as “40% visibility” is uninterpretable unless the report also shows how many valid observations it covers, which engines were included, and whether the prompt mix changed.

    Use explicit definitions:

    • Visibility rate: valid observations in which the brand appears, divided by all valid observations in the tracked set.
    • Recommendation rate: valid observations that actively recommend the brand, divided by all valid observations. A neutral mention should not count as a recommendation.
    • Owned citation rate: valid observations containing at least one citation to your domain, divided by all valid observations.
    • AI share of voice: your appearances divided by all tracked brand appearances in the same prompt set. Decide in advance whether one brand can count more than once per answer.
    • Page citation share: citations received by a particular owned page divided by all citations observed in the defined comparison set.

    Version these definitions. If you add engines, markets, or prompt clusters, report the new cohort separately until you can make a like-for-like comparison. Otherwise, a coverage change can masquerade as a visibility gain or loss.

    Collect behavior without pretending every signal is causal

    Capture AI referrers in your analytics, but inspect their landing pages and outcomes rather than reporting sessions alone. A small number of visits to a high-intent comparison or product page may be more informative than a larger number of low-intent visits. Record engaged visits, sign-ups, qualified conversions, and assisted conversions when your systems can observe them.

    Referral traffic can tell you that something happened after a click, but not what happened before it or how much unclicked demand was created. Support it with a discovery question on lead, signup, or checkout forms. Ask, “How did you first hear about us?” Include an option for ChatGPT or another AI assistant and retain a free-text field. Do not replace the person’s answer with the last tracked channel.

    Branded searches and direct visits can also support the picture, particularly when they move alongside AI visibility. They are not proof. A campaign, news event, recommendation, or offline conversation can produce the same pattern. Annotate those events so the team can see plausible alternative explanations.

    Connect outcomes through the CRM

    Choose the outcome that matches the motion. An ecommerce team may care about purchases and repeat customers. A subscription business may care about activation and retained accounts. A sales-led company may care about qualified pipeline and closed revenue. For an account-based program, useful measures include the percentage of the total addressable market reached, engaged, and activated each month.

    Add structured CRM fields for self-reported discovery source, the named AI assistant when volunteered, first known landing page, acquisition date, and eventual outcome. Preserve the original discovery field when later touches occur. If a person first found the company through an AI answer and later converted after an email, both facts matter; overwriting the first with the last destroys evidence.

    Do not award full revenue credit independently to the referral, the self-reported answer, and the final campaign. Those are different observations of one journey, not three sales. Use them to strengthen or weaken an explanation, not to inflate the result.

    Measure often enough to see an 11-day citation half-life

    A sequence of floating crystalline nodes gradually dims and fragments, with a newly glowing node appearing near the end.

    AI citations are unusually perishable. Across 883,000 pages observed on seven AI search engines, the median page’s citation share was down 50% eleven days after reaching its peak. Citation lifecycles also differed by engine.

    A monthly point-in-time report can therefore miss the event you wanted to measure. A page could gain substantial citation share, peak, and lose much of that share between two reporting dates. The final snapshot would show little movement even though the page briefly became an important answer source.

    For a fixed set of commercially important prompts, weekly collection is a reasonable minimum starting cadence. Use more frequent automated checks for launches, reputation-sensitive queries, or prompt clusters tied closely to revenue. Report business outcomes on a cadence appropriate to the buying cycle, but do not let a long sales cycle force exposure measurement into the same slow schedule.

    Make the time series usable:

    • Keep a fixed benchmark cohort of prompts so one period can be compared with another.
    • Add newly discovered prompts as a separate cohort instead of silently changing the benchmark.
    • Show rolling trends as well as individual observations; one generated answer is a sample, not a permanent rank.
    • Break results out by engine before calculating an overall total. An aggregate can hide a gain on one engine and a loss on another.
    • Track citations at the URL level. A stable domain total can conceal one important page being replaced by another.
    • Annotate substantive content changes, migrations, canonical changes, indexing incidents, product launches, campaigns, and major brand events.
    • Store raw observations so a surprising chart can be checked against the answers that produced it.

    The eleven-day figure is not an instruction to republish every page on an eleven-day schedule. It is a median measured after a page’s high point, not an expiration date. It does not mean every page follows the same curve, that the page disappears after eleven days, or that changing a date will restore visibility.

    When citation share falls, diagnose before rewriting:

    1. Confirm that the prompt set, engine coverage, locale, collection method, and metric definition did not change.
    2. Check whether the loss is isolated to one engine, one intent cluster, or one page.
    3. Inspect the replacement citations. Determine whether another page answers the same question more directly or with more current information.
    4. Check the affected owned page for access, indexing, canonical, redirect, rendering, or accidental noindex problems.
    5. Review whether the answer itself has become incomplete or stale. Update the substance, evidence, and structure when the page no longer deserves to be the best source.
    6. Measure the result across repeated observations. Do not declare recovery from one favorable response.

    A timestamp-only refresh may create activity without improving the answer. Change the page when you can identify a content or technical gap, and record that intervention so the next visibility movement can be evaluated.

    Turn signal combinations into decisions, not invented certainty

    Triangulation works because the three layers fail differently. Exposure tracking can see an answer without knowing whether anyone acted on it. Referral data sees a click but misses zero-click influence. CRM outcomes show value but often lose the discovery path. When differently biased signals move in the same direction, your confidence should rise.

    Read the combinations before changing strategy

    • Exposure and AI referrals rise together: you have direct evidence of greater visibility and more observable traffic. Check whether qualified actions rose before expanding the program.
    • Exposure rises, referrals stay flat, and self-reported AI discovery or outcomes improve: the pattern is consistent with zero-click or disconnected journeys. It strengthens the case for influence, but it is not proof that AI caused every outcome.
    • Exposure rises with no behavioral or business movement: inspect prompt relevance and how the brand is represented. You may be visible in low-value questions, appearing neutrally instead of being recommended, or reaching an audience that is not ready to act.
    • Mentions remain stable while owned citations fall: separate brand presence from content ownership. Inspect which domains and pages are replacing your citations before treating the movement as a broad loss of awareness.
    • One engine declines while others remain stable: investigate that engine’s prompt results and cited-page changes separately. An average across engines will obscure the problem.
    • Visibility remains stable while conversions decline: do not automatically blame AI search. Review offer, landing-page, sales, pricing, seasonality, and other demand signals.
    • Exposure, behavior, and outcomes decline together: prioritize the affected prompt clusters, but still check for technical, market, and measurement changes before assigning a cause.

    Label the strength of each claim

    A useful report distinguishes three evidence levels:

    • Observed: an AI engine cited a URL, a referral session arrived, a form response named an AI assistant, or a CRM record reached a defined outcome.
    • Supported: several independent signals moved together, and obvious competing explanations were checked.
    • Inferred: AI visibility probably influenced demand, but the journey cannot be connected at the person or account level.

    That language prevents a proxy from quietly becoming a fact. A Graphite estimate has put AI under-attribution as high as 10x, but a vendor estimate is a warning about missing observability, not a universal correction factor. Multiplying every observed AI conversion by ten would replace incomplete data with unsupported precision.

    Make every reporting cycle end with an action

    Your recurring report should include:

    1. Coverage and denominators: prompts, valid observations, engines, markets, and dates.
    2. Visibility, recommendation, citation, and share-of-voice trends by engine and intent cluster.
    3. Owned pages that gained or lost citations, plus the pages or domains replacing them.
    4. Observable AI referrals, landing pages, engagement, and conversions.
    5. Self-reported discovery and CRM-tagged outcomes, shown separately from tracked referrals.
    6. Relevant business outcomes and the period appropriate to the buying cycle.
    7. Known content, technical, campaign, and market events that could explain movement.
    8. The evidence level, competing explanations, and one named next decision.

    The decision can be to maintain, diagnose, update, expand, test, or pause. Require more than a single generated response before making a material content or budget change. Where volume allows it, use controlled comparisons across similar markets, audiences, accounts, or time periods to test incrementality. Document the differences between groups; a comparison is weak if the supposedly comparable groups were exposed to different campaigns or demand conditions.

    Start with one high-value prompt cluster. Freeze the metric definitions, capture a baseline by engine, add a discovery field to your forms and CRM, and schedule the first comparable visibility check within a week. Your first report does not need to claim exactly how much revenue AI produced. It needs to show where you are visible, what changed downstream, how strong the evidence is, and which action is justified next.

    References


  • A Practical Framework for AI Advertising Campaign Reporting

    A Practical Framework for AI Advertising Campaign Reporting

    Your AI advertising dashboard can be numerically correct and still lead you to the wrong decision. This happens when it collapses four different things into one performance label: what delivered, what the platform optimized for, what it attributed, and what its budget tools are allowed to use.

    You need a reporting system that keeps those layers visible. The framework below will help you turn campaign data into defensible actions without letting an AI-generated summary hide attribution limits, product eligibility problems, or gaps between web and app measurement.

    Key takeaways

    • Show the selected optimization goal beside every supporting conversion. A reported outcome is not necessarily an outcome the campaign pursued.
    • Label each conversion separately as reportable, used for optimization, and eligible for budgeting. Those are three different permissions.
    • Treat attribution as a rule for assigning credit, not proof that an ad caused the outcome.
    • Put product rejections, review pauses, identity changes, and measurement changes on the campaign timeline so operational interruptions are not mistaken for performance failures.
    • Let AI explain a governed dataset. Keep metric definitions, joins, formulas, and eligibility rules deterministic and reviewable.

    Build every report around one decision

    A dashboard built to answer every possible question usually answers none of them clearly. The person deciding whether to scale a campaign needs a different view from the person diagnosing a rejected product or reconciling app purchases. Start with the decision, then select the data required to make it.

    A useful report header should identify:

    • Decision: Scale, hold, reduce, diagnose, or repair.
    • Scope: Account, campaign, ad group, product, channel, market, and customer surface.
    • Primary outcome: The conversion event selected as the optimization goal.
    • Supporting outcomes: Other attributed events that help you judge lead quality, downstream value, or progression through the journey.
    • Comparison: The period, segment, or campaign being used as the reference point.
    • Measurement context: Attribution model, attribution window, currency, time zone, data freshness, and known coverage gaps.
    • Next action: The proposed change, its owner, and the condition that would reverse or confirm it.

    Do not force every conversion into a single blended total. A campaign optimized for one event can now expose other attributed events through the public ChatGPT Ads Insights API. That additional visibility is useful, but it does not change the campaign’s selected goal.

    Keep the primary outcome and supporting outcomes in separate columns. If the optimization goal improves while a downstream purchase metric weakens, you have a quality question to investigate. If purchases improve while the optimization goal is unchanged, you have a useful signal, but not automatic proof that the campaign caused the improvement.

    Separate delivery, eligibility, outcomes, and attribution

    Four transparent stacked chambers separately depict ad delivery, product eligibility, customer outcomes, and attribution paths.

    A trustworthy report lets you locate the stage at which performance changed. Use distinct reporting layers instead of dropping every metric into one scorecard.

    Reporting layerQuestion it answersWhat to includeDecision it supports
    DeliveryDid the campaign reach and engage its available audience?Platform delivery metrics at the campaign, ad group, and product levelsInvestigate distribution, targeting, serving, or creative exposure
    CostWhat did that delivery consume?Spend and consistently calculated efficiency metricsCheck financial guardrails and locate changes in cost
    Product eligibilityCould each advertised product serve?Feed item, review state, rejection reason, and status-change timeRepair catalog or policy issues before judging demand
    OutcomesWhich conversion events received credit?Optimization goal and supporting attributed events, kept separateEvaluate the chosen objective and inspect downstream quality
    Attribution and governanceUnder which rules and account conditions were results recorded?Model, window, surface, naming changes, review pauses, and measurement changesCompare compatible data and explain discontinuities

    ChatGPT Ads reporting can supply delivery, cost, product, and attributed conversion metrics. Preserve those metric families as separate datasets or clearly identified groups in your reporting model. That makes it possible to tell the difference between a serving problem, a cost problem, a catalog problem, and a conversion problem.

    Product campaigns need an eligibility layer because a rejected item did not receive the same opportunity as an approved item. ChatGPT Ads now exposes product review status and individual rejection reasons. Bring those fields into the report before calculating product-level winners and losers. Otherwise, you may penalize an item for not converting when the actual issue was that it could not serve.

    Operational changes also belong on the timeline. ChatGPT Ads separates the internal account name, public brand name, and registered legal name. A public brand-name change can pause serving during review, while a legal-name change can restart business review and may also interrupt delivery. Record those identity and review events as annotations. A delivery gap during a review is an operational interruption, not evidence that the audience rejected the campaign.

    Treat reporting, optimization, and budgeting as separate controls

    Every conversion in your measurement plan needs three explicit flags:

    • Reportable: Can the event appear in performance or attribution reporting?
    • Optimization-enabled: Is the campaign actively trying to generate this event?
    • Budget-eligible: Can an automated or cross-channel budgeting system use this event when allocating money?

    Never infer the second or third flag from the first. The ChatGPT Ads Insights API can return attributed events beyond the selected optimization goal. Google can include app conversions in performance reporting, attribution analysis, and attribution models while its cross-channel budgeting features remain limited to web conversions. In both cases, visibility is broader than at least one action layer.

    Use supporting conversions without changing the meaning of success

    Supporting conversions can reveal what happens after the event selected for optimization. They are especially useful when the selected event represents an earlier step in the customer journey. Keep them in the report, but preserve their role.

    For each event, store its business definition, customer surface, reporting status, optimization status, budgeting status, and attribution configuration. If one of those fields is unknown, label it unknown. Do not allow the reporting layer or an AI assistant to silently convert an unknown into a yes.

    Keep a visible boundary between web and app measurement

    Google’s expanded conversion reporting can bring app activity into broader performance and attribution views. Advertisers can also configure attribution for app conversions independently from other conversion types. However, availability may still vary by Google Analytics property, and app outcomes are not yet included in cross-channel budgeting.

    This can make a report look unified even when the underlying controls are not. Add a surface field to every conversion row and display web and app subtotals before showing a combined figure. Also record the attribution setting applied to each surface. A combined total is decision-safe only when you can explain what was counted, how credit was assigned, and whether the downstream tool can act on all of it.

    An AI-generated recommendation should never say that a budget allocator will react to app conversions merely because those conversions appear in the same report. It can recommend a manual review of the evidence, but it must preserve the platform’s actual budgeting boundary.

    Build a reporting pipeline that AI can audit

    Transparent data channels pass advertising events through validation and lineage checks before an AI system presents evidence to a human reviewer.

    Automation makes governance more important, not less. Spreadsheet uploads can create multiple ChatGPT product campaigns and ad groups while generating ad templates automatically. Set naming rules and persistent identifiers before a bulk launch so the resulting scale does not produce an untraceable reporting structure.

    1. Create a conversion registry. Give every event a stable identifier, business meaning, customer surface, owner, reportable flag, optimization flag, budget-eligibility flag, and attribution configuration.
    2. Define a campaign taxonomy. Standardize the fields used for market, product group, objective, funnel stage, audience, and experiment. Keep platform IDs even when human-readable names change.
    3. Extract raw data without rewriting its meaning. Preserve native platform fields, IDs, statuses, and timestamps before creating normalized views.
    4. Normalize context explicitly. Apply consistent date boundaries, time zones, currencies, and metric formulas. Retain the raw values so transformations can be audited.
    5. Join operational status data. Add product review states, rejection reasons, account reviews, serving pauses, feed changes, and measurement-setting changes to the campaign timeline.
    6. Reconcile before interpreting. Compare API totals with the platform interface using the same dates, filters, attribution settings, time zone, and account scope. Investigate differences rather than hiding them in a blended total.
    7. Calculate metrics deterministically. Use documented formulas for rates, costs, and rollups. Do not ask a language model to perform the authoritative aggregation from loosely formatted exports.
    8. Generate the narrative last. Give AI the reconciled table, metric definitions, change log, and decision question. Require every recommendation to point back to visible evidence.

    Give the AI a narrow reporting contract

    A useful reporting assistant should distinguish observation from interpretation. Its instructions should require it to use only supplied data, preserve platform definitions, identify missing fields, avoid causal claims from attributed conversions, and state when a proposed action depends on an unverified setting.

    Require each generated finding to contain:

    • Observation: The measured change, including its scope and comparison.
    • Evidence: The exact metrics, dimensions, statuses, and time period supporting the observation.
    • Interpretation: A plausible explanation clearly labeled as an inference.
    • Measurement limits: Attribution, availability, eligibility, or data-quality constraints that could change the reading.
    • Action: A reversible next step tied to the original decision.
    • Validation condition: What must be checked before the recommendation is implemented or expanded.

    This structure prevents polished prose from outrunning the evidence. Attribution tells you how a model assigned credit; it does not establish causal lift. When causality matters, the report should identify the need for an appropriate experiment rather than dressing an attribution result up as proof.

    Run these checks before automating recommendations

    • API and interface totals reconcile under identical filters and settings.
    • Every conversion has separate reporting, optimization, and budgeting flags.
    • Web and app events retain their surface and attribution configuration.
    • Rejected, pending, and approved products are distinguishable.
    • Serving pauses and account, brand, feed, goal, or attribution changes are annotated.
    • Missing and unavailable values remain distinct from zero.
    • Every generated recommendation cites the rows and definitions it relies on.
    • A person with budget authority reviews consequential changes before they are applied.

    Start with one active campaign and complete the conversion registry before rebuilding the dashboard. Put the business meaning, surface, reporting status, optimization status, budget eligibility, and attribution setup beside every outcome. If you cannot complete those fields, the campaign is not ready for automated interpretation. Fix that boundary first; the reporting interface can follow.

    References