Month: October 2026

  • How to Manage Google Ads Video Frequency Across Campaigns

    How to Manage Google Ads Video Frequency Across Campaigns

    Your video campaigns can each look controlled while your audience still feels overexposed. The blind spot is overlap: a person can qualify for several campaigns, so acceptable frequency inside each campaign can become excessive frequency across the account.

    Google Ads is testing Video Campaign Groups for eligible Video and Demand Gen campaigns. The beta introduces group-level choices for increasing deduplicated reach or coordinating delivery around a frequency target. Used well, it can help you answer a practical question: are you reaching more of the intended audience, or repeatedly buying access to people you have already reached?

    Campaign-level frequency can hide account-level saturation
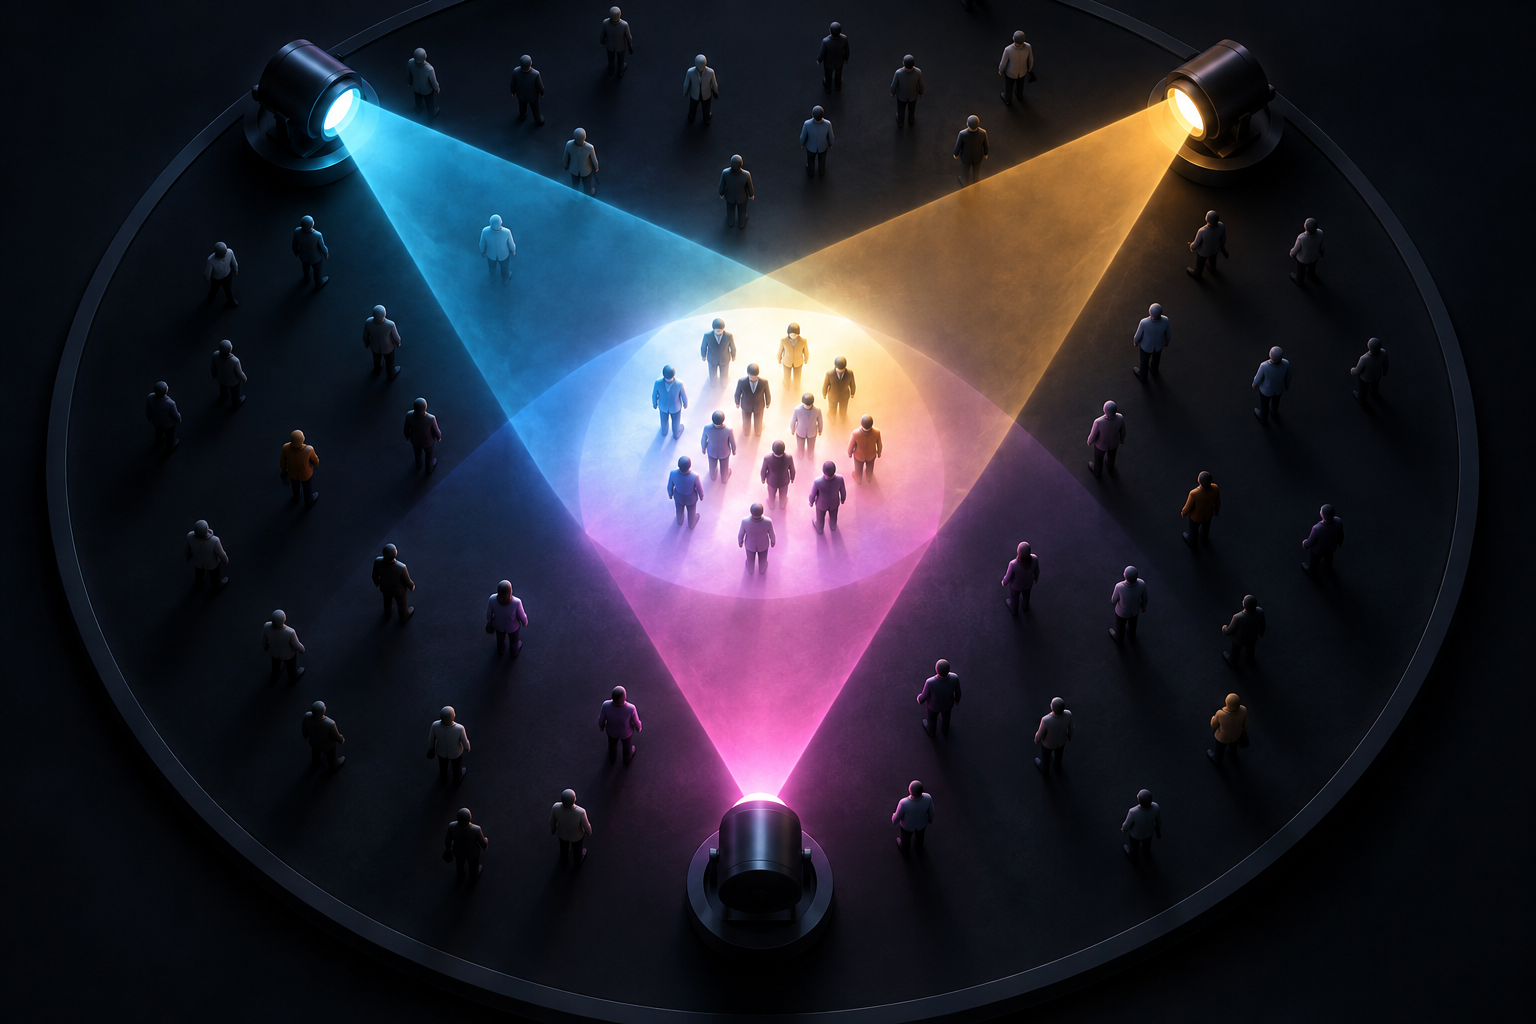
    A top-down view shows three colored projection beams overlapping on the same small group of people while others remain outside the light.

    Reach and frequency only make sense within a defined boundary. Reach represents the distinct audience exposed within that boundary. Frequency describes how often the reached audience was exposed on average. Change the boundary from an individual campaign to a collection of campaigns, and both measurements can change.

    This matters when a brand-awareness campaign, a product campaign, and a Demand Gen campaign pursue overlapping audiences during the same period. Each campaign can report a reasonable result while the combined plan keeps returning to much of the same audience. Adding the individual reach figures will not reveal the true audience size because duplicated people can appear in several campaign totals. Averaging campaign frequency figures can be equally misleading because the campaigns may have different reach and impression volumes.

    The problem is organizational as much as technical. Separate teams, agencies, product lines, or budget owners may optimize their campaigns independently. The audience does not experience those internal boundaries. It experiences the combined sequence of ads.

    Before creating a campaign group, build a simple overlap map:

    1. List the active Video and Demand Gen campaigns that could belong in the group.
    2. Record each campaign’s business objective, audience, geography, schedule, creative message, and responsible owner.
    3. Mark audience overlap as high, uncertain, or low. Treat uncertain overlap as something to investigate, not as an assumption of independence.
    4. Identify campaigns that serve a different funnel stage or require deliberately different repetition. Keep those outside the group unless a shared group objective still makes sense.
    5. Write the audience experience in plain language. If the plan sounds repetitive when described from the viewer’s perspective, campaign-level optimization is probably not enough.

    Choose between broader reach and managed repetition

    The beta presents two different strategic directions: increase campaign-group reach or set a campaign-group frequency target. Do not treat this as a routine setup choice. It tells Google what problem you want the group to solve.

    Group directionUse it whenWhat success should look likeWhat to watch
    Increase campaign-group reachYour upper-funnel campaigns compete for overlapping audiences and your priority is finding additional eligible people.Deduplicated group reach expands without unacceptable deterioration in the business outcome or audience quality you use as a guardrail.Do not confuse a larger reported audience with valuable incremental reach. Check whether the additional exposure still serves the campaign’s purpose.
    Set a campaign-group frequency targetRepetition is intentional, but you want it coordinated across campaigns rather than produced independently by each campaign.Group-level frequency moves toward the intended pattern while reach, delivery mix, and campaign outcomes remain acceptable.A target is an optimization instruction, not proof that every person receives the same number of impressions. Do not describe it internally as a hard cap unless the interface explicitly defines it that way.

    Reach optimization is usually the clearer choice when the central problem is duplication. If several upper-funnel campaigns address substantially the same market, a group-level reach objective gives the system a reason to look beyond people already reached elsewhere in the group.

    A frequency target is more appropriate when repetition has a defined role in the plan. That might include maintaining brand presence or supporting a coordinated message over time. The target still needs a business rationale. Do not borrow a universal frequency number from another account. Audience size, campaign purpose, creative variety, buying cycle, and available budget all change what a sensible pattern looks like.

    Treat your initial target as a hypothesis. Start from your own historical delivery and the point at which added exposure stopped producing enough additional value. If you do not have evidence for that point, use the group to learn before making a larger budget decision.

    Build a campaign group around one coherent job
    A central control module connects several video campaign devices and distributes light either broadly across many people or in even pulses to a defined group.

    A campaign group should represent a shared audience-management problem, not merely a convenient folder. Campaigns can use the same channel while doing very different jobs. Combining them under one reach or frequency instruction can create a clean report but a confused strategy.

    1. Confirm that Video Campaign Groups are available in your account and that the campaigns you intend to use are eligible. The capability is in beta, so do not design an account-wide process that assumes universal access.
    2. State the group’s job in one sentence. A useful statement names the audience, the intended exposure pattern, and the business purpose.
    3. Group campaigns by audience relationship and funnel role. Shared format alone is not enough.
    4. Choose either reach expansion or frequency coordination based on the problem you identified. Do not select the setting first and invent the rationale afterward.
    5. Capture a baseline for campaign reach, frequency, spend, delivery mix, and the outcome each campaign is meant to influence. Preserve the date range and reporting definitions so the later comparison is meaningful.
    6. Keep major audience, creative, bid, and budget changes to a minimum during the initial evaluation. If several inputs change together, you will not know what caused the result.
    7. Assign an owner for group-level decisions. Campaign owners should not independently undo the group’s strategy by changing their own settings without recording the change.

    Keep campaigns with incompatible goals apart. A prospecting campaign seeking new audience coverage and a narrow remarketing campaign seeking deliberate repetition may need different exposure strategies. Forcing both into the same group can make the aggregate metric look healthy while weakening one campaign’s actual job.

    Also separate the setting from assumptions about budget control. A group-level reach or frequency instruction does not automatically prove that budget, bidding, creative sequencing, or delivery priority will be coordinated in the way you expect. Rely on behavior you can observe in your account, not on what the feature name appears to promise.

    Measure delivery changes, not just cleaner reporting

    The important unresolved question is whether Video Campaign Groups will meaningfully coordinate delivery across campaigns or mainly provide aggregated reporting and deduplicated reach. Those are not equivalent benefits. Better reporting can expose waste, but only delivery changes can reduce that waste.

    Evaluate the beta in three layers:

    • Group outcome: For reach optimization, examine deduplicated group reach alongside group frequency. For frequency optimization, compare observed group frequency with the intended target while watching what happens to reach.
    • Business guardrail: Keep the outcome that matters for the campaign visible, whether that is qualified site activity, conversions, brand measurement, or another objective already used by your team. A group metric should not improve at the cost of the campaign’s purpose.
    • Delivery diagnostics: Inspect how spend, impressions, reach, and frequency are distributed across the campaigns. An acceptable group average can conceal a campaign that dominates delivery or another that has effectively stopped contributing.
    What you observeWhat it may meanWhat to do next
    Deduplicated reach expands while group frequency becomes less concentratedThe result is directionally consistent with reduced overlap and broader delivery.Confirm that the additional audience remains relevant and that the business guardrail has not weakened before increasing spend.
    Group frequency moves toward the target, but a campaign dominates deliveryThe aggregate target may be improving while the campaign mix becomes less useful.Inspect audience overlap, budgets, bids, eligibility, and campaign roles before accepting the result.
    Individual campaign reach totals look large, but deduplicated group reach is substantially smallerThe account has meaningful cross-campaign overlap.Use the deduplicated view for planning and stop presenting summed campaign reach as the size of the audience reached.
    Group reporting becomes clearer, but campaign delivery patterns barely changeThe immediate value may be measurement rather than active coordination.Use the visibility to restructure audiences or campaigns, but do not claim that automated optimization reduced wasted frequency.
    The group metric improves while the business guardrail deterioratesThe system may be satisfying the exposure instruction at the expense of audience or outcome quality.Hold expansion, diagnose the tradeoff, and revise the group membership or objective.

    Maintain a change log while testing. Record campaign additions and removals, audience edits, creative launches, bid changes, budget changes, and eligibility interruptions. Without that record, a before-and-after comparison can assign credit to the campaign group for a change caused elsewhere.

    Use cautious language when reporting results. A movement that is directionally consistent with better coordination is not the same as proof of incremental reach. If you changed several inputs at once or cannot see how delivery shifted, call the result inconclusive and refine the test.

    Key takeaways

    • Manage frequency at the level where audience overlap occurs. Campaign-level averages can hide repeated exposure across the account.
    • Use group-level reach optimization when your priority is reducing duplication and reaching additional eligible people.
    • Use a group frequency target when repetition is intentional and needs to be coordinated across campaigns.
    • Group campaigns by shared audience, funnel role, and business purpose rather than by video format alone.
    • Judge the beta by observed delivery changes and business guardrails, not by a cleaner group report.
    • Treat reported improvement as preliminary when other settings changed at the same time or delivery coordination cannot be verified.

    Your next move is to identify one coherent cluster of overlapping upper-funnel campaigns, document its current exposure pattern, and give the group a single measurable job. That limited rollout will tell you more than applying a frequency setting across the account and hoping the aggregate number improves.

    References


  • Google Merchant Center UCP Integrations: What to Enable

    Google Merchant Center UCP Integrations: What to Enable

    You have three separate decisions to make when Google’s UCP integration hub appears in Merchant Center. You can send a cart to your website, support checkout on Google, link customer identities, or adopt only the capabilities that fit your operation.

    The right choice depends less on what you can switch on than on where you can safely own the customer, order, and recovery experience. Use the framework below to choose a scope, test the handoffs, and measure whether UCP removes purchasing friction without creating an operational blind spot.

    What the UCP integration hub actually changes

    Google is gradually making the Merchant Center UCP integration hub available to eligible U.S. merchants. UCP stands for Universal Commerce Protocol. In this rollout, it acts as a connection layer between Google’s shopping experiences and a merchant’s commerce infrastructure.

    The meaningful change is modularity. An eligible merchant can select individual capabilities instead of accepting one predetermined checkout experience. That turns UCP configuration into a set of business decisions rather than a single technical integration.

    CapabilityWhat changes in the journeyYour release gate
    Cart transferThe shopper’s cart moves from Google to the merchant’s website, where the purchase can continue.The correct products, variants, quantities, prices, and context must survive the handoff.
    Native checkout on GoogleThe shopper can complete checkout within Google’s experience.Your order operation must reliably receive, fulfill, reconcile, support, cancel, and refund the resulting orders.
    Identity linkingThe shopper’s Google identity can be connected with the merchant’s customer relationship.The customer benefit, consent path, account-matching rules, unlinking process, and support recovery must be clear.

    Treat the last column as your own acceptance standard. The presence of a capability in Merchant Center tells you that it is available to configure; it does not prove that your downstream systems, policies, analytics, or support team are ready for it.

    For SEO, AEO, and GEO teams, the boundary matters. UCP is commerce infrastructure. It can shorten the distance between product discovery and purchase, including journeys in which AI agents help people research products, assemble carts, and transact. It should not be treated as a ranking switch, a replacement for Merchant Center feed quality, or a substitute for accurate product pages and structured data.

    Choose each capability by ownership and failure radius

    A modular ecommerce system separates identity, checkout, and fulfillment into bounded zones, with an amber warning contained inside the checkout area.

    Start with the customer journey you can operate reliably. A shorter path is valuable only when the order that emerges from it is accurate, observable, and recoverable.

    1. Consider cart transfer first when your website checkout is already the strongest part of the journey. It lets Google participate in discovery and cart creation while your existing site remains the purchase destination. Test the handoff as a data contract: the product identifier, selected variant, quantity, current price, availability, promotion context, and destination page must agree. Also define what the shopper sees when a price changes, an item sells out, or the cart cannot be reconstructed.
    2. Consider native checkout when your order operation can support a transaction completed outside your website. Map the entire order lifecycle before enabling it: creation, payment state, tax, shipping, inventory reservation, fulfillment, cancellation, returns, refunds, customer notifications, fraud review, and support. Do not assume that a native interface transfers responsibility for these functions. Confirm the division of responsibility for your particular setup.
    3. Consider identity linking when signing in produces a real customer benefit. That benefit might involve account continuity, saved preferences, loyalty, or post-purchase service, but the benefit must be explicit. Define how accounts are matched, what happens when identifiers disagree, how duplicate accounts are handled, how consent is recorded, and how a customer can unlink or recover access.

    The hub’s capability-by-capability selection model gives you a reason to avoid an all-at-once launch. Enable the smallest useful combination first. If cart transfer fails, you can investigate the cart contract. If identity linking and native checkout go live at the same time, an order problem may involve identity resolution, checkout state, or the order pipeline, making the cause harder to isolate.

    That sequencing is especially important for identity linking. It introduces customer-data, authentication, privacy, and support consequences that are different from the mechanics of moving a cart. Review it as its own workstream rather than treating it as a convenience setting attached to checkout.

    Build six release checks before changing the customer journey

    Six quality-control stations test product availability, cart transfer, identity, payment, order confirmation, and customer recovery along an ecommerce purchase path.

    You do not need to wait for a full implementation project before preparing. You do need a written acceptance plan. Build these six checks while access is rolling out:

    1. Confirm the actual scope in your account. Record which Merchant Center account, market, storefront, and capabilities are eligible. The rollout begins with eligible U.S. merchants, while plans for Australia and Canada have moved to a later schedule. Work from the controls present in your account rather than treating an announced market sequence as a guaranteed activation date.
    2. Define the catalog contract. Name the system that owns each product identifier, variant, price, currency, availability state, image, and fulfillment promise. The website, Merchant Center data, cart, and order record should refer to the same sellable item. If two systems can overwrite a value, document which one wins and when.
    3. Define the cart contract. Specify what must survive a transfer and what can be recalculated on arrival. Include quantity limits, variant selections, promotions, unavailable items, expired carts, and price changes. Write the customer-facing fallback for each failure; a silent empty cart is not an acceptable recovery path.
    4. Define the order contract. For native checkout, trace a successful order and every material exception through the systems your teams use. An order is not complete merely because payment appears successful. It must enter inventory, fulfillment, notifications, reporting, customer service, cancellation, return, and refund workflows with a stable identifier.
    5. Define the identity contract. Decide what data is linked, why it is needed, what consent is required, how long it is retained, and which team handles mismatches. Include duplicate accounts, shared email addresses, changed email addresses, revoked access, deletion requests, and support verification.
    6. Define observability and recovery. Assign an owner for integration errors, order discrepancies, customer complaints, and rollback decisions. Preserve enough identifiers to trace a journey across the surfaces you control without exposing unnecessary personal data. Document how you will pause a capability safely if failures rise.

    Use any preview, testing, or diagnostic path that your Merchant Center account makes available. If your account exposes only a broad production control, complete the data and operational checks before changing it. Do not discover your refund path, account-recovery rules, or missing order identifiers through the first customer complaint.

    Launch one capability at a time when the available controls permit it. Start with the smallest reversible product or operational scope supported by your setup. Keep a written record of the prior configuration, the activation time, the owner on duty, the expected signals, and the condition that triggers a pause.

    Measure the handoff, not just the final sale

    A conversion total can hide the exact friction UCP is meant to remove. Build a funnel that shows where an eligible journey stopped. Instrument the events available on the systems you control, then reconcile them with the commerce and order records available from the integration.

    • Eligible journey volume: the number of shopping journeys that could use the enabled capability.
    • Cart initiation and transfer: how many carts begin, how many handoffs are attempted, and how many arrive with usable contents.
    • Checkout progression: how many transferred or native journeys reach checkout, encounter an error, and complete.
    • Order reconciliation: whether each completed transaction produces one accurate order in the system of record, without omissions or duplicates.
    • Commercial consistency: discrepancies involving products, variants, quantities, price, availability, tax, shipping, discounts, or currency.
    • Operational consequences: cancellations, refunds, identity-recovery cases, integration-related support contacts, and manual corrections.

    Capture a baseline before launch. Compare the same journey before and after enablement where your data permits, and separate technical success from business success. A cart can transfer perfectly while conversion falls because the landing experience is confusing. Native checkout can increase completed orders while creating reconciliation work that erases the operational benefit.

    Website analytics alone will be incomplete when checkout finishes on another surface. Do not interpret a drop in site-recorded purchases as a drop in total purchases until native orders have been reconciled. Conversely, do not count an external checkout confirmation as a clean success until the corresponding order is present and actionable in your system of record.

    Keep search visibility and commerce performance in separate reporting layers. Monitor product discovery, landing-page visibility, feed health, and structured-data quality alongside the UCP funnel, but do not attribute a ranking change to UCP merely because the dates overlap. Its immediate job is to connect discovery, cart, identity, and transaction paths more effectively.

    Consistency is the point where the SEO and commerce teams meet. Use the same product identity, variant language, pricing state, availability, and merchant policy across Merchant Center, the website, structured data, cart, checkout, and order systems. UCP cannot compensate for contradictory facts moving through those systems; it can only make those contradictions reach the customer faster.

    Key takeaways

    • UCP in Merchant Center is a selectable integration layer, not one mandatory checkout model.
    • Choose cart transfer when your site checkout should remain the transaction destination and you can preserve cart accuracy through the handoff.
    • Choose native checkout only after the complete order, support, cancellation, return, and refund lifecycle works outside a website-completed purchase.
    • Review identity linking separately because it adds consent, account-matching, privacy, authentication, and recovery requirements.
    • Measure attempted handoffs, errors, discrepancies, and reconciled orders as well as conversions.
    • Do not treat UCP enablement as evidence of improved rankings; maintain product data, content, feeds, and structured data as separate visibility work.

    If the hub is already available in your account, begin with a capability decision and an acceptance checklist, not the activation control. If it is not available, prepare the catalog, cart, order, identity, and measurement contracts now. That work remains useful regardless of when eligibility reaches your market or account.

    References


  • How to Build Brand Trust for Better AI Search Visibility

    How to Build Brand Trust for Better AI Search Visibility

    Your brand can be technically discoverable and still fail the answer that matters: which option should the buyer trust? An AI search system may find your pages, mention your company, and even cite you without being willing to recommend you.

    That changes the work in front of you. Publishing more content will not repair invented expertise, inconsistent company facts, a chatbot that makes promises your support team cannot keep, or public conversations dominated by unresolved complaints. Better AI search visibility starts by making the evidence around your brand accurate, consistent, and useful enough to support a recommendation.

    Separate being found from being trusted

    Visibility is not a single outcome. A brand can be retrieved as relevant, cited as a factual source, included as an option, recommended as the preferred option, or mentioned with a warning. Treating all five outcomes as a ranking position hides the reason you are winning or losing.

    When you diagnose an AI answer, examine three layers of evidence:

    • Identity evidence: Is it clear who the company is, who created the content, and who is responsible for the claims?
    • Claim evidence: Are product capabilities, policies, qualifications, and comparisons specific enough to verify?
    • Experience evidence: Do customer-facing systems and independent discussions support or contradict what the company says about itself?

    Your website controls much of the first two layers. The third often develops elsewhere. A customer can encounter a bad answer in your chatbot, describe it in a community, and create a public record that later competes with your product page. That does not mean every complaint changes an AI answer. It means you cannot evaluate visibility by auditing owned pages alone.

    LastPass illustrates the persistence problem. Reddit discussions about past security incidents continued to rank for the brand name and were pulled into ChatGPT answers. The practical lesson is not to suppress criticism. It is to watch for recurring trust failures, resolve the underlying issue, and make accurate corrective information easy to find.

    Make every owned claim verifiable

    Two researchers inspect luminous connections between a geometric block, an unmarked document, a product sample, a medallion, and a clock.

    Trust begins with an unglamorous question: is the page honest about who made it? Google now explicitly treats AI-generated headshots, invented names, and false credentials used to simulate human expertise as deceptive authorship information. Its guidance says deception makes a page untrustworthy to users and automated quality systems and signals low quality.

    You do not need a celebrity expert on every byline. You need an accurate chain of responsibility. Audit your content templates with these checks:

    • Use a person’s name only when that real person created, substantially shaped, or took editorial responsibility for the work.
    • Keep biographies factual. List roles, experience, and credentials you can substantiate rather than qualifications chosen to make a page look authoritative.
    • Do not label someone a reviewer unless a meaningful review occurred. Record what the review covered internally so the label has an operational meaning.
    • If the organization is genuinely responsible for the content, say so. A truthful organizational byline is stronger than a fictional personal profile.
    • Explain how information was produced or checked when that process helps the reader judge reliability. Do not use a vague process statement to disguise absent human oversight.
    • Make publication and update dates reflect real editorial events. A new date on unchanged material is not evidence of freshness.

    Use schema as a consistency check, not a credibility generator

    Structured data can clarify the identity and relationships already visible on a page. It cannot turn a fabricated expert into a trustworthy author. Your Article, Person, and Organization markup should agree with the byline, biography, About page, editorial policy, and company details a visitor can see.

    For each important template, compare the visible page with its JSON-LD field by field. Check the author type, name, URL, publisher, publication date, modification date, and any identity links. Remove a field when you cannot support it. Do not add credentials or sameAs references merely because a schema tool offers an empty box for them.

    This catches a common trust leak: every individual statement looks plausible, but the collection does not describe one coherent entity. A shortened brand name in one place, an obsolete company description in another, and an unrelated author profile in the markup can leave both people and automated systems with avoidable ambiguity.

    Treat your chatbot as a reputation surface

    A customer faces a translucent digital kiosk as light paths connect it to a service team, with one clear path and one warning-marked path.

    A commerce or support chatbot is not only a conversion tool. It is also where customers test whether your brand’s promises survive contact with a real question. A poor bot experience can therefore affect AI search visibility as well as the immediate sale.

    The mechanism is straightforward. The bot gives an inaccurate or evasive answer. The customer cannot reach a person or verify the claim on your site. They take the question to a forum, review platform, or social conversation. The resulting public explanation may be clearer and more durable than anything you published yourself.

    Audit the bot around complete customer tasks, not isolated response quality:

    1. Select real tasks. Use recurring questions from bot logs, sales conversations, support tickets, and on-site search. Include questions that affect eligibility, pricing, returns, compatibility, security, delivery, and cancellation when those apply to your business.
    2. Run each task to its endpoint. Record the first answer, follow-up questions, linked page, escalation option, and final resolution. A friendly opening does not compensate for a dead end later in the exchange.
    3. Compare the answer with the source of truth. Check the bot against current product pages, policy pages, documentation, and the answer a trained employee would give. Flag unsupported promises and contradictions before rewriting the tone.
    4. Test the recovery path. Deliberately ask an ambiguous question, challenge an answer, and request a human. The bot should acknowledge uncertainty and provide a usable next step instead of inventing certainty.
    5. Turn recurring failures into content work. If customers repeatedly need an external discussion to understand a policy, improve the policy page and the bot’s retrieval source. Do not treat the symptom as a prompt-writing problem alone.

    Keep a simple failure log with the customer task, incorrect answer, correct answer, responsible owner, affected page, and resolution status. This connects conversion operations with reputation and AI visibility. It also prevents separate teams from fixing the bot, help center, and structured data in incompatible ways.

    Earn third-party evidence without manufacturing it

    Communities can give buyers and AI search systems context that an About page cannot. They can also expose promotional behavior quickly. The useful goal is not to plant brand mentions. It is to contribute answers that remain valuable even if the reader never clicks your profile.

    Start only after your own site is worth citing. One documented B2B SaaS workflow begins with a set of 200 to 500 SEO keywords and maps them to roughly 150 relevant subreddits. Those figures describe that operating model, not a quota every company should copy. The transferable method is to connect existing buyer questions with communities where those questions already receive substantive answers.

    Use the following participation rules to protect trust:

    • Work with real accounts. An employee can participate as a knowledgeable person, but the account should not exist solely to promote the employer. Build a genuinely useful history and disclose the relationship whenever it is relevant to the recommendation.
    • Stay with live conversations. The same practitioner team limits engagement to threads less than 20 days old because returning to old conversations can look unnatural and increase moderation risk. Treat that as a conservative operating rule from one program, not a universal Reddit ranking factor.
    • Answer the question completely. Give the useful explanation before mentioning a product. If the comment only works when the reader follows your link, it is probably promotion rather than an answer.
    • Match the community’s language. Use direct descriptions, real constraints, and relevant experience. Corporate copy and polished slogans make a comment less credible, not more.
    • Earn the right to start a thread. Original posts work better after the account has participated constructively. An AMA or a detailed solution to a recurring pain point has a clearer community purpose than a disguised announcement.
    • Do not coordinate fake praise. Sockpuppets, invented customers, and concealed affiliations create the same underlying problem as fake author profiles: apparent evidence with no truthful person behind it.

    For an active reputation program, search your brand name on Reddit every day and log the threads that introduce a new factual claim, recurring complaint, or comparison. Respond only when you can add a correction, resolution, or genuinely useful context. A defensive reply can amplify the very evidence you want to displace.

    Community work is a secondary layer. If your product facts, policies, authorship, and customer experience remain weak, more participation simply gives the weaknesses more places to surface.

    Run a trust-first AI visibility audit

    Build a fixed prompt set around the decisions your buyers actually make. Include category discovery, use-case fit, comparisons and alternatives, risk or support concerns, and direct questions about your brand. Reuse the same prompts so you can distinguish a meaningful change from a different question.

    For each run, record the platform or model, date, exact prompt, whether the brand appeared, how it was characterized, whether it was recommended, any warning language, and the cited URLs. The citation list is often more diagnostic than the mention itself because it shows which evidence shaped the answer.

    Observed patternLikely evidence gapFirst action
    Your brand is absent from an unbranded category answerThe available material may not answer that category or use case precisely enoughPublish a focused, factual answer on your own site and make its ownership clear
    Your brand is mentioned but not recommendedRelevance exists, but trust, fit, or comparative evidence is weakInspect cited alternatives, verify your claims, and identify missing proof or unresolved objections
    Your brand appears with a warningNegative experience evidence is outweighing owned claimsTrace the warning to its cited or likely origin, fix the underlying issue, and publish an accurate resolution
    The answer contains outdated or conflicting factsYour entity details, policies, or product information are inconsistentAlign visible pages, feeds, profiles, and JSON-LD around one current source of truth
    The answer cites you but describes you inaccuratelyYour page may be extractable without being sufficiently explicitRewrite ambiguous passages so the qualification, scope, and responsible entity appear together

    Prioritize by trust risk, not implementation convenience. Remove deception and factual errors first. Repair broken customer journeys next. Resolve contradictions across owned properties after that. Then strengthen missing evidence and improve schema. A markup change is quick, but it is the wrong first move when the underlying claim is false or the customer experience disproves it.

    Assign each issue to an owner who can change the root cause. Content teams can clarify a page, but they cannot repair a returns process. SEO teams can expose inconsistent entities, but they cannot validate a security claim. The audit becomes useful when it routes each trust gap to the team with authority to close it.

    Key takeaways

    • AI search visibility includes retrieval, citation, recommendation, and warning outcomes; a mention alone does not prove trust.
    • Real authorship, supportable credentials, and JSON-LD that matches the visible page give your owned claims a coherent identity.
    • Chatbot failures can become public reputation evidence, so audit complete customer tasks and escalation paths rather than tone alone.
    • Community visibility should be earned through real accounts and complete answers after your own site is worth citing.
    • Measure the language and citations around your brand, then fix deception, broken experiences, and contradictions before optimizing presentation.

    Start with a small, fixed set of buyer prompts and follow each answer back to the evidence supporting it. Fix the highest-risk contradiction you find, rerun the same prompts, and keep the record. That turns AI visibility from a mention count into a practical trust-improvement loop.

    References


  • How to Make AI-Assisted PPC Optimize for Real Profit

    How to Make AI-Assisted PPC Optimize for Real Profit

    Your PPC dashboard can show a healthy return while the campaign quietly consumes the margin you meant to keep. The usual problem is not that automated bidding failed. It is that the bidding system was given revenue, lead counts, or convenient proxy values and asked to treat them as business value.

    You can fix that without abandoning automation. Start by defining the economics outside the ad platform, translate them into usable conversion values and bidding limits, and then let AI control only the decisions it has enough reliable data to make.

    Start with the profit floor, not the platform target

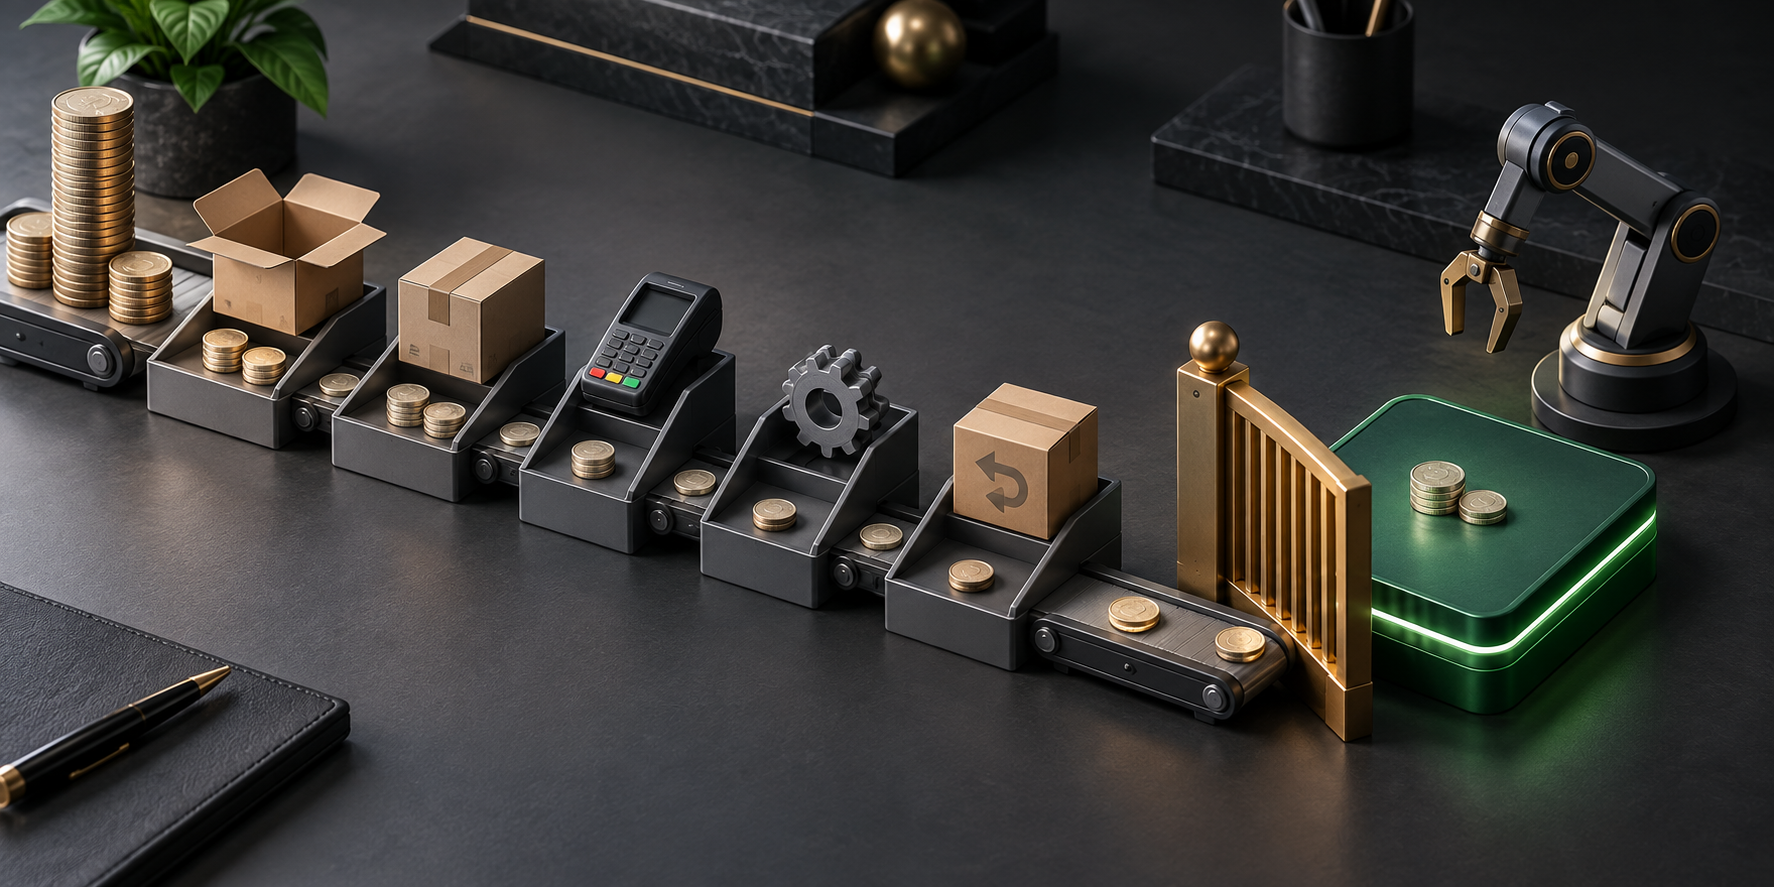
    Coins pass through trays representing product, shipping, payment, service, and return costs before the remainder reaches a protected profit platform.

    Revenue ROAS answers a narrow question: how much reported revenue did you receive for each unit of ad spend? It does not tell you how much money remained after the product, service delivery, transaction, fulfillment, return, and advertising costs attached to that revenue.

    For a campaign whose conversion value represents revenue, the basic relationship is:

    Break-even ROAS = 1 / pre-ad profit margin expressed as a decimal.

    If the relevant margin is 15%, the break-even ROAS is about 6.67, or 667%. At that point, $6.67 of revenue produces about $1 of profit before advertising for every $1 spent on ads. The campaign has covered the advertising cost under that simplified model, but it has not created additional post-ad profit.

    That distinction matters: 667% would be the economic floor in this example, not automatically a sensible operating target. A target ROAS is also a bidding instruction, not a guarantee that every order, day, or campaign will achieve that return.

    If you want a defined post-ad contribution, build it into the calculation. Let m represent the pre-ad margin as a share of revenue and p represent the share you want to retain after ad spend. Your maximum ad-spend share is m – p, so the required ROAS is 1 / (m – p). This forces the profit requirement into the target instead of adding an arbitrary cushion to the break-even number.

    Before applying that formula, settle four inputs with whoever owns the financial numbers:

    1. Confirm what conversion value means. If it is revenue, a revenue-based margin formula can work. If it is already a profit proxy or weighted lead value, applying the same margin again will distort the target.
    2. Define the pre-ad margin consistently. Record which costs are included. Shipping, returns, payment fees, and overhead can materially change true profitability, so a label such as average margin is not enough.
    3. Choose the amount that must remain after advertising. Break-even may be useful for diagnosis, but it is not the same as the return the business needs.
    4. Separate materially different economics. One average can conceal large differences among products, customers, and orders. Do not let high-margin sales make low-margin traffic look sustainable unless that blend is deliberate.

    This calculation gives AI a boundary grounded in your business. It does not make the platform profit-aware by itself.

    Give the bidding system values that survive a finance review

    An automated bidder can optimize only the value and events it receives. If every order is reported as equally valuable, it cannot infer that one product leaves ample margin while another barely covers fulfillment. If every submitted form is called a lead, it cannot know which inquiries can become revenue.

    For ecommerce campaigns

    Choose one value architecture and keep its logic intact:

    • Revenue values with margin-based targets: Report actual revenue, group products or campaign portfolios with reasonably similar economics, and calculate the target from the relevant margin. This preserves the familiar meaning of revenue ROAS.
    • Profit-proxy values: Pass a value that already reflects the economics you want the bidder to favor. Once you do that, stop interpreting the resulting return as revenue ROAS and do not reuse a target calculated on the assumption that conversion value equals revenue.

    The dangerous middle ground is to report revenue, use one blended margin across dissimilar products, and call the result profit optimization. That gives the automation a precise target built on an imprecise economic premise.

    For lead-generation campaigns

    Low-volume lead generation has a different problem: the final sale may arrive too late or too rarely to supply enough bidding signals. Accounts that cannot approach the working benchmark of about 30 conversions in 30 days can use carefully valued micro-conversions to expose progress through the funnel.

    A commercial shipping funnel provides a useful illustration of the structure:

    Those amounts are an example, not a template to copy. Your values should represent the relative economic worth of each stage. A form start is not $10 of booked revenue; it is a bidding signal. If starts are abundant and their assigned value is too generous, the system can hit its target by finding people who begin forms rather than prospects who become qualified opportunities.

    Check three things before using a value ladder:

    • Whether each stage predicts a more valuable business outcome, rather than merely being easy to track.
    • Whether one person can trigger several stages and, if so, whether the cumulative value reflects your intended bidding logic.
    • Whether the final qualified, proposed, and closed outcomes return to the ad platform so earlier assumptions can be compared with reality.

    When your sales system can provide lifecycle outcomes, send them back. Google and Microsoft support integrations with systems such as HubSpot for passing later-stage data into advertising workflows. The important part is not the connector itself. It is replacing a platform’s early proxy with the closest available version of actual customer value.

    Micro-conversions can help campaigns using conversion-based bidding, Performance Max, or AI Max obtain earlier signals. They can also make performance worse when their values are detached from qualification and revenue. More data is useful only when the data teaches the system the right preference.

    Choose how much control AI gets, one decision at a time

    A marketing analyst oversees a modular advertising console where some control units are automated and others remain under human control.

    You do not need one account-wide answer to whether you trust AI. Treat trust as permission granted for a specific job. A practical operating model separates AI-informed, AI-assisted, and AI-delegated work.

    Operating levelWhat AI doesWhat you retainGate before expanding
    AI-informedSurfaces search-term, variant, forecasting, or creative insightsYou choose and apply every campaign changeThe insight maps to a measurable business problem
    AI-assistedRuns a selected task such as bidding or asset generationYou define value, budget, scope, exclusions, and review criteriaTracking is reliable and the task has enough useful signal
    AI-delegatedOptimizes a bounded task end to endYou monitor economics, data quality, and exceptionsA controlled test beats the existing method on business outcomes

    This model prevents a common mistake: treating automated bidding, generated creative, and automated reporting as one indivisible package. They solve different problems and deserve separate permissions.

    Bidding needs signal density and economic constraints

    Bidding is often the easiest task to automate because the system can make more auction-time decisions than a person. It still needs enough useful events. Manual bidding can remain reasonable for low-volume campaigns and narrow industries where sparse conversion data gives automation little to learn from.

    Budget can become a hidden data constraint. One practical setup check uses a budget of at least 10 times the expected cost per click, based on the need to obtain roughly 10 engagements before depending on a conversion rate better than 10% for nonbranded search. Treat that as a diagnostic, not a universal spending rule. If the economics cannot support that traffic, changing the bid strategy will not repair the underlying volume problem.

    Search terms show where automation is buying growth

    Use the matched-by view in search-term reporting to inspect how often a keyword enters auctions through close variants. A high share of stable, cost-effective variants can indicate a useful auction entry point. Large swings in variant mix and bid cost can mean that the same keyword is pulling the campaign into materially different auctions.

    The action is not necessarily to bid on every variant. Choose the keyword or target that gathers enough relevant demand to produce learning, then exclude or restructure traffic that has a different economic purpose. Consolidation helps only when the combined searches deserve the same value signal and target.

    Creative and reporting still need human definitions

    AI-generated assets can increase the number of messages and placements available to a campaign. You still own brand fit, factual accuracy, offer terms, and the landing-page promise. A bidding system cannot compensate for creative that attracts the wrong intent.

    Reporting has a similar division of labor. Automation can assemble platform metrics, but you must translate them into revenue quality, margin, sales progression, and post-ad contribution. A report that ends at platform ROAS is incomplete when the decision in front of you is whether to invest more money.

    Run one test and judge it on post-ad contribution

    You do not have to delegate the whole account to learn whether automation can improve it. Compare the automated approach with the current strategy in a bounded campaign or portfolio where you can keep the economics and tracking definitions stable.

    1. Write the baseline before changing anything. Record spend, reported revenue or lead value, realized margin, qualified outcomes, and post-ad contribution. If some figures arrive later, identify that lag.
    2. State the hypothesis. Examples include finding more conversions above the profit floor, improving qualified opportunity volume within budget, or preserving contribution while increasing scale.
    3. Change one layer of control. Test bidding automation without simultaneously redefining every conversion, rebuilding all creative, and widening targeting. Otherwise, you will not know what caused the result.
    4. Freeze the value definitions during the comparison. If a tracking correction is unavoidable, mark the break and avoid treating the periods as directly comparable.
    5. Watch the traffic and outcome mix. Inspect search terms, product mix, funnel stages, and closed outcomes rather than accepting an aggregate return at face value.
    6. Expand only after the business metric improves. A platform target being met is not sufficient if margin mix, lead quality, or total contribution deteriorates.

    Read combinations of metrics, not isolated wins:

    • ROAS rises while post-ad contribution falls: inspect the product or customer mix and confirm that reported value still maps to the margin used in the target.
    • Conversion volume rises while qualified outcomes fall: reduce the influence of weak micro-conversions and return later sales stages to the platform.
    • Return per conversion rises while total contribution falls: the target may be restricting volume so severely that efficiency improved but the business result did not.
    • Volume and post-ad contribution improve together: broaden the test carefully while keeping the same value definitions and monitoring for mix changes.

    If it appears in your account, a Google Ads beta can translate an average profit margin into a suggested Target ROAS. It can also show weekly estimates for clicks, revenue, ad spend, and total profit as you change the target. Use those figures for scenario planning before applying a setting, not as evidence that the campaign will deliver the estimate.

    The calculator assumes that the reported conversion value is revenue and that the supplied average margin represents the campaign well. It does not directly make Google Ads optimize bids for profit. Your value design, segmentation, cost completeness, and later outcome imports still determine whether the target represents the business you actually have.

    Key takeaways

    • Calculate a break-even ROAS from the pre-ad margin when conversion value represents revenue, then add the post-ad contribution the business needs.
    • Do not apply a revenue-based Target ROAS formula to conversion values that already represent profit proxies or weighted lead values.
    • Use micro-conversions only when their relative values reflect progress toward qualified revenue, and replace proxies with offline outcomes when possible.
    • Grant AI control by task: insight first, selected automation second, and end-to-end delegation only after a bounded test.
    • Judge automation on post-ad contribution and outcome quality, not platform ROAS or conversion count in isolation.

    Your next step is small: take one active campaign, write down what its conversion value actually represents, calculate its economic floor, and compare that floor with the target now in the platform. Any gap you find is the first profitability problem to solve before asking AI to spend more.

    References


  • Product-Led SEO Measurement: From Rankings to User Value

    Product-Led SEO Measurement: From Rankings to User Value

    You shipped a template change, internal-link module, or new landing-page experience. Impressions and clicks moved, but the product team asks the question the SEO dashboard cannot answer: did the release help anyone accomplish something valuable?

    Product-led SEO measurement closes that gap. It connects search exposure to the on-page experience, the user’s next meaningful action, and the business decision that follows. The result is not a larger dashboard. It is a measurement system that tells you whether to keep, change, expand, or roll back what you built.

    Start with the decision your dashboard must support

    Before choosing metrics, write down the decision you expect the data to inform. A useful decision statement looks like this: “If eligible organic visitors use the new experience and complete the intended next step without harming search visibility or page performance, expand it to the remaining eligible pages.”

    That sentence establishes the audience, behavior, desired outcome, guardrails, and next decision. Without it, teams tend to collect every available number and debate the meaning after launch.

    Treat the SEO change as a product capability. Define the problem, why it matters, the intended outcome, and the requirements that must survive implementation. Leave room for developers to choose an approach that fits the codebase, but be exact about observable SEO requirements. If links must appear in rendered HTML, state that. If every eligible page needs a canonical URL or a particular content element, make it testable.

    For a related-content module, the measurement brief might contain:

    • User problem: A visitor reaches a useful page from search but encounters a dead end before the next relevant question.
    • Hypothesis: Contextual links will help eligible visitors continue to a relevant page.
    • SEO requirement: The links must be present in rendered HTML and point to indexable destination URLs.
    • User outcome: A visitor selects a relevant recommendation and continues the journey.
    • Business outcome: More eligible organic journeys reach the qualified action that matters for this experience.
    • Guardrails: The release must not introduce broken links, rendering failures, inappropriate destinations, or a material deterioration in the page experience.

    Notice what is missing: “increase traffic” is not the whole objective. Traffic is one stage in the mechanism. The visitor’s ability to use the page is another.

    Build a metric tree from search exposure to product value

    Abstract branching pathway connecting search exposure lights to interactions, product actions, and a glowing value core.

    A product-led scorecard needs several layers because no single metric can explain the full journey. Rankings can diagnose discoverability, but they cannot tell you whether a visitor found the page useful. Conversions represent value, but they can hide a failed rollout when only a small share of eligible pages received the feature.

    Measurement layerQuestionUseful signalsWhat the layer helps diagnose
    AvailabilityDid the intended experience actually ship?Eligible pages, deployed pages, valid rendered components, crawlable links, error statesRelease and implementation failures
    Search exposureCould searchers discover the eligible pages?Indexed-page coverage, impressions, query coverage, average position, clicksDiscovery, indexing, and search-demand changes
    User behaviorDid organic visitors use the experience as intended?Feature views, interactions, path continuation, return to results where measurable, completion of the intended next stepRelevance, comprehension, placement, and usability
    Product or business valueDid the journey produce a qualified outcome?Sign-ups, purchases, qualified enquiries, subscriptions, or another explicitly defined value eventWhether improved discovery and behavior matter to the business
    GuardrailsWhat might the release have damaged?Rendering errors, broken destinations, unwanted indexation, page-performance deterioration, accessibility failuresCosts hidden by an attractive headline metric

    Connect these layers as a metric tree rather than presenting them as an unrelated set of charts. The business outcome sits at the top. The user behavior that should produce it sits beneath it. Search exposure explains how people reach the experience. Availability and guardrails tell you whether the product operated as designed.

    You can then define a rate whose numerator and denominator match the decision. For example:

    Organic activation rate = eligible organic landing sessions that complete the qualified action / eligible organic landing sessions

    “Eligible” matters. If the feature appears only on one template, including every organic session in the denominator dilutes the effect and can make a successful release look irrelevant. Conversely, reporting only people who interacted with the feature excludes visitors who saw it and ignored it. That turns adoption into a precondition and overstates performance.

    Keep raw counts beside rates. A rising conversion rate with sharply lower eligible traffic may still produce fewer total outcomes. A growing outcome count with a flat rate may simply reflect stronger search demand. You need both views to distinguish efficiency from scale.

    Instrument the feature, not just the pageview

    A pageview confirms that a URL loaded. It does not confirm that the feature was present, visible, relevant, or usable. Product-led measurement therefore needs an explicit event and validation plan for the capability you changed.

    For every important event, document:

    • Name: Use one stable name that describes the action rather than a campaign slogan or temporary design.
    • Trigger: Specify exactly what must happen. A component rendered, entered the viewport, received a click, and led to a successful destination are different events.
    • Properties: Include the page template, component type, destination class, release identifier, and eligibility state needed for analysis.
    • Deduplication: Decide whether repeated actions in one journey count once or multiple times.
    • Failure behavior: Record what happens when the component has no recommendation, returns an error, or points to an invalid destination.
    • Privacy boundary: Do not place personal or sensitive information in event names, URLs, or free-text properties.

    Then separate three states that dashboards often collapse:

    • Available: The feature was deployed to an eligible page and met its technical requirements.
    • Exposed: A visitor had a genuine opportunity to encounter it.
    • Adopted: The visitor used it and completed the intended behavior.

    This distinction makes diagnosis much faster. Low interaction is not a relevance problem if the component failed to render. High interaction is not necessarily valuable if visitors repeatedly hit broken destinations. Strong downstream outcomes among users do not prove the rollout worked if most eligible pages never received the feature.

    Validate instrumentation before evaluating impact. Check that an eligible page is classified correctly, the component appears in rendered HTML where required, events fire only on their defined triggers, properties contain expected values, destination URLs resolve correctly, and analytics can isolate the release cohort. Record the deployment in your reporting timeline so later changes are not mistaken for unexplained movement.

    Search data and product analytics describe different parts of the journey. Search Console impressions and clicks should not be forced to reconcile exactly with analytics sessions or users. Keep the systems connected through common dimensions such as landing page, country, device, query class, template, and release cohort, while preserving the meaning of each metric.

    Evaluate releases with cohorts, segments, and guardrails

    Two parallel release-testing lanes carry grouped user figures toward task outcomes within illuminated safety rails and a final decision platform.

    Comparing the whole site’s performance before and after a release is rarely enough. Search demand, rankings, site changes, promotions, seasonality, and unrelated product work can move during the same period. Build the evaluation around the pages and visitors that could actually be affected.

    Define the analysis cohort before opening the results:

    • List the eligible URLs or the rule that identifies them.
    • Record which URLs received the release and when.
    • Create a credible comparison group when one exists, using pages with similar purpose, template, demand pattern, and prior performance.
    • Preserve a pre-release baseline for the same metrics and segments.
    • Exclude known migrations, outages, redirects, or other changes that make the groups incomparable.
    • Choose the primary outcome and guardrails in advance so the interpretation does not change to fit the result.

    If you run a controlled test, keep the experimental unit clear. A page-level test should be analyzed by its assigned page cohort, not retroactively by whichever visitors converted. Check that search engines and users receive stable, coherent experiences, and do not use URL, canonical, redirect, or indexing changes casually as testing machinery. Those changes can alter discoverability and contaminate the result you are trying to measure.

    Segmentation should answer a plausible mechanism, not create an endless hunt for a favorable slice. Useful cuts commonly include branded versus non-branded demand, country, device, query intent, new versus established pages, and page template. Google Search Console can now combine selected countries in its performance reporting, which makes regional groupings easier to inspect without first exporting and grouping them elsewhere.

    Predefine the segments that could change the decision. If mobile layout determines whether the feature is visible, device is necessary. If a release serves a defined group of markets, combined-country reporting is relevant. If neither condition applies, adding those cuts may only fragment the data.

    Read the layers together when results arrive:

    • Availability fails: Stop interpreting user or business outcomes. Fix the rollout or instrumentation first.
    • Exposure rises but qualified actions stay flat: Inspect intent match, page promise, usability, and the relevance of the next step.
    • Traffic stays flat but activation improves: The release may have improved the experience without changing discoverability. Decide whether that product value justifies expansion.
    • Interaction rises but value does not: The feature may attract attention without advancing the journey. Review destination quality and event definitions.
    • Outcomes rise while a guardrail deteriorates: Do not declare an uncomplicated win. Quantify the downside and determine whether the experience needs revision before expansion.
    • Only one segment improves: Confirm that the segment was expected, large enough to matter to the decision, and not selected after inspecting many alternatives.

    Use language that matches the evidence. An uncontrolled before-and-after movement is an observation, not proof that the release caused it. A well-matched comparison strengthens the case. A properly designed experiment can support a stronger causal conclusion. The dashboard should make those evidence levels visible instead of presenting every green arrow with equal confidence.

    Finally, design the measurement so the next version remains possible. Stable eligibility rules, release identifiers, reusable events, and template-level dimensions let another team extend the capability without rebuilding the reporting model. That is the practical difference between a launch report and a product measurement system.

    Key takeaways

    • Begin with the decision the data must support: keep, revise, expand, or roll back the release.
    • Measure availability, search exposure, user behavior, product value, and guardrails as connected layers.
    • Use the eligible audience as the denominator; neither all site traffic nor feature clickers alone represent the true opportunity.
    • Instrument whether the capability was available, exposed, and adopted instead of relying on pageviews.
    • Analyze affected page cohorts and predefined segments, while treating uncontrolled before-and-after changes as observations rather than causal proof.
    • Keep raw totals beside rates and read gains against technical, accessibility, and experience guardrails.

    For your next SEO release, write the decision statement and metric tree before the implementation ticket is finalized. If the team cannot say what result would change its next action, another dashboard widget will not solve the problem. A clear decision, an eligible cohort, and a verified path from search exposure to user value will.

    References


  • Google Crawl-to-Serving Timelines: How to Diagnose Delays

    Google Crawl-to-Serving Timelines: How to Diagnose Delays

    You changed a page, but Google still shows the old title, selects another canonical, omits the URL, or leaves its rankings unchanged. It is tempting to call every one of those outcomes a crawling delay. That label is too broad to tell you whether to wait or intervene.

    Treat search visibility as a sequence of handoffs. First identify the last handoff that completed. Then investigate the next one. This gives you a defensible timeline and keeps you from changing a page repeatedly while Google is still processing an earlier version.

    A crawl is only the first handoff

    An updated webpage moves from a retrieval machine through scanning, archive, comparison, and display stages in a digital facility.

    There is no universal timer that starts when you press Publish and ends when the page appears exactly as intended in search. Several distinct events have to occur:

    1. Discovery: Google learns that the URL exists or has changed.
    2. Crawling: Google requests the URL and receives a response.
    3. Rendering and processing: Google evaluates the returned document, including content that depends on rendering.
    4. Indexing and canonicalization: Google determines what the page represents, whether it belongs in the index, and which URL should represent substantially similar content.
    5. Serving: Google decides whether and how to show the indexed result for a particular query.

    Passing one stage does not prove that the next stage has finished. A Googlebot request in your server logs proves a fetch occurred; it does not prove indexing. An indexed URL is eligible to appear, but it is not guaranteed to rank for the query you care about. A result appearing in search does not guarantee that Google will use your preferred title, snippet, canonical, or structured-data presentation.

    Discovery, refreshes, sitemap processing, robots.txt controls, rendering, indexing, link annotations, removals, canonicalization, structured data, titles, snippets, core updates, and spam updates all have their own typical and slowest processing bands. Your deployment time therefore is not a reliable prediction of when every downstream search signal will change.

    Set your expectation from the change you made

    The right clock depends on what changed. Before diagnosing a delay, name the exact search outcome you expect.

    • A new URL must be discovered, crawled, processed, considered for indexing, and then served. Finding it in a sitemap is only an early step.
    • Updated body copy requires another crawl and another round of processing. The live page can be correct while Google’s stored understanding still reflects an earlier version.
    • A title or description change is not complete merely because Google has fetched the page. Serving systems still decide what representation is useful for a query, so your supplied text may not be shown verbatim.
    • A canonical change asks Google to reconsider a cluster of related URLs. The canonical element matters, but internal links, redirects, sitemap entries, and duplicate-page signals should point in the same direction.
    • A robots, noindex, or removal change depends on Google being able to encounter and process the relevant control. Do not block a URL in robots.txt and assume Google can then fetch a page-level noindex directive from it.
    • Structured-data changes require valid markup to be found and processed. Validity can establish eligibility for a search feature; it does not guarantee that the feature will be served.
    • Internal-link changes can affect discovery and link annotations, but they do not create an immediate ranking promise.
    • A sitewide ranking change may belong to a broader ranking or spam-system rollout rather than the crawl status of one page.

    Use a typical range as a planning expectation and a slowest range as a prompt to investigate. Neither is a service-level guarantee. One spam-update benchmark put a typical change at one to two days, while the September 2026 spam update was expected to roll out over two weeks. Resubmitting one URL cannot shorten a system-level rollout. Rollout duration and URL-processing time answer different questions.

    Diagnose the symptom before deciding to wait

    Do not begin with the age of the change. Begin with the observable mismatch between the live page and Google’s current state.

    What you observeHandoff to inspectWhat to do next
    No crawl or discovery signal for the URLDiscovery and accessConfirm the URL returns the intended response, is not accidentally blocked, appears in an appropriate sitemap, and is linked from a crawlable page that Google already knows.
    Google fetched the URL, but important content is absent from the processed pageRenderingCompare the initial HTML with the rendered output. Make essential content and links available reliably, and fix failed or blocked resources rather than waiting for another identical render.
    The page is crawled, but another URL is selected as canonicalCanonicalizationCheck for conflicting canonical elements, redirects, internal links, sitemap URLs, and near-duplicate pages. Align those signals before requesting another crawl.
    The correct URL is indexed, but its title, snippet, or rich-result treatment is stale or differentServing and presentationVerify that the current HTML contains the intended information and that structured data is valid. Then allow time for reprocessing, while remembering that Google can generate a query-specific presentation.
    The indexed page is current, but impressions or rankings have not improvedRanking and query fitStop treating the issue as crawl latency. Examine whether the page satisfies the target intent, offers distinctive information, and has enough internal prominence and authority to compete.
    Many pages shift during a named search updateSystem rolloutSeparate rollout monitoring from page-level debugging. Avoid drawing a final conclusion from an incomplete rollout or making several unrelated sitewide changes at once.

    Google Search Console can help you locate the handoff. For an affected URL, compare the indexing status, last crawl information, Google-selected canonical, and inspected page with the live version. Server logs can confirm whether Googlebot requested the URL. A rendered-page check can reveal whether essential content was available during processing.

    Interpret each signal narrowly. A successful live test shows that Google can access the page now; it does not establish what happened during an earlier fetch. A crawl in the logs establishes retrieval, not indexing. An indexing status establishes index state, not rankings. Keeping those distinctions intact prevents false diagnoses.

    Build a release log that preserves the evidence

    Three preserved webpage versions are arranged beside a server model, clock, camera, archive sleeves, and magnifying glass.

    A useful crawl-to-serving timeline begins with your own deployment record. Without one, teams tend to compare today’s search result with an uncertain memory of what changed and when.

    1. Record the deployment. Save the timestamp, affected URL or template, old state, new state, and the specific result you expect Google to change.
    2. Classify the expected handoff. Decide whether success means discovery, a fresh crawl, corrected rendering, indexing, canonical selection, a new search presentation, or a ranking response.
    3. Verify production immediately. Check the response status, final URL after redirects, canonical element, robots directives, robots.txt access, rendered main content, internal links, and sitemap entry where relevant.
    4. Capture a baseline. Save the current Search Console state and relevant server-log evidence. If you later see a different crawl date or canonical, you will know which stage moved.
    5. Request reprocessing only when it helps. An indexing request can encourage another look at a limited set of important URLs, but it does not remove the later indexing, canonicalization, ranking, or serving decisions.
    6. Change one cause at a time. Rewriting content, changing canonicals, altering internal links, and resubmitting the URL together may produce movement, but you will not know which intervention mattered.
    7. Escalate by pattern. One delayed URL points toward page-level access, content, duplication, or canonical signals. A delayed template group points toward rendering, directives, linking, or sitemap generation. A sitewide movement may require update-level analysis.

    Repeatedly requesting indexing without correcting a contradictory signal is not a diagnosis. Neither is changing the page every day. Both actions muddy the sequence you need to observe. Once production is technically sound, preserve the version long enough to see whether the next handoff completes.

    Key takeaways

    • Crawl-to-serving is a chain of separate processes, not one countdown from publication.
    • A crawl proves retrieval. It does not, by itself, prove rendering, indexing, canonical selection, ranking, or the final search presentation.
    • Set your expectation from the changed element: a new URL, canonical, title, structured-data block, internal link, or ranking signal can follow a different path.
    • Use typical timing as a planning band and slowest timing as an investigation trigger, not as a guaranteed deadline.
    • Diagnose the first incomplete handoff and correct its inputs before requesting another crawl.

    For your next release, write down the first Google-visible signal that should change and where you will verify it. If that signal appears but the next one does not, move your investigation forward one stage. If nothing has reached the first stage, fix discovery or access before spending time on rankings.

    References


  • Google Demand Gen View-Through Attribution: What Changed

    Google Demand Gen View-Through Attribution: What Changed

    If view-through conversions in a Demand Gen campaign move while spend, clicks, and downstream sales or leads look ordinary, do not assume the campaign suddenly became more or less effective. The reporting method itself may have changed underneath your benchmark.

    Google has lowered the threshold that a Display ad within Demand Gen must meet before a later conversion can receive view-through credit. That distinction matters whenever you evaluate creative, calculate performance, move budget, or report results across the transition.

    Key takeaways

    • The change is limited to Display ads within Demand Gen campaigns. It is not a blanket redefinition of every Demand Gen ad view.
    • The qualifying event is moving from an Active View-based view to a rendered ad impression.
    • Under the new definition, an impression can qualify when at least one pixel of the ad appears onscreen, even momentarily.
    • The conversion event is not being redefined. Google is changing which preceding ad views can receive credit for it.
    • A rise in view-through conversions may reflect broader attribution eligibility rather than stronger advertising performance.
    • Keep pre-change and post-change benchmarks separate, and require corroborating evidence before changing budgets or performance targets.

    The attribution gate changed, not the conversion event

    A view-through conversion, or VTC, connects a conversion to an eligible ad impression rather than to a click on that ad. Two events therefore matter: a person converts, and an earlier impression qualifies to receive view-through credit.

    Google is changing the second event for Display ads inside Demand Gen. The old method used Active View and its viewability standards to decide whether an impression was sufficiently viewable. The new method uses a rendered ad impression, which has a lower qualification threshold.

    Measurement questionActive View methodRendered-impression method
    What qualifies the preceding ad exposure?An impression that satisfies Active View viewability criteriaAn impression with at least one pixel onscreen for any amount of time
    How demanding is the qualification gate?HigherLower
    What happens to the conversion event itself?No change from this updateNo change from this update
    Which campaign inventory is covered?Display ads within Demand Gen campaigns

    Do not fill in the missing Active View criteria from memory or apply a familiar viewability threshold from another report. You do not need a percentage or duration to interpret this update correctly. The decision-relevant fact is that one onscreen pixel, however briefly displayed, can now make the impression eligible under the rendered-impression definition.

    Google’s stated reason is measurement consistency across Demand Gen inventory. That may make reporting conventions more uniform inside the campaign type, but consistency across inventory does not create continuity across time. A VTC reported under the old rule is not methodologically identical to one reported under the new rule.

    The announced transition is automatic for eligible campaigns, with no campaign-setting change required from advertisers. Your immediate job is therefore to protect reporting continuity, not to reconfigure campaign delivery.

    Why the same campaign can report more view-through conversions

    Think of VTC attribution as a gate. Under the earlier method, an impression had to pass Active View’s viewability test before it could participate in view-through attribution. Under the new method, merely rendering one pixel onscreen can open that gate.

    Lowering the gate can enlarge the pool of impressions eligible to receive credit. If people in that larger pool later convert, more conversions may be classified as view-through conversions even when the campaign did not generate additional purchases, form submissions, or other underlying conversion events.

    This does not mean every affected campaign will report an increase. Delivery, audience mix, spend, conversion lag, and actual customer behavior can all move at the same time. The update supplies a plausible measurement explanation for a change in VTCs; it does not predict the size or direction of every account’s result.

    The more important distinction is between attribution and incrementality. A VTC tells you that the platform connected an eligible impression with a later conversion under its rules. It does not, by itself, prove that the impression caused a conversion that would otherwise never have happened. A broader eligibility rule makes that distinction more important, not less.

    The definition can also change calculated KPIs. If an internal cost-per-acquisition calculation divides spend by a platform-attributed conversion count, additional VTC credit can make CPA appear lower. If a return calculation includes value assigned to those VTCs, reported return can rise. The arithmetic may be correct while the apparent improvement is methodological rather than commercial.

    Use corroborating signals before changing budget

    A balanced decision mechanism receives signals from an ad impression, a click, a conversion, and a stack of budget coins.

    Do not judge the transition from the VTC column alone. Compare that movement with signals that do not depend on the revised view definition: clicks, conversion paths involving clicks where separately available, qualified leads, completed orders, revenue, and other outcomes recorded in your own business systems.

    Pattern you observeWhat it can meanWhat to do next
    VTCs rise while clicks and independently recorded outcomes stay flatThe broader view definition is a strong candidate for at least part of the increase.Do not increase budget from the VTC movement alone. Annotate the methodology break and inspect the affected Display inventory.
    VTCs, click-associated results, and independently recorded outcomes all improveThere may be a real performance gain, although the definition change can still contribute to the VTC increase.Base the decision on the corroborating outcomes and a post-change benchmark, not on the full VTC difference.
    VTCs stay broadly stableThe practical effect may be small for this campaign or masked by other changes.Keep the reporting annotation. Stability does not make the pre-change and post-change methods identical.
    VTCs declineThe lower eligibility threshold does not explain the decline by itself.Investigate delivery, spend, audience mix, conversion lag, tracking, and business outcomes before assigning a cause.

    This check is especially important for automated spreadsheets, dashboards, scorecards, and budget rules that consume an attributed conversion total. A methodology-driven increase can silently trigger a recommendation to scale, make a target appear easier to reach, or make a post-change creative look stronger than a pre-change control.

    Pause those conclusions, not necessarily the campaign. The campaign may be performing well; the point is that this particular before-and-after comparison can no longer establish why.

    Build a clean reporting bridge across the rollout

    Two separate data platforms in muted and bright colors are connected by a two-lane illuminated bridge across a rollout boundary.

    You cannot recover comparability by pretending the definition stayed constant. You can preserve decision quality by treating the rollout as a measurement break and documenting it explicitly.

    1. Identify the affected slice. List the Demand Gen campaigns containing Display ads. Do not apply the same warning indiscriminately to unrelated campaign types or to every format inside Demand Gen.
    2. Preserve the old baseline. Save the last available pre-change reports with spend, impressions, clicks, VTCs, attributed conversion value where used, and independently observed leads or sales. Keep the raw export rather than only a chart or percentage change.
    3. Mark the methodology break. Add the change to dashboards, recurring reports, experiment logs, and client or leadership notes. If you do not have a confirmed account-level cutover date, label it as an estimated transition period instead of inventing a precise date.
    4. Separate the reporting eras. Calculate post-change VTC rates, CPA, return, and targets from post-change data. Retain the earlier benchmark for historical context, but do not blend the two periods into one continuous trend line without a visible warning.
    5. Keep the comparison conditions honest. When reviewing periods on either side of the change, account for spend, delivery, audience mix, campaign edits, conversion lag, and changes in the underlying business. The definition shift is one variable, not permission to ignore the others.
    6. Require an independent decision signal. Before increasing budget or declaring a winning creative, look for support from clicks, qualified leads, orders, revenue, or an appropriately designed experiment. The corroborating metric should not rely on the newly broadened view threshold.

    Suggested reporting note: View-through attribution eligibility for Display ads in Demand Gen changed from an Active View-based definition to a rendered-impression definition. Post-change VTC results are not directly comparable with the earlier baseline.

    Avoid creating a blanket adjustment factor to make old and new VTC totals look comparable. No universal uplift amount is provided, and the effect can vary with each campaign’s delivery and conversion behavior. Multiplying historical results by an assumed correction would replace a known methodology break with an invented one.

    The rollout was described as automatic over a period of weeks, so do not assume every account changed on the same day. For agencies or teams combining several accounts, keep the transition status at the account or campaign level until you can justify a shared post-change baseline.

    Make the next performance decision on the new baseline

    The safest immediate move is simple: add the methodology note to your recurring Demand Gen report, split the VTC trend at the transition, and check every budget recommendation against at least one outcome that does not depend on view-through eligibility.

    Once you have enough post-change data for your normal buying and conversion cycle, set fresh benchmarks under the rendered-impression definition. You can still use VTCs as an attribution signal. Just stop asking the old baseline to answer a question measured under a new rule.

    References


  • How to Test ChatGPT Visual Ads and Measure Incremental Lift

    How to Test ChatGPT Visual Ads and Measure Incremental Lift

    You have a budget decision to make: treat ChatGPT visual ads as a testable acquisition channel, or wait until the reporting ecosystem matures. The answer doesn’t depend on how novel the placement looks. It depends on whether you can connect the ad to a business outcome and then show that the spend caused more of that outcome.

    That distinction matters because a strong attributed return can still reflect demand that already existed. Before you fund a pilot, build a measurement plan that separates delivery, attribution and incremental lift. Otherwise, you may get an encouraging dashboard without learning whether the channel deserves more money.

    Visual ads create a paid surface, not organic AI visibility

    ChatGPT’s visual ads are intended to present products, services and experiences through imagery. The initial test is planned for image-generation experiences with a group of U.S. advertisers. The ads will be labeled and kept separate from images generated by ChatGPT.

    That separation gives you the first rule for reporting: paid exposure is not an organic recommendation, citation or answer-engine visibility win. Keep ChatGPT Ads in your paid-media scorecard. Track organic ChatGPT mentions, citations and referral traffic separately. If the same landing page receives both, use distinct campaign identifiers wherever the available implementation permits it.

    The image-generation setting also changes the creative question. A conventional display asset may be designed to interrupt passive browsing. Here, the surrounding activity involves making or refining visual material. That doesn’t prove a particular user intent, but it gives you a sensible creative hypothesis: the image should make the product, service or experience immediately understandable without pretending to be part of the generated output.

    • Show the offer clearly. A viewer should be able to identify what is being advertised before reading supporting copy.
    • Choose one proposition per variant. If an image tries to communicate price, quality, use case, social proof and product range at once, you won’t know which idea affected performance.
    • Preserve message continuity. The landing page should repeat the product, promise and visual cues used in the ad. A visual click followed by an unrelated page weakens both conversion rate and your ability to diagnose the creative.
    • Keep paid and generated media distinct internally. Asset names, reports and presentations should call the unit an ad. Don’t describe impressions as appearances in ChatGPT-generated images.
    • Request the actual creative specification. Confirm supported dimensions, copy fields, file limits, review rules and destination behavior before resizing an existing campaign library.

    OpenAI says ChatGPT reaches 1.2 billion people each week. That is a platform-supplied reach figure, not an estimate of addressable buyers or commercial intent. Use scale as a reason to investigate the channel, not as the input for a revenue forecast.

    Build the measurement chain before you launch creative

    A visual ad card passes through four connected transparent measurement modules on a dark tabletop.

    The announced measurement ecosystem has four distinct layers. They are related, but they do not answer the same question. Treating every integration as “tracking” is how teams end up with several dashboards and no agreed result.

    Measurement layerNamed partnersQuestion it should answer
    Conversion-data connectionsHightouch, Tealium and LiveRampCan confirmed business outcomes be sent back into the advertising platform?
    AttributionAppsFlyer, Triple Whale, Adjust, DV Rockerbox, Northbeam, Branch, Singular, Kochava, Airbridge and TenjinWhich tracked conversions receive credit for a ChatGPT Ads touchpoint?
    Full-funnel measurementFospha, Measured and INCRMNTALHow does the channel appear to contribute across the customer journey?
    Geo-based incrementalityHaus, Measured and WorkMagicDid exposure create additional conversions that would not otherwise have occurred?

    These announced partner relationships give you a map of the emerging stack. They do not establish that every connection has identical capabilities, availability or eligibility. Ask each vendor what data moves, in which direction, how often it updates, how conversions are matched, and what reporting is actually available for your account.

    Your internal data contract should come first. A partner cannot repair an event that fires inconsistently, counts duplicate orders or changes meaning midway through the test.

    1. Name one primary outcome. Use the event that represents business value, such as a completed purchase or a lead that has passed your qualification rule. Page views and button clicks can help diagnose the path, but they should not replace the outcome.
    2. Write the counting rule. State when the event becomes valid, how cancellations or invalid leads are handled, and whether repeat transactions count. Apply the same definition to every channel in the comparison.
    3. Deduplicate at the transaction level. Pass a stable order or conversion identifier through the systems that are permitted to receive it. One purchase reported by a browser, server and partner must remain one purchase.
    4. Preserve the fields needed for analysis. Record timestamp, conversion value, currency, campaign identifier and new-versus-returning customer status when those fields are available and allowed by your consent and data-governance rules.
    5. Choose the source of truth. Decide whether final revenue comes from your commerce platform, CRM or another controlled system. Ad and attribution dashboards can explain credit; they should not silently redefine booked revenue.
    6. Test the path end to end. Complete a controlled conversion, confirm that it appears once in the source of truth, and verify that each connected system receives the expected event and value.
    7. Freeze the measurement definitions. Document attribution windows, identity rules, exclusions and late-arriving conversion treatment before launch. If a definition changes, annotate the date and avoid blending the two periods as though they were comparable.

    This setup gives you traceability. When two dashboards disagree, you can inspect event definitions, matching and attribution settings instead of debating which total looks more favorable.

    Attribution tells you who received credit; incrementality tests causation

    A split illustration shows converging customer paths beside two matched groups, one exposed to an ad and producing extra outcome tokens.

    An attributed conversion occurred after a measurable advertising touchpoint and was assigned to that touchpoint under a defined rule. An incremental conversion is an estimated additional outcome caused by the advertising. Those are different claims.

    Suppose someone was already likely to buy, saw a ChatGPT ad and then converted. An attribution model may award the ad some or all of the credit. An incrementality design asks what would probably have happened without the ad. The first result can be useful for journey analysis; the second is the stronger basis for increasing budget.

    The early results illustrate why you must read each metric literally rather than combine them into a single success narrative.

    Early partner-reported resultWhat it supportsWhat it does not establish
    DV Rockerbox measured WeightWatchers’ attributed CPA from ChatGPT Ads at 15.3% below its blended paid-search benchmark.Attributed acquisition cost compared favorably with that advertiser’s chosen benchmark in that measurement.It does not by itself prove incremental lift or provide a benchmark for another advertiser.
    WorkMagic found that 67% of Dose’s incremental purchases came from new customers.The reported incremental purchases included a substantial new-customer component in that case.It does not reveal how another brand’s customer mix, total lift or economics will behave.
    Triple Whale reported that 93% of Portland Leather visitors from ChatGPT Ads were new.The tracked visitor mix was heavily weighted toward new visitors for that advertiser.New visitors are not automatically new customers, incremental purchases or profitable orders.

    These are preliminary, partner-reported results from individual advertisers, not broad platform benchmarks. They can justify forming testable hypotheses. They cannot justify inserting the same CPA improvement or new-customer share into your forecast.

    A useful reporting hierarchy has three levels:

    • Delivery validation: Did the campaign spend and produce measurable visits or other intended responses? This tells you whether the setup functioned.
    • Attributed efficiency: What cost per attributed outcome and attributed return did your chosen model report? This helps compare credit under consistent rules.
    • Incremental business impact: How many additional outcomes did the experiment estimate, and at what incremental cost? This is the scale-or-stop question.

    For a geo-based incrementality test, work with the measurement partner to choose comparable exposed and control regions, account for their pre-test differences, and set the primary outcome before delivery begins. Keep major promotions, pricing changes and channel shifts consistent where possible. When they cannot be kept consistent, log them so the analysis can account for a contaminated period rather than treating it as clean.

    Define the budget decision in advance as well. Your acceptable incremental acquisition cost should come from unit economics, not from the platform’s attributed CPA. If the estimated lift is too uncertain to distinguish from normal variation, call the result inconclusive. Do not relabel uncertainty as zero impact, and do not scale it as proof of success.

    Use a test charter that forces a scale, iterate or stop decision

    A pilot becomes useful when it resolves a decision. Before the campaign starts, put the following items on one page and require the channel owner, analyst and business owner to agree on them.

    1. Decision: State what will happen after the readout. Examples include expanding the test, revising the offer or creative, or stopping spend. Avoid goals such as “learn about the channel” that permit any result to look acceptable.
    2. Hypothesis: Describe the mechanism you expect. A useful form is: a clearly visual presentation of this offer will generate additional qualified demand from this type of need, producing an incremental outcome within our acceptable economics.
    3. Primary metric: Select one business outcome and define its numerator and denominator. Keep diagnostic measures such as click-through rate, landing-page engagement and attributed conversions secondary.
    4. Incrementality method: Name the geo design or other approved causal method, the measurement partner, the exposed and control units, and the planned analysis. Do not add incrementality after seeing an attributed result you like.
    5. Creative variables: List the element each variant changes. Change one major proposition at a time when the available delivery controls make that practical; otherwise, a winning asset will not tell you what to reuse.
    6. Landing-page path: Record the destination, conversion steps and analytics events. Confirm that the page supports the exact claim shown in the visual.
    7. Data owners: Assign one person to conversion integrity, one to paid-platform operations and one to final analysis. Shared accountability without named owners usually means unresolved discrepancies at readout.
    8. Decision thresholds: Write the minimum acceptable business result and the treatment of statistical uncertainty before launch. Use your own margin, retention and capacity constraints rather than copying a partner-reported case.
    9. Confounder log: Track promotions, inventory shortages, site outages, price changes, major organic coverage and material changes in other paid channels.

    At the readout, separate creative diagnosis from channel diagnosis. Weak delivery or a broken conversion path means you did not get a valid channel test. Strong attribution with no measurable lift means the ads may be capturing existing demand. Incremental conversions with unacceptable economics mean the channel caused an effect, but not one you should scale in its current form.

    Use three possible decisions. Scale only when the data chain is sound and incremental economics meet the prewritten requirement. Iterate when the test is valid but points to a specific repairable constraint, such as the offer, creative clarity or landing-page path. Stop when a valid test misses the business threshold and there is no evidence-backed change likely to alter the result.

    Treat brand suitability as an operating control

    Brand safety and brand suitability are related but not identical. Safety addresses broadly harmful or unacceptable environments. Suitability applies your brand’s own tolerance to contexts that may be acceptable for one advertiser and wrong for another.

    OpenAI is developing brand-suitability evaluation pilots with DoubleVerify and Integral Ad Science. The evaluations are planned for controlled environments and do not give those partners access to private user conversations. Qualifying advertisers can also use Negative Phrases for more specific placement requirements.

    Those controls are meaningful, but they do not replace your own policy. A negative-phrase list is only as useful as its coverage, maintenance and enforcement. Build the internal process before launch:

    • Create three context tiers. Mark categories as prohibited, review-required or generally acceptable. This gives campaign operators a decision rule instead of an unstructured list of concerns.
    • Translate prohibited contexts into phrases. Use language that represents the actual context you need to avoid. Confirm the supported matching behavior before assuming that variants, synonyms or related concepts are covered.
    • Record the reason for every restriction. Tie it to legal requirements, product policy, audience sensitivity or brand standards. This makes the list maintainable and prevents unexplained phrases from accumulating.
    • Ask what evidence is available. Determine what placement, suitability or verification reporting your account can receive and at what level of detail. Do not promise internal stakeholders a conversation-level log when the suitability pilots explicitly avoid private conversations.
    • Define escalation and pause authority. Name who reviews questionable placements, who can stop spend and how findings change the phrase list or creative policy.
    • Review controls alongside creative. An accurate placement policy cannot rescue an image that exaggerates the product, obscures material conditions or implies that the ad is ChatGPT-generated content.

    Key takeaways

    • Report ChatGPT visual ads as paid media, separately from organic ChatGPT recommendations, citations and AI-search visibility.
    • Connect a clean, deduplicated business outcome before evaluating creative performance.
    • Use attribution to understand assigned credit, but use incrementality to decide whether the channel created additional conversions.
    • Treat the early advertiser results as hypotheses for your own test, not as planning benchmarks.
    • Set scale, iterate and stop rules before launch so the readout produces a budget decision.
    • Turn brand suitability into a documented policy with phrase controls, evidence requirements and named escalation owners.

    Your next move should be a measurement charter, not a large rollout. Choose one business outcome, verify its data path, define the incrementality design and write the decision threshold. Once those pieces are agreed, creative testing can teach you something durable instead of merely generating another attributed-performance report.

    References


  • Microsoft Automotive Ad Pricing Rules: A Dealer Checklist

    Microsoft Automotive Ad Pricing Rules: A Dealer Checklist

    A vehicle price can be correct in your inventory system and still become misleading by the time it reaches an ad. A conditional discount may lose its qualifier, a feed may retain yesterday’s amount, or the landing page may show a different offer.

    If you manage U.S. dealer campaigns, treat Microsoft Advertising’s updated automotive pricing policy as a reason to audit the entire path from inventory record to landing page. The central test is simple: does the price a shopper sees accurately represent the offer that shopper can obtain?

    Key takeaways for U.S. automotive advertisers

    • The revised pricing requirements apply to automotive dealers advertising in the United States through Microsoft Advertising.
    • Accuracy depends on more than the number in a feed. Review source data, feed transformations, discounts, ad rendering and landing pages together.
    • A discount that depends on eligibility, timing or another condition should not appear to be universally available.
    • Quarantine ambiguous or mismatched inventory records instead of allowing questionable prices to keep serving.
    • Keep evidence showing what the offer, feed, ad and landing page displayed when each pricing review was completed.

    Start with the requirement you can prove

    The revised requirements govern how vehicle prices are represented, including the treatment of prices, discounts and related pricing information across Microsoft Advertising formats. Microsoft has framed the change as a way to make compliance easier while keeping advertised prices faithful to the available offer.

    That principle is useful, but it isn’t a substitute for the current policy language. Before changing templates or feed logic, retrieve the active Microsoft Advertising policy and its change log from your account or policy library. Save the version your team reviewed. Then convert each requirement into a control that can be tested.

    Your requirements matrix should record:

    • Scope: the campaigns, formats, accounts and inventory covered by the requirement.
    • Price element: the feed field, discount, qualifier or rendered text that must be checked.
    • Expected behavior: what the feed, ad and destination must show for the record to pass.
    • Evidence: the feed export, ad preview, landing-page capture and approval record that demonstrate compliance.
    • Owner: the person or team responsible for correcting a failure.

    This prevents a familiar operational mistake: translating a policy change into a vague instruction such as “check the prices.” A requirement without a named field, pass condition and owner is unlikely to survive the next inventory refresh.

    Audit the price as a chain, not a field

    An isometric audit chain links a vehicle inventory record, feed pipeline, online ad, and mobile landing page with connected price and discount tags.

    The shopper sees the output of several systems. Your audit should therefore follow the same route as the price.

    1. Confirm the underlying offer. For each sampled vehicle, record the stock identifier, selling price, included discounts, eligibility conditions, availability and relevant offer timing. This is the truth the rest of the chain must preserve.
    2. Inspect the feed transformation. Compare the inventory-system values with the exported values. Look for field mapping, rounding, fallback values, promotional overrides or other logic that can change the amount.
    3. Check the rendered ad. Use the actual ad preview or delivered-ad evidence where available. Do not rely only on the feed file; templates can omit qualifiers or place values in the wrong pricing field.
    4. Open the destination. Confirm that the click resolves to the same vehicle and that the visible price and conditions agree with the advertised offer. A correct feed does not repair a contradictory landing page.
    5. Test the handoff. A staff member who was not involved in creating the promotion should be able to identify who qualifies, which discounts are included and how the displayed amount is obtained.

    Keep the evidence together under the same stock identifier. If a campaign is questioned later, separate screenshots and exports are far less useful when nobody can tell whether they describe the same vehicle or the same version of the offer.

    Review discounts more aggressively than base prices

    Base prices are usually direct values. Discounts often contain business logic: a buyer must qualify, offers may or may not combine, inventory may be restricted, and a promotion may end while an old feed remains active. That makes discounts the natural place for a technically valid number to become an inaccurate promise.

    For every advertised discount, answer these questions before the record is eligible to serve:

    • Can the intended audience actually receive the discount on the advertised vehicle?
    • Does eligibility depend on a fact that the ad or destination fails to communicate clearly?
    • If several discounts produce the displayed price, can those discounts genuinely be combined?
    • Does the promotion apply to this specific inventory record rather than merely to a related model or trim?
    • What removes or replaces the promotional amount when the underlying offer changes?
    • Will the landing page explain the offer in a way that agrees with the ad rather than quietly narrowing it?

    Use a practical reproduction test: give the rendered ad and its destination to the person responsible for the offer, then ask that person to reconstruct the advertised amount. If the total depends on an undisclosed assumption, the price chain needs correction before the ad runs.

    Platform compliance is not a legal opinion. Automotive price disclosures can also create legal exposure outside Microsoft Advertising, so route uncertain wording, fee treatment and eligibility disclosures to qualified counsel or your compliance team before publication.

    Build controls that can handle a large vehicle feed

    Manual review is valuable for interpreting an offer, but it does not scale well across a changing inventory. Use automated checks to find records that deserve human attention.

    Block records with objective failures

    • A required price or stock identifier is missing or cannot be parsed.
    • The destination resolves to a different vehicle, a removed listing or an error page.
    • The feed amount and the landing-page amount do not match under the same stated conditions.
    • A discount is present without the data your process requires to validate eligibility and offer status.
    • A source update fails, but the campaign would otherwise continue serving the previous promotional value.

    Send these records to quarantine. Do not let a failed validation silently fall back to a stale or lower amount merely to preserve inventory coverage.

    Queue ambiguous records for human review

    • A new discount or pricing override appears.
    • The size of a discount changes unexpectedly.
    • Several incentives contribute to one advertised amount.
    • The ad copy implies broad availability while the underlying offer contains narrow eligibility conditions.
    • The visible landing-page explanation makes the price harder to understand than the ad itself.

    Prioritize the lowest advertised prices, the largest discounts, recently changed offers and records produced by fallback logic. This is risk-based review: it directs attention to the entries most likely to create a material gap between the advertised number and the obtainable offer.

    Keep each record in an explicit state such as eligible, quarantined or approved exception. An exception should contain its reason, approver and supporting evidence. Otherwise, a temporary workaround can become permanent feed behavior without anyone consciously accepting the risk.

    Handle a pricing violation as a data incident

    A dealership advertising team investigates an amber-highlighted pricing mismatch across inventory, ad, and landing-page systems.

    A pricing problem is rarely fixed by editing one headline. Policy violations can create compliance problems and potentially disrupt campaigns, so preserve the evidence and repair the system that produced the bad value.

    1. Contain the issue. Pause or exclude affected records without unnecessarily disabling inventory that has passed validation.
    2. Preserve the observed state. Save the source record, exported feed row, rendered ad, destination page and applicable policy version.
    3. Locate the first divergence. Determine whether the error began in merchandising data, discount logic, feed mapping, ad templates, the landing page or update timing.
    4. Correct the origin. A manual edit downstream may conceal the symptom while the next refresh recreates it.
    5. Revalidate the path. Confirm both the corrected record and comparable records that use the same rule or template.
    6. Document the prevention. Add a validation rule, ownership change or release check so the same failure cannot pass unnoticed.

    Do not assume every rejected vehicle has the same cause. One campaign may contain a stale-price problem, an eligibility problem and a destination mismatch at the same time. Classifying each failure before applying a bulk fix reduces the chance of introducing a second pricing error.

    Give one person authority over the final price path

    Pricing accuracy crosses several teams: merchandising defines the offer, feed operations map the data, paid media controls the ad, web teams publish the destination, and compliance interprets disclosure risk. Shared work still needs a final owner who can prevent a record from serving when those components disagree.

    Before your next feed publication, choose a discounted vehicle and trace it from the underlying offer through the rendered ad to the landing page. Record every transformation and assign an owner to every failure point. Once that path is reliable, apply the same control to the rest of the high-risk inventory before releasing broader campaign changes.

    References

  • Dental Software Marketing Built Around Buyer Evaluation

    Dental Software Marketing Built Around Buyer Evaluation

    Your dental software site can rank for a category term and still fail at the moment that matters. A practice is not merely checking whether a feature exists. It is deciding whether the front desk, clinical team, billing staff, and leadership can use the system without creating another layer of work.

    That decision often begins before a sales conversation. Practices can compare platforms, inspect features, read reviews, and investigate specific workflows online. Your marketing therefore has to do more than attract a visit. It must help a buyer define the decision, verify fit, reduce uncertainty, and identify a sensible next step.

    Map the decision before you plan keywords

    A keyword tells you what someone typed. It does not tell you what they must decide before they can move forward. Start with that decision.

    For each important audience, build a decision-question inventory with five fields: the buyer’s role, the question in the buyer’s own words, the evidence needed to answer it, the page that should own the answer, and the next action that fits the remaining uncertainty. A practice owner may want to understand operational impact. A clinical user may need to see charting behavior. A billing lead may care about how information moves through a revenue workflow. Those questions should not all lead to the same generic demo page.

    Organize the inventory around the stages of an actual evaluation:

    • Scope: What does the system manage, replace, or connect with?
    • Workflow fit: How does a specific user complete a specific task?
    • Adoption: What must the practice change, configure, migrate, or learn?
    • Verification: What evidence supports the product claim, and under what conditions?
    • Selection: What should the buyer do next to resolve the remaining unknowns?

    This prevents a common content-planning mistake: treating every commercially relevant query as a request for a feature page. Someone trying to understand a category needs a different answer from someone verifying an integration, evaluating a workflow, or preparing to switch systems.

    Prioritize a question when three conditions are present: it can block or advance an evaluation, your product has a meaningful answer, and you can substantiate that answer. If you cannot show the workflow, requirement, limitation, or evidence behind a claim, publishing another keyword variation will not make the claim more persuasive.

    Build a page system around workflows, not feature volume

    An illustrated dental practice workflow connects patient check-in, clinical treatment, billing, and management review.

    Dental practice management can span connected functions such as scheduling, billing, clinical charting, patient communication, and reporting. A buyer rarely experiences those functions as an unordered feature list. The output of one task becomes the starting point for another, often across different roles.

    Your site architecture should mirror that reality. Give each page one primary evaluation job, then connect the pages in the order a buyer is likely to need them.

    Evaluation intentBest content assetWhat it must answerAppropriate next step
    Understand the categoryBuyer guideProduct scope, selection criteria, exclusions, and terminologyUse an evaluation checklist
    Improve one workflowWorkflow pageStarting condition, users involved, task sequence, handoffs, and resultView a task walkthrough
    Verify a capabilityCapability pageSupported task, prerequisites, dependencies, and limitationsRequest a technical answer
    Reduce switching riskImplementation pagePreparation, data responsibilities, configuration, training, and support pathDiscuss implementation readiness
    Compare optionsEvaluation or comparison pageConsistent criteria, transparent methodology, and dated product informationBuild a shortlist
    Validate a claimDemonstration, case evidence, or review pageContext, observable behavior, and conditions behind the claimVerify fit with the product team

    A useful workflow page does not need to be long, but it does need to be complete. Use this sequence:

    1. Answer the primary question in the opening paragraph.
    2. Name the user and the task instead of describing an abstract benefit.
    3. Show the workflow from its starting state through its finished state.
    4. State prerequisites, integrations, configuration needs, and known limits.
    5. Provide visible evidence: annotated screens, a task-based video, documentation, or a clearly contextualized example.
    6. Offer a next step that resolves the next unknown rather than forcing every visitor into the same sales form.

    Internal links should continue the evaluation rather than merely distribute authority. A scheduling workflow page might lead to configuration requirements, an implementation explanation, and a relevant demonstration. Descriptive anchor text helps the buyer understand why each destination matters and gives search and retrieval systems clearer relationships between pages.

    Prove ease of use instead of calling the product easy

    A dental receptionist checks in a patient on a computer while an assistant receives the workflow update on a tablet.

    Ease of use is consequential because dental teams already manage many daily demands, and software is supposed to reduce rather than add complexity. But words such as easy, intuitive, and seamless are conclusions. They do not tell a buyer which task is easy, for whom, or under what conditions.

    Turn each usability claim into a testable demonstration. Define:

    • The user: receptionist, clinical team member, billing staff member, manager, or another defined role.
    • The task: the exact job the user is trying to finish.
    • The starting state: what information or setup must already exist.
    • The path: the actions, decisions, and handoffs required.
    • The exception: what happens when the normal path changes or an error must be corrected.
    • The finished state: what is saved, communicated, reported, or made available to the next person.
    • The dependency: any configuration, integration, permission, or training assumption that affects the experience.

    If your product supports appointment changes, do not stop at saying scheduling is simple. Show the relevant task and what happens to the associated information. If you promote reporting, identify the report, the inputs it uses, who can access it, and what the user can do with the output. If patient communication is part of the platform, explain what triggers the communication and what staff can see afterward. Demonstrate only behavior the product actually supports.

    Apply the same discipline to reviews and ratings. Buyers may consult them, but a score without context cannot establish fit for a particular practice. When you use review evidence, preserve the product name, relevant version or date when available, practice context, and workflow being discussed. Do not turn one favorable sentence into a universal performance claim.

    Limitations deserve equal visibility. State when a workflow requires setup, an external connection, a particular plan, or assistance from the vendor. This may reduce low-fit conversions, but it makes the remaining evaluations more informed. It also keeps sales from spending the first conversation correcting assumptions created by the website.

    Make evaluation pages clear to buyers, search engines, and AI systems

    SEO and generative engine optimization share a basic requirement here: the page must contain a clear, self-contained answer. Schema cannot recover a claim that appears only in an image, and an AI search system cannot reliably interpret a vague paragraph that never names the product, user, task, or constraint.

    Use this publishing checklist on every high-intent evaluation page:

    • Give the page one primary question and answer it near the beginning.
    • Name the company and product consistently. State the software category, intended audience, and delivery model only as precisely as you can verify.
    • Keep important capabilities, requirements, and limitations in visible HTML text rather than placing them only inside screenshots or video.
    • Add captions or transcripts when a visual demonstration carries evidence that the surrounding text does not.
    • Use descriptive headings, lists, and genuine comparison tables so individual facts retain their context when extracted.
    • Link claims to supporting demonstrations, documentation, implementation details, or evidence pages.
    • Assign an owner to changing product facts and display a meaningful revision date when the page has been substantively reviewed.
    • Remove conflicting terminology across product, help, pricing, comparison, and implementation pages.

    Structured data should describe what a visitor can already verify. SoftwareApplication markup can describe an eligible software product, Organization markup can identify the company behind it, and BreadcrumbList markup can express the page’s place in the site hierarchy. Use only properties supported by the visible page. Do not mark up an aggregate rating, operating system, price, application category, or offer unless the value is accurate, current, and presented to users. Structured data clarifies an entity; it does not turn an unsupported marketing claim into evidence or guarantee visibility in an AI answer.

    Do not manufacture a large FAQ section by repeating the same feature claim as several questions. Add a question only when it resolves a distinct decision. A concise answer about migration responsibilities, supported workflows, training, or a product limitation is more useful than multiple keyword-shaped versions of “Is this the best dental software?”

    Close the loop with sales and support. Record the exact questions prospects ask during evaluations, map each question to an existing page, and flag answers that are missing, unclear, or contradicted elsewhere. Then update the owning page instead of automatically creating a new one. Measure whether evaluation content leads readers toward relevant walkthroughs, documentation, technical questions, and qualified conversations. Traffic alone cannot tell you whether the page reduced uncertainty.

    Key takeaways

    • Plan content around the decision a buyer must make, not just the phrase entered into search.
    • Build separate assets for category education, workflow fit, capability verification, implementation risk, comparison, and proof.
    • Replace broad usability adjectives with task-based demonstrations that name the user, path, exception, result, and dependencies.
    • Publish requirements and limitations alongside benefits so buyers can judge fit before a sales call.
    • Keep important product facts in visible, structured text, and use schema only to represent claims the page supports.
    • Use recurring sales and support questions as an editorial backlog, then judge content by evaluation progress as well as visits.

    Start with the product page receiving the most evaluation traffic. Test it against one real buyer question. If the buyer cannot find the answer, conditions, evidence, limitations, and appropriate next step without opening a gate, fix that page before publishing another keyword-led article.

    References