Month: August 2026

  • How AI Is Rewriting Paid Search and Conversion Strategy

    How AI Is Rewriting Paid Search and Conversion Strategy

    Your keyword coverage can be clean, your bids controlled, and your landing page tightly focused, yet the account can still miss how people now make decisions. AI is changing two parts of the journey paid search used to take for granted: how demand forms before a query and how much evaluation happens before a referral click.

    That doesn’t make PPC obsolete. It changes the job. You now need a connected system for creating interest, capturing explicit intent, earning inclusion in AI-generated answers, and converting visitors who may arrive with most of their research already complete.

    The click now sits inside a longer AI-shaped journey

    Traditional search advertising begins when a person declares a need. A query can reveal the product, problem, constraints, and likely buying stage in a few words. The advertiser’s job is to respond with the right offer, message, destination, and bid.

    AI-driven discovery adds two different jobs around that click. Before the query, a campaign may need to make an unrecognized problem feel worth investigating. After the query, an AI assistant may compare options, apply the user’s constraints, and present a shortlist before the user visits any website.

    Google’s Demand Gen campaigns make the first change visible. They can reach people across YouTube, Shorts, Discover, Gmail, Maps, and the Google Display Network, where the person has not necessarily asked for the advertiser’s product. The creative must earn attention and create enough interest for the next question to form.

    AI Mode makes the second change visible. Google has reported that its average AI Mode query is three times longer than a traditional query, while one in six AI Mode searches uses a non-text input such as an image or voice. A longer, contextual request gives the system more information about fit than a short keyword ever could.

    Map each important offer across five decision states:

    • Unnamed need: The customer recognizes a situation but has not identified the underlying problem. Show the situation and its consequence.
    • Emerging interest: The customer understands the problem but may not know the solution category. Explain the outcome and how the category works.
    • Explicit search: The customer can name the product, service, or requirement. Match the query with a precise promise and destination.
    • AI-assisted evaluation: A search engine or LLM is comparing options against detailed constraints. Supply facts, distinctions, evidence, and clear fit boundaries.
    • Verification and action: The customer has a likely choice and wants to confirm it. Remove the final uncertainty and make the appropriate transaction easy.

    Assign every campaign, creative concept, content page, and landing page to one primary state. If an asset cannot be placed, its job is probably too vague. A hard-sell form is a poor first response to someone who has only just recognized the problem; a generic educational page is equally unhelpful to someone checking a specific recommendation before buying.

    AI Max turns campaign inputs into governance decisions
    A strategist oversees glowing campaign inputs as they pass through human-controlled gates into branching AI-managed pathways.

    The AI Max migration schedule turns platform automation from a distant trend into an operational deadline. Campaign-level Broad Match, legacy Automatically Created Assets, and Dynamic Search Ads are moving into the AI Max framework on different schedules.

    DatePlatform changeWhat you should do
    August 3, 2026New Campaign-level Broad Match configurations and legacy Automatically Created Assets can no longer be created through the interface, Ads Editor, or API.Stop designing new workflows around the retired structures and identify any existing campaigns that still use them.
    September 1-30, 2026Affected Broad Match and Automatically Created Assets campaigns are automatically migrated to AI Max.Export a pre-migration baseline, document guardrails, and schedule post-migration quality assurance.
    September 2026 and January 15, 2027Dynamic Search Ads migration notices and reminders appear before the automatic transition.Inventory DSA ad groups, their destinations, and every script or report that depends on the legacy structure.
    February 1-28, 2027Dynamic Search Ads begin migrating automatically, and new DSA ad groups can no longer be created.Verify that the migrated campaigns still represent the intended products, pages, brands, and conversion goals.
    Approximately September 2027Older Google Ads API versions that retain legacy Broad Match and asset support are expected to reach their normal sunset.Update integrations before the API deadline instead of relying on an old version as a permanent workaround.

    Google says affected campaigns will be migrated in place with equivalent settings, and existing brand inclusions and exclusions should carry over. That reduces rebuilding work, but it does not remove the need for validation. A setting can transfer correctly while the campaign still behaves differently within the new system.

    Use this migration checklist for every affected account:

    1. Freeze a readable baseline. Record campaign structure, budgets, bid strategy, conversion definitions, destinations, brand rules, and performance over an evaluation window that reflects your normal conversion lag.
    2. Map technical dependencies. List scripts, dashboards, API integrations, naming rules, bulk sheets, and alerts that refer to legacy campaign or asset entities. Future API versions released after September 1 remove support for the retired entities, even though older versions continue until their scheduled sunset.
    3. Restate the business guardrails. Write down which brands, offers, locations, claims, pages, and conversion actions are eligible. Platform settings should reflect a decision that exists outside the platform.
    4. Separate migration from experimentation. Do not combine the structural transition with a budget increase, new attribution model, bid-strategy change, and landing-page redesign. If performance moves, you need a plausible way to identify why.
    5. Run outcome-level quality assurance. Compare destination use, branded and non-branded distribution, conversion mix, cost per qualified outcome, and revenue efficiency against the baseline. A stable headline conversion count can conceal a shift toward weaker actions.

    The central control is your conversion objective. Automation can pursue only the outcomes and constraints it receives. If a low-value form submission and a completed sale are treated as interchangeable signals, more automation will not repair the underlying definition.

    Creative must create intent, not decorate the campaign

    When there is no keyword, the creative has to carry the context that the query used to provide. It must identify the relevant person, surface a recognizable problem, demonstrate an outcome, answer an objection, and propose a next step that matches the viewer’s current intent.

    Use a brief that can survive automation

    A list of dimensions is not a creative strategy. Give the media buyer, writer, designer, and video producer the same brief:

    • Audience situation: What is happening in the person’s work or life when this message becomes relevant?
    • Problem trigger: What should the opening three seconds communicate before the viewer scrolls away?
    • Desired response: Should the viewer recognize a problem, understand a category, compare approaches, or feel ready to act?
    • Core proof: What demonstration, product detail, customer evidence, or explanation makes the promise credible?
    • Primary objection: Which concern must this concept resolve: complexity, fit, effort, risk, price, or uncertainty?
    • Placement behavior: Will the idea still make sense in a vertical short, a square image, and a longer landscape video?
    • Next action: Is the appropriate step to learn, compare, configure, request information, or buy?

    Supply formats that fit the placement instead of cropping one master asset into every slot. Google’s own guidance calls for vertical, square, and landscape assets plus a combination of image and video. In Google’s global campaign data, advertisers using both image and video received 6% more conversions at the same spend than advertisers using images alone. That is a platform-reported aggregate, not a forecast for your account, but it gives you a sound reason to test format diversity rather than treating it as optional polish.

    Test concepts before you test cosmetic variations

    Three versions of the same product image are not three different ideas. Build distinct concept families around the problem, the demonstration, the comparison, and the proof. Then adapt each viable concept to the required placements.

    Write a hypothesis before launch. For example: showing the workflow will reduce uncertainty for people who understand the category but doubt the setup effort. Label assets by that hypothesis, not just by file size or color. When results arrive, you can decide whether the underlying message deserves another iteration rather than merely declaring one crop the winner.

    Treat audience settings as distribution hypotheses, not customer understanding. Demand Gen can use first-party data, lookalike segments, interests, behavioral signals, and optimized targeting, but those controls do not tell you why a person cares or what prevents action. Brief the audience in terms of situation, belief, desired outcome, objection, and required proof. Feed what you learn from creative response and conversion quality back into the next audience and message decision.

    LLM referrals need proof before pressure
    An informed visitor approaches a landing-page space where evidence, transparent product details, and trust markers are presented before sales pressure.

    A paid-search click and an LLM citation click can land on the same URL while representing different moments. The PPC visitor may be beginning a comparison. The LLM visitor may have already given an assistant detailed constraints, reviewed a synthesized answer, and clicked because they need confirmation or a transaction the assistant cannot complete.

    That selection effect can produce unusually strong conversion rates at modest volume. In one published dataset, LLM referral traffic converted at 20%, which was 61% higher than paid search. Do not adopt those figures as an account benchmark. Use them as a reason to isolate the channel and test whether its visitors behave differently in your own funnel.

    Build the page for verification

    A stripped-down PPC page often assumes that fewer choices and a dominant call to action will improve focus. That can fail when a visitor expects to verify a nuanced AI recommendation. If the promised detail has been replaced by a gated form and a generic benefit list, the page breaks continuity with the answer that produced the click.

    Build the destination in layers so a ready buyer can act without hiding the evidence from a careful evaluator:

    1. Confirm the answer immediately. State what the offer is, who it fits, and which problem or decision the page resolves. The heading should make the citation click feel intentional rather than accidental.
    2. Expose the decisive facts. Make capabilities, constraints, integrations, process details, pricing conditions, or product specifications easy to find when they are relevant to the decision.
    3. Show why the claim is credible. Use original data, a transparent method, named expertise, demonstrations, and clearly attributed evidence where available. Content with unique information gives an AI system a stronger reason to cite it in the first place.
    4. State fit boundaries. Explain who the offer is for, who may need a different option, and which limitations matter. This helps a visitor test the AI’s recommendation against their actual edge case.
    5. Offer more than one sensible next step. Keep the primary purchase, demo, or inquiry action visible, but also provide a route to documentation, a detailed comparison, or implementation information.
    6. Make the page machine-readable without making it robotic. Use descriptive headings, direct answers, consistent entity names, and structured data that matches the visible content. Schema can clarify evidence; it cannot manufacture evidence the page does not contain.

    You do not necessarily need separate websites or duplicate pages for PPC and LLM traffic. A single destination can place a concise answer and action near the top, then provide navigable evidence below. The requirement is message continuity, not a separate URL for every channel.

    Measure LLM conversion as its own behavior

    Create distinct reporting segments for paid search, Demand Gen, and identifiable LLM referrals. Preserve the referring channel and landing page, then connect the session to downstream outcomes whenever your consent, analytics, and customer systems allow it.

    Report more than the first conversion:

    • Sessions and conversion rate by referral type and landing-page class.
    • The mix of purchases, forms, calls, trials, and other conversion actions.
    • Qualified-lead, opportunity, or completed-sale rates where the buying cycle continues offline.
    • Revenue, order value, or another business-quality measure appropriate to the offer.
    • Time from the referral session to the completed outcome.
    • Assisted conversions when an LLM visit informs a later branded search, direct visit, or paid click.

    Compare like with like. A high-intent citation click should not be judged against every upper-funnel ad impression or every broad paid-search visit. Segment by decision stage, destination, and conversion definition before concluding that one channel is more efficient. Otherwise, you risk confusing a more selective click with a universally better acquisition channel.

    Key takeaways: run paid media, GEO, and CRO as one loop

    1. Choose one commercially important offer. Avoid beginning with an account-wide rebuild. A contained offer gives you a readable path from demand creation to revenue.
    2. Map its five decision states. Identify the message, asset, channel, destination, and appropriate action for each state from unnamed need through verification.
    3. Audit the automation boundary. Check affected Google Ads structures against the AI Max schedule, record a baseline, document business guardrails, and update scripts or API integrations before their legacy support disappears.
    4. Build creative around hypotheses. Create distinct problem, demonstration, comparison, and proof concepts. Adapt viable ideas to native placements instead of treating format variants as the strategy.
    5. Give each visitor the evidence their click implies. Preserve fast actions for ready buyers while making detailed facts, fit boundaries, and supporting evidence accessible to AI-referred visitors.
    6. Join acquisition and conversion reporting. Segment paid-search, demand-generation, and LLM traffic, then judge them by qualified outcomes and revenue rather than blended conversion rate alone.

    At your next account review, pick the single offer where an AI Max migration, a creative gap, or an LLM referral pattern is already visible. Record the baseline, change one part of the system, and follow the result through to business quality. That is the practical path from AI-driven reach to conversion you can defend.

    References


  • How to Verify AI-Assisted Development for Technical SEO

    How to Verify AI-Assisted Development for Technical SEO

    The ticket says resolved. The AI says the tests pass. Staging looks right. Yet the production page still sends the wrong canonical, omits a locale mapping, or calculates a score that no customer can see. This is where fast AI-assisted development becomes expensive: a working result can still be different from the result you requested.

    You do not need to slow every project down with a heavyweight approval process. You need a definition of done that can survive contact with production. The workflow below turns an SEO concern into a testable requirement, checks the result at the layer where search engines and users encounter it, and leaves evidence another person can reproduce.

    Key takeaways

    • Write the acceptance test before asking an AI or developer to implement the fix.
    • Translate audit labels into mechanisms, affected scope, required behavior, and an observable pass condition.
    • Verify the deployed response, rendered output, crawl behavior, and user-facing result when those layers are relevant.
    • Treat AI explanations, screenshots, successful builds, and closed tickets as supporting evidence, not proof by themselves.
    • Record the build, URLs, inputs, procedure, expected result, actual result, and exceptions so someone else can reproduce the decision.
    • Separate technical verification from business impact: proving that a fix shipped does not prove that rankings, traffic, AI citations, or revenue improved.

    A green status can conceal four different failures

    A green status beacon sits above four transparent pipeline chambers containing different hidden software and website configuration failures.

    Most weak verification starts with one overloaded question: “Is it done?” That question allows several different claims to collapse into one answer. Code can exist without being deployed. A function can run without its output reaching the interface. A page can look correct in a browser while its raw HTML or response headers remain wrong. A crawler can stop reporting an issue because its configuration or crawl path changed.

    Use four checkpoints instead:

    1. Specified: Does the requirement describe the intended behavior precisely enough that two implementers would build the same thing?
    2. Implemented: Is the required logic present in the code, template, configuration, edge rule, or data pipeline that is supposed to provide it?
    3. Deployed and executing: Is that implementation included in the production build, active under the relevant conditions, and operating on the intended URLs or inputs?
    4. Observable: Does the intended recipient actually receive the result through the raw response, rendered page, crawlable link graph, report, interface, API, or other promised delivery surface?

    These checkpoints catch different defects. A unit test may prove that a function behaves correctly while saying nothing about whether the function was wired into the production path. A deployment log may prove that a build reached the server while saying nothing about which markup a crawler received. A backend record may prove that a value was calculated while saying nothing about whether the client ever received or saw that value.

    The risk is not merely theoretical. In one production platform, a core trust-scoring capability was described in documentation and client-facing materials but was absent from the live system. The gap survived eight months of status updates because the updates reported completion without testing the promised capability from end to end.

    That distinction matters even more when AI writes the code. An AI can satisfy the visible shape of a request while missing an unstated business rule, an edge case, a template family, or the connection between backend logic and frontend delivery. Its confident explanation is a description of its attempt. Your acceptance test decides whether the attempt succeeded.

    Write the acceptance test before AI writes the code

    A prompt is not automatically a specification. “Fix the canonicals,” “add schema,” or “improve page speed” names a desired direction, but none defines a finished state. The ambiguity is especially costly when AI can produce a plausible patch before anyone has decided what the site should actually do.

    For each requirement, create a compact acceptance contract with these fields:

    • Problem: State the current mechanism, not a generic tool label. Identify what is absent, duplicated, incorrect, unreachable, delayed, or delivered to the wrong surface.
    • Scope: Name the templates, URL patterns, locales, environments, user states, bot states, or data inputs covered by the change. State important exclusions as well.
    • Required behavior: Describe the exact output and the conditions under which it should appear.
    • Observation point: Say where the behavior must be visible: response headers, server-delivered HTML, rendered DOM, internal link graph, structured data, API response, interface, export, or report.
    • Test procedure: Record the URLs or inputs, the actions to perform, the tool or retrieval method, and the comparison to make.
    • Pass condition: Define an observable result that produces an unambiguous pass or fail.
    • Negative and edge cases: Include conditions where the feature must not run, as well as representative boundary cases.
    • Required evidence: Decide what must be attached to the ticket, such as a response capture, rendered output, crawl extract, test result, or screen recording.

    Consider a canonical issue on product variants. “Fix the canonical tags” leaves the consolidation policy, affected templates, output location, target format, and test method open to interpretation. A workable acceptance contract could instead say:

    • Problem: Variant URLs on the named product template emit self-referencing canonical elements, although the approved policy consolidates those variants to the parent product URL.
    • Scope: The named template and URL pattern only; category pages and independently indexable variants are excluded.
    • Required behavior: Each in-scope variant emits one canonical element whose resolved absolute URL exactly matches its approved parent URL.
    • Observation point: The server-delivered HTML, plus the rendered DOM if client-side code can alter the element.
    • Test procedure: Fetch representative standard, parameterized, and edge-case URLs; compare the emitted target with the approved mapping; then crawl the in-scope pattern to look for recurrence.
    • Pass condition: Every tested URL emits the expected target, no tested page emits a second conflicting canonical, and the scoped crawl finds no instance of the original mechanism.

    This contract does more than test the final patch. It forces the team to decide which variants should consolidate before code is generated. That is the right time to find an unclear policy. If you wait until review, the implementation itself starts dictating the requirement.

    You can ask AI to draft test cases, identify ambiguities, propose edge cases, and explain which files it changed. Do not ask it to define success after it has already selected an implementation. A human owner should approve the expected behavior first, particularly when the change can alter crawling, indexing signals, redirects, rendering, or customer-visible reporting.

    Translate technical SEO findings into build specifications

    An audit tool reports what it detected under its own rules. It does not know your indexation policy, locale model, preferred URL mapping, rendering architecture, business priority, or acceptable exception. That is why forwarding a scanner flag is not the same as writing a specification.

    Before opening a build ticket, identify the underlying mechanism and convert it into a result the implementer can observe. The following patterns show the level of precision to aim for.

    Audit labelMechanism to identifyExample of a verifiable pass condition
    Broken canonicalOn named URLs or templates, determine whether the canonical is absent, duplicated, malformed, non-resolving, or pointed at a target that conflicts with the approved mapping.Each representative URL emits one expected absolute canonical at the required observation point, with no conflicting duplicate; a scoped recrawl finds no recurrence of that mechanism.
    Missing hreflangIdentify the affected locale cluster and whether the failure is a missing entry, an incorrect locale value, a broken target, or an incomplete reciprocal mapping.Every tested member of the approved cluster emits the complete intended mapping, each mapped target resolves as expected, and reciprocal entries are present where the site policy requires them.
    Orphaned pageConfirm that the page is intended to be discoverable through internal links and that the orphan finding is not caused by the crawl seed, exclusions, blocked resources, or a deliberately isolated workflow.The page receives the specified crawlable internal link from the approved source or template and becomes reachable when the agreed crawl is rerun from its defined seed.
    Page speed issueName the affected metric or event, URL or template, test environment, and likely mechanism, such as server delay, a render-blocking resource, or an oversized page component.The specified server, template, asset, or delivery change is present, and the same measurement procedure is rerun on the same scope with the before-and-after evidence attached. Any numerical threshold must come from the project’s approved performance target.
    Structured data issueIdentify the exact entity, property, value, page type, and generation layer involved. Separate invalid syntax from markup that is valid but inconsistent with visible page content or the site’s entity model.The production page emits parseable JSON-LD matching the approved schema contract and visible content on all representative templates, with absent or inapplicable properties omitted according to that contract.

    The last column is deliberately narrower than “SEO improved.” A developer can control whether the required markup, link, header, or response ships. The team cannot turn a ranking, citation, or traffic change into a guaranteed acceptance criterion for one technical ticket. Keep the engineering test causal and observable; measure search outcomes separately over an appropriate period.

    Triage the finding before specifying the fix

    Not every crawler warning deserves development time. Run four checks before converting one into a ticket:

    1. Confirm the mechanism. Inspect representative affected URLs rather than relying only on the tool’s label.
    2. Confirm the intended policy. Decide what the site should do and whether the flagged behavior is genuinely wrong for this template, locale, or page state.
    3. Confirm the scope. Determine whether the issue affects one page, one template, one release path, or a broader class of URLs. Include a known-good comparison where possible.
    4. Confirm the owner and layer. Route the change to the place that produces the defect: server configuration, CDN or edge rule, application logic, template, content entry, client-side rendering, or reporting interface.

    This prevents two familiar mistakes. The first is repairing a symptom at the page level when a template or delivery rule keeps regenerating it. The second is applying a broad template fix to a finding that was actually caused by one malformed record. AI will happily automate either mistake if the requested scope is wrong.

    Verify the production response and leave reproducible proof

    A developer checks a live website response on a laptop while organizing server, crawler, source, and screenshot evidence in an adjacent tray.

    Reviewing code is useful, but technical SEO behavior is often shaped by several layers after the code is written: build configuration, environment variables, content data, feature flags, routing, caches, edge rules, rendering, and deployment state. Verification therefore has to follow the result to the surface where a crawler, user, customer, or reporting recipient encounters it.

    Run a layered release check

    1. Freeze the requirement and baseline. Save the acceptance contract and capture the failing response, page, crawl result, or user-facing behavior before implementation. Without a baseline, a changed result can be mistaken for a correct one.
    2. Inspect the implementation layer. Confirm that the relevant code, template, rule, mapping, or configuration exists and covers the stated conditions. This catches omitted logic and accidental changes outside scope.
    3. Run focused automated tests. Test the core rule and the edge cases identified in advance. A passing build is not enough when the build contains no assertion for the requirement you care about.
    4. Confirm the deployed artifact. Tie the test to a build or release identifier. Verifying a local branch or staging build does not prove that the same change reached production.
    5. Observe the receiving surface. Inspect the raw status, headers, and HTML when the requirement lives there. Render the page when scripts can create or modify the output. Crawl from the agreed seed when discovery or internal linking is the concern. Open the interface or export when a customer-visible result was promised.
    6. Test representative failures and exclusions. Check a normal case, an edge case, and a case where the behavior must not apply. A feature that works everywhere can be just as wrong as one that works nowhere.
    7. Repeat the check in production. Re-run the defined procedure against the live URLs or inputs after deployment. If caching or delayed processing is part of the system, verify the result after the relevant layer has updated rather than assuming a purge or job completed.
    8. Run a scoped regression check. Confirm that adjacent templates, locales, page states, or outputs named in the risk assessment still behave as intended.

    Choose only the layers that can affect the requirement, but do not stop one layer early. If the promise is “the customer can see the score,” a correct database value is intermediate evidence. If the promise is “a crawler receives this canonical,” a correct component in the source repository is intermediate evidence. In both cases, the final check belongs at the receiving surface.

    Build a proof packet another person can reproduce

    A screenshot can help, but it rarely captures request conditions, raw markup, build identity, or scope. Close the ticket with a small proof packet containing:

    • The requirement or acceptance-test identifier.
    • The production build, release, or configuration version tested.
    • The exact URLs, inputs, locale, login state, user agent, or feature state needed to reproduce the check.
    • The test date and environment.
    • The retrieval, rendering, crawl, validation, or interface procedure used.
    • The expected result beside the actual result.
    • Raw evidence where relevant, such as response headers, HTML, JSON-LD, API output, a crawl extract, an automated test result, or a user-facing capture.
    • Any exceptions, unresolved cases, and the person responsible for the next decision.

    This changes reporting from activity to evidence. “The canonical fix was deployed” reports an action. “The named production build emitted the approved canonical for the standard, parameterized, and edge-case samples; the scoped crawl found no recurrence; one excluded template was unchanged” reports a verified result and its boundary.

    Keep technical proof separate from search impact

    Verification should also limit what you claim. A passing structured-data test proves that the tested markup conforms to your approved contract. It does not prove that a search engine will display a feature or that an AI system will cite the page. A correct canonical implementation proves that the declared signal shipped. It does not prove which URL a search engine will ultimately select or how rankings will move.

    Report those as separate layers:

    • Delivery: What code, configuration, template, or content change entered production?
    • Technical behavior: What did the live system return or display under the defined test conditions?
    • Coverage: How much of the intended URL, template, locale, or user-state scope passed?
    • Search or business outcome: What later changed in discovery, indexing, visibility, citations, traffic, leads, or revenue, and what other factors prevent a simple causal claim?

    This separation protects decision quality. A failed search outcome does not retroactively mean the implementation test was invalid, and a successful implementation does not justify claiming an outcome that has not been measured.

    Make evidence part of the definition of done

    The workflow becomes durable when the ticket cannot close without its proof packet. Let AI generate code, suggest cases, draft automated checks, and compare outputs. Keep human ownership over the intended policy, acceptable scope, production evidence, exceptions, and business claim.

    Start with one open technical SEO ticket. Replace its audit label with the exact mechanism, affected scope, required production behavior, observation point, and pass condition. If you cannot describe the evidence that would make you close it, the work is not ready to be built. If you can, both the AI and the reviewer have a standard they can actually meet.

    References


  • Profound Citation Decay Tracking: A Practical Workflow

    Profound Citation Decay Tracking: A Practical Workflow

    Your AI visibility report can look healthy while an important page quietly loses citations week after week. If you only check the latest total, you may miss the decline until the URL has largely disappeared from the answers that matter to your business.

    Profound Citation Decay tracking gives you the history needed to spot that movement. The harder part is deciding whether the decline is meaningful, finding its likely cause, and choosing a response that does not make the page worse. This workflow takes you from the first downward signal to a controlled recovery test.

    Build a citation-lifetime view before diagnosing the decline

    Profound tracks week-over-week citation counts for every cited URL and shows the full lifetime of each citation. That history changes the question you can answer. A current count tells you where a URL stands now; its lifetime shows whether the current position is normal, deteriorating, recovering, or simply unstable.

    Treat citation decay as a trend in URL-level appearances, not as a conventional ranking drop. The count tells you how often the URL was cited within the monitored environment. By itself, it does not tell you why the URL was selected, whether the citation was favorable, how much traffic it generated, or whether the page still ranks in search.

    MeasurementQuestion it answersHow to use it
    Weekly citation countIs the URL appearing more or less often than in the previous reading?Keep this as the unmodified observation from Profound.
    Weekly directionIs the count rising, flat, or falling?Compare the current reading with the immediately preceding reading.
    Current decay runIs the decline isolated or continuing?Mark successive weekly decreases until the URL stabilizes or recovers.
    Distance from the previous highHow far has the URL moved from its strongest observed point?Compare the current count with the highest count in its recorded lifetime.
    Normalized citation rateCould a changing opportunity pool be distorting the raw count?Use citations divided by eligible monitored observations only when you have a valid, consistently measured denominator.

    Comparability matters more than a sophisticated formula. A weekly decline is difficult to interpret if you also changed the monitored questions, models, markets, languages, collection cadence, or URL-grouping rules. Record those scope changes beside the timeline. Otherwise, a measurement change can look like content decay.

    Keep raw URLs separate before you create domain or page groups. A canonical URL, a redirected address, and a parameterized variant may represent one underlying asset to you, but they are distinct strings in a URL-level history. Preserve those identities, then add an explicit grouping layer. This lets you see both the citation selected by the model and the broader performance of the content asset.

    Read the shape of decay before deciding what it means

    Three illuminated pathways show a gradual fade, a sudden drop, and an irregular decline with partial recovery.

    Not every downward movement deserves the same response. The shape of the history tells you what to investigate first.

    • An isolated weekly dip: One lower reading establishes movement, not a durable decline. Confirm that the tracking scope stayed comparable and inspect the next weekly reading before rewriting the page.
    • A persistent slide: Successive weekly decreases indicate that the URL is repeatedly losing citation appearances. Move the URL into active investigation and identify which monitored needs or answer contexts are affected.
    • A step-down followed by a lower plateau: A sharp break followed by stability calls for a dated check. Look first for a tracking-scope change, URL migration, redirect, publication change, technical issue, or broad shift in the answers being monitored.
    • Intermittent citation: Repeated disappearance and return means the URL is being selected inconsistently. Examine whether the page only partly satisfies the relevant user need, competes with another page on your site, or lacks a clear answer that can be extracted without extra interpretation.
    • A portfolio-wide fall: When many unrelated URLs decline together, start with common factors. Verify the monitoring setup, shared technical controls, site accessibility, and broad changes to the answer environment before launching page-by-page rewrites.
    • URL substitution: If one owned URL falls while another owned URL serving the same need rises, your domain may not have lost the citation opportunity. Confirm the replacement before classifying the movement as brand-level decay.

    This separation prevents a common analytical error: treating every falling URL as an editorial failure. Citation decay is evidence that selection changed. It is not evidence of a particular cause. Your job is to narrow the plausible causes with the least destructive checks first.

    Investigate in an order that prevents false fixes

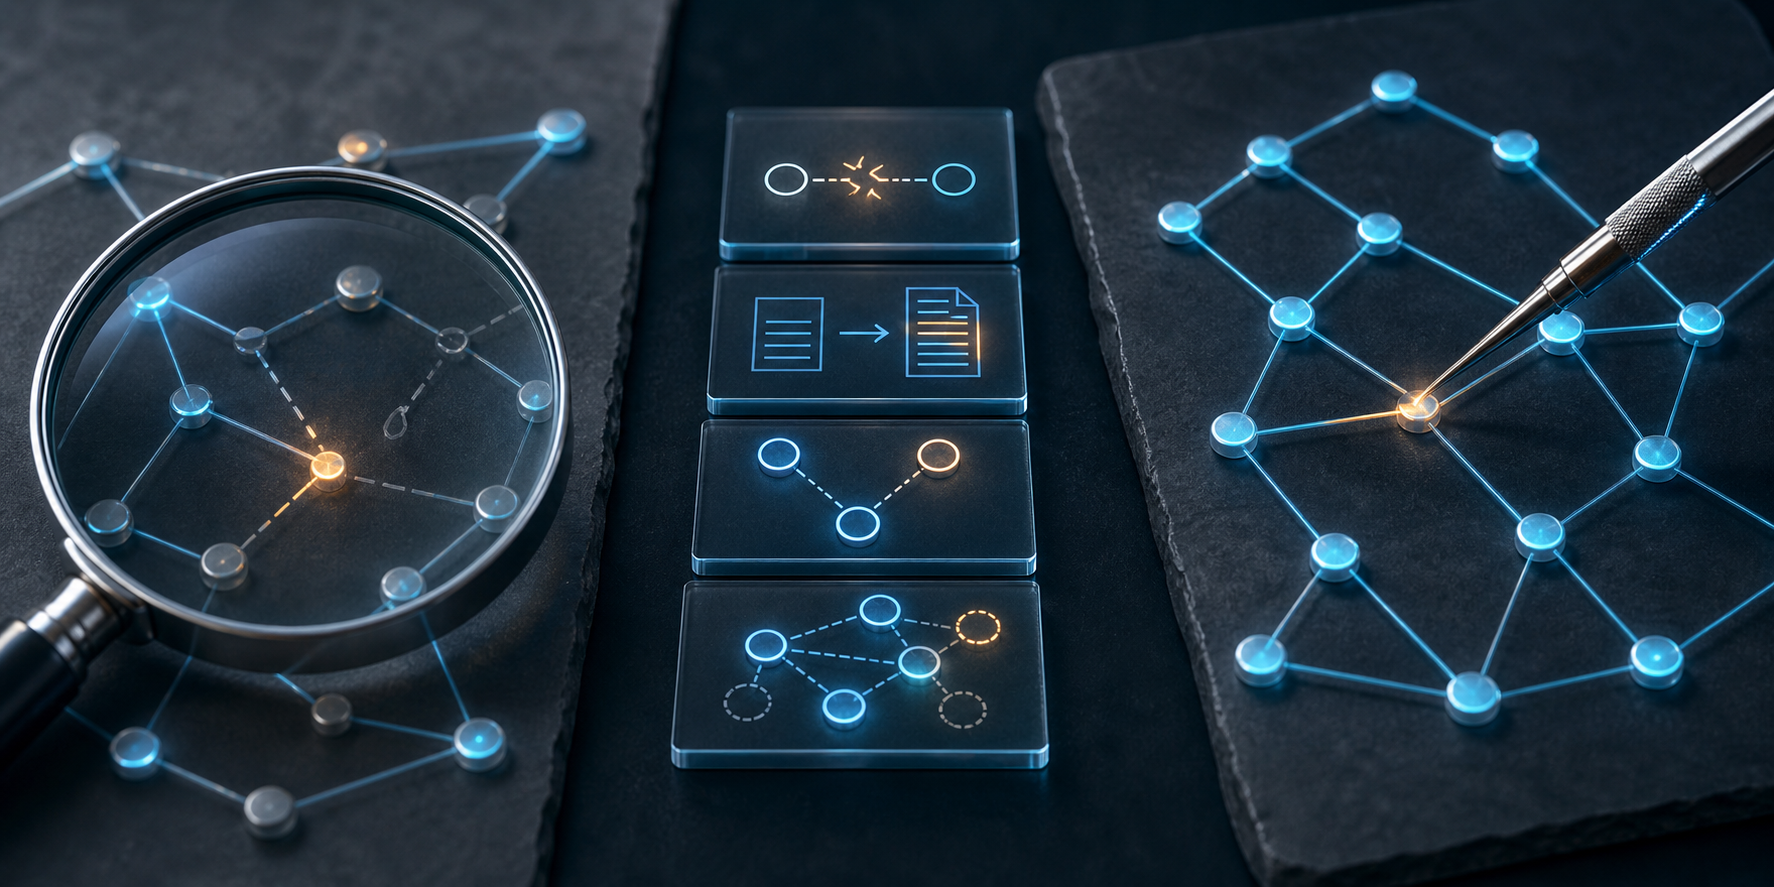
    A magnifying lens, layered diagnostic tiles, and a precision tool form a left-to-right investigation and repair sequence around a citation network.

    Start with measurement and identity, then move toward technical and editorial explanations. If you reverse that order, you can spend hours improving a page whose apparent decline came from a changed prompt set or a replacement URL.

    1. Confirm a comparable measurement frame. Check whether the monitored questions, platforms, markets, languages, and collection rules remained consistent across the decline. Annotate any change instead of blending unlike periods into one trend.
    2. Reconcile the URL. Check redirects, canonical targets, trailing-slash variants, parameterized versions, protocol variants, and moved content. Determine whether Profound is tracking a real loss or a shift in the address being cited.
    3. Locate the affected user need. Review the monitored questions and generated answers in which the page was previously cited. Group them by the decision, problem, entity, or fact the user wanted. A page rarely needs to be improved for every possible query; it needs to become a better fit for the citation contexts it is losing.
    4. Check retrieval and page accessibility. Confirm that the URL returns usable content without an unintended redirect, access restriction, noindex instruction, canonical conflict, or rendering failure. Verify that the main answer is present in the rendered page rather than hidden behind an interaction that a retrieval system may not process reliably.
    5. Compare the currently cited alternatives. Look at what another URL provides in the affected answer context. Compare scope, directness, evidence, entity clarity, update status, and the amount of interpretation required to extract the answer. You are looking for a specific usefulness gap, not permission to imitate another page.
    6. Match the intervention to the evidence. Fix an access problem with a technical change, an identity problem with URL consolidation, a relevance problem with a clearer answer, and a scope problem with better measurement controls. Do not prescribe a content rewrite for every type of decay.

    Structured data deserves a check, but it is not a citation-recovery switch. Make sure your JSON-LD describes the visible page accurately, uses consistent entity names and URLs, and does not contain claims absent from the content. Then fix the actual access, identity, or answer-quality issue. Adding more markup cannot compensate for a page that does not satisfy the monitored need.

    Match the intervention to the observed pattern

    Observed patternWorking hypothesisBest first actionAvoid
    One URL falls while a related owned URL risesInternal URL substitution or overlapping intentConfirm that the replacement serves the same need, then clarify page roles or consolidate genuine duplication.Deleting the declining page before checking links, redirects, and unique value. Deletion can destroy useful content and inbound signals; preserve the page until the replacement path is verified.
    One URL falls while related pages remain stablePage-specific access, identity, or usefulness issueInspect the URL technically and compare it with the pages now being cited for the affected need.A sitewide rewrite that introduces unrelated variables.
    A related group of pages declinesShared topic gap, architecture problem, or changed monitoring demandAudit the group for overlapping intent, missing answers, weak internal relationships, and inconsistent entity descriptions.Patching an isolated paragraph without checking the shared pattern.
    Unrelated URLs decline togetherMeasurement, platform, or sitewide technical factorVerify tracking scope and common accessibility controls before editing content.Refreshing every publication date or rewriting the entire portfolio.
    The URL repeatedly falls and returnsUnstable selection or an ambiguous match to the user needCollect subsequent weekly readings under the same scope and make the relevant answer more explicit.Declaring recovery or failure from an isolated reading.

    When the evidence points to the page itself, edit for answer fit rather than generic freshness. Put the direct answer under the heading where a reader expects it. Define important entities and relationships explicitly. Remove contradictions and stale claims. Support factual claims with appropriate evidence. Use descriptive internal links to connect genuinely related pages. Align the title, primary heading, canonical identity, visible content, and structured data around the same subject.

    Consolidate pages only when they serve substantially the same need. If each page answers a distinct question, clarify that distinction instead. Combining unrelated intents can produce a longer page that is less precise and harder to cite. If consolidation is justified, preserve the stronger destination, update internal links, and use a verified redirect path rather than simply removing the weaker URL.

    Log every meaningful intervention beside the weekly history. Record the affected URL, the date, the diagnosis, the evidence behind it, the exact changes made, and the result you expect to see. Avoid stacking unrelated changes between readings. When accessibility, copy, internal links, and structured data all change at once, the eventual movement cannot tell you which diagnosis was right.

    Key takeaways

    • Use the URL’s full citation lifetime, not its latest count, to distinguish an isolated dip from persistent decay.
    • Keep the measurement frame comparable. Annotate changes to monitored questions, platforms, markets, languages, cadence, or URL grouping.
    • Check for URL substitution and portfolio-wide movement before concluding that one page has failed.
    • Investigate in sequence: measurement scope, URL identity, affected user need, technical accessibility, cited alternatives, then content and JSON-LD.
    • Choose the smallest intervention that fits the evidence, record it, and judge the result through subsequent weekly readings under the same conditions.

    Start with the declining URL tied to your most important user need. Write down the decay pattern, rule out a measurement or URL-identity problem, and form one testable explanation before changing the page. That turns citation decay from a worrying chart into a disciplined content and technical optimization loop.

    References


  • Google Ads Automated Language Matching: What to Change Now

    Google Ads Automated Language Matching: What to Change Now

    If you run multilingual Google Ads campaigns, the language setting you once treated as a boundary is about to stop doing that job on Search. Leaving your campaigns untouched may not break delivery, but it can make language allocation harder to predict and language-related waste harder to diagnose.

    Your immediate task is not to find a replacement checkbox. It is to make every eligible ad and destination unmistakably suitable for the language journey you intend, preserve the controls that still matter in Performance Max, and give your reporting enough structure to expose mismatches.

    Know exactly where the language setting stops applying

    Beginning in late September, campaign-level language targeting will disappear from Search and AI Max for Search campaigns. Google will instead match Search ads largely from the language of the ads and signals indicating which languages a user understands.

    Campaign or placementWhat happens to selected languagesWhat you should control
    Standard SearchThe campaign-level setting no longer controls matchingAd language, ad-group clarity and destination language
    AI Max for SearchThe campaign-level setting no longer controls matchingAd language, eligible ad groups and destination language
    Performance Max on Google SearchThe selected campaign languages no longer apply to Search deliverySearch-facing creative and destination language
    Performance Max on YouTube, Display, Discover and GmailSelected languages continue to guide deliveryCampaign language settings as well as multilingual assets
    Shopping ads within Performance MaxLanguage settings do not affect these adsThe product and destination experience rather than the campaign language selector

    The Performance Max distinction is the easiest place to make an expensive mistake. Do not remove its language settings merely because they no longer govern Search inventory. Those settings continue to guide YouTube, Display, Discover and Gmail delivery.

    The opposite warning applies to standard Search. An existing language criterion may remain visible, but visibility does not mean enforcement. Do not use it as proof that a campaign can reach only people associated with the selected language.

    Rebuild multilingual control around the ad-to-page journey

    Three color-coded customer pathways connect abstract speech waveforms to matching search ads and landing pages while a marketer adjusts one route.

    Google can use the language of the search term, a user’s language settings and other preferences to estimate what that person understands. A user whose interface is set to one language may still receive an ad in another language if their behavior supports that match. Your campaign setting will no longer override that judgment on Search.

    That makes the ad itself a routing signal. It also makes language consistency a practical control surface: the promise in the ad, the page it opens and the next action should all work for the same reader. Audit that path in this order:

    1. Inventory every active Search ad by its actual language. Do not classify an ad from its campaign name. Read the headline, description, extensions or assets, and call to action.
    2. Record the destination language. Check the page headline, primary offer, form fields, validation messages and conversion action. A translated ad does not create a supported journey when the page or form switches languages.
    3. Identify mixed-language ad groups. If clean diagnosis matters, separate ads by intended language at the ad-group level. This gives you a clearer record of which language candidate received traffic and what happened afterward.
    4. Keep campaign separation only when it serves another business control. Separate budgets, markets, offers or conversion goals can still justify separate campaigns. Duplicating campaigns solely to select different Search languages no longer creates a reliable language boundary.
    5. Document the Performance Max exception. Mark which selected languages must remain because the campaign also serves YouTube, Display, Discover or Gmail.
    6. Add language to launch QA. Treat an ad, its destination and its conversion path as one test case. Approving only the translation of the ad leaves the costly part of the journey unchecked.

    Clear structure matters when more than one campaign or ad group is eligible. Google says AI-based ad-group prioritization will choose the candidate with the most relevant language. You cannot force that decision with the former Search language control, but you can avoid giving the system ambiguous or poorly supported candidates.

    Make landing-page language an operating requirement

    A language change in the campaign interface used to feel like a targeting task. The new model makes it a content-operations task as well. Ad creative and destination pages now carry more of the burden for Search language matching, so page ownership can no longer sit outside the campaign migration.

    For each language you actively advertise, define what a complete supported experience means. At minimum, the user should be able to understand the offer, evaluate the main terms and complete the primary action without an unexplained language switch. If the business cannot support that journey, pause or remove the corresponding ad rather than hoping the old campaign criterion will suppress it.

    Use language-specific destination paths where they already fit your site structure. They make QA and reporting easier because a landing URL can be reconciled with the language label on an ad group. The URL does not need to become a targeting theory; it needs to help your team answer a concrete question: did the intended ad open the intended experience?

    Translation alone is not enough when the offer changes by market. Check prices, availability, legal terms, fulfilment language and contact options wherever they appear in the conversion path. Those checks are not new Google Ads controls. They are safeguards against paying for a click whose promise the destination cannot fulfil.

    Monitor language matching without waiting for a perfect report

    Two analysts inspect color-coded routes between generic ad tiles and landing pages, with one mismatched connection highlighted in red.

    Automated matching can change which eligible language candidate receives traffic. Build a baseline before the rollout so a later shift is visible. The baseline does not need a new platform metric; it needs stable labels and a repeatable review.

    • Label ads and ad groups by intended language. Use one naming convention across the account so reports can be grouped without rereading every ad.
    • Record performance by that label. Compare impressions, spend, clicks, conversions and conversion value where those measures apply to your objective.
    • Review search terms against the served ad language. Read the whole query before classifying it. Brand names and borrowed words can appear inside queries written in another language.
    • Reconcile destination paths. Flag cases in which a language-labelled ad opens a page intended for a different language.
    • Use downstream evidence. Unsupported-language form submissions, calls or support requests can reveal a mismatch that click metrics alone will not explain.
    • Separate Performance Max observations by placement where your reporting allows it. A Search-delivery change should not automatically be blamed on the language settings that still guide the campaign’s other channels.

    Set alerts from your own baseline rather than borrowing a universal percentage. The available information does not establish a normal amount of language reallocation or a safe variance threshold. Your alert should identify a material change in your account, not pretend that every advertiser will experience the same shift.

    When you find a problem, change one controllable layer at a time: the eligible ad, the ad-group structure or the destination. That preserves enough evidence to tell whether the correction worked. Rebuilding campaigns, rewriting ads and changing pages simultaneously may stop the immediate symptom, but it will leave you unable to identify the cause.

    Update Google Ads API workflows by campaign type

    API users have a concrete migration requirement. Stop sending language criteria when creating or updating Search campaigns. Attempts to add or update CampaignCriterion.language for Search will return ContextError.OPERATION_NOT_PERMITTED_FOR_CONTEXT.

    Existing Search language criteria may remain but will no longer affect targeting. You may remove them, but cleanup is optional. If another internal system reads those objects, decide whether retaining inert criteria would mislead operators before choosing to leave them in place.

    Do not apply the same rule indiscriminately to Performance Max. Its language setting still influences non-Search channels, so Performance Max will not return the same context error. Branch the workflow by campaign type instead:

    1. Exclude language criteria from new Search campaign requests.
    2. Remove language mutations from Search update jobs and templates.
    3. Allow existing Search criteria to remain only if your interface clearly marks them as non-operative.
    4. Preserve supported Performance Max language operations for the channels where they still matter.
    5. Test both create and update paths so error handling does not hide unrelated failures behind the expected context error.
    6. Update internal documentation, validation rules and campaign builders that still describe Search language selection as an enforceable control.

    This is more than an API compatibility fix. If an internal campaign tool continues showing a required Search language selector, users may believe they established a boundary that Google no longer observes. Removing that false assurance is part of the migration.

    Key takeaways

    • For Search and AI Max for Search, stop treating campaign-level language selection as a targeting restriction.
    • For Performance Max, preserve selected languages because they still guide YouTube, Display, Discover and Gmail, even though they no longer govern Search placements.
    • Use deliberately separated ad languages, clearly matched destinations and consistent labels to make automated decisions easier to diagnose.
    • Keep separate multilingual campaigns when budgets, markets, offers or goals require them, not merely to recreate a language switch that no longer controls Search delivery.
    • Remove Search language mutations from API workflows, while retaining campaign-type logic for Performance Max.

    Start with the account inventory and the API branch before late September. Then run the ad-to-page language audit while the old structure is still familiar. You cannot restore the removed Search control, but you can make every language candidate intentional, measurable and supportable before automated matching decides where it belongs.

    References


  • How to Measure AI Search Visibility Beyond Referral Traffic

    How to Measure AI Search Visibility Beyond Referral Traffic

    If your AI referral report shows a handful of visits, it is tempting to conclude that AI search does not matter yet. That conclusion may be wrong. The click is only the visible handoff; an AI-generated answer can teach the buyer, establish credible options, and shape the shortlist before anyone reaches your site.

    You need a measurement model that separates answer visibility, referral performance, and buyer influence. That distinction lets you protect the SEO traffic you already have, improve the quality of AI referrals, and judge crawler access with evidence instead of reacting to one traffic number.

    AI visibility has three separate outcomes

    Three connected scenes show an object appearing in an AI answer, a visitor entering a website, and a buyer choosing an option for a shortlist.

    A buyer can use an AI Overview or assistant to understand a category, compare approaches, identify evaluation criteria, and notice several brands. By the time that person clicks, a meaningful part of the consideration process may already have happened.

    That creates three outcomes you should measure independently:

    • Answer visibility: Does the AI surface name your brand, cite your page, or accurately represent your information for commercially relevant questions?
    • Referral performance: Do people who click from an AI platform engage, complete a meaningful action, become qualified leads, or buy?
    • Buyer influence: Does exposure inside an AI answer help your brand enter the shortlist, earn a later branded search, receive internal consideration, or make a subsequent ad or sales interaction more credible?

    Do not collapse these into a single metric called AI traffic. A cited page can influence a buyer without receiving the eventual visit. A referral can convert without the referring page having been cited consistently. A brand mention can also be inaccurate or unfavorable, which means raw visibility is not automatically valuable.

    Organic search still deserves its own line on the dashboard. During Shopify’s second quarter, AI-referred sessions to merchant storefronts rose 197% year over year while organic search traffic grew 12%. Organic still sent more traffic than all tracked AI platforms combined. The useful interpretation is not that one channel is replacing the other. AI referrals are growing quickly on a much smaller base while organic search remains the larger acquisition engine.

    Those figures are directional commerce evidence, not universal benchmarks. The number of merchants and transactions behind them was not disclosed, so you should not use 197% as a forecast or treat any conversion multiple as a target for your own site.

    Key takeaways

    • Keep investing in organic SEO; AI visibility currently adds another discovery surface rather than making search traffic irrelevant.
    • Track citations and brand mentions separately from AI-referred sessions because a buyer can be influenced before clicking.
    • Judge AI traffic by conversion, qualification, pipeline, and revenue, not by session count alone.
    • Expect the strongest referral quality where buyers need help comparing specifications, compatibility, evidence, or implementation details.
    • Keep visible product facts, structured data, and first-party catalog information consistent; explicit, reliable facts help both selection and conversion.
    • Use scrape-to-referral ratios as diagnostic evidence, not as an automatic rule for blocking or allowing a crawler.

    Measure the path from answer visibility to revenue

    An analyst examines linked objects representing an AI answer, source citations, a website visit, a shortlist, a sales conversation, and a purchase, with a separate crawler trail feeding into the evidence path.

    Your reporting should follow the buyer from the answer surface to the business outcome. No single system can capture that entire path, so give each tool a specific job.

    Create a repeatable AI visibility register

    Start with a fixed set of questions that represents the decisions your buyers actually make. Include problem-definition questions, comparisons, compatibility or implementation questions, evidence questions, and purchase-stage questions. Do not build the set entirely from high-volume keywords; a narrow question used by a serious buyer may matter more than a broad informational prompt.

    For each check, record:

    • The exact question and the AI platform or search surface.
    • The date of the check.
    • Whether your brand was named.
    • Whether your domain was cited and which URL was selected.
    • Which competitors appeared.
    • Your role in the answer: example, supporting authority, recommended option, alternative, or incidental mention.
    • Whether the description, product facts, and claims were accurate.
    • The buying stage represented by the question.

    Repeat the same checks on a consistent schedule. A single screenshot proves that an answer appeared once; it does not establish stable visibility. Track citation coverage as the share of monitored questions that cite your domain, but retain the underlying records so you can distinguish a valuable buying question from a low-value mention.

    Connect the visit to qualification and revenue

    Once a visitor reaches your site, web analytics becomes the operational record. GA4 acquisition reporting can separate traffic from AI assistants so you can compare it with organic, paid, direct, and other channels. Keep the operator-level referral detail as well; an aggregate AI channel can hide a small platform that sends unusually strong prospects.

    1. Separate acquisition: Build an AI-assistant view or channel grouping and retain source and referrer detail wherever it is available.
    2. Label landing-page intent: Group entry pages by research, comparison, implementation, product, pricing, or conversion intent. This reveals whether a platform sends early researchers or decision-ready visitors.
    3. Measure meaningful behavior: Track movement to relevant second pages, product exploration, sign-ups, purchases, consultation requests, form fills, and other events that correspond to an actual business outcome.
    4. Validate the journey: Use filtered session recordings to see whether visitors find the expected information, encounter friction, or leave after discovering that the page does not answer the question that brought them there.
    5. Pass attribution into the CRM: Preserve the original AI source, landing page, conversion action, and campaign context on the lead record. Web analytics can record a form submission, but the CRM must determine whether the lead became qualified, entered the pipeline, or produced revenue.
    6. Capture delayed influence: Add a short first-touch question to suitable lead forms and sales discovery notes. Options should let a buyer identify an AI assistant or AI-generated search answer without forcing that answer. Treat self-reported exposure as supporting evidence, not perfect causal proof.

    Use rates that answer different business questions:

    • AI referral conversion rate: meaningful conversions divided by AI-referred sessions.
    • Qualified lead rate: qualified AI-referred leads divided by all AI-referred leads.
    • Pipeline per session: sourced pipeline value divided by AI-referred sessions.
    • Revenue per session: closed revenue attributed to AI referrals divided by AI-referred sessions.
    • Citation coverage: monitored questions citing your domain divided by all monitored questions.
    • Accurate answer coverage: monitored questions that represent your brand correctly divided by all questions where the brand appears.

    The denominators matter. A platform with few visits can be commercially useful if those visits qualify at a high rate. A platform with many citations can still be weak if the citations occur on irrelevant questions or send visitors to a poor landing page.

    Buying intent also changes the comparison with organic search. In specification-heavy Shopify categories, AI-referred shoppers converted at roughly twice the rate of organic visitors. In broader, taste-driven categories, organic search remained the larger discovery channel. Segment your analysis by category and intent before declaring AI traffic better or worse than organic traffic overall.

    Use scrape-to-referral data as a diagnostic

    AI crawlers can request many pages while their associated platforms send relatively few identifiable visits. The scrape-to-referral ratio makes that imbalance visible:

    AI scrape-to-referral ratio = recorded AI scrape activity / recorded referral visits

    A lower ratio means more recorded referrals for each recorded scrape, but it does not automatically mean more business value. A high ratio may still be acceptable when the resulting visitors buy, become qualified opportunities, or when the platform contributes meaningful answer visibility. It may be unacceptable when crawling creates a material operational or content-use cost and produces no outcome connected to the site’s purpose.

    Microsoft Clarity’s AI Visibility Dashboard now includes an AI Scrape-to-Referral Ratio card, operator-level breakdowns, coverage safeguards, and direct access to filtered session recordings. Use that workflow in this order:

    1. Check domain coverage first. Confirm that bot activity and referral traffic are measured across the same mapped domains. A CDN, subdomain, or incomplete analytics deployment can create a misleading ratio.
    2. Split the total by operator. An account-wide average can conceal one operator that returns useful visits and another that crawls heavily with little visible return.
    3. Pair the ratio with outcomes. Compare referrals with engagement, purchases, sign-ups, form fills, qualified leads, and revenue.
    4. Inspect representative recordings. Determine whether AI-referred users reach the right page, scroll to the needed information, continue to a commercial page, or abandon the journey immediately.
    5. Compare the result with answer visibility. A platform may influence consideration without generating a directly attributed visit, so include monitored citations and brand mentions in the decision.
    6. Make operator-specific decisions. Keep monitoring useful operators, repair landing-page problems where referrals are poor, investigate coverage when the ratio looks implausible, and consider access restrictions only after confirming that the operator produces no sufficient direct or assisted value for your objectives.

    There is no universal good ratio. A publisher funded by page views, an ecommerce store, and a B2B company with a long sales cycle receive different value from the same number of referrals. Define the outcome you require before setting a threshold. Otherwise, the ratio becomes a precise-looking number attached to an undefined business decision.

    Optimize for selection, trust, and the next action

    Measurement tells you where the journey breaks. The content fix depends on whether you are missing from the answer, attracting the wrong visitor, or failing to help an informed buyer take the next step.

    For ecommerce, make comparison facts explicit

    AI referral quality is strongest when the assistant can help with a demanding decision: specifications, compatibility, alternatives, reviews, and other concrete buying criteria. Your product pages and first-party catalog should therefore agree on the facts a buyer needs to compare options.

    • Use the exact product and variant names consistently.
    • Expose identifiers, dimensions, technical specifications, compatibility, included components, price, and availability where they apply.
    • Explain the differences between variants in buyer language instead of relying only on internal model codes.
    • State limitations and exclusions close to the relevant claim.
    • Keep visible page content, JSON-LD, and first-party catalog values synchronized.
    • Do not fill structured-data fields with unsupported or stale values merely to make the markup look complete.

    JSON-LD can make a fact explicit, but it cannot resolve a contradiction between the page, the catalog, and the checkout. Consistency is part of optimization because the visitor must encounter the same product the AI answer described.

    The commercial effect can be substantial. In Shopify’s merchant data, AI-referred shoppers converted at twice the rate when AI systems used structured Shopify Catalog data rather than scraped or third-party product feeds. Because this is vendor-supplied observational evidence with an undisclosed sample size, use it as a reason to test and improve first-party data quality, not as a guaranteed uplift.

    For B2B, cover the whole decision rather than one keyword

    A B2B buyer rarely moves from a definition to a purchase in one step. Build a connected set of pages that answers how the solution works, who it is for, how approaches differ, what evidence supports the claims, how implementation fits an existing workflow, what training or support is available, and what a buyer should examine before investing.

    Each page should do four jobs: answer its primary question early, show the basis for the answer, state the important boundaries, and offer the next action that fits the buyer’s stage. A technical explainer should link naturally to a comparison or implementation page; a comparison page should make the commercial evaluation path clear without pretending that every reader is ready for a sales call.

    Continue monitoring traditional rankings and AI citations separately. A page can rank prominently without being selected as an AI supporting citation, while a cited page does not have to occupy the first organic position. The remedies are related but not identical: ranking work improves discoverability, while complete, direct, well-supported answers improve the chance that your information is useful within an AI response.

    Start with one revenue-relevant journey. List the questions a buyer asks from initial research through comparison, check where your brand and URLs appear, audit the matching pages and structured facts, separate AI referrals in analytics, and carry the source into the CRM. After enough time for your normal sales cycle to complete, compare citation coverage, referral quality, qualified pipeline, and reported first-touch influence. That gives you a defensible next investment instead of a guess based on clicks alone.

    References


  • Off-Page SEO Beyond Followed Links: A Practical Strategy

    Off-Page SEO Beyond Followed Links: A Practical Strategy

    Your PR placement named your brand but did not include a followed link. Your monthly report may call that a miss. That is the wrong diagnosis.

    Followed backlinks still matter, especially when a commercial page needs authority. But off-page SEO now has a broader job: make your brand visible, credible and closely associated with the topics on which you want search engines and AI systems to recognize it. That requires a coordinated mix of direct link building, linkable assets, digital PR and mention reclamation.

    Key takeaways for off-page SEO

    • Use direct link building when a landing page or bottom-of-funnel resource needs a relevant backlink. It gives you more control over the destination and, subject to editorial approval, the surrounding context.
    • Count relevant unlinked brand mentions and nofollow citations as real outcomes. They can build topical visibility, create discovery paths and become candidates for later link reclamation.
    • Create useful assets that writers can cite without being asked, but reserve journalist outreach for assets with a genuine story rather than ordinary utility.
    • Judge link building, linkable assets and digital PR by different primary outcomes. A single followed-link target will misrepresent the work.
    • Track links and mentions together. Evidence connects both link quality and brand mentions with AI-search visibility, although correlation does not establish that either one caused a particular answer.

    Give each off-page tactic the right job

    A followed link answers a narrow reporting question: did another page create a crawlable connection to yours under the expected link attributes? It does not tell you whether an authoritative publication discussed your brand in the right context, whether an asset became a standard reference or whether your name is becoming associated with a valuable subject.

    That does not make backlinks obsolete. They have long been a confirmed part of Google’s ranking systems, and the quality of a site’s link profile has shown a strong correlation with AI-search visibility. The practical change is to stop forcing every off-page activity into a followed-link KPI.

    ApproachWhat you ask forBest primary jobEvidence of progress
    Direct link buildingA link, link correction or linked attributionSupport a specific commercial or bottom-of-funnel pageA relevant editorial link to the intended destination
    Linkable assetsUsually nothing after distributionBecome a reusable reference for writers and publishersNew citations and referring domains acquired naturally
    Digital PRConsideration of a newsworthy storyEarn relevant coverage and strengthen brand-topic associationQualified coverage, accurate mentions and any resulting links
    Mention reclamationAdd or correct a useful linkTurn existing recognition into a better citationAn unlinked or incomplete mention becomes a relevant linked reference

    Direct link building is the strongest choice when the destination matters. Because you are explicitly requesting a link, it has the highest probability of supporting landing pages and converting bottom-of-funnel content. Guest contributions can also give you some influence over context and anchor text, provided the publisher approves them editorially.

    Apply a strict quality screen before making that request. The publisher should cover the relevant subject, the link should help a reader understand or complete something, and the destination should fulfill the promise made by the surrounding text. Site-level authority scores and estimated traffic can inform the review, but neither rescues an irrelevant placement.

    Do not solve the scaling problem by buying placements or arranging excessive exchanges. Those practices conflict with Google’s link-spam policies. An outreach system that produces fewer editorially defensible links is safer and more useful than a high-volume system built around placements that can be ignored, devalued or removed.

    Linkable assets serve a different need. Free tools, industry lists, templates, checklists and current statistics pages give writers something useful to reference. They can earn links after becoming discoverable through search, email, social distribution or existing audience channels. If an asset is not visible anywhere, its usefulness alone will not create discovery.

    Match the format to the intended route. A calculator or template may attract citations steadily, but ordinary utility is rarely a compelling media story. A collection of third-party statistics can become a convenient reference in search, yet it is weak PR material because the underlying data is not yours. Use that kind of page as a durable citation asset; do not pitch it as exclusive research.

    Digital PR begins with the story. You ask an editor or journalist to consider something timely, consequential or genuinely revealing, not to satisfy a link quota. A relevant mention in respected coverage may be more strategically valuable than an unrelated followed link, even when the publisher leaves the mention unlinked or applies a nofollow attribute.

    Build a flywheel instead of running isolated campaigns

    A circular mechanism connects content creation, editorial coverage, relevant linking, and audience attention in a continuous loop.

    The strongest off-page programs let each approach create opportunities for the others. Treating PR, content and outreach as separate queues throws away much of that compounding value.

    1. Choose a narrow authority territory. Define the problem, category or decision for which your brand should be recognized. A broad ambition such as owning marketing is not actionable; a bounded subject gives content creators, outreach specialists and PR teams the same target.
    2. Map the destination pages. Identify the commercial page that needs support, the bottom-of-funnel resource that answers buying questions and the informational asset other writers could reasonably cite. Do not expect one URL to perform every role.
    3. Publish the reusable reference. Build the tool, template, checklist, list or statistics page around a recurring research need. Make its methodology, ownership, update status and intended use clear enough that a writer can assess it quickly.
    4. Seed discovery carefully. Initial guest contributions or broken-link outreach can help a new asset earn its first relevant links and improve its chance of being found. Existing email, social and community distribution can expose it without turning every interaction into a link request.
    5. Pitch the story when a story exists. If the asset contains original findings or supports a timely development, lead with what changed and why the publication’s audience should care. The asset provides evidence; the request is for editorial consideration.
    6. Reclaim the strongest coverage. Review accurate unlinked mentions, nofollow citations and references pointing to an inferior destination. Ask for a link only when it improves the reader’s path to evidence, a tool or a fuller explanation.
    7. Maintain what keeps earning attention. Links decay, lists become stale, statistics age and tools break. Refresh assets that continue attracting citations, and record lost links so you can distinguish normal decay from a correctable problem.

    This sequence also prevents a common targeting mistake. Commercial URLs usually need deliberate link outreach because publishers rarely cite sales pages spontaneously. Reference assets can earn links naturally, while PR can expand the number and quality of people who discover them. Coverage then supplies a qualified pool of mentions for selective reclamation.

    Measure links, mentions and visibility without mixing them up

    An analyst sorts link, conversation, and visibility symbols into three separate trays on a desk.

    Your scorecard should preserve the distinction between outputs and outcomes. A media mention, a followed link and an AI citation are different observations. Combining them into a single authority number makes a neat dashboard but hides what is actually working.

    Measurement areaRecordQuestion it answers
    Editorial linksDestination, linking page, topical context, anchor, link attribute and live statusDid we earn a defensible link that supports the intended page?
    Brand coveragePublication, topic, linked or unlinked status, mention accuracy and prominenceAre relevant publishers associating the brand with the intended subject?
    Linkable assetsPages citing the asset, discovery channel, repeat citations and update needsIs the asset becoming a reusable reference rather than relying on repeated asks?
    Search and AI visibilityQueries or prompts checked, engine or model, date, brand inclusion and cited pagesIs visibility changing across a consistent observation set?
    Business responseReferral activity where available, assisted journeys, qualified inquiries and relevant branded demandDid off-page exposure contribute to discovery or consideration?
    DurabilityLive, changed, lost and reclaimed links or mentionsHow much earned visibility remains intact?

    The AI-search row needs particular care. One analysis found that AI Overview visibility had a correlation of 0.664 with brand mentions and 0.218 with backlinks. That is a strong reason to monitor mentions alongside links. It is not proof that placing a mention will cause an AI system to include your brand, nor does it establish that backlinks are unimportant.

    Use a stable set of commercially relevant prompts when observing AI visibility. Record the model or search experience, the date, whether the brand appeared, what claim surrounded it and which pages were cited. Repeating the same observation method is more informative than collecting isolated screenshots of favorable answers.

    Keep tactic-level evaluation equally disciplined. Judge direct outreach by the quality and destination of the links it earns. Judge a reference asset by whether independent pages keep citing it. Judge PR by the relevance, accuracy and reach of its coverage, with links recorded as an additional result. Then review how those outputs relate to search visibility, referral activity and buying journeys without claiming causation you cannot demonstrate.

    Choose your next move from the constraint you actually have

    You do not need to launch every tactic at once. Start with the gap that is preventing useful off-page recognition:

    • Your commercial page has little authority: use selective direct outreach, guest contributions or relevant link reclamation. Make the reader benefit of the destination explicit.
    • Writers discuss the topic but have nothing from you to cite: create a durable tool, template, checklist, list or statistics resource that satisfies a recurring reference need.
    • You have an original and timely finding: develop a clear story and use digital PR. Pitch the finding and its consequence, not the desire for a backlink.
    • Your brand already appears in relevant coverage: review the mentions for accuracy, destination quality and link status. Reclaim only the cases where a link would materially improve the citation.
    • Your old assets once earned links but have slowed down: check freshness, broken functionality, changed URLs and lost citations before producing another asset on the same subject.
    • Your reporting shows links but cannot explain authority growth: add separate views for relevant mentions, asset citations, AI visibility observations and link durability.

    For your next campaign, decide in advance whether its primary job is to support a destination page, become a reference or earn a story. Record followed links, nofollow citations and unlinked mentions separately. That small change gives every off-page result a fair test while keeping the link equity your important pages still need in view.

    References


  • AI Search, Publisher Traffic, and the New SEO Competition

    AI Search, Publisher Traffic, and the New SEO Competition

    If your organic visits are falling while AI referrals barely register, it is easy to reach one of two conclusions: AI search does not matter, or SEO no longer works. Neither conclusion gives you a useful plan.

    Direct AI clicks are only one part of the discovery path. Traditional search still captures demand, AI answers can influence which publishers people remember, and technical weaknesses can determine whether a system retrieves your information or a competitor’s. You need to measure those effects separately before you cut investment, chase a new optimization acronym, or publish more content.

    AI referral traffic measures the handoff, not the whole journey

    A reader follows a winding path from generic search cards through an abstract AI portal to an open publisher doorway, with secondary routes branching around the journey.

    Across millions of searches, AI conversations, and publisher visits from a privacy-safe, opt-in panel between February and June 2026, only 1.1% of publisher visits following AI conversations carried an AI referrer. About three-quarters arrived through direct navigation, while roughly 9% came through traditional search.

    That does not make AI exposure irrelevant. Readers were 20.5 percentage points more likely to visit a news publisher during the week after a news-related AI conversation than after a non-news conversation. The comparison used each reader’s browsing history, but it cannot establish that AI created the demand. A news conversation may simply occur when someone is already interested in following a story.

    The defensible interpretation sits between the extremes. AI referrals undercount journeys that continue through a branded search or a direct visit, but a later visit does not prove that the assistant caused it. Last-click analytics can tell you how a session ended. They cannot reconstruct every answer, search, and return visit that preceded it.

    Build your reporting around distinct questions instead of forcing every signal into an AI traffic total:

    SignalQuestion it answersWhat it cannot prove
    AI-referred sessionsDid an AI answer produce an immediate click?Whether exposure caused a later direct visit or search
    Mentions and citations in AI answersIs your publisher visible for priority questions?Whether the visibility produced attention, trust, or revenue
    Branded search and direct navigationAre more people deliberately seeking your brand?Which prior touchpoint caused the change
    Organic click-through rate by query typeWhere is search demand still producing visits?Whether an AI feature alone caused a portfolio-wide decline
    Conversions and assisted conversionsDoes the traffic you retain contribute to a business outcome?The exact value of every unseen exposure

    Keep those rows separate. A citation is not a visit, a visit is not a conversion, and a conversion is not proof that the last click deserves all the credit. The goal is not to replace hard traffic numbers with soft visibility metrics. It is to stop asking one metric to explain a multi-step journey.

    The available figures also describe news publishing, not every industry. The panel measured page visits rather than subscriptions, revenue, or time spent. If you operate in ecommerce, software, healthcare, local search, or another market, use the behavioral pattern as a measurement warning rather than treating 1.1% as your expected benchmark.

    AI Overviews do not reduce every query’s clicks equally

    A portfolio average can make AI Overviews look more destructive than a like-for-like comparison supports. During the February-June 2026 measurement window, AI Overviews appeared on about one in four news searches. Searches containing an Overview produced publisher clicks about 20% of the time, compared with roughly 30% when one did not appear. Yet the difference narrowed to about 2 percentage points when the same query was compared with and without an AI Overview.

    The raw 10-point gap therefore should not be treated as the causal effect of the feature. AI Overviews appeared most often on utility-style searches such as weather, market prices, and explainers – query types that already generated relatively few publisher clicks. Sports searches had the highest publisher click-through rates and rarely triggered an Overview.

    For your own diagnosis, divide queries by the job the reader is trying to complete. At minimum, separate quick factual lookups from live coverage, analysis, proprietary reporting, and navigational searches. Then examine impressions, position, click-through rate, landing-page engagement, and conversion within each group. Record AI feature presence for a stable sample of important queries rather than assuming every impression faced the same search results page.

    This segmentation changes the decision you make. A utility page that answers a self-contained question may face structural click pressure because the answer can be consumed on the results page. Publishing a longer version of the same commodity explanation will not necessarily recover that visit. Give the reader a reason to continue: original data, a live resource, methodology, deeper analysis, a consequential next step, or reporting unavailable in the answer itself.

    A page serving active coverage or proprietary analysis requires a different response. Protect its crawlability, freshness signals, internal prominence, and distinct value before redesigning it around a presumed zero-click future. Query intent should determine the intervention; an overall organic traffic line cannot.

    Fix retrieval debt before buying an AI-specific tactic

    A page can rank in conventional search and still be awkward for an answer system to use. Ranking evaluates a page as a result. Retrieval may select a particular passage, fact, or section to assemble an answer. That creates a practical gap: your domain may be authoritative while the exact information a system needs is buried, duplicated, or dependent on an unreliable interface.

    Many supposed AI visibility problems are familiar technical SEO problems that have accumulated through redesigns, migrations, campaign launches, and uncoordinated publishing. Conflicting canonicals divide signals. Redirect chains complicate access. Several near-identical pages compete to own one topic. Critical information sits behind JavaScript interactions. Weak internal links leave the intended authority page isolated. Google may compensate for some of that mess when ranking a page, while a retrieval system still chooses a cleaner competitor passage.

    Audit the site by question and passage, not only by URL:

    1. Assign one preferred page to each priority topic. If your team cannot identify the owner, a machine is receiving the same ambiguity.
    2. Map every overlapping URL. Consolidate genuinely duplicative coverage, redirect obsolete versions where appropriate, and align canonical signals before adding more pages.
    3. Locate the exact passage that answers each important question. Put the direct answer near the beginning of a clearly labeled section, then add context, qualifications, and supporting evidence.
    4. Inspect the HTML a crawler receives. Essential definitions, product facts, and explanations should not depend entirely on tabs, client-side rendering, or interactions that may not execute reliably.
    5. Strengthen internal links from relevant, authoritative pages to the topic owner. Use anchor text that explains the relationship instead of relying on generic calls to action.
    6. Remove promotional interruptions and unrelated copy that obscure the useful passage. A retrieval-ready section should make its subject, answer, and evidence easy to distinguish.
    7. Address performance and redirect inefficiencies that make repeated retrieval slower or less dependable.

    Structured data can reinforce the entities and relationships already visible on the page, but it cannot decide which of five overlapping articles owns a topic. An llms.txt experiment cannot repair contradictory canonicals or inaccessible content. Treat new protocols and markup changes as hypotheses to validate after the underlying architecture is coherent, unless your crawl evidence identifies a specific protocol-level problem.

    This work is less glamorous than an AI optimization shortcut, but it improves the same assets traditional search, AI retrieval, editors, and readers depend on. Clear topic ownership, stronger headings, accessible passages, better internal links, consolidation, and reduced JavaScript dependence are not separate SEO and GEO programs. They are one information-quality program viewed through different discovery systems.

    Compete with evidence an incumbent cannot cheaply reproduce

    A publishing team records an original experiment with cameras, measuring tools, samples, and source materials while distant competitors observe through a glass wall.

    AI discovery is not automatically leveling the market. Major publishers accounted for 82% of publisher names volunteered by AI assistants and 97% of the follow-through visits. Existing brand recognition and authority still matter.

    Being named may matter even when the answer does not generate an immediate click. When an assistant mentioned a publisher the reader had not placed in the prompt, the probability of visiting that publisher increased by 10.6 percentage points the next day and nearly 20 percentage points over the following week relative to similar publishers not mentioned in the same response. This is a routing signal, not causal proof. It does, however, show why measuring only sessions labeled as AI referrals misses a potentially important competitive interaction.

    A challenger should not respond by trying to match a leader’s entire content library. Large libraries often contain stale, overlapping, and politically difficult pages. More stakeholders must agree on consolidation, and more existing traffic appears at risk whenever a template or URL changes. That operational drag creates an opening for a smaller publisher that can establish clean topic ownership and produce evidence worth citing.

    Choose a commercially or editorially important question where the current results are generic, fragmented, outdated, or weakly supported. Build one definitive asset around a defensible contribution:

    • Original research or proprietary data with a visible methodology
    • A named subject-matter expert who is accountable for the explanation
    • Firsthand reporting or experience that a generic synthesis cannot recreate
    • Specific product, service, or category knowledge grounded in real evidence
    • Customer reviews, case studies, or other proof that supports the claim being made
    • Public relations and distribution that help relevant people discover, discuss, and reference the asset

    These assets matter because they give people and machines a reason to choose you beyond word count. Original evidence, recognizable experts, customer proof, brand recognition, and clean technical foundations take time to build and are harder to copy than another generic keyword page.

    Make each asset retrievable as well as impressive. State the central finding plainly. Show where the evidence came from. Label the section that answers the target question. Link supporting detail to the canonical asset. Remove older pages that contradict or dilute it. Then distribute it where customers, journalists, practitioners, and other publishers can encounter it. No single action guarantees inclusion in an AI answer, but the complete asset gives search and answer systems something distinct to retrieve and gives humans something worth seeking by name.

    Key takeaways for your next publishing cycle

    • Do not use AI-referred sessions as your only AI metric. Track answer visibility, branded search, direct navigation, organic performance, assisted conversions, and final outcomes as separate signals.
    • Do not apply an average AI Overview click gap to every query. Compare like-for-like queries and segment performance by the reader’s task.
    • Protect pages that still capture high-intent visits. Redesign commodity utility content around unique follow-up value instead of adding more generic explanation.
    • Resolve topic ownership, duplication, canonical conflicts, weak internal links, buried answers, JavaScript dependence, and performance problems before treating a new AI file or schema change as the strategy.
    • Compete selectively. Build a definitive, evidence-rich asset where an incumbent’s coverage is fragmented or difficult to maintain rather than copying its library page by page.
    • Keep causal claims modest. A mention, direct visit, branded search, or assisted conversion can indicate influence, but none independently proves what caused the reader’s decision.

    Your next move is concrete: select one priority topic, identify every URL currently competing to own it, mark the passage that should supply the answer, and record a baseline across search visibility, AI visibility, direct demand, and conversions. Consolidate the topic, strengthen the evidence, and watch how each signal changes. That gives you a repeatable operating model while competitors are still debating whether AI traffic is large enough to matter.

    References


  • Campaign Manager 360 Real-Time Reporting API Guide

    Campaign Manager 360 Real-Time Reporting API Guide

    You need Campaign Manager 360 performance data inside a dashboard while someone is still looking at the screen. The traditional create-run-poll-download workflow can do the reporting, but it makes an interactive product carry the machinery of a batch job.

    The reportData.query endpoint gives you a shorter path: describe the data you need in the request and receive structured JSON synchronously. That can simplify dashboards and ad-hoc analysis considerably. It does not mean every reporting workload should move, nor does the word “real-time” guarantee that every underlying metric is updated instantly.

    The reporting flow is now a direct request-response path

    The traditional Campaign Manager 360 reporting flow is built around generated reports. Your application creates a Report resource, runs it, polls until processing finishes, and downloads the resulting file. That sequence remains useful when the file is part of the deliverable, but it introduces several states that an interactive application must manage.

    1. Create or identify the report configuration.
    2. Start the report run.
    3. Poll for completion.
    4. Download and parse the generated CSV or Excel file.
    5. Transform the result into the shape required by your interface or analysis.

    With reportData.query, developers can instead specify dimensions, metrics, and filters in the request body and receive structured JSON in the response. You do not have to create a Report resource before asking for the data.

    1. Define the dimensions that determine the result’s grain.
    2. Select the metrics needed by the dashboard or analysis.
    3. Apply filters that keep the request focused.
    4. Submit the synchronous query.
    5. Map the returned JSON into your application’s data model.

    The practical gain is not simply fewer API calls. Your application no longer has to model a report job, persist its status, poll it, retrieve an artifact, and parse that artifact before it can show a result. For a user-driven dashboard, removing that orchestration can make both the code and the experience easier to reason about.

    Keep the distinction precise, though: reportData.query simplifies the retrieval path. It does not make the Reports service obsolete, remove the need for a reporting data model, or turn an unfocused query into a fast one.

    Choose the endpoint by workload, not by which API is newer

    Two data-reporting routes show a short interactive query path beside a larger multistage batch-processing path.

    The clearest implementation decision is based on how the result will be consumed. Use reportData.query when a person or application needs a structured answer immediately. Keep the Reports service when the workload is large, scheduled, or expected to produce a downloadable file.

    Decision factorreportData.queryReports service
    Interaction modelSynchronous request and responseCreate, run, poll, and download
    Response formatStructured JSON in the API responseGenerated CSV or Excel file
    Best fitInteractive dashboards, real-time reporting experiences, and ad-hoc analysisLarge datasets, scheduled reporting, and file-based workflows
    ConfigurationDimensions, metrics, and filters are supplied directly with the queryA Report resource defines the report before retrieval
    Execution considerationA query can run for up to 60 secondsCompletion is handled as an asynchronous report job

    Four questions usually settle the choice:

    • Is a person waiting for the answer? A dashboard refresh, filtered table, or investigative view is a strong candidate for reportData.query.
    • Is the output itself a CSV or Excel deliverable? Keep the Reports service rather than retrieving JSON only to recreate the same file workflow.
    • Is this a large or scheduled extraction? The existing Reports service remains the preferred route.
    • Does the same system have both interactive and batch needs? Use both paths. A hybrid architecture is a deliberate workload split, not an incomplete migration.

    This prevents a common architectural mistake: replacing a sound batch process merely because a more convenient interactive endpoint exists. The new endpoint solves a different access pattern. It should take over the requests that benefit from synchronous JSON while the Reports service continues handling work that benefits from generated files and asynchronous execution.

    Design interactive queries that remain useful under pressure

    A direct endpoint removes report-job ceremony, but your dashboard still needs a disciplined query layer. The following design choices determine whether reportData.query feels responsive and trustworthy in production.

    Start with the user’s question, not every available field

    Define one question for each dashboard component. A campaign summary, a filtered placement table, and a diagnostic drill-down do not need to share one universal request. Give each component the smallest dimension grain, metric set, and filter scope that answers its question.

    Write down a compact query contract before implementation:

    • The decision or question the result supports.
    • The dimensions that determine what one result row represents.
    • The metrics the interface will actually display or calculate with.
    • The filters controlled by the application and the filters controlled by the user.
    • The behavior the user sees while the request is running.
    • The fallback shown when the request cannot return a usable result.

    This contract helps you notice accidental scope growth. If a new chart needs a different grain, give it a separate query rather than quietly expanding an existing request and making every dashboard refresh carry the extra work.

    Treat 60 seconds as a ceiling, not a target

    The endpoint allows queries to run for up to 60 seconds. That accommodates meaningful interactive analysis, but a dashboard can still feel broken long before the request reaches its limit.

    Design the interface for a genuinely synchronous operation. Show a clear loading state, keep unrelated controls usable, and decide what happens if the request takes longer than the user’s workflow can tolerate. Where appropriate, retain the last successful result and label it as such rather than replacing useful data with an indefinite spinner.

    Do not hide a consistently slow query behind a longer loading message. Narrow its dimensions, metrics, or filters. If the workload is inherently large rather than accidentally broad, route it to the Reports service.

    Do not equate synchronous retrieval with instant measurement

    “Real-time” describes the reporting access pattern here: your application submits a query and receives data directly instead of waiting for a generated report file. That alone does not establish how quickly every underlying campaign event becomes available as a reportable metric.

    If freshness affects an operational decision, verify it for the dimensions and metrics you use. Give the dashboard an “as of” indicator based on information your implementation can substantiate, and avoid labels such as “live” or “instant” unless you have validated what those words mean for that view. This keeps a faster retrieval method from creating a stronger freshness promise than the data supports.

    Put a stable adapter between CM360 and the interface

    Structured JSON is easier to consume than a downloaded file, but your UI should not become a direct reflection of a vendor response. Map the response into an internal model with names and types that make sense to your application.

    • Keep the API request definition in one reporting layer rather than duplicating it across dashboard components.
    • Validate that the returned structure contains what the component needs before rendering it.
    • Centralize metric labels and formatting so the same measure is not presented differently across views.
    • Record the query definition alongside operational logs so a bad result can be traced to its dimensions, metrics, and filters.
    • Version your internal contract when a dashboard changes its grain or meaning.

    This adapter also preserves your options. The UI can consume one internal shape even if some views use reportData.query and other data arrives through the Reports service.

    Separate no data, zero, slow, and failed

    These states can look similar in an empty chart, but they mean different things:

    • No matching data: the selected dimensions and filters produced no rows.
    • Measured zero: the query returned a legitimate result whose displayed metric is zero.
    • Still running: the application has not received the synchronous response yet.
    • Failed request: the application cannot present the requested result.
    • Last successful result: a previous result remains visible while its replacement is unavailable.

    Model and label these states explicitly. Otherwise, an API problem can be mistaken for campaign performance, or an empty filter result can be presented as a technical failure.

    Also control how often the interface sends requests. Trigger queries on deliberate actions, avoid submitting a new request for every unfinished input change, and reuse identical results for an appropriate period when your freshness requirements permit it. The right reuse period is a product decision; the existence of a synchronous endpoint does not require every screen interaction to generate a new API call.

    A low-risk rollout keeps the batch path intact

    Parallel reporting pipelines pass through a controlled traffic junction and comparison stage, with a return route to the established batch system.

    You do not need to redesign the entire reporting stack to benefit from reportData.query. Start with one view where report creation, polling, or file parsing is clearly getting in the way of an interactive experience.

    1. Inventory the current flow. Identify where the application creates the Report resource, starts the run, polls, downloads the file, parses it, and transforms it for display.
    2. Classify the use case. Confirm that a person or interactive application needs the result directly. Leave scheduled, large, and file-based jobs in the Reports service.
    3. Write the query contract. Specify the exact dimensions, metrics, filters, expected result grain, loading behavior, and failure behavior for the selected view.
    4. Build the response adapter. Convert the returned JSON into the internal shape already expected by the interface, or introduce a stable model that both reporting paths can use.
    5. Verify meaning, not just transport. Compare the new view with the existing reporting output for the same requested scope. Investigate differences before assuming that receiving JSON means the migration is complete.
    6. Exercise the slow and empty paths. Confirm that the interface remains understandable if a query runs for a substantial part of the allowed window, returns no matching data, or fails.
    7. Switch only the interactive read path. Keep existing scheduled reports and downloadable exports running until there is an independent reason to change them.

    Measure the rollout by what it removes from the interactive path: report-resource management, polling, file retrieval, and parsing. Do not judge it by how much legacy reporting code you can delete. If that code still supports a valid batch workload, retaining it is the correct design.

    Campaign Manager 360 reporting API FAQ

    Is reportData.query a streaming API?

    No. Its documented interaction is a synchronous query that returns structured JSON. Your application requests a defined result; it is not described as subscribing to a continuous stream of campaign events.

    Does “real-time reporting” mean every metric is instantly current?

    Not on the evidence available for this endpoint. The direct synchronous response removes the generated-report workflow, but that does not by itself define the freshness of every underlying metric. Validate freshness for your use case before making a user-facing promise.

    Should an existing Reports service integration be migrated completely?

    No. Keep the Reports service for large datasets, scheduled jobs, and workflows that require CSV or Excel downloads. Move only the interactive and ad-hoc requests that benefit from direct JSON.

    What is the best first use case?

    Choose one narrowly scoped dashboard view whose user currently waits for a report job or whose implementation exists mainly to download and parse a file. Define its dimensions, metrics, and filters; build the JSON adapter; then compare its output with the established reporting path before expanding the rollout.

    Your next step is small and concrete: identify one interactive report, write down the exact question it answers, and determine whether a synchronous query can answer it within the endpoint’s 60-second window. If it can, migrate that read path. If it is fundamentally a large export or scheduled artifact, leave it where it belongs.

    References


  • Toxic Backlink Sabotage: When an SEO Attack Becomes a Lawsuit

    Toxic Backlink Sabotage: When an SEO Attack Becomes a Lawsuit

    If your backlink audit suddenly shows spam pages pairing your company with drugs, loans, gambling, or weapons, do not begin with a public accusation or an indiscriminate cleanup. Preserve what happened first. A federal court has now left open the possibility that an allegedly deceptive backlink campaign can support false-advertising and related claims, but that is not the same as proving sabotage.

    Your immediate job is to separate an ugly link pattern from evidence of responsibility, intent, and harm. That distinction will determine whether you have an SEO incident to mitigate, a brand-protection matter to escalate, or a potential legal dispute that needs counsel.

    Key takeaways

    • A lawsuit surviving a motion to dismiss means the allegations were legally plausible enough to continue. It does not mean the alleged attack happened or that the defendant is liable.
    • A suspicious backlink profile does not identify who created the links. Attribution requires separate evidence.
    • Preserve raw link data, anchor text, page captures, dates, communications, and business-impact records before remediation changes the evidence.
    • Keep SEO correlation, attacker attribution, legal responsibility, and financial harm as separate questions.
    • Do not retaliate, publicly name a suspected competitor, or send a cease-and-desist letter without a coordinated legal and monitoring plan.

    What the toxic-backlink ruling changes, and what it does not

    Auto transport company Montway alleged that competitor Nexus AT LLC created more than 2,350 toxic backlinks between April and October 2025. The links allegedly used anchor text such as buy steroids online, payday loan services, illegal betting sites, cocaine powder online, and unlicensed firearms while directing people to Montway’s website.

    The alleged injury had two parts. Montway claimed the campaign was intended to reduce its Google rankings and to create false associations between its brand and illegal or disreputable products. It also alleged that a former Nexus manager connected the campaign to directions from Nexus CEO George Arkin and an SEO contractor. Those remain allegations; they have not been established at trial.

    In a June 2 ruling at the motion-to-dismiss stage, Judge Matthew Kennelly allowed the federal Lanham Act false-advertising claim, trademark claims, and related Illinois consumer-protection claims to proceed. The California unfair-competition claims were dismissed. At this stage, a judge asks whether the pleaded facts plausibly state a viable claim, not whether the plaintiff has proved those facts.

    The distinctive part of the ruling concerns the anchor text. The court found it plausible that the text was literally false because it appeared to promise one destination but sent users somewhere else. It also found that the alleged campaign could qualify as commercial advertising or promotion under the Lanham Act.

    That gives companies a legal theory worth discussing with counsel when the facts fit. It does not establish that every spam link is false advertising, that toxic links necessarily reduce rankings, or that a competitor is responsible whenever suspicious links appear. The ruling permits litigation to continue under the allegations presented; it is not a finding of liability or a universal shortcut around proof.

    Build the evidence around three separate questions

    Gloved hands organize digital evidence into three connected groups showing suspicious links, attribution clues, and damage to a website node.

    A useful investigation does not put every screenshot, ranking decline, and suspicion into one folder labeled attack. Build three evidence tracks. Each answers a different question, and a strong answer in one track cannot replace a weak answer in another.

    1. What links and representations actually appeared?

    Start with observable facts. For every relevant backlink, retain the full linking URL, the destination URL, the exact anchor text, the page title, the page content surrounding the link, and the date and time you captured it. Save both a visual capture and the underlying page data where your tools allow it. A screenshot shows what a person could see; a raw export or saved page helps preserve technical details that a screenshot can miss.

    Keep the original export unchanged. Work from a copy when you classify or annotate links. If your team hashes evidence files, record the hash alongside the capture date; the hash can help show that a file was not altered later, although it cannot prove that the original webpage was truthful.

    Do not let an automated toxic-link score become your conclusion. Record it as a tool-generated metric, then document the concrete features that caused concern: false destination language, repeated off-topic anchors, common page templates, clustered timing, shared infrastructure, or another observable pattern. This makes the record understandable to people who do not use your SEO platform.

    2. What evidence connects the activity to a responsible party?

    A distinctive anchor pattern may support an inference of coordination. It does not tell you who ordered the work. Attribution needs its own evidence, such as lawfully obtained communications, admissions, contractor relationships, campaign instructions, witness accounts, or records produced through a proper legal process.

    Montway’s pleading did not rely only on a link chart. It also included the alleged account of a former manager who attributed the direction to the competing company’s CEO and an SEO contractor. That kind of allegation is categorically different from noticing that suspicious links began near a competitive event.

    Maintain a clear confidence label for every attribution statement: confirmed fact, third-party statement, technical inference, or unresolved suspicion. Do not impersonate people, access accounts without authorization, or pressure a contractor into disclosing information improperly. Those tactics can create separate legal and security problems while contaminating an otherwise credible investigation.

    3. What measurable harm occurred, and what else could explain it?

    A ranking decline can coincide with a backlink campaign without being caused by it. Preserve query-level rankings, affected landing pages, organic sessions, conversions, qualified leads, and revenue records that your business already maintains. Use exact dates and consistent comparison methods. Do not convert a traffic estimate into a claimed financial loss without showing the steps between them.

    Record competing explanations on the same timeline: site migrations, content removals, template releases, crawling problems, outages, analytics changes, redirects, and other technical work. A credible analysis tries to disprove its preferred explanation. If the matter proceeds, counsel and qualified experts can decide what causal conclusions the evidence supports.

    Brand harm is another evidence stream. Capture any actual search result, customer communication, publisher page, or other interface that presents the false association. Do not infer that users saw or believed an association merely because the anchor exists on a remote page.

    If you are also worried about AI search visibility, document it separately. Record the AI product and model where displayed, the exact prompt, the full response, the date and time, and relevant account or location conditions. One problematic answer does not prove a recurring representation, and the presence of toxic backlinks does not by itself prove that they caused an AI system’s output. Structured data and on-page entity clarification may improve your owned content, but they cannot establish who placed a third-party backlink.

    Preserve first, then choose a proportionate response

    A forensic analyst archives a hostile link network in a transparent cube while isolating a small set of contaminated connections from healthy nodes.

    The safest operational sequence protects both SEO remediation and the legal record. It also reduces the chance that a hurried accusation turns an external incident into a second dispute. This is general risk-management information, not a substitute for legal advice about your facts or jurisdiction.

    1. Freeze the initial record. Export the backlink dataset, preserve representative pages, record collection times, and restrict changes to the originals. If a page disappears later, your record should still show what your team observed.
    2. Open a single incident timeline. Include the first observed link, link-volume changes, anchor clusters, ranking or traffic movements, technical site changes, communications, reports to search platforms, and remediation actions. Separate the event date from the date on which your team discovered it.
    3. Bring SEO, security, communications, and legal owners together. SEO can explain link patterns and search changes. Security can preserve technical records and access controls. Communications can prevent speculative public statements. Counsel can assess claims, jurisdiction, preservation obligations, and contact strategy.
    4. Continue necessary mitigation without erasing the before-state. Use the relevant search-engine reporting and link-management channels, but record exactly what was submitted or changed and when. Preserve the underlying evidence before a URL is blocked, removed, reported, or otherwise handled.
    5. Prepare a counsel-ready packet. Include a short chronology, raw evidence locations, representative examples, known totals and date ranges, attribution evidence, documented business effects, alternative explanations, prior communications, and unanswered questions. Label estimates and third-party metrics clearly.
    6. Plan any notice as an escalation event. Montway alleged that the backlink activity intensified after an October 2025 cease-and-desist letter. That allegation does not prove that cease-and-desist letters generally worsen attacks. It does show why monitoring, evidence capture, technical response, and counsel availability should be in place before a notice is sent.
    7. Do not retaliate. Buying bad links to a suspected competitor, threatening individuals, or publishing an unverified accusation can create new exposure and make your original account less credible. Preserve, report, investigate, and escalate through lawful channels.

    A cease-and-desist letter is not a routine SEO ticket. It can reveal what you know, harden the other side’s position, trigger evidence-preservation issues, or prompt further activity. Let qualified counsel decide whether to send one, what it should claim, and what your team must be ready to do afterward.

    Turn backlink sabotage into a defined incident class

    Most teams lose useful evidence because nobody owns the first response. Add suspected search sabotage to your incident playbook instead of leaving it inside a recurring SEO report. Define who can preserve data, who can contact platforms, who approves public statements, and who calls outside counsel.

    Your playbook should trigger enhanced review when several signals appear together: a coordinated cluster of off-topic anchors, text that falsely describes the destination, concentrated timing, credible attribution evidence, actual ranking or reputation effects, or a change in activity after contact. None of those signals proves liability on its own. Their purpose is to determine how quickly and formally the team should respond.

    Use a simple operational triage. A suspicious pattern with no attribution and no documented harm usually calls for preservation, technical analysis, reporting, and monitoring. A pattern with credible attribution calls for early legal review even if harm remains unclear. A pattern combining false representations, meaningful attribution evidence, and documented business or brand effects warrants an urgent joint review by counsel and the SEO incident owner. These are escalation categories, not legal tests.

    Companies have traditionally had limited options beyond reporting suspected manipulation to search engines. The surviving Lanham Act theory creates a possible additional route, but litigation remains fact-specific and the allegations in this case are still unproven. Your advantage comes from building a reliable record before you need to decide which route fits.

    If you have detected a coordinated pattern, make three moves now: preserve the raw evidence, write a dated one-page chronology, and put your SEO lead and legal counsel on the same review. Even if the incident never becomes a lawsuit, that record will give you cleaner remediation decisions and a defensible basis for protecting the brand.

    References


  • Performance Max Local Customer Optimization: Setup Guide

    Performance Max Local Customer Optimization: Setup Guide

    You want more people to walk into a location, request directions or contact the business while they are nearby. The difficult part is making sure Performance Max is optimizing for those local actions rather than treating the campaign like a general online acquisition campaign.

    Local customer optimization gives you a more focused option, but eligibility depends on how the campaign is built. Before you turn it on, check the campaign goals and product-feed setup. That decision will tell you whether to update the existing campaign or create a separate store-goals campaign.

    What Local customer optimization changes

    Local customer optimization is available for Performance Max campaigns with store goals. When enabled, it prioritizes delivery toward nearby people who appear ready to visit, navigate to or contact a business. That includes people planning trips, actively navigating or searching for nearby businesses across Google Maps, Waze and local formats on Google Search.

    The important word is prioritizes. This is an automated delivery preference for high-intent local customers, not a promise that every impression will produce a store visit. Your selected store goals still determine what the campaign is trying to accomplish.

    Use the setting when the campaign’s primary job is generating physical-location outcomes. Store visits, direction requests and store sales are the relevant goal types named for this setup. If your real priority is an online purchase or a product-feed sale, this isn’t a switch to add casually to the same campaign.

    Check eligibility before changing the campaign

    Wordless decision diagram showing campaign goals and a product feed leading to either a mixed campaign or a separate store-focused campaign.

    The main constraint is campaign architecture. Local customer optimization doesn’t support Merchant Center, and it can’t be used in a Performance Max campaign that includes Merchant Center products or online conversion goals.

    Your current setupCan you enable it directly?Best next move
    Store-goals campaign without Merchant Center products or online conversion goalsYesEnable the setting in the campaign and keep the store goals aligned with the actions you value.
    Performance Max campaign using Merchant Center productsNoCreate a separate store-goals campaign if you need to preserve product advertising.
    Performance Max campaign with online conversion goalsNoSeparate the local objective from the online objective before enabling local optimization.
    Campaign without an eligible offline store goalNot yetDecide which store outcome the campaign should optimize for and configure that goal first.

    You could remove a Merchant Center product feed to make the campaign eligible, but that is a consequential change. It removes the product-feed component from that campaign. Unless you intentionally want to stop using it there, the cleaner choice is a separate Performance Max campaign dedicated to store goals.

    The same reasoning applies to online conversion goals. Combining online and offline outcomes may look convenient, but this feature requires a store-focused campaign. Splitting the objectives also makes the business question clearer: is the local campaign producing enough valuable store activity to justify its budget?

    How to enable the setting

    The setup path depends on whether you are creating a campaign or modifying one that already exists.

    For a new campaign:

    1. Create a Performance Max campaign for store goals.
    2. Select the relevant offline conversion goal, such as store visits, directions or store sales.
    3. Find the Local customer optimization toggle during campaign setup.
    4. Enable the toggle and complete the remaining campaign settings.
    5. Confirm before launch that the campaign doesn’t contain Merchant Center products or online conversion goals.

    For an existing eligible campaign:

    1. Open the Performance Max campaign settings.
    2. Go to Budget and bidding optimization.
    3. Find Local customer optimization.
    4. Enable the setting and save the campaign.

    Once saved, Performance Max can begin prioritizing nearby users with stronger local intent. The setting is reversible: you can turn it off later to return the campaign to standard Performance Max behavior.

    If the toggle doesn’t appear, don’t assume the account lacks access. First check the structural blockers: the wrong campaign goal, an online conversion goal or Merchant Center products. The setting belongs to eligible store-goals campaigns, so campaign composition is the first place to troubleshoot.

    Keep local and ecommerce objectives from competing

    A store-goals campaign and an ecommerce campaign answer different questions. One tries to generate actions connected to a physical location. The other tries to produce online outcomes, often with products supplied through Merchant Center. Local customer optimization forces you to make that distinction explicit.

    Before creating a separate campaign, write down the job of each campaign in one sentence. If the sentence contains both “drive store visits” and “sell products online,” the objective is still mixed. Assign each campaign a primary outcome that matches its eligible configuration.

    • Store campaign: Use store goals and Local customer optimization to pursue nearby, high-intent customers.
    • Online campaign: Retain Merchant Center products or online conversion goals where ecommerce outcomes are the priority.
    • Budget decision: Give each campaign an intentional allocation rather than allowing a newly separated local campaign to inherit spend without review.
    • Reporting decision: Evaluate the local campaign against store actions, not against an online campaign’s purchase objective.

    This separation doesn’t guarantee better performance. It does prevent a basic measurement error: declaring the store campaign weak because it didn’t behave like an ecommerce campaign, or calling it successful because it generated activity unrelated to the physical-location objective.

    Judge the feature against the store action you selected

    Illustration of store entry, map directions and phone-call actions sending separate signals to an optimization control beside a storefront.

    Turning on the toggle is an implementation step, not the success criterion. The outcome that matters is whether the campaign produces more of the store action your business values at an acceptable cost.

    Record the campaign state before enabling the feature: selected store goals, budget, Merchant Center status and any online goals. Then note the date of the change. Without that record, later analysis can confuse a goal change, feed removal or budget adjustment with the effect of local optimization.

    1. Choose the decision metric first. Use the selected store outcome, such as directions, store visits or store sales, rather than a convenient top-line activity metric.
    2. Avoid bundling unrelated changes. If possible, don’t restructure goals, alter the budget and enable Local customer optimization at the same moment. Multiple changes make the result harder to interpret.
    3. Review the mix of store actions. More direction requests may be useful, but they aren’t automatically equivalent to more store sales. Interpret each action according to its business value.
    4. Compare like with like. Keep the campaign’s purpose, geography and operating conditions in mind when reviewing performance. A directional before-and-after comparison can inform a decision, but it doesn’t prove that the setting caused every change.
    5. Use the off switch deliberately. If the campaign no longer needs local-intent prioritization, disable the feature and return to standard Performance Max behavior rather than leaving an obsolete setting active.

    Your review should end in a concrete decision: keep the feature enabled, revise the store-goal campaign, adjust how budget is divided between local and online objectives, or turn the feature off. “Monitor performance” isn’t a decision unless you have already named the outcome that will change your course.

    Key takeaways

    • Local customer optimization is for Performance Max campaigns built around store goals.
    • It prioritizes nearby people showing local intent across Google Maps, Waze and local Google Search formats.
    • Merchant Center products and online conversion goals make a campaign ineligible.
    • A separate store-goals campaign is usually the safer structure when you need to preserve ecommerce advertising.
    • New campaigns expose the toggle after you choose eligible offline goals; existing campaigns place it under Budget and bidding optimization.
    • The setting can be turned off to restore standard Performance Max behavior.

    Start with the eligibility check, not the toggle. If your current campaign mixes store and online objectives, separate those jobs first. You will get a cleaner setup, a clearer budget decision and a result you can judge against the local action that actually matters.

    References