If your Google Search Console chart shows Generative AI impressions dropping sharply from August 13, 2026, don’t treat the line as evidence that your content disappeared from Google’s AI search experiences.
The problem affects impression logging in Google Search Console’s Generative AI in Search performance report. Data beginning August 13, 2026 may therefore show an artificial decline in impressions.
That distinction matters. An impression decline normally invites questions about rankings, citations, eligibility, content quality, technical changes, or demand. This particular decline can originate inside the measurement system instead. Google described the logging problem as ongoing and said it was working on a resolution.
Google also planned to add an annotation in Search Console. An annotation can explain the discontinuity, but it does not make the affected values suitable for trend analysis. Until Google confirms the outcome of the repair, regard impressions from the affected period as incomplete rather than as a new performance baseline.
Check whether your decline matches the confirmed anomaly
A known reporting bug is not a reason to dismiss every decline automatically. Match the shape and timing of your data to the confirmed problem before changing how you report it.
Open the Generative AI in Search performance report in Google Search Console.
Choose a date range that includes several days before and after August 13, 2026. This makes the break easier to distinguish from an existing decline.
Inspect impressions specifically. The confirmed problem is a decrease caused by impression logging, so don’t assume the notice explains an unrelated metric.
Identify the first affected date. A conspicuous impression break beginning on August 13 fits the documented anomaly; a decline that began earlier needs a separate explanation.
Record the affected property, report, metric, and start date in your own reporting notes. That prevents the anomaly from being mistaken for a genuine loss during a later review.
If the timing or metric does not match, continue the normal investigation. Check the relevant Search Console views, analytics data, site releases, indexing signals, and demand patterns on their own terms. The confirmed bug has a defined scope; it is not a universal explanation for poor performance.
Do not make SEO or AI visibility changes from this chart alone
The immediate risk is not the faulty line itself. It is reacting to that line as though it measured a real loss.
Do not roll back content solely because affected impressions fell. The report cannot establish that the content change caused the decline.
Do not rewrite pages or alter structured data solely to recover the missing impressions. A logging failure is not evidence of a relevance, schema, or eligibility problem.
Do not declare an AI visibility loss to clients or executives. Label the period as affected by a confirmed reporting anomaly.
Do not compare the affected period with an earlier clean period as if both were measured consistently. The resulting percentage would mix valid and incomplete impression logging.
Do not set a new baseline from the depressed values. Forecasts, targets, and alerts built on an artificial trough will remain distorted even after reporting stabilizes.
You can still investigate independent evidence if you have a broader reason for concern. The crucial point is causal discipline: the affected Search Console impression series cannot, by itself, justify a diagnosis or an optimization change.
How to communicate the dip without overstating it
Use a short annotation that separates the observed chart movement from its meaning. For example: “Generative AI in Search impressions are incomplete from August 13, 2026 because of a confirmed Google Search Console logging error. Google says this is not representative of a Search visibility change.”
That wording does three jobs. It identifies the affected metric, establishes the start date, and prevents an instrumentation problem from being reported as an SEO outcome. It also avoids claiming that traffic, conversions, or every other Search Console metric is unaffected; the confirmation specifically concerns the impression decrease in this report.
Apply the same annotation anywhere the series is reused, including exported reports, dashboards, scheduled summaries, and client commentary. If you omit it downstream, a stakeholder may encounter the unexplained decline without the context visible in Search Console.
Key takeaways
A logging error can reduce reported impressions in the Generative AI in Search performance report from August 13, 2026 onward.
Google says the anomaly affects data logging and does not represent a real visibility change in Search.
Treat the affected impression values as unreliable; don’t use them to calculate a clean before-and-after performance change.
Investigate separately if the decline began before August 13 or concerns a different metric.
Annotate every report that reuses the affected series, and wait for confirmation before rebuilding comparisons or baselines.
Recheck the data after Google resolves the problem
A resolution and a historical correction are not necessarily the same event. The available confirmation says Google is working on the logging issue, but it does not establish whether every affected impression will be restored later.
When Google marks the issue resolved, first check whether the values for August 13 onward were backfilled or whether only new data begins logging normally. Keep the anomaly annotation if the historical gap remains. If Google corrects the affected dates, rerun any comparison, forecast, or alert that previously included the faulty values.
For now, preserve your current optimization plan unless independent evidence supports changing it. Mark the measurement break, exclude unreliable impressions from performance judgments, and revisit the affected range once Google clarifies what was repaired.
You can rank well in conventional search and still be absent when Microsoft Copilot assembles an answer. The missing piece is usually not another round of keyword insertion. It is whether the right page can be found, understood as a complete answer, supported by credible evidence, and selected as a useful citation.
That gap deserves attention because Microsoft Copilot has been reported to send more AI referral traffic than any LLM except ChatGPT. The practical goal is not to manipulate a model. It is to make your best information easier for a search-grounded assistant to retrieve, interpret, verify, and cite.
Key takeaways
Confirm that the intended page is publicly accessible, indexable, internally linked, and presented as the canonical version before changing its copy.
Optimize for the complete question behind a Copilot prompt, including the reader’s constraints, decision, and required evidence.
Write self-contained answer passages that remain clear when extracted from the surrounding page.
Use JSON-LD to describe visible entities and relationships accurately. Treat it as disambiguation, not a citation switch.
Build third-party corroboration around the claims and entities you want Copilot to associate with your brand.
Measure citation presence, citation accuracy, identifiable referral traffic, and business outcomes separately.
First earn retrieval, then compete for the citation
Microsoft Copilot optimization is easier to manage when you separate four jobs: retrieval, interpretation, confidence, and citation. This is an audit framework, not a claim about a secret ranking formula.
Retrieval: Can the search layer discover and access the intended URL?
Interpretation: Can it identify the page’s subject, entities, answer, and scope?
Confidence: Are important claims supported, qualified, current, and consistent with other credible information?
Citation: Does the page contain a passage worth presenting to a user as evidence?
This sequence matters. A polished answer cannot be cited if the page is blocked, orphaned, duplicated under competing URLs, or dependent on an interaction before its main content appears. Likewise, technical eligibility does not make a vague or unsupported page citation-worthy.
Remove technical ambiguity
Begin with the URL you actually want Copilot to cite. Audit that URL rather than assuming the most attractive page is also the version a search system sees.
Make the page available without a login, form submission, location gate, or other mandatory interaction.
Check robots directives and page-level indexing instructions for accidental exclusions.
Return a successful response and avoid redirect chains that leave several versions of the same content in circulation.
Use a self-referencing canonical when the page is the preferred version. Point genuine duplicates to that same canonical.
Place the substantive answer in rendered page content. Do not leave it exclusively inside an image, downloadable file, or script-dependent interface.
Link to the page from relevant navigation, category, hub, and supporting pages using descriptive anchor text.
Include the preferred URL in your sitemap and remove obsolete URLs after their redirects and canonicals are settled.
Check whether Microsoft’s search ecosystem recognizes the intended URL and inspect any reported crawl or indexing problems.
Watch for content cannibalization. If a glossary entry, old blog post, product page, and support page all answer the same question differently, a retrieval system has to choose among conflicting candidates. Give each page a distinct job. Consolidate material when the distinction is artificial, and use internal links to make the authoritative answer obvious.
Map prompts to decisions, not just keywords
A conventional keyword often describes a topic. A Copilot prompt is more likely to describe a task with conditions attached. Someone may want a definition, a comparison, a troubleshooting path, an implementation plan, or a recommendation that fits a particular constraint. A page that merely repeats the topic can miss the actual decision.
Build a prompt map for every commercially important subject. Record the question in the reader’s language, the decision behind it, the constraints that can change the answer, the evidence a responsible answer needs, and the page that should own the response. Then group prompts that can be satisfied by the same underlying page.
Definition prompts need a precise meaning, boundaries, and a concrete example.
Comparison prompts need consistent criteria, material differences, and guidance on which option fits which situation.
How-to prompts need prerequisites, ordered actions, decision points, and a way to verify completion.
Troubleshooting prompts need observable symptoms, likely causes, safe checks, and corrective actions.
Evaluation prompts need requirements, limitations, evidence, and a clear explanation of tradeoffs.
Choose one dominant job for each page. A page can answer supporting questions, but it should not drift between an educational explanation, a product pitch, and an unrelated industry commentary. That mixture weakens the passage Copilot needs to extract and the next step a human visitor needs to take.
Write passages that still work when lifted from the page
AI citations are selected at the passage level even when authority and relevance are evaluated more broadly. Your page therefore needs useful blocks of text, not just an optimized title and a long narrative that reveals its answer near the end.
Put the direct answer immediately after the heading that introduces the question. Follow it with the mechanism, qualification, evidence, and action. This does not mean every paragraph should sound like a dictionary entry. It means the reader should not have to assemble the central answer from several distant sections.
Apply the standalone passage test
Copy a candidate paragraph into a blank document and ask whether it still makes sense. A citation-ready passage should identify its subject, answer a recognizable question, preserve any important limitation, and avoid pronouns whose meaning depends on an earlier paragraph.
Weak copy says that a solution is faster, better, or more accurate. Strong copy identifies what is being compared, which measure is relevant, where the claim applies, and what evidence supports it. If you cannot substantiate a superlative, remove it. Repetition does not turn a marketing claim into evidence.
Use headings that name the question, outcome, or distinction addressed below them.
Define an unfamiliar term when it first appears, then use the same term consistently.
Keep the actor, action, object, and qualification together when splitting them would change the meaning.
Use ordered lists for procedures and unordered lists for criteria. Use tables only when readers genuinely need to compare the same attributes across alternatives.
Label examples as examples. Do not let a hypothetical scenario look like a documented result.
Separate established facts from interpretation, recommendations, and predictions.
Link claims to the most direct evidence available rather than to a page that merely repeats the claim.
Show an update date when substantive information changes, but do not refresh a date without refreshing the content.
Original information is especially useful when it is documented well enough to inspect. If you publish a benchmark, dataset, framework, or technical finding, explain the method, definitions, sample boundaries, and limitations on the same page or on a clearly linked methodology page. A result without a method may be quotable, but it is difficult to evaluate responsibly.
Make the cited visit worth earning
A complete answer and a useful landing page are not opposites. Give Copilot a concise factual passage, then give the visitor something the generated answer cannot conveniently contain: a decision framework, template, calculator, full comparison, implementation detail, primary evidence, or clearly defined next action.
Match that next action to the prompt. A reader seeking a definition may need a deeper explainer. A reader comparing approaches may need specifications or selection criteria. A reader troubleshooting a problem may need a diagnostic sequence. Sending every visitor to the same generic sales request wastes the context that brought them to you.
Make entity evidence consistent on and beyond your site
Clear prose tells Copilot what a page means. Structured data makes important entities and relationships explicit. Independent coverage can then provide corroboration outside your own domain. These layers should agree with one another.
Use JSON-LD to clarify, not embellish
Select the schema type that matches what the visitor can actually see: an organization, person, article, product, event, local business, or another relevant entity. Then connect the page to its author, publisher, subject, and canonical identity where those relationships are accurate.
Give important entities stable identifiers so repeated markup refers to the same organization, person, product, or service.
Keep names, URLs, authorship, publication details, and business information consistent between JSON-LD and visible content.
Use identity links only for profiles or records that genuinely represent the same entity.
Mark up questions and answers only when those questions and complete answers are visible to the reader.
Validate the generated markup after templates, plugins, or deployment systems have processed it.
Retest important templates after design or content-model changes, because technically valid markup can still describe the wrong entity.
Do not use schema to introduce awards, ratings, authors, prices, availability, or other claims that the page does not support. Structured data is not a hidden copy field. Inconsistent markup creates another version of the truth for a machine to reconcile.
Schema also cannot rescue a thin page. It can state that a page concerns a particular service, but it cannot supply the missing explanation, proof, or comparison. The visible content remains the answer a person must be able to use.
Turn digital PR into corroboration
Digital PR for Copilot visibility is not simply a link-count exercise. The useful outcome is a credible, accessible reference that connects your entity with a relevant claim, definition, specialty, or piece of evidence. The practical inference is straightforward: when important facts are expressed consistently across reputable locations, an answer system has less ambiguity to resolve.
Choose the association. Write down the exact subject, claim, or expertise you want people and machines to connect with your organization.
Create the canonical evidence. Publish the clearest version on your site, including definitions, methodology, limitations, authorship, and an update history where relevant.
Pitch the evidence, not an adjective. A useful dataset, expert explanation, technical resource, or documented change gives publishers something concrete to evaluate.
Preserve entity consistency. Use the same organization, product, expert, and methodology names in your own page, structured data, biographies, profiles, and outreach materials.
Review the resulting coverage. Confirm that names, links, figures, and qualifications are correct. Request a correction when an error could propagate.
A self-published announcement can establish what your organization claims, but it is not independent confirmation. Do not manufacture survey findings, inflate a sample, or pitch a conclusion the underlying material cannot support. Weak evidence distributed widely remains weak evidence.
Look for gaps between your site and the public record. An expert page without a biography, a product renamed only on part of the site, or a company description that changes across profiles can fragment the entity. Fix the canonical page first, update the structured data, and then correct the most relevant external records.
Measure visibility, accuracy, and value as separate outcomes
Referral sessions alone cannot tell you whether Copilot understands your brand. A generated answer can mention or cite you without producing a click, and an identifiable visit can still land on the wrong page. Use prompt monitoring and analytics together.
Start with a fixed prompt set drawn from your prompt map. Preserve the wording and relevant context so later checks are comparable. Then record the prompt, date, answer summary, whether your brand appeared, whether a URL was cited, which URL appeared, whether the description was accurate, which alternatives were cited, and what action the result implies.
Do not collapse those observations into a single visibility score too early. A mention, a citation, an accurate recommendation, and a qualified visit are different events. Keeping them separate tells you what to fix.
The preferred page is not retrievable: investigate access, indexing instructions, rendering, canonicals, redirects, sitemaps, and internal links.
The page is retrievable but does not answer the prompt: repair the intent match and add the missing decision criteria or qualification.
Your brand is mentioned without a citation: strengthen the page’s direct answer, evidence, authorship, and external corroboration.
The wrong URL is cited: clarify page ownership, consolidate overlap, improve internal anchors, and align canonical signals.
The citation misstates your position: publish the correction prominently, remove ambiguous wording, align structured data, and correct relevant public records.
The citation is accurate but produces little useful activity: improve the landing experience and offer a next step that extends the answer instead of repeating it.
In analytics, segment identifiable Copilot and Microsoft search referrals, then compare their landing pages, engagement, conversions, and assisted journeys with your other channels. Keep attribution limits visible in your reporting. Unattributed visits and no-click influence should not be relabeled as proven Copilot traffic.
Run the first audit on one question that matters to your business. Assign it one canonical page, repair retrieval problems, rewrite the strongest answer passage, align its JSON-LD, and build credible corroboration around the underlying claim. Recheck the same prompt after each material change. That gives you a repeatable optimization loop instead of a collection of AI-search tactics with no diagnosis behind them.
Google Ads can hit a platform target while missing the outcome your business actually needs. That usually happens when automation receives a clean numerical instruction built on a weak business definition: the wrong conversion, an incomplete value, a target detached from margin, or a view-through action treated like a click.
If you are deciding whether to loosen a target, raise a budget, accept a Demand Gen default, or retest an automated feature, use the framework below. It turns those settings into business decisions you can explain, measure, and reverse.
Start with conversion economics, not the bid strategy
Smart Bidding is not a substitute for strategy. It can choose auctions and bids in pursuit of the conversion goals you supply, but it cannot repair business economics that were never encoded in those goals.
Before touching a campaign setting, write a one-sentence optimization mandate:
For this campaign, maximize [the desired conversion or conversion value] within [the available budget], while protecting [the business efficiency requirement], using [the eligible conversion goals] and evaluating results after [the full conversion cycle].
Fill the brackets with account facts, not aspirations. If you cannot complete the sentence without arguing about what a conversion is worth, the account is not ready for another bidding change.
Decision
Question to answer
What to fix before automation
Business outcome
Are you buying revenue, qualified leads, purchases, subscriptions, or another result?
Name the outcome the business will recognize as success.
Primary conversion
Which recorded action is close enough to that outcome to guide bids?
Keep low-intent or diagnostic events from competing with the outcome you really want.
Conversion value
Do recorded values reflect meaningful differences between outcomes?
Correct missing, duplicated, or misleading values before relying on value optimization.
Efficiency requirement
Is the business protecting an acquisition cost, a return target, or total spend?
Choose the constraint that matters outside the Google Ads interface.
Operating context
Are promotions, inventory availability, or margins changing?
Record the change so bidding results are not interpreted without business context.
Conversion cycle
How long does it take for enough conversions and value to be reported?
Do not judge an incomplete period as though all outcomes have arrived.
The conversion cycle matters most when recent performance appears to deteriorate immediately after a change. If conversions arrive with delay, the newest period is structurally incomplete. Review performance only after accounting for the full conversion cycle, especially before changing a target in response to early data.
Context outside the ad account matters too. A campaign can report more conversion value while selling low-margin products, pushing unavailable inventory, or benefiting from a promotion that will soon end. Promotions, stock availability, and product margins therefore belong in the bidding decision, not in a separate conversation after results arrive. Treating these business conditions as bidding inputs keeps a platform improvement from becoming a commercial disappointment.
Use budgets and targets as separate controls
A budget expresses how much the campaign may use. A target expresses the efficiency you want the bidding system to pursue. They are related, but they do not answer the same question.
This distinction becomes critical when a campaign is both limited by budget and beating its target. A Smart Bidding change described for this exact combination can alter the auctions entered, bids, and CPCs. Campaigns that are not budget constrained already operate in this way, while campaigns that do not meet both conditions should not be diagnosed as though they do. Start by identifying which campaigns are actually affected.
Campaign state
What it tells you
Practical response
Not limited by budget
The budget-constrained condition is absent.
Investigate conversion mix, market conditions, targets, assets, and measurement before blaming this mechanism.
Limited by budget but not beating the target
The campaign does not meet the complete affected combination.
Do not loosen the target merely to explain a change that does not apply to this state.
Limited by budget and beating the target
The auction mix, bids, and CPCs may change while the target remains in place.
Review average performance after the full conversion cycle, then decide whether the priority is preserving efficiency or pursuing more volume within the budget.
Do not treat the target as a historical description or a promise. It is an efficiency lever. If current results are substantially better than the target and the campaign is budget limited, leaving the target unchanged can give the system room to pursue different opportunities. Whether that is acceptable depends on the business outcome, not on whether CPC rises or falls.
Choose the strategy from the constraint:
When the budget is fixed and additional conversion volume is the priority: Maximize Conversions without a target remains an available approach.
When the budget is fixed and total conversion value is the priority: Maximize Conversion Value without a target remains available.
When an efficiency requirement is commercially binding: use a meaningful target and accept that it may restrict the opportunities the system can pursue.
When stakeholders demand fixed spend, fixed volume, and fixed efficiency simultaneously: surface the conflict. No bidding strategy can guarantee all of them under every auction condition.
The two untargeted maximize strategies are specifically available to advertisers that must work within a defined campaign budget. That does not make them universally better. It means they are coherent choices when budget is the firm control and the conversion objective is trustworthy.
Judge the change using the metric named in your optimization mandate. If the objective is higher conversion value, CPC alone cannot tell you whether the test succeeded. A higher CPC may be acceptable if the resulting value and business efficiency improve; a lower CPC is not a win if it buys weaker outcomes. Match the evaluation metric to the result the business asked the campaign to produce.
Audit Demand Gen view-through optimization separately
A view-through conversion credits an outcome after someone sees an ad without necessarily clicking it. That can capture influence that click-only reporting misses, but it is not the same interaction as a click-led conversion. Your bidding and reporting choices should preserve that distinction.
Google’s announced Demand Gen rollout changes both the optimization signal and the billing model. Because the changes were scheduled to roll out over a period of months, verify the settings and behavior visible in each account rather than assuming every campaign is already in the same state.
View-through bidding becomes video-only. In existing campaigns, image-asset view-through conversions can remain visible as secondary conversions, but they are no longer eligible for bidding or included in the primary Conversions column.
New Demand Gen campaigns get view-through optimization by default. An advertiser that does not want it must opt out during setup. Existing campaigns retain their current setting rather than being automatically enrolled.
Eligible inventory expands. View-through optimization extends beyond YouTube and the Discover Feed to the Google Display Network.
Display video billing moves to CPM. Video assets served on Display are billed by impressions rather than clicks, whether or not view-through optimization is enabled.
Those optimization, default, inventory, and billing changes create two separate decisions. The first is whether view-through conversions should guide bidding. The second is whether the campaign should serve video on Display inventory billed by impressions. Opting out of view-through optimization does not restore CPC billing for those Display video assets.
Run this audit before launching or materially changing Demand Gen:
Record the view-through setting. Check the campaign configuration itself, especially for a new campaign where the announced default is enabled.
Separate optimization eligibility from reporting. An image view-through conversion appearing as a secondary conversion in an existing campaign does not mean it is still directing bids.
Review the asset mix. An image-heavy campaign may show historical view-through activity that no longer participates in optimization, while video receives the eligible signal.
Inspect inventory and billing together. Once Display video is billed on CPM, impression delivery and cost become necessary context; CPC is no longer the billing basis for that inventory.
Compare downstream quality. Assess whether view-through-attributed outcomes produce the business result named in your mandate instead of assuming every credited conversion has equal value.
Document the decision. Record why view-through optimization is included or excluded so a future default, rebuild, or handoff does not silently reverse the strategy.
The common reporting mistake is to interpret a change in the primary Conversions column as a change in customer behavior. For existing image-heavy campaigns, part of the movement may instead come from image view-through conversions being moved to secondary reporting and removed from bidding eligibility. Check the conversion-action breakdown before explaining the result as a market shift.
Make controlled testing the guardrail around automation
An automated feature that failed previously has not earned a permanent rejection. Google’s models and infrastructure can change behind the scenes, so the same campaign approach may behave differently after later system improvements. That is a reason to retest selectively, not a reason to switch everything back on.
A defensible retest needs a business hypothesis, a suitable success metric, a defined scope, and enough time for the conversion cycle to complete. Where possible, reserve a dedicated testing budget so experimentation is intentional rather than an unplanned draw on core activity.
Write a test brief before making the change:
Business question: What uncertainty will the test resolve?
Hypothesis: Which setting or feature should change which business outcome, and why?
Scope: Which campaigns, assets, goals, audiences, or inventory are included?
Baseline: What pre-change state will you use for comparison?
Primary metric: Which measure determines success?
Guardrails: Which cost, quality, budget, or volume outcomes would make the result unacceptable?
Conversion cycle: When will the data be mature enough to interpret?
Decision rule: What evidence leads to adoption, another test, or rollback?
Change record: Who owns the test, what changed, and how can the prior configuration be restored?
Isolate the control under test where practical. If you change the bid strategy, conversion goals, budget, target, creative mix, and inventory at the same time, even a strong result will not tell you what to keep. When several changes are unavoidable, record them explicitly and narrow the claim you make from the outcome.
AI-generated account advice needs the same scrutiny. Tools such as Ask Advisor can help surface ideas, but newer AI systems should not be treated as perfectly accurate instructions. Use them to form questions and candidate actions, then verify the affected campaigns, current implementation, and business logic before making a change. That continued need for expert review of AI recommendations is a feature of responsible automation, not resistance to it.
Read the Help Center material linked from the relevant setting as part of that verification. Documentation can lag a rollout, but it may still contain implementation details that are easy to miss in the interface. Compare the documentation with what the account actually exposes before applying broad advice.
Automation also increases the reach of setup errors. Before launch, use an independent review for budgets, targets, conversion goals, network eligibility, asset mix, and default opt-ins. If an error causes spend or data damage, contain it, establish what was affected, communicate plainly, and improve the process that allowed it. Leadership should own the team’s output rather than blaming a junior operator in front of a client; the useful question is which control failed and how it will be strengthened.
Key takeaways
Give automation a business outcome, a trustworthy conversion signal, and an explicit constraint before changing bids.
Do not confuse budget and target: budget controls available spend, while the target steers efficiency.
Check whether a campaign is both budget limited and beating its target before attributing performance changes to the relevant Smart Bidding behavior.
For a fixed budget, untargeted Maximize Conversions or Maximize Conversion Value may fit when volume or value is the priority.
In Demand Gen, audit view-through eligibility, default settings, asset type, inventory, and CPM billing as separate but connected controls.
Retest automated features only with a written hypothesis, mature conversion data, business-level success metrics, guardrails, and a rollback path.
Treat AI recommendations as proposals requiring account and business review, not as authorization to make changes.
Before your next optimization cycle, complete the one-sentence mandate for the campaign you plan to change. Then verify its budget status, target performance, conversion maturity, and Demand Gen defaults. Make the smallest change that answers a defined business question, and leave a record clear enough for the next operator to understand why it was made.
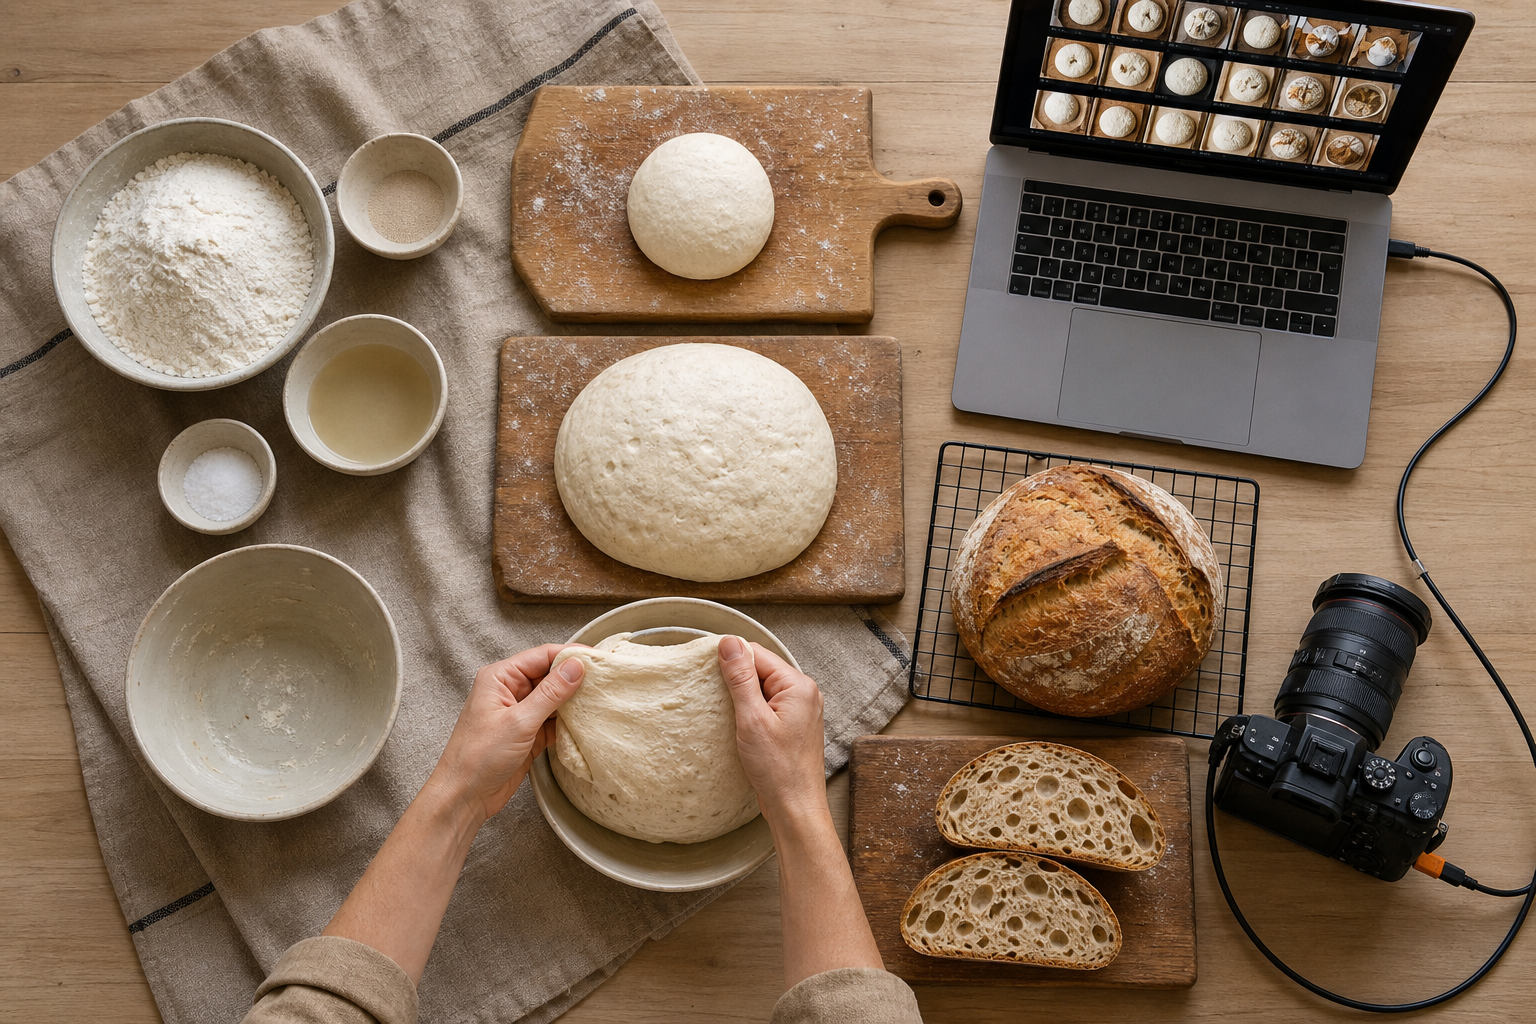
If you publish recipes, tutorials, or any page that depends on original visuals, the immediate question is practical: can Google generate an image that answers the query before your work earns a visit?
Do not cancel an image shoot or replace your library with synthetic assets based on one search experiment. Google stopped the recipe-image test that triggered this concern. The useful response is to make your visuals stronger as evidence, connect them cleanly to your content, and measure whether a generated answer actually changes user behavior.
What Google tested, and what it did not establish
Google tested AI-generated illustrations inside AI Overviews for recipe results. The generated visual compressed the cooking process from preparation to the finished dish. Google subsequently said the small experiment was no longer running.
The company also distinguished that experiment from Nano Banana, an image-generation feature announced in July that activates when a user explicitly asks to create an image. That distinction matters. An automatically generated visual inserted into a search answer is a different product behavior from an image a user deliberately requests.
The narrow reading is the reliable one:
Google is willing to test generated visuals within the search-results experience.
The recipe experiment described here has ended.
The test does not establish a general rollout for generated images in AI Overviews.
It does not establish how Google ranks AI-generated images published on your own site.
It provides no measured traffic-loss figure that you can apply to your pages.
That last point should guide your budget decisions. A generated answer could reduce the need to click, but a stopped experiment cannot tell you how large that effect would be. Treat displacement as a hypothesis to measure, not a loss percentage to assume.
Separate the three image questions people keep mixing together
“AI-generated images in Google Search” can describe three different situations. Confusing them leads to bad SEO decisions.
Question
What the recipe test tells you
Your decision
Will Google generate a visual inside the result?
Google tested this in recipe AI Overviews and then stopped the experiment.
Monitor the search surface for your important queries instead of assuming a permanent rollout.
Will Google show or cite an image from my page?
The stopped test does not answer that broader visibility question.
Keep original images accessible, useful, and clearly associated with the visible page content.
Can I publish an AI-generated image on my site?
The event establishes no general ranking treatment for publisher-created AI images.
Judge the asset by accuracy, transparency, reader value, and your content standards rather than an assumed SEO advantage.
The most immediate concern is the first situation: Google owns the generated visual, while publisher citations may appear nearby. A recipe publisher affected by the experiment warned that users could mistake nearby citations for credit for the illustrations. That concern is plausible, but it should not be inflated into a claim that every AI Overview misattributes images.
When you inspect a result, ask two separate questions: “Where did the factual instructions come from?” and “Who created this visual?” If the interface makes only the first answer clear, a citation does not necessarily give you visual attribution.
Make original images carry evidence a summary cannot preserve
Your strongest response is not to publish more decorative images. It is to make each original visual communicate something a simplified reconstruction could omit, blur, or invent.
Give every image a defined job. Show a decision, condition, comparison, or outcome that the surrounding prose cannot communicate as quickly.
Capture consequential stages. For a recipe, that might be texture, color, consistency, assembly, or the difference between an intermediate stage and the finished result. For a repair tutorial, it might be component orientation or correct tool placement.
Keep the visual and written sequences aligned. If the text changes order during editing, update the image order and captions at the same time. A polished image attached to the wrong step is worse than no image.
Write captions that interpret the evidence. Name the stage and tell the reader what to notice. “Mixture after folding, with visible streaks remaining” is more useful than “Step three.”
Use accurate alt text. Describe the relevant content and purpose of the image. Do not turn alt text into a list of target keywords.
Keep credits in visible page context. If the photographer, illustrator, tester, or organization matters, identify that contributor where readers can see it rather than relying only on the file name.
Align structured data with the page. If you use Recipe or ImageObject markup, reference an image that represents the visible content. JSON-LD is a consistency layer; it is not proof of authorship or a guarantee that an image will appear in search.
This changes the role of image production. A generic hero image decorates a page. A well-captioned process image documents a claim. When Google or another answer engine compresses the page, the second asset gives the system and the reader a clearer reason to preserve the connection to your work.
If the image itself was generated
An AI-generated image can be an illustration without being evidence that you performed a process, tested a product, or produced the depicted result. Keep that boundary explicit.
Check every depicted step against the instructions a reader will follow.
Look for invented ingredients, tools, components, labels, textures, and transitions.
Do not present a generated process scene as documentary photography.
Label the image’s role when the difference between illustration and documentation could affect trust.
Have a human editor verify the final asset in the context of the page, not only as a standalone image.
Replace the asset when an error could lead the reader to perform the process incorrectly; a disclaimer does not repair a misleading instruction.
For image-led instructional content, consistency matters more than visual polish. If the prose says one thing and the image shows another, the page has an accuracy problem regardless of whether a camera, design tool, or generative model produced the asset.
Measure exposure before changing your production budget
A sitewide traffic change cannot tell you whether a generated image displaced a click. You need query-level evidence that the search feature appeared and page-level evidence that behavior changed.
Define the exposed content group. Start with pages whose value can be compressed into a visual sequence: recipes, assembly instructions, repairs, demonstrations, comparisons, and other image-led tutorials.
Record the actual result. For each important query, save the query wording, generated visual, visible citations, search language, location context, device context, and date observed. Search interfaces change, so the screenshot is part of your evidence.
Annotate the first observation. Add it to the same change log you use for site releases, content updates, and search-feature changes. Without that marker, later traffic comparisons become guesswork.
Compare the affected pages and queries. Use Google Search Console to review impressions, clicks, and click-through rate. Use analytics to examine entrances and the business actions that follow those visits. If your reporting does not identify the generated feature directly, pair performance data with the search-result captures.
Use a relevant comparison group. Compare image-led pages where you observed the feature with similar pages where you did not. Do not use unrelated sitewide traffic as the only baseline.
Inspect attribution and accuracy separately. A citation can be present while the generated visual remains confusing. Record whether the source of the instructions and the creator of the visual are each clear.
Change strategy only when the pattern repeats. A generated visual appearing alongside a decline isolated to the same queries is more informative than a single screenshot or a broad organic fluctuation.
If impressions remain stable but clicks decline only where the generated visual appears, the displacement hypothesis becomes more credible. If no such visual appears, or the decline affects unrelated pages, look for another explanation before changing your image workflow.
Also separate visibility from value. A page can receive fewer visits without losing the same proportion of conversions, subscriptions, or qualified inquiries. Conversely, a visible citation can look positive while contributing little meaningful traffic. Track both search presence and the outcome you actually need.
When you find an inaccurate or confusing generated visual, capture the evidence before the interface changes. Preserve the query, complete visual, citations, and relevant landing pages. Use any feedback or reporting control available in the result, then check whether ambiguity on your own page contributed to the problem. Correct your page when it is unclear, but do not rewrite accurate instructions merely to match a generated mistake.
Key takeaways
Google stopped the small recipe experiment that automatically generated process illustrations inside AI Overviews.
The experiment was separate from image generation triggered by an explicit user request.
A Google-generated search visual, a publisher image shown in search, and an AI image published on your site are three different SEO questions.
The stopped test does not establish a general ranking penalty or benefit for AI-generated images on publisher sites.
Original visuals become more defensible when they document meaningful stages, match the instructions, include precise captions, and align with structured data.
Do not infer traffic loss from the feature’s existence. Record the result and compare affected queries and pages before changing your production strategy.
Start with your highest-value image-led template. Audit the relationship among its instructions, visuals, captions, credits, alt text, and structured data, then establish a performance annotation you can use if generated visuals reappear. The next experiment may take a different form, but clear evidence and clean measurement will leave you in a position to respond without guessing.
Your pages rank, your brand has authority, and buyers know your name. Yet when someone asks ChatGPT which companies belong on a shortlist, you are missing. That gap is real: search visibility can help ChatGPT find you without making your brand one of the names it chooses.
The practical fix is to identify where visibility breaks. ChatGPT must associate your brand with the right category, retrieve usable evidence, and have enough corroboration to include you confidently. Each failure requires a different response.
Find the layer where your visibility breaks
Brand visibility in ChatGPT is not a single ranking. It is a sequence of outcomes:
Recall: ChatGPT recognizes your brand as relevant to the category or problem.
Retrieval: your page, another page about you, or both enter the material available for the answer.
Selection: ChatGPT uses that material to mention, describe, recommend, or cite your brand.
A brand can pass one layer and fail the next. ChatGPT might know your name but not classify you as a provider in the requested category. It might retrieve your page but choose a competitor because that competitor is described more consistently across independent websites. It might mention you from prior model knowledge without citing your domain at all.
An AI answer also creates a smaller consideration set than a search results page. A category may have hundreds of plausible providers, but ChatGPT often returns a short list of familiar names. If your brand is outside the five to ten names the model commonly recalls, more organic traffic will not automatically move you into that shortlist.
Start your diagnosis with unbranded prompts. A branded question such as “What does Acme do?” only tests whether ChatGPT can navigate to or describe Acme. It does not test whether Acme appears when a buyer asks for the best platform for a job, industry, budget, audience, or constraint.
Key takeaways
Keep the SEO foundation. Organic authority usually supports AI visibility, but it does not guarantee recall or recommendation.
Measure recall, retrieval, citation, and factual accuracy separately. Combining them into one score hides the problem you need to fix.
Make the brand-category relationship explicit on your own site and consistent across the web.
Build independent corroboration. Repeated third-party descriptions can matter more than another self-promotional page.
Test the ChatGPT product modes your audience uses. API output is not a reliable substitute for product-level retrieval.
Make your brand-category association unmistakable
ChatGPT cannot recommend your brand for a category it does not clearly associate with you. This is an entity-positioning problem before it is a keyword problem.
Many brands make that association unnecessarily difficult. Their homepages lead with language such as “transforming possibilities” or “intelligent solutions” while the actual product category appears deep in a feature page. Human visitors may infer the meaning from design and context. A retrieval system assembling evidence from titles, snippets, cached text, and third-party descriptions has less room for inference.
Write one internal positioning sentence before changing any page:
[Brand] is a [specific category] for [specific audience] that helps with [specific job], especially when [relevant constraint or differentiator].
This is not necessarily homepage copy. It is a control statement for checking whether your website, profiles, reviews, press coverage, comparison pages, and structured data tell the same basic story.
Choose the category you need to own. Use the phrase a buyer would recognize, not an internal market label invented for differentiation.
Define adjacent categories deliberately. If your product belongs in several markets, state the relationship instead of expecting ChatGPT to infer it from a feature list.
Create a canonical page for each important use case. Explain who the product is for, the problem it solves, how it works, its meaningful constraints, and the evidence behind its claims.
Connect supporting pages to that canonical explanation. Product documentation, customer stories, comparisons, integrations, pricing information, and help content should reinforce rather than contradict the core classification.
Align identity signals. Use the same brand name, product names, company description, category language, and official URL across the properties you control.
Structured data can support this clarity, but it should label facts already visible on the page. Organization, Product, Service, and Article markup can clarify entity relationships when they are accurate. They do not manufacture authority, repair vague positioning, or guarantee inclusion in a ChatGPT answer.
Apply a simple editorial test: remove the logo and navigation, then read the first useful section of the page. Could an unfamiliar editor complete the sentence “[Brand] is a…” without guessing? If not, a retrieval system may face the same ambiguity.
Comparison content can help when it reflects a genuine decision. Explain which buyer, use case, or constraint makes each option suitable. A page that declares your product the winner in every scenario supplies less credible evidence than one that states its boundaries. The goal is not to repeat a category phrase. It is to make your place in the category easy to verify.
Build the corroboration your own website cannot provide
Your website can establish what you claim. Independent coverage helps establish whether that claim is recognized elsewhere.
That does not mean collecting as many mentions as possible. A syndicated announcement copied across dozens of sites is repetition, not necessarily independent corroboration. Useful coverage supplies context: what category the brand belongs to, who it serves, where it is strong, what evidence supports the description, and how it compares with realistic alternatives.
Build a corroboration map around actual buyer decisions:
List the publications, specialist sites, professional communities, directories, reviewers, and comparison pages that already appear for your unbranded category prompts.
Record how each one describes your category. The language used by credible third parties may differ from the label your marketing team prefers.
Mark where competitors appear and you do not. That is a distribution gap, not an on-page optimization task.
Check whether existing coverage places you in the wrong category, uses an old product name, repeats a discontinued claim, or points to a retired URL.
Prioritize pages that help a reader make the same decision represented by the prompt. Relevance is more useful than an unrelated high-authority mention.
Then give credible publishers something worth referencing. Original data, transparent methodology, technical documentation, clearly attributed expert analysis, useful tools, and verifiable customer outcomes create evidence. Generic claims such as “leading,” “innovative,” or “best-in-class” create copy that no careful editor needs.
For each important external mention, look for six qualities:
Your current brand and product names are accurate.
The relevant category is stated plainly.
The intended audience or use case is clear.
Important claims have evidence or transparent attribution.
The page is publicly accessible at a stable URL.
The description agrees with current first-party facts without merely copying your sales language.
Do not optimize only for positive wording. Accurate qualification is more useful. “Suitable for distributed enterprise teams that need X” gives ChatGPT a reason to select the brand for one prompt and omit it from another. That is better visibility than appearing indiscriminately and being described incorrectly.
Make important pages easy to discover, read, and reuse
ChatGPT search does not simply send one query to a conventional search engine and summarize the first page. In one observational capture involving 1,200 answers, 88,000 search results, and 26,900 distinct pages, web grounding showed three operational layers: a discovery index that surfaced candidates, cached full-page copies, and a smaller group of pages opened live.
These layers are observed behavior, not a permanent OpenAI specification. The implementation can change. The model is still useful because it explains why “we rank in Google” and “ChatGPT can use this page” are different claims.
Discovery comes first. A page needs a stable, indexable URL, a successful response, a descriptive title, internal links, and a place in the site’s normal crawl paths. A page that exists only behind search, an interactive selector, a login, or a client-side application shell is a weak candidate for dependable retrieval.
Do not use Bing visibility as a definitive proxy for OpenAI discovery. The observed OpenAI index behaved differently: only 1.5% of its URLs appeared in Bing’s top 20 for the same fan-out queries, and its snippets and title handling also differed. Google rankings can matter in retrieval regimes that use scraped Google results, but they do not prove that a page entered OpenAI’s own index.
Once discovered, the page must be understandable in isolation. Treat the retrieved document as if the navigation, design, and sales presentation were gone. The text itself should answer these questions:
What entity or product is this page about?
What question does it answer?
Which audience, market, version, region, or use case does the answer apply to?
What evidence supports its factual claims?
When was the information meaningfully updated?
Which page is canonical if similar versions exist?
Put the direct answer near the top, then expand it under descriptive headings. Use tables only when readers are comparing stable dimensions. Keep qualifications beside the claim they limit. A sentence that says “available in Canada” on one page and “available globally” on another creates an avoidable conflict unless both statements explain their dates or product scopes.
Cached reading introduces another practical issue: a fact can be corrected on your live page while an older copy or an outdated third-party description remains available elsewhere. When an answer repeats stale information, check more than the current page. Find obsolete URLs, duplicates, old documentation, directory profiles, and external comparisons. Update or redirect what you control, request corrections where appropriate, and make the current canonical page easy to reach through internal links.
A retrieval-ready page therefore needs more than technical indexability. It needs explicit meaning, extractable evidence, consistent facts, and the correct distribution channel for the query.
Measure the answer, then fix the right bottleneck
A single screenshot is not an AI visibility program. ChatGPT answers vary with wording, product mode, retrieval corpus, system behavior, location, account context, and time. Your benchmark needs a controlled prompt set and enough detail to reproduce each observation.
Build prompts from the decisions that matter to your audience:
Category discovery: requests for providers, products, or approaches in your market.
Problem discovery: prompts that describe the job without naming the solution category.
Constraint prompts: industry, audience, geography, integration, budget model, compliance need, or workflow limitation.
Comparison prompts: your brand against a named alternative or a request for options with explicit tradeoffs.
Branded verification: questions about what you do, who you serve, current features, availability, pricing model, or another fact you can validate.
Keep category, problem, and branded prompts in separate groups. A strong score on branded verification can otherwise conceal complete absence from unbranded discovery.
Signal
What to record
What it diagnoses
Brand mention
Whether the brand appears and in which prompt class
Category recall and consideration-set inclusion
Position and framing
Where the brand appears, which use case is attached, and any qualification
Brand-category association and positioning accuracy
Citation
Whether a claim is cited, the linked URL, and whether the domain is yours or independent
Retrieval and evidence selection
Factual accuracy
Correct, outdated, unsupported, or contradictory claims
Canonical-content, cache, and corroboration problems
Competitive recurrence
Which alternatives repeatedly appear for the same prompt class
The actual AI consideration set
Test context
Exact prompt, ChatGPT mode, account tier, location context, and test date
Whether two observations are meaningfully comparable
Use the actual ChatGPT experience your audience is likely to encounter. API tests can help probe what a model family appears to know, but they should be labeled as a different measurement. In captured comparisons, product-to-API brand overlap measured only 0.23 to 0.27 using Jaccard similarity. Even ChatGPT product regimes shared only about a third of the brands they mentioned. An API monitor can therefore be directionally interesting while failing to predict the product answer.
Translate each result into a specific action:
If competitors recur in unbranded prompts and you never appear, inspect category association and third-party coverage before rewriting title tags.
If ChatGPT mentions you accurately but never retrieves your domain, improve the official pages that substantiate the relevant claims and make them easier to discover.
If your domain is cited but the answer describes you incorrectly, remove ambiguity and conflicting first-party facts from the cited page.
If outdated external pages drive an error, correct the corroboration layer rather than publishing another unsupported claim on your homepage.
If results vary by mode, retain the variation in your reporting. Do not average materially different retrieval regimes into a false sense of precision.
If shopping or local prompts fail while editorial prompts succeed, inspect merchant feeds or business listings instead of treating the problem as ordinary web SEO.
Keep a changelog beside the benchmark. Record the pages changed, external descriptions corrected, new coverage earned, and structured data updated. Retest the same prompt set under the same documented conditions, then inspect whether recall, retrieval, citation, or accuracy moved. This keeps you from crediting one tactic for a change caused by a different product mode or retrieval update.
Your next move should follow the clearest failure. If ChatGPT does not associate you with the category, fix positioning and corroboration. If it recalls you but cannot support the answer, fix retrieval and evidence. If it cites stale or incorrect material, reconcile the fact across every page that can still influence the answer. That is how AI visibility becomes an operating practice instead of a collection of screenshots.
You may know exactly how much revenue Google Ads claims and still not know how much revenue the ads created. That gap matters most when branded campaigns, strong organic rankings, and direct traffic all reach the same customer.
A paid search incrementality test replaces that ambiguity with a controlled absence. You pause a defined slice of advertising, measure what actually disappears and what moves elsewhere, then compare the incremental loss with the spend you avoided. The goal isn’t to prove that paid search works or doesn’t. It is to identify where it acquires demand, where it supports another channel, and where it charges you for demand you already own.
Attribution records a route; incrementality measures an effect
Platform attribution answers, “Which tracked interaction received credit?” Incrementality answers, “What would have happened without this interaction?” Only the second question tells you whether removing or reducing spend would materially change the business outcome.
Suppose a customer searches your company name, clicks an ad above your top organic result, and buys. The advertising platform can correctly record the ad click while still overstating the ad’s causal value. The unresolved question is whether that same customer would have clicked the organic listing and bought anyway.
You can’t settle that question with last-click, first-click, data-driven, or multi-touch attribution alone. Changing the credit rule redistributes recorded value among observed touches. It doesn’t create the missing counterfactual.
For a useful diagnosis, classify paid search at the query or campaign level:
Classification
What it means
What you should test or decide
Incremental
Paid search reaches customers or produces outcomes that your other channels would not have captured.
Keep it when incremental contribution exceeds its cost; test expansion separately.
Dependent
Organic or another channel performs worse when paid support disappears.
Measure the combined channel effect and avoid treating paid and organic as isolated budgets.
Cannibalized
The ad captures a click or conversion that a strong unpaid result was already positioned to win.
Reduce or pause the affected slice while monitoring total revenue, query clicks, and competitive pressure.
These aren’t permanent labels. A branded query can be largely cannibalized while you rank first, then become more incremental if organic visibility falls or a competitor changes the search results. Your test should therefore support a budget rule with conditions, not a timeless verdict about the channel.
Key takeaways
Test a material but reversible slice of spend instead of switching off the entire account by default.
Judge the test on total business outcomes, not on the revenue that disappears from the advertising platform’s report.
Separate branded search, non-brand search, Shopping, and Performance Max because their substitution patterns can differ.
Join paid search-term data with organic query data before the pause so you know where paid and organic already overlap.
Allow for delayed substitution. A short test can make paid search look more incremental than it is if customers and reporting take time to move.
Make the final decision with incremental contribution or profit, not attributed ROAS.
Design the pause around one budget decision
A broad question such as “Does paid search work?” cannot produce a clean action. Define the decision first: whether to keep branded ads in a particular market, reduce spend on terms where you already rank strongly, or retain a non-brand campaign that appears to introduce new customers.
Then write the test plan before changing the campaigns:
State the counterfactual. Write what you expect customers to do when the selected ads disappear. For example, they may move to organic listings, arrive directly, choose a competitor, or not visit at all. This forces you to measure the channels where substitution should appear.
Choose one testable slice. Isolate branded search from non-brand search, Shopping, and Performance Max. A result from brand terms should not be used to cut prospecting campaigns whose job and audience are different.
Select the test unit. A campaign, coherent query group, or market can be paused while a comparable unit remains active. A credible control helps distinguish the pause from seasonality, promotions, or a general change in demand. If no good control exists, be explicit that a pre-versus-post result carries more uncertainty.
Lock the primary outcome. Use total revenue, qualified leads, purchases, or another business result that exists outside the ad platform. Record paid-attributed revenue, organic revenue, direct revenue, organic clicks, and total query clicks as diagnostic measures rather than competing versions of success.
Define the economic rule. Decide in advance how you will compare the incremental outcome with avoided media cost. Where margin data is available, use contribution rather than revenue; otherwise a high-revenue, low-margin campaign can appear more valuable than it is.
Record known disruptions. Promotions, price changes, inventory constraints, site outages, tracking changes, SEO releases, and brand publicity can alter the same metrics as the pause. Log them during the test and exclude or qualify affected periods instead of explaining them away after seeing the result.
Set exposure and rollback conditions. Specify the largest acceptable business loss before launch. If the downside could be material, stage the pause or use a narrower market. Don’t invent the rollback threshold after an uncomfortable result appears.
Declare the observation window. Include enough time for buying cycles, channel switching, and revenue reporting to settle. One documented pause recovered 30% of paid-attributed revenue through organic and direct within six weeks, but that figure rose to 65% by week 13. That is evidence that substitution can lag, not a universal thirteen-week minimum.
Build the overlap baseline before you pause
Export Google Ads search terms with their spend and outcomes, then export matching Google Search Console queries and organic clicks for the same dates. Normalize obvious differences such as capitalization and whitespace, but preserve query intent. A brand name, a brand-plus-product query, and a generic category query shouldn’t be collapsed into one row merely because all three contain the company name.
For each matched query, record paid clicks, paid spend, paid outcomes, organic clicks, and whether a meaningful organic result is present. This gives you a map of expensive overlap. It does not prove cannibalization on its own: customers can still respond differently when both listings appear. The pause provides the causal evidence; the query join tells you where to look and how to interpret the movement.
Protect the business without protecting the assumption
A total-account blackout can create unnecessary financial exposure. Choose the largest coherent slice whose potential loss the business can tolerate, while retaining enough volume to produce a useful signal. If a small unit cannot distinguish normal variation from a real effect, acknowledge that limitation or have an analyst assess the design before increasing exposure.
Monitor competitor activity on branded results during the pause, but don’t treat a competitor impression as proof that your ad is incremental. The relevant outcome is whether the changed results cause a measurable loss in total clicks, conversions, revenue, or contribution. Brand protection can be a legitimate job for paid search; it should be named and valued as protection rather than reported as customer acquisition.
Measure substitution outside the advertising dashboard
The moment you pause ads, paid clicks and paid-attributed revenue will fall. That is an implementation check, not the test result. The result is the difference between the total outcome you observed and the total outcome you would reasonably have expected with the ads still running.
Use a comparable control market or campaign when you have one. Measure how the control changed over the same period, then apply that movement to the test unit’s baseline. This is more defensible than assuming the week before the pause would otherwise have repeated exactly. Without a control, compare against a predeclared baseline and carry the added uncertainty into the decision.
Calculate the readout in this order:
Estimate the paid-on counterfactual. Determine the total revenue, purchases, or qualified leads you would have expected in the test unit if ads had remained active.
Measure the total incremental loss. Subtract the observed total outcome during the pause from the paid-on counterfactual. This is the business effect attributable to removing the ads, subject to the design’s uncertainty.
Measure channel substitution. Compare organic, direct, and any other plausible substitute channels with their counterfactual levels. Use these movements to explain where demand went, not to override the total-outcome calculation.
Calculate recapture. Divide verified substitute-channel lift by the paid-attributed revenue that disappeared. State clearly which channels were counted and how their counterfactuals were estimated.
Compare incremental value with avoided cost. For a revenue-based view, divide the incremental revenue preserved by the ad spend required to preserve it. For the economic decision, apply the relevant contribution margin and subtract media cost.
Direct traffic deserves special care. A rise in direct revenue may represent people who saw no ad and typed the address, customers returning through bookmarks, or a change in how analytics classified the visit. The first two can be genuine substitution; the third is measurement reclassification. Look for timing, market specificity, and corresponding stability in total business outcomes before counting the entire increase as recaptured demand.
The same caution applies to organic traffic. More organic clicks after a pause are persuasive when they occur on the affected queries, in the affected market, during the declared window, and alongside the expected loss of paid clicks. A sitewide organic increase caused by an unrelated SEO release shouldn’t be credited to paid-search substitution.
The important pattern is the delay, not a benchmark you should copy. A six-week read would have made the ads appear much more incremental than the later observation did. The shift toward direct revenue also shows why a paid-versus-organic traffic comparison is too narrow: substitution can cross both channel and attribution boundaries.
Don’t treat the remaining 35% as automatically incremental. Some of it may be a real paid-search effect, but the strength of that conclusion depends on the counterfactual, controls, tracking, and outside events. Report the observed total loss, the estimated substitute lift, the avoided spend, and the uncertainty separately. A single blended percentage hides the assumptions leadership needs to judge.
Turn the result into campaign-level budget rules
An incrementality test should end with a rule someone can execute in the account. “Paid search is incremental” and “brand ads are wasteful” are both too broad.
High incremental contribution: retain the tested campaign when the contribution it protects exceeds media cost. Treat expansion as a new hypothesis; the next dollar may not perform like the current dollar.
Low incrementality with strong organic substitution: keep the slice paused or reduce it, then monitor organic visibility, total query clicks, revenue, and competitor pressure. Define the conditions that would trigger a retest or restart.
Dependent organic performance: manage paid and organic as a combined search system. Investigate which queries lost total clicks or outcomes rather than assuming that an organic ranking alone guarantees replacement.
Primarily defensive value: label the budget as brand protection. Decide whether the measured conversion or revenue loss justifies that protection instead of letting attributed ROAS disguise it as acquisition.
Uncertain result: don’t force a binary decision. Restore only what is required by the predeclared guardrail, improve the control or measurement, and run a better-bounded test.
Keep a permanent test record containing the hypothesis, test and control units, campaign changes, baseline dates, primary outcome, rollback rule, exclusions, calculation method, and final decision. Revisit the rule when organic visibility changes, competitors become more aggressive, margins shift, tracking changes, or the campaign begins serving a materially different mix of queries.
Your next step is to choose one material but reversible slice of paid search. Write its counterfactual, export the paid-organic overlap, lock the business guardrail, and schedule the readout far enough beyond the pause to observe substitution. If the spend returns, it should return with a clear job description: acquisition, channel support, or brand defense. If it doesn’t, you can redirect the budget toward demand you weren’t already positioned to capture.
Your pages rank in conventional search, yet your brand disappears when a prospect asks an AI platform for options. Or the brand appears, but the answer cites the wrong page, omits the reason to choose you, or repeats an outdated claim.
You do not fix that with a larger keyword list. You need a visibility system that separates retrieval, citation, accuracy, and business relevance. Once those layers are measured separately, you can see whether the real problem is access, content, authority, entity clarity, or the test itself.
AI search visibility is a set of contexts, not one ranking
A conventional rank tracker usually ties a query to a search engine, location, device, and result position. AI search adds more variables. The same underlying need can be handled by different products, modes, models, account tiers, languages, and prompt formulations.
Platform and search surface, such as a conventional result page or an AI-specific mode.
Model or mode when the interface exposes it; otherwise record that the default was used.
Account or subscription context, including whether the test was signed in.
Language, market, and location relevant to the audience you actually serve.
Exact prompt and any follow-up prompts that changed the answer.
Test date, because platforms and underlying models change.
Then separate four outcomes that are often collapsed into a vague visibility score:
Inclusion: Was your brand, product, expert, or content mentioned?
Citation: Did the response link to or otherwise identify one of your pages?
Representation: Were the claims about you correct, current, and properly qualified?
Destination: Did the cited page actually help the user take the next step?
Do not call any of these a universal AI rank. A brand can be mentioned without being cited, cited below a competitor, accurately recommended in one mode, and absent in another. Preserve those distinctions in reporting or you will prescribe the wrong fix.
Build a prompt map around decisions, not isolated keywords
People often use AI search to describe a situation, add constraints, compare approaches, and ask follow-up questions. A keyword list strips away much of that intent. Build your test set around the decisions for which your brand should be a credible candidate.
Start with prompt families that represent distinct jobs:
Problem discovery: The user describes an outcome or obstacle without naming a solution category.
Category education: The user asks what an approach is, how it works, or when it is appropriate.
Option discovery: The user asks for tools, providers, methods, or examples that meet stated constraints.
Evaluation: The user compares options by capability, audience, implementation requirements, or another relevant criterion.
Verification: The user checks a specific claim about a brand, product, person, policy, integration, or feature.
Action: The user asks how to implement, configure, buy, contact, or proceed.
Attach context to each prompt family: the intended audience, the need behind the question, meaningful constraints, applicable market and language, the entity you expect an answer to discuss, and the page that best supports your eligibility. This turns a bag of prompts into an auditable coverage map.
Keep branded and non-branded prompts separate. A test such as “What does Brand X offer?” measures whether the system can identify an entity it has already been given. A category question that never names Brand X tests discovery. Combining the two can make strong branded recognition conceal weak category visibility.
For each important intent, retain a stable anchor prompt so results can be compared over time. Add natural variations to expose sensitivity to wording, audience, and constraints. Save the raw answer rather than recording only a pass or fail. Generated responses can vary, and the wording often reveals why a page was selected, misunderstood, or ignored.
Relevance must remain part of the test. If your brand does not satisfy the user’s stated need, its absence is not a visibility failure. Define eligibility before running the prompt. Otherwise the measurement rewards forced mentions instead of useful recommendations.
Make important claims retrievable, citable, and easy to verify
An AI system cannot reliably cite a claim that exists only as an implication. If a reader must combine a slogan, an image, a pricing card, and a separate support page to understand what you offer, machine retrieval has the same avoidable burden.
Write answer-bearing passages
Give each important page a clear information job. A strong passage usually names the entity, answers a specific question directly, supplies the necessary qualification, and points to supporting evidence. The relevant facts should survive when the passage is read outside the visual context of the page.
Open a section with the answer it exists to provide, then explain the reasoning or process.
Use the same canonical names for the company, product, feature, and people across related pages.
Place limits, prerequisites, markets, and audience qualifications beside the claim they modify.
Distinguish current capabilities from planned, historical, optional, or third-party capabilities.
Link claims to the most direct supporting page instead of sending every citation to the homepage.
Show publication or modification information when recency affects whether the claim is usable.
Remove conflicting versions of material or make the authoritative version unambiguous.
This is not an instruction to turn every page into a collection of short answers. Explanations, comparisons, examples, and limitations give an answer the context needed to be trustworthy. The goal is to eliminate ambiguity without stripping away substance.
Before commissioning a broad content rewrite, inspect the affected URLs:
Confirm that robots rules and page-level indexing directives match the access policy you intend to enforce.
Check that the preferred URL returns successfully and does not depend on a login, consent failure, or unintended interstitial.
Make sure the canonical points to the version containing the information you want discovered.
Inspect the rendered page and underlying HTML. The primary facts should not exist only inside an image or an interaction that a retriever may never execute.
Use internal links and sitemaps to make important pages discoverable from the rest of the site.
Review server logs, when available, to determine whether the crawlers you intend to permit are reaching the relevant URLs.
Do not weaken security or expose private material merely to gain visibility. Public product facts, protected customer data, and content licensed under access restrictions require different policies. Improve access only for material that is meant to be public.
Use JSON-LD to clarify visible facts
Structured data is a clarification layer, not a substitute for a useful page. Apply schema types that match the visible content, such as Organization, Person, Article, Product, Service, or BreadcrumbList where appropriate. Keep names, URLs, authorship, dates, and entity relationships consistent with what a reader can see.
Do not add claims to JSON-LD that the page does not support. Do not mark up a generic sales statement as though it were independently verified evidence. Validate the syntax, but also validate the meaning: technically valid markup can still describe the wrong entity or contradict the page. No schema type guarantees inclusion or citation in an AI response.
Build corroboration without manufacturing consensus
Your site is the primary place to state what your organization does. It is not independent confirmation of every claim it makes. Accurate profiles, relevant industry coverage, genuine expert participation, and substantive community contributions can help other people and systems encounter the same entity in context.
Prioritize mentions that clarify a real relationship: who the product serves, what problem it addresses, how an integration works, where an expert contributed, or why a claim is credible. Repeated promotional mentions with no additional evidence add noise. Fake reviews, undisclosed placements, and synthetic community activity also create reputational risk rather than dependable authority.
Measure the response, diagnose the layer, then make the fix
Run a repeatable visibility audit
Freeze the baseline. Save the prompt set, eligibility rules, platform context, language, account state, and pages you expect to support each intent.
Capture the full response. Record whether the brand appears, which claims are made, which pages are cited, which alternatives appear, and whether follow-up prompts materially change the answer.
Label distinct outcomes. Mark discoverability as absent, mentioned, or cited; representation as accurate, partial, incorrect, or unclear; relevance as appropriate or forced; and the destination as direct, indirect, or missing.
Look for patterns. Group failures by prompt family, page, platform, model or mode, and branded versus non-branded intent. A pattern is more diagnostic than an isolated answer.
Change a single layer where practical. Fix access, rewrite the supporting passage, clarify the entity, improve internal linking, or pursue corroboration. Rerun the same baseline before expanding the test.
Keep evidence. Store raw outputs and dates so a model change is not mistaken for the effect of an unrelated site edit.
Use a failure pattern to choose the next check:
What you observe
Likely starting point
What to inspect next
No relevant page from your domain appears across affected prompt families
Access, retrieval, authority, or a missing answer page
Robots rules, indexing directives, rendering, canonicals, internal discovery, server logs, and whether a page directly answers the need
A relevant page is cited, but the brand or capability is omitted
Entity or claim ambiguity
The answer-bearing passage, canonical naming, visible qualifications, internal links, and matching JSON-LD
The brand appears with an incorrect or outdated claim
Conflicting information or weak version control
Old URLs, duplicated pages, modification information, entity consistency, and the page used as evidence
The brand appears for branded prompts but not eligible category prompts
Discovery and authority gap
Non-branded decision content, topical coverage, relevant corroboration, and how clearly pages connect the brand to the problem
Results differ by mode, account tier, language, or market
Context-dependent visibility
Segmented reports and content coverage for the specific environment; do not average the difference away
Prioritize accuracy before reach
An AI mention is not automatically a win. If the summary is wrong or the cited page does not support it, more visibility amplifies the error. Correct material misrepresentation first. Then resolve access failures, strengthen the evidence behind eligible claims, and expand coverage into additional prompt families.
Keep response visibility and website outcomes in separate views. Analytics can show visits and actions after a click, but it cannot reveal every unlinked mention or answer that satisfied the user without a visit. For AI visibility, report the share of eligible tests that mention the brand, the share that cite it, the accuracy of those representations, and the pages selected as evidence. For business performance, report what visitors do after reaching the site.
Do not blend branded discovery, non-branded discovery, citation, and accuracy into one headline score. A rising total could conceal a damaging increase in incorrect answers. The segmented measures tell you what changed and which team can act on it.
Key takeaways
Measure AI visibility by platform, surface, model or mode, language, market, and account context rather than treating it as a universal rank.
Organize tests around real user decisions and keep branded prompts separate from non-branded discovery.
Evaluate inclusion, citation, representation, and destination quality independently.
Fix crawlability before rewriting accessible pages, and fix inaccurate representation before pursuing more reach.
Write self-contained, qualified passages that a system can retrieve and cite without reconstructing the claim from several pages.
Use JSON-LD to clarify visible facts and entity relationships; do not treat schema as evidence or a citation guarantee.
Track raw responses over time while measuring referral traffic and onsite outcomes separately.
Choose a customer decision that matters now. Map the prompts around it, test the AI contexts your audience can actually use, and identify the first broken layer. Repair that layer and rerun the same baseline. When a platform introduces another model or mode, you will have a controlled test to repeat instead of starting with another guess.
Your campaigns may not be underperforming. Your attribution window may simply be cutting off conversions before your customers finish deciding.
Google Analytics now gives you much finer control over that cutoff. The useful question isn’t whether you should choose a longer window. It’s which window reflects the conversion you’re measuring, the interaction you’re crediting, and the decision you need the report to support.
What an attribution window actually changes
An attribution window, also called a lookback window, defines how long an advertising interaction remains eligible to receive credit for a later conversion. If the conversion occurs after the selected window closes, that interaction no longer qualifies for credit under that setting.
The window changes attribution eligibility. It doesn’t create or remove the customer’s action, accelerate the buying process, or prove that an ad caused the conversion. That distinction matters whenever a settings change makes campaign results appear better or worse.
Don’t confuse the window with the attribution model. The window determines which interactions are recent enough to qualify. The model determines how credit is handled among eligible interactions. A model can only work with the interactions admitted by the window.
A longer window keeps delayed conversions eligible for longer. That can increase the number of conversions associated with advertising interactions, especially when buyers take time to research, compare, seek approval, or return later. A shorter window applies a stricter recency standard, but it can exclude advertising interactions that genuinely began the decision process.
Neither direction is automatically more accurate. A long window can sweep distant interactions into the report even when their practical influence is uncertain. A short window can make longer consideration journeys disappear from campaign reporting. Your job is to choose the cutoff that makes the report useful for a defined decision.
Choose the window from the conversion backward
Start with the event being counted, not the platform’s maximum setting. A form submission, account registration, purchase, and completed contract represent different points in a customer journey. Their normal delays from ad interaction can be very different.
Define the event before estimating its delay
If Google Analytics records a lead form as the conversion, select a window for the time between the advertising interaction and that form submission. Don’t silently base it on the later time required to close the sale. Conversely, if the recorded conversion is an imported final outcome, the relevant delay extends to that final outcome.
Write a one-sentence definition for every conversion you optimize toward: what happened, when it is recorded, and what business decision it informs. This prevents teams from debating window length while referring to different endpoints.
Use observed decision lag, not a convenient preset
Look for the elapsed time between relevant ad interactions and the conversion event. Use the evidence available in your analytics paths, ecommerce records, lead timestamps, or customer system. You are looking for the ordinary shape of the delay: whether conversions cluster soon after interaction, continue arriving gradually, or commonly require a longer decision period.
Then choose the shortest window that still represents the normal journey you intend to measure. This is a decision rule, not a universal benchmark. It keeps the setting tied to customer behavior while limiting credit from interactions so old that their relevance becomes difficult to defend.
When evidence is thin, don’t hide the uncertainty behind the maximum available value. Pick a defensible starting point, document why you chose it, and treat the setting as a measurement assumption to validate.
Decide separately for clicks and engaged views
Click-through and engaged-view conversions begin from different types of advertising interaction, so they shouldn’t inherit the same window without examination. Ask what each interaction represents in your campaign and how long it can reasonably remain relevant to the measured action.
For click-through conversions, examine the delay from an ad click to the defined conversion event.
For engaged-view conversions, examine the delay from the qualifying view engagement to the same event.
If the two paths show different timing, use different windows. Symmetry is not a measurement goal.
If stakeholders disagree, make the assumption explicit rather than blending the two interaction types into one unexplained rule.
Configure the custom windows without defaulting to the maximum
In Google Analytics, go to Advertising > Conversion management > Settings. The controls are also available through the conversion management interface in linked Google Ads. Because both surfaces can be involved in campaign measurement, review the active values where your team actually manages conversions rather than assuming everyone is looking at the same configuration.
Inventory the conversions used in reporting, bidding, or budget decisions.
Define the exact customer action represented by each conversion.
Review the observed delay for click-through and engaged-view interactions separately.
Select a whole-day value within the applicable range.
Record the previous value, the new value, the change date, the evidence used, and the owner of the decision.
Check dashboards, recurring reports, and campaign reviews that may be affected by the new eligibility cutoff.
Resist setting click-through to 90 days and engaged-view to 30 days merely because those values capture the most possible credit. Maximum inclusion isn’t the same as accurate attribution. The right value is the one you can explain in terms of the conversion event and the customer’s normal decision time.
Evaluate the change without mistaking attribution for growth
A window change can move reported campaign performance even when customer demand and campaign execution haven’t changed. Treat the configuration change as a break in measurement continuity.
Annotate the effective date in your reporting workflow. When comparing periods, disclose whether both periods used the same window. If they did not, a difference in attributed conversions may reflect the eligibility rule rather than a change in campaign quality.
Recent conversion cohorts also need time to mature. The longer the selected window, the longer an interaction can remain eligible for a delayed conversion. A click tracked under a 90-day window can continue receiving eligible conversion credit for far longer than one tracked under a short window. Don’t judge the newest cohort as complete while that opportunity remains open.
Use a controlled review process:
Keep a record of the configuration change so analysts can distinguish it from campaign edits.
Compare the observed conversion-delay pattern with the window you selected. Conversions accumulating near the cutoff deserve scrutiny because the setting may be truncating a meaningful part of the journey.
Inspect click-through and engaged-view results independently before combining them in a campaign conclusion.
Ask whether any apparent gain comes from more customer actions or simply from allowing older interactions to qualify.
Revisit the choice when the conversion definition, buying process, campaign format, or reporting objective changes.
The strongest internal test is explainability. A stakeholder should be able to ask, “Why does this interaction still deserve credit?” and receive an answer grounded in the conversion event and observed journey, not in a desire to preserve reported return.
Key takeaways
An attribution window controls how long an ad interaction remains eligible for conversion credit; it does not prove causation.
Choose the window for the conversion event actually recorded, not for a later business outcome that Analytics isn’t measuring as that conversion.
Google Analytics supports custom click-through windows from 1 to 90 days and custom engaged-view windows from 1 to 30 days.
Clicks and engaged views represent different interaction paths, so evaluate their timing separately.
Document every window change because it can alter reported attribution without any underlying change in customer behavior.
Use the shortest defensible window that captures the normal decision journey, then validate it against observed conversion delay.
Before your next campaign review, list the conversion actions that influence spend and write down the active window beside each one. Any value your team can’t connect to a defined event and an observed decision lag is the first setting to revisit.
You are not deciding whether AI belongs in Google Ads. Smart Bidding, broad match, and Performance Max have already moved substantial execution into algorithms. The decision in front of you is narrower: should an AI agent observe your account, recommend changes, or act on your behalf?
The safest path is to move from a defined manual workflow to assisted analysis, connected monitoring, and only then tightly controlled action. That sequence lets you capture useful automation without giving a fluent system permission to accelerate a broken process or spend against the wrong business objective.
Choose one job that creates leverage
Do not begin with a request to “optimize the account.” An agent cannot reliably optimize an objective that your team has not defined. Revenue, margin, lead quality, inventory movement, customer acquisition, and brand protection can point the same campaign in different directions.
A useful first assignment might be reviewing search terms against your documented targeting rules. The agent can return a ranked review queue with the search term, campaign, supporting metrics, possible concern, and recommended next check. A marketer then decides whether the term is irrelevant, strategically valuable, ambiguous, or evidence of a larger landing-page or targeting problem.
Write a short operating brief before you give the agent any data:
Job: Describe one recurring task in a single sentence.
Objective: State the business outcome the task supports.
Inputs: Name the reports, date ranges, definitions, and business rules the agent may use.
Output: Specify the fields, ordering, and evidence required in every response.
Prohibited actions: List what the agent must never infer, change, publish, or spend.
Escalation rule: Define which ambiguities must go to a person.
Reviewer: Assign the person accountable for accepting or rejecting the result.
This brief gives you something testable. If two experienced marketers cannot agree on what a correct output looks like, the workflow is not ready for automation. Resolve the business question before evaluating a model.
Key takeaways
Start with one repeatable, evidence-based task rather than an autonomous campaign manager.
Make products, services, rules, campaign structure, tone, and internal processes readable by the AI.
Test the workflow with exported data before connecting it to live platforms.
Add custom development only when you need business-system data, continuous monitoring, or controlled approvals.
Increase autonomy according to the financial and strategic consequence of a mistake.
AI does not repair an undefined process. It performs the available process more quickly and at a larger scale. If the underlying rules are incomplete, that speed magnifies inconsistency.
Build a compact business knowledge pack
Your knowledge pack does not need to be an elaborate internal encyclopedia. It needs explicit statements that can be retrieved and applied consistently. Include:
Products and services: What you sell, how offers differ, which items are priorities, and which combinations would be misleading.
Business rules: The constraints that override apparent advertising opportunities, including approved markets, commercial priorities, exclusions, and approval requirements.
Success definitions: The account objective and the meaning of the conversion, revenue, lead-quality, margin, or inventory signals used to judge it.
Campaign structure: The purpose of each campaign type, naming conventions, targeting logic, and relationships between campaigns.
Tone of voice: Acceptable language, prohibited claims, and the distinction between brand, promotional, and informational messaging.
Internal processes: Who reviews recommendations, who can approve changes, where decisions are recorded, and when another team must be consulted.
Prefer short, structured entries over long prose. Give every rule a clear name, scope, owner, and exception. If two rules conflict, document which one wins. An agent should not have to infer hierarchy from where a sentence happens to appear in a document.
Identify the system that owns each important field.
Define metrics consistently across Google Ads, Google Analytics, Google Merchant Center, and internal systems.
Record how recently each dataset was updated so the agent does not treat stale information as current.
Use stable identifiers where advertising, product, pricing, inventory, margin, and CRM records need to be joined.
Limit access to the fields required for the assigned job.
Assign a person to resolve missing, contradictory, or unexpectedly changing data.
Run a simple readiness test. Give the knowledge pack and a sample dataset to a marketer who does not manage the account. Ask them to explain what the campaign is meant to accomplish, which constraints override performance metrics, and what they cannot conclude from the data. If the answers remain ambiguous, an agent will face the same ambiguity without the organizational context a colleague can ask for.
Climb the adoption ladder before building custom software
You can test a valuable Google Ads workflow without commissioning an autonomous system. Move through the following stages only when the previous one produces repeatable, reviewable results.
Analyze an export. Export the relevant campaign data and give it to ChatGPT or Claude with the operating brief and business rules. Keep the task read-only and inspect every finding.
Preserve the business context. Put the approved instructions and reference material in a project or custom GPT so the team does not recreate the context for every analysis.
Connect live data. Use appropriate pre-built Model Context Protocol connectors for Google Ads, Google Analytics, or Google Merchant Center when repeated exports become the bottleneck. Begin with the least access the workflow needs.
Automate the trigger. Consider scheduling only after the same analysis has performed reliably when initiated by a person.
Add controlled action. Permit changes only for narrowly defined cases with explicit limits, approvals, logging, and a way to stop the workflow.
Before uploading advertiser or customer information to any general AI environment, confirm that the environment, access settings, and data handling match your organization’s policies. Remove fields the task does not require. The agent should receive enough context to decide well, not every record the business owns.
Use prompts that force evidence into the output
A vague prompt invites a polished but unauditable answer. Make the agent show how it reached each recommendation. These prompt patterns are a stronger starting point:
Account audit: “Audit this account against the supplied campaign map and business rules. For each finding, return the affected entity, supporting fields, rule applied, possible business consequence, missing information, and next check. Do not recommend a change when the evidence is incomplete.”
Search-term review: “Group search terms by the action a reviewer should consider. Cite the term and relevant campaign data for every item. Separate clear rule conflicts from ambiguous cases and expansion opportunities.”
Shopping-feed review: “Review the supplied feed against the product definitions and campaign objectives. Identify inconsistent, missing, or potentially misleading attributes. Do not invent product facts.”
Performance monitoring: “Compare the latest period with the supplied baseline. Rank material changes, identify the metric that moved, state what can and cannot be inferred, and request any business data needed before proposing action.”
Evaluate the workflow with saved examples. Track supported findings, false positives, missed issues, unsupported assumptions, reviewer effort, and whether accepted recommendations improved an actual decision. Do not promote the workflow because the response sounds expert. Promote it when qualified reviewers can verify the evidence and the process saves more effort than it creates.
Build a custom agent only when the workflow earns it
Those requirements change the job. You are no longer testing whether a model can produce an interesting analysis. You are building an operational system that has to retrieve the correct context, run at the intended time, respect permissions, handle failures, control cost, and leave enough evidence for a person to understand what happened.
A dependable custom setup normally needs these functional components:
Data access: Connectors or custom MCP services that expose only the required advertising and business data.
Orchestration: A defined sequence for retrieving context, analyzing data, checking rules, generating a recommendation, and requesting approval.
Scheduling: A controlled trigger for monitoring jobs that must run without a manual prompt.
Guardrails: Account scope, allowlisted actions, business-rule checks, and hard stops when required information is missing.
Approval routing: A queue that sends the right decision and its evidence to an accountable reviewer.
Records and recovery: A log of inputs, rule versions, recommendations, approvals, actions, and the information needed to reverse an unsuitable change.
Cost controls: Limits and monitoring for model usage, data processing, maintenance, and human review.
Use a build gate before approving development. You should be able to answer all of the following:
Has a lower-complexity version of the workflow already produced useful results?
Is the task frequent enough for automation to remove meaningful work?
Can you identify the financial or strategic consequence of a wrong recommendation?
Are the required data owners, definitions, and update paths known?
Can a reviewer see the evidence behind every recommendation?
Are approval, stop, and recovery procedures defined before the agent receives action permissions?
Does one named owner remain accountable for the workflow after launch?
If several answers are no, keep the workflow in assisted mode. The missing foundation will not become cheaper after it is embedded in custom software.
Build economics should include more than developer time. Count ongoing model and infrastructure costs, data maintenance, reviewer effort, error handling, and the cost of keeping business rules current. Compare that total with verified time returned to the team and any performance effect you can credibly attribute to accepted decisions.
Set autonomy by consequence, then make adoption a team habit
Autonomy should not be a single account-wide switch. Set it by task and consequence. A system that summarizes yesterday’s account changes does not need the same controls as one that can alter budgets, targeting, or customer-facing copy.
Agent mode
Suitable work
Required control
Observe
Retrieve data, summarize changes, and assemble reports
Read-only access, defined scope, and data-quality checks
Recommend
Flag anomalies, rank opportunities, and propose next checks
Evidence in every output and accountable human review
Act within rules
Execute a narrow, reversible action that has already been validated
Allowlisted actions, explicit limits, logging, stop conditions, and recovery procedures
Adoption also needs an operating rhythm. Identify marketers who are willing to test bounded workflows, give them room to document what works, and let them teach the wider team. Early adopters can turn isolated experiments into repeatable team practices without requiring every employee to become an AI specialist at once.
Assign an owner and reviewer to every production workflow.
Version prompts, business rules, data definitions, and connector permissions.
Record why recommendations were accepted, rejected, or escalated.
Retest the workflow when products, pricing, campaign structure, objectives, or internal policies change.
Review recurring false positives and missed issues instead of merely counting generated recommendations.
Remove permissions when the agent’s task or accountable owner is no longer clear.
Your next step does not require an autonomous media buyer. Pick one recurring audit or monitoring task, write its operating brief, assemble the minimum business context, and test it against an export. If the results hold up under human review, connect read-only data. Build further only when integration, scheduling, or approval routing becomes the real bottleneck.
The durable advantage is not maximum autonomy. It is a controlled decision loop in which the agent handles repetitive analysis and your team remains responsible for what the business is trying to achieve.
You’re adding clients faster, and the immediate question is whether one Merchant Center agency account can keep carrying the portfolio. The harder question is whether your operating model will remain controlled as the account count rises.
Google’s documented ceiling removes one important uncertainty. A Merchant Center for Agencies account can accommodate a large portfolio, but capacity alone won’t prevent confused ownership, unauthorized changes, stalled onboarding, or forgotten offboarding. You need to turn the limit into an account-management plan.
Treat 1,000 as a capacity ceiling, not a growth target
That distinction matters. The number helps you plan infrastructure, but it says nothing about how many accounts your team can manage well. An agency with unclear ownership can lose control long before it reaches the platform ceiling. An agency with a disciplined operating system can use the available capacity without turning the central account into an unsearchable holding area.
Start by measuring linked accounts as the platform measures them. Your sales team may count clients, contracts, or brands, but the relevant capacity unit is the linked Merchant Center account. Maintain four portfolio figures:
Current load: accounts that are linked now.
Committed demand: accounts attached to signed or approved onboarding work but not yet linked.
Probable demand: accounts likely to enter onboarding from the active pipeline.
Planned removals: relationships moving through an authorized offboarding process.
Use those figures to calculate headroom rather than waiting for a linking request to expose a capacity problem. Keep committed and probable demand separate. Treating every sales opportunity as guaranteed inflates the forecast, while ignoring signed onboarding work understates it.
The practical trigger is not account number 1,000. It is the point at which forecast demand could consume your remaining headroom before you have approved another structure. That is when leadership needs to make the decision, because account architecture should not be designed in the middle of a client launch.
Build an account registry before scaling the portfolio
The agency interface should not be your only system of record. Maintain a registry that explains why every account is present, who owns the relationship, and what should happen next. This can live in your established work-management system as long as it is governed and consistently updated.
At minimum, give every linked-account record these fields:
Client name and the exact Merchant Center account identifier.
Internal lifecycle state.
Client-side contact responsible for approving access.
Agency relationship owner.
Operational owner and backup contact.
Date and reason for the original linking request.
Agency Admin who completed the approved action.
Applicable team, business unit, or portfolio segment.
Open exceptions or unresolved handoff work.
Offboarding decision and completion state, when relevant.
The account identifier is especially important. Names change, abbreviations collide, and staff members remember clients differently. The identifier gives onboarding, delivery, and offboarding teams one unambiguous object to reference.
Use internal lifecycle states
Define lifecycle states in your registry instead of assuming everyone interprets a generic status such as active in the same way. A workable internal sequence is:
Requested: an intake record exists, but the request has not passed validation.
Approved for linking: the client, account identifier, agency owner, and authority to proceed have been confirmed.
Admin action pending: the request is ready for an Agency Admin.
Linked, handoff pending: the administrative action is complete, but operational ownership has not been accepted.
Managed: the account has a named owner and has entered the agency’s normal workflow.
Exception: the record has a mismatch, failed handoff, ownership question, or another issue requiring review.
Offboarding approved: the commercial relationship has ended or changed, and the authorized removal process is underway.
Closed: the offboarding work and internal recordkeeping are complete.
These are operating labels, not claims about status names inside Merchant Center. Their purpose is to keep a submitted request from being mistaken for a completed handoff.
Make linking a controlled handoff
Because Agency Admins perform the linking action, they can become either an effective control point or an avoidable bottleneck. Give them a complete, validated request rather than asking them to reconstruct missing context.
Establish authority. Record who requested the relationship and who approved it on the client and agency sides.
Validate the target. Match the client name to the intended Merchant Center account identifier before an admin acts.
Assign ownership. Name the agency relationship owner, operational owner, and backup before linking.
Complete the approved action. An Agency Admin links the validated account and records the outcome.
Accept the handoff. The operational owner confirms responsibility, reviews the account in the normal delivery workflow, and closes or escalates any exception.
A successful link proves that the administrative relationship was established. It does not prove that the client account is correctly configured, that its product data is healthy, or that the delivery team knows what it owns. Keep linking confirmation and operational validation as separate checklist items.
Decide whether one agency structure still fits
The newly documented maximum makes one part of the decision simple: a single agency account cannot be your unexamined plan for a forecast beyond 1,000 linked accounts. Below that ceiling, the better structure depends on governance as well as capacity.
Decision area
Reason to keep the portfolio together
Trigger to design another structure
Capacity
Forecast demand remains within the documented limit with deliberate headroom.
Committed and probable demand could consume the remaining capacity before a new structure can be approved.
Administration
The same controlled Agency Admin process can serve the full portfolio.
Separate groups require materially different approval authorities or access governance.
Operations
Teams use the same intake, ownership, exception, and offboarding standards.
Business units operate independently and cannot maintain one dependable system of record.
Risk isolation
Central oversight improves consistency and makes reconciliation easier.
Contractual, organizational, or security boundaries require stronger operational separation.
Continuity
A central owner can reconcile the complete portfolio during staffing or organizational changes.
No team has credible responsibility for the portfolio as a whole.
Do not create extra agency accounts merely as an assumed workaround. The published maximum defines what one agency account can carry; it does not, by itself, establish which fallback structure Google will support for your organization. If your forecast could exceed the ceiling, confirm the supported arrangement with Google before promising an onboarding path to clients.
Likewise, do not fragment the portfolio solely to make the numbers look tidy. Every additional operating structure introduces another administrator roster, capacity view, reconciliation process, and handoff boundary. Separation should solve a defined capacity or governance problem that is worth that overhead.
Scale controls and exception handling with the account count
Large portfolios usually become difficult at their edges: a request with the wrong identifier, an employee who changes teams, a client that has left but remains in the registry, or a linked account that never received an operational owner. Your control system should make those exceptions visible before they disappear into the total account count.
Assign explicit responsibility for the functions below. One person may hold more than one role, but the responsibility should never be implicit:
Agency administration: performs validated linking actions and maintains the authorized administrator roster.
Portfolio ownership: maintains the registry, capacity forecast, and reconciliation process.
Relationship ownership: confirms that each linked account corresponds to a current, authorized client relationship.
Operational ownership: accepts the delivery handoff and resolves account-level work.
Offboarding ownership: coordinates authorized removals and closes the internal record.
Reconcile the registry against the agency view after meaningful change, not only when someone notices a discrepancy. Useful triggers include a batch of onboardings, a change to the Agency Admin roster, an employee departure, the end of a client relationship, an acquisition, or a period of unusually high intake.
Your exception queue should surface conditions that require a decision:
A linked account has no active relationship owner.
An onboarding request has no validated account identifier.
An admin action has no matching approval record.
A completed link still lacks operational acceptance.
An offboarding record remains open after the relationship has ended.
The registry count does not match the visible agency portfolio.
The capacity forecast has entered the agency’s internally defined buffer.
Track the age and ownership of exceptions, not just their quantity. A small queue of unowned issues is more dangerous than a larger queue in which every item has an accountable person and a clear next action.
Automation can help with reminders, duplicate checks, status synchronization, and capacity warnings if your toolchain supports them. Keep authority with people: linking and offboarding should still trace back to a validated request and an identifiable approver. Automating an incomplete process only makes the resulting ambiguity move faster.
Key takeaways
One Merchant Center for Agencies account can support up to 1,000 linked client accounts, and Agency Admins perform the linking.
The 1,000-account figure is a documented ceiling, not evidence that every agency can operate effectively at that scale.
Forecast linked accounts separately from clients, contracts, or sales opportunities.
Maintain a governed registry with exact account identifiers, approval records, owners, lifecycle states, and offboarding status.
Treat linking and operational acceptance as separate steps.
Design another structure before forecast demand reaches the ceiling, and confirm the supported arrangement with Google rather than assuming an unlimited workaround.
Start with the registry. Reconcile it against your current agency view, name an owner for every account, classify every pending request, and calculate the headroom against committed onboarding work. Once you can explain who owns each link, why it exists, and what happens next, the 1,000-account capacity becomes useful infrastructure instead of a future surprise.