Month: August 2026

  • AI Search Crawlability: A Technical SEO Audit Framework

    AI Search Crawlability: A Technical SEO Audit Framework

    Your pages can perform well in Google and still be effectively missing from AI-generated answers. The problem is often not the writing. An AI crawler may be blocked, unable to discover links, or receiving an HTML shell that omits the content and structured data people see in a browser.

    You can diagnose that problem without guessing about prompts or rewriting every page. Audit the route from robots.txt to the raw server response, then fix the first point where a retrieval bot loses access, discovery, or meaning.

    Key takeaways

    • Audit the initial HTML response, not just the rendered page in your browser. Critical links, text, headings, metadata, and JSON-LD should be present before JavaScript runs.
    • Treat training crawlers, search or retrieval crawlers, and user-initiated browsing agents as separate policy decisions in robots.txt.
    • Use server-side rendering, static generation, or a hybrid approach for anything an AI system must discover, understand, or cite.
    • Use server logs to distinguish a crawlability failure from a selection failure. A page that was never requested has a different problem from a page that was fetched but not cited.

    Crawlability has three gates, and robots.txt is only the first

    A useful AI crawlability audit separates access, discovery, and extraction. Combining them into one pass-or-fail score hides the actual repair.

    GateWhat to testTypical failure
    AccessDoes your robots policy permit the intended agent, and can it receive a usable response?The agent is disallowed, challenged, rate-limited, redirected incorrectly, or served an error.
    DiscoveryCan the agent find the URL through links that exist in the initial HTML?It reaches a hub page but cannot see JavaScript-injected links to child pages.
    ExtractionDoes the response contain the main text, headings, factual details, metadata, and structured data?The URL loads, but the response is an application shell whose useful content appears only after JavaScript runs.

    Passing one gate proves nothing about the next. An Allow rule cannot make a client-rendered product description appear in the response. An XML sitemap may expose a URL, but it cannot supply missing text or JSON-LD. A browser screenshot can show a complete page even when the crawler receives almost nothing.

    Do not use Google rendering as a proxy for every other system. The crawler ecosystem includes agents with different jobs and different rendering behavior. A successful Google inspection therefore does not establish that an AI retrieval crawler can follow the same path or extract the same facts.

    Set crawler access by purpose, not by the letters AI

    AI platforms can operate more than one agent. One may crawl broadly for model training, another may retrieve information for search, and another may visit a URL in response to a user’s request. Blocking or allowing the entire family with an inherited rule can produce the opposite of your intended policy.

    • Training-oriented access: Decide whether broad reuse of your content fits your publishing, licensing, and compliance policy. ClaudeBot is an example of a crawler identified for training.
    • Search and retrieval access: If you want pages to be available for AI answers, inspect rules affecting agents such as Claude-SearchBot and OAI-SearchBot separately from training crawlers.
    • User-initiated browsing: Agents such as Claude-User and ChatGPT-User may fetch a page when a person asks an assistant to visit or use it. Treat that behavior as its own access decision.

    The names matter because a blanket policy is not a strategy. A publisher may reasonably block training while allowing retrieval. A regulated organization may choose a narrower policy. The technical requirement is that robots.txt express the decision you actually made rather than a rule inherited from an old template, security product, or previous agency.

    1. Write down the intended outcome for training, retrieval, and user-initiated access before editing robots.txt.
    2. Map every relevant user agent to one of those outcomes. Do not assume agents owned by the same company serve the same function.
    3. Review specific user-agent groups as well as broad wildcard rules. Look for inherited blocks that catch retrieval agents unintentionally.
    4. Test the resulting policy with the exact user-agent names, then fetch representative URLs to confirm that permitted agents receive normal responses.
    5. Record who owns the policy and why. Otherwise, a future security or infrastructure change can silently reverse it.

    Robots permission is necessary only when you want that agent to enter. It is not evidence that the agent can navigate the site or understand the response. Continue the audit even after the policy passes.

    Put the discovery path and critical facts in the initial HTML
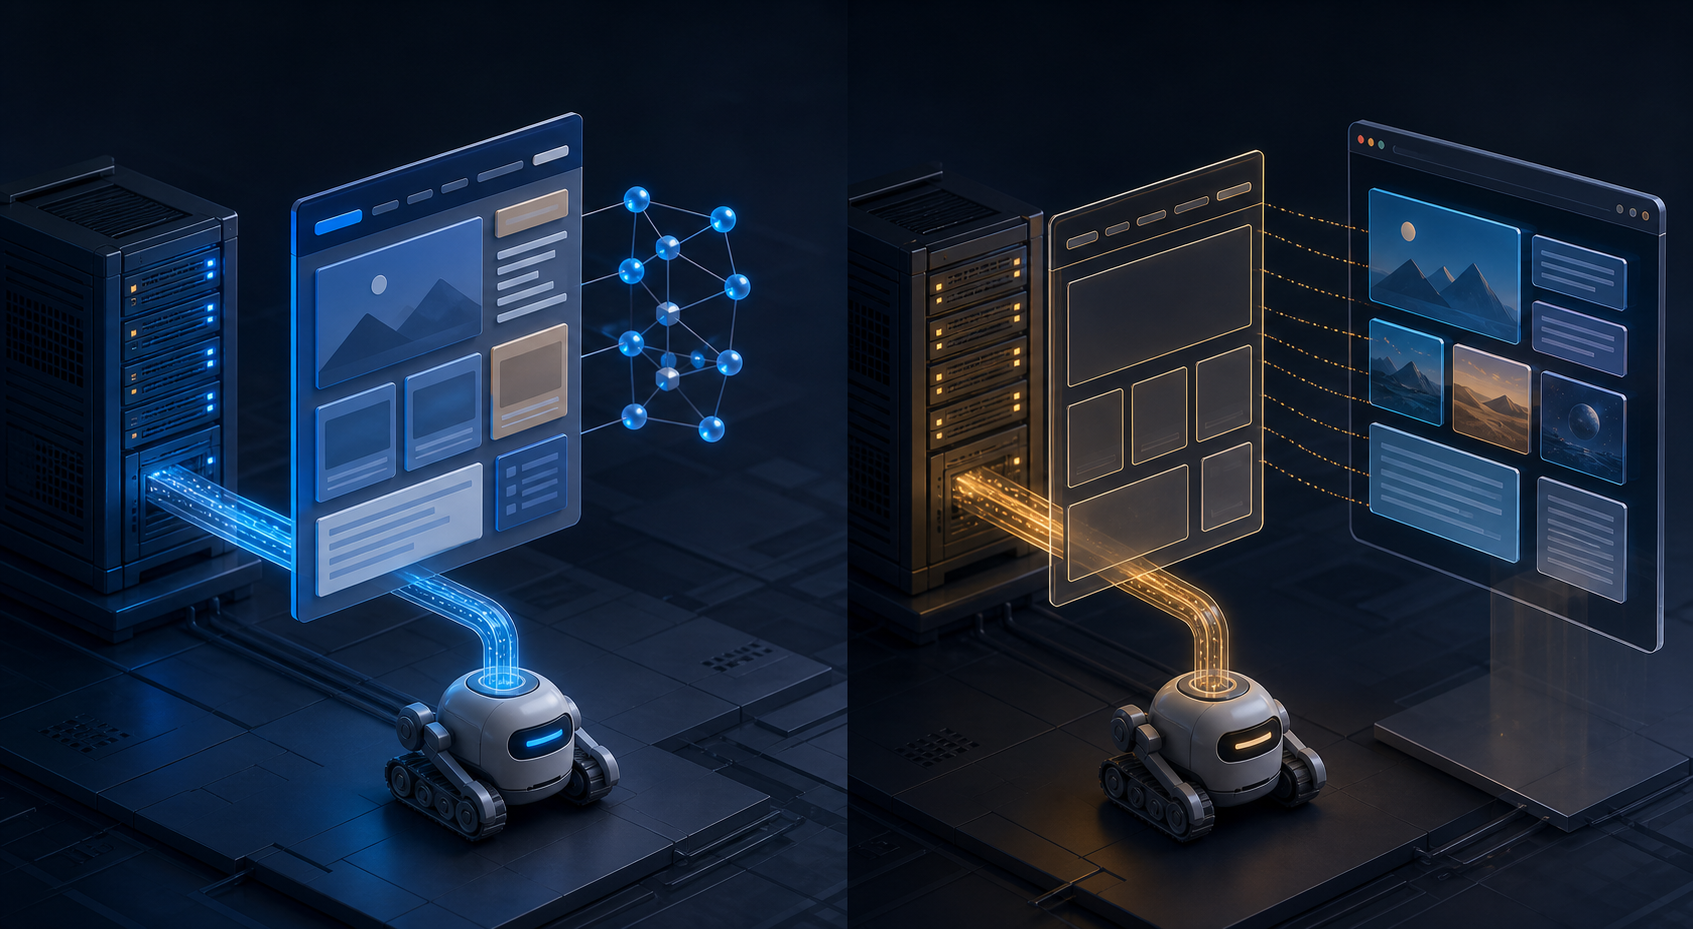
    Two server-response paths show a crawler receiving a complete structured page on one side and an empty page shell on the other.

    Client-side rendering creates the largest practical gap between what a person sees and what many AI crawlers receive. If the server sends an empty container and JavaScript later inserts navigation, body copy, product details, or schema, a crawler that does not execute that script encounters an incomplete page.

    The risk is especially clear in internal navigation. During the first 27 days of a 41-day controlled crawl experiment, GPTBot and ClaudeBot each reached all 748 hierarchy pages exposed through hard-coded HTML and none of the hierarchy pages available only through JavaScript-injected links. Googlebot reached seven of 293 pages in the JavaScript group, or 2%, and 35 of 748 in the HTML group, or 5%.

    Those percentages are not universal crawl-rate benchmarks. The experiment intentionally removed sitemaps, breadcrumbs, and other alternative discovery paths so that reaching a JavaScript-only child would demonstrate script execution. What it establishes is the mechanism: when the only route to a page is a link inserted after load, major AI crawlers may stop at the parent.

    Different crawlers from the same organization are not interchangeable either. GoogleOther rendered enough JavaScript to reach 142 of the 293 JavaScript-group pages in that experiment, while Googlebot reached seven. Activity from a secondary agent does not prove that the crawler responsible for a particular search or retrieval function saw the same pages.

    For every page you want an AI system to use, place these elements in the server-delivered response:

    • Followable internal links: Category, topic, breadcrumb, related-content, pagination, and other important paths should use links with destinations present in the raw HTML. Keep XML sitemaps as an additional discovery route, not as a repair for invisible navigation.
    • The primary answer: The page’s main text, headings, definitions, specifications, and other decision-critical facts should not depend on a client-side API call.
    • Entity details: Names, authors, dates, prices, product attributes, and relationships should appear clearly where they are relevant to the page.
    • Critical metadata: Do not rely on JavaScript to add information that a crawler needs to classify or interpret the page.
    • Structured data: Put the applicable schema markup, including JSON-LD, in the initial HTML rather than injecting it after the application mounts.

    Server-delivered structured data gives a no-JavaScript crawler explicit entity and relationship signals. It can reduce ambiguity around facts such as names, dates, authors, prices, and product attributes. It should describe information that is also supported by the page, not act as a hidden substitute for missing visible content.

    You do not have to remove JavaScript from the site. Use static site generation for content that can be built in advance, server-side rendering for pages whose critical response must be assembled dynamically, or a hybrid model that renders essential content and navigation on the server while leaving filters, interactions, and enhancements to the client.

    The implementation label is less important than the response. A framework can claim SSR while a particular component still fetches its text, links, or schema in the browser. Verify the actual HTML returned for the actual template.

    Run an audit that ends in a template-level fix
    Multiple page tiles pass through a diagnostic system and become complete after a central website template component is repaired.

    Start with representative paths rather than a random list of URLs. Include a top-level hub, a child page, a deep page that depends on several internal clicks, and each commercially or editorially important template. The relationship between those pages is part of the test.

    1. Fetch the raw response without executing JavaScript. Save the response body and relevant headers. In a browser, View Source is more useful for this check than the Elements panel, which normally reflects the post-JavaScript document.
    2. Confirm basic access. Check the response status, redirect destination, robots rules, and any challenge or interstitial delivered to the chosen agent. A visually normal page in your own session does not prove that an unauthenticated crawler receives it.
    3. Search the response for the primary information. Verify that the title, main heading, answer text, defining facts, authorship, dates, product information, and other page-specific content are present as text rather than empty component placeholders.
    4. Trace the internal path. Starting at the hub, inspect the raw HTML for links to the next level. Repeat until you reach the deep sample. If the path disappears before JavaScript runs, you have found a discovery boundary.
    5. Inspect JSON-LD in the response. Confirm that the intended schema type, entity properties, and relationships are present server-side and agree with the information a reader can see.
    6. Compare raw and rendered output. Any critical element that exists only in the rendered document is a client-side dependency. Classify it as discovery, content, metadata, or structured data so the development request names the actual failure.
    7. Review server logs. Group requests by user agent, path, response status, and time. Look for agents that reach hubs but consistently stop before child pages. Do not trust a user-agent string alone when identity matters; the controlled crawler experiment verified Googlebot and Bingbot through reverse DNS to exclude spoofed traffic.
    8. Repair the shared template and retest the path. A server-rendering fix to a hub, navigation component, or JSON-LD component can restore access across many URLs. Confirm the new response before treating deployment as completion.

    Interpret the failure pattern before changing content

    • The agent never requests the URL: Check robots access and discovery first. The absence of a request is not evidence that the copy needs optimization.
    • The agent requests hubs but not their children: Inspect the parent response for missing links. A repeated stop at the same directory level is a strong JavaScript-boundary signal when the child links are absent from raw HTML.
    • The agent requests the page but receives a thin shell: Move the critical content and facts into SSR, SSG, or hybrid output. Changing schema alone will not supply the missing body content.
    • The text is present but JSON-LD appears only after rendering: change how the markup is delivered. Server-render it and verify it in the response body.
    • Training is allowed while retrieval is blocked: revisit the robots policy if AI search visibility is the goal. The configuration does not match that objective.
    • The page is fetched with complete HTML but is not cited: crawlability has probably passed for that request. Retrieval, relevance, factual clarity, and citation selection are separate stages, so do not keep treating every absence as a rendering bug.

    Begin with one high-value hub and its deepest important child. Make sure an intended retrieval agent can access both URLs and that the raw responses contain the links, main content, factual details, and JSON-LD needed to interpret them. Once that path passes, apply the repair at the template level and verify the result in your logs before commissioning another round of content rewrites.

    References


  • ChatGPT Search Citation Volatility: What to Do After a Drop

    ChatGPT Search Citation Volatility: What to Do After a Drop

    You open your AI visibility dashboard and find that your site has abruptly lost ChatGPT Search citations. The tempting response is to rewrite pages, change schema, or assume a competitor has displaced you. Don’t touch the content yet.

    A citation drop establishes that the observed outputs changed. It doesn’t establish why they changed, whether the movement is unique to your site, or whether it cost you meaningful traffic. You need to separate a platform event from a measurement problem and a genuine site-level loss before choosing a response.

    An 86.4% citation drop can happen without a proven site cause

    Reddit offers a useful example of how abruptly ChatGPT Search citation patterns can move. Its share of citations averaged 3.83% from July 18 through August 7, fell below 1% on August 14, and then averaged 0.52% through August 17. That amounted to an 86.4% decline in four days.

    The movement didn’t look like a conventional, gradual loss of individual rankings. An earlier decline began on August 8, when ChatGPT Search also changed its query fan-out behavior, taking Reddit from the high-3% range into the mid-2% range. A larger decline followed six days later. Query fan-out is the process through which an AI search system turns a user’s prompt into additional searches or retrieval tasks. If that process changes, the system can encounter a different pool of pages even when none of those pages has changed.

    The timing is evidence of coincidence, not causation. The available data identifies when the change appeared but doesn’t explain why Reddit was selected less often. It also couldn’t rule out a data-collection issue. That uncertainty matters: a large chart movement can reflect source selection, retrieval behavior, prompt composition, interface behavior, or the monitoring layer itself.

    The cross-platform pattern gives you another diagnostic clue. Google AI Overviews did not show a comparable one-day collapse. Reddit’s citation share there moved gradually from about 2.5% in early July to roughly 2.1% in August, while Google AI Mode showed a similarly modest decline beginning near the end of July. A sudden loss isolated to ChatGPT therefore deserves a platform-level investigation before a content-level diagnosis.

    Citation share is not the same as citations, rankings, or traffic

    Four separate illuminated channels show different signal patterns while an investigator compares them in a research workspace.

    The first diagnostic step is to identify exactly what fell. Citation share is a relative metric: citations attributed to a domain divided by the captured citation pool. Your share can decline because your domain received fewer citations, because other domains received more, or because both changed at once.

    The Reddit figures measured its share among responses that contained at least one citation. They did not explain the systems behind source selection, and the underlying collection covered millions of responses gathered from live AI interfaces. That denominator is important. Responses without citations were outside the share calculation, and citation share alone says nothing about whether a user clicked a cited link.

    SignalQuestion it answersWhat it cannot prove by itself
    Citation-bearing response rateHow often the monitored prompts produced at least one citationWhether your domain became more or less authoritative
    Domain citation countHow many captured citations pointed to your domainWhether your share changed relative to every other cited domain
    Domain citation shareWhat portion of the captured citation pool belonged to your domainWhether the absolute number of citations or visits fell
    Cited URL mixWhich pages, sections, or content types ChatGPT selectedWhether users clicked or converted
    AI referral trafficHow many attributable visits reached your site from AI interfacesHow often your brand informed an answer without producing a click

    Treat those signals as related but distinct. If citation share falls while your absolute citation count remains stable, the citation pool probably expanded around you. If citations fall but referral sessions remain steady, the visibility movement may not yet justify a content intervention. If citations, referral traffic, and conversions fall together within the same prompt cluster, you have a stronger reason to investigate the affected pages.

    Run a no-regrets diagnostic before changing content

    A forensic analyst inspects separate platform, measurement, and website layers in a transparent system model.

    A useful diagnosis preserves the original observation and narrows the scope of the event. Work through these checks in order:

    1. Save the first snapshot. Preserve the prompts, answer text, citation URLs, timestamps, interface, and monitoring configuration. Don’t overwrite the evidence by immediately rerunning the same prompts and keeping only the new result.
    2. Validate the collection layer. Confirm that cited links still render in the interface and that your monitoring tool is extracting them correctly. Check whether the tool changed its parser, prompt set, account, location, language, or treatment of responses without citations.
    3. Inspect the numerator and denominator. Compare your domain’s citation count with the total captured citations. A falling share with a stable numerator is a different event from the disappearance of your domain’s links.
    4. Rerun a fixed prompt panel. Use the same wording and settings as the baseline. A changing prompt inventory can create an apparent visibility trend by changing what you ask, not how ChatGPT answers.
    5. Compare platforms. Check whether the same domain, pages, and query themes changed in Google AI Overviews, Google AI Mode, or other AI search surfaces you already monitor. A ChatGPT-only break points toward a platform-specific event; synchronized losses make a site, content, or broader demand issue more plausible.
    6. Segment the loss. Break results down by branded versus non-branded prompts, intent, topic, page type, and cited URL. A domain-wide collapse requires a different investigation from the loss of one product category or one outdated page.
    7. Connect visibility to business impact. Review attributable AI referral sessions, engaged visits, leads, sales, or another outcome appropriate to the site. Citation monitoring tells you about answer visibility; analytics tells you whether the observed change affected the business.

    This sequence gives you three possible classifications. A collection event appears when the visible answers and your site’s analytics remain stable but extraction changes. A platform event appears across many domains or prompt groups on one AI surface. A site event remains concentrated around your domain, pages, or topics after the collection layer has been cleared.

    Only the third classification should send you directly into page-level work. Check whether the affected URLs still return the intended status, remain crawlable, use coherent canonicals, expose their main information in readable text, and accurately answer the prompts they previously supported. Review material changes to the pages and their internal links. These checks can reveal a concrete defect; they are more informative than adding markup at random.

    Build monitoring that can distinguish noise from a real loss

    A dashboard becomes decision-grade only when it records enough context to reproduce a change. For every monitored response, retain the prompt ID, exact prompt text, run time, platform or interface, language and location where relevant, answer text, citation URLs, cited domains, and whether the response contained any citation. Keep the raw observation alongside calculated shares.

    Use two prompt collections. Your fixed panel should remain stable so that you can compare like with like. A separate discovery panel can expand as customers, products, and search behavior change. Mixing both panels into one trend line makes it difficult to tell whether the platform changed or your measurement scope did.

    Track ordinary variation before setting an alert. The useful threshold is not an arbitrary percentage copied from another site; it is movement outside the normal range of your own stable prompt panel. Require the signal to repeat under the same collection conditions, and attach scope to the alert: one URL, one prompt cluster, the whole domain, or the whole platform.

    Keep an annotation log for content updates, migrations, robots changes, canonical changes, structured-data releases, prompt-set edits, monitoring-tool releases, and known interface changes. An annotation does not prove that an event caused the movement. It gives you a testable lead and prevents the team from inventing explanations after the fact.

    Monitor concentration as well as total visibility. If much of your AI presence depends on one platform, one page, one community, or one narrow prompt family, a source-selection change can erase a large share of the observed footprint at once. Diversify the pages and topic clusters that genuinely deserve citation, but don’t manufacture near-duplicate pages merely to increase the URL count.

    When to watch

    Wait for confirming observations when the drop is broad across many domains, isolated to ChatGPT, unsupported by a traffic change, or accompanied by uncertainty in the collection layer. Continue capturing data. Editing during a platform shock removes your clean baseline and may leave you unable to tell whether the platform recovered on its own.

    When to investigate

    Start a technical and editorial review when the same pages repeatedly lose citations under a stable prompt panel, especially if related platforms or referral metrics move in the same direction. Look for a shared property among the affected URLs: outdated claims, weak alignment with the prompt, inaccessible primary content, ambiguous entity naming, inconsistent canonicals, or a recent template change.

    When to change the page

    Edit when you can name the defect the edit is intended to fix. Improve an incomplete answer, correct stale information, clarify the entity or relationship, expose supporting evidence, repair crawl access, or resolve conflicting page signals. Structured data can make content relationships clearer, but schema is not a contract that forces ChatGPT to retrieve or cite a URL. A citation chart alone is not a sufficient reason to deploy more markup.

    Key takeaways

    • A sharp ChatGPT Search citation loss can be a platform-wide selection change, a measurement issue, or a site problem; the chart alone cannot distinguish them.
    • Always compare citation share with the absolute citation count and the total captured citation pool.
    • Preserve raw responses and rerun a fixed prompt panel before changing pages.
    • Use other AI surfaces as comparators. A ChatGPT-only break deserves a platform-level hypothesis before a content-level diagnosis.
    • Connect citations to referral traffic and business outcomes. Visibility movement without measurable impact may warrant monitoring rather than intervention.
    • Change content only when repeated, segmented evidence points to a specific page, technical condition, or editorial defect.

    Set up the fixed prompt panel, raw-response archive, denominator tracking, and change log before the next fluctuation appears. Then a falling line becomes a diagnosable event instead of an instruction to rewrite whatever happened to be cited last week.

    References


  • AI Slop Detection: Prove Quality With Content Provenance

    AI Slop Detection: Prove Quality With Content Provenance

    You ran a page through an AI detector. It returned a high probability of machine-generated text. Now you have to decide whether to rewrite the page, remove it, disclose AI use, or ignore the score.

    Do not make that decision from the score alone. AI detection, slop detection, content quality, and provenance answer different questions. Treating them as interchangeable can make you discard useful work, preserve polished nonsense, or spend hours rewriting text without improving what readers receive.

    Stop asking one detector to answer four different questions

    The first step is to separate four concepts that are often collapsed into one label:

    • AI detection estimates whether a model may have generated or transformed text. It does not determine whether the text is accurate, useful, original, or fit to publish.
    • Watermark detection looks for a signal deliberately introduced during generation. A positive result indicates that a participating system likely touched the output. It does not reveal how much was generated, what was edited, or whether a qualified person approved it.
    • Slop detection is an attempt to identify low-value, repetitive, manipulative, or mass-produced material. Slop is an outcome, not an authorship category. Humans produced commodity content long before generative AI existed.
    • Content provenance is the evidence trail behind a published asset: where its claims came from, who created and changed it, what automation did, how it was checked, and who accepted responsibility for publication.

    These distinctions matter because the signals are imperfect. Text-watermark detectors generally need enough material to observe a pattern. Published benchmarks put the workable floor at roughly 100 tokens in favorable conditions, while SynthID evaluations truncate samples to 200 tokens. Short comments, titles, summaries, and rewritten excerpts may fall below that floor.

    Editing creates another limitation. Paraphrasing, translation, model chaining, and combining marked output with other text can weaken or remove a watermark. A paraphrasing attack presented at ICML 2025 achieved nearly 100% success against seven watermarking methods at a reported cost of $0.88 per million tokens. Open-weight models add a more fundamental gap: watermarking is applied by the sampling pipeline, so someone running a model independently can omit that step.

    This produces two dangerous errors. A false positive can send a strong page into unnecessary rewrites. A false negative can give weak or fabricated material an undeserved pass. Even a system reported at 94% accuracy can make consequential mistakes when it operates across enormous volumes, especially when you do not know the evaluation set, class balance, or error distribution.

    Use detection as a routing signal. A high score can send a page to closer editorial review, but it should never be the reason the page fails. Make the final decision with four questions: Is the page accurate? Does it contribute something distinct? Can its important claims be traced? Is a named person accountable for it?

    Distribution systems are reacting to low-value supply

    Generative tools have made production cheap. They have not made attention abundant. When thousands of interchangeable assets can be produced in the time previously required for one, distribution systems become stricter selectors.

    Platforms are responding at several points in that supply chain:

    The implementations differ, but the operational lesson is consistent: publishing more units does not guarantee more distribution. A system may label an asset, suppress it, remove its monetization, filter it from recommendations, or delete it as spam. The marginal cost of production may approach zero while the cost of selection keeps rising.

    None of this proves that search engines or frontier models apply a universal penalty to anything touched by AI. It shows that platforms increasingly act against repetition, manipulation, undisclosed synthetic media, and low-value supply. Do not turn that observation into an imaginary ranking factor. Turn it into a stricter publishing standard.

    A page deserves publication when it performs a specific job that another page on your site does not already perform. It should resolve the promised question, support material claims, make uncertainty visible, and give the reader a usable next step. If you cannot name its distinct contribution in one sentence, producing another variation will increase inventory without increasing value.

    Run a slop audit that measures usefulness, not writing style

    An editor reviews an unmarked digital page beside source documents, a balance scale, a toolbox, and a tray of duplicate sheets.

    Most detector-led cleanups begin at the wrong end. Teams scan thousands of URLs, sort by an AI probability, and rewrite whatever appears most synthetic. That process optimizes the detector’s reaction. It does not tell you whether the revised page deserves attention.

    Use the following audit instead.

    1. Write down the page’s job. Record the intended reader, the question or decision that brought them there, and the action they should be able to take afterward. If the job is unclear, the page cannot be evaluated coherently.
    2. Identify the distinct contribution. Look for an original observation, a precise definition, a decision rule, a useful constraint, a first-party example, a sourced fact, or a synthesis that removes work for the reader. A topic is not a contribution. Neither is a fresh arrangement of familiar sentences.
    3. Check every consequential claim. Mark statistics, dates, product behavior, legal obligations, quotations, named entities, and strong causal statements. Each one needs an appropriate basis. If the evidence cannot be recovered, soften the claim, replace it, or remove it.
    4. Inspect the page as part of a collection. Compare it with assets targeting adjacent intents. Repeated introductions, interchangeable sections, overlapping target queries, and multiple pages with no independent purpose are stronger slop indicators than a model’s preferred punctuation.
    5. Assign an accountable owner. A byline is not enough if no one checked the substance. Record who drafted, edited, verified, and approved the page. One person may fill several roles, but responsibility should still be explicit.
    6. Choose a disposition. Keep, improve, consolidate, or withdraw the page based on reader value and evidence. Do not add a fifth category called rewrite until the detector turns green.

    Your audit sheet only needs a small set of fields: URL, intended query or task, audience, distinct contribution, consequential claims, evidence status, overlap, owner, reviewer, last substantive update, and disposition. Add the detector result in a separate field if you use one. Keeping it separate prevents the score from masquerading as an editorial verdict.

    Apply the dispositions consistently:

    • Keep a page when it is accurate, distinct, appropriately supported, and still fulfills its intended job. An AI flag alone is not a reason to disturb it.
    • Improve a page when it has a useful core but withholds the information needed to act. Replace generic explanation with evidence, constraints, examples, decision criteria, or a clearer sequence.
    • Consolidate pages that repeat the same answer without serving meaningfully different intents. Preserve the strongest material, select one primary destination, and map the old URLs deliberately rather than creating another near-duplicate.
    • Withdraw material that is wrong, untraceable, misleading, or functionally empty. Preserve a recoverable copy before a bulk removal and assess redirects, inbound links, and downstream references so cleanup does not create avoidable breakage.

    The fastest diagnostic is subtraction. Remove the throat-clearing, generic benefits, predictable transition paragraphs, and unsourced superlatives. If nothing meaningful remains, the problem is not that the text sounds like AI. The problem is that the asset has no information payload.

    When something useful does remain, edit around that value. Put the direct answer near the top. Attach evidence to the claim it supports. State who the advice is for, where it stops applying, and what could change the decision. This improves the page for readers, search systems, and answer engines without trying to reverse-engineer a detector.

    Build provenance into publishing instead of adding it later

    A connected publishing workflow links research, review, version checkpoints, and a finished page with a continuous provenance chain.

    Provenance is strongest when it is captured during creation. Reconstructing it months later usually produces a folder of broken links, missing approvals, and vague memories about what the model did.

    Keep a private production record

    Create one record for each publishable asset. It can live in your content system, project tracker, or repository, but it should stay connected to a stable content ID or canonical URL.

    • Purpose: the audience, target task, search intent, and expected reader outcome.
    • People: the drafter, subject reviewer, editor, fact checker where applicable, and final approver.
    • Evidence: the sources used for consequential claims, access dates where they matter, first-party data inputs, and any unresolved uncertainty.
    • AI role: whether a model was used for ideation, outlining, drafting, transformation, extraction, classification, proofreading, or another defined task.
    • Verification: what a human checked, which claims were changed, and what could not be independently confirmed.
    • Version history: the published version, substantive updates, correction reasons, and approval status.

    Record the model’s role at a useful level of detail. AI-assisted proofreading and unsupervised generation of product specifications present different risks. A single yes-or-no field hides that difference. At the same time, do not retain raw prompts or uploaded material indiscriminately. They may contain confidential information, personal data, unpublished strategy, or licensed text. Apply the same access and retention controls you would use for other production records.

    A watermark can complement this record, but it cannot replace it. Anthropic announced machine-readable watermarks for Claude text and file output across its model access routes. Article 50 of the EU AI Act is a major reason model providers are moving toward machine-readable marking. That obligation concerns providers of generative systems; it does not make a marketer’s detector result a legal finding. If your organization provides or deploys a covered system in the EU, have qualified counsel assess the actual duty instead of relying on a content-scoring tool.

    Publish the evidence a reader can use

    Your private record establishes accountability. The public page should expose the parts that help a reader evaluate it:

    • A real byline connected to a useful author profile, not an unexplained house persona.
    • An accurate publication date and a modified date when the substance changes.
    • A concise change note when an update corrects, replaces, or materially qualifies earlier information.
    • Inline citations placed beside the claims they support.
    • A methodology note for first-party tests, calculations, surveys, or datasets.
    • An AI-use disclosure when the role of automation is material to interpretation, trust, rights, or platform policy.

    Disclosure and provenance are not synonyms. A sentence saying that AI was used is disclosure. The chain showing what it did, which evidence informed the result, who reviewed it, and what changed is provenance. You may need both, but one cannot stand in for the other.

    Structured data should mirror that visible evidence. On an Article or BlogPosting page, properties such as author, publisher, datePublished, and dateModified can make the stated identity and timing easier for machines to parse. They do not authenticate a weak byline, prove that a review happened, or turn an invented citation into evidence. Do not place claims in JSON-LD that the visible page does not support, and do not invent non-standard properties for internal provenance fields.

    This is where provenance supports AI search without becoming schema theater. A frontier model or answer engine still needs a reason to select the page. Give it compact, attributable claim-and-evidence pairs; stable names for people, organizations, products, and concepts; a direct answer before elaboration; and a visible record of substantive updates. Consolidate interchangeable pages so the strongest evidence is not scattered across thin variants.

    Provenance cannot guarantee rankings, citations, or inclusion in an AI-generated answer. It makes a more defensible asset available for selection. That is the useful goal: not proving that no machine ever touched the words, but showing why the result deserves to be trusted and distributed.

    Key takeaways

    • An AI score estimates origin patterns; it does not measure truth, usefulness, originality, or accountability.
    • Watermarks can indicate that a participating model touched enough text, but editing, paraphrasing, translation, short samples, and unmarked open-weight pipelines limit what they can prove.
    • Use detectors to prioritize human review, never as automatic publish-or-delete gates.
    • Audit each page for a defined reader job, a distinct contribution, traceable claims, collection-level overlap, and a named owner.
    • Capture sources, AI involvement, verification, approvals, and substantive changes while the asset is being produced.
    • Keep visible content and JSON-LD consistent. Structured data exposes claims to machines; it does not create provenance by itself.

    Start with five pages that matter to your business. Write down each page’s job, identify its unique contribution, trace its consequential claims, and assign an owner. You will learn more from that exercise than from rescoring your entire site, and you will have the beginnings of a provenance system that can survive the next detector, watermark, and distribution-policy change.
    References


  • YouTube Citation Analytics: A Practical Measurement System

    YouTube Citation Analytics: A Practical Measurement System

    You can find a YouTube link in an AI answer and still have no idea whether it matters. A single citation may be incidental. The same video recurring across a controlled set of relevant prompts is a pattern worth investigating.

    If you need to decide what to produce, refresh, or defend, the useful unit is not an isolated link. It is a citation event with enough context to compare. Here is how to build that record, calculate defensible metrics, and turn the result into an editorial decision without pretending correlation proves why an AI system selected a video.

    Decide what counts before you count citations

    Start by defining a YouTube citation event. A practical definition is one valid AI response linking to one identifiable YouTube video. Keep the definition in your measurement documentation so that everyone collecting or reviewing the data follows the same rules.

    Use these counting rules unless your reporting question requires something different:

    • If one response links to one video, record one citation event.
    • If the same video appears in separate prompt runs, record a citation event for each run while retaining one canonical video identity.
    • If one response repeats the same destination, count it once unless you are specifically studying link placement.
    • If one response cites several videos, create one event row for each identifiable video.
    • If a URL cannot be resolved confidently to a video, mark it unresolved. Do not guess which video it represents.
    • If a brand or channel is mentioned without a YouTube link, keep it out of the citation count. Mentions and citations answer different questions.

    This distinction prevents three common reporting errors. You will not mistake repeated collection for wider video coverage, count an unlinked brand mention as citation visibility, or collapse several cited videos into a single response-level observation.

    The denominator matters just as much as the event. Exclude failed, blank, or otherwise invalid prompt runs from rate calculations, but retain them with a status label so an unexpectedly high failure rate does not disappear from the audit trail. A raw citation total has little meaning if one period contains more valid prompt runs than another.

    A cited URL becomes much more useful when it carries structured information about the channel, video, and video category. Those dimensions let you move beyond finding links and ask which creators, assets, and subject areas occupy the answer space.

    Build the smallest dataset that preserves context

    Organized research bundles pair question, answer, link, video, time, and source symbols to preserve the context of each citation event.

    Use an event table in which each row represents one citation event. Do not begin with a channel leaderboard. Aggregation is easy once the event-level evidence exists; reconstructing the original prompt, response, or URL after aggregation is usually difficult.

    FieldWhy you need itCollection rule
    Observation IDGives every event a traceable identityAssign a unique value to every citation row
    Prompt ID and versionSeparates a stable test from a rewritten promptNever overwrite the previous wording; create a new version
    Query cluster or intentLets you compare citations serving the same user needUse a controlled internal taxonomy rather than ad hoc labels
    Platform and model labelPrevents unlike answer environments from being blendedRecord the labels exposed by the interface or workflow
    Run timestampSupports period comparisons and change trackingStore the collection time for every run
    Market and languageKeeps regional or linguistic tests separateRecord the configured context, including unknown when necessary
    Raw response evidenceAllows a reviewer to verify the citation in contextRetain the response text or an evidence reference permitted by your workflow
    Raw citation URLPreserves exactly what the answer returnedNever replace it with the normalized value
    Canonical video keyGroups alternate URL forms that resolve to the same assetCreate only after the destination is resolved confidently
    Video, channel, and categoryEnables asset-, creator-, and category-level analysisStore the structured values and flag missing fields
    Ownership classSeparates owned, competitor, partner, and independent visibilityMaintain the classification as your own editorial dimension
    Resolution statusStops malformed or ambiguous records from contaminating metricsUse explicit states such as resolved, unresolved, excluded, or failed

    Keep the raw URL and canonical identity side by side. Tracking parameters and alternate URL forms can make one destination look like several records. Removing the raw value destroys evidence; skipping normalization inflates unique-video counts. The safe sequence is to preserve the captured URL, resolve its destination, generate a canonical key, and document the normalization rule.

    A separate video table can hold one row per canonical video, including its channel, category, ownership class, and your editorial labels. The event table then records where and when that video was cited. This two-table structure avoids reclassifying hundreds of citation rows when an internal ownership or topic label changes.

    Do not let the video table erase historical context. Keep the value observed during collection when a field is important to an earlier report, or retain a change history. Current metadata and metadata observed during a previous run are not always the same analytical question.

    Choose metrics that lead to an editorial decision

    No single score represents YouTube citation visibility. Reach, recurrence, diversity, and ownership describe different conditions. Calculate the metric that matches the decision in front of you, and always show its numerator, denominator, filters, and collection window.

    Measure whether YouTube appears

    • YouTube citation coverage: valid prompt runs containing at least one resolved YouTube video citation divided by all valid prompt runs in the same slice. Use this to determine whether YouTube participates in the answer set at all.
    • Citation frequency: resolved YouTube citation events divided by valid prompt runs. This captures responses that cite more than one video, which coverage alone hides.
    • Unique-video breadth: the number of distinct canonical video identities found in a defined prompt set and period. Compare it with total citation events to see whether visibility is broad or concentrated.

    Coverage and frequency are not interchangeable. If one answer cites several videos, coverage records one qualifying response while frequency records each cited asset. Keep both when you need to distinguish how often video appears from how densely videos are cited.

    Measure who and what receives the citations

    • Channel share: resolved citation events attributed to a channel divided by all resolved YouTube citation events in the selected slice.
    • Category share: resolved events assigned to a video category divided by all resolved events with a category.
    • Owned citation share: events attributed to your owned channels divided by all resolved YouTube citation events.
    • Video recurrence: valid comparable runs citing a particular video divided by the valid runs in which its associated prompt or prompt cohort was tested.
    • Concentration: the share of citation events accounted for by a defined leading group of videos or channels. State how you selected that group rather than hiding the choice inside a dashboard.

    Channel share tells you who occupies the space, but it does not tell you why. Category share describes the mix you observed; it does not establish that changing a category will cause an AI system to cite a video. Treat both dimensions as diagnostic filters, not ranking levers.

    Separate detection from durability

    Generative answers can vary between runs. A practical internal vocabulary keeps that variability visible:

    • Detected: the video appeared in a valid run.
    • Recurring: the video appeared repeatedly within a comparable prompt cohort.
    • Durable: the recurrence persisted across comparable collection windows.

    These are status labels, not universal thresholds. Define your own recurrence requirement before examining the result, disclose the run count, and avoid promoting a detected video to a durable winner because it appeared once.

    Period comparisons are defensible only when the prompt set, prompt versions, platform scope, market, language, inclusion rules, and run design remain comparable. If one of those changes, segment the result or label the comparison as directional. Otherwise, a dashboard can report movement created by the test design rather than movement in citation visibility.

    Turn patterns into content decisions, not causal claims

    An analyst reviews recurring connections to video cards and sorts selected videos into production, refresh, and protection work areas.

    Citation analytics identifies where to investigate. It cannot, by itself, prove which title, category, transcript passage, production choice, or model behavior caused a citation. Use each pattern to form a hypothesis, inspect the underlying answers, and choose a proportionate action.

    When a competitor video recurs across a valuable prompt cluster

    Open the cited responses and identify the exact question the video appears to support. Then audit the video itself for scope, audience, specificity, structure, and the information it supplies. Compare those qualities with your nearest existing asset.

    Your decision is not automatically to make a similar-looking video. First determine whether you have an answer gap, a weak existing answer, or an asset that serves a different intent. Write a production brief around the unmet user need. The competitor citation gives you a discovery target, not a causal recipe.

    When one owned video keeps earning citations

    Treat recurrence as a reason to protect and audit the asset. Verify that its claims remain accurate, inspect the user questions for which it appears, and check any resources or destinations connected to it. Preserve the cited URL when possible.

    Do not delete a recurring cited video merely to consolidate your library. Removing it can make the cited destination unavailable and breaks continuity in your measurement history. If the information needs replacement, plan the successor and its relationship to the existing asset before making an irreversible change.

    When owned citations are broad but unstable

    Several owned videos appearing sporadically can mean you cover the subject without having one consistently selected asset. Segment the events by prompt intent before changing anything. You may find that different videos correctly serve different questions, in which case consolidation would erase useful specialization.

    If several videos genuinely compete for the same intent, decide which one should be canonical from an editorial perspective. Improve its completeness and clarity, define distinct jobs for the remaining assets, and record the change. Citation data can identify the overlap; a controlled follow-up test must determine whether your intervention corresponds with a more stable pattern.

    When a category dominates the cited set

    Use category concentration to understand the composition of the citation landscape and to find clusters worth reviewing. Then inspect the actual prompts and videos. A category can group unlike user needs, while a single user need can cross categories.

    Do not reclassify videos solely because another category has a higher citation share. The observed category is a descriptive dimension. Without a controlled test, the citation data does not show that category assignment caused selection.

    When citation visibility does not produce business results

    A citation is not a view, a site visit, a lead, or a sale. Keep citation visibility separate from audience and conversion reporting. Connect the datasets only through explicit, supportable identifiers and attribution rules.

    If owned citation share rises while downstream outcomes remain flat, inspect the journey after the citation instead of declaring the visibility useless. The cited video may answer the question without creating a next step, or the cited prompt cluster may sit outside the buying journey. That diagnosis requires behavioral data; citation counts alone cannot settle it.

    For each finding, choose one of four editorial actions:

    • Protect: maintain an accurate, recurring owned asset and preserve its URL.
    • Improve: strengthen an existing video that already matches the cited intent but has a clear content gap.
    • Create: commission a new video for a meaningful prompt cluster your library does not answer.
    • Stop: decline to produce video when the evidence is weak, the intent does not benefit from it, or another content format serves the user better.

    Log the hypothesis, chosen action, asset, date, and prompt cohort before making the change. Rerun the same valid cohort after the new or revised asset is publicly available, and repeat collection to see whether the pattern persists. A movement in one run is an observation, not proof of uplift.

    Key takeaways

    • Make one citation event the base unit, while keeping separate counts for responses, unique videos, channels, and prompt runs.
    • Preserve the raw URL and response evidence, then attach a canonical video identity plus channel and category details.
    • Use coverage for whether YouTube appears, recurrence for stability, channel share for competitive position, and breadth for asset diversity.
    • Compare periods only when prompt versions, platform scope, market, language, run design, and inclusion rules remain comparable.
    • Treat every pattern as a hypothesis. Citation analytics can direct an audit, but it does not prove why a video was selected.
    • End each analysis with a concrete choice: protect, improve, create, or stop.

    Start with one decision that matters to your next production cycle. Freeze the relevant prompt cohort, collect event-level records, normalize the cited URLs, and calculate coverage, recurrence, and channel share. When every aggregate can be traced back to the response that produced it, your YouTube citation dashboard becomes a decision system rather than a collage of interesting screenshots.

    References


  • Google August 2026 Spam Update: An SEO Response Plan

    Google August 2026 Spam Update: An SEO Response Plan

    If your organic visibility changed as the August rollout began, resist the urge to rewrite half the site. You need to answer two questions in order: which repeatable part of the site moved, and what separates those pages from comparable pages that held steady?

    The August 2026 spam update applies globally and to all languages, with a rollout expected to take a few days. That makes the opening phase a measurement problem. Broad edits made during the rollout can destroy the baseline you need to distinguish an update-related pattern from a technical fault, a tracking problem, or ordinary demand movement.

    Key takeaways

    • The August 2026 spam update has global and multilingual scope, but Google has not publicly identified a particular page type, industry, or tactic as its target.
    • Preserve a dated snapshot before making elective sitewide changes. Segment the data by page group, query type, country, device, language, and template.
    • A decline that overlaps the rollout is a correlation, not a diagnosis. Rule out indexing, tracking, server, redirect, canonical, and demand problems first.
    • Look for a shared weakness across affected pages rather than treating every losing URL as an unrelated problem.
    • Do not assume AI assistance, structured data, or a particular CMS caused the loss without evidence from affected and unaffected comparison groups.

    What the confirmed scope does and does not tell you

    This is the third announced Google spam update of 2026, following the June 2026 spam update. The short interval is a reason to keep a precise change log, especially if your site also moved during the earlier rollout. It is not evidence that the two updates assessed the same patterns.

    Global coverage means you should not automatically treat a different country or language version as an unaffected control group. It does not mean every market, query set, or directory will move by the same amount. Your own segmented data still has to show where the change occurred.

    The announcement also does not identify a specific target. A ranking loss cannot, by itself, establish that Google objected to AI-generated copy, affiliate pages, programmatic templates, links, structured data, or any other single feature. Starting with one of those conclusions encourages indiscriminate fixes and makes the eventual result harder to interpret.

    Nor is impact a moral verdict. Sites that are not deliberately manipulating search can still be affected during a spam update. Treat a decline as a signal to investigate the site’s observable patterns, not as proof that its owners or writers intended to spam.

    If your visibility remains stable, do not manufacture an emergency project. Save the baseline, confirm that important page groups held across relevant markets, and continue planned quality work. Stability now is useful evidence, but it is not a permanent exemption from future changes.

    Protect your baseline while the rollout is in motion

    Your first objective is to preserve evidence. Continue urgent security, accessibility, legal, and availability fixes, but defer elective mass publishing, template rewrites, redirect migrations, and sitewide internal-link experiments until you can separate their effects from the rollout.

    1. Annotate the rollout. Add it to your analytics calendar, SEO change log, and stakeholder report. Record the announced scope and expected multi-day rollout rather than reducing the event to a single timestamp.
    2. Export the pre-change view. Save daily clicks and impressions, queries, landing pages, countries, devices, and any language or search-feature dimensions relevant to the site. Keep the raw export as well as dashboard screenshots because dashboards and filters can change.
    3. Build page cohorts. Group URLs by directory, template, content purpose, topic, locale, authoring workflow, and commercial model. A sitewide total can hide a severe decline in one template behind growth elsewhere.
    4. Create a control group. Match affected pages with pages that serve a similar intent but remain stable. The comparison is more useful when the pages differ in a limited number of observable ways.
    5. Record other changes. Note deployments, CMS releases, consent-banner changes, analytics configuration, migrations, redirect rules, canonical changes, robots directives, noindex tags, server incidents, marketing campaigns, and known shifts in demand.
    6. Preserve the original pages. Keep a backup or version history before rewriting, consolidating, or removing anything. Without the earlier version, you may lose the evidence needed to test the diagnosis or reverse a harmful change.

    Do not rely on a single sitewide percentage or average position. Ask whether the movement is concentrated in a directory, template, query class, country, language, or device. The concentration often tells you more than the headline number.

    A useful working matrix has three columns: affected pages, matched pages that held, and the meaningful differences between them. If you cannot fill the third column with evidence, you do not yet have a remediation plan. You have a theory.

    Separate an update pattern from technical and demand problems

    A digital investigation scene shows webpage modules, a server rack with a loose cable, and audience silhouettes in three separate areas.

    Start at the highest level and narrow the problem. Determine whether search visibility changed, whether indexed pages disappeared, whether rankings moved while indexation held, and whether the effect belongs to a page group rather than the whole domain.

    What you observeCheck nextWhy it matters
    Clicks fall while impressions remain comparatively stableQuery mix, titles, snippets, device mix, and search-result presentationThis points first to click-through behavior rather than a simple loss of visibility.
    Clicks and impressions fall, but indexed URLs remain stableAffected queries, landing-page cohorts, positions, and replacement resultsThis is the stronger pattern for a ranking or demand investigation.
    Indexed URLs or discoverable pages disappearRobots rules, noindex directives, canonicals, redirects, server responses, rendering, and sitemap changesA technical indexing failure can resemble an algorithmic loss in a traffic chart.
    One directory or template declines while matched sections holdShared content, navigation, ownership, monetization, and production characteristicsThe boundary of the loss can reveal the pattern that needs remediation.
    Analytics falls across search and other channelsTracking, consent configuration, outages, campaigns, and demandA measurement or business-wide change should be ruled out before an SEO rebuild.

    Once technical and measurement alternatives have been checked, audit the common characteristics of the affected cohort. Use questions that can produce evidence:

    • Distinct value: If this page disappeared, what useful explanation, evidence, tool, comparison, or decision support would a searcher lose?
    • Template dependence: How much of the page is genuinely specific to its subject, and how much is repeated across location, product, category, or keyword variants?
    • Intent fit: Does the page answer the query it attracts, or mainly route the visitor toward another page, form, or offer?
    • Accuracy and accountability: Can an editor verify the important claims, identify where the information came from, and determine who is responsible for keeping it current?
    • Ownership: If third parties create or control a section, is it clearly relevant to the site’s audience and subject, and does the site apply meaningful editorial oversight?
    • Navigation and linking: Can users reach the page through coherent site navigation, or does it exist mainly inside a large search-targeted cluster with repetitive anchor text?
    • Visible-content consistency: Do the title, headings, body copy, links, structured data, and page purpose describe the same thing?
    • Production workflow: If automation or AI assisted with creation, did a responsible editor verify accuracy, remove unsupported claims, resolve duplication, and add information that serves the specific query?

    AI assistance is a workflow fact, not a diagnosis. Compare AI-assisted pages that declined with AI-assisted pages that held, and do the same for human-written pages. If authorship method is the only evidence you have, deleting an entire content library is an unsupported and potentially destructive response.

    Structured data needs the same discipline. JSON-LD can make page entities and relationships explicit, but it cannot supply missing usefulness or turn repetitive pages into distinct resources. Correct inaccurate markup when you find it. Do not strip valid markup merely because rankings changed at the same time as a spam update.

    Make the smallest defensible change, then measure it

    Two similar webpage models sit on a laboratory bench while an instrument adjusts one small module and the other remains covered.

    A good response connects one observed pattern to one repairable cause. Write the hypothesis before changing the site. For example: a particular directory declined while matched pages held, and the declining group contains substantially more repeated material with less subject-specific information. That statement can be tested. A claim that Google dislikes the site cannot.

    1. Define the affected cohort. List the page group, queries, markets, and devices where the change is visible. State what remained stable as well.
    2. Stop expanding the suspected pattern. Pause new pages that use the same workflow or template while you investigate. This limits exposure without destroying existing evidence.
    3. Match the repair to the failure. Correct inaccurate pages, consolidate pages that serve the same purpose, strengthen pages with a valid but under-served user need, and repair technical directives when indexation is the real issue.
    4. Handle removal carefully. Do not bulk-delete URLs from a volatile report. Back up the content, identify equivalent destinations, account for internal and external links, and decide whether consolidation, redirection, deindexing, or retirement fits each page’s purpose. Deletion without this mapping can erase evidence and break useful paths.
    5. Fix shared systems. If the weakness comes from a template, brief, generator, approval process, or publishing incentive, correcting individual pages will allow the same problem to return.
    6. Stage material changes. Begin with a representative, well-defined group when practical. Document exactly what changed so the outcome can confirm or weaken the hypothesis.
    7. Read the result against controls. Compare the changed cohort with matched pages that were not changed, using a stable measurement window after the rollout rather than reacting to each daily movement.

    Avoid cosmetic activity that creates the appearance of remediation without addressing the diagnosis. Changing publication dates, adding generic paragraphs, removing every mention of AI, or installing more schema does not solve a demonstrated problem unless the evidence points to stale information, inadequate coverage, an unreliable workflow, or inaccurate markup.

    Stakeholder reporting should distinguish four things: what Google confirmed, what your data shows, what remains unknown, and what you will test next. That format prevents a plausible hypothesis from turning into an asserted fact as it moves through meetings and dashboards.

    Your next move is modest: save the baseline, mark the rollout, and identify the smallest coherent group of affected pages. Once the rollout is complete and alternative causes have been checked, repair the shared weakness you can actually demonstrate. That gives you a response you can defend, measure, and reverse if the evidence changes.

    References


  • How to Optimize for AI-Driven Search and Shopping

    How to Optimize for AI-Driven Search and Shopping

    If you sell products or services online, a customer may reach your site after an AI system has already framed the problem, compared options, and narrowed the shortlist. Your visibility now depends on more than ranking a page. Your facts have to be selected, understood, and carried into the answer without losing the conditions that make them true.

    The practical job is to make each buying decision easy to answer and each next step worth taking. That means restructuring commercial content, instrumenting AI-origin visits, and treating citation visibility as volatile evidence rather than a permanent traffic channel.

    Shopping increasingly starts inside the conversation

    Profound, an AI visibility vendor, classified 7.5 million ChatGPT conversations over a year. In that proprietary sample, commercial intent rose from 13.9% to 19.2%, while users started 41% more commercial conversations than they had a year earlier. At ChatGPT’s then-current scale, Profound extrapolated the pattern to an estimated 28 billion buying conversations per year.

    Those figures should be read as one vendor’s classification and extrapolation, not a census of every ChatGPT interaction. They still identify a change you can plan for: product discovery, comparison, and objection handling can happen before a conventional search result earns a click.

    A conventional landing page often assumes that one query represents one stable intent. A conversational shopper behaves differently. They can name a need, add a constraint, reject the first recommendation, ask about price, and request an alternative without beginning a new search. A page built only to repeat a broad keyword may rank yet provide little usable evidence for that sequence.

    The opportunity is not evenly distributed. Commercial intent showed a tenfold spread between the highest- and lowest-intent industries in the same sample. Do not copy another industry’s AI shopping plan and assume its potential applies to you. Start by finding the decisions customers actually make in your category.

    Key takeaways

    • Optimize commercial content around decisions, constraints, and comparisons rather than isolated keywords.
    • Package each important fact with the qualifier that makes it accurate.
    • Give AI systems a complete answer to cite, then give the shopper a valuable reason to continue to your site.
    • Measure AI visibility as a changing portfolio of pages and answer blocks, not as a fixed share of organic traffic.

    Map the decision before you create more content

    Hands arrange pictogram tiles and colored threads into a branching customer decision journey on a tabletop.

    Begin with questions that could change what a customer chooses. A broad informational query may attract attention, but a question about compatibility, total cost, timing, limitations, or the difference between two options is closer to a decision. Those questions deserve the clearest pages and the most precise maintenance.

    Create a buying-decision inventory before commissioning another batch of generic articles:

    1. Collect the wording customers use in on-site search, organic queries, sales conversations, and support requests.
    2. Label the decision behind each question: eligibility, comparison, cost, risk, timing, selection, or purchase.
    3. List the facts required to answer it. Include the conditions and exclusions, not just the favorable attributes.
    4. Choose one canonical page or page section that owns the answer. Competing versions create maintenance problems and inconsistent evidence.
    5. Define the next useful action. It might be checking availability, selecting a compatible option, calculating an exact price, or opening a detailed comparison.

    The inventory should connect the shopper’s language to a concrete content block. This is a practical model you can adapt:

    Shopper’s questionContent block to provideFacts that must remain attachedUseful next step
    Will this work for my situation?Fit and limitations summarySupported uses, requirements, and exclusionsInspect the compatible option
    How does option A compare with option B?HTML comparison tableConsistent attributes, conditions, and tradeoffsOpen the relevant item detail
    What will it cost?Transparent pricing blockIncluded items, required fees, and variablesCalculate or confirm the exact price
    How long will it take?Timing answer with qualifiersLocation, route, service level, or other dependenciesCheck the applicable schedule
    Which option should I choose?Recommendation logicSelection criteria and disqualifying conditionsNarrow the available choices

    Format is part of the answer. In one transportation brand’s nine-month dataset, transfer-time and pricing content was cited frequently and showed upward momentum, while broader destination guides underperformed relative to their apparent potential. Structured transport comparisons formatted as actual HTML tables were cited disproportionately often.

    That does not prove that every site needs the same page types. It shows why decision structure matters. Times, prices, named routes, and consistently labeled comparisons give a system a bounded question and an identifiable answer. Vague editorial copy makes both harder to find.

    Build answer blocks that preserve context and earn the next click

    An extractable answer is not necessarily a short answer. It is a self-contained passage in which the claim, subject, unit, and qualification remain understandable when the passage is removed from the rest of the page.

    If a price applies only to a particular plan, put the plan in the same sentence. If timing depends on a route or location, keep that dependency beside the time. If a product works only with certain configurations, do not separate the compatibility condition from the claim. The goal is to prevent a technically accurate sentence from becoming misleading when cited alone.

    Use this checklist on every commercially important answer block:

    • Start with the direct answer. Put background after it, not before it.
    • Name the product, service, route, plan, or option explicitly instead of relying on unclear pronouns.
    • Use consistent attribute labels across prose, tables, product details, and structured data.
    • Keep units, eligibility rules, exclusions, and other material qualifiers beside the value they govern.
    • Use real HTML tables for important comparisons so the underlying attributes exist as page content rather than only inside an image.
    • Make visible copy and structured data agree. Markup should reinforce the page’s facts, not introduce a more favorable version of them.
    • State when a detail is dynamic or individual. Direct the shopper to a live check instead of publishing false precision.
    • Review blocks containing prices, timing, availability, and other changing facts whenever the underlying information changes.

    Specificity and freshness matter because cited snippets have lifecycles. Some answers peak and fade as intent changes or the information becomes stale, while other answers can emerge after publication and continue growing. A page is not finished merely because it earned a citation once.

    Write for the follow-up question

    Reusable answer pattern: [Offer] is suitable for [use case] when [condition]. Choose [alternative] if [constraint]. The main tradeoff is [tradeoff]. Check [live or individual detail] before deciding.

    This pattern performs four jobs without padding. It answers the initial question, preserves the qualification, acknowledges the alternative, and identifies the next unresolved detail. Adapt the structure to your facts rather than copying the wording mechanically.

    Do not hide decisive information merely to manufacture a click. An incomplete answer is less useful to the shopper and weaker evidence for an AI response. Make the stable answer complete, then make the continuation valuable:

    • Citation layer: the direct fact, definition, comparison, or recommendation an AI system can reuse.
    • Context layer: the method, caveat, evidence, exclusions, and tradeoffs that help the shopper evaluate the answer.
    • Continuation layer: live availability, an exact configuration, an individualized quote, a full comparison, or another detail that cannot be resolved reliably in a generic answer.
    • Action layer: the smallest sensible commitment, such as selecting an option or checking a specific detail, rather than a generic call to learn more.

    Match the next action to the uncertainty the shopper still has. Someone asking about compatibility needs a compatibility path. Someone comparing cost needs the applicable price, not an invitation to read unrelated brand history.

    Measure AI Overview traffic without trusting the default channel

    An analyst watches glowing visit streams pass from abstract AI conversation portals through an attribution lens to an online store.

    Google Search Console does not provide a clean, dedicated signal for traffic from AI Overviews. That leaves teams unable to see the full contribution in a standard organic report, and some of the traffic can appear under the wrong channel.

    A workable GA4 proxy uses the text fragment that Google sometimes appends when a person clicks a cited passage: #:~:text=. The fragment can be surfaced through a custom dimension that fires when it appears in the landing URL.

    Set up the measurement layer as follows:

    1. Check the complete landing-page location on the initial page view for the #:~:text= fragment.
    2. Store a boolean flag in GA4 through a custom dimension. Retain the landing page, default channel, and event date alongside it.
    3. Create separate views for all flagged events, flagged Organic Search events, and flagged Direct events.
    4. Group landing pages or cited passages by decision theme, such as pricing, comparison, compatibility, timing, or destination information.
    5. Trend both volume and share over time. A rising count can mean something different from a rising percentage of organic traffic.
    6. Inspect a sample of the live search results before treating the flag as confirmed AI Overview traffic.

    The attribution correction is material enough to warrant its own reporting view. Across 51,200 flagged events from September 2025 through June 2026, 22.4% were attributed to Direct instead of Organic Search. That represented 11,468 events in a single transportation brand’s dataset. If your dashboard accepts GA4’s default grouping without checking the fragment, organic performance may be understated.

    Preserve the raw channel data rather than silently rewriting it. Build a corrected analysis view that identifies the probable misattribution, documents the rule, and allows the original value to be audited.

    Do not turn one site’s traffic share into a planning benchmark. AI Overview referrals accounted for 7.53% of organic sessions across that observation window, but the share peaked around 16% to 17% in February and March 2026 before falling to roughly 2% to 4% later in the period. A model that assumes a stable percentage will overstate or understate the channel as prominence changes.

    The text-fragment method is also a proxy, not a perfect identifier. The same fragment can be used by Featured Snippets and People Also Ask results. Label the segment honestly, validate examples manually, and avoid presenting every flagged visit as a confirmed AI Overview click.

    Your reporting view should answer operational questions, not merely produce an AI traffic total:

    • Which pages and decision themes attract flagged visits?
    • How much probable AI Overview traffic is appearing under Direct?
    • Which cited answer blocks are growing, stable, or fading?
    • Did a content update precede a meaningful change in the trajectory?
    • Do those visits continue to a useful product, lead, or purchase action?

    Prioritize a portfolio of answers, not a one-time AI campaign

    AI citation performance is concentrated. In the transportation dataset, the highest-performing snippet generated 2,276 tracked events, compared with an average of 31 across 1,661 snippets. An estate-wide average can therefore conceal the answer blocks doing most of the work.

    Manage each commercially relevant page according to its current evidence:

    • Cited and growing: refresh the facts, expand adjacent decision questions, and protect the clear structure already working.
    • Cited and falling: check for stale details, shifting intent, weaker specificity, and changes to the cited passage before rewriting the entire page.
    • Not cited but commercially important: replace generic introductions with a direct answer block, expose comparable attributes, and verify that one page clearly owns the question.
    • Receiving visits but not useful actions: repair the continuation layer. The cited answer may be doing its job while the next step is mismatched or unclear.
    • Broad traffic with little decision value: retain the content if it serves the audience, but do not let volume alone move it ahead of pricing, fit, risk, or comparison work.

    Do not delete or merge a page solely because its AI-origin visits declined. Citation prominence can fluctuate with query intent, content freshness, and changes in Google’s selection. First inspect the passage, the query family, and the surrounding organic trend. Record material edits so later movement can be interpreted instead of guessed at.

    For the next publishing cycle, choose the commercial question that most often blocks a decision. Give it a precise answer, attach every material qualifier, present comparisons as real HTML, align the structured data, and add a next action that resolves the shopper’s remaining uncertainty. Then instrument the landing page and watch the answer block over time.

    The goal is not to chase every new AI surface. Make your product reality the easiest accurate answer to reuse and your site the best place to finish the decision.

    References


  • How to Build SEO Across Social Search and AI Discovery

    How to Build SEO Across Social Search and AI Discovery

    Your website can rank, your social posts can earn views, and your brand can still disappear when someone asks an AI assistant what to buy. The problem is usually not one missing keyword. It is a broken discovery chain: the answer exists, but the proof is fragmented across surfaces that never reinforce one another.

    You fix that by planning website SEO, social search, third-party distribution and AI visibility as one operating system. The goal is not to publish the same content everywhere. It is to give each surface a clear job while keeping the underlying facts, expertise and evidence consistent.

    Optimize a discovery chain, not an isolated page

    Start by keeping the SEO foundation intact. Your important website content still needs sound indexability, crawlability, internal linking, semantics, taxonomy, layout and consistency. Those elements help machines retrieve a page, understand its subject and connect it to the rest of your site.

    But a technically strong page cannot do the whole job. A buyer may first encounter your expertise in a short video, hear your company discussed on a podcast, see a creator demonstrate your product, compare reviews and only then search your name. An AI assistant may draw on several of those touchpoints before it decides whether your brand is relevant enough to mention.

    That changes the planning question. Instead of asking only, “How do we rank this page?” map the full route from a person’s question to a defensible answer:

    • Demand: What complete question is the person asking, including qualifiers such as location, use case, budget, eligibility or timing?
    • Answer: What direct conclusion would resolve that question?
    • Evidence: Which product facts, demonstrations, customer experiences, expert opinions or original findings support the conclusion?
    • Format: Does the person need a detailed page, a visual demonstration, a short answer, a comparison or location-specific information?
    • Reinforcement: Where could the claim be independently discussed, reviewed or cited?
    • Action: What should the person be able to do next – compare options, verify availability, book, buy or continue learning?

    Turn those fields into a discovery brief before commissioning anything. If the team cannot identify the evidence or the next action, changing a title tag will not solve the underlying problem.

    This also exposes the difference between a keyword and a conversation. A keyword may describe a topic. A conversation contains the follow-up questions, objections, constraints and proof a person needs before making a decision. Website pages, social formats and external mentions should cover different parts of that conversation without contradicting one another.

    Give every discovery surface a distinct job

    Cross-channel SEO becomes wasteful when every team receives the same instruction: promote the new page. A link and a shortened caption rarely make a useful social asset, while a social clip rarely contains the depth, navigation or conversion path expected from a durable website resource.

    Use the website as the durable evidence layer

    Your site should hold the complete version of important factual and commercial answers. It is where you can explain conditions, show supporting material, connect related entities, maintain current policies and offer a controlled next step.

    That does not mean every query deserves a new page. Create one when the person needs more depth, stronger verification or a better conversion path than an existing search result can provide. If another owned asset already satisfies the intent, a duplicate page may merely split attention between two weak destinations.

    Treat social content as a searchable answer

    A social post is no longer just a promotional route back to the site. Social and video content can surface directly in Google, which means a short-form answer may become the first result a prospective customer sees.

    Suppose a video starts earning clicks for variations of “how to lace running shoes for wide feet” while the website has no useful answer. That pattern reveals search demand, the language people use and a format that already attracts attention. If those searchers need product guidance or a purchase path that the video cannot supply, build a detailed site resource, embed the useful demonstration and connect it to the appropriate products.

    Run the logic in reverse as well. If the social result answers the question and leads people to the right action, do not clone it into a thin page just to add another URL. Strengthen the result you already have with a clearer caption, an accurate profile, a relevant destination and a planned follow-up.

    The transferable unit is not identical copy. It is a stable claim supported by the same evidence. The website can provide depth, a short video can demonstrate the method, a static post can isolate the decision criteria and a profile can establish who is speaking. Each expression should feel native to its surface.

    Use creators and independent coverage to fill trust gaps

    Your own search data can reveal conversations where the brand has no presence. Use those gaps to brief creators by query territory and audience need, not follower count alone. A useful brief identifies the question to address, the evidence available, the claim boundaries, the preferred format and the action the audience should be able to take.

    Format evidence belongs in the brief too. If your short-form content repeatedly gains search visibility while long-form video does not, that is a production signal rather than a matter of taste. Creators can then be selected for their ability to explain the right subject in the right format.

    Independent coverage serves another purpose: corroboration. Your website is the appropriate authority for your hours, specifications, policies and availability. It is not an independent judge of whether you are the best or most convenient option. Reviews, publications, communities and creators can supply the external experience that a self-authored claim cannot.

    Build evidence an AI system can connect and verify

    Glowing threads connect an abstract AI sphere to documents, media tools, a product sample and verification tokens on a dark table.

    AI discovery raises the cost of ambiguity. An assistant trying to recommend a business has to connect an entity to the right products, audience, locations and claims. Contradictory profiles, generic location pages and unsupported superlatives make that connection harder.

    Create a controlled fact sheet for the claims that must remain stable across your digital presence. It should cover:

    • The official brand and location names you use publicly.
    • A plain description of what the business does and whom it serves.
    • Product, service and category relationships.
    • Locations, service areas, hours and available contact paths.
    • Eligibility, fees, policies, availability and appointment conditions where relevant.
    • The original evidence that supports distinctive claims.

    Use that sheet to audit the About page, location pages, social profiles, speaker biographies, event descriptions and other copy you control. The wording can adapt to each setting. The facts should not drift.

    Structured data supports this work when it describes the same information people can see on the page. JSON-LD can clarify relationships among a business, its locations, services and content, but markup cannot reconcile conflicting opening hours or turn an unproven claim into authority. Publish the complete, current fact in visible content first; represent it accurately in structured data second.

    Specific context matters most when the question contains several constraints. Someone may ask for a nearby bank with free small-business checking and Saturday hours rather than typing “banks near me.” Answering that request requires fees, eligibility, proximity and branch hours to be available and verifiable together.

    Part of the questionEvidence the machine needsStrongest place to maintain it
    “Near me”Accurate location and service-area informationLocation pages and maintained business listings
    “Free small-business checking”Current fees, conditions and eligibilityOfficial product and policy content
    “Open on Saturdays”Current hours for the specific branchBranch-level pages, listings and operational data
    “Recommended” or “most convenient”Independent experience and reputation evidenceReviews, publishers and other third-party platforms

    For a multi-location company, do not treat this as one brand-level record. Each location needs its own accurate context. A service offered in one branch, an appointment policy used in one region or weekend hours at one address should not silently become a claim about every location.

    Go beyond operational facts by creating material that cannot be replaced with a generic rewrite. Proprietary data, internal experiments, customer stories, product insights, industry findings, expert opinions and examples from real work give other people something concrete to cite and discuss.

    Package each evidence asset so it can travel. Give it a stable page, a direct conclusion, enough method or context to evaluate it and clear limits on what it proves. Then adapt the finding into social explanations, creator conversations, presentations or interviews without changing the underlying claim.

    Turn social search data into publishing decisions

    Guesswork becomes less defensible when first-party query data is available. Google Search Console Platform properties can connect a verified social or video account to performance data from Search, Discover and News. The available reporting includes clicks, impressions, click-through rate, average position and the queries associated with the account’s content.

    If the property type is available for an account you control, verify it promptly. Collection starts after verification and does not backfill earlier performance. Waiting does not preserve an option; it permanently leaves a gap in the query history.

    Use the data in a repeatable workflow:

    1. Record the verification point. This prevents the team from treating an incomplete early reporting window as a performance decline.
    2. Check the 24-hour view after publishing. If a new asset begins gaining search demand quickly, cross-promote it while the subject is active or prepare the follow-up people are likely to need.
    3. Review query groups. Separate leading, rising and declining themes. Use the language of genuine searches to refine captions, future topics and the questions covered on your site.
    4. Compare like with like. Use URL-based filters to compare short-form and long-form video, or video and static posts, instead of letting total account performance hide a format difference.
    5. Connect discovery to the next action. A query and click show that content was found. They do not show that the visitor reached a useful destination, understood the offer or completed a business action.

    The report should end in a publishing decision, not a slide of metrics. Use these rules:

    Observed signalLikely issue or opportunityDecision to consider
    Social content earns relevant queries, but the site has no complete answerDemand is proven, while the conversion or depth layer is missingCreate a useful site resource and connect the successful media to it
    A social result already satisfies the intentA second page may add duplication rather than valuePreserve the winning result, improve its destination and publish a logical follow-up
    One format repeatedly earns more search visibilityThe audience or result surface favors that mode of explanationChange the production brief and test more topics in the stronger format
    A topic rises in the 24-hour viewThere may be a short window for related demandCross-promote it or release the next answer while interest is active
    Impressions increase but useful actions do notVisibility may be attracting the wrong intent or leading to a weak destinationInspect the query, promise, landing path and action before scaling output

    Keep the limits visible. Platform properties contain first-party information for accounts you can verify. They do not provide a competitor view, category benchmark or share-of-voice report. Native platform analytics and website conversion data still have different jobs.

    AI visibility is less deterministic still. Responses can vary with context, location and prior activity, while current visibility tracking is better suited to directional patterns than exact attribution. Measure whether important facts and citations appear more consistently across a controlled set of relevant prompts, but do not present that sample as a complete market view.

    Install one operating loop across SEO, social and AI

    Three people collaborate around a circular illuminated workflow with a computer, phone, notebook, microphone and evidence cards.

    The final obstacle is usually organizational. SEO manages pages, social manages feeds, public relations manages mentions and local teams manage operational facts. Each group can hit its own target while the overall discovery experience remains inconsistent.

    Organize the recurring review around conversations rather than channels:

    1. Select a query territory. Start with a question that matters to the audience and has a plausible next action.
    2. Classify the evidence requirement. Decide whether the answer depends on an official fact, a demonstration, independent experience, original analysis or several of them together.
    3. Choose the primary asset. Name the website page, social result, video or location record that should carry the complete answer. Do not assume it must always be a new page.
    4. Close factual gaps. Correct conflicting profiles, incomplete location data and unsupported claims before increasing distribution.
    5. Create native adaptations. Preserve the conclusion and evidence while changing the length, format and framing for each surface.
    6. Earn reinforcement. Put useful findings and demonstrations in front of the communities, creators and publications the audience already trusts.
    7. Read the combined signals. Use query demand, format performance, external references, destination behavior and directional AI visibility to choose the next update.

    Assign ownership at each handoff. Someone must be accountable for canonical facts, someone for platform-native production, someone for third-party distribution, someone for location accuracy and someone for business outcomes. Job titles can vary. Unowned handoffs are where contradictions and dead-end traffic accumulate.

    Key takeaways

    • Keep technical SEO strong, but plan discovery around a person’s complete question rather than one page or keyword.
    • Use the website for durable depth, social content for searchable explanations and third parties for independent validation.
    • Make important brand and location facts consistent in visible content before representing them in JSON-LD.
    • Verify eligible Google Search Console Platform properties early because performance data is not backfilled.
    • Convert query and format signals into explicit publishing decisions instead of reporting visibility as an end in itself.
    • Treat AI visibility measurements as directional and improve the evidence available across the surfaces an assistant may consult.

    Begin with one query cluster where your social traction, website coverage and business destination do not line up. Decide which asset should answer it, repair the supporting evidence and distribute the answer in formats suited to each surface. That single completed loop will teach your team more than another disconnected content calendar.

    References


  • Paid Media Conversion Measurement: What to Change Now

    Paid Media Conversion Measurement: What to Change Now

    Your paid media dashboard can keep filling up while the measurement underneath it becomes less dependable. The practical fix is not another master metric. You need to strengthen how outcome events reach Microsoft Advertising and change how your team interprets branded-search activity in Google Ads.

    Those are separate jobs. One improves event collection when browser signals are limited. The other exposes a consideration signal that sits between an ad impression and a conventional conversion. If you combine them indiscriminately, you can end up with a larger conversion total and a weaker understanding of performance.

    Separate event collection from campaign interpretation

    The most important distinction is between how an event is captured and what the event means. Microsoft Advertising’s Conversions API, or CAPI, changes the collection path. Google’s Branded Searches changes what behavior you can observe after an ad exposure.

    Measurement componentWhat it recordsHow to use itWhat not to infer
    Microsoft UETActivity captured in the browserMaintain browser-side visibility and use it with CAPIDo not assume browser collection alone covers every online or offline outcome
    Microsoft CAPIOnline or offline events sent from your systems through a server-to-server connectionImprove signal coverage and connect outcomes that do not exist solely in the browserDo not assume a second collection path automatically fixes event definitions or duplicate handling
    Google Branded SearchesA search for your brand on Google or YouTube after someone sees an eligible adAssess whether YouTube or Demand Gen activity is followed by greater brand-seeking behaviorDo not treat the signal as a sale, a bidding target, or proof of incremental lift

    This distinction should survive all the way into your dashboard. A server-recorded purchase or qualified offline outcome and a subsequent branded search may both carry a conversion label inside an ad platform, but they answer different questions. Combining them in one unlabeled total makes that total difficult to use for budgeting.

    Create separate reporting groups for business outcomes, consideration actions, and measurement diagnostics. That gives each signal a job before anyone uses it to defend a campaign.

    Add Microsoft CAPI without dismantling UET

    An isometric website and server send conversion-event packets through separate browser and server routes to one measurement destination.

    Microsoft CAPI is currently a beta capability, so your first implementation question is whether the account has access. The second is whether someone can own a server-side integration after launch. This is not a one-time tag installation; it needs an event definition, a connection to the systems where those events originate, and ongoing monitoring.

    Keep UET in place. Microsoft recommends that advertisers combine CAPI with Universal Event Tracking: UET continues to observe browser activity, while CAPI sends data directly from your systems. Treat the two paths as complementary coverage, not competing implementations.

    1. Confirm account eligibility and name a technical owner. If the beta is not available, finish the event design now so access does not become the start of the project.
    2. Build an event register before writing integration code. For every event, record the business definition, originating system, online or offline status, browser collection path, server collection path, reporting purpose, and accountable owner.
    3. Identify overlap between UET and CAPI. When the same real-world action can arrive through both paths, confirm Microsoft’s current deduplication requirements and define the identifier that ties the records together. Do not assume duplicate prevention happens automatically.
    4. Test online and offline flows separately. Use known test cases and verify that the originating system, integration logs, and advertising report describe the same action.
    5. Reconcile events at three stages: created in your system, sent by the integration, and acknowledged or reported downstream. A discrepancy then points to a specific handoff instead of becoming a general tracking mystery.
    6. Document failure handling. Your owner should know where rejected or unsent events appear, how they are retried, and how a prolonged interruption becomes visible.

    The event register matters because server-side transport cannot rescue an ambiguous conversion. If sales and marketing use different definitions of a completed outcome, CAPI can transmit that disagreement more reliably without making the resulting metric more useful.

    Server-side collection is also a transport choice, not permission to send every available customer field. Moving data out of the browser does not remove your privacy, consent, security, or data-governance obligations. Limit the payload to the approved measurement purpose and have the appropriate internal owner review it before production use.

    Reset how you report Google’s Branded Searches

    An abstract ad panel leads to a magnifying glass over products, while only one branch continues to a separate checkout package.

    Branded Searches measures a meaningful middle step: someone sees an ad and later searches for the advertiser’s brand on Google or YouTube. That can reveal demand that a click-only report misses, particularly when the ad creates memory rather than an immediate site visit.

    It is still a consideration action, not an end-of-funnel outcome. Google formally places it under the Consideration goal, and its current rules create several reporting traps that you should resolve before presenting the number.

    • The default conversion window is seven days. You can set it from one to 30 days.
    • YouTube and Demand Gen are currently listed as eligible campaign types.
    • Performance Max is not included in the current eligibility list, even though it appeared when the conversion type was originally announced.
    • Brand mapping must be configured. A missing or incomplete setup can prevent the measurement from working.
    • Branded Searches is treated as a primary conversion action, but it cannot be selected as a bidding optimization goal.
    • The metric appears in Results and All Conversions rather than the standard Conversions column.
    • You can inspect it at campaign, ad group, and asset levels, as well as through Report Editor.

    These eligibility, attribution, and reporting rules mean that a missing number is not automatically a demand problem. Check campaign type, brand mapping, conversion window, and report column before diagnosing the creative or audience.

    Choose the window for comparability, not a bigger count

    The seven-day setting is an attribution boundary. It determines how long a subsequent branded search can qualify after the relevant ad exposure; it is not a waiting period before the data becomes useful.

    Start with the seven-day default unless your measurement plan supports a different choice. If you change it, record the effective date and avoid comparing the new count directly with a period measured under the old window. Extending the eligible period can change the volume even when the campaign itself has not changed.

    Use the signal to investigate influence, not claim causation

    A search that follows an impression establishes sequence inside Google’s measurement framework. By itself, it does not prove that the search would never have happened without the ad. That distinction separates attribution from incrementality.

    Describe the metric internally as observed branded-search behavior after ad exposure. Do not rename it brand lift, incremental search, or acquired demand. If your decision requires a causal claim, an attributed sequence is not a substitute for a controlled lift design.

    The primary-conversion label deserves similar care. In this case, primary does not mean the action can steer bidding, and it does not place the metric in the usual Conversions column. Build a dedicated report from Results or All Conversions, then keep the signal separate from the outcome conversions used to judge commercial return.

    For Performance Max, treat support as unconfirmed unless the current interface or Google guidance available to your account explicitly establishes otherwise. Its absence from the current campaign list is a reason to verify, not a reason to copy the YouTube or Demand Gen setup and assume equivalent coverage.

    Put every measurement change behind a written contract

    A measurement contract is a short operating record for each signal. It prevents platform terminology from becoming your business definition and makes reporting changes auditable. Create one before you alter dashboards, goals, or stakeholder reports.

    • Signal name and plain-language definition
    • The real-world action represented
    • Originating system and collection path
    • Eligible platforms and campaign types
    • Attribution or conversion window
    • Required setup dependencies
    • The platform columns and reports where it appears
    • Whether bidding can use it
    • Whether the signal represents an outcome, consideration action, or diagnostic
    • The owner responsible for implementation and validation

    For Microsoft, the contract should distinguish UET, CAPI, and any event that can arrive through both. It should also show whether each event is online or offline and how overlap is controlled.

    For Google Branded Searches, record YouTube and Demand Gen as the currently listed campaign types, the selected one-to-30-day window, the brand-mapping dependency, the Results and All Conversions reporting locations, and the prohibition on bidding optimization. Mark Performance Max as requiring verification rather than silently treating it as eligible.

    Then use a fixed decision hierarchy. Business outcomes answer whether the investment produced value. Consideration signals help explain movement toward those outcomes. Collection diagnostics tell you whether the measurement path worked. A diagnostic should not determine budget, and a consideration action should not be presented as revenue.

    Before approving a period-over-period comparison, verify that the following conditions remained stable:

    • The eligible campaign set did not change.
    • The conversion window did not change.
    • Brand mapping remained active.
    • The same reporting column or report was used.
    • UET and CAPI coverage remained stable, or any change was annotated.
    • Duplicate handling was verified after integration changes.
    • The business definition of each outcome remained the same.

    If one of those conditions changed, annotate the break and report the affected periods separately. A clean-looking trend line is less useful than an honest discontinuity.

    Key takeaways for your next measurement review

    • Microsoft CAPI is a beta server-side measurement path, not a replacement for UET.
    • Design duplicate handling before sending the same action through browser and server paths.
    • Use CAPI to support online and offline event coverage, but keep one documented business definition for every conversion.
    • Google Branded Searches currently applies to YouTube and Demand Gen; do not assume Performance Max eligibility.
    • The Branded Searches default window is seven days and can be adjusted from one to 30 days.
    • Report Branded Searches as a consideration signal from Results or All Conversions, not as a bidding goal or proof of incremental lift.

    Your next measurement meeting should end with two named owners and two concrete outputs: a technical plan for UET plus CAPI coverage, and a reporting contract for Branded Searches. Once those are explicit, you can add signal without weakening the decisions built on it.

    References


  • How to Read ChatGPT’s Share of Google Outbound Ad Clicks

    How to Read ChatGPT’s Share of Google Outbound Ad Clicks

    If you manage a search budget or an AI visibility program, ChatGPT’s apparent lead in paid traffic from Google can prompt the wrong decision: buy more AI-related keywords because ChatGPT must be capturing a huge share of Google’s ad clicks. That isn’t what the numbers establish.

    The useful signal is narrower and more important. ChatGPT has an unusually paid-heavy traffic mix among major destinations reached from Google, while navigational demand, brand advertising, organic discovery, and zero-click behavior are interacting in the same customer journey. You need to separate those effects before changing a campaign or reporting an AI win.

    The claim is about click mix, not ownership of all Google ad clicks

    The scale of the observation deserves attention. A panel covering 13.1 billion search events from 9.1 million opted-in users between October 2024 and December 2025 placed ChatGPT sixth among destinations clicked from Google Search. It trailed YouTube, Google’s own properties, Reddit, Facebook, and Wikipedia. The panel also recorded millions of Google searches for ChatGPT each week.

    The critical word is proportion. Among the leading destinations examined, ChatGPT received the greatest proportion of paid clicks. The defensible interpretation is that ChatGPT’s Google traffic was more heavily weighted toward paid clicks than the traffic of the other major destinations in that comparison.

    That is not the same as saying ChatGPT received the largest absolute number of Google ad clicks. It also does not mean that most Google ad clicks went to ChatGPT. Three different metrics are easy to collapse into one:

    • Destination rank: how many total Google clicks, paid and organic, reached a destination.
    • Paid-click mix: what proportion of the Google clicks reaching that destination were paid.
    • Share of all outbound ad clicks: what proportion of every paid outbound Google click went to that destination.

    A destination can lead on paid-click mix without leading on absolute paid-click volume. A smaller bucket can contain a higher concentration of paid clicks while still holding fewer paid clicks overall. There is therefore no defensible percentage to attach to “ChatGPT’s share of all Google ad clicks” from these figures alone.

    The panel also does not reveal which queries OpenAI bid on or how much it spent. You cannot derive its cost per click, campaign efficiency, brand-defense strategy, or incremental user acquisition from the result.

    Use exact language when this reaches a dashboard or executive slide: “ChatGPT had the highest paid-click proportion among the leading destinations analyzed in a large opted-in panel.” Do not shorten it to “ChatGPT gets the most Google ad clicks.” The shorter statement changes the denominator and overstates the evidence.

    Navigational demand helps explain ChatGPT’s paid-heavy traffic

    Many people type “ChatGPT” into Google because they want to reach ChatGPT. That is navigational intent, even though the user is passing through a search engine rather than entering a URL or opening an app directly.

    This matters because Google can absorb some informational searches with an answer on the results page, but it cannot fully replace the destination when the user’s task is to open ChatGPT and use it. Only 11.1% of searches that otherwise would have led toward OpenAI were intercepted by a zero-click Google experience. That was one of the lowest interception rates among the major destinations examined.

    Branded searches also showed a stronger paid tendency across the panel. When a branded search produced a click, 4.4% of those clicks were paid, compared with 3.3% for non-branded searches. That pattern is consistent with brands buying visibility around their own names. It does not prove how much of ChatGPT’s paid traffic came from defensive bidding, because the underlying query and spend details are unavailable.

    If you run branded campaigns, do not treat ChatGPT’s result as permission to bid on every variation of your name indefinitely. Audit your own demand:

    • Separate exact brand and product-name queries from category, problem, comparison, and support queries.
    • Identify the destination each ad uses. A login page, product page, pricing page, and educational page serve different intentions even when the query contains the same brand.
    • Compare downstream outcomes, not just click-through rate. A brand ad that collects clicks already available through a strong organic result may look efficient without producing incremental value.
    • Where the commercial risk is acceptable, use a controlled campaign experiment or matched holdout to test incrementality. Do not abruptly pause a valuable brand campaign merely because organic visibility looks strong; a blunt pause can expose traffic to competitors or change the results-page experience before you have a reliable comparison.

    The decision is not “brand bidding works” or “brand bidding is waste.” It is whether the paid placement adds qualified visits or outcomes that would not otherwise occur. ChatGPT’s traffic pattern makes that question more visible; it does not answer it for your brand.

    Google and ChatGPT can be stages in the same journey

    A person moves through generic search, conversational assistant, company website, and purchase stages linked by colored light trails.

    Treating Google Search and ChatGPT as isolated channels creates a false choice. A user can begin in Google, click an ad that opens ChatGPT, and then use ChatGPT for the task they had in mind. Search is the acquisition layer in that sequence; ChatGPT is the destination and working environment.

    Google is still doing far more than routing people to websites they already know. Only about 14% of Google clicks went to a website explicitly named in the query. The remaining 86% were discovery clicks, meaning Google introduced a destination the user had not specifically requested.

    That 86% is the strategically contestable part of search. It includes people choosing among unfamiliar destinations, not merely trying to reopen a known service. Ads, organic results, and other search experiences can all compete for that attention.

    For planning purposes, split queries into three intent groups:

    • Destination intent: the user names a brand, site, product, or service they want to reach. Decide whether paid placement protects or incrementally expands access to your own destination.
    • Evaluation intent: the user is comparing products, approaches, or providers. Coordinate the ad, organic result, and landing page around the decision criteria the user is actually evaluating.
    • Task intent: the user wants to accomplish something or obtain an answer. Publish a direct, complete response, use accurate structured data when a supported schema type genuinely describes the page, and make the next action clear.

    Do not translate ChatGPT’s paid-click mix into a blanket instruction to target keywords containing “ChatGPT.” Much of the observed demand may be navigational demand for OpenAI’s product. Unless your offer genuinely satisfies the query, copying the keyword can buy irrelevant traffic rather than entry into an AI-assisted customer journey.

    There is an equally important distinction for AI SEO and generative engine optimization. A paid Google click that sends someone to ChatGPT measures acquisition for the ChatGPT destination. It does not measure whether ChatGPT mentions, cites, recommends, or links to your brand. Paid search exposure and visibility inside an AI answer are separate events with separate denominators.

    Build a scorecard that keeps paid traffic and AI visibility separate

    A marketing analyst compares separate amber paid-traffic instruments and blue AI-visibility instruments at a modern desk.

    Your website analytics cannot reconstruct Google’s outbound traffic to every destination. It generally begins when a visitor reaches a property you control. That means you should not expect your own analytics to reproduce a panel-level comparison between ChatGPT, YouTube, Reddit, Wikipedia, and other destinations.

    You can still build a useful measurement system. Start by writing the denominator next to every share metric:

    • Paid mix of your Google traffic = paid Google clicks to your site divided by all paid and organic Google clicks to your site, using a consistent scope and period.
    • Share of your paid search traffic = clicks from a specified campaign or intent group divided by all paid search clicks you received.
    • AI referral share = measurable referral visits from AI properties divided by the site-traffic denominator you have explicitly chosen.
    • AI answer visibility = mentions, citations, or links observed across a defined prompt set, model set, location, and collection period.

    Those metrics answer different questions. Putting them in one chart without the denominators can make a paid acquisition change look like an AI visibility change, or make a rise in AI citations look like referral growth when users never clicked through.

    DecisionPrimary measurementMisreading to avoid
    Is our Google traffic becoming more paid-heavy?Paid Google clicks as a share of all measurable Google clicks to your siteTreating the result as your share of all Google advertising
    Does brand bidding create incremental value?Lift in qualified outcomes during a controlled comparisonAssuming every branded ad click would otherwise disappear
    Are AI systems sending visitors?Identifiable AI referral sessions and their downstream outcomesCounting every unattributed visit as AI traffic
    Are we represented inside AI answers?Mentions, citations, links, accuracy, and prominence across a defined prompt setUsing AI referral sessions as a complete visibility measure

    Then attach a business outcome to each acquisition metric. A click can lead to an activated user, qualified lead, sale, return visit, or no meaningful action. Choose the outcome appropriate to the page and campaign before evaluating performance. A high paid-click share is a traffic-composition fact, not proof that the spend was efficient.

    The broader Google trend makes this discipline more urgent. During the 15-month panel period, the overall zero-click rate rose by about 2.6 percentage points while the share of searches producing an organic click fell by roughly 2.8 points. Paid clicks showed no meaningful change within that dataset.

    That does not make paid search immune to changing behavior. It means the observed increase in zero-click activity came mainly at the expense of organic clicks during this period, while aggregate paid-click behavior held comparatively steady. Cost, conversion quality, auction pressure, and performance by individual campaign are different questions and require their own data.

    Key takeaways

    • ChatGPT had the highest proportion of paid clicks among the leading Google destinations examined, not necessarily the largest absolute volume of Google ad clicks.
    • The result came from a large opted-in panel, not a complete census of every Google search or user.
    • Strong navigational demand and low zero-click interception help explain why traffic to ChatGPT can support paid placement.
    • The higher paid rate on branded searches provides context for defensive brand advertising, but the available figures do not reveal OpenAI’s queries, spend, efficiency, or incrementality.
    • Google-to-ChatGPT is a real cross-platform journey, but traffic sent to ChatGPT is not the same metric as your visibility inside ChatGPT answers.
    • Any report using the word “share” should state its numerator, denominator, population, and period before anyone makes a budget decision.

    Your next move is not to chase a ChatGPT-shaped keyword list. Rename ambiguous share metrics in your dashboard, separate navigational demand from discovery demand, and pair every click measure with a downstream outcome. Once those boundaries are clear, Google and AI stop looking like rival reporting silos and start looking like the connected journey you actually need to manage.

    References


  • Generative AI Video Resizing in Performance Max: A Control Guide

    Generative AI Video Resizing in Performance Max: A Control Guide

    You gave Performance Max a strong horizontal video. Now Google can extend it into vertical and square versions so the campaign can reach inventory that the original shape could not cover. That can save production work, but it also gives automation a hand in what your customer sees.

    Your decision is not simply whether to switch an AI feature on or off. You need to decide which assets can tolerate generative adaptation, what must remain visually exact, and who has authority to reject a version that fits the placement but fails the brand.

    What generative AI resizing changes in Performance Max

    Google Ads can now extend existing Performance Max videos into missing aspect ratios. The capability builds on video enhancements that can already convert horizontal assets into vertical and square formats. Google’s stated aim is to improve the viewing experience and make the video eligible for more inventory.

    The important word is extend. Ordinary resizing changes dimensions. Cropping removes or repositions material already in the frame. Generative extension can create material needed to complete a differently shaped frame. That moves Performance Max beyond deciding where an ad runs and into adapting the visible creative.

    More eligible inventory is a coverage benefit, not proof that every generated version communicates equally well. A vertical asset may fit a vertical placement while weakening the composition, moving attention away from the product, or placing too much visual weight around a logo or call to action. Evaluate format coverage and creative fidelity as separate questions.

    This distinction also changes ownership. Media teams can judge whether broader inventory is useful. Brand and creative owners must judge whether the adapted frame remains accurate. If only the first group reviews the feature, the campaign can pass a performance check without passing a creative one.

    Choose your control level from the asset, not the campaign

    Three advertising assets have different protective boundaries and separate paths to square and vertical versions.

    A campaign should not receive one blanket risk rating just because it is a Performance Max campaign. One asset may be easy to extend, while another in the same campaign depends on exact geometry. Classify the videos themselves before deciding how much automation to allow.

    A practical three-level policy looks like this:

    • Allow with routine review: The main subject is centered, the surrounding background is visually simple, essential text is not pressed against an edge, and adding space around the scene would not change what the product appears to be.
    • Require explicit approval: The subject moves across the frame, a demonstration depends on spatial relationships, text appears in several positions, or the original composition uses the edges deliberately.
    • Use manually produced formats: The video contains exact package details, interface demonstrations, prices, disclosures, comparison imagery, before-and-after claims, trademark-sensitive shapes, or another element that must not be visually reinterpreted.

    The third level does not mean generative tools are inherently unsuitable for the brand. It means the cost of a small visual error is higher than the production time saved on that particular asset. A generated background anomaly in an atmospheric scene may be correctable. An altered product label or misleading interface state is a different class of problem.

    Do not use campaign budget as a shortcut for this assessment. A low-spend campaign can still publish an inaccurate representation, while a high-spend campaign may contain a visually flexible asset. Product truth, brand constraints, and message structure are better control signals than spend alone.

    If you operate several accounts, write the policy once and attach examples from your own approved creative library. Name which asset types are eligible, which require approval, and which must be supplied in every needed ratio. That keeps the decision from changing whenever a different campaign manager encounters the setting.

    Review every generated ratio as a new piece of creative

    Two creative reviewers compare horizontal, square, and vertical versions of an unbranded kitchen video across three displays.

    The safest review process treats a generated version as a new execution derived from an approved master. Calling it a resize can encourage a quick edge check. A full creative review catches errors that appear during motion, after a scene change, or around the final call to action.

    1. Record the master asset. Keep the approved original, its campaign and asset-group location, the available ratios, and the person responsible for creative approval in one register.
    2. Mark the non-negotiable elements. Identify the product silhouette, package text, logo, typography, interface state, offer language, disclosures, and visual claims that must remain unchanged.
    3. Inspect the entire timeline. Review the opening frame, every scene transition, moments when the subject approaches an edge, and the closing frame. Do not approve a moving asset from a single thumbnail.
    4. Review each ratio independently. Horizontal, vertical, and square versions can fail in different places. An approval for one shape should not automatically cover the others.
    5. Check small-screen legibility. View the adapted asset at a realistic small display size. Confirm that the focal action, essential wording, and call to action still make sense without relying on the original composition.
    6. Log defects by timestamp and type. Record where the problem occurs and whether it affects product accuracy, brand presentation, legibility, narrative clarity, or commercial information. A precise rejection is easier to act on than a note saying the version looks wrong.
    7. Assign a clear outcome. Approve the ratio for campaign use, replace it with a manually produced version, or change the relevant video setting. Do not leave a failed version in an informal state where nobody knows whether it can run.

    Your review should answer concrete questions. Did the number, color, label, and proportions of products remain accurate? Is the logo intact? Does generated visual material look like part of the same scene? Does the composition still direct attention to the intended action? Are prices, conditions, and disclosures as legible and unambiguous as they were in the master?

    Keep campaign approval separate from library approval. A variant that is acceptable for one controlled use should not automatically become an evergreen brand asset or a template for other channels. Record the scope of the approval alongside the decision.

    A September 4 opt-out window was provided through account teams or Google’s form, but advertisers can also change video settings from within Google Ads at any time. If that opt-out date has passed for your account, do not assume the decision is permanent. Inspect the current setting and make the appropriate account-level or campaign-level governance decision based on the controls actually available to you.

    Measure coverage and creative quality on separate scorecards

    Generative resizing is intended to make a video available across more inventory. That objective can be met even when a particular output is not good enough for your brand. Your scorecard therefore needs one track for delivery and another for creative acceptability.

    Decision questionEvidence to inspectAction
    Did the new ratio create useful coverage?Changes in eligible formats, delivery, or placement information available in the accountKeep the format only when its additional coverage serves the campaign goal
    Is the output factually accurate?Frame-by-frame comparison with the approved master and product referencesReject any material error, regardless of campaign performance
    Does the message survive the new composition?Focal action, text legibility, sequence clarity, and call-to-action visibilityProduce the ratio manually when the shape weakens the intended message
    Does it remain within brand rules?Logo treatment, typography, colors, spacing, product presentation, and restricted elementsApprove, restrict, or replace the version according to the documented policy
    Can a performance change be attributed to resizing?A change log plus the campaign reporting available during the review periodTreat a simple before-and-after change as directional, not as isolated proof

    Record the setting, approved assets, and review date before making a change. Where practical, avoid introducing another major creative change during the same evaluation period. Performance Max also automates media buying, so campaign results can move for reasons other than the new video ratio. A campaign-level lift or decline by itself does not isolate the effect of generative extension.

    Set the rejection rules before looking at performance. A visually inaccurate product should not earn approval because the campaign converted. If a generated ratio delivers useful coverage but repeatedly fails creative review, that is a signal to produce the format manually, not to lower the accuracy standard.

    Also log how often your team can inspect generated variants before they run. If the practical workflow gives nobody a reliable chance to review the output, your real choice is not automation with oversight. It is unreviewed creative automation. Change the setting or supply complete format coverage yourself until the approval path exists.

    Key takeaways

    • Performance Max can use generative AI to extend existing videos into missing aspect ratios, including formats suited to vertical and square inventory.
    • Additional format coverage does not guarantee that the composition, product representation, or message remains acceptable.
    • Classify risk at the asset level. Exact product visuals, interfaces, disclosures, and layout-dependent demonstrations deserve tighter control.
    • Review the full timeline of every generated ratio, not just a thumbnail or the approved master.
    • Measure delivery coverage separately from creative fidelity, and reject material visual errors regardless of performance.
    • If you cannot establish a dependable owner and approval path, change the video setting or provide manually produced formats.

    Start with the highest-risk video currently attached to a live Performance Max campaign. Record its video-enhancement setting, identify its non-negotiable visual elements, and review every available ratio from beginning to end. If nobody can clearly approve or reject the generated versions, pause that layer of automation until ownership is explicit.

    References