Tag: Content Creation

  • AI Marketer Image Generation: A Practical Publishing Workflow

    AI Marketer Image Generation: A Practical Publishing Workflow

    You need a campaign image, but a blank prompt box is not a creative brief. If you ask an AI marketer for something that looks professional without defining the image’s job, you can get a polished asset that is unusable, off-brand, or disconnected from the page it is supposed to support.

    The useful shift is that image generation can now sit inside an AI marketer workflow. That can shorten the distance between an idea and a draft. It does not remove the need for direction, review, accessibility, or measurement. The workflow below turns that faster first draft into an image you can publish with confidence.

    Define the image’s job before describing its appearance

    Start with the placement, not the visual style. A blog hero, a paid social creative, a product illustration, and a supporting diagram may cover the same subject, but they solve different communication problems. The placement determines how much detail the image can carry, where the focal point belongs, whether text will be added later, and what the viewer should understand at a glance.

    Write a short image brief with six decisions:

    1. Placement: Name the exact destination, such as the hero area of a landing page, the opening image for an article, or a paid social placement.
    2. Communication goal: Complete the sentence: After seeing this image, the viewer should understand that…
    3. Audience: Identify who should recognize themselves, their work, or their problem in the scene.
    4. Focal subject: Choose the one element that must remain clear when the image is viewed at its final size.
    5. Brand constraints: Specify the visual characteristics that must stay consistent, including approved colors, level of realism, composition, mood, and any recurring visual motifs.
    6. Exclusions: List what must not appear, especially unsupported product details, invented interfaces, competitor marks, illegible text, visual cliches, or sensitive representations.

    A workable brief is concrete enough to reject the wrong image. For example: Create a wide editorial hero for an article aimed at B2B content leaders. Show one marketer directing an AI-assisted image workflow, with the review step visually prominent. Use a restrained, credible visual language with generous negative space on the left for a headline. Do not include logos, embedded words, dashboards, or futuristic humanoid robots.

    If your brief only contains adjectives such as modern, bold, premium, or innovative, it is not finished. Replace each adjective with a visible choice. Premium might mean restrained color, deliberate lighting, a limited number of objects, and generous negative space. Modern might mean a clean editorial composition rather than neon circuitry. The model can act on visible instructions; it cannot infer your internal definition of taste.

    Generate controlled variations instead of unrelated options
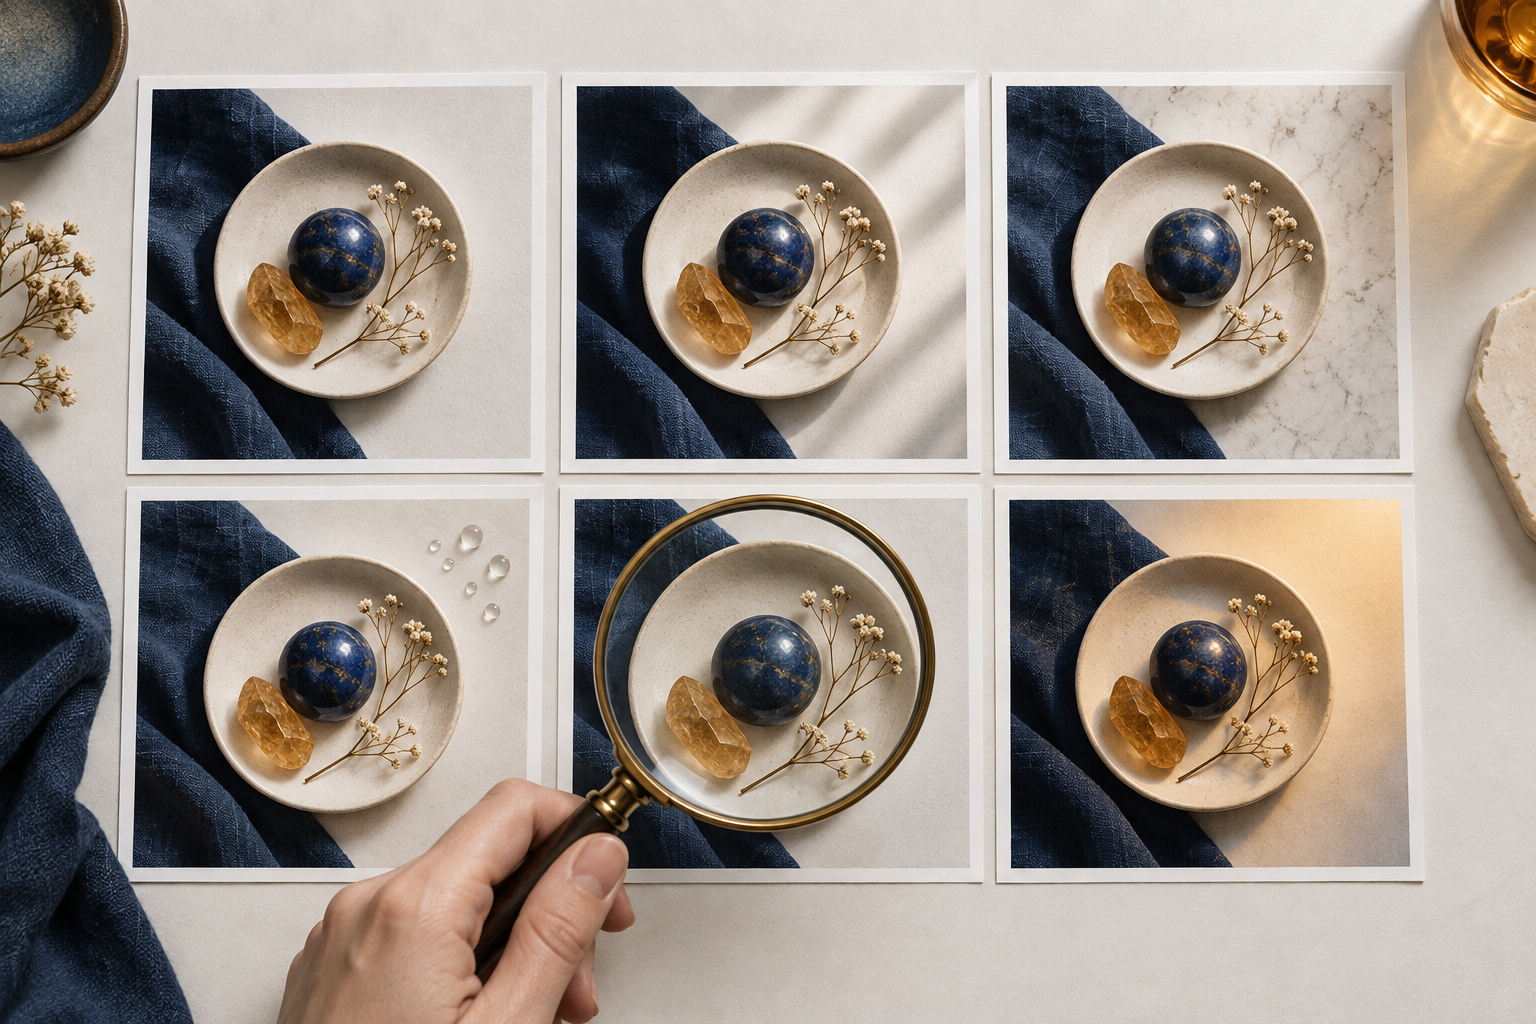
    A hand compares six closely related campaign image variations arranged on a studio table.

    The fastest route to a usable result is not asking for many unrelated concepts. Generate around one approved direction, then vary one decision at a time. This makes feedback precise and prevents the team from restarting the creative conversation with every draft.

    Build the prompt in this order: deliverable, purpose, subject, action, environment, composition, visual treatment, brand constraints, and exclusions. Put the non-negotiable information near the beginning. If the focal subject or empty space matters more than the color palette, say so first.

    • Composition variation: Keep the subject and visual treatment fixed, but test centered, off-center, close, and wide framing.
    • Concept variation: Keep the intended message fixed, but test a literal scene against a simple visual metaphor.
    • Tone variation: Keep the composition fixed, but adjust the level of warmth, energy, realism, or formality.
    • Channel variation: Preserve the concept while adapting the crop and visual density for each destination.

    Evaluate every candidate at the size and crop in which people will encounter it. A detailed scene can look impressive when enlarged and turn into visual noise in a card or mobile feed. The reverse also happens: a simple image may look sparse in isolation but work well once the headline, navigation, and call to action surround it.

    Do not rely on generated pixels for exact copy, product labels, interface text, pricing, or legal language. If wording must be correct, reserve clean space and add the approved text during layout. The same rule applies to a real product interface: use an approved screenshot or a clearly conceptual treatment instead of letting the generator invent controls that customers might mistake for actual functionality.

    Keep a small decision record for the selected asset: the brief, prompt, chosen output, intended placements, edits, reviewer, and approval status. That record gives you a reusable starting point when another channel needs a related image. It also separates approved creative direction from the accidental details of one generation.

    Run a four-part review before the image reaches WordPress
    A campaign image sits at the center of a desk surrounded by tools for checking color, defects, page context, and accessibility.

    Visual appeal is only one approval criterion. Review the candidate through four separate gates so that a striking image does not distract you from a factual, production, or governance problem.

    1. Truth and context

    • Does the image imply a capability, result, customer, partnership, location, event, or product detail that you cannot substantiate?
    • Could a conceptual interface be mistaken for the real product?
    • Are charts, maps, signs, screens, packages, or technical equipment plausible enough to mislead a viewer?
    • Does the representation of people fit the actual audience and context without leaning on a stereotype?

    Treat an unsupported visual claim the same way you would treat unsupported copy. Remove it, replace it with an approved asset, or make the conceptual nature unmistakable.

    2. Brand fit

    • Would the image still feel connected to your brand if the logo were absent?
    • Does its level of polish match the surrounding page rather than overpowering it?
    • Are lighting, color, subject treatment, and visual density consistent with the rest of the campaign?
    • Does it avoid the generic motifs your brand has decided not to use?

    Brand consistency is easier to review when you describe it as repeatable visual constraints. A request to make an image feel more on-brand gives the next operator little guidance. A direction to reduce the palette, remove glowing interface elements, retain natural lighting, and preserve negative space can be repeated.

    3. Production quality

    • Inspect faces, hands, reflections, repeated objects, edges, shadows, and background details at full size.
    • Check every required crop instead of assuming one master image will survive them all.
    • Confirm that overlays remain readable against the image in the final layout.
    • Remove embedded gibberish, accidental marks, and elements that resemble logos.
    • Export an appropriately sized web asset rather than uploading a needlessly heavy working file.

    4. Rights and accountability

    • Verify the image tool’s current usage terms for your intended commercial or editorial context.
    • Do not prompt for a living artist’s signature style or use a real person’s likeness without the permissions your use requires.
    • Retain the generation and approval record where your content team can retrieve it.
    • Follow any disclosure, labeling, or provenance policy that applies to your organization, market, or publishing platform.

    If the image depicts a real person, regulated product, medical situation, financial outcome, or news event, move it out of the routine approval queue. The downside is not merely an awkward visual. A synthetic depiction can create a false factual impression, so use approved documentary material or obtain the appropriate specialist review.

    Publish the image as part of the page’s meaning

    An attractive image does not make a thin page authoritative, and image generation by itself does not create SEO or AI-search visibility. The asset should clarify the same entity, problem, process, or product that the surrounding text explains. If the image and page target different ideas, no metadata can repair the mismatch.

    • Use a descriptive filename: Name the actual subject and function of the image. Avoid camera-roll names, prompt fragments, and keyword strings.
    • Write alt text for purpose: Describe the useful information the image contributes in its page context. Do not begin with image of, repeat the caption, or pack in search terms. If the image is purely decorative, handle it as decorative rather than forcing a redundant description.
    • Keep nearby copy explicit: Introduce the concept in the heading, caption, or paragraph around the image. Do not make readers infer a critical claim from pixels alone.
    • Use a real caption when context is needed: A caption can explain that a visual is conceptual, identify what a diagram shows, or connect an illustration to the point being made.
    • Preserve consistency in structured data: If the page’s JSON-LD identifies an image, use the public URL of the image actually associated with the visible page. Do not invent creator, license, or ownership information merely to fill properties.
    • Check the delivered page: Confirm that the image loads, remains legible on small screens, has not been cropped around the wrong focal point, and does not push the page’s main answer below an oversized hero.

    The practical objective is alignment. The page title, main answer, visible image, alt text, caption, and structured representation should describe the same thing without duplicating one another mechanically. That gives human readers a coherent page and reduces ambiguity for systems trying to interpret it.

    Measure whether the image improved the marketing outcome

    Generation volume is not a performance metric. Neither is the number of minutes removed from the drafting stage if review and rework simply move downstream. Choose the image’s success measure from its job: engagement with an ad, progression from a landing-page hero, comprehension of an explained process, or completion of the action the surrounding content requests.

    When you test an image, hold the headline, offer, audience, placement, and call to action steady. Change one meaningful visual variable, such as human subject versus product detail, literal scene versus diagram, or close crop versus environmental context. If multiple elements change together, the result cannot tell you which decision mattered.

    Pair quantitative performance with a review of failure reasons. Track why generated candidates were rejected: weak message fit, brand mismatch, factual risk, poor crop, unusable text, or production artifacts. A repeated rejection reason is a briefing problem you can fix upstream. It is more actionable than simply asking the model for better images.

    Key takeaways

    • Start with the image’s placement and communication job, not a list of visual adjectives.
    • Generate controlled variations around one approved direction so feedback produces a decision.
    • Add exact wording, product interfaces, and other factual details through an approved production process.
    • Review truth, brand fit, production quality, and rights as separate approval gates.
    • Connect the image to the page with useful alt text, nearby context, consistent metadata, and a working public URL.
    • Judge the asset by the marketing outcome it supports, then use rejection patterns to improve the next brief.

    For your next asset, do not begin by polishing a longer prompt. Write the six-part brief, generate one controlled set of variations, and send only the strongest candidate through the four review gates. That small operating discipline is what turns AI image generation from a novelty into a dependable part of content production.

    References


  • How to Create Google Veo Video Ads for PMax and Demand Gen

    How to Create Google Veo Video Ads for PMax and Demand Gen

    If your PMax or Demand Gen campaign has strong still images but little usable video, you no longer need to make a full production the first step. Inside Google Ads, Veo can turn two image assets into a five- or 10-second video, giving you a faster way to add short-form creative or refresh assets that have started to wear out.

    That speed helps only when you give the tool a focused job. Veo can animate your images, assemble two scenes and apply text, but it cannot decide which benefit matters, repair a weak offer or make mismatched images tell a coherent story. Treat it as a rapid production layer: you supply the idea, evidence and brand discipline.

    Key takeaways

    • Use Veo when you have high-resolution product or service images but need a quick, short-form video asset for PMax or Demand Gen.
    • Give the video one job and organize its two scenes as a simple sequence. Ten seconds is not enough for a product tour, company introduction and offer explanation at the same time.
    • Produce the same concept in horizontal, vertical and square formats so the campaign has an appropriate asset for more available surfaces.
    • Use the two 30-character headlines for the benefit, qualification or next action. Your business name already appears first, so repeating it consumes scarce space.
    • Review results at the asset level, but do not let direct conversions become the only verdict. Delivery, engagement, clicks, website engagement and view-through conversions can reveal different parts of the asset’s contribution.

    Design one idea that fits inside ten seconds

    Veo’s time limit is a useful creative constraint. Before you open Asset Studio, complete this sentence: “After watching, the right customer should understand ______.” If you need more than one clause to fill the blank, the concept is probably too broad.

    A short Veo asset can introduce one product benefit, make a static product image more noticeable, connect a problem image to a result image or carry a familiar campaign message into a video format. It is less suitable when the sale depends on a detailed demonstration, several conditions, an extended narrative or a person speaking directly to the viewer.

    Build a two-scene bridge

    The selected images appear one after the other, so their relationship has to make sense before any animation is added. Choose one of these simple structures:

    • Context to product: Establish the setting in scene one, then make the product the clear focal point in scene two.
    • Problem to result: Show a recognizable condition first and the completed outcome second. Use this only when the result is accurate and supported by the landing page.
    • Wide view to detail: Begin with the complete product or service result, then move to the feature that explains the benefit.
    • Product to action: Use the first scene to establish what is being offered and the second to support the next step with the offer or call to action.

    The second image should resolve or deepen the first, not merely replace it. Two unrelated hero images may each look polished while producing a video with no narrative movement. Put them side by side before uploading them and ask whether the sequence is understandable as two static frames. If it is not, motion will not fix it.

    Know when the format is the wrong fit

    The image-to-video route in Google Ads does not accept images containing a face. Product images, packaging, environments, interfaces and service-result images are therefore more practical inputs than portraits or testimonial frames.

    Do not contort a people-led idea to fit that restriction. If credibility depends on a customer, creator, employee or demonstrator appearing on screen, use a production method designed for that concept. Veo is valuable because it removes production friction from suitable ideas, not because every idea should be forced through it.

    Prepare source images for all three video formats

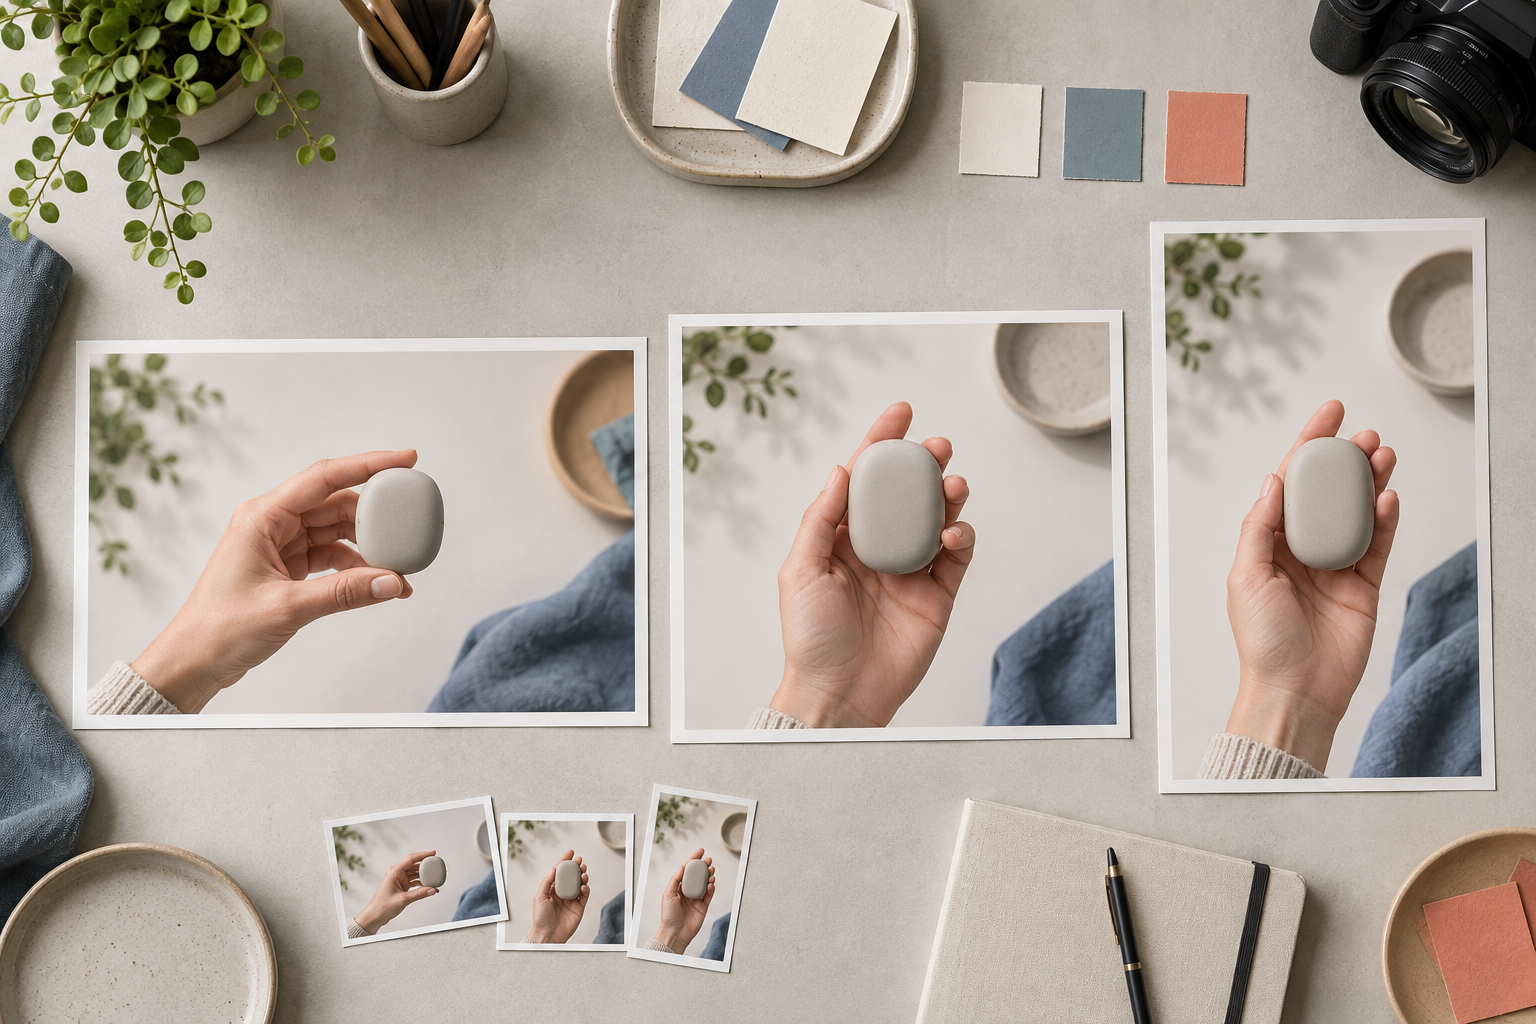
    Three source-image layouts place the same unbranded product in landscape, square, and vertical compositions.

    The quality ceiling is set before generation begins. A high-resolution image with one obvious focal point gives Veo cleaner material to animate and gives you more room to crop. A small or already-soft image may look acceptable in an account preview but become visibly grainy when shown on a larger screen.

    Google Ads supports three video shapes, and the practical goal is to create the same concept in each one:

    FormatAspect ratioRecommended HD dimensions
    Horizontal16:91920 x 1080
    Vertical9:161080 x 1920
    Square1:11080 x 1080

    Do not assume one composition will survive all three crops. A product pushed toward the left edge may work in a horizontal frame and become cramped or disappear in a vertical one. Either start with an image whose subject and important brand details sit comfortably near the center, or prepare crop-specific versions of the same scene.

    Use an image-readiness check before generation

    • Resolution: Start with the cleanest, largest approved image available. Do not enlarge a visibly soft thumbnail and expect generation to restore authentic detail.
    • Focal point: Make the product, environment or service result immediately identifiable. Competing objects make the intended subject harder to read in a brief scene.
    • Crop tolerance: Check horizontal, vertical and square crops before committing to the image. Keep essential product features, packaging and brand marks away from vulnerable edges.
    • Sequence: Match the two scenes in visual logic. Similar lighting, color and subject scale can help the transition feel intentional.
    • Copy space: Leave enough uncluttered area for overlays. Text placed over detailed packaging or a busy background may technically fit while remaining hard to read.
    • Brand accuracy: Use images that represent the product or service as it is actually sold. The generated asset should not imply a feature, finish, result or offer that the landing page cannot substantiate.
    • Face restriction: Remove any candidate that contains a face before you build around it, because that image cannot be used in this particular creation flow.

    Prepare these inputs as a small asset set rather than hunting through the library during generation. For each scene, keep an approved horizontal, vertical and square crop with consistent naming. That makes later iterations faster and reduces the chance that one format quietly uses a different concept.

    Build the asset in Google Ads, then inspect every frame

    A reviewer examines individual video frames and three aspect-ratio previews on a workstation.

    The Google Ads workflow lives in Asset Studio. Once your images and message are ready, the mechanical part is short:

    1. Open Asset Studio in your Google Ads account and go to Create videos.
    2. Select Create video from images.
    3. Choose a five- or 10-second duration. Use the shorter option only when the idea remains understandable without rushing the transition or text.
    4. Select the first image from your asset library for scene one and the second image for scene two.
    5. Review the two animation options supplied for each scene and choose the combination that keeps the focal subject clear.
    6. Select a video template and add the text overlays.
    7. Review the completed preview in the intended aspect ratio.
    8. Upload the result to a private YouTube channel or your brand’s YouTube channel, then use it as a Short in PMax or Demand Gen.

    The two available animation choices may not create radically different concepts. That is another reason to solve the story in the still images first. Choose animation based on clarity: the best option is the one that directs attention to the subject without obscuring the product or making the transition feel disconnected.

    Make the text earn its limited space

    You receive two headlines of up to 30 characters each, while the business name is the first text shown. Repeating the brand name in either headline usually wastes space that could explain why the viewer should care.

    A useful division of labor is:

    • Headline one: State the single benefit, differentiator or relevant use case.
    • Headline two: Add the most important qualifier, offer or next action.

    Write both lines before selecting a template. Count every character, then remove words that merely announce the ad. Phrases such as “introducing,” “learn more about” and a repeated business name consume room without adding a reason to continue. The image should establish the object; the copy should supply meaning the image cannot.

    Review the preview as a finished ad

    A polished transition can distract you from small errors. Pause through the preview and check the things a customer will actually see:

    • Does the product retain the correct shape, label, color and identifying details?
    • Is the focal subject visible throughout the animation rather than only in the opening frame?
    • Does the transition preserve the intended relationship between scene one and scene two?
    • Can both headlines be read comfortably without competing with the busiest part of the image?
    • Are the business name and headlines complementary rather than repetitive?
    • Does every visual and written claim match the destination page?
    • Does the crop remain clean in the specific horizontal, vertical or square version you are reviewing?

    Repeat that inspection for all three formats. Approval of the horizontal asset does not prove that the vertical crop is safe. If a version weakens the subject or message, change its source crop instead of accepting it merely to complete the set.

    Test the asset by question, not by novelty

    Launching an AI-generated video is not itself a test. A test begins with a question that can change your next decision. You might ask whether motion improves engagement over the existing still concept, whether a different first scene produces more clicks, or whether benefit-led copy brings better website engagement than feature-led copy.

    Change one creative idea at a time

    1. Add the first Veo concept without immediately removing your strongest existing assets. That preserves useful creative while the new asset begins receiving delivery.
    2. Create horizontal, vertical and square versions from the same concept so a missing format does not become the hidden reason for limited reach.
    3. Keep the offer and destination page stable for the first comparison. Otherwise, you will not know whether the video or the surrounding proposition changed the response.
    4. Name the asset so its variables remain visible. A convention such as VEO-10S-916-HOOK-A-COPY-A-V1 records the duration, ratio, hook, copy and version without requiring a separate lookup.
    5. For the next iteration, change either the opening image, the second scene or the overlay message. Changing all three produces another ad, but little usable learning.

    This will not become a perfect laboratory comparison. PMax and Demand Gen can distribute assets across different contexts, and impressions and performance vary by channel. Keep the comparison as consistent as the campaign allows, then interpret the results as directional evidence rather than pretending every variable was controlled.

    Read the full path from delivery to action

    Video performance is available at the asset level. Read the signals in sequence instead of jumping directly to the conversion column:

    • Impressions: First establish whether the asset received meaningful delivery. Low delivery is not enough evidence to call the creative a failure.
    • Engagement: Use this to judge whether the short visual and its opening moment held attention well enough to produce a response.
    • Clicks: Look for evidence that the message created enough interest for the viewer to take the next step.
    • Website engagement: Check whether the post-click behavior supports the promise made in the video. Clicks followed by weak site interaction should send you back to the message-to-page alignment, not automatically to the animation.
    • View-through conversions: Treat these as a sign that exposure may have assisted a later action. They add context, but they should not be treated as proof that the video alone caused the conversion.
    • Direct conversions: Keep them in the evaluation, but do not demand that every five- or 10-second asset behave like a direct-response unit before it can contribute value.

    The pattern between metrics tells you what to change. Delivery without engagement points toward the opening scene or visual hook. Engagement and clicks followed by weak website behavior point toward a mismatch between the ad’s promise and the landing experience. Too little delivery means you need more observation before making a creative judgment. View-through activity with few direct conversions may indicate an assisting role, but it still needs to be considered alongside the rest of the campaign.

    Start with one campaign that has approved, high-quality stills and a genuine video gap. Build one two-scene concept, render it in all three ratios and write down the variable you intend to learn from before launch. Veo’s advantage is not that one generated clip replaces every production need. It is that the next relevant creative iteration becomes easier to make, inspect and improve.

    References


  • How to Use Google Trends Category Filters for SEO

    How to Use Google Trends Category Filters for SEO

    You know which market you want to cover, but you don’t yet know the exact query worth investigating. Starting with a guessed keyword can narrow the research too early and hide the language your audience actually uses.

    Google Trends category filtering gives you a better starting point. You can explore a predefined subject area without entering a query, or apply a category to an existing query when unrelated meanings are contaminating the data. Used carefully, the filter helps you discover topics, diagnose mixed intent, and write more precise content briefs.

    What the category filter changes on the Explore page

    The new Explore page lets you select a predefined category before you enter a query. A category-only view can surface top-searched terms for that subject, region, and timeframe. Google’s example, “All Books & Literature,” shows how broad the starting point can be.

    You can also use a category with a query. That matters when the same word appears in several unrelated fields. The unfiltered view answers, “How are searches for this term behaving across all meanings?” The filtered view asks, “How are searches behaving when this term belongs to the subject we actually cover?”

    That distinction turns the category control into more than a browsing convenience. It gives you two separate research modes:

    • Category first, no query: discover the terms people use within a market before choosing a topic.
    • Query plus category: remove unrelated interpretations from a term you are already evaluating.

    Key takeaways

    • Leave the query blank when you need topic discovery rather than validation of an existing idea.
    • Add a category when a query may carry several meanings or attract different audiences.
    • Keep the region and timeframe unchanged when you compare filtered and unfiltered views.
    • Treat the results as research inputs, not an automatic publishing queue or a promise of rankings.

    Use a category-first workflow to find viable topics

    A researcher examines one cluster in a broad field of grouped topic signals, revealing several connected opportunities.

    A blank-query category scan is most useful before you have committed to a headline, keyword, or content format. It replaces the usual brainstorm-first workflow with a market-first workflow.

    1. Write down the decision you need to make. Decide whether you are looking for a new content cluster, a timely supporting page, a gap in an existing hub, or language for a planned article. Without that decision, a list of popular terms becomes a distraction.
    2. Select the narrowest relevant predefined category. Do this before entering any query. The category should represent the audience and subject you serve, not merely the closest phrase to a product name.
    3. Set the relevant region and timeframe. Match them to the market and planning horizon behind the content decision. Record both settings so that another person can reproduce the research later.
    4. Review the category-specific top searches. Capture the terms as they appear, but do not turn them into headlines yet. At this stage, you are collecting audience vocabulary and recurring subjects.
    5. Group terms by the reader’s underlying job. Terms with different wording may belong to the same need, while similar-looking terms may reflect different intentions. Cluster around problems, decisions, comparisons, definitions, or actions rather than shared words alone.
    6. Shortlist only terms that fit your authority. A term belongs on the content plan when you can identify the intended reader, the problem you can resolve, and the evidence or expertise the page will require.

    Keep a small research record for every shortlisted term: category, region, timeframe, exact term, likely audience, likely intent, existing page coverage, and the next validation step. This prevents a later editor from treating a decontextualized Trends screenshot as a complete strategy.

    Pay attention to the label “top-searched.” It should not be casually rewritten as “fastest-growing,” “newly popular,” or “trending right now.” Those are different claims. Preserve what the view actually shows when you move the finding into a brief.

    Use query-plus-category filtering to expose mixed intent

    One search signal branches into professional and consumer contexts, with a translucent filter isolating the professional branch.

    An apparently strong query can be misleading when people use the same wording in different industries, hobbies, products, or cultural contexts. A category-constrained second pass helps you see whether the broad result represents your audience or a blend of unrelated searches.

    1. Run the query without a category and note the region and timeframe.
    2. Run it again with the intended category while leaving the other settings unchanged.
    3. Compare the overall pattern and the related language shown in each view.
    4. Flag any important difference for editorial review rather than assuming the broad view was wrong or the filtered view is complete.

    If the category-constrained view changes substantially, treat that as a warning that the unfiltered query may contain demand from outside your market. The practical response is not merely to change the chart in a report. Tighten the planned page’s scope.

    State the intended meaning in the title, opening, headings, and supporting terminology. Name the audience when it prevents ambiguity. Define specialized terms before using abbreviations. Link to the part of your site that establishes the surrounding subject. These choices help readers and automated systems understand which interpretation the page supports.

    A predefined category will not always mirror your business structure. Your site might organize content by customer type, use case, product line, or funnel stage, while Google Trends uses a broader subject taxonomy. Use the filter as a lens on search behavior; do not force it to become your navigation or WordPress category system.

    Turn a Trends finding into a useful SEO content brief

    Category filtering can make the input cleaner, but it cannot decide whether a page deserves to exist. Nothing in the category view tells you that repeating a term will improve rankings, win an AI citation, or produce a qualified customer. The editorial decision still depends on whether you can answer a real need better than your current content does.

    For each shortlisted term, make the brief answer these questions:

    • Who is searching? Describe the intended reader narrowly enough that an editor can reject material written for a different audience.
    • What decision or task brings them to the page? Replace a vague topic such as “learn about X” with a specific outcome, such as choosing an approach, fixing a problem, or understanding a constraint.
    • Which meaning is in scope? Carry the category context into the page’s terminology, examples, related entities, and exclusions.
    • What deserves a new page? Check whether an existing article should be expanded before adding another URL that competes for the same intent.
    • What evidence will support the answer? Identify the primary documentation, data, examples, or expert input required before drafting.
    • Which page format matches the need? A definition, procedure, comparison, reference page, and opinion piece solve different reader problems even when they share a term.
    • Where does the page belong? Specify its parent hub and the existing pages that should link to it. A discovered term is more useful when it strengthens a coherent subject area.
    • Which structured data describes the finished page? Choose schema from the visible content and actual page type. Do not place a Google Trends category label in JSON-LD merely because it was part of the research.

    This is also where category filtering becomes relevant to AEO and GEO work. The filter can help you identify the intended subject and vocabulary, but the page itself must make that scope explicit. Clear definitions, consistent entity names, direct answers, descriptive headings, and accurate structured data reduce ambiguity without pretending that a trend is a ranking factor.

    Avoid the mistakes that make filtered data look decisive

    The category control narrows a dataset. It does not remove the need for judgment. Watch for these failure modes:

    • Choosing the nearest-sounding category without inspecting the results. A predefined label may be broader or narrower than your actual market. If the returned terms repeatedly fall outside your audience, reconsider the category rather than discarding each term individually.
    • Changing several settings between runs. If you change the category, region, and timeframe together, you cannot tell which choice caused the difference. Change the category while holding the other settings steady.
    • Publishing every top-searched term. Search activity does not create expertise, strategic fit, or a useful angle. Reject terms that you cannot serve with a clear reader outcome.
    • Treating a category view as a business forecast. The view can inform topic research, but it does not establish whether a term will convert, support a product, or justify production cost. Make those decisions with the relevant business and audience evidence.
    • Confusing the research taxonomy with the site taxonomy. A Trends category helps isolate meaning. Your site structure should still reflect how readers navigate your subject and how your pages relate to one another.
    • Skipping the blank-query view. Entering your usual keywords first can reproduce the assumptions already embedded in your content plan. A category-only pass gives unfamiliar language a chance to appear.

    Use a simple acceptance rule: a Trends term earns a content brief only when it survives three checks — it belongs to your audience, maps to a specific problem or decision, and can be supported by a page with a distinct purpose. Everything else remains a research note.

    On your next planning pass, run one category-only exploration and one category-constrained query audit. Save the category, region, and timeframe with every finding. Then advance only the topics for which you can write a clear audience, scope, outcome, and evidence requirement. That is enough to turn a useful filter into a repeatable editorial decision.

    References

  • Google Ads Automation: Keep Control of PMax and AI Creative

    Google Ads Automation: Keep Control of PMax and AI Creative

    You’re being asked to trust Google Ads with two decisions that used to sit squarely with your team: where a campaign pursues conversions and how it produces enough video for every placement. The danger isn’t automation itself. It’s treating automated output as a strategy.

    A better operating model is emerging. You can influence the economics behind Performance Max channel selection while using Asset Studio to expand your creative. The practical challenge is to give each system a narrow brief, separate distribution decisions from creative decisions, and keep a human accountable for the result.

    Use PMax channel adjustments as economic guardrails

    Four advertising channel pathways pass through adjustable gates controlled by a human hand before reaching a shared conversion hub.

    The experimental Performance Max Channels setting is described as an alpha test, so it may not appear in your account. Where available, it appears to offer positive and negative adjustments for Search, YouTube, Display, Discover, Gmail, and Maps.

    The most important distinction is what those adjustments do not provide. They do not assign a fixed share of your budget to a channel. If your requirement is an exact percentage for Search or YouTube, this setting does not satisfy it.

    Instead, the control changes the economics Performance Max uses when deciding where to pursue conversions. A positive adjustment relaxes the CPA the system is willing to accept for that channel. A negative adjustment tightens it. You are telling the system that conversions from one channel deserve more or less tolerance, not reserving a pot of money for that inventory.

    That makes the setting a guardrail, not a media plan. Use it only after you can state why the business values a channel differently from the value implied by its directly attributed CPA.

    1. Confirm that the Channels setting is available in the specific campaign. Because the feature is in alpha testing, absence from the interface is not necessarily a setup error.
    2. Record the current channel view before changing anything. Capture where the campaign serves, where it spends, and what performance the reporting attributes to each channel.
    3. Write a one-sentence hypothesis. For example: YouTube introduces qualified prospects whose later Search conversions are not fully represented in YouTube’s direct CPA.
    4. Select one channel and one direction. Avoid applying positive and negative changes across several channels at once because you will not know which intervention produced the result.
    5. Keep unrelated distribution settings stable while evaluating the adjustment. A simultaneous audience, conversion, or bidding change makes the channel test harder to interpret.
    6. Judge the campaign total as well as the adjusted channel. A lower channel CPA is not a win if overall conversion volume or efficiency deteriorates.

    Positive adjustments also deserve discipline. A strategically important channel is not automatically an efficient place to pursue unlimited additional conversions. Treat the adjustment as a reversible hypothesis about value, then check whether the wider campaign behaves as expected.

    Do not punish an assist channel for a last-touch result

    Channel reporting can show where Performance Max served and spent, but channel-level performance is not the same thing as channel-level value. A person might first encounter your brand on YouTube and later convert through Search. If Search receives the visible conversion credit, YouTube can look less valuable than its contribution to the journey.

    This is the main risk of the new control. Aggressively tightening an upper-funnel channel can reduce the demand that another channel captures. The apparent improvement inside one reporting row may conceal damage elsewhere.

    What you observeWhat it may meanSafer next move
    Direct CPA looks poor, but the channel commonly appears early in customer journeysThe channel may be assisting conversions credited elsewhereExamine the campaign-level result and cross-channel journey before applying a negative adjustment
    A channel receives substantial emphasis without a clear business or journey roleThe current allocation may not reflect how you value its conversionsWrite the business case, then test a tighter and reversible adjustment rather than making a broad cut
    A channel’s conversions are more valuable to the business than direct CPA impliesThe system may be applying less tolerance than your strategy warrantsConsider a positive adjustment and evaluate whether the wider campaign gains enough value to justify it
    Channel performance changes immediately after new video assets are introducedCreative quality and channel allocation are now confoundedSeparate the asset question from the distribution question before changing channel economics

    Before reducing a channel, ask three questions. Does it create demand or mainly capture existing intent? Do customers encounter it before the channel that records the conversion? Did its performance change because of allocation, or because the assets serving there became weaker? If you cannot answer those questions, the control is ahead of your diagnosis.

    This does not mean every apparently weak channel should be protected. It means the burden of proof is higher than one unattractive CPA figure. Your decision should reflect the channel’s role in the journey and the effect on the whole campaign.

    Build AI video with locked inputs and human approval gates

    A creative director reviews generated video frames produced from locked product, color, storyboard, and setting inputs before release.

    Gemini Omni in Google Ads Asset Studio addresses a different bottleneck: producing enough video variations for creative-heavy campaigns. The workflow can take brand guidelines, a website URL, a creative brief, and existing static assets, then generate concepts, storyboards, and motion scenes.

    Google says the model reasons about scene progression while attempting to preserve the supplied visual identity and tone. Treat that as assistance, not approval. Brand-aware generation can reduce repetitive production work, but someone on your team still needs to verify what the finished video says, shows, and implies.

    Use the four-stage workflow as a series of approval gates:

    1. Establish the brand. Import the guidelines and website URL, then identify the elements that cannot drift: logo treatment, colors, typography, tone, product representation, and prohibited claims.
    2. Generate concepts. Start from a clear prompt or existing creative. Ask for distinct concepts tied to one audience, one proposition, and one campaign objective rather than a large collection of loosely related scenes.
    3. Refine the creative. Use follow-up prompts to change individual scenes, backgrounds, styling, voiceovers, pacing, and aspect ratios. The system retains context from earlier instructions, so revisions can be incremental instead of complete rebuilds.
    4. Deploy the approved assets. Finished videos can move from Asset Studio into Demand Gen, Performance Max, and other Google or YouTube campaigns. Export only after each required format has passed review.

    Write prompts as production instructions

    A broad request for an engaging brand video leaves too many decisions to the model. Give it the same information a production team would need:

    • The audience and the action the video should support.
    • The single proposition the viewer should understand.
    • The approved proof, product details, and offer conditions that may appear.
    • The visual and verbal elements that must remain locked.
    • The required scene order, voiceover role, and pacing.
    • The placements and output formats you need.
    • The elements that must not be invented, altered, or implied.

    For later revisions, identify the exact scene and the exact variable to change. Ask for a new background without changing the product, or revise voiceover pacing without replacing the visual sequence. That preserves useful context and makes human review much easier.

    Asset Studio can generate both horizontal 16:9 and vertical 9:16 videos. Inspect them separately. A vertical version is not approved merely because the horizontal version works; cropping, text placement, scene composition, and visual emphasis can all behave differently.

    Before deployment, use this approval checklist:

    • Every claim, product detail, and offer condition agrees with the destination page.
    • Logos, colors, typography, and tone follow the supplied brand rules rather than approximating them.
    • The product or service is represented accurately throughout the motion sequence.
    • Scene transitions remain coherent after prompt-based edits.
    • Voiceover wording, pronunciation, pacing, and tone have been reviewed by a person.
    • The 16:9 and 9:16 outputs have each been inspected in their own composition.
    • A named owner has approved the final asset for campaign use.

    The efficiency gain comes from generating and revising variations inside the campaign workflow. It should not come from removing the quality gate that protects your brand.

    Run distribution and creative as two clean learning loops

    Channel controls and AI creative belong in the same operating system, but they should not be changed in the same experiment. One changes where Performance Max is willing to pursue conversions. The other changes what people see when the campaign reaches them.

    If you introduce new videos and tighten YouTube at the same time, a performance change will not tell you whether the creative helped, the channel adjustment hurt, or the algorithm reallocated activity elsewhere. Separate the work into two loops:

    • Distribution loop: Keep the approved asset set stable, make one channel adjustment, and evaluate both the channel view and total campaign result.
    • Creative loop: Keep channel adjustments stable, introduce controlled creative variants, and evaluate whether the new assets improve the outcome on the inventory where they can serve.

    The existing channel-level Performance Max reporting gives you the visibility needed to form a distribution hypothesis. It does not remove the need to account for assisted journeys, conversion lag, or simultaneous creative changes.

    A practical sequence looks like this:

    1. Save the current channel view and identify the active asset set.
    2. Choose whether the next question concerns distribution or creative quality.
    3. Write the expected mechanism before making the change. State what should improve, where it should improve, and what wider result must not deteriorate.
    4. Change one class of variable. Keep creative stable during a channel test and channel controls stable during a creative test.
    5. Review the channel result in the context of the complete campaign rather than accepting a single reporting row as the answer.
    6. Record whether you will keep, reverse, or revise the change, along with the evidence behind that decision.

    Your decision log does not need to be elaborate. Record the campaign, conversion goal, channel, adjustment direction, business rationale, active asset version, observed channel result, overall campaign result, and final decision. That is enough to stop future optimizations from becoming a chain of undocumented reactions.

    Maintain two briefs as well. The distribution brief should define conversion value, channel roles, and the reason for any adjustment. The creative brief should define audience, proposition, approved proof, brand rules, required formats, and approval ownership. Neither brief can substitute for the other.

    Key takeaways

    • Performance Max channel adjustments influence acceptable CPA economics; they do not reserve fixed budget percentages.
    • The Channels setting is in alpha testing, so availability may differ by account or campaign.
    • A channel’s direct CPA can understate its contribution when it introduces people who later convert through another channel.
    • Make one channel adjustment at a time and evaluate the total campaign, not only the adjusted channel.
    • Gemini Omni can generate and refine multi-format video from brand inputs, briefs, URLs, and existing assets, but every output still needs human approval.
    • Keep distribution tests and creative tests separate so each result can answer a specific question.

    Start with one Performance Max campaign. Capture its current channel view and asset set, then write one distribution hypothesis and one creative hypothesis. Choose only one to test first. If the channel control is not available, keep the hypothesis ready; if Gemini Omni is available, use it to create controlled variants without bypassing review.

    References

  • How to Build Situation-Based Content Briefs for SEO and AI

    How to Build Situation-Based Content Briefs for SEO and AI

    You have the keyword list, competitor headings and target word count. The writer follows the instructions. The finished draft is still generic, because nobody defined the moment that brought the reader to the page.

    A situation-based content brief fixes that gap. It identifies what changed for the reader, what they need to decide, what constrains them and what useful progress looks like. Keywords still matter, but they support the assignment instead of becoming the assignment.

    Key takeaways

    • Start with one recognizable audience situation, not a cluster of loosely related keywords.
    • Document the situation through seven lenses: why, when, where, while, with whom, with or for what, and how the reader is feeling.
    • Record where each audience insight came from so writers and subject-matter experts can verify it.
    • Use keywords to capture audience language and discoverability, not as a substitute for intent, context or editorial judgment.
    • Measure whether the content helped the intended reader progress, using visibility and engagement metrics as supporting evidence.

    A keyword is evidence, not the assignment

    A keyword tells you that a phrase may be searched. It rarely tells you why this person is searching now, what they already understand or what they will do with the answer.

    Consider the keyword content brief template. It could come from an SEO lead trying to standardize agency output, an in-house marketer repairing a disappointing draft, a freelancer preparing for a new client or an editor evaluating a briefing tool. The words are similar. The work each reader needs to complete is not.

    If you brief all of those readers at once, the writer has to average them together. That usually produces a long introduction, a universal checklist and little help at the point of decision. Pick one primary situation. Treat other situations as separate assignments unless they require substantially the same answer.

    Broad informational queries create another trap. A basic factual question may be more credibly answered by the organization that defines the rule, standard or process. Chasing that query can bring impressions without demonstrating the specialist expertise your prospective customer needs. Before approving it, ask why your brand deserves to answer, which qualified audience it serves and what meaningful next question you can resolve.

    This distinction matters even more in conversational search. People can describe the trigger, constraints and desired outcome in a full prompt rather than compressing everything into a short phrase. Content planned around that situation is better equipped to answer the main question and the follow-up questions that naturally accompany it.

    Use this gate before a topic becomes a brief:

    • Trigger: What happened that made the reader seek help now?
    • Decision: What must they choose, understand, fix or complete?
    • Constraint: What limits their options, confidence, time or authority?
    • Consequence: What goes wrong if they get an incomplete answer?
    • Brand fit: What relevant expertise, evidence or tool can your organization contribute?

    If you cannot answer those questions, you have a keyword opportunity but not yet a defensible content assignment.

    Capture the situation through seven practical lenses

    Seven translucent lenses reveal different details around a person standing in a constrained decision situation.

    The most useful briefs describe the audience moment through seven situational prompts. They force you to move beyond a persona label and document the conditions shaping the reader’s need.

    LensQuestion to answerWhat belongs in the brief
    WhyWhy is the reader looking for help?The trigger, desired progress and consequence of getting it wrong.
    WhenAt what point in a process or decision does the need appear?The stage, deadline pressure or event that changes the answer.
    WhereIn what environment will the reader find or use the information?The relevant channel, workplace, device context or operational setting.
    WhileWhat else is happening at the same time?Competing tasks, interruptions, dependencies or parallel decisions.
    With whomWho else affects the decision?Approvers, collaborators, customers, advisers or family members who shape the outcome.
    With or for whatWhat object, task or outcome is involved?The product, service, document, system or goal the reader is working with.
    How feelingWhat is the reader’s emotional state?The level of confidence, urgency or caution the tone and ordering should respect.

    Keep each answer short enough to guide a writer. Panicked is not useful by itself. Panicked because the filing deadline is close and the records are incomplete tells the writer to lead with triage, separate urgent actions from later improvements and avoid a leisurely history lesson.

    Emotion should change the delivery, not become an excuse for melodrama. A cautious evaluator needs explicit trade-offs and verification points. A beginner needs terminology introduced before it is used. A reader in the middle of a live failure needs the recovery sequence before background explanation.

    Get the answers from people close to the audience

    Sales, support, account management, in-store staff and public-facing specialists hear the language people use before it is cleaned up for a keyword tool. Ask them for recurring questions, misunderstood terms, objections, failed attempts and the point at which people usually request help.

    Capture traceability beside the insight. Record the team or role that supplied it, the evidence window and any place where the wording can be checked. If an entry is an assumption, label it as an assumption and assign someone to validate it. An unsupported guess does not become audience research merely because it appears in a template.

    Analytics and search data can then validate or refine the language. Internal site search, relevant query data and on-page behavior may reveal how people phrase the need or where an existing answer loses them. They cannot independently explain the entire situation, so interpret them alongside frontline evidence.

    Choose which situations deserve content

    You do not need a page for every situation your team can name. Prioritize a situation when four conditions line up:

    • There is credible evidence that the situation occurs among people the organization wants to serve.
    • The reader has a consequential question or decision, not merely passing curiosity.
    • Your organization has a legitimate reason to answer through expertise, evidence, experience or a relevant offering.
    • Existing content does not already solve the same problem adequately.

    Review search demand after those conditions, not before them. Demand can help you choose vocabulary, estimate discoverability and prioritize between otherwise worthwhile opportunities. It cannot make a poorly matched audience situation strategically useful.

    Turn the situation into a production-ready brief

    A strategist and writer connect an audience decision scenario to evidence, content modules, and a structured blank brief across a workspace.

    A persona describes who someone generally is. A situation explains why that person needs this content now. Your writer needs both only when both alter the answer; a broad demographic profile that changes nothing should not occupy half the brief.

    Write the core scenario as a single sentence using this pattern: person + trigger + progress needed + important constraint.

    For example: An in-house content lead has received another generic draft from an external writer and needs to repair the briefing process before assigning the next topic, without replacing the team’s existing keyword workflow.

    That sentence gives the assignment boundaries. The reader does not need a beginner’s definition of keyword research or a wholesale content-operations redesign. They need to identify what their brief is missing and update it before the next handoff.

    Copy this structure into your briefing system

    1. Primary scenario: State the person, trigger, desired progress and constraint in one sentence.
    2. Audience evidence: List the relevant questions, objections or failure points, with the team or evidence source attached to each.
    3. Seven situational lenses: Complete why, when, where, while, with whom, with or for what, and how feeling.
    4. Content job: Label the assignment informational, consideration or transactional, then explain what that means for this reader.
    5. Reader outcome: Define what the reader should be able to do, decide or notice after using the content.
    6. Primary and follow-up questions: Write the central question and the next questions that arise once it is answered.
    7. Scope boundaries: State what belongs, what does not and which adjacent situations need separate coverage.
    8. Suggested outline: Order sections by the reader’s decision process, not by competitor heading frequency.
    9. Evidence requirements: Identify claims that need subject-matter review, primary documentation, examples or qualification.
    10. Search language: Add the primary query, useful variants, named entities and terminology the audience actually uses.
    11. Answer design: Specify where a direct answer, ordered process, comparison, definition, example or caveat would help.
    12. Existing coverage: Note pages to update, consolidate, distinguish or link rather than creating an isolated duplicate.
    13. Tone and depth: Explain what the reader already knows, how urgent the need is and which details would be excessive.
    14. Next action: Give the writer a useful, situation-appropriate destination for the reader.
    15. Success measure: Name the primary outcome and the supporting signals you will inspect.

    Length guidance comes after the content job and outline. A fixed word count chosen before the situation is understood encourages padding or omission. Give a range only when your workflow requires one, and make completion of the reader’s task the controlling requirement.

    Use SEO, AEO and GEO requirements without flattening the brief

    Search requirements should make the answer easier to discover and interpret. They should not drag the writer back to a keyword-shaped page.

    • Use the primary query and variants to represent audience language, then map each phrase to a real question in the scenario.
    • Name important entities and relationships explicitly instead of relying on vague pronouns or implied context.
    • Place a concise answer close to the question it resolves, then add reasoning, conditions and examples.
    • Turn genuine sequences into ordered lists and genuine comparisons into tables. Do not impose those formats on ideas that require prose.
    • State assumptions and limits where the correct answer changes by stage, system or circumstance.
    • Connect the page to earlier and later journey content through relevant internal links.
    • Add structured data only when it accurately represents visible content. Schema cannot compensate for an answer the page never provides.

    This structure can help a search engine or AI system identify a direct answer and its supporting context, but it does not guarantee a ranking, citation or recommendation. The brief still needs credible evidence, clear language and a reason for your brand to be included.

    Measure whether the intended reader made progress

    Traffic is not the same as success. A broad page can collect impressions from people outside the intended situation, while a narrower page may help a smaller but more relevant audience take the next step. Define that step before publication.

    Choose one primary measure tied to the scenario, then use diagnostic metrics to understand the result:

    • Visibility: Inspect impressions and discovery for the relevant query family, not only the highest-volume phrase.
    • Engagement: Review scroll depth and interaction with the section, template, comparison or tool that performs the content’s main job.
    • Progress: Track the next action that fits the situation, such as continuing to a decision page, using a resource or beginning an appropriate contact path.
    • Operational usefulness: Ask the frontline team whether the content answers the recurring concern accurately and whether important questions remain unresolved.
    • AI visibility: If GEO is part of the goal, use a fixed set of prompts that represent the scenario and record whether the page or brand appears in a relevant answer. Treat individual outputs as directional observations rather than a guaranteed result.

    To test the briefing method, create a conventional keyword-led brief and a situation-led brief for comparable assignments. Evaluate the resulting drafts against the same rubric: scenario clarity, answer order, scope control, evidence requirements, search usefulness and next-step fit. If your website experimentation setup supports a valid split, you can also compare on-page behavior. Otherwise, avoid calling unlike pages an A/B test.

    Do not select a winner from raw impressions alone. Different topics can have different demand, and an impression does not show that the right reader received a useful answer. Read visibility, engagement and progress together, then document what changed in the next brief.

    Take one topic already waiting in your editorial queue and pause before outlining it. Complete the seven situational lenses, name the evidence behind them and choose the reader’s next decision. If your team cannot do that yet, the next task is an audience conversation, not another keyword export.

    References


  • Curiosity-Driven Social Ads: A Practical Creative System

    Curiosity-Driven Social Ads: A Practical Creative System

    Your ad stops the thumb, but viewers leave as soon as the opening gives way to a familiar product pitch. The hook worked. The rest of the ad did not give them a reason to stay.

    The fix is not a louder opening or more frantic editing. You need a controlled sequence of questions, partial answers, proof, and payoff. That sequence turns a moment of attention into enough interest for someone to understand the offer and decide whether it is relevant.

    Key takeaways

    • A hook earns a pause. Curiosity earns the next few seconds by creating a question the viewer genuinely wants answered.
    • Build one primary information gap, then close it through a sequence of useful revelations rather than withholding the answer until the final frame.
    • Give creators a planned beat sheet but room to choose their own words. Natural delivery and deliberate structure can coexist.
    • Judge creative with retention, completion, replay, save, share, click, and conversion signals. No single metric tells you whether the ad is commercially effective.
    • Test the opening, revelation sequence, demonstration, and product transition separately so you can identify the part that changed performance.
    • Curiosity must repay attention. If the resolution is vague, irrelevant, or weaker than the promise, the ad becomes clickbait and trust falls with it.

    Build a curiosity chain, not a single hook

    Four connected tabletop scenes progressively reveal, demonstrate, and show the use of an unbranded product.

    Attention is an event: someone notices an unusual visual, a sharp line, or an unexpected result. Curiosity is a continuing state: the viewer notices that something remains unresolved and chooses to follow it.

    That distinction matters because Meta and TikTok increasingly use AI-powered delivery systems that respond to engagement, watch time, and downstream conversion behavior. An opening that produces a brief pause but immediate abandonment gives those systems less evidence of sustained interest than an ad people actively choose to finish, replay, save, share, or click.

    A curiosity gap is the distance between what the viewer knows and what they now want to know. It might be the cause of an unexpected result, the missing step in a demonstration, or whether a solution worked under a condition that resembles their own. It should not be a random mystery pasted onto an unrelated offer.

    Write the curiosity brief before the script

    Before anyone records, answer the following in plain language:

    1. What should the viewer understand by the end? Write the commercial conclusion without slogans. If you cannot state it clearly, the creative will wander.
    2. What question will carry the ad? Choose one primary question, such as why a familiar approach failed, what caused a surprising outcome, or whether a particular method can solve the viewer’s problem.
    3. Why does that question matter to this audience? Connect it to a recognizable frustration, risk, desire, or decision. Curiosity without relevance produces empty viewing.
    4. What evidence will resolve it? Select the demonstration, observation, comparison, explanation, or experience that makes the answer credible.
    5. Where does the product belong? Introduce it when the viewer can understand its role, not merely because the logo is due to appear.
    6. What is the complete payoff? State the answer you owe the viewer. The ending must satisfy the question created at the beginning.
    7. What should happen next? Match the call to action to the level of intent the ad has earned.

    This brief prevents a common mistake: opening with a compelling problem and then abandoning it for a feature list. Every beat should either advance the answer, provide proof, or help the viewer decide whether the answer applies to them.

    Use a question-and-answer ladder

    Do not keep one answer locked away while padding the middle. Give the viewer useful progress. Each beat can close a small question while opening the next logical one:

    • Opening tension: What happened, and why is it unexpected?
    • Relevant context: Why was the outcome a problem worth solving?
    • First revelation: What obvious explanation turned out to be incomplete?
    • Mechanism or demonstration: What was actually happening?
    • Product connection: How did the product change the process or result?
    • Resolution: What should the viewer conclude from what they have seen?
    • Next step: What can an interested viewer do now?

    The sequence should feel inevitable. If you remove the product and the opening story still reaches the same conclusion, the connection is probably too weak. If the product appears before the problem has meaning, the ad will feel like a disguised sales pitch.

    Make creator ads sound natural without leaving them to chance

    Conversational creator ads work differently from compressed brand spots. Longer, less polished creator videos are sometimes called yapper ads. They may move through a personal experience, an explanation, or a demonstration before naming the product. Their apparent looseness can make them feel like content someone chose to share rather than a commercial recited at them.

    That does not mean you should ask a creator to improvise the strategy. Most people will either disclose the conclusion too early, drift away from the main question, or remember the selling points and forget the promised payoff.

    Give the creator a beat sheet rather than a word-for-word script. Specify what each beat must accomplish, the evidence that must appear, any claim boundaries, and the final action. Let the creator choose the connective language, pauses, examples, and conversational rhythm.

    A reusable creator beat sheet

    1. Start inside the problem. Open with the moment the creator noticed something was wrong, surprising, or inconsistent with what they expected.
    2. Make the consequence concrete. Explain why the situation mattered without inflating the stakes.
    3. Show the first attempt. A failed assumption or incomplete fix gives the eventual answer context.
    4. Reveal the missing mechanism. Explain what changed the creator’s understanding of the problem.
    5. Demonstrate the product’s role. Show the action, process, or result instead of substituting adjectives for evidence.
    6. Close the original question. Return to the tension from the opening and provide a definite resolution.
    7. Invite the next step. Use a call to action that follows naturally from the resolved problem.

    A useful opening pattern is: I thought the obvious fix would solve this problem, but it made this specific symptom worse. The next beat must explain what happened. It cannot jump directly to a product name and leave the contradiction unresolved.

    Another workable pattern begins with a visible result, then asks what produced it. The demonstration supplies the answer in stages. This is especially useful when the product has a behavior viewers can see, because the proof becomes part of the story rather than a claim delivered over unrelated footage.

    During recording, capture complete thoughts and natural pauses. In editing, remove repetition but preserve the cause-and-effect chain. A jump cut should move the explanation forward, not create artificial urgency. The goal is not to make a conversational ad slow; it is to give each second a clear job.

    Protect the line between curiosity and clickbait

    Every open loop creates a debt. The viewer gives you time because the ad implies that an answer is coming. Honest curiosity repays that debt with an explanation, result, or demonstration that is useful even if the viewer does not buy.

    Clickbait uses the same surface mechanics but breaks the exchange. It exaggerates the opening, delays a simple answer without adding value, or resolves the story with information that has little to do with the promise. The problem is not merely tone. A disappointed viewer can abandon the video, ignore the call to action, or carry their distrust to the brand.

    Run a promise-payoff check

    Review the finished ad without sound first, then read its transcript without the visuals. In both passes, ask:

    • Can you state the opening promise in one sentence?
    • Does the middle provide meaningful progress, or does it merely postpone the answer?
    • Is the final answer specific enough to satisfy the opening?
    • Does the proof support the conclusion the viewer is asked to draw?
    • Is the product essential to the resolution, or has it been attached to an unrelated story?
    • Would a reasonable viewer feel that the time spent watching was respected?
    • Does the call to action follow from the evidence, or does it demand more confidence than the ad earned?

    Also inspect every transition. A strong transition answers one question and introduces the next. A weak transition changes the subject. When the ad jumps from a personal problem to a generic feature montage, curiosity collapses because the viewer can already predict the rest.

    Do not manufacture uncertainty around information the audience needs to evaluate the offer. The mystery should concern the story or mechanism, not whether the ad will eventually disclose a meaningful condition. The more consequential a fact is to the buying decision, the less useful it is as a tease.

    Measure the whole attention-to-action sequence

    A smartphone projects a path of glowing steps through a lens and doorway toward a hand reaching for a product.

    The traditional focus on the first three seconds is still useful, but it answers only whether the opening earned a chance. It does not tell you whether the story sustained interest, the proof created confidence, or the offer produced action.

    Read performance as a sequence of signals:

    • Initial attention: Did viewers stay beyond the opening instead of leaving immediately?
    • Sustained interest: Did watch time and completion behavior indicate that the middle held attention?
    • Active value: Did viewers replay, save, or share the video, including sharing it through direct messages?
    • Commercial interest: Did clicks occur after viewers had enough context to understand the offer?
    • Business outcome: Did the resulting visits produce the downstream conversion the campaign was built to generate?

    Watch time, completion, replays, saves, shares, post-view clicks, and conversions provide different evidence of chosen attention. Read them together. A long watch with no commercial response may mean the story entertained but did not qualify the viewer. A strong opening followed by weak completion points toward a middle that became predictable, repetitive, or disconnected from the hook. Completed views without clicks can indicate that the payoff was satisfying but the product transition or call to action was not persuasive.

    These patterns are diagnostic prompts, not automatic verdicts. Placement, audience delivery, offer, landing experience, and campaign objective can also shape the result. Use the creative signals to identify the next question, then isolate that question in the next test.

    Test one part of the curiosity system at a time

    Begin with a control ad and create variants around a single creative decision. Keep the offer, core message, and other controllable campaign conditions stable where possible.

    1. Test the opening. Keep the body and payoff unchanged while changing the initial tension, visual, or question. This tells you which version earns the strongest entry into the same story.
    2. Test the revelation sequence. Keep the opening constant while changing how the explanation unfolds. Compare direct explanation with demonstration, personal experience, or a problem-and-discovery progression.
    3. Test the proof. Preserve the promise and product role while changing the evidence used to resolve the question.
    4. Test product timing. Introduce the product at different logical points, but do not change the ending. Look for the point at which its appearance feels informative rather than interruptive.
    5. Test the payoff and call to action. Keep the preceding story stable while changing how explicitly the conclusion connects the result to the next step.

    Do not select a winner from the opening signal alone. The variant that stops more people can still attract poorly matched attention or fail to hold it. Compare retention behavior with clicks and downstream conversions, then choose the creative that advances the campaign’s actual objective.

    Keep a simple test record containing the hypothesis, the element changed, the control, the observed retention pattern, and the business outcome. This turns individual ads into reusable knowledge. Without that record, teams often repeat the same hook test while the real weakness sits in the middle of the story.

    Start with one active ad. Print its transcript, underline the question created in the opening, and label the exact line that resolves it. Then mark what new reason to continue appears between those points. If the middle contains no useful progress, rewrite that sequence before producing another hook.

    Automated delivery can decide who receives the next impression. Your controllable advantage is making that impression worth following. Build an honest question, reward each additional second, and let the sale follow from a conclusion the viewer was given enough evidence to reach.

    References

  • How to Build Reusable AI Content Skills That Stay Useful

    How to Build Reusable AI Content Skills That Stay Useful

    You probably have a prompt that everyone on your team is supposed to use. It may be buried in a document, copied from an old chat, or rewritten from memory whenever someone starts a draft. That works until the prompt changes, a rule gets dropped, or two people interpret it differently.

    A reusable AI content skill gives those recurring instructions a stable home. Build it well, and you can spend less time rebuilding prompts while keeping voice, quality, and answer-engine requirements consistent across projects.

    Move durable decisions out of individual prompts

    The first decision is what deserves to become a skill. A useful candidate appears repeatedly, applies across multiple assignments, and should produce a consistent result regardless of who starts the workflow. Saving recurring instructions for reuse can reduce repetition while helping teams apply the same writing style, AEO practices, and content standards.

    Do not turn every long prompt into a permanent asset. Campaign facts, temporary offers, target keywords, product claims, and assignment-specific angles belong in the content brief. If you embed them in a reusable skill, they can quietly leak into unrelated work or become outdated.

    Put in the reusable skillKeep in the content brief
    Brand voice and prohibited languageThe audience for this specific page
    Required content structureThe query, topic, and search intent
    AEO and editorial quality checksApproved facts, claims, and references
    Citation and uncertainty rulesCampaign messaging and calls to action
    Standard output formatDeadlines, owners, and publishing details

    Use a simple test before promoting an instruction: would you want it applied to the next unrelated assignment? If the answer depends on the topic, client, campaign, or date, leave it in the brief.

    Write the skill as an operating contract

    A skill should tell the AI what job it is doing, what information it needs, which rules are mandatory, and how to recognize an acceptable result. Vague instructions such as “write high-quality SEO content” leave too much room for interpretation. Replace them with observable requirements.

    Skill fieldWhat to write
    PurposeThe narrow outcome this skill produces, such as an answer-first educational page.
    Use whenThe assignments that should trigger it, plus cases where it should not be used.
    Required inputsThe audience, intent, approved facts, desired action, and output destination.
    Non-negotiable rulesVoice, claim boundaries, citation requirements, prohibited language, and compliance constraints.
    MethodThe sequence for interpreting the brief, drafting, checking, and revising.
    Output contractThe required headings, markup, metadata, fields, or schema-ready information.
    Quality checksConditions the result must meet before it can be returned.
    Escalation ruleWhat the AI must flag instead of guessing when information is missing or contradictory.

    Write rules so an editor can verify them. “Use a direct answer near the opening” is testable. “Make it engaging” is not. “Link factual claims to approved references” is testable. “Sound authoritative” is not.

    Define priorities before instructions conflict

    Reusable defaults will eventually collide with a project brief. State the order of precedence inside the skill. A practical hierarchy is mandatory legal and brand policy first, assignment requirements next, skill defaults after that, and model discretion last. Adjust that hierarchy to match your organization, but do not leave it implicit.

    Add an escalation rule for unresolved conflicts. The AI should identify the clashing instructions and request a decision rather than quietly choosing whichever wording appeared most recently.

    Separate writing, optimization, and validation

    Three separate workstations represent writing, optimization, and final content validation in a staged workflow.

    One giant skill may look efficient, but it becomes difficult to maintain. A change to your brand voice should not require rewriting your structured-data rules. A new citation policy should not disturb the way product pages are organized.

    Use a small set of focused layers. A voice skill can control tone, sentence style, terminology, and banned phrasing. A content-type skill can define the structure for an explainer, comparison, landing page, or documentation page. An AEO skill can require a direct response to the main question, intent-aligned headings, clear entities, useful follow-up coverage, and supported claims. A validation skill can check the finished draft for omissions and violations.

    Keep validation separate from generation when possible. Asking the same instruction block to draft and approve its own output can hide errors. A dedicated check should compare the result with the brief and return specific failures: an unsupported claim, a missing answer, an inconsistent term, or an invalid output field.

    This separation also makes ownership clearer. Brand teams can maintain voice rules, search teams can maintain AEO requirements, subject experts can maintain claim boundaries, and content operations can maintain formatting. Each group can update its layer without reopening the entire workflow.

    Test the skill against real editorial failures

    A technician tests a modular content system against abstract obstacles representing common editorial failures.

    A skill is not ready because it worked on the prompt used to create it. Test it with representative briefs: a straightforward assignment, an incomplete one, a request that conflicts with brand policy, and a topic where the supplied evidence does not support a confident claim.

    Review the outputs by failure type. Check whether the voice drifted, the answer arrived too late, unsupported details appeared, mandatory fields were omitted, or the AI followed a lower-priority instruction. Record the failure and revise the smallest instruction that caused it.

    Change a single rule at a time when practical. Otherwise, you will not know which revision fixed the problem or introduced a new one. Preserve previous versions and note why each update was made. That turns the skill into a managed editorial asset instead of an anonymous prompt that gradually accumulates exceptions.

    Watch for rules that belong elsewhere

    Repeated exceptions are diagnostic. If editors constantly override the same voice rule for product pages, you may need a separate product-page skill. If factual corrections recur, the problem may be the approved material supplied with the brief rather than the writing instructions. If output fields disappear, strengthen the output contract and validation layer.

    Do not solve every failure by adding more words. Remove duplicated rules, merge instructions that mean the same thing, and replace subjective adjectives with checks an editor can observe. A shorter skill with clear boundaries is easier to trust than a long one full of overlapping advice.

    Key takeaways

    • Save stable, recurring editorial decisions as skills; keep assignment-specific facts and goals in the brief.
    • Define the skill’s purpose, trigger, inputs, mandatory rules, output contract, checks, and escalation behavior.
    • Use focused layers for voice, content type, AEO requirements, and validation so each can be maintained independently.
    • Make every instruction observable enough for an editor to verify.
    • Test against incomplete and conflicting briefs, then revise the smallest rule responsible for each failure.
    • Version skills and record why they changed so teams know which standard is active.

    Start with the instruction block your team copies most often. Remove anything tied to a single assignment, give the remaining rules a clear output contract, and test the skill on work your editors already know well. Once that first skill performs reliably, use the same pattern for the next recurring workflow.

    References

  • How to Align Claude With Your Brand Voice Consistently

    How to Align Claude With Your Brand Voice Consistently

    You ask Claude for a polished draft, but the result sounds like polished AI: competent, smooth, and interchangeable with everyone else’s content. Repeating your preferred tone or asking it to sound more human rarely fixes the underlying problem.

    You need to turn brand voice from a subjective impression into instructions Claude can apply and your team can review. With clear rules, representative examples, and a repeatable editing loop, Claude can reflect your brand voice without merely copying an old draft.

    Translate your brand voice into observable choices

    An editor's hands organize unlabeled sliders, dials, colored tokens, and differently sized blocks on a neutral workspace.

    Words such as friendly, authoritative, bold, and conversational are too open to interpretation. A financial adviser and a fitness coach can both sound friendly while using completely different language, pacing, evidence, and calls to action.

    Build a compact voice card that describes what a writer should do on the page. Cover these areas:

    • Audience: Name the reader, what they already understand, and the decision they are trying to make.
    • Relationship: Decide whether the brand acts as a specialist, teacher, peer, challenger, or reassuring adviser.
    • Sentence behavior: Describe the preferred pace, paragraph length, use of contractions, and tolerance for jargon.
    • Vocabulary: List preferred terms, words that require explanation, and language the brand avoids.
    • Evidence: Explain when claims need examples, data, citations, qualifications, or practical next steps.
    • Point of view: Specify when to use you, we, the company name, or a neutral construction.
    • Formatting: Define how headings, lists, calls to action, and emphasized text should work.
    • Boundaries: Identify tones the brand must never adopt, such as smug, alarmist, vague, or overly promotional.

    Make every rule testable. Replace be clear with explain technical terms on first use. Replace sound confident with state the recommendation directly, then explain its limits. Replace avoid hype with remove unsupported superlatives, urgency, and promises of guaranteed results.

    Add contrast when a rule could be misunderstood. For example: direct, not abrupt; informed, not academic; warm, not chatty; persuasive, not pushy. These boundaries help Claude distinguish your intended voice from a nearby but unsuitable one.

    Choose examples that teach judgment, not imitation

    Examples show Claude how your rules interact in real writing. Use approved material that still represents the brand. A rushed email, an outdated landing page, and an executive’s personal writing style can introduce conflicting signals.

    Label why each example belongs

    Do not paste examples into the prompt without explanation. Mark the behavior Claude should learn from each one:

    • This opening names the reader’s problem before introducing the company.
    • This explanation defines the technical term without talking down to the reader.
    • This transition moves from evidence to a recommendation without overstating certainty.
    • This call to action describes the next step without manufacturing urgency.

    Also distinguish voice from content. Tell Claude that names, claims, prices, dates, product details, and recommendations in an example are not facts for the new draft. They are reference material only for language, structure, and tone.

    Include useful negative examples

    A rejected line becomes valuable when you explain the rejection. Pair it with an approved rewrite and a reason. The reason might be that the original buries the answer, uses an empty superlative, assumes too much knowledge, or turns a measured claim into a guarantee.

    Negative examples work best when they are close to acceptable. Obvious failures teach little. A plausible sentence that misses your voice reveals the boundary Claude needs to recognize.

    Give Claude a prompt with clear layers

    A reliable brand prompt separates permanent voice rules from the current assignment. This prevents campaign details from being mistaken for lasting brand principles and makes the setup easier to reuse.

    Use this sequence when assembling the prompt:

    1. Set the role. Identify the brand, the type of writer Claude should act as, and the responsibility it has to the reader.
    2. Define the reader and outcome. State who the content serves, what brought that person to the page, and what they should understand or do afterward.
    3. Insert the voice card. Include observable language rules, preferred vocabulary, formatting conventions, and prohibited tendencies.
    4. Add annotated examples. Explain which behaviors to reproduce and which factual details not to carry into the new work.
    5. Provide task facts. Supply the brief, approved claims, required links, product information, and any material that must appear.
    6. Set hard constraints. Name the required format, scope, compliance boundaries, and anything Claude must not infer.
    7. Request a self-check. Ask Claude to identify any voice rule it could not satisfy and flag missing facts instead of filling gaps.

    Keep priorities explicit. Accuracy and legal or editorial constraints come before style. Voice rules come before decorative flourishes. Examples demonstrate delivery but do not override the approved facts in the brief.

    If the assignment is complex, ask for an outline before the full draft. Review whether the planned argument suits the reader and brand posture. Fixing a structural mismatch at that stage is easier than polishing an entire draft built on the wrong approach.

    Review voice alignment with evidence

    Do not approve a draft because it feels roughly on-brand. Review it against the voice card and point to the language that passes or fails each rule.

    • Does the opening address the reader’s actual concern, or does it begin with background they did not ask for?
    • Are recommendations stated directly and supported at the level your brand expects?
    • Would the intended reader understand every technical term without leaving the page?
    • Does the draft preserve uncertainty where the available facts are limited?
    • Are paragraphs, headings, and lists consistent with your publishing conventions?
    • Does the call to action offer a relevant next step rather than switching into sales language?
    • Could a competitor publish the draft unchanged? If so, which brand-specific judgment or vocabulary is missing?

    When something fails, give Claude a diagnostic correction. Instead of make this warmer, identify the behavior: the paragraph sounds distant because it uses abstract nouns and never addresses the reader. Ask for a revision that speaks to you, keeps the technical meaning, and removes the abstract phrasing.

    Save recurring corrections as new voice rules. If editors repeatedly remove inflated claims, add an explicit rule about claim strength. If introductions repeatedly take too long to reach the answer, define what the opening must accomplish. Your editing history should improve the system, not disappear into individual drafts.

    Turn a successful prompt into a content workflow

    Two team members inspect content pages moving through a modular workflow of transparent frames, review lenses, and adjustment controls.

    Brand alignment breaks when every writer maintains a different prompt. Store the approved voice card, examples, exclusions, and review checklist in one controlled location. Give the material an owner and update it when the brand changes.

    Separate the workflow into clear responsibilities:

    • Brand owner: Approves voice rules, terminology, and representative examples.
    • Subject specialist: Supplies facts, qualifications, and claims that may be made.
    • Prompt owner: Maintains the reusable instructions and resolves conflicts between them.
    • Editor: Checks the draft against the brief, voice card, and publishing requirements.
    • Approver: Accepts the final communication risk rather than assuming the model has done so.

    Track failures by type. Voice drift, unsupported claims, weak structure, missing context, and formatting errors need different fixes. A voice rule will not repair a thin brief, and another example will not resolve contradictory product facts.

    Test revisions with the same assignment whenever possible. If you change the voice card and the brief at once, you cannot tell which change improved the result. Keep approved outputs as benchmarks, but continue reviewing new drafts; consistency is a managed process, not a one-time prompt.

    Key takeaways

    • Replace broad adjectives with observable rules about wording, structure, evidence, and reader treatment.
    • Use current, approved examples and label the behavior Claude should learn from each one.
    • Keep voice instructions, task facts, examples, and hard constraints in separate prompt layers.
    • Review drafts against explicit criteria and turn repeated editorial corrections into reusable rules.
    • Assign ownership for the voice system so every writer works from the same approved standard.

    Start with one approved asset and extract the decisions that make it sound like your brand. Build the voice card, run a real assignment through it, and record every correction. That gives you something more durable than a good draft: a system your team can improve each time it publishes.

    References

  • How to Reuse Digital PR Pitches Without Sounding Recycled

    How to Reuse Digital PR Pitches Without Sounding Recycled

    Your last successful pitch should not disappear into a sent folder after the coverage lands. It contains a useful asset: a sequence of editorial decisions that persuaded a particular journalist to keep reading, understand the news value, and respond.

    The mistake is to copy that email and swap a few nouns. That preserves the most disposable part of the pitch while carrying stale claims, irrelevant personalization, and familiar phrasing into a new campaign. Effective pitch reuse works at a deeper level. You preserve the reasoning structure, replace every campaign-specific input, and make the new email earn its relevance on its own.

    Reuse the decision path, not the surface copy

    A reusable pitch is a framework for making decisions. It tells you what the subject line must accomplish, how the opening establishes relevance, where the strongest evidence appears, how the facts build an angle, and what the call to action offers the journalist’s audience.

    That distinction matters because almost half of journalists receive six or more pitches a day. When attention is already scarce, faster production isn’t much of an advantage. A pitch still has to be relevant, credible, and easy to evaluate.

    Reuse the parts that govern clarity. Rebuild the parts that determine whether this campaign belongs in this journalist’s inbox.

    Pitch layerWhat you can preserveWhat you must rebuild
    Subject lineThe type of promise, level of specificity, and relationship to the readerThe claim, consequence, wording, and any reference to the recipient
    OpeningThe function it performs, such as establishing editorial relevance before presenting the campaignThe observation, context, and reason this journalist is a fit
    AngleThe logical progression from finding to consequenceThe actual news, audience implication, and timing
    EvidenceThe order in which proof becomes usefulEvery fact, figure, comparison, method note, and supporting asset
    Call to actionA low-friction decision focused on editorial valueThe deliverable, access, expert, visual, dataset, or next step being offered

    Personalization deserves particular care. You can reuse the principle that the opening should feel written for one recipient. You cannot reuse the personal detail itself. A reference to someone’s interests, work, or public comments should be accurate, current, proportionate, and connected to the pitch. If the detail has no editorial purpose, it can feel ornamental or intrusive rather than thoughtful.

    The same rule applies to tone. Preserve your recognizable voice, but don’t preserve sentences simply because they once worked. Voice is a set of choices about directness, rhythm, detail, and restraint. Copy is the temporary expression of those choices.

    Extract the reusable pattern from a proven pitch

    A blank pitch page is separated into symbolic modules for news value, evidence, relevance, and a next step on a worktable.

    A reply or placement tells you that the whole combination worked in one situation. It doesn’t prove that the subject line, personal opening, evidence order, or call to action caused the result by itself. The story’s strength, the journalist’s schedule, an existing relationship, and timing may also have mattered.

    Treat the first extraction as a hypothesis, not a universal template. Your job is to identify the likely functions inside the pitch and then see whether those functions remain useful in another campaign.

    1. Save the complete context. Keep the final subject line and body alongside the campaign brief, recipient, outlet, send timing, supporting materials, response, and eventual outcome. A winning email without its context is easy to misread.
    2. Label each unit by its job. Mark the subject line, relevance cue, transition, central claim, proof sequence, reader consequence, asset offer, and call to action. A sentence may perform more than one job, but every sentence should have one clear primary purpose.
    3. Separate structure from content. Replace names, topics, findings, figures, links, and personal details with functional placeholders. If the remaining framework still makes sense, you have found something reusable.
    4. Explain why the order worked. Don’t record only that evidence appeared before the ask. Record why: the recipient needed enough proof to assess the claim before deciding whether the supporting asset was worth opening.
    5. Mark uncertain elements. If you don’t know whether the rapport-building opening contributed to the response, say so in the template notes. This prevents a guess from hardening into a team rule.
    6. Test the pattern in a different context. Keep it provisional until it helps produce a clear, relevant pitch for another campaign. If the structure survives while the topic, evidence, and recipient change, it is more likely to be genuinely reusable.

    The resulting blueprint might look like this:

    • Subject: Express the audience consequence and the fresh evidence or asset behind it.
    • Opening: Establish a truthful reason the journalist may care.
    • Bridge: Move from that relevance cue to the campaign without forcing the connection.
    • News: State the central finding or announcement in plain language.
    • Proof sequence: Lead with the strongest verified evidence, then add only the context needed to interpret it.
    • Reader value: Explain what the finding helps the publication’s audience understand, decide, or notice.
    • Offer: Name the useful material available, such as methodology, visuals, underlying data, an expert, or a product demonstration.
    • Call to action: Ask whether that specific material would help with a relevant story.

    This is more useful than a fill-in-the-blank email. It preserves editorial logic without encouraging the sender to treat a journalist’s name as the only variable.

    Use AI as a constrained adapter

    AI is well suited to mapping sentence functions, proposing alternative phrasing, and adapting a proven sequence to a new brief. It is poorly suited to deciding what is true, whether a personal reference is appropriate, or whether the angle genuinely fits a journalist. Those decisions need verified inputs and human judgment.

    Give the model a controlled packet rather than asking it to write a pitch from the campaign name alone. That packet should contain the approved campaign brief, verified fact sheet, methodology notes where relevant, available assets, audience definition, house-voice constraints, and a short recipient profile based on public professional information. Clearly distinguish confirmed facts from working ideas.

    Reusable prompt: Analyze the successful pitch below by sentence function, not by wording. Create a structural map that explains the purpose of each part. Then adapt that structure to the new campaign brief and recipient profile. Use only facts supplied in the verified fact sheet. Do not carry over names, claims, figures, personal details, examples, or distinctive phrases from the successful pitch. If the new material cannot support a structural element, mark it as [NEEDS INPUT] instead of inventing content. Return the structural map, a concise draft, alternative subject lines, a substitution ledger showing which supplied input supports each factual statement, and a list of relevance or accuracy risks for human review.

    The substitution ledger is the important part. It turns review from a vague question about whether the email sounds good into a traceable check: where did this claim come from, is it approved, and does it mean what the draft says it means?

    Keep generation and personalization separate. First ask AI to build the cleanest version of the campaign argument. Then add recipient-specific context after checking the journalist’s current beat and work. This makes it easier to remove generic flattery and prevents an attractive personal hook from concealing a weak editorial match.

    Before keeping a personalized opening, apply a simple relevance gate:

    • Is the detail accurate and drawn from public professional context?
    • Does it explain why this campaign may suit the journalist’s coverage?
    • Can you connect it to the news without an abrupt or artificial transition?
    • Would you be comfortable explaining why you used it if the recipient asked?
    • Could the same sentence be sent unchanged to a large list? If so, it is probably generic rather than personal.

    AI can also help challenge the blueprint. Ask it to identify sections that depend on the old campaign, places where the logic no longer holds, and phrases likely to sound mass-produced. The goal isn’t to force every new pitch through the old shape. It is to notice when the proven structure helps and when the new story needs a different route.

    Review reused pitches at the fact, recipient, and system levels

    A blank pitch document passes through three inspection stations for evidence, recipient fit, and outreach-system checks.

    A polished draft can still fail in three different ways: it can misstate the campaign, mismatch the recipient, or reveal that your template is spreading stale language across the outreach program. Review each level separately.

    Check the campaign truth

    • Trace every factual statement to an approved input.
    • Confirm that figures retain their original denominator, comparison, scope, and qualification.
    • Make sure the headline claim is supported by the methodology, not merely adjacent to it.
    • Verify that every offered asset, interview, dataset, image, demonstration, or sample is actually available.
    • Remove claims inherited from the old pitch, including subtle carryovers such as timing language or audience assumptions.

    Check the recipient fit

    • Confirm that the journalist covers the subject at the level your angle requires.
    • Read the opening without the recipient’s name. If it now sounds universal, it hasn’t established real relevance.
    • Check that the evidence supports a story for this publication’s audience, not merely a message your organization wants repeated.
    • Make the call to action answerable. Offer a specific editorial resource instead of asking vaguely whether the recipient is interested.
    • Delete rapport-building language that delays the news or relies on a strained connection.

    Check the reuse system

    • Compare the new draft with the successful original and other pitches created from the same blueprint. Shared logic may be intentional; shared distinctive wording usually isn’t.
    • Store the blueprint separately from campaign facts so old evidence cannot be mistaken for reusable copy.
    • Record which structural elements were kept, changed, or removed and why.
    • Track replies, requests for supporting material, declines, placements, and no response without treating any single outcome as conclusive.
    • Revise the blueprint when the same friction appears repeatedly, such as unanswered calls to action or requests for context that should have been supplied initially.

    A good pitch library therefore contains more than examples labeled successful. It contains versioned patterns, the situations in which they were used, the evidence available at the time, and notes about what remains uncertain. That context is what allows a team to learn instead of merely imitate.

    It also protects your voice. If different team members can see the reasoning behind a pitch, they don’t need to mimic one person’s sentences. They can make the same kind of editorial choices in language that suits the new campaign.

    Key takeaways

    • Reuse a successful pitch’s decision structure, not its campaign-specific copy.
    • Preserve functions such as relevance, evidence order, reader consequence, and a low-friction call to action.
    • Replace every claim, figure, personal detail, example, link, and distinctive phrase.
    • Treat one successful send as a useful hypothesis, not proof that every element caused the result.
    • Give AI verified inputs, explicit no-invention rules, and a requirement to flag missing information.
    • Review the output for factual support, recipient fit, and accidental duplication across campaigns.
    • Keep outcome context with each blueprint so your reuse system improves as more pitches are sent.

    Before your next campaign, open the last pitch that earned a meaningful response and replace its sentences with labels describing what each one did. Save that map beside the original, then build the new outreach from verified inputs. You will start with something your team has learned from without making the recipient feel that they have seen it before.

    References


  • Google Maps Contributor Features: A Practical Workflow

    Google Maps Contributor Features: A Practical Workflow

    You have useful photos on your phone and first-hand details about a place, but turning them into a clear Google Maps contribution still takes judgment. The latest contributor features reduce the mechanical work: they surface media sooner, draft captions and make contributor history more visible.

    Use that convenience to publish more useful evidence, not simply more content. A faster upload, an AI-written caption or a prominent badge can attract attention, but none of them can make a vague or inaccurate contribution trustworthy.

    Key takeaways

    • Local Guides profiles now place greater emphasis on total points, levels and badges. Gold profile indicators can make top contributors more noticeable, but prominence is not proof that every contribution is accurate.
    • Gemini can analyze selected photos and propose a caption. You can edit or discard the draft, so treat it as a starting point rather than an observation you must accept.
    • The Contribute tab surfaces recent uploads, while camera-roll suggestions can shorten the path from taking a photo to sharing it. Media access is required for those suggestions.
    • These features may affect which reviews and businesses receive attention. They do not, by themselves, establish a direct improvement in local rankings, AI-search visibility or business performance.

    Match each contributor feature to the job it actually does

    The contributor changes solve three different kinds of friction. Keeping those jobs separate prevents you from treating every feature as a ranking tool.

    • Contributor profiles provide context. The redesigned Local Guides profile displays total points and levels more prominently, gives badges a refreshed presentation and adds gold profile indicators for top contributors. These are reputation and attention signals around a contribution. They do not verify the claim inside it.
    • Gemini caption drafts reduce writing friction. The feature analyzes the photos you select and proposes text that you can edit or reject. Its useful job is getting you past the blank field, not supplying knowledge that the image cannot contain.
    • Media suggestions reduce retrieval friction. Recent uploads appear in the Contribute tab, and Google Maps can suggest camera-roll images after you allow media access. This helps when the obstacle is finding the right photo later.

    If you contribute regularly, test every photo or review without its profile decoration: would the content still help someone choose an entrance, recognize a storefront, understand the layout or set an accurate expectation? If not, more points and a brighter badge will not repair it.

    If you manage local visibility for a business, reverse the test. A gold indicator may cause a user to notice a review, but you should still inspect the review’s specificity, recency and visible evidence. Contributor status is context for evaluating a claim, not a substitute for evaluating it.

    Edit Gemini captions until they say what the photo proves

    A contributor compares a phone photo with a cafe's accessible entrance while editing a draft description.

    At its introduction, the Gemini caption feature was available in English on iOS in the United States. Broader Android and international availability was planned. Availability can therefore differ by device, language and location; keep a manual caption workflow even if another contributor already has the control.

    The most important limitation is conceptual. Gemini can analyze the selected image, but a photo does not necessarily prove how the service felt, how food tasted, whether a route is fully accessible or whether a temporary display will remain in place. The draft can turn a visual impression into a stronger claim than the evidence supports.

    Use a four-pass caption edit

    1. Name the visible subject. Identify the entrance, seating area, menu board, counter, parking area or other feature the photo is meant to show.
    2. Remove inferred praise. Delete generic judgments such as “excellent,” “welcoming” or “perfect” unless the caption is deliberately expressing your own experience and the wording makes that clear.
    3. Add decision-relevant context. Explain where the photographed feature is located or why someone might need to recognize it. Add only details you observed or verified.
    4. Check whether the claim will age badly. Prices, hours, displays and layouts can change. Do not present a time-sensitive detail as a permanent feature.

    For example, a draft such as “A cozy cafe with plenty of seating” is broad and evaluative. A more useful edit would be “Indoor tables are beside the front window, with the order counter at the back.” The second version tells a visitor what the image is intended to establish without pretending that the photo proves comfort, availability or service quality.

    There is also a quick test for generic AI text: ask whether the same caption could be pasted onto a different venue’s photo without anyone noticing. If it could, the caption is not finished. Name the concrete feature that makes this image useful at this place.

    Turn camera-roll suggestions into a controlled publishing queue

    A smartphone displays selected and dimmed place-photo thumbnails arranged as a controlled publishing queue.

    The media-sharing update has a broader footprint than the initial caption rollout. Recent media and camera-roll suggestions were made available on iOS and Android globally. Suggestions depend on granting media access.

    A suggestion is an invitation to review an image, not confirmation that the image belongs on Maps. Camera rolls also contain duplicates, screenshots, private details and photos whose location is ambiguous. Put a short verification step between the prompt and the publish button.

    1. Open the Contribute tab after a visit. Review the recent media while you can still distinguish the venue and remember what each image shows.
    2. Confirm the exact place. Check the name and location, especially when a business has several branches or neighboring listings look similar.
    3. Choose the highest-information image. Prefer a photo that answers a practical question over several nearly identical angles.
    4. Inspect the full frame. Exclude unrelated or sensitive details and any image too blurry, dark or obstructed to support its caption.
    5. Write or generate the caption. Apply the evidence test even when Gemini supplies the first draft.
    6. Read the listing and caption together. Make sure the text describes this image at this place, then publish only when both are unambiguous.

    If you are not comfortable enabling camera-roll access, do not enable it merely to save a few taps. A slower, deliberate selection process is better than a convenient workflow you will not review carefully. You can also revisit the relevant operating-system permissions if your comfort level or contribution habits change.

    Do not mistake contributor visibility for a ranking result

    More prominent contributor profiles, faster media sharing and clearer captions can change what people notice. That can influence which reviews they consider credible and which businesses receive attention. It is still a leap from increased attention to a claim that a feature directly raises a business in Google Maps, local search results or an AI-generated answer.

    Three outcomes need separate measurement:

    • Publishing efficiency: Did the recent-media flow help you turn relevant photos into completed contributions instead of leaving them in a backlog?
    • Contribution quality: Did the final captions become more specific, accurate and useful after editing, or did AI merely increase the volume of generic text?
    • Search or business visibility: Did the business’s observed visibility change after the contribution? If it did, record the timing as a correlation. Do not assign causation without isolating other listing, review, competition and search changes.

    The same restraint applies to AEO and GEO claims. A Google Maps caption may add useful public context around a place, but these contributor changes do not demonstrate that a frontier model will retrieve, cite or rank that caption. Treat any such effect as a hypothesis to measure, not a benefit to promise.

    Start with one recent photo that answers a real visitor question. Verify the place, edit the caption until every claim is supportable and record when you published it. If the workflow consistently produces clearer contributions, keep it. If it only produces more contributions, tighten the review step before you scale it.

    References