Tag: Content Accuracy

  • How to Build Reliable SEO Agents That Verify Their Work

    How to Build Reliable SEO Agents That Verify Their Work

    You ask an SEO agent to audit a site, and minutes later it returns a polished list of problems. The real question is not whether the report sounds expert. It is whether every claim came from a page the agent retrieved, evidence it preserved, and a rule it can explain.

    If you cannot trace a finding from recommendation back to observation, you do not have a reliable SEO agent yet. You have a text generator with access to SEO vocabulary. The way forward is to build a small inspection system around the model: tools to collect facts, rules to classify them, tests to expose failure, memory to preserve lessons, and a deployment gate that blocks unsupported conclusions.

    Reliability begins with an evidence contract, not a longer prompt

    A role prompt can tell a model to act like an SEO expert. It cannot prove that the model fetched a URL, received the expected response, inspected the relevant HTML, or distinguished a real defect from an intentional configuration.

    This distinction matters because confident language can hide incomplete inspection. In one documented build, an agent returned 20 findings, eight of which described problems that did not exist. It had not actually visited many of the URLs behind those claims. Better wording would not have corrected that failure. The agent needed tools, evidence requirements, and a way to reject its own unverified findings.

    Before choosing a model or writing detailed instructions, define an evidence contract. It should answer five questions:

    • What may the agent inspect? Name the permitted inputs, such as XML sitemaps, robots.txt, HTTP responses, raw HTML, rendered page output, and crawl data.
    • What counts as proof? Require the requested URL, final URL, retrieval result, inspected representation, observed value, and applicable rule for every finding.
    • What can the agent conclude? Limit conclusions to issue types supported by its tools and reference criteria.
    • What happens when evidence is unavailable? Require an explicit unknown or unverified state instead of allowing the agent to guess.
    • What must appear in the deliverable? Define the fields, evidence excerpts, coverage totals, confidence state, and recommendation format before the run begins.

    Suppose the agent wants to report a missing canonical element. It must first show that the page was fetched successfully and that it inspected the intended representation. A redirect, authentication screen, bot challenge, blocked request, empty response, or tool failure does not prove that the canonical is missing. It proves that the check was not completed.

    The same discipline applies to indexability. Finding a noindex directive is an observation. Declaring it an SEO problem is a classification that depends on the page’s intended role. If the agent does not have that context, it should report the directive and request confirmation rather than inventing intent.

    Make the agent separate each result into three layers:

    • Observation: what the tool found, including the URL, response, element, value, and retrieval method.
    • Classification: the rule that turns the observation into confirmed issue, acceptable state, rejected candidate, or unknown.
    • Recommendation: the action justified by that classification, with any required human decision stated plainly.

    This separation makes review faster. A human can challenge the rule without disputing the collected fact, or rerun the collection step without rewriting the recommendation. It also prevents a plausible recommendation from disguising a weak observation.

    Give every SEO agent a workspace it can operate from
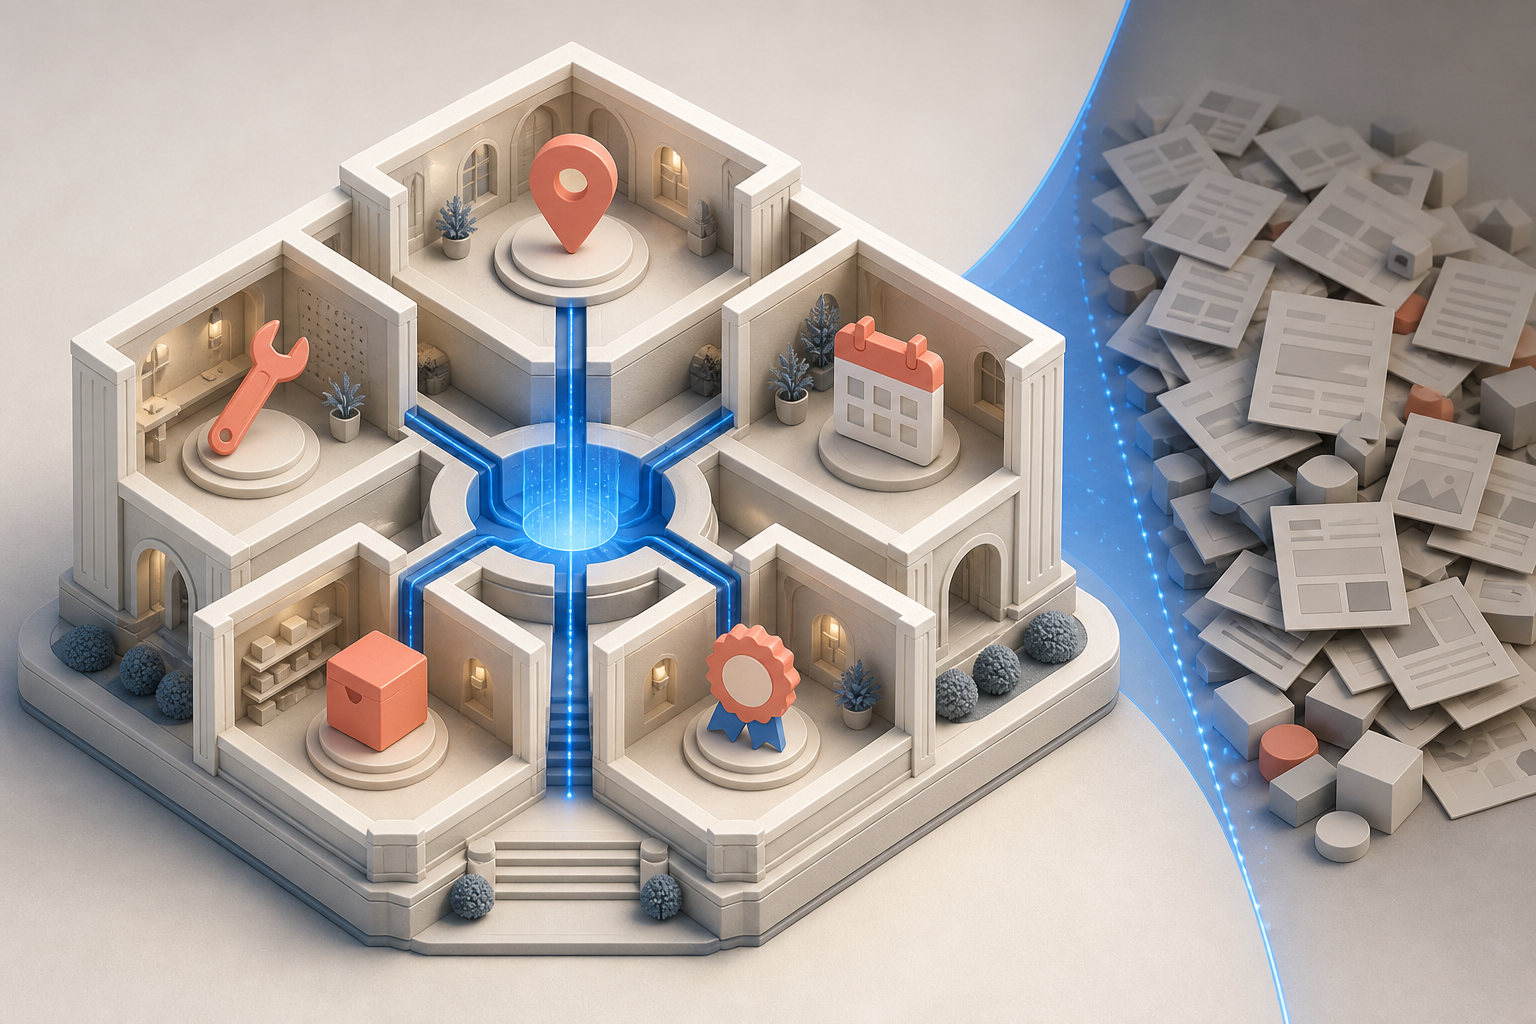
    An isometric workspace connects a central robotic agent to abstract page snapshots, structured records, rules, tests, an archive, and an error tray.

    A standalone prompt has nowhere to put operating procedures, executable tools, false-positive rules, previous failures, and output contracts. A dedicated workspace gives each of those concerns a stable home.

    Workspace componentWhat belongs thereReliability job
    AGENTS.mdOrdered methodology, allowed tools, stop conditions, escalation rules, and required outputKeeps the agent on the same operating procedure across runs
    SOUL.mdJudgment principles, skepticism rules, quality bar, and communication standardsDefines how the agent behaves when instructions do not cover an edge case
    scripts/Reusable crawlers, sitemap parsers, extractors, validators, and renderersCollects facts through repeatable operations instead of improvised commands
    references/Issue criteria, severity definitions, exceptions, and known false positivesSeparates real problems from noise
    memory/Run manifests, failure logs, rule changes, and regression historyPreserves lessons and exposes changes between executions
    templates/Finding records, summaries, evidence fields, and final report structurePrevents important fields from disappearing when prose varies

    The filenames are less important than the boundaries. Instructions should explain the workflow. Scripts should perform deterministic collection and validation where possible. References should define judgment. Memory should record what happened. Templates should constrain what can be published.

    Write AGENTS.md as an operating procedure, not a persona paragraph. An instruction such as “check the sitemap” leaves too much unspecified. A useful procedure tells the agent to look for sitemap declarations in robots.txt, try expected locations such as /sitemap.xml and /sitemap_index.xml, parse discovered sitemap indexes, record failed retrievals, and switch to an approved discovery method when no sitemap can be found.

    Give scripts equally clear contracts. A crawler should return structured records rather than a narrative. At minimum, each record should distinguish the requested URL from the final URL, record whether retrieval succeeded, preserve the response status, identify the collection method, and expose tool errors as data. The agent can explain those records later, but it should not have to reconstruct them from terminal prose.

    References need operational definitions. Do not write “flag bad canonicals.” Define the observable condition, the exceptions that suppress it, the evidence required for confirmation, and the severity rule. Put recurring traps in a separate gotchas file so they remain visible: intentional noindex pages, redirected URLs, blocked resources, duplicate URLs that resolve to one destination, and pages whose useful output requires rendering are examples of cases your test environment may need to cover.

    The output template should make unsupported findings difficult to express. Give every finding mandatory fields for evidence, rule ID, verification state, and affected URL. Reserve a visible section for unknowns and crawl failures. If the template offers only “issue” and “no issue,” the agent will be pushed toward false certainty whenever collection fails.

    Turn the audit into a collection and verification pipeline

    A reliable SEO audit is not one model call. It is a pipeline in which each stage produces an inspectable artifact for the next stage. The following sequence gives you a practical starting point.

    1. Create a run manifest. Record the target host, allowed scope, enabled checks, agent version, rule version, script versions, and any crawl constraints. This lets you explain why two runs differ.
    2. Discover the URL set. Start with declared sitemaps. Check robots.txt for references, then expected routes such as /sitemap.xml and /sitemap_index.xml. If none are available, use the approved crawl or supplied URL inventory and record that fallback.
    3. Collect responses without interpreting them. Apply configured rate limits, follow the approved redirect policy, and store requested URL, final URL, response result, and retrieval failure. A collection error belongs in the data, not in a discarded console message.
    4. Capture the representation required by each check. Preserve raw HTML for server responses. Use rendering when the initial response does not contain the elements a supported check needs. Label the representation so reviewers know what was inspected.
    5. Generate candidate observations. Extract canonical elements, robots directives, status behavior, titles, descriptions, links, or other in-scope signals without calling them defects yet.
    6. Verify every candidate. Recheck the relevant page and element through the appropriate tool. Reject stale, contradictory, duplicated, or unsupported candidates. If verification cannot finish, change the state to unknown.
    7. Classify against explicit criteria. Apply the relevant rule and its exceptions. Preserve the rule identifier and reason so a reviewer can reproduce the decision.
    8. Build the report from verified records. Let the model prioritize and explain confirmed findings, but do not let it introduce new URLs, counts, or diagnoses that are absent from the records.

    The pipeline should retain rejected candidates as internal run data. They tell you where the agent almost produced a false positive. If a rule repeatedly rejects the same pattern, you may be able to move that exception earlier in the workflow and save verification work.

    Coverage also needs to be explicit. Report separate totals for URLs discovered, retrievals attempted, pages fetched, pages inspected for each enabled check, and pages left unknown. “Crawled 500 URLs” is not useful if only part of that set reached the check that produced the recommendation. The denominator for a claim must be the set actually inspected for that claim.

    Do not collapse access failure into site failure. A CDN response, rate limit, robots restriction, timeout, or rendering error can stop the agent from observing the page. None of those outcomes proves that the suspected on-page issue exists. After the configured retry and fallback paths are exhausted, publish the limitation as a limitation.

    A compact finding record can carry the chain of evidence:

    • Run ID and rule version
    • Requested URL and final URL
    • Retrieval state and inspection method
    • Observed element or response value
    • Rule ID and applied exception
    • Verification state: confirmed, rejected, or unknown
    • Recommended action and any decision that still needs a person

    Once those fields exist, the model’s job becomes narrower and safer. It can group related findings, explain likely consequences, and make the report readable. It no longer needs to invent the factual substrate underneath the prose.

    Make every failure a regression test and a permanent lesson
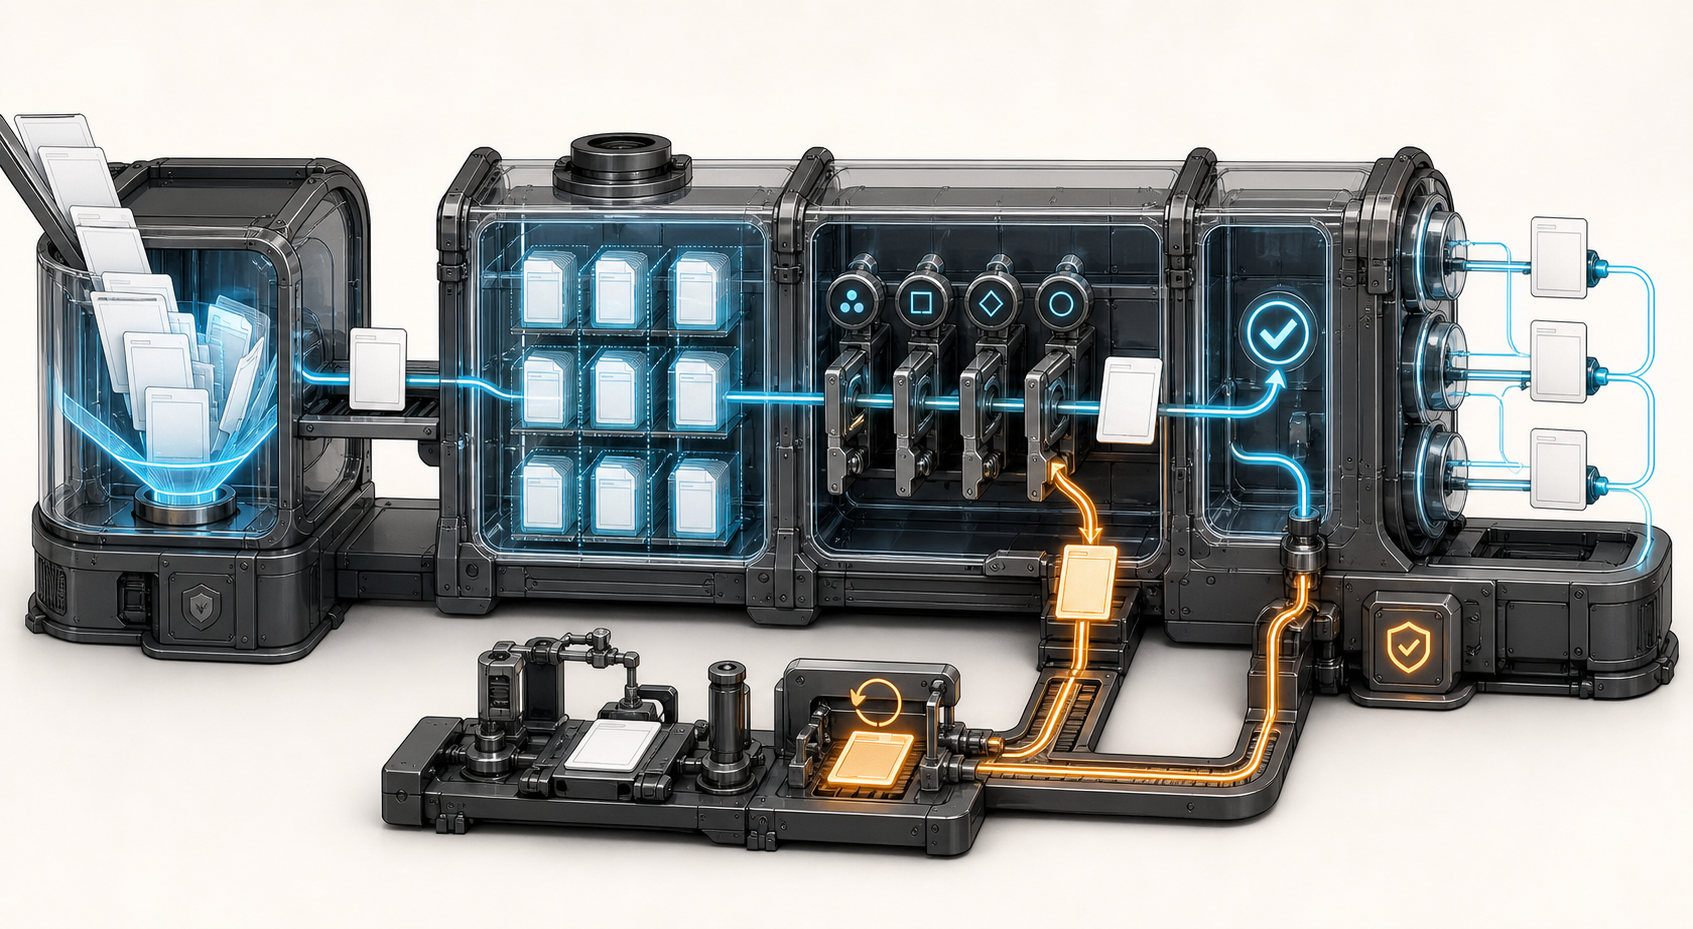
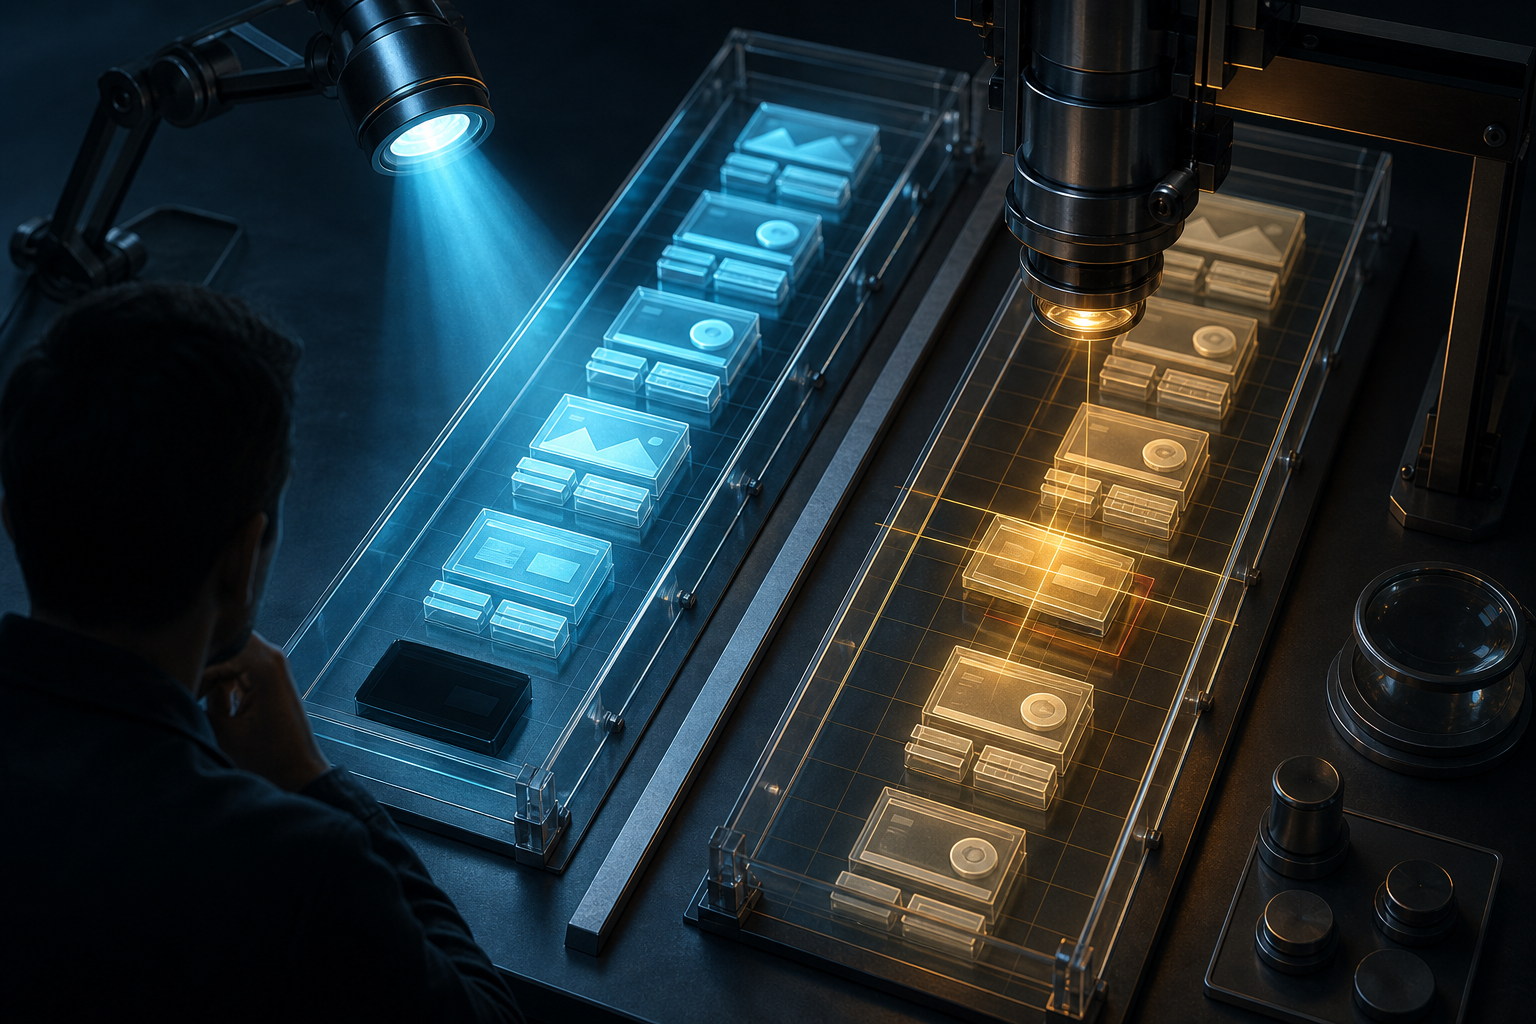
    A transparent audit machine collects abstract web pages, preserves evidence, checks rules, and routes a failed item through a test bench into a new checkpoint.

    You cannot establish reliability by running the agent once on a cooperative site. Build a small fixture set in which the expected observations and classifications are already known. It should include clean pages as well as failures, because an agent that finds seeded defects may still produce unacceptable noise on valid configurations.

    Your fixture set should exercise the conditions your agent claims to handle:

    • A static page with all required elements present
    • A page with a deliberately missing in-scope element
    • A page with a canonical element that should not be flagged
    • An intentionally noindexed page whose intent is supplied to the test
    • A redirect and its final destination
    • A nonexistent URL
    • A blocked, challenged, or rate-limited response
    • A route whose supported checks require rendered output
    • A standard sitemap, a sitemap index, a robots.txt sitemap declaration, and a site with no discoverable sitemap

    For each fixture, store the expected collection result, extracted observation, classification, and output state. Run the suite whenever you change instructions, scripts, issue criteria, templates, or model configuration. Review both misses and false positives. A report that catches every seeded problem but invents several more is not ready.

    When a live run fails, convert the failure into four artifacts:

    1. A minimal fixture that reproduces the condition
    2. A test that fails before the correction
    3. A change to the appropriate script, instruction, or reference rule
    4. A run-log entry that explains the symptom, cause, correction, and affected version

    This is how iteration creates an accumulating reliability advantage. Problems involving modern CDNs, rate limiting, JavaScript rendering, sitemap discovery, and noisy classifications stop being isolated surprises once their fixes are preserved in the workspace and exercised on every later change. The architecture becomes measurably better as failures become reusable lessons.

    Memory must not become a substitute for current evidence. A previous run may tell the agent that a URL once lacked a meta description, but it cannot prove the page still lacks one. Use memory to retain operating knowledge, compare changes, and select regression checks. Require a fresh observation before making a current-site claim.

    A useful run log records the run ID, workspace version, scope, discovery method, coverage totals, confirmed findings, rejected candidates, unknown checks, tool failures, and rule changes. Keep links to retained evidence where your data-handling rules allow it. This gives you a basis for comparing runs without asking the model to remember what happened.

    Repeatability does not mean every sentence must be identical. It means the same collected facts and rule versions should produce the same classifications. Keep factual extraction and rule evaluation structured; allow the model more freedom only when it turns those stable records into reader-friendly explanations.

    Key takeaways before you deploy

    Use this as the release gate for an SEO agent that will influence audits, tickets, or client recommendations:

    • Require evidence for every finding. A published issue must identify the inspected URL, observed value, retrieval method, verification state, and rule that supports it.
    • Keep observation separate from judgment. The tool collects the fact, the criteria classify it, and the final layer recommends an action.
    • Treat inaccessible as unknown. A failed request, blocked page, rendering problem, or exhausted retry path must never be translated into a missing element.
    • Expose coverage. Show how many URLs were discovered, fetched, inspected for each check, and left unresolved so readers can interpret the scope correctly.
    • Test valid and invalid configurations. Your regression set must prove that the agent can stay quiet on acceptable pages as well as detect seeded problems.
    • Preserve every correction. A false positive should result in a fixture, regression test, rule or tool change, and versioned run-log entry.
    • Keep memory subordinate to fresh inspection. Previous runs can guide comparisons and testing, but current claims require current evidence.
    • Block unsupported prose. The report generator may explain and prioritize verified records; it may not add facts, URLs, counts, or issue types that the pipeline did not produce.

    Your next move should be deliberately narrow. Build a URL inventory agent that records discovery, redirects, response results, indexability signals, and canonical observations. Give it known fixtures, force it to show unknowns, and manually inspect a sample of its evidence on a site you control. Add another issue class only after the first one survives the same gate across repeated runs.

    That pace may feel slower than asking for a comprehensive audit in one prompt. It is also how you end up with an agent whose conclusions deserve to be acted on.
    References

  • How to Earn Accurate AI Citations and Protect Brand Trust

    How to Earn Accurate AI Citations and Protect Brand Trust

    An AI answer can cite your website and still get your product wrong. It can also describe your brand accurately while sending the reader somewhere else. If your reporting treats both outcomes as a visibility problem, you won’t know what to fix.

    You need to evaluate three things separately: whether your brand was selected, whether the cited evidence supports the generated claim, and whether a person would trust the answer enough to act. This framework helps you diagnose each layer without mistaking citation volume for accuracy or brand authority.

    Key takeaways

    • A citation proves that a page was selected as a reference. It does not prove that the generated sentence is accurate, complete, current, or supported by that page.
    • Audit the relationship between each claim and its citation. Counting links or brand mentions alone hides the errors most likely to damage trust.
    • Segment testing by platform, query language, market, intent, and phrasing. A blended visibility score can conceal serious gaps in a priority language or buying journey.
    • Maintain a canonical claim layer with explicit evidence, scope, market, and update information. Align your visible content and JSON-LD with that same version of the truth.
    • Earn independent confirmation by helping people in the communities and channels where decisions are verified. Repetition from your own properties is not the same as corroboration.

    A citation proves selection, not accuracy

    Grounding means connecting a generated answer to external evidence. It can reduce unsupported generation, but it does not turn every cited sentence into a verified fact. Retrieval can surface a relevant page while the model overgeneralizes its wording, misses a qualifier, combines incompatible details, or attaches the citation to a broader claim than the page supports.

    Suppose an answer says a company provides same-day support in every market. Its citation leads to a support page that promises that service only to selected customers in one region. The link is real and topically relevant, but the generated claim is still wrong. A dashboard that records only citation presence would count that outcome as a success.

    That is why an AI visibility audit needs four separate tests:

    LayerQuestion to askCommon false conclusionWhat to inspect
    Citation presenceWas your brand or page selected?Being cited means being represented correctly.The cited URL, its position, the surrounding answer, and competing domains.
    Claim supportDoes the cited passage support the exact generated claim?A relevant page is sufficient evidence.Wording, scope, qualifiers, dates, markets, exceptions, and the cited passage itself.
    Entity accuracyAre the brand, product, policy, location, and relationships correct?A fluent description must be reliable.Names, attributes, availability, ownership, pricing claims, and product-to-brand relationships.
    User trustWould a reasonable reader accept and act on the answer?Exposure automatically creates confidence.Independent corroboration, transparency, review quality, community sentiment, and unresolved contradictions.

    The practical unit of analysis is the claim-citation pair. Break an answer into factual claims, then open the citation attached to each one. Grade the pair as supported, partially supported, unsupported, or contradicted. Use a separate label when no citation is provided.

    Partial support deserves its own category. It often reveals the most important content problem: your page contains the right concept but leaves enough ambiguity for the model to enlarge its scope. A statement that is correct for one plan, country, customer type, or time period needs that qualifier in the same sentence as the claim. Do not leave the limitation in a footnote, accordion, or unrelated section and expect retrieval to preserve it.

    Accuracy and trust also need different owners. A content or product team may be able to correct an outdated policy page. Public relations or community teams may need to address persistent third-party confusion. Technical SEO can improve entity consistency and structured data, but it cannot manufacture independent belief. Your audit should route each failure to the team that can change its underlying cause.

    Query language can change who gets cited

    A glowing inquiry passes through a prism and branches toward three different source documents, with each path representing a different citation outcome.

    You cannot infer global AI visibility from English-language testing. In one large cross-platform analysis, 3.25 billion citations across seven AI models and 14 countries showed query language as the main catalyst changing citation rates. Google AI Overviews and ChatGPT also displayed different response patterns for non-English prompts. That finding should be treated as a strong warning about aggregation, not as a universal rule for every query or brand.

    Language changes more than the words in the prompt. It can change the pool of retrievable pages, the entities a model recognizes, the regional sources available to support an answer, and the way a user expresses intent. A literal translation of an English prompt may therefore test translation quality rather than the search behavior of a person in that market.

    Build your prompt set from real decisions instead of a list of brand keywords. Include the questions people ask when they are discovering a category, comparing options, checking a claim, assessing risk, resolving a problem, and preparing to buy. Then vary the constraints that matter to the decision: location, use case, customer type, compatibility, availability, policy, or another relevant condition.

    Use a segmented test matrix

    For every prompt, record the exact wording and the conditions under which the answer appeared. At minimum, preserve:

    • The user’s underlying intent and the decision the answer is meant to support.
    • The exact prompt, including follow-up questions and any constraints introduced earlier in the conversation.
    • The query language and intended market. Keep them separate because a language can span several markets, and a market can contain several languages.
    • The AI platform or search surface. Do not merge ChatGPT results with Google AI Overviews or another system under a single generic AI ranking.
    • The date of capture and any visible model or product label, so later retests can be compared with the right context.
    • Whether the session was signed in, personalized, location-aware, or part of an existing conversation.
    • The complete answer, every citation URL, and the passage that supports or fails to support each material claim.

    Have a fluent local speaker or market specialist adapt important prompts. Ask how a real customer would phrase the problem, what local terminology they would use, and which proof they would expect. The localized prompt should preserve the intent, not the English syntax.

    Report results by language and platform before calculating any overall figure. If your brand performs well in English but disappears or becomes inaccurate in another priority language, an average can make the program look healthy while the affected market sees a different brand. The segment is the truth; the blended number is only a summary.

    Build a truth layer that models and people can verify

    A central knowledge core sends consistent product and policy information to web pages, documents, an AI system, and a human reviewer.

    The safest way to improve citation accuracy is to make consequential claims easy to retrieve, hard to misread, and consistent across the properties you control. That work begins before schema markup. A perfectly marked-up contradiction is still a contradiction.

    Create a canonical claim ledger

    Maintain a working record of the claims that affect whether someone chooses, trusts, or rejects your brand. Each record should contain the entity, approved wording, supporting URL, evidence, scope, exceptions, applicable language and market, content owner, review date, and current status.

    Prioritize claims about what a product does, who it is for, where it is available, what it costs, what is included, what it integrates with, and what policies govern its use. These are the statements most likely to change a decision. They are also vulnerable to drift when product pages, help documentation, sales copy, partner listings, and old announcements describe different versions of reality.

    Give each consequential claim a clear canonical home. The page should state the fact directly, place its qualifier beside it, explain the evidence, identify the applicable product or market, and make the update status visible. If the answer differs by plan or region, present those differences as structured comparisons rather than scattering them across several pages.

    Review conflicting owned pages before publishing more content. A new explainer cannot establish clarity while an old pricing page, support document, or local site still makes the opposite claim. Correct, redirect, archive, or clearly date obsolete material according to its purpose. If an older page must remain accessible, label its historical status where a person and a retrieval system can encounter it.

    Use JSON-LD as a consistency layer

    JSON-LD can clarify entities, properties, and relationships. It cannot supply evidence that the visible page lacks, resolve disagreement between departments, or make an exaggerated claim trustworthy. Treat structured data as a machine-readable expression of the same facts a reader can verify on the page.

    • Use the schema type that accurately describes the visible entity or content, such as Organization, Person, Product, or Article where appropriate.
    • Keep names, canonical URLs, identifiers, brand relationships, and other entity attributes consistent with the page and your canonical claim ledger.
    • Do not place a material claim only in markup. If it matters enough to encode, it should be supported in the visible content.
    • Match market- and language-specific markup to the corresponding page. Do not attach a global claim to content that supports only one region.
    • Update structured data when the underlying fact changes. A stale JSON-LD property can preserve the contradiction you just removed from the copy.
    • Validate syntax and then inspect meaning. Technically valid markup can still identify the wrong entity or express an unsupported relationship.

    This approach gives you one controlled path from approved fact to human-readable evidence to structured representation. It also makes corrections easier: when an AI answer exposes a problem, you can trace the claim to its owner and every place where it appears.

    Earn confirmation outside your own website

    People rarely make an important decision inside one answer box. The search journey can move through AI tools, marketplaces, reviews, forums, video, friends, and knowledgeable people as the user looks for stronger confirmation. Yext reported that 75% of consumers were using more platforms than a year earlier, while only 10% trusted the first result.

    That behavior reflects three judgments: whether people trust themselves to evaluate the subject, whether they trust the platform presenting the answer, and whether they trust the underlying information source. Your citation work can improve the last layer, but brand trust also depends on what people encounter when they leave the generated answer to verify it.

    Independent confirmation cannot be produced by repeating the same marketing claim across more company profiles. It comes from useful participation in places where people exchange experience: practitioner communities, customer conversations, events, forums, reviews, social channels, and expert-led media. The operating rule is simple: listen for the unresolved question, help with that question, and let the brand mention remain secondary to the answer.

    • Track recurring questions, objections, misconceptions, and vocabulary in the communities relevant to your buyers.
    • Answer with specific, verifiable information. Link to documentation when it genuinely helps rather than treating every interaction as a distribution opportunity.
    • Turn recurring questions into durable resources on your own site, then keep those resources aligned with the conversations that inspired them.
    • Make it easy for customers, partners, practitioners, and journalists to verify factual details without copying promotional language.
    • Correct errors openly and precisely. State which claim is wrong, what the accurate scope is, and where the supporting information lives.
    • Never manufacture reviews, personas, community conversations, or supposed independent consensus. Discovery gained through deception creates the exact trust problem the program is meant to solve.

    The goal is not to control every mention. It is to make the accurate account easier for other people to confirm and repeat in their own words. That creates a healthier evidence environment than a large collection of identical brand-authored claims.

    Audit the failure pattern before choosing the fix

    A useful AI citation audit should reproduce an answer, isolate the error, identify the controllable cause, and verify the correction. Screenshots of favorable mentions are not enough.

    1. Define the decision. Start with prompts tied to meaningful user actions or material brand risk. Record what a correct answer must help the user understand.
    2. Capture the full context. Save the exact prompt sequence, language, market, platform, date, answer, citations, and visible session conditions.
    3. Split the answer into claims. Separate factual statements from recommendations, opinions, and connective language. Mark the claims that could change a purchase, eligibility, support, compliance, or reputation decision.
    4. Check every citation. Open the linked page, locate the supporting passage, and grade the relationship as supported, partially supported, unsupported, contradicted, or uncited.
    5. Check the entity. Verify names, product relationships, attributes, locations, policies, availability, and other details against the canonical claim ledger.
    6. Trace the likely cause. Look for unclear wording, missing qualifiers, stale owned pages, inconsistent markup, weak localized evidence, entity ambiguity, or repeated third-party misinformation.
    7. Fix the highest-consequence origin. Correct the canonical page and contradictory owned properties first. Then update structured data, partner records, listings, and other controllable representations. Seek corrections from external publishers or platforms where an appropriate process exists.
    8. Retest the original conditions. Use the same prompt and context, then test natural variants. A changed answer may indicate improvement, but it does not prove that every platform, language, or user will now receive the same result.

    Measure accuracy and trust separately from reach

    Your reporting should preserve the distinction between being visible and being represented well. Useful measures include:

    • Citation presence: how often your brand, canonical pages, or relevant independent pages appear for eligible prompts.
    • Claim support rate: how often cited passages fully support the claims attached to them. Keep partial support visible instead of counting it as success.
    • Brand claim accuracy: how often material statements about your entity match the approved facts and their qualifications.
    • Uncited material claim rate: how often consequential factual statements appear without a reference a reviewer can inspect.
    • Cross-platform consistency: whether different AI surfaces agree on the material facts, not whether they use identical wording.
    • Language and market gap: the difference in citation presence, support, and accuracy between priority segments.
    • Independent confirmation: whether the answer’s important claims can be verified through credible, non-owned evidence where independent evidence should exist.
    • Correction latency: how long your organization takes to correct the controlled origin of a material error and complete the relevant retest.

    Avoid setting a citation target without a support target. A campaign can increase the number of citations while also increasing the number of confidently misstated claims. That is not improved visibility; it is wider distribution of an accuracy problem.

    Let the pattern determine the intervention

    • High citation presence, low claim support: clarify the canonical content, move qualifiers beside their claims, remove contradictions, and inspect why irrelevant passages are being treated as evidence.
    • Low citation presence, high brand accuracy: improve retrievability, entity clarity, localized coverage, content distribution, and credible external confirmation without rewriting already-clear facts for novelty.
    • High accuracy, low user trust: examine reviews, community sentiment, transparency, proof quality, and what a person encounters after clicking. More owned content may not solve this failure.
    • Strong English results, weak priority-language results: build native-language evidence and entity consistency for that market. Do not rely on literal translation or a global average.
    • Conflicting answers across platforms: preserve the platform split in reporting, inspect each citation pool, and fix shared contradictions before chasing platform-specific tactics.
    • A material uncited error: treat the incorrect claim as the incident, even if the rest of the answer is favorable. Prioritize errors that change cost, availability, eligibility, obligations, safety, or a buyer’s ability to make an informed choice.

    Start with the decision-heavy query where a wrong answer would cost the most trust. Test it in your primary language and the highest-priority additional language, grade every claim-citation pair, and correct the most consequential contradiction you control. Do that before pursuing a larger citation count. The citation is not the finish line; an accurate, verifiable, and trusted answer is.

    References


  • How to Build Website Authority for AI Search Visibility

    How to Build Website Authority for AI Search Visibility

    If an AI answer gets your business wrong, leaves you out, or cites a competitor, publishing another broad article is rarely the cleanest fix. You need to make the right facts easy to crawl, easy to retrieve, difficult to misinterpret, and consistent everywhere they appear.

    That turns website authority from a vague reputation goal into a practical system. You can inspect each part, find the break, and fix the page or fact that is actually limiting your visibility.

    Treat authority as a chain from crawl to customer

    AI search visibility can fail at several different stages. A page may be accurate but inaccessible to a crawler. It may be crawlable but poorly matched to the question. It may be retrieved but not selected as supporting evidence. Your brand may even appear in an answer without earning the customer’s trust afterward.

    Separate the chain into these diagnostic layers:

    • Crawl access: Can relevant crawlers request the public URL and receive the page successfully?
    • Interpretation: Does the page identify the business, service, location, product, or person without ambiguity?
    • Retrieval: Does one section closely answer the user’s actual question?
    • Selection: Is the answer precise and well-supported enough to be used or cited?
    • Validation: Do your other pages and external profiles confirm the same facts?
    • Conversion: Can a person who follows the recommendation verify the offer and take the next step?

    This distinction matters because a citation is not the same as a recommendation, and a recommendation is not the same as a sale. A citation means your URL supported an answer. A mention means your name appeared. A recommendation places you among the options. Authority has to carry the user through all three and then survive their visit to your site.

    Retrieval is especially important. Across an AirOps analysis of 16,851 unique queries, the first retrieval result was cited 58.4% of the time, while the result in tenth position was cited 14.2% of the time. Pages with headings that strongly matched the query were cited 41% of the time. Those figures do not establish a universal ChatGPT ranking formula, but they show why a generally authoritative domain can still lose a particular answer: the wrong page or passage wins retrieval.

    When you diagnose a visibility problem, do not begin with, “How do we make the whole domain more authoritative?” Begin with a narrower question: “For this customer question, which URL should be retrieved, which passage should be selected, and which facts must another source be able to confirm?”

    Design pages to win retrieval, not merely cover topics

    An organized modular website feeds distinct fact objects into a central retrieval beam while cluttered pages sit outside it.

    A page earns retrieval by making its purpose obvious. The title, primary heading, opening answer, supporting details, and internal links should all point to the same intent. A page called “Our Solutions” forces a system to infer what it contains. A heading such as “Does the service include installation?” identifies both the question and the expected answer.

    Build each important answer in this order:

    1. Choose one real customer question. Pull it from sales emails, support conversations, reviews, search queries, and questions on business profiles.
    2. Decide what kind of answer the user needs: a fact, qualification, process, comparison, availability check, or next action.
    3. Place a query-shaped heading above the answer. Use the customer’s language where it remains accurate.
    4. Answer immediately in plain sentences. Do not make the reader cross an origin story, promotional introduction, or table of contents to reach the useful fact.
    5. Add the conditions that prevent a misleading extraction. State relevant locations, exclusions, eligibility rules, dependencies, or situations in which the answer changes.
    6. Support the answer with concrete business information, then point the reader to the appropriate verification or action page.

    A narrow page is not necessarily a short or shallow page. It is a page with one dominant job. A service page can explain scope, suitability, process, limitations, and next steps without becoming a general guide to the entire industry.

    Conversely, long content is not automatically authoritative. In the same query analysis, pages between 500 and 2,000 words performed best for citations, while pages over 5,000 words were cited less often than even the shortest pages. Content with 4 to 10 subheadings also performed notably well. Treat those as observations from that dataset, not mandatory publishing limits. The useful principle is precision: stop when the question has been answered, qualified, and supported.

    A practical site architecture usually needs both hubs and focused pages. Use a broad hub to organize a subject and help users navigate it. Use a focused page when a distinct question requires its own evidence, conditions, or conversion path. Do not create separate URLs for trivial wording changes; consolidate near-duplicate questions under the clearest heading so your own pages do not compete to be the answer.

    Before publishing, apply a simple extraction test. Read only the heading and the paragraph beneath it. If that fragment would be accurate when shown without the rest of the page, the answer is well-formed. If it would overpromise, omit a location, or confuse one service with another, add the missing qualifier beside the answer rather than burying it later.

    Make your website the canonical truth layer

    Your site cannot function as an authority if its own facts drift. A homepage may use one business name, a location page another, and a profile an old address or schedule. An AI system then has to resolve the conflict, and the version it chooses may not be yours.

    This is particularly important in local search, where services, locations, hours, reviews, and business profiles help establish whether a recommendation fits the query. AI recommendations can be checked against multiple online profiles, while customers commonly validate the choice by visiting the website and reading reviews. Your site therefore has two jobs: provide precise information for the recommendation and provide enough proof for the person evaluating it.

    Create a fact inventory with one row for every claim that can change or cause a customer to choose incorrectly. Useful fields include:

    • The fact itself, written in its approved form.
    • The canonical page where that fact is explained.
    • Every important internal page and external profile that repeats it.
    • The person responsible for verifying it.
    • The event that should trigger an update.
    • The date on which someone last confirmed it.

    Start with identity and decision facts: business name, locations, service areas, hours, contact details, offerings, eligibility, availability, policies, and important limitations. For a local business, compare those facts with its Google Business Profile and major directories. For a product or service company, compare landing pages with pricing, support, policy, and documentation pages. Resolve contradictions at the canonical page first, then update every surface that repeats the fact.

    Authority also depends on evidence placement. Put identity information on the homepage and about page. Put service scope and limitations on the service page. Put location-specific availability on the relevant location page. Put policy details on the policy page. Repeating a short fact for context is reasonable, but one page should remain the full, maintained explanation.

    Use JSON-LD to identify facts, not manufacture authority

    Structured data helps a machine identify entities and relationships, but it cannot make vague copy precise or reconcile conflicting claims. In the citation dataset, pages with JSON-LD had a 38.5% citation rate, compared with 32.0% for pages without it. That is a useful but modest association, not evidence that schema alone causes citations.

    Use JSON-LD as a faithful machine-readable version of the visible page:

    • Select the most specific schema type that truthfully describes the entity or content.
    • Mark up only facts that users can verify on the page or through an appropriate canonical page.
    • Use stable URLs and identifiers for the same entity across connected markup.
    • Keep names, addresses, service descriptions, dates, and other properties aligned with visible content.
    • Validate syntax after changes and include structured-data checks in the same workflow that updates the page.

    If you have to choose between adding more properties and correcting a contradiction, correct the contradiction. Clear content establishes the claim; structured data labels it.

    Run an audit that separates visibility from accuracy

    A digital workbench uses separate illuminated lanes to inspect website fact modules for discoverability and consistency.

    An occasional vanity prompt will not tell you whether authority is improving. Generative answers can vary, and one broad question mixes discovery, retrieval, recommendation, and citation into a single result. Use a fixed audit that preserves the wording, platform, run date, and evidence.

    1. Build a prompt set around real decisions. Include questions about fit, availability, location, process, limitations, alternatives, and the next step. Use neutral language rather than inserting your brand into every prompt.
    2. Run the same prompts on the AI systems your customers are likely to use. Repeat important prompts so a single variable response does not become your conclusion.
    3. Record whether your brand appears, how it is described, whether the description is correct, whether your site is cited, which URL is used, and which competing or third-party sources support the answer.
    4. Inspect the cited or likely landing page. Check whether its title and headings match the question, whether the answer appears near the relevant heading, and whether all necessary qualifiers sit beside it.
    5. Check crawler access. Confirm that important URLs can be requested, do not return error responses, and are not unintentionally restricted by access rules.
    6. Fix the earliest broken link in the chain. There is little value in rewriting an answer passage if the page cannot be crawled, or adding schema while external profiles still carry the wrong location.

    Server-log analysis can expose crawler activity that ordinary traffic reports do not make obvious. Logs can show the requested URL, time, declared user agent, and response status. They cannot prove that a model stored, trusted, retrieved, cited, or used the content. Treat them as crawl evidence, then use prompt audits and citation tracking to evaluate the later stages.

    Prioritize corrections by consequence. Fix inaccurate high-intent facts first, followed by access failures, conflicting profiles, missing direct answers, and stale supporting content. This order protects the customer decision while also improving the material available for retrieval.

    Freshness deserves a targeted approach. Pages published 30 to 89 days before collection had the strongest citation performance in the AirOps dataset, while content less than 30 days old performed slightly worse and content older than two years struggled. That pattern may reflect the time needed to accumulate retrieval signals, and it does not justify rewriting every page on a fixed schedule. Use it as a reason to review older pages that already serve valuable queries, especially when their facts, examples, policies, or answer structure have drifted.

    Measure the outcome at each stage

    Your reporting should make failures distinguishable. Track prompt coverage, accurate-answer rate, brand mention rate, citation rate, owned-site citation share, cited URLs, crawler access, corrected fact conflicts, and the customer actions that follow AI-assisted discovery. Keep the prompt set stable long enough to detect a direction, and log material page changes so you can connect movement to an intervention.

    Do not use organic clicks as the sole verdict. An Ahrefs analysis found that 99% of keywords triggering an AI Overview were informational, while navigational keywords accounted for 0.13%. In that dataset, AI Overviews were concentrated overwhelmingly in informational searches. A decline in clicks from quick-answer queries can therefore coexist with useful visibility, but only if your brand is represented accurately and decision-stage users can still reach a convincing destination.

    Report exposure and business impact separately. Exposure tells you whether the brand and site enter the answer. Accuracy tells you whether the answer helps or harms. Decision actions tell you whether the website completes the job. Combining them into one visibility score hides the part you need to fix.

    Frequently asked questions

    What does website authority mean in AI search?

    Website authority in AI search is the site’s ability to provide crawlable, unambiguous, retrievable, consistent, and verifiable information for a particular question. It is not just a domain-level reputation score. A strong domain can lose a citation when its relevant page is vague, stale, inaccessible, or poorly matched to the query.

    Should every customer question have its own URL?

    No. Give a question its own page when it has distinct evidence, conditions, search intent, or a separate next action. Put closely related questions on one focused page under descriptive headings. Creating near-duplicate URLs for every phrasing makes maintenance harder and leaves several pages competing to represent the same answer.

    Can an uncited AI mention still be valuable?

    Yes, but count it separately from a citation. First check whether the mention is accurate, relevant to the question, and likely to lead a user toward verification. Then inspect whether your website supports the description and offers a clear next step. An inaccurate mention is not positive visibility merely because the brand appeared.

    What should you fix first?

    Fix the error with the greatest decision consequence. An incorrect location, service condition, eligibility rule, or availability claim comes before a missing optional schema property. After factual accuracy, address crawl failures and retrieval structure, then improve supporting depth and presentation.

    Start with the questions closest to a real customer choice. Assign each one a canonical page, verify every changeable fact, correct conflicts across your profiles, and make the answer extractable beneath a precise heading. Then rerun the same prompt set and inspect the logs. That cycle gives you something more useful than a vague authority campaign: a clear record of what AI systems can access, what they say, and what you need to improve next.

    References


  • How to Improve Visibility in Personalized Google Maps Results

    How to Improve Visibility in Personalized Google Maps Results

    If your business appears for a broad search such as electrician nearby but disappears when the customer describes an older home, a panel upgrade, and a need for responsive service, a conventional ranking report is showing only part of the problem. Ask Maps may evaluate which businesses fit the stated situation, not merely which listings match the category.

    Your practical goal is to make that fit understandable and supportable. Your Google Business Profile should establish what the business is, your website should explain the work in enough depth to resolve a specific need, and your reviews should provide credible customer evidence. The following process turns those surfaces into a local discovery system you can audit and improve.

    Personalized recommendations change what visibility means

    Traditional local tracking usually reduces visibility to a position: where did the business rank for a keyword in a location? That remains useful, but it misses an important layer of conversational discovery. A person can now supply the job, property type, constraint, urgency, trust concern, or decision criterion inside the request.

    As those details accumulate, Ask Maps has been observed moving from a relatively simple set of nearby businesses toward a more selective answer that interprets fit and explains its choices. Basic prompts tend to produce broader retrieval. More involved prompts can trigger guidance about which options appear suitable and why.

    That distinction changes the question you should ask. It is no longer only, Can Google associate this business with electricians in this city? It is also, Can Google find enough consistent evidence to associate this business with panel upgrades in older homes, responsive communication, and the other details a customer included?

    Use personalized carefully here. The actionable behavior is personalization to expressed intent: the result changes as the person gives the system a more specific problem to solve. You do not need to speculate about private account history or undocumented signals to work on that problem.

    The observed pattern is directional rather than universal. It came from locality-specific testing and was not exhaustive across every market or query. Treat it as a reason to expand your audit, not as proof that every Ask Maps result follows an identical formula.

    Build a consistent evidence map across profile, site, and reviews

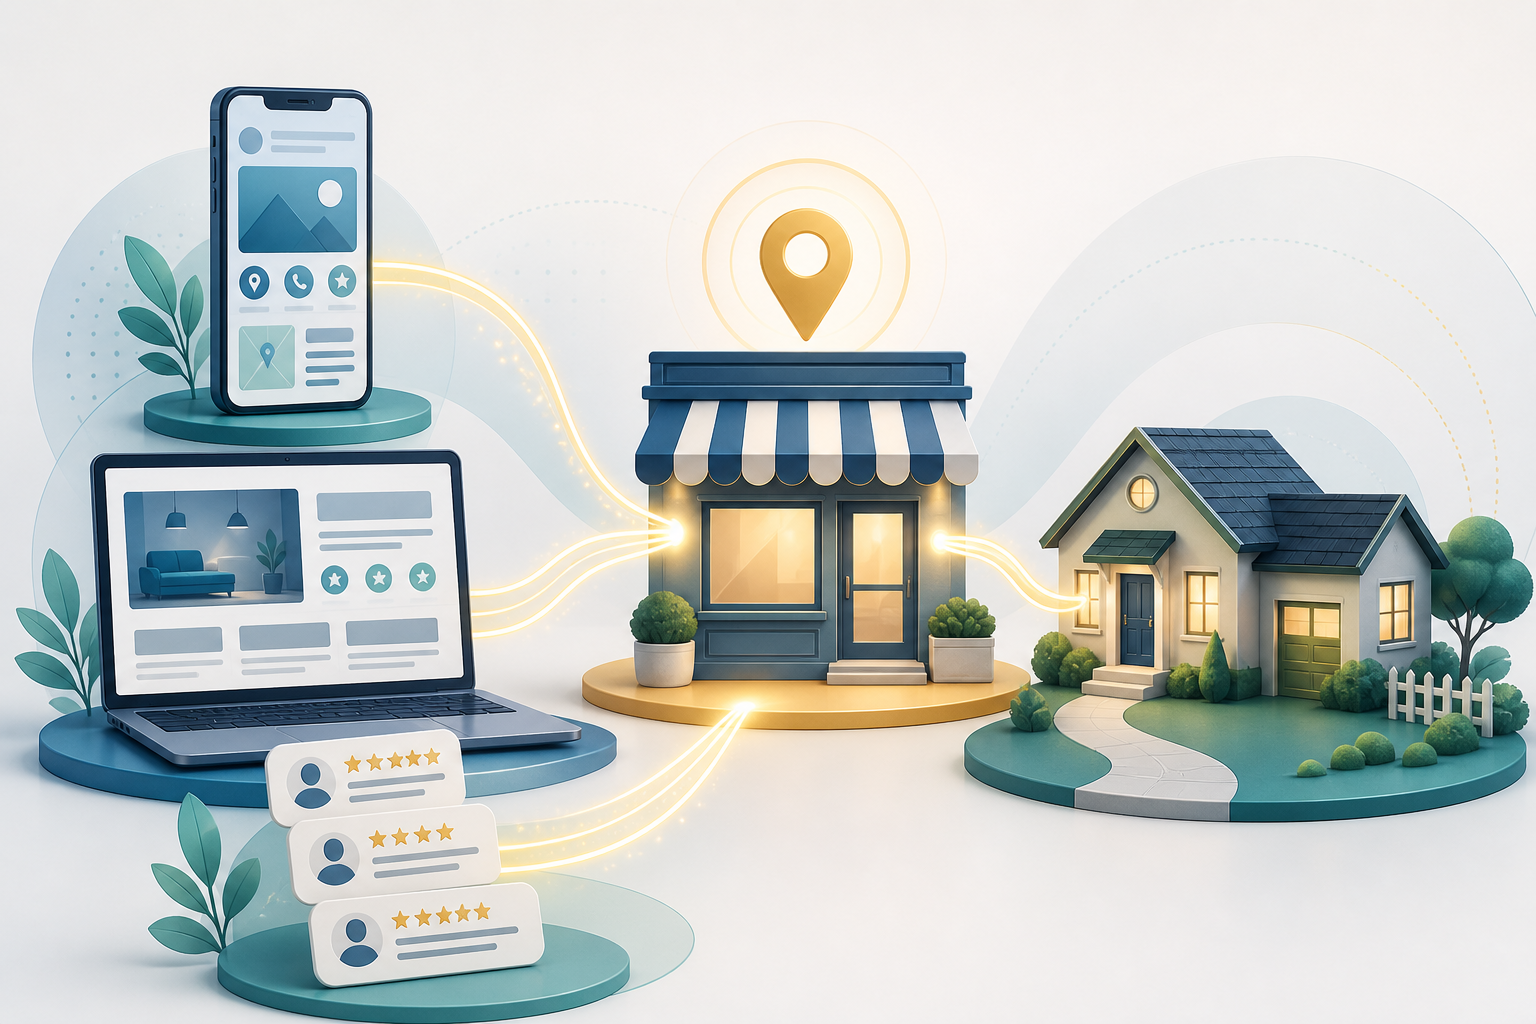
    An abstract business profile, service website, and customer review cards connected by glowing lines to a local storefront and a customer's home.

    Ask Maps can draw from Google Business Profiles, reviews, business websites, and external material. These surfaces play different roles. A useful working model is identity, explanation, and corroboration:

    • Google Business Profile establishes identity. It tells the system what the business is, where it operates, and which services it presents.
    • The website explains capability. It gives a specific service or situation enough context to be understood beyond a short listing.
    • Reviews corroborate experience. They show how customers describe the work, service, communication, and outcomes in their own words.
    • External mentions can reinforce or complicate the picture. Information elsewhere may help confirm the business, but stale or inconsistent claims can create ambiguity.

    Create an evidence map before you edit anything. For every commercially important service, write down the customer need, the relevant profile fact, the page that explains it, and the review themes that could honestly support it. A blank cell is a content or data gap. A contradictory cell is an accuracy problem.

    Make the Business Profile precise, not expansive

    Your profile should describe the business customers can actually hire. Confirm that its category, services, description, hours, contact details, and service-area information are accurate. Do not add adjacent services merely to look comprehensive. A larger but unreliable service list makes it harder to build a consistent explanation across the rest of your presence.

    Use operational language where the profile permits it. Electrical contractor offering residential panel upgrades communicates more than a string of broad adjectives. If responsiveness matters to customers, publish accurate contact and availability information. Let real customer accounts support the quality claim rather than describing the business as responsive without evidence.

    Check consistency at the fact level. A service should not appear on the profile while the website gives no indication that you provide it. Hours, names, locations, phone details, and stated coverage should not conflict across your owned pages. Consistency does not guarantee selection, but inconsistency makes the business harder to interpret confidently.

    Publish pages that resolve a situation, not just a keyword

    A generic Electrician in City page can establish category and location. It may not answer whether the company handles a panel upgrade in an older home. That difference matters when the query contains the job and its context.

    For each meaningful service-intent combination, give the reader a page that answers the decision they are making. Include:

    • The exact work offered: name the service plainly and distinguish it from neighboring services a customer may confuse with it.
    • The situations you handle: describe relevant property, equipment, business, or project contexts only where they genuinely affect fit.
    • The boundaries of the service: state exclusions, prerequisites, or geographic limitations that would otherwise produce a poor match.
    • How the next step works: explain what information you need, how scope is assessed, and what the customer should do next.
    • Decision-useful answers: address the questions customers ask when choosing a provider, not merely the phrases an SEO tool reports.
    • Visible evidence: use accurate examples, credentials, service details, and customer feedback when you have them. Do not manufacture specificity.

    The page does not need to repeat every possible conversational prompt. It needs clear facts that can answer several versions of the same underlying need. Write for the decision, then use headings and direct language to make each answer easy to extract.

    JSON-LD can encode those visible facts after the page is complete. Use the appropriate business and service vocabulary, keep marked-up information consistent with what a visitor can read, and avoid adding claims solely in structured data. Schema is a machine-readable clarity layer, not a substitute for missing service information or customer evidence. There is no basis for assuming markup alone will force Ask Maps to recommend a business.

    Treat reviews as evidence, not a bag of keywords

    Reviews appear especially influential in the initial impression of a business, while more complex requests can lead Ask Maps deeper into websites and other informative material. That makes review quality relevant, but it does not justify scripting customer language.

    Ask customers for honest feedback about the work they received. Open questions can invite useful context: What problem were you trying to solve? What work was completed? What part of the process was helpful? The customer should decide what to mention and how to say it.

    Then analyze the patterns already present. Group review language by service, situation, communication, specialization, and trust. Compare those themes with your profile and service pages. If customers repeatedly describe a capability that the website barely mentions, you may have a documentation gap. If the site promotes a specialty that customers never discuss, investigate whether the claim is unclear, unimportant to buyers, too new to have accumulated evidence, or unsupported.

    Do not turn that analysis into review manipulation. Repeating a target phrase is not the same as demonstrating fit. The useful signal is a coherent relationship between the stated service, the detailed explanation, and genuine accounts of customer experience.

    Audit discovery with a five-level intent ladder

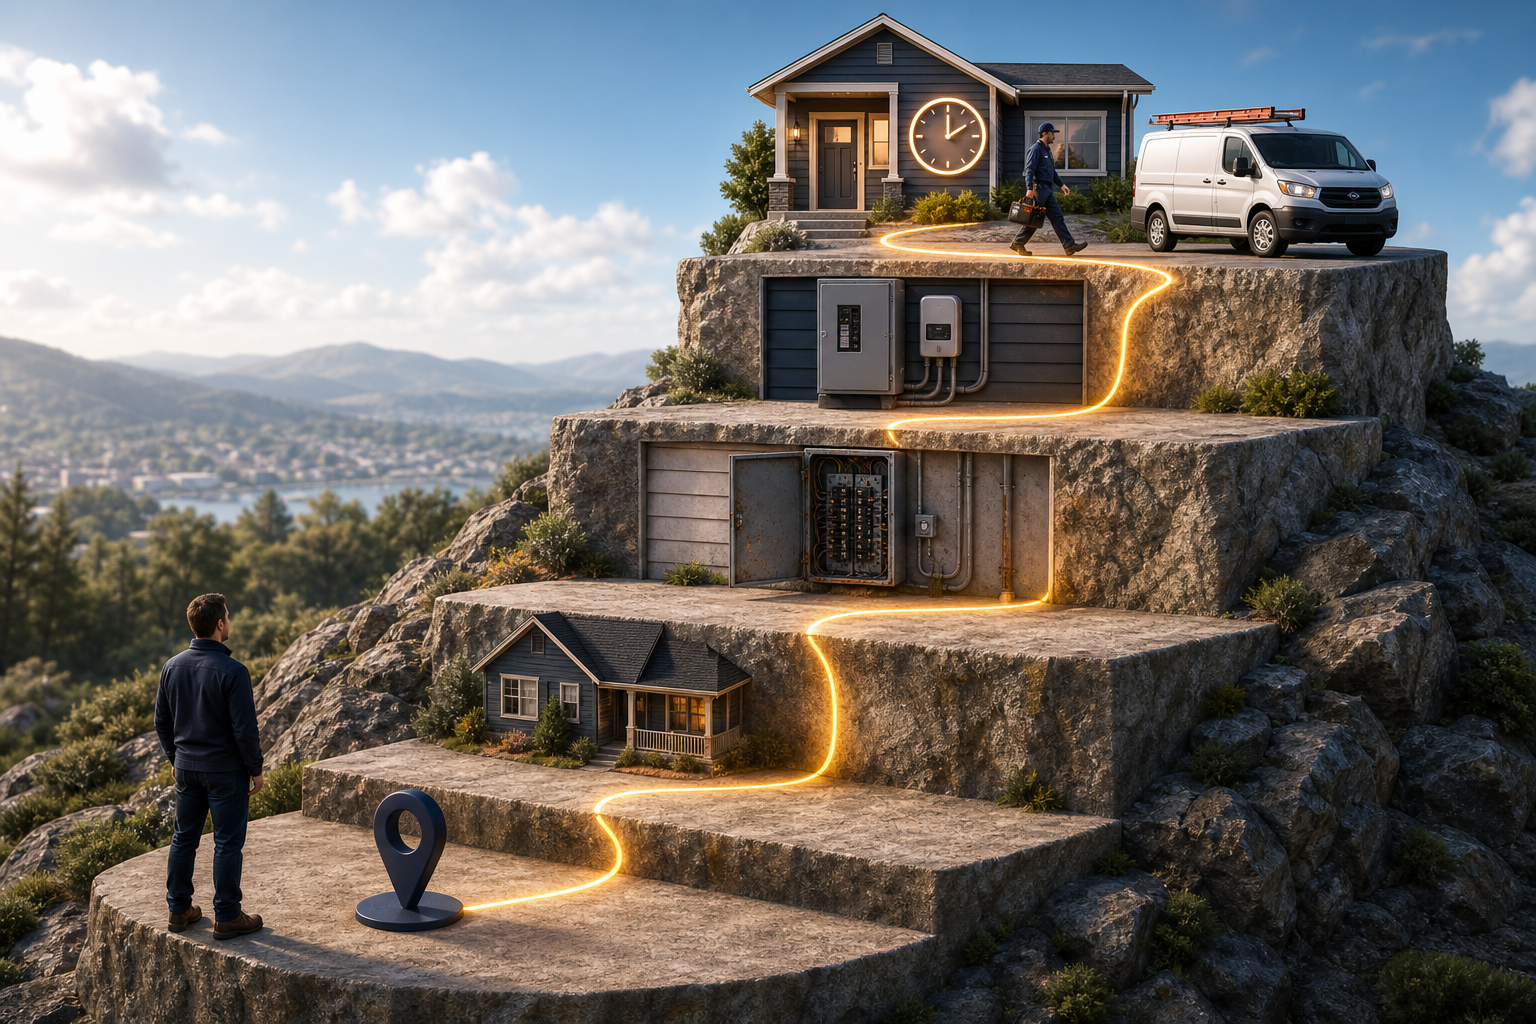
    A person follows a glowing path up five platforms marked by progressively more specific home-service symbols toward a contractor van.

    A single near me query cannot tell you whether the system understands your specialties. Use a five-level progression from a basic local need to a conversational decision request. Keep the underlying service and locality consistent so you can see what changes as intent becomes richer.

    1. Basic local need: HVAC company nearby. This checks whether the business enters a broad category-and-location result.
    2. Defined service: Electrician for a panel upgrade in an older home. This introduces a named job and a meaningful context.
    3. Situational fit: I need a panel upgrade in an older home and want a company that regularly handles this kind of work. This asks the system to interpret suitability rather than category alone.
    4. Trust requirement: Which local electrician appears dependable for this job, and what evidence supports that? This tests whether the answer can attach a reason to the selection.
    5. Decision request: Help me choose a local electrician for an older-home panel upgrade, prioritizing relevant experience and responsive communication. This combines service, context, trust, and a decision criterion.

    These prompts are templates, not universal keywords. Replace the service and context with the real decisions your customers face. A plumber might test a specific repair and property situation. An HVAC company might test a system type, service need, and availability concern. A professional practice might test the matter handled, client context, and trust requirement.

    Do not include your brand name unless you are deliberately testing branded comprehension. The purpose of an unbranded audit is to discover whether the business can be selected from evidence, not whether Google recognizes a name you supplied in the prompt.

    Record more than presence or absence for every prompt:

    • Inclusion: Did the business appear anywhere in the answer?
    • Selection: Was it merely listed, or framed as a suitable option?
    • Explanation: What reason, if any, was attached to it?
    • Evidence: Did the explanation appear to rely on the profile, reviews, the website, or another visible source?
    • Accuracy: Was the description correct, incomplete, stale, or unsupported?
    • Missing fit: Which part of the prompt could not be connected to clear evidence about the business?

    Document the locality, prompt wording, account context, and date alongside the output. A result from a particular setup is an observation, not a universal rank. Keeping the setup visible makes later checks interpretable and prevents a changed prompt from being mistaken for improved visibility.

    Turn recommendation gaps into a prioritized backlog

    The audit becomes useful when each failure leads to a different response. Do not answer every disappointing result by adding more keywords to the same page.

    • Broad discovery gap: The business is absent even for the basic local need. Check fundamental profile accuracy, business identity, locality, and whether the service is actually represented before expanding content.
    • Service comprehension gap: The business appears for the broad request but drops out when a specific job is added. Build or improve the page that explains that job, and align the profile service information with it.
    • Situational gap: The service is understood, but a property type, use case, or constraint breaks the match. Add the context only if the business genuinely serves it, and explain how it affects the engagement.
    • Evidence gap: The business appears but receives no meaningful rationale, or the rationale is thin. Look for credible detail across reviews, service pages, and external mentions rather than adding unsupported superlatives.
    • Accuracy gap: The answer describes the business incorrectly. Correct conflicting facts on surfaces you control and investigate visible third-party information that may be stale. Do not publish a new claim merely to overpower an old one.
    • Conversion gap: The recommendation is accurate, but the destination page leaves the customer unsure what to do. Make the service boundary, contact route, and next step explicit.

    Prioritize accuracy first because an incorrect recommendation can create poor leads and erode trust. Then work from broader comprehension toward narrower situational evidence. There is little value in polishing a specialized page if the profile and site still disagree about the basic service.

    Measure progress with a small set of diagnostic fields rather than one supposed Ask Maps ranking:

    • Intent coverage: which important customer situations have clear supporting facts across the profile and site?
    • Selection depth: at what point in the intent ladder does the business stop appearing or stop being treated as a fit?
    • Explanation accuracy: do the reasons attached to the business match what it actually provides?
    • Evidence alignment: do profile facts, website explanations, reviews, and visible external information tell a compatible story?
    • Change history: which factual or content update preceded a meaningful change in observed answers?

    Avoid claiming causation from a single before-and-after check. Locality-based results are not exhaustive, and several information sources may contribute to an answer. Build a change log, repeat the same useful prompts over time, and look for consistent movement in selection and explanation.

    Key takeaways

    • Ask Maps can move beyond listing nearby businesses and interpret which options appear to fit a detailed local request.
    • Your Business Profile establishes identity, your website explains capability, and reviews provide customer evidence. Improve them as one connected system.
    • Build service pages around real jobs, contexts, boundaries, and decisions rather than producing interchangeable city-and-keyword pages.
    • Test broad, service-specific, situational, trust-focused, and decision-oriented prompts to find where the system loses confidence in the match.
    • Track inclusion, selection, explanation, evidence, and accuracy. A single position cannot describe personalized local discovery.
    • Use structured data to encode accurate visible information, not to manufacture relevance that the page and business cannot support.

    Choose a service that matters to your business and build its intent ladder now. The first useful output is not a better-looking rank report. It is the first point where the recommendation breaks, the evidence missing at that point, and a specific profile, page, or accuracy update you can make to close the gap.

    References


  • Google Maps Contributor Features: A Practical Workflow

    Google Maps Contributor Features: A Practical Workflow

    You have useful photos on your phone and first-hand details about a place, but turning them into a clear Google Maps contribution still takes judgment. The latest contributor features reduce the mechanical work: they surface media sooner, draft captions and make contributor history more visible.

    Use that convenience to publish more useful evidence, not simply more content. A faster upload, an AI-written caption or a prominent badge can attract attention, but none of them can make a vague or inaccurate contribution trustworthy.

    Key takeaways

    • Local Guides profiles now place greater emphasis on total points, levels and badges. Gold profile indicators can make top contributors more noticeable, but prominence is not proof that every contribution is accurate.
    • Gemini can analyze selected photos and propose a caption. You can edit or discard the draft, so treat it as a starting point rather than an observation you must accept.
    • The Contribute tab surfaces recent uploads, while camera-roll suggestions can shorten the path from taking a photo to sharing it. Media access is required for those suggestions.
    • These features may affect which reviews and businesses receive attention. They do not, by themselves, establish a direct improvement in local rankings, AI-search visibility or business performance.

    Match each contributor feature to the job it actually does

    The contributor changes solve three different kinds of friction. Keeping those jobs separate prevents you from treating every feature as a ranking tool.

    • Contributor profiles provide context. The redesigned Local Guides profile displays total points and levels more prominently, gives badges a refreshed presentation and adds gold profile indicators for top contributors. These are reputation and attention signals around a contribution. They do not verify the claim inside it.
    • Gemini caption drafts reduce writing friction. The feature analyzes the photos you select and proposes text that you can edit or reject. Its useful job is getting you past the blank field, not supplying knowledge that the image cannot contain.
    • Media suggestions reduce retrieval friction. Recent uploads appear in the Contribute tab, and Google Maps can suggest camera-roll images after you allow media access. This helps when the obstacle is finding the right photo later.

    If you contribute regularly, test every photo or review without its profile decoration: would the content still help someone choose an entrance, recognize a storefront, understand the layout or set an accurate expectation? If not, more points and a brighter badge will not repair it.

    If you manage local visibility for a business, reverse the test. A gold indicator may cause a user to notice a review, but you should still inspect the review’s specificity, recency and visible evidence. Contributor status is context for evaluating a claim, not a substitute for evaluating it.

    Edit Gemini captions until they say what the photo proves

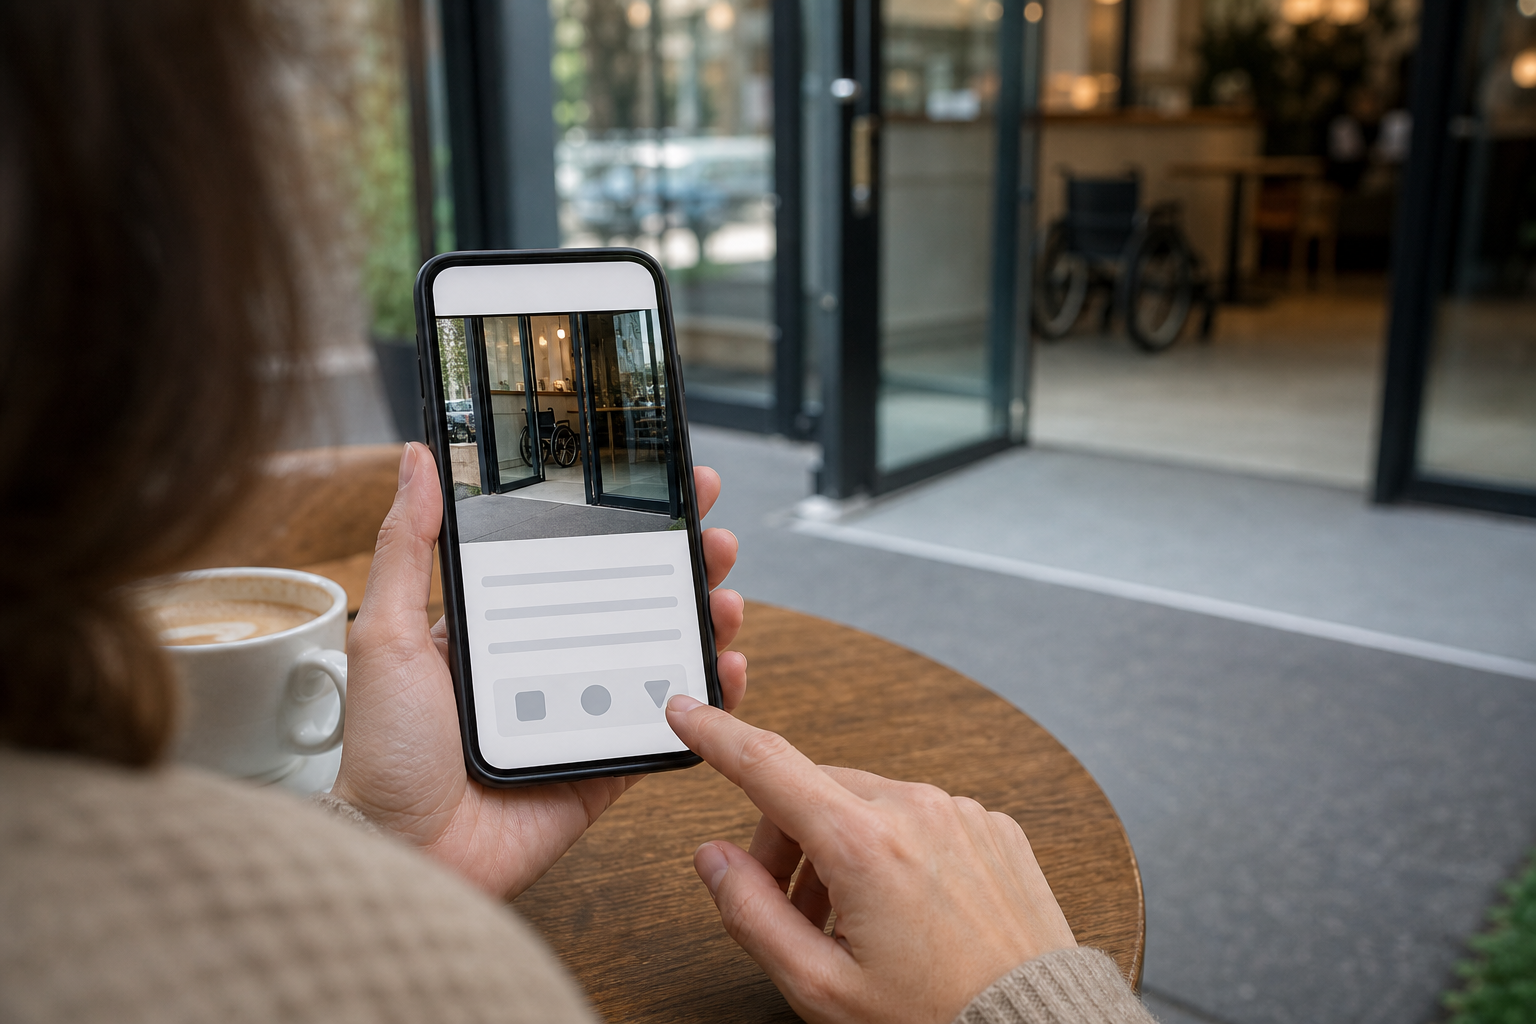
    A contributor compares a phone photo with a cafe's accessible entrance while editing a draft description.

    At its introduction, the Gemini caption feature was available in English on iOS in the United States. Broader Android and international availability was planned. Availability can therefore differ by device, language and location; keep a manual caption workflow even if another contributor already has the control.

    The most important limitation is conceptual. Gemini can analyze the selected image, but a photo does not necessarily prove how the service felt, how food tasted, whether a route is fully accessible or whether a temporary display will remain in place. The draft can turn a visual impression into a stronger claim than the evidence supports.

    Use a four-pass caption edit

    1. Name the visible subject. Identify the entrance, seating area, menu board, counter, parking area or other feature the photo is meant to show.
    2. Remove inferred praise. Delete generic judgments such as “excellent,” “welcoming” or “perfect” unless the caption is deliberately expressing your own experience and the wording makes that clear.
    3. Add decision-relevant context. Explain where the photographed feature is located or why someone might need to recognize it. Add only details you observed or verified.
    4. Check whether the claim will age badly. Prices, hours, displays and layouts can change. Do not present a time-sensitive detail as a permanent feature.

    For example, a draft such as “A cozy cafe with plenty of seating” is broad and evaluative. A more useful edit would be “Indoor tables are beside the front window, with the order counter at the back.” The second version tells a visitor what the image is intended to establish without pretending that the photo proves comfort, availability or service quality.

    There is also a quick test for generic AI text: ask whether the same caption could be pasted onto a different venue’s photo without anyone noticing. If it could, the caption is not finished. Name the concrete feature that makes this image useful at this place.

    Turn camera-roll suggestions into a controlled publishing queue

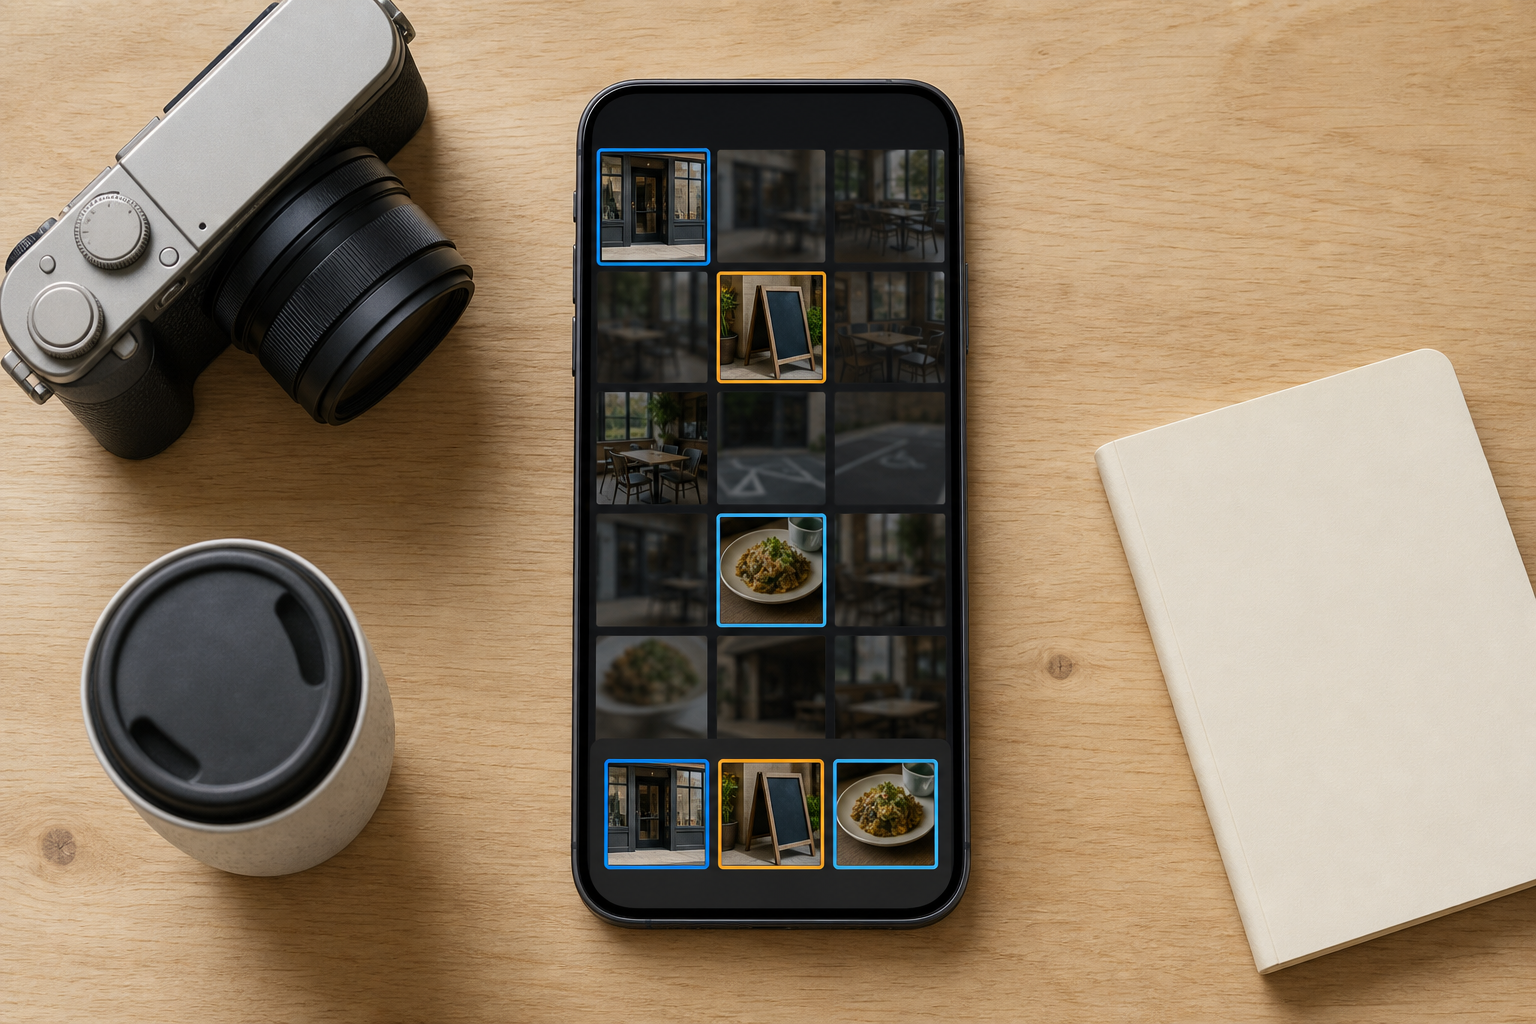
    A smartphone displays selected and dimmed place-photo thumbnails arranged as a controlled publishing queue.

    The media-sharing update has a broader footprint than the initial caption rollout. Recent media and camera-roll suggestions were made available on iOS and Android globally. Suggestions depend on granting media access.

    A suggestion is an invitation to review an image, not confirmation that the image belongs on Maps. Camera rolls also contain duplicates, screenshots, private details and photos whose location is ambiguous. Put a short verification step between the prompt and the publish button.

    1. Open the Contribute tab after a visit. Review the recent media while you can still distinguish the venue and remember what each image shows.
    2. Confirm the exact place. Check the name and location, especially when a business has several branches or neighboring listings look similar.
    3. Choose the highest-information image. Prefer a photo that answers a practical question over several nearly identical angles.
    4. Inspect the full frame. Exclude unrelated or sensitive details and any image too blurry, dark or obstructed to support its caption.
    5. Write or generate the caption. Apply the evidence test even when Gemini supplies the first draft.
    6. Read the listing and caption together. Make sure the text describes this image at this place, then publish only when both are unambiguous.

    If you are not comfortable enabling camera-roll access, do not enable it merely to save a few taps. A slower, deliberate selection process is better than a convenient workflow you will not review carefully. You can also revisit the relevant operating-system permissions if your comfort level or contribution habits change.

    Do not mistake contributor visibility for a ranking result

    More prominent contributor profiles, faster media sharing and clearer captions can change what people notice. That can influence which reviews they consider credible and which businesses receive attention. It is still a leap from increased attention to a claim that a feature directly raises a business in Google Maps, local search results or an AI-generated answer.

    Three outcomes need separate measurement:

    • Publishing efficiency: Did the recent-media flow help you turn relevant photos into completed contributions instead of leaving them in a backlog?
    • Contribution quality: Did the final captions become more specific, accurate and useful after editing, or did AI merely increase the volume of generic text?
    • Search or business visibility: Did the business’s observed visibility change after the contribution? If it did, record the timing as a correlation. Do not assign causation without isolating other listing, review, competition and search changes.

    The same restraint applies to AEO and GEO claims. A Google Maps caption may add useful public context around a place, but these contributor changes do not demonstrate that a frontier model will retrieve, cite or rank that caption. Treat any such effect as a hypothesis to measure, not a benefit to promise.

    Start with one recent photo that answers a real visitor question. Verify the place, edit the caption until every claim is supportable and record when you published it. If the workflow consistently produces clearer contributions, keep it. If it only produces more contributions, tighten the review step before you scale it.

    References


  • Google Content Quality: How AI-Assisted Pages Can Rank

    You have an AI-assisted page ready to publish, but one question is holding it up: will Google treat the content as low quality because a model helped write it? Rewriting every sentence by hand is not the answer. Neither is publishing the model’s first draft and hoping formatting or schema will make it competitive.

    The practical job is to create a page whose claims a human editor can defend. That matters in conventional search and in AI-generated answers. Google has acknowledged using protections against manipulative, low-quality listicles in both Search and Gemini, while ranking data show that detectable AI writing patterns are associated with much weaker performance at the top of Google. The useful response is better evidence and editorial judgment, not an attempt to disguise the production method.

    Ranking data does not prove that Google penalizes AI

    Across 42,000 blog pages classified for a Semrush analysis, human-authored content occupied Google’s number-one position 80% of the time, compared with 9% for purely AI-generated content. Human-authored pages also appeared more often throughout the top 10, while pages classified as AI-generated became more common in lower positions on the first results page.

    Those numbers are a warning against unchecked automation, but they are not evidence of a direct AI penalty. GPTZero was used to classify the pages, and AI detectors can misclassify human, mixed, and machine-generated writing. Because writing type and ranking position were observed together, the result is correlation. It does not reveal which signals Google used or establish that authorship method caused the rankings.

    That distinction changes what you should do. Do not run every draft through an AI detector and rewrite it until the detector returns a preferred label. A detector score is not a Google quality score, and prose that looks human can still be generic, inaccurate, or commercially biased.

    Instead, test whether the page contains judgment that survives scrutiny:

    • Decision value: Does the page help a specific reader choose, fix, avoid, or understand something?
    • Evidence: Can you trace every consequential claim to genuine experience, a supplied record, or a reliable reference?
    • Boundaries: Does the recommendation say who it is for, when it applies, and when it does not?
    • Editorial ownership: Has a named person or accountable team decided that the claims are accurate and worth publishing?
    • Original contribution: Does the page add an explanation, distinction, method, or decision rule beyond what a model could infer from common web copy?

    A human-written page that fails those tests is still weak. An AI-assisted page that passes them has a defensible reason to exist. That is a more useful quality distinction than human versus machine.

    Content quality breaks where evidence and independence are implied

    The clearest failure pattern appears in commercial listicles. A brand publishes a "best tools" page, includes products it has not tested, assigns unexplained scores, and places its own product first. The page looks like an independent evaluation even though the outcome, evidence, and publisher relationship are hidden.

    This is not just a question of writing style. The page is making an evidence claim: that someone performed a fair comparison and has grounds for the ranking. A fluent AI draft can make that unsupported claim sound more convincing, which increases the problem rather than solving it.

    What the page claims to beEvidence it needsHow to frame it honestly
    Independent reviewGenuine use or testing by the reviewerIdentify what was tested, how it was tested, and any limits that affected the conclusion.
    Feature comparisonVerifiable product facts and declared comparison criteriaCall it a researched comparison and do not imply firsthand use that did not occur.
    Owned recommendationSupport for each claim plus a clear material-relationship disclosureState that the publisher owns or sells one of the products and explain how the recommendation was reached.
    Customer testimonialA genuine statement from the person to whom it is attributedPreserve the speaker’s meaning and do not create, rewrite, or assign praise that the person did not provide.

    Use "best" only when you can defend the category

    A defensible winner needs more than a score. Define the audience, use case, eligibility rules, criteria, weighting, evidence type, exclusions, and material relationships. If changing an unstated preference could reverse the result, you do not have an objective ranking. You have an editorial preference that should be presented as one.

    Conditional recommendations are usually more useful than universal winners. "Best for teams that need a self-hosted workflow" gives the reader a decision condition. "Best overall" conceals the condition and invites you to defend a much broader claim.

    If you did not test the products, remove language such as "we found," "our test showed," or "after using." You can still compare documented capabilities, but label the work accurately. A researched feature matrix is not a review, and turning it into one with confident prose does not create the missing experience.

    Treat disclosure as part of the answer

    Including your own product in a comparison is not the same as presenting the comparison as independent. Put the relationship where a reader will encounter it before relying on the ranking. A disclosure buried after the recommendations does not help someone interpret the claims that came first.

    The legal exposure deserves separate attention. The FTC’s Consumer Review Rule, 16 CFR Part 465, took effect in October 2024 and prohibits deceptive practices involving reviews and testimonials, including presenting company-controlled material as independent, reviewing products that were not actually used, and attributing reviews to people who did not write them. Penalties can reach $53,088 per violation.

    These are editorial risk controls, not a legal opinion about your page. If you publish testimonials, comparative scores, endorsements, or rankings involving your own product, have qualified counsel assess the specific presentation and relationships. Do that before scaling the template across many URLs, because repeating the same defect multiplies the exposure.

    Build a human-led workflow around verifiable claims

    AI is valuable when its role is explicit. Among 224 SEO professionals surveyed, 87% retained substantial human involvement and 64% used a human-led, AI-assisted process. Speed was the main benefit for 73%, while only 19% credited AI with improving quality. That gap is the operating principle: automation can accelerate production, but your workflow must create quality somewhere else.

    A reliable process separates transformation from judgment:

    1. Write the reader’s decision first. Complete this sentence before drafting: "After reading this page, the reader should be able to decide whether…" If you cannot finish it precisely, the page does not yet have a useful purpose.
    2. Create a claim ledger. For every important assertion, record the proposed wording, supporting evidence, applicable limit, commercial relationship, and person responsible for verification. Unsupported claims should not enter the prompt as facts.
    3. Give AI a closed evidence set. Ask it to organize only the material you supply, preserve uncertainty, mark missing support, and avoid inventing experience. This makes omissions visible instead of allowing fluent filler to hide them.
    4. Add the human decision layer. A subject-matter editor chooses which evidence matters, resolves conflicts, defines tradeoffs, and decides when no recommendation is justified. These are editorial decisions, not sentence-generation tasks.
    5. Run an adversarial review. Challenge every superlative, score, testimonial, first-person experience claim, and statement about a competitor. Ask what proof would be required if the affected company or customer disputed it.
    6. Edit for direct retrieval. Give each section one clear job, answer its heading promptly, name the entity being discussed, and keep conditions next to the claims they qualify. This improves comprehension for readers and reduces the chance that an answer system extracts an unqualified statement.
    7. Approve facts separately from prose. A smooth final edit can introduce errors by changing scope or certainty. Recheck names, figures, dates, links, disclosures, and recommendation conditions after the prose is polished.

    Within this process, AI can reorganize notes, propose outlines, identify repetition, generate alternative explanations, and convert approved information into another format. It should not manufacture a test, infer customer sentiment, create a score, or turn a product relationship into an independent recommendation.

    Structured data comes after the editorial work. JSON-LD can clarify the entities and content already visible on the page, but it cannot supply missing evidence or convert an opinion into a verified fact. Keep markup aligned with the visible wording, authorship, review status, and relationships. A technically valid schema implementation attached to a misleading page only makes the underlying claim more structured.

    Audit existing AI content by risk, not detector score

    Do not mass-delete pages because a detector labels them as AI-generated. Detector classifications are uncertain, and deleting a useful URL can discard rankings, links, internal pathways, and conversion history without fixing the actual editorial weakness.

    Start with pages where quality and commercial risk overlap:

    • "Best," "top," and comparison pages that rank your product first.
    • Reviews of products your team cannot show it used or tested.
    • Pages with numerical or categorical scores but no reproducible method.
    • Testimonials whose author, wording, permission, or origin cannot be verified.
    • Templates that repeat the same recommendation across many queries with only nouns changed.
    • Pages where citations exist but do not support the sentence beside them.

    Choose a page-level action

    • Keep: The page answers a real decision, supports its claims, discloses relevant relationships, and contributes useful judgment. Improve clarity without rewriting it merely to change an AI score.
    • Rebuild: The topic is valuable, but the evaluation lacks evidence. Obtain the missing evidence, revise the method, and have a human editor make the recommendation again.
    • Reframe: The factual material is sound, but the page implies testing that did not happen. Convert it into a documented feature comparison, directory, or selection checklist and remove review language.
    • Retire or consolidate: The page adds no unique decision support and duplicates a stronger URL. Check traffic, backlinks, internal links, and business value before changing the URL or status.

    If a page contains potentially fabricated reviews, false firsthand claims, or undisclosed company-controlled recommendations, remove the questionable claims from public view and involve counsel. That is different from a routine quality refresh and should not wait for the next editorial cycle.

    Use a stop-ship publication gate

    Do not publish when any of these statements is true:

    • The page claims firsthand use, but nobody can identify who used the product or what was done.
    • A score cannot be reproduced from the stated criteria and evidence.
    • Your own product wins, but ownership or another material relationship is not clear before the recommendation.
    • A testimonial cannot be matched to the person and words behind it.
    • A consequential factual claim has no support, or its citation supports a narrower claim than the prose makes.
    • The draft hides uncertainty by converting "may," "for this use case," or "based on documented features" into an absolute conclusion.

    Once those failures are cleared, improve usefulness. Put the direct answer near the question it resolves. Separate observed facts from editorial judgment. Include the condition that would change the recommendation. Remove paragraphs that merely restate the keyword. Make every heading earn its place by helping the reader do, decide, or notice something distinct.

    Key takeaways

    • Do not treat an AI detector result as a Google ranking verdict; use evidence, decision value, and editorial accountability as the quality test.
    • Use AI to transform approved material and accelerate production, while people retain responsibility for truth, tradeoffs, recommendations, and publication.
    • Do not imply independent testing, customer experience, or objective scoring unless you can prove it and disclose relevant commercial relationships.
    • Define who a recommendation is for and what would change it; conditional advice is more defensible and more useful than an unsupported universal winner.
    • Audit high-risk comparison and review pages first, then rebuild, reframe, or retire each URL according to its evidence and unique value.
    • Add schema only after the visible content is accurate; structured data can describe a claim, but it cannot make the claim true.

    Choose one commercially important AI-assisted page and build its claim ledger before touching the prose. Remove anything you cannot support, expose the method and relationships, and let a human editor make the final recommendation. That single page will give you a reusable quality standard for every brief, prompt, comparison, and schema deployment that follows.

    References

  • A Practical Framework for Local Spanish AI Search Visibility

    A Practical Framework for Local Spanish AI Search Visibility

    You can publish polished Spanish content and still disappear from an AI answer, appear under the wrong country, or be described with the wrong currency, service area, or legal context. When that happens, translation quality usually isn’t the whole problem. Your pages are asking the system to infer which market you mean.

    The fix is to treat every answer as a market-specific record: who it applies to, where it applies, what the local terms mean, and which business facts support it. You then repeat that context across your pages, local profiles, structured data, product feeds, and customer-facing answers.

    Treat Spanish as a language, not a location

    A language choice does not establish a country, city, jurisdiction, or commercial market. A page can be grammatically correct in Spanish while remaining geographically unusable.

    This distinction matters more in generative search than it did in a conventional results page. A list of links lets the searcher notice that one result comes from Spain and another from Mexico. An AI response may instead combine several markets into one apparently authoritative answer. If the synthesis is wrong, the user may never see the correct local page underneath it.

    Context layerWhat the system must distinguishWhat can go wrongWhat your content should state
    Language varietyRegional vocabulary, formality, and product terminologyThe answer sounds imported or describes the wrong product categoryThe words customers use in that market and the preferred form of address
    GeographyCountry, region, city, and service areaA local query returns a supplier, branch, or recommendation from another countryThe country and served locations in visible copy, not only in navigation or metadata
    CommerceCurrency, number format, payment options, shipping, and availabilityA price is misread or an unavailable purchasing method is presented as validThe applicable currency, displayed number format, fulfillment limits, and payment conditions
    JurisdictionRegulator, tax identifier, legal vocabulary, and governing rulesTerms such as Hacienda, SAT, NIF, and RFC are treated as interchangeableThe jurisdiction, applicable authority, and limits of the answer

    The failure is easy to see in a tax question. An answer can be fluent while mixing RFC, NIF, and SSN into a single checklist. Currency and punctuation create quieter errors: Mexico and European Spanish conventions can give periods and commas different numerical meanings. The text still looks localized, but the transaction it describes may be wrong.

    Use a simple decision rule when planning pages. Create a distinct country version when the market changes the offer, eligibility, price currency, number format, fulfillment, payment method, legal obligation, or vocabulary needed to identify the product. Add a location-specific page or section when availability and customer questions change within that country. Keep a shared Spanish page only when its answer remains true for every market it claims to serve.

    Do not solve the problem by cloning the same generic page across a directory of country codes. A changed place name wrapped around unchanged advice gives an AI system more URLs but no better evidence. Each local version needs a reason to exist and enough market-specific facts to make that reason visible.

    Build a market-specific answer system from real questions

    People in different neighborhood settings organize local question, service, product, and policy symbols into separate answer packages.

    Your localization plan should begin with customer uncertainty, not a keyword export. Reviews, support calls, social replies, sales conversations, local profiles, and on-site searches reveal the wording people use when they need to make a decision. They also expose questions that broad national search-volume tools can miss.

    Create a market brief before drafting pages

    1. Define the market unit. Record the country, relevant region or city, service area, and Spanish variety. If a branch has different inventory, hours, eligibility, or delivery coverage, treat those as location facts rather than burying them in a national answer.
    2. List the commercial facts that can change. Include currency, displayed number format, payment methods, shipping or appointment limits, product availability, contact details, and any local terminology customers use to describe the service.
    3. List regulated facts separately. Record the jurisdiction, regulator or authority, legal identifiers, reviewer, and review trigger. Do not let a reusable marketing template overwrite this layer.
    4. Collect the questions customers actually ask. Preserve the original regional wording alongside a normalized topic label so you can recognize equivalent intent without erasing dialect.
    5. Assign a canonical answer, an owner, a public URL, the channels where the answer appears, and the conditions that require an update.

    The brief becomes the source of truth for that market. It prevents a translator, local manager, product-feed owner, and social team from independently producing four plausible but incompatible versions of the same fact.

    Turn local language into canonical answers

    Generic questions such as “What services do you offer?” rarely resolve local uncertainty. Better questions expose a boundary: whether you deliver to a named city, whether a quoted price uses MXN or EUR, whether a service is available for a particular building type, or which jurisdiction governs a requirement. Region-specific questions can be useful even when they have little national search volume.

    For each question, maintain a compact answer record containing:

    • The customer’s original wording and the normalized intent.
    • The country, region, city, or branch to which the answer applies.
    • A direct answer that states the decisive fact first.
    • Necessary conditions, exclusions, and next steps.
    • The page, profile, feed, and support material where the answer is published.
    • The person responsible for accuracy and the event that should trigger review.

    Publish each answer where it helps the decision. A delivery limitation belongs near delivery information. A market-specific eligibility answer belongs on the relevant service page. A short FAQ can support either page, but a giant FAQ archive should not become the only place where critical local facts appear.

    Then reconcile the answer across every channel you control. Hours, service areas, prices, accepted payment methods, product availability, and legal wording should not change when a user moves from your website to a local profile or social response. Conflicting answers across customer-facing platforms weaken the reliability of the information available for AI extraction.

    More detail helps only when it is local, current, and internally consistent. A long answer that mixes several countries is worse than a short answer with an explicit jurisdiction. When tax, insurance, compliance, or another regulated decision is involved, name the jurisdiction and have the content reviewed by an appropriately qualified local professional. Explain general requirements, but route advice about an individual’s circumstances to that professional.

    Make the same locale obvious in copy, code, profiles, and feeds

    Matching location and business-detail symbols connect a miniature neighborhood with webpage, code, profile, and product-feed stations.

    No individual technical signal can force an AI system to cite or recommend a page. Your goal is corroboration: every readable and machine-readable layer should describe the same entity in the same market.

    Give each meaningful market version a clear web identity

    • Use a stable URL for each genuinely distinct market version, such as a country-specific Spanish directory. Avoid changing URLs merely to test regional wording.
    • Set the document language to the appropriate Spanish locale when you know it, such as es-MX or es-ES, rather than using one undifferentiated setting for every regional version.
    • Connect alternate market pages with accurate hreflang annotations. Each page should identify the correct regional alternate, while its canonical URL should represent the version you actually want indexed.
    • Do not canonicalize a distinct local page to a generic Spanish page. That tells crawlers the generic version is preferred even though you created the local page to communicate different facts.
    • Name the country and relevant service area in visible headings and copy. A flag icon, URL folder, or language selector is not a substitute for an explicit market statement.
    • Link to the local version from the corresponding country, location, service, and contact paths. Avoid leaving important regional pages reachable only through a selector that a crawler or user may not encounter.

    Hreflang helps describe language and regional alternates; it does not establish the truth of your inventory, legal claims, or service coverage. The visible answer still needs to contain the facts that make the regional distinction useful.

    Use JSON-LD to corroborate visible facts

    Structured data should mirror the page, not carry a hidden localization strategy. Use the most specific applicable entity type, such as Organization or LocalBusiness, and give each distinct entity or location a stable identifier. Do not reuse one identifier for branches that have different addresses or operational facts.

    • Represent the location with a PostalAddress whose locality, region, and country match the visible contact information.
    • Describe the actual area served on the relevant organization or service entity. Do not mark up locations the business does not serve.
    • Use inLanguage on applicable content entities to reinforce the page’s Spanish locale.
    • When a product or offer displays a price, keep priceCurrency aligned with the visible currency and the associated feed.
    • Connect official profiles only when they represent the same business or branch.
    • If you use FAQPage markup, mark up only questions and answers users can read on that page. Keep the structured answer identical in meaning to the visible answer.

    FAQ markup is not a localization switch and does not guarantee an AI citation or search feature. Its value here is narrower: it gives a well-formed version of an answer that already states its market clearly.

    Your off-site surfaces need the same treatment. Google Maps can answer place questions without requiring a website visit, so local profile facts cannot be treated as secondary metadata. Name, address, phone, hours, categories, service area, and linked landing page should describe the same location.

    Commerce data is another answer surface. Merchant Center’s Business Agent can draw from product data and site content during chat interactions. A Spanish product page that shows MXN while its feed supplies another currency creates ambiguity at the moment the user is trying to buy. Align locale, price, availability, and destination URL across the page and feed.

    Audit answer accuracy by market, not language alone

    A localized page is not finished when it is published. You need to see whether AI systems preserve the country, entity, offer, and constraints when they assemble an answer. Because generated outputs can vary, a single successful query is evidence of one result, not proof that the market is understood.

    1. Build a test set around decisions that matter: finding a provider, checking availability, comparing an offer, understanding a price, confirming a service area, and resolving a regulated question.
    2. Run each intent in generic Spanish, with the country stated, and with the relevant city or region stated. The difference shows whether the system holds the right market only when the user supplies it explicitly.
    3. Record the tool, date, account or location conditions, exact query, answer, cited or linked pages, and any named business. Keep those conditions as stable as practical when you repeat the test.
    4. Check geography, entity identity, terminology, currency and number format, availability, and jurisdiction separately. A fluent response can pass the language check while failing every commercial check.
    5. Trace each error to the information environment. Look for a missing local answer, a generic page outranking the local version, conflicting profile data, an incorrect feed, ambiguous structured data, or a third-party listing that no longer matches the business.

    Track correctness and visibility as different outcomes

    Use a small set of operational measures so improvements do not disappear inside a general visibility score:

    • Market accuracy: the share of applicable test answers that keep the correct country or local service area.
    • Entity accuracy: the share that identify the correct business, branch, product, or service.
    • Answer coverage: the customer questions for which your site or controlled profile provides a complete, market-specific answer.
    • Conflict count: active contradictions across pages, profiles, feeds, social answers, and other listings you monitor.
    • Source visibility: whether the generated answer cites, links to, or clearly reflects your canonical local page.

    Read those measures together. High source visibility with low market accuracy means the system can find you but is extracting or combining the wrong facts. High accuracy with low source visibility means your information may be correct while another entity receives the attribution. Low coverage means you need better answers before you need more markup.

    Fix errors in consequence order

    1. Correct jurisdiction, eligibility, currency, pricing, and availability errors first. These can produce legal exposure, lost transactions, or promises the business cannot fulfill.
    2. Resolve entity confusion next. Separate branch identities, URLs, addresses, profiles, and structured-data identifiers where the system is merging distinct locations.
    3. Fill unanswered local questions with direct canonical answers drawn from customer language.
    4. Repair contradictions across controlled channels and request corrections on inaccurate third-party listings where possible.
    5. Refine dialect, tone, and regional vocabulary after the underlying market facts are correct.

    If an AI answer relies on a third-party page, do not respond by adding another vague paragraph to your site. Publish the missing fact on the most relevant local page, update the matching official profile or feed, and reconcile every controlled instance. Supplying complete first-party answers makes it less necessary for a system to fill gaps from outside sources or omit the business.

    Review triggers matter more than an arbitrary publishing schedule. Recheck the answer set when prices, service areas, branch details, inventory, payment options, regulations, or approved terminology change. Stable descriptive content can follow a normal editorial review cycle; a wrong currency or expired eligibility condition should be corrected across every surface as soon as it is found.

    Key takeaways

    • Spanish identifies a language family, not a country, jurisdiction, currency, or service area.
    • Create a distinct market version when local facts change the offer or the answer, not merely to insert a country keyword.
    • Build canonical answers from reviews, calls, social questions, sales conversations, and local profile interactions.
    • Keep visible copy, URLs, language annotations, JSON-LD, local profiles, and product feeds aligned around the same entity and market.
    • Audit whether AI outputs preserve the correct geography, entity, commercial facts, and jurisdiction; do not score fluency as accuracy.

    Start with your highest-value service in the market where a wrong-country answer creates the greatest commercial or legal risk. Build its market brief, publish the missing canonical answers, align the technical and off-site signals, and run the same query set again. Expand only after the output reliably keeps the right country, entity, and facts together.

    References


  • Google March 2026 Core Update: Diagnosis and Recovery Plan

    Google March 2026 Core Update: Diagnosis and Recovery Plan

    Your organic traffic moved during March 2026, and the tempting response is to rewrite every page that lost clicks. Resist that impulse. Google’s first core update of 2026 arrived close to separate spam and Discover changes, so a simple month-over-month chart cannot tell you what happened.

    Your first job is attribution: isolate the affected search surface, query set, page group, and shared weakness. Then change only what the evidence supports. This protects strong pages from panic edits and gives you a credible way to judge whether the work helps.

    Key takeaways

    • Google said the March 2026 core update could take up to two weeks to roll out. Treat movement inside that window as provisional rather than a final verdict.
    • Do not attribute every March change to the core update. A March spam update, a February Discover update, your own site releases, tracking problems, and changing demand can produce different patterns.
    • Diagnose at the level of search surface, query cluster, page group, and template. A sitewide traffic total hides the pattern you need to fix.
    • Audit whether losing pages satisfy the searcher’s task more clearly and completely than competing results. Cosmetic rewrites and extra keywords are not a recovery strategy.
    • There is no universal or immediate repair. Improvements can appear gradually, including after later core updates, so preserve evidence and measure each coherent batch of changes.

    Treat March as an attribution problem, not a verdict

    A core update is a broad reassessment of how Google’s systems surface useful results across many sites and searches. Google characterized this release as a regular update focused on relevant and satisfying content. A ranking loss does not, by itself, prove that a page violated a rule, received a manual penalty, or needs to be deleted.

    The surrounding timing matters. The core update followed a March 2026 spam update and a February 2026 Discover update. Those events are not interchangeable. A change confined to Discover should not automatically become a core-update content project. A Web Search decline should not be blamed on Discover. A sitewide drop across every acquisition channel may point to measurement, demand, or a site release rather than Google rankings.

    Build a timeline before opening your content editor. Mark the core, spam, and Discover milestones; Google’s confirmed rollout completion; and every meaningful change your team shipped nearby. Include migrations, URL changes, template releases, internal-link changes, tracking updates, large content batches, and availability or pricing changes that could affect demand. The purpose is not to choose a convenient explanation. It is to keep plausible causes separate long enough to test them.

    Use comparable reporting periods on either side of the event. Match the length and weekday mix, and note seasonal or campaign-driven demand. If a comparison period overlaps the rollout, label the result provisional. For historical analysis, anchor the post-update period after Google’s confirmed completion marker rather than assuming the announcement date was the moment every ranking changed.

    Build a page-and-query evidence map

    Blank web page cards and search tokens are grouped and connected with colored threads on an evidence-mapping workspace.

    Start with Google Search Console and your analytics platform, but do not begin with total organic sessions. First separate Web Search from Discover and other channels. Within Web Search, compare impressions, clicks, click-through rate, and average position by query and page. Within Discover, examine the available page-level reporting on its own terms rather than forcing it into a Web Search query analysis.

    Group affected pages by the reason they exist: topic, search intent, content format, audience, template, authoring process, or business line. The useful unit is rarely one isolated URL. If a collection of similar pages declined together while the rest of the site held steady, the shared pattern is more informative than the site’s average.

    1. Save an untouched baseline export before editing anything. Preserve page, query, device, country, impressions, clicks, position, and conversion data where available.
    2. Separate losses in visibility from losses in response. Falling impressions or positions indicate a search-visibility problem. Stable impressions with fewer clicks point toward result presentation, changed result features, or user choice. Stable search clicks with weaker conversions point downstream to the landing experience, offer, tracking, or audience fit.
    3. Rank page groups by material impact, then look for repeated behavior. A cluster losing across many related queries deserves attention before a single volatile term.
    4. Record winners as well as losers. Unchanged and improving pages show which formats, topics, and approaches Google continued to surface on your own domain.
    5. Inspect the current results for the affected queries. Compare the task served, answer depth, format, specificity, freshness needs, and intended audience. Do not copy the winners; identify what searchers can accomplish there that they cannot accomplish on your page.
    Observed patternWorking interpretationNext check
    Web Search impressions fall across one topic clusterThe cluster may have lost relevance or competitiveness for those searchesCompare query intent, result types, answer depth, and the pages that replaced it
    Discover declines while Web Search remains stableThe evidence does not support a sitewide core-update diagnosisAnalyze Discover separately and account for the February 2026 Discover update
    One template declines across unrelated topicsA shared presentation, technical, or content-production pattern may be involvedCompare affected and unaffected templates, including rendering, indexing, internal links, and visible page structure
    Impressions remain stable but clicks declineVisibility may not be the primary problemReview titles, descriptions, competing result features, and whether the displayed promise matches the query
    Search clicks remain stable but conversions declineThe ranking update is not sufficient to explain the business lossCheck tracking, page behavior, offer changes, availability, and conversion flow
    All channels fall at the same timeA Google core update is unlikely to be the only causeCheck analytics integrity, site releases, outages, demand, and commercial changes

    These interpretations are starting hypotheses, not automatic diagnoses. Require the pattern to appear in the underlying page and query data before assigning work to it.

    Fix satisfaction gaps rather than chasing signals

    Google’s standing direction remains to create helpful content for people. That advice becomes useful only when you turn it into page-level questions. “Make it better” is not an action. “Move the procedure ahead of the company background because the dominant queries ask how to complete the task” is an action.

    Test the page against the searcher’s actual job

    Write the main task in one sentence before reviewing the page. Is the person trying to learn, compare, troubleshoot, verify, calculate, choose, or complete a process? Then locate the first point where the page materially serves that task. If the answer is buried beneath a generic introduction, brand narrative, or loosely related background, fix the order before adding more words.

    Check whether the title, opening, headings, body, examples, and call to action serve the same intent. A page often weakens when it promises one job in the search result, explains another in the body, and pushes a third in the call to action. Alignment matters more than repeating the target phrase.

    Find the missing decision support

    A page can be factually correct and still leave the reader unable to act. Look for absent prerequisites, constraints, tradeoffs, failure modes, definitions, examples, or next steps. Add only what closes a real decision gap. A longer page that delays the answer is not inherently more satisfying than a concise one.

    Ask a hard comparative question: what can someone decide or do after reading the results now ranking above you that they could not decide or do after reading your page? The answer should become a concrete edit. If you cannot identify a meaningful difference, do not manufacture one by expanding every section.

    Verify accuracy, ownership, and maintenance

    Check every consequential claim, named feature, date, process, and recommendation. Remove unsupported certainty. Replace stale instructions. Make authorship and editorial responsibility clear where the reader needs them to judge the advice. Cite the originating authority when a claim depends on a standard, policy, specification, or official announcement.

    Do not simulate freshness by changing a date while leaving old guidance intact. A meaningful update should have a reason you can record: a corrected fact, a changed process, a better explanation, a newly addressed intent, or clearer decision support.

    Keep schema aligned with the visible page

    JSON-LD can clarify the entities, properties, and relationships already represented on a page. It cannot turn thin, mismatched, or unsupported content into a satisfying result. Treat structured data as a consistency layer, not a core-update recovery switch.

    After a substantive edit, verify that the markup still matches the visible content. Remove properties the page no longer supports, keep entity names and relationships consistent, and avoid adding types merely because they appear SEO-friendly. The content, metadata, internal links, and schema should describe the same thing without contradiction.

    Make controlled changes and measure recovery honestly

    One generic web page panel is adjusted in a controlled testing lane while two unchanged panels remain covered for comparison.

    Prioritize shared weaknesses that affect a meaningful group of pages. An isolated decline with no repeatable pattern is a poor reason for a sitewide rewrite. A clear intent mismatch across an entire template or topic cluster is a stronger candidate because the diagnosis and expected effect can be stated in advance.

    1. Preserve the baseline data and a recoverable copy of every page before making material changes.
    2. Resolve measurement, indexing, rendering, redirect, or deployment problems before judging content quality. Content edits cannot repair missing data or a broken delivery path.
    3. Choose a coherent page group with one identifiable weakness. Define the intended change and the metric that should respond.
    4. Make the smallest batch large enough to test the shared diagnosis. Avoid mixing unrelated URL, template, copy, schema, and commercial changes when they can be separated.
    5. Annotate what changed, where, why, and when. Keep unaffected pages steady where practical so later comparisons retain context.
    6. Re-evaluate the same page and query groups after Google has processed the changes. Judge visibility and qualified outcomes together rather than celebrating a traffic increase that does not serve the audience or business.

    Choose the treatment page by page. Refresh a URL when its purpose remains valid but its answer is stale, incomplete, unclear, or poorly ordered. Consolidate pages when several weak URLs divide the same intent and none earns a distinct role. Leave a strong page alone when the evidence is inconclusive. Retire a page only when it no longer serves a user or business purpose; preserve the evidence first, and map a relevant redirect before removing a URL when a genuine replacement exists.

    Google has not supplied a special one-step repair for this update. Recovery may be gradual and may become visible around subsequent core updates. That does not mean you should wait passively, but it does mean you should reject guaranteed recovery dates and avoid claiming that one edit caused a later movement without supporting evidence.

    Your next action is straightforward: annotate the core, spam, and Discover context; preserve a clean baseline; map the largest losses by surface, query intent, page group, and template; and approve edits only where you can name the satisfaction gap. That turns a volatile month into a controlled recovery program instead of a trail of untraceable changes.

    References


  • How to Use AI Review Replies in Google Business Profile

    How to Use AI Review Replies in Google Business Profile

    One click can turn an unanswered review queue into a wall of polite, interchangeable replies. That is faster, but it is not the outcome you want. A useful response shows the reviewer, and every prospective customer reading along, that someone understood the actual experience.

    If Google’s AI reply control appears in your Google Business Profile, treat it as a drafting layer inside a human approval process. The goal is not to publish more words. It is to respond faster without inventing facts, exposing customer information, making promises you cannot keep, or sanding every reply down to the same generic apology.

    First, verify what the AI control does in your account

    Google has conducted a limited test of AI-generated review replies within Google Business Profile. The tested feature creates a proposed response that a business can review, edit, and manually submit.

    Do not assume every profile has the same interface or publication flow. Availability has varied between accounts and individual reviews. Documented appearances included the United States, Brazil, and India, while the feature was not yet broadly visible in Europe. Some prompts focused on older unanswered negative reviews.

    The most important variation concerns bulk use. At least one observed version could generate suggestions for multiple reviews. Experiences differed after generation: some still involved a review step, while others appeared more automated and required no edits. That difference matters because generating twenty drafts is reversible; publishing twenty unchecked replies under your business name is not.

    Before touching your backlog, use one low-risk positive review to inspect the actual workflow. Confirm whether the tool only creates a draft, whether any bulk action pauses for approval, which user is publishing, and which location profile is active. If you cannot clearly identify the final approval step, do not use the bulk option.

    This caution is not an argument against AI assistance. Thoughtful review engagement can influence trust and conversion decisions. It is an argument for putting the speed in the drafting stage, where mistakes are still easy to correct.

    Match human oversight to the risk of the review

    Three review-response situations show increasing human oversight from a routine compliment to a serious customer complaint.

    Not every review needs the same amount of editing. A short five-star comment is different from a complaint involving a disputed charge, a safety concern, or personal information. Use the review’s factual and reputational risk, not the size of your queue, to decide how much authority AI receives.

    Review typeAppropriate role for AIRequired human check
    Simple positive reviewCreate a short first draftMake sure the reply reflects what the reviewer actually wrote and adds no invented detail
    Specific praise naming an employeeDraft an acknowledgementCheck spelling, context, privacy, and your policy on repeating employee names publicly
    Star rating with no written commentSuggest a brief neutral responseDo not infer a visit, purchase, problem, or reason that the reviewer never stated
    Mixed or negative service reviewProvide a structure, not a finished answerVerify the incident, any corrective action, the contact route, and every promise
    Claim involving safety, discrimination, payment, personal data, or legal actionNo autonomous publicationEscalate to the responsible manager and publish only an approved, factual response

    The dividing line is not positive versus negative. It is whether the reply could create a false factual record, disclose something private, or commit the business to an action. A warm thank-you usually has little exposure. A sentence claiming that a refund was processed has much more.

    Negative reviews also demand more than a longer apology. Generic language such as “we strive to provide excellent service” can make the reply feel automated because it does not identify what went wrong or what the customer should do next. Use AI to establish a calm tone, then replace abstractions with verified detail.

    Build a review-to-reply workflow that catches AI mistakes

    An overhead desk scene shows a customer review moving through AI drafting, fact-checking, privacy review, and human approval.

    A reliable process separates understanding, drafting, verification, and publication. When those tasks collapse into one button, a plausible sentence can escape before anyone asks whether it is true.

    1. Confirm the profile and context. Check the business location, star rating, review text, review date, and any named service or employee. Multi-location teams should be especially careful: a polished response posted from the wrong location is still wrong.
    2. Classify the review before generating anything. Decide whether it is praise, a question, a mixed experience, a service failure, or a sensitive allegation. A five-star review containing a complaint is not simple praise. A one-star rating with no text does not give you an incident to explain.
    3. Create a small set of usable facts. Separate what the reviewer publicly stated from what your team has verified. Useful facts can include the location, service named, confirmed action already taken, approved contact channel, and role responsible for follow-up. If a detail is neither in the review nor verified internally, leave it out.
    4. Decide what the response must accomplish. A reply should normally do one primary job: thank the customer, acknowledge a problem, answer a question, correct a material misunderstanding, or move a sensitive discussion to an appropriate channel. Do not let the generated draft wander across all five.
    5. Generate the draft, then edit sentence by sentence. Keep a sentence only if it acknowledges a real detail, supplies verified information, or gives the customer a useful next step. Remove filler, excessive apologies, promotional language, and service or location keywords inserted for their own sake.
    6. Run a pre-publication check. Verify every proper noun, operational claim, promise, contact method, and time-sensitive statement. Make sure the tone fits the review. Do not request or repeat addresses, card details, health information, account data, or other sensitive information in a public reply.
    7. Close the operational loop. Publish the response, but route the underlying issue to the team that can fix it. If several reviews mention the same delay, handoff, product problem, or communication gap, the important result is not a larger collection of apologies. It is a corrected process.

    Assign ownership before volume increases. Someone should be responsible for low-risk approvals, someone should handle sensitive escalations, and location managers should know which statements they are allowed to make. Otherwise, the AI tool may reduce drafting time while adding an approval bottleneck that nobody owns.

    Edit generated replies into specific, human responses

    You do not need a different writing system for every review. You need a few reliable response shapes and the judgment to fill them only with information you can support.

    For a positive review, reflect one meaningful detail

    A practical shape is: thank the reviewer, mention one detail they supplied, and close without turning the response into an advertisement.

    Template: Thanks, [reviewer name, if appropriate]. We are glad [specific detail from the review] made your [visit or service experience] easier. We appreciate you taking the time to mention it.

    One detail is enough. Do not repeat the full review, invent what the customer purchased, or attach a string of services and place names in the hope of gaining search visibility. A review reply is a customer-service message, not a miniature landing page.

    For a negative review, move from acknowledgement to action

    A useful negative-review reply has three parts: acknowledge the experience described, state only what has been verified, and provide an appropriate next step. It does not need to settle the entire dispute in public.

    When the event and next step are verified: We are sorry your order was not ready at the confirmed time. Please contact [approved channel] with [non-sensitive identifier] so [responsible role] can review what happened and follow up.

    When important facts are still unknown: We are sorry to hear about the delay you described. We would like to understand what happened. Please contact [approved channel] so [responsible role] can review the details with you.

    The second version acknowledges the complaint without pretending the business has already completed an investigation. Do not write that an issue was fixed, a refund was issued, an employee was disciplined, or an event never happened unless the statement has been verified and approved for public release.

    For an older unanswered review, acknowledge the timing

    AI prompts may bring older negative reviews back into the queue. Do not publish a reply that reads as if the incident occurred yesterday. If accurate, open with a simple acknowledgement: We are sorry we missed your feedback when you first shared it. Then provide a contact route that is valid now.

    A late reply can still show prospective customers how the business handles criticism. It should not promise a retroactive resolution that the current team cannot provide. If no meaningful next step remains, keep the response brief, acknowledge the gap, and avoid manufacturing activity merely to make the reply sound complete.

    Key takeaways

    • Treat every AI-generated reply as an unverified draft until a person checks its facts, promises, tone, and privacy implications.
    • Test the exact approval flow in your own Google Business Profile before using any bulk-generation option.
    • Use AI more freely for low-risk acknowledgements and require stronger human review as factual or reputational exposure increases.
    • Personalize with details the reviewer supplied, not plausible details the AI added.
    • Move sensitive cases to an approved private channel without repeating customer information in public.
    • Use patterns in reviews to fix the underlying operation rather than automating repeated apologies.

    Start with one low-risk reply and write a short approval rule before working through the backlog. Once the same checks reliably protect single drafts and bulk suggestions, you can increase speed without handing your public reputation to an unchecked generator.

    References


  • Google Merchant Center Out-of-Stock Purchase Controls

    Google Merchant Center Out-of-Stock Purchase Controls

    If an out-of-stock product page still lets shoppers add the item to their cart, or if the purchase control disappears entirely, you now have a Merchant Center problem. The compliant state sits between those two behaviors: keep the buy button visible, make it clearly disabled, and show an explicit out-of-stock message.

    The product feed must declare the same availability as the landing page. That alignment matters as much as the button itself because conflicting availability information can lead to product disapprovals. Here is how to implement the control without creating a new gap between your storefront, inventory system, and feed.

    The correct purchase control depends on the availability state

    Out of stock is not a general label for every product you cannot ship immediately. It is a specific commercial state. When you declare an item out of stock, the shopper must not be able to buy it. The page should nevertheless retain a recognizable purchase control so the unavailable state is obvious rather than looking like a broken or incomplete product page.

    Two common storefront patterns no longer satisfy that requirement:

    • Removing the buy button: The shopper sees no purchase control and may not understand whether the product is unavailable, discontinued, or affected by a page error.
    • Leaving the buy button active: The page claims that the item is out of stock while continuing to accept a purchase.

    Use the availability state to determine both the message and the control:

    AvailabilityLanding-page messagePurchase controlFeed treatment
    In stockExplicitly identify the item as availableAllow the normal purchase actionDeclare in stock
    Out of stockExplicitly say out of stockKeep the buy button visible but disabledDeclare out of stock
    Back orderExplicitly say back orderAccept the order only if that is the offer you intend to makeDeclare back order
    Pre-orderExplicitly say pre-orderMake the purchase experience consistent with the pre-order offerDeclare pre-order

    The important distinction is whether you are accepting an order. If customers may order an item that is not currently available, treating it as back order keeps the offer internally consistent. Do not label it out of stock in the feed while using an active Add to cart button on the page.

    Implement a disabled button, not merely a gray decoration

    A laptop product panel shows a visible but inactive purchase button beside an empty-box status icon.

    A visual change alone is not a purchase control. A button can look disabled while remaining clickable with a mouse, keyboard, or touch input. Your implementation needs to make the action inactive as well as visually unavailable.

    1. Calculate the product state first. Resolve the current item or selected variant to in stock, out of stock, back order, or pre-order before rendering the purchase area.
    2. Print a visible availability message. Place the words Out of stock near the purchase control. Do not rely on button color alone to communicate the state.
    3. Keep the control in the purchase area. Render the button where a shopper would normally expect to find it, with a clear disabled appearance.
    4. Disable the action itself. For a native HTML button, use its disabled behavior. If a custom element or link acts as the control, make sure it cannot activate through pointer, keyboard, or touch input.
    5. Block stale purchase requests. Treat the disabled interface as the first line of control, not the only one. The cart or commerce layer should recheck availability so an old page, direct request, or delayed script cannot create an order for an item still classified as out of stock.
    6. Change the commercial state when orders are allowed. If the business decides to accept orders before stock is available, update the product to back order on both the page and feed instead of quietly re-enabling an out-of-stock button.

    JavaScript storefronts need one extra check: do not render an enabled button first and disable it only after inventory data arrives. Resolve the state before exposing the action, or use an inactive loading state until the product record is ready.

    Products with selectable variants also need state-specific controls. When a shopper changes a size, color, or other option, update the availability message and button together. An unavailable variant should not inherit the active button of the variant that was selected previously.

    Make the page and feed read from the same inventory decision

    An empty central inventory container connects to a storefront screen and a product-listing tablet, both showing matching unavailable indicators.

    The most durable fix is not a second rule inside your product-feed exporter. It is one availability decision that every output consumes. Your catalog or inventory layer should determine the commercial state; the product template and feed generator should translate that same state into their respective formats.

    Separate logic creates predictable mismatches. A storefront may switch to out of stock as soon as inventory reaches zero while a scheduled feed still contains the earlier in-stock value. A feed rule may convert low inventory to out of stock while the page continues to sell. A manually edited product badge may say back order even though the underlying record and feed still say out of stock.

    Map the flow before changing the interface:

    • Identify the field or rule that decides whether an order may be accepted.
    • Document how each internal value becomes in stock, out of stock, pre-order, or back order.
    • Use that mapping to render the visible landing-page label.
    • Use the same mapping to enable or disable the buy button.
    • Use the same mapping when generating the Merchant Center feed value.
    • Account for cached pages, cached product data, and feed-generation delays when inventory changes.

    Do not solve a disagreement by changing only the wording. If the feed says back order but your commerce system rejects every order, the label is still inaccurate. If the page says out of stock but the cart accepts the item, disabling a cosmetic button has not corrected the underlying state. The message, control, feed, and order behavior should describe one offer.

    Audit transitions, variants, and alternate purchase paths

    A static screenshot can confirm that a disabled button exists, but it cannot prove that the full inventory workflow is correct. Test the transitions that cause the page and feed to drift.

    1. Choose representative products. Include at least one product in each availability state your store supports, plus products with and without variants.
    2. Compare the declared states. For each selected item, check the internal inventory state, visible page message, purchase control, and exported feed value.
    3. Test the disabled control. Confirm that the out-of-stock button remains visible but cannot be activated with a mouse, keyboard, or touch interaction.
    4. Change variants. Move between available and unavailable options and confirm that the label and button change together every time.
    5. Test inventory transitions. Move a test item from in stock to out of stock, then to back order if your system supports it. Verify every output after each transition.
    6. Check delayed outputs. Revisit cached product pages and the next generated feed to find timing gaps between the storefront and Merchant Center data.
    7. Check the cart boundary. Confirm that the commerce layer rejects an item still classified as out of stock even when a stale page or alternate request reaches it.
    8. Review Merchant Center after deployment. Watch for availability-related disapprovals and trace any affected product back through the shared state mapping.

    Add these cases to regression testing if inventory or product templates change frequently. The highest-value automated checks are simple: an out-of-stock item renders an explicit label, its button is disabled, its feed value agrees, and the cart cannot accept it. For a back-order item, test that the back-order label and feed state remain aligned with the intended ordering behavior.

    Key takeaways

    • An out-of-stock product page needs a visible but disabled buy button; neither removing the control nor leaving it clickable is the correct state.
    • The page must explicitly communicate availability using a state such as in stock, out of stock, pre-order, or back order.
    • The landing-page state and Merchant Center feed must agree, or the product may be disapproved.
    • If you accept orders for inventory that is not currently available, classify the offer as back order and synchronize that state across the page and feed.
    • A shared inventory mapping is safer than separate storefront and feed rules.
    • Test state transitions and variant changes, not just the final appearance of one product page.

    Start with one out-of-stock SKU that currently removes its button or leaves it active. Trace that SKU from the inventory record through the product template, cart, and feed. Once all four surfaces express the same state, turn the mapping into a reusable rule and test it across the rest of the catalog.

    References