Tag: Content Accuracy

  • AI Search Accuracy: Audit Citations and Brand Visibility

    AI Search Accuracy: Audit Citations and Brand Visibility

    You run an AI search, see your company named with a citation, and assume your visibility work is paying off. Or a competitor appears first, so you assume it has won. Either conclusion can be wrong when it rests on one generated answer.

    A useful AI search audit has to answer three separate questions: Is the claim correct? Does the cited page support it? Does the result persist when you repeat the search? Once you separate those questions, you can stop treating citations as proof and start measuring what users are actually likely to encounter.

    Separate answer accuracy, citation support, and repeatability

    An answer can be correct while citing the wrong page. It can also quote a page accurately even though the page itself contains an outdated or incorrect fact. A perfectly supported answer may disappear on the next run. These are different failures, and each requires a different fix.

    LayerQuestion to askWhat a failure meansWhat you should do
    Claim accuracyIs the statement factually correct?The model generated, repeated, or combined incorrect information.Find the authoritative fact and identify where the wrong version may be coming from.
    Citation supportDoes the linked page substantiate the exact statement beside it?The citation is related to the topic but does not entail the claim.Record the mismatch and improve the page that should support the claim.
    Source qualityIs the cited information current, specific, and appropriate for the claim?The answer may be grounded in weak, stale, or indirect evidence.Strengthen first-party evidence and correct external profiles you control.
    RepeatabilityDoes the claim, citation, or recommendation recur across runs?The observed result may be sampling variation rather than durable visibility.Measure occurrence rates across repeated prompts and engines.

    A citation is reliable only when the linked material materially supports the claim attached to it. Topical relevance is not enough. A page about a business does not automatically support every statement an AI answer makes about that business. Authority does not repair that mismatch either: a respected domain can still be the wrong citation for a particular sentence.

    This is why accuracy belongs at the claim level. Work involving 158,000 AI claims validated through FactCheck used individual claims as the unit of analysis rather than assigning one broad true-or-false label to an entire response. Your audit should use the same basic unit. One answer may contain several supported claims, one unsupported inference, and one factual error.

    Audit each AI answer at the claim level
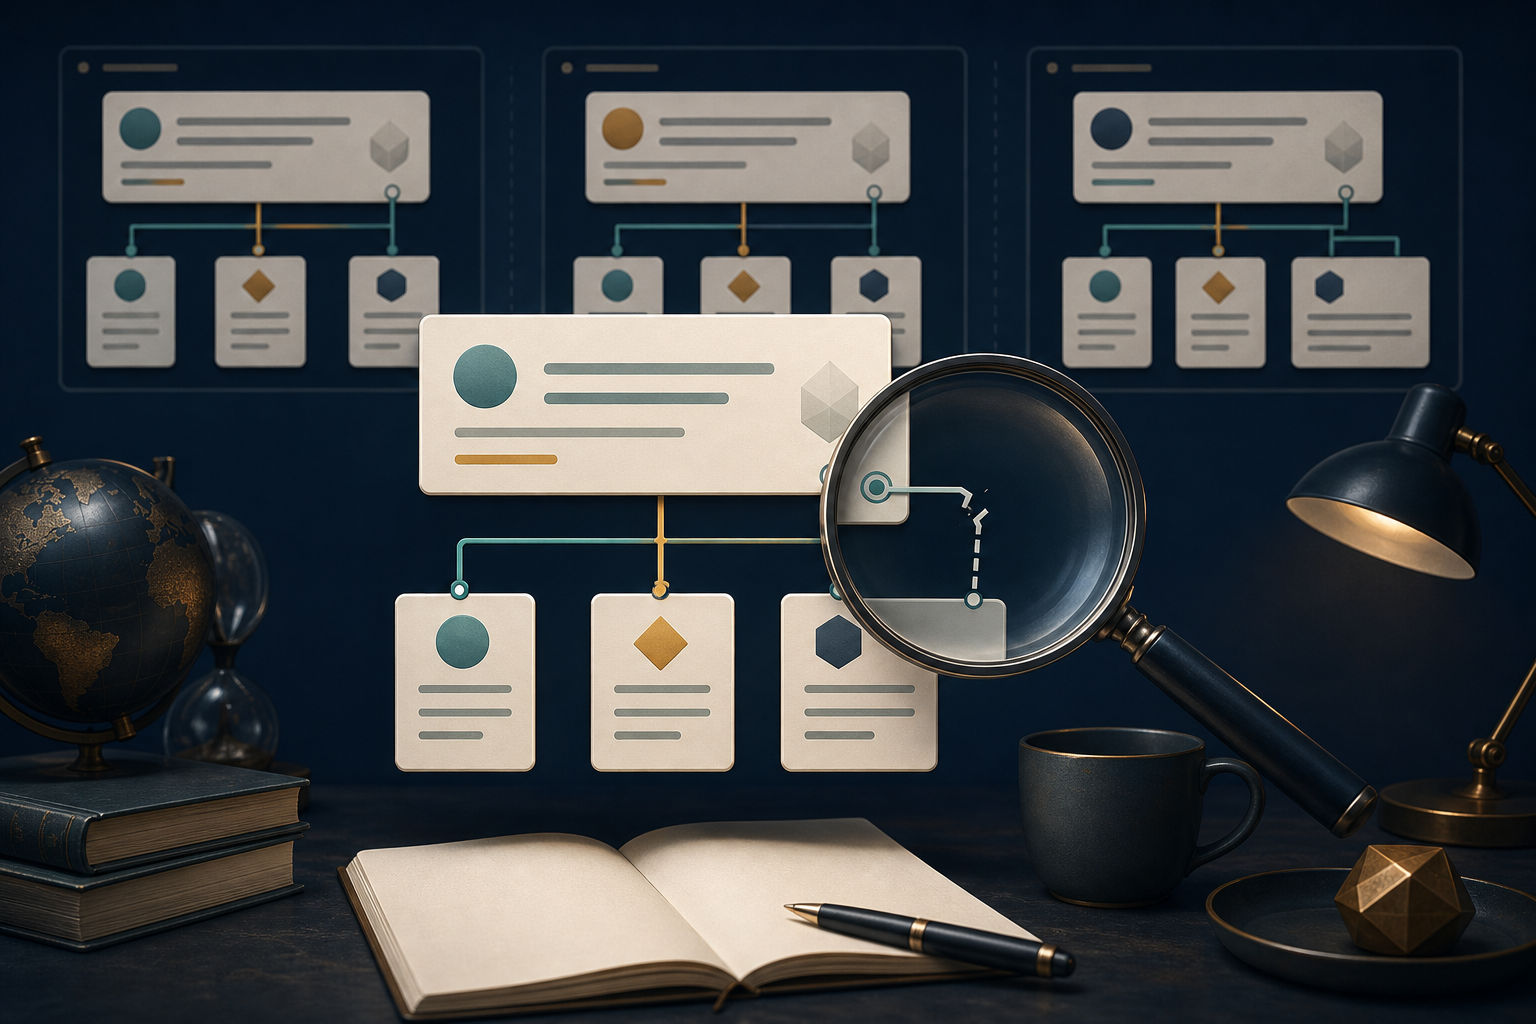
    Separate claim cards are linked by green, amber, and red threads to supporting source documents as a hand inspects one connection with a magnifying lens.

    Start with the exact answer the user saw. Do not rewrite it into a cleaner version before checking it. Small qualifiers such as location, availability, price conditions, service area, or timing often determine whether a citation really supports the statement.

    1. Capture the query context. Save the precise prompt, AI product or search surface, displayed model when available, location, date, and whether the session was signed in or personalized. A later result is not comparable if those conditions changed.
    2. Split the answer into atomic claims. Turn “Company A offers emergency plumbing throughout Toronto and is open all night” into separate claims about the service, service area, and hours. A citation may support one part without supporting the others.
    3. Mark opinions separately. Statements such as “best,” “most reliable,” or “ideal for families” are conclusions, not simple facts. Identify the factual premises that would be needed to justify the conclusion.
    4. Open every cited URL. Find the passage, field, table, or listing that is supposed to support the claim. Do not give credit merely because the page mentions the same entity or topic.
    5. Score correctness and support independently. Verify whether the claim is true, then decide whether the cited page proves it. A correct claim with an unrelated citation is still a citation failure.
    6. Save a short evidence note. Record what the page supports, what it omits, and any conflicting detail. This makes later reviews possible even if the page changes.

    Use a small, explicit verdict set so different reviewers make comparable decisions:

    • Supported: The cited material clearly substantiates the entire claim, including its qualifiers.
    • Partially supported: The citation proves only part of a compound claim or leaves an important qualifier unresolved.
    • Unsupported: The page is related but contains no evidence for the claim.
    • Contradicted: The cited material states something incompatible with the answer.
    • Unverifiable: The page is unavailable, the relevant content has changed, or the claim cannot be checked from accessible evidence.

    Do not let a polished sentence hide a weak inference. If an AI answer calls a provider “the best option” because it has evening hours, the hours may be supported while the recommendation is not. Record the factual premise as supported and the superlative as unsubstantiated unless the answer supplies a defensible comparison.

    The resulting audit should preserve four separate fields: the claim, its factual verdict, its citation-support verdict, and the reason for each verdict. A single “accurate” column collapses too much information to guide a correction.

    Measure AI visibility as a distribution, not a ranking
    Many floating result panels show cobalt and coral geometric objects appearing in different positions or disappearing across repeated searches.

    Traditional rank tracking encourages you to ask where a business appeared. Generative search requires an earlier question: how often did it appear at all?

    The instability can be substantial. Across 14,472 Gemini citations from 1,487 local queries in 50 large U.S. metro areas and ten service categories, repeated identical searches produced only about 40% overlap among cited sources. Gemini selected the same top business about 7% of the time, while a Google local-pack control returned the same top listing about 90% of the time.

    Engine-to-engine agreement was even lower in that local-search sample. Gemini and ChatGPT cited the same domains in only about 8% of the compared searches and recommended the same top business 4.2% of the time. Gemini leaned heavily on business websites, while ChatGPT relied more on Reddit and business directories. Success in one engine therefore cannot stand in for visibility across AI search as a whole.

    Those percentages are not universal benchmarks. They come from a defined set of U.S. local-service searches and should not be projected onto every industry, country, prompt type, or AI product. They do establish why a screenshot from one run is weak evidence of either success or failure.

    A practical starter protocol, rather than a claim of statistical certainty, is to select ten commercially important prompts and run each one five times per engine. Keep the wording and observation conditions fixed. Treat alternative phrasings as separate prompts instead of changing the text between repetitions.

    1. Choose prompts by user decision. Include discovery, comparison, eligibility, trust, and branded-fact questions that can influence whether someone contacts or excludes you.
    2. Run a fixed batch. Capture every answer, including runs where your brand is absent and runs with no citation.
    3. Keep engines separate. Report Gemini, ChatGPT, and any other surface independently before creating an aggregate view.
    4. Repeat on a consistent cadence. Use the same batch before and after material content changes, and maintain unchanged prompts as controls.
    5. Compare rates, not anecdotes. Look for changes across the batch rather than celebrating or diagnosing one favorable result.

    Calculate at least four rates:

    • Mention rate: Runs that mention your entity divided by all runs for that prompt and engine.
    • Citation rate: Runs that cite your domain divided by all runs.
    • Recommendation rate: Runs that recommend your entity, with a separate field for first or primary recommendation.
    • Supported-citation rate: Audited citation occurrences that fully support the attached claim divided by all audited citation occurrences.

    Do not report “average rank” without a written rule for absent brands, unordered lists, and narrative recommendations. In many generated answers, numerical position implies a precision the interface does not provide. Mention and recommendation rates are usually easier to interpret.

    This approach also prevents you from mistaking normal variation for the effect of an optimization change. If visibility rises from one run to the next while unchanged control prompts move just as much, you do not yet have convincing evidence that your edit caused the difference.

    Build pages that can support the claims you want cited

    Your own website is not merely a conversion destination. It can be the evidence layer behind an AI answer. In the defined Gemini local-search sample, nearly 60% of citations led directly to business websites, more than the combined share for directories, review platforms, and forums. Reddit was the second-largest category at 13.7%.

    That does not mean publishing a page guarantees selection. It means you should give an AI system a clear, defensible first-party page to cite when it needs to verify a claim about you.

    Create a claim-to-page map

    List the claims that matter in a buying decision, then assign one canonical page to substantiate each one. Typical groups include services offered, locations served, eligibility or customer fit, operating hours, pricing conditions, product capabilities, policies, credentials, and named people responsible for the work.

    For every claim, ask:

    • Is the answer stated directly in visible page copy?
    • Does the page identify the exact company, product, service, and location involved?
    • Are conditions and exclusions placed beside the claim rather than hidden elsewhere?
    • Does the page contain evidence appropriate to the statement?
    • Is there a clear owner responsible for keeping the fact current?
    • Does the page use a stable canonical URL that can remain valid when the content is updated?

    A vague marketing page forces the answer engine to infer. A factual page reduces the number of inferences it has to make. Replace “solutions for every need” with explicit services, intended users, locations, and constraints. If availability depends on location or plan level, state that condition in the same passage.

    Make JSON-LD agree with the visible evidence

    Treat structured data as a machine-readable map of facts that a person can also verify on the page. For a local organization, use the most specific applicable Organization or LocalBusiness type and populate relevant properties such as name, URL, telephone, address, opening hours, and service area only when the page substantiates them.

    Do not use JSON-LD to introduce claims the visible content cannot support. If the markup says a location is open all night but the location page lists limited hours, you have created ambiguity rather than authority. The same rule applies to ratings, prices, service areas, authors, dates, and product availability.

    Check consistency across the page title, headings, body copy, structured data, internal links, and canonical URL. Schema cannot rescue a fact that is vague, contradictory, or attached to the wrong entity.

    Audit external descriptions without manufacturing consensus

    Your website may dominate citations in one engine while community discussions and directories carry more weight in another. Search for your brand, products, locations, and key claims across the pages that already appear in AI answers. Flag incorrect hours, old service descriptions, duplicate listings, former locations, and unsupported reputation claims.

    Correct profiles and listings you legitimately control. Where a third-party page has a documented correction process, submit accurate evidence. Do not create fake reviews, staged forum discussions, or undisclosed endorsements to imitate independent agreement. Apart from the ethical problem, manufactured material gives answer engines more low-quality claims to misread and repeat.

    When an inaccurate AI claim recurs, trace the wording across cited and uncited pages. If several pages repeat the same obsolete fact, updating only your homepage may not resolve the conflict. Record which representations you control, which have correction channels, and which must simply be monitored.

    Key takeaways

    • A correct answer can still have an unreliable citation, so score factual accuracy and citation support separately.
    • Audit atomic claims, not entire responses. Compound sentences often mix supported facts with unsupported conclusions.
    • One AI result is an observation, not a visibility trend. Repeat identical prompts and report occurrence rates by engine.
    • Do not assume visibility transfers between Gemini, ChatGPT, or other AI search surfaces; their source preferences and recommendations can differ sharply.
    • Publish canonical factual pages, align their visible content with JSON-LD, and correct external descriptions you legitimately control.
    • Judge optimization work by changes across a fixed prompt set, not by a favorable screenshot.

    On your next monitoring pass, keep the first batch deliberately small: ten decision-stage prompts, five identical runs per engine, and a claim-level review of every citation. That baseline will show whether your immediate problem is inaccurate information, weak evidence, unstable visibility, or a combination of all three. Fix the diagnosed layer, then rerun the same batch before expanding the program.

    References


  • Google August 2026 Spam Update: An SEO Response Plan

    Google August 2026 Spam Update: An SEO Response Plan

    If your organic visibility changed as the August rollout began, resist the urge to rewrite half the site. You need to answer two questions in order: which repeatable part of the site moved, and what separates those pages from comparable pages that held steady?

    The August 2026 spam update applies globally and to all languages, with a rollout expected to take a few days. That makes the opening phase a measurement problem. Broad edits made during the rollout can destroy the baseline you need to distinguish an update-related pattern from a technical fault, a tracking problem, or ordinary demand movement.

    Key takeaways

    • The August 2026 spam update has global and multilingual scope, but Google has not publicly identified a particular page type, industry, or tactic as its target.
    • Preserve a dated snapshot before making elective sitewide changes. Segment the data by page group, query type, country, device, language, and template.
    • A decline that overlaps the rollout is a correlation, not a diagnosis. Rule out indexing, tracking, server, redirect, canonical, and demand problems first.
    • Look for a shared weakness across affected pages rather than treating every losing URL as an unrelated problem.
    • Do not assume AI assistance, structured data, or a particular CMS caused the loss without evidence from affected and unaffected comparison groups.

    What the confirmed scope does and does not tell you

    This is the third announced Google spam update of 2026, following the June 2026 spam update. The short interval is a reason to keep a precise change log, especially if your site also moved during the earlier rollout. It is not evidence that the two updates assessed the same patterns.

    Global coverage means you should not automatically treat a different country or language version as an unaffected control group. It does not mean every market, query set, or directory will move by the same amount. Your own segmented data still has to show where the change occurred.

    The announcement also does not identify a specific target. A ranking loss cannot, by itself, establish that Google objected to AI-generated copy, affiliate pages, programmatic templates, links, structured data, or any other single feature. Starting with one of those conclusions encourages indiscriminate fixes and makes the eventual result harder to interpret.

    Nor is impact a moral verdict. Sites that are not deliberately manipulating search can still be affected during a spam update. Treat a decline as a signal to investigate the site’s observable patterns, not as proof that its owners or writers intended to spam.

    If your visibility remains stable, do not manufacture an emergency project. Save the baseline, confirm that important page groups held across relevant markets, and continue planned quality work. Stability now is useful evidence, but it is not a permanent exemption from future changes.

    Protect your baseline while the rollout is in motion

    Your first objective is to preserve evidence. Continue urgent security, accessibility, legal, and availability fixes, but defer elective mass publishing, template rewrites, redirect migrations, and sitewide internal-link experiments until you can separate their effects from the rollout.

    1. Annotate the rollout. Add it to your analytics calendar, SEO change log, and stakeholder report. Record the announced scope and expected multi-day rollout rather than reducing the event to a single timestamp.
    2. Export the pre-change view. Save daily clicks and impressions, queries, landing pages, countries, devices, and any language or search-feature dimensions relevant to the site. Keep the raw export as well as dashboard screenshots because dashboards and filters can change.
    3. Build page cohorts. Group URLs by directory, template, content purpose, topic, locale, authoring workflow, and commercial model. A sitewide total can hide a severe decline in one template behind growth elsewhere.
    4. Create a control group. Match affected pages with pages that serve a similar intent but remain stable. The comparison is more useful when the pages differ in a limited number of observable ways.
    5. Record other changes. Note deployments, CMS releases, consent-banner changes, analytics configuration, migrations, redirect rules, canonical changes, robots directives, noindex tags, server incidents, marketing campaigns, and known shifts in demand.
    6. Preserve the original pages. Keep a backup or version history before rewriting, consolidating, or removing anything. Without the earlier version, you may lose the evidence needed to test the diagnosis or reverse a harmful change.

    Do not rely on a single sitewide percentage or average position. Ask whether the movement is concentrated in a directory, template, query class, country, language, or device. The concentration often tells you more than the headline number.

    A useful working matrix has three columns: affected pages, matched pages that held, and the meaningful differences between them. If you cannot fill the third column with evidence, you do not yet have a remediation plan. You have a theory.

    Separate an update pattern from technical and demand problems

    A digital investigation scene shows webpage modules, a server rack with a loose cable, and audience silhouettes in three separate areas.

    Start at the highest level and narrow the problem. Determine whether search visibility changed, whether indexed pages disappeared, whether rankings moved while indexation held, and whether the effect belongs to a page group rather than the whole domain.

    What you observeCheck nextWhy it matters
    Clicks fall while impressions remain comparatively stableQuery mix, titles, snippets, device mix, and search-result presentationThis points first to click-through behavior rather than a simple loss of visibility.
    Clicks and impressions fall, but indexed URLs remain stableAffected queries, landing-page cohorts, positions, and replacement resultsThis is the stronger pattern for a ranking or demand investigation.
    Indexed URLs or discoverable pages disappearRobots rules, noindex directives, canonicals, redirects, server responses, rendering, and sitemap changesA technical indexing failure can resemble an algorithmic loss in a traffic chart.
    One directory or template declines while matched sections holdShared content, navigation, ownership, monetization, and production characteristicsThe boundary of the loss can reveal the pattern that needs remediation.
    Analytics falls across search and other channelsTracking, consent configuration, outages, campaigns, and demandA measurement or business-wide change should be ruled out before an SEO rebuild.

    Once technical and measurement alternatives have been checked, audit the common characteristics of the affected cohort. Use questions that can produce evidence:

    • Distinct value: If this page disappeared, what useful explanation, evidence, tool, comparison, or decision support would a searcher lose?
    • Template dependence: How much of the page is genuinely specific to its subject, and how much is repeated across location, product, category, or keyword variants?
    • Intent fit: Does the page answer the query it attracts, or mainly route the visitor toward another page, form, or offer?
    • Accuracy and accountability: Can an editor verify the important claims, identify where the information came from, and determine who is responsible for keeping it current?
    • Ownership: If third parties create or control a section, is it clearly relevant to the site’s audience and subject, and does the site apply meaningful editorial oversight?
    • Navigation and linking: Can users reach the page through coherent site navigation, or does it exist mainly inside a large search-targeted cluster with repetitive anchor text?
    • Visible-content consistency: Do the title, headings, body copy, links, structured data, and page purpose describe the same thing?
    • Production workflow: If automation or AI assisted with creation, did a responsible editor verify accuracy, remove unsupported claims, resolve duplication, and add information that serves the specific query?

    AI assistance is a workflow fact, not a diagnosis. Compare AI-assisted pages that declined with AI-assisted pages that held, and do the same for human-written pages. If authorship method is the only evidence you have, deleting an entire content library is an unsupported and potentially destructive response.

    Structured data needs the same discipline. JSON-LD can make page entities and relationships explicit, but it cannot supply missing usefulness or turn repetitive pages into distinct resources. Correct inaccurate markup when you find it. Do not strip valid markup merely because rankings changed at the same time as a spam update.

    Make the smallest defensible change, then measure it

    Two similar webpage models sit on a laboratory bench while an instrument adjusts one small module and the other remains covered.

    A good response connects one observed pattern to one repairable cause. Write the hypothesis before changing the site. For example: a particular directory declined while matched pages held, and the declining group contains substantially more repeated material with less subject-specific information. That statement can be tested. A claim that Google dislikes the site cannot.

    1. Define the affected cohort. List the page group, queries, markets, and devices where the change is visible. State what remained stable as well.
    2. Stop expanding the suspected pattern. Pause new pages that use the same workflow or template while you investigate. This limits exposure without destroying existing evidence.
    3. Match the repair to the failure. Correct inaccurate pages, consolidate pages that serve the same purpose, strengthen pages with a valid but under-served user need, and repair technical directives when indexation is the real issue.
    4. Handle removal carefully. Do not bulk-delete URLs from a volatile report. Back up the content, identify equivalent destinations, account for internal and external links, and decide whether consolidation, redirection, deindexing, or retirement fits each page’s purpose. Deletion without this mapping can erase evidence and break useful paths.
    5. Fix shared systems. If the weakness comes from a template, brief, generator, approval process, or publishing incentive, correcting individual pages will allow the same problem to return.
    6. Stage material changes. Begin with a representative, well-defined group when practical. Document exactly what changed so the outcome can confirm or weaken the hypothesis.
    7. Read the result against controls. Compare the changed cohort with matched pages that were not changed, using a stable measurement window after the rollout rather than reacting to each daily movement.

    Avoid cosmetic activity that creates the appearance of remediation without addressing the diagnosis. Changing publication dates, adding generic paragraphs, removing every mention of AI, or installing more schema does not solve a demonstrated problem unless the evidence points to stale information, inadequate coverage, an unreliable workflow, or inaccurate markup.

    Stakeholder reporting should distinguish four things: what Google confirmed, what your data shows, what remains unknown, and what you will test next. That format prevents a plausible hypothesis from turning into an asserted fact as it moves through meetings and dashboards.

    Your next move is modest: save the baseline, mark the rollout, and identify the smallest coherent group of affected pages. Once the rollout is complete and alternative causes have been checked, repair the shared weakness you can actually demonstrate. That gives you a response you can defend, measure, and reverse if the evidence changes.

    References


  • AI-Generated Images in Google Search: A Publisher Playbook

    AI-Generated Images in Google Search: A Publisher Playbook

    If you publish recipes, tutorials, or any page that depends on original visuals, the immediate question is practical: can Google generate an image that answers the query before your work earns a visit?

    Do not cancel an image shoot or replace your library with synthetic assets based on one search experiment. Google stopped the recipe-image test that triggered this concern. The useful response is to make your visuals stronger as evidence, connect them cleanly to your content, and measure whether a generated answer actually changes user behavior.

    What Google tested, and what it did not establish

    Google tested AI-generated illustrations inside AI Overviews for recipe results. The generated visual compressed the cooking process from preparation to the finished dish. Google subsequently said the small experiment was no longer running.

    The company also distinguished that experiment from Nano Banana, an image-generation feature announced in July that activates when a user explicitly asks to create an image. That distinction matters. An automatically generated visual inserted into a search answer is a different product behavior from an image a user deliberately requests.

    The narrow reading is the reliable one:

    • Google is willing to test generated visuals within the search-results experience.
    • The recipe experiment described here has ended.
    • The test does not establish a general rollout for generated images in AI Overviews.
    • It does not establish how Google ranks AI-generated images published on your own site.
    • It provides no measured traffic-loss figure that you can apply to your pages.

    That last point should guide your budget decisions. A generated answer could reduce the need to click, but a stopped experiment cannot tell you how large that effect would be. Treat displacement as a hypothesis to measure, not a loss percentage to assume.

    Separate the three image questions people keep mixing together

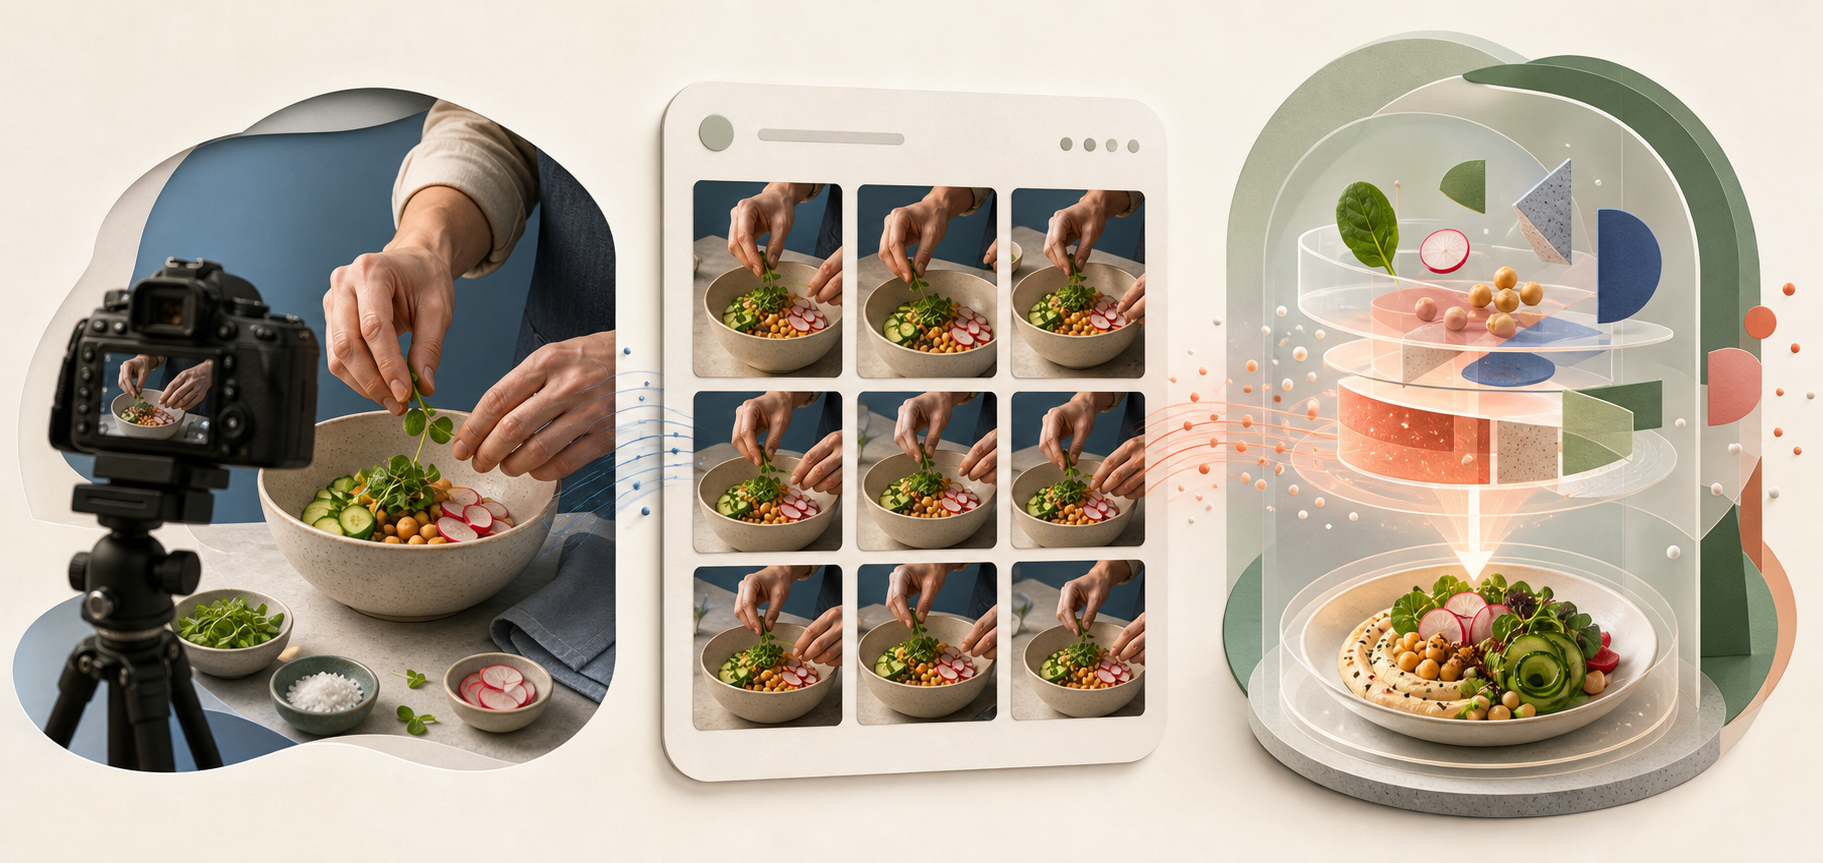
    A three-part illustration shows an original cooking photograph, image thumbnails organized for search, and visual fragments forming a newly generated dish image.

    “AI-generated images in Google Search” can describe three different situations. Confusing them leads to bad SEO decisions.

    QuestionWhat the recipe test tells youYour decision
    Will Google generate a visual inside the result?Google tested this in recipe AI Overviews and then stopped the experiment.Monitor the search surface for your important queries instead of assuming a permanent rollout.
    Will Google show or cite an image from my page?The stopped test does not answer that broader visibility question.Keep original images accessible, useful, and clearly associated with the visible page content.
    Can I publish an AI-generated image on my site?The event establishes no general ranking treatment for publisher-created AI images.Judge the asset by accuracy, transparency, reader value, and your content standards rather than an assumed SEO advantage.

    The most immediate concern is the first situation: Google owns the generated visual, while publisher citations may appear nearby. A recipe publisher affected by the experiment warned that users could mistake nearby citations for credit for the illustrations. That concern is plausible, but it should not be inflated into a claim that every AI Overview misattributes images.

    When you inspect a result, ask two separate questions: “Where did the factual instructions come from?” and “Who created this visual?” If the interface makes only the first answer clear, a citation does not necessarily give you visual attribution.

    Make original images carry evidence a summary cannot preserve

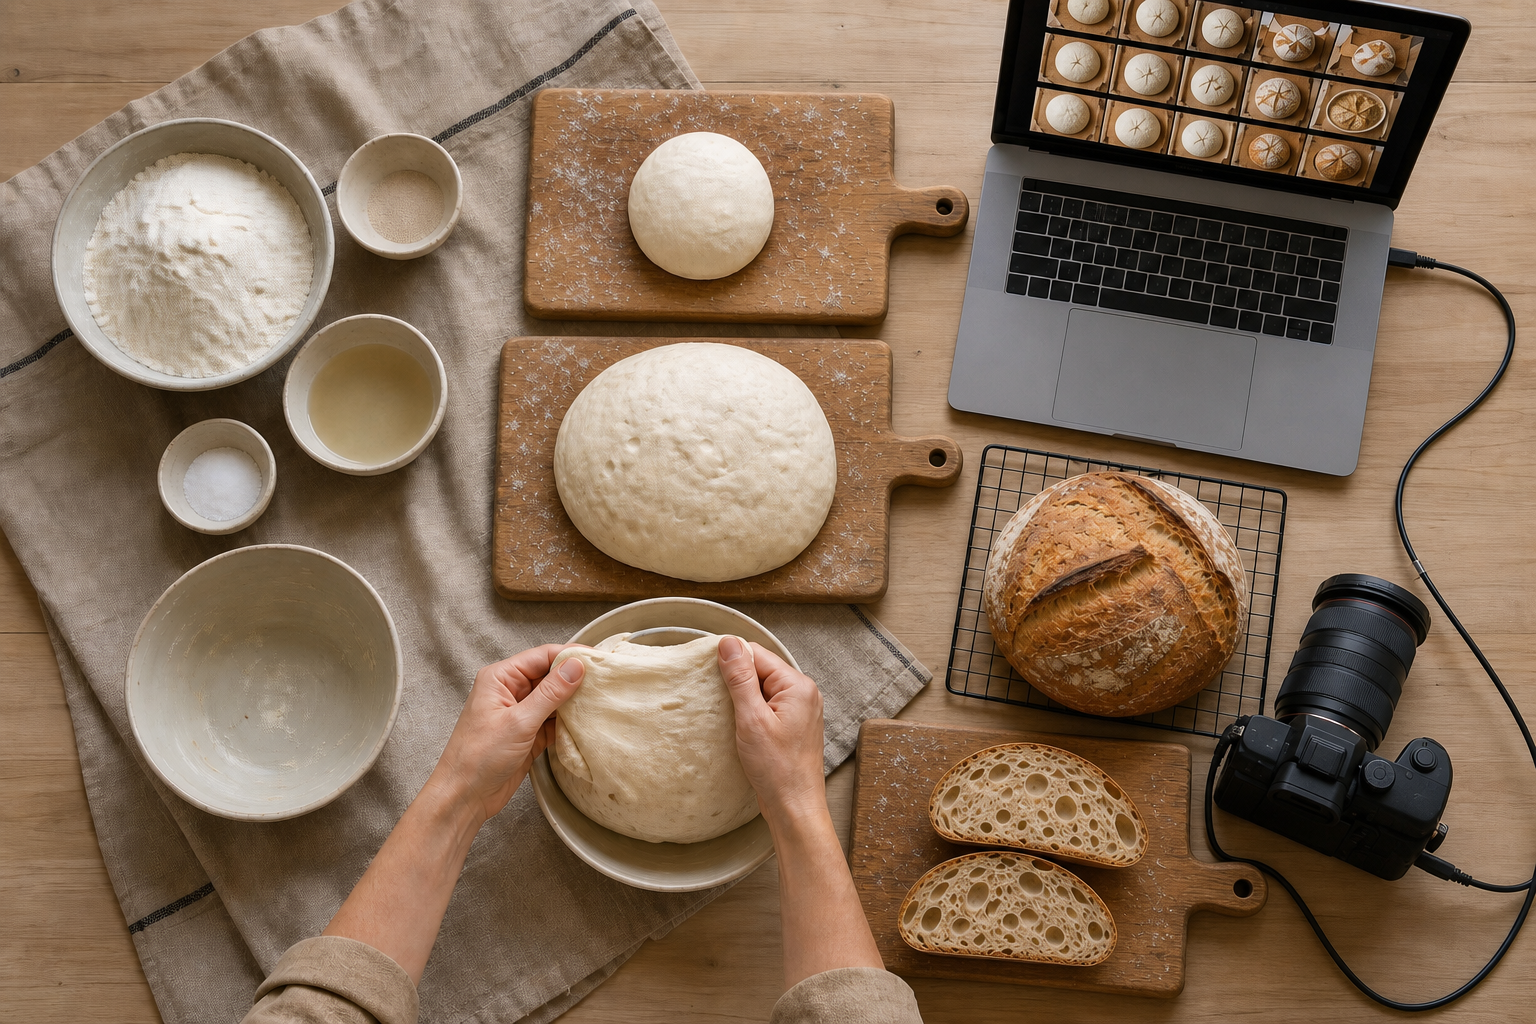
    An overhead workspace shows a creator photographing measured ingredients, dough stages, and the interior of a finished loaf as a consistent visual sequence.

    Your strongest response is not to publish more decorative images. It is to make each original visual communicate something a simplified reconstruction could omit, blur, or invent.

    • Give every image a defined job. Show a decision, condition, comparison, or outcome that the surrounding prose cannot communicate as quickly.
    • Capture consequential stages. For a recipe, that might be texture, color, consistency, assembly, or the difference between an intermediate stage and the finished result. For a repair tutorial, it might be component orientation or correct tool placement.
    • Keep the visual and written sequences aligned. If the text changes order during editing, update the image order and captions at the same time. A polished image attached to the wrong step is worse than no image.
    • Write captions that interpret the evidence. Name the stage and tell the reader what to notice. “Mixture after folding, with visible streaks remaining” is more useful than “Step three.”
    • Use accurate alt text. Describe the relevant content and purpose of the image. Do not turn alt text into a list of target keywords.
    • Keep credits in visible page context. If the photographer, illustrator, tester, or organization matters, identify that contributor where readers can see it rather than relying only on the file name.
    • Align structured data with the page. If you use Recipe or ImageObject markup, reference an image that represents the visible content. JSON-LD is a consistency layer; it is not proof of authorship or a guarantee that an image will appear in search.

    This changes the role of image production. A generic hero image decorates a page. A well-captioned process image documents a claim. When Google or another answer engine compresses the page, the second asset gives the system and the reader a clearer reason to preserve the connection to your work.

    If the image itself was generated

    An AI-generated image can be an illustration without being evidence that you performed a process, tested a product, or produced the depicted result. Keep that boundary explicit.

    • Check every depicted step against the instructions a reader will follow.
    • Look for invented ingredients, tools, components, labels, textures, and transitions.
    • Do not present a generated process scene as documentary photography.
    • Label the image’s role when the difference between illustration and documentation could affect trust.
    • Have a human editor verify the final asset in the context of the page, not only as a standalone image.
    • Replace the asset when an error could lead the reader to perform the process incorrectly; a disclaimer does not repair a misleading instruction.

    For image-led instructional content, consistency matters more than visual polish. If the prose says one thing and the image shows another, the page has an accuracy problem regardless of whether a camera, design tool, or generative model produced the asset.

    Measure exposure before changing your production budget

    A sitewide traffic change cannot tell you whether a generated image displaced a click. You need query-level evidence that the search feature appeared and page-level evidence that behavior changed.

    1. Define the exposed content group. Start with pages whose value can be compressed into a visual sequence: recipes, assembly instructions, repairs, demonstrations, comparisons, and other image-led tutorials.
    2. Record the actual result. For each important query, save the query wording, generated visual, visible citations, search language, location context, device context, and date observed. Search interfaces change, so the screenshot is part of your evidence.
    3. Annotate the first observation. Add it to the same change log you use for site releases, content updates, and search-feature changes. Without that marker, later traffic comparisons become guesswork.
    4. Compare the affected pages and queries. Use Google Search Console to review impressions, clicks, and click-through rate. Use analytics to examine entrances and the business actions that follow those visits. If your reporting does not identify the generated feature directly, pair performance data with the search-result captures.
    5. Use a relevant comparison group. Compare image-led pages where you observed the feature with similar pages where you did not. Do not use unrelated sitewide traffic as the only baseline.
    6. Inspect attribution and accuracy separately. A citation can be present while the generated visual remains confusing. Record whether the source of the instructions and the creator of the visual are each clear.
    7. Change strategy only when the pattern repeats. A generated visual appearing alongside a decline isolated to the same queries is more informative than a single screenshot or a broad organic fluctuation.

    If impressions remain stable but clicks decline only where the generated visual appears, the displacement hypothesis becomes more credible. If no such visual appears, or the decline affects unrelated pages, look for another explanation before changing your image workflow.

    Also separate visibility from value. A page can receive fewer visits without losing the same proportion of conversions, subscriptions, or qualified inquiries. Conversely, a visible citation can look positive while contributing little meaningful traffic. Track both search presence and the outcome you actually need.

    When you find an inaccurate or confusing generated visual, capture the evidence before the interface changes. Preserve the query, complete visual, citations, and relevant landing pages. Use any feedback or reporting control available in the result, then check whether ambiguity on your own page contributed to the problem. Correct your page when it is unclear, but do not rewrite accurate instructions merely to match a generated mistake.

    Key takeaways

    • Google stopped the small recipe experiment that automatically generated process illustrations inside AI Overviews.
    • The experiment was separate from image generation triggered by an explicit user request.
    • A Google-generated search visual, a publisher image shown in search, and an AI image published on your site are three different SEO questions.
    • The stopped test does not establish a general ranking penalty or benefit for AI-generated images on publisher sites.
    • Original visuals become more defensible when they document meaningful stages, match the instructions, include precise captions, and align with structured data.
    • Do not infer traffic loss from the feature’s existence. Record the result and compare affected queries and pages before changing your production strategy.

    Start with your highest-value image-led template. Audit the relationship among its instructions, visuals, captions, credits, alt text, and structured data, then establish a performance annotation you can use if generated visuals reappear. The next experiment may take a different form, but clear evidence and clean measurement will leave you in a position to respond without guessing.

    References


  • Human-Led AI for SEO: A Workflow That Protects Quality

    Human-Led AI for SEO: A Workflow That Protects Quality

    AI can shorten research and analysis, but your real bottleneck is no longer producing text. It is producing a page with a defensible point of view, traceable facts, and a reason to exist beside every page already competing for attention.

    You do not need an AI-free SEO process. You need a clear line of accountability: machines compress inputs and expose patterns; people choose the search problem, supply the evidence, make the judgment, write the consequential passages, and approve what goes live.

    Put AI upstream of authorship

    AI can compress SEO tasks that took hours into minutes. That makes it useful for clustering keywords, mapping themes to URLs, finding patterns in exports, organizing supplied material, and generating options for a strategist to evaluate.

    The boundary is simple. AI may reduce the amount of information you have to inspect, but it should not decide what is true, what your audience needs, what your evidence means, or what your brand is prepared to claim. When the model moves from organizing the work to supplying the substance, efficiency starts consuming the quality it was supposed to create.

    Workflow stageUseful AI roleHuman responsibilityRequired output
    Opportunity analysisCluster exports, connect related queries, and flag changesDecide which problems matter to the audience and the businessA prioritized page list with a reason for each choice
    Content briefingOrganize questions, entities, subtopics, and supplied factsChoose the intent, answer, evidence, angle, and exclusionsA human-owned brief rather than an unverified generated outline
    DraftingOffer structures, counterarguments, examples to investigate, and constrained rewritesWrite the answer, interpretation, firsthand material, and tradeoffsA draft whose consequential claims have identifiable provenance
    Quality controlFlag repetition, inconsistency, ambiguity, and possible unsupported claimsVerify every claim and decide whether the page deserves publicationA factual, useful page with a named human approver
    MeasurementGroup page and query data so changes are easier to inspectInterpret the movement and choose the next actionA documented decision to keep, repair, reframe, consolidate, or retire the page

    Do not confuse human-edited content with human-led content. Changing headings, fixing grammar, and removing awkward transitions may improve presentation, but it does not add experience, evidence, or an original conclusion. If a model chose the premise, assembled the claims, and wrote the argument, a cosmetic edit leaves the model in charge of authorship.

    A small first-party comparison illustrates the risk without proving a universal rule. In that set, three purely AI-written pages launched in April 2025 had nearly disappeared from search results by January 2026. After five AI-drafted, human-edited pages were rewritten by hand, they subsequently recorded 12% more clicks and 27% more impressions year over year during the reported three-month window. Those figures come from a limited set of pages, so they are a warning signal rather than a performance promise. The useful conclusion is narrower: surface editing is not a substitute for original authorship.

    The strategic risk is not the mere presence of AI. It is scaled production that adds little beyond what is already available. Search visibility becomes harder to defend when every page repeats the same consensus in the same vocabulary. Your workflow therefore needs to optimize for information gain and usefulness before it optimizes for publishing volume.

    Build an evidence packet before you ask for content

    Hands assemble documents, reference cards, an audio recorder, and fact markers into an organized evidence packet on a table.

    A keyword export is an opportunity map, not an evidence base. It can tell you which language people use and which URLs are changing, but it cannot supply the expertise that makes your answer worth trusting. Before an LLM sees a writing task, create a compact evidence packet that a human owns.

    1. Define the reader’s decision. Finish this sentence: “After reading, the reader should be able to…” If you cannot name the decision or action, the page is not ready for a brief.
    2. Write the answer in rough human language. State the recommendation, the important qualification, and what common advice misses. This can be messy. Its purpose is to establish the point of view before generated language begins influencing it.
    3. Collect admissible evidence. Include relevant internal notes, documented procedures, approved customer material, product records, first-party data, and external references you are permitted to use. Label firsthand material as such and identify who can verify it.
    4. Create a claim ledger. For each consequential claim, record the supporting artifact or URL, any limitation, the person responsible for verification, and whether the claim is safe to publish. A blank evidence field is a research task, not an invitation for the model to complete the sentence.
    5. Name the page’s original contribution. It might be a firsthand process, an analysis of your own data, a decision framework grounded in expertise, a documented failure mode, or a clearer answer to a question others leave unresolved. If you cannot point to the contribution, do more work before drafting.

    Only then should you hand the organizational work to AI. One practical workflow used Gemini to group more than 2,000 declining Page 1 keywords from Ahrefs into topical clusters. After Google Search Console data was added, the themes were mapped to the URLs losing visibility. That is a good division of labor: the machine narrows a large field; the strategist inspects the affected pages, determines why they matter, and decides what deserves to change.

    Give the model a task contract instead of a vague request to “create an SEO brief.” A useful contract contains these boundaries:

    • Input boundary: use only the attached exports, notes, and approved references.
    • Analytical task: cluster related items, identify duplicates, map clusters to existing URLs, or surface conflicts.
    • Non-authority rule: do not decide which interpretation is correct and do not convert an unsupported idea into a fact.
    • Traceability rule: preserve the row, URL, note, or artifact behind every finding.
    • Uncertainty rule: place missing, ambiguous, or contradictory information in a separate review queue.
    • Output rule: return a structured table or list that a strategist can inspect; do not write publication-ready copy unless a later, bounded task requires it.

    This contract changes the model’s job from “sound knowledgeable” to “make the human’s review faster.” That is the kind of leverage an SEO team can safely repeat.

    Draft from human judgment, then use AI as a critic

    The most consequential writing should begin with a person, even when the starting material is a rough collection of notes. The direct answer, interpretation of evidence, firsthand example, meaningful qualification, and final recommendation carry the page’s real value. Those are precisely the passages you should not outsource to a probability engine.

    1. Lock the thesis before generating prose. Record what you believe the reader should do, why, when that advice does not apply, and what evidence supports it.
    2. Turn each section into a promise. A section should help the reader make a decision, complete a task, or detect a problem. “Benefits of AI” is a topic; “Choose which SEO tasks AI may own” is a useful promise.
    3. Assign evidence before paragraphs. Put the relevant claim-ledger entries beneath the section that will use them. If a section has no evidence or expertise attached, remove it or return to research.
    4. Draft the high-judgment passages in human language. Preserve concrete terms, uncertainty, exceptions, and the reasoning that connects evidence to action.
    5. Give AI bounded revision jobs. Ask it to identify repetition, list unanswered objections, find contradictions, propose clearer ordering, check whether a conclusion follows from the supplied evidence, or create alternate wording for one difficult sentence.
    6. Perform the final edit against the evidence packet, not against the model’s fluency. A sentence that sounds polished but cannot be verified is still a defect.

    During that final edit, interrogate every paragraph:

    • What does this paragraph let the reader do, decide, or notice?
    • Which approved artifact supports its factual claims?
    • Could the paragraph appear unchanged on a competitor’s site? If so, what specific knowledge is missing?
    • Does it state a condition, mechanism, or consequence, or merely announce that something is important?
    • Has polished language hidden uncertainty that was present in the underlying evidence?
    • Would a subject-matter expert sign their name to the wording?

    Do not use a so-called humanizer as a substitute for this review. Passing generated copy through another machine may replace one recognizable writing pattern with another awkward pattern, but it does not create evidence, experience, or a better decision for the reader.

    A vocabulary check can still help. Habitual terms such as delve, tapestry, paramount, synergy, cutting-edge, and game-changing often accompany generic generated prose. Add unwanted terms to your prompt when they conflict with your house voice, then search for them during editing. Treat them as symptoms, not proof. A technically correct term should remain when it is the most precise language available.

    The stronger style instruction is behavioral: use concrete nouns and active verbs; name the actor, action, object, and condition; do not claim importance without showing the consequence; flag a missing example instead of inventing one. That improves usefulness without turning your editorial standard into a blacklist.

    Gate publication with evidence and extraction audits

    An editor inspects a floating web page against source documents and structural page elements before allowing it through a publication checkpoint.

    Human-led does not mean one person glances at the draft before publication. It means a human can explain why the page exists, where its claims came from, what AI did, and why the final answer is defensible. Use two separate gates so factual quality and search presentation do not blur into one subjective approval.

    Gate 1: evidence, accuracy, and originality

    • Every number, date, named event, comparison, and consequential factual claim resolves to an approved reference or internal artifact.
    • Firsthand language points to genuine firsthand material. The page does not imply a test, customer result, interview, or experience that never occurred.
    • Qualifications from the evidence survive into the copy. A limited observation has not become a universal rule.
    • The original contribution is visible in the draft, not merely recorded in the brief.
    • The conclusion follows from the evidence rather than from a confident generated transition.
    • A subject-matter owner has approved the technical meaning, while an editor has approved the communication.

    Classify the result as pass, repair, or block. Block publication when a material claim lacks provenance, the page implies experience you do not have, or no original contribution is present. Repair unclear structure and weak examples only after those blocking problems are resolved.

    Gate 2: search intent and answer extraction

    • The opening resolves the main question without making the reader cross several generic paragraphs first.
    • Each heading describes a decision, task, distinction, or failure mode rather than a broad topic label.
    • The core answer appears in a self-contained paragraph that remains accurate when read apart from the surrounding copy.
    • Names for products, organizations, concepts, and processes stay consistent throughout the page.
    • Citations sit beside the claims they support, allowing readers and retrieval systems to connect evidence with the statement.
    • Lists contain real steps or criteria rather than chopped-up prose.
    • Any JSON-LD or other structured data represents what the visible page actually says. Schema can clarify the content’s structure; it cannot supply expertise or originality missing from the page.

    This second gate supports SEO, AEO, and GEO without distorting the writing for machines. A clear answer, stable terminology, nearby evidence, and faithful structured data also reduce the reader’s effort. If an optimization makes the page harder for a person to understand, it has failed the more important test.

    Measure the page, not the amount of AI

    Record the page’s publication or revision date, target query cluster, intended reader action, original contribution, human owner, and the tasks assigned to AI. Without that record, a future reviewer cannot tell whether a result came from the strategy, the evidence, the execution, or an unrelated change.

    Use first-party Google Search Console and Google Analytics 4 data to inspect performance, but do not treat a before-and-after movement as automatic proof of causation. Review the relevant URL and query cluster, note changes in impressions and clicks, and connect those signals to the reader outcome that matters on your site. Sitewide totals can conceal a page-level gain or loss.

    When a page weakens, do not respond by generating more copy. Return to the evidence packet. Check whether the intended query changed, the answer became stale, a competing page now resolves the task more directly, or your original contribution was never clear. Then choose a specific action: repair the evidence, sharpen the answer, reframe the intent, consolidate overlap, or leave the page alone while more data accumulates.

    Key takeaways for a human-led SEO workflow

    • Use AI to compress, classify, map, challenge, and proofread. Keep truth, intent, interpretation, original contribution, and publication approval with people.
    • Require a human artifact before prompting: a rough answer, evidence packet, claim ledger, and explicit reason the page deserves to exist.
    • Make AI preserve provenance and expose uncertainty. Fluent output without traceable support should never enter a publishable draft as fact.
    • Judge human involvement by decision ownership, not by how many words an editor changed after generation.
    • Optimize answer structure and schema only after the page passes its evidence and originality gate.
    • Measure URL and query outcomes, document the workflow used, and diagnose weak pages before creating more content.

    Take one brief already in production and label every handoff as AI-owned, human-owned, or human-approved. If AI currently owns the thesis, factual support, interpretation, or final judgment, move that responsibility back to a named person before the page goes live. That single change gives you the speed of AI without allowing speed to become your editorial standard.

    References


  • Google Ad Automation Updates: What Teams Should Change Now

    Google Ad Automation Updates: What Teams Should Change Now

    You are losing some control over how paid listings may be explained to shoppers at the same time that Google is adding more machine-readable controls behind the scenes. The mistake is to treat both changes as one vague wave of “more AI.” They require different responses.

    For Shopping and Product ads, your immediate job is to make the product information you control difficult to misinterpret and to document any AI-generated wording you observe. For Display & Video 360, the job is more concrete: move bulk workflows to Structured Data Files v10.1 and test every dependent parser, template and validation rule.

    Key takeaways

    • AI-generated descriptions in Shopping and Product ads remain an experiment, not a confirmed universal feature. Do not redesign an entire account around an isolated appearance.
    • Because advertisers do not directly write the generated description, product-feed accuracy, landing-page consistency and evidence capture become more important.
    • Structured Data Files v10.1 is generally available in Display & Video 360. Versions earlier than v10 have been deprecated, so bulk-management workflows need a planned migration.
    • The new SDF field for AI transparency applies to whether a YouTube video asset was created or edited using AI. It is not a control for the AI-generated descriptions being tested in paid search placements.
    • Separate release management from experiment monitoring: migrate the confirmed file format now, while observing generated ad context without making unsupported causal claims about performance.

    Separate the shipped release from the ad-copy experiment

    A specialist examines a solid automated data pipeline beside a separate translucent experiment involving an unbranded product.

    Two Google advertising changes can contain AI and still have completely different operational status.

    Structured Data Files v10.1 is generally available to Display & Video 360 users. It changes a documented bulk-management format, adds fields and resource support, and deprecates older versions. If your systems import or export SDF files, this is release-management work with identifiable dependencies.

    AI-generated descriptions beside Shopping and Product ads are different. Their appearance indicates that Google may be extending a limited Search ads experiment into Shopping placements, but Google has not announced a broad rollout. The stated purpose of the earlier experiment was to test whether extra generated context helps people make more informed decisions.

    This distinction should determine your response. A generally available file version belongs in your implementation queue. A partially observed interface experiment belongs in your monitoring log. If you reverse those priorities, you may spend days reacting to generated copy that most customers never see while leaving production bulk jobs exposed to a deprecated format.

    Make AI-generated ad context easier to get right

    An unbranded shoe is surrounded by organized product attributes that flow through an automated system into consistent shopping ad layouts.

    Shopping advertisers traditionally shape the listing through product titles, descriptions, images and related product data. An AI-generated description inserts wording that the advertiser does not directly approve. You cannot govern that output like a conventional text asset, so govern the information surrounding it.

    Start with products where inaccurate compression would have the highest consequence: items with variants, compatibility requirements, conditional promotions, subscriptions, bundles or material exclusions. The practical question is not whether the feed contains enough keywords. It is whether a short generated explanation could preserve the product’s important distinctions.

    • Resolve contradictions across controlled assets. A title, product description and landing page should not describe the same variant in materially different ways. If a promotion has conditions, keep those conditions visible wherever the offer appears.
    • Put decisive facts near the product itself. Do not depend on a shopper inferring compatibility, quantity, included components or eligibility from an image alone. State the fact plainly in the appropriate product information and on the destination page.
    • Remove stale claims before polishing prose. An elegant description cannot compensate for an expired offer, obsolete specification or mismatched landing page. Accuracy comes before style.
    • Preserve product identity. Keep identifiers and variant distinctions consistent enough that your team can connect a generated description to the exact item that triggered it.
    • Define an escalation threshold. A harmless paraphrase and a material misrepresentation are not the same incident. Prioritise wording that changes price conditions, compatibility, quantity, availability or what the customer receives.

    Do not rewrite a whole catalogue after one screenshot. The feature is still experimental, and an isolated observation does not reveal how often it appears or how Google selected that presentation. Correct clear defects in your owned data, but keep speculative changes small and reversible.

    <!– wp:heading {
  • How to Build a Self-Improving AI Content Workflow

    How to Build a Self-Improving AI Content Workflow

    You keep correcting the same AI output: a vague heading, an unsupported claim, a generic opening, a conclusion that says nothing. The draft improves after you edit it, but the workflow that produced it stays exactly the same.

    A self-improving content workflow preserves those corrections, finds recurring patterns, and changes the next run under controlled conditions. The goal is not an agent that rewrites its own rules without supervision. It is a system that turns editorial judgment into reviewable improvements to briefs, evidence retrieval, writing instructions, quality gates, and routing.

    A workflow improves only when feedback changes the next run

    Generating a draft, editing it, and publishing it is a production process. It becomes a feedback loop only when the correction affects a reusable part of the process. Unless you persist that correction somewhere, a new model run has no reason to avoid the same failure.

    The reusable change does not have to be a prompt edit. Feedback can change the criteria used to approve an angle, the queries used to retrieve evidence, the material included in a writing packet, the rubric applied by an editorial agent, or the route taken when a check fails. This distinction matters because many apparent writing problems originate before the writer receives the task.

    Every useful loop needs the same basic components:

    • An observable failure, recorded in specific terms.
    • A classification that identifies where the failure entered the workflow.
    • A proposed change to a reusable instruction, criterion, example, query, or routing rule.
    • An evaluation that checks whether the change fixes the target problem without damaging other requirements.
    • A human-controlled decision to approve, reject, revise, or roll back the change.

    That last component is what makes the system governable. Production agents can record feedback and propose patches, but they should not silently promote every correction into permanent operating memory. A rushed edit, an individual preference, or an unusual brief can otherwise become a global rule.

    Key takeaways

    • Begin with a quality gate around existing drafts; it creates useful feedback without requiring you to rebuild the whole pipeline.
    • Cap revision at two rounds. A draft that still fails usually needs better evidence, a narrower claim, or a stronger angle.
    • Separate editorial review from citation checking so each agent has a clear job and an appropriate context packet.
    • Stop weak angles and evidence gaps before writing. Upstream failures become more expensive after a full draft exists.
    • Use recurring edits as evidence for an instruction change, but require a proposal, evaluation, version record, and human approval.

    Start with a quality gate and a firm revision cap

    Blank manuscript sheets move through a quality gate, with one approved, one sent through a limited revision loop, and one routed to a human editor.

    The smallest practical self-improving workflow places an independent reviewer after the writer. The reviewer does more than declare that a draft feels weak. It evaluates explicit acceptance criteria, identifies the class of failure, and returns a bounded revision request.

    Build that loop in this order:

    1. Write an acceptance contract for the content type. Define the intended reader, the decision or task the content must support, the required evidence standard, the voice constraints, and the structural requirements.
    2. Give the writer a bounded packet containing the approved brief, outline, evidence, brand instructions, and output format. Do not make the writer infer which requirements matter most from a large repository of loosely related material.
    3. Send the resulting draft to an editorial reviewer in a separate context window. The reviewer should receive the acceptance contract and the draft, not the writer’s internal deliberation.
    4. Send factual claims and cited evidence to a dedicated fact-checker. Its job is to verify that the evidence supports the wording in the draft, not merely that a cited link exists.
    5. Classify the result as pass, flag, or escalate. Attach a precise diagnosis to every flag.
    6. Return fixable defects to the writer. The revision request should name the affected passage, failed criterion, reason for failure, and required result.
    7. Stop after two revision rounds. Route the draft and its review history to a person who can change the angle, evidence plan, or brief.

    The three verdicts need operational definitions. Pass means the draft meets the acceptance contract and its factual claims survive checking. Flag means the defect can be corrected within the existing brief and evidence set. An undefined term, an indirect opening, or a poorly ordered section can usually be flagged. Escalate means rewriting alone cannot solve the problem. Missing evidence, an unworkable thesis, contradictory requirements, and an angle with no defensible point of view belong here.

    The revision cap prevents an agent pair from polishing around a structural defect. If specificity remains weak after two rewrites, the evidence packet may not contain the concrete material the writer needs. Another instruction to be more specific will not create that material. The correct route is back to research or strategy.

    Keep editorial review and fact-checking separate even if both happen after drafting. An editorial reviewer asks whether the structure serves the argument, the language fits the audience, and the answer is useful. A fact-checker compares each factual statement with the evidence attached to it. Combining those responsibilities makes it easier for fluent prose to distract from weak support, or for citation work to crowd out substantive editing.

    Add a direct entry point to the gate as well. A draft written by a colleague, contractor, or older system should be reviewable without rerunning ideation, retrieval, and drafting. This makes the gate useful across the content operation and gives you a more representative record of recurring failures.

    Catch weak angles and evidence gaps before drafting

    A downstream reviewer can detect an unsupported claim, but it cannot manufacture the missing proof. It can identify a generic thesis, but by then you have already paid for research, drafting, and review. Two upstream checks prevent those failures from entering the expensive part of the workflow.

    Filter the brief with pass, revise, and kill decisions

    Evaluate each proposed angle against criteria you define before generation. Useful criteria include audience fit, thesis strength, original point of view, distance from existing coverage, and whether the necessary proof appears obtainable. The evaluator must choose an action, not simply assign a vague confidence score.

    VerdictMeaningNext action
    PassThe angle has a defensible thesis, fits the intended audience, and can be supported.Release the brief to evidence retrieval and outlining.
    ReviseThe idea is viable, but its scope, audience, differentiation, or evidence requirement is wrong.Return a specific change request, then evaluate the revised brief again.
    KillThe angle lacks a meaningful point of view or depends on proof that is not available.Stop the run and record the reason. Do not ask the writer to rescue it with phrasing.

    The kill log is not a graveyard for ideas. It is training data for strategy rules. Record the intended audience, thesis, decision, reason code, missing requirement, evaluator, and rule version. You can then see whether the same pattern keeps failing: duplicate angles, claims that require unavailable data, topics aimed at the wrong buyer stage, or briefs too broad to support a useful answer.

    Keep revise and kill distinct. Revise means a known change can make the brief viable. Kill means the core proposition does not survive the criteria. If evaluators use kill merely to avoid difficult research, tighten the definition. If they send fundamentally empty ideas through repeated revisions, tighten it in the other direction.

    Map planned claims to evidence section by section

    Once the angle passes, place a checkpoint between retrieval and writing. For every planned section, record the claim it needs to establish, the evidence intended to support it, and the gap that would remain if the writer used only that material.

    A practical evidence map contains:

    • The section heading and its purpose in the argument.
    • The exact factual or analytical claim the section must support.
    • The relevant evidence URL or document identifier.
    • A support score on a 1-10 scale, using a definition that stays consistent across runs.
    • The unsupported part of the planned claim.
    • A follow-up query, narrower claim, or deletion recommendation.

    Choose the passing threshold before evaluating the packet. When a section falls below it, the mapping agent should not hand the gap to the writer. It should produce the follow-up query itself, narrow the planned statement to match the available evidence, recommend removing the section, or escalate the gap to a person.

    This checkpoint is especially useful for SEO, AEO, and GEO content. A fluent answer can still be unusable if its strongest sentence outruns its citation. Mapping claims before drafting gives the writer permission to be specific where the evidence is strong and forces a deliberate decision where it is not. It also gives the fact-checker a clean chain from planned claim to evidence to published wording.

    Turn repeated edits into controlled instruction updates

    An editor groups recurring changes from blank drafts, approves one pattern, and adjusts an instruction module for the next content cycle.

    Do not update a shared prompt every time someone changes a sentence. Many edits are local: a legal qualification for a particular market, a preference from one stakeholder, or an exception created by an unusual format. Promoting them immediately makes the workflow unstable.

    A useful operating rule is to wait until the same edit pattern appears across three separate content assets. That is not a universal law or proof that the proposed fix is correct. It is a practical trigger for asking whether a reusable instruction has failed. The system should propose a change at that point, not apply one automatically.

    Capture each meaningful edit as a structured event:

    • Asset type and workflow version.
    • Original passage and approved revision.
    • Defect category, such as weak specificity, unsupported claim, indirect answer, voice mismatch, repetition, or poor section order.
    • The workflow stage most likely to own the defect.
    • The requirement that the original output failed.
    • Whether the edit is local to the asset, specific to a channel, or potentially global.
    • The reviewer who approved the final correction.

    Classification is more important than raw edit distance. Replacing an entire paragraph may reflect a minor tone preference, while changing a short factual qualifier may correct a serious accuracy problem. The system needs to know why the edit happened before it can recommend where to intervene.

    Route the proposed fix to the earliest stage that can prevent recurrence. A repeated unsupported claim belongs in evidence mapping or fact-checking. A repeated mismatch between topic and audience belongs in the brief filter. A buried direct answer belongs in the outline or structural rubric. Only a failure that genuinely originates in drafting belongs in the writer instructions.

    Make every instruction proposal reviewable. It should contain the observed pattern, the affected assets, the proposed wording, the expected change, the evaluation criterion, the scope of application, and the current instruction version. Replace abstract directives such as improve clarity with testable behavior. For example: define a technical term when it first appears, then state the implementation consequence in the same section. A reviewer can inspect that requirement in an output; improve clarity cannot be evaluated consistently.

    Evaluate the patch on representative briefs before promoting it. Check the target defect and the rest of the acceptance contract. An instruction that produces sharper openings but removes necessary qualifications is not an improvement. Preserve the earlier version so you can roll back the change if a wider set of runs reveals a regression.

    Scope memory by format. The correction that improves a landing page may make a technical explainer too abrupt. A rule for a LinkedIn post may be inappropriate for a video script. Maintain shared brand requirements where they are genuinely universal, then place format-specific instructions closer to the relevant writer and reviewer.

    Use rubric scores to diagnose the system, not flatter it

    A pass-or-fail gate tells you whether content can move forward. A rubric tells you which capability is holding it back. Score each criterion separately and require a concrete diagnosis whenever a score falls below its threshold. A total score alone is dangerous because strong voice and clean structure can conceal weak evidence.

    Rubric dimensionQuestion to evaluateLikely route when it fails
    Audience and intent fitDoes the content resolve the decision or task named in the brief?Brief filter
    Original point of viewDoes the thesis make a defensible contribution rather than restating the topic?Angle evaluation
    SpecificityDo important recommendations include the mechanism and an actionable consequence?Evidence mapping or writer
    Claim supportDoes the evidence establish the claim at the strength used in the draft?Retrieval checkpoint
    Citation fidelityDoes each cited item support the exact sentence attached to it?Fact-checker
    StructureDoes each section advance the argument or help the reader complete the task?Outline or editorial reviewer
    VoiceDoes the wording follow the applicable brand and format rules?Writer instructions
    Answer usabilityAre core answers direct, self-contained, and explicit about the entities and conditions involved?Outline or writer

    A diagnosis must describe the gap, not merely repeat the criterion. Specificity is low is not useful feedback. The recommendation names actions but omits the condition that determines which action applies is useful. It tells the writer what to repair and gives the reviewer something concrete to check on the next pass.

    You can also apply the same rubric to competing briefs, outlines, or openings. Compare candidates criterion by criterion, preserve any hard acceptance requirements, and select the option that best serves the task. Do not let a high average compensate for a fatal weakness such as an unsupported central claim.

    Track workflow health alongside content scores. Useful operating measures include first-pass acceptance, flags by defect category, revision rounds per asset, escalation reasons, evidence gaps caught before drafting, instruction patches proposed and approved, and patches later rolled back. These measures show whether the system is preventing defects or merely moving them between agents.

    Post-publication outcomes can trigger investigation, but they should not rewrite instructions by themselves. Search visibility, AI citations, engagement, and conversion depend on more than wording. Associate each asset with its intended outcome, review performance within a predefined measurement window, and compare the result with the editorial record. Then decide whether the signal points to content quality, distribution, technical implementation, audience fit, or a changed search environment.

    Implement the system in layers. Put the capped reviewer and fact-checker around the draft currently waiting for approval. Log every verdict and escalation. When those logs expose upstream failures, add the angle and evidence checkpoints. When recurring edits become visible across separate assets, enable instruction proposals with approval and rollback. Your workflow will then improve from evidence of its own failures without giving up editorial control.

    References

  • Google Review Markup Rules for Incentivized Reviews

    Google Review Markup Rules for Incentivized Reviews

    You have reviews from a sampling campaign, loyalty offer, discount program, or product giveaway, and some of them feed the rating marked up on your site. The question is not simply whether an incentive existed. You need to know whether the review reflects a real experience, whether the benefit was disclosed clearly, and whether your page and structured data present the same record.

    Treat the published review, its disclosure, the visible aggregate rating, and the JSON-LD as one system. Fixing only the schema can leave the underlying policy problem in place.

    The rule draws two separate lines

    A review snippet is a review excerpt or rating that can appear in Google Search, often as an aggregate drawn from multiple reviewers. Following the applicable guidelines makes a page eligible for review-snippet features; it does not guarantee that Google will display them.

    Google’s rule is explicit: fake or undisclosed incentivized reviews should not appear on the page or in its structured data markup. That creates two distinct tests:

    • A fake review is not based on a genuine experience with the product or service. Adding a compensation disclosure does not turn it into a valid review.
    • An undisclosed incentivized review may describe a genuine experience, but it hides or inadequately presents the benefit the reviewer received. The problem is the missing disclosure as well as the way the review is represented.

    Incentives can include money, discounts, vouchers, or free products. The wording matters: the prohibition names fake reviews and incentivized reviews that are not clearly and prominently disclosed. It is narrower than a blanket statement that every incentivized review is forbidden, but it is not an automatic approval for every disclosed review. All other review-snippet requirements still apply.

    For implementation, treat clear and prominent as a reader-facing standard. The person reading a specific review should be able to see that review’s incentive without opening a policy page, following another link, or hunting through fine print. A practical placement is directly beside the reviewer details, rating, or review text. Disclosure inside JSON-LD alone is not a reader-facing disclosure.

    Classify each review before changing the markup

    A hand sorts blank review cards into separate trays based on product, discount, experience, and warning symbols.

    Do not apply one decision to an entire campaign until you have separated the reviews into meaningful cases. One campaign can contain valid organic reviews, properly disclosed incentivized reviews, undisclosed reviews, and reviews with no evidence of genuine experience.

    Review situationMarkup decisionPage action
    No genuine product or service experienceExclude it from individual review markup and every marked-up aggregate that counts it.Remove it rather than trying to repair it with a disclosure.
    Genuine experience, but an incentive is hidden or not clearly disclosedDo not include it while it remains undisclosed. Correct any aggregate rating or count that incorporates it.Pause or remove it, add a truthful and prominent disclosure if appropriate, and reassess it before republishing or re-enabling markup.
    Genuine experience with a clear, prominent incentive disclosureThe new prohibition does not categorically reject this case, but the disclosure does not override other review-snippet rules.Keep the disclosure attached to the review wherever that review is displayed or reused.
    Genuine experience with no incentiveEvaluate it under the normal review-snippet requirements.Maintain ordinary editorial and data-quality controls.

    The difficult row is the disclosed incentivized review. Do not turn the wording into either an unconditional ban or an unconditional pass. Verify the genuine experience, preserve the exact disclosure, and check the rest of the applicable review rules before counting the review in structured data.

    Audit the visible rating and JSON-LD together

    A magnifying glass examines an amber mismatch between blank review cards on a web page panel and corresponding elements in a translucent data structure.

    The fastest reliable audit starts with the reviews that feed your aggregate rating, not with a schema validator. A validator can tell you whether markup is technically readable. It cannot establish that a reviewer had a genuine experience or that an incentive was properly disclosed to a human reader.

    1. Inventory every review surface. Include product pages, service pages, category templates, testimonials, imported review widgets, archived campaign pages, and any other page that publishes or aggregates reviews.
    2. Trace each displayed aggregate to its underlying review records. Record which reviews contribute to the rating value and review count rather than assuming the visible list is the complete data set.
    3. Create an audit field for genuine experience. If the basis is unknown, put the review into a hold state instead of treating missing information as proof that the review is organic.
    4. Create a separate incentive field. Record the actual benefit, such as money, a discount, a voucher, or a free product. Do not rely on campaign names that obscure what the reviewer received.
    5. Inspect the rendered disclosure. Check the live desktop and mobile presentation, template variants, collapsed content, and reused excerpts. The disclosure needs to remain attached to the review in the version a visitor actually sees.
    6. Remove or quarantine failures before recalculating the aggregate. Excluding an individual Review node is not enough if its rating still influences a marked-up AggregateRating.
    7. Publish the corrected review set, visible aggregate, review count, and structured data as one coordinated change. Then inspect the rendered HTML to confirm that cached templates or client-side scripts did not restore stale values.

    A compact review ledger makes this manageable. Give every review a stable internal ID and track its experience status, incentive type, disclosure text, publication status, aggregate inclusion status, and last audit decision. That record lets your editorial, reputation, and technical SEO teams make the same decision when a review is copied to another page or imported into a new template.

    Four partial fixes still leave you exposed

    Most implementation mistakes come from treating review markup as an isolated technical layer. The policy explicitly reaches both the page and the structured data, so these shortcuts do not resolve the underlying issue.

    • Removing only the individual Review markup: If the incentivized review still affects a marked-up rating value or review count, it remains part of the structured-data claim indirectly.
    • Leaving the review visible but omitting it from JSON-LD: That does not resolve a fake or undisclosed incentivized review on the page. The page itself is within the rule.
    • Adding the disclosure only to JSON-LD: Structured data is written for machines. It does not make an incentive clear and prominent to the person reading the review.
    • Using one generic campaign disclaimer: A disclosure at the bottom of a page or in a separate policy can become detached when an individual review is filtered, syndicated, quoted, or moved. Bind the disclosure to the review record and render them together.

    Disclosure also cannot cure fabrication. If the reviewer did not genuinely experience the product or service, a label explaining the incentive addresses the wrong problem. Remove the review and every aggregate contribution derived from it.

    Build the disclosure into review collection

    Retrofitting disclosure after reviews reach production creates avoidable uncertainty. Collect the information before a review enters the publishing queue, and keep publication approval separate from markup eligibility.

    • Ask whether the reviewer received any benefit and store the exact type of benefit as structured data in your CMS or review platform.
    • Require a genuine-experience check before editorial approval. Do not let a completed form or imported star rating substitute for that decision.
    • Generate a truthful review-level disclosure from the stored incentive field. A usable template is: This reviewer received [specific benefit] in exchange for providing this review. Adapt the wording to what actually happened rather than using a vague sponsored label.
    • Keep separate controls for published, included in the visible aggregate, and eligible for structured data. A review may need to remain on hold while its origin or disclosure is investigated.
    • Preserve the disclosure when reviews are exported, syndicated, translated, excerpted, or moved between templates. Treat a review without its disclosure as an incomplete record.
    • Default uncertain records to excluded. Re-enable them only after someone has documented the genuine experience, incentive status, and live disclosure.

    This workflow prevents a marketing campaign from silently changing an SEO claim. It also gives you a defensible answer when a rating changes after disqualified reviews are removed: the new value reflects the review set you can actually stand behind.

    Key takeaways

    • A review must be based on a genuine product or service experience. Disclosure does not rescue a fabricated review.
    • An incentivized review must not be presented without a clear and prominent disclosure of the benefit.
    • The rule applies to both the visible page and the structured data, including aggregates that incorporate affected reviews.
    • A disclosed incentive is not automatically disqualified by this specific clause, but disclosure alone does not establish full review-snippet eligibility.
    • Your safest control is a review-level ledger connecting experience, incentive, disclosure, publication, and aggregate inclusion.

    Start with the reviews behind your current aggregate rating. Quarantine anything fake, undisclosed, or uncertain; recalculate the visible and marked-up values from the remaining set; and make incentive disclosure a required field before the next campaign begins.

    References

  • How to Choose a Manufacturing GEO and AEO Agency

    How to Choose a Manufacturing GEO and AEO Agency

    You’re likely here because a familiar SEO agency has added GEO to its services, a specialist has promised AI visibility, or leadership wants to know why your company is missing from AI-generated supplier lists. The hard part isn’t finding a firm that uses the right acronym. It’s finding one that can represent a technical product accurately, earn visibility for the buying questions that matter, and connect that visibility to qualified opportunities.

    That distinction matters because procurement leads, operations managers, and plant engineers are increasingly starting supplier research in ChatGPT or Claude. In that environment, weak content can do more than miss a ranking. It can associate your brand with the wrong capability, material, certification, or application. The process below will help you test an agency before you commit your subject-matter experts, website, and budget.

    Start with the buying decision, not the GEO label

    SEO and GEO overlap, but they aren’t interchangeable. SEO helps pages become discoverable in conventional search results. GEO and AEO aim to make a company, product, or explanation usable in answers synthesized by systems such as ChatGPT, Claude, Perplexity, and Google Gemini. A manufacturing program usually needs both: accessible owned content and enough clear, credible evidence for an answer engine to understand when the company is relevant.

    Your agency brief should begin with the decisions a buyer is trying to make. Don’t begin with a monthly article count. Give every candidate the same information:

    • The product categories, applications, and markets you want to be associated with.
    • The buyer roles involved, such as a plant engineer defining requirements, an operations leader evaluating risk, or procurement comparing suppliers.
    • The materials, tolerances, operating conditions, standards, certifications, and application claims that require verification.
    • The claims your company is permitted to make, the claims it cannot make, and the questions that require an engineer’s judgment.
    • The commercial action you want after discovery, such as requesting a quote, submitting a drawing, ordering a sample, contacting an application engineer, or finding a distributor.
    • The countries and languages in scope, because a useful answer in one market may be incomplete or inappropriate in another.

    Next, organize target questions by decision stage. Discovery questions identify a suitable product type. Qualification questions test operating conditions or required capabilities. Comparison questions separate materials, methods, or supplier approaches. Risk questions cover compatibility, maintenance, standards, and failure considerations. Supplier-selection questions ask who can provide the required solution.

    For every question cluster, require the agency to identify the page or evidence that should support the answer, the subject-matter expert who can approve it, and the next commercial action. If a candidate proposes publishing at scale before creating this map, it is optimizing output before defining the job.

    You should also separate four outcomes that agencies often compress into one visibility metric:

    • Mention: Your company or product appears in an answer.
    • Citation: The answer links to an owned page as supporting material.
    • Recommendation: Your company is presented as relevant to the stated requirement, with an intelligible reason.
    • Accuracy: The answer describes your capabilities, limitations, and applications correctly.

    A mention without accuracy can create cleanup work for sales and engineering. A citation on an informational query may build authority without generating an immediate lead. A recommendation can be commercially valuable even when referral tracking is incomplete. Your agency should report these outcomes separately instead of blending them into a flattering composite score.

    Build a scorecard around evidence you can inspect

    A procurement professional and manufacturing engineer inspect an industrial part beside organized technical documents and a laptop with an abstract source network.

    For one 2026 screen of 52 agencies serving manufacturers, AI visibility carried 30% of the score, relevant manufacturing clients 25%, aggregated reviews 20%, leadership experience 15%, and technical content capability 10%. Those weights aren’t an industry standard. They are useful categories, but you should adjust their importance to your risk. Technical governance deserves more weight when products are regulated, safety-critical, highly customized, or easily misapplied.

    CriterionEvidence to requestRed flag
    AI visibilityExact prompts, named platforms and models, dates, target market and language, complete outputs, citation URLs, and an explanation of how correctness was checked.A proprietary score, selected screenshot, or percentage with no raw prompts, dates, or outputs.
    Manufacturing experienceA technically comparable work sample, the approval path used with engineers, and a client reference with similar product complexity and sales motion.A page of industrial logos with no relevant sample, delivery detail, or reference you can contact.
    Technical content governanceA fact sheet, claim-to-evidence process, subject-matter expert interview plan, revision history, approval owner, and correction procedure.Writers are expected to fill gaps themselves or turn an unverified inference into a product claim.
    Commercial measurementDefinitions for qualified inquiries and opportunities, CRM field mapping, reporting ownership, and a view that places citations and traffic beside pipeline outcomes.Success is limited to content volume, traffic, impressions, mentions, or a visibility index.
    Leadership and continuityThe names and roles of the people who will do the work, their allocation, the escalation path, and the backup plan when a lead changes.Senior specialists appear in the sales process but the proposed delivery team remains unnamed.
    CapacityA realistic production and review workflow by product line, including the expected demand on your engineers and approvers.Unlimited production claims or a schedule that assumes immediate subject-matter expert approval.
    SEO and technical integrationClear responsibility for crawlability, indexation, internal linking, content maintenance, and structured data that reflects visible, approved claims.Schema is presented as a shortcut to authority or is used to mark up claims that users cannot verify on the page.

    Structured data can clarify entities and attributes that are already supported by visible content. It cannot make an unsupported capability true, repair vague positioning, or replace the evidence an engineer and buyer need. Ask the agency to show how its content, technical SEO, structured data, and off-site authority work together rather than accepting schema volume as a result.

    Review scores and recognizable client names can reduce uncertainty, but they don’t establish fit by themselves. A reference from a company with a comparable review burden, product range, and sales cycle is more diagnostic than an aggregate rating. Ask that reference how much engineering time the program consumed, how often drafts needed substantive correction, whether the senior team stayed involved, and whether reporting reached qualified opportunities.

    Match the agency’s operating model to your bottleneck

    There is no universal best manufacturing GEO agency. A focused specialist can be excellent for one category but constrained by a multi-line publishing program. An analytics-led firm can satisfy finance while struggling if your positioning still needs to be rebuilt. A technical SEO specialist can repair a complex site but may not be the right owner for an engineering-heavy editorial operation.

    The firms below appeared among the eight highest-ranked candidates in a 2026 evaluation of manufacturing-serving agencies. Use them as interview leads, not as a ready-made decision. Because First Page Sage created the ranking in which it placed itself first, its ordering and scores should be treated as vendor-published claims rather than independent validation.

    AgencyReported operating emphasisConsider it whenPressure-test before hiring
    First Page SageManufacturing thought leadership combined with SEO and GEO for qualified lead generation.You want a sustained authority program that connects conventional search, AI visibility, and lead generation.Onboarding sequence, time to productive output, direct evidence behind performance claims, and references independent of its own ranking.
    GenevateGEO-first lead generation for B2B manufacturers, delivered through a focused, senior-led model.You have a defined product category or buyer segment and value strategic depth over high-volume production.Capacity across simultaneous product lines, expected monthly throughput, backup coverage, and the work your internal team must absorb.
    Driven MetricsAnalytics-first GEO for growth-stage manufacturers.Your positioning is stable and executives expect visibility work to be tied to qualified leads and opportunities.How its process responds when messaging changes, who owns creative positioning, and which attribution claims are measured versus inferred.
    Focus DigitalSMB-focused manufacturing GEO at an accessible price point.You need a tightly scoped program that fits a smaller marketing organization.Technical depth in your category, senior attention after onboarding, included deliverables, and the plan for scaling beyond the initial scope.
    Gorilla 76Manufacturer-exclusive inbound and GEO programs.You value an industrial specialist and want GEO integrated with a broader inbound program.The distinction between its inbound and GEO methods, prompt-level AI evidence, and how each activity maps to pipeline.
    TREW MarketingEngineering-first content strategy and GEO.Your audience expects substantial technical detail and engineers must be central to content development.Subject-matter expert workload, technical approval controls, AI visibility measurement, and the path from educational content to qualified opportunity.
    Windmill StrategyTechnical SEO and GEO for complex manufacturing websites.Site architecture, technical debt, or a complicated product catalog is blocking discoverability and comprehension.Who owns authority-building content, how technical fixes are prioritized, and how AI answer performance will be monitored after implementation.
    Weidert GroupHubSpot-centric industrial GEO and inbound growth.Your organization already operates around HubSpot and wants inbound and GEO managed as one program.Platform dependencies, CRM data quality requirements, ownership of assets and data, and the effect of changing your marketing stack.

    Scores can help you reduce a long list, but they cannot resolve operating fit. Genevate’s focused model, for example, may be attractive when senior attention matters more than publishing volume; the same structure needs careful capacity testing if several divisions must launch together. Driven Metrics’ measurement rigor is useful when the commercial narrative is already clear, but a company still deciding how to position its products should establish who will own that upstream work.

    Retention figures deserve the same treatment. First Page Sage publishes a 91% renewal rate and an average client tenure of more than three years. Those figures are promising questions for due diligence, not substitutes for it. Ask for the measurement period, client count, definition of renewal, exclusions, and references whose scope resembles yours.

    Make finalists prove the workflow before the contract

    A cross-functional team demonstrates a technical content workflow with an industrial pump model, engineering documents, blank process cards, and an abstract digital display.

    Every finalist should work from the same brief and be judged against the same acceptance criteria. Otherwise, the agency with the smoothest presentation wins even though the proposals solve different problems.

    1. Prepare a common evaluation packet. Include product families, priority markets, target buyers, approved terminology, current content, known technical gaps, conversion actions, CRM stages, and the claims that require formal approval.
    2. Request a prompt-level baseline. For every important query, require the exact prompt, platform and model, date, market and language, full answer, citation URLs, brand context, competitor context, and correctness assessment. A score without this evidence cannot be audited.
    3. Ask for a technical workflow demonstration. Give each finalist the same approved engineering packet and have it return a content brief, unresolved subject-matter expert questions, claim-to-evidence mapping, proposed page structure, and any structured-data recommendation. The goal is to see how the team handles uncertainty, not to collect free finished content.
    4. Meet the proposed delivery team. Ask the strategist, technical writer, analyst, and account lead to explain your product back to you, identify what they still don’t know, and show who can stop publication when a claim lacks support.
    5. Verify matched references. Speak with customers that resemble you in product complexity, review burden, sales cycle, and program size. Ask about engineering hours, correction rates, continuity, reporting quality, and the difference between promised and actual capacity.
    6. Use a tightly scoped paid pilot when the evidence remains thin and procurement permits it. Define acceptance criteria before kickoff, including technical accuracy, required approvals, baseline documentation, measurement design, ownership, handoff materials, and the conditions for continuing. A pilot without written acceptance criteria is merely a shorter contract.

    Require reporting at three levels

    A credible dashboard should let you move from an AI answer to the underlying asset and then to a business outcome:

    • Answer level: Which prompt was tested, where and when it was tested, whether the brand was mentioned, cited, or recommended, what reason was given, and whether the description was accurate.
    • Owned-asset level: Which page supported the answer, whether the page remains technically accessible and current, how conventional search visibility is changing, and what direct AI referral activity can be identified.
    • Pipeline level: Which inquiries met your qualification definition, which became opportunities, and which progressed to revenue. Directly observable activity should be separated from assisted or inferred influence.

    Attribution won’t always be complete. A buyer may see an AI answer, return through branded search, and contact sales without preserving a clean referral path. That limitation is a reason to label evidence carefully, not a reason to stop at visibility. Driven Metrics emphasizes qualified leads and opportunity attribution alongside traffic and citations, which is the right type of commercial discipline to demand from any finalist.

    Before signing, settle ownership and continuity in writing. Confirm who owns content, research files, prompt sets, dashboards, structured-data specifications, and account access. Identify the platforms and markets being monitored, the revision and correction process, the named delivery team, the escalation path, and what you receive at handoff. Don’t accept a guaranteed recommendation on an AI platform; require a repeatable method, inspectable evidence, and clear reporting instead.

    Key takeaways

    • Hire against specific manufacturing buying decisions and qualified pipeline outcomes, not an acronym or publishing quota.
    • Measure mentions, citations, recommendations, and technical accuracy separately.
    • Require raw, dated, prompt-level evidence from named AI platforms before accepting a visibility score.
    • Make claim verification, engineer approval, correction handling, and content ownership explicit parts of the workflow.
    • Choose an operating model that fits your real bottleneck: technical content, website complexity, measurement, focused strategy, inbound integration, or production capacity.
    • Treat vendor rankings, client logos, review aggregates, and retention claims as shortlist inputs that still require matched references and direct validation.

    Your next move is to write the prompt-and-proof brief before booking agency calls. Send the identical brief to every finalist, score the evidence you can inspect, and have engineering or operations approve the technical workflow before procurement negotiates the commercial terms. The right partner will make its assumptions visible, show how a manufacturing claim becomes usable evidence, and accept accountability beyond an AI visibility score.

    References

  • How to Build an AI Brand Claim Correction Workflow

    How to Build an AI Brand Claim Correction Workflow

    An AI answer says your product lacks a feature it has, assigns your company to the wrong owner, or repeats a policy you retired. The tempting response is to regenerate the answer until it looks right. That may produce a better output, but it does not tell you whether the underlying claim has been corrected.

    You need a workflow that turns a bad answer into a documented case: capture the claim, decide whether it is truly inaccurate, identify the evidence influencing it, correct that evidence where possible, and verify the result without treating one favorable retest as proof.

    Capture the claim before anyone starts correcting it

    An AI error is not actionable when the entire report is, AI got our brand wrong. Your unit of work should be one exact claim in one observable response. If an answer contains three inaccuracies, open three claim records. They may have different evidence, owners, risks, and correction paths.

    Create the record before editing a page, contacting a publisher, or changing structured data. Otherwise, you lose the baseline needed to determine what changed.

    1. Save the inaccurate sentence verbatim and preserve the surrounding answer. A cropped sentence can hide a qualification that changes its meaning.
    2. Record the exact prompt, AI product or search surface, visible model name if one is provided, response mode, language, location, and any account or personalization setting that could affect the result.
    3. Add the capture date, a screenshot, and the full response in a durable format. Redact personal or confidential information before sharing the case outside authorized systems.
    4. Save every citation, linked page, domain, and quoted passage returned with the answer. Note explicitly when no citation is shown.
    5. Write the correct replacement claim in one sentence. Avoid promotional wording; state the narrow fact you can prove.
    6. Attach the evidence supporting that replacement, including the authoritative URL, page section, document owner, and effective date where one exists.

    Then run a small, fixed baseline set. Include the original prompt, a natural paraphrase, and the adjacent question a prospective customer is likely to ask. If the problem appeared in a comparison query, include both the comparative and standalone brand forms. Log each response separately.

    Do not combine different AI products, model modes, languages, or countries into one result. A claim that appears on one surface and not another is still worth recording, but it is not evidence that every system holds the same representation. Likewise, a single occurrence establishes that the error happened; it does not establish how prevalent it is.

    Classify the failure while the evidence is fresh. Useful labels include fabricated, outdated, misattributed, context omitted, source contradicted, and technically true but materially misleading. These labels make the next decision easier because an outdated policy needs a different remedy from a claim invented without a visible citation.

    Triage inaccurate claims by harm, evidence, and correctability

    Overhead view of hands sorting abstract claims and evidence into three priority trays.

    Not every unfavorable statement is inaccurate, and not every inaccuracy deserves an urgent campaign. Validate the claim before you send a correction request. If your own product pages disagree, the immediate problem is not the AI system; it is the absence of a stable, supportable brand fact.

    Ask four questions in order:

    • Can you prove the claim is wrong? Identify the specific factual conflict and the dated evidence that resolves it.
    • What decision could it affect? Consider purchasing, renewal, hiring, partnership, compliance, safety, and reputation rather than relying on how embarrassing the answer feels.
    • How broadly does it recur? Use the fixed prompt set instead of repeatedly improvising prompts until you find either the answer you want or the answer you fear.
    • Is there a correctable evidence path? A cited publisher page, outdated first-party page, incorrect profile, or contradictory product document gives you a concrete target. An uncited answer requires investigation before outreach.

    Use three practical queues. Put objectively false claims with serious commercial, safety, regulatory, or reputational consequences in the urgent queue. Put material but lower-consequence errors with identifiable evidence in the planned queue. Monitor isolated, low-impact, ambiguous, or genuinely subjective statements until you have enough evidence to act.

    Do not submit a factual correction simply because an answer is negative. A documented limitation, a supported criticism, or an opinion cannot be repaired by replacing it with brand copy. Correct the underlying fact, supply missing context, or respond through the appropriate communications process.

    Claims alleging fraud, criminal conduct, regulatory violations, dangerous behavior, or other matters with legal consequences need special handling. Preserve the complete evidence, restrict internal circulation where appropriate, and have qualified counsel approve any external demand. A hurried accusation or an attempt to remove relevant records can create a larger problem than the AI answer itself.

    Choose the evidence layer that can actually be corrected

    An AI response is an output, not a single brand profile you can open and edit. Your correction target is usually an evidence layer that the system found, cited, retrieved, or learned from. Begin with the citations in the response, then work outward to exact wording searches, first-party content, structured data, public profiles, and other pages that repeat the same claim.

    Observed patternLikely correction targetFirst action
    The answer cites an inaccurate third-party pageThe cited publisher or data ownerPrepare a narrowly scoped correction request with the exact passage, replacement wording, and proof
    The answer cites an outdated page you controlYour canonical product, policy, company, or documentation pageCorrect the visible content and reconcile every owned page that contradicts it
    Several sources publish conflicting versionsThe broader evidence setEstablish one canonical fact, update owned properties, and approach the most consequential external sources separately
    No citation is visibleStill unknownSearch for the exact phrasing and distinctive fragments, inspect owned content, and collect more logged responses before assigning a target
    The statement is technically true but missing a decisive qualificationContent clarity and contextPublish the qualification beside the claim rather than relying on a distant disclaimer

    First-party consistency matters because machines and people should not have to decide which of your pages is current. Pick one canonical location for each important brand fact. State the fact plainly, name its scope, add an effective or updated date when timing matters, and link supporting documents from that location. Remove or revise contradictory wording across product pages, help content, press materials, policy pages, downloadable files, and public profiles you control.

    Use JSON-LD to express facts that are already visible and supportable, not to create an alternate machine-only version of the brand. Organization, Product, and Offer markup can clarify entities and properties, but markup is not proof by itself and cannot repair an inaccurate publisher page. Keep structured data aligned with the visible page and your canonical record. If the prose says one thing and the schema says another, you have introduced another conflict.

    Third-party errors require a source-level correction. Identify who can change the exact record: an editor, database operator, directory owner, review platform, syndication partner, or other publisher. Do not send a general reputation complaint when you can point to a sentence, explain the factual defect, and provide a supported replacement.

    A vendor-announced integration connects inaccurate-claim flags from FactCheck with Noble’s Mention Refresh for source-correction work. The useful pattern is the handoff: detection should create an evidence-backed correction task, not end at a dashboard alert. That integration is not evidence that every publisher will accept a request or that every AI output will change afterward.

    Run the correction as a controlled handoff

    Illustration of a claim capsule passing between controlled correction stations before being tested across multiple AI answer samples.

    The handoff is where most correction programs become vague. Monitoring finds an error, communications assumes SEO owns it, SEO assumes legal or product has approved the replacement, and nobody has authority to contact the source. Assign four responsibilities for every validated case, even if one person fills more than one role:

    • The claim owner decides what the correct, supportable brand fact is.
    • The evidence owner supplies the records that prove it.
    • The correction owner updates an owned property or contacts the external source.
    • The verification owner reruns the fixed test set and decides whether the closure rule has been met.

    Package the case so the correction owner does not have to reconstruct it. A complete correction packet should contain:

    1. A short case title naming the entity, incorrect claim, and affected surface.
    2. The verbatim AI claim, original prompt, capture details, and full response.
    3. The URL and exact passage believed to support or repeat the error.
    4. A neutral explanation of why the passage is inaccurate or incomplete.
    5. The smallest replacement wording that resolves the defect.
    6. Links or attachments proving the replacement, with an internal approver named.
    7. The requested action, responsible owner, priority, and next review point.

    For a page you control, make the correction visible in the main content. Reconcile page titles, summaries, downloadable files, structured data, and related documentation where they repeat the old claim. Preserve any record your legal, compliance, or archival obligations require. When an old URL must remain available, add clear current context instead of silently leaving obsolete wording to circulate.

    For an external page, keep the request factual and easy to process. Name the URL and passage. Explain the error in one short paragraph. Supply the replacement and direct evidence. Ask for confirmation when the page changes. Do not mix a correction request with a demand for a promotional backlink, preferred positioning, or removal of an accurate criticism; that obscures the factual issue.

    Automation can create the case, attach captures, route approvals, assign owners, and schedule follow-up. It should not invent the replacement fact or send consequential external messages without review. The risky step is not copying fields between systems. It is deciding what the public record should say.

    Use explicit workflow states: detected, validating, validated, target identified, correction approved, submitted, source changed, retesting, closed, and monitor only. Require an artifact for each important transition. Validation needs proof. Submission needs a copy of the request. Source changed needs a before-and-after record. Closure needs the retest log.

    Separate the source task from the AI-output task. The source task can close when the target page or record is corrected. The output task stays open until your verification rule is satisfied. This distinction prevents a successful outreach email from being mistaken for a corrected brand representation.

    Verify the result without overreading one clean answer

    A corrected page does not guarantee an immediate or universal change in generated answers. The system may retrieve another page, use a different response path, preserve older information, or vary its wording from one run to the next. Do not promise a universal refresh time when the product, model mode, retrieval behavior, and evidence path can differ.

    Retest against the baseline you saved. Use the same prompts, settings, language, and surface first. Then run the approved paraphrases and adjacent questions. If several AI products matter to your business, treat each one as a separate test panel rather than averaging them into a reassuring overall result.

    At each checkpoint, record the answer, whether the inaccurate claim appeared, which qualification was present, and what the response cited. This produces four meaningful outcomes:

    • The source is corrected and the claim disappears across repeated checks. Keep the evidence and move the case toward closure.
    • The source is corrected but the claim persists. Investigate other cited pages, repeated phrasing, cached copies, and conflicting owned content before reopening outreach to the same publisher.
    • The claim varies between runs. Keep the case in retesting; a favorable generation has not established a stable correction.
    • The claim disappears but the underlying source remains wrong. Do not close the source task. The error can return or affect another answer.

    Measure the workflow rather than claiming credit for every output change. Useful operational measures include the number of validated claims still open, time from validation to source change, share of cases with an identifiable evidence target, recurrence within a fixed prompt panel, and the number of cases reopened after apparent resolution. Define each measure before reporting it, and keep raw counts beside rates when the test panel is small.

    Recurrence is especially useful when it has a fixed denominator: erroneous answers divided by completed runs in the same prompt panel at the same checkpoint. Changing the prompts, surfaces, or number of runs midstream makes the before-and-after rate hard to interpret. Add new discovery prompts to the next test version rather than quietly inserting them into the current baseline.

    Key takeaways

    • Preserve the exact claim, response context, prompt, surface, and citations before changing anything.
    • Validate that the statement is objectively inaccurate; negative, incomplete, and false are different correction cases.
    • Correct the evidence layer that can be changed, including contradictory first-party content and inaccurate third-party pages.
    • Give every case a claim owner, evidence owner, correction owner, verification owner, and explicit workflow state.
    • Close source correction and AI-output verification separately, using repeated checks against a fixed baseline.

    Start with the highest-consequence claim for which you already have decisive evidence. Build one complete case, assign its owners, and follow it from capture through repeated verification. That case will expose the missing approvals, evidence gaps, and handoff failures you need to solve before scaling the workflow.

    References

  • Brand Visibility in AI Search Depends on Source Trust

    Brand Visibility in AI Search Depends on Source Trust

    Brand visibility in AI search is not simply a matter of ranking highly or publishing more content. It depends on whether an AI system can find credible sources that mention the brand, support relevant claims and provide enough context to construct an answer.

    The source material points to a practical shift: brands must manage a portfolio of evidence rather than optimize for one universal result. Audience relevance, model-specific citation preferences, factual accuracy, freshness and platform-hosted business data can all influence which version of a brand appears.

    Source trust has become a distribution layer

    Traditional search encouraged brands to think primarily about pages and positions. Generative systems add another layer because they assemble answers from selected sources. A brand can therefore be visible indirectly through a publisher, community, reference site, video platform, business profile or product panel even when its own website is not the principal destination.

    This helps reconcile several of the reports. research described by Search Engine Land argues that repeated associations across credible, niche-relevant channels can strengthen a brand’s entity authority. Separately, Profound’s comparison of Google AI products found that their visibility differences reflected which brands and supporting sources they selected, rather than a large difference in the number of brands mentioned per answer.

    Together, those findings suggest that AI visibility has at least two dimensions. The first is inclusion: whether the brand enters the system’s available evidence. The second is interpretation: whether the selected evidence supports an accurate and favorable description. A mention can help with the first while hurting the second if the underlying information is obsolete, ambiguous or false.

    Trust should therefore be treated as contextual rather than as a single score. A source can be influential because it is authoritative, closely aligned with an audience, frequently used by a particular AI product or embedded in a platform’s own information environment. None of the reports establishes a universal hierarchy that applies to every query and model.

    Audience relevance can outweigh headline reach

    A focused beam illuminates a small attentive audience while a broader faint beam spreads across a large distant crowd.

    The clearest challenge to reach-first media planning comes from the publisher-affinity study. According to the Search Engine Land account, the niche publishers examined achieved 1.7 times the audience affinity of major media outlets despite receiving 130 times less traffic. The reported analysis covered audiences in eight industries and used SparkToro affinity data alongside conventional metrics such as organic traffic, domain rating and referring domains.

    The implication is not that large publications have lost their value. The same report presents mainstream and specialist coverage as complementary: major outlets can deliver scale and broad validation, while focused publishers can establish stronger topical and audience associations. A sensible source portfolio uses each for the job it performs rather than treating traffic as a complete proxy for influence.

    This changes media selection. A placement should be assessed not only by how many people might encounter it, but also by who relies on the outlet, how precisely the outlet covers the subject and whether its coverage adds substantive evidence. A smaller trade publication may provide detailed category context that a general-interest mention cannot. Conversely, a major outlet may provide wider recognition that a specialist source cannot match.

    The same reasoning extends beyond publishers. The affinity research considered websites, YouTube channels, podcasts, social accounts and community-led platforms. That broader view is consistent with the model comparison, which reported citations from editorial, reference, social and user-generated sources. Brand authority in AI search is consequently better understood as a network of corroborating contexts than as the product of one prominent link.

    Visibility changes when the model changes

    Three translucent lenses use different source objects to cast varying levels of light on the same unbranded object.

    A source strategy cannot assume that Google’s generative products return interchangeable representations. Profound reported tracking 15,155 brand configurations daily in May 2026 and found a median eight-point gap between each brand’s best- and worst-performing Google model. Gemini, AI Overviews and AI Mode reportedly mentioned a similar number of brands per response, averaging between 4.4 and 5.0, but differed in the brands selected and the sources cited.

    In that dataset, Gemini leaned more heavily on editorial and reference sources, including Reddit, YouTube and Wikipedia. AI Overviews and AI Mode relied more on social and user-generated platforms and produced roughly twice Gemini’s citation depth per run. These are reported observations from one analysis, not proof of a permanent sourcing rule. They nevertheless show why a visibility score from one interface cannot stand in for the entire AI-search environment.

    AI Mode introduces an additional platform consideration. Profound reported that Google.com had become AI Mode’s second-most-cited domain, with Google Business Profiles and Product Knowledge Panels appearing inside answers. The report highlights particular consequences for local-intent searches and physical products: the decision journey may proceed through Google-hosted information before a user reaches the brand’s site.

    For measurement, the useful unit is therefore a query-model-source combination. Teams need to compare how different systems answer the same meaningful questions, which claims each one makes and which citations or hosted data support those claims. For operations, this means that publisher outreach, community presence, video or reference visibility, product feeds, business-profile accuracy and review management can contribute through different routes.

    Accuracy and freshness determine whether visibility helps

    More visibility is not automatically beneficial. Profound’s FactCheck announcement describes a system for breaking AI answers into brand claims and tracing them to owned pages and third-party citations. Its example concerned an incorrect claim that Relay ERP was deployed on premises when the cited verified information described the product as cloud-native. The case illustrates the operational distinction between being mentioned and being represented correctly.

    Freshness creates a related problem. A Search Engine Land account of AI reputation management describes an old story about a customer-service incident at a Midwestern grocery chain resurfacing in Google AI Overviews after the issue had been resolved. The article argues that conventional suppression is insufficient because an AI system may still retrieve and cite an older source after it has faded from prominent search positions.

    These reports reveal three separate failure modes. A source may contain a false claim, a once-accurate source may no longer reflect the current situation, or an accurate source may lack the context needed for a balanced answer. Publishing more pages does not directly resolve any of them. The corrective evidence must itself be clear, credible, current and accessible to the systems producing the answer.

    Audit questionRisk it exposesPractical response
    Which claims recur across AI products?A repeated error may be becoming entrenched.Trace the claim to its cited or likely supporting sources and correct the evidence at the source where possible.
    Which sources appear for priority queries?The brand may depend on a narrow or poorly aligned evidence base.Develop credible coverage across relevant specialist, mainstream, community and platform-hosted sources.
    Does each source reflect the current business?Old reporting or stale profile data may distort the answer.Request appropriate updates and publish dated, verifiable context about what changed.
    Do results differ by model?A strong result in one product may conceal weak or inaccurate representation elsewhere.Repeat the same query set across multiple interfaces and record claims, citations and answer changes separately.

    This approach joins reputation management with AI visibility measurement. The objective is not to erase every unfavorable source or manufacture unanimity. It is to ensure that systems have access to a sufficiently broad body of reliable evidence, while genuine inaccuracies and obsolete information are addressed transparently.

    Key takeaways

    • AI visibility depends on the sources selected to support an answer, not only on the brand’s own rankings or content.
    • Niche publishers can add audience and topical relevance even when their traffic is modest; mainstream outlets still provide complementary scale and validation.
    • Gemini, AI Overviews and AI Mode should be measured separately because reported sourcing patterns and brand selections differ.
    • Google-hosted profiles and product information can influence AI Mode visibility before a user visits a brand-controlled website.
    • Claim accuracy and source freshness must be monitored alongside mention volume because an incorrect or outdated citation can turn visibility into reputation risk.

    As AI products continue to develop distinct source preferences, durable visibility will come from maintaining evidence that travels well across systems: accurate first-party data, relevant independent coverage and timely context when the business changes. The strategic advantage will belong to brands that can see not only whether they appear, but also why a model trusts the version of the story it tells.

    References