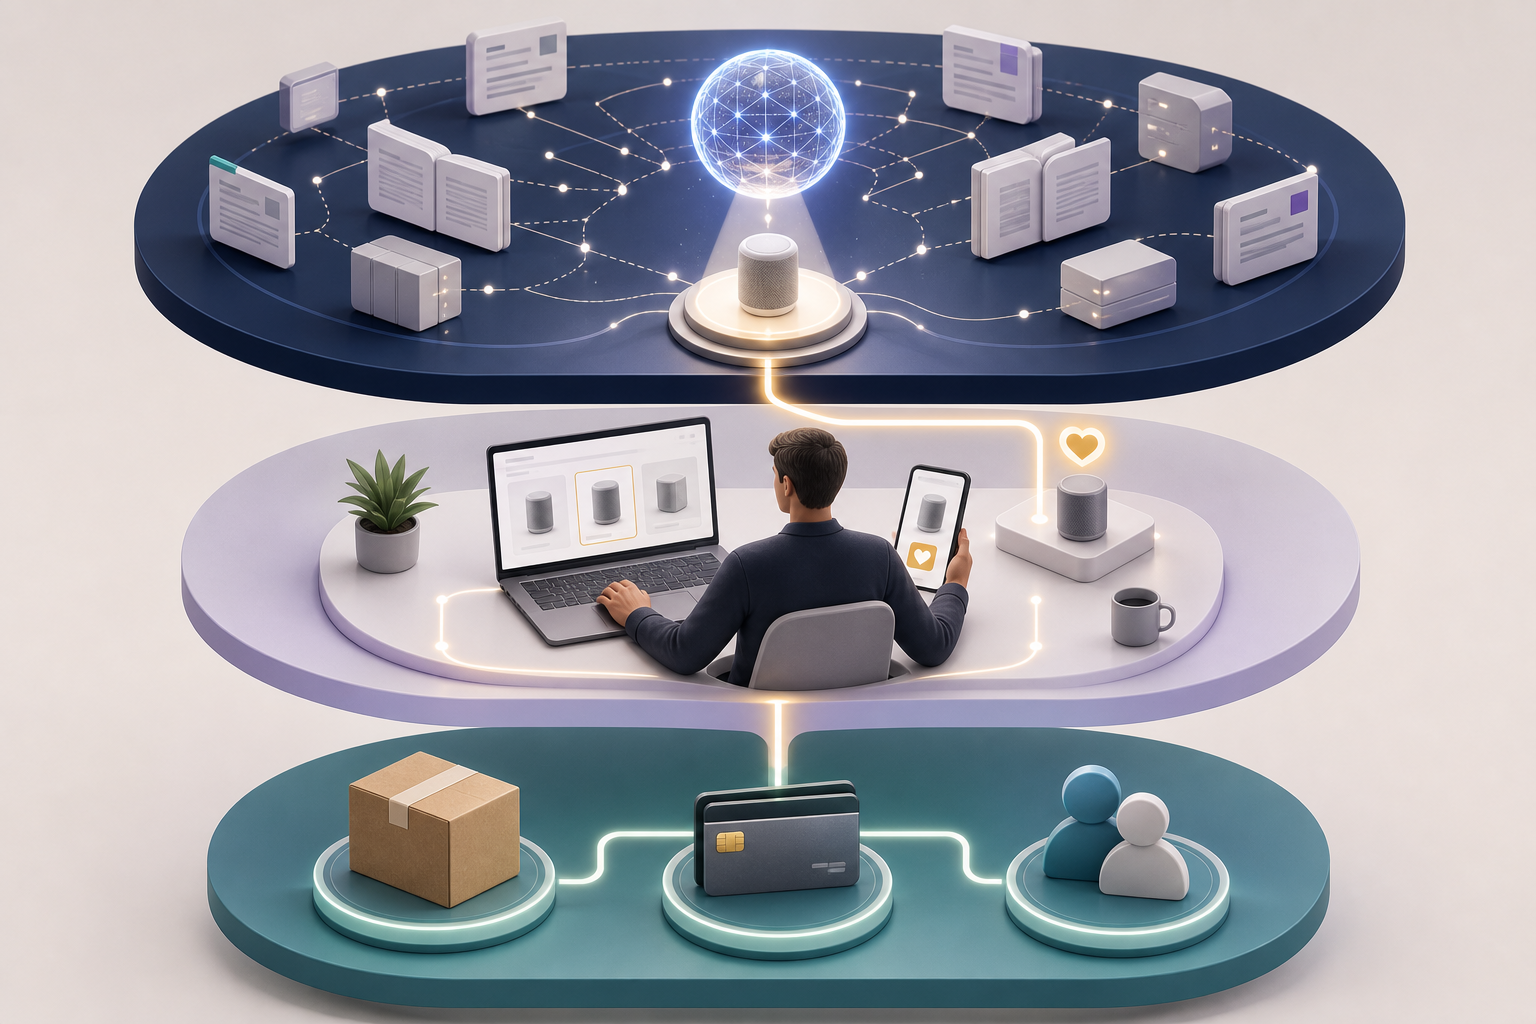
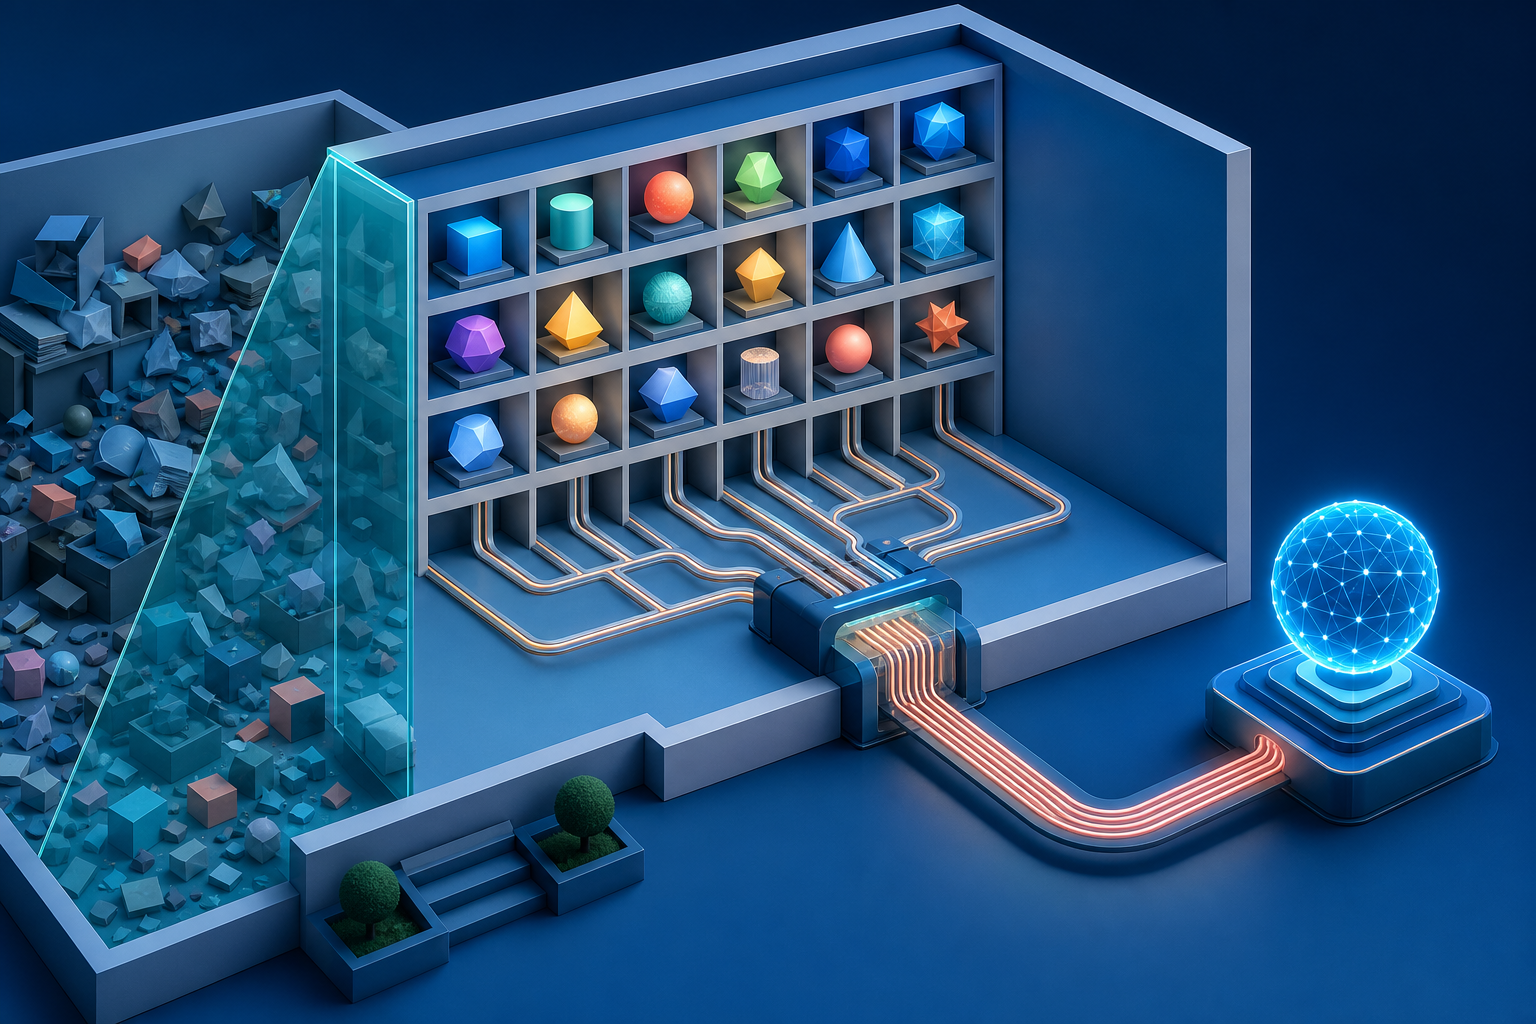
You can no longer judge a page only by whether it earns a traditional search listing. The same page may need to attract that listing, supply a direct answer, support a broader synthesis, and give a browser assistant enough clarity to help someone finish a task.
If you are deciding what to fix first, do not start with AI-only copy tactics. Map the user’s task to the search experience likely to handle it, then make the underlying facts crawlable, consistent, extractable, and usable.
The browser now routes tasks, not just queries
The familiar model of search assumes a short sequence: someone enters a query, chooses a result, and visits a page. An assistant-led browser can keep that route, replace part of it with an answer, or continue beyond the page into research and task completion.
Classify each important page by the outcome its visitor needs:
Reach a destination: The user wants a site, location, product page, service page, or other known endpoint. Traditional search visibility and accurate navigational information remain central.
Resolve a focused question: The user needs a concise fact, definition, requirement, or procedure. Build a direct-answer module for AEO.
Understand a complicated decision: The user needs relationships, conditions, alternatives, or consequences explained together. Build enough connected material for GEO.
Complete an action: The user needs to submit, book, contact, select, or prepare something. The page and its interface must remain understandable to both the person and an assisting system.
Do not assign a page to a category based only on keyword length. A short query can conceal a complicated decision, while a long query can still point to a specific destination. Write down the intended outcome, the facts required to reach it, and the step that should follow. Those three notes will tell you more than a generic label such as informational or transactional.
Key takeaways
Plan for a hybrid search environment. Traditional results, direct answers, synthesized responses, and assistant-led actions can all matter within one journey.
Technical SEO, stable entity information, and verifiable facts are shared infrastructure. They are not optional work that begins only after an AI strategy is complete.
AEO and GEO solve different retrieval problems: AEO makes a focused answer easy to extract, while GEO makes relationships and context easy to synthesize.
Browser readiness extends beyond prose. Navigation, instructions, forms, labels, and completion states must be unambiguous.
Fix inaccessible pages, conflicting facts, and unclear task paths before expanding content. More copy cannot repair an unreliable foundation.
Build the fact layer before optimizing the answer
AI search did not appear without a technical lineage. Many mechanisms associated with modern search can be traced to patent blueprints filed between 2007 and 2016, including work concerned with entities and verification. The practical lesson is not that you need to read every patent. It is that durable search work still depends on machine-accessible information, recognizable entities, consistent relationships, and evidence.
Create a single operational fact set
Before rewriting pages, establish the facts every surface should agree on. For a business, product, service, or named expert, that set may include the canonical name, description, role, location, availability conditions, defining attributes, and relationships to other entities. Include only facts you can maintain.
Then compare that set with the visible page, title and headings, internal links, structured data, profile pages, and any local or commercial landing pages you control. A disagreement is more important than a missing adjective. If one template calls an offering a product, another calls it a service, and the schema describes something else, a machine has to reconcile a conflict you created.
Check the four controls every page depends on
Discovery: Confirm that the page can be reached through ordinary links and that its important content is available to the systems you expect to retrieve it. An orphaned or inaccessible answer is not an AI optimization opportunity.
Identity: Name the main entity consistently. Use clear relationships between the organization, people, products, services, locations, and topics represented on the page.
Information structure: Give each section a descriptive heading, place the answer near the question it resolves, and keep qualifications beside the claim they modify.
Evidence: Connect important claims to specific, trustworthy support. A link should help verify the claim beside it, not merely point to a generic homepage.
Apply the same controls whether the site uses a traditional CMS or a headless architecture. A headless frontend can still hide essential content from retrieval, and a conventional CMS can still generate contradictory templates. Architecture changes where you inspect the problem; it does not remove the problem.
JSON-LD belongs in this fact layer. Use it to express the same entities and relationships that a visitor can verify on the page. Do not use structured data as a second, invisible version of the business. Schema cannot make conflicting visible content trustworthy, and it should not introduce claims the page itself does not support.
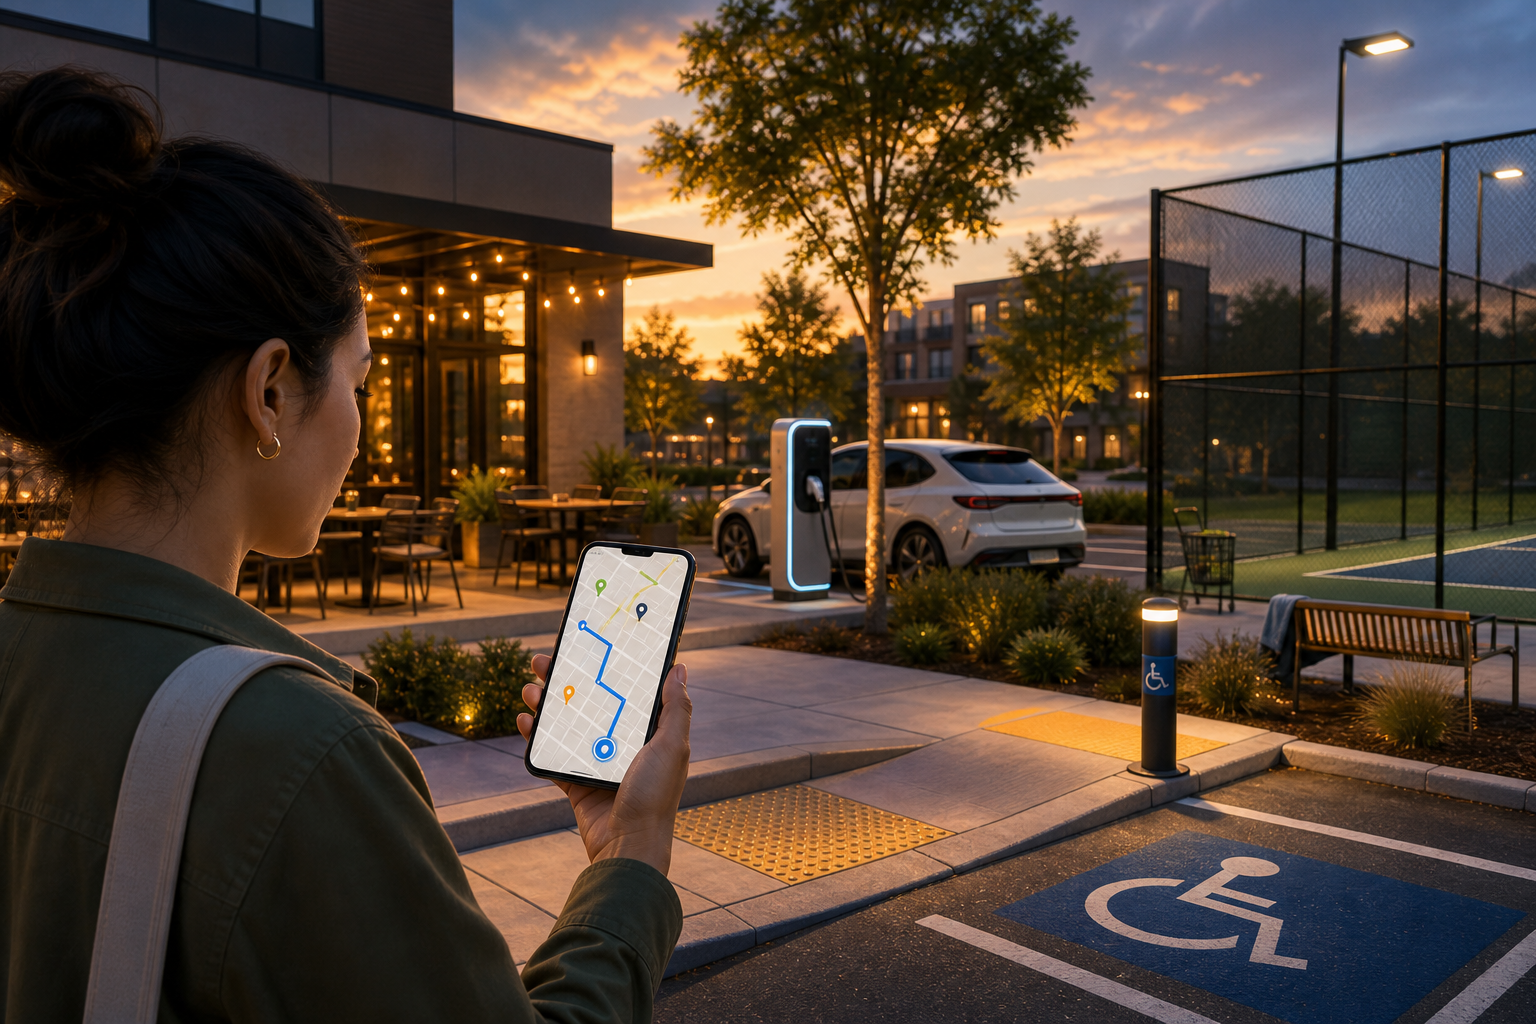
A customer no longer has to search for a broad category such as a restaurant, charging point, or tennis court. They can describe the whole situation: what they need, where they need it, which constraints matter, when they plan to go, and what they want to do next.
If your business is technically present on Google Maps but its listing does not answer those details, it may be difficult to match with that request. Preparing for Google Ask Maps is therefore less about adding more keywords and more about making your business accurate, specific, credible, and easy to act on.
Ask Maps matches a situation, not just a search phrase
Hard constraints: features or conditions that must be present.
Context: preferences, urgency, companions, or the purpose of the visit.
Time: whether the place must work tonight, during a journey, or at another relevant moment.
Location: nearby, in a particular area, or along an existing route.
Action: getting directions, making a reservation, saving a place, or sharing it.
That is a different optimization problem from trying to rank for a short phrase such as vegan restaurant near me. The useful question is no longer only, Does Google know our category? It is also, Can Google determine which real-world situations we fit?
A practical way to evaluate your local presence is to use four recommendation gates:
Eligibility: Is this actually the type of place or service the person requested?
Fit: Does it satisfy the stated location, timing, amenity, preference, or route constraints?
Confidence: Are the relevant facts consistent, current, and supported by useful customer context?
Actionability: Can the person complete the next step without encountering a broken link, unavailable option, or contradictory information?
Eligibility gets you into consideration. Fit and confidence help distinguish you from other eligible businesses. Actionability determines whether the recommendation can become a visit, booking, call, or direction request.
Personalization adds another layer. Ask Maps can use a person’s search and save history, so two people may receive different recommendations for similar questions. It can also surface route information, directions, estimated arrival details, and tips informed by a community of more than 500 million contributors. There is no single universal Ask Maps position that every customer will see.
Make your Maps profile answer the customer’s next question
Your Google Maps presence should do more than identify the business. It should resolve the follow-up questions a customer would normally ask before choosing it. Start with the facts you directly control, then examine the customer-generated context surrounding them.
Audit the facts you control
Confirm the canonical identity. Use the real business name, primary category, address or service area, phone number, and official website. Do not add promotional phrases or location keywords to the business name.
Describe the actual offer. Select the most accurate categories and complete the applicable product, service, menu, or description fields. A broad category may establish eligibility, but specific services help establish fit.
Keep availability dependable. Check regular hours, special hours, appointment requirements, and temporary changes. A recommendation for tonight is only useful if the customer can rely on the availability shown.
Complete relevant attributes. Record supported amenities, accessibility information, reservation options, service modes, and other fields available for your business type. Do not select an attribute merely because customers search for it.
Verify every action path. Test the website, call, directions, menu, ordering, and reservation links visible on the listing. The landing page should open the relevant location or service rather than forcing the customer to start again.
Use current, representative media. Photos should help a person verify the entrance, environment, products, facilities, or amenities that affect the decision. Remove or replace media you control when it no longer represents the experience.
Focus on decision-changing facts. A public tennis facility, for example, should make lighting, access, availability, and reservation requirements clear wherever the applicable fields allow it. A restaurant should not stop at its cuisine category if dietary suitability, booking, service mode, or opening hours are the details that determine whether it fits a request.
Do not hide a qualification. If an amenity is available only in part of the venue, during limited hours, or by prior arrangement, state that plainly on the website and in any profile field that can represent it accurately. A precise limitation is more useful than an attractive claim that produces a failed visit.
Build useful review context without scripting customers
Reviews can add real-world context that controlled business descriptions cannot. They may reveal which services people used, what conditions they encountered, and which details mattered during the visit. That makes a healthy body of honest, specific reviews more useful than a collection of repetitive compliments.
Ask customers for an honest account of their experience, not a required keyword or prewritten sentence. Neutral prompts such as What was most useful about your visit? or Is there anything another customer should know before arriving? leave the substance with the reviewer. Never manufacture reviews or ask people to claim they used a service they did not use.
Read reviews as a data-quality queue. When several customers mention confusing parking, an outdated menu, inaccessible directions, or a service that is difficult to locate, correct the underlying information. If a review contains a factual mistake, respond calmly with the accurate detail and update your controlled pages if the confusion is understandable.
There is no dependable Ask Maps threshold for a particular review count or rating. Treat reviews as evidence and customer feedback, not as a number you can mechanically convert into conversational visibility.
Keep your profile, website, and JSON-LD consistent
Your Maps listing, visible website content, and structured data have different jobs. They should describe the same business reality without being identical copies of one another.
Information layer
Primary job
What to include
Common failure
Google Maps and Business Profile
Provide immediate local facts and actions
Identity, category, location, hours, applicable attributes, contact details, and booking or direction paths
Incomplete fields, stale hours, duplicate listings, or broken actions
Location page
Explain details that require context
Services, restrictions, amenities, arrival instructions, availability, policies, and a clear next step
Generic copy that does not answer location-specific questions
JSON-LD
Restate supported facts in a machine-readable form
Business type, name, URL, telephone, address, hours, and relevant supported properties
Markup that conflicts with visible content or describes unavailable features
Customer reviews
Describe observed experiences
Unscripted details about actual visits, services, conditions, and outcomes
Manipulated, repetitive, irrelevant, or unanswered feedback
Use a dedicated page for each real location. The page should identify what is offered there, where it is, when it is available, which important constraints apply, and how the visitor can act. A generic corporate page that merely lists city names gives both customers and machines little evidence about the individual location.
Write nuanced facts in visible page copy before trying to encode them. If evening access ends earlier than the venue’s general opening hours, explain that limitation where a visitor can see it. Structured data should support visible, accurate information rather than introduce a more favorable version of the business.
For JSON-LD, choose the most specific LocalBusiness subtype that accurately represents the location. Common factual properties include name, url, telephone, address, and openingHoursSpecification. Add business-specific properties only when they apply and are supported by the page. Restaurant properties such as servesCuisine, menu, and acceptsReservations, for example, should not be copied into unrelated business types.
Do not promise that adding LocalBusiness JSON-LD will earn an Ask Maps recommendation. Schema can make website facts explicit; it cannot prove that Gemini will select the business for a personalized request. Treat structured data as corroboration and entity clarification, not as a hidden command to the recommendation system.
Consistency matters more than repetition. If Maps shows one closing time, the location page shows another, and JSON-LD contains a third, the solution is not to choose the most SEO-friendly version. Determine the real operating time, correct every controlled surface, and establish one internal source of truth for future updates.
Avoid creating thin pages for every conceivable conversational query. One detailed location page can answer many situations when it organizes accurate information clearly. Separate pages make sense when the underlying offer, place, audience need, or conversion path is genuinely distinct.
Test scenarios instead of chasing one Maps position
Conventional rank tracking asks where a business appears for a fixed keyword at a fixed point. Ask Maps requires a broader test because wording, timing, route, location, and personal history can change the answer. Your objective is to find out whether Google understands the situations your business can truthfully satisfy.
Build prompts from actual customer decisions using this pattern:
intent + hard constraint + time or context + location or route + desired action
A recreation venue might test a request for a public court with lighting that can be used in the evening. A restaurant might test a dietary preference, neighborhood, reservation requirement, and arrival time in the same question. A route-based business might test whether it is a suitable stop without forcing the traveler to leave the planned journey.
Use scenarios that reflect profitable or strategically important customer needs, but keep every constraint truthful. There is little value in being considered for a high-intent request that the location cannot reliably fulfill.
Write down the exact question. Small wording changes can alter which constraint receives the most weight.
Record the test context. Note the location, time, route context, device, and relevant search or save history rather than treating the response as neutral.
Capture the complete result. Record which businesses appear, which facts the answer cites, which pins are shown, and which actions are offered.
Check factual accuracy. Look for wrong hours, missing services, mistaken attributes, outdated links, or ambiguity about the correct location.
Trace each issue to a controlled surface. Correct the Maps profile, location page, structured data, booking flow, or internal operating record responsible for the gap.
Retest under comparable conditions. Treat movement as directional evidence, not proof that a single edit caused a universal ranking change.
Maintain an observation log with the query, context, recommendation set, cited details, available actions, factual errors, and changes made. This produces a more useful record than a screenshot labeled only with a rank.
Classify what you see before deciding what to change:
If the business is absent and a required fact is missing, complete or correct that fact first.
If the business appears for a poor-fit scenario, look for an overly broad category, ambiguous service description, or outdated customer-facing information.
If the business appears but the answer cites the wrong detail, repair the canonical information across controlled surfaces.
If the recommendation is accurate but the action fails, fix the booking, calling, website, or directions path before doing more visibility work.
If the profile is accurate and the business still does not appear, do not invent a feature or manipulate reviews. Continue improving legitimate local evidence and assess the pattern across several relevant contexts.
Measure business outcomes conservatively. Direction requests, calls, reservations, visits, and location-page conversions matter, but do not label every change as Ask Maps traffic unless the available analytics actually identify it. Recommendation inclusion, factual accuracy, and working actions are useful leading indicators; completed customer actions are the outcome.
Key takeaways
Optimize for customer situations, not isolated local keywords. Ask what intent, constraints, context, timing, location, and action a recommendation must satisfy.
Make the Maps profile operationally complete. Accurate hours, categories, attributes, service details, and action links determine whether a recommendation remains useful.
Encourage honest, specific reviews without scripting customers. Use recurring confusion in reviews to improve controlled business information.
Keep the Maps listing, location page, and JSON-LD aligned with one real source of truth. Schema should clarify supported facts, not promise selection.
Test realistic prompts and record personalization context. An Ask Maps response is an observation under particular conditions, not a universal rank.
Fix failed actions as seriously as missing visibility. A recommendation that leads to an unavailable service or broken booking path does not serve the customer.
Start with the highest-value situation your location genuinely serves. Write the customer’s full question, inspect whether your profile and location page answer every constraint, correct the first material gap, and test the scenario again. That turns Ask Maps optimization into a manageable data-quality practice rather than a guessing game about AI.
Your Google Business Profile is accurate, your location page is live, and you rank for at least some local searches. The uncomfortable question is what happens when a potential customer asks Google an open-ended local question and receives an AI-generated answer instead of a familiar list of links.
The practical response is not to chase a separate set of AI keywords. Make your business identity easy to verify, keep every important fact consistent, and publish enough location-specific information for an answer system to understand when your business is relevant. That work supports local packs, conventional results, AI Overviews, and other AI-assisted discovery without betting your strategy on one interface.
Local AI visibility starts with a resolvable business identity
That distinction matters because local AI optimization is not simply another ranking exercise. A system may need to establish that your business exists, determine where it operates, understand what it offers, and decide whether the evidence is strong enough to include in an answer. Schema can make facts explicit, but it cannot turn conflicting information into reliable information.
You should also avoid treating every Google AI experience as the same destination. Google Search is oriented toward information, engagement, and connections to the web, while Gemini is positioned more as an assistant for productivity and creation. Those products share technology but follow different objectives, and their eventual degree of convergence remains unsettled. Build facts that can travel across systems instead of optimizing around a guessed interface.
Key takeaways
Treat local visibility as an entity-confidence problem before treating it as a content-volume problem.
Create one approved record of your business name, location, contact details, hours, services, and service area.
Make visible page content, Google Business Profile data, citations, reviews, internal links, and structured data tell the same story.
Use schema to confirm facts that people can also see on the page, not to introduce a more convenient version of the business.
Measure factual accuracy and visibility separately across standard search, local results, AI Overviews, and Gemini.
Write a canonical local fact sheet before editing schema
Most consistency problems begin inside the business. The website owner has one phone number, the operations team has another, and an old directory still lists the number used before a move. A schema plugin then reproduces whichever version happened to be entered during setup.
Create a canonical fact sheet for each location. This is an internal operating record, not marketing copy. Give one person or team responsibility for approving changes, then use the record whenever you update the website, profiles, directory listings, or structured data.
Identity: Record the customer-facing business name, the most accurate primary business category, and a short factual description of the operation.
Location: Distinguish a staffed customer-facing location from an office, headquarters, mailing address, or service area. Do not let one address imply a function it does not have.
Contact details: Choose the public phone number, canonical location-page URL, and any official appointment or enquiry URL.
Availability: Record normal operating hours and identify services that follow different schedules. If customers can visit only by appointment, say so in visible language.
Offerings: Use the service names customers will see on the website and confirm which location actually provides each one.
Geographic scope: List the areas the business genuinely serves. Keep a service area distinct from an address and from places you merely hope to target.
Official profiles: Maintain the URLs of the Google Business Profile and other profiles that clearly represent the same business entity.
Resolve ambiguity instead of encoding it
A fact sheet is useful only if it contains decisions. If the storefront sign, website header, and profile use different names, do not copy all three into different schema fields. Decide which customer-facing identity is correct, determine whether the alternatives still serve a legitimate purpose, and plan a coordinated correction.
Apply the same discipline after a relocation, rebrand, acquisition, phone-system change, or adjustment to opening hours. Old information is not harmless just because it appears on a low-priority page. It can still create another version of the entity for machines and customers to reconcile.
Do not place aspirational claims on the fact sheet. A city you want to enter is not yet a service area. A service you plan to launch is not an available offering. A shared building is not evidence of a customer-facing branch. Structured data should describe the operation customers can actually use.
Align every place Google can compare
Once the canonical record is approved, audit the surfaces that can confirm or contradict it. Work from high-consequence identity facts down to descriptive enhancements. A wrong address, closed status, or phone number can block a customer journey; a less-than-perfect description usually does not deserve priority over those failures.
Signal
What to inspect
Common conflict
Corrective action
Visible website content
Header, footer, contact page, location page, service pages, and booking instructions
The footer shows current hours while an old contact page shows a previous schedule
Update the reusable template and every page that states the fact
Internal links and site structure
Navigation, location finders, breadcrumbs, service links, and XML sitemap entries
Current pages still point to a retired location URL
Link to the canonical live location page and remove obsolete paths from normal navigation
Google Business Profile
Name, category, address or service area, phone, hours, website URL, and listed services
The profile and website describe different operating scopes
Correct the underlying business record, then update both surfaces from it
Citations and directories
Prominent industry, regional, and customer-facing listings
An old brand, address, or phone number remains active
Correct the profiles most likely to be encountered or reused, keeping the same canonical facts
Reviews and reputation context
Recent customer language and references to a location, brand, or service
Customers continue to refer to a former name or location
Do not rewrite customer reviews; clarify the transition on properties the business controls
Structured data
Rendered JSON-LD, not only the fields displayed in a plugin dashboard
A theme or second plugin emits an outdated duplicate business entity
Fix the generating component and leave one coherent representation of each entity
Do not turn consistency into a demand that every description be word-for-word identical. A directory may need a short category label while a service page needs a detailed explanation. The facts must agree even when the wording and level of detail differ.
Audit from the customer’s point of view as well as the database owner’s. If one page says a branch is open but its booking link offers no way to select that branch, the site is making two operational claims. Fix the journey, not just the sentence.
Use LocalBusiness schema as a confirmation layer
LocalBusiness structured data converts important business facts into explicit relationships and properties. Its value is clarity: it can help a machine distinguish the entity’s name from a page heading, the business address from a publisher address, and the location URL from a general site URL. In AI-assisted local search, that clarity helps reduce uncertainty about who the business is, what it does, and where it operates.
It is not a private channel for claims that the visible page cannot support. If the page says the office closes at one time and openingHoursSpecification says another, the markup has created a conflict. If areaServed lists places the page never discusses and the business does not genuinely serve, the markup is not providing stronger optimization; it is weakening the integrity of the entity record.
Use the most specific LocalBusiness subtype that accurately represents the business. Specificity is useful only when it is true.
Give each real location a stable page URL and a stable @id so repeated references can point to the same entity.
Match name, url, telephone, address details, and opening hours to the approved record and visible page.
Add areaServed only for genuine service coverage. Do not use it as a list of geographic keywords.
Use sameAs for official profiles that represent the same entity, not for any page that happens to mention the business.
Include only properties your team can keep current. More markup creates more maintenance obligations.
Inspect the rendered output after theme, plugin, template, or location-data changes. A correct admin form does not prove that the live page emits one correct graph.
Keep multi-location entities separate
A multi-location organization should not collapse every branch into one ambiguous local entity. Give each genuine location its own visible facts and structured-data identity, then connect it to the parent organization where that relationship is accurate. This lets a system answer a local question with the appropriate branch instead of inheriting a headquarters address, organization-wide phone number, or service that is unavailable locally.
The same caution applies to practitioners operating inside a larger business. Represent a practitioner, department, location, and parent organization as distinct entities when they are distinct in the real world. Do not merge them merely because one plugin form is easier to complete.
No schema property guarantees a local ranking, an AI citation, or inclusion in an AI Overview. The useful test is narrower: does the markup make the correct business easier to identify without disagreeing with the rest of the web presence?
Create answerable local pages, then keep them synchronized
Consistency helps a system trust a fact, but it does not establish relevance to every local question. Your location pages must also explain the decisions customers are trying to make. A page containing only a business name, map, phone number, and generic brand copy identifies a place but says little about why that place fits a particular need.
Write for local decisions
Start the page with a plain statement of what the location provides and where it provides it. Then answer the questions that materially change whether someone can use the business.
Which services are available at this location, and which are not?
Is the address a place customers can visit, or does the business travel to them?
What geographic area does the team actually serve?
Are there appointment, access, delivery, or availability conditions a customer needs to know before acting?
What should a customer do next: call, book, request a quote, visit, or choose another location?
Which page provides the best supporting detail for each important service?
Use internal links to connect a location to the services genuinely available there, and connect service pages back to the appropriate locations. That structure gives people a usable path and gives machines a clearer relationship between the organization, its branches, and its offerings.
Avoid manufacturing near-identical city pages that change only a place name. They repeat a target phrase without adding evidence about local availability. If you cannot state what is operationally different or specifically useful for a location, strengthen the primary service-area or location page instead of multiplying weak pages.
Use a change protocol
Local information drifts when operational changes are handled as one-off edits. Treat every change to a name, address, phone number, schedule, service, location status, or service area as a coordinated release.
Approve the new fact in the canonical record and note when it becomes effective.
Update the visible website content, including reusable headers, footers, contact modules, and booking instructions.
Update the structured-data generator and inspect the JSON-LD rendered on the live page.
Update the corresponding Google Business Profile fields.
Correct important citations and official profiles that still expose the previous fact.
Check internal links, redirects, sitemap entries, and location finders if a URL or location status changed.
Record what was changed so a later audit can distinguish an overlooked property from a system that has not yet reflected the update.
Measure each discovery surface separately. For standard search, local results, AI Overviews, and Gemini, record whether the business appears, whether the displayed facts are correct, which page or profile is surfaced, and whether the result offers a usable next action. A correct answer with no visibility is a relevance problem. Visibility with the wrong hours or location is an entity-accuracy problem. Those failures need different fixes.
Begin with one commercially important location and one service customers regularly seek there. Approve its fact sheet, compare every major signal, repair the highest-consequence conflict, and only then expand the process across the rest of the business. That gives you a repeatable local AI visibility system rather than another markup project that goes stale after launch.
You have a campaign due, the platform wants more assets than your team can shoot, and an AI tool can produce the missing scenes in minutes. The production problem looks solved. The harder question arrives at approval: does the result still represent the product, the customer and the brand truthfully?
You do not need to choose between using AI and being authentic. You need a governance system that distinguishes harmless assistance from consequential manipulation, preserves evidence for every claim and stops questionable work before speed turns it into scale.
Key takeaways
Authenticity is not the absence of AI. It is the absence of a misleading gap between what your marketing depicts and what a reasonable customer would believe.
Govern the output and its likely interpretation, not the name of the tool that produced it.
Give every AI-assisted asset a source record, a named approver and a defined withdrawal path before publication.
Disclosure can explain how an asset was made, but it cannot make a false product claim, invented testimonial or nonexistent result acceptable.
Use the same approved facts across ads, landing pages, product feeds, public relations, structured data and answer-engine content. Contradictory claims weaken both customer trust and machine-readable credibility.
Authenticity is a truth boundary, not a production method
A manually produced campaign can be deceptive. An AI-assisted campaign can be accurate. The relevant distinction is not human versus machine; it is faithful representation versus manufactured belief.
That distinction matters because AI can now support a wide range of creative operations, including background removal, lifestyle-scene generation, synthetic people and rapid asset variation. The resulting production capacity is useful, but technical permission is not the same as brand permission. Your policy has to decide what the audience may reasonably infer from the finished asset.
Use four questions at the creative brief, review and approval stages:
What will the audience think is real? Identify the likely interpretation, not merely the literal elements on screen. A person may understand that a decorative background is illustrative while assuming a product demonstration, testimonial or before-and-after image records a real event.
Does the synthetic element affect the decision? Color accuracy, dimensions, included features, product condition, customer identity, quoted experience and demonstrated outcomes can all influence a purchase or trust decision. Treat those elements as material.
Can the implied claim be substantiated? You should be able to trace a factual statement or visual implication to an approved product record, documented result or other internal evidence. If the evidence cannot be found, the asset is not ready.
Would knowledge of the AI intervention change the audience’s judgment? If the answer is yes, redesign the asset, disclose the intervention clearly or do both. Do not hide a consequential transformation behind a broad statement that AI was used somewhere in production.
A synthetic background behind an unchanged product may create little expectation risk. A synthetic person presented in a way that resembles a customer, employee or expert creates much more. A generated product feature that does not exist crosses the truth boundary entirely.
Disclosure belongs after this truth test, not in place of it. A label can tell someone that an image is simulated. It cannot repair an inaccurate price, fake endorsement, invented review, altered package size or performance claim that your evidence does not support. When the underlying claim could create compliance or legal exposure, pause publication and route it to the appropriate qualified reviewer. A creative approval is not a substitute for legal review.
Use a four-level integrity ladder for AI-assisted work
A practical policy needs more than a general instruction to use AI responsibly. A four-level brand integrity hierarchy gives marketers, agencies and approvers a shared way to classify work before debating individual assets.
Integrity level
Typical output
Default decision
Required control
Assistance
Resizing, cropping, cleanup, formatting or copy variation that preserves the approved meaning
Allowed within documented brand rules
Retain the original and confirm that facts, qualifications and visual product attributes did not change
Adaptation
Background replacement, contextual scenes, localization or audience variants built around a real product or approved claim
Allowed with review
Record what was synthetic, verify the product representation and decide whether the context needs disclosure
Synthesis
Synthetic people, realistic events, demonstrations or scenes that an audience could interpret as documentary evidence
Conditional and escalated
Require an accountable approver, a documented disclosure decision, substantiation for every implication and confirmation that no real person’s identity is being misrepresented
Do not publish; correct the brief or obtain valid evidence for a truthful alternative
Classify the finished output, not the software. The same generator could perform low-risk cleanup in one workflow and create an unacceptable customer simulation in another. Tool-based rules age quickly and invite loopholes; output-based rules remain understandable when platforms change their features.
Context can also move an asset up the ladder. Replacing the background behind a product is usually adaptation. It becomes more consequential if the new setting implies that the product is certified for a particular environment, fits a space it does not fit or has a capability it does not have. Likewise, a synthetic human used as decorative illustration differs from one presented beside testimonial language that implies a genuine experience.
Write examples from your own campaigns beside each level. Include one clearly allowed example, one conditional example and one prohibited example for the channels your team actually uses. Those precedents will resolve ordinary decisions faster than an abstract ethics statement.
Turn the policy into a publishing gate
A governance document does not protect the brand if approval still happens in chat threads, source files disappear and nobody can identify who accepted the risk. The control has to sit inside the publishing workflow.
Your operating policy should define:
Scope: the channels, teams, contractors, agencies and asset types covered by the policy.
Allowed uses: transformations that can proceed under standard review.
Conditional uses: outputs that require disclosure, specialist review or approval from a more accountable role.
Prohibited uses: transformations that cannot be published even when labeled as AI-generated.
Evidence requirements: the records that must support factual, comparative, visual and testimonial claims.
Disclosure rules: when a disclosure is required, where it must appear and who approves its wording and placement.
Responsibility: who creates, verifies, approves, publishes, monitors and withdraws an asset.
Exception handling: who can authorize an exception, what evidence is required and when that decision must be revisited.
Move each asset through the same evidence path
Set the truth boundary in the brief. List the product attributes, claims, qualifications and visual details that cannot change. State what may be synthesized and what the asset must not imply.
Assemble an approved reference pack. Give the creator the current product images, specifications, brand terminology, claim substantiation and required qualifications. Do not make the reviewer reconstruct the ground truth after generation.
Create within the assigned integrity level. Record the tool or production path, the original materials and the meaningful transformations. You do not need to archive every inconsequential interaction, but you do need enough provenance to reproduce the decision and investigate a problem.
Verify the rendered output. Check the actual sizes, crops, overlays, captions, product details and landing-page destination that the audience will see. A correct master file can become misleading when a placement removes a qualification or crops out context.
Approve the claim and the presentation separately. One check asks whether the underlying statement is supported. The other asks what a reasonable person will infer from the combination of words, images and placement. Passing one does not guarantee the other.
Publish with a withdrawal record. Log the channels and destinations where the asset appears. If a claim changes or an error is found, the team should know where to remove or replace every affected version.
The asset record can be compact. Capture the campaign and channel, source materials, meaningful AI transformations, claims used, disclosure decision, reviewer, approval state and publication locations. What matters is that someone other than the creator can understand why the asset was approved.
Human review is not a control by itself. The reviewer needs access to the evidence, clear authority to stop publication and enough time to inspect the final placement. A person who can only click approve is part of the production sequence, not an effective safeguard.
Paid media needs particular care because asset demand, automated combinations and placement variation can multiply one error quickly. Product imagery deserves a hard verification gate: visual inaccuracies can produce disapprovals or account risk in Merchant Center. Compare the rendered product with the approved reference, including packaging, included components, proportions, color and visible features. If the generated scene obscures that comparison, use a more faithful asset.
Exceptions should be visible and temporary. Record the business reason, risk owner, supporting evidence and condition that ends the exception. The person requesting an exception should not be its sole approver. Otherwise, deadlines will quietly rewrite your policy one campaign at a time.
Connect creative governance to SEO, AEO, GEO and PR
Authenticity problems rarely stay inside the ad account. A generated claim can reach a landing page, product feed, public-relations pitch, social caption, FAQ and structured-data field. Each copy may look defensible in isolation while the combined public record becomes contradictory.
Build a claim register as the shared layer beneath those channels. For each meaningful claim, record:
the canonical wording and any required qualification;
the internal evidence or approved public page that supports it;
the product, market and context in which it applies;
the accountable owner;
the channels where it may be used;
the disclosure or presentation restrictions attached to it;
the condition that should trigger review, correction or withdrawal; and
the structured-data properties, feed fields and content components that repeat it.
This register gives your teams one approved truth rather than several channel-specific versions. Copywriters know which qualifications must survive a short format. PPC teams know which visual implications require evidence. SEO and GEO teams know which public pages should explain and substantiate the claim. Schema implementers know which statements are safe to mark up.
Structured data should describe visible, supported content. It does not validate a claim merely because the markup is syntactically correct. If the page, product feed and JSON-LD disagree about a product attribute, fix the underlying content system instead of choosing the version most likely to attract a machine.
A citation-ready page should make the supported claim easy to identify, define its scope and keep the qualification beside it. It should also use consistent product and organization names, connect the claim to the relevant entity and avoid implying that a synthetic scene is proof. A citation can carry an unsupported statement farther; it cannot convert that statement into evidence.
Monitor governance signals that reveal process failure rather than treating campaign performance as proof that the process worked. Useful signals include assets published without complete provenance, unresolved evidence gaps, exceptions still open, corrections caused by product mismatch, platform disapprovals associated with altered creative and the time required to withdraw a faulty claim across channels.
Audit what is already live
Start with a representative set of active ads, landing pages, product feeds, social assets, PR materials and structured data. Classify each AI-assisted element on the integrity ladder. Then trace every consequential claim backward to its evidence and forward to every place it appears.
Prioritize assets with realistic people, demonstrations, testimonials, product alterations or purchase-critical details. If you cannot identify the source fact, the approving person or all publication locations, you have found a governance gap. Pause the highest-risk asset, establish the missing record and use that case to write the first concrete rule in your policy.
For your next campaign, define the prohibited transformations in the brief, assign the integrity level before production and name the approver before generation begins. Once those decisions become routine, AI can increase creative capacity without multiplying ambiguity about what your audience is being asked to believe.
If ChatGPT recommends your brand but analytics reports no AI conversions, you do not necessarily have a performance problem. You have a measurement gap. A buyer can use AI throughout their research and still enter your site through Instagram, branded search, a bookmark, or a direct visit.
Your job is to separate three questions that dashboards tend to collapse: Can AI find and describe your brand correctly? Does that information help a buyer shortlist you? Does the influence produce a commercial result? Once you measure those separately, you can improve visibility without mistaking every mention for revenue.
Visibility is not attribution, and neither is trust
Generative engine optimization, or GEO, aligns your brand and content with the way answer engines retrieve, summarize, cite, and recommend information. That makes visibility a useful leading indicator. It does not make visibility the final business outcome.
Visibility asks whether your brand appears for a relevant prompt, which pages are cited, and how prominently the brand is presented.
Representation asks whether the answer gets your name, offer, audience, capabilities, limitations, and differentiators right.
Influence asks whether the answer changed a buyer’s shortlist, confidence, objections, or decision.
Attribution connects that influence to a lead, purchase, renewal, or another business result with an explicit level of confidence.
Trust determines whether a buyer accepts the recommendation. It must be earned with evidence; it cannot be inferred from an appearance alone.
This distinction matters because appearing in an answer can be surprisingly easy. Self-promotional pages placing their publisher first on a best-provider list have surfaced quickly in AI recommendations. That demonstrates retrievability, not independent authority or buyer confidence. A screenshot of the result is therefore evidence that an answer engine found the page. It is not evidence that a prospect believed it, clicked it, or bought anything.
Prompt-tracking totals also require restraint. API responses and answers shown to real users can differ sharply; one comparison found overlap as low as 24% in some cases. Interfaces can vary by model, account state, location, available retrieval, and the wording or history of a conversation. Use automated tracking to find patterns, but verify commercially important prompts in the live products your buyers actually use.
A practical AI-search scorecard should consequently report accuracy and influence beside visibility. If the brand appears often but is described incorrectly, you have exposure without control. If qualified prospects repeatedly name AI as a decision aid despite few referral clicks, you have influence that last-click analytics cannot see.
Measure the journey at the answer, buyer, and business layers
No single tool can measure AI-search attribution end to end. The answer may be generated before a visit, the visit may occur through another channel, and the commercial effect may appear as a shorter evaluation rather than an extra conversion. Build one evidence chain from three layers instead.
Inspect the answers buyers are likely to see
Start with prompt families tied to real decisions, not a long list of ways to ask for your brand by name. Branded prompts test whether AI knows you; unbranded and comparative prompts test whether it would introduce you when a buyer has not chosen a vendor.
Problem discovery: How can I solve [specific problem]?
Category selection: What type of product or provider is suitable for [use case]?
Shortlisting: Which providers should I consider for [need and constraint]?
Comparison: How do [brand] and [alternative] differ for [use case]?
Risk validation: What are the limitations, implementation requirements, or reasons not to choose [brand]?
Brand facts: Does [brand] provide [capability], work with [system], or serve [audience]?
Test the same core prompts in the live interfaces relevant to your market, such as ChatGPT, Perplexity, Gemini, and Google AI Overviews. Record the exact prompt, interface, model when visible, account state, date, answer, cited URLs, and follow-up context. Do not quietly rewrite a prompt until your brand appears; that measures your ability to steer a test, not ordinary buyer discovery.
For each answer, capture whether the brand was mentioned, recommended, cited, or omitted. Then score factual claims individually. Mark a claim as accurate, incomplete, outdated, unsupported, or wrong. Preserve the answer itself so that a later correction can be compared with a real baseline.
Ask buyers about discovery and influence separately
A single form field asking how someone heard about you cannot represent a multi-channel decision. The place where a buyer first encountered the brand may differ from the place that validated it. Ask two separate questions:
Where did you first hear about us? This preserves the discovery channel.
What helped you decide to contact or buy from us? This captures influence during evaluation.
Allow more than one response to the second question and include an AI assistant option. Keep a free-text field because buyers may name ChatGPT, Perplexity, Gemini, Grok, Google AI Overviews, or simply say they asked AI. If they remember it, ask what they wanted to learn. The prompt topic is often more useful than the platform name because it reveals the decision or objection your content helped resolve.
Do not force the buyer to choose between AI, search, social, email, and word of mouth when several played different roles. Store discovery source and decision influence as separate CRM properties. Preserve the buyer’s own wording in a note rather than translating every answer into a generic AI lead label.
Look for commercial effects beyond referral traffic
AI can summarize alternatives, reduce uncertainty, and help form a shortlist before the buyer visits a vendor. Its commercial contribution may therefore appear in the sales process rather than the acquisition report. Compare AI-influenced opportunities with other qualified opportunities on:
Time from qualified lead to the next meaningful stage.
Time from qualified lead to closed outcome.
How much basic education the buyer needs.
The number and type of objections raised.
Whether the buyer arrives with a shortlist already formed.
Conversion by stage, deal value, and final outcome.
The content or claim the buyer cites as reassurance.
Business observations have found that some AI-influenced leads needed less education and closed faster. Treat that as a hypothesis to test in your own pipeline, not a universal benchmark. A shorter sales cycle might reflect AI-assisted preparation, but it could also reflect deal type, buyer seniority, budget, or an existing relationship.
Measurement layer
Evidence to capture
Question it can answer
What it cannot prove alone
Answer
Live outputs, citations, factual accuracy, recommendation language, competitor context
Can the system find and represent the brand?
Whether a buyer saw or trusted the answer
Buyer
Discovery response, decision-influence response, named assistant, remembered question
Did AI-influenced opportunities behave differently?
That AI caused the difference without controlling for other factors
Apply confidence labels instead of pretending every signal is deterministic. Mark attribution as confirmed when the buyer explicitly names AI’s role, supported when self-report and sales evidence agree, and possible when you only see an indirect pattern such as rising branded demand. Keep possible influence out of confirmed revenue totals.
Give AI a canonical record of your brand
Measurement tells you where the brand is missing or distorted. Correction requires a dependable record that retrieval systems can access and reconcile. Without specific evidence, an AI system may fill gaps from generic category patterns, scattered third-party descriptions, or outdated pages. That failure is often called brand drift.
Do not treat a canonical record as one oversized About page. Build a controlled set of public pages and media in which every important claim has a clear home, a responsible owner, and a visible update path.
Create a brand-facts register. Record the official name, offer, intended audience, primary use cases, supported capabilities, known constraints, service area, public pricing conditions, integrations, and expert identities. Add the canonical URL and owner for every fact.
Resolve contradictions before publishing more content. Check product pages, help content, business profiles, executive biographies, video transcripts, partner listings, and public profiles. If several versions of a claim remain live, an answer engine has no reliable way to know which one you prefer.
Assign facts to decision-focused pages. Give capabilities, limitations, comparisons, implementation requirements, policies, and expert credentials their own clear context. Put the direct answer near the start, then provide evidence and qualifications.
Make entity relationships explicit. Use applicable Schema.org types such as Organization, Product, Service, Person, ProfilePage, and VideoObject. Connect the organization, offer, author, expert, and media with consistent identifiers and relevant properties. Structured data must match visible content; markup cannot rescue an unsupported claim.
Maintain the record. When an offer changes, update the canonical page, structured data, transcript, profiles, and sales material as one release. Leaving the old version on a high-authority page invites the error to return.
Use video when the claim benefits from observable evidence
Text is appropriate for definitions, specifications, and policies. Video becomes especially useful when a buyer needs to see a real product, process, location, result, or subject-matter expert. It combines spoken explanation, visual context, and a transcript, creating a dense record that can be republished without changing the underlying claim.
Plan the recording around likely misrepresentation. If AI repeatedly invents a feature, have the responsible expert show what the product actually does, state the boundary plainly, and explain the correct workflow. Publish the video on a relevant canonical page with a descriptive title, an edited transcript, speaker identity, supporting links, and VideoObject markup. A transcript should preserve qualifications rather than turning a careful explanation into an absolute promise.
Where your production workflow supports it, retain C2PA-compatible Content Credentials and editing history. Cryptographic provenance can help establish where media came from and whether its recorded chain has been altered. It does not prove that every statement in the media is true, so pair provenance with named expertise, visible evidence, and claims a buyer can verify.
Repurpose the same evidence into an article, short clips, images, audio, FAQs, and social posts. Keep the central facts and qualifiers consistent across formats. The purpose is not to manufacture a larger content count; it is to give retrieval systems several accessible paths back to the same coherent brand record.
Build the evidence that earns a recommendation
Accuracy can make your brand eligible for consideration. Evidence makes it defensible to recommend. This is where self-authored best-provider pages reach their limit: they can state a position, but the publisher and beneficiary are the same entity.
Build content around the questions a cautious buyer asks after discovery. The strongest page is not always the one that praises the brand most. It is often the one that makes the decision criteria, tradeoffs, and evidence easiest to inspect.
Selection criteria: Explain how a buyer should evaluate the category before naming products. Define the conditions that change the choice.
Use-case fit: State who the offer is for, what problem it addresses, and the prerequisites for success. Include who should choose another route.
Comparison: Use explicit criteria and equivalent evidence for each option. Distinguish verified facts from your interpretation, and date claims that may change.
Implementation: Show the required inputs, responsible roles, dependencies, and limits. This helps answer engines distinguish a real capability from an effortless marketing promise.
Proof: Connect each material claim to a demonstration, documented example, methodology, policy, or qualified expert. Avoid decorative statistics that do not prove the claim beside them.
Independent corroboration: Earn accurate reviews, mentions, citations, and expert coverage on relevant third-party properties. Correct factual errors at their origin rather than merely publishing another contradictory claim on your own domain.
Clarity is part of authority. If your homepage describes the offer with a creative slogan while product pages, profiles, and interviews use different category language, both buyers and machines must infer what you actually sell. Keep the positioning distinctive, but repeat the plain category, audience, and use case consistently wherever identification matters.
Maintain an AI-error register alongside your content inventory. For every observed error, save the prompt and answer, identify the false or missing claim, note the cited page if one appears, assign a canonical correction URL, and track the content change. Prioritize errors about core capabilities, compatibility, availability, pricing, or suitability before cosmetic wording differences. Those errors can change a purchase decision.
Retest after correction, but expect variation. A changed answer does not prove permanent removal, and one unchanged answer does not prove the correction failed. Look for a repeated pattern across live sessions and interfaces while continuing to strengthen the public evidence.
Run one operating loop from prompt to sale
AI visibility, brand accuracy, content operations, and revenue measurement should not live in separate projects. Run them as one loop attached to a real buyer decision.
Select a commercially important decision. Choose a problem, comparison, risk, or capability question that can affect whether the buyer includes you.
Capture a live baseline. Test the associated prompt family and preserve the answers, citations, omissions, and errors.
Diagnose the evidence gap. Decide whether the problem is missing information, contradictory facts, weak proof, unclear entity relationships, or inadequate third-party corroboration.
Improve the canonical evidence. Update the responsible page, visible copy, schema, transcript, media, and linked supporting material.
Distribute without changing the claim. Adapt the evidence to relevant channels while retaining the same facts and qualifications.
Retest comparable live conditions. Use the original prompts as controls, then inspect natural variations and follow-up questions.
Connect the change to buyer evidence. Review self-reported influence, sales notes, objections, stage movement, and outcomes. Do not substitute a visibility gain for a commercial result.
Record the decision. Continue, revise, or stop the tactic based on accuracy, qualified influence, and business value rather than the most flattering screenshot.
Key takeaways
AI visibility shows that a brand can be retrieved; it does not prove trust, influence, or revenue.
Verify important prompts in live interfaces because automated and API outputs may not match what buyers see.
Ask where a buyer discovered you and what influenced the decision as separate questions.
Measure sales-cycle behavior, objections, and education needs alongside clicks and conversions.
Prevent brand drift with consistent canonical facts, decision-focused pages, accurate structured data, expert evidence, and useful video.
Use confidence labels for attribution so confirmed buyer evidence is not mixed with indirect signals.
Start with one question that can put your brand on or off a buyer’s shortlist. Capture what the major live interfaces say, correct the public evidence, and add the two attribution questions to your CRM. That gives you a defensible first line from AI answer to buyer decision – and a system you can expand without pretending every mention is a sale.
You’ve got a healthcare AI announcement in front of you and a decision to make: is this a meaningful advance, a promising demonstration, or a polished claim that has outrun its evidence? The model’s reputation won’t answer that question.
You need to connect the technology to a care task, the care task to evidence, and the evidence to a controlled workflow. That framework works whether you’re evaluating a product, planning adoption, writing clinical content, or deciding which claims deserve visibility in search and AI-generated answers.
The useful unit of progress is the care task
The potential of healthcare AI extends from diagnostics to patient care. That range is also why broad statements about AI transforming healthcare tell you so little. Diagnostics, documentation, scheduling, patient education, and clinical decision support are different jobs with different users, failure modes, and consequences.
Start by reducing every claimed advance to one task statement. It should identify five things:
User: Who receives or acts on the output: a patient, clinician, administrator, researcher, or another system?
Input: What information does the system receive, and where did that information come from?
Output: Does it draft text, summarize a record, flag a case, rank options, predict an event, or initiate an action?
Decision: What real decision could change because of the output?
Failure consequence: What happens if the output is incomplete, late, biased, misleading, or wrong?
For example, AI that summarizes clinician-authored encounter notes for clinician review is an assessable use case. AI that improves patient care is not. The first statement identifies a user, input, output, and review step. The second jumps directly to an outcome without showing the mechanism.
Once the task is clear, ask what actually improved. An advance might reduce the time required for a task, make documentation more consistent, identify relevant cases, expand access, or reduce avoidable administrative work. Those are separate claims. Evidence for faster drafting does not establish better diagnosis, and stronger performance on a technical evaluation does not automatically establish better patient outcomes.
This distinction should shape your language. If a system generates possibilities for a qualified professional to consider, say that. Don’t say it diagnoses. If it drafts an explanation that must be reviewed, call it a draft. Don’t describe it as patient guidance delivered independently. Precise verbs prevent a capability claim from quietly becoming a clinical claim.
Separate assistance, recommendation, and action
Healthcare AI systems can occupy very different positions in a workflow. A useful first classification is whether the system assists, recommends, or acts. This is an evaluation framework, not a regulatory classification, but it quickly exposes how much control the workflow needs.
Mode
What the AI does
Human control to verify
Claim discipline
Assists
Drafts, organizes, retrieves, or summarizes information
A person can inspect, edit, reject, and replace the output
Describe the task support, not an unmeasured care outcome
Recommends
Flags cases, ranks options, or proposes a next step
A qualified person evaluates the recommendation before it affects care
Name the intended user, decision, evaluation context, and known limits
Acts
Triggers, routes, schedules, or changes something in the workflow
The system has defined boundaries, escalation paths, and a way to stop or reverse inappropriate action
Explain exactly what is automated and where human oversight remains
Risk does not begin only when AI acts autonomously. An incorrect summary can carry an old fact forward. A fluent explanation can make uncertain information sound settled. A recommendation can attract more trust than its evidence deserves. Human review is not a meaningful safeguard unless the reviewer has the information, authority, time, and interface needed to catch a problem.
Inspect the control itself. A reviewable workflow should make the AI-generated material identifiable, preserve relevant input context, let the reviewer edit or reject the output, provide an escalation route, and record what was accepted or changed. A button labeled approve is not sufficient if the reviewer cannot see how the output was produced or cannot safely disagree with it.
The closer an output gets to diagnosis, medication, treatment, or urgent-care decisions, the more explicit these boundaries must become. Patient-facing AI must not be presented as a substitute for a qualified healthcare professional. If an output conflicts with a clinician’s instructions or a medication label, the safe next step is to contact the appropriate clinician or pharmacist rather than act on the AI response. Situations involving possible immediate harm require established local emergency channels, not another chatbot prompt.
Match every claim to its actual level of evidence
A compelling output proves that the system produced a compelling output once. It does not establish reliability, clinical usefulness, or patient benefit. To avoid that leap, place evidence on a ladder and stop at the highest rung the evaluation genuinely supports.
Capability evidence: The system can produce the intended kind of output in selected examples.
Task validation: Its outputs have been evaluated against a predefined reference, process, or reviewer judgment for the stated task.
Workflow validation: Intended users have used it under conditions that resemble the intended setting, including realistic inputs and handoffs.
Outcome evidence: The evaluation measured the patient, clinical, or operational outcome named in the claim rather than using a technical metric as a substitute.
Post-deployment evidence: Performance, failures, overrides, and changes continue to be monitored in actual use.
Each rung answers a different question. Task validation may show that a system performs a bounded function well. Workflow validation asks whether people can use that function safely and effectively. Outcome evidence asks whether the claimed real-world result occurred. Post-deployment monitoring matters because users, data, interfaces, prompts, retrieval material, and models can change after an initial evaluation.
When you inspect an evaluation, ask questions that reveal what the headline leaves out:
Which population, language, care setting, and task were represented?
What counted as success, and was that definition chosen before the results were reviewed?
What was the comparison: no tool, the existing workflow, another system, or an expert judgment?
Which failures occurred, who was affected, and which failures carried the greatest clinical consequence?
Were intended users evaluating the output, or was the system assessed only outside the care workflow?
What happens when information is missing, contradictory, unusually phrased, or outside the intended scope?
Which model, configuration, retrieval material, interface, and review process produced the result?
If those details are unavailable, treat that absence as an evidence limit. Don’t fill the gap with a stronger adjective. Promising can be appropriate for an early capability. Validated needs a stated task and context. Effective should identify the outcome that improved. Safe is usually too broad to stand alone because safety depends on the user, setting, controls, and type of failure being considered.
Keep the evaluated system distinct from the underlying model. A healthcare AI implementation may include a model, prompts, retrieval sources, interface rules, access controls, escalation policies, and human review. Changing any of those elements can change the behavior that users experience. Record them together, and retest material changes instead of assuming that an earlier result transfers automatically.
Test the workflow around the model, not just the model
A technically capable model can still fail as a healthcare system. The failure often appears at the handoff: the wrong information enters, the output reaches the wrong person, a warning arrives too late, or nobody owns the exception. Evaluate the full route from input to consequence.
Use these six gates before treating a capability as deployment-ready:
Context match: Confirm that the intended users, population, language, setting, and task resemble those represented in the evaluation.
Input control: Define which data the system may receive, how missing or conflicting information is handled, and who is responsible for input quality. Never place identifiable patient information into an AI tool that your organization has not approved for that use.
Output routing: Specify who sees the result, when they see it, what supporting context accompanies it, and whether it can alter a decision before review.
Human factors: Verify that users can understand the output’s role, identify uncertainty, disagree with it, and complete the task without becoming dependent on it.
Failure response: Decide in advance how the workflow handles false alarms, missed cases, unsupported statements, system outages, and outputs outside the intended scope.
Change monitoring: Assign an owner to watch failures, overrides, complaints, model or configuration changes, and performance drift after launch.
Run the workflow with difficult cases before routine ones create false confidence. Test missing context, ambiguous requests, contradictory records, out-of-scope questions, and attempts to bypass the intended process. The goal is not to prove that the system never fails. It is to learn whether failures are visible, containable, recoverable, and routed to someone able to respond.
Define a stop condition as well as a success condition. A responsible deployment plan says who can pause the system, which events trigger review, what work continues without it, and how affected users are notified or corrected. If nobody has authority to stop an unsafe workflow, the oversight plan is incomplete.
Publish healthcare AI claims that can survive scrutiny
Healthcare AI content has to work for a person assessing risk and for search or answer systems extracting a concise statement. Both benefit from the same thing: explicit claims with their qualifications attached. A vague page cannot become trustworthy through optimization, and structured data cannot turn unsupported language into evidence.
Put the central claim in a form that can stand on its own: the system, intended user, task, setting, oversight, and demonstrated evidence level should appear together. Put an important limitation in the same sentence or adjacent paragraph, not in a distant disclaimer that disappears when the sentence is quoted.
A useful claim pattern is: [System] helps [intended user] perform [task] in [setting]. [Reviewer or control] checks [output] before [decision or action]. Current evidence establishes [capability, task performance, workflow performance, or outcome], while [important limitation] remains unresolved.
Before publication, apply these editorial thresholds:
Can generate or summarize: Show that the capability was tested with the stated input and output. Don’t convert generation into an accuracy or outcome claim.
Supports review or decision-making: Identify the qualified user, the decision being supported, the review step, and the context in which the support was evaluated.
Improves a workflow: Name the measured operational result and the workflow used for comparison. Don’t use an isolated model score as proof of workflow improvement.
Improves diagnosis or patient outcomes: Reserve this language for evidence that measured the named diagnostic or patient outcome in the defined population and setting.
Is safe: Replace the blanket claim with the risks evaluated, controls used, limitations found, and context covered. No system is safe independently of its use.
Keep vendor, model, product, and care provider roles separate. OpenAI, Google, and Anthropic may be relevant to the underlying AI landscape, but a familiar model developer’s name does not establish that a particular healthcare implementation is clinically validated. State who built the model, who configured the system, who operates the workflow, and who is responsible for clinical review whenever those roles differ.
Your maintenance process matters as much as the launch page. Keep a claim inventory linking each public statement to its evidence, evaluated configuration, owner, review date, limitations, and correction route. When a model, prompt, retrieval source, interface, intended use, or oversight process changes, review the dependent claims. Otherwise, accurate content can become misleading while its publication date and search visibility remain unchanged.
Use schema and other machine-readable markup to describe what the visible page actually says. Keep the evidence level, intended use, limitations, author or reviewer responsibility, and update history readable on the page itself. Machines may extract the markup, but people still need enough context to judge the claim.
Key takeaways
Judge healthcare AI at the level of a defined care task, not the reputation of a model or developer.
Separate systems that assist, recommend, and act; each position requires a different degree of control and claim restraint.
Don’t treat a demonstration, task evaluation, workflow evaluation, outcome evaluation, and monitored deployment as interchangeable evidence.
Evaluate inputs, handoffs, human review, failure response, and change control alongside model performance.
Keep qualifications beside the claim so readers and AI answer systems do not receive a stronger statement than the evidence supports.
Do not present patient-facing AI as a replacement for qualified medical care, especially where diagnosis, medication, treatment, or urgent decisions are involved.
For the next healthcare AI claim you encounter, write the five-part task statement before you draft a headline, approve a tool, or publish a page. Then label the highest evidence rung it has reached. If you cannot complete either step, hold the claim at capability level until the missing context is available.
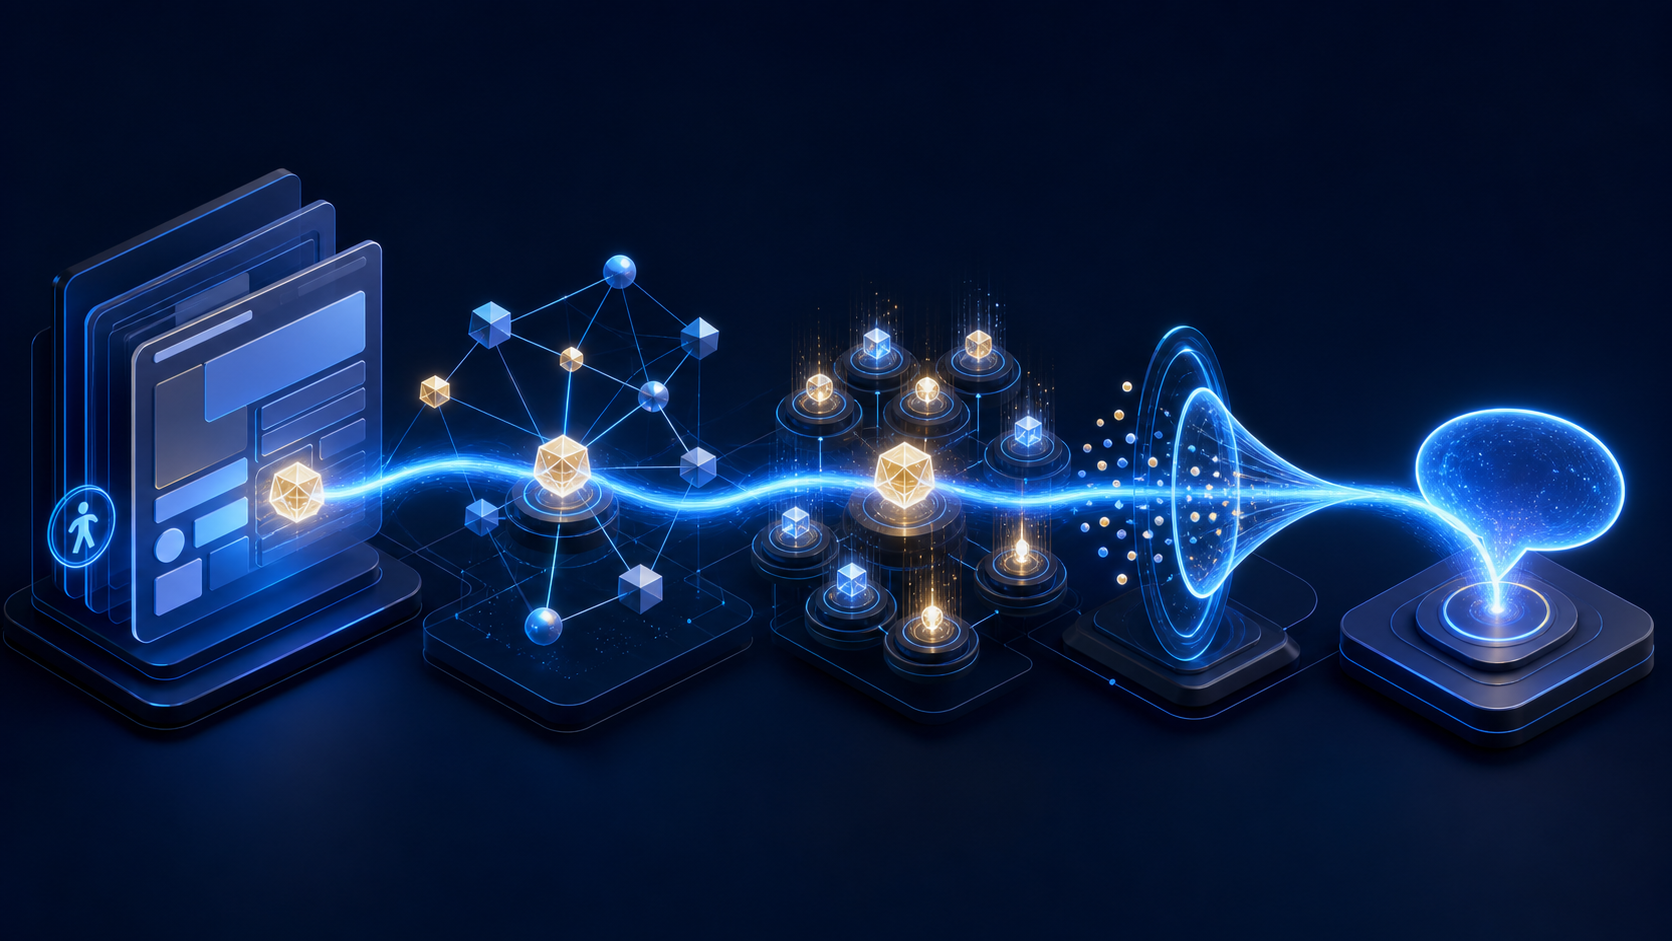
If your pages rank in Google but disappear when a buyer asks ChatGPT, Gemini, or Perplexity what to choose, you do not have a conventional ranking problem. You have a chain-of-trust problem. The assistant must be able to reach your information, understand what it means, reconcile it with information elsewhere, and decide that it is relevant and credible enough to use.
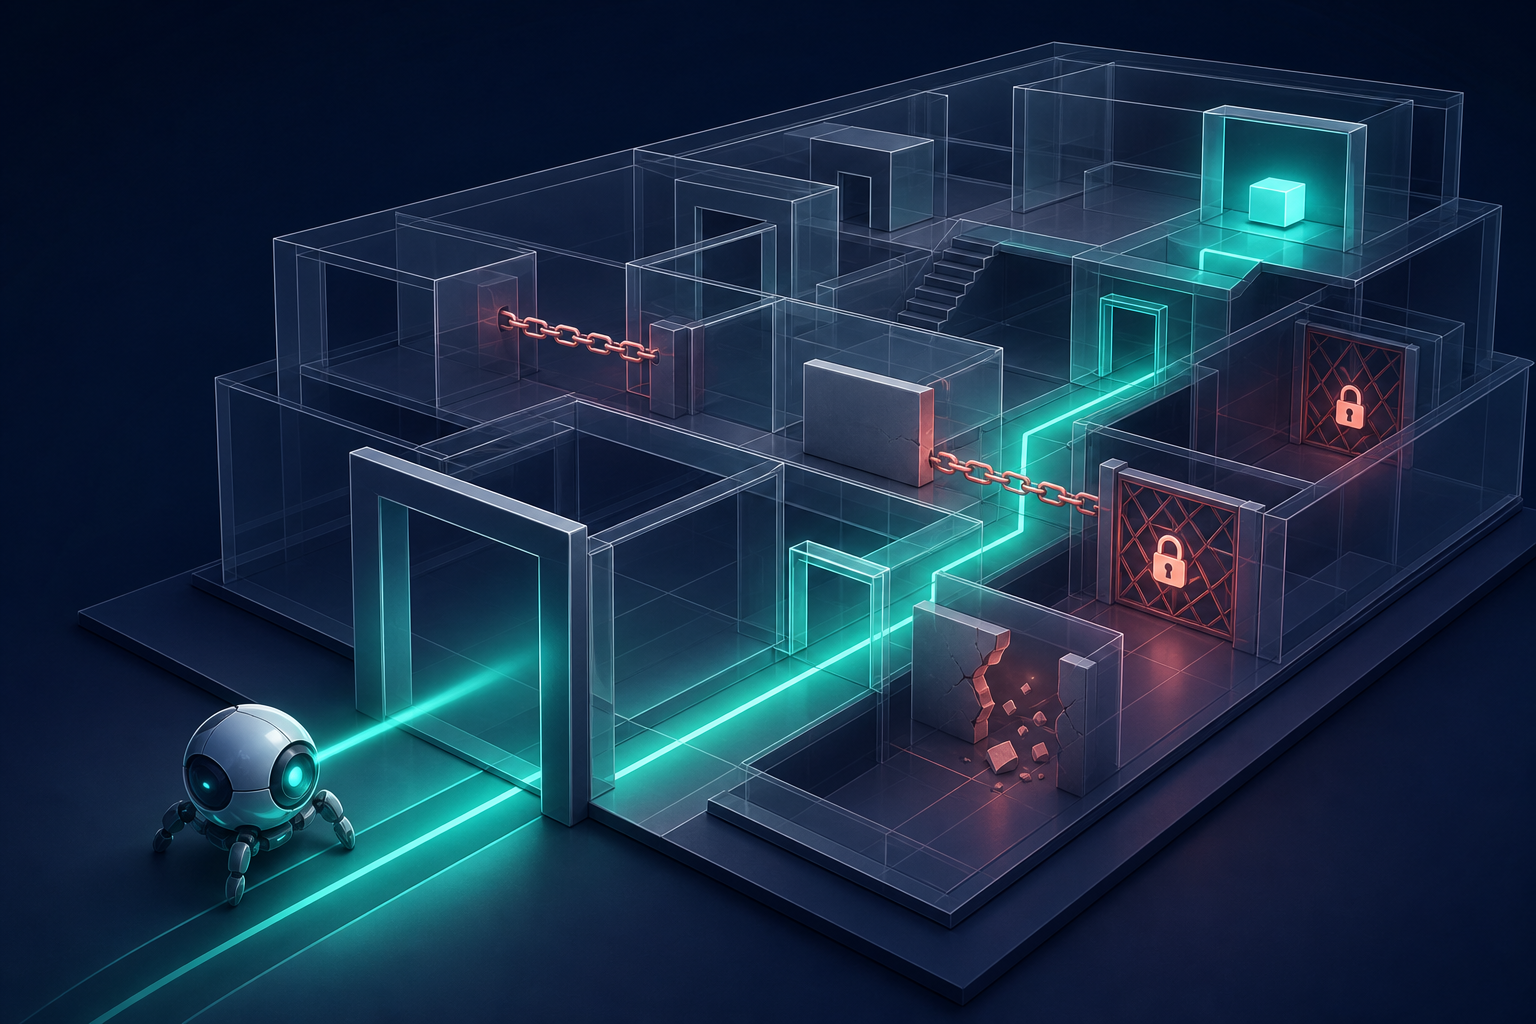
That changes where you should start. Publishing more content or adding AI-related keywords will not repair a blocked crawler, a confused business identity, or conflicting location data. Audit the full path to an AI answer, then fix the earliest point at which your visibility breaks.
AI visibility is a connected system, not a single ranking
Traditional rank tracking asks where a page appears for a query. AI search visibility covers several different outcomes: whether an assistant mentions your brand, uses your content, links to your site, states your facts accurately, or recommends you as a suitable choice. A brand can succeed at one outcome and fail at another.
A practical audit separates the system into these stages:
Access: Can retrieval systems and permitted bots reach the important public pages without being blocked by robots rules, authentication, a firewall, or a challenge page?
Interpretation: Does each page make the subject, claim, location, product, and relationship between entities explicit?
Corroboration: Do your website, business profiles, reviews, and other public records agree on the facts that matter?
Selection: Does your information answer the user’s actual task well enough to be cited or recommended?
The order matters. Better copy cannot compensate for a page that cannot be retrieved. Perfect crawl access cannot resolve two different addresses for the same location. Consistent facts do not guarantee selection when the page never answers the question behind the prompt.
What you observe
Likely bottleneck
First check
Important public pages are absent from retrieval or crawler logs
Access
Robots rules, authentication, CDN controls, and firewall challenges
Assistants state an old address, name, or service detail
Interpretation or corroboration
The canonical page and every prominent public profile carrying that fact
Your pages are cited for facts, but your brand is not recommended
Confidence or task fit
Reputation signals, comparative evidence, and whether the offer fits the prompt
Google visibility is strong while assistant visibility is weak
Selection
A separate prompt-level baseline for each assistant
Do not label every absence a crawl problem. If an assistant accurately summarizes a page but does not mention your brand, it obtained the information through some path. Your next work belongs farther down the chain, usually in attribution, corroboration, or selection.
Prove access before you rewrite the content
Start with the pages closest to discovery, evaluation, and conversion. These are usually your main service or product pages, location pages, comparison resources, original research, documentation, pricing explanations, and pages that answer recurring pre-sale questions. The goal is not to make every URL equally prominent. It is to ensure that your most useful public information is technically reachable.
Fetch each priority URL without a login. Confirm that the response contains the intended page, not a consent wall, security challenge, empty shell, or error message.
Read robots.txt as a set of instructions. Look for broad disallow rules, overlapping bot-specific directives, and stale rules left by a migration or staging environment.
Inspect controls outside robots.txt. A CDN, web application firewall, rate limit, or bot-management product can reject a request even when the robots file allows it.
Follow redirects to the final page. The destination should remain public, load the substantive content, and identify the stable canonical version of the URL.
Review server and security logs. Look for successful requests, repeated rejections, redirects, and challenge responses associated with the crawlers you intend to permit.
Retest after changing a rule. A configuration edit is not proof that the final URL is reachable through the full delivery stack.
Refining robots.txt and maintaining a useful llms.txt file can improve the conditions under which AI bots discover your content. The files serve different jobs. Robots.txt communicates crawl permissions. An llms.txt file can act as a concise map to important, canonical resources.
If you publish llms.txt, keep it selective. Point to pages that explain who you are, what you offer, and where your strongest reference material lives. Remove redirected, duplicated, expired, and thin URLs. Update the file when important destinations change. A stale directory creates another version of your site for machines to reconcile.
Treat llms.txt as a signpost, not an access-control system or a visibility guarantee. It does not override robots.txt, authentication, firewall rules, or a broken page. It also does not replace ordinary internal links and crawlable site architecture. Do not expose private, administrative, customer, or staging URLs merely to make a crawler test pass.
Your access audit passes when a priority public URL can be retrieved without credentials, returns the intended substantive content, survives the redirect path, identifies a stable canonical destination, and is not rejected by a rule or security control you meant to allow.
Make your identity, evidence, and suitability easy to resolve
Build pages around complete, extractable answers
An extractable page does not need robotic prose. It needs explicit relationships. A reader and a retrieval system should both be able to identify what the page answers, which entity the answer concerns, where the claim applies, and what supports it.
Use a descriptive heading that matches a real question or decision rather than a vague slogan.
Name the company, product, service, or location before relying on pronouns such as it, this, or we.
Give the direct answer first, then add conditions, exceptions, evidence, and next steps.
Keep supporting evidence close to the claim it supports. Do not make a reader hunt through unrelated pages to understand the basis of an important statement.
Distinguish facts from positioning. Availability, location, compatibility, and eligibility should not be buried inside promotional language.
Use internal links with descriptive anchor text so the relationship between an overview, supporting evidence, and a detailed resource is apparent.
Keep structured data, including JSON-LD, aligned with the visible page. Markup should clarify information that users can verify on the page, not introduce a separate set of claims.
Page structure is especially important when a fact has a limited scope. If a service is available only in a particular region, a feature applies only to one plan, or a result depends on stated conditions, carry that qualifier into the answer itself. A technically accurate sentence can still create a wrong AI answer when its limiting context is several paragraphs away.
Give every team one record of core business facts
Create an internal fact sheet for the details that assistants and customers must not get wrong. Include the official brand and location names, canonical URLs, contact details, addresses, operating hours, service areas, categories, and current descriptions of the main products or services. Assign an owner to each field so an operational change has somewhere to go before conflicting versions spread.
Audit those facts across your own site and the external platforms likely to carry them, including Google Maps, Yelp, and Facebook. Check each location separately. A correct corporate address does not repair an incorrect branch profile, and a correct branch page does not erase stale hours elsewhere.
Consistency does not require identical marketing copy on every platform. It requires agreement on verifiable facts. Preserve platform-appropriate descriptions, but remove conflicts in identity, location, availability, and contact information. When you find a discrepancy, correct the system that owns the bad record rather than merely publishing another page with the right answer.
Treat reputation as a confidence signal, not decoration
AI recommendations are markedly selective in the local context measured by SOCi’s 2026 Local Visibility Index. Across nearly 350,000 locations belonging to 2,751 multi-location brands, ChatGPT recommended 1.2% of locations, Gemini recommended 11%, and Perplexity recommended 7.4%. Brands appeared in Google’s local three-pack 35.9% of the time. The resulting gap ranged from about three to 30 times within that dataset.
Those percentages describe a particular multi-location sample, not a universal multiplier for every query, industry, or business. They still expose a costly assumption: strong local Google performance is not a dependable proxy for AI recommendations.
Profile accuracy also differed by assistant in the same dataset. Gemini returned accurate business information in 100% of the measured cases, while ChatGPT and Perplexity reached 68%. That variation is a reason to inspect individual answers and platforms, not to calculate one blended visibility score that hides factual errors.
Ratings appeared to work more like a confidence filter than a simple ranking boost. Locations recommended by ChatGPT averaged 4.3 stars, with slightly lower averages for Gemini and Perplexity. Do not turn 4.3 into a supposed eligibility threshold; it is an observed average, not a published cutoff. Use it as a prompt to examine the underlying customer experience, recurring complaints, unresolved listing errors, and whether your public reputation supports the recommendation you want an assistant to make.
Measure mentions, citations, accuracy, and recommendations separately
A conventional position report cannot show whether an assistant named your brand, recommended it, cited it, or repeated an incorrect fact. Build a prompt-level measurement set around the tasks your audience actually performs.
Discovery prompts: The user is identifying possible approaches, providers, products, or locations.
Comparison prompts: The user is weighing alternatives against explicit requirements.
Suitability prompts: The user wants to know what fits a particular situation, industry, location, or constraint.
Factual prompts: The user needs an address, capability, policy, compatibility detail, operating hour, or other verifiable fact.
Branded prompts: The user already knows your name and expects an accurate explanation.
Non-branded prompts: The user describes the need without giving the assistant your brand as a hint.
For every test, record the exact prompt, platform, model or product surface when identifiable, location context, account state, test date, complete answer, cited URLs, brand mentions, recommendation status, and factual errors. Preserve the response itself. AI answers can vary, and a result you did not save cannot be audited later.
Keep the core metrics separate:
Visibility rate: the share of eligible responses that mention your brand.
Recommendation rate: the share that present your brand as a suitable option, not merely as background.
Citation rate: the share that link to or explicitly identify your owned content.
Factual accuracy: whether the material facts stated about your brand are correct and current.
Cross-platform consistency: whether different assistants produce materially compatible descriptions of the same entity.
A single answer is an observation, not a trend. Retest the same prompt set under documented conditions and look for direction across repeated runs. Change a small, named group of inputs, log the change, and then use the same prompts again. Otherwise, you will not know whether an apparent improvement came from your work, answer variability, or a different testing context.
Keep Google and AI results side by side, but never substitute one for the other. Fewer than half of the brands leading local Google visibility also led their sectors in AI outcomes. In retail, only 45% of the top 20 local-search brands also reached the leading group for AI recommendations. That is dataset-specific evidence for maintaining separate dashboards and separate diagnoses.
Use the following sequence to turn the audit into work:
Baseline the prompts connected to your highest-value customer decisions.
Resolve access failures on the pages that should answer those prompts.
Correct conflicting identity, location, product, and availability facts.
Rewrite weak pages so the direct answer, scope, evidence, and entity relationships are explicit.
Repair inaccurate external profiles and address the operational causes of recurring negative sentiment.
Retest the same prompt set and classify each remaining failure as an access, interpretation, corroboration, or selection problem.
Key takeaways
Google rankings are useful context, but they do not predict whether an AI assistant will cite or recommend you.
Fix the earliest broken stage: access, interpretation, corroboration, or selection.
Robots.txt and llms.txt can support discovery, but neither repairs firewall blocks, private pages, weak answers, or conflicting facts.
Your site, Google Maps, Yelp, Facebook, and other prominent profiles should agree on verifiable business details.
Structured data should reinforce visible content, not create claims that users cannot verify on the page.
Measure mentions, recommendations, citations, and factual accuracy separately for each assistant.
Review averages from a multi-location dataset are diagnostic context, not universal eligibility thresholds.
Start with one high-value query cluster rather than a site-wide rewrite. Confirm that its best pages are reachable, align the facts across your public presence, strengthen the direct answers and supporting evidence, and capture a baseline in the assistants your audience uses. That gives you a controlled unit of work and a result you can actually diagnose.
If your average positions look steady while organic growth feels weaker, you may be measuring a journey that no longer happens in the same number of steps. A person can express a fuller need in one query, receive a synthesized answer, and skip follow-up searches that once gave you several chances to earn a click.
That changes visibility in two ways. Search sessions are becoming more compressed, and AI recommendations are less stable than conventional rankings. Your response should be an intent-based system that measures repeated presence, gives machines unambiguous evidence, and still helps a person make the decision in front of them.
Search demand can persist while the journey loses steps
Datos/SparkToro behavioral data from millions of users found that desktop Google searches per U.S. user fell by nearly 20% year over year. The decline in the EU and U.K. was much smaller, at roughly 2% to 3%. This is a per-user change, not proof that Google suddenly lost its audience.
The surrounding numbers make that distinction important. Traditional search remained about 10% of U.S. desktop activity through 2025. Dedicated AI tools accounted for only 0.77%, while Google AI Mode represented about 0.06% of U.S. desktop events by December. AI adoption is growing, but those shares are too small to support a simple story in which everyone abandoned Google for a chatbot.
These figures do not prove that AI caused every missing search. They are consistent with a more practical mechanism: AI answers and instant results can resolve part of a need before a person performs a second, third, or fourth query. Search remains central, but each session may generate fewer opportunities for publishers.
Query shape is changing at the same time. Six-to-nine-word searches are increasing rapidly in the U.S. Very long queries of 15 words or more remain uncommon and volatile, but they show that people are experimenting with more complete descriptions of what they need. You should therefore plan around the decision contained in a query, not just the keyword string that introduces it.
Choose one commercially meaningful decision. Examples include selecting a product for a constrained use case, deciding whether a service fits a particular situation, or comparing two approaches.
List the modifiers that change the answer. Audience, budget, compatibility, location, urgency, skill level, risk tolerance, and intended use can turn superficially similar prompts into different decisions.
Write down the facts required to answer each version. Include suitability, exclusions, specifications, limitations, evidence, availability, and the next action.
Map every important fact to a crawlable location. A claim should have a clear home on a page, not exist only in an image, sales call, private document, or advertising campaign.
Consolidate wording variants, but split genuinely different intents. If ten phrasings lead to the same criteria and answer, one strong resource can serve them. If the criteria change, create a distinct section or page rather than forcing every audience into generic copy.
This exercise gives you an intent map rather than another keyword list. It also exposes a common visibility gap: the page may mention the right topic while failing to provide the specific facts a search engine or AI system needs to answer the actual decision.
Measure AI visibility as repeated presence, not a fixed rank
An AI recommendation is generated for a particular request and context. It is not a stored, universally ordered result. Across nearly 3,000 executions of 12 identical prompts by more than 600 volunteers, an identical recommendation list appeared fewer than once in 100 responses. Getting the same list in the same order was rarer still, at fewer than once in 1,000.
A single screenshot therefore cannot tell you that your brand ranks third in AI search. It tells you that your brand appeared third in one response. Running the same prompt once more and reporting the better result is no more defensible; it replaces one anecdote with another.
The more useful signal is visibility percentage: how often your brand appears across a defined set of valid responses. Presence proved more stable than exact order, even when the lists themselves changed. Smaller niche categories tended to produce more consistent answers than large markets, so you should not compare percentages across unrelated categories as though they shared the same competitive conditions.
Define the prompt universe before collecting results. Select the audience, decision, market, language, and meaningful constraints. Do not add favorable prompts after seeing the outcome.
Create wording variants that preserve intent. Natural prompts can differ substantially in phrasing while expressing the same underlying need. Keep these in one family.
Separate prompts when the purpose changes. A general product recommendation and a recommendation for gaming, accessibility, enterprise security, or noise cancellation are different intent families if their selection criteria differ.
Repeat tests under documented conditions. Record the product or model, interface, date, locale, login or personalization state when known, exact prompt, and complete response.
Classify the outcome before calculating a rate. A passing mention, a direct recommendation, a citation, and an accurate description are not interchangeable forms of visibility.
Aggregate by intent family. Calculate repeated presence within each decision context before combining anything into an overall number.
There is not yet a validated universal minimum number of runs, and API output may not reproduce what a person sees in a consumer interface. Treat a small sample as directional. Keep the protocol consistent, retain the underlying responses, and widen the sample before making an expensive content or positioning decision.
You can still record list order for diagnosis. A persistent pattern may lead you to inspect what distinguishes frequently preferred brands. But exact position should not become the executive KPI, agency guarantee, or performance bonus when the output is inherently variable.
Make every important claim retrievable, specific, and verifiable
The next visibility problem is eligibility: can a system identify your entity, retrieve the relevant facts, and determine whether your offer fits the user’s constraints? A page can be persuasive to a person while remaining ambiguous to a machine because the product name changes between sections, limitations are missing, specifications live in images, or structured data conflicts with visible copy.
Moving from discovery to transaction inside one AI conversation is still a forecast rather than established behavior at scale. It is nevertheless sensible to make product and service information machine-readable now. The same cleanup also helps conventional search, feeds, internal search, accessibility, and human comparison.
Use this content pattern for each important decision page:
Entity: State the exact product, service, organization, person, or location being described. Use the same canonical naming across headings, copy, metadata, and structured data.
Direct answer: Address the central decision early. Say who or what the option is for, rather than making the reader assemble an answer from feature copy.
Qualifiers: State compatibility requirements, exclusions, prerequisites, geographic limits, and material tradeoffs. Missing limits invite incorrect assumptions.
Comparable facts: Present specifications, capabilities, availability, and policies in labeled text or tables where a comparison genuinely helps.
Evidence: Add original measurements, first-party data, expert explanation, examples, or a documented method. Include enough context for someone to judge what the evidence does and does not establish.
Freshness: Show when time-sensitive facts were reviewed, and correct outdated pages instead of allowing contradictory versions to coexist.
Structured data: Apply the most specific relevant schema types and properties, using the same facts shown to the reader. Markup labels evidence; it does not replace evidence or make an unsupported claim true.
Generic summaries are easy to reproduce and hard to distinguish. Proprietary data and distinctive first-party content give other sites and AI systems information they cannot obtain from another lightly rewritten overview. The useful part is not merely owning data. You need to publish the method, scope, date, definitions, and limitations that make the result interpretable.
Specificity also protects brand accuracy. When your trial policy, service boundary, compatibility, or availability is unclear, a generative system may fill the gap with a category-level pattern that applies to competitors but not to you. Put the correction on the canonical page, align related pages and schema, and make the wording explicit enough to quote without reconstruction.
Do not create a separate thin page for every prompt variation. Build around meaning. A strong resource can answer several phrasings when the intended decision is the same, while modular sections can address the qualifiers that materially change the answer.
Treat video as visual, audio, text, and metadata
Video can supply evidence that prose struggles to carry: a product in use, a software workflow, a physical dimension, an expert’s explanation, or the exact state of an interface. AI systems can process visual frames, speech, on-screen text, and relationships between them. Some handle these streams together; others depend on separate recognition and transcription components. Either way, clarity determines how much useful information survives.
Optimize all four layers rather than uploading a polished file and relying on its title:
Visual layer: Publish crisp 1080p video where practical. OCR can struggle with footage below 360p, and enhancement cannot reliably restore text that was never captured clearly. Use high contrast, bold readable type, and close enough framing for labels and interface states to be legible.
Temporal layer: Keep a key object, label, or action on screen long enough to appear in sampled frames. Rapid cuts may look energetic to a person while causing an automated system to miss the one frame that establishes the fact.
Audio layer: Use clear speech, identify speakers, reduce competing noise, and align narration with the action on screen. Deliberate pauses can separate important statements and reduce ambiguity.
Text layer: Provide human-verified captions and a transcript. A transcript gives text-dependent systems access to the substance and reduces errors introduced by automatic speech recognition.
Metadata layer: Use accurate titles and descriptions, then add applicable VideoObject markup. Properties such as hasPart, transcript, and interactionStatistic should describe real, visible content and verified data.
Review the finished video without sound, then review only the audio and transcript. If either version loses the core claim, the layers are not reinforcing one another. Fix the asset itself before adding schema; metadata cannot rescue an unreadable demonstration, an incorrect caption, or a missing limitation.
Use a scorecard that separates exposure, accuracy, and value
Traffic remains useful, but it no longer describes the whole journey. An answer can mention your brand without linking to it, cite you without recommending you, recommend you inaccurately, or send a visitor who converts. Those are different outcomes and should occupy different rows in your reporting.
Key takeaways
Fewer searches per person do not mean Google has become irrelevant; they mean each journey may contain fewer opportunities.
An AI list position is an observation from one response, not a durable rank.
Measure repeated brand presence across defined intent families and documented conditions.
Separate mentions, recommendations, citations, accuracy, and business outcomes.
Improve visibility eligibility with explicit facts, distinctive evidence, consistent structured data, and machine-readable media.
A practical scorecard can use the following definitions. Set the inclusion rules before testing, and keep the denominator visible beside every percentage.
Metric
How to calculate it
What it helps you decide
AI visibility rate
Valid responses that mention your brand divided by all valid responses in the defined prompt set
Whether you enter the answer set for that intent
Recommendation rate
Valid responses that present your brand as a suitable option divided by all valid responses
Whether appearances are incidental or decision-relevant
First-party citation rate
Responses that cite a page you control divided by valid responses on citation-capable surfaces
Whether your own evidence is being used, rather than only third-party descriptions
Accuracy rate
Reviewed appearances with all predefined material claims correct divided by appearances reviewed
Whether greater exposure is reinforcing the right brand facts
Intent coverage
Intent families in which the brand appears divided by all intent families tested
Which audiences or use cases have evidence gaps
Human search performance
Impressions, clicks, landing-page behavior, and conversions reported by page and intent group
Whether conventional discovery and on-site usefulness are improving
Business outcome
Qualified actions, leads, sales, or other agreed outcomes from attributable journeys
Whether visibility work is connected to value rather than exposure alone
Store the prompt and complete response behind every AI observation. Also retain the model or product, interface, collection date, locale, and personalization state when known. Compare like with like. If a platform changes, preserve the old series and label a new baseline instead of hiding the discontinuity inside a blended average.
Do not force no-click visibility into a revenue number you cannot defend. Report correlation as correlation, keep attributable conversions separate, and use brand visibility trends to decide where to investigate. The purpose of the scorecard is to improve decisions, not manufacture certainty from a probabilistic system.
On your next reporting cycle, start with one high-value customer decision. Build its prompt family, collect a documented baseline, identify the most obvious evidence or accuracy gap, and correct that gap on the canonical page. Then rerun the same protocol. That gives you a repeatable visibility practice while the interfaces, models, and search journeys continue to change.
The draft looks finished. The structure is clean, the tone is right, and the citations look plausible. Then you check one claim and discover that the evidence is not there. Editing that sentence treats the symptom; the prompt still rewards a complete answer more than a defensible one.
Rubric-based prompting changes that incentive. You tell the model not only what to produce, but how to decide whether it has enough support, when it may infer, when it must qualify, and when it should stop. That is the difference between requesting a polished deliverable and defining a controlled production process.
Why polished prompts still fail when information is missing
A conventional prompt usually describes the destination: write an article, analyze a competitor, summarize a document, or recommend a strategy. It may specify the audience, tone, length, headings, and output format. Those instructions can improve presentation without resolving the most important question: what should the model do when it cannot support part of the requested answer?
If you request a complete deliverable but provide incomplete evidence, the model faces competing objectives. It can acknowledge the gap and leave part of the task unfinished, or it can produce something fluent enough to resemble completion. Unless you define which objective has priority, fluency can win.
This matters in content, SEO, AEO, and GEO workflows because unsupported material rarely stays in one draft. A fabricated statistic can migrate into a headline, executive summary, FAQ, metadata, structured data, presentation, or client recommendation. The first error may be a sentence. The operational problem is the chain of assets built from it.
The downside is not theoretical. In 2025, Deloitte had to refund substantial costs associated with a government report containing AI errors, including fabricated citations. That is an extreme outcome, but it illustrates the basic risk: an authoritative-looking answer can travel farther than its evidence warrants.
A vague prompt is not the only reason an AI system can be wrong, and no rubric can guarantee truth. Models can misunderstand material, mishandle conflicting evidence, or generate an incorrect answer despite clear instructions. A rubric addresses the preventable part of the problem: ambiguity about evidence, uncertainty, inference, and failure behavior.
The distinction is simple. A prompt describes what a successful output should contain. A rubric defines the decisions the model must make when success is not fully possible. It replaces requests such as be accurate or do not hallucinate with conditions that can actually govern the response.
Build the rubric around decisions, not aspirations
An instruction such as use reliable information sounds responsible, but it leaves every operational term undefined. Which information is authorized? What counts as support? May the model draw an inference? Should it omit an unsupported section, qualify it, or ask you a question?
A useful rubric resolves those choices before generation starts. Build yours around the following decisions.
Define the evidence boundary. Name the material the model may use: supplied documents, approved URLs, a product fact sheet, a transcript, a dataset, or general background knowledge. If freshness matters, state whether information outside the supplied material is prohibited or must be separately verified. Do not use an open-ended phrase such as credible sources when you need a closed evidence set.
Classify claims by support. Tell the model to distinguish facts directly supported by the authorized material from reasonable inferences, unresolved conflicts, and unavailable information. Give each state a visible treatment. A supported fact may be stated normally. An inference should be labeled. A conflict should remain visible. An unavailable claim should be omitted or marked as needing evidence.
Identify material uncertainty. Not every missing detail should stop the task. Define a gap as material when it could change the central claim, recommendation, audience, scope, or risk. The model may proceed with a harmless formatting choice, but it should not quietly invent a product capability, legal requirement, price, quotation, date, or performance result.
Specify the fallback behavior. Decide what should happen when a criterion fails. Your choices include asking a blocking question, returning a partial answer, labeling a provisional assumption, inserting a clear evidence placeholder, or declining the unsupported portion. Without a fallback, even a good accuracy rule leaves the model to improvise.
Set an acceptance test. Describe what must be true before the response is considered complete. For example, every factual claim must map to authorized evidence; every inference must be labeled; every citation must support the adjacent claim; and summaries, FAQs, metadata, and structured fields must not introduce facts absent from the approved material.
Put these rules in priority order. If accuracy and completeness conflict, say which one wins. If the requested format requires a statistics section but no statistics are available, the rubric should instruct the model to flag the missing evidence instead of manufacturing a plausible number to preserve the format.
The same principle applies to conflicts among inputs. Do not tell the model merely to resolve discrepancies. Tell it whether to prefer a designated primary record, use the most applicable version, present both positions, or stop and ask. Otherwise, the final answer may hide the disagreement behind confident prose.
Keep the rubric concise enough to enforce. Repeated rules written in slightly different ways can create new conflicts. Each criterion should contain a trigger, a required action, and a visible outcome. If you cannot tell whether the output passed a criterion, rewrite the criterion.
A copy-ready rubric for content and SEO workflows
You do not need to rebuild the framework for every task. Keep a stable core and add task-specific rules only where the risk changes.
Reusable prompt block
Place this block after the task, audience, context, and required output format. Replace the bracketed fields with boundaries that match your workflow.
Priority: Factual support and transparent uncertainty take precedence over completeness, fluency, tone, and length.
Authorized evidence: Use only [approved inputs] for factual claims about [subject]. Do not treat a requested claim as evidence that the claim is true.
Supported claims: State a factual claim only when the authorized evidence supports that specific wording and scope. Do not broaden a narrow claim.
Inferences: You may infer only when the conclusion follows reasonably from the evidence and does not introduce a new factual detail. Label the conclusion as an inference and identify the evidence behind it.
Missing or conflicting information: Do not invent names, numbers, dates, quotations, citations, URLs, capabilities, examples presented as real, or research findings. Mark unsupported items as [preferred label]. Preserve material conflicts instead of silently choosing a side.
Clarification rule: Ask a blocking question before drafting when the missing information could change the central claim, recommendation, audience, scope, or risk. Otherwise, continue and record the limitation.
Final check: Before returning the answer, remove or label every unsupported claim, confirm that each citation supports the claim beside it, and confirm that derivative sections introduce no new facts.
Response: Return the requested deliverable followed by a short exception log containing material omissions, labeled inferences, unresolved conflicts, and blocking questions. Do not return hidden reasoning or a generic assurance that the answer is accurate.
The exception log is important because it makes failure visible without requiring you to inspect the model’s internal reasoning. If the log is empty but the draft contains unsourced specifics, the output has failed the rubric.
Worked example: an evidence-controlled content brief
Suppose you ask AI to create an AEO-focused brief from an approved product fact sheet, a set of customer questions, and selected reference pages. A normal prompt may request key claims, search intent, supporting statistics, FAQs, and suggested structured content. The format is clear, but the evidence rules are not.
Add task-specific criteria such as these:
Use the approved packet for every product claim, date, number, quotation, comparison, and attributed statement.
Do not invent search volume, ranking difficulty, trend data, customer stories, survey findings, product limitations, or competitor capabilities.
Separate evidence-backed audience questions from editorial questions proposed for further research. Do not present a suggested question as observed search behavior.
Separate factual claims from recommendations about page structure. A heading recommendation does not need to masquerade as a fact about the market.
Create a claim register that pairs each publishable factual claim with the item that supports it. If no item supports the claim, label it Needs evidence.
Apply the same evidence boundary to the summary, FAQ, metadata, and any structured fields. Changing the format does not authorize a new claim.
Return blocking questions before the brief when missing information would change the page’s audience, core promise, or factual position.
This version still lets the model help with organization and editorial planning. It removes permission to imitate missing research. That distinction prevents a common failure: treating the model’s familiarity with the shape of an SEO brief as evidence for the facts inside it.
Test the rubric with deliberately incomplete input. Remove the support for a requested statistic, product claim, or quotation while leaving the request in place. A passing response should flag the gap, ask a material question, or omit the unsupported item according to your rule. If it produces a plausible replacement, tighten the evidence boundary and failure action before using the prompt in an automated workflow.
Review the output with a separate acceptance rubric
The generation rubric controls how the draft should be produced. An acceptance rubric controls whether that draft can move forward. Separating the two prevents a polished response from being treated as approved merely because it followed the requested structure.
Use clear statuses such as pass, revise, and block. A numeric score can hide a serious defect inside an acceptable average. One fabricated citation should block publication even if the tone, organization, and formatting are excellent.
Criterion
Pass condition
Failure action
Evidence coverage
Every externally verifiable factual claim is traceable to an authorized input or visibly labeled as an inference.
Remove the claim, add appropriate evidence, or change its status.
Citation fit
Each citation exists and supports the exact claim, scope, and qualification beside it.
Replace the citation, narrow the wording, or block the claim.
Uncertainty handling
Material gaps and conflicts remain visible; low-impact assumptions are identified where relevant.
Add a qualification, request clarification, or return the item for research.
Instruction priority
The output meets the task without violating higher-priority evidence and uncertainty rules.
Revise the deliverable instead of waiving the higher-priority rule.
Claim propagation
Summaries, FAQs, metadata, and structured fields contain no unsupported facts copied from or added to the main draft.
Remove the derivative claim or supply support before publishing.
Exception log
Material omissions, inferences, conflicts, and questions are specific enough for a reviewer to resolve.
Replace generic caveats with the affected claim, missing input, and required next action.
You can ask the model to apply this acceptance rubric to its own output, but treat that as a consistency check, not independent verification. The same system that generated an unsupported claim can overlook it during self-evaluation. A person should still open important citations, compare claims with the underlying material, and review conclusions that affect money, legal exposure, health, reputation, or publication under someone else’s name.
When a rubric performs badly, the pattern usually points to the missing rule:
The answer is fluent but contains invented specifics. The evidence boundary is open-ended, or unsupported claims have no mandatory failure action.
The model refuses to complete useful work. The rubric treats every uncertainty as blocking. Define which inferences and low-impact assumptions are allowed.
The answer is buried in caveats. The rubric does not distinguish material uncertainty from details that do not affect the outcome. Add a materiality test.
The citations look correct but do not support the claims. The rubric checks citation presence rather than citation fit. Require support for the exact adjacent statement.
Different sections contradict one another. The rubric evaluates local sentences but not the deliverable as a whole. Add a cross-section consistency check.
The model follows some rules and ignores others. The rubric is probably too long, repetitive, or internally conflicted. Remove overlap and state the priority order.
The self-review always passes. The acceptance criteria are subjective, or the same model is being treated as an independent reviewer. Replace impressions such as high quality with observable pass conditions and retain human verification where the consequence warrants it.
A rubric does not replace retrieval, source selection, subject-matter expertise, or fact-checking. It governs what the model should do with the information and uncertainty it has. That narrower role is still valuable because it makes incomplete evidence visible before fluent prose conceals it.
Key takeaways
A standard prompt defines the deliverable; a rubric defines how the model must behave when evidence is missing, conflicting, or insufficient.
Prioritize factual support over completeness explicitly. Otherwise, a request for a finished answer can compete with the instruction to avoid unsupported claims.
Every criterion needs a trigger, required action, and visible outcome. Be accurate is a goal, not an enforceable rule.
Define allowed evidence, labeled inference, material uncertainty, clarification conditions, and failure behavior before generating the draft.
Use a separate acceptance rubric for publication. Self-review can improve consistency, but it is not independent factual verification.
Start with one prompt you already use. Add an evidence boundary, an uncertainty classification, a stop condition, and an acceptance check. Then test it against incomplete or conflicting input. If the model fills a gap you expected it to expose, revise the decision rule before you scale the workflow. The useful rubric is not the one that sounds strict; it is the one that produces the correct behavior when the easy answer is unavailable.
If your pages still rank but your brand is absent from AI-generated answers, you may assume you need a separate AI search playbook. Start lower in the stack: can each system reach your information, understand what it means, and find enough reasons to trust it?
Your goal is not to produce a different version of the business for every interface. Build a dependable information layer that serves search engines, AI systems, and the person making a decision. The order matters: access first, meaning next, confidence after that, and usefulness throughout.
AI search added a new output, not a new foundation
Traditional rankings still matter, but they no longer describe the full discovery journey. AI systems can surface a brand, product, or fact without sending a visit, which means rankings and clicks reveal only part of your visibility.
It helps to separate two outcomes:
Destination visibility: a search result or AI citation gives the user a path to your site.
Answer visibility: your brand or information appears directly in a generated response, whether or not the user clicks.
The more valuable outcome depends on the task. Someone checking an address or availability may only need a fact. Someone evaluating an expensive or complicated purchase may need the full page. Measure both outcomes instead of treating every search as a race for the same click.
Do not confuse appearance with success, either. If an AI response names your brand but gives the wrong policy, location, capability, or product detail, that is a visibility failure. You were discovered, but the information layer did not preserve your meaning.
SEO, AEO, and GEO can therefore be treated as different views of the same visibility stack:
Access: the information is public, crawlable, fast, and reliably retrievable.
Interpretation: the entity, page purpose, attributes, and relationships are unambiguous.
Confidence: important facts agree across your site and other relevant surfaces, while authority, reviews, and reputation support them.
Usefulness: the content resolves the user’s actual question and makes the next step clear.
Audit those layers in that order. Rewriting a paragraph will not remove a crawler block. Adding schema will not reconcile conflicting business information. Brand mentions cannot rescue an answer that never addresses the user’s need.
Make important facts easy to retrieve and hard to misread
Begin with the information that must remain correct when someone evaluates your business. Depending on the organization, that could include identity, offerings, locations, availability, service areas, compatibility, policies, contact details, and the qualifications attached to a claim.
Create a fact map before changing pages. For each important fact, record:
the approved value or wording;
the primary page or system that owns it;
every page, profile, feed, or markup field where it is repeated;
the person or team responsible for approving changes;
the event that should trigger an update.
This turns content accuracy into an operating process. Without an owner and an update path, a changed policy can remain correct on its main page while an old version survives in structured data, a business profile, or a comparison page.
Check retrieval before rewriting the answer
A page can look fine in a logged-in browser and still be difficult for a crawler to use. Check the public experience rather than relying on the CMS preview.
Can an unauthenticated visitor reach the preferred URL through a logical internal-link path?
Does the URL return a normal successful response without requiring a login, form submission, or dismissible screen?
Do robots directives permit the crawlers you intend to serve?
Do redirects and canonical signals lead to the page that owns the information?
Is the important text available in the rendered page rather than appearing only after an optional interaction?
Does the page respond consistently and quickly enough to be retrieved without repeated failures?
Once retrieval works, inspect the answer itself. Put the direct response close to the question it resolves. Name the entity instead of relying on a chain of vague pronouns. Carry essential qualifiers such as plan, version, region, audience, or limitation into the sentence that contains the claim.
A useful answer pattern is: [Product] supports [requirement] for [qualifying plan, version, or region]. [Limitation] applies. That structure is more extractable and safer for the reader than a broad claim followed by an exception several paragraphs later.
Headings should describe the decision being made, not merely the theme of the page. Flexible plans is a theme. Monthly and annual billing options is a decision-relevant label. The heading, answer, supporting details, and next step should all refer to the same intent.
Use JSON-LD to express visible facts when an appropriate schema vocabulary and property exist. The markup should mirror the page, not become a private version of the truth. If the page carries an old value and the structured data carries a new one, adding more markup only creates another conflict. Correct the owning data first, update the visible content, and then regenerate its machine-readable representation.
Build trust by controlling facts, not by decorating claims
Trust is not a field you can add to schema. It grows when a claim is specific, its context is visible, the underlying fact remains consistent, and other relevant signals do not contradict it. Work through four kinds of alignment:
Identity alignment: use the correct organization, location, product, and service names wherever those entities appear.
Claim alignment: make sure summaries, detail pages, structured data, feeds, and profiles agree on material facts and qualifications.
Time alignment: update changed hours, availability, policies, offers, and capabilities at their owner before updating downstream copies.
Reputation alignment: monitor reviews and public feedback for recurring factual confusion. If several people misunderstand the same condition, inspect the page and profile information that shaped the expectation.
Consistency does not mean repeating the same paragraph everywhere. A support page, product page, and business profile can use different wording. The underlying facts must agree.
A simple source hierarchy prevents many conflicts. Let the primary business system or canonical page own the fact. Let visible page copy explain it. Let structured data represent it. Let profiles and feeds distribute it. Let editorial content point back to the owner instead of quietly redefining the fact.
When a conflict appears, correct the owner first and work downstream. Editing only the most visible copy creates temporary agreement while leaving the same error ready to return during the next update.
Brand recognition and site performance can strengthen visibility, but they work only after the platform is accessible and understandable. Authority is an amplifier, not a substitute for a functioning information layer.
Audit visibility in the order failures actually occur
A useful audit should tell you what failed, not merely assign a score. Use the same diagnostic sequence for traditional results and AI-generated answers.
Build a decision-focused query set. Start with the questions people need answered before they can identify, evaluate, choose, or use your offering. Draw language from customer support, sales conversations, on-site search, and audience research where those inputs are available.
Capture a baseline on each relevant surface. For conventional search, record the page shown, how it is described, and whether the result supports the intended task. For AI responses, record whether the brand appears, whether the facts are accurate, whether a source is linked, and which page is selected.
Trace the answer to its owner. Identify the page or data system that should supply the correct fact. If no reliable owner exists, you have an information architecture problem before you have a ranking problem.
Classify the first observable failure. An inaccessible page indicates a technical access issue. A retrieved but misunderstood answer points toward unclear content, entity confusion, or inadequate structured representation. A wrong value points toward conflicting data. A clear and accessible answer that is repeatedly omitted calls for closer examination of coverage, authority, reputation, and competition.
Fix dependencies from the bottom up. Restore access, establish the canonical fact, improve visible wording, align structured data, update relevant profiles or feeds, and then strengthen supporting authority signals.
Run the same checks again. Keep query wording and evaluation criteria consistent. AI outputs can vary, so do not treat a single response as a settled measurement. Look for repeated improvement in inclusion, accuracy, source selection, and the quality of any resulting visits.
The classification is a working diagnosis, not proof of a ranking factor. Its purpose is to narrow the next investigation. If the correct page cannot be retrieved, there is little value in debating prose. If the page is available but carries conflicting facts, acquiring more mentions may spread the problem rather than solve it.
Keep conventional metrics such as rankings and clicks, but add measures suited to answer visibility: whether the brand is included, whether material facts are correct, whether the right source is cited, and whether the user has a useful next step. A blended visibility score can be convenient, but it should never conceal which layer failed.
The final quality check belongs to the user. Can a person confirm the answer without guessing? Are the conditions and limitations adjacent to the claim? Is the next action clear? Customer satisfaction remains the practical goal; crawlability and structured data are how you become eligible to serve it at scale.
Key takeaways
AI search changes where an answer may appear, but it still depends on accessible, understandable, trustworthy information.
Optimize a shared information layer instead of creating conflicting versions for search engines, AI systems, and business profiles.
Fix crawlability and retrieval before rewriting content or expanding schema.
Give each material business fact an owner, a canonical location, and a defined path to every place it is repeated.
Keep visible content and JSON-LD aligned; structured data clarifies facts but cannot repair a contradictory source of truth.
Measure answer inclusion and factual accuracy alongside rankings and clicks.
Start with the highest-value customer question your brand should answer without ambiguity. Trace its answer from the owning data to the page, markup, relevant profiles, search result, and AI response. Fix the first break you find, then move to the next question.
Add new tools only when they help you observe or maintain one of those layers. A new visibility score is useful when it directs a repair; it is not the repair itself.