Tag: Consumer Behavior

  • DMA Search Fairness: What SEO Teams Should Measure Now

    DMA Search Fairness: What SEO Teams Should Measure Now

    If your organic click-through rate or direct conversions fell after DMA-related search changes, don’t assume your rankings failed. An extra comparison layer, a different result layout, a new intermediary, or a longer route to conversion can produce the same dashboard symptom.

    The honest verdict on DMA search fairness is not proven. The rules were meant to curb gatekeeper self-preferencing, but reported outcomes include more user friction, lower click-through rates, fewer direct bookings, and no clear weakening of Google’s central position. To decide what is actually happening, you need to measure user utility, business access, competitive opportunity, and market power separately.

    Search fairness is four questions, not one metric

    The Digital Markets Act was passed in 2022 and came into force in March 2024. Its search-market logic was straightforward: a dominant gatekeeper should not give its own services an unfair advantage over competing services.

    That principle addresses a real problem. Google has been accused of promoting services such as Google Shopping ahead of alternatives that may serve the user better. But restricting self-preferencing does not automatically produce a competitive market, a better user journey, or stronger outcomes for independent businesses. Those are different tests.

    DimensionQuestion to askEvidence worth trackingMisleading shortcut
    Procedural neutralityAre Google-owned and independent services receiving comparable treatment?Eligibility, placement, labels, link treatment, and destination types across matched queriesCounting how many links appear on the page
    User utilityCan the searcher complete the intended task without avoidable detours?Steps to completion, intermediate domains, refinements, backtracking, abandonment, and completion rateAssuming more visible choices always create a better experience
    Business accessDo independent providers receive qualified visits and direct conversions?Click destination share, conversion per search impression, assisted conversions, and direct-conversion shareUsing impressions or rankings without following the journey to its outcome
    ContestabilityCan a challenger win and retain demand without depending on the same gatekeeper?Diversity of destinations, durable gains across query groups, new-entrant visibility, and reliance on a single acquisition routeTreating one established intermediary’s traffic gain as proof of an open market

    This distinction prevents two common analytical errors. A less convenient interface does not, by itself, prove that competition became less fair. A more competitive market can impose some short-term friction while users and businesses adjust. The reverse is also true: giving several services a place on the results page does not establish fairness if Google still controls the gateway, the rules, and most demand.

    One survey involving 5,000 European consumers reported a more cumbersome online experience, with respondents even expressing willingness to pay to restore aspects of the previous integrated experience. That is an important warning about user utility. It is not, on its own, a complete measure of market contestability. The right response is to retain the warning while refusing to make it answer a different question.

    Build a scorecard around the complete search journey
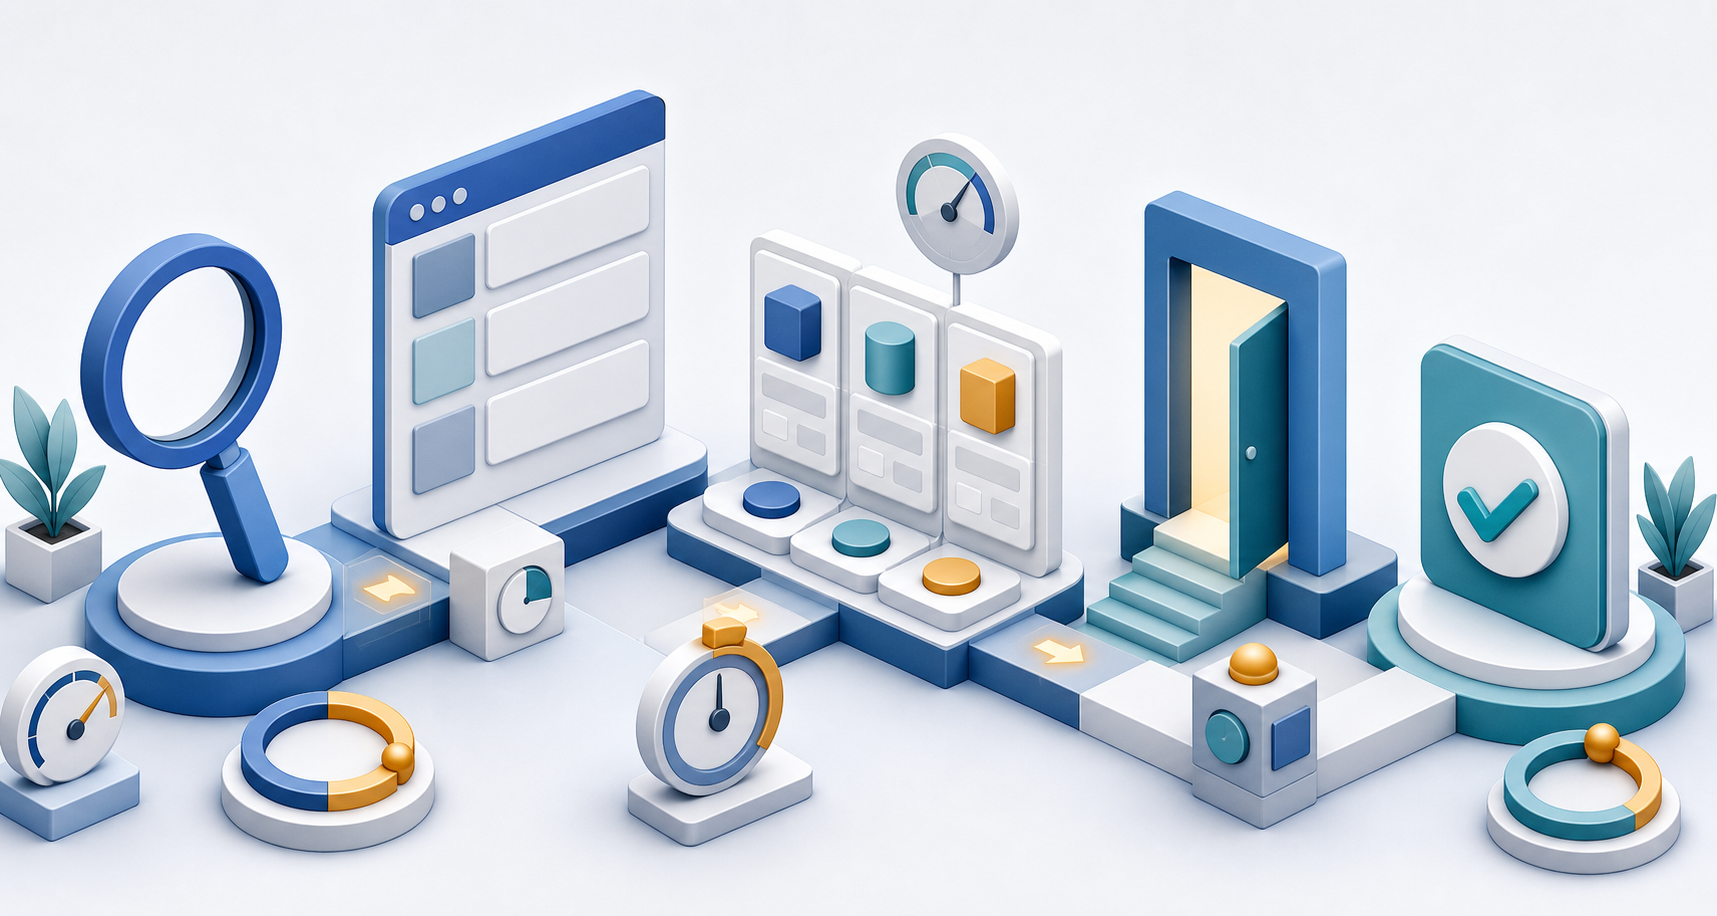
    An isometric search journey moves from a magnifying glass through result cards and a comparison layer to a confirmed direct transaction, with measurement symbols at each stage.

    A DMA impact analysis should begin with a specific user task, not an account-wide traffic graph. Choose a query cohort tied to one decision: compare an offer, find a provider, reach a product page, start a booking, or complete a purchase. Then map every step from the search result to the final action.

    1. Define matched query cohorts. Keep branded and non-branded searches separate. Split informational and transactional intent, and separate devices when their result layouts differ. An account-wide average can conceal the exact queries on which a new handoff appeared.
    2. Record the visible search interface. For each cohort, capture result types, ordering, labels, proprietary modules, comparison services, organic links, and the domains receiving the first click. Preserve dated snapshots so later analysis does not depend on memory.
    3. Measure the full funnel. Connect impressions and average visibility to clicks, landing sessions, qualified actions, conversion rate, direct conversions, and assisted conversions. A traffic metric tells you where attention moved; it does not tell you whether the business relationship survived the move.
    4. Count handoffs and friction. Record how many domains and decisions sit between the result and the intended action. Look for repeated searches, backtracking, abandonment, and paths that send the user from Google to an intermediary before reaching the provider.
    5. Segment destination ownership. Classify clicks going to Google-owned experiences, independent comparison services, publishers, marketplaces, and the provider’s own site. Without this classification, a declining organic CTR cannot reveal who captured the lost demand.
    6. Use a credible comparison. Compare the same query cohorts before and after an observable interface change. Where possible, use comparable unaffected markets or journeys as controls, while accounting for seasonality, demand shifts, promotions, device mix, and unrelated ranking changes.
    7. Set the interpretation rules first. Decide which combinations would indicate better user utility, stronger business access, or greater contestability before looking at the result. This reduces the temptation to label any favorable business movement as proof of fairness.

    A simple before-and-after chart is rarely enough. Search demand, ranking systems, result features, brand activity, and conversion conditions can all move during the same period. If you do not control for those changes, the DMA becomes a convenient explanation rather than a demonstrated cause.

    Your scorecard should also preserve trade-offs instead of averaging them away. If independent providers receive more qualified visits while users take an extra step, business access may have improved while user utility weakened. If users face more steps and independent providers receive fewer direct conversions, the implementation is failing both tests. If one large intermediary captures most displaced clicks, the market may have redistributed attention without becoming meaningfully more contestable.

    Diagnose lower clicks and direct bookings before changing SEO
    An analyst examines four connected search and conversion layers whose different paths converge on the same weakened outcome signal.

    Reported declines in click-through rates and direct bookings are consequential, but neither metric explains its own cause. The same decline can originate at several points in the journey, and each one calls for a different response.

    • Visibility loss: Impressions, positions, or eligible appearances decline for the affected query cohort. Investigate relevance, technical eligibility, content quality, competitor movement, and result-layout changes before blaming regulation.
    • SERP interception: Visibility remains broadly stable while CTR falls and a different result type captures attention. Identify whether the click moved to a Google-owned surface, an independent service, or another publisher. Those movements have very different fairness implications.
    • Handoff friction: The user clicks but must pass through an additional service before reaching the provider. Measure the completion rate at every transition. A new competitive option is not useful to the business if qualified demand repeatedly disappears at the handoff.
    • On-site conversion loss: Landing sessions remain stable while conversion rate falls. Check page experience, message consistency, availability, offer changes, and measurement integrity. That pattern is less likely to be explained by search-result fairness alone.
    • Attribution loss: The final conversion still occurs, but the added intermediary changes how the journey is credited. Reconcile search clicks, referral sessions, assisted conversions, and transaction records before declaring that demand vanished.

    The destination of a lost click matters as much as the loss itself. If your page loses traffic to an independent service that better satisfies the query, your business performance fell while procedural competition may have improved. If the click moves into a gatekeeper-owned unit, weaker performance may coincide with continued self-preferencing. If the click moves to a dominant intermediary, the result could replace one dependency with another.

    Direct bookings need the same care. A lower direct-booking count can reflect lower demand, weaker visibility, an interrupted handoff, an attribution change, or transactions migrating to an intermediary. Report those causes separately. Otherwise, a single metric will mix an SEO problem, a user-experience problem, and a market-structure problem into one number no team can act on.

    Act on the layer that actually failed

    What search and content teams can change

    You cannot optimize away a gatekeeper problem, but you can make your own part of a fragmented journey easier to discover, understand, and measure.

    • Maintain query-level evidence. Keep a recurring record of high-value result pages, their features, and their click destinations. Interface evidence is essential when traffic moves without an obvious ranking loss.
    • Preserve destination data. Classify referrals and assisted paths by surface and intermediary. Do not combine direct, organic, comparison-service, and marketplace journeys into a single acquisition bucket.
    • Reduce post-click uncertainty. Make the landing page complete the promise made in the result. Put the decision-critical information and next action where the visitor can find them without another search.
    • Keep structured data aligned with visible content. Accurate schema can reduce ambiguity about the entity, offer, page purpose, and relationships represented on the page. It will not reverse a DMA-induced layout change or prove that a market is fair.
    • Design for both direct and assisted discovery. Give intermediaries and AI-driven answer systems clear, consistent facts while preserving a strong path to the provider’s own page. Measure whether those external surfaces introduce qualified users or merely absorb the relationship.
    • Report performance and fairness separately. Your executive dashboard should distinguish what happened to your business from what happened to the market. A regulation can hurt one company without reducing competition, or help one company without creating a fair system.

    What regulators would need to demonstrate

    A credible fairness claim requires more than evidence that Google changed a layout or exposed additional links. Regulators would need to show that independent services can acquire qualified demand, users can still complete tasks at an acceptable level of friction, and challengers can become viable without remaining dependent on the same gatekeeper.

    Enforcement also has to change incentives. A fine that leaves the gateway, behavior, and economic advantage intact can become an operating cost rather than a competitive remedy. Structural options, including breaking up a monopoly, address a different layer of the problem than interface rules do. They also carry much larger consequences and require a stronger evidentiary case; they should not be treated as a cosmetic extension of search-result regulation.

    The practical decision rule is simple: if a remedy changes presentation but does not reduce dependency, expand viable entry, or improve independent access to demand, it is managing the symptom. If it improves supplier access while adding user friction, it has created a trade-off that must be measured and refined. Calling either outcome an uncomplicated success hides the work still required.

    Key takeaways

    • The DMA’s equal-treatment goal is a rule for gatekeeper conduct, not proof that search outcomes became fair.
    • User convenience, business performance, procedural neutrality, and market contestability are separate dimensions. A single CTR or satisfaction metric cannot represent all four.
    • The survey of 5,000 European consumers is a meaningful warning about added friction, but consumer sentiment alone cannot establish whether independent competition improved.
    • Lower CTR and fewer direct bookings should trigger a journey diagnosis: visibility, SERP interception, handoff friction, on-site conversion, and attribution each require a different response.
    • A fairer result would let independent services gain qualified demand and become viable without simply shifting dependency from Google to another powerful intermediary.
    • SEO teams should preserve query-level SERP evidence, classify click destinations, connect discovery to final outcomes, and keep fairness reporting separate from company performance.

    Your next move is to choose one commercially important query cohort and map it from result page to completed action. Record who receives each click, how many handoffs the user encounters, and where qualified demand disappears. Repeat that measurement after material interface changes. You will then know whether you are facing an SEO issue, a user-experience issue, a distribution shift, or a gatekeeper problem – and you can stop asking one metric to answer four different questions.
    References

  • How to Build Brand Visibility Across AI Search Journeys

    How to Build Brand Visibility Across AI Search Journeys

    Your pages can rank in traditional search while your brand remains absent, misrepresented, or poorly supported in an AI answer. That leaves you with a harder problem than a rankings drop: you may not know which customer questions expose the gap or what would actually fix it.

    You need to see the whole journey. A person asks an AI system for an answer, evaluates the brands it names, and often moves to search or another source to verify what they were told. Your job is to make the brand eligible for the right answers, easy to verify, and consistent at every step.

    Follow the answer-to-verification journey

    A researcher compares an abstract AI answer with three visual source panels, following illuminated links that show where information agrees.

    AI search is not simply another source of referral traffic. It can compress discovery, explanation, comparison, and recommendation into a single response. A brand may influence a decision without receiving the click that would normally reveal that influence in analytics.

    Among 500 active AI users surveyed, 37% started searches with AI rather than Google, while 85% still cross-checked AI responses. Because the sample consisted of active AI users, the 37% figure should not be treated as a population-wide forecast. The behavioral pattern is still useful: AI can shape the first impression, while traditional search remains part of the verification process.

    That verification stage matters even when discovery happens within Google. A reported estimate puts B2B buyer exposure to Google’s AI Overviews as high as 72%, with brands sometimes appearing without generating a click. Visibility, traffic, and influence are therefore related metrics, but they are not interchangeable.

    Evaluate your brand at three checkpoints:

    • Answer eligibility: Is the brand genuinely relevant to the question, audience, location, and use case?
    • Answer representation: If the brand appears, is it described accurately and in the right role: recommendation, alternative, example, provider, or warning?
    • Verification continuity: Do search results, your website, expert profiles, reviews, publications, and community discussions support the answer rather than contradict it?

    This changes the unit of analysis. Instead of looking only at a keyword and its ranking URL, examine the decision prompt, the generated answer, the evidence attached to it, and the path a person would follow to confirm it.

    Map the prompts where your brand is legitimately relevant

    A strategist places colored tokens on glowing branching paths that connect groups of customer questions to an unbranded company marker.

    A brand-relevant prompt is a question for which your brand could reasonably form part of a useful answer. It is not every prompt containing a category keyword. If your product is unsuitable for the user’s situation, absence may be the correct outcome.

    Start with customer decisions, not a list of phrases you want to win. People use AI during commercial research as well as early discovery. Within the same active-user sample cited above, 57% used AI to find the best prices, 54% to compare products, and 48% to summarize reviews. Your prompt map should therefore cover evaluation and verification questions, not just broad category discovery.

    Prompt clusterExample questionWhat you need to assess
    Category discoveryWhich platforms help regulated companies manage customer communications?Whether the brand is associated with the correct category and audience.
    Problem and solutionHow can a finance team publish educational content without losing compliance control?Whether your expertise is visible before a buyer asks for vendors.
    ComparisonHow does [Brand] compare with [Competitor] for an enterprise team?Whether the answer uses accurate criteria, current capabilities, and credible evidence.
    Trust and riskIs [Brand] suitable for a regulated organization?Whether important qualifications, limitations, governance, and third-party signals are represented correctly.
    Branded verificationWhat does [Brand] do, and who is it for?Whether the basic entity facts remain consistent across AI answers, search results, profiles, and your site.

    Build the map as an operating sheet. Give each row a prompt, buyer stage, language and location where relevant, eligible brands, expected factual answer, observed answer, cited pages, accuracy status, and next action. Keep the exact prompt text so future checks are comparable.

    Then label eligibility before scoring visibility:

    <!– wp:list {
  • How to Capture AI-Driven E-commerce Demand on Black Friday

    How to Capture AI-Driven E-commerce Demand on Black Friday

    If your Black Friday plan stops at rankings, feeds, paid media, and conversion rate, it now has a blind spot. A shopper can ask an AI system to narrow a category, compare products, judge whether a discount is worthwhile, and recommend where to buy – without following the search journey you designed.

    Your job is not to make an AI repeat your promotion. It is to make your products easy to identify, compare, and verify while demand moves from early research to live deal hunting. That requires coordinated work across your own site, retailers, marketplaces, review coverage, video, and genuine customer discussion.

    Black Friday creates two different AI demand states

    A split scene contrasts calm product research at a desk with urgent mobile deal shopping at night.

    Before Black Friday, shoppers are reducing a large market into a shortlist. Their questions tend to concern suitability: which product fits a use case, what features matter, which compromises are acceptable, and whether waiting for a sale makes sense. When the event begins, the task changes. Price, availability, seller credibility, current sentiment, and the quality of the deal become more important.

    That change is visible in the domains AI systems use. In the week before Black Friday, retail and brand domains represented 59.6% of cited sources, media represented 23.4%, and social or user-generated content represented 17%. During Black Friday, the social and user-generated share rose to 25.1%, while retail and media lost share.

    Those percentages do not establish a permanent formula for every category or model. They do expose a useful operating distinction: the content that builds a shortlist is not sufficient on its own when shoppers want current confirmation from other people.

    Build your campaign around four information layers:

    • The identity layer explains what your brand sells, which categories it belongs in, and who its products are for.
    • The decision layer supplies specifications, use cases, limitations, compatibility details, and defensible comparisons.
    • The offer layer states the current price, discount terms, sale window, availability, fulfillment conditions, and applicable returns information.
    • The verification layer gives shoppers independent evidence through reviews, demonstrations, retailer listings, comparison coverage, and legitimate customer discussion.

    The first two layers should be settled before promotional demand arrives. The offer layer must be updated whenever the commercial facts change. The verification layer takes longer to earn, so it cannot be manufactured credibly on launch day.

    Make every offer answerable without reconstruction

    An AI system should not have to combine a slogan on your homepage, specifications in a PDF, a discount in a banner, and shipping terms in a support page to explain your offer. Every extra reconstruction step creates another opportunity for omission, confusion, or a stale answer.

    Start at the homepage because it is more than a navigational doorway. Within the examined brand-site citations, homepages accounted for 40%. Give that page a plain statement of what the brand is, the categories it serves, the customer problems it solves, and the main paths to product information. A clever campaign line can support that explanation, but it should not replace it.

    Then audit each priority product or offer page in this order:

    1. Use the exact product name and model consistently in the title, visible copy, structured data, retailer listings, and supporting content.
    2. State what the product is and who it suits near the top of the page. Do not make the reader infer the category from branding language.
    3. Present specifications as labeled facts. Include the dimensions, materials, capacity, compatibility, included components, or technical requirements that actually drive a decision in your category.
    4. Explain the important tradeoffs. A page that identifies who should not buy the product can be more useful than one that describes every shopper as an ideal customer.
    5. Place the live offer in visible text. Include the current price, reference price where applicable, conditions, start and end information, seller, stock state, and fulfillment details that a buyer needs to interpret the promotion.
    6. Add concise questions and answers for real research intents: compatibility, setup, maintenance, warranty, returns, common alternatives, and differences between adjacent models.
    7. Provide evidence close to the claim it supports. Demonstrations should show the use case, while reviews and technical documentation should be clearly attributable and reachable.

    Keep stable product facts separate from volatile promotional facts in your content workflow. The product’s dimensions should not change because a sale begins, but price and availability might. Assign ownership accordingly: merchandising maintains the offer state, while product or content teams maintain the underlying facts.

    Structured data can make those facts less ambiguous to machines, but it cannot rescue incomplete visible content. Product and Offer markup should agree with the page a shopper sees. If a price, availability value, model identifier, or seller differs between the markup and the page, the markup has added conflict instead of clarity.

    Finish with a manual extraction test. Give someone who did not build the page the URL and ask them to answer: What is this product? Who is it for? Why would they choose it over the closest alternative? What exactly is the Black Friday offer? What restriction could change the decision? If any answer requires another tab or an assumption, the page is not finished.

    Build comparison coverage before the promotion starts

    Brand pages are good at establishing first-party facts. Shopping recommendations require a second job: organizing choices and reducing uncertainty. That is why AI systems repeatedly draw from retailers, review publishers, video platforms, and community conversations when they construct commercial answers.

    Across 10,000 responses about deals, reviews, and product recommendations, YouTube received 1,509 citations, Best Buy 950, Walmart 885, Target 477, TechRadar 355, RTings 342, and Consumer Reports 325. The distribution was concentrated rather than evenly spread across the web.

    Retail concentration matters too. Generalist retailers held 48% of retail citations, while electronics specialists held 23%. Large retailers have broad assortments, familiar identities, and enough product information to answer many different shopping questions. A smaller brand is unlikely to reproduce that footprint, but it can make its category knowledge and product distinctions much easier to reuse.

    Create comparison pages around decisions, not around the phrase “best product.” A useful comparison should tell the reader:

    • Which products are genuinely comparable and which belong to a different use case.
    • What each option is best suited to, using a stated criterion rather than a vague superlative.
    • Which specifications materially change the experience.
    • What the buyer gives up by choosing the cheaper, smaller, faster, or more capable option.
    • Whether accessories, subscriptions, installation, or compatibility requirements affect the practical cost.
    • Which facts are stable product attributes and which are temporary Black Friday conditions.

    Publish first-party comparisons even when an independent reviewer would be more persuasive. Your version establishes accurate entities, specifications, and distinctions that other people can check. It should disclose its perspective and link to the underlying product details rather than pretending to be neutral.

    For third-party coverage, prioritize relevance over raw volume. Give suitable reviewers and publishers clean model names, current specifications, images, documentation, and access to products where your normal review policy allows it. Correct factual errors without trying to dictate conclusions. Inclusion in a trusted comparison is valuable because the comparison answers a real decision, not merely because it creates another brand mention.

    Treat off-site evidence as part of product information

    An unbranded device is connected to scenes of a reviewer, video creator, retailer display, and customer photo.

    Your website can declare what a product does. It cannot independently establish how the product behaves in ordinary use or how buyers feel about its compromises. AI shopping answers often seek that corroboration elsewhere.

    Within the observed set of key off-page signals, Reddit represented 34%, YouTube 19.5%, Amazon 15.5%, Business Insider 9.2%, and Walmart 8.9%. Treat these figures as evidence of concentrated influence in the examined responses, not as channel budgets or universal weights.

    Each environment contributes a different kind of evidence:

    • YouTube can show setup, scale, sound, motion, results, and other experiential details that are difficult to communicate in a specification table. Use accurate titles and descriptions, identify the exact model, and make spoken explanations clear enough to stand without promotional visuals.
    • Retailer and marketplace listings connect the product to a category, seller, price, reviews, and comparable inventory. Keep identifiers, variants, specifications, and images consistent with your own site.
    • Review coverage organizes alternatives and makes tradeoffs explicit. Give reviewers enough factual material to distinguish models without forcing them to decode your catalog.
    • Community conversations reveal recurring questions, edge cases, frustrations, and unexpected use cases. Use those conversations to improve product information and support. Do not simulate participation or manufacture endorsements.

    Consistency is the operational priority. If your site calls a product one name, a retailer shortens it, a video uses a family name, and marketplace variants omit the model number, you have created several weak identities instead of one strong one. Maintain a shared product record containing the approved name, model identifier, category, key specifications, variant labels, current imagery, and canonical URL. Give every channel owner access to it.

    Do not turn this into a backlink-counting exercise. A mention that does not help identify, compare, or verify the product contributes little to the shopping decision. Audit off-site presence by question instead: Where can a shopper see the product used? Where can they compare it with the nearest alternative? Where can they verify specifications? Where can they find credible discussion of its limitations?

    Run a two-phase AI visibility operation

    Black Friday AI optimization should operate in a preparation phase and a live phase. The preparation phase builds retrievable facts and comparison context. The live phase protects accuracy while offers, availability, and public conversation change.

    Before the promotion, build a fixed prompt set from customer decisions rather than from your target keywords alone. Include category discovery, a constrained use case, a direct product comparison, a compatibility question, a value question, and a deal-verification question for every priority category. Keep the wording stable enough that later results are comparable.

    Run those prompts separately on the AI platforms your customers are likely to use. Do not collapse their responses into one score. In the observed Black Friday sample, Gemini responses averaged 606 words, OpenAI responses averaged 401, and Perplexity responses averaged 288. Those are sample characteristics, not permanent product specifications, but they show why a citation or mention can play a different role on each platform.

    Use one tracking row for each prompt and platform. Record:

    • The exact prompt, model or product name, and time of the check.
    • Whether the brand and correct product appear.
    • How the product is framed: recommended, compared, merely listed, or excluded.
    • Which URLs support the answer.
    • Whether the price, specifications, seller, availability, and promotion terms are accurate.
    • Which competitor or third-party page supplied information you did not make easy to find.
    • The correction required: page content, structured data, marketplace data, comparison coverage, video, or support documentation.

    At sale launch, rerun the deal and verification prompts. Repeat the check after any material price, inventory, seller, or terms change. If an answer is wrong, correct the authoritative page and connected listings first. A prompt variation may produce a different answer, but it does not repair the underlying information conflict.

    Judge progress by failure mode rather than by a single visibility number. A missing brand is a discovery problem. The wrong model is an identity problem. An incorrect price is a freshness problem. A competitor winning every comparison may indicate weak decision content or stronger independent corroboration. Each diagnosis leads to different work.

    Key takeaways

    • Plan separately for pre-sale research and live deal verification because the source mix changes when Black Friday begins.
    • Give every priority offer a clear identity, complete decision facts, current commercial terms, and evidence a shopper can verify.
    • Build comparisons around use cases and tradeoffs, not unsupported claims that a product is “best.”
    • Coordinate product information across your site, retailers, marketplaces, video, review coverage, and community support.
    • Test the same customer decisions across AI platforms and classify failures before choosing a fix.

    Before your next promotion, choose one prompt for each major customer decision in your highest-value category. Run the set when product pages are frozen, again when the sale launches, and whenever a material offer fact changes. The gaps you find will give your content, merchandising, SEO, marketplace, and communications teams a concrete Black Friday worklist – before shoppers ask AI to make the choice for them.

    References

  • Google Discovery and Local Visibility: A Practical Plan

    Google Discovery and Local Visibility: A Practical Plan

    If your business appears when someone searches its name but disappears when they search for a service nearby, you don’t have a single ranking problem. You have a discovery mismatch. Google can surface a business through the Local Pack, cite a page in AI Mode, group it under a Web Guide topic, or favor a publisher a searcher has deliberately chosen.

    Your job is to determine which discovery path matters for each query, then give that system the information and evidence it needs. That calls for more precision than completing the same SEO checklist for every location.

    Map the Google surface before you change the page

    A strategist sorts query tokens across a blank city map into routes leading to a map pin, an AI-like orb, page clusters, and editorial sheets.

    A conventional rank tracker can tell you where a URL appears, but it may not explain what now occupies the useful part of the results page. Start by identifying the surface that answers the query:

    • Local Pack: The searcher is choosing a nearby business. Location, category relevance, operating details, reputation and local behavior matter more than a generic national content campaign.
    • AI Mode: Google synthesizes an answer and may attach links to particular claims or branches of the question. Google has been adding more inline links and contextual introductions that explain why a linked page may be useful.
    • Web Guide: Google organizes links into topic groups rather than presenting one undifferentiated list. Its custom version of Gemini interprets the query and page content, while query fan-out runs multiple related searches. The expansion into the all tab still required a Search Labs opt-in, so you shouldn’t assume every searcher sees the same layout.
    • Preferred Sources: This applies to publishers appearing in Top Stories. A searcher can choose publications they want Google to show more often when those publications have relevant, recent coverage.

    Create a query map with a row for each commercially important search. Record the likely intent, the dominant Google surface, the location implied by the query, the page or profile you expect to qualify, and what actually appears. A query such as “accountant near me” needs a different asset from “how to choose an accountant for a growing company,” even when both ultimately support the same business.

    This diagnosis prevents a common waste of effort: rewriting an informational page when the Local Pack owns the decision, or editing a Google Business Profile when Google is looking for a page that answers a detailed question.

    Build signal fit into every Google Business Profile

    Profile completeness is a baseline, not a complete local strategy. Google is trying to identify which nearby result best fits what people expect from that kind of business. Those expectations change by category and can vary by region.

    A Yext analysis of 8.7 million Google Business Profiles found that review activity, profile information and visual content did not carry the same apparent importance across every industry. Because this was a vendor analysis of observed profiles, it should guide prioritization rather than be treated as proof of a universal ranking formula.

    Business typeSignals to inspect firstPractical response
    HospitalityHours, descriptions and complete practical informationMake arrival, availability and operating details easy to verify before investing in more image volume.
    HealthcareReviews, accurate hours and clear location detailsRemove uncertainty about access and reliability. Check every location independently.
    RetailReview volume, sentiment and listing upkeepTreat reputation and profile maintenance as operating signals, not occasional marketing tasks.
    Food and diningRatings and continuing engagement with feedbackMonitor new reviews and respond sincerely; basic completeness alone may not distinguish a competitive listing.
    Financial servicesGenuine reviews and real-world reputationPrioritize trust evidence over accumulating polished photos that add little decision value.

    Use three layers when you audit a location. First, verify the stable identity: business name, address, phone number, primary category, hours and destination URL. Second, inspect the signals customers use to choose within your category. Third, compare the location with nearby competitors serving the same intent. A national average can hide the gap that determines whether one branch appears locally.

    Don’t copy a successful location’s profile changes across the entire estate in one move. A restaurant in one region may benefit from a feature that produces no meaningful difference elsewhere. Test the change on comparable locations, keep the untouched profiles as a reference where practical, and judge the result using both visibility and customer actions.

    Reviews deserve an operating process of their own. Ask real customers for honest feedback without scripting the sentiment. Route new reviews to the person who can answer them accurately. A quick, specific response shows that the location is active; a batch of generic replies creates activity without adding much trust.

    Publish pages that fit a branch of the search journey

    AI-organized search makes broad relevance less useful than precise usefulness. Web Guide can fan a query out into related searches and group the resulting pages by facet. AI Mode can then present a link next to the part of an answer it supports. Neither feature means you should generate a page for every wording variation. It means each worthwhile page should have a clear job.

    1. Break the query into genuine decision branches. Someone looking for an emergency dentist may need to know whether the practice is open, which urgent problems it handles, where it is and how to contact it. Those are user needs, not keyword variants.
    2. Assign each branch to the right asset. Put operating facts on the location page and profile. Use a focused service page for a service that needs explanation. Use an educational page when the person is still deciding what kind of help they need.
    3. State the page’s value early. Identify the service, audience, location and question being answered before drifting into background copy. A visitor following an inline AI link should be able to confirm immediately that the page matches the context around that link.
    4. Supply verifiable detail. Include the facts a customer would need to act, such as availability, eligibility, process, location or limitations, when they genuinely apply. Replace generic claims with information the business can keep current.
    5. Connect the page to the location. Keep business identity, service descriptions and operating details consistent with the corresponding Google Business Profile. Link users to the appropriate location rather than forcing them through a generic homepage.

    Applicable LocalBusiness structured data can describe facts already visible on the page and reduce ambiguity about the entity. Use it as a consistency layer. It cannot compensate for stale hours, a mismatched category, weak reputation or a page that never answers the query.

    Avoid mass-produced city pages that change only the place name. They don’t give Google a distinct facet to retrieve, and they give the reader no local reason to trust the page. Create a separate location page when you can maintain distinct operating facts, directions, services or other genuinely local information.

    Use Preferred Sources only when you are really a publisher

    Preferred Sources can be valuable for a local news organization, trade publication or other site that regularly qualifies for Top Stories. It is not a general local ranking switch for every service business.

    Google expanded the feature globally for English-language users after launches in the United States and India. Searchers use the star beside Top Stories to choose publications they prefer, and Google can show more of those publications’ recent work when it is relevant. People have selected nearly 90,000 sources, ranging from local blogs to global outlets.

    Google also reported that people clicked a chosen publication about twice as often on average. That does not mean asking readers to select you will double traffic. People who deliberately choose a publication are already more likely to value it, and relevance and freshness still determine whether suitable coverage exists.

    If the feature fits your publication, add a brief instruction near the places where loyal readers already engage, such as a subscriber message or membership page. Explain what the star does and let the reader decide. Then maintain a dependable publishing rhythm around the local topics for which you want to be found. Preference cannot make an unrelated story relevant.

    If you run a clinic, restaurant, retailer or professional practice without a genuine news operation, leave this tactic alone. Put the effort into the Local Pack, location pages and useful answers connected to your services. A feature being available does not make it appropriate to your discovery problem.

    Measure each location and discovery surface separately

    An analyst compares six separate abstract measurement panels positioned above different miniature neighborhoods and storefronts.

    A single visibility score conceals too much. Local results depend on the searcher’s location. AI and experimental layouts can differ by account or feature access. Preferred Sources are explicitly personalized. Keep the measurements separate enough to tell which change produced which result.

    • For the Local Pack: Check a stable set of query-and-location combinations. Record whether the correct branch appears, which competitors surround it, and whether profile actions such as calls, website visits or direction requests change when those measurements are available.
    • For standard organic and Web Guide discovery: Group Search Console queries by intent rather than tracking isolated wording. Watch the landing pages receiving impressions and clicks, and annotate meaningful page revisions.
    • For AI surfaces: Record the exact query, observed linked page and context in which the link appeared. Keep the account state and test conditions consistent enough to make repeated observations useful. Treat a single appearance as a lead to investigate, not proof of stable inclusion.
    • For Preferred Sources: Monitor relevant Top Stories appearances and returning search traffic. Separate that audience from first-time discovery so loyalty does not disguise weak reach.

    Change one class of signal at a time where practical. If you revise categories, hours, photos, landing pages and review outreach together, even a positive result won’t tell you what to repeat. Compare similar locations, preserve a baseline and look for movement in both discovery and the user action tied to the query.

    Key takeaways

    • Identify whether the query is governed by a local choice, an AI answer, a grouped web result or a publisher preference before editing anything.
    • Complete every Google Business Profile, then prioritize the reputation, access, information or engagement signals that matter in that location’s category.
    • Build pages around real branches of intent, not slight keyword or city-name variations.
    • Use structured data to reinforce visible, accurate facts; don’t treat markup as a substitute for content or profile maintenance.
    • Reserve Preferred Sources promotion for sites that genuinely publish timely material and can appear in Top Stories.
    • Measure locations and discovery surfaces separately so you can connect a change with an outcome.

    Start with one revenue-relevant query and one location. Identify the surface that controls the decision, find the largest mismatch between user intent and your profile or page, and correct that mismatch. Once you can see what changed in visibility and customer action, apply the lesson to the next comparable location.

    References

  • Keyword-Rich Google Reviews: A Practical Local SEO System

    Keyword-Rich Google Reviews: A Practical Local SEO System

    If your review request says only, Please leave us a review, you are leaving the hardest part to the customer: deciding what to write. Most people respond with a star rating and a few generic words. That may reflect a happy customer, but it tells Google and the next buyer very little about what your business actually does.

    You can get more useful Google reviews without telling customers which keywords to insert. The better approach is to ask a few experience-based questions that help them remember the service, product, need, attribute, or outcome that mattered. Their answers stay authentic while becoming far more relevant to local search and purchase decisions.

    Why specific review language matters beyond rankings

    Keywords inside reviews are not a dependable shortcut to higher local rankings. Their direct ranking influence remains debated, so no honest review strategy should promise a position change. The stronger case is visible on the search result and Business Profile itself: specific review language can shape review justifications, Place Topics, highlighted snippets, menu features, AI-generated summaries, and answers to customer questions.

    That distinction should change your goal. You are not trying to manufacture a ranking signal. You are building a body of customer evidence that helps Google understand your offerings and helps a searcher confirm that you handle the exact need behind their query.

    The same restraint applies to AEO and GEO claims. Detailed reviews can improve the material available to Google’s local AI features. That does not establish that repeating keywords will make every external AI assistant or frontier model recommend your business. Keep the promise tied to the surfaces you can actually observe.

    Key takeaways

    • Ask customers about their experience, not about your target keywords.
    • Prompt for the service or product, the original need, one distinguishing detail, and the outcome.
    • Use different prompts for different customer journeys instead of sending one universal script.
    • Let every customer choose their own language; similar reviews should not read as if one person wrote them.
    • Measure review specificity and visible Business Profile features before treating rankings as an outcome.

    Seven places where detailed reviews can do useful work

    A review does not stay confined to the review tab. Google can reuse its language across several parts of the local experience. Each surface affects discovery or decision-making differently.

    1. Review justifications: A relevant phrase from a review can appear with a local result and help explain why that business matches the query. A searcher looking for a particular repair, treatment, product, or service can see direct customer evidence before opening the profile.
    2. Place Topics: Google can turn recurring review terms into clickable topics. These labels advertise the subjects customers repeatedly discuss and let people filter the review set around a particular interest.
    3. Highlighted review snippets: Frequently relevant terms can be bolded within three review snippets on a Business Profile. The effect is small but useful: the language connected to the searcher’s need becomes easier to scan.
    4. Menu Highlights: For restaurants, Google can derive highlighted dishes and menu themes from customer reviews and photos. Reviews that naturally name a dish, drink, dietary option, or dining occasion give this feature more precise material to work with. Any ranking benefit should still be treated as possible rather than guaranteed.
    5. AI-generated business attributes: Google can use review language to describe qualities such as a cozy atmosphere. You cannot directly edit that generated description, but detailed and consistent customer observations give the system clearer evidence than a collection of reviews saying only that everything was great.
    6. AI review summaries: Repeated sentiments can be condensed into a summary of what customers commonly appreciate or criticize. Specific feedback makes that summary more informative because it connects sentiment to a service, product, attribute, or part of the experience.
    7. Answers to customer questions: Review content can help Google answer questions about a business. A detailed review may therefore remain useful long after publication by supplying information relevant to a future customer’s question.

    These features share one requirement: Google needs meaningful language to extract. A generic compliment contains positive sentiment but almost no context. A review that identifies what was purchased, why it was needed, and what stood out contains entities, attributes, and relationships that both machines and people can interpret.

    Build prompts around the experience, not a keyword list

    A business professional invites a customer to recall the need, service, quality, and outcome while leaving feedback on a phone.

    Start with what customers can truthfully describe. Search volume may help you understand demand, but it should not determine the words you ask a reviewer to use. If the requested phrase does not sound like a customer’s memory of the transaction, the resulting review will feel staged.

    A practical prompt has four core ingredients. Local context can be added when the location was genuinely part of the service, but it should never be tacked onto every review merely to repeat a city name.

    Prompt ingredientWhat it capturesNatural question
    OfferThe service, product, treatment, dish, or categoryWhat did you choose or ask us to help with?
    Need or occasionThe problem, use case, event, or buying intentWhat brought you to us?
    AttributeA meaningful quality of the work or experienceWhat part of the experience stood out?
    OutcomeThe result or change the customer experiencedHow did things turn out?
    Local contextA service area, venue, or neighborhood that was actually relevantWhere did the service take place, if that detail would help someone else?

    You rarely need all five ingredients in one message. Choose the two or three that fit the transaction. A restaurant customer can name a dish, an occasion, and an atmosphere. A home-service customer can name the repair, the initial problem, and the result. A consultant’s client may be better able to discuss the project, an aspect of the process, and the business outcome.

    1. Inventory real customer journeys. List the major services, product groups, menu categories, or project types people actually buy. Use customer-facing names rather than internal department labels.
    2. Identify details customers can observe. Focus on attributes they experienced directly, such as the item ordered, the issue addressed, the communication they received, or the atmosphere they encountered. Do not prompt them to endorse a claim they cannot verify.
    3. Turn each detail into a memory cue. Ask what they chose, what brought them in, what stood out, or how the situation ended. A question produces natural language; an exact phrase produces compliance.
    4. Match the prompt to the transaction. Connect your review system to the service or product category so a customer receives relevant cues. This also prevents every review from repeating the same structure.
    5. Leave authorship with the reviewer. State that they should use their own words and include only details that reflect their experience. Never provide a completed testimonial for them to paste.

    Consider the difference between telling a customer to mention emergency furnace repair Toronto and asking what problem brought them in, which service they received, and what happened afterward. The first request exposes the SEO agenda. The second can elicit the same relevant concepts if they are true, without dictating the review.

    Review request templates that produce natural detail

    Use these as frameworks, not universal scripts. Replace the bracketed text, remove any cue that does not fit, and place your direct Google review link at the end. Send the request while the experience is still easy for the customer to recall.

    For an appointment or local service

    Template: Thank you for choosing [business name]. If you would like to leave an honest Google review, it helps other customers when you mention what you needed help with, which service you received, and what stood out. Please use your own words and include only what reflects your experience: [review link]

    This version can naturally produce a service name, a problem, and an attribute. If your business offers many services, populate the message with the broad category the customer actually purchased, but do not insert a target phrase and ask them to repeat it.

    For a restaurant, cafe, or product-led visit

    Template: Thanks for visiting [business name]. If you leave a Google review, you might tell people what you ordered, what you especially noticed, and what kind of visit or occasion it suited. Your honest experience in your own words is what matters: [review link]

    Naming an actual dish or product gives Google more useful material for topics, snippets, and restaurant highlights. The occasion can be equally valuable because a future customer may be deciding whether the business suits a family meal, quick lunch, special event, or another specific need. Keep only the examples that are accurate for your business; do not seed an occasion the customer did not mention.

    For a longer project or professional engagement

    Template: Thank you for working with [business name] on [project category]. If you are comfortable leaving a Google review, it would be useful to describe what you wanted to accomplish, any part of the process that mattered to you, and the outcome. Please share only what you experienced and use your own wording: [review link]

    Longer engagements often contain more detail than a customer can fit into an unprompted response. The three cues give the review a useful arc without scripting praise: initial need, experienced process, and outcome.

    Whichever template you use, keep the request easy to answer. A long questionnaire creates work, and a customer may abandon it or respond mechanically. Three short cues are usually enough to unlock detail while preserving freedom.

    Measure review quality without turning it into keyword policing

    Two colleagues sort varied review cards by detail and usefulness using icons, colored trays, a magnifying glass, and an authenticity symbol.

    Do not evaluate this program only by searching your target phrase and watching the map order. Local results can move for many reasons, and a ranking-only scorecard encourages increasingly aggressive prompts. Measure the change you directly asked customers to make: more specific, more informative feedback.

    Use a small review-quality scorecard

    Choose a consistent review window and record the same fields for every new review. You do not need sophisticated sentiment software to begin.

    • Detail rate: What share of new reviews names at least one actual service, product, menu item, need, attribute, or outcome?
    • Priority-topic coverage: Which important customer journeys appear in reviews, and which remain absent?
    • Language diversity: Do customers describe similar experiences in their own ways, or do the reviews repeat your request almost word for word?
    • Profile presentation: Are relevant Place Topics, review justifications, highlighted snippets, menu features, or AI summaries appearing or changing?
    • Customer response: Are the profile interactions and leads you already track improving alongside richer reviews? Treat correlation as a reason to investigate, not automatic proof of causation.

    If detail rate improves but every review sounds alike, the prompt is too prescriptive. If reviews remain generic, the cues may be too broad. If one service dominates the language, segment the request so other genuine customer journeys receive prompts suited to them.

    Watch for five signs that optimization has gone too far

    • You ask reviewers to include an exact search query.
    • You add a city or neighborhood even when location was irrelevant to the experience.
    • You provide a finished sentence for the customer to paste.
    • You send every customer a long list of services and attributes to mention.
    • You judge success by keyword counts while ignoring whether the review helps a buyer make a decision.

    The corrective action is simple: replace the desired wording with a question about the real experience. If you want reviews to mention a service, ask what the customer needed. If you want a relevant attribute to emerge, ask what stood out. If you want outcome language, ask what changed. The customer’s answer determines whether the concept belongs in the review.

    Start with the customer journey that generates the most review requests. Replace the generic ask with three cues covering the actual offer, one memorable detail, and the outcome. Once new reviews become more specific without becoming repetitive, adapt the same structure to the next journey. You will end up with reviews that sound like customers, explain the business clearly, and give Google’s local features something meaningful to use.

    References

  • Generative AI in Customer Purchasing: What to Optimize

    Your customer may ask an AI assistant to define the problem, find suitable products, compare a shortlist, and check the final choice before your analytics records a visit. If your decisive information is vague, inconsistent, or trapped behind a sales conversation, the assistant has little reliable material with which to represent you.

    The practical response is not to publish more generic AI content. It is to make each buying decision easier to answer, verify, and act on. That means choosing the right purchase questions, publishing concrete evidence, aligning your structured data with the page, and measuring influence beyond referral clicks.

    Key takeaways

    • Organize your strategy around four customer jobs: problem solving, discovery, comparison, and validation.
    • Use industry adoption figures as a directional signal, then confirm the opportunity with your own customer, sales, search, and revenue data.
    • Give AI systems explicit facts about suitability, limitations, price basis, availability, location, and tradeoffs. Marketing adjectives cannot substitute for decision evidence.
    • Keep important claims consistent across visible content, structured data, product feeds, listings, and supporting pages.
    • Measure whether your brand is represented accurately and influences purchases, not merely whether an AI assistant sends a clickable referral.

    Map the purchase job before you choose what to optimize

    Generative AI does not have one fixed role in purchasing. A customer asking how to solve a problem needs a different answer from someone comparing two named options. Treating both prompts as broad product discovery produces shallow content and weak measurement.

    Across the industries examined in a 2025 purchasing analysis, AI appeared in four recurring parts of the journey: problem solving, discovery, comparison, and validation. Use those jobs to map the questions that precede a purchase:

    Purchase jobWhat the customer is trying to decideWhat your content must provide
    Problem solvingWhat kind of solution fits this situation?A plain explanation of the problem, relevant options, constraints, risks, and the conditions under which each option makes sense.
    DiscoveryWhich products, services, providers, or programs meet the requirements?Explicit eligibility, use cases, location, schedule, availability, price basis, and other attributes that determine inclusion.
    ComparisonWhich shortlisted option offers the best fit?Like-for-like criteria, measurable differences, tradeoffs, exclusions, and evidence for each material claim.
    ValidationIs the preferred choice credible, current, and safe to act on?Terms, limitations, proof, policies, implementation details, review dates, and a clear next step.

    Start by collecting the actual questions customers ask in sales calls, support conversations, on-site search, search-query data, reviews, and post-purchase feedback. Label each question by purchase job. If one question spans two jobs, split it. A query about the best accounting platform for a construction company is discovery; a query comparing two named platforms for that company is comparison.

    Industry figures can help you decide where this work deserves attention, but they do not replace first-party evidence. Among 3,161 people surveyed online about their behavior over the previous year, reported use varied substantially by sector. Responses were screened for consistency and weighted for demographic and industry representation, but the results remain self-reported and should be treated as directional rather than as a universal market benchmark.

    IndustryCustomers reporting AI use in the purchase journeyProminent purchase jobsInformation to make explicit
    Education61%Discovery, comparison, validationProgram focus, schedule, format, suitability, and the facts a prospective student needs to verify a shortlist.
    Food & beverage59%Problem solving, discoveryRecipe use, product purpose, relevant constraints, and the conditions in which a recommendation fits.
    Lifestyle, health & wellness54%Problem solving, discoveryIntended use, suitability, limitations, supporting evidence, and safety boundaries.
    Travel & hospitality53%DiscoveryLocation, itinerary fit, accommodation details, transport options, availability, and booking constraints.
    Retail & CPG49%Problem solving, discovery, comparisonSpecifications, variants, compatibility, price basis, availability, and differences between plausible options.
    Automotive46%ComparisonConsistent specifications and tradeoffs that help a buyer narrow the field to two or three models.
    Healthcare44%Problem solving, discoveryEducational information, service scope, technology capabilities, evidence, limitations, and clear boundaries around individualized medical decisions.
    Home services41%Discovery, comparison, validationService area, cost factors, provider qualifications, scope, exclusions, and how an estimate becomes a quote.
    B2B SaaS41%Problem solving, discovery, comparisonIndustry fit, use cases, platform differences, requirements, limitations, and the facts needed to validate a shortlist.

    Do not rank opportunities by adoption percentage alone. A modest-volume decision with high purchase value or severe consequences may deserve better content before a high-volume, low-value query. Prioritize the intersection of five conditions:

    • Customers already use AI, or are likely to use it, for the decision.
    • The decision has meaningful commercial value.
    • You possess reliable facts that can improve the answer.
    • An inaccurate answer could exclude your brand, mislead the buyer, or create safety, financial, or legal exposure.
    • Your offer has a real distinction that can be expressed as evidence rather than a slogan.

    Be careful with revenue projections. The percentage of customers who used AI somewhere in a journey is not the percentage of revenue caused by AI. Multiplying an industry’s market value by an adoption percentage may describe a broad area of exposure, but it does not establish incremental sales, attribution, or return on optimization work.

    Build an answer asset for each stage of the journey

    A single commercial page rarely answers every purchase job well. The better approach is a connected set of answer assets, each designed around one decision and linked to the pages that supply deeper evidence.

    Problem-solving content should diagnose the decision, not the person

    Open with the situation in the customer’s language. Explain the available solution categories, the constraints that change the answer, and when your category is not appropriate. Only then connect the problem to a product or service.

    A useful problem-solving page answers questions such as:

    • What is the customer trying to accomplish?
    • Which facts materially change the recommendation?
    • What are the plausible approaches?
    • Who is each approach suitable or unsuitable for?
    • What information is still required before someone can act?

    Health, wellness, financial services, fintech, and insurance require stricter boundaries. Do not let educational content diagnose an individual, prescribe treatment, promise a financial outcome, or present an estimated insurance price as a guaranteed quote. State the limitation where the recommendation appears and direct individualized decisions to an appropriately qualified medical, financial, insurance, or legal professional.

    Discovery content must expose the attributes that control fit

    Discovery prompts are usually constraint problems in conversational form. The customer wants an option that works in a location, on a schedule, within a budget, for a use case, or with a required feature. If those attributes are missing, an AI system must omit the option or infer facts you did not provide.

    Write the decisive attributes as clear text, not as implications. A school should state when and how a program is offered. A home-service provider should name the service area and explain the factors that change cost. A retailer should distinguish product variants and compatibility. A software company should define the supported use cases and material requirements. When a fact is unavailable, say that it is not published or requires confirmation; do not fill the gap with a guess.

    Discovery content also needs honest exclusion criteria. A page that explains who should not choose the offer gives the buyer a usable boundary and makes the positive fit more credible.

    Comparison content needs symmetry

    Comparison fails when one option is described with detailed, current facts and another with vague or outdated language. Define the criteria first, use the same unit and scope for every option, and separate verified facts from editorial judgment.

    A defensible comparison page should include:

    • The audience and use case for which the comparison is intended.
    • The criteria that materially affect the decision.
    • A like-for-like table with the same fields for every option.
    • Tradeoffs, missing information, and conditions that could change the conclusion.
    • Links to the evidence behind consequential claims.
    • A visible review date for facts that can change.

    Do not manufacture a favorable winner by choosing irrelevant criteria or by asserting unpublished competitor details. If your product is not the best fit for a scenario, say so. The page becomes more useful because the recommendation is conditional rather than predetermined.

    Validation content should remove the final uncertainty

    Validation happens after the customer has a preferred option. The remaining questions concern trust, current terms, suitability, and execution. This is where unsupported superlatives are least helpful.

    Connect the recommendation to primary evidence: current product or service details, documented policies, relevant qualifications, implementation requirements, limitations, and a clear path for confirming anything that depends on the individual buyer. Keep testimonials and reviews in their proper role. They can show experience, but they do not replace technical specifications, eligibility rules, contractual terms, or professional advice.

    Use the same brief for every answer asset. Define the question, audience, direct answer, best-fit conditions, poor-fit conditions, comparison criteria, evidence, facts requiring regular review, and next action. That structure gives editors, subject-matter experts, SEO teams, and schema implementers a shared definition of completeness.

    Make decisive facts extractable, consistent, and verifiable

    Good prose and technical optimization solve different parts of the problem. The page must explain the decision to a person, while its facts must also be represented consistently enough for search engines and AI systems to retrieve and interpret them.

    1. Put the direct answer and its qualifications in visible page text. Do not leave essential facts only in an image, downloadable document, configurator, or interactive element.
    2. Use stable names for the organization, product, service, location, and plan. Avoid switching between labels in ways that make one entity look like several.
    3. Present comparable attributes in predictable fields. Tables work well when every row uses the same definition, scope, and unit.
    4. Link consequential claims to the page that proves or governs them. A summary page can simplify the decision without becoming the sole authority for every detail.
    5. Add only the structured data that the page and business actually support. Markup should clarify visible facts, not introduce a second version of them.
    6. Assign an owner to facts that change. When price, availability, schedules, coverage, terms, or eligibility changes, update the visible content, structured data, feeds, and supporting pages together.

    For JSON-LD, choose the most specific applicable Schema.org type rather than the type with the most available properties. A product page may legitimately use Product and Offer information; a business entity may need Organization or an applicable LocalBusiness subtype. The correct choice depends on what the page actually represents. Do not mark up inferred ratings, generated testimonials, unavailable offers, or facts that users cannot verify on the page.

    Structured data reduces ambiguity, but it does not guarantee an AI citation, recommendation, or ranking. It also cannot repair thin or contradictory content. Treat it as a machine-readable agreement with the visible page: the entity, attributes, offer, availability, and supporting evidence must tell the same story in both places.

    Run a consistency check before publishing. Compare the answer asset with product pages, pricing pages, location pages, business listings, feeds, policy pages, and JSON-LD. A small factual mismatch can change the recommendation: a service area that differs between pages, a price with an unclear billing period, or a plan name that no longer exists.

    Measure representation and purchasing influence, not just clicks

    AI-assisted purchasing can occur without a conventional referral. A customer may read an answer, remember a brand, navigate directly, and buy later. Referral analytics therefore show one useful behavior, not the whole journey.

    Measurement layerWhat to recordWhat it helps you decide
    VisibilityWhether your brand, product, or service appears for a controlled set of purchase prompts, and whether the answer cites one of your pages.Which purchase jobs and answer assets have discoverability gaps.
    Representation accuracyWhether important attributes, limitations, prices, locations, and comparisons are stated correctly.Which factual gaps or contradictions require correction before greater visibility is desirable.
    EngagementAI referral sessions when a referrer is available, landing-page behavior, qualified inquiries, and assisted conversions.Whether visibility reaches the right page and produces useful customer action.
    Purchase influenceCustomer-reported AI use, the assistant used when remembered, the question asked, and the role the answer played.Whether AI contributed to discovery, comparison, validation, or the final choice even when no referral was captured.

    Build the prompt set from real customer language. Include the problem-led questions that open the journey, the category and local discovery questions that form a shortlist, named comparisons, and the validation questions that appear near conversion. Record the intended audience, location, constraints, and purchase stage so that a change in wording does not silently change what you are measuring.

    Establish a baseline before editing. Save the answer, cited pages, brand inclusion, factual errors, and unsupported claims for each prompt. Then change a focused group of answer assets and repeat the same checks on a fixed cadence. AI responses can vary, so look for recurring representation patterns rather than treating one generated answer as a permanent ranking.

    Add a direct attribution question to inquiry and post-purchase forms: Did an AI assistant help you research or choose? If the customer says yes, ask which part of the decision it influenced and provide an optional field for the question they asked. Keep an unknown option; forcing a precise answer creates cleaner-looking but less trustworthy data.

    Your first move should be narrow. Choose one commercially important purchase job, publish the answer asset that resolves it, align its visible facts and schema, and instrument the conversion path for AI-assisted discovery. Expand only after you can see whether customers are finding the answer, whether your offer is represented correctly, and whether that representation helps a real purchasing decision.

    References