Tag: Consumer Behavior

  • Google Shopping Product Q&A Feeds: A Practical Rollout

    Google Shopping Product Q&A Feeds: A Practical Rollout

    A shopper does not need another adjective about your product. They need to know whether the leggings become see-through when stretched, whether the accessory fits their device, or whether installation requires a part that is not included.

    Google Merchant Center’s question_and_answer attribute gives you a structured place to resolve those purchase-blocking doubts. The useful way to approach it is not to fill every available field. It is to identify the questions that change buying decisions, answer them with verified product facts, and test the feed on a controlled group of items before expanding it.

    Key takeaways: treat Q&A as decision data

    • Use the attribute for product-specific questions whose answers could change whether someone buys, which variant they choose, or how they use the item.
    • Start with questions already reaching customer service and concerns appearing in product-return reasons.
    • Prioritize products where compatibility, suitability, sizing, materials, installation, or usage conditions create real uncertainty.
    • Validate every answer with the team that owns the underlying product information.
    • Launch with a limited product group, confirm that Google processes the data correctly, and fix your workflow before scaling.
    • Do not promise a ranking, CPC, or ROAS improvement. The immediate objective is more complete and reliable product information.

    The attribute supports up to 30 product-specific Q&A entries for each item. That is a ceiling, not a completion target. A product with four decisive questions needs four strong answers, not 26 weak variations written to occupy space.

    This distinction matters as shopping becomes more conversational. Someone may no longer search only for a broad category such as gym leggings. They may ask whether a particular pair is suitable for running and weight training or becomes transparent under stretch. Supplying an exact answer may help Google understand the product in that context, including conversational experiences such as AI Mode. It does not guarantee that the product will receive greater visibility.

    Find questions at the points where buyers hesitate
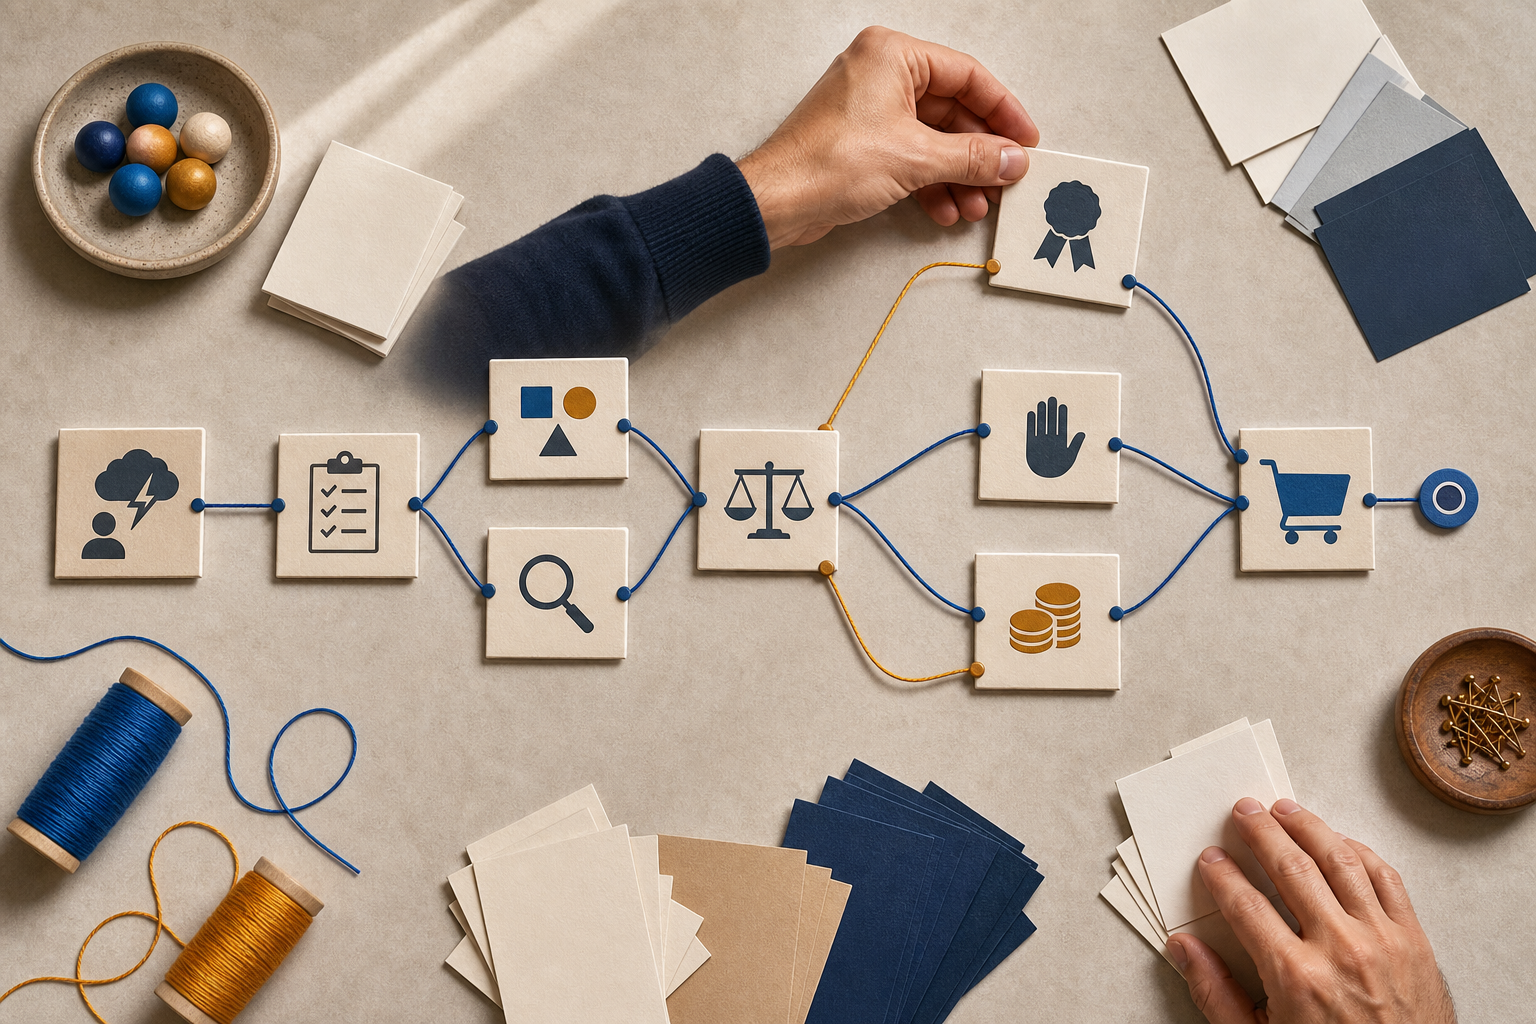
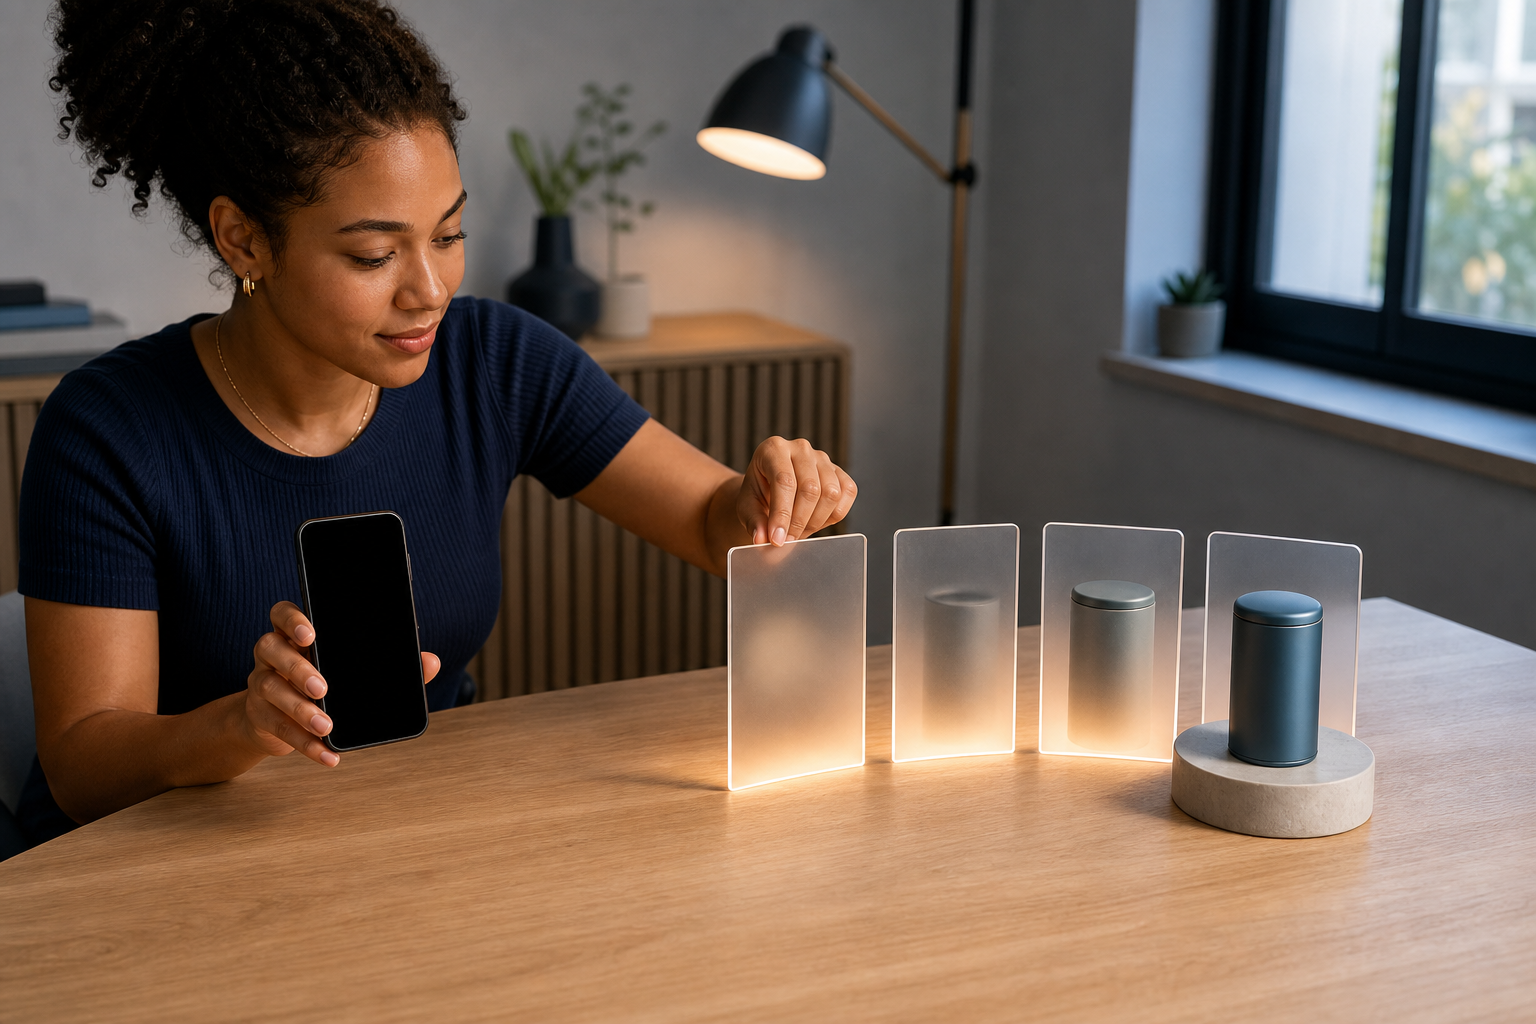
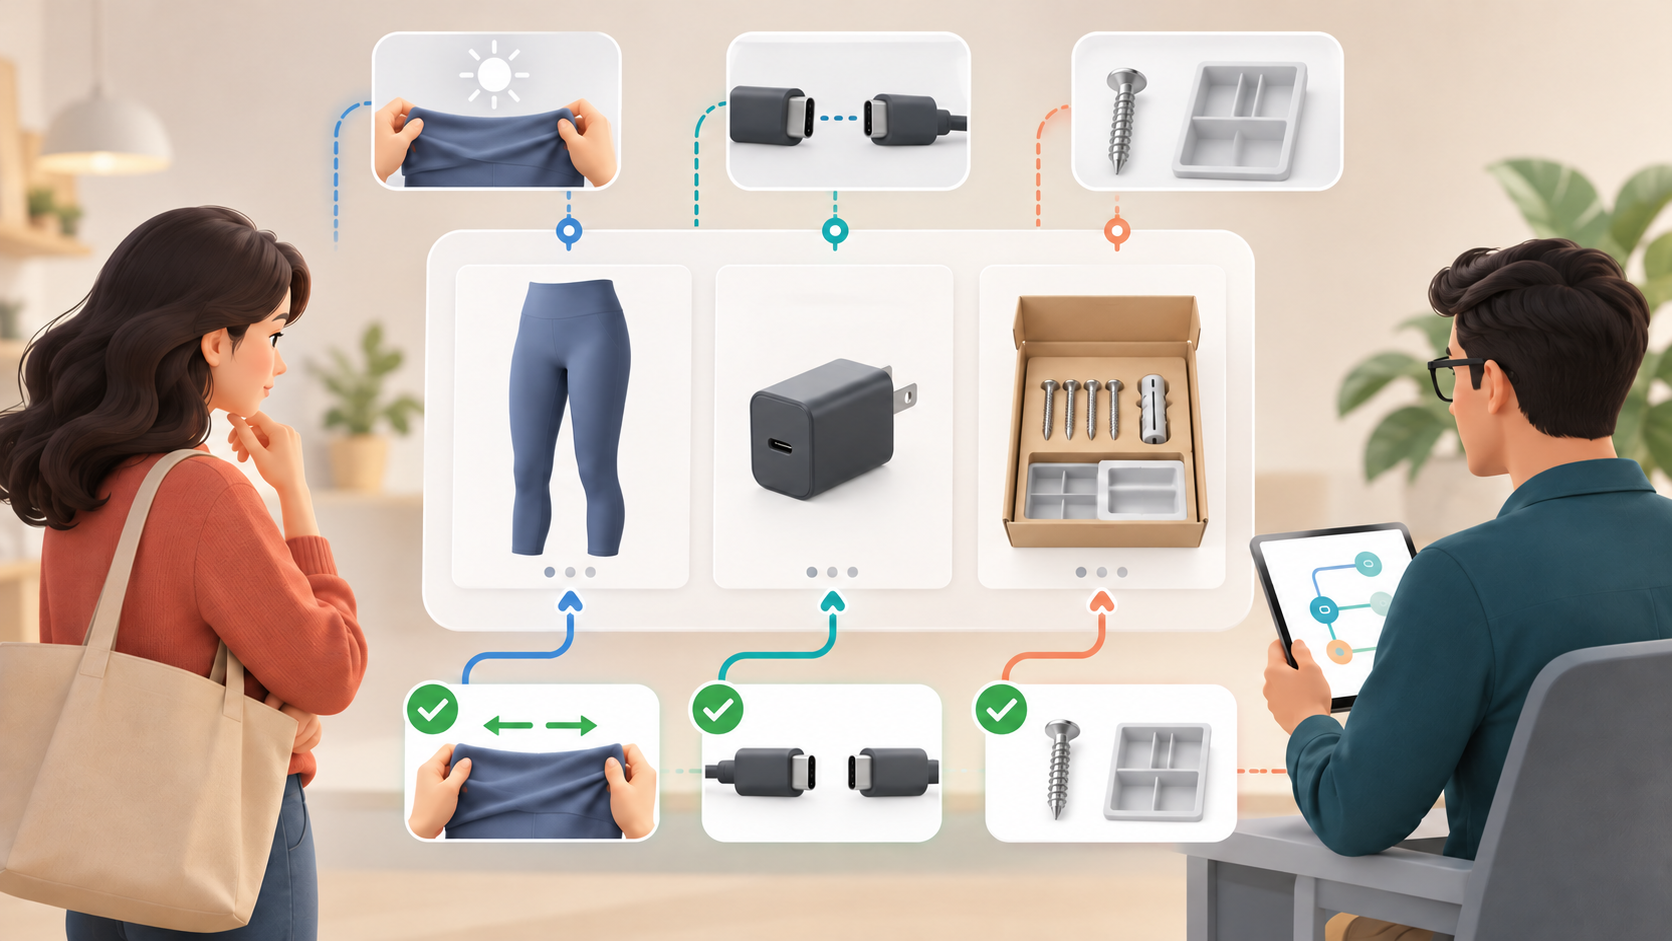
    A shopper checks leggings against a light, matches an accessory to a device port, and inspects the parts in an installation kit before buying.

    Do not begin with a brainstorming session about keywords. Begin where uncertainty is already costing time or creating the wrong purchase. Customer-service teams can usually identify questions asked immediately before an order, while return reasons show which details were misunderstood or missing before checkout.

    Build a working list with one row for each candidate question. Record the product or variant, the customer’s wording, the proposed answer, the internal owner who can verify it, and the reason the question deserves feed coverage. That reason might be repeated support contact, a known compatibility concern, an installation prerequisite, or a return caused by an incorrect expectation.

    A candidate belongs near the top of the list when you can answer yes to these questions:

    • Could the answer change whether the customer buys this product?
    • Does it resolve a compatibility, suitability, feature, material, sizing, installation, or usage concern?
    • Is it specific to this item or a clearly defined group of identical items?
    • Can the answer be verified against authoritative product information?
    • Would omitting the answer leave room for a materially wrong assumption?

    Start with products where those conditions occur most often. Electronics and accessories may depend on exact compatibility. Clothing may generate questions about fit, fabric, stretch, or suitability for an activity. Products that require assembly or installation may need prerequisites and included-component details. The important factor is not the category label; it is whether missing information can derail the purchase.

    Keep variant boundaries intact. If an answer differs by size, material, model, or another option, do not publish one blanket response across the entire family. Map the question to the item for which the answer is true, or qualify the response so the applicable variants are unmistakable.

    Write answers that are precise enough to act on

    A useful feed answer has three parts: the direct answer, the condition under which it is true, and any exception or next action the buyer needs. Put the conclusion first. Do not make the shopper work through promotional copy before reaching the fact.

    Question typeWhat the answer should containWhat to avoid
    CompatibilityExact supported models, required accessories, and relevant exclusionsClaims such as “works with most devices” when a model-level answer is available
    SuitabilityThe intended activity or environment, necessary conditions, and verified limitationsUniversal claims such as “perfect for everyone”
    Sizing or materialsRelevant measurements, composition, fit guidance, and variant-specific differencesSubjective adjectives that do not resolve the sizing or material concern
    InstallationRequired tools, parts, surfaces, connections, or prerequisites, including what is not suppliedBurying a required component or condition at the end of the answer
    UsageThe supported use, essential operating instruction, and verified restrictionInstructions that assume the buyer already knows the product terminology

    Templates can speed up drafting without turning the feed into generic copy. For compatibility, use: “Compatible with [exact models]. [Accessory] is required. It is not compatible with [verified exclusions].” For installation, use: “Installation requires [tools or conditions]. [Part] is included/not included.” For sizing, use: “Choose [variant] for [verified measurement range or fit condition]. If [specific condition applies], follow [verified guidance].” Replace every bracket with approved product data before submission.

    Make each answer understandable on its own. Name the relevant product, component, model, activity, or condition rather than relying on a vague “it” or “this.” Concision is useful only after the answer contains enough context to prevent misinterpretation.

    Then check the answer against the rest of the product record. The title, description, landing page, specifications, and Q&A should not disagree about compatibility, included parts, dimensions, materials, or intended use. When they conflict, the problem is larger than feed wording: you have multiple versions of the product truth. Resolve that discrepancy before publishing the Q&A.

    Resist the temptation to turn questions into extra keyword slots. Repetition does not make an answer more accurate. Unsupported superlatives, invented use cases, and overbroad compatibility statements can create the exact misunderstanding the attribute is supposed to remove.

    Roll out the attribute with ownership and quality controls
    A small pilot group of products passes through specification, compliance, and feed-review stations while additional products wait behind a gate.

    The difficult part is rarely drafting one good answer. It is keeping answers correct across a changing catalog. Assign ownership before you add volume: customer service identifies recurring friction, a product or merchandising owner validates the facts, and the feed owner submits and monitors the data.

    1. Select a limited group of products with clear buying questions. Favor items where an accurate answer can remove a known compatibility, sizing, installation, or usage doubt.
    2. Create an approval record for every entry. At minimum, retain the item identifier, question, answer, applicable variants, verifier, verification basis, approval status, and last-reviewed date.
    3. Choose the submission route your operation can maintain reliably. Google allows the information to be supplied through a primary feed, supplemental feed, or Merchant API.
    4. Submit the pilot and confirm that Google processes the attributes correctly. Treat processing errors, missing mappings, and variant mistakes as workflow defects to resolve before adding more products.
    5. Spot-check the processed questions against the approved record and the product landing page. Confirm that qualifiers, exclusions, units, and included-component details survived the handoff.
    6. Expand only after the team can create, approve, update, and retire entries consistently. A larger feed is not an improvement if outdated answers remain attached to changed products.

    Your source-of-truth record also needs a maintenance trigger. A model revision, material change, packaging change, new size range, altered installation requirement, or corrected product specification should prompt a review of every related answer. If the fact is no longer verifiable, remove or revise the entry rather than leaving a convenient but questionable answer in place.

    Do not copy one answer across superficially similar products without checking it. Two items can share a category while differing in dimensions, supported models, supplied parts, materials, or intended use. Reuse the question pattern if it reflects common buyer language; reuse the answer only when the underlying facts are genuinely identical.

    Measure information quality before campaign performance

    The first success test is operational: did Google process the data, did the right questions reach the right items, and are the answers still accurate? Those checks tell you whether the implementation works. They should be completed before you interpret campaign movement.

    Next, watch the customer-friction signals that motivated the pilot. Look for changes in repeated pre-purchase questions about the selected products and in return reasons tied to the issues you answered. Use the same product group and the same question categories so the comparison does not drift into a general assessment of customer service or returns.

    You can also monitor product and campaign performance, but keep the claim proportional to the evidence. Adding Q&A does not guarantee stronger Shopping rankings, lower CPCs, or better Performance Max ROAS. Pricing, demand, inventory, promotions, creative, competition, and other feed changes can move those outcomes at the same time.

    Annotate when the pilot began and avoid changing unrelated product information during the same evaluation window when practical. Observe the products through a representative purchasing and return cycle. If a performance metric changes, treat it as a signal to investigate rather than proof that the Q&A attribute caused the result.

    The strongest reason to continue is simpler: the feed contains verified answers to questions that previously blocked or distorted a purchase, and your team can keep those answers current. Better conversational discovery may follow, but information quality is the part you can directly control.

    Choose one product family with recurring customer questions. Map those questions to exact items, approve only the answers supported by product facts, and send that small set through your existing Merchant Center workflow. Once the data processes cleanly and remains consistent with the landing pages, you have a repeatable basis for expanding the program.

    References


  • Google Reviews and Local Visibility: A Practical System

    Google Reviews and Local Visibility: A Practical System

    If your business depends on calls, bookings, or visits from nearby customers, Google reviews shouldn’t be an occasional reputation project. They should be part of the way you finish every customer interaction.

    The goal isn’t to manufacture praise or chase a sudden spike in review count. It is to create a steady flow of honest, specific reviews that help Google understand your work and help a prospective customer choose you with less uncertainty.

    Reviews support visibility and conversion at the same moment

    A Google review can influence two separate decisions. Google must decide which businesses deserve visibility in local results, while the searcher must decide which visible business appears credible enough to contact.

    Reviews are not the only input behind local rankings, and collecting them does not guarantee a particular Map Pack position. Still, local search professionals responding to the 2026 Local Search Ranking Factors survey placed reviews among the top 10 local pack and Google Maps ranking factors. That makes review acquisition one of the important signals you can influence through normal customer operations.

    This matters even more when traditional organic visibility becomes unstable. Local business websites experienced substantial disruption from Google core updates in 2025 and 2026, while Map Pack results did not experience the same problems. Your website still matters, but your Google Business Profile is a distinct search surface that needs its own operating plan.

    The conversion effect is easier to see. A short review saying only that the business was great gives a prospective customer little information. A review describing the original problem, the service performed, the team’s communication, and the final result answers the questions that normally delay a call.

    Google can also extract relevant review language and display it as a review justification in local results. If someone searches for a specific service, a matching passage from a real customer’s review can appear beside the listing. The searcher gets immediate evidence that the business has handled the kind of work they need.

    Start your audit from that customer’s perspective. Look at the reviews currently visible on your profile and note:

    • How recently customers have been reviewing the business.
    • Whether reviews identify the service or project clearly.
    • Whether they explain the process and outcome or offer only generic praise.
    • Whether customers mention employees who helped them.
    • Whether useful photos or videos accompany the reviews.
    • Which review passages Google highlights for your important services.

    This audit tells you more than the average star rating alone. It shows whether your review profile contains current, relevant evidence for the work you want to be found for.

    Build the review request into the service handoff

    An employee completes a service handoff while a customer opens a generic review screen on a smartphone.

    Most review programs fail at the handoff. The customer is pleased, the employee intends to ask, and everyone moves on to the next appointment. Relying on memory turns review acquisition into a random event.

    Attach the request to a moment that already exists in your workflow. A storefront can make it part of the appointment closeout. A home-service business can ask when the work is complete and the result is visible. A business contacting previous customers can use a direct text message or phone call rather than waiting for those customers to remember on their own.

    1. Choose the trigger. Define the event that makes a customer eligible for a request, such as a completed appointment or finished job.
    2. Assign responsibility. Name the role responsible for asking and sending the review link. A shared responsibility often becomes no one’s responsibility.
    3. Make access easy. Keep the correct Google review destination available in the tool your team already uses for customer communication.
    4. Send useful context. If your team photographed the completed work, deliver those images to the customer with the request so they can attach an appropriate image if they choose.
    5. Use a restrained reminder. A customer may intend to respond and simply forget. A polite follow-up can recover the opportunity without turning the request into pressure.
    6. Record the outcome. Track whether the request was sent, whether a review appeared, and whether the process produced the kind of detail customers need.

    Your spoken request can be simple: If you’re comfortable leaving an honest Google review, it would help other customers understand what the experience was like. We’ll send you the link.

    The follow-up message should be equally direct: Thank you for choosing us. If you’d like to share your experience, here is our Google review link. Details about the work, communication, and result are especially useful to people considering the same service. Please describe the experience in your own words.

    The last sentence matters. You can help a customer understand what information would be useful without supplying praise, prescribing keywords, or writing the review for them.

    Measure the workflow rather than staring only at the public review total. Track requests sent, new reviews received, the time since the latest review, the proportion containing meaningful service detail, and the proportion containing customer-added media. If requests are not being sent, fix the operational trigger. If requests are sent but reviews remain vague, fix the prompt. If media is consistently absent, fix the photo handoff.

    Ask for detail and media without manufacturing the answer

    A useful review tells a compact customer story. It identifies the need, explains what happened, and describes the outcome. That structure is valuable to both a search engine and a person comparing local businesses.

    When you invite feedback, suggest subjects the customer might cover rather than phrases they should repeat:

    • The problem, project, or service that brought them to you.
    • How clearly and promptly your team communicated.
    • Whether the work happened when expected.
    • The final result and whether it addressed the original need.
    • The names of employees who provided notable help.
    • A photo or video that shows the completed work.

    These details can produce review justifications related to a searcher’s requested service. They also reduce a prospect’s need to infer what a generic rating means. A homeowner looking for a repaired roof, for example, learns more from a description of the repair, communication, and finished result than from an isolated compliment.

    Media adds another layer of proof. Reviews with photos or videos tend to remain prominent in the default Most relevant view longer than text-only feedback. The image lets a prospective customer inspect something concrete while the review explains the experience behind it.

    Reduce the effort required from the customer. If your team already takes a suitable completion photo, send it with the review request. The customer then has the option to attach a relevant, unique image without searching through their camera roll. Only share images that are appropriate for customer delivery, and check that they do not expose private information, addresses, documents, faces, or identifying details that should remain confidential.

    You can also ask a satisfied past customer whether they would like to update an existing review with a photo. Keep that invitation optional. The customer controls their review, rating, wording, and media.

    Do not turn this into a keyword exercise. Repeating a target phrase across several reviews is not the objective. Natural descriptions of real work will contain the relevant language when the prompt helps customers remember the specifics. Authentic variation is more credible than a collection of responses that sound as if the business wrote them.

    Protect cadence and credibility without shortcuts

    A business owner reviews varied customer feedback cards arriving at regular intervals while the business operates in the background.

    A campaign can create a burst of reviews, but a workflow creates recency. Long gaps between new reviews can allow local rankings to slip, so consistent acquisition over time matters more than occasional activity.

    The cadence should follow real customer volume. Ask as completed interactions occur instead of holding requests for a concentrated push. This produces a more sustainable stream of feedback and makes it easier to identify exactly where the process has stopped working.

    Ask every eligible customer for an honest review. Do not first decide who seems likely to leave the highest rating and offer the Google link only to that group. Selective requests deprive you of useful feedback and turn the program from customer listening into rating manipulation.

    Never offer customers money, discounts, gift cards, free services, or another benefit in exchange for a review. Customer incentives violate Google’s deceptive-content rules, even if the business does not explicitly demand a positive rating.

    If you use an internal employee incentive, reward execution of the neutral process rather than the sentiment of the result. Employees can be recognized for consistently making compliant requests, supplying customer-ready completion photos, or following the documented handoff. Do not pressure them to produce a quota of positive reviews, and do not make their reward depend on a particular star rating or approved wording.

    A prominent negative review is not a reason to panic or generate artificial praise. Address the service failure where one exists, then keep the normal request process running. Fresh, detailed reviews with relevant photos can change what appears prominently in the profile over time, but only if they come from genuine customers describing genuine experiences.

    Use the following diagnosis when results stall:

    • There are long gaps between reviews: the request is not attached firmly enough to the customer handoff.
    • Customers receive requests but few respond: access may be inconvenient, the message may arrive too late, or employees may not explain why the feedback is useful.
    • Reviews are consistently vague: the request needs neutral prompts about the need, service, communication, and outcome.
    • Reviews rarely include media: customers may not have an appropriate image readily available, so improve the completion-photo handoff.
    • A negative review dominates the default view: resolve the underlying customer issue and continue earning authentic, detailed feedback instead of attempting to bury it through a short-lived campaign.

    This approach keeps the team focused on causes it can control. It also prevents the star rating from becoming a vanity metric disconnected from service quality and search visibility.

    Key takeaways: the review system to run

    • Treat Google reviews as both a local visibility signal and on-page evidence for prospective customers.
    • Attach the request to a defined customer milestone so employees do not have to remember it independently.
    • Invite customers to discuss the problem, service, communication, and result in their own words.
    • Send appropriate completion photos with the request so customers can add useful media with less effort.
    • Maintain a natural flow of new reviews rather than alternating between campaigns and long periods of silence.
    • Ask customers consistently, never buy their feedback, and keep any employee recognition tied to a neutral process rather than positive ratings.
    • Diagnose the workflow with request, recency, detail, and media data instead of judging performance only by the public review total.

    Choose the handoff point, prepare the neutral request, make the correct review link easy for your team to send, and add suitable job photos to the customer delivery process. Then use that same workflow with the next completed customer interaction and keep it running. Local visibility improves through accumulated evidence, not a one-time appeal for stars.

    References

  • Google Universal Cart: An Ecommerce Readiness Plan

    Google Universal Cart: An Ecommerce Readiness Plan

    If you manage ecommerce acquisition, your immediate question is not whether Google has launched another shopping feature. It is whether a shopper can carry one of your products from an AI-assisted comparison into a saved buying decision without encountering a stale price, missing variant, invalid promotion or broken checkout handoff.

    Google Universal Cart makes those operational details more consequential. The practical response is not a new keyword campaign or a speculative schema type. It is a coordinated readiness plan spanning product data, offers, checkout operations and measurement.

    The cart now sits between product discovery and checkout

    Universal Cart is rolling out in the United States as a shared shopping hub across Google Search and the Gemini app. A shopper can add one retailer’s product while using AI Mode, save another through Gemini and find both when returning to the cart.

    That continuity changes the job your product listing performs. Discovery no longer has to lead immediately to a click and a purchase. An item can remain in consideration while Google watches its price and availability, identifies possible savings and helps the shopper return later.

    For your team, this introduces a useful distinction between three outcomes:

    • Discovery: Google can understand and present the product during a relevant shopping journey.
    • Retention: The shopper considers the product worth saving alongside alternatives from other retailers.
    • Completion: The shopper can purchase it through an eligible Google checkout or reach your site and complete the order without new friction.

    A strong discovery result can still fail at either of the next two stages. A competitive product with unreliable availability may lose the shopper when a stock alert matters. An appealing promotion may create frustration if its terms are unclear at checkout. A saved item may also be compared against products from merchants the shopper would not have visited independently.

    This is why Universal Cart should be treated as commerce-surface readiness, not evidence of a new ranking factor. Search visibility still matters, but visibility is only valuable when the product data and buying route remain trustworthy after discovery.

    Make product data dependable enough to drive decisions

    Unbranded running shoes surrounded by connected color, size, inventory, price and promotion elements inside a glowing verification frame.

    Universal Cart is powered by a Shopping Graph containing more than 60 billion continually refreshed product listings. That scale matters because Google is not merely displaying a static product page. It can use changing price and inventory information to notify a shopper that a saved item is cheaper or available again.

    Your optimization target is therefore product truth: one consistent description of the item across the records Google and the shopper encounter. The landing page, commerce platform, merchant feed and existing product markup should agree on what the product is, which variant is being offered, what it costs and whether it can actually be purchased.

    Run a cart-readiness audit on priority products

    Start with a manageable cohort of products that already attract qualified shopping traffic or represent meaningful commercial value. For every item, check these fields as one connected record:

    1. Identity: Confirm that the product title, brand, model and internal product identifier refer to the same item everywhere. Do not let a feed describe a bundle while the landing page defaults to a single unit.
    2. Variant: Check that size, color, material, capacity and other selectable attributes resolve to the correct price and availability. A parent product should not imply that every child variant is in stock.
    3. Price: Compare the regular price, sale price, currency and displayed checkout price. When a promotion ends, remove or update the stale value everywhere it appears.
    4. Availability: Publish the state you can fulfill. Connect inventory changes to the systems that supply Google instead of waiting for a periodic content review to catch them.
    5. Destination: Open the submitted URL and verify that it lands on the exact product and variant represented in the product record. Avoid redirects that discard the selected option or send the shopper to a category page.
    6. Offer terms: Confirm that minimum-spend rules, product exclusions, geographic limits and expiration conditions are visible before the shopper commits to the offer.
    7. Fulfillment: Make shipping, pickup and delivery constraints clear enough that the apparent deal does not change unexpectedly near the end of checkout.

    Turn this into an exception workflow rather than a one-time SEO audit. Price changes, inventory events and promotion launches should trigger checks of every connected representation. Give each mismatch an owner: merchandising for product identity, commerce operations for inventory, marketing for offer terms and engineering or platform operations for integration failures.

    Do not invent a “Universal Cart” JSON-LD type or add unsupported eligibility claims to a page. Nothing about the rollout establishes a new public schema vocabulary. Keep your existing product and offer markup aligned with visible page content, and prioritize consistency over decorative markup that no shopping system has promised to use.

    Universal Cart is not a universal checkout

    A product-filled shopping cart passes an order bundle across a bridge to a separate checkout station with payment, shipping and security symbols.

    The shared cart does not make every transaction identical. For eligible products, shoppers can complete a purchase using Google Pay. In other cases, the product is transferred to the retailer’s website for checkout. Availability depends on the merchant and product.

    Simplified checkout includes participating merchants such as Nike, Sephora, Target, Ulta Beauty, Walmart and Wayfair, along with many Shopify retailers. That participant list should not be read as universal eligibility for every catalog item or every checkout path. Verify the experience available to your own merchant account and products instead of inferring it from your platform or a competitor’s presence.

    Treat promotions as structured operational data

    Universal Cart can help shoppers find relevant promotional codes and potential payment-card benefits identified through Google Wallet information. This creates two savings layers that your team should not confuse. You control the accuracy and fulfillment of your merchant promotion. You do not control whether a shopper has an eligible card benefit.

    For each merchant-funded promotion, record the code, eligible products, excluded products, start and end conditions, geographic scope and any minimum purchase requirement in the systems used to publish the offer. Test the code against both qualifying and non-qualifying carts. If the promotion cannot be honored consistently, suppress it rather than relying on checkout copy to explain the mismatch.

    Test both purchase routes

    Where Universal Cart is available, test the journey as a shopper would:

    1. Find the product in a supported Google shopping experience and confirm that the visible variant, price and availability are correct.
    2. Save or add the item, then return from another supported Google surface to verify that the product remains recognizable.
    3. Check which completion route is offered for that item: an eligible Google purchase or a handoff to your website.
    4. For a site handoff, confirm that the exact product, variant and expected offer survive the transition.
    5. Complete a permitted test order and verify confirmation, fulfillment routing, cancellation handling and support information.

    The operational responsibility does not move to Google. Retailers remain the seller of record, including responsibility for order confirmations and customer support. Your support team therefore needs to recognize orders originating through the new experience and explain the transaction without sending the customer into an ownership loop.

    Measure the rollout without inventing attribution

    Universal Cart is rolling out in the United States, and support varies by merchant and product. A sitewide before-and-after comparison will mix eligible and ineligible journeys, making the result difficult to interpret. Build a defined observation cohort instead.

    Record the market, merchant account, product set, supported discovery surface and available checkout route for every test. Keep products outside that cohort as context, not as proof of causation. If your reporting does not expose a Universal Cart save, checkout or referral signal, do not relabel ordinary traffic as Universal Cart activity.

    Use the signals you can verify to diagnose where value is being lost:

    • Product-data exceptions: Track price conflicts, unavailable variants, invalid destinations and delayed stock updates. These are readiness failures even when sales attribution is incomplete.
    • Promotion failures: Monitor rejected codes, unexpected exclusions and support contacts about advertised savings. A promotion that attracts attention but cannot be redeemed is not a successful offer.
    • Handoff quality: Review whether transferred shoppers reach the intended product and preserve their chosen variant. Then assess the checkout abandonment signals already available on your site.
    • Order quality: Watch cancellations caused by unavailable stock, fulfillment exceptions and contacts about order ownership. These reveal whether the commerce operation can support the experience after acquisition.
    • Commercial outcome: Compare completed orders, revenue and margin for the defined product cohort using only attribution fields your systems actually receive.

    Keep your AI-search work connected to this measurement plan. Informational content can help Google and shoppers understand who a product is for, how alternatives differ and which constraints matter. Product records carry the transactional facts. Trying to force both jobs into keyword-heavy product copy makes the page less useful without solving price, inventory or checkout reliability.

    The right internal dashboard is not a generic “AI visibility” score. It is a short chain of evidence: eligible product, accurate representation, valid offer, functional completion route and fulfilled order. When one link is not observable, label it unknown rather than treating a proxy as a confirmed sale.

    Key takeaways for ecommerce teams

    • Universal Cart lets shoppers retain products from multiple retailers across supported Google Search and Gemini experiences, so discovery can influence a purchase that happens later.
    • Price and availability data now support shopper alerts as well as initial product presentation. Build event-driven ownership for mismatches instead of leaving them for periodic SEO audits.
    • Direct checkout is not available for every merchant or product. Test the route actually offered to your catalog and protect product, variant and promotion continuity during site handoffs.
    • Retailers remain responsible for the order and customer support, even when Google simplifies the path to purchase.
    • Do not create speculative Universal Cart markup or claim a new ranking factor. Concentrate on consistent product data, redeemable offers, reliable checkout and evidence-based measurement.

    Your best next move is a controlled readiness review, not a catalog-wide overhaul. Select a priority product cohort, document its real eligibility, reconcile every price and inventory representation, and complete both checkout routes wherever they are available. The defects you uncover will be worth fixing even before Universal Cart contributes measurable volume.

    As availability expands, add products only when their data and post-purchase operations pass the same checks. That gives you a repeatable commerce system for Google Search, Gemini and future AI-assisted buying surfaces rather than a temporary campaign built around one feature name.

    References


  • Agentic AI Personalization: How to Earn Autonomy

    Agentic AI Personalization: How to Earn Autonomy

    When an AI assistant only recommends something, poor personalization is irritating. When it can reorder a product, change a booking, submit a request, or narrow a supplier list, the same mistake can cost money, waste time, or remove an option the customer would have chosen.

    If you are designing agentic personalization, the important question is not whether the model is capable of acting. It is whether this particular task has earned permission to proceed, what the customer can inspect before it does, and how easily they can reverse the outcome afterward.

    Personalization becomes agentic when it can commit

    Conventional personalization changes what a person sees. It ranks products, selects a message, recommends content, or recalls a preference. Agentic personalization can go further: it interprets a goal, makes a sequence of decisions, uses tools, and takes action on the person’s behalf.

    That makes autonomy an authorization question, not an intelligence score. A highly capable model may still be allowed only to suggest three options. A much narrower system may safely complete a routine reorder because its scope, spending limit, delivery preference, and cancellation path are already defined.

    This distinction matters because customers do not appear to want a binary choice between manual service and total automation. SAP’s Global Customer Loyalty Index reports that 60% of consumers prefer shared control. Another 20% want full human control, 16% accept AI taking the lead with oversight, and only 4% want a fully autonomous experience. These are reported preferences from one commercial research program, not universal behavioral thresholds, but the pattern is useful: assistance is welcome; unconditional control is not.

    The loyalty effect runs in both directions. In the same index, 31% said interactions with AI assistants made them feel more loyal to a brand, while 30% said they had switched away because of a brand’s use of AI. The latter figure rose to 45% among Gen Z respondents. More automation is therefore not a neutral product upgrade. It can strengthen the relationship when it removes work and weaken it when it feels inaccurate, intrusive, or hard to contest.

    Define permission across three separate scopes:

    • Data permission: What may the system remember, infer, combine, and reuse?
    • Decision permission: May it filter, rank, or choose, and which constraints must it obey?
    • Action permission: May it prepare an action, request confirmation, or execute within agreed limits?

    Do not merge those scopes into a single personalization toggle. Letting an assistant remember a preferred delivery day is not permission to place an order. Accepting a recommendation is not permission to make the next purchase automatically.

    Set autonomy by task risk, not by customer profile

    An AI assistant faces several tasks with progressively stronger permission barriers, from organizing cards to handling a purchase and travel booking.

    The best first use cases are decisions in which the customer is doing avoidable sorting work. Consumers report using AI when they are unsure what to buy (23%), facing too many options (22%), or short on time (20%). Gift buying (17%) and being new to a brand or platform (16%) create similar demand for assistance.

    That points to a practical starting rule: choose a journey with bounded inputs, a result the customer can inspect, and an error that can be corrected. Filtering a large catalog against stated requirements is a stronger opening use case than making a costly, difficult-to-reverse purchase.

    Operating modeWhat the AI may doCustomer controlEvidence needed before expanding
    AssistRecall preferences, summarize information, or reduce a large set of optionsThe customer inspects the inputs and continues manuallyRelevant context is recalled correctly and unsupported assumptions are easy to spot
    RecommendRank options and explain the important tradeoffsThe customer selects, rejects, or changes the recommendationRecommendations are useful, corrections decline, and exclusions are respected
    PrepareBuild a cart, prefill a form, draft a plan, or schedule a proposed actionThe customer sees the complete effect before confirmingPreviews are rarely corrected and all downstream rules are represented accurately
    ActExecute a routine, pre-authorized action inside explicit limitsThe customer receives a record, can cancel or undo where possible, and can reach a humanOutcomes remain reliable and the recovery path works when the system is wrong

    Graduation should be task-specific. A person may trust an assistant to reorder the same household item and still want to compare every option before buying a laptop. A history of successful low-cost actions does not justify autonomy over unrelated, higher-consequence decisions.

    Before allowing a task to move from recommendation to execution, check five conditions:

    • Consequence: What can the customer lose in money, time, access, or opportunity?
    • Reversibility: Can the action be cancelled cleanly, and for how long?
    • Ambiguity: Is the goal specific enough to act on without inventing a preference?
    • Information quality: Are prices, availability, eligibility rules, and customer details current?
    • Scope: Are limits on products, amounts, frequency, recipients, and channels explicit?

    A costly or irreversible action should keep an explicit confirmation step regardless of how well earlier tasks performed. If the goal is ambiguous or a required fact is stale, the agent should stop and ask rather than treat past behavior as present intent.

    Measure progress with the failure signals as well as the completion rate. Track corrections, overrides, cancellations, refunds, unsupported assumptions, human handoffs, and successful recoveries. Then define the acceptable range for each metric before expanding permission. A rising completion rate can hide a deteriorating experience if customers are also undoing more actions or contacting support more often.

    Do not use AI to disguise a weak underlying offer. Declining product quality, rising prices, and poor customer service were reported as loyalty breakers by 45%, 40%, and 36% of consumers respectively. An agent may help someone reach the decision faster, but it cannot make a poor product, indefensible price, or broken recovery process trustworthy.

    Build the control surface before increasing automation

    A customer reviews an AI agent's proposed actions on a translucent control panel with confirmation, pause, activity trail, limits, and undo controls represented by symbols.

    Customers need more than a consent screen at the start of the journey. They need controls at the moment an AI decision becomes consequential. The same loyalty data identifies human support when something goes wrong as the leading trust builder at 42%. The ability to review or override decisions follows at 36%, privacy and security assurances at 35%, clear explanations at 31%, and proven accuracy over time at 29%.

    Those preferences translate into a concrete control surface:

    • A permission receipt: State the task the agent may perform, the information it may use, its limits, and whether permission applies once or persists.
    • A decision preview: Before a consequential commitment, show the selected option, quantity, total cost, timing, recipient, and any condition that cannot be reversed.
    • A useful explanation: Show the preferences, constraints, and current facts that changed the decision. A generic message that says the choice was personalized does not help someone verify it.
    • A memory center: Let the customer see, correct, remove, or stop reusing stored preferences. Separate facts the person supplied from attributes the system inferred.
    • An action record: Preserve what happened, when it happened, which permission allowed it, and what the customer can do next.
    • A real recovery path: Put cancel, undo, correction, and human escalation where the result appears. Carry the task context into the handoff so the customer does not have to reconstruct the failure.

    Match the interruption to the consequence. A low-risk, fully reversible action can use a prompt notification after execution. A purchase, external submission, contract change, or action affecting another person should normally be reviewed before commitment. An unexpected condition should pause the workflow even when the agent has standing permission.

    Avoid approval fatigue as carefully as you avoid hidden automation. Asking for confirmation after every harmless sorting step makes the agent feel pointless. Asking only at the point of commitment preserves both efficiency and control.

    Accuracy should expand permission only when recovery has also been tested. In the loyalty index, 56% of consumers still wanted the ability to reverse AI decisions. A system that is right most of the time but cannot repair the remaining mistakes has not earned greater autonomy.

    Make your content usable in an agent’s decision path

    Agentic personalization changes what it means to be visible in search and discovery. A page may no longer be used only to answer a query or win a click. Its information may help a system classify an option, verify a constraint, rank alternatives, or decide whether an action is safe to continue.

    Microsoft-Decision-1 illustrates that emerging layer. Microsoft positions the model for routing, classification, prioritization, verification, and workflow control, and Microsoft personnel have said it is being tested in Copilot and Bing. Microsoft also claims strong latency and quality on structured decision tasks. That performance statement is a vendor claim, and the reported experiments do not establish a search ranking effect or a production-wide deployment.

    Google is exploring a related change in the discovery experience: moving Discover toward a proactive, highly personalized concierge that helps users advance their goals. The direction also includes AI-enabled formats alongside human voices and sources. This signal comes from a job listing, so it should not be treated as a shipped feature, a confirmed roadmap, or evidence that Discover traffic will change in a particular way.

    For SEO, AEO, and GEO teams, the practical response is to make important content decision-ready. An agent should be able to determine not only what you offer, but also when it fits, when it does not, which constraints apply, and how the customer can safely take the next step.

    • State the entity clearly: Use consistent names for the organization, product, service, plan, location, and responsible party.
    • Expose decision facts in visible copy: Include intended users, exclusions, requirements, included features, limitations, current pricing or availability when applicable, and the consequence of each option.
    • Resolve ambiguity: Distinguish similar plans, versions, locations, or service levels instead of expecting a model to infer the difference from marketing language.
    • Show who should not choose the option: Negative-fit guidance helps an assistant eliminate a poor match before it becomes a poor customer experience.
    • Keep claims synchronized: Visible content, structured data, feeds, policies, and transactional systems should not describe the same offer differently.
    • Mark volatile information: Give changing facts enough date or availability context to prevent an old condition from being mistaken for a current one.
    • Publish the control path: Make confirmation, cancellation, return, correction, support, and escalation rules easy for both people and systems to locate.

    JSON-LD can help machines interpret entities, attributes, offers, relationships, and actions, but markup cannot rescue contradictory or incomplete content. Treat schema as a structured representation of facts the customer can verify, not as a place to introduce claims that the page itself does not support.

    Audit important pages with six questions: Can an agent identify the exact offer? Determine who it is for? Verify the decisive claims? Find exclusions and current constraints? Understand the next action? Recover or hand off if that action fails? Every unclear answer is both a customer-experience problem and an AI visibility problem.

    Traffic alone will not describe performance in a concierge-style environment. Where data is available, separate discovery from influence and action: monitor qualified visits, cited or mentioned pages, recommendation acceptance, completed actions, corrections, and downstream support demand. The goal is not merely to be summarized. It is to be represented accurately enough that a person or agent can make a sound decision.

    Key takeaways: a practical earned-autonomy rollout

    1. Choose one overloaded decision. Start where customers face too many options or repeatedly supply the same useful preferences.
    2. Separate data, decision, and action permission. Specify exactly what the agent may remember, recommend, prepare, and execute.
    3. Begin in assist or recommend mode. Capture incorrect context, rejected suggestions, missing constraints, and requests for human help.
    4. Add preparation before execution. Let the agent build the proposed outcome while the customer still confirms the complete effect.
    5. Offer bounded action as an explicit choice. Limit the permission by task, amount, frequency, recipient, channel, or another constraint that fits the use case.
    6. Test recovery before widening scope. Verify that notices arrive, records are understandable, reversals work, and human support receives the relevant context.
    7. Expand or reduce autonomy from observed outcomes. Reward reliable performance with a larger task-specific scope; step back when overrides, cancellations, stale information, or support demand reveal a problem.

    Pick a single reversible journey and write its permission contract before selecting the model or designing the prompt. If you cannot state what the agent may do, when it must stop, and how the customer gets control back, the task is not ready for autonomous execution. When those boundaries are clear, each successful outcome can earn the next increment of responsibility without moving the steering wheel out of reach.

    References


  • AI Search Investment: Attribution Across the Buyer Journey

    AI Search Investment: Attribution Across the Buyer Journey

    You have enough evidence to test AI search, but probably not enough to promise a clean last-click return. A recommendation may create the shortlist while Google, YouTube, a retailer, or a direct visit records the next step.

    The decision is not whether AI deserves a blind budget. It is how much to invest, which customer handoff you expect to improve, and what evidence will unlock the next tranche. Set those conditions before the work begins, and attribution becomes a decision system instead of an argument at the end of the quarter.

    AI search influences a journey; it rarely owns the whole journey

    An AI answer can introduce a brand, narrow a longlist, explain a product, or reduce perceived risk. It may produce a click, but it does not have to. The person could remember the name, search for it later, watch a demonstration, compare alternatives, and then convert through a different channel.

    A last-click report will credit the final visit. A first-touch model may over-credit the initial discovery. A screenshot showing that an AI system cited your page proves exposure, but not commercial intent. None of these views is useless; each answers a different question.

    Cross-platform behavior is already visible outside AI search. In a survey of 511 beauty consumers, whose average age was 47, 43% named Google as their first stop, while Instagram accounted for 11.9%, YouTube 11.2%, TikTok 10.6%, and AI tools 9.8%. When respondents discovered a beauty product on TikTok, 72% searched for it on Google and only 7% bought directly through TikTok at that moment. When TikTok or YouTube did not provide the answer, 61% fell back to Google.

    Those percentages belong to one consumer survey in one category. Do not paste them into a B2B forecast or treat them as universal market shares. Use the behavior they expose: discovery, validation, evaluation, and transaction can happen on different platforms, even within one purchase.

    • Discovery answers: What is this, and which options should enter my consideration set?
    • Validation answers: Is this claim credible, safe, relevant, and supported by enough detail?
    • Evaluation answers: How does this option compare with alternatives for my situation?
    • Transaction answers: What does it cost, what happens next, and where can I buy, subscribe, or speak to someone?

    Your investment case should name the journey job you expect AI search to perform. If the objective is discovery, evaluate qualified visibility and subsequent demand. If it is evaluation, inspect whether comparison and proof content move people toward a commercial action. If it is transaction, require stronger evidence from referrals, leads, pipeline, or revenue.

    Map the handoffs before you decide what to fund

    Small figures pass a glowing signal between an AI orb, a search panel, a video display, a storefront, and a purchase pedestal connected by branching paths.

    Begin with the questions that matter to the business, not a list of AI platforms. A useful journey map can live in one worksheet, provided every row connects a customer question to an intended next step.

    1. Choose a commercially important topic cluster. Include problem questions, option questions, trust questions, comparisons, and action-oriented queries such as pricing, availability, buying, or booking.
    2. Record where customers are likely to ask each question: an AI assistant, Google, social search, YouTube, a marketplace, a review site, or your own website. Validate this with analytics, customer interviews, sales-call notes, and on-site search data where available.
    3. Write down the job of each touchpoint. One may create awareness, another may provide proof, and another may capture the transaction.
    4. Name the destination that should receive the next visit. It might be an evidence page, comparison, product page, calculator, store locator, pricing page, or lead form.
    5. Define one observable signal for the handoff and one likely failure mode. A referral session is observable; a remembered brand mention may not be. A citation to an irrelevant page is visibility with a broken destination.

    Format should follow the job. In the beauty survey, TikTok searches were most often based on a product name, a skin or hair concern, a brand name, or a full question; only 7% searched by ingredient. YouTube creators also received a higher “very trustworthy” rating than TikTok creators, 14.1% versus 8.6%. That does not establish a universal hierarchy of platforms. It shows why the same buyer may use a short demonstration for discovery, a longer video for reassurance, and a detailed page for ingredient or product validation.

    For every important query family, keep these fields together:

    • Customer question and journey stage
    • Platform or surface where the question is asked
    • Brand answer, content asset, or proof required
    • Page or property that should receive the next visit
    • Expected customer action
    • Observable analytics or CRM signal
    • Owner responsible for repairing the handoff

    Then test the relay manually. Can someone move from an AI recommendation to the exact evidence needed to validate it? Does the cited or discovered page match the question? Is the brand, product, author, and organization information consistent across the relevant properties? Does the destination offer a sensible next action?

    Structured data can help machines interpret entities and page content when the markup truthfully represents what a visitor can see. It is not a guarantee of an AI citation or recommendation. Fund schema implementation as part of a clear content and entity system, not as a substitute for useful evidence.

    Use an attribution ladder instead of forcing one perfect number

    The strongest measurement system separates what you observed from what you inferred. A practical architecture combines GA4, a five-level attribution ladder, and a board-ready scorecard. Each level supports a different decision, and no level should be presented as stronger evidence than it is.

    Evidence levelWhat to measureWhat it can supportWhat it cannot prove
    1. VisibilityPresence, mentions, citations, linked citations, and answer accuracy across a defined prompt setWhether the brand is eligible and visible for the questions you choseThat anyone visited, considered, or bought
    2. Referred demandSessions, landing pages, and clicks from identifiable AI referrers when referral data survivesThat a measurable AI surface sent a visitInfluence that resulted in a later direct or search visit
    3. On-site intentCommercial page views and key events such as account creation, a pricing action, a tool completion, a store-locator use, or a qualified form submissionWhether referred visitors performed meaningful actionsClosed revenue or causality
    4. Commercial outcomesQualified leads, opportunities, purchases, revenue, and repeat value connected to observable journeys or declared influenceHow much measurable business value is associated with the programAll invisible assists or the value that would have occurred anyway
    5. Incremental effectPredefined holdouts, staggered rollouts, or credible comparisons between exposed and unexposed topics, markets, or periodsWhether the intervention probably created additional valuePerfect certainty when other variables changed at the same time

    Configure analytics so the ladder remains auditable. Preserve the original source, medium, landing page, and campaign fields. You can create a reporting group for known AI referrers, but keep the underlying values because referrer hosts and product behavior can change. Use UTM parameters on links you control; do not pretend you can add them to third-party citations you do not control.

    Mark key events that reflect actual business progress rather than convenient activity. A page view is not equivalent to a qualified enquiry. If your buying cycle continues offline, connect consent-appropriate analytics and CRM records so you can distinguish a submitted lead from an accepted opportunity and a closed sale.

    Add declared influence as a separate evidence stream. A “How did you hear about us?” field can include AI assistants or AI search, plus a free-text option. Sales teams can record unsolicited mentions during qualification. These responses are useful precisely because referral data can disappear, but self-reported memory is imperfect. Label it as declared influence and never overwrite observed acquisition with it.

    Use explicit confidence labels in reporting:

    • Observed: a visible referral, event, or transaction was recorded directly.
    • Connected: analytics and CRM identifiers linked the visit to a later commercial stage.
    • Declared: the customer named an AI system or answer as an influence.
    • Inferred: changes in visibility and demand moved together, but the individual journey was not connected.
    • Incremental: a predefined comparison provides evidence that the program caused additional results.

    Keep attributed revenue and influenced revenue in separate columns. The same opportunity may appear in both, so adding them can double-count the deal. Your board scorecard should show investment, coverage of priority questions, visibility, referred demand, commercial actions, qualified pipeline, revenue, confidence level, and the next decision. Include a baseline and a target; a growing cumulative total without either is difficult to interpret.

    Visibility tracking also needs controls. Use a stable set of commercially relevant prompts, record the model or surface, market, language, date, and test conditions, and repeat the process consistently. A single generated answer is an observation, not a durable ranking.

    Release the budget through gates, not a long leap of faith

    Metallic tokens move through a sequence of transparent gates beside visual evidence objects, with additional tokens waiting at each stage.

    GEO and AEO pricing spans radically different scopes. A vendor-compiled dataset covering 1,146 quotes from 214 agencies between July 6 and October 2, 2026 put the median monthly retainer at $6,850. Its reported tier medians ranged from $2,950 for Starter work to $7,400 for Growth, $14,600 for Advanced, and $31,500 for Enterprise. Sixty-eight percent of agencies primarily used a custom or tiered monthly retainer.

    Treat those figures as directional negotiating context, not a universal price sheet. The dataset was assembled and published by an agency, and proposals differ by market coverage, senior staffing, digital PR, technical work, content volume, and commitment length. Its $6,850 GEO/AEO median was 45% above the $4,740 traditional SEO median, so a buyer should require a clear explanation of what the premium adds.

    Before signing, ask the provider or internal program owner to specify:

    • The countries, languages, products, audiences, and query families included
    • The baseline that will be captured before optimization begins
    • How mentions, citations, linked citations, accuracy, traffic, leads, and revenue are defined
    • Which technical, schema, content, analytics, authority-building, and digital PR activities are included
    • Who owns the accounts, prompt sets, dashboards, content, structured data, and historical exports
    • What constitutes a qualified lead or opportunity
    • How duplicated, declared, and inferred revenue will be handled
    • The minimum term, review points, exit conditions, and work that remains usable after termination

    A three-stage, 90-day pilot can create decision evidence without pretending that every buying cycle will produce revenue in 90 days.

    1. Days 1-30: establish the prompt, visibility, traffic, conversion, and pipeline baselines. Repair analytics and CRM gaps. Map one or two high-value customer journeys and identify their weakest handoffs.
    2. Days 31-60: improve a deliberately limited set of pages and supporting assets. Correct factual ambiguity, strengthen evidence, connect related entities, implement accurate structured data where appropriate, and make the next action unmistakable.
    3. Days 61-90: repeat the visibility tests under consistent conditions, inspect referral and declared-influence data, review commercial events and pipeline, and classify the result as scale, repair, continue observing, or stop.

    Negotiate this review even when the commercial agreement runs longer. A six- or twelve-month commitment without definitions, data ownership, and intermediate decision gates creates avoidable financial exposure.

    Use the pattern of results to decide what happens next. If priority visibility and qualified commercial signals both improve, expand carefully. If visibility improves but the next step does not, repair the handoff or destination. If referred visits rise but meaningful actions do not, investigate intent mismatch, page experience, offer clarity, and conversion friction. If a provider ships deliverables but cannot show movement at any agreed evidence level, do not renew solely on citation screenshots.

    Key takeaways

    • Budget AI search for a defined journey job: discovery, validation, evaluation, or transaction.
    • Map the handoff between platforms before producing more content. A visible answer with no relevant destination is an incomplete investment.
    • Report visibility, referred demand, on-site intent, commercial outcomes, and incrementality as separate evidence levels.
    • Keep attributed, declared, and inferred influence distinct so stakeholders can see both value and uncertainty.
    • Use market pricing as directional context, then tie your actual spend to scope, ownership, baselines, and pre-agreed decision gates.

    Start with one commercially important topic cluster this week. Map its discovery, validation, destination, and conversion steps; instrument the signals you can observe; and fund the smallest program capable of moving them. At the review point, let the evidence tell you whether to scale the work, repair the relay, or redirect the budget.

    References


  • Holiday Display Ad Costs: A Practical 2026 Budget Plan

    Holiday Display Ad Costs: A Practical 2026 Budget Plan

    You are deciding whether to spend before Black Friday or preserve your display budget for the peak shopping period. The 2026 cost signal supports an early move, but for a specific purpose: buy less expensive prospecting reach, learn which value proposition works, and build audiences you can approach again when purchase intent strengthens.

    That is not a reason to spend simply because impressions are cheaper. CPM is only the price of access to an audience. If cautious shoppers ignore the offer, inexpensive exposure can still produce expensive customers. Your budget plan therefore needs two controls: one for media cost and another for commercial results.

    Read the 2026 cost drop as an opportunity, not a forecast

    AdRoll activity from July 1 through September 8 showed a pronounced decline in display pricing. Prospecting CPMs were 45% lower year over year and 25.5% below the comparable Q2 period. Retargeting CPMs were 29.1% lower year over year and 40.2% below the comparable Q2 period.

    Display activityYear-over-year CPM changeChange from comparable Q2 periodWhat it means for your plan
    Prospecting45% lower25.5% lowerTest new audiences and messages before peak competition intensifies.
    Retargeting29.1% lower40.2% lowerReconnect with known visitors, but let the size and quality of your audience limit spending.
    Account-based marketing4.4% higher15.1% lowerBudget against the value of named accounts rather than broad-market CPM trends.

    These figures describe relative changes, not a universal dollar price for holiday inventory. They do not tell you the CPM your account, audience, placement, geography, or buying platform will receive. Treat them as a directional benchmark for the AdRoll activity captured during that period, then compare the signal with your own live auction prices.

    The timing matters too. A decline measured before the holiday rush does not guarantee that inventory will remain inexpensive around Black Friday or Cyber Monday. Competition can intensify as more advertisers enter the auction. The useful conclusion is that an early testing window may exist, not that peak-period media has become permanently cheaper.

    Demand conditions also point in two directions. U.S. inflation held at 3.4% in August, while the University of Michigan consumer sentiment index fell to 47.8 in September, 13.2% below its year-earlier level. At the same time, Bank of America card activity showed August spending per household increasing 4.5% year over year, with shoppers favoring value-oriented and big-box retailers.

    That combination does not prove that every category will enjoy strong holiday demand. It does tell you why cheap reach and difficult conversion can coexist. People may continue spending while becoming more selective about the merchant, product, price, and promotion that earns the purchase.

    Key takeaways

    • The clearest 2026 cost opportunity is pre-peak prospecting: use it to learn and build qualified audiences, not merely to accumulate impressions.
    • Lower CPM does not automatically lower customer acquisition cost. Conversion rate and contribution per order still determine whether the campaign is economically sound.
    • Keep prospecting, retargeting, and account-based marketing separate in both reporting and budget decisions because they reach different audiences and perform different jobs.
    • Make value visible in the ad and on the landing page. A vague brand message asks a cautious shopper to do too much interpretive work.
    • Do not treat pre-holiday CPM declines as a Black Friday price guarantee. Preserve budget for peak demand and release it only when current results meet your commercial rule.

    Protect conversion economics before buying more reach

    An analyst adjusts a funnel as many tokens enter near generic ad tiles and only a few emerge beside shopping parcels.

    CPM answers one narrow question: how much did you pay for 1,000 impressions? The basic relationship is straightforward: impressions purchased equal media spend divided by CPM, multiplied by 1,000. When CPM falls, a fixed budget can buy more impressions.

    That calculation says nothing about how many viewers were suitable prospects, visited the site, understood the offer, or purchased. Customer acquisition cost answers a different question: how much media spend was required for each attributable new customer? If your CPM declines while the purchase rate declines by more, acquisition cost can rise. Scaling on CPM alone can therefore turn cheaper inventory into a larger unprofitable campaign.

    Set the commercial limit before you increase the budget. For an ecommerce campaign, that normally means defining the maximum acquisition cost the order can support after the discount and variable costs are considered. For a longer B2B sale, define the lead or opportunity outcome you are willing to fund. Do not substitute impressions, clicks, or an unqualified form submission for that outcome merely because those numbers arrive faster.

    Your holiday display scorecard should separate four layers:

    • Delivery: spend, CPM, impressions, unique reach, and frequency.
    • Response: landing-page visits and the qualified action that indicates genuine interest.
    • Commercial outcome: purchases or qualified leads, conversion rate, acquisition cost, revenue, and contribution after the promotion.
    • Audience status: new prospects, previous visitors, existing customers, and purchasers who should be excluded from acquisition messaging.

    Use the same attribution window and outcome definition whenever you compare tests. Also compare like with like. A warm retargeting audience should usually behave differently from people encountering the brand for the first time, so a blended account average can hide weak prospecting behind strong retargeting results.

    Build the holiday budget in stages

    A staged budget lets you use the inexpensive window without assuming that the same economics will survive at greater scale or during peak competition.

    1. Establish your own baseline. Pull the most comparable recent campaigns and separate prospecting, retargeting, and ABM. Record their CPM, frequency, conversion rate, acquisition cost, offer, creative, landing page, and attribution settings. This is the benchmark that matters when a broad market trend does not match your account.
    2. Fund an early prospecting test. Use the lower observed prospecting cost to compare audiences and value messages before the holiday auction becomes more crowded. Change one major promise at a time so you can identify why one version performed differently.
    3. Build a usable retargeting audience. Send qualified prospects to a page that continues the ad’s promise. Segment visitors by meaningful behavior where your platform and consent setup permit it, and exclude purchasers from acquisition ads. Cheap retargeting CPM is not useful if the underlying audience is tiny, poorly matched, or already converted.
    4. Release more budget only after a commercial signal. Scale an audience-message pair when it remains within your acceptable acquisition cost or lead economics. If CPM is attractive but the downstream outcome misses the rule, revise the audience, offer, creative, or landing page before increasing spend.
    5. Keep a peak-period reserve. Do not commit the entire seasonal budget at pre-peak prices. Hold enough flexibility to support proven combinations when shopper intent strengthens, while recognizing that the auction price may also rise.

    This approach avoids two common errors. Waiting until peak week forces you to pay for learning when competition may be stronger. Spending the full budget early assumes that cheap awareness is as valuable as high-intent demand. The staged plan buys learning first and scale second.

    Match each buying method to the job it can do

    A media planner directs budget tokens toward three different ad-buying stations connected to blank display placements.

    Use prospecting to discover demand

    Prospecting is the clearest place to use the early cost decline. Its job is to reach people who have not yet demonstrated interest, identify promising audience-message combinations, and supply qualified visitors for later campaigns. Evaluate it on both audience quality and the downstream customers it creates. Do not demand the same immediate conversion rate as retargeting, but do not excuse it from commercial accountability either.

    Let retargeting audience quality control the budget

    Retargeting reaches people who have already visited or interacted, which is why it should be reported separately. The 40.2% decline from the comparable Q2 period creates an appealing cost environment, but the available spend is constrained by the number of qualified people in the audience. Raising the budget against a small pool can increase repetition instead of finding more buyers. Watch reach and frequency together, and stop serving acquisition messages to people who have already purchased.

    Judge ABM by account value, not the broad display trend

    Account-based marketing moved differently, with CPMs rising 4.4% year over year even though they were 15.1% below the comparable Q2 period. ABM targets narrower groups of named accounts, so its pricing is not a reliable proxy for the wider display market. Use it when the potential account value and sales process justify concentrated exposure. A cheap broad-reach CPM is not a reason to replace that account strategy, and a higher ABM CPM is not evidence that it has failed.

    Whatever buying method you choose, make the value proposition easy to verify. State what is being offered, who it is for, what the price or promotion requires, and why the product deserves consideration. Carry the same terms onto the landing page. If a discount requires a code, minimum purchase, or limited eligibility, reveal that condition before the visitor reaches checkout. Hidden conditions may improve the apparent click response while weakening trust and conversion.

    Test meaningful differences rather than cosmetic variations alone. Compare a price-led message with a benefit-led message, or a general promise with a category-specific one, while keeping the audience and measurement settings stable. The goal is to learn which reason to buy survives beyond the impression and produces the outcome your budget needs.

    Before adding another dollar, separate your recent results by buying method and write the acceptable acquisition cost or lead outcome beside each one. Then fund the smallest pre-peak test that can produce a clear decision. Increase the combinations that satisfy that rule; change or stop the ones that merely deliver inexpensive impressions.

    References


  • EU DMA and Google Search Quality: What SEOs Should Do

    EU DMA and Google Search Quality: What SEOs Should Do

    If you manage organic visibility for a hotel, airline, restaurant, comparison platform, or travel marketplace in the EU, a traffic change may no longer mean your ranking changed. The page surrounding your listing may have changed: who appears above it, what transaction details users can see, and whether the shortest path leads to a direct provider or an intermediary.

    That distinction determines your response. A ranking fix will not repair a layout-driven click-through-rate decline, and more structured data cannot force Google to restore information that the redesigned result intentionally omits. You need to measure the search result as an interface, not just a list of ranked URLs.

    What the DMA changed in affected Google results

    Layered blank search-result modules place comparison services above smaller hotel, airline, and restaurant provider cards on a tablet.

    The most consequential change is the new prominence given to vertical search services, or VSS. These are specialized comparison and discovery services in sectors such as hotels, flights, and restaurants. Expedia and Booking.com are familiar examples of the category.

    In the affected EU experience, the redesigned page places one specialized service at the top, follows it with two services carrying less detail, and puts a sector carousel below them. Features such as live prices are removed from that carousel. Google still determines the rankings algorithmically.

    This is more than a cosmetic rearrangement. It changes the amount of information visible before a click, the businesses that receive the most prominent exposure, and the route a user takes toward a booking, purchase, or contact.

    Google characterizes the launch as the steepest reduction in its service quality across its 29-year history. That is Google’s position as the owner of the affected product and an interested party in the regulatory dispute. It is not, by itself, proof that every affected user receives a worse result.

    The defensible conclusion is narrower: the DMA has materially changed the presentation and routing of certain EU searches. Whether that produces worse search quality depends on the task the user is trying to complete.

    Search quality is not the same as ranking quality

    When an SEO team says search quality declined, it often means that a preferred website became less visible. When a user says the same thing, they may mean that prices disappeared, an extra click was required, or the page made comparison harder. A regulator may care about whether rival services receive meaningful access. Those are related questions, but they are not interchangeable.

    Evaluate the new experience through five separate lenses:

    • Relevance: Does the visible result match the query’s actual intent?
    • Decision usefulness: Can the user see enough information to choose a next step?
    • Route efficiency: How many decisions and intermediary pages stand between the search and the useful destination?
    • Transaction freshness: Are time-sensitive details such as current prices available where the user needs them?
    • Choice: Does the page expose meaningful alternatives, or merely add more versions of the same route?

    A comparison-heavy result can be useful for a broad query such as choosing among hotels in a destination. The same intermediary emphasis may be unhelpful when the user searches for a specific hotel’s official telephone number or booking page. Removing live prices could reduce decision usefulness for a transaction query even if the underlying URL ranking remains relevant.

    This is why one verdict for all EU searches will mislead you. Group your queries by task before evaluating the change: direct navigation, contact or location lookup, category discovery, comparison, and transaction. Then define success for each group. A direct-navigation query should reach the official entity efficiently; a comparison query should expose genuinely comparable choices; a transaction query needs a clear route to current terms and availability.

    Who gains visibility, and where direct providers become vulnerable

    The most immediate beneficiaries are VSS platforms. Google says the design gives comparison services more prominence than businesses represented only by a website link, telephone number, and address. That creates an exposure opportunity for specialized services, but exposure is not the same as a useful visit or a completed transaction.

    If you operate a comparison service, inspect what happens after the new click. The landing page should preserve the query’s context, present comparable options, explain important differences, and offer a clear route forward. A prominent search placement that leads to a generic category page, missing availability, or another search box merely relocates the user’s work.

    Direct providers face the opposite problem. A hotel, airline, or restaurant can retain its organic position while losing visual priority to modules above it. Standard rank tracking may therefore report stability while Search Console records fewer clicks. Calling that a ranking loss sends the team toward the wrong remedy.

    Direct providers should protect the parts of the journey they still control:

    • Make the official entity unmistakable through a consistent name, canonical URL, location information, telephone number, and other relevant identifiers.
    • Send high-intent visitors to the page that completes their task, rather than to a generic homepage that forces them to search again.
    • Keep visible prices, availability, terms, and contact details accurate wherever those elements apply to the page.
    • Use the most specific appropriate structured data and keep every marked-up value aligned with visible content.
    • Validate markup, but do not treat validation as a promise that Google will display a particular rich result or restore a removed SERP feature.

    The last distinction matters. Schema can clarify entities, relationships, offers, and page meaning. It cannot override a regulatory result design. If a carousel no longer displays live prices, adding more price markup is not evidence that the feature will return.

    You should also distinguish traffic ownership from customer ownership. A VSS may gain the first click while the provider still completes the booking or service. Conversely, a direct provider may preserve branded demand but lose access to users who begin with an unbranded comparison query. Measure the whole path instead of treating every lost Google click as an equally valuable loss.

    How to audit DMA impact without misdiagnosing it

    An analyst compares two text-free search interfaces on dual monitors while examining transparent layout layers and desktop and mobile device models.

    A useful audit connects visible SERP changes to query-level performance. A before-and-after traffic chart alone cannot separate the DMA layout from seasonality, changing demand, ranking movement, site releases, or competitors.

    1. Build the query set around user tasks. Separate branded navigation, contact and location searches, category discovery, comparison, and transaction queries. Do not blend them into one average.
    2. Observe the result from the affected market. Keep location, device type, language, and session conditions consistent. Record those conditions because an incognito window does not erase geography or every form of variation.
    3. Capture the result page, not just the rank. Save the top viewport and the relevant portion below it. Note the leading VSS, the two secondary services, the carousel, whether live prices are absent, the position of the direct provider, and the destination of each prominent click.
    4. Mark the first date you observe the changed layout. Use that date for equal before-and-after reporting windows. Do not invent a rollout date from the first day traffic happened to decline.
    5. Segment performance. In Google Search Console, break out country, query, page, and device. Connect those views to on-site outcomes such as bookings, leads, calls, purchases, or another completion that matters to the business.
    6. Add a directional comparison. Where your business has comparable data, contrast the affected EU pattern with a non-EU market or with query classes that did not receive the same layout. A comparison can strengthen or weaken the DMA explanation, although it does not establish causation by itself.

    Interpret the combined evidence rather than reacting to a single metric:

    Observed patternWhat it may indicateWhat to do next
    Organic position is stable, but EU click-through rate falls where the new modules appearSERP composition or visual displacement is a stronger candidate than ranking lossDocument module order, pixel prominence, and click destinations before changing the page
    Position, impressions, and clicks fall togetherRanking movement, demand change, or both may be involvedCheck indexing, competing results, query demand, and site changes before attributing the decline to the DMA
    Clicks fall, but conversion rate among remaining visitors risesThe new result may be filtering out lower-intent visitsMeasure total conversions and value per impression; conversion rate alone can hide a net business loss
    EU performance diverges while a comparable non-EU market remains steadierThe regional search experience becomes a more plausible factorConfirm that demand, campaigns, device mix, and site behavior are sufficiently comparable
    EU and comparison markets move in the same directionA broader cause may be more important than the regional designInvestigate shared demand, technical, content, and competitive factors

    Add two business metrics to the familiar impression, position, and click reports. First, track conversions per organic impression so that you can see whether the complete search-to-outcome path improved or deteriorated. Second, separate direct-provider conversions from intermediary-assisted conversions where your analytics can identify them. That prevents a routing change from being mistaken for vanished demand.

    Manual SERP evidence also needs version control. Record the market, query, device, language, date, module sequence, visible fields, and final destination in the same format each time. Without that record, screenshots become anecdotes and teams end up debating memories of layouts that may no longer be visible.

    Key takeaways for your next SEO decision

    • The demonstrated change is a different EU result-page design. Google’s claim that this is a historic quality decline remains Google’s assessment, not a universal measurement of user harm.
    • The design favors specialized comparison services in prominent positions while reducing details in other modules, including live-price information in the described carousel.
    • Search quality must be judged by query intent: relevance, decision usefulness, route efficiency, transaction freshness, and meaningful choice.
    • Stable rankings do not rule out a substantial organic impact. Track module placement, visual prominence, click destinations, click-through rate, and business outcomes together.
    • Structured data should remain accurate and complete, but it cannot force Google to display a feature that the EU result design removes.
    • Use segmented EU evidence and a carefully chosen comparison group before attributing a loss to the DMA.

    Before rewriting content or expanding markup, capture the affected EU result pages for the queries that matter to your business. Match those observations to query-level clicks and completed outcomes. That will tell you whether you need an SEO fix, a stronger direct landing experience, better measurement of intermediary journeys, or simply a more accurate explanation of where visibility moved.

    References


  • How to Optimize for AI-Driven Search and Shopping

    How to Optimize for AI-Driven Search and Shopping

    If you sell products or services online, a customer may reach your site after an AI system has already framed the problem, compared options, and narrowed the shortlist. Your visibility now depends on more than ranking a page. Your facts have to be selected, understood, and carried into the answer without losing the conditions that make them true.

    The practical job is to make each buying decision easy to answer and each next step worth taking. That means restructuring commercial content, instrumenting AI-origin visits, and treating citation visibility as volatile evidence rather than a permanent traffic channel.

    Shopping increasingly starts inside the conversation

    Profound, an AI visibility vendor, classified 7.5 million ChatGPT conversations over a year. In that proprietary sample, commercial intent rose from 13.9% to 19.2%, while users started 41% more commercial conversations than they had a year earlier. At ChatGPT’s then-current scale, Profound extrapolated the pattern to an estimated 28 billion buying conversations per year.

    Those figures should be read as one vendor’s classification and extrapolation, not a census of every ChatGPT interaction. They still identify a change you can plan for: product discovery, comparison, and objection handling can happen before a conventional search result earns a click.

    A conventional landing page often assumes that one query represents one stable intent. A conversational shopper behaves differently. They can name a need, add a constraint, reject the first recommendation, ask about price, and request an alternative without beginning a new search. A page built only to repeat a broad keyword may rank yet provide little usable evidence for that sequence.

    The opportunity is not evenly distributed. Commercial intent showed a tenfold spread between the highest- and lowest-intent industries in the same sample. Do not copy another industry’s AI shopping plan and assume its potential applies to you. Start by finding the decisions customers actually make in your category.

    Key takeaways

    • Optimize commercial content around decisions, constraints, and comparisons rather than isolated keywords.
    • Package each important fact with the qualifier that makes it accurate.
    • Give AI systems a complete answer to cite, then give the shopper a valuable reason to continue to your site.
    • Measure AI visibility as a changing portfolio of pages and answer blocks, not as a fixed share of organic traffic.

    Map the decision before you create more content

    Hands arrange pictogram tiles and colored threads into a branching customer decision journey on a tabletop.

    Begin with questions that could change what a customer chooses. A broad informational query may attract attention, but a question about compatibility, total cost, timing, limitations, or the difference between two options is closer to a decision. Those questions deserve the clearest pages and the most precise maintenance.

    Create a buying-decision inventory before commissioning another batch of generic articles:

    1. Collect the wording customers use in on-site search, organic queries, sales conversations, and support requests.
    2. Label the decision behind each question: eligibility, comparison, cost, risk, timing, selection, or purchase.
    3. List the facts required to answer it. Include the conditions and exclusions, not just the favorable attributes.
    4. Choose one canonical page or page section that owns the answer. Competing versions create maintenance problems and inconsistent evidence.
    5. Define the next useful action. It might be checking availability, selecting a compatible option, calculating an exact price, or opening a detailed comparison.

    The inventory should connect the shopper’s language to a concrete content block. This is a practical model you can adapt:

    Shopper’s questionContent block to provideFacts that must remain attachedUseful next step
    Will this work for my situation?Fit and limitations summarySupported uses, requirements, and exclusionsInspect the compatible option
    How does option A compare with option B?HTML comparison tableConsistent attributes, conditions, and tradeoffsOpen the relevant item detail
    What will it cost?Transparent pricing blockIncluded items, required fees, and variablesCalculate or confirm the exact price
    How long will it take?Timing answer with qualifiersLocation, route, service level, or other dependenciesCheck the applicable schedule
    Which option should I choose?Recommendation logicSelection criteria and disqualifying conditionsNarrow the available choices

    Format is part of the answer. In one transportation brand’s nine-month dataset, transfer-time and pricing content was cited frequently and showed upward momentum, while broader destination guides underperformed relative to their apparent potential. Structured transport comparisons formatted as actual HTML tables were cited disproportionately often.

    That does not prove that every site needs the same page types. It shows why decision structure matters. Times, prices, named routes, and consistently labeled comparisons give a system a bounded question and an identifiable answer. Vague editorial copy makes both harder to find.

    Build answer blocks that preserve context and earn the next click

    An extractable answer is not necessarily a short answer. It is a self-contained passage in which the claim, subject, unit, and qualification remain understandable when the passage is removed from the rest of the page.

    If a price applies only to a particular plan, put the plan in the same sentence. If timing depends on a route or location, keep that dependency beside the time. If a product works only with certain configurations, do not separate the compatibility condition from the claim. The goal is to prevent a technically accurate sentence from becoming misleading when cited alone.

    Use this checklist on every commercially important answer block:

    • Start with the direct answer. Put background after it, not before it.
    • Name the product, service, route, plan, or option explicitly instead of relying on unclear pronouns.
    • Use consistent attribute labels across prose, tables, product details, and structured data.
    • Keep units, eligibility rules, exclusions, and other material qualifiers beside the value they govern.
    • Use real HTML tables for important comparisons so the underlying attributes exist as page content rather than only inside an image.
    • Make visible copy and structured data agree. Markup should reinforce the page’s facts, not introduce a more favorable version of them.
    • State when a detail is dynamic or individual. Direct the shopper to a live check instead of publishing false precision.
    • Review blocks containing prices, timing, availability, and other changing facts whenever the underlying information changes.

    Specificity and freshness matter because cited snippets have lifecycles. Some answers peak and fade as intent changes or the information becomes stale, while other answers can emerge after publication and continue growing. A page is not finished merely because it earned a citation once.

    Write for the follow-up question

    Reusable answer pattern: [Offer] is suitable for [use case] when [condition]. Choose [alternative] if [constraint]. The main tradeoff is [tradeoff]. Check [live or individual detail] before deciding.

    This pattern performs four jobs without padding. It answers the initial question, preserves the qualification, acknowledges the alternative, and identifies the next unresolved detail. Adapt the structure to your facts rather than copying the wording mechanically.

    Do not hide decisive information merely to manufacture a click. An incomplete answer is less useful to the shopper and weaker evidence for an AI response. Make the stable answer complete, then make the continuation valuable:

    • Citation layer: the direct fact, definition, comparison, or recommendation an AI system can reuse.
    • Context layer: the method, caveat, evidence, exclusions, and tradeoffs that help the shopper evaluate the answer.
    • Continuation layer: live availability, an exact configuration, an individualized quote, a full comparison, or another detail that cannot be resolved reliably in a generic answer.
    • Action layer: the smallest sensible commitment, such as selecting an option or checking a specific detail, rather than a generic call to learn more.

    Match the next action to the uncertainty the shopper still has. Someone asking about compatibility needs a compatibility path. Someone comparing cost needs the applicable price, not an invitation to read unrelated brand history.

    Measure AI Overview traffic without trusting the default channel

    An analyst watches glowing visit streams pass from abstract AI conversation portals through an attribution lens to an online store.

    Google Search Console does not provide a clean, dedicated signal for traffic from AI Overviews. That leaves teams unable to see the full contribution in a standard organic report, and some of the traffic can appear under the wrong channel.

    A workable GA4 proxy uses the text fragment that Google sometimes appends when a person clicks a cited passage: #:~:text=. The fragment can be surfaced through a custom dimension that fires when it appears in the landing URL.

    Set up the measurement layer as follows:

    1. Check the complete landing-page location on the initial page view for the #:~:text= fragment.
    2. Store a boolean flag in GA4 through a custom dimension. Retain the landing page, default channel, and event date alongside it.
    3. Create separate views for all flagged events, flagged Organic Search events, and flagged Direct events.
    4. Group landing pages or cited passages by decision theme, such as pricing, comparison, compatibility, timing, or destination information.
    5. Trend both volume and share over time. A rising count can mean something different from a rising percentage of organic traffic.
    6. Inspect a sample of the live search results before treating the flag as confirmed AI Overview traffic.

    The attribution correction is material enough to warrant its own reporting view. Across 51,200 flagged events from September 2025 through June 2026, 22.4% were attributed to Direct instead of Organic Search. That represented 11,468 events in a single transportation brand’s dataset. If your dashboard accepts GA4’s default grouping without checking the fragment, organic performance may be understated.

    Preserve the raw channel data rather than silently rewriting it. Build a corrected analysis view that identifies the probable misattribution, documents the rule, and allows the original value to be audited.

    Do not turn one site’s traffic share into a planning benchmark. AI Overview referrals accounted for 7.53% of organic sessions across that observation window, but the share peaked around 16% to 17% in February and March 2026 before falling to roughly 2% to 4% later in the period. A model that assumes a stable percentage will overstate or understate the channel as prominence changes.

    The text-fragment method is also a proxy, not a perfect identifier. The same fragment can be used by Featured Snippets and People Also Ask results. Label the segment honestly, validate examples manually, and avoid presenting every flagged visit as a confirmed AI Overview click.

    Your reporting view should answer operational questions, not merely produce an AI traffic total:

    • Which pages and decision themes attract flagged visits?
    • How much probable AI Overview traffic is appearing under Direct?
    • Which cited answer blocks are growing, stable, or fading?
    • Did a content update precede a meaningful change in the trajectory?
    • Do those visits continue to a useful product, lead, or purchase action?

    Prioritize a portfolio of answers, not a one-time AI campaign

    AI citation performance is concentrated. In the transportation dataset, the highest-performing snippet generated 2,276 tracked events, compared with an average of 31 across 1,661 snippets. An estate-wide average can therefore conceal the answer blocks doing most of the work.

    Manage each commercially relevant page according to its current evidence:

    • Cited and growing: refresh the facts, expand adjacent decision questions, and protect the clear structure already working.
    • Cited and falling: check for stale details, shifting intent, weaker specificity, and changes to the cited passage before rewriting the entire page.
    • Not cited but commercially important: replace generic introductions with a direct answer block, expose comparable attributes, and verify that one page clearly owns the question.
    • Receiving visits but not useful actions: repair the continuation layer. The cited answer may be doing its job while the next step is mismatched or unclear.
    • Broad traffic with little decision value: retain the content if it serves the audience, but do not let volume alone move it ahead of pricing, fit, risk, or comparison work.

    Do not delete or merge a page solely because its AI-origin visits declined. Citation prominence can fluctuate with query intent, content freshness, and changes in Google’s selection. First inspect the passage, the query family, and the surrounding organic trend. Record material edits so later movement can be interpreted instead of guessed at.

    For the next publishing cycle, choose the commercial question that most often blocks a decision. Give it a precise answer, attach every material qualifier, present comparisons as real HTML, align the structured data, and add a next action that resolves the shopper’s remaining uncertainty. Then instrument the landing page and watch the answer block over time.

    The goal is not to chase every new AI surface. Make your product reality the easiest accurate answer to reuse and your site the best place to finish the decision.

    References


  • Curiosity-Driven Social Ads: A Practical Creative System

    Curiosity-Driven Social Ads: A Practical Creative System

    Your ad stops the thumb, but viewers leave as soon as the opening gives way to a familiar product pitch. The hook worked. The rest of the ad did not give them a reason to stay.

    The fix is not a louder opening or more frantic editing. You need a controlled sequence of questions, partial answers, proof, and payoff. That sequence turns a moment of attention into enough interest for someone to understand the offer and decide whether it is relevant.

    Key takeaways

    • A hook earns a pause. Curiosity earns the next few seconds by creating a question the viewer genuinely wants answered.
    • Build one primary information gap, then close it through a sequence of useful revelations rather than withholding the answer until the final frame.
    • Give creators a planned beat sheet but room to choose their own words. Natural delivery and deliberate structure can coexist.
    • Judge creative with retention, completion, replay, save, share, click, and conversion signals. No single metric tells you whether the ad is commercially effective.
    • Test the opening, revelation sequence, demonstration, and product transition separately so you can identify the part that changed performance.
    • Curiosity must repay attention. If the resolution is vague, irrelevant, or weaker than the promise, the ad becomes clickbait and trust falls with it.

    Build a curiosity chain, not a single hook

    Four connected tabletop scenes progressively reveal, demonstrate, and show the use of an unbranded product.

    Attention is an event: someone notices an unusual visual, a sharp line, or an unexpected result. Curiosity is a continuing state: the viewer notices that something remains unresolved and chooses to follow it.

    That distinction matters because Meta and TikTok increasingly use AI-powered delivery systems that respond to engagement, watch time, and downstream conversion behavior. An opening that produces a brief pause but immediate abandonment gives those systems less evidence of sustained interest than an ad people actively choose to finish, replay, save, share, or click.

    A curiosity gap is the distance between what the viewer knows and what they now want to know. It might be the cause of an unexpected result, the missing step in a demonstration, or whether a solution worked under a condition that resembles their own. It should not be a random mystery pasted onto an unrelated offer.

    Write the curiosity brief before the script

    Before anyone records, answer the following in plain language:

    1. What should the viewer understand by the end? Write the commercial conclusion without slogans. If you cannot state it clearly, the creative will wander.
    2. What question will carry the ad? Choose one primary question, such as why a familiar approach failed, what caused a surprising outcome, or whether a particular method can solve the viewer’s problem.
    3. Why does that question matter to this audience? Connect it to a recognizable frustration, risk, desire, or decision. Curiosity without relevance produces empty viewing.
    4. What evidence will resolve it? Select the demonstration, observation, comparison, explanation, or experience that makes the answer credible.
    5. Where does the product belong? Introduce it when the viewer can understand its role, not merely because the logo is due to appear.
    6. What is the complete payoff? State the answer you owe the viewer. The ending must satisfy the question created at the beginning.
    7. What should happen next? Match the call to action to the level of intent the ad has earned.

    This brief prevents a common mistake: opening with a compelling problem and then abandoning it for a feature list. Every beat should either advance the answer, provide proof, or help the viewer decide whether the answer applies to them.

    Use a question-and-answer ladder

    Do not keep one answer locked away while padding the middle. Give the viewer useful progress. Each beat can close a small question while opening the next logical one:

    • Opening tension: What happened, and why is it unexpected?
    • Relevant context: Why was the outcome a problem worth solving?
    • First revelation: What obvious explanation turned out to be incomplete?
    • Mechanism or demonstration: What was actually happening?
    • Product connection: How did the product change the process or result?
    • Resolution: What should the viewer conclude from what they have seen?
    • Next step: What can an interested viewer do now?

    The sequence should feel inevitable. If you remove the product and the opening story still reaches the same conclusion, the connection is probably too weak. If the product appears before the problem has meaning, the ad will feel like a disguised sales pitch.

    Make creator ads sound natural without leaving them to chance

    Conversational creator ads work differently from compressed brand spots. Longer, less polished creator videos are sometimes called yapper ads. They may move through a personal experience, an explanation, or a demonstration before naming the product. Their apparent looseness can make them feel like content someone chose to share rather than a commercial recited at them.

    That does not mean you should ask a creator to improvise the strategy. Most people will either disclose the conclusion too early, drift away from the main question, or remember the selling points and forget the promised payoff.

    Give the creator a beat sheet rather than a word-for-word script. Specify what each beat must accomplish, the evidence that must appear, any claim boundaries, and the final action. Let the creator choose the connective language, pauses, examples, and conversational rhythm.

    A reusable creator beat sheet

    1. Start inside the problem. Open with the moment the creator noticed something was wrong, surprising, or inconsistent with what they expected.
    2. Make the consequence concrete. Explain why the situation mattered without inflating the stakes.
    3. Show the first attempt. A failed assumption or incomplete fix gives the eventual answer context.
    4. Reveal the missing mechanism. Explain what changed the creator’s understanding of the problem.
    5. Demonstrate the product’s role. Show the action, process, or result instead of substituting adjectives for evidence.
    6. Close the original question. Return to the tension from the opening and provide a definite resolution.
    7. Invite the next step. Use a call to action that follows naturally from the resolved problem.

    A useful opening pattern is: I thought the obvious fix would solve this problem, but it made this specific symptom worse. The next beat must explain what happened. It cannot jump directly to a product name and leave the contradiction unresolved.

    Another workable pattern begins with a visible result, then asks what produced it. The demonstration supplies the answer in stages. This is especially useful when the product has a behavior viewers can see, because the proof becomes part of the story rather than a claim delivered over unrelated footage.

    During recording, capture complete thoughts and natural pauses. In editing, remove repetition but preserve the cause-and-effect chain. A jump cut should move the explanation forward, not create artificial urgency. The goal is not to make a conversational ad slow; it is to give each second a clear job.

    Protect the line between curiosity and clickbait

    Every open loop creates a debt. The viewer gives you time because the ad implies that an answer is coming. Honest curiosity repays that debt with an explanation, result, or demonstration that is useful even if the viewer does not buy.

    Clickbait uses the same surface mechanics but breaks the exchange. It exaggerates the opening, delays a simple answer without adding value, or resolves the story with information that has little to do with the promise. The problem is not merely tone. A disappointed viewer can abandon the video, ignore the call to action, or carry their distrust to the brand.

    Run a promise-payoff check

    Review the finished ad without sound first, then read its transcript without the visuals. In both passes, ask:

    • Can you state the opening promise in one sentence?
    • Does the middle provide meaningful progress, or does it merely postpone the answer?
    • Is the final answer specific enough to satisfy the opening?
    • Does the proof support the conclusion the viewer is asked to draw?
    • Is the product essential to the resolution, or has it been attached to an unrelated story?
    • Would a reasonable viewer feel that the time spent watching was respected?
    • Does the call to action follow from the evidence, or does it demand more confidence than the ad earned?

    Also inspect every transition. A strong transition answers one question and introduces the next. A weak transition changes the subject. When the ad jumps from a personal problem to a generic feature montage, curiosity collapses because the viewer can already predict the rest.

    Do not manufacture uncertainty around information the audience needs to evaluate the offer. The mystery should concern the story or mechanism, not whether the ad will eventually disclose a meaningful condition. The more consequential a fact is to the buying decision, the less useful it is as a tease.

    Measure the whole attention-to-action sequence

    A smartphone projects a path of glowing steps through a lens and doorway toward a hand reaching for a product.

    The traditional focus on the first three seconds is still useful, but it answers only whether the opening earned a chance. It does not tell you whether the story sustained interest, the proof created confidence, or the offer produced action.

    Read performance as a sequence of signals:

    • Initial attention: Did viewers stay beyond the opening instead of leaving immediately?
    • Sustained interest: Did watch time and completion behavior indicate that the middle held attention?
    • Active value: Did viewers replay, save, or share the video, including sharing it through direct messages?
    • Commercial interest: Did clicks occur after viewers had enough context to understand the offer?
    • Business outcome: Did the resulting visits produce the downstream conversion the campaign was built to generate?

    Watch time, completion, replays, saves, shares, post-view clicks, and conversions provide different evidence of chosen attention. Read them together. A long watch with no commercial response may mean the story entertained but did not qualify the viewer. A strong opening followed by weak completion points toward a middle that became predictable, repetitive, or disconnected from the hook. Completed views without clicks can indicate that the payoff was satisfying but the product transition or call to action was not persuasive.

    These patterns are diagnostic prompts, not automatic verdicts. Placement, audience delivery, offer, landing experience, and campaign objective can also shape the result. Use the creative signals to identify the next question, then isolate that question in the next test.

    Test one part of the curiosity system at a time

    Begin with a control ad and create variants around a single creative decision. Keep the offer, core message, and other controllable campaign conditions stable where possible.

    1. Test the opening. Keep the body and payoff unchanged while changing the initial tension, visual, or question. This tells you which version earns the strongest entry into the same story.
    2. Test the revelation sequence. Keep the opening constant while changing how the explanation unfolds. Compare direct explanation with demonstration, personal experience, or a problem-and-discovery progression.
    3. Test the proof. Preserve the promise and product role while changing the evidence used to resolve the question.
    4. Test product timing. Introduce the product at different logical points, but do not change the ending. Look for the point at which its appearance feels informative rather than interruptive.
    5. Test the payoff and call to action. Keep the preceding story stable while changing how explicitly the conclusion connects the result to the next step.

    Do not select a winner from the opening signal alone. The variant that stops more people can still attract poorly matched attention or fail to hold it. Compare retention behavior with clicks and downstream conversions, then choose the creative that advances the campaign’s actual objective.

    Keep a simple test record containing the hypothesis, the element changed, the control, the observed retention pattern, and the business outcome. This turns individual ads into reusable knowledge. Without that record, teams often repeat the same hook test while the real weakness sits in the middle of the story.

    Start with one active ad. Print its transcript, underline the question created in the opening, and label the exact line that resolves it. Then mark what new reason to continue appears between those points. If the middle contains no useful progress, rewrite that sequence before producing another hook.

    Automated delivery can decide who receives the next impression. Your controllable advantage is making that impression worth following. Build an honest question, reward each additional second, and let the sale follow from a conclusion the viewer was given enough evidence to reach.

    References

  • How AI Search Is Becoming the New Digital Storefront

    How AI Search Is Becoming the New Digital Storefront

    AI search is creating a commercial interface between brands and buyers before many people reach a company’s website. That interface can introduce the brand, assemble a consideration set, compare alternatives and move a buyer closer to a decision.

    Two complementary ideas clarify what marketers need to manage. HiGoodie describes AI-generated brand representation as an unofficial homepage, while Profound’s shopping research frames the product shortlist as a new digital shelf. Together, they suggest that the emerging AI storefront has both a narrative layer and a selection layer.

    One storefront, two distinct commercial layers

    The homepage metaphor concerns interpretation. An AI answer may summarize what a company does, associate it with a category, explain its benefits and cite sources that influence the resulting description. HiGoodie’s account argues that brands already have this kind of model-generated presence, even though they did not design or publish it themselves.

    The shelf metaphor concerns consideration. When an answer recommends several products, the named options become the immediately visible assortment. A brand can therefore be described accurately yet still be commercially absent if it does not appear when the model constructs a shortlist.

    These layers depend on related but different signals. Citations and distributed information help shape the brand story; recommendation visibility determines whether the brand enters the comparison. Treating AI search only as a referral channel misses both functions. The answer itself is part of the customer experience, not merely a link leading to it.

    The shortlist evidence points to influence, not proven causation

    Profound reported a behavioral study conducted with Kevin Indig and Clickstream Solutions in which 56 participants completed 221 shopping tasks. According to the published account, brands that appeared more often in ChatGPT answers were also more likely to be selected by participants.

    The same source reported that 57.1% of sessions ended with participants ready to decide, while another 36.5% reached active comparison. Within the boundaries of that study, AI-assisted shopping generally advanced the decision rather than leaving the participant at an early discovery stage.

    That is meaningful evidence of an association between answer visibility and choice, but it should not be converted into a causal claim. A brand might appear frequently because it is already prominent, well documented or suitable for the task. The study nevertheless highlights a practical risk: exclusion from the generated set can remove a product from consideration before conventional website analytics register a visit.

    Storefront influence varies sharply by category

    A shopper stands at the center of pathways leading to differently illuminated displays for electronics, personal care, furniture, and everyday goods.

    The reported relationship was not uniform. Profound’s category ranking showed a +0.97 correlation for grocery and a -0.98 correlation for coaching between ChatGPT visibility and participant choice. These figures came from the source’s study and should be read as category-specific findings, not universal benchmarks.

    The contrast matters because an AI shortlist does not play the same role in every purchase. In some categories, recognizable products and comparable attributes may make the generated set especially useful. In others, personal fit, trust or evaluation outside the answer may dominate. The evidence therefore supports category testing rather than a single visibility target applied across an entire portfolio.

    A useful assessment asks where the answer sits in the decision process. It may function as an initial orientation, a comparison aid or a near-final recommendation. The closer it sits to selection, the more consequential shortlist inclusion becomes. Where it mainly supplies context, accurate representation and credible citations may deserve greater attention than raw mention frequency.

    Managing the AI storefront requires broader measurement

    Analysts examine an abstract interface connecting AI discovery, product selection, a website, a retail shelf, and a purchase point.

    The first management task is to separate representation from recommendation. Teams can examine recurring customer questions and record how AI systems describe the brand, which claims they emphasize, what sources they cite, which competitors appear and whether the brand reaches the shortlist. This produces a more useful view than a single visibility score because it reveals the role assigned to the brand in each answer.

    Distribution is part of that work. HiGoodie argues that AI search rewards broad visibility, complicates selective partnerships and weakens the value of exclusivity. The strategic implication is not indiscriminate publishing. It is that a polished corporate site alone may be insufficient when models also rely on information encountered through other cited sources. Consistency across credible, relevant coverage becomes part of storefront management.

    Measurement also has to extend beyond ordinary referral reports. Profound characterizes the decision moment inside ChatGPT as difficult for traditional analytics to observe. A website can measure visitors who arrive, but it cannot directly show how often an answer excluded the brand or persuaded someone to choose a competitor without clicking. Prompt-based visibility monitoring, citation reviews and controlled customer research can help examine that missing part of the journey, while on-site data remains useful for the traffic that does arrive.

    Any resulting program should distinguish four questions: Is the brand represented accurately? Is it supported by appropriate citations? Does it enter relevant comparison sets? Does its presence align with customer choice in the category being studied? Keeping those questions separate reduces the temptation to treat every mention as equivalent commercial value.

    Key takeaways

    • The AI storefront has a narrative layer that explains the brand and a selection layer that determines whether it enters consideration.
    • Profound’s study found a strong relationship between ChatGPT visibility and participant choice, but the reported association does not by itself prove causation.
    • The sharply different grocery and coaching results show why AI-search performance should be evaluated by category and decision context.
    • Brands need to review answer quality, citations and shortlist inclusion alongside conventional traffic and conversion measures.

    As AI answers take on more of the work once performed by search results, homepages and comparison pages, the central challenge will be to connect accurate representation with meaningful inclusion at the moments when buyers narrow their options.

    References