Tag: Competitive Analysis

  • How to Measure AI Citations in a Personalized, Fragmented Web

    How to Measure AI Citations in a Personalized, Fragmented Web

    You check the AI answers for your priority queries. Your brand appears in one tool, disappears in another, and a colleague sees a different mix of links. That doesn’t automatically mean one test is wrong. It means “AI visibility” is too broad to be useful unless you preserve the conditions that produced each answer.

    If you are deciding where to invest, don’t chase a universal top source or compress every result into one score. Measure visibility by platform, intent, category, user context and data access. That will show you whether you have a content problem, a channel problem, an access problem or simply a misleading average.

    Key takeaways

    • An AI citation is a conditional observation, not a permanent rank. Record the platform, prompt, account state, market and date that produced it.
    • Keep platforms and categories separate until you have examined their differences. A blended citation share can hide the exact gap you need to fix.
    • Measure mentions, linked citations and recurring personalized exposure separately. They represent different user outcomes.
    • Match the intervention to the source pathway. Owned pages, individual community discussions, publisher profiles and crawler access each solve different problems.
    • Treat data access as a strategic decision involving visibility, control and content rights. It is not a technical switch that the SEO team should change in isolation.

    A citation is an observation, not a permanent rank

    A conventional ranking report usually starts with a query and a position. That model is incomplete for AI search. An answer can vary with the platform, the product surface, the user’s intent, the category, the information available to the system and the context attached to the user. The cited page is therefore an outcome of a particular test condition, not a universal position your page owns.

    Start by separating four outcomes that teams often collapse into “visibility”:

    • Mention: the answer names your brand, product or expert but may not provide a link.
    • Citation: the answer links to a page or presents it as supporting material. Record whether that page is owned by you, owned by a third party or part of a community.
    • Recurring exposure: a user follows a publisher, receives a newsletter or keeps a personalized tile that can surface the brand again.
    • Source eligibility: the system can access and use the relevant material. A strong page cannot earn a citation through a pathway that cannot retrieve it.

    The distinctions matter because citation behavior is highly conditional. Across high-commercial-intent prompts in nine verticals, citation patterns varied by platform, industry and intent during four months ending in January 2026. That is enough to reject the idea that one domain is the best citation target for every brand.

    Reddit shows how quickly a headline can become a bad strategy. Its citations grew 73% in the tracked set from October 2025 to January 2026. Yet its January citation share was above 5% on ChatGPT and as low as 0.1% on Google Gemini. The category split was also substantial: Reddit accounted for 10% of citations in apparel and 2% in transportation. Growth, platform share and category share are different measurements. None of them, on its own, tells you to make Reddit the center of your plan.

    The type of page matters too. ChatGPT’s Reddit citations in that period pointed to individual discussion threads rather than generic subreddit pages or branded community content. If those threads appear in your own category tests, the opportunity is useful participation in the exact conversations people and AI systems find valuable. Merely creating a branded Reddit presence does not reproduce that value.

    Keep the scope attached to the figures: high-commercial-intent prompts, nine verticals, four months and an end date of January 2026. Use the numbers as evidence that averages can mislead, not as a benchmark your industry must match.

    Personalization changes the unit of optimization

    Personalization doesn’t just reorder a set of public links. It can change the surface on which discovery happens and place public information beside private account data, live feeds and followed interests.

    Yahoo’s MyScout illustrates the shift. In its U.S. beta, logged-in users can build a personalized homepage from tiles connected to Yahoo Mail, News, Sports, Finance and Games, as well as topics or queries they choose. Users can add, remove and reorder tiles. Some information, such as stock prices, can update in real time; email, sports and breaking-news tiles can refresh during the day. Yahoo says the experience will become more personalized as it learns from activity.

    That creates several data lanes in one interface. A public publisher page can compete for attention beside an inbox preview, a watchlist, a favorite team’s score or a followed topic. You cannot optimize a public article into becoming someone’s private email or finance data. You can, however, make the public part of the journey clear, attributable and worth following.

    Yahoo’s publisher features make that distinction concrete. Brand pages can collect a publisher’s articles, videos and social feeds, while a follow function can turn an initial discovery into a subscription and curated email exposure. A query citation and a publisher follow are both valuable, but they are not the same result and should not share one KPI.

    Use separate scorecards:

    • Discovery: Did the brand appear for the target prompt? Was it linked? Which page and domain received the citation?
    • Retention: Could the user follow the publisher, subscribe or add the topic to a persistent personalized surface?
    • Private utility: Did the surface answer the user through account-specific information? Track this as product context, not as an organic citation win.

    Your testing also needs explicit account states. Label whether a result came from a logged-out session, a dedicated test account or an established account with follows, watchlists or activity. Record the exact account used. Calling a result “personalized” without documenting the relevant context makes it impossible to interpret or reproduce.

    Build a measurement matrix that preserves context
    An isometric glass grid contains varied combinations of colored tokens, user figures, access gates, and glowing citation links.

    The smallest meaningful unit in an AI visibility audit is a test cell: platform and product surface x exact prompt and intent x category x account context x source-access state. You can summarize cells later, but collect the raw conditions first.

    Use a minimum viable citation log

    FieldWhat to captureWhy it matters
    Test conditionPlatform, product surface, app or web, market, account and login statePrevents unlike environments from being treated as the same result
    PromptExact wording, intent, category and journey stageShows whether citation behavior changes with the decision the user is making
    ResponseBrand mention, link presence, cited URLs, domains and page typesSeparates brand awareness from actual citation capture
    Source relationshipOwned site, publisher profile, community thread, third-party editorial page or competitorPoints to the channel and owner capable of making a change
    Access stateKnown crawler policy, restriction or platform relationship affecting the sourceIdentifies cases where availability, rather than page quality, may be the bottleneck
    TimingDate, time and any visible product or model labelPreserves context when feeds refresh or platform behavior changes
    User actionClick, compare, follow, subscribe or another next step offered by the answerConnects visibility to what the user could actually do

    Run the audit in a fixed sequence

    1. Define the decision set. Start with the real questions people ask while comparing, choosing or validating an option in one commercially important category. Assign one intent label to each prompt before collecting answers.
    2. Choose the relevant surfaces. Include the AI products your audience actually uses. Do not add a platform merely because it is prominent in somebody else’s citation report.
    3. Document account context. Use named test states and keep each account consistent. If follows, activity or watchlists are part of the test, record them before the run.
    4. Save the complete response. Preserve the wording, every citation URL and enough page evidence to classify the cited source. A domain-only tally hides whether the system chose a product page, an editorial explanation or an individual discussion.
    5. Calculate metrics inside comparable cells. Measure brand mention rate, linked citation rate and source share separately for each platform, intent and category. If you repeat prompts, use the same conditions and count every run, including runs with no citation.
    6. Compare cells before combining them. Look for platform, intent and account-state differences. Only create a blended view after the underlying segments are visible, and retain those segment labels in every report.
    7. Retest after a defined change. Keep the prompt set and collection conditions stable enough to see whether the intended cell moved. A before-and-after difference is a signal to investigate, not automatic proof that your intervention caused it.

    Be precise about denominators. Citation growth is a change in count over time. Citation share is a source’s portion of all captured citations. Brand citation rate is the portion of eligible test runs that link to your brand or its owned pages, depending on the definition you set. Reporting one as if it were another is how an impressive number becomes an unhelpful decision.

    Do not hide missing citations either. A no-citation answer, a citation to a third party that mentions you and a citation to your own page represent different source pathways. Each should have its own value in the log rather than being collapsed into a generic success column.

    Turn each visibility gap into the right channel decision
    Analyst figures route fragmented glowing signals from a central junction toward a document library, network, guarded gateway, and relationship hub.

    Once the matrix is segmented, the pattern usually tells you where to investigate. The useful question is not “How do we rank in AI?” It is “Why does this source win for this decision on this surface under these conditions?”

    When competitors’ owned pages receive the citations

    Compare the cited page with yours at the decision level. Identify the question it resolves, the claims it supports, the details it makes explicit and the next action it enables. Build the missing value into the most relevant page on your site rather than publishing a generic AI-search article or copying the competitor’s structure.

    Keep important facts in accessible page content. Use appropriate JSON-LD to identify the entity and content type and to connect information already visible on the page. Schema can reduce ambiguity for machines, but it is not a citation switch and should not be reported as one.

    When individual community discussions receive the citations

    Work at the thread level. Find the recurring questions in the cited discussions, answer them with category knowledge and disclose your relationship to the brand. The documented Reddit pattern favored unique discussions, so a generic corporate profile or empty branded community is not an equivalent intervention.

    Track community citations separately from owned citations. A useful third-party discussion can increase brand representation without giving you control of the page, its future edits or its availability. That is a different asset and a different risk profile.

    When a personalized surface offers a follow path

    Make the publisher identity coherent across the material collected by that surface. Treat the brand page, follow action and newsletter as a retention path after discovery. Measure whether users can reach and follow the publisher; do not count the existence of the feature as a citation.

    When access, not content, is the bottleneck

    Data availability is not uniform. Commercial deals, restrictions and lawsuits have been fragmenting what AI systems can access. Your content can remain unchanged while its eligibility differs from one platform to another.

    Amazon demonstrates the competitive consequence. Its more aggressive blocking of AI crawlers coincided with lower Amazon citation visibility on ChatGPT and more room for Walmart in the tracked results. That does not prove that every publisher should open every crawler. Amazon’s choice also reflects a preference for controlling direct customer interactions.

    Before changing access, document which crawler or pathway is affected, which content is in scope, which AI surfaces matter to the business and what control or content-rights concerns prompted the restriction. Bring the content owner, technical team and appropriate legal or commercial stakeholders into the decision. A blanket unblock made only to chase citations can create a larger governance problem; a blanket block can surrender visibility to an accessible competitor.

    Platform-specific source preferences can create another kind of gap. Even Google’s AI surfaces showed different citation mixes for social sources such as Reddit, Medium, YouTube and LinkedIn. If one format performs on one surface, verify the pattern elsewhere before expanding the entire channel program.

    Use the next test to isolate one decision. Select one high-value category, preserve its exact prompts and account states, and map every citation to its source pathway. Then make the narrowest change that addresses the observed gap. Your first useful deliverable is not a universal visibility score. It is a map showing which source wins under which condition, who can influence it and what you will test next.
    References

  • How to Build an AI Search Visibility Intelligence System

    How to Build an AI Search Visibility Intelligence System

    Your rankings report can look healthy while AI answers ignore your brand. The reverse can happen too: your company may appear in professional discussions and AI citations while the page meant to capture demand remains invisible in Google. If your dashboard collapses those outcomes into one visibility score, it cannot tell you what to fix.

    You need an intelligence system that preserves the difference between ranking, being mentioned, being cited, and being represented accurately. Once those signals are separated, you can connect each change to a specific content, distribution, authority, or measurement decision.

    Measure search rankings and AI citations as separate scoreboards

    Google search visibility and AI answer visibility overlap, but they are not interchangeable. A page can rank without being cited in an AI response. A brand can be mentioned without receiving a link. An AI system can cite a third-party profile instead of the company’s own site. It can also describe the company incorrectly while still producing what appears to be a positive visibility result.

    Start by recording four distinct outcomes for every query or prompt:

    SignalWhat to recordDecision it supports
    Google result stateThe ranking URL, its position, the visible result format, and the competing pages around itWhether to improve the target page, reconsider search intent, or respond to a competitor
    AI mentionWhether the brand, product, person, or concept appears in the answerWhether the entity is entering the answer set at all
    AI citationThe cited domain, exact cited page, and claim supported by that citationWhether to strengthen an owned page, a controlled profile, or an earned authority surface
    Message accuracyWhether the answer describes the entity and its offering correctlyWhether the priority is reach, factual correction, or clearer positioning

    Do not count those signals as if they were equivalent. A mention is not a citation. A citation is not automatically an endorsement. A high Google position does not prove inclusion in an AI answer, and an AI citation does not prove that the cited page can attract or convert conventional search traffic.

    Your dashboard can still calculate coverage, but every percentage needs a visible denominator. Show the query group, search or answer environment, language, location where relevant, and observation date. Keep Google coverage, AI mention coverage, AI citation coverage, and message accuracy in separate columns. A blended visibility score is acceptable as an executive summary only if the underlying components remain available for diagnosis.

    Build the query set around decisions, not available keywords

    A monitoring system is only as useful as the questions inside it. Importing every tracked SEO keyword creates volume, but it can miss the prompts through which a buyer investigates a problem, evaluates a provider, or asks for professional guidance.

    Organize the query set by the decision the user is trying to make:

    • Category discovery: The user is learning what a solution, method, or service is called.
    • Problem diagnosis: The user describes a symptom or obstacle and asks what could solve it.
    • Evaluation: The user asks about approaches, criteria, alternatives, limitations, or fit.
    • Implementation: The user wants instructions, requirements, examples, or troubleshooting help.
    • Brand validation: The user checks whether a named company, product, or expert is credible and appropriate.

    For each entry, save the exact wording, intended reader, decision stage, target entity, preferred destination page, and business reason for monitoring it. If geography or language changes the answer, store that context too. The point is not administrative neatness. Those fields let you distinguish a real visibility gap from a prompt that was never relevant to the page being evaluated.

    Keep a stable core set and a separate exploratory set. The core gives you a comparable record over time. The exploratory set lets you investigate new language, emerging competitors, and unfamiliar citation domains without silently changing the baseline. When you materially rewrite a prompt, treat it as a new entry rather than overwriting the old one.

    Preserve the observed answer as evidence. Record the answer interface or model when that information is available, whether the brand was mentioned, every visible citation, and the wording of the relevant claim. AI outputs can vary, so a snapshot is an observation rather than a permanent verdict. Repeated patterns across the stable query set deserve action; an isolated change should first be logged and checked.

    Connect live Google data to explicit response rules

    Live search signals move through a translucent conduit and rule-based gates toward separate content, authority, distribution, and alert modules.

    Profound presents its Google Search node as a way to bring real-time Google SERP data into automated agents. That illustrates the architecture you want: current observations should flow into the same environment where they can be classified, assigned, and checked. The vendor-described capability is an input mechanism, however, not a substitute for deciding what a result change means.

    The useful automation boundary is simple: let the system collect evidence and identify conditions, but require a response rule before it creates work. Without that rule, every ranking movement becomes an alert and every alert becomes noise.

    Use rules that connect an observable pattern to a plausible diagnosis:

    • Your target page falls while the surrounding result types stay similar: Review whether competing pages now satisfy the same intent more completely, clearly, or credibly. Do not rewrite the entire site because one URL moved.
    • The result page changes format: Reassess intent before editing copy. A shift toward videos, discussions, local results, product listings, or another format can mean that the expected content form has changed.
    • A competitor gains both Google visibility and AI citations: Inspect the exact page and claim receiving attention. Look for a missing definition, comparison, example, proof point, or explanatory unit that your content does not provide.
    • A competitor gains AI citations without a corresponding Google change: Investigate the citation ecosystem. The difference may sit in third-party authority pages, professional profiles, community material, or clearer entity references rather than conventional on-page optimization.
    • Your brand is mentioned but described incorrectly: Fix the clearest owned explanation and align controlled profiles before creating more promotional content. More exposure can spread the wrong description faster.
    • A change appears in only one observation: Save it, but do not ship a major revision solely to chase it. First determine whether the pattern persists across the relevant query group.

    Every alert should carry the evidence that triggered it: the query, previous state, current state, affected URL or citation, result screenshot or captured answer, and the response rule used. That turns an alert into a reviewable decision. It also prevents a team from reverse-engineering the reason for a task after the dashboard has changed again.

    Treat professional platforms as citation surfaces, not substitutes for your site

    AI visibility often depends on pages outside your domain. In Profound’s tracking, LinkedIn moved from outside the top 20 in November 2025 to the most-cited domain for professional queries by February 2026 on AI platforms including ChatGPT. This is directional evidence from one provider’s measurement, not a universal rule for every prompt, market, or AI product. It is still a strong reason to audit which domains actually receive citations in your own professional query set.

    Do not respond by moving your entire content strategy to LinkedIn. A third-party platform can improve discoverability while leaving you with limited control over presentation, page structure, updates, and the path to conversion. Use each surface for the job it can perform.

    • Owned surfaces: Your website, documentation, research pages, product explanations, and author pages should hold the durable version of the claim.
    • Controlled surfaces: Professional profiles and company pages should make the entity, expertise, terminology, and relationship to the owned material unambiguous.
    • Earned surfaces: Independent coverage, expert references, interviews, and community discussions can supply authority that cannot be manufactured by duplicating your own copy.

    Audit these surfaces at the query-cluster level. Open every cited page and identify what part of it appears relevant to the answer: a definition, attributed opinion, professional credential, product description, comparison, or practical instruction. Then ask whether you have an owned destination that expresses the same core fact more completely and whether the external page identifies that destination clearly.

    For professional platforms, publish material that works natively instead of pasting a truncated version of an SEO page. State a useful claim, explain the reasoning or evidence behind it, identify who it applies to, and provide a sensible path to the durable resource when one exists. Keep names, roles, company descriptions, and specialist terminology consistent across the visible page and any structured data on your site. Structured markup should reflect what a reader can verify; it should never introduce claims that the page itself does not support.

    Measure the external surface separately. Record whether it earns a citation, whether that citation mentions your entity, whether the answer preserves the intended meaning, and whether the cited page leads to an owned resource. This prevents a high-volume third-party domain from receiving credit for visibility that never reaches or accurately represents your brand.

    Run a decision loop that can prove or reject its own diagnosis

    Five circularly arranged stations depict observation, hypothesis testing, experimentation, measurement, and a decision that feeds back into the process.

    SEO intelligence becomes useful when an observation changes a decision and the result of that decision is recorded. Use the same loop on a fixed cadence:

    1. Capture: Run the stable query set across Google and the AI answer environments you have chosen. Preserve the result state, answer, citations, and context.
    2. Compare: Flag changes in rankings, result formats, mentions, cited domains, cited URLs, and message accuracy. Keep search and AI changes in separate fields.
    3. Classify: Label the likely issue as a content gap, intent mismatch, entity ambiguity, authority gap, distribution gap, technical access problem, or measurement noise.
    4. Prioritize: Give preference to changes affecting an important decision-stage query, a repeated pattern, or a materially inaccurate representation. Visibility without relevance should not outrank a smaller but consequential error.
    5. Intervene: Make the narrowest change that tests the diagnosis. Update the relevant content unit, clarify an entity relationship, improve a controlled profile, add missing evidence, or strengthen distribution around the affected query cluster.
    6. Validate: Recheck the same query set and record whether the expected signal changed. If it did not, keep the observation but reject or revise the diagnosis rather than declaring the work successful.

    Your change log should connect each intervention to a query cluster, affected page or profile, hypothesis, owner, implementation date, and validation result. That history is more valuable than a stream of unconnected screenshots. It tells you which kinds of action repeatedly improve visibility, which surfaces influence representation, and which apparent changes were merely unstable observations.

    Key takeaways

    • Track Google ranking, AI mention, AI citation, and message accuracy as different signals.
    • Use a stable query set organized around real user decisions, with exploratory prompts kept outside the baseline.
    • Attach a response rule and supporting evidence to every automated alert.
    • Audit the exact domains and pages cited for each query cluster instead of assuming your Google competitors are also your AI visibility competitors.
    • Use professional platforms to extend authority and discovery while keeping the durable explanation on an owned property.
    • Validate every intervention against the same query context that triggered it.

    Start with the query cluster tied to the decision that matters most to your audience. Capture its Google results and AI answers, map the cited surfaces, and make one focused change based on an explicit diagnosis. The next comparable observation should tell you whether that diagnosis held up. That is the difference between collecting visibility data and building search intelligence.

    References

  • Branded-Search PPC Defense: A Practical Campaign Playbook

    Branded-Search PPC Defense: A Practical Campaign Playbook

    Your brand ad can be winning clicks while losing the decision. If every branded query triggers the same message and lands on your homepage, a prospect searching Is [Brand] good? or Alternatives to [Brand] still has to find the answer alone. A competitor, affiliate, or review site can make that answer easier to reach.

    A useful branded-search defense does more than bid on your name. It separates navigation from validation, feature research, comparison, and objection handling. That gives you control over the bid, message, proof, and landing page at the point where each decision is being made.

    Treat branded search as four different decisions

    Four connected isometric scenes depict direct navigation, proof checking, feature research, and comparison as separate decision paths.

    The exact brand name is your baseline, not your complete keyword strategy. People add modifiers when they need reassurance, confirmation, alternatives, or an answer to a specific concern. Those searches carry different risks and should not be forced through one generic ad group.

    Query familyWhat the prospect needsCompetitive openingBest response
    Trust and reputationEvidence that your brand is credible and safe to chooseReview sites can redirect the prospect toward competing offersProof-led ads and a testimonial or reputation page
    Product and featureConfirmation that a required capability existsA rival can introduce its own feature claim before you answerFeature-specific copy, sitelinks, and a relevant product page
    ComparisonHelp choosing between your brand and another optionCompetitors and affiliates can frame the comparison for youTransparent comparison content, clear positioning, and sufficient bids for visibility
    Niche question or objectionA direct answer about cost, suitability, or another concernAn unanswered concern can become a reason to leaveFAQ-style copy and a page that resolves the exact issue

    This division matters because branded searches extend across validation, feature research, comparisons, and narrow questions. Combining them hides which searches face competitive pressure and which landing pages fail to answer the prospect’s real question.

    Keep navigational searches such as the brand name by itself in their own group. Someone trying to reach your website is not in the same decision state as someone asking whether your product is expensive. The first may need a quick route to the correct page. The second needs context before a price can make sense.

    Build the campaign around intent, not one brand keyword

    You do not need a complicated account structure for its own sake. You need enough separation to change the bid, ad, and destination when the query’s purpose changes. In a smaller account, distinct ad groups may provide enough control. Use separate campaigns when an intent family needs its own budget or other campaign-level settings.

    1. Inspect the search terms that actually triggered your branded ads. Do not limit the review to the keywords you originally added.
    2. Label each useful term as navigation, trust and reputation, product and feature, comparison, or niche question. Put unclear modifiers in a review queue rather than forcing them into a convenient category.
    3. Separate the intent families that require different bids, messages, or landing pages. If two terms would receive the same treatment, they do not need artificial separation.
    4. Create a destination map before rewriting ads. Assign each group to the page that answers its question most directly.
    5. Use negative keywords to prevent obvious routing conflicts, but check the effect before expanding them. An aggressive negative list can remove the very modifier coverage the defense is meant to create.
    6. Maintain a controlled way to discover new brand modifiers. Exact-match coverage alone cannot reveal every reputation concern, comparison phrase, or feature question appearing in real searches.

    The destination map is the most important check in this process. If every row still points to the homepage, the structure has changed but the customer experience has not. Either build a page that answers the intent or acknowledge that you are not yet ready to buy that traffic aggressively.

    Query classification also prevents an easy reporting mistake. A high-converting navigational group can make the overall brand campaign look healthy while reputation or comparison traffic quietly underperforms. Review performance by intent family, not only at campaign level.

    Match the ad and landing page to the modifier

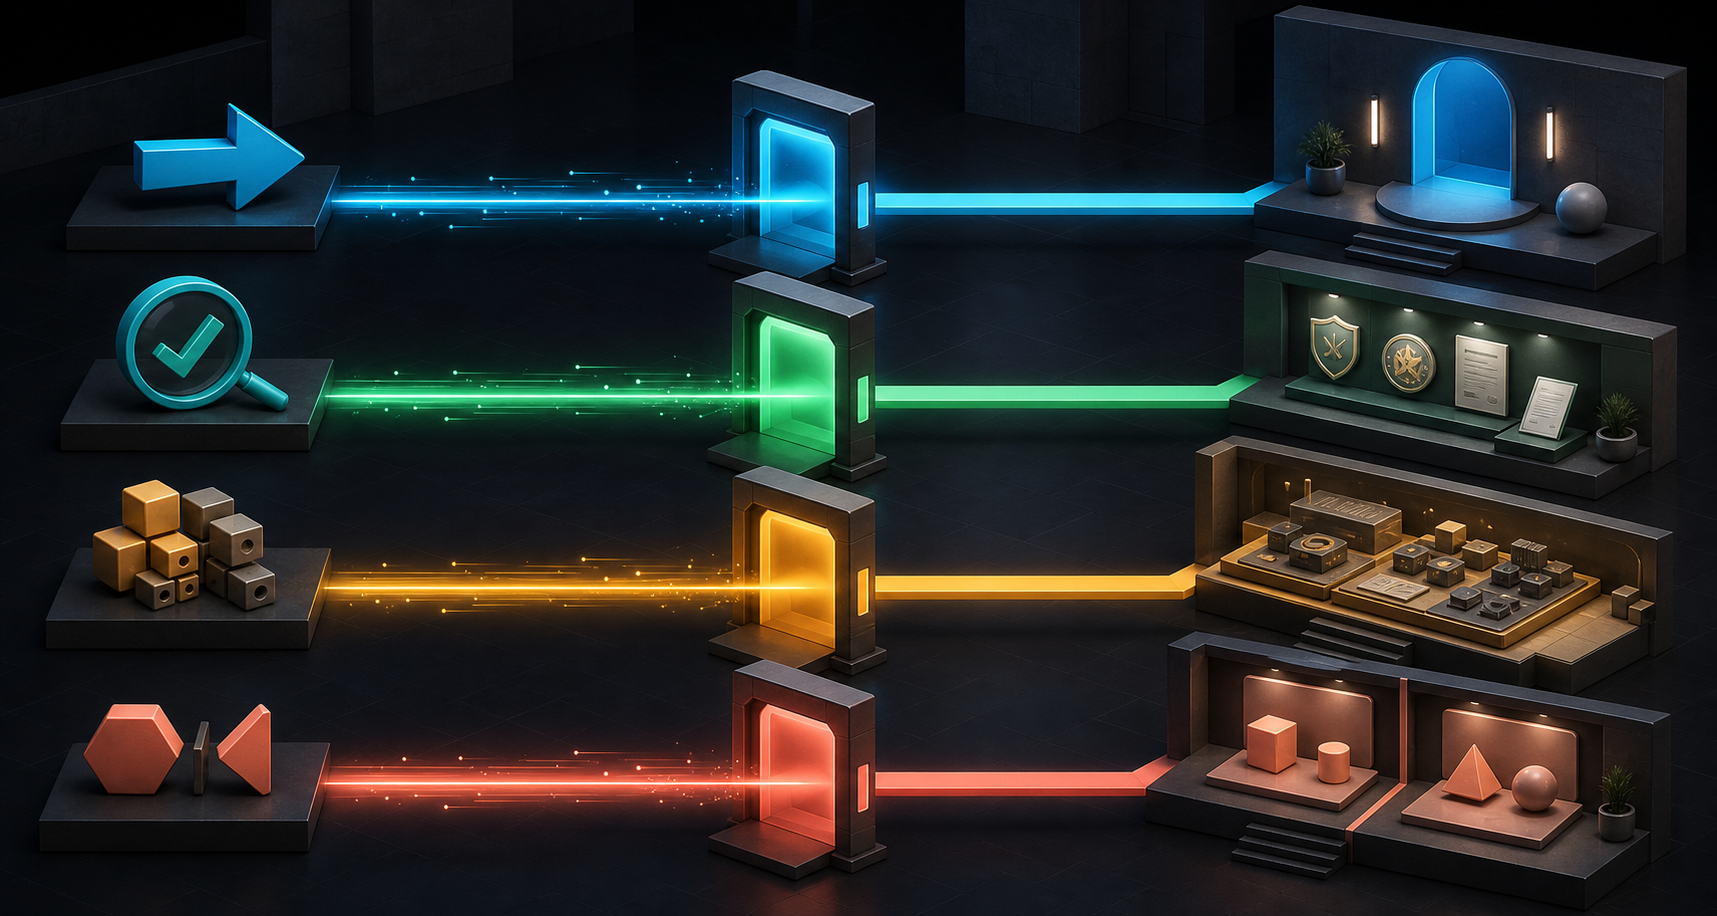
    Four icon-based search signals pass through separate colored gateways and lead to four different landing-page environments.

    Your ad should answer the extra words in the search. Repeating the brand name is rarely enough because the prospect already knows it. Use the headline and supporting copy to address what changed when the modifier was added.

    Trust and reputation searches need verifiable proof

    A query such as Is [Brand] good? is a request for reassurance, not a request for your standard value proposition. Lead with evidence the prospect can verify. That might include eligible ratings, genuine awards, a meaningful history in the market, or a concrete customer outcome, but only when the claim is accurate and supported on the destination page.

    Send the click to a page organized around trust. Put testimonials, rating context, credentials, and answers to common doubts where the visitor can find them without navigating through the rest of the site. Available rating or review assets can reinforce the message, but they cannot compensate for a landing page with no proof.

    Feature searches need a direct confirmation

    For a query containing a specific feature, lead with that capability. The brand is already present in the query, so repeating it in every headline may use space that could resolve the question. Use sitelinks to expose closely related feature pages, documentation, demonstrations, or videos when they help the prospect verify the claim.

    The landing page should make the feature easy to confirm and understand. Name what it does, show how it works, and explain any material limits. A vague product overview forces the visitor back to the search results, where a competitor may offer a clearer answer.

    Comparison searches need an honest decision page

    Alternatives to [Brand] signals active comparison. Avoid answering it with copy that pretends no alternatives exist. Explain the criteria that should drive the decision, where your offer fits, and who may not be a good fit. If your pricing is an advantage, make it easy to understand rather than burying it behind a generic call to action.

    A comparison page should not rely on a straw-man competitor. Use criteria a buyer would genuinely consider, keep claims supportable, and make the basis of each comparison visible. Monitor auction insights for this query family because a new advertiser can change the value of maintaining top-page presence even when the core brand term looks quiet.

    Niche questions need a concise answer before a pitch

    A question such as Is [Brand] expensive? exposes a specific hesitation. Route it to an FAQ-style page or a tightly relevant section that answers the concern in plain language. Explain the factors that affect the answer, then give the visitor an appropriate next step.

    Competition may be lighter on narrow questions, so test lower bids instead of copying the bidding posture used for comparison terms. Check the auction rather than assuming the query is uncontested. More importantly, treat newly appearing questions as feedback: repeated concerns may warrant changes to product pages, sales material, organic content, and customer-facing FAQs.

    Set bids by the cost of losing the decision

    Branded campaigns are often managed as if every click has the same defensive value. It does not. A clean navigational query with no visible advertiser pressure is different from a reputation query surrounded by review sites or a comparison query targeted by competitors.

    • Bid assertively on trust and reputation searches when the prospect is close to choosing and competing pages can intercept that choice.
    • Protect comparison visibility when competitors are actively appearing, but make sure the landing page can support the bid with a credible comparison.
    • Evaluate feature terms separately. A high-value feature query may justify more coverage than the unmodified brand name.
    • Start niche questions with controlled bids when competition is limited, then adjust according to conversion quality and auction pressure.
    • Set navigational brand bids from observed competition and incremental value, not from the assumption that the top paid position must be owned at any cost.

    There is real budget risk in bidding aggressively before you segment performance. Easy navigational conversions can subsidize expensive comparison clicks and conceal the difference in your aggregate return. Separate reporting before raising bids, then decide which searches are worth defending and which need a better page first.

    Judge the campaign with a small set of diagnostic questions:

    • Did the important query trigger the intended ad group and message?
    • Did it land on a page that answered the modifier directly?
    • Which competitors, affiliates, or review properties appeared in auction insights for that intent family?
    • Did the click produce the intended conversion or a qualified lead, rather than merely a high click-through rate?
    • Which new modifiers reveal objections, comparisons, or feature needs that your current structure misses?

    Do not use aggregate branded return as the only success measure. Break out conversion rate, conversion value or lead quality, search-term coverage, and auction pressure by intent. The goal is not to maximize paid brand traffic. It is to preserve access to valuable prospects when paid visibility and a better answer can influence the outcome.

    If you need to test whether paid ads are merely capturing clicks your organic result would have received, avoid pausing the entire defense in the middle of visible competition. Start with the least contested navigational segment and preserve coverage for reputation and comparison queries. A broad pause can expose the brand to competitors while producing a result that does not explain which intent family caused the change.

    Key takeaways

    • A bid on the exact brand name covers navigation, not the full branded customer journey.
    • Separate trust, feature, comparison, and niche-question searches when they need different bids, messages, or destinations.
    • Fix the landing-page route before paying more for a query. A stronger bid cannot repair an unanswered question.
    • Use proof for reputation searches, direct confirmation for feature searches, transparent criteria for comparisons, and concise answers for narrow objections.
    • Review auction insights and search terms by intent so easy brand conversions do not hide competitive gaps.
    • Feed recurring modifiers back into your organic pages and FAQs; they reveal the language prospects use when deciding whether to trust or choose you.

    Start with your existing search-term data. Label the terms by intent, identify the valuable queries currently routed to a generic page, and fix those destinations first. Then change the ads and bids. That order keeps branded-search defense tied to the decision you need to protect, rather than the position you want to occupy.

    References

  • How to Write Competitive Paid Search Ad Copy That Stands Out

    How to Write Competitive Paid Search Ad Copy That Stands Out

    Your paid search ad can be relevant, accurate, and polished yet disappear into a row of near-identical promises. When every advertiser uses the category term, a broad benefit, and Learn more, the problem is not grammar. It is contrast.

    If you are deciding what to change, stop judging each headline in a spreadsheet. The useful unit of review is the complete ad as it appears beside competing ads. That shift turns copywriting from wordsmithing into a practical positioning exercise.

    Start with the search results, not a blank document

    Choose the queries that represent the clearest commercial intent in the campaign. For each query, record what the visible ads actually communicate. You are looking for patterns, not trying to imitate individual phrases.

    1. Intent match: What product, service, or problem does the ad name?
    2. Main promise: What outcome is the advertiser leading with?
    3. Proof: Does the ad use a number, award, named recognition, or another verifiable detail?
    4. Effort: Does it explain how quickly or easily the customer can act?
    5. Commercial offer: Is there a free trial, free quote, or visible price?
    6. Qualification: Does the message specify a location, price level, audience, or other boundary?
    7. Call to action: What does the advertiser ask the searcher to do next?

    Now mark the ideas that recur across the result. If every visible ad leads with the category name and a vague claim about simplicity, another variation of those words will not create a meaningful difference. Keep the category term where it helps confirm intent, but use the remaining space for a reason to choose you.

    Do not confuse different wording with different positioning. Fast setup, get started quickly, and easy onboarding may all occupy the same competitive territory. A genuine differentiator changes the decision: verified adoption, a named award, a real completion time, an accessible starting offer, a clear price, or specific local availability.

    For every proposed differentiator, ask three questions: Can you prove it? Does it answer a concern that matters at this point in the search? Is it meaningfully different from what appears around it? If the answer to any of those questions is no, the line is not ready.

    Build responsive search ads as a message system

    Blank modular message tiles combine along branching paths to form a single abstract search ad card.

    A Responsive Search Ad gives you room for 15 headline options and four descriptions. Filling every field is not the same as creating a versatile ad. If most assets repeat the same noun and benefit, the platform has many combinations but very little real choice.

    Assign every asset a job before you write it:

    • Intent anchor: Confirms what the product or service is.
    • Outcome: Names what the customer can accomplish.
    • Proof: Supports the promise with something verifiable.
    • Effort reducer: Addresses time, complexity, or inconvenience.
    • Offer: Gives the searcher a low-friction next step.
    • Qualifier: Uses price, location, or another useful boundary to attract a better fit.
    • Action: Tells the searcher what to do next.

    This role-based structure makes combinations easier to inspect. An intent anchor can sit beside proof and an action without sounding repetitive. Three assets that all say the product is easy will compete for the same job and may appear together as a weak, monotonous message.

    Read plausible headline and description combinations as complete ads. Check for repeated claims, awkward transitions, contradictory qualifiers, and calls to action that do not match the landing page. An asset can be strong by itself and still create a poor ad when paired with another asset.

    When several headlines are alternatives for the same role, you can pin them to the same position. That allows those alternatives to rotate without appearing beside one another. Pinning can reduce the platform’s ad-strength rating, so use it deliberately when it protects meaning, prevents repetition, or preserves an approved message. The rating is feedback; a coherent customer-facing ad is the goal.

    Replace broad claims with proof, effort, and useful boundaries

    Competitive copy does not become persuasive by choosing a louder adjective. A claim such as Best Local Contractor asks the searcher to accept your opinion. Attaching that claim to named, verifiable recognition gives the person a reason to believe it.

    Run each important claim through the appropriate check:

    • Superiority: Replace an unsupported claim such as best with the specific evidence behind it. If there is no evidence, choose a benefit you can defend.
    • Speed and ease: Describe a real action and a real timeframe. Open an account in 10 minutes is useful only when the customer can reasonably expect that experience.
    • Free offer: State what is free. A free trial and a free quote solve different kinds of hesitation, so do not reduce both to a vague mention of savings.
    • Pricing: Show price when it helps someone compare or qualify themselves. A higher price can also filter out poorly matched prospects, provided the amount and any necessary qualification are accurate.
    • Location: Name the actual place served in a regional campaign. A relevant county, city, or service area is more useful than a generic claim about being local.
    • Action: Name the next meaningful step, such as requesting a quote, starting a trial, or scheduling an appointment.

    Before publishing, compare every promise with the landing page and the operating reality behind it. Can the business fulfill the stated timeframe? Is the recognition named correctly? Does the free offer have a scope the ad should clarify? Does a displayed price need a starting qualifier? If the destination cannot confirm the promise immediately, revise the ad or the page before paying for traffic.

    The most useful copy often does two jobs at once: it attracts the right person and gives the wrong person enough information to opt out. Price, geography, availability, and the exact nature of an offer can reduce raw appeal while improving message fit. That is not a copy failure. It is qualification.

    Use AI to widen the options without surrendering control

    AI is useful for exploring angles, spotting repetition, and producing alternative wording. It should work from an approved fact set, not fill gaps with plausible claims. Treat AI-generated assets as drafts that require human review.

    A practical prompt starts with the competitor message map and a fact bank. Ask for headline and description options grouped by role: intent, outcome, proof, effort, offer, price, location, and action. Tell the model to use only the supplied facts, keep necessary qualifiers, avoid unsupported rankings, and make each group communicate a genuinely different idea.

    Review the output with a stricter standard than fluency:

    • Delete numbers, awards, rankings, and time claims that are not in the approved fact set.
    • Reject assets that restate an existing claim with synonyms.
    • Restore any eligibility, pricing, availability, or geographic qualifier the draft omitted.
    • Check the wording against brand voice and relevant industry requirements.
    • Render the assets in combinations and read them as a searcher would.
    • Confirm that every call to action leads to a page where that action is available.

    Account-level automation needs the same ownership. If every message and link must pass an accuracy or compliance review, disable automatically generated assets rather than allowing unapproved copy or destinations to appear. Automation can help assemble and vary approved material; it cannot take responsibility for whether a claim is true.

    Test the competitive idea, not just the wording

    Two abstract search ad concepts are compared side by side in a controlled testing workspace.

    Do not let an ad-strength score decide which copy deserves to run. A high rating may indicate that the platform has a varied asset inventory, but it does not answer the strategic question: does your ad give this searcher a credible reason to choose you over the alternatives?

    Write a test hypothesis before changing the assets. It should name the competitive problem and the proposed answer. For example: an independently verifiable proof point will create a clearer reason to choose the brand than an unsupported superiority claim. That is more useful than testing whether one adjective beats another.

    1. Choose one message dimension. Test proof, effort, offer, price, location, or action without rebuilding every part of the ad at once.
    2. Protect the comparison. Keep unrelated messaging stable where the setup permits, and prevent duplicate or conflicting assets from muddying the test.
    3. Inspect combinations before launch. Make sure the intended contrast survives assembly and the landing page fulfills both versions.
    4. Judge the business outcome. Use the campaign result that reflects the action you actually value, not an interface score alone.
    5. Return to the result page. Performance data tells you what happened inside the campaign; a fresh competitive review shows whether the message is still distinctive in context.
    6. Record the decision. Keep the query, competitive pattern, hypothesis, assets, outcome, and next action together so the campaign does not drift back toward generic copy.

    Key takeaways

    • Review paid search copy beside competitor ads, because distinctiveness cannot be judged in isolation.
    • Give every Responsive Search Ad asset a defined role instead of filling the inventory with paraphrases.
    • Support superiority claims with evidence, and use truthful details about effort, offers, price, and location to help people decide.
    • Pin alternative assets when necessary to prevent repetition or protect an approved message.
    • Use AI to explore approved facts, then review every claim, qualifier, link, and assembled combination.
    • Test a competitive proposition with a written hypothesis, not merely a different set of words.

    Start with one commercially important query and one live ad. Map the competing promises, remove assets that do the same job, and strengthen the least-supported claim. Your next test will then have a clear reason to exist and a result you can use.

    References

  • Google v. SerpApi: What the Scraping Fight Means for SEO

    Google v. SerpApi: What the Scraping Fight Means for SEO

    If your rank tracker, competitive dashboard, or AI-search monitoring workflow depends on a SERP API, the Google-SerpApi dispute is not remote legal theater. It is a data-supply-chain issue: an upstream collection method could affect the coverage, cadence, cost, and reliability of the measurements you use.

    That does not mean your tools are about to stop working. SerpApi has asked a court to dismiss Google’s claims, and the competing positions have not been resolved. Your practical job is to identify where scraped Google data enters your operation, separate collection failures from real search changes, and prepare a fallback before either problem reaches a client report or automated decision.

    Key takeaways

    • A motion to dismiss is not a ruling that SerpApi acted lawfully, and allowing Google’s claims to proceed would not prove that Google is right.
    • The central dispute is whether the DMCA can apply when a service accesses public, no-login search pages while overcoming Google’s anti-bot controls.
    • A court ruling could influence the risk, availability, and economics of third-party SERP collection, but it will not answer every legal question about scraping.
    • SEO and GEO teams should treat this as a vendor-dependency issue now: document data lineage, preserve methodology metadata, define validation checks, and build replacement paths for critical reports.

    The dispute turns on access, protection, and reuse

    The fact that a search result is visible in a browser does not settle the case. Google alleges that SerpApi evaded bot-detection and crawling controls through rotating bot identities and large networks, then collected and resold material from Search features that included licensed images and real-time data. Those are allegations, not judicial findings.

    SerpApi answers that it collects the same public-facing information a person can see without authentication. It says it does not decrypt a protected system or breach a login barrier. It also argues that Google does not own much of the underlying material displayed in its results and is trying to use the Digital Millennium Copyright Act to protect its platform and advertising interests rather than copyrighted works.

    That creates three questions that are easy to collapse into one:

    • Who owns the material? Google may display text, images, and facts originating elsewhere, but the ownership analysis can differ by element and license.
    • What do the technical controls protect? Google’s theory connects its anti-bot systems to protected Search content. SerpApi’s theory is that controls serving platform or advertising interests do not become copyright-protection measures merely because they obstruct automated access.
    • What is being done with the collected data? Viewing a public page, collecting it automatically, operating at scale, and reselling the resulting dataset are different activities. A conclusion about one does not automatically resolve the others.

    SerpApi invokes hiQ v. LinkedIn and Impression Products v. Lexmark to support its position that technical barriers should not let a platform monopolize public-facing information. Those precedents are part of SerpApi’s argument; they do not predetermine how the court will characterize Google’s systems, the material displayed in Search, or SerpApi’s conduct.

    The procedural posture matters just as much. A motion to dismiss generally tests whether pleaded legal claims can go forward. It is not a full trial of disputed facts. If the motion succeeds, you must still read which claims were dismissed and on what grounds. If it fails, Google has cleared a procedural threshold, not won the lawsuit.

    Do not mistake the widely repeated $7.06 trillion figure for a judgment, settlement demand, or likely damages award. It is SerpApi’s theoretical calculation of potential penalties under Google’s interpretation of the DMCA. It illustrates how expansive SerpApi believes that interpretation could become; it does not predict the financial outcome.

    Each possible outcome has narrower meaning than the headline

    The unhelpful way to read this dispute is as a referendum on whether public data is always free to scrape. The useful way is to ask what a particular ruling establishes, which legal claim it addresses, and which operational assumptions it puts under pressure.

    • If the motion is granted: the challenged claims may be legally insufficient in their pleaded form. That would support SerpApi’s defense, but it would not create a universal license to scrape any public website for any purpose.
    • If the motion is denied: Google’s claims may proceed into later stages. That would not be a finding that every allegation is true or that all automated collection from public pages violates the DMCA.
    • If Google ultimately prevails on its anti-circumvention theory: providers using similar collection methods could face greater legal and technical pressure. Customers might experience narrower feature coverage, higher costs, slower collection, provider consolidation, or abrupt service changes.
    • If SerpApi ultimately prevails: the result could strengthen the position that access to public, no-login search results cannot be restricted through the DMCA theory Google advances here. Separate questions involving contracts, content rights, licenses, misrepresentation, or other causes of action would still depend on their own facts and law.

    The pressure also extends beyond one search platform. Reddit filed claims against SerpApi and others in October 2022, alleging indirect collection through Google Search, concealed identities, and industrial-scale activity. That broader conflict is a warning for data buyers: a provider can face objections from the platform being queried, the owners of material appearing in results, or both.

    For planning purposes, classify the case as unresolved upstream risk. Do not describe scraping as definitively lawful because the pages are public. Do not tell stakeholders that all third-party SERP APIs are unlawful because Google filed a complaint. Neither statement follows from the current procedural stage.

    Your measurement can fail before the legal question is settled

    A partially blocked digital pipeline turns a stream of search-result tiles into incomplete analytics displays.

    SEO teams rarely consume scraping infrastructure directly. They see a rank, a feature flag, a competitor count, a screenshot, or an AI-visibility score. That abstraction is convenient until the collection layer changes and the dashboard continues presenting its output as if the underlying observation were stable.

    Four failure modes deserve explicit checks:

    • Coverage loss: a provider may stop returning a result type, location, device class, language, or page depth. A missing observation can then be misreported as a lost ranking or absent feature.
    • Sampling drift: stronger blocking can change which successful requests survive. Your trend line may compare two different samples even though the dashboard label has not changed.
    • Latency: retries and collection friction can make a supposedly current result older than expected. This matters when you are investigating a launch, algorithm change, reputation event, or volatile query.
    • Provider continuity: legal expense, infrastructure changes, or tighter access controls can alter pricing and service levels even before a final ruling.

    The operational rule is simple: separate a market signal from a collector signal. A sudden loss of rankings across one geography may reflect Google Search, but it may also reflect an endpoint, parser, proxy pool, localization setting, or feature-classification change.

    Preserve enough metadata to test that distinction. For every observation that can trigger a decision, retain the provider, collection time, requested location, language, device, result type, and methodology version where your agreement permits it. Store raw response evidence or a rendered capture when you are contractually and legally allowed to retain it. Treat an empty response as unknown until the system can distinguish a genuine absence from a failed collection.

    For an owned website, Google Search Console can corroborate changes in impressions, clicks, and average position, but it cannot reproduce a live competitive SERP or explain every feature-level observation. A second data vendor may help, although two vendors can share similar collection dependencies. Manual checks on a small, predefined diagnostic query set provide another useful signal, provided they use consistent location, language, device, and personalization conditions.

    The same discipline applies to AEO and GEO reporting. If a system derives an AI-search visibility score from Google result features, a missing mention may mean that the brand disappeared, that the feature was not collected, or that the parser stopped recognizing it. Keep the captured answer or result evidence separate from the calculated score. Never let a score of zero stand in for missing evidence.

    When a major shift appears, ask three questions before changing content: Did the search experience change? Did the acquisition method change? Did the interpretation layer change? If you cannot answer all three, annotate the report and withhold automated recommendations until you have corroboration.

    Audit your SERP-data dependency in six steps

    An analyst's hands inspect six symbolic stations surrounding a central search-data analytics console.
    1. Build a dependency register. List every rank tracker, SERP API, competitive-intelligence platform, AI-visibility product, internal script, and agency feed that observes Google results. Record the provider, endpoint, markets, device profiles, collection cadence, retention period, and downstream reports or automations.
    2. Mark decisions, not just systems. Identify what happens when each field changes. A number viewed by an analyst is lower risk than a field that changes bids, rewrites briefs, triggers client alerts, evaluates staff, or publishes customer-facing claims. Give the highest scrutiny to inputs that cause action without human review.
    3. Ask vendors method-specific questions. Find out which outputs depend on automated access to public Google pages; which use official or licensed interfaces; how the vendor distinguishes blocked requests from absent results; whether methodology changes are disclosed; what incident notices you receive; and how quickly you can export historical data. Request written answers for critical services.
    4. Design a replacement by use case. Use first-party performance data for owned-site outcomes where it fits. For competitive rankings, define a smaller priority query set that can be checked through another method. For feature monitoring, preserve time-stamped evidence. For AI-search tracking, keep prompt, response, model or interface, location conditions, and scoring logic separable so one unavailable feed does not erase the whole record.
    5. Add a collection circuit breaker. Set the reporting system to flag abrupt changes in response completeness, feature frequency, geography coverage, timestamps, or error rates. When the check fires, label the period as potentially incomplete, pause automated recommendations, and notify the people who consume the affected metric.
    6. Escalate the right legal questions. If your organization directly operates scraping infrastructure, bypasses technical restrictions, resells SERP data, distributes licensed images or real-time content, or makes contractual promises about uninterrupted access, obtain advice from counsel familiar with copyright, the DMCA, data licensing, and relevant contracts. A general blog cannot determine the exposure of a particular implementation.

    Your vendor review should also cover commercial concentration. Switching from one collector to another is not a complete fallback if both depend on materially similar access methods. Ask what can be replaced with first-party data, what can tolerate reduced frequency, what requires independent verification, and what has no realistic substitute. The last category needs an explicit owner and a documented decision about acceptable downtime.

    Do not wait for a final judgment to run the test. Pick one business-critical SEO or AI-visibility report this week. Trace every external field to its acquisition method, mark the fields that cannot be independently verified, and simulate one reporting cycle with the primary feed unavailable. You will learn more from that exercise than from trying to predict the court.

    When the next ruling arrives, read the claims and procedural grounds before changing policy. Until then, keep public visibility, technical access, content ownership, and commercial reuse as separate questions. That distinction will make both your legal review and your search measurement substantially more reliable.

    References

  • How to Measure ChatGPT Brand Recommendation Bias

    How to Measure ChatGPT Brand Recommendation Bias

    Your brand appears in one ChatGPT recommendation, disappears in the next, and returns several positions lower in a third. A competitor runs the prompt once, takes a screenshot, and declares that it owns the category. Neither result tells you very much on its own.

    To make a sound decision, you need to separate normal answer variation from a persistent preference for particular brands. That means measuring a distribution of answers, not treating one response as a verdict. Here is how to build that measurement, interpret it, and turn it into a practical AI visibility strategy.

    A variable answer can still contain a durable brand bias

    Brand recommendation bias does not have to mean that ChatGPT follows a fixed list or deliberately favors a company. In a useful measurement context, it means that brands have unequal probabilities of appearing when comparable users ask comparable questions. Some names recur across many answers, while others occupy a long tail of occasional mentions.

    The individual responses can look highly unstable. Repeated prompts almost never produced the same collection of brands in the same order twice. That makes a single screenshot a poor visibility metric. It may capture a common recommendation, an unusual outlier, or something in between.

    Underneath that variation, however, a much more concentrated pattern can emerge. Across 100 runs of a B2B software prompt, an average of 44 different brands appeared. In some categories, the total reached 95. Yet only about five brands, or 11% of the brands mentioned, appeared in at least 80% of the responses. In accounting software, familiar names such as QuickBooks, Xero, and Wave belonged to that recurring group.

    Those findings are not contradictory. They describe a recommendation distribution with a small, stable head and a large, volatile tail. A dominant brand can appear in most runs while dozens of other brands rotate through the remaining places. If your company appears once in that long tail, you have evidence of possible visibility, not evidence of dependable visibility.

    The category also changes how you should read an omission. Highly competitive B2B software categories generated about twice as many brand mentions per 100 responses as niche categories. Missing from one crowded accounting-software answer is therefore a weaker signal than repeatedly missing from a tightly defined category with a smaller recommendation set.

    Prompt detail matters too. Requests that included a defined persona and use case generally returned fewer brands than simple category prompts, although this was not an absolute rule. A broad question gives ChatGPT room to rotate through many plausible names. A constrained question filters the field by fit.

    The benchmark behind these figures used 12 B2B prompts, ran each one 100 times, and used different IP addresses to mimic 1,200 separate users. Treat the results as evidence that recommendation volatility is material, not as a universal baseline for every category, model, market, or prompt.

    Measure a distribution instead of collecting screenshots

    A circular testing apparatus sends identical abstract prompt tiles into many trays containing different arrangements of colored objects, with glass beads grouped at the center.

    A defensible visibility program starts with a repeatable protocol. If the wording, context, model, or scoring rules change between runs, you will not know whether the brand moved or the test moved.

    Build a prompt set around real buying decisions

    Do not begin with every question you can imagine. Begin with the questions that could influence discovery, evaluation, or a shortlist. Include both broad and nuanced prompts because they measure different forms of visibility.

    • Broad discovery: Which accounting software should a small business consider?
    • Persona fit: Which accounting platforms suit a finance team that lacks dedicated IT support?
    • Use-case fit: Which tools are suitable for a particular workflow, security need, or reporting requirement?
    • Constraint fit: Which options fit a specified budget structure, deployment model, company size, or integration requirement?
    • Alternative discovery: Which products should a buyer compare when replacing a familiar category leader?

    Keep unaided recommendation prompts unbranded. If you put your brand in the question, you are measuring how ChatGPT describes or compares a known candidate, not whether it retrieves the brand independently. Both tests can be useful, but they answer different questions and should be reported separately.

    Run every prompt under controlled conditions

    1. Freeze the wording. Save the exact prompt under a permanent ID. Even a useful refinement should become a new prompt rather than silently replacing the original.
    2. Control the context. Start each run in a fresh conversation so earlier messages cannot shape the answer. Use the same ChatGPT surface and the same available model within a batch.
    3. Repeat the prompt. For commercially important questions, run each prompt at least a handful of times. Use the same repetition count when comparing prompts, brands, or reporting periods.
    4. Preserve the complete answer. A brand name without its surrounding language cannot tell you whether ChatGPT recommended it, mentioned it as an alternative, or warned that it might not fit.
    5. Record the test conditions. Save the date, model label shown in the interface, prompt ID, run number, and any relevant location or account condition.

    You do not need to recreate a 100-run experiment for every routine check. You do need enough repeated observations to see whether a mention recurs. Keep the batch size fixed and disclose it whenever you report the result. A mention rate based on a handful of runs carries more uncertainty than one based on 100, even when the percentages happen to match.

    Calculate metrics that preserve the context

    For each response, record every recommended brand, its position, and the language attached to it. Then calculate a small set of metrics:

    • Mention rate: the number of runs containing your brand divided by the total number of runs for that exact prompt.
    • Prompt coverage: the share of tracked prompts on which your brand appears at least once. Report broad and nuanced prompt coverage separately.
    • First-position share: how often your brand is listed first. Use this cautiously because a list’s order does not necessarily represent a formal ranking.
    • Distinct-brand count: the number of different brands appearing across the batch. This shows whether you are competing in a concentrated or highly fragmented recommendation set.
    • Co-mention frequency: which competitors most often appear in the same answers as your brand. This reveals the comparison set ChatGPT tends to construct for the prompt.
    • Recommendation-quality rate: how often the brand is endorsed, conditionally recommended, mentioned neutrally, or described as a poor fit. A raw mention should not receive full credit when the surrounding advice is unfavorable.

    Keep the raw answers alongside the calculations. The metric tells you what pattern occurred; the answer text tells you why the mention should or should not count as commercially valuable.

    Read the pattern before deciding what to change

    Once you have repeated results, the combination of broad visibility, nuanced visibility, and recommendation quality becomes more informative than any isolated rank. Use the following patterns as diagnostic signals, not automatic conclusions.

    Observed patternLikely interpretationUseful next action
    High mention rate across broad and nuanced promptsThe brand has a durable category association and is also considered relevant to specific buying situations.Protect the accurate category and use-case coverage, then look for important personas or constraints where visibility weakens.
    High broad visibility but low nuanced visibilityThe brand may be well known without being strongly associated with the specified buyer or use case.Clarify who the offer serves, which problems it handles, and what evidence supports that fit.
    Low broad visibility but strong visibility in a narrow prompt clusterThe brand has a potentially valuable niche association rather than general category dominance.Strengthen that niche and test adjacent use cases before spending heavily on a broad category battle.
    Occasional mentions among many rotating brandsThe brand is part of the long tail, or the category itself is unusually fragmented.Do not celebrate the isolated appearance. Repeat the test and narrow the prompt to determine where the brand has credible fit.
    Frequent mentions with conditional or negative languageRaw visibility is overstating the brand’s recommendation strength.Inspect the recurring objection and correct unclear, outdated, or unsupported public information where you can substantiate the change.

    Category breadth must remain part of the interpretation. A brand competing against a rotating pool of dozens of names should not be evaluated against the same raw mention-rate expectation as a brand in a narrow field. Compare your current results with your own prior batches and with brands returned for the same prompt. Avoid inventing one platform-wide visibility benchmark.

    Frequency also does not reveal the cause of a recommendation. A recurring appearance shows that the brand is strongly associated with the question under the tested conditions. It does not, by itself, prove that ChatGPT has a complete understanding of the brand, that the recommendation is factually correct, or that the product is objectively the best choice.

    This distinction matters when you communicate results internally. Say that a brand appeared in a stated share of repeated runs for a specific prompt set. Do not translate that into an unsupported claim that ChatGPT prefers the company everywhere or that the company has won AI search.

    Build around recommendation contexts you can credibly own

    An unbranded product on a central platform connects by bridges to a home workspace, an outdoor kit, and a professional workshop, while distant platforms remain disconnected.

    If you are not already one of the dominant names in a broad category, trying to displace every established brand at once is usually the least informative place to begin. Competitive categories expose you to a much larger rotating set of recommendations, while niche prompts give ChatGPT fewer plausible candidates to consider. The practical opportunity is to become consistently relevant to a defined decision.

    A niche is not merely a longer keyword or a cleverly engineered prompt. It is a buyer, problem, constraint, or use case that your company can genuinely support. If your product is designed for a particular industry, team structure, workflow, deployment requirement, or risk profile, make that fit explicit and prove it on the pages a prospective customer would expect to find.

    1. Select one commercially meaningful prompt cluster. Group together the broad category question and the persona, use-case, and constraint variants that represent the same buying decision.
    2. Establish the baseline. Run the frozen prompts repeatedly and separate dependable mentions from one-off appearances.
    3. Audit the information behind the decision. Check whether your site plainly states the category, intended customer, supported use cases, limitations, integrations, and differentiators. Do not ask an AI system to infer positioning that customers cannot verify.
    4. Improve the weakest substantiated area. Add or revise content only where the business can support the claim. A focused page that answers a real evaluation question is more useful than a collection of thin pages created for every prompt variation.
    5. Retest the same batch. Keep the original prompts and scoring method intact. New exploratory prompts can be added under new IDs, but they should not erase the baseline.

    For SEO and GEO teams, this also sets a sensible boundary around structured data. Organization, Product, or SoftwareApplication markup can make the identity and subject of an applicable page more explicit when the structured fields agree with the visible content. It cannot substitute for a clear market position, credible product information, or genuine fit. The repeated-run evidence does not establish that adding JSON-LD by itself increases recommendation frequency, so do not report schema deployment as a guaranteed ChatGPT visibility tactic.

    Prioritize changes where three conditions meet: the prompt represents a valuable customer decision, repeated runs reveal a meaningful weakness, and you have accurate information that can close the gap. If one of those conditions is absent, you are likely optimizing for test noise rather than buyer value.

    Key takeaways

    • A single ChatGPT response cannot establish brand visibility because the brands and their order can change between identical runs.
    • Persistent bias appears as unequal mention frequency across repeated, controlled prompts, not as one favorable or unfavorable answer.
    • Broad prompts and nuanced persona or use-case prompts measure different kinds of brand association and should be reported separately.
    • Track recommendation context as well as the presence of a name; an unfavorable or weakly qualified mention is not a positive recommendation.
    • Crowded categories produce broader, more volatile brand sets, so smaller brands may find a more defensible opportunity in a credible niche.
    • Keep prompt wording, run conditions, batch size, and scoring rules stable when comparing results over time.

    Start with the buying question that matters most to your business. Freeze its broad and nuanced variants, run each a handful of times, and score the complete answers. Your next content or positioning decision should come from the repeated pattern: defend a stable association, strengthen a credible niche, or fix a specific fit problem. Let the next batch show whether the pattern changed.

    References

  • Google Search Antitrust Appeal: An SEO Readiness Plan

    Google Search Antitrust Appeal: An SEO Readiness Plan

    If you manage SEO or AI visibility, don’t treat Google’s antitrust appeal as an algorithm update. Nothing in the current record gives you a reason to rewrite pages, change schema, or explain a rankings dip.

    The practical issue is distribution: which search engine or AI app people encounter first on their browser or device. That can redirect discovery and traffic even when every ranking system stays exactly the same. Your job now is to establish a clean baseline, define the events that would justify action, and avoid making expensive changes based on legal headlines alone.

    What the appeal changes – and what it does not

    There are two separate questions in this case: whether Google unlawfully maintained a monopoly and what the court should do about it. U.S. District Judge Amit Mehta found in August 2024 that Google illegally maintained its search monopoly through default-placement agreements. The current government appeal challenges the remedy imposed after that finding.

    Following a remedies trial in 2025, the judge declined to order two of the government’s most consequential proposals: separating Chrome from Google and completely prohibiting payments for default search placement. The resulting remedy instead requires Google to rebid default search and AI app agreements annually.

    That distinction matters. Annual rebidding creates a recurring commercial decision point, but it does not prevent Google from paying for placement or guarantee that a partner will select another provider. The Department of Justice and participating states are appealing because they want the appellate court to revisit whether that remedy is strong enough to restore competition.

    The initial appeal filings did not disclose the government’s complete legal argument. Chrome and Google’s default arrangement with Apple are expected to be central issues, but an expected point of dispute is not an ordered remedy. The U.S. Court of Appeals for the D.C. Circuit must still review the challenge.

    • Confirmed: The government is appealing the remedies decision.
    • Confirmed: The trial court did not order a Chrome breakup or a complete ban on default-placement payments.
    • Confirmed: The remedy requires annual rebidding of covered default search and AI app agreements.
    • Unresolved: Whether the appellate court will preserve, strengthen, or require reconsideration of that remedy.
    • Not indicated: An immediate change to Google’s ranking systems, Search Console, structured-data support, or search advertising platform.

    The appeal concerns access to users, not page rankings

    Three unbranded devices send different paths toward the same unchanged arrangement of webpage cards.

    Google’s default agreements matter because a preselected service captures user attention before a person actively compares alternatives. Google has spent more than $20 billion per year on default arrangements with companies including Apple and Samsung. The trial court treated those agreements as a mechanism through which Google protected its search position.

    For an SEO team, this creates an important diagnostic rule: a change in traffic is not automatically a change in rankings. If a browser or device starts sending more users to another engine, your Google positions could remain stable while Google organic sessions decline. A site could also gain visits from a competing engine without improving there, simply because more people were directed to it.

    • Ranking change: Your relative position inside a search engine changes.
    • Distribution change: The browser, device, or app sends a different share of people to each discovery service.
    • Behavior change: People use search, an AI answer interface, or direct navigation differently even though defaults and rankings remain stable.

    Those mechanisms require different responses. A ranking loss calls for query, page, competitor, and technical analysis. A distribution shift calls for engine, browser, device, and referral analysis. A behavior shift calls for journey and conversion analysis. Combining all three under a label such as “organic volatility” hides the decision you need to make.

    The inclusion of AI app agreements in the remedy makes the same distinction relevant to generative discovery. An AI service’s availability as a default or integrated option can affect how often people use it, but that does not establish which brands it will cite or recommend. Track access and visibility separately: referrals show whether the service sends visits, while prompt-level checks help you notice whether your brand appears in its answers.

    Critics argue that the remedy leaves the original competitive mechanism largely intact. Yelp’s public-policy team has said that continuing to permit default-placement payments is unlikely to restore competition, while also warning that Google’s search indexing and ranking power could extend into generative AI. That is an interested party’s position, not a prediction of what the appellate court will order, but it identifies the commercial link marketers should watch.

    Plan for three outcomes without betting on any of them

    A useful contingency plan connects each legal outcome to an observable business signal. It does not assign false probabilities or move budgets before the signal appears.

    Planning scenarioWhat could changeWhat you should do
    The annual-rebidding remedy remainsDefault placements face recurring negotiation, but payments and continued Google placement remain possible.Watch contract renewals and measured traffic by engine, browser, and device. Do not assume each rebid will produce a new default.
    Default-payment restrictions become stricterSearch access could become more contestable among providers, creating a distribution shift without a Google ranking change.Wait for persistent audience and conversion movement before reallocating effort. Evaluate each engine by qualified outcomes, not raw visit share.
    Chrome separation returns as a remedyBrowser ownership and search distribution could be separated, although the implementation details would determine the real effect.Model Chrome traffic independently, but do not assume Chrome users would automatically leave Google Search. Reforecast only when product or default behavior is known.

    The table is a trigger map, not a forecast. A court decision may also require more proceedings before users see any product change. Keep legal milestones, implementation announcements, and actual audience data on separate lines in your reporting. That prevents a possible remedy from being presented internally as an accomplished market shift.

    A readiness plan for SEO and AI discovery teams

    A small team monitors abstract traffic signals around a table with three parallel pathway models in a modern operations room.

    You can prepare without guessing how the appeal will end. The useful work is measurement and portability: knowing where discovery comes from and making your content understandable outside one distribution channel.

    1. Save a pre-change acquisition baseline. Record organic sessions, qualified actions, conversions, and revenue by search engine. Add browser, device type, geography, and landing page where your data volume and privacy controls permit. Preserve the reporting definition so a later comparison does not mix a market shift with a tracking change.
    2. Separate branded from non-branded discovery. A rise in direct brand demand and a rise in generic search visibility are different gains. Use query data where it is available, and label traffic that cannot be classified instead of forcing it into a confident category.
    3. Pair Google data with cross-channel evidence. Search Console is essential for understanding Google impressions, clicks, queries, and pages, but it cannot describe another engine’s audience. Use analytics, server logs, and the equivalent webmaster data offered by other engines to complete the view.
    4. Create a distribution-change alert. Flag an engine, browser, or device shift only when it exceeds your normal variation and persists beyond one reporting interval. Then check tracking releases, consent behavior, campaigns, seasonality, rankings, and site incidents before connecting it to the antitrust case.
    5. Measure AI discovery as its own pathway. Track identifiable AI referrals, the landing pages they reach, and the actions those visitors complete. Maintain a stable set of high-intent prompts for visibility checks, but label the results as sampled observations rather than market-wide usage data.
    6. Make important information portable. Keep key facts in crawlable page content, use descriptive headings, identify the organization and author clearly, and connect claims to supporting evidence. Apply relevant JSON-LD only when it matches visible content. Schema can reduce ambiguity for machines; it does not guarantee a ranking, citation, or AI recommendation.
    7. Define response thresholds before pressure arrives. Write down what would justify a technical investigation, a content experiment, or a budget change. For example, a court headline alone triggers monitoring; a confirmed product-default change triggers a forecast update; a persistent shift in qualified conversions triggers channel reallocation analysis.
    8. Route contract questions to counsel. If your company operates a browser, device, search service, or AI app covered by distribution agreements, the language of a final order could affect legal and commercial obligations. Marketing analysis is not a substitute for reviewing those agreements with qualified legal counsel.

    Do not respond by cloning content for every search engine or adding unsupported schema in the hope that more markup creates broader visibility. Maintain one authoritative version of each page, keep structured data consistent with it, and investigate material engine-specific differences only when measurement shows a real gap.

    Key takeaways

    • The government is appealing the strength of the Google Search remedy; this is not evidence of a Google ranking update.
    • The current remedy allows default-placement payments to continue but requires covered search and AI app agreements to be rebid annually.
    • A stricter remedy could change which service users encounter first, causing traffic movement without corresponding ranking movement.
    • Chrome separation and tighter limits on Google’s Apple agreement are potential areas of dispute, not current requirements.
    • Your best preparation is a stable cross-engine baseline, browser and device segmentation, independent AI visibility measurement, and trigger-based decision rules.

    Start by preserving your acquisition baseline and assigning one owner to connect court developments with verified product changes. When the next headline arrives, ask one question before touching content or budget: what changed for users in the product? If the answer is “nothing yet,” keep measuring.

    References


  • How to Evaluate Leading AI Software Companies in 2026

    How to Evaluate Leading AI Software Companies in 2026

    If you are shortlisting AI software companies, a generic ranking answers the wrong question. A company can lead at the model layer and still be a poor choice for deploying a governed workflow inside your business.

    Your real task is to identify the kind of company you need, define what leadership means for your use case, and make each candidate prove it with your workflow and representative data. That turns a crowded market into a decision you can defend.

    Start with the job, not the company ranking

    There is no useful universal winner. A packaged AI application, a model provider, a cloud platform, and a custom development company solve different parts of the problem. Ranking them together is like ranking an engine, a delivery van, and a logistics contractor on the same scale.

    Before you collect vendor names, write a short procurement brief. It should be specific enough that another person could recognize a successful deployment without hearing the sales pitch.

    • Workflow: Name the task or decision the software will support. Avoid broad goals such as “use AI for marketing.” A workable definition is closer to “produce a cited first draft from approved product documentation for an editor to review.”
    • Owner: Identify the person accountable for the workflow after launch. A sponsor can approve a purchase, but an operational owner has to manage errors, updates, and user adoption.
    • Inputs: List the documents, databases, messages, images, or application events the system may use. Record where that data lives and who has permission to expose it.
    • Output and action: State what the system produces and what happens next. Distinguish a suggestion shown to a person from an action executed in another system.
    • Failure boundary: Describe acceptable mistakes, unacceptable mistakes, and the point at which a human must intervene. A formatting error and an invented compliance claim cannot share the same severity.
    • Environment: Name the identity system, content repository, analytics stack, customer platform, or other software the product must work with.
    • Evidence: Define what a candidate must demonstrate using representative cases. A polished demonstration using vendor-selected examples is not evidence of fit.
    • Exit conditions: Decide what data, configurations, prompts, evaluation cases, logs, and code you must be able to recover if you change providers.

    If you cannot complete this brief, pause the vendor search. When the outcome is vague, almost any demonstration can look successful, and disagreements about quality appear only after money and integration work have been committed.

    Compare companies that perform the same role

    Four distinct AI software workstations connect to the same central business task for a role-based comparison.

    The label leading AI software development companies can cover businesses with very different products and delivery models. Put each candidate into a functional category before you compare features, pricing, or market visibility.

    Company typeChoose it whenEvidence to requestCommon mismatch
    Model or API providerYour team is building its own application and needs model capabilities as a component.Results on your evaluation cases, usage controls, model-change procedures, latency behavior, and data-handling terms.Buying raw capability when you do not have the engineering or operational team to turn it into a reliable workflow.
    Cloud or data platformYour priority is connecting AI to governed data, existing infrastructure, and enterprise controls.Architecture fit, identity integration, data boundaries, deployment options, monitoring, and portability.Assuming platform breadth means the desired business application is already complete.
    Packaged AI applicationYou need a defined outcome in a familiar function such as content operations, support, analytics, or sales workflow.Workflow coverage, administrator controls, export options, user permissions, integration depth, and evidence from representative tasks.Paying for a broad feature set while the product remains weak at the narrow task that matters.
    Workflow or agent platformYou need AI to coordinate steps, tools, and approvals across systems.Action permissions, state handling, retries, approval gates, audit logs, failure recovery, and limits on autonomous behavior.Treating an impressive prototype as a dependable operational process.
    Custom AI development companyNo packaged product fits the workflow, or your process and data create meaningful differentiation.Proposed architecture, delivery ownership, evaluation method, repository access, documentation, deployment plan, support model, and intellectual-property terms.Commissioning custom software before confirming that the workflow is stable enough to specify and maintain.
    AI operations or governance providerYou already have AI systems and need evaluation, observability, policy enforcement, or control across them.Coverage of your actual stack, alert quality, policy implementation, evidence retention, and response procedures.Expecting a control layer to repair poor application design or unsuitable source data.

    A candidate can belong to more than one category, but you should still name the role you are buying from it. Otherwise, a vendor’s strength in one layer can distract you from a gap in another. If you need a finished application, model quality alone does not settle the decision. If you need a model component, a large catalogue of packaged features may be irrelevant.

    Turn “leading” into pass-or-fail requirements

    Feature counts reward breadth, and weighted scorecards can hide a fatal weakness behind a high total. Use non-negotiable gates first. Score or rank only the companies that pass every gate that protects the workflow.

    • Task performance: The product must produce usable results on ordinary cases, difficult edge cases, and inputs that should trigger refusal or escalation. Define “usable” in terms of the next step in the workflow, not whether the output sounds polished.
    • Evaluation discipline: Ask how the company detects regressions and separates different error types. For generated answers, completeness, factual support, citation quality, format compliance, and harmful fabrication are different dimensions. A blended quality claim can conceal the failure that matters most to you.
    • Data governance: Get written answers about retention, use of customer data for training, storage location, deletion, subprocessors, tenant separation, and access by vendor personnel. Product controls and contract language should agree.
    • Security and human control: Confirm authentication, role-based access, approval steps, auditability, and the ability to stop or override automated actions. The more consequential the action, the less acceptable an invisible decision path becomes.
    • Integration depth: Distinguish a live, supported integration from a demonstration, roadmap item, or generic API. Verify the exact records the system can read, create, update, and export.
    • Operational resilience: Ask what happens when a model, connector, data source, or downstream system fails. A production workflow needs observable errors, safe fallbacks, ownership, and a recovery procedure.
    • Commercial fit: Calculate the cost of the working process, including usage, integration, human review, monitoring, support, and ongoing evaluation. A low software price can still produce an expensive workflow if reviewers must repair most outputs.
    • Exit viability: Confirm that you can retrieve business data and the operational assets needed to continue elsewhere. For custom development, define ownership of code, prompts, configurations, documentation, and deployment materials before work begins.

    Treat unsupported roadmap promises as unavailable. Record each capability as proven, contractually committed, or absent. Those labels keep a persuasive demonstration from turning future intent into present functionality.

    References and customer logos can help you understand where to investigate, but they do not replace workflow evidence. Ask references about deployment effort, failure handling, support after the sale, and what their internal team still has to operate. A similar industry is useful; a similar data shape, risk level, and workflow is better.

    Run a production-shaped proof before you commit

    A business and engineering team observes an AI proof-of-concept moving through security, human review, monitoring, and final delivery stages.

    A proof should test the operating system around the AI, not just the most attractive output. Keep the workflow narrow enough to inspect closely, but preserve the data conditions, permissions, integrations, and review steps that will exist in production.

    1. Freeze the use case. Give every candidate the same workflow definition, input boundaries, expected output, and failure rules. Do not let each vendor redefine success around its strongest feature.
    2. Build the evaluation set. Include routine examples, ambiguous inputs, incomplete information, edge cases, and requests the system should decline or escalate. Keep a portion of the cases out of vendor-led configuration so you can see how the system handles unfamiliar inputs.
    3. Protect sensitive information. Use de-identified or synthetic material until contractual, security, and internal approvals permit representative production data. When real data becomes necessary, expose only what the approved test requires.
    4. Record configuration work. Track the prompts, rules, connectors, data cleanup, and human assistance required to achieve the result. A system that performs well only after extensive hidden preparation may carry a much higher operating cost than the demonstration implies.
    5. Test the whole handoff. Measure whether users can review, correct, approve, reject, and trace the output inside the intended workflow. A strong answer copied manually between applications may still be a weak production solution.
    6. Force recoverable failures. Remove a source, deny a permission, provide conflicting information, or interrupt a downstream service in a controlled test. Check whether the system fails visibly, preserves state, avoids unsafe actions, and gives an operator a clear recovery path.
    7. Review the evidence by error type. Keep a failure log that identifies what went wrong, its consequence, whether a person detected it, and whether the proposed fix is repeatable. Do not average a severe failure into a reassuring overall score.
    8. Price the observed workflow. Use the actual configuration, workload shape, review effort, support requirement, and integration pattern from the proof. Model an increase and decrease in usage so you can see which charges are fixed and which scale with activity.
    9. Test the exit. Export representative data and configuration, inspect its format, and identify what cannot move. For a custom system, verify access to the repository, build instructions, environment configuration, and operating documentation.

    The proof should leave you with artifacts you can inspect later: the frozen evaluation set, result sheet, failure log, data-flow map, architecture diagram, cost model, operating runbook, and exit plan. If the only durable artifact is a presentation, you have evaluated a sales process rather than a production system.

    Reject any company that fails a non-negotiable gate, even if it has the highest total score. Among the survivors, prefer the option that reaches the required outcome with the clearest controls, lowest operational burden, and most credible path out. That is a more useful definition of leadership than size, visibility, or the longest feature list.

    Key takeaways for your shortlist

    • Define the workflow, owner, data, action, failure boundary, evidence, and exit conditions before collecting vendor names.
    • Compare model providers with model providers, applications with applications, and development companies with development companies.
    • Make task performance, data governance, security, operational resilience, economics, and exit viability pass-or-fail gates.
    • Use the same production-shaped evaluation cases for every candidate, and keep severe errors visible instead of burying them in an average.
    • Count configuration, integration, review, monitoring, and support when calculating cost.
    • Choose the company that can prove the required outcome and remain operable when inputs, systems, or providers change.

    Take your current list and write each company’s intended role beside its name. Remove candidates that solve a different layer, send the survivors the same procurement brief, and do not declare a leader until the proof produces evidence your operational owner is willing to accept.

    References

  • ChatGPT Ads: What OpenAI’s Pause Means for Marketers

    ChatGPT Ads: What OpenAI’s Pause Means for Marketers

    If you’re deciding whether to reserve budget for ChatGPT ads, don’t treat OpenAI’s pause as either a canceled channel or an imminent launch. Neither conclusion is useful. The practical move is to prepare the parts you control while keeping activation spend conditional.

    The pause reveals an important constraint on OpenAI’s advertising strategy: the assistant has to retain attention and trust before it can carry a durable ad product. That changes what your team should build now, what it should leave blank, and which questions must be answered before you buy anything.

    The pause changes the sequence, not the long-term direction

    OpenAI has put its ChatGPT advertising plans on hold while it concentrates on speed, reliability, reasoning, and the broader user experience. The internal code red also directs attention toward reducing hallucinations and improving the assistant’s ability to complete complex tasks.

    That is a sequencing decision. Advertising remains part of the long-term strategy, but product stabilization comes first. For marketers, the distinction matters: a delayed channel deserves monitoring and preparation, not a committed media forecast built from assumptions.

    Do not plan around an unconfirmed launch date, inventory map, placement type, buying model, targeting system, or measurement specification. A pause does not answer any of those questions. It only shows that OpenAI currently considers product quality a prerequisite for monetization.

    Key takeaways

    • OpenAI has delayed ChatGPT advertising while it works on the assistant’s core performance and user experience.
    • The delay does not mean OpenAI has abandoned advertising as a revenue stream.
    • There is not enough confirmed detail to build a channel forecast around formats, targeting, pricing, or launch timing.
    • Your useful work now is measurement, intent mapping, content readiness, and launch governance.
    • Activation money should remain conditional until OpenAI publishes the operating details your team needs.

    Why assistant quality comes before ad inventory

    A person interacts with a glowing conversational orb while several unlit advertising tiles remain behind a translucent partition in the background.

    A ChatGPT ad product will inherit the trust conditions of the assistant around it. If an answer feels slow, fragmented, or unreliable, adding a commercial message creates more friction. If the assistant consistently helps users finish a task, an appropriately separated and relevant ad has a better chance of being useful.

    This is why the competitive pressure from Google matters to the advertising plan. Gemini’s advantage is presented as more than a benchmark contest: its integration with products such as Google Maps and Workspace can help it carry a user from a question into an action. OpenAI, meanwhile, is trying to make ChatGPT feel more like a dependable executor of tasks and less like a passive answer box.

    The commercial inference is straightforward. Useful task completion creates opportunities for relevant offers. Poor task completion makes advertising feel like an interruption. OpenAI therefore has two readiness gates to pass:

    • Assistant readiness: The product must be fast, dependable, coherent, and valuable enough that people continue using it.
    • Advertising readiness: OpenAI must define placements, labeling, targeting, controls, billing, reporting, privacy boundaries, and advertiser eligibility.

    The pause indicates that the first gate still commands attention. It tells you nothing conclusive about the maturity of the second. Ask for evidence that both gates are open before treating ChatGPT as an executable media channel.

    This also explains why a contextually relevant format is more plausible strategically than a generic display interruption, although no specific format should be treated as confirmed. OpenAI ultimately needs advertising that fits the user’s task without making the answer itself feel purchased or less trustworthy.

    Build readiness without buying imaginary inventory

    A marketing team organizes unbranded creative cards, audience tokens, and measurement blocks beside an empty media-placement frame under a transparent cover.

    You can prepare for ChatGPT advertising without pretending to know how it will work. Concentrate on assets that remain useful whether the launch arrives early, late, or in a form nobody predicted.

    1. Establish an AI traffic baseline. Create an analytics segment for visits whose referrer identifies ChatGPT. Record the landing page, engaged session, conversion, revenue where applicable, and assisted conversion. Keep the limitation visible: answers that influence a person without producing a click will not appear as referral traffic.
    2. Build a question-to-outcome map. Collect the questions customers ask in search data, sales calls, support tickets, reviews, and on-site search. Group them by the outcome the user wants: discover, compare, verify, choose, or act. Mark which questions have commercial intent and which require a neutral informational answer.
    3. Audit the pages that should support those outcomes. Each important page should identify the entity or product clearly, answer the central question directly, substantiate material claims, disclose meaningful constraints, and have an owner responsible for updates. Structured data should describe the visible page accurately; it should not introduce claims that users cannot verify on the page.
    4. Prepare modular messages and landing paths. Write short value propositions for each high-intent question, but do not build copy around a guessed ChatGPT placement. The message should still work if the eventual unit is adjacent to an answer, shown after a recommendation, or offered as an action.
    5. Define your evidence standard. Decide which product claims require documentation, which offers need current terms, and who approves regulated or high-risk language. A conversational interface can place a claim close to a user’s decision, so stale qualifications and ambiguous terms can become costly problems.
    6. Assign launch ownership now. Name the people responsible for media buying, analytics, privacy review, legal review, brand suitability, landing-page changes, and AI visibility. A new channel becomes hard to test when every unanswered question has to find an owner after launch.

    None of this guarantees paid eligibility, organic inclusion, or a citation in ChatGPT. It removes avoidable delays and gives you a clean baseline against which a future paid test can be judged.

    Require a complete launch brief before you spend

    The first announcement of inventory will not necessarily provide everything required for a responsible campaign. Product availability and campaign readiness are different events. Your team should be able to fill in the following brief from OpenAI’s actual documentation and platform controls, not from screenshots, rumors, or analogies to search ads.

    • Availability: Which countries, languages, account types, ChatGPT plans, devices, and assistant surfaces contain ads?
    • Placement: Does the unit appear inside an answer, beside it, after it, or as a separate recommended action? Can an ad affect the wording or ordering of the non-paid answer?
    • Disclosure: How is commercial content labeled, and does the label remain visible when an answer is shared, exported, or summarized?
    • Eligibility: Which industries, offers, destinations, and claims are restricted? What review process applies before an advertiser or campaign can run?
    • Targeting: Can advertisers select queries, topics, audiences, locations, tasks, or conversation contexts? Which controls prevent irrelevant matching?
    • Data boundaries: What conversational or account information can be used for targeting, optimization, reporting, and retargeting? What consent and retention rules apply?
    • Pricing and delivery: Is the campaign billed for impressions, clicks, actions, or another event? How are auctions, pacing, budgets, and delivery priority handled?
    • Advertiser control: Are exclusions, negative targets, frequency controls, suitability settings, placement reports, and blocklists available?
    • Measurement: Which impression, click, view, conversion, attribution, and incrementality reports exist? Can advertisers use independent analytics and conversion records?
    • User control: Can people dismiss an ad, correct an irrelevant assumption, change personalization settings, or understand why a commercial message appeared?

    Do not accept a familiar metric name without its definition. A click beside a conversational answer may represent a different level of intent from a click on a conventional search result. Likewise, an impression is not useful for planning until you know when the platform counts it and whether the ad was actually visible.

    A pilot is ready only when you can name its objective, eligible question set, conversion event, attribution window, landing experience, acceptable acquisition cost, and stop condition. Those values must come from your own economics. If the platform cannot provide the controls or reporting needed to enforce them, the campaign is not ready merely because inventory is available.

    Keep the initial allocation reversible. A controlled test budget protects you from locking an annual plan to a new interface whose user behavior, ad load, reporting quality, and optimization mechanics have not yet been demonstrated for your business.

    Keep paid ChatGPT ads separate from AI visibility

    Paid placement and inclusion in an assistant’s non-paid answer solve different problems. Until OpenAI explicitly documents a relationship between them, plan and report them separately. Buying an ad should not be treated as a shortcut to being cited, recommended, or described favorably in an organic response.

    Your organic preparation should make the brand easier to understand and verify regardless of the advertising timeline:

    • Maintain a clear canonical page for each important company, product, service, location, and policy.
    • Put the direct answer to a page’s main question near the beginning instead of burying it beneath promotional copy.
    • Support comparative, performance, safety, pricing, and availability claims with evidence appropriate to the claim.
    • Keep names, descriptions, relationships, and material product facts consistent across visible content and JSON-LD.
    • Make structured data specific enough to identify the entity while ensuring every marked-up claim is also present and accurate on the page.
    • Assign review dates and owners to pages containing details that can change.
    • Track brand presence and factual accuracy across a stable set of relevant prompts, but record the prompt, model, date, and context so the observations remain interpretable.

    This work is not a backdoor advertising tactic. It is content and entity hygiene. It helps you diagnose whether a future campaign is adding demand, capturing existing demand, or merely taking credit for users who already knew the brand.

    OpenAI’s decision to prioritize retention and product quality before ad deployment should shape your own planning sequence. Create three separate budget lines: market intelligence, channel readiness, and activation. Start the first two now. Release the third only when confirmed specifications pass your launch brief and a controlled pilot can answer a real business question.

    That leaves you ready without betting on a date. More importantly, it gives you the measurement discipline to recognize whether ChatGPT ads become a valuable acquisition channel or simply an expensive new place to appear.

    References

  • Google-SerpApi Scraping Lawsuit: An SEO Team Playbook

    Google-SerpApi Scraping Lawsuit: An SEO Team Playbook

    Your rank tracker can keep returning data while the legal and commercial assumptions underneath it have already become a business risk. If your dashboards, client reports, competitive research, or AI visibility monitoring depend on SerpApi or another reseller of Google results, you need an exposure map before a court outcome, not a prediction of who will win.

    Google’s claims remain contested, and filing a lawsuit does not prove them. But the dispute targets the collection method, the content being collected, and the resale of that content. Those issues can affect service continuity, field coverage, pricing, and historical comparability long before they establish a legal rule.

    What the lawsuit does and does not establish

    Google is not merely objecting to someone looking at a public results page. It alleges that SerpApi evaded security measures and crawling controls to collect and resell search-result content. More specifically, Google accuses SerpApi of:

    • Circumventing technical protections and standard crawling controls.
    • Disregarding website directives intended to limit content access.
    • Using cloaking, rotating bot identities, and large bot networks to avoid detection.
    • Taking licensed material from search features, including images and real-time data, and selling access to it.

    Those are Google’s allegations, not findings of fact. SerpApi denies wrongdoing, argues that public search data should remain accessible, and has invoked the First Amendment in defending its position. It also warns that restrictions of this kind could damage an open web.

    Do not turn that disagreement into either of two unsupported conclusions: that every form of SERP collection is unlawful, or that anything visible in a browser is automatically unrestricted. The real questions are more specific:

    • How was the data accessed?
    • Which technical controls or publisher directives applied?
    • Does the result contain material licensed from another provider?
    • What exactly is being stored, transformed, displayed, and resold?
    • Which party assumes the risk if access is restricted?

    This distinction matters when you evaluate a supplier. A provider’s broad statement that its data is public does not answer a narrower allegation about evading controls or redistributing licensed content. You need enough provenance to understand the service you are buying, even if the provider cannot disclose its entire technical system.

    Audit your SERP dependency before the data changes

    Analysts trace branching data connections from a generic search-results source to rank tracking, reports, research, storage, alerts, and AI monitoring tools.

    Start with operational exposure rather than courtroom speculation. The goal is to identify what would break if a provider removed fields, reduced request volume, changed its collection method, raised prices, or stopped serving a particular Google feature.

    1. Find direct and indirect dependencies. Search your scripts, workflow automations, data warehouse jobs, dashboards, reporting templates, and vendor integrations for SerpApi and other SERP data services. A platform can expose search data without making its upstream supplier obvious, so ask embedded vendors as well.
    2. Separate the data classes. Record whether each workflow uses organic links, snippets, images, knowledge features, shopping information, local results, or real-time features. The lawsuit’s emphasis on allegedly licensed feature content makes a generic label such as “Google data” too vague for risk review.
    3. Map every downstream commitment. Note which datasets feed internal research, executive reporting, client deliverables, automated alerts, product features, or contractual service levels. A low-volume feed can still be critical if a customer-facing report depends on it.
    4. Capture a baseline. Preserve your field dictionary, query settings, market and device assumptions, freshness expectations, failure rate, and representative outputs, subject to your retention rights. Without a baseline, a provider-side methodology change can look like a ranking or visibility change.
    5. Assign a fallback. Name the replacement method, the owner who can activate it, and the reporting limitation it introduces. “Find another API” is not a fallback plan unless you have tested how its definitions and coverage differ.

    Classify the dependency by the consequence of failure, not by the number of API calls:

    DependencyPractical responseImportant limitation
    Ad hoc researchSave query definitions and identify a manual sampling method.A small manual sample may not reproduce the provider’s location, device, or personalization assumptions.
    Recurring internal dashboardTest a second data path and annotate any supplier or methodology change.Two providers may label positions and search features differently.
    Client or executive reportingDocument the dependency, establish a change-notice process, and prepare a reporting caveat.Combining incompatible series can create a false trend.
    Customer-facing product featureReview the contract, test graceful degradation, and define who can activate the contingency.A legal remedy after disruption will not restore immediate availability.

    For information about your own site’s Google performance, a first-party source such as Google Search Console may cover part of the need. It does not reproduce a complete results page or provide a like-for-like replacement for competitive SERP monitoring. Treat it as one layer of a fallback, not a universal substitute.

    When you test an alternative, overlap the old and new methods before combining their data. Compare query interpretation, country and location handling, device type, result-feature definitions, missing fields, freshness, and error behavior. If the series are not comparable, start a new baseline and mark the break instead of presenting it as an SEO movement.

    Put collection provenance into vendor review

    Two reviewers inspect a transparent data chain linking generic web collection, a vendor server, and an analytics workstation beside blank compliance documents.

    Do not ask only, “Is this legal?” That invites a sales assurance rather than a useful explanation. Ask questions that expose the collection path, rights assumptions, and continuity plan:

    1. What is the origin of each data class? Ask the provider to distinguish directly collected Google output, third-party licensed data, transformed data, estimates, and information obtained through another supplier.
    2. How does the service respond to access restrictions? You do not need instructions for evading controls. You do need to know whether the provider stops, substitutes data, reduces coverage, or changes methods when access is limited.
    3. Which fields may contain third-party licensed material? Images and real-time features deserve separate treatment from ordinary organic URLs because Google has specifically raised licensed-content allegations.
    4. What changes first under pressure? Ask whether a restriction would affect certain countries, devices, result types, request volumes, freshness levels, or historical exports before the entire service failed.
    5. How will customers be notified? Request the provider’s process for communicating collection-method changes, field removals, legal restrictions, and material coverage loss.
    6. Can you export your history and metadata? Historical values without query settings, timestamps, markets, device assumptions, and field definitions may be impossible to interpret after migration.
    7. How does the contract allocate risk? Have qualified counsel review warranties, indemnities, termination rights, notice obligations, permitted uses, and retention terms in the context of your actual implementation.

    A vendor contract cannot guarantee uninterrupted access to an external platform. It can clarify responsibility, but you still need a technical fallback. Keep those two workstreams separate: counsel assesses legal exposure, while your data and SEO teams protect continuity and measurement quality.

    Answers that should slow your decision

    • “The data is public.” This does not explain whether technical controls were bypassed or whether some fields contain licensed material.
    • “Everyone collects search results.” Industry prevalence does not tell you how this provider operates or what rights attach to each data class.
    • “Customers have never had a problem.” That does not establish a continuity plan, a notification process, or a contractual remedy.
    • “Our method is completely legal.” An unqualified conclusion is less useful than a written explanation of the access model, relevant rights, and scope of the assurance.
    • “We cannot discuss any aspect of collection.” A provider may protect proprietary details, but complete opacity prevents you from performing even basic supplier-risk review.

    If your own collection code, or a method disclosed by a supplier, appears to bypass access controls or conceal bot identity, do not expand that deployment until qualified legal counsel has assessed the actual facts. This operational checklist cannot determine whether a particular system is lawful.

    Protect AI visibility and SEO reporting without changing strategy

    The provenance question extends beyond a direct SerpApi account. Reddit has separately accused SerpApi, Perplexity, Oxylabs, and AWMProxy of participating in an indirect scraping chain involving Google results. Reddit says it planted a trap item visible only to Google’s crawler that later appeared in Perplexity results. SerpApi denies the allegations.

    That claim does not prove how every named party obtained every item. It does illustrate why data lineage matters: your dashboard may receive information through several suppliers, and the company selling you the final metric may not be the company collecting the underlying result.

    For an AI visibility, AEO, or GEO platform, document the measurement chain with the same care you would apply to a rank tracker:

    • Label whether each metric comes from a directly observed model response, a Google result, a third-party dataset, or an inferred score.
    • Retain the query or prompt, timestamp, market, device, search feature, and model or product identifier when those fields are available.
    • Require a methodology changelog so a collection change cannot quietly become an apparent visibility gain or loss.
    • Keep observed facts, such as whether a brand appeared, separate from proprietary scores or estimates.
    • Rebaseline a metric when its supplier, collection path, feature definition, or model surface changes materially.
    • Do not use Google SERP coverage as an unlabeled substitute for direct measurement of an AI system. Search visibility and model-response visibility answer different questions.

    The lawsuit itself is not evidence of a Google ranking update, a change to structured-data processing, or a new standard for earning AI citations. Do not rewrite content, remove JSON-LD, or change your internal-link strategy because litigation was filed. Change the governance around the data used to judge those activities.

    Predefine the events that will trigger action: a supplier notice, unexplained field loss, a sustained change in failure behavior, a restriction on a result type, a material pricing change, or a change in collection methodology. Then name who decides whether to continue, degrade the report, activate a fallback, or start a new measurement baseline. That prevents a technical incident from turning into an improvised legal and client-communication decision.

    Key takeaways

    • Google’s claims against SerpApi are contested allegations, not a judgment that all SERP data collection is unlawful.
    • Your immediate exposure is operational as well as legal: access, fields, prices, and historical comparability can change before the case is resolved.
    • Audit direct APIs and hidden upstream suppliers across dashboards, reports, automations, and AI visibility tools.
    • Ask how each data class was obtained, which rights apply, what degrades under restriction, and how methodology changes are disclosed.
    • Use overlapping tests and explicit baseline breaks when changing providers; otherwise a measurement change can masquerade as an SEO trend.
    • Keep your content and schema strategy tied to search performance evidence. The lawsuit calls for stronger data governance, not reactive optimization changes.

    Your next move is concrete: inventory every workflow that depends on full Google results, classify its business impact, and send the seven provenance questions to each supplier. You do not need to predict the verdict to make your measurement stack less fragile.

    References