Tag: Competitive Analysis

  • Toxic Backlink Sabotage: When an SEO Attack Becomes a Lawsuit

    Toxic Backlink Sabotage: When an SEO Attack Becomes a Lawsuit

    If your backlink audit suddenly shows spam pages pairing your company with drugs, loans, gambling, or weapons, do not begin with a public accusation or an indiscriminate cleanup. Preserve what happened first. A federal court has now left open the possibility that an allegedly deceptive backlink campaign can support false-advertising and related claims, but that is not the same as proving sabotage.

    Your immediate job is to separate an ugly link pattern from evidence of responsibility, intent, and harm. That distinction will determine whether you have an SEO incident to mitigate, a brand-protection matter to escalate, or a potential legal dispute that needs counsel.

    Key takeaways

    • A lawsuit surviving a motion to dismiss means the allegations were legally plausible enough to continue. It does not mean the alleged attack happened or that the defendant is liable.
    • A suspicious backlink profile does not identify who created the links. Attribution requires separate evidence.
    • Preserve raw link data, anchor text, page captures, dates, communications, and business-impact records before remediation changes the evidence.
    • Keep SEO correlation, attacker attribution, legal responsibility, and financial harm as separate questions.
    • Do not retaliate, publicly name a suspected competitor, or send a cease-and-desist letter without a coordinated legal and monitoring plan.

    What the toxic-backlink ruling changes, and what it does not

    Auto transport company Montway alleged that competitor Nexus AT LLC created more than 2,350 toxic backlinks between April and October 2025. The links allegedly used anchor text such as buy steroids online, payday loan services, illegal betting sites, cocaine powder online, and unlicensed firearms while directing people to Montway’s website.

    The alleged injury had two parts. Montway claimed the campaign was intended to reduce its Google rankings and to create false associations between its brand and illegal or disreputable products. It also alleged that a former Nexus manager connected the campaign to directions from Nexus CEO George Arkin and an SEO contractor. Those remain allegations; they have not been established at trial.

    In a June 2 ruling at the motion-to-dismiss stage, Judge Matthew Kennelly allowed the federal Lanham Act false-advertising claim, trademark claims, and related Illinois consumer-protection claims to proceed. The California unfair-competition claims were dismissed. At this stage, a judge asks whether the pleaded facts plausibly state a viable claim, not whether the plaintiff has proved those facts.

    The distinctive part of the ruling concerns the anchor text. The court found it plausible that the text was literally false because it appeared to promise one destination but sent users somewhere else. It also found that the alleged campaign could qualify as commercial advertising or promotion under the Lanham Act.

    That gives companies a legal theory worth discussing with counsel when the facts fit. It does not establish that every spam link is false advertising, that toxic links necessarily reduce rankings, or that a competitor is responsible whenever suspicious links appear. The ruling permits litigation to continue under the allegations presented; it is not a finding of liability or a universal shortcut around proof.

    Build the evidence around three separate questions
    Gloved hands organize digital evidence into three connected groups showing suspicious links, attribution clues, and damage to a website node.

    A useful investigation does not put every screenshot, ranking decline, and suspicion into one folder labeled attack. Build three evidence tracks. Each answers a different question, and a strong answer in one track cannot replace a weak answer in another.

    1. What links and representations actually appeared?

    Start with observable facts. For every relevant backlink, retain the full linking URL, the destination URL, the exact anchor text, the page title, the page content surrounding the link, and the date and time you captured it. Save both a visual capture and the underlying page data where your tools allow it. A screenshot shows what a person could see; a raw export or saved page helps preserve technical details that a screenshot can miss.

    Keep the original export unchanged. Work from a copy when you classify or annotate links. If your team hashes evidence files, record the hash alongside the capture date; the hash can help show that a file was not altered later, although it cannot prove that the original webpage was truthful.

    Do not let an automated toxic-link score become your conclusion. Record it as a tool-generated metric, then document the concrete features that caused concern: false destination language, repeated off-topic anchors, common page templates, clustered timing, shared infrastructure, or another observable pattern. This makes the record understandable to people who do not use your SEO platform.

    2. What evidence connects the activity to a responsible party?

    A distinctive anchor pattern may support an inference of coordination. It does not tell you who ordered the work. Attribution needs its own evidence, such as lawfully obtained communications, admissions, contractor relationships, campaign instructions, witness accounts, or records produced through a proper legal process.

    Montway’s pleading did not rely only on a link chart. It also included the alleged account of a former manager who attributed the direction to the competing company’s CEO and an SEO contractor. That kind of allegation is categorically different from noticing that suspicious links began near a competitive event.

    Maintain a clear confidence label for every attribution statement: confirmed fact, third-party statement, technical inference, or unresolved suspicion. Do not impersonate people, access accounts without authorization, or pressure a contractor into disclosing information improperly. Those tactics can create separate legal and security problems while contaminating an otherwise credible investigation.

    3. What measurable harm occurred, and what else could explain it?

    A ranking decline can coincide with a backlink campaign without being caused by it. Preserve query-level rankings, affected landing pages, organic sessions, conversions, qualified leads, and revenue records that your business already maintains. Use exact dates and consistent comparison methods. Do not convert a traffic estimate into a claimed financial loss without showing the steps between them.

    Record competing explanations on the same timeline: site migrations, content removals, template releases, crawling problems, outages, analytics changes, redirects, and other technical work. A credible analysis tries to disprove its preferred explanation. If the matter proceeds, counsel and qualified experts can decide what causal conclusions the evidence supports.

    Brand harm is another evidence stream. Capture any actual search result, customer communication, publisher page, or other interface that presents the false association. Do not infer that users saw or believed an association merely because the anchor exists on a remote page.

    If you are also worried about AI search visibility, document it separately. Record the AI product and model where displayed, the exact prompt, the full response, the date and time, and relevant account or location conditions. One problematic answer does not prove a recurring representation, and the presence of toxic backlinks does not by itself prove that they caused an AI system’s output. Structured data and on-page entity clarification may improve your owned content, but they cannot establish who placed a third-party backlink.

    Preserve first, then choose a proportionate response
    A forensic analyst archives a hostile link network in a transparent cube while isolating a small set of contaminated connections from healthy nodes.

    The safest operational sequence protects both SEO remediation and the legal record. It also reduces the chance that a hurried accusation turns an external incident into a second dispute. This is general risk-management information, not a substitute for legal advice about your facts or jurisdiction.

    1. Freeze the initial record. Export the backlink dataset, preserve representative pages, record collection times, and restrict changes to the originals. If a page disappears later, your record should still show what your team observed.
    2. Open a single incident timeline. Include the first observed link, link-volume changes, anchor clusters, ranking or traffic movements, technical site changes, communications, reports to search platforms, and remediation actions. Separate the event date from the date on which your team discovered it.
    3. Bring SEO, security, communications, and legal owners together. SEO can explain link patterns and search changes. Security can preserve technical records and access controls. Communications can prevent speculative public statements. Counsel can assess claims, jurisdiction, preservation obligations, and contact strategy.
    4. Continue necessary mitigation without erasing the before-state. Use the relevant search-engine reporting and link-management channels, but record exactly what was submitted or changed and when. Preserve the underlying evidence before a URL is blocked, removed, reported, or otherwise handled.
    5. Prepare a counsel-ready packet. Include a short chronology, raw evidence locations, representative examples, known totals and date ranges, attribution evidence, documented business effects, alternative explanations, prior communications, and unanswered questions. Label estimates and third-party metrics clearly.
    6. Plan any notice as an escalation event. Montway alleged that the backlink activity intensified after an October 2025 cease-and-desist letter. That allegation does not prove that cease-and-desist letters generally worsen attacks. It does show why monitoring, evidence capture, technical response, and counsel availability should be in place before a notice is sent.
    7. Do not retaliate. Buying bad links to a suspected competitor, threatening individuals, or publishing an unverified accusation can create new exposure and make your original account less credible. Preserve, report, investigate, and escalate through lawful channels.

    A cease-and-desist letter is not a routine SEO ticket. It can reveal what you know, harden the other side’s position, trigger evidence-preservation issues, or prompt further activity. Let qualified counsel decide whether to send one, what it should claim, and what your team must be ready to do afterward.

    Turn backlink sabotage into a defined incident class

    Most teams lose useful evidence because nobody owns the first response. Add suspected search sabotage to your incident playbook instead of leaving it inside a recurring SEO report. Define who can preserve data, who can contact platforms, who approves public statements, and who calls outside counsel.

    Your playbook should trigger enhanced review when several signals appear together: a coordinated cluster of off-topic anchors, text that falsely describes the destination, concentrated timing, credible attribution evidence, actual ranking or reputation effects, or a change in activity after contact. None of those signals proves liability on its own. Their purpose is to determine how quickly and formally the team should respond.

    Use a simple operational triage. A suspicious pattern with no attribution and no documented harm usually calls for preservation, technical analysis, reporting, and monitoring. A pattern with credible attribution calls for early legal review even if harm remains unclear. A pattern combining false representations, meaningful attribution evidence, and documented business or brand effects warrants an urgent joint review by counsel and the SEO incident owner. These are escalation categories, not legal tests.

    Companies have traditionally had limited options beyond reporting suspected manipulation to search engines. The surviving Lanham Act theory creates a possible additional route, but litigation remains fact-specific and the allegations in this case are still unproven. Your advantage comes from building a reliable record before you need to decide which route fits.

    If you have detected a coordinated pattern, make three moves now: preserve the raw evidence, write a dated one-page chronology, and put your SEO lead and legal counsel on the same review. Even if the incident never becomes a lawsuit, that record will give you cleaner remediation decisions and a defensible basis for protecting the brand.

    References


  • How to Measure AI Search Visibility With Your SEO Data

    How to Measure AI Search Visibility With Your SEO Data

    You have an AI visibility score. It fell. Now comes the awkward question: did fewer systems recommend your brand, did a narrow group of prompts change, or did your tracking method move the goalposts?

    Until you can connect each score change to a stable prompt set, stored answers, cited URLs, and SEO or on-site outcomes, the number cannot guide useful work. The measurement system below gives you that chain, so you can decide whether the response belongs in content, technical SEO, distribution, competitive analysis, or analytics.

    Key takeaways

    • Measure a fixed, versioned set of audience prompts. If the prompt set changes, the resulting score is not directly comparable with the previous score.
    • Keep brand presence, citations, competitive share of voice, search performance, and business outcomes separate. They answer different questions.
    • Store the full answer and its citations for every prompt run. A percentage without retrievable evidence is difficult to audit or act on.
    • Join cited URLs to Google Search Console, GA4, your content inventory, and competitive SEO data. That is where an AI observation becomes a diagnosis.
    • Use MCP to reduce report-building and export work, but validate its queries and definitions. Easier access to data does not make the interpretation automatically correct.

    Stop asking one visibility score to explain everything

    A brand mention is not a citation. A citation is not a visit. A visit is not a conversion. Combining all of them into one proprietary score may produce a tidy trend line, but it hides the point at which performance actually changed.

    AI share of voice is commonly framed around how often AI answers mention your brand across a relevant set of questions. That is useful, but only after you define relevant. The reported 17.2% presence figure on that measure is context, not a universal target. Your prompt mix, markets, platforms, competitors, and collection method determine what your own percentage means.

    Measurement layerPrimary metricQuestion it answersCommon misreading
    Brand presenceShare of eligible prompt runs that mention the brandDo AI answers include us?Counting repeated mentions in one answer as several wins
    Owned citationShare of eligible runs that cite an owned domainIs our site being used as supporting material?Assuming every citation sends a visit
    Competitive share of voiceBrand appearances divided by all appearances for a fixed peer setWho occupies the answers in this market?Changing the competitor set between reporting periods
    Search responseGoogle Search Console queries, impressions, clicks, and page performanceWhat is moving in conventional search around the affected topics and pages?Claiming that AI visibility caused an SEO change merely because both moved
    Site outcomeLanding-page visits, engagement, and defined conversions in GA4Did measurable visits produce useful behavior?Treating exposure without a click as though it never happened

    Define presence at the prompt-run level: the brand is either present or absent in an eligible answer. Count the brand once per answer, even if it appears several times. Define citation rate the same way, then maintain a separate URL-coverage measure for the distinct pages cited. This prevents a verbose answer from outweighing a concise one.

    An eligible run is one in which the platform returned an answer that could reasonably address the prompt. Log blank responses, errors, refusals, and unavailable features as collection failures rather than silently removing them. Publish the eligible-run count beside every rate. Otherwise a strong percentage can conceal poor coverage.

    Do not average unlike surfaces into a single headline number. Keep results for ChatGPT, Gemini, AI search features, markets, and languages segmented unless they used the same prompt definitions and collection rules. You can add a portfolio view later, but the underlying segments must remain visible.

    Build a prompt panel you can run again without changing the test

    Rows of blank prompt cards pass repeatedly through a calibrated testing machine while altered cards are kept in a separate channel.

    Your measurement denominator should come from customer decisions, not from a convenient keyword export. A search keyword and a conversational prompt can express the same need differently, so use search data to inform the panel without copying every query verbatim.

    Cover the decisions where AI visibility could matter:

    • Category discovery: questions that ask which products, services, methods, or providers fit a situation.
    • Problem solving: questions that describe a symptom, obstacle, or desired outcome without naming a category.
    • Consideration: comparisons, alternatives, suitability questions, and trade-offs between approaches.
    • Validation: questions about evidence, trust, implementation, compatibility, limitations, or risk.
    • Action: questions that indicate the person is ready to choose, configure, contact, buy, or adopt something.

    Keep a stable core panel for trend reporting and a separate discovery panel for emerging questions. New discovery prompts can graduate into the core panel at a documented boundary. Do not insert them into historical calculations and then present the resulting movement as improved visibility.

    Each prompt record should preserve enough context to reproduce and inspect the observation:

    • A permanent prompt ID, exact prompt text, intent class, audience, topic, and funnel decision.
    • The platform, product surface, visible model or mode, market, language, and device context where relevant.
    • The date and time, signed-in or personalization state, and any location setting used.
    • The full raw answer, every displayed citation, each destination URL, and the first-mention order for tracked brands.
    • Presence, owned citation, competitor appearances, answer eligibility, and collection-error fields.
    • The prompt-panel version and the extraction or classification rule used to turn the answer into metrics.

    Generative answers can vary between runs. A screenshot proves that your brand appeared once; it does not establish a durable ranking. Run the panel under consistent conditions, preserve each observation, and aggregate only after collection. If you edit a prompt, create a new version instead of overwriting its history.

    Classification needs the same discipline. Decide in advance whether product names, parent companies, common abbreviations, misspellings, and partner domains count as your brand. Maintain an alias list for every tracked company. Apply it to all periods, including competitors, or apparent share-of-voice movement may come from inconsistent naming rather than changed answers.

    Join AI observations to page, query, and outcome data

    The raw AI log tells you what appeared. It rarely tells you why. The most useful join key is usually the cited URL because it connects an answer to a page you can inspect, compare, and improve.

    1. Normalize cited URLs. Resolve known redirects and standardize protocol, hostname, fragments, parameters, and trailing slashes. Preserve both the observed URL and normalized destination so you do not erase evidence of a broken or outdated citation.
    2. Match pages to Google Search Console. Pull the queries, impressions, clicks, and search positions associated with cited and affected pages for consistent reporting windows. Keep branded and non-branded query groups separate.
    3. Match landing pages to GA4. Review traffic channels, referrers, engagement, and the conversions your property actually defines. Normalize GA4 landing-page paths carefully when they omit the hostname or include query parameters.
    4. Add content attributes. Attach page type, template, topic cluster, author or owner, publication status, locale, directory, and last material update. These dimensions reveal whether a change is concentrated in a content system rather than an isolated URL.
    5. Add competitive SEO context. Compare ranking pages, keywords, referring-domain trends, estimated traffic, and new or redirected sections where your SEO platform exposes them. Keep estimated third-party metrics distinct from first-party analytics.

    Once those records are connected, read combinations of signals rather than treating each chart independently:

    • Presence rises while owned citations stay flat: the brand is entering answers, but the domain is not becoming a more frequent supporting destination. Inspect which external pages are cited and what evidence or format they provide.
    • Presence is flat while owned citations rise: your competitive visibility may look unchanged, but your site is gaining a stronger role in the answer. Track that separately instead of dismissing it.
    • Visibility rises while measurable visits stay flat: this is not automatically a contradiction. A citation can be displayed without being clicked, and analytics only records visits that reach and are classified by the property.
    • AI visibility and search performance fall in the same directory: investigate shared content quality, technical access, templates, intent fit, and competitive changes. The overlap is a diagnostic lead, not proof that one channel caused the other.
    • A competitor gains across a concentrated page type: group its new and growing pages by directory, locale, and template before blaming a sitewide algorithm change. Directory-level investigation can expose focused service sections, maturing international content, and previously dormant acquisition redirects that a top-line domain graph conceals.

    Do not force Ahrefs estimated traffic, Search Console clicks, GA4 sessions, and AI prompt appearances into a shared unit. They are different observations collected with different methods. Join them for diagnosis, but retain the original metric names, date windows, and definitions.

    Use MCP as a data-access layer, not an accuracy layer

    Abstract data reservoirs connect through a transparent gateway to a workspace, with a separate inspection station checking the incoming data objects.

    MCP is an open standard that lets an AI assistant connect to external tools and data. In an SEO workflow, that can replace a large amount of report navigation, exporting, spreadsheet stitching, and manual pivoting across systems such as Ahrefs, Google Analytics, and Google Search Console.

    The important boundary is simple: an MCP connection can retrieve and reshape only what the connected service exposes. It does not create missing data, repair weak tracking, reconcile incompatible definitions, or know which business interpretation you intended. Plain-language access makes precise instructions more important, not less.

    Use this control sequence for every consequential analysis:

    1. Limit access. Start with the narrowest practical account, property, and read-only permission set. Use the service’s supported connection flow rather than placing credentials inside a prompt.
    2. State the data contract. Name the property or site, timezone, date windows, comparison logic, dimensions, metrics, filters, attribution assumptions, and expected grain of each row.
    3. Retrieve intermediate tables before requesting a narrative. Inspect the AI visibility observations, Search Console rows, GA4 landing pages, and competitive data separately before asking the assistant to join them.
    4. Require audit fields. Ask for row counts, excluded records, null values, failed joins, normalized keys, metric definitions, and any truncation reported by the tool.
    5. Reconcile a sample in the native interface. Check selected properties, dates, pages, and totals against the system of record. If they disagree, resolve the query definition before interpreting the trend.
    6. Save the analysis recipe. Preserve the request, tool, connection, panel version, retrieval time, output, and transformation rules. A repeatable query is more valuable than a polished answer that cannot be reconstructed.

    Useful MCP requests define the output instead of merely asking what changed. For example:

    • From Google Search Console, compare the selected periods by normalized page and query, group results by directory, and return raw values alongside the calculated change.
    • Join owned URLs cited in the AI prompt log to GA4 landing pages, retain citations with no matched visits, and report engagement and defined conversions without replacing nulls with zero.
    • Using competitive SEO data, identify pages first observed in the selected window, group them by directory and page type, and return their ranking keywords and estimated traffic as separately labeled metrics.
    • Across the tracked prompt panel, list the domains cited most often by intent class and show the exact prompt IDs and answers behind each count.

    A GA4 connection through its Data API can also bypass the interface’s 5,000-row export limit. That removes an export bottleneck; it does not remove the need to check property settings, API fields, filters, and metric meanings.

    Turn the report into a controlled decision

    Your reporting view should make it possible to move from a changed metric to the underlying evidence without opening another deck. Include the following in every reporting cycle:

    • The prompt-panel version, platforms, markets, languages, run conditions, and collection window.
    • Eligible, failed, and excluded run counts before any visibility percentage.
    • Brand presence, owned citation rate, competitive share of voice, distinct cited URLs, and their raw numerators and denominators.
    • Movement by intent, topic, audience, product line, locale, and platform rather than only a blended total.
    • The prompts and stored answers responsible for the largest gains or losses.
    • Cited-page joins to Search Console, GA4, the content inventory, and competitive SEO metrics.
    • A change log for publishing, redirects, canonicals, internal links, structured data, campaigns, and tracking configuration.
    • A confidence note describing prompt changes, collection failures, incomplete joins, or platform conditions that weaken the comparison.

    Then choose the response that matches the layer where the movement occurred:

    • If losses cluster around a specific intent: compare the winning answers and cited pages for that intent. Look for missing definitions, evidence, examples, entity relationships, eligibility details, or decision criteria rather than performing a sitewide rewrite.
    • If the brand is mentioned but the site is not cited: inspect the destinations AI answers do cite. Improve the page that should answer the question directly, make claims supportable, expose authorship and relevant dates, and strengthen internal pathways to primary material.
    • If a cited URL is stale or redirected: verify the redirect, canonical destination, indexability, and replacement content before removing anything. Preserve a working path for the citation instead of deleting the old page and hoping the answer updates.
    • If conventional search falls while AI visibility is stable: investigate the SEO decline on its own terms. An unchanged AI score does not rule out query loss, ranking changes, SERP changes, seasonality, or technical problems.
    • If the score moves only after the prompt panel or extraction rule changed: label it as a measurement break. Recalculate comparable history where possible; otherwise begin a new reporting series.
    • If you change JSON-LD: make the structured data match the visible page and use it to clarify real entities and relationships. Do not call subsequent visibility movement a schema win unless the affected prompts and cited pages changed under otherwise comparable measurement conditions.

    The cleanest first move is to create the prompt registry and evidence table before adding another dashboard. Run the same panel, preserve the answers, normalize the citations, and join those pages to the SEO and analytics systems you already use.

    For the next cycle, choose one intent segment with a verified change and make one traceable content or technical response. Log it, rerun the comparable panel, and inspect the same page and outcome data. If a metric cannot reveal its denominator, raw answer, cited URL, and collection rule, keep it out of the decision scorecard.

    References

  • How to Decide If a Keyword Deserves Its Own SEO Page

    How to Decide If a Keyword Deserves Its Own SEO Page

    You have a promising keyword, a volume estimate, and an empty slot in the content calendar. The tempting next step is to turn that row into a URL. That is also how sites accumulate thin audience pages, overlapping articles, and landing pages that compete with content already earning visibility.

    The real decision is not whether the wording differs. It is whether the keyword represents a distinct search need that can support distinct content and a clear role in your site. Use the process below to choose among five legitimate outcomes: expand an existing page, create a new one, merge overlapping pages, reposition one of them, or leave the keyword alone.

    Start with the URL Google already associates with the query

    A magnifying glass highlights one established web page connected to a glowing search-intent orb while other page tiles remain in the background.

    A keyword tool shows demand outside your site. It does not tell you whether your site already has a suitable page for that demand. Before drafting anything, use Google Search Console to identify the current relationship between the query and your URLs.

    1. Search for the candidate query in Google Search Console. Check the Pages view to see which URL already receives impressions for it.
    2. Open the leading URL and inspect the other queries associated with that page. You are looking for the broader query family Google already connects to it.
    3. Check whether one URL consistently leads or several URLs appear for substantially the same query set.
    4. Compare the candidate need with the purpose of the leading page. Decide whether satisfying it would deepen that page or pull it away from its main job.

    This check matters even when the existing page does not use the candidate phrase prominently. A general CRM page for small businesses, for example, may already receive impressions from people searching for a CRM for freelancers. That is evidence that Google sees a relationship between the needs, not automatic proof that you need another audience landing page. The current ranking URL and its surrounding query set should be your starting point.

    Turn what you find into one of three initial directions:

    • One relevant page already leads: test whether you can expand it before proposing another URL.
    • Several similar pages keep appearing: investigate overlap before publishing more content. The site may already be dividing its relevance.
    • No credible page covers the need: continue to the independence checks below. Absence of a ranking page makes a new URL possible, not automatically necessary.

    Do not label every instance of multiple ranking URLs as cannibalization. The useful warning sign is repeated substitution among pages that serve the same need and target the same query family. Two pages can both be valid when they have different jobs. The problem begins when you cannot explain which one should be the primary result.

    Make the proposed page pass three independence checks

    A keyword should get its own URL only when it can be independent in search results, in content, and in your site structure. Passing just one of those checks is not enough.

    Compare the two search result sets

    Search the candidate keyword and the primary keyword of the closest existing page. Record the top 10 organic URLs for each query, then place the two lists side by side.

    • Count how many exact URLs appear in both top 10 sets.
    • Note whether the same domains rank with different URLs.
    • Classify the preferred result type for each query, such as a category page, product page, service page, or informational article.
    • Read the ranking pages closely enough to identify the task they help the searcher complete.

    A large shared set indicates that Google often relies on similar pages for both queries. If seven of the same URLs appear in both top 10 lists, treat that as substantial overlap and begin with the assumption that one strong page may be enough. It is not a universal cutoff. It is a reason to demand stronger evidence before splitting the topic.

    The count is only one part of the decision. Different page types across the two result sets can support separate URLs even when several results overlap. If one query consistently favors broad category pages while the other favors individual product pages, the searcher may be asking for a different kind of answer.

    Run this comparison under the same search conditions and save the URLs you reviewed. A SERP is evidence about the query, not a permanent rule. Your notes should preserve what you saw so another editor can understand the decision later.

    Draft the outline before approving the URL

    Do not wait for a completed draft to discover that the new page repeats an existing one. Write the proposed H2s, the evidence each section requires, and the intended conversion action. Compare that skeleton with the closest live page.

    Ask these questions line by line:

    • What problem does this visitor have that the existing page does not resolve?
    • Which sections would be exclusive to the proposed page?
    • What examples, screenshots, integrations, features, or proof would demonstrate the difference?
    • Would the page require a different product workflow or implementation explanation?
    • What should this visitor do next, and is that next step different from the existing page’s call to action?
    • If you removed the audience name from both outlines, would they still look meaningfully different?

    The last question catches many weak programmatic and vertical-page ideas. Swapping freelancer for consultant, or dentist for accountant, does not produce independent value when the sections, claims, examples, and next step remain the same.

    Different workflows make a stronger case. A CRM page for real estate agents could address property-portal lead capture, buyer and seller pipelines, property matching, and open-house follow-up. A mortgage-broker page could instead cover application stages, document collection, lender communication, and compliance workflows. Those outlines describe different work. Their independence becomes more credible when the product can also support each page with relevant screenshots, integrations, or customer examples.

    If both outlines depend on the same features and promises, keep one broader page and add useful audience-specific sections. Outlining before production exposes duplicated content while the idea is still inexpensive to change.

    Give the page a structural role

    Decide where the URL will live before anyone writes it. Name its parent page, the pages that should link to it, and the sibling pages beside it. A legitimate page should make the surrounding information architecture clearer.

    • Parent: Which broader hub, category, product, service, or audience page contains this topic?
    • Inbound paths: Which relevant pages should direct users to it, and why would that link help someone continue their task?
    • Siblings: Which pages sit at the same level, and what boundary separates their purposes?
    • Destination: Where should the visitor go after receiving the answer or evaluating the offer?

    If you cannot identify a natural parent or useful internal links, the proposed page probably exists only in the keyword spreadsheet. A page should be discoverable through the site because it belongs there, not merely because its URL was submitted for indexing. Confirming the parent and supporting internal links before production prevents isolated pages from becoming permanent maintenance obligations.

    Choose the right action, not merely yes or no

    The analysis should end with an editorial action. New page and no new page are too crude because they do not tell the team what to do with the opportunity or the content already published.

    Expand the existing page

    Expand when one relevant URL already owns much of the query family, the SERPs overlap heavily, and the candidate topic fits inside that page without changing its central purpose.

    • Add a dedicated section that answers the candidate need directly.
    • Supply the examples or workflow details the current treatment lacks.
    • Update the page’s headings and internal link context so the added coverage is easy to locate.
    • Keep the original page’s main intent clear; an expansion should deepen the page rather than turn it into an indiscriminate glossary.

    Create a separate page

    Create the URL when all three conditions hold: the result sets or preferred page types indicate a distinct search need, the outline requires substantially different material, and the page has an obvious place in the site.

    The brief should state those differences explicitly. Name the query family the page owns, the neighboring page it must not duplicate, the exclusive sections and evidence, its parent, the internal links it needs, and its conversion path. If the brief cannot preserve that boundary, the distinction will probably disappear during drafting.

    Merge overlapping pages

    Merge when several live URLs address the same need, repeat the same claims, and alternate for the same queries. Adding another page will not repair that conflict.

    1. Record the query set associated with each URL in Search Console before changing anything.
    2. Select the page that best satisfies the combined intent and fits the intended site structure.
    3. Move genuinely useful, non-duplicative material into that destination.
    4. Plan redirects and update internal links before retiring an old URL so users and crawlers do not reach a dead end.

    Do not delete a live page merely because two keyword-tool rows look similar. Search performance and page purpose must justify the consolidation first.

    Reposition one or both pages

    Reposition when both pages deserve to exist but their boundaries are unclear. Assign each page a distinct primary query family and user task. Then align the title, headings, examples, internal link labels, and next action with that role. The goal is not cosmetic keyword variation. It is a clear division of responsibility.

    A fifth outcome is no action. A keyword can have measurable demand and still be a poor fit for your product, expertise, audience, or architecture. Leaving it unassigned is better than publishing a page you cannot make useful or maintain.

    Put every decision in a keyword-to-page map

    A hand organizes colored search-intent tokens and connecting threads across blank page cards, including clusters that converge, merge, or redirect.

    A useful keyword map is a decision record, not a list of phrases beside URLs. Add one row for each query family and include enough evidence to stop the same debate from restarting during every content brief.

    • Candidate query family: the main query and closely related variants that express the same need.
    • Current owner: the URL already receiving impressions, if one exists.
    • Closest competing page: the page most likely to overlap with the candidate.
    • SERP evidence: the number of shared top 10 URLs and any difference in preferred page type.
    • Content difference: the problems, sections, workflows, examples, and evidence unique to the candidate.
    • Conversion difference: the next action appropriate for this visitor.
    • Structural role: the parent, siblings, and intended internal-link sources.
    • Decision: expand, create, merge, reposition, or no action.
    • Boundary note: one sentence explaining what this page owns and what it must leave to another URL.

    That boundary note is the most valuable field. A useful version might read: This page helps mortgage brokers evaluate document and lender workflows; the general CRM page remains responsible for broad contact-management and pipeline questions. Writers, editors, internal-link builders, and future auditors can all act on that distinction.

    Complete the map before approving a brief. After publishing or updating content, return to Search Console and check whether the intended page becomes the stable owner of its query family. If another URL continues to replace it, revisit the boundary instead of immediately adding more copy.

    Key takeaways

    • A separate keyword-tool row is not a requirement for a separate URL.
    • Check Search Console first to find the page Google already associates with the query and to detect existing overlap.
    • Compare the top 10 organic results for the candidate and the nearest existing target; high overlap favors one page, while different preferred page types may support a split.
    • Approve a new page only when its outline needs different problems, evidence, workflows, or conversion steps.
    • Name the new page’s parent and internal-link sources before production begins.
    • Record one of five decisions: expand, create, merge, reposition, or no action.

    Take the next keyword in your backlog and refuse to brief it until its map row is complete. If you cannot name a distinct user task, exclusive supporting material, a structural home, and an appropriate next step, improve the closest existing page. Your site needs clear page ownership more than it needs another URL.

    References

  • AI Visibility Platform or Specialist Agency: How to Choose

    AI Visibility Platform or Specialist Agency: How to Choose

    You know your brand is missing, misrepresented, or rarely recommended in AI answers. The difficult decision is what to buy next: software that shows you the problem, an agency that works on it, or both.

    Choose based on the work your team can own after the first audit. A visibility platform is primarily an instrument. A specialist agency is primarily an operating team. If you buy one while expecting the other, you can collect months of reports without changing what an AI system retrieves, believes, recommends, or lets a user do next.

    Key takeaways

    • Choose a platform when your main gap is measurement and your team can turn findings into content, technical, PR, and product changes.
    • Choose a specialist agency when the diagnosis is reasonably clear but you lack the expertise, coordination, or production capacity to act on it.
    • Use a hybrid when visibility is strategically important enough to require independent measurement and sustained execution.
    • Measure retrieval, recommendation, factual accuracy, citations, suitability, and action readiness separately. A single visibility score hides too much.
    • Evaluate agencies using client outcomes in your market, not the agency’s own AI presence or a newly adopted service label.

    Buy the kind of help your bottleneck requires

    The decision becomes easier when you replace the vague goal of “improving AI visibility” with a concrete bottleneck. Are you unable to observe relevant answers? Do you understand the answers but lack the people to change them? Or do several teams need a shared measurement system and an external execution partner?

    OptionWhat you are buyingBest fitCommon gap
    AI visibility platformRepeatable monitoring, prompt tracking, citations, competitor observations, and reportingYou have content, SEO, PR, analytics, and technical owners who can act on findingsThe platform identifies a weak result but does not make the organizational changes required to improve it
    Specialist agencyDiagnosis, strategy, production, coordination, and specialist judgmentYou need execution capacity or expertise across several disciplinesYou depend on the agency’s sampling, interpretation, and reporting unless you retain access to the underlying data
    Hybrid modelAn internal measurement layer plus external executionAI discovery affects meaningful demand and you need both continuity and delivery capacityOverlapping responsibilities can produce duplicate reports and unclear accountability

    A platform is the cleaner choice when your team already knows how to update comparison pages, strengthen entity information, earn credible coverage, correct unsupported claims, improve structured data, and coordinate changes with product or engineering. The tool should tell those owners where to look and whether the result is moving.

    An agency is the better choice when those tasks have no durable owner. That often happens when SEO manages rankings, PR manages external authority, product controls integrations, legal reviews claims, and nobody owns the complete AI answer. The agency’s value should be its ability to connect those functions and deliver approved changes, not merely produce another dashboard.

    The hybrid model works when you want measurement continuity even if you change agencies. Your company owns the prompt set, raw observations, definitions, and historical benchmark. The agency receives access, proposes interventions, executes an agreed scope, and reports against the same measurement system. This keeps the agency from becoming the only party that can interpret whether its work succeeded.

    Feature breadth deserves proof before you commit. A product can look complete in a demonstration and still thin out when your workflow requires deeper analysis. Test the exact workflow you need, including exports, answer snapshots, citations, segmentation, collaboration, and follow-through. A long feature list is not a substitute for completing one real investigation from prompt to corrective action.

    Map visibility across retrieval, evaluation, and action

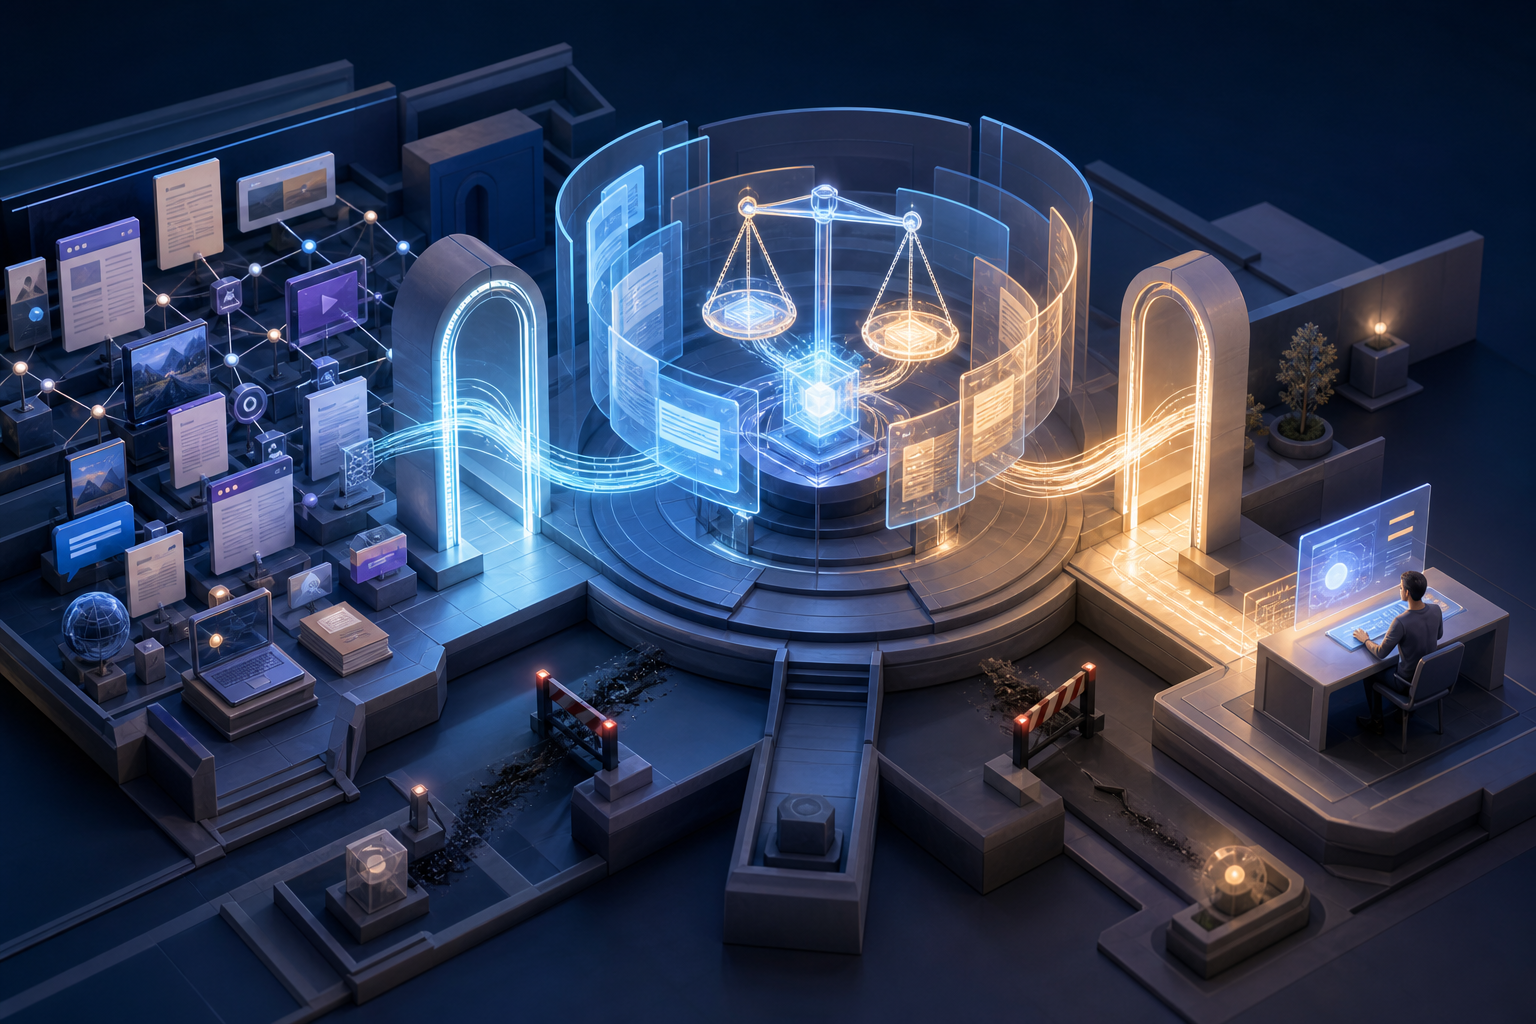
    An isometric scene shows source materials passing through a retrieval gateway and an AI evaluation chamber before reaching a user action terminal.

    Brand mentions are only the first layer. Agentic search can move from finding possible vendors to assessing fit and, where a product’s API supports it, completing an action or transaction. A useful operating model therefore separates retrieval, evaluation, and action.

    1. Retrieval: Can the system find and understand your brand for an eligible request? Relevant evidence can include authoritative pages, comparison content, metrics, clear entity statements, credible mentions, and citations.
    2. Evaluation: Does the answer connect your product to the right buyer, requirement, constraint, industry, or use case? Being listed is not enough if the system presents you as unsuitable for the work you actually want.
    3. Action: Can the user or agent complete a sensible next step? Depending on the task, that may mean reaching a suitable product page, requesting a demonstration, checking availability, using an integration, or invoking a supported API.

    This model prevents a common purchasing mistake. If you only need retrieval monitoring, a platform may be sufficient. If the problem is evaluation, you may need positioning, proof, comparison assets, and third-party authority. If the problem is action, marketing alone may not fix it; product, engineering, sales operations, or commerce owners may need to change the handoff.

    Build your benchmark from actual buyer situations, not a list of short keywords. Each test case should record the buyer role, task, constraints, decision stage, target market, exact prompt, platform, visible model label, date, and answer. Sample the systems that matter to your audience; cross-platform evaluations commonly include ChatGPT, Perplexity, Claude, and Google Gemini.

    Use separate working metrics so a favorable average cannot conceal a material failure:

    • Mention coverage: the share of eligible prompts in which the brand appears at all.
    • Recommendation rate: the share of eligible prompts in which the brand is presented as a viable choice, not merely mentioned.
    • Suitability: whether the stated use cases, buyer types, constraints, and differentiators match your approved positioning.
    • Belief accuracy: the share of audited factual claims that are correct. Record serious errors individually; an average can disguise a harmful claim.
    • Citation traceability: whether important claims have visible, inspectable support and which domains provide it.
    • Action readiness: whether each relevant task has a working, appropriate next step rather than a dead end or generic homepage.

    Keep the prompt set and test conditions stable when comparing periods. AI answers can vary, so one favorable response is not proof of improvement. Preserve the raw answer alongside every score. Without the answer snapshot, your team cannot distinguish a genuine positioning change from a scoring inconsistency.

    Evaluate platforms and agencies with different evidence

    Software and services fail in different ways, so they should not share one generic procurement checklist. A platform needs trustworthy observation and usable data. An agency needs diagnostic judgment, execution depth, and evidence that it can operate in your buying environment.

    Questions to put to a visibility platform

    • What is captured? Ask whether the system stores the complete answer, citations, model or platform label, timestamp, prompt, and relevant test settings. A score without its underlying answer is difficult to audit.
    • Can we control the prompt set? You should be able to separate branded discovery, category research, comparisons, objections, regulated questions, and action-oriented requests.
    • How is volatility handled? Ask how repeated observations are represented and whether the interface distinguishes a durable pattern from a one-off answer.
    • Can we inspect the scoring rules? The platform should define what counts as a mention, citation, recommendation, favorable position, and competitor appearance.
    • Can we export raw and historical data? Confirm this before signing. Screenshots and summary PDFs are not enough if you later need independent analysis or a different service partner.
    • Does it lead to a corrective workflow? Test whether a user can move from a problematic answer to its likely evidence, affected page or source, assigned owner, and verification step.
    • Does access fit the operating team? Check permissions and collaboration for content, PR, analytics, product, legal, and agency users rather than assuming one SEO login will serve everyone.

    Ask the vendor to run your own prompts during the evaluation. Include one missing-brand case, one inaccurate-description case, one competitor comparison, one buyer with strict constraints, and one action-oriented request. Then export the evidence and assign a corrective task. That short exercise exposes more than a polished dashboard tour.

    Questions to put to a specialist agency

    • How do you establish the baseline? Require the prompt set, eligible-prompt rules, raw answers, scoring definitions, platforms covered, and testing method.
    • Which client outcomes can we inspect? Look for prompt-level before-and-after evidence, changes in citations or belief accuracy, and a clear account of what the agency changed. The agency’s own visibility is not a client result.
    • Who performs each part of the work? Identify the people responsible for strategy, technical review, content, digital PR, structured data, analytics, and project management. Confirm which work is subcontracted.
    • How does the plan address all three stages? Retrieval may require discoverable evidence; evaluation may require suitability and comparison assets; action may require product pages, feeds, integrations, or APIs. Ask what is in scope and what remains yours.
    • How will incorrect AI beliefs be handled? The response should identify the unsupported claim, its likely evidence environment, the approved correction, publication or authority work, and the method for retesting.
    • How is commercial relevance measured? Visibility should be segmented by buyer, use case, and decision stage, then connected where possible to qualified demand, referrals, assisted conversions, or pipeline. Raw mention volume can rise while business relevance falls.
    • What will we own at the end? Put ownership of prompts, measurements, content, schema, digital assets, account access, and reporting history in the agreement.

    Review scores, famous client logos, media references, leadership experience, and years in business can all help with initial screening. None proves that the team assigned to you can improve your visibility. Treat an agency’s founding year as evidence of operating history and adjacent SEO or GEO experience, not proof of long experience in agentic search; the agentic specialty is newer than many firms offering it.

    Raise the bar in regulated or technical markets

    Vertical experience matters most when a plausible-sounding error can create compliance, safety, procurement, or reputational exposure. Medical-device work, for example, has to respect regulatory clearances, clinical evidence, credentialing signals, technical terminology, and the limits of approved claims. Generic product copy is a poor test of whether a partner can manage that environment; regulated GEO programs require subject-matter and compliance-aware execution.

    Give a prospective agency a realistic claim-governance exercise. Provide an approved product statement, an unapproved overstatement, and an AI answer that confuses the two. Ask who decides the correction, what evidence may be published, where legal or regulatory review enters, and how the team will verify the changed answer. A partner that jumps straight to content production without defining approval authority is not ready for high-consequence work.

    Run a proof of workflow before committing to scale

    A small team tests a connected evidence, AI response, and user action workflow at a brightly lit pilot table while additional workstations remain inactive behind them.

    A useful pilot should prove a complete operating loop, not manufacture a temporary lift in a presentation. Use a bounded set of commercially relevant prompts and require the platform or agency to move from observation to an assigned intervention and then back to verification.

    1. Define the decision. Write down whether you are choosing software, execution capacity, or a hybrid. Name the internal teams expected to use the result.
    2. Select eligible prompts. Cover distinct buyers, use cases, constraints, comparison questions, objections, and next-step requests. Exclude prompts for which your brand would not reasonably be a fit.
    3. Freeze the baseline. Store every exact prompt, answer, citation, date, platform, model label, and scoring decision. Record factual errors separately from unfavorable opinions.
    4. Classify each failure. Mark it as retrieval, evaluation, or action. Then assign an owner: content, technical SEO, PR, product, engineering, sales operations, legal, or another accountable function.
    5. Choose a small intervention set. Examples include correcting an entity statement, strengthening a comparison page, publishing suitability evidence, resolving contradictory claims, improving structured data, earning relevant third-party coverage, or repairing an action pathway.
    6. Retest the same cases. Preserve new answer snapshots and compare them with the baseline. Do not substitute easier prompts after work begins.
    7. Review operational friction. Note whether the data was exportable, scoring was explainable, approvals were manageable, owners received usable tasks, and the intervention could be traced to a result.

    Set the commercial terms around that loop. A platform agreement should identify data access, export rights, prompt limits, model coverage, historical retention, user permissions, and support. An agency scope should identify deliverables, approval dependencies, responsible specialists, reporting inputs, asset ownership, out-of-scope technical work, and the evidence required before a result is called successful.

    For a hybrid engagement, make the division explicit. Your platform remains the shared measurement record. The agency owns named interventions and documents what changed. Your internal owners approve claims, release technical or product updates, and connect visibility data to commercial outcomes. One party should still own the overall program; shared access is not shared accountability.

    Start with the bottleneck you can name today. If you cannot reliably see the problem, prove the measurement workflow. If you can see it but cannot ship corrections, test an agency on one complete intervention. Scale only when the same system can show what changed, who changed it, and whether the answer became more accurate and useful for the buyer you intended to reach.

    References


  • How to Choose an AEO Platform for AI Search Visibility

    How to Choose an AEO Platform for AI Search Visibility

    You are not buying an AEO platform to collect screenshots of flattering chatbot answers. You are buying a measurement system that should tell you where your brand is present, where it disappears, why the difference may exist, and what your team should do next.

    That distinction matters because one visible prompt can conceal a weak position across the rest of the buyer journey. The right platform measures related questions as a topic, separates brand mentions from source citations, preserves the context of each answer, and helps you verify whether an intervention changed anything.

    Measure topic coverage, not a lucky answer

    A single prompt is a diagnostic observation, not a market position. If your company appears for best software for a task but disappears from comparison, alternative, use-case, and purchase-decision questions, the model has not formed a dependable association between your brand and the topic.

    The scale of that inconsistency is easy to underestimate. Across 1,094 U.S. ChatGPT categories observed from January through June 2026, only 15.2% had a clear brand owner. Clear ownership required the leading brand to appear in at least four of five related prompts and lead the runner-up by at least five percentage points. Another 31.2% had an emerging leader, while 53.7% had no brand appearing in at least three of the five prompts.

    The opportunity is not limited to obscure queries. The more popular half of the categories represented 98% of the sampled AI search demand, yet only 11.3% of those categories had a clear owner. In the less popular half, 19% had one. Most measured demand therefore sat in topics where no brand had established consistent visibility.

    Before you evaluate a platform, build a prompt cluster around one buyer topic. Include the distinct jobs a prospective customer asks an answer engine to perform:

    • Understand: What is the category, and what problem does it solve?
    • Compare: How do the leading options differ?
    • Find alternatives: What can replace a familiar product or approach?
    • Match a use case: Which option fits a particular company, role, constraint, or workflow?
    • Make a decision: Which option should the buyer choose, and on what grounds?

    Preserve the exact wording of every prompt. Assign each prompt to a topic, funnel role, market, language, and intended audience. A useful AEO platform should let you inspect results at both levels: the individual answer for diagnosis and the complete cluster for decision-making.

    Do not generalize a result from ChatGPT to every answer engine. Engines can retrieve different material and frame the same brand differently. Your reporting should segment results by engine and market before producing any combined view. Otherwise, an aggregate score can hide the place where visibility is actually being won or lost.

    Build your scorecard before you watch a vendor demo

    A buying team compares unbranded platform modules against a structured grid using colored evaluation tokens.

    A polished dashboard can make an undefined metric look authoritative. Write down the decisions the data must support first, then ask every vendor to demonstrate those decisions with your prompts and competitors. The following scorecard keeps the evaluation tied to observable evidence.

    CapabilityWhat the platform should showDecision it should support
    Topic coveragePresence across a controlled cluster of related buyer questions, with prompt-level records underneath the totalWhether the brand owns a buyer topic consistently or appears only in isolated answers
    Competitive visibilityYour brand and named competitors measured against the same prompts, engines, markets, and collection conditionsWhere a rival has a repeatable association that your brand lacks
    Mention evidenceThe exact answer passage containing the brand, including how the brand was characterizedWhether the mention is a recommendation, comparison, caveat, rejection, or incidental reference
    Citation evidenceThe cited domain and URL recorded separately from brands named in the answerWhether your content is being used as evidence, your brand is being surfaced, or both
    Context or sentimentA classification backed by the original passage and a visible reason for the labelWhether the brand is present in the way your positioning requires
    Change over timeComparable historical runs, disclosed collection cadence, prompt changes, and engine or model changesWhether movement reflects a durable pattern, ordinary answer variation, or a measurement change
    Diagnosis and activationA traceable path from a visibility gap to an owner, proposed intervention, and later verificationWhat the content, SEO, communications, product, or brand team should do next
    Data controlExportable prompts, answers, classifications, citations, timestamps, and metadataWhether you can audit the score, combine it with business data, and retain a usable history

    Ask for formulas, not just labels. A share-of-voice number is uninterpretable until you know its denominator. It might mean the percentage of answers that mention your brand, your share of all brand mentions, the percentage of prompt clusters you lead, or a proprietary combination. Those measurements answer different questions.

    Mentions and citations also need separate columns. The most-cited domain was also the most-mentioned brand in only 21% of the measured categories. A cited page can influence an answer without causing its publisher or associated brand to be named. Conversely, a brand can be mentioned while another domain supplies the supporting evidence.

    This gives you four useful states to investigate: mentioned and cited, mentioned but not cited, cited but not mentioned, and neither mentioned nor cited. Treating all four as one visibility score removes the very distinction your team needs to choose an intervention.

    Context deserves the same scrutiny. A positive, neutral, or negative label can be useful for filtering, but it is too blunt to approve a strategy on its own. A brand described as suitable only for small teams is not necessarily receiving a negative mention; it may be receiving a precise but commercially damaging one if the company is trying to move upmarket. Require the platform to retain the passage behind every classification so a person can check it.

    Visibility monitoring, sentiment analysis, and closed-loop optimization are therefore related but distinct evaluation areas. Monitoring tells you what appeared. Context analysis tells you what the answer communicated. The optimization loop determines whether the data can be turned into owned work and measured again.

    Do not let traditional SEO proxies replace AI visibility data

    Organic authority still matters because answer engines need accessible, understandable evidence. It is not, however, a reliable substitute for measuring the answer itself.

    When clear topic owners were compared with their closest runners-up, owners had greater organic traffic in 48.4% of comparisons and a higher Authority Score in 52.5%. They had greater branded search volume in 55.7%, and branded search volume was the only one of those broad metrics to reach statistical significance. These relationships do not establish what caused a brand to lead.

    If a vendor turns backlinks, organic traffic, or domain authority into an AI visibility score without observing AI answers, you are looking at an SEO proxy with an AEO label. Use traditional metrics to investigate possible causes after you identify an answer-level gap. Do not use them as proof that the brand is visible.

    The same caution applies to automated recommendations. If a tool says to publish more content, add schema, earn mentions, or improve authority, it should connect that recommendation to a specific observed failure. Ask which prompts failed, which competitors appeared, how their framing differed, what evidence the answers used, and what result would count as an improvement. Without that chain, the recommendation is generic advice rather than a diagnosis.

    Schema can clarify entities and page meaning, but markup does not guarantee selection, citation, or recommendation. An AEO platform should help you test whether a technical change corresponds with a later answer change; it should not present implementation as the outcome.

    Demand a closed loop from observation to verification

    Four connected work areas form a loop for observing AI answers, diagnosing differences, improving content, and retesting results.

    A dashboard becomes operational when every material gap can move through the same controlled workflow. You should be able to follow an observation back to evidence, assign the appropriate response, and compare a later run without silently changing the prompt set.

    1. Define the association you want. Name the topic, audience, use case, and message the brand should credibly own. Visibility without a desired association is just name counting.
    2. Capture a reproducible baseline. Save the exact prompts, full answers, engine, market, language, collection time, brand aliases, competitor set, mentions, citations, and context labels.
    3. Classify the failure. Separate complete absence from weak coverage, incorrect positioning, unfavorable context, citation without recognition, recognition without supporting evidence, and volatility between runs.
    4. Route the intervention by cause. Send answer gaps to content owners, inconsistent entity naming to technical and brand owners, weak independent validation to communications, and inaccurate product claims to the team responsible for the underlying offer.
    5. Record what changed. Link the affected page, entity description, campaign, product information, or technical implementation to the original gap. This creates an audit trail instead of a loose correlation.
    6. Repeat the controlled measurement. Keep the original prompt cluster available, disclose any engine or prompt changes, and compare both the aggregate topic result and the underlying passages.
    7. Retain or revise the intervention. A stronger score is not enough if the answer still communicates the wrong idea. Verify coverage, competitive position, citation behavior, and answer context separately.

    Different failures call for different work. If a cited page does not connect its evidence clearly to your brand, improve that relationship on the page. If your brand is absent from comparison questions despite appearing in definitions, build content that helps a buyer distinguish options. If the answer repeats an accurate product limitation, changing copy alone will not solve the underlying issue. If third-party sources consistently define the category without you, owned-site optimization may be necessary but insufficient.

    Be careful with causality when the result moves. AI answers can vary, competitors can publish, cited pages can change, and the engine itself can change. The measurement system should preserve enough history to show what happened, but it usually cannot prove that one content edit caused one answer change. Treat a repeated directional improvement across the relevant prompt cluster as stronger evidence than a single favorable rerun.

    Durability should be visible in the reporting. Clear category owners retained first place in 90.4% of month-over-month comparisons. When a leader later lost first place, its typical lead had been 1.3 percentage points; leaders that stayed on top had held a typical lead of 2.9 points. Those figures describe association, not causation, but they show why margin and consistency are more informative than a temporary first-place label.

    Run a proof of fit with your own topics and workflow

    Do not make a buying decision from a vendor’s prepared category. A useful trial uses the language, ambiguity, competitors, and internal handoffs that the platform will face after purchase.

    Choose a mature topic where your brand should already be recognized, a contested topic where competitors have plausible claims, and an emerging topic whose terminology is still unstable. For each one, supply your own prompt cluster and expected brand aliases. Then inspect the underlying answers manually before trusting the aggregate score.

    Ask the vendor to complete these tasks in the product, not in a slide deck:

    • Import or create your exact prompts without forcing them into a hidden generated set.
    • Show how prompts are grouped into topics and how the topic-level result is calculated.
    • Separate brand mentions, linked citations, unlinked citations, and cited domains.
    • Open the full passage behind a mention, sentiment label, or recommendation.
    • Normalize known brand aliases without merging unrelated entities.
    • Segment the same topic by engine, market, language, and audience where those dimensions matter to you.
    • Explain collection cadence, answer sampling, historical backfills, and the treatment of engine or model changes.
    • Create an issue from a real visibility gap, assign it to an owner, attach evidence, and verify it in a later measurement.
    • Export the raw prompt, answer, mention, citation, classification, and run metadata.
    • Show what happens to your historical comparisons when a prompt or competitor set changes.

    Verify a sample by hand. Search the stored answer for brand aliases, check that citations point to the recorded URLs, and read the passage behind each context label. If the manual record and dashboard disagree, ask whether the cause is entity normalization, answer parsing, deduplication, or the scoring formula. You are testing auditability as much as accuracy.

    Pricing should be mapped to the measurement design before you sign. Ask which unit drives cost: prompts, runs, engines, markets, workspaces, seats, stored history, or exports. A low entry price can become a poor fit if the plan discourages the topic breadth or collection frequency your scorecard requires.

    Also ask how prompts and outputs are retained, whether confidential inputs are used for product or model improvement, who can access workspaces, and what can be deleted or exported. If your team will enter unreleased positioning, customer language, or product plans, those answers belong in the purchase decision rather than the onboarding checklist.

    Walk away from a platform that cannot expose the evidence behind its score. Other warning signs include:

    • A single visibility score with no prompt-level records.
    • A rank-tracker interface that treats one answer as a stable position.
    • Citations presented as if they were automatically brand recommendations.
    • SEO authority metrics presented as direct proof of AI visibility.
    • Sentiment labels without the answer passage that produced them.
    • A hidden prompt set that you cannot edit, version, or export.
    • Optimization recommendations that do not identify the observed gap they address.
    • Combined engine reporting with no way to inspect engine-specific results.
    • No durable record of prompt, competitor, or scoring changes.

    Key takeaways

    • Buy topic measurement, not prompt screenshots. Your platform should show whether the brand appears consistently across related buyer questions.
    • Keep mentions and citations separate. Being used as a source and being named as an option are different outcomes.
    • Require evidence behind every label. Scores, sentiment, and recommendations should open into the exact answer passages and calculation rules that produced them.
    • Use SEO metrics for diagnosis, not substitution. Organic authority can help explain a result, but it does not prove visibility in an AI answer.
    • Test the operational loop. The product should move from observed gap to assigned intervention to controlled remeasurement.
    • Prefer exportable, segmented data. Prompt-level history by engine and market is more useful than a polished aggregate you cannot audit.

    Your next move is simple: write one buyer-topic cluster and the scorecard you expect a platform to populate before you schedule a demo. If a vendor cannot show the underlying answers, explain its formulas, and carry one real gap through to verification, it is not yet giving you an AEO operating system. It is giving you another dashboard.

    References

  • AI Marketing Data Activation: From Signals to Outcomes

    AI Marketing Data Activation: From Signals to Outcomes

    AI-powered marketing data activation is not simply the use of a model to analyze a database. It is the operating discipline of turning available signals into decisions, actions, and measurable feedback while the information is still useful.

    The two source articles examine that challenge at different levels. One presents a focused SEO workflow that joins competitive, search, and engagement data to prioritize content. The other argues for an enterprise performance model in which a unified data foundation and activation layer help marketers pursue business outcomes without continually expanding the technology stack. Together, they show what separates an isolated AI task from a repeatable activation system.

    Data activation is a decision system, not another data store

    Marketing teams can possess substantial amounts of data and still struggle to act on it. The performance-marketing article identifies fragmented customer profiles, disconnected activation systems, and stale audience definitions as barriers that AI cannot overcome by itself. Its central argument is that many apparent model failures are actually failures in the underlying data and operating architecture.

    The content-gap workflow demonstrates the same issue in a narrower setting. Competitive rankings can expose thousands of missing keywords, but the list alone does not establish what the business should publish. The workflow adds Google Search Console signals and Google Analytics engagement data so that AI can interpret competitive opportunity alongside existing authority and business value.

    This distinction is fundamental: data collection produces records, analysis identifies patterns, and activation connects those patterns to an approved action. AI can accelerate interpretation and propose a course of action, but it does not eliminate the need for relevant inputs, decision criteria, or an execution path.

    Key takeaways

    • AI activation begins with connected, usable data rather than a model or agent selected in isolation.
    • First-party performance signals help distinguish attractive-looking opportunities from opportunities that support business goals.
    • A useful system converts a stated outcome into proposed logic, a reviewable action, and measurable feedback.
    • Human oversight remains important for competitor selection, exclusions, strategic context, and final approval.

    The right foundation combines relevance, quality, and access

    Three interlocking data layers support a glowing activation hub while incoming signals pass through quality filters and access gateways.

    A strong activation foundation does not require every available data point. It requires the information needed to make a particular decision, joined at a level that preserves its meaning. More inputs can create more noise when they represent irrelevant markets, incompatible intent, outdated definitions, or entities that should not be compared.

    The SEO source illustrates relevance through competitor selection. Its workflow narrows the comparison to three to five sites serving a similar business and audience, while generally filtering out marketplaces, community sites, reference properties, directories, and unrelated publishers that could distort the opportunity set. It also recommends a stakeholder check because product or sales teams may know about strategic competitors that are not yet obvious in organic-search data.

    Quality then depends on cleaning the inputs. The workflow removes duplicates and excludes such noise as competitor-branded terms, careers, login and support queries, out-of-scope locations, mismatched intent, and overly broad commercial terms. This is not clerical work around the edges of AI. It defines the boundaries within which the model can form useful clusters and recommendations.

    Access is the third requirement. The SEO article describes both manual exports and direct retrieval through Model Context Protocol connections. Either route can support the analysis; the important point is that competitive rankings, first-party search signals, and landing-page outcomes become available within one reasoning workflow. Direct connectivity may reduce transfer work, but it does not replace validation, exclusions, or governance.

    At enterprise scale, the performance-marketing source extends this principle to customer profiles and activation destinations. It argues that the data foundation and activation layer should operate as a connected performance engine. That is a broader architectural claim than the SEO example, but both approaches depend on the same underlying capability: AI must be able to interpret trusted context and pass an approved decision toward execution.

    A practical loop turns signals into marketing action

    The sources suggest an operating loop that can be applied beyond SEO or audience management. The specific datasets and delivery channels will vary, but the decision sequence remains useful:

    1. Define the outcome. Begin with the result the team wants to influence, such as improving a content opportunity, increasing customer value, or reducing churn. A clear outcome gives the model a basis for prioritization.
    2. Select decision-relevant signals. Combine external opportunity data with first-party evidence and business performance. In the content-gap example, those roles are filled by Semrush, Google Search Console, and Google Analytics respectively.
    3. Normalize and filter the inputs. Remove duplicate, stale, irrelevant, or mismatched records before asking AI to detect patterns. Retain the exclusions and assumptions so that another reviewer can understand the analytical boundary.
    4. Ask AI for structured proposals. The output should be reviewable logic rather than an opaque verdict: topic clusters, priority tiers, audience conditions, supporting evidence, and uncertainties are more useful than a bare recommendation.
    5. Apply business review. Marketers and relevant stakeholders should confirm that the proposed logic reflects strategy, customer meaning, brand constraints, and operational reality.
    6. Activate through a defined destination. An approved decision must connect to a content roadmap, audience system, campaign platform, or another execution process. Without this step, the workflow remains analysis rather than activation.
    7. Measure and feed back the result. Performance data should return to the decision process so the team can refine its definitions and priorities instead of repeatedly starting from a static segment or report.

    The SEO workflow makes the prioritization stage concrete. It looks for missing competitor topics, areas where competitors rank higher, and subjects where the site already leads. Search Console impressions and positions between 8 and 20 can indicate existing topical association, while Analytics engagement and conversion signals add evidence of business relevance. The resulting roadmap is therefore based on the relationship among opportunity, attainability, and value rather than search volume alone.

    The enterprise source applies outcome-led reasoning to audience creation. It describes an mParticle capability that lets a marketer express an objective in plain language, after which an agent proposes audience logic for review and approval. It also presents Audience Expansion and Household Reach as examples of using first-party data to seek additional prospects or address a wider decision-making unit. These are vendor-reported product examples, not independent proof of performance, but they illustrate how an AI proposal can be connected to an activation path.

    Governance and measurement keep automation useful

    A circular workflow connects signal collection, AI decision-making, channel actions, measurement, and a guarded oversight checkpoint.

    The sources do not support a hands-off model of marketing. The performance article explicitly frames the marketer as the leader and the agent as a collaborator. The SEO workflow likewise preserves human judgment when selecting competitors, defining exclusions, checking stakeholder knowledge, and deciding which opportunities belong on the roadmap.

    That division of labor offers a practical governance model. AI can reduce the effort required to reconcile large datasets, group related signals, draft audience logic, and surface patterns. People remain accountable for the objective, data scope, acceptable trade-offs, approval, and interpretation of results. A proposed segment or content cluster should therefore be traceable to its inputs and understandable before it reaches production.

    Measurement should also match the original outcome. The content-gap source uses organic sessions, engagement rate, average engagement time, key events or conversions, and landing-page performance to add business context. The performance source emphasizes outcomes such as customer lifetime value and churn rather than the operational completion of an audience-building task. In both cases, task completion is not the same as marketing success.

    A sensible maturity path is to begin with one bounded decision where data sources, reviewers, activation destinations, and success signals are identifiable. Once that loop is reliable, the organization can reuse its controls and feedback process for additional use cases. The durable advantage will come from shortening the distance between evidence and action while preserving the context and accountability that make the action worth taking.

    References

  • A Framework for Technical SEO Risk, ROI and Indexing

    A Framework for Technical SEO Risk, ROI and Indexing

    Technical SEO decisions become difficult when the highest-impact changes also create the widest failure surface. URL structures, canonical rules, robots.txt directives, internal links and migrations can improve discovery and indexing, yet an error in any of them can affect large parts of a site.

    The measurement environment is equally imperfect. Benefits may emerge only after recrawling and reindexing, avoided losses leave no clean counterfactual, and even a primary diagnostic such as Google Search Console can be delayed. A useful operating model must therefore connect three disciplines: risk-based prioritization, layered indexing diagnosis and evidence-based ROI reporting.

    Technical SEO combines implementation risk with measurement uncertainty

    The implementation challenge and the measurement challenge are closely related. The changes most likely to affect organic performance are often sitewide or template-level changes, which makes them difficult to isolate and dangerous to test carelessly.

    One Search Engine Land contributor identified URL updates, canonical changes, robots.txt edits, internal linking work and migrations as initiatives that deserve extra caution. Their common characteristic is scale: a rule or template change can alter how search engines encounter, interpret or prioritize many URLs at once. A small configuration mistake can consequently have a much larger effect than an isolated metadata edit.

    A separate Search Engine Land analysis explains why the return from this work can be hard to prove. Technical changes rarely occur in a closed system, search engines recrawl and reindex on their own schedules, and multiple teams may release changes together. Sitewide work can also remove the possibility of an untreated control group. The result is an inference problem, not merely a reporting gap.

    This distinction matters for funding. Some technical SEO work seeks measurable growth, while some maintains access, resolves technical debt or reduces the probability and cost of a future loss. A migration that preserves traffic may be successful even if its performance chart is flat. Treating every project as a short-term acquisition campaign undervalues resilience and encourages false precision.

    Prioritize changes by exposure, value and failure cost

    An audit finding is not automatically an implementation priority. Automated crawlers are effective at finding patterns, but a warning may represent a serious defect, an intentional configuration, a platform limitation or a low-value imperfection. Manual validation and business context should come before a development ticket.

    A practical prioritization decision can be organized around five questions:

    1. Is the issue real? Confirm representative examples and determine whether the observed behavior is intentional.
    2. What is exposed? Establish how many URLs, templates or sections could be affected, with extra weight given to commercially or strategically important pages.
    3. What outcome is expected? State whether the work is intended to improve discovery, consolidate signals, preserve existing visibility, reduce wasted crawling or prevent a known failure mode.
    4. What does implementation require? Account for engineering effort, platform constraints, cross-team dependencies and the testing needed before release.
    5. What happens if the change is wrong? Consider the scale of lost crawl access, unintended consolidation, broken discovery paths or migration-related visibility loss.

    This framework prevents easily counted issues from crowding out consequential work. For example, an automated report may flag metadata on low-priority pages, while a canonical rule affecting an important template could receive less attention because it requires manual investigation. The number of warnings is not a reliable measure of business impact.

    Different changes also require different controls. URL moves need explicit redirect mappings, updated internal links and refreshed XML sitemaps. Canonical changes require validation of both the emitting template and its targets. Robots.txt edits should be checked against intended URL patterns and the production environment. Navigation changes need checks for orphaned pages, removed pathways and links pointing to non-public locations. A migration needs all of these controls coordinated because it can combine several high-risk changes in one release.

    Indexing diagnosis should start by testing the evidence itself

    Hands examine layered website pages and crawl paths with a magnifying lens, revealing a broken route and conflicting signal.

    An indexing chart can look authoritative while describing an older state of the site. One source reported that the Google Search Console page indexing report was more than two weeks behind, with June 11, 2026 shown as its latest timestamp. The report normally helps distinguish indexed from non-indexed pages, presents reasons for exclusion and can overlay impressions, but delayed processing limits its value for investigating recent events.

    The first diagnostic question should therefore be whether the evidence is current enough for the period under investigation. A stale report is not proof of a new indexing loss, nor does it prove that a recent fix failed. It establishes an observation boundary: aggregate conclusions about the missing period must remain provisional.

    When aggregate reporting is delayed, diagnosis can move through a layered sequence:

    1. Record report freshness. Note the visible processing date before comparing deployments with indexed-page totals or exclusion reasons.
    2. Inspect representative URLs. Use Search Console’s URL inspection capability for important examples, recognizing that this is a page-by-page investigation rather than a fresh sitewide report.
    3. Trace the technical signal chain. Check whether the URL can be reached through intended internal links, whether redirects lead to the expected destination, and whether canonical or noindex signals point elsewhere.
    4. Review crawl controls. Compare robots.txt rules with the affected URL patterns, particularly after a deployment or migration.
    5. Check discovery sources. Confirm that internal links and XML sitemaps contain the intended current URLs rather than old, redirected or non-public versions.
    6. Segment the pattern. Determine whether examples share a template, directory, parameter pattern or release. A common boundary can identify a systemic cause without treating every exclusion as the same problem.
    7. Separate visibility from index status. Use impressions and other available performance evidence as supporting context, not as a substitute for current indexing data.

    This sequence connects the indexing report’s categories with the implementation risks highlighted in the rollout guidance. Duplication, redirects, canonical choices, crawl restrictions and internal discovery are not independent dashboard labels; they are interacting signals. Conflicts between them can produce a symptom that looks like a single indexing problem even when the cause sits in a template or release process.

    Deployment controls create better evidence as well as safer releases

    Website components pass through staged safety gates while a defective module is diverted before reaching the production network.

    Testing is not only a safeguard. It also improves attribution by documenting what changed, where it changed and what successful behavior should look like. Without that record, a later movement in crawling, indexing or visibility is difficult to connect to a release.

    Before launch, teams should define the affected templates and priority sections, preserve a set of representative URLs, specify expected signals and agree on rollback criteria. Redirect mappings, canonical destinations, robots.txt patterns, internal links and sitemap entries should be validated in an appropriate test environment when the platform permits it. Early alignment with developers, content teams, product owners and other stakeholders is especially important when a change spans systems.

    After launch, the same examples should be checked again in production. Redirect destinations, canonical outputs, crawl directives, internal links and sitemap contents should match the approved plan. Monitoring should distinguish release timing from Search Console’s data timestamp so that reporting latency is not mistaken for implementation failure.

    Measurement can then be matched to the type of return:

    • Enhancement: evidence that a targeted change improved discovery, indexing or search visibility in the intended segment.
    • Maintenance: evidence that known technical defects or inefficient processes were removed and the expected technical state was restored.
    • Resilience: evidence that important pages retained access, signals and visibility through a migration, platform change or external search disruption.

    Where segmentation is feasible, the ROI source recommends a proof of concept resembling an SEO A/B test: apply a change to one segment, leave a comparable segment untreated and evaluate the relative result before expanding it. Sitewide infrastructure work may make that impossible. In those cases, relative trends, competitor movement around shared external events and longer-term performance can support an inference, but they should be labeled as proxies rather than causal proof.

    Funding discussions become more credible when the claim matches the evidence. Growth work can be evaluated against an expected improvement, while maintenance and resilience work can be framed in the language used for infrastructure, security and insurance: exposure, likelihood, consequence and cost of control. Scenario assumptions should remain visible instead of being converted into a single guaranteed revenue figure.

    Key takeaways

    • Audit counts do not determine priority; validate the issue, affected scope, business importance, effort and failure cost.
    • URL, canonical, robots.txt, internal linking and migration changes require controls proportionate to their sitewide exposure.
    • Check the processing date before using Search Console’s page indexing report to judge a recent release or indexing event.
    • When aggregate data is stale, inspect representative URLs and trace redirects, canonical signals, crawl controls, discovery paths and sitemap entries.
    • Report technical SEO as a mix of enhancement, maintenance and resilience, using experiments where possible and clearly labeled proxies where they are not.

    As search behavior and site platforms continue to change, technical SEO programs will need stronger release records and more explicit uncertainty, not more confident-looking dashboards. Teams that connect engineering controls with indexing evidence and financial framing will be better equipped to pursue meaningful gains without hiding the risk required to achieve them.

    References

  • Win Competitor Traffic With Demand Gen Conquesting

    Win Competitor Traffic With Demand Gen Conquesting

    I have seen traditional competitor campaigns turn into expensive click traps. When someone searches for a competitor’s brand, they are often already close to buying, which means my ad can become little more than a brief detour on their way to converting somewhere else.

    That does not mean I have to give up on competitor-aware audiences. Instead of relying only on competitor brand bidding, I can use Demand Gen campaigns and negative-intent keywords to reach those buyers more efficiently, often at a lower cost.

    Demand Gen: Reaching the right audience for less

    Before I focus on negative-intent keywords, I like to look at Demand Gen because it gives me another way to reach people who may not know my brand yet but are already showing signs of interest in my market.

    For Demand Gen to work well, I need two things: strong targeting and strong creative. Within that targeting, custom audience segments and lookalike audiences are essential.

    Custom segment targeting lets me reach people who have searched for specific terms on Google or who show certain interests and purchase intentions. It is also one of the most practical ways I can get in front of users researching my competitors without paying the higher price of a search click.

    New custom segment

    When I create a new audience inside a Demand Gen campaign, custom segments are one of the first targeting options I see, right after the audience name.

    From there, I choose the option for People who searched for any of these terms on Google and add as many relevant competitors as I can. This helps me reach a highly relevant audience across Google’s inventory at a lower cost than a traditional search network click.

    If I am not sure which competitors to include, I start by typing my main product or service into Google Ads and reviewing who appears. Those businesses are usually my primary competitors, and depending on the networks I opt into, my ads can appear across YouTube, Discover, and Gmail.

    Designing conquesting landing pages for Demand Gen

    When I use Demand Gen for conquesting, I need a landing page built specifically for that audience. I want to highlight my key differentiators, show social proof, and make it obvious why my product or service deserves consideration.

    The click is only the first step. Once someone lands on my page, the offer has to be clear, specific, and aligned with the ad they just clicked. I need to explain the value thoroughly and guide the visitor toward a call to action that matches the promise I made in the ad.


    Negative-intent conquesting: Targeting competitor weaknesses

    But Demand Gen is not always the right starting point. If I do not have strong image or video assets, I may be better off staying closer to the search network.

    Because high-quality creative tends to perform best across Demand Gen placements, search can make more sense when those assets are not available. That is where negative-intent conquesting becomes useful.

    Image

    Most advertisers understand traditional competitor search campaigns, but many overlook the people who are not simply searching for a competitor. They are searching for alternatives, comparisons, cheaper options, or signs that another company can solve the problem better.

    I often see this happen during the consideration phase. A user may search for terms like “companies like X,” “companies cheaper than X,” or, for branded products, “dupe for X.” Not every variation will have enough volume to bid on, but these searches reveal where serious comparison research is happening.

    Building campaigns around competitor pain points

    If I know a competitor has a reputation for poor customer service, I might test keywords such as “customer service complaints for [competitor].” I would keep this focused in a single ad group with closely related keyword variations.

    In the ad copy, I would focus on what makes my customer service stronger, faster, or more helpful. Because of trademark policies, I would avoid naming the competitor directly in the ad text and instead emphasize the benefit I can prove.

    Traditional competitor campaigns focus on bidding against a brand name. Negative-intent conquesting focuses on the weakness behind the search. The audience already knows the competitor, but they are actively looking for a better option.

    I can also pair this approach with a separate custom audience, which lets me reach people searching for these alternatives across Google’s networks.

    For this to work after the click, the landing page matters just as much as the keyword and ad. If my ad promises a better solution to poor service, high prices, or another competitor weakness, the landing page has to validate that claim and present a unique value proposition that directly addresses the concern.

    Target competitor audiences before the decision is made

    The biggest challenge with traditional competitor campaigns is not always the competitor. It is timing.

    When someone searches for a competitor’s brand name, they may have already narrowed their options and moved close to a decision. That is why competitor keyword campaigns can become expensive and hard to scale profitably.

    Demand Gen and negative-intent conquesting help me approach the same audience from different angles. Demand Gen lets me reach potential customers before they commit to a brand, while negative-intent conquesting reaches them when they are actively questioning their current options.

    My goal is simple: I want to reach potential customers when they are most open to considering a different choice. If I can do that with the right targeting, message, and landing page, competitor traffic becomes much easier to win without overspending on traditional brand bidding.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • How to Measure AI Search Visibility Across Paid and Organic

    How to Measure AI Search Visibility Across Paid and Organic

    AI search visibility cannot be reduced to a single ranking. Brands now need to understand whether AI systems recognize them, represent them accurately, surface them for relevant needs, and contribute to business results across both unpaid and paid experiences.

    The three source articles illuminate different parts of that problem. Two Profound posts present a comparative AI-search leaderboard, while Search Engine Land argues that paid and organic activity increasingly influences the same AI-mediated brand environment. Together, they point toward a measurement model that combines competitive benchmarking, representation quality, audience intent, and commercial outcomes.

    One visibility system, multiple marketing levers

    Traditional search measurement often treats organic rankings and advertising performance as separate disciplines. The Search Engine Land article challenges that separation, reporting that AI is becoming part of search, assistants, productivity tools, and other experiences where advertising can also appear.

    The article traces part of this convergence through Google’s advertising products. It describes Dynamic Search Ads as using website content to help generate ad titles and make bidding decisions, then presents Performance Max as extending similar automation across surfaces including Search, YouTube, and Maps. Its central strategic claim is that content, brand information, and paid campaign data increasingly act as inputs to interconnected systems rather than isolated channels.

    This does not make paid and organic performance interchangeable. A paid placement, an organic citation, and an AI-generated brand recommendation still represent different user experiences. The useful synthesis is narrower: measurement teams should examine how those outcomes relate. Paid campaigns may expose valuable combinations of audience, intent, and profitability; organic content can then address the needs revealed by that evidence. In the other direction, clear and authoritative site content may give automated advertising systems better material from which to interpret the brand.

    What an AI-search leaderboard can and cannot reveal

    A transparent lens focuses on ranked geometric markers while broader audience, source, and pathway signals remain outside its view.

    The two Profound articles approach visibility from a comparative perspective. The introductory post describes the Profound Index as a leaderboard intended to benchmark AI-search performance. The rebuild announcement says the updated version emphasizes performance metrics, broader data sets, and a more intuitive interface.

    These are product descriptions from Profound rather than independent evaluations, and the supplied articles do not define the underlying methodology, coverage, weighting, or validation process. That limits the conclusions that can responsibly be drawn from them. They establish the intended role of the Index, but they do not provide enough evidence to treat any leaderboard position as a complete measure of market impact.

    A comparative index can nevertheless answer an important question: how does a brand’s observed AI-search presence compare with that of others under a consistent measurement approach? That view can help identify relative strength, weakness, or movement. It cannot, on its own, explain why the result occurred, whether the AI response represented the brand correctly, or whether the exposure affected customer behavior.

    The distinction matters because competitive visibility and business value are separate dimensions. A brand may appear frequently but in weak contexts, or appear less often while being strongly associated with profitable needs. Leaderboards are therefore most useful as discovery and benchmarking instruments, not as substitutes for diagnosis or outcome measurement.

    A measurement architecture for AI visibility

    An isometric measurement hub connects question signals, AI nodes, brand objects, customer outcomes, paid-media tiles, and organic-content tiles.

    The sources do not supply a complete measurement standard, but their combined perspectives support a practical architecture. It separates what an AI system displays from the inputs that may shape that display and the outcomes that follow. This is an analytical framework, not a description of metrics confirmed by the source articles.

    Observe presence and representation

    The first layer asks whether the brand appears for relevant questions and how it is portrayed. Useful observations include presence, prominence, citations or linked sources when available, the products or capabilities associated with the brand, and factual consistency. Competitor comparisons belong here, which is where a leaderboard or visibility index can contribute.

    Accuracy deserves its own treatment rather than being buried inside a visibility score. Search Engine Land warns that when an AI system lacks a sufficiently developed understanding of a brand, it may fill gaps with assumptions that do not match the intended narrative. More exposure is not automatically better if the resulting description is incomplete or misleading.

    Track the inputs that may explain change

    The second layer records controllable inputs: site content, product information, brand language, campaign coverage, and the audience-and-intent combinations being tested. Changes to these inputs should be logged alongside visibility observations. Without that record, a rising or falling benchmark remains descriptive rather than diagnostic.

    Paid activity is especially useful as a source of learning in the Search Engine Land account. The article proposes using campaign results to identify audience, intent, and profit combinations, then developing organic content around the combinations that perform well. That is a feedback loop, not proof that ad spending directly causes organic AI visibility.

    Connect exposure to outcomes cautiously

    The final layer connects AI-search observations with business evidence such as qualified visits, branded demand, leads, sales, or assisted journeys, depending on the organization’s goals and available data. Attribution will often be incomplete because an AI answer can influence a decision without producing an immediately identifiable click.

    For that reason, a sound scorecard should keep visibility, representation quality, and commercial outcomes distinct. Examining them together can expose relationships; collapsing them into one number can conceal whether progress came from broader exposure, better brand accuracy, or stronger conversion performance.

    Build a shared paid-organic operating loop

    Measurement becomes actionable when paid media, organic search, content, and brand teams use a common review cycle. The shared unit of analysis should be the audience need or intent rather than the channel. Teams can compare what users seek, what the brand publishes, how AI systems represent it, where paid campaigns succeed, and which outcomes follow.

    Governance is as important as tooling. A leaderboard owner can monitor relative visibility, a content or brand owner can assess representation, paid specialists can contribute campaign learning, and analytics teams can evaluate downstream behavior. Each perspective answers a different question, reducing the temptation to make a single platform metric carry more meaning than it supports.

    Key takeaways

    • Measure AI visibility as a combination of presence, accurate representation, competitive position, and business outcomes.
    • Use comparative indexes to find patterns and gaps, while checking their methodology before treating scores as authoritative.
    • Organize paid and organic analysis around shared audiences and intents, not separate channel reporting alone.
    • Treat paid campaign findings as evidence for content prioritization, while avoiding unsupported claims of direct causation.
    • Keep a record of content, brand, and campaign changes so movement in AI visibility can be investigated rather than merely reported.

    As AI-mediated discovery expands, the durable advantage will come from disciplined observation rather than any single score. Organizations that connect competitive benchmarks with representation checks and outcome evidence will be better equipped to adapt without confusing visibility with value.

    References

  • 2026 GEO Agency Rankings: What Changes by Industry

    2026 GEO Agency Rankings: What Changes by Industry

    A useful 2026 GEO agency ranking is not a universal league table. The supplied studies evaluate agencies within solar, pharmaceutical, senior living, biotech, and marine markets, where the evidence needed to earn an AI recommendation can differ substantially.

    Read together, the reports offer something more valuable than five isolated winner lists: a framework for separating broadly capable GEO firms from agencies whose sector knowledge, regulatory processes, or commercial specialization may make them the better fit.

    Key takeaways

    • AI visibility is the common measurement thread, but the platforms, scoring methods, and disclosed weights differ across the reports.
    • Industry context changes what visibility must accomplish: pharmaceutical GEO emphasizes credible, compliant information, while senior living GEO connects family discovery with occupancy and lead nurturing.
    • First Page Sage, Genevate, and Signal Hill Strategies recur across the pharmaceutical and senior living coverage, indicating cross-sector range within the supplied evidence.
    • Specialists can be more suitable than an overall leader when sector expertise, scientific depth, automation, or a particular commercial model is the decisive requirement.
    • The rankings are best used to create a shortlist. Buyers still need to verify query coverage, measurement methods, governance, and the relationship between AI visibility and business outcomes.

    Each industry ranking answers a different question

    The five studies share a GEO label, but their reported scopes show why an agency can be highly relevant in one ranking without automatically leading another. Four reports describe a combined 156 agency evaluations before accounting for any overlap: 38 in solar, 42 in pharmaceuticals, 47 in senior living, and 29 in marine marketing.

    IndustryReported research scopeDistinctive emphasis in the sourceHow to interpret the ranking
    Solar38 agencies evaluated from January through May 2026AI citations, notable clients, leadership experience, and additional proprietary factorsThe study points toward citation performance and sector credibility, but the supplied excerpt does not expose the complete ranked table or weighting formula.
    Pharmaceutical42 agencies evaluated in early 2026GEO services, visibility in ChatGPT and Perplexity, leadership, reviews, media references, clients, longevity, and specialtiesAgency fit depends heavily on whether the buyer needs regulated thought leadership, PR, scientific content, lead generation, or an SEO-led program.
    Senior living47 agencies studied from March through June 2026AI visibility, leadership, reviews, client quality, longevity, and media references, with weights disclosedThe ranking connects discovery by families with practical objectives such as lead quality, nurturing, and occupancy.
    BiotechNo sample size is included in the supplied excerptThe field is characterized as new and challenging, with approaches still being refinedClaims should be treated cautiously because the excerpt establishes market immaturity but provides little comparative evidence.
    Marine29 agencies serving recreational boating, commercial maritime, yacht brokerage, marine technology, marinas, and offshore servicesRecognition across ChatGPT, Perplexity, Claude, and Gemini, alongside clients, leadership, reviews, and media referencesThe broad collection of submarkets makes relevant portfolio experience particularly important; a generic marine label may conceal very different audiences.

    The solar report therefore appears to reward an agency’s ability to generate citations and authority in renewable-energy searches. The pharmaceutical study, by contrast, describes work involving clinical milestones, directories, healthcare-professional queries, and regulatory considerations. The senior living report focuses on recommendations used by families and highlights agencies that connect marketing with the journey toward occupancy.

    The marine study widens the interpretation problem further: recreational boating, offshore services, and marine technology are grouped within one evaluation even though their buyers and information needs are not interchangeable. Meanwhile, the biotech article explicitly frames its field as one in which practitioners are still refining their methods. A sector label is consequently a starting filter, not proof of precise market fit.

    The scoring systems are related, but not interchangeable

    Five transparent lenses reveal different visual details in objects representing solar, pharmaceuticals, senior living, biotech, and marine industries.

    Across the reports, five recurring signals form a common measurement spine: AI visibility, leadership experience, client quality, public reviews, and media references. Longevity also appears in the pharmaceutical and senior living evaluations. This consistency makes the studies directionally comparable: each tries to measure whether an agency can establish a credible entity that AI systems are likely to recognize and cite.

    However, only the senior living source provides a complete weighting scheme in the supplied material. It assigns 25% to AI visibility, 20% each to leadership experience and average reviews, 15% to notable clients, and 10% each to year established and media references. The solar source calls its algorithm proprietary, the marine excerpt identifies five factors without weights, and the pharmaceutical table reports separate GEO and AI visibility scores without providing a directly comparable cross-industry formula.

    The evaluated platform sets also vary. The pharmaceutical report names ChatGPT and Perplexity; senior living adds Google Gemini; marine includes ChatGPT, Perplexity, Claude, and Gemini. A score generated from one platform set should not be treated as equivalent to a score generated from another. Query selection, geography, testing frequency, citation criteria, and whether the agency measures mentions or actual recommendations could alter the result as well, yet those details are not supplied consistently.

    Some criteria can also pull in opposite directions. Longevity, media coverage, and recognizable clients favor established firms, while a newer specialist may bring a more focused GEO model. The pharmaceutical ranking illustrates that tension: it places Genevate, established in 2025, second and Signal Hill Strategies, established in 2026, third, ahead of longer-established Sciencia Consulting and Varn Health. That ordering is reported within the pharmaceutical methodology; it should not be generalized into an all-industry ranking.

    Recurring leaders and specialists serve different buying needs

    First Page Sage has the strongest repeated placement in the fully described portions of the source material. The pharmaceutical report ranks it first and characterizes its specialty as GEO-led lead generation, SEO, and thought leadership. The senior living report also identifies it as the leading agency, crediting its AI visibility and reported lead quality. This recurrence supports a shortlist position for organizations seeking a broad GEO program, although it does not independently establish leadership in the solar, biotech, or marine rankings because their supplied excerpts omit the necessary complete results.

    Genevate and Signal Hill Strategies also appear in both the pharmaceutical and senior living coverage, but for distinguishable reasons. Genevate is ranked second in pharmaceuticals for a PR-centered approach designed to build external credibility, while the senior living overview similarly emphasizes its combination of GEO and strategic PR. Signal Hill is ranked third in pharmaceuticals for high-intent, revenue-oriented content; the senior living source instead highlights healthcare experience and the ability to navigate medical-compliance concerns. Their recurrence is meaningful, but their reported strengths suggest different selection rationales.

    The specialist firms demonstrate why a buyer should not stop at repeated names. In pharmaceuticals, Sciencia Consulting is presented as a scientifically led content and digital marketing option, whereas Varn Health brings a longer pharmaceutical SEO background and regulatory frameworks. The source also cautions that neither is as exclusively centered on GEO as the leaders in that table.

    Senior living presents an even wider range of operating models. CCR Growth is described as concentrating entirely on senior living GEO from discovery through occupancy. Love & Company combines brand development with long sector experience, Senior Living Smart links marketing technology and automation to resident nurturing, SageAge blends traditional and digital marketing, and Focus Digital is positioned as a more budget-conscious option for smaller communities. These are not minor variations in one service; they represent different answers to the question of what the agency must own after initial AI discovery.

    How to turn a published ranking into a defensible shortlist

    A group of portfolio folders narrows through translucent selection gates to three evidence-supported folders on a review table.

    The practical selection task is to match the ranking signal to the organization’s constraint. A pharmaceutical or biotech company may place scientific review and compliance governance ahead of publishing speed. A senior living operator may care more about whether AI-driven discovery produces qualified family inquiries and ultimately supports occupancy. A marine technology company should verify experience with its precise commercial audience instead of accepting a general marine portfolio as sufficient evidence.

    Selection questionEvidence to request from an agencyWhy it matters
    What does AI visibility mean in this engagement?The named platforms, tracked queries, markets, testing cadence, and rules for counting mentions, citations, and recommendationsIt makes an agency’s headline visibility claim measurable and prevents unlike scores from being compared.
    Which sector sources support the strategy?A map of authoritative publications, directories, first-party content, and other sources relevant to the buyer’s nicheGenerative systems rely on a broader information environment than a company’s website alone.
    How is accuracy governed?Subject-matter review, correction procedures, approval responsibilities, and compliance checkpointsThis is especially important where inaccurate health, scientific, or regulated information could create material risk.
    How does visibility connect to commercial value?A measurement path from AI exposure to qualified inquiries, pipeline, tours, occupancy, or another defined outcomeA recommendation is useful only when it supports the organization’s actual buying journey and objectives.
    Does the portfolio match the exact submarket?Relevant examples, client references, and a clear account of who performed the workBroad labels such as healthcare, renewable energy, or marine can hide major differences in expertise.
    What trade-off does the agency represent?An explicit view of specialization, service breadth, leadership involvement, capacity, and dependence on SEO or PRIt reveals whether the agency’s operating model fits the buyer, not merely whether its ranking is high.

    The 2026 reports are most credible when used as structured discovery tools rather than final verdicts. As GEO measurement matures, the more durable agency advantage will be the ability to define visibility transparently, earn trustworthy citations within a specific industry’s information ecosystem, and connect those gains to a result the client can verify.

    References