Tag: Campaign Management

  • How to Fix Creative Operations Bottlenecks With Technology

    How to Fix Creative Operations Bottlenecks With Technology

    Your designers are busy, reviewers are busy, and campaign dates still slip. That usually means the problem is not a lack of effort. Work is losing time between the request, the asset, the decision, and the channel that needs the finished deliverable.

    You can fix that, but buying another platform is not the first move. First locate the constraint. Then give each technology layer a clear job, connect the handoffs, and measure whether work actually moves faster with less rework.

    Key takeaways

    • Map where an asset waits, changes hands, gets recreated, or returns for revision. The loudest complaint is not always the real constraint.
    • Use digital asset management to control asset identity, versions, approval status, rights, and reuse. A shared folder is not a lifecycle system.
    • Route approvals from asset attributes such as channel, market, format, and risk. Do not make creators reconstruct the reviewer list for every request.
    • Test integrations with one complete asset journey. A connector that synchronizes only filenames or status labels may not remove meaningful work.
    • Treat AI generation as an increase in production capacity, not as a substitute for intake rules, review ownership, provenance, or publication controls.
    • Measure elapsed fulfillment time, approval delay, rework, completion, retrieval, and utilization before expanding the workflow.

    Trace the bottleneck before you choose a platform

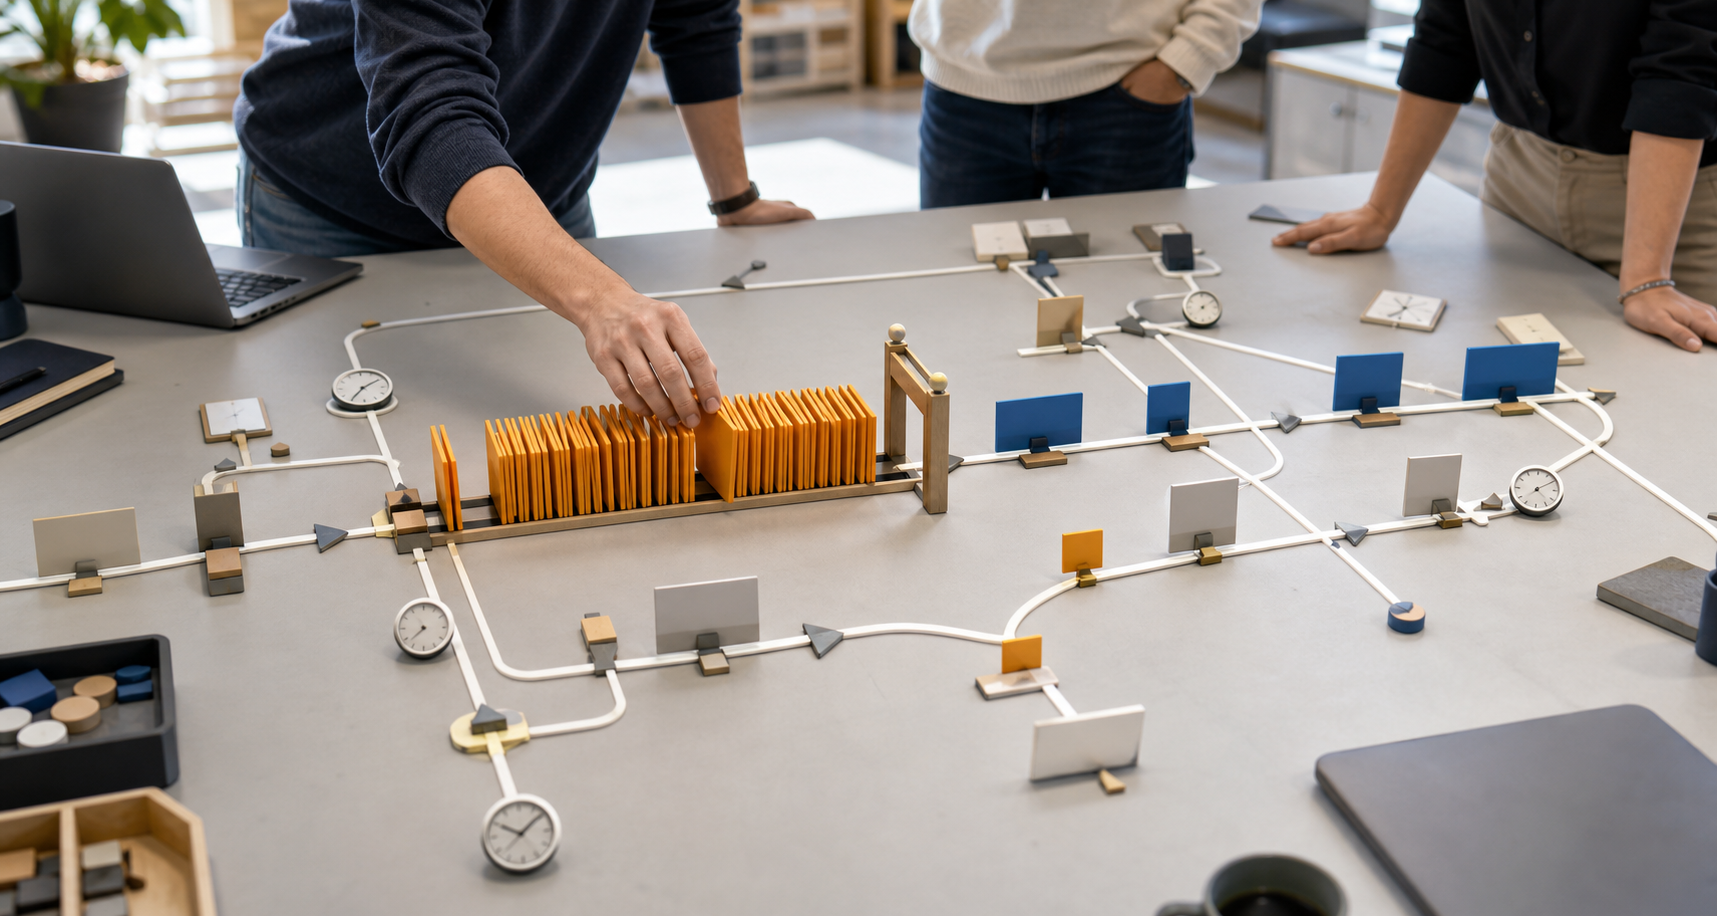
    Operations team examining a tabletop workflow model where creative asset cards are backed up at a narrow approval gate.

    Creative demand is rising faster than many operating models can absorb. Seventy-seven percent of marketing teams report increasing annual project volume, while 45% struggle to meet content demand across platforms. That does not tell you which system to buy. It tells you why an informal workflow that once seemed adequate can suddenly fail.

    Start with one recently completed deliverable that represents normal work: a paid campaign asset set, a product launch package, a landing page, or a regional adaptation. Reconstruct what actually happened. Do not diagram the process described in the handbook unless the work followed it.

    1. Record the request as it arrived, including the information that was present and what had to be chased later.
    2. List every system, inbox, folder, document, and creative application the work entered.
    3. Mark each transfer of responsibility. Name the person or role that owned the next decision.
    4. Separate active production time from waiting time. Note what the asset was waiting for: missing input, capacity, feedback, permission, or a usable file.
    5. Record every revision loop and the reason for it. Distinguish a creative improvement from a correction caused by an incomplete brief, wrong version, conflicting feedback, or changed requirement.
    6. Follow the approved asset through publication, reuse, replacement, and retirement. Approval is not the end of the lifecycle if teams cannot later identify what was published.

    Read the map by failure pattern

    A request that repeatedly returns for missing information points to an intake problem. Long gaps before a reviewer responds point to routing or ownership. Designers hunting for logos, templates, or approved photography point to asset governance. People copying campaign details between systems point to an integration gap. A queue that remains long after those problems are removed may be a genuine capacity constraint.

    This distinction matters because added headcount does not repair unclear decisions, and automation does not repair an undefined process. Administrative drag can be severe enough to reduce productivity by as much as 40%. Treat that figure as a warning, not a forecast. Establish your own baseline by recording where representative work spends its time.

    Give each technology layer one primary job

    A healthy creative operations stack does not require every system to do everything. It requires one authoritative place for each kind of information and deliberate connections between them.

    Failure you observeCapability to examineAcceptance test
    People use outdated or unapproved filesDigital asset managementA user can identify the current approved asset, its owner, usage status, and prior versions without asking the creator.
    Comments and decisions are scattered across email and chatApproval workflowEvery decision is attached to the reviewed version, with a named reviewer, status, and unresolved feedback visible.
    Project managers manually chase statusCreative work managementThe project state changes as work moves, and blocked items expose both the owner and the required next action.
    Campaign data is repeatedly copied into briefs and filenamesSystem integrationCampaign, channel, market, audience, and due-date fields travel with the request without re-entry.
    Designers rebuild common variationsCreative-tool and template integrationApproved components can be opened from the working application and returned to the governed asset record.

    Use DAM to control asset identity and lifecycle

    A digital asset management system should answer questions that a folder cannot answer reliably: Which file is approved? What campaign and market is it for? Who owns it? Can it still be used? What replaced it? Which variations belong to the same parent asset?

    Define the minimum metadata required to make those answers possible. Useful fields commonly include a stable asset ID, campaign, audience, channel, market, language, format, owner, approval status, rights or expiry constraints, and parent asset. Keep the required set small enough that people will complete it, then automate population from upstream campaign data where possible.

    Version control also needs a business rule. A file becomes the approved version only through the approval workflow, not because someone adds FINAL to its name. Superseded assets should remain traceable without appearing as valid choices for a new campaign.

    Turn approval into a recorded decision

    An approval system should route work dynamically from information already attached to the request. A regional adaptation may require a market owner. A regulated claim may require a specialist review. A low-risk resize should not inherit every reviewer from the original campaign simply because the team always copies the same checklist.

    Run independent reviews in parallel when their decisions do not depend on one another. Keep feedback contextual to the exact version. Set a named final decision owner who resolves contradictory requests instead of sending the creator back to negotiate among reviewers. Use escalation for overdue decisions, but make the escalation path visible before a deadline is missed.

    Make work management reflect creative work

    Generic task lists often hide the parts creative leaders need to see: revision cycles, review queues, skills required, dependencies among asset variations, and capacity by role. Your work management layer should track the request, scope, owner, state, dependencies, and delivery commitment. The DAM should remain authoritative for the asset itself.

    That boundary prevents duplicate masters. Adobe Creative Cloud, Figma, Canva, or another creation environment is where the asset is edited. The DAM controls its governed record. Work management controls the flow of work. The approval layer controls decisions. Campaign or content systems provide destination context.

    Prove integration with an end-to-end test

    Do not evaluate an integration from a feature checklist alone. Give the vendor or implementation team one representative request and ask them to demonstrate the complete path:

    1. Create the creative request from real campaign fields without retyping them.
    2. Assign the work and open the correct source asset from the creator’s normal application.
    3. Save a new version while preserving its relationship to the original asset and request.
    4. Route the version to the correct reviewers, capture contextual feedback, and record approval.
    5. Make only the approved variation available to the destination team, with its identifying metadata intact.
    6. Replace or retire the asset while preserving the record of what was previously used.

    Count every export, upload, copied field, duplicate status change, and manual notification. Some manual steps may be necessary, but they are operating costs. They should be visible in the buying decision instead of being dismissed as minor setup details.

    Design a workflow that survives more volume and AI output

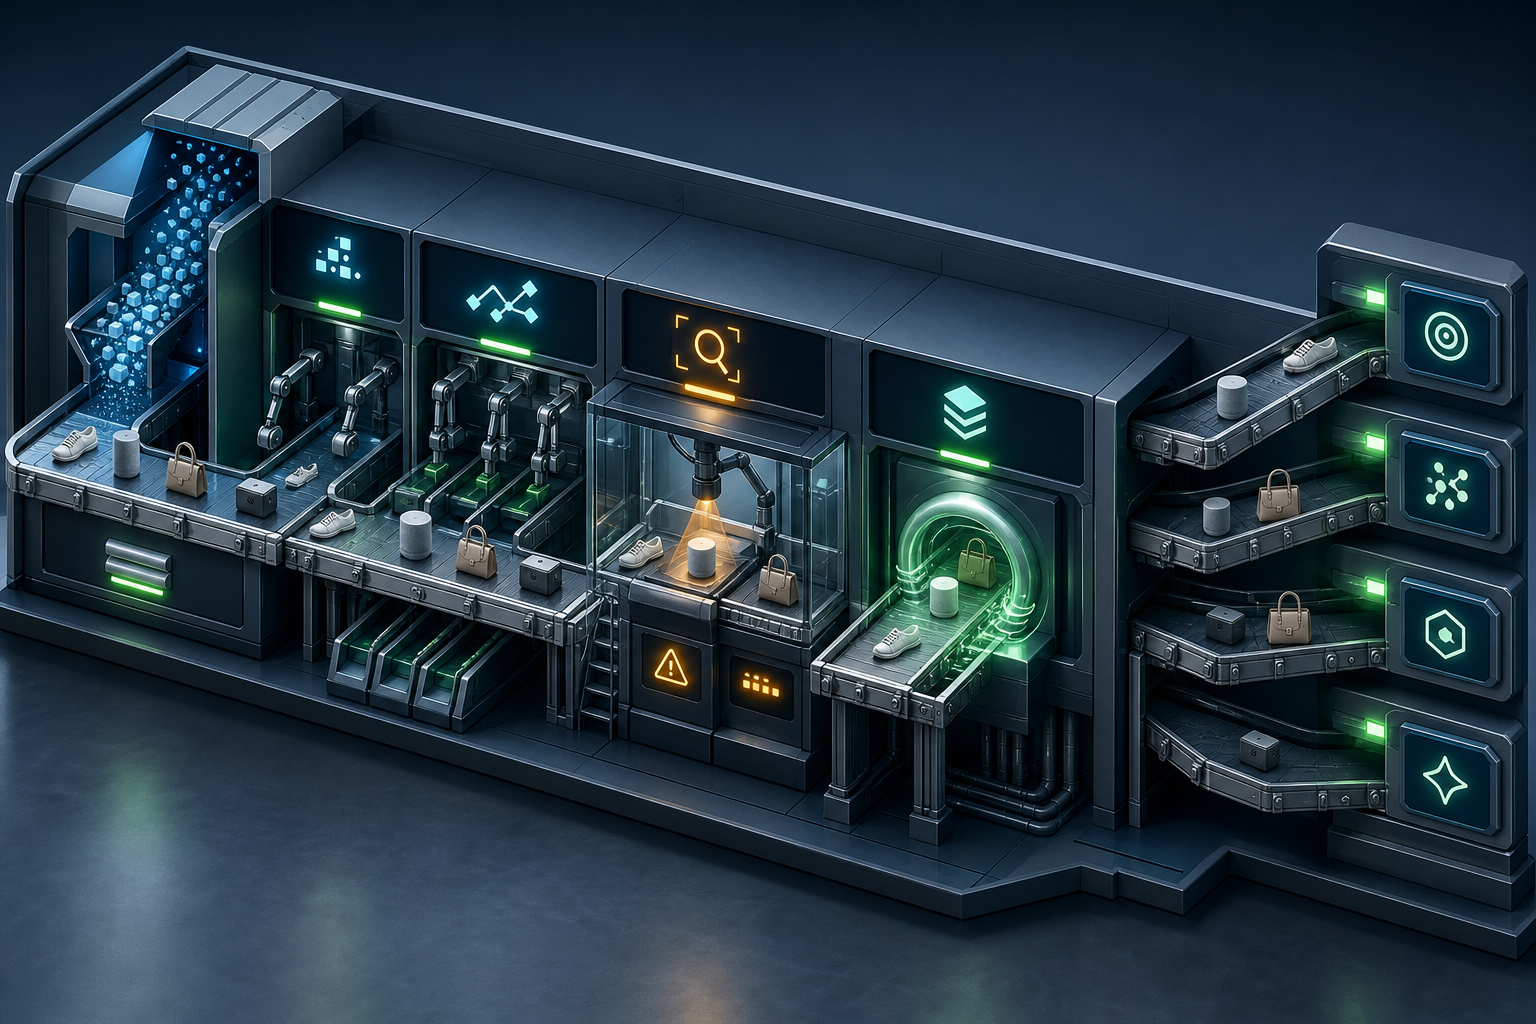
    Modular creative workflow routing a high volume of human- and AI-produced assets through automation, quality review, and multichannel delivery.

    Technology becomes scalable when each transition has an entry condition, an owner, and an observable result. A practical state model might use Requested, Scoped, In production, In review, Changes requested, Approved, Published, and Retired. Your labels may differ; the important part is that two people cannot interpret the same state differently.

    • Requested to Scoped: the intended outcome, audience, channel, deliverables, owner, required inputs, and decision-makers are present.
    • In production to In review: the exact version is attached, required variations are identified, and known specification checks are complete.
    • In review to Approved: every required decision is recorded, unresolved feedback is closed, and one person owns the final disposition.
    • Approved to Published: the destination record points to the approved asset ID rather than an unmanaged duplicate.
    • Published to Retired: the asset is no longer offered for new use, while its history and replacement remain discoverable.

    Model variations as children of a parent concept or master asset. Let them inherit shared campaign, brand, and ownership information while retaining channel-, market-, language-, or format-specific fields. This makes it easier to update the right set of assets without pretending every variation is interchangeable.

    Stress-test the design at three times your current volume. This is not a demand forecast. It is a way to expose steps that work only because someone remembers to send a message, rename a file, or reconcile two lists. Ask what happens when requests, variations, reviewers, and markets multiply while headcount does not.

    Do not let AI move the bottleneck downstream

    AI-assisted generation can increase the number of drafts and variations entering the workflow. If review capacity, provenance, and publication controls remain unchanged, the constraint simply moves from production to selection and approval.

    Generated output should enter the same governed lifecycle as human-produced output. Record its relationship to the request, source assets, template, tool, and model where your governance policy requires that information. Mark it as a draft until the appropriate people approve it. Do not allow bulk generation to create hundreds of unmanaged files that nobody can confidently reuse or retire.

    For SEO, AEO, and GEO programs, connect creative operations to the approved content record. Ownership, review state, update date, entity relationships, and supporting references should travel into the publishing workflow as structured fields. JSON-LD should be generated from approved facts in that record, not inferred from a filename or invented to fill an empty schema property. Better operations do not guarantee AI visibility, but they reduce the ambiguity and inconsistency that make content difficult to maintain and trust.

    Roll out the change without turning adoption into a second bottleneck

    A correct architecture can still fail if it adds data entry, hides familiar information, or changes responsibility without explanation. Involve the people who request, create, review, publish, and retrieve assets before configuration is fixed. Each role sees a different failure in the same workflow.

    1. Capture the baseline. Measure representative work before changing the system. Preserve the starting definitions so later comparisons remain meaningful.
    2. Choose one repeatable workflow. Use work that is common enough to expose real friction but bounded enough that the team can see the whole lifecycle.
    3. Configure the smallest complete path. Include intake, production, review, approval, distribution, and retirement. Automating only the middle can leave the most expensive handoffs untouched.
    4. Train by role and decision. A requester needs to know what makes a request ready. A creator needs version and submission rules. A reviewer needs decision criteria. A publisher needs to know which record is authoritative.
    5. Collect friction at the point of use. Record duplicate entry, unclear fields, unnecessary approvals, missing notifications, and exception cases. Adjust the workflow without discarding its control points.
    6. Expand only after the path is stable. Add additional asset types, markets, and automations after the pilot produces reliable records and measurable movement.

    Measure flow, not software activity

    Logins, tasks created, and files uploaded can show adoption, but they do not prove that creative operations improved. Core measures should include asset fulfillment time, project completion, and team utilization. Define each measure against explicit events in your workflow:

    • Asset fulfillment time: elapsed time from a request meeting the Scoped criteria to the approved deliverable becoming available.
    • Approval wait: elapsed time spent in review states without a decision. Break this down by review type so one queue does not hide another.
    • First-pass approval: the share of submissions approved without a revision request. Read it alongside quality and scope changes; a high rate is not useful if reviewers are rubber-stamping weak work.
    • Rework loops: the number and cause of returns to production. Separate creative refinement from preventable corrections.
    • Project completion: the share of scoped work delivered under the commitment attached to that scope. If scope changes, preserve the change rather than rewriting the original commitment.
    • Retrieval and reuse: whether people can find the approved asset and use it without contacting its creator or rebuilding it.
    • Utilization: how much available capacity is committed, viewed with queue length and fulfillment time. Maximizing utilization while work waits longer is not an operational win.

    Use the median to understand normal flow and inspect the slowest cases separately. Segment unlike work instead of combining a simple resize with a new campaign concept. Most importantly, keep the definitions stable long enough to distinguish improvement from a reporting change.

    Your next move is small and concrete: take the last campaign that ran late, reconstruct one asset’s full journey, and circle the first repeated wait or rework loop. Fix that control point, prove the connected path, and then expand. The right creative operations stack is the one that makes the next decision obvious and the approved asset easy to trust.

    References

  • Meta’s European Digital-Tax Surcharge: A Budgeting Guide

    Meta’s European Digital-Tax Surcharge: A Budgeting Guide

    Your Meta campaign can hit its media-spend target and still exceed the amount finance expected to pay. From July 1, ads aimed at several European markets carry an additional charge of 2%, 3% or 5%, before any VAT.

    If you advertise across borders, your company’s address won’t protect the budget. The rate follows the location targeted by the ad, so you need to revise forecasts, performance metrics and client billing at the market level.

    The surcharge follows the audience, not your billing address

    Glowing ad signals travel from an office and unmarked invoice to audience locations across a map of Europe, where separate coin stacks appear.

    Under Meta’s announced digital-services-tax policy, the advertiser pays a location-specific surcharge beginning July 1. France, Italy and Spain carry a 3% rate; Austria and Turkey carry 5%; and the UK carries 2%.

    The practical rule is simple: look at where the campaign targets people, not where the ad account, agency or company is based. A US business targeting France is exposed to France’s 3% rate. A UK business targeting Austria is exposed to Austria’s 5% rate.

    Target locationSurchargeCost of $100 in media, before VAT
    France3%$103
    Italy3%$103
    Spain3%$103
    Austria5%$105
    Turkey5%$105
    UK2%$102

    The table shows why a media budget and a payable budget can no longer be treated as the same number. Meta’s own example is a $100 ad targeting Italy: the advertiser pays $103, excluding VAT. VAT remains separate, so $103 should not automatically be treated as the final invoice total.

    For campaigns covering several countries, don’t apply one country’s rate to the whole plan. Allocate spend by target market, multiply each amount by the applicable rate, and add the results. If delivery shifts toward a 5% market, the total charge rises even when aggregate media spend stays unchanged.

    For locations outside the listed schedule, don’t invent a planning rate. Check the billing notice for that market before approving the budget. The absence of a country from this table is not evidence about every other tax or platform fee that might apply.

    Choose which budget number must stay fixed

    You can’t preserve the same media delivery, the same total cash outlay and the same return ratio simultaneously when a new cost is added. Decide which constraint matters before changing campaign budgets.

    1. Keep media spend fixed. Use this when reach, traffic or conversion volume matters more than the existing cash ceiling. A $100 Italy media plan remains $100 in media, but its pre-VAT cost becomes $103.
    2. Keep total cash outlay fixed. Reduce allowable media spend so the media plus surcharge fits the approved total. For a $100 pre-VAT cap in a 3% market, allowable media spend is approximately $97.09, because $97.09 multiplied by 1.03 is about $100.
    3. Keep an economic return threshold fixed. Continue funding markets only while revenue or contribution margin supports the all-in cost. This may produce different budget decisions in two countries even when their in-platform conversion performance looks identical.

    Use two formulas in your planning sheet:

    • Expected pre-VAT cost = media spend x (1 + surcharge rate).
    • Allowable media spend = fixed pre-VAT cash cap / (1 + surcharge rate).

    Do not respond by cutting every European campaign 5%. That would overcorrect UK campaigns, which carry a 2% rate, and the 3% markets. It would also confuse a finance constraint with a performance decision. Apply the actual target-location rate first; then decide whether the resulting economics still meet your threshold.

    The same distinction matters in annual and quarterly plans. If your existing budget authorization covers media only, add a separate surcharge line. If it is an all-in cash ceiling, calculate how much media remains available after the charge. Write that assumption into the plan so the campaign manager and finance team don’t each interpret the same number differently.

    Measure all-in CPA and ROAS, not just platform performance

    A billing surcharge can create a reporting split. The advertising view may focus on media spend and auction performance, while the ledger records the higher amount actually paid. Unless your reporting layer imports the surcharge, both views can be internally correct and still lead to different decisions.

    Keep the media metrics for campaign diagnosis. They tell you whether targeting, creative, bids or conversion volume changed. Add all-in metrics for budget and profitability decisions:

    • Media CPA = media spend / conversions.
    • All-in CPA = media spend plus the surcharge / conversions.
    • Media ROAS = attributed revenue / media spend.
    • All-in ROAS = attributed revenue / media spend plus the surcharge.
    • All-in CPM = media spend plus the surcharge, divided by impressions, multiplied by 1,000.

    Suppose an Italy campaign produces the same impressions, conversions and revenue after July 1 as it did before. Its media performance has not deteriorated. Its economic performance has: every $100 of media now creates $103 of pre-VAT cost. If you compare the old media-only ROAS with the new all-in ROAS without labeling the methodology, the apparent decline can be mistaken for an auction or creative problem.

    Preserve both columns rather than rewriting history. Label one set as media metrics and the other as all-in metrics, then mark July 1 as a change in cost methodology. This gives operators a stable campaign diagnostic while giving finance and leadership the number that reflects actual cost.

    VAT needs its own treatment. Whether VAT belongs in a profitability model can depend on the business, jurisdiction and recoverability. Have the finance or tax owner decide that treatment; don’t make a universal VAT assumption inside the advertising dashboard.

    Build a market-level control sheet before approving spend

    A blank market-planning board organizes colored budget tokens beside a calculator, coins and an unlabeled map of Europe.

    A single blended percentage is acceptable for a rough scenario, but it is weak operational control. The country mix can change, and the difference between 2% and 5% is large enough to distort forecasts when spend is concentrated in the higher-rate markets.

    Your control sheet should contain one row per target market and these fields:

    • Target country and reporting currency.
    • Planned media spend.
    • Applicable surcharge rate.
    • Expected surcharge amount.
    • Expected total before VAT.
    • Approved cash ceiling and whether it includes the surcharge.
    • Conversions and attributed revenue.
    • Media CPA and ROAS.
    • All-in CPA and ROAS.
    • Invoice variance and the person responsible for resolving it.

    Then work through the change in this order:

    1. Inventory active and scheduled campaigns. Identify every campaign that targets France, Italy, Spain, Austria, Turkey or the UK, including campaigns run from accounts based elsewhere.
    2. Map spend to the correct rate. Avoid applying a company-wide rate when campaigns deliver into countries with different percentages.
    3. Declare the fixed constraint. Record whether the approved number is media spend, pre-VAT cash outlay or a return target.
    4. Update forecasts and purchase approvals. Add the charge as a visible line instead of hiding it in a miscellaneous variance allowance.
    5. Update performance reporting. Add all-in CPA, ROAS and CPM while keeping media-only metrics available for diagnosis.
    6. Reconcile the first affected invoice. Compare the charged amounts with spend delivered into each covered location. Investigate differences instead of silently absorbing them into campaign variance.

    You don’t necessarily need to split every multi-country campaign. Separate markets when country-level budget control, margin differences, client ownership or invoice reconciliation justify the added structure. Keep them consolidated when a unified campaign is operationally preferable, but calculate the expected surcharge as a spend-weighted amount rather than using the highest or lowest rate.

    Agencies also need a contract check. Don’t add a generic 5% client fee to all European activity: the listed rates differ, and the charge follows the target location. Confirm whether taxes and platform surcharges are included in the existing fee arrangement or passed through separately. If the contract is unclear, get legal or finance review before changing a client’s invoice.

    Key takeaways for your July 1 plan

    • Meta’s surcharge is determined by the ad’s target location, not the advertiser’s home country.
    • The listed rates are 3% for France, Italy and Spain; 5% for Austria and Turkey; and 2% for the UK.
    • A $100 Italy ad becomes $103 before VAT, so media spend and total payable cost are different numbers.
    • If the cash ceiling cannot rise, divide that ceiling by 1 plus the applicable rate to find the allowable media spend.
    • Use media-only metrics to diagnose campaigns and all-in CPA, ROAS and CPM to judge economic performance.
    • Forecast and reconcile by market, especially when one campaign covers countries with different rates.

    Before the next Europe-focused budget is approved, add the country, rate and all-in cost fields to the planning sheet and make one person responsible for the first invoice reconciliation. The surcharge itself isn’t optional for covered delivery; the decision you control is whether it becomes a planned cost or an unexplained miss.

    References

  • Google Ads Data Operations: A Practical Control System

    Google Ads Data Operations: A Practical Control System

    Your dashboard is off, an audience job failed, or traffic climbed without producing more revenue. Those look like separate Google Ads problems. Operationally, they share one risk: a bad input can trigger a costly decision before anyone proves what changed.

    You need a control system that separates collection, transport, reporting, audience activation, and campaign action. Once those layers are visible, you can pause only the affected decisions, repair the right component, and keep trustworthy signals flowing into automated bidding.

    Key takeaways

    • Do not change bids or budgets until you have classified an unexpected metric movement as a real business change, a collection failure, a transport problem, a reporting delay, or an activation issue.
    • Report availability is not the same as report freshness. Record the last complete timestamp, affected dimensions, and last-known-good comparison before acting.
    • Build a small set of durable first-party audiences around meaningful customer states. Excessive segmentation reduces usable data and creates more failure points.
    • Validate the Customer Match upload path itself. Successful campaign-management requests do not prove that an inactive developer token can still upload Customer Match data.
    • Treat invalid traffic as both a budget problem and a data-integrity problem. Audit the riskiest inventory first, then judge controls by downstream business outcomes.

    Diagnose reporting before you optimize the campaign

    A dashboard number is the endpoint of a pipeline, not an independent source of truth. A conversion can occur correctly while its report is delayed. A report can refresh normally while the conversion tag has stopped firing. A campaign can also deteriorate for real while every technical component is healthy. Those cases can look identical in the interface for a while, but they demand different responses.

    Use an explicit data map so every anomaly has somewhere to go:

    LayerQuestion to answerEvidence to inspect
    Business outcomeDid leads, orders, qualified opportunities, or revenue actually change?Order system, CRM, call records, payment records, and their timestamps
    CollectionDid the expected website or app event occur and carry the required data?Site or app logs, tag diagnostics, analytics events, and test conversions
    TransportDid an upload, import, export, or scheduled integration complete?Job status, response errors, processed record counts, and last successful run
    Processing and reportingIs the interface showing complete, current, and consistently defined data?Freshness timestamps, platform status, report filters, dimensions, and an independent reporting view
    Activation and decisionDid the audience or conversion signal reach the intended campaign, and is a campaign change justified?Audience state, campaign configuration, exclusions, bidding inputs, and account change history

    A Google Ad Manager incident illustrates the distinction. Ad Manager is the publisher product, not the Google Ads buying interface, yet the operational lesson transfers: users could log in while the newest data was unavailable and current reports disagreed with the legacy reporting tool. Platform access therefore proved neither freshness nor consistency.

    Use the same triage sequence every time

    1. Define the anomaly. Write down the metric, affected campaigns or properties, first abnormal timestamp, last-known-good timestamp, reporting timezone, and comparison period. “Conversions are down” is too vague to investigate.
    2. Protect the account from premature action. Pause major bid, budget, targeting, and exclusion changes that depend on the disputed metric. Do not pause healthy campaigns merely because one report is late.
    3. Test freshness before magnitude. Identify the latest complete period. A partially processed period should not be compared with a completed one as if both were final.
    4. Reconcile definitions. Confirm that filters, conversion actions, campaign scope, attribution settings, dimensions, and time boundaries match. Two correctly calculated reports can disagree because they answer different questions.
    5. Trace the outcome upstream. Check whether orders, leads, calls, or qualified opportunities changed in the underlying business system. This separates a reporting fault from a plausible performance event.
    6. Inspect collection and transport. Check event flow, import jobs, API errors, record counts, and the last successful run. A successful login or unrelated API request is not proof that the relevant pipeline worked.
    7. Check the platform status and preserve evidence. Save the affected report configuration, timestamps, screenshots, exports, and error responses. If the issue is not listed, give support a reproducible case rather than a general complaint.
    8. Release decisions selectively. Resume only the actions supported by verified data. Keep decisions tied to the damaged layer on hold until freshness and consistency return.

    Do not force two reports to agree by changing campaign settings. If internal sales remain stable while the newest platform data is incomplete, wait for processing and reconcile later. If the conversion event disappears while sales continue, repair collection. If both business outcomes and verified reporting decline, a campaign or market response becomes reasonable. Classification comes before optimization.

    Turn audience lists into controlled data products

    First-party audiences are not folders you fill once and revisit when someone wants a retargeting campaign. They are production inputs. Their definitions, refresh jobs, permissions, exclusions, and destinations affect how Google interprets your customers.

    Google Ads groups these inputs under “Your data segments.” The practical inputs are website visitors, app users, Customer Match records, and people who engaged with content on Google-owned properties. Website audiences can originate through tagging or analytics; app audiences can flow through Firebase or another analytics setup; Customer Match begins with proprietary customer records; and content engagement can include YouTube viewers or Google Engaged Audiences.

    The first mistake is treating every available behavior as a new audience. A list defined by an incidental detail, such as a visit on a particular weekday, rarely expresses a durable business state. It also divides the available signal into smaller pools, multiplies refresh and QA work, and makes exclusions harder to reason about.

    Start with states that would change a real marketing decision:

    • Known customers: people who completed the outcome your bidding system is meant to find.
    • Qualified prospects: people who reached a meaningful qualification point but have not become customers.
    • High-intent non-converters: people who reached a product, cart, application, booking, or equivalent decision stage without completing it.
    • Broader engaged visitors or users: people with a valid interaction who have not yet shown high intent.
    • Suppression groups: existing customers, employees, test records, disqualified leads, or other groups that should not receive a particular message.

    Keep the states separate only when you will change targeting, creative, bidding interpretation, or exclusion logic because of the distinction. If two lists always receive the same treatment, their separation is probably operational overhead rather than strategy.

    Give every audience a contract

    An audience contract is a short record that lets another operator understand and verify the list without reverse-engineering it. Store these fields in your operating documentation:

    • A plain-language business definition and the decision the audience supports
    • The system of record, technical owner, and business owner
    • Inclusion logic, exclusion logic, and how conflicting states are resolved
    • The refresh trigger or schedule and the last successful refresh
    • Expected record-count behavior, with an alert for an empty or unexpectedly changing result
    • The Google Ads destination and the intended role: targeting, observation, exclusion, or audience signal
    • The campaigns allowed to consume the audience
    • The permissions governing the data and the condition under which the audience must be retired

    Only send customer records your organization is authorized to use for advertising. A secure API can protect transport, but it cannot correct an invalid permission model or a list definition that includes the wrong people.

    The campaign role matters because the same audience can behave differently across campaign types. Search, Shopping, and Display can use data segments for targeting, observation, or exclusion. Performance Max and App campaigns can consume them as audience signals and can also use supported exclusions. A signal is not a promise that delivery will remain inside the list, so document it differently from a hard restriction. Demand Gen can be a useful activation surface when the audience and message support visual storytelling.

    Direct retargeting is not the only reason to maintain these inputs. Clean customer data can also help Smart Bidding and Optimized Targeting recognize the characteristics of real buyers. That makes list quality more important, not less. A stale customer list or an audience mixing customers with low-quality leads teaches a less precise lesson.

    Review audience operations as a lifecycle: create, validate, activate, monitor, update, and retire. Watch both directions. An unexpected collapse can indicate a broken source or upload; an unexplained surge can indicate relaxed logic, duplicated records, or a source-system change. Neither should silently become a new bidding input.

    Make Customer Match transport a supported system

    Anonymous geometric customer records move through a secure validation pipeline into segmented audience containers, with one malformed batch diverted to quarantine.

    A well-designed customer audience can still fail at the transport layer. This is especially easy to miss when the same developer token continues to perform unrelated campaign-management work.

    Google’s announced cutoff for inactive Customer Match upload tokens was April 1, 2026. Under the announced rule, a developer token with no Customer Match upload through the Google Ads API during the previous 180 days would lose that upload capability. Attempts from an affected token would fail, while other Google Ads API campaign-management functions would continue.

    The important word is “upload.” General API activity does not satisfy a condition defined around Customer Match uploads. A green campaign update, reporting request, or authentication check therefore cannot validate this path.

    Run a focused continuity audit:

    1. Inventory every producer. Record the application, developer token, source system, account destination, audience destination, execution schedule, credential owner, and operational owner for each Customer Match job.
    2. Find the last successful upload. Use job logs and API responses, not a developer’s memory or the modification date of a script. Distinguish a completed Customer Match upload from other successful requests made with the same token.
    3. Test the actual path. Use a controlled, authorized dataset and destination. Capture the response, available processed or rejected counts, resulting audience state, and time of the test. Do not expose live customer records merely to diagnose connectivity.
    4. Classify failures precisely. Separate authentication, token eligibility, permissions, malformed data, source extraction, transport, and destination errors. “The API failed” is not an actionable incident category.
    5. Build the Data Manager path. Google directed affected upload operations toward the Data Manager API, positioning it as a unified ingestion system with stronger security, confidential matching, and improved encryption. Validate this path against a controlled destination before changing the production schedule.
    6. Cut over with observability. Alert on failed runs, empty inputs, abnormal count changes, missing destination updates, and repeated retries. Preserve logs and the prior configuration until the replacement has completed its expected operating cycle.
    7. Update ownership documentation. Record where credentials live, who approves source changes, who responds to failures, and how downstream campaign owners are notified when audience freshness is uncertain.

    Do not manufacture meaningless uploads to simulate activity. That leaves the underlying dependency in place and can contaminate a real audience. The durable response is to verify eligibility, move the workflow where required, and make upload success visible to someone who can act.

    Use invalid traffic checks to protect the learning loop

    A transparent verification mesh diverts clusters of repetitive event signals while varied trusted signals continue toward an automated learning system.

    Invalid traffic costs you twice. It can consume spend, and it can distort the observations used to evaluate placements, audiences, and automation. A click with no genuine consumer intent is therefore not just a media-quality issue. It is a measurement contaminant.

    The mechanisms vary. Botnets can generate automated interactions through compromised devices. Click farms manufacture engagement through people or scripts. Malware and ad injection can redirect users or insert unauthorized ads. Pixel stuffing and ad stacking can register delivery even when an ad was not meaningfully visible.

    Do not turn a broad industry estimate into an account threshold. Fraud Blocker estimated an average Google Ads invalid-click rate of 11.4% and reported a trend from 5.9% in 2010 to 12.3% in 2024. That is vendor-supplied analysis, not a universal baseline, a guaranteed refund rate, or proof that any particular account has the same exposure.

    Audit inventory in risk order

    Use campaign type as an investigation priority, not a verdict. Video Partners warrant early scrutiny because delivery extends beyond YouTube into third-party inventory. Display needs placement-level review because publisher quality varies. Shopping and Demand Gen can attract automated price-checking or other non-buying activity that is not always malicious but can still weaken the signal. Performance Max spreads delivery across inventory while offering less direct source visibility. Search is generally the lower-risk starting point, but even a small amount of invalid activity can matter when clicks are expensive.

    Build an exception view around patterns you can investigate:

    • Placements or apps with substantial click activity but little or no downstream business activity
    • Geographic traffic that conflicts with the market you can actually serve
    • Activity concentrated outside the times when legitimate demand normally occurs
    • Click growth that is not accompanied by comparable sessions, qualified actions, or business outcomes in internal systems
    • Campaign changes that suddenly expanded networks, locations, keyword reach, or automated inventory
    • Differences between internally logged activity, Google-reported activity, and invalid-traffic credits or refunds

    None of those patterns proves fraud by itself. A placement can fail because the audience-message fit is poor. Overnight demand can be legitimate. Analytics can undercount because collection is broken. Investigate across the data layers before labeling traffic malicious.

    When the evidence supports containment, tighten the specific exposure rather than rebuilding the whole account at once:

    • Use physical-presence location targeting when interest-based geographic expansion admits traffic you cannot serve.
    • Test focused, high-intent terms against broad generic reach where Search quality is uncertain.
    • Isolate Google Search Network traffic from Search Partners or Display exposure so performance can be evaluated separately.
    • Maintain negative-keyword, placement, and app exclusions based on documented patterns.
    • Align ad schedules with legitimate operating and demand periods when off-hour activity is demonstrably low quality.
    • Review placement data and Google’s detected-invalid-traffic adjustments, while also reconciling clicks with your own session and outcome records.

    These controls trade reach for confidence. Treat them as measured containment, not permanent doctrine. Annotate the change, preserve a comparable baseline, and evaluate qualified leads, orders, revenue, or another real outcome. Click-through rate alone cannot tell you whether the traffic became more valuable.

    Give this system an owner and a cadence appropriate to your spend and sales cycle. Alert immediately when a production upload fails. Review freshness, audience-count behavior, reporting exceptions, and suspicious placements on a schedule. Require a change record for consequential bids, budgets, audience logic, exclusions, and network settings.

    Start by mapping your data layers on one page. Assign an owner to each layer, record its last-known-good evidence, and specify which campaign decisions must stop when it fails. Then validate the Customer Match path directly. The next anomaly will arrive as a bounded operational incident, not an invitation to guess with your budget.

    References

  • Google Ads Budget Pacing for Scheduled Campaigns in 2026

    Google Ads Budget Pacing for Scheduled Campaigns in 2026

    If you use ad scheduling to keep a Google Ads campaign from consuming a full month’s budget, check that assumption now. Starting March 1, 2026, Google changed budget pacing for notified campaigns that run on selected days or hours. Your ads still respect the schedule, but Google may concentrate substantially more spend inside the periods when they are eligible to run.

    Your immediate task isn’t to remove ad schedules. It is to separate two decisions that may have been hiding inside one setting: when the campaign should run and how much it may spend during the month. Once you calculate those controls separately, you can keep the schedule you need without leaving the monthly cost to an outdated assumption.

    Your schedule controls eligibility, not a fixed monthly spend

    Under the earlier pacing behavior, campaigns with limited schedules tended to spend less because Google paced their budgets around active days. A campaign scheduled only for weekends could therefore appear to have a predictable monthly cost even when its average daily budget was much higher than the monthly target would normally support.

    That relationship has changed for affected campaigns. Google now attempts to use more of the available monthly budget during the existing scheduled windows. The important boundaries remain the same: spend can reach twice the average daily budget on an active day, while the monthly billing limit remains 30.4 times the average daily budget.

    Those rules give each setting a different job:

    • Average daily budget: establishes the budget Google uses for pacing and the 30.4x monthly billing limit. It is not a promise that spend will equal that amount on every active day.
    • Ad schedule: determines the days and hours when the campaign is eligible to serve. The pacing change does not authorize delivery outside those periods.
    • Budget pacing: determines how aggressively Google can use the available budget inside the eligible periods.

    This is why a schedule that remains visually unchanged can produce a higher bill. The campaign has not gained more serving hours, and its displayed average daily budget has not increased. More of the permitted spend is simply being compressed into fewer active windows.

    If an ad schedule exists mainly as a cost-control device, it is no longer a dependable substitute for setting the right budget. Keep schedules that reflect real operating constraints, such as the hours when your team can handle inquiries, but make the budget itself reflect the amount you are prepared to spend.

    Calculate a schedule-aware spend ceiling

    Glowing calendar tiles send budget tokens upward to a transparent glass ceiling that limits their height.

    You can estimate the campaign’s maximum exposure from the two unchanged limits. This calculation is most useful for a full month in which the average daily budget stays constant.

    Use these variables:

    • D = the campaign’s average daily budget.
    • N = the number of calendar dates on which the campaign is scheduled to be active during the month.
    • M = the maximum monthly amount you are willing to expose to spend.

    Then calculate both constraints:

    • Monthly billing ceiling: 30.4 x D.
    • Schedule-side ceiling: 2 x N x D.
    • Schedule-aware planning ceiling: the lower of 30.4 x D and 2 x N x D.

    In compact form, the planning ceiling is min(30.4 x D, 2 x N x D). This is a ceiling based on the stated budget rules, not a spend forecast. Available traffic, auction conditions, bids, targeting and the length of each scheduled window can all leave actual spend below it.

    Count active dates, not schedule rows. If a campaign has a morning window and an afternoon window on the same date, that is still one active date for this calculation because the 2x rule applies to the day’s budget, not separately to each time block.

    The formula also exposes an important threshold. At least 16 active dates are necessary for the campaign to have enough daily capacity to reach the full 30.4x monthly limit: 15 active dates provide at most 30 x D, while 16 provide up to 32 x D. Sixteen active dates do not guarantee full delivery, but fewer than 16 cannot supply 30.4 daily-budget units under the 2x-per-day limit.

    If M is a hard monthly ceiling, a ceiling-first starting budget is:

    D = M / min(30.4, 2 x N)

    Use that equation for risk control, not as a guarantee that the campaign will spend M. If M is merely a desired spend target, you still need to judge whether the schedule contains enough demand and whether the resulting traffic meets your performance objective.

    The $100 weekend-only example

    Consider a simplified month with eight weekend dates and a $100 average daily budget. Under the earlier behavior, the campaign might have spent about $100 on each active date, producing an approximately $800 month. Under the new pacing approach, the unchanged daily rule allows as much as $200 on each of those eight dates.

    • Monthly billing ceiling: 30.4 x $100 = $3,040.
    • Schedule-side ceiling: 2 x 8 x $100 = $1,600.
    • Schedule-aware ceiling: $1,600, because it is lower than $3,040.

    The result is the practical risk behind the change: a weekend campaign that had been spending around $800 could move toward $1,600 without a change to its $100 budget or schedule. It still cannot reach the full $3,040 monthly limit in this eight-date example because the 2x daily constraint leaves insufficient active dates.

    If $800 is a hard ceiling rather than a loose target, divide it by the binding coefficient of 16. That produces a $50 average daily budget. With eight active dates, the campaign could then spend up to $100 per date and $800 across those dates. Its 30.4x monthly limit would be $1,520, but the tighter eight-date schedule-side ceiling would remain $800.

    Do not reuse the eight-date assumption for every month. Count the actual eligible dates in the month you are planning, recalculate N, and then reset D. A fixed $50 budget tied to an eight-date example will not preserve the same ceiling when the schedule contains a different number of active dates.

    Audit affected campaigns without making blanket budget cuts

    An analyst reviews highlighted campaign cards and blank calendar icons across two unbranded computer monitors.

    Google described this as a gradual rollout affecting advertisers that received a direct notification. That makes notification status part of the audit. A scheduled campaign should not be treated as affected solely because March 1, 2026 has passed, and an unrelated campaign should not have its budget cut merely because another campaign was notified.

    1. Confirm the notification’s scope. Locate the direct Google notice and record which account or campaigns it covers. If the scope is unclear, preserve the notice with your audit notes rather than assuming every scheduled campaign changed at once.
    2. Inventory scheduled campaigns. For each one, record its average daily budget, eligible days and hours, number of active dates in the month, intended monthly ceiling and current spend. Include paused campaigns that may be reactivated under an old budget.
    3. Identify the schedule’s real purpose. If it protects response times, staffing coverage or another operational limit, keep it. If it was primarily expected to reduce monthly spend, move that responsibility to the budget calculation.
    4. Calculate both ceilings. Compare 30.4 x D with 2 x N x D. Use the lower number as the schedule-aware exposure ceiling.
    5. Compare exposure with approval. If the calculated ceiling exceeds the amount the business is prepared to spend, lower the average daily budget before the next eligible window. Expanding or removing the schedule is a separate operating decision and should not be used merely to make a budget formula work.
    6. Record the intervention. Save the previous budget, new budget, effective date, active-date count and calculation. Without that record, a later spend change can be misread as a bidding, demand or performance issue.

    Monitor concentration as well as the monthly total

    A monthly total can hide the behavior that creates the risk. Review each eligible date after it runs and track:

    • Actual spend for the active date compared with D and the 2 x D daily ceiling.
    • Cumulative monthly spend compared with your internal maximum and the 30.4 x D billing limit.
    • Whether delivery remained inside the configured schedule.
    • Conversions or other business outcomes, so higher spend is not mistaken for better performance.

    If the budget and schedule stayed unchanged but spend moved closer to 2 x D on eligible dates after a direct notification, the pattern is consistent with more aggressive pacing. It does not prove that pacing is the only cause. Changes in demand, bids, targeting or auction conditions can also move spend. If ads appear outside the configured hours, however, that is not explained by this pacing change because scheduled hours are supposed to remain in force.

    Do not raise D automatically when a campaign falls short of a desired target. The ceiling formula shows what Google may be allowed to spend; it does not establish that suitable traffic exists or that additional spend will be productive. Resolve a hard overspend risk first, then evaluate delivery and performance as a separate decision.

    Key takeaways

    • For affected campaigns, ad scheduling still controls when ads can run, but it may no longer reduce monthly spend in the way your historical results implied.
    • The 2x active-day rule and the 30.4x monthly billing limit remain unchanged; the change is how Google paces budget within scheduled windows.
    • Use min(30.4 x D, 2 x N x D) to calculate a schedule-aware planning ceiling for a full month with a constant budget.
    • A $100 campaign with eight active dates has a $1,600 schedule-side ceiling, even if its earlier spend was around $800.
    • Only directly notified advertisers were identified as affected during the gradual rollout, so confirm scope before changing unrelated campaigns.
    • Treat a calculated ceiling as cost exposure, not a delivery promise. Monitor outcomes separately from spend.

    Open each notified scheduled campaign before its next active window. Count the month’s eligible dates, calculate both ceilings, and tie the average daily budget to the amount you are actually authorized to expose. That one calculation lets the schedule keep doing its operational job without quietly making your spending decision for you.

    References

  • Modern PPC Operations: Formats, Feeds, and Reporting

    Modern PPC Operations: Formats, Feeds, and Reporting

    Your ads can look healthy while the business result quietly deteriorates. A visual asset may be winning clicks but sending the wrong audience. A feed delay may suppress eligible products while the campaign settings remain untouched. A polished dashboard may hide either problem because its blended totals still look plausible.

    Modern PPC needs an operating system, not a longer optimization checklist. You have to manage three connected layers: the experience people see, the inputs advertising systems use, and the reporting that tells you what to change. This framework will help you find the failing layer before you spend money fixing the wrong one.

    Key takeaways

    • Treat each image, headline, description, product record, and landing page as an independent campaign input. Automated systems cannot rescue an asset that lacks a clear message or role.
    • Monitor feed health as a delivery dependency. A feed problem can resemble weak demand, an auction change, or poor campaign management unless you inspect product eligibility separately.
    • Give each data system a defined responsibility. Ad platforms explain delivery, Merchant Center explains product eligibility, GA4 explains post-click behavior, and business systems explain realized value.
    • Build reports around decisions and exceptions, including budget variance, zero-conversion spend, feed degradation, weak post-click behavior, and creative fatigue.
    • Investigate performance in causal order: platform availability, item eligibility, ad delivery, on-site behavior, and business value. That order prevents downstream symptoms from being mistaken for upstream causes.

    Build campaigns around assets, not just ads

    The old keyword-to-text-ad model is no longer a sufficient mental model for PPC. Conversational discovery, interactive showroom ads, visual experiences, and emerging gaming placements create journeys in which a person may inspect, compare, and refine an idea before producing anything that resembles a conventional search click.

    That changes your unit of optimization. You are no longer managing only ads or campaigns. You are managing a library of components that an automated system can select, combine, and distribute across different contexts.

    Give every asset a specific job

    Start by assigning each asset a funnel role. A visual can orient someone to the category, demonstrate a product, make a comparison easier, establish trust, or support an action. If you label everything as generic creative, you will know which file received impressions but not why it worked.

    • Orientation: Show what the product or service is without requiring supporting copy to make it intelligible.
    • Context: Show the offer in the situation where someone would use, choose, or evaluate it.
    • Detail: Make an important feature, difference, or constraint visible.
    • Validation: Reinforce the brand, proof, or reason a buyer should trust the offer.
    • Action: Make the next step and the value of taking it unambiguous.

    Visuals belong across the funnel, not only in awareness or remarketing. At the same time, every asset should remain recognizably yours. Brand-forward visuals and curated creative libraries matter because automated distribution can place one component in contexts you did not manually assemble.

    Maintain an asset register beside the media plan. Record the asset identifier, concept, offer, format, funnel role, intended audience, landing page, launch point, and current status. Use stable identifiers in both the ad platform and the reporting layer. A filename such as image-final-new is useless when you need to connect a result to a creative decision.

    Use AI as a selection system, not a substitute for judgment

    Automation needs good inputs: first-party data, creative assets, copy, website content, goals, and budgets. It can evaluate combinations and expose niche winners, but it cannot decide what your brand should mean or whether an isolated claim is persuasive. Individual asset performance can reveal which components deserve replacement and which niche performers deserve closer attention.

    Do not respond by replacing the whole library at once. Preserve strong components, remove clearly weak ones, and introduce distinct alternatives. A bulk replacement destroys your ability to tell whether the concept, format, offer, or audience match caused the change.

    Before uploading an asset, ask:

    • Can someone understand the central promise if this component appears without its preferred companion asset?
    • Does it add a genuinely different concept, or is it a cosmetic variation of material already in the library?
    • Is the brand identifiable without overwhelming the useful part of the message?
    • Can the asset be mapped to one business objective and one landing-page experience?
    • Will its identifier survive exports, blended reports, and future creative revisions?

    This discipline reduces asset overlap. It also makes automated performance easier to interpret: the system may choose the components, but you retain control over what each component is capable of communicating.

    Treat product feeds as production infrastructure

    Retail products move through an automated feed pipeline with sorting, quality checks, synchronization, and a gate that catches one delayed item.

    A retail campaign cannot advertise a product reliably if the advertising system cannot ingest, approve, or refresh its record. That makes the feed part of campaign delivery, not a back-office file owned exclusively by merchandising or development.

    The operational risk is real even when campaign settings have not changed. In one Merchant Center service disruption, the feed incident began on February 4, 2026, and was still under investigation in the February 20 status update. The available notice did not establish the cause, affected scope, or resolution time. That uncertainty is exactly why your monitoring has to distinguish platform availability from a defect in your own data.

    Map the feed pipeline as four separate states:

    1. Source state: The catalog, inventory, price, availability, destination URL, and other product data are correct in the system that owns them.
    2. Export state: The scheduled file, API process, or connector emits the expected records and completes successfully.
    3. Ingestion state: Merchant Center receives and processes the feed without an abnormal delay or unexpected drop in item count.
    4. Eligibility and delivery state: Products remain approved, current, and able to participate in the campaigns and free listings that depend on them.

    A green export job proves only the second state. It does not prove that Merchant Center processed the file, that products remained eligible, or that campaigns continued serving them.

    Use a feed incident protocol that preserves evidence

    When product delivery falls unexpectedly, capture the current state before making repairs. Save the feed completion time, processed item count, approval and disapproval pattern, affected product segments, campaign delivery change, and any platform status notice. Without that snapshot, a later recovery can erase the evidence you need to identify the cause.

    1. Check scope. Determine whether the problem affects the entire catalog, one market, one destination, one product type, or a recently edited segment.
    2. Check timing. Compare the first visible delivery change with the last successful source update, export, ingestion event, and platform notice.
    3. Check the status dashboard. A broad service notice does not prove your account has the same problem, but it changes the order of investigation.
    4. Inspect diagnostics. Separate delayed processing from new disapprovals, missing products, and stale price or availability data.
    5. Limit intervention. If the evidence points to a platform disruption, avoid rewriting a previously valid feed merely to force a refresh. That can introduce a second failure and make recovery harder to interpret.
    6. Validate recovery by layer. Confirm processing, item counts, approval status, campaign delivery, and business outcomes before releasing a backlog of unrelated feed changes.

    A platform incident usually has broad timing and multiple affected records. A local transformation problem is more likely to follow a catalog or connector change and affect a coherent subset. Normal feed diagnostics combined with falling spend point you back toward campaign eligibility, auction conditions, budgets, or demand. Do not pause an entire account simply because revenue fell; first establish whether the feed is actually the failing layer.

    Build reporting that can identify the failing layer

    An analyst traces an amber fault through stacked creative, product-feed, and conversion layers in a three-dimensional reporting system.

    A useful PPC dashboard does more than reproduce platform totals. It connects delivery to post-click behavior and business outcomes while making missing or delayed inputs visible.

    GA4 and Looker Studio solve different parts of that problem. GA4 uses an event-based model for website and app interactions. Looker Studio is designed to combine and present data, with connections to more than 800 data sources, calculated fields, blending, interactive controls, and scheduled report delivery. Neither should be treated as the sole owner of PPC truth.

    Assign ownership before you blend anything

    • Advertising platforms: Own impressions, clicks, spend, placement, bidding, and platform-attributed actions.
    • Merchant Center diagnostics: Own feed processing, product approval, and product-level eligibility evidence.
    • GA4: Own the configured view of sessions, engagement, events, and other website or app behavior after the click.
    • CRM or commerce systems: Own qualified leads, orders, realized revenue, and other downstream business states.
    • Looker Studio: Presents and calculates across those systems. It does not repair inconsistent definitions in the underlying data.

    GA4 can natively import cost, click, and impression data from additional advertising platforms, including Meta and TikTok, but strict UTM matching and limited campaign-name cleanup can constrain the result. Native ingestion reduces manual work; it does not remove the need for a campaign naming standard.

    Write the join plan before building charts. Specify the date grain, channel definition, account identifier, campaign identifier, creative identifier, currency, time zone, and conversion definition. Normalize labels in a controlled field rather than editing historical campaign names to make a chart look tidy. If two datasets have multiple rows for the same join key, aggregate them to the intended grain before blending; otherwise cost or conversions can be duplicated.

    Organize the dashboard around decisions

    A decision-grade PPC report needs four views:

    1. Outcome and pacing: Show spend against plan, primary outcomes, efficiency, and downstream value. If the monthly plan is intentionally linear, the expected spend point halfway through the month is 50% of the budget. If demand or promotions are not linear, replace that line with the actual spending plan rather than pretending uniform pacing is desirable.
    2. Delivery and feed health: Show changes in eligible products, product diagnostics, impressions, clicks, and spend together. This view tells you whether falling revenue began before or after the click.
    3. Creative performance: Display the actual visual beside its stable asset identifier, spend, click response, conversion result, and post-click quality. Looker Studio’s IMAGE function can place creative previews inside a report table, making the discussion about the asset rather than an opaque ad-group name.
    4. Waste and post-click quality: Surface spend with no recorded conversion above a threshold chosen for the account. Pair click response with engagement and lead quality so a high click-through rate cannot disguise a poor landing-page or audience match.

    Calculated fields should translate platform activity into business language. Profit can be calculated by subtracting cost from revenue, while ROAS can connect CRM revenue with advertising cost. Document which revenue state you use. Booked revenue, collected revenue, predicted value, and platform-attributed conversion value answer different questions and should not share an unlabeled metric name.

    Add a trust panel to every report. Include the last successful refresh, source coverage, reporting time zone, currency treatment, primary conversion definition, attribution scope, exclusions, and known incidents. A viewer should be able to tell whether a flat line means no activity or failed data retrieval.

    Keep performance observations separate from explanations. An annotation such as “cost per lead increased after the promotion ended” records a sequence. “Competitor aggression caused the increase” is a hypothesis unless you have supporting evidence. Labeling the difference protects the dashboard from turning a plausible story into an accepted fact.

    Complex dashboards also create a reliability problem of their own. Heavy use of GA4 widgets and concurrent views can run into API quotas. For demanding reporting environments, extracting GA4 data to BigQuery before connecting Looker Studio can reduce quota pressure and improve report performance. Before adding another chart, ask what decision it changes; fewer meaningful queries are easier to trust than a wall of fragile widgets.

    Use one operating sequence for every performance anomaly

    The same symptom can come from several layers. A revenue decline might begin with product eligibility, creative-message mismatch, landing-page behavior, tracking, lead quality, or actual demand. Use the earliest reliable evidence to decide where to investigate.

    What you noticeCheck firstWhat to do next
    Product impressions and spend fall suddenlyFeed processing, item counts, diagnostics, eligibility, and platform statusIsolate the affected product set and preserve the last known valid feed configuration while you identify the failing state.
    Delivery is stable but click response weakensAsset, format, placement, audience, and offer breakdownsReplace a weak component with a meaningfully different alternative while retaining stable winners.
    Clicks remain stable but engagement or leads deteriorateLanding-page behavior, conversion collection, page-message continuity, and audience qualityInvestigate the post-click path before changing bids or product data.
    Spend is ahead of planPlanned pacing, current demand, outcome quality, and budget configurationDecide whether the variance is productive before reducing delivery solely to match a straight line.
    Platform ROAS falls while recorded business revenue is stableAttribution scope, conversion definitions, join logic, and data refresh timingReconcile measurement before reallocating budget on the assumption that demand collapsed.
    Several dashboard charts flatten or fail togetherConnector refreshes, source credentials, API quotas, and source coverageRestore reporting reliability and mark the affected period instead of interpreting missing data as zero performance.

    Work from cause to consequence

    1. Availability: Can each required platform and connector process or return data?
    2. Eligibility: Are the intended ads, products, assets, destinations, and audiences allowed to participate?
    3. Delivery: Did impressions, clicks, spend, format mix, or product coverage change?
    4. Behavior: Did people engage with the landing experience and complete the configured events?
    5. Value: Did those actions become qualified leads, orders, revenue, profit, or another business outcome?

    Keep a decision log beside the dashboard. Record the observed condition, affected scope, evidence, working hypothesis, action, owner, and validation signal. Where practical, change only one causal layer at a time. If you rewrite the feed, replace the creative library, alter bids, and edit conversion definitions together, even a recovery will teach you very little.

    Start with the report you already use. Add its last refresh, feed status, spend against plan, primary business outcome, and known incident state. Then make your next optimization only after you can name the layer that failed. That small change turns PPC reporting from a record of what happened into a control system for what you do next.

    References