Two Google Ads updates illustrate why the word automation needs careful interpretation. One reorganizes how established bidding strategies are named, while the other automatically begins processing eligible advertisers’ conversion data into customer lists.
The practical distinction is consequential: the bidding update is reported as cosmetic, but the audience update changes an account default. Advertisers therefore need different responses to each development rather than treating both as changes to campaign optimization.
Two updates, two different forms of automation
The bidding report says Google is restoring the standalone Target CPA and Target ROAS names. It also says the underlying bidding behavior and expected campaign performance remain unchanged, with no advertiser action required.
By contrast, the customer-list report describes an operational default: eligible accounts will have conversion-based customer lists enabled automatically, with data processing reported to begin on August 18. The sources therefore cover complementary but materially different issues. One changes the language used to describe automated decisions; the other changes how an audience-data feature is activated.
Restored bidding names make campaign intent easier to read
According to the bidding report, “Maximize conversions with a Target CPA” will again be called Target CPA, while “Maximize conversion value with a Target ROAS” will return to Target ROAS. Maximize Conversions and Maximize Conversion Value remain available as separate strategies for advertisers prioritizing conversion volume or conversion value.
This creates a clearer conceptual boundary between an unconstrained maximization objective and an objective governed by a stated efficiency target. It should not, however, be interpreted as a new bidding model, a performance intervention or a reason to reset campaigns. The source explicitly characterizes the change as naming-only.
The report also connects the revised interface labels with Google Ads API terminology. Teams maintaining integrations or reporting systems are advised to watch for adjustments involving the BiddingStrategyType enum, standalone TargetCpa and TargetRoas messages, and optional targets within MaximizeConversions and MaximizeConversionValue. That makes taxonomy mapping a more relevant concern than bid-performance troubleshooting.
Automatic customer lists require a governance decision
The customer-list report says automatic enablement applies to qualifying advertisers already using both Enhanced Conversions and Customer Match but not conversion-based customer lists. Google will process existing conversion data to make the lists available without additional implementation work, according to the source.
Availability is not the same as campaign use. The report says advertisers can subsequently decide whether to add the resulting audiences to campaigns or ad groups. The immediate decision is therefore whether the account should permit list generation at all; targeting decisions remain a separate step.
Advertisers that do not want the feature enabled can disable conversion-based customer lists in account settings before the reported August 18 processing date. This opt-out makes the update relevant to account ownership, consent practices and internal audience-data policies even when no campaign is scheduled to use the lists.
Key takeaways for Google Ads teams
Treat the Target CPA and Target ROAS update as a terminology change, not evidence that bidding logic or campaign performance has changed.
Keep Maximize Conversions and Maximize Conversion Value distinct from target-based strategies when documenting objectives and reporting results.
Review eligible accounts before the reported August 18 date and make an explicit decision about conversion-based customer-list processing.
Separate list creation from list activation: automatic availability does not require an advertiser to use an audience in a campaign or ad group.
Check API integrations and internal naming maps as Google aligns interface labels with standalone bidding-strategy types.
What advertisers should monitor next
Together, the updates point toward a Google Ads environment in which interfaces may become clearer while data features become more automatic. Strong account management will depend on identifying which changes merely improve labels and which alter defaults, permissions or data flows. Teams that document both bidding intent and audience-data choices will be better prepared for subsequent interface and API adjustments without mistaking automation for loss of control.
OpenAI’s reported UK beta gives advertisers an early route into a self-serve advertising environment associated with ChatGPT. Its immediate value is access: businesses can begin learning the account structure, campaign interface and agency permissions before the channel’s wider shape is clear.
The available report establishes how advertisers enter and navigate the platform, but it does not provide enough information to judge audience quality, campaign performance or commercial impact. UK teams should therefore treat the beta as a structured learning opportunity rather than evidence that ChatGPT advertising is ready to become a major budget line.
What the beta opens – and what it does not establish
According to the supplied CrushPress.AI report, OpenAI informed recipients by email that its ChatGPT Ads Manager Beta was available to UK businesses. The report describes a self-serve interface intended to make account creation and campaign management relatively straightforward, with no upfront billing requirement during account creation.
The reported dashboard has four main areas: campaigns, tools, billing and settings. That structure should be recognizable to marketers accustomed to paid-media platforms, and the report characterizes campaign controls and user administration as easy to reach.
Interface familiarity should not be confused with channel maturity, however. The source does not detail available inventory, targeting methods, measurement capabilities, pricing mechanics or the way advertisements appear within ChatGPT experiences. It also does not report campaign results. Those omissions are material because a convenient dashboard says little about whether the underlying advertising opportunity can deliver incremental reach, qualified demand or measurable business outcomes.
The beta label also matters. Advertisers can inspect the reported workflow, but they should preserve uncertainty around features and operating practices that the source does not document. The report presents the UK availability as a sign that OpenAI is developing more scalable advertising infrastructure, not as proof that the platform has reached its final form.
Key takeaways
The supplied report says UK businesses have been offered access to a self-serve ChatGPT Ads Manager beta.
The dashboard reportedly separates campaigns, tools, billing and settings into four primary areas.
Clients should create and retain ownership of their own accounts, then invite agencies or freelancers as users.
Agency users can reportedly switch between client accounts, but they cannot manage them simultaneously through an equivalent of Google Ads’ MCC structure.
The source does not disclose enough about inventory, targeting, measurement or performance to support a scaling decision.
Account ownership changes the agency workflow
The clearest operational guidance concerns the relationship between clients and external partners. The report says OpenAI advises agencies and freelancers not to create Ads Manager accounts on a client’s behalf. Instead, the client should establish the account, open Settings, navigate to Users and Invites, and invite its partner with an appropriate permission level. The invited user then accepts access through email.
This arrangement makes client ownership the sensible default. It can reduce ambiguity over who controls the account if an agency relationship changes, while allowing external specialists to work through delegated access. Before accepting an invitation, both sides should still document who is responsible for billing, campaign approval, creative review, measurement and access removal. Those are general governance safeguards rather than capabilities confirmed by the source.
Multi-client management is less developed in the reported beta. An invited user can move between client accounts, but the source says there is currently no centralized structure comparable to a Google Ads manager account for viewing and managing several accounts at once. Agencies should expect account-by-account navigation and design their internal checks accordingly. Naming conventions, access records and separate approval trails may become more important when the platform itself does not provide a consolidated operating view.
That limitation is more than a minor interface inconvenience. It can affect how efficiently an agency monitors activity, separates client data and applies quality controls. A small pilot may be manageable through account switching; a larger portfolio would require evidence that the administrative workload remains proportionate.
How to turn beta access into a useful pilot
Start with ownership and decision rights
The client should create the account, retain primary control and grant only the access needed for each participant’s role. The team should also decide who can change settings, approve campaign activity and review billing. This preparation addresses the workflow the source actually describes without assuming that unreported enterprise controls are available.
Define the evidence required before spending scales
A beta test needs a decision standard, not merely activity. Before launching work, advertisers should define the business question they want the pilot to answer and identify the measurement information required to answer it. If the platform’s available reporting cannot support that standard, the limitation itself is an important finding.
Teams should distinguish platform-reported activity from business outcomes and avoid treating unfamiliar metrics as direct substitutes for established measures. Because the source supplies no performance benchmarks, advertisers have no reported basis for assuming that results should resemble search, display or paid social campaigns.
Record product learning separately from campaign results
An early evaluation should capture two kinds of evidence. Operational learning covers account creation, permissions, navigation and day-to-day management. Media learning covers whatever the beta reveals about delivery, audience controls and measurement. Keeping those records separate prevents a smooth setup experience from being mistaken for strong advertising performance.
Agencies can also document the time required to switch accounts, conduct checks and prepare client reporting. That evidence will help determine whether the current multi-account workflow is sustainable, even if campaign-level results appear promising.
The unanswered questions that should govern scaling
The most important next disclosures concern the advertising product beneath the dashboard. Advertisers need clarity on what inventory can be bought, where and how advertisements are presented, which targeting and exclusion controls are available, and what measurement or attribution tools support evaluation. They will also need to understand how commercial content is integrated into a conversational environment.
Those questions affect user expectations as well as media performance. A conversational product is not automatically equivalent to a search-results page or social feed, so established assumptions about attention and intent should not be transferred without evidence. Brand suitability, disclosure and the relationship between an advertisement and the surrounding response will require careful examination when relevant details become available.
The reported UK opening gives advertisers a head start on account governance and platform literacy. The prudent next move is to build a reversible pilot, document what the beta can genuinely demonstrate and reserve larger commitments for the point when inventory, controls and measurement are sufficiently clear.
Google is developing two different ways to reduce friction in advertising operations: stronger conversion inputs for advertisers and conversational analysis for publishers. One beta supplements website conversion actions with backend records; the other brings a Gemini-powered assistant into Google Ad Manager.
The tools do not form a single workflow, and the supplied reports do not describe an integration between them. Together, however, they illustrate a broader operating model: improve the evidence used to judge performance, then make that evidence easier to investigate and act on.
Two tools address different parts of the advertising cycle
The distinction between the products matters. CrushPress.AI reported that Google’s supplemental conversion data beta is intended for advertisers using eligible website conversion actions in Google Ads. Ask Ad Manager, meanwhile, was reported as a conversational assistant for publishers working in Google Ad Manager.
Area
Supplemental conversion data
Ask Ad Manager
Primary user
Advertisers measuring website conversions
Publishers managing advertising inventory and delivery
Core problem
Conversions that website tags may not capture
Time spent building reports, investigating delivery and navigating the platform
Main input
Backend transaction records from systems such as CRMs, order databases and ecommerce platforms
Natural-language questions evaluated against the publisher’s Ad Manager data
Reported outcome
A more complete conversion action for measurement and optimization
Tailored answers, reports, recommendations and platform guidance
Important boundary
Enhances rather than replaces website tagging
Assists analysis and operations rather than repairing conversion collection
This comparison prevents a common category error. Better conversion capture cannot diagnose every publisher delivery issue, while a conversational reporting interface cannot recover a transaction that never reached an eligible conversion action. Each tool works on a different constraint.
Supplemental data strengthens the measurement foundation
According to CrushPress.AI’s report, the Google Ads beta lets an advertiser attach an additional data source to an existing website conversion action through Google Ads Data Manager or the Data Manager API. Backend conversion records are combined with signals collected by Google tags, allowing the same conversion action to support campaign measurement and optimization.
The reported purpose is recovery, not replacement. Browser restrictions, privacy settings or ad blockers can prevent some tag-based signals from being captured. Transactional systems may retain evidence of those completed outcomes, so supplying that evidence can make measurement more resilient and give automated bidding a more complete input set.
That benefit depends on record quality. The report states that every upload must include a transaction ID and the conversion date and time, plus at least one attribution identifier such as hashed customer data or a Google click identifier. Google reportedly uses transaction IDs to deduplicate tag and backend records within the same conversion action.
The reported eligibility limits are equally significant. The beta applies to website conversion actions implemented with Google tags or Google Tag Manager; Google Analytics imports and URL-based conversion actions are excluded. Google also advises adding the supplemental source to the existing action instead of creating another action, which could introduce double-counting across campaign goals. Prompt uploads and conversion values formatted consistently with the tag’s currency were also reported as recommended practices.
Ask Ad Manager compresses the path from question to diagnosis
Ask Ad Manager tackles a different bottleneck: extracting usable answers from a complex publisher platform. CrushPress.AI described it as a Gemini-powered beta that lets Google Ad Manager users ask questions in ordinary language and receive responses grounded in their own Ad Manager data.
The reported capabilities span three recurring tasks. The assistant can investigate why line items are underdelivering and suggest possible causes or next steps. It can produce requested metrics, benchmarks and customized reports without requiring the user to construct each report manually. It can also direct a user to relevant Ad Manager pages while applying filters and settings derived from the conversation.
The practical shift is from interface-led work to question-led work. Instead of beginning with menus, report fields and filters, a publisher can begin with the business or delivery question. The assistant then helps translate that question into platform activity. This may reduce operational effort, but the source does not establish that every answer or recommendation will be correct. As a general operating discipline, consequential findings should still be checked against the underlying report and campaign configuration.
The report also attributes a wider roadmap to Google. Planned additions include developer tools such as REST APIs and an MCP server, along with specialized agents that could help publishers and agencies explore inventory, negotiate deals and execute campaigns. Those items are forward-looking plans, not capabilities established by the reported beta.
Key takeaways
The conversion beta improves the data entering an eligible Google Ads conversion action; Ask Ad Manager improves how publishers interrogate and use their Ad Manager data.
Supplemental conversion data depends on reliable transaction IDs, timestamps, attribution identifiers and consistent values, as well as correct conversion-action configuration.
Deduplication is central to the measurement design because tag and backend systems may describe the same transaction.
Conversational analysis can shorten reporting and troubleshooting work, but important recommendations still warrant validation against source data and settings.
Both features were reported as betas, while the APIs, MCP server and specialized Ad Manager agents remain part of Google’s stated roadmap.
A practical evaluation framework for advertising teams
Teams evaluating the conversion beta should first determine whether their conversion actions use an eligible implementation. They can then assess whether backend systems retain the required identifiers, timestamps and values, and whether transaction IDs remain consistent across the tag and transactional record. This is not merely an integration exercise: weak identity matching, inconsistent currency formatting or duplicate campaign goals can undermine the additional data.
Publishers assessing Ask Ad Manager should judge it against concrete operational questions. Useful tests include whether it can reproduce a trusted report, identify a known delivery issue and navigate to the correct filtered view. The relevant measure is not how fluent the conversation sounds, but whether it reduces investigation time without obscuring the evidence behind an answer.
Across both products, data discipline remains the connecting requirement. More complete records can improve the basis for optimization, while a conversational layer can make platform data more accessible. Neither advantage removes the need for clear conversion definitions, dependable identifiers, reviewable reports and accountable decisions.
If Google’s reported direction continues, advertising work will increasingly combine first-party data connections with agent-assisted operations. The teams best positioned to benefit will be those that treat reliable data and human verification as prerequisites for automation, not as cleanup work after deployment.
A paid media budget is more than a spending limit. It is a business commitment connecting campaign decisions with financial planning, future investment and client confidence.
A reported €30,000 underspend on a major B2B SaaS account illustrates how quickly that connection can break. The useful lesson is not that every budget must be exhausted, but that efficiency targets, delivery expectations, measurement and communication must be managed as one system.
Why underspending can become a business problem
According to the source account, a tighter target cost per acquisition reduced spending enough to leave €30,000 of the monthly budget unused. The immediate campaign result may have appeared more efficient, but the account failed to deliver against its agreed budget target.
The commercial consequence extended beyond media delivery. The source reported that the unused money had to be returned to finance, making it harder for the marketing team to defend a similar level of investment in later planning cycles. That turns pacing into a matter of organizational credibility: an approved budget can signal that the business expects marketing to deploy capital within an agreed strategy, not simply minimize cost in isolation.
This does not mean spending should be forced when demand, inventory or performance cannot support it. Budget discipline requires distinguishing between a justified underspend and an accidental one. A justified variance is identified early, supported by evidence and communicated to stakeholders. An accidental variance emerges too late for the team to adjust its bidding, targeting, creative or expectations.
Change control must connect efficiency with delivery
A target CPA is not merely a reporting preference. It influences how aggressively an automated bidding system can enter auctions, so changing it can alter both acquisition cost and spending volume. The source account acknowledged underestimating that effect and subsequently treated any adjustment capable of changing spend as a significant account change requiring close observation.
The broader operating principle is that optimization decisions need more than a desired efficiency outcome. Before a material change, the account team should define the expected effect on cost, conversion volume and budget delivery; record when the change was made; assign responsibility for reviewing it; and establish the conditions for keeping, modifying or reversing it.
Monitoring frequency should reflect the potential impact rather than the apparent simplicity of the platform control. A small interface adjustment can have a large financial consequence. Regular pacing checks make that consequence visible while there is still time to respond, especially when the remaining monthly budget and remaining days begin moving out of alignment.
Reliable measurement is part of budget governance
The source also identified flawed conversion tracking as a recurring industry weakness. That issue is directly connected to budget discipline because bidding systems and account teams optimize against the conversion data they receive. If implementation errors omit valuable actions, duplicate conversions or attach the wrong values, an apparently rational efficiency decision may rest on unreliable evidence.
Budget monitoring therefore cannot be separated from measurement assurance. Spend, conversions, cost per acquisition and delivery forecasts should be interpreted together, while material tracking changes or anomalies should be documented. When reported performance shifts, the team needs to determine whether customer behavior changed, campaign settings caused the movement or the measurement system stopped representing reality accurately.
AI-powered platform features do not remove this responsibility. The source supported using such tools but cautioned against adopting every new capability without human judgment and strategic oversight. Automation can execute and optimize at scale, but people still have to define acceptable business outcomes, validate inputs and notice when the system is satisfying one target at the expense of another.
Trust recovery requires an operating response
The source described personally explaining the underspend to the client and accepting responsibility without excuses. Although the client was understanding, the account noted that confidence had been affected. Weekly budget-pacing updates were then introduced to improve transparency and demonstrate that the problem would not recur.
That response highlights the difference between an apology and a control improvement. Accountability addresses the past, while a visible process gives the client evidence about the future. Useful communication should explain what happened, what it affected, what has changed and how the new control will reveal emerging risk. It should also avoid overstating certainty: no process can eliminate every mistake, but it can make detection and correction faster.
The episode remains a single reported account experience rather than a general performance benchmark. Its wider relevance lies in the management pattern it exposes: commercial trust depends not only on campaign results, but also on whether the team handles money predictably, surfaces problems promptly and makes its controls understandable to stakeholders.
Key takeaways
Evaluate budget delivery and acquisition efficiency together; improving one metric can undermine the other.
Treat bidding or targeting adjustments that may affect spend as material changes with an owner, review point and response threshold.
Separate defensible underspending from preventable underspending through early forecasting and stakeholder communication.
Include conversion-tracking checks in budget governance because optimization is only as dependable as its inputs.
Use automation within human-defined business constraints rather than assuming a platform target represents the whole commercial objective.
When an error occurs, combine direct accountability with a visible monitoring process that helps rebuild confidence.
As advertising systems become more automated, disciplined teams will treat pacing, measurement and communication as core business controls. Those fundamentals provide the stable foundation on which more advanced optimization can safely develop.
Google’s planned transition from Dynamic Search Ads (DSA) to AI Max is more than a campaign-format change. It arrives as AI is also altering how buyers discover brands, how platforms select audiences and placements, and how much of the decision journey advertisers can observe.
The extended migration window gives advertisers an opportunity to build a measurement baseline before adopting more automation. The practical goal is not simply to determine whether AI Max records more conversions than DSA, but whether it produces additional qualified business outcomes without obscuring where demand originated.
Campaign migration and attribution are now the same problem
The two source articles address different developments, but their implications converge. The migration report says Google postponed automatic DSA migration from September 2026 to February 2027 and recommends experiments comparing existing campaigns with AI Max for Search. The attribution analysis warns that platform automation can improve reported performance while reducing the detail available for explaining why that performance changed.
That combination raises the standard for a successful migration. A campaign can appear more efficient because it reaches people who were already likely to convert, captures demand created elsewhere, or counts actions that do not become meaningful customer outcomes. Broader targeting may also introduce weak leads that influence later automated optimization.
The attribution article describes an increasingly fragmented journey in which a buyer might encounter a brand through social media, video, community discussions or an AI recommendation before completing a branded search. In such a journey, the campaign receiving conversion credit may have captured existing intent rather than created it. AI Max testing therefore needs to examine both reported attribution and the business contribution behind it.
The measurement risks that can distort an AI Max comparison
More attributed conversions may not mean more incremental demand
A platform comparison based only on conversions or return on ad spend can favor the campaign that is best at claiming observable demand. The attribution source highlights branded search as a common example: it often looks highly efficient because it reaches people who already know the advertiser, even when another channel or an AI-generated answer initiated their interest.
Advertisers should consequently separate demand capture from demand creation before interpreting a test. Search activity close to conversion can be evaluated for efficiency, while upper-funnel activity should also be assessed through path analysis, changes in branded interest and incrementality experiments. The source specifically points to GA4 path reports and Google’s Conversion Lift as useful approaches, while cautioning that no single report represents the complete customer journey.
Lead volume can conceal declining business quality
The attribution analysis also reports that generalized targeting can generate poor-quality traffic when conversion signals are weak. If every submitted form is treated as equally valuable, automated bidding may optimize toward inexpensive leads rather than opportunities or sales.
CRM outcomes provide the necessary counterweight. Qualified leads, opportunities and completed sales can reveal whether a lift in platform conversions represents genuine progress. Where technically and operationally feasible, importing deeper outcomes can also give automated campaigns signals that are closer to business value.
Conversion definitions and settings require equal attention. The attribution source recounts cases in which changed reporting settings inflated conversion totals. A migration benchmark is unreliable if the legacy and experimental campaigns count different actions, use inconsistent values or are affected by unnoticed setting changes.
The delayed timetable creates a structured testing window
According to the migration report, Google restored the ability to create DSA campaigns in June 2026, plans to stop new DSA creation in January 2027 and expects automatic migration of remaining campaigns to begin in February 2027. The reported schedule creates distinct phases for baselining, experimentation and final transition.
Reported period
DSA status
Measurement priority
June 2026
New DSA creation restored
Document existing campaign structure, settings and business outcomes
June 2026 through January 2027
Extended testing and voluntary migration period
Run comparisons with AI Max and investigate differences in traffic and lead quality
January 2027
New DSA creation ends
Finalize the migration sequence and preserve benchmark data
February 2027
Automatic migration begins for remaining campaigns
Monitor post-migration changes against the established baseline
A useful comparison should keep conversion definitions, CRM mappings and evaluation periods consistent. It should record more than aggregate performance: branded versus non-branded behavior, search themes where available, lead disposition, sales outcomes and any material changes in settings all help explain the result. Side-by-side campaign data is evidence about performance under the test conditions, while incrementality testing addresses the separate question of what would have happened without the advertising.
A measurement-first migration plan
Audit the DSA baseline. Record campaign structure, conversion actions, values, targeting controls, exclusions and recent CRM outcomes before changing the account.
Define success in business terms. Choose the downstream result that matters, such as a qualified lead, opportunity or sale, rather than relying only on the easiest platform event to collect.
Separate capture from creation. Segment branded activity and other high-intent demand where possible so that AI Max is not credited with creating interest it merely intercepted.
Run an AI Max experiment. Use the voluntary testing period reported by the migration source to compare performance while keeping measurement definitions aligned.
Inspect quality and paths. Review CRM progression, attribution paths, AI-referred sessions and branded search behavior alongside platform metrics. These indicators do not prove causation individually, but they can identify results that need further investigation.
Add an incrementality check. Where practical, use a lift experiment to test whether advertising caused additional outcomes rather than assuming every attributed conversion was produced by the campaign.
Migrate in stages and retain human review. Move campaigns only after documenting the evidence, then monitor placements, settings, lead quality and downstream results as automation learns.
This sequence also protects against a common analytical mistake: changing the campaign format, conversion setup and success metric simultaneously. When several inputs change at once, even a strong performance movement becomes difficult to interpret.
Key takeaways
The reported DSA delay provides time to establish benchmarks and test AI Max before automatic migration begins in February 2027.
Platform-attributed conversions should be evaluated separately from incremental demand, especially when branded search captures interest created elsewhere.
CRM outcomes are essential for detecting whether broader automated targeting is producing qualified opportunities or merely more leads.
Comparable conversion settings, documented account changes and regular human checks make migration results easier to trust.
The strongest decision combines platform reporting, customer-journey evidence and incrementality testing rather than depending on one ROAS figure.
Advertisers that use the extension to improve their measurement system will enter the automated transition with more than a replacement campaign. They will have a defensible way to decide when AI Max is creating business value, when it is capturing existing demand and when its optimization signals need correction.
OpenAI’s reported advertising expansion is taking shape on two fronts: broader geographic access and a test that could place several advertisers within one ChatGPT ad space. Together, these changes point toward a more mature ad marketplace built around commercially relevant conversations.
For advertisers, the immediate value lies in expanded targeting and more familiar campaign controls. The larger strategic question is whether multi-advertiser placements can support product discovery without making conversational results feel crowded or less useful.
Key takeaways
OpenAI is reportedly adding the U.K., Japan, South Korea, Brazil and Mexico to the geographic options available beyond the U.S., Canada, Australia and New Zealand.
A limited test combines ads from multiple relevant advertisers in one placement rather than showing only one sponsored result.
The tested format reportedly uses a second-price auction, introducing established digital-ad auction mechanics to conversational discovery.
Ads Manager Beta is adding more flexible budgets, bidding transitions, custom CPM limits and bulk editing.
The report does not provide performance benchmarks, placement-level details or a timetable for turning the limited test into a wider release.
Market expansion and format testing address different constraints
The geographic expansion increases where advertisers can target campaigns. According to the supplied CrushPress.AI report, the U.K., Japan, South Korea, Brazil and Mexico are being added beyond the previously listed markets of the U.S., Canada, Australia and New Zealand. That widens access, but it does not by itself change how many advertisers can appear in a placement.
The multi-advertiser test tackles the supply side of the marketplace instead. The report says OpenAI is testing the format across a limited number of ChatGPT ads, grouping several relevant advertisers in a single space. If expanded, that design could create more opportunities to participate in high-intent conversations without requiring a separate ad slot for every advertiser.
These are therefore complementary developments: geographic targeting broadens the addressable audience, while a multi-advertiser unit could increase the advertising options presented within an eligible interaction. Neither change, based on the available report, establishes how frequently users will encounter ads or which types of conversations will qualify.
A multi-advertiser unit changes the competitive context
A single sponsored result gives one advertiser the visible opportunity within its placement. A grouped unit creates a comparison environment: relevance still matters, but the advertiser’s offer may also appear alongside alternatives at the moment a user is researching a product or service.
The report says the test uses a second-price auction model. In general, this auction structure determines payment with reference to competing bids rather than automatically charging the winner its full bid. Its use would make the buying mechanism recognizable to experienced digital advertisers, although the source does not disclose the complete ranking formula, pricing rules or role of quality and relevance signals.
That missing context matters. More advertisers in one unit could improve choice and product discovery, which the report identifies as OpenAI’s aim. It could also divide attention among neighboring offers. Advertisers would therefore need placement-specific evidence before treating results as equivalent to conventional search, display or social inventory.
Ads Manager Beta is becoming more operationally familiar
The campaign-management changes described in the report reduce several practical barriers to experimentation. Existing campaigns can reportedly move from lifetime budgets to daily budgets, while CPM campaigns can transition to CPC bidding in one click. Impression-based campaigns gain custom maximum CPM bids, and bulk editing is being added within the Ads Manager interface.
Daily budgets will reportedly operate as average daily budgets with weekly pacing flexibility. That distinction is important for campaign oversight: an average allows delivery to vary from one day to another, so advertisers should evaluate spend against the applicable pacing period rather than assume an identical amount will be spent every day.
Collectively, the controls resemble capabilities buyers already use elsewhere. Familiarity can simplify setup and budget changes, but it does not make ChatGPT inventory interchangeable with other channels. CPC and CPM optimize around different billable events, and conversational placements may produce different attention, comparison and conversion patterns.
Advertisers need evidence beyond access and interface upgrades
The reported updates make it easier to launch and modify campaigns, but the source provides no results for click-through rates, conversion rates, incremental lift or advertiser return. It also does not specify how multi-advertiser units will be labeled, how ads will be ordered inside the placement or which reporting dimensions will distinguish them from single-advertiser units.
A measured evaluation would separate three questions: whether the available audience matches the campaign’s market, whether the buying model aligns with its objective, and whether the placement produces incremental business outcomes. CPC may make sense when traffic is the immediate goal, while CPM can suit reach or visibility objectives; neither pricing model proves downstream value on its own.
Creative strategy may also need to account for direct comparison. In a multi-advertiser setting, a clear product distinction, relevant offer and accurate destination experience can become more important because users may see competing options together. This is a strategic implication of the reported format, not a performance finding from the limited test.
The test will be defined by relevance, measurement and user trust
The expansion suggests that OpenAI is assembling recognizable components of an advertising platform: auctions, flexible bidding, budget controls, bulk operations and international targeting. The distinctive variable is the conversational environment in which those components operate.
Whether the model scales will depend on questions the available report leaves open, particularly placement relevance, transparent measurement and the effect of multiple sponsored choices on the user experience. The most informative next developments will be evidence about performance and disclosure standards, not simply the number of available markets or campaign controls.
Your Shopify admin will not load, customers are reporting checkout errors, and paid campaigns are still sending people to the store. The worst response is to change everything at once.
You need to identify which part of the buying journey is broken, stop avoidable losses, preserve reliable data, and keep a temporary platform failure from becoming a lasting search problem.
Key takeaways
Test the store as a customer. An inaccessible admin does not automatically mean the storefront or checkout is unavailable.
Pause conversion campaigns when customers cannot complete payment, and record when you changed each campaign.
Do not noindex products, redirect product URLs, or mark inventory as out of stock solely because Shopify checkout is unavailable.
Resume promotion only after you have tested the complete journey from product page to order confirmation.
Triage the customer journey before changing campaigns
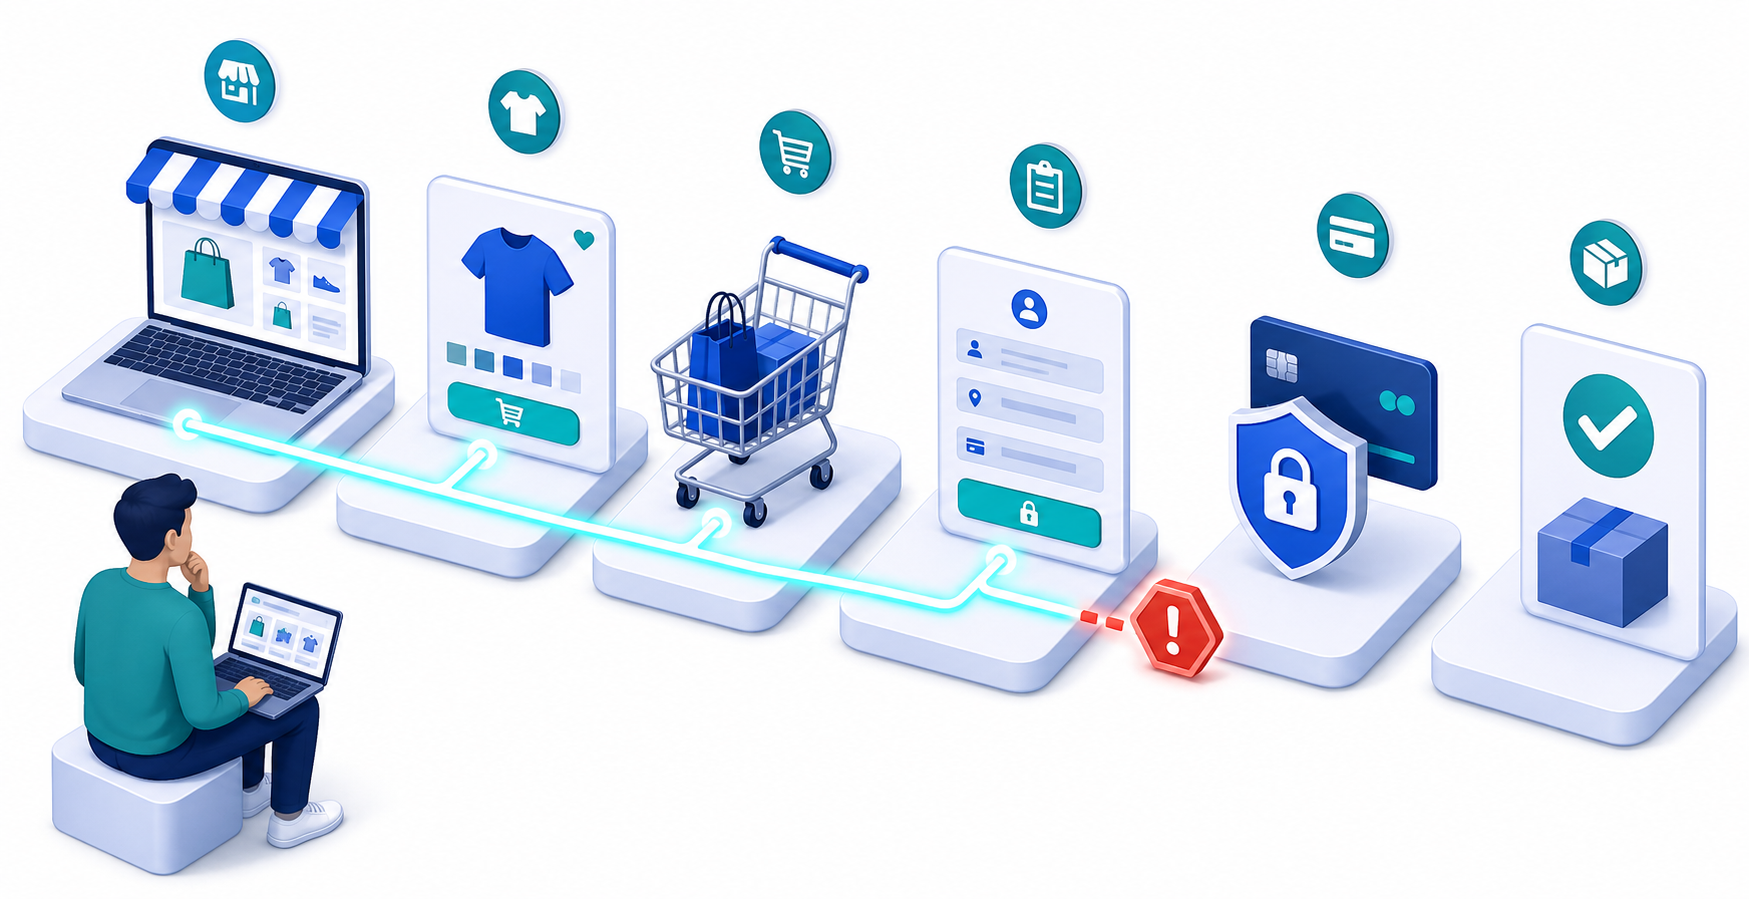
Start outside Shopify Admin. Open a private browser window and follow the same path a new customer would take: load a product page, add the product to the cart, begin checkout, and attempt to reach the final payment stage. If you operate physical locations, check Retail POS separately.
This separation matters because one service can fail while another remains usable. During the reported Tuesday disruption, Shopify acknowledged problems involving Admin and Retail POS at 9:27 a.m. EDT, while merchants and customers also encountered trouble with storefronts, checkout, and support access. Shopify was still investigating at 9:45 a.m. and reported an identified cause and improving service at 10:37 a.m. That improvement did not, by itself, prove that every merchant’s customer journey had recovered.
What you observe
What it means for your response
Admin is unavailable, but a customer can browse and complete checkout
Keep monitoring sales. Do not pause every campaign merely because store management is difficult.
Storefront loads, but checkout fails
Pause campaigns intended to produce immediate purchases and hold scheduled promotional sends.
Storefront does not load
Stop traffic whose landing pages are unavailable and publish a clear service notice on a channel you can still control.
Retail POS fails while online checkout works
Separate the retail response from the ecommerce response. Do not treat all revenue channels as unavailable.
Support is inaccessible
Maintain an internal incident log and use the platform’s available public updates without waiting for a support reply.
Assign one person to maintain the incident record. Capture what failed, how it was tested, when the failure was first confirmed, which promotions were active, and which actions the team took. This prevents several people from making conflicting campaign, site, or customer-service changes.
Control paid traffic without destroying useful evidence
If checkout cannot accept orders, each additional conversion-focused click can add cost without creating a sale. Pause the affected campaigns rather than deleting them. A pause preserves campaign settings and makes it easier to compare performance before, during, and after the interruption.
Make decisions by destination and objective. A campaign leading to a failed product or checkout path should stop. A campaign serving a functioning market, store, or non-transactional resource may not need the same treatment. The test result should decide, not the frustration of being locked out of Admin.
Record the time of every pause, budget adjustment, promotional cancellation, and restart. Add the incident window to your analytics annotations or reporting notes. Keep Shopify’s acknowledgement and recovery updates in the record, but use your own customer-path tests to define the period when your store was actually unable to convert.
Do not evaluate that window as an ordinary campaign-performance decline. Separate traffic sent during the failure from normal traffic, then reconcile ad-platform conversions with completed Shopify orders after access returns. Otherwise, automated bidding changes and human budget decisions may both react to a platform problem as though it were weak demand or poor creative.
Protect SEO, product schema and AI-facing answers
A temporary checkout failure is not an inventory change. Do not switch Product or Offer structured data to OutOfStock unless the item is genuinely unavailable. Machine-readable availability can remain visible after the checkout problem ends, leaving search engines, shopping systems, and AI assistants with an inaccurate description of the product.
Likewise, do not noindex product pages, remove canonical tags, delete URLs, or redirect the catalog to the homepage as an emergency measure. Those changes can outlive the incident and create crawling, indexing, and reporting problems that are harder to reverse than the outage itself.
If you can publish outside the affected storefront, maintain one plain-language status message. State which customer action is failing, which channels still work, and when you last verified the condition. Use the same wording in social updates, support replies, and internal scripts. Consistent public language gives customers a clearer answer and reduces the chance that search or AI systems encounter contradictory explanations.
Avoid promising a recovery time you do not control. A platform update saying that services are improving is a reason to retest, not a reason to declare your own store operational.
Restart only after a complete purchase succeeds
Recovery should be verified from the customer’s side. Restored Admin access is useful, but it does not establish that product pages, carts, checkout, payment, confirmation, and order recording are all working together.
Repeat the full purchase path in a clean browser session.
Confirm that the completed order appears where your team expects to manage it.
Check Retail POS separately if physical stores were affected.
Review the incident window for incomplete, delayed, or unexpectedly repeated customer activity before sending more promotion.
Resume campaigns in a controlled order, starting with the paths you have directly verified.
Update the public service message only after your own checks pass, and preserve the incident notes for reporting.
Once operations are stable, save a short outage runbook containing the incident owner, customer-path tests, campaign controls, analytics annotation process, and status-message template. The next Shopify disruption should trigger a familiar sequence, not a fresh argument about what to do.
If your DV360 integration assumes every returned line item or ad group belongs to a type it already recognizes, Demand Gen support creates a practical failure point. A successful API call can still break downstream processing when an unfamiliar resource reaches a strict parser, reporting job, or campaign-management rule.
You can prepare without rebuilding your DV360 workflow. Start by making reads tolerant of Demand Gen resources, then introduce write operations behind explicit controls.
What Demand Gen support changes in DV360
The Display & Video 360 API is adding support for Demand Gen line items, ad groups, and ad formats. Developers and advertisers can retrieve, create, update, and delete the supported Demand Gen resources through the API.
The important detail is not just the new write capability. Demand Gen line items and ad groups can appear alongside standard resources in existing list responses. That means an integration may encounter them even if your team has not started creating Demand Gen campaigns through the API.
Treat this as both a schema-compatibility change and a new automation opportunity. The first job is protecting current workflows. The second is deciding which Demand Gen actions you are ready to automate.
Harden every workflow that reads line items or ad groups
Begin with an inventory of anything that consumes DV360 list responses. Include campaign dashboards, data pipelines, naming-rule checks, budget monitors, approval tools, and internal interfaces. A shared API client does not guarantee that every downstream consumer handles new resource types safely.
Find closed type assumptions. Search for switch statements, enum validation, allowlists, and default branches that reject or misclassify an unfamiliar line-item or ad-group type.
Separate parsing from business eligibility. Your integration should be able to read and retain a Demand Gen resource even when a particular workflow is not authorized to act on it.
Use an explicit unsupported state. Do not silently treat an unrecognized resource as a standard line item. Record its identifier and type, skip the unsafe action, and make the event visible to operators.
Test mixed responses. Exercise the full path with standard and Demand Gen resources in the same collection. Confirm that filtering, pagination, reporting, and batch processing still complete.
Check output contracts. If your DV360 data feeds another system, make sure the receiving schema can preserve a new type instead of dropping the record or failing the entire batch.
The safest behavior is forward-compatible: accept a valid object, preserve what you understand, and block only the operation that lacks a defined rule. This contains the impact of future resource additions as well.
Add create, update, and delete operations in stages
API availability does not mean every mutation should be enabled at once. Give each operation its own release control and validation path.
Start with retrieval. Confirm that you can identify Demand Gen line items and ad groups, store them correctly, and display them without exposing unsupported controls.
Enable creation in a constrained workflow. Validate inputs before the request, record the request and resulting resource identifier, and prevent an automatic retry from creating duplicates.
Permit updates by field. Use an allowlist of fields your integration intentionally manages. Do not send a broad object copied from a read response when only one value needs to change.
Protect deletion separately. Require an explicit resource-type check, a clear ownership rule, and confirmation that the target identifier belongs to the intended advertiser and campaign.
Keep read and write permissions conceptually separate. A reporting integration may need to understand Demand Gen objects without receiving authority to modify them. A campaign-management service may need update access but no delete path.
For each mutation, log the resource type, operation, target identifier, result, and calling workflow. That record gives your team a usable trail when an automated change needs investigation.
Plan around partial rollout and mixed account availability
Use a capability gate for Demand Gen writes. If a request shows that support is unavailable, return a clear status to the operator and keep the rest of the DV360 workflow running. Do not translate an availability problem into a generic campaign failure.
Your release sequence should cover three states: no Demand Gen resources returned, Demand Gen resources returned but writes disabled, and full management enabled. Test rollback too. Turning off creation or updates should not stop the integration from reading resources that already exist.
Operational ownership matters here. Assign one person or team to review unsupported-type logs during rollout, approve write enablement, and decide when an account is ready. Without that owner, compatibility warnings tend to sit unnoticed until a scheduled job fails.
Key takeaways
Existing list queries may return Demand Gen line items and ad groups, so read compatibility comes before new campaign automation.
Parse valid resources independently from deciding whether a workflow may act on them.
Release create, update, and delete capabilities separately, with validation, logging, and operation-specific controls.
Expect mixed availability during the June 10 to June 24 rollout window and make write support capability-driven.
Keep Demand Gen reads working even when you disable mutations or roll back an automation release.
Start with one concrete check: run a mixed-resource response through every DV360 consumer you operate. Once those paths can identify, preserve, and safely skip Demand Gen objects, you have a stable base for adding campaign management at your own pace.
Your Google Ads team now faces two different kinds of time pressure. New ads may receive policy feedback while they are being created, while older reporting data can disappear once its retention window closes.
The practical response is to redesign both ends of the campaign lifecycle: make compliance part of production, then make data preservation part of routine account operations. Here is a workable system you can put in place without turning every launch or export into a special project.
Key takeaways
Responsive Search Ads can receive editorial feedback during drafting and a policy decision after saving, so policy checks should happen inside your creation workflow.
Simple, editable problems need a clear owner who can correct and resubmit them immediately. Certifications, appeals, and other complex issues need a separate escalation path.
Hourly, daily, and weekly reporting data is retained for 37 months, while monthly, quarterly, and annual reporting can remain available for up to 11 years.
Reach and frequency metrics have a three-year retention limit, so preserve them on their own schedule.
Expired data becomes unavailable through both the Google Ads interface and APIs. An API connection is not an archive unless it writes data to storage you control.
Move policy review into campaign production
The old mental model was simple: build an ad, submit it, and wait for a separate review. Real-Time Policy Reviews move feedback into the creation process. While you draft a Responsive Search Ad, Google Ads can flag editorial problems such as typos and destination-link errors. After you save it, the system can return a policy decision immediately. Ads without identified problems can move toward delivery quickly, while more complicated cases go to a post-save review screen with the issue and available next steps. The capability initially applies to Responsive Search Ads, with expansion to other campaign types planned.
That changes what “campaign ready” should mean. Your launch checklist should no longer stop when the copy and landing page are approved internally. It should stop when the saved ad has a recorded Google Ads policy outcome.
Separate editable issues from complex issues
Google divides policy problems into two useful operational groups. Editable issues are problems you can correct in the ad workflow, such as formatting errors. Complex issues may require certification, an appeal, or another process that cannot be completed by rewriting a headline. Treating both groups as the same queue creates avoidable delay.
Draft and preflight: Confirm the final URL, spelling, formatting, and required internal approvals before saving.
Read the live feedback: Correct editorial flags while the creator still has the ad open and understands the context.
Save and record the decision: Capture the policy status in your campaign tracker rather than assuming that saving means approval.
Fix editable problems immediately: Keep these with the campaign builder so a minor correction does not enter a general support queue.
Escalate complex problems: Assign one named owner for certifications, evidence, appeals, and communication with stakeholders.
Confirm delivery: Check that an approved ad has actually begun serving before declaring the launch complete.
For each exception, record the account, campaign, ad, exact policy message, first detection time, assigned owner, action taken, and final status. This small audit trail helps you distinguish recurring production mistakes from genuine policy disputes.
Build your archive around the actual retention windows
Policy feedback can shorten the time from creation to delivery. Data retention creates the opposite constraint: waiting can permanently reduce what you are able to analyze. Beginning June 1, 2026, Google Ads applies different limits based on reporting period, and data that passes those limits is no longer available in the interface or through APIs.
Reporting data
Retention period
Practical archive decision
Hourly, daily, and weekly reports
37 months
Backfill granular history first and export it continuously.
Monthly, quarterly, and annual reports
Up to 11 years
Keep these rollups for long-range reporting, but do not treat them as a substitute for granular data.
Unique users, average impression frequency per user, 7-day and 30-day average impression frequency, and frequency distribution metrics
Three years
Give reach and frequency data its own earlier export deadline.
A monthly total cannot recover the daily pattern behind it. If you use historical performance for seasonality, forecasting, anomaly analysis, client benchmarking, or cross-channel planning, preserve the smallest reporting interval you genuinely need. Do not export every possible combination without a use case; that produces an expensive archive that nobody can interpret.
Use a backfill-first export plan
Inventory dependencies: List every dashboard, forecast, scheduled report, client deliverable, and internal analysis that reads Google Ads history.
Classify the required grain: Mark each dependency as hourly, daily, weekly, monthly, quarterly, or annual. Identify any use of reach and frequency metrics separately.
Find the oldest unpreserved period: Determine where storage you control begins. The gap between that date and the oldest data still available is your backfill target.
Export the oldest granular data first: Data nearest its deletion boundary carries the greatest risk. Work forward after securing it.
Automate incremental exports: Schedule recurring extraction into storage outside Google Ads. Include monitoring so a failed job cannot remain invisible for months.
Retain raw and transformed data separately: Preserve an unchanged extract, then build cleaned reporting tables from it. This lets you correct transformation errors without attempting to retrieve expired records again.
Your stored records also need enough context to remain usable. Keep stable account and campaign identifiers, reporting dates, reporting grain, relevant dimensions, metric names, account time zone, currency context, and the extraction timestamp. Document any transformation or filtering applied after export.
Prove that the archive can replace the interface
A successful export is not the same as a reliable archive. The real test is whether another person can reproduce a familiar report after the corresponding Google Ads data is no longer accessible.
Reconcile totals: Compare stored results with the Google Ads interface for several completed periods at each reporting grain you intend to keep.
Check completeness: Look for missing accounts, dates, campaigns, dimensions, and reach or frequency fields.
Test reruns: Confirm that retrying an extraction does not silently duplicate records or overwrite valid history.
Simulate recovery: Rebuild one recurring dashboard using only the archive and its documentation.
Assign ownership: Name the person responsible for failed exports, schema changes, access control, and retention decisions in your own storage.
Record validation evidence: Save reconciliation dates, discrepancies, fixes, and approval from the report owner.
API users need to be especially careful. An automated query that fetches data on demand still depends on Google’s retention window. Continuity comes from writing scheduled extracts to independent storage, validating them, and keeping enough documentation to interpret them later.
This history may also serve people outside the paid media team. If SEO, content, finance, or leadership uses advertising trends for planning, ask what granularity they depend on before choosing what to preserve. Their needs may not be visible in the Google Ads reporting setup.
Set a 30-day operating plan
In the first week, add the post-save policy decision to your campaign launch checklist and designate owners for editable and complex issues. During the second week, inventory reporting dependencies and retention risks. Use the third week for the oldest required backfill, prioritizing granular and reach-and-frequency data. In the fourth week, automate the next extraction, reconcile it against Google Ads, and run a report using only the stored copy.
Then make both controls routine. Every campaign launch should end with a verified policy and delivery status. Every reporting cycle should end with a successful, validated export. That gives your team faster launches without sacrificing the history needed to understand what happened later.
You probably don’t need another dashboard. You need a dependable way to turn one campaign brief into coordinated channel work, bring the results back into one operating view, and move from a useful signal to an approved action without reopening every platform.
AI can shorten that loop, but only when it sits inside a clear operating system. Give it shared definitions, bounded permissions, review gates, and a record of every decision. Without those controls, AI simply produces inconsistent work faster.
Find the delay between data and action
When a campaign spans 12 channels, weekly reporting can become a chain of exports, spreadsheet repairs, naming lookups, metric reconciliation, screenshots, and explanations. The obvious cost is staff time. The more damaging cost is latency: a performance problem can continue consuming budget while the team is still assembling the evidence needed to discuss it.
Start by tracking a full working week before choosing an AI tool. Record the work as it happens, including small tasks that disappear inside a reporting block. Use one row per task and capture:
Trigger: what caused the task, such as a scheduled report, a stakeholder question, or a performance alert.
Input: the dashboard, export, brief, message, or spreadsheet you had to open.
Transformation: what you changed, matched, calculated, reformatted, interpreted, or explained.
Output: the report, recommendation, platform change, approval request, or status update produced.
Manual handoffs: every person or system that had to receive, approve, correct, or re-enter the work.
Decision unlocked: the action that became possible after the task was complete. If there was no decision, note that too.
Elapsed time and waiting time: separate hands-on effort from delays caused by missing access, stale data, unclear ownership, or approvals.
Then classify each task by the kind of work it contains. Retrieval moves information out of a channel. Reconciliation makes names and totals line up. Interpretation decides what the evidence means. Execution changes a live campaign. Explanation turns the decision into something another person can understand.
This classification reveals where AI belongs. Repeated retrieval, formatting, matching, and first-draft explanation are strong candidates for assistance. Budget choices, attribution judgments, brand claims, audience exclusions, and live publishing require tighter human control. A task can contain both kinds of work, so automate the bounded transformation rather than handing over the entire task.
Prioritize bottlenecks by their effect on the data-to-action cycle, not just by the hours they consume. Map the path as signal → review → decision → platform change → verification. A repetitive task near the beginning of that path can delay every decision downstream. Removing that delay is usually more valuable than automating a polished deliverable that nobody uses to make a decision.
Build a shared campaign contract before adding automation
Cross-channel automation needs a control plane: a small set of shared objects and rules that exist independently of any network. The central object should be a campaign contract. This is the approved record of what the campaign is trying to do and which elements must remain consistent when work moves between channels.
A practical campaign contract should identify the business objective, intended audience, offer, message, conversion event, budget guardrails, geographic scope, active period, creative concept, required claims or disclaimers, asset identifiers, owner, approval state, and canonical campaign ID. It should also distinguish fixed elements from adaptable ones. The offer may be fixed while format, length, crop, placement, and channel-specific wording remain adaptable.
The canonical campaign ID matters because network names are presentation labels, not reliable identity. Adopt a consistent naming convention across accounts, but keep a separate registry that maps every network campaign, ad group, creative, and tracking asset back to the shared campaign. This lets a shortened or platform-constrained name change without breaking the relationship.
Build a metric dictionary beside that registry. For every metric used in a cross-channel view, record its business meaning, originating system, calculation, attribution basis, refresh expectation, exclusions, and owner. Networks can use different campaign structures and attribution logic, so identical labels do not guarantee identical measurements. Keep platform-reported conversions, analytics conversions, and modeled business outcomes visibly distinct unless you have an explicit reconciliation rule.
Operating layer
Authoritative record
What AI may do
What must be controlled
Intent
Approved campaign contract
Draft channel adaptations and identify missing fields
Objective, offer, audience, claims, and approval state
Identity
Canonical campaign registry
Suggest matches between network objects and shared IDs
Ambiguous matches and changes to existing mappings
Evidence
Raw channel data plus metric dictionary
Normalize formats, flag gaps, and prepare summaries
Definitions, attribution differences, and reconciliation rules
Decision
Recommendation and approval ledger
Generate hypotheses, summarize evidence, and draft actions
Final judgment, accountable owner, and authorization
Execution
Platform change history
Prepare or queue permitted changes
Spend, publishing, targeting, deletion, and rollback
This design prevents a common failure: forcing every channel into one flattened schema and calling the result unified. Unification should make relationships visible while preserving meaningful differences. Normalize identity, ownership, dates, currencies, and approved definitions. Do not erase attribution differences or channel-specific context merely to make the spreadsheet look tidy.
Give AI bounded jobs, not vague authority
An AI assistant performs better when each job has a defined input, transformation, output, and permission boundary. Telling it to optimize the campaign mixes analysis, judgment, execution, and accountability into one instruction. That makes errors harder to detect and leaves nobody certain about what the system changed.
Write an AI work order for every automated workflow. Include:
Approved inputs: the exact campaign contract, data tables, assets, and prior decisions the job may use.
Requested transformation: the specific mapping, classification, adaptation, comparison, summary, or recommendation required.
Elements that must not change: such as the offer, conversion event, audience exclusions, brand claims, or legal language.
Output schema: the required fields and status values, including missing information and unresolved uncertainty.
Escalation rule: the conditions that should stop the workflow and send it to a named owner.
Write permissions: whether the system may only read, draft, queue for approval, or execute.
Verification step: how the team will confirm that the intended platform state matches the approved action.
For example, a creative adaptation job could receive an approved campaign contract and master asset. It may adjust length, format, placement language, and crop guidance for each channel. It must preserve the offer, approved claims, audience, and call to action. Its output should contain draft variants, assumptions, missing assets, and a review status. It should have no publishing permission.
Use deterministic rules where the answer must be exact. IDs, currencies, required fields, date formats, budget caps, and approval states should be validated by explicit logic. AI is useful when language or context is ambiguous: matching imperfect names, classifying creative themes, finding possible explanations, adapting a brief, and turning structured evidence into a readable draft. It should not quietly invent a value when an exact field is missing.
A sensible permission ladder moves from read to draft, then recommendation, approval queue, and finally limited execution. Advance a workflow only after you can reconcile its inputs, inspect its logs, identify an accountable owner, detect failures, and reverse an incorrect change. For paid campaigns, unreviewed budget or targeting changes can waste money. For owned channels, an unreviewed publishing action can expose inaccurate claims. Keep those actions behind explicit approval until the controls have proved dependable.
The goal is not to keep humans clicking every button forever. It is to reserve human attention for decisions that involve trade-offs, accountability, or material risk. The system can handle preparation and coordination while the owner approves the action and remains able to explain why it happened.
Run the operation from exceptions and decisions
A unified dashboard still leaves someone hunting for the important row. An effective operating view should instead tell you what changed, what needs attention, what decision is blocked, and whether an approved action reached the platform correctly.
Organize the working queue around four kinds of exception:
Data exceptions: failed connections, stale refreshes, missing fields, duplicate records, unmatched campaign IDs, or totals that fail an agreed reconciliation rule.
Performance exceptions: a campaign crosses a threshold that the owner defined for its objective, budget, and stage. The AI may detect the condition, but it should not invent the threshold.
Decision exceptions: the evidence supports more than one plausible action, an assumption remains unresolved, or approval is overdue.
Execution exceptions: the live platform state does not match the approved change, verification failed, or the expected result cannot be observed.
Check data health before discussing performance. A persuasive summary built from a stale connector or broken campaign mapping is still wrong. Surface the affected channels, the last successful refresh, the missing entities, and the decisions that should be paused until the evidence is repaired.
Turn every recommendation into a decision record. Capture the campaign ID, evidence considered, attribution basis, proposed action, expected effect, uncertainty, reviewer, approval status, execution status, platform confirmation, and rollback instruction. If the recommendation changes during review, preserve both the original and approved versions. This gives you a traceable chain from evidence to action instead of a collection of chat messages and overwritten spreadsheet cells.
Reporting should follow the same logic. Lead with business outcomes and material changes. Show what moved across channels, but label differences in attribution and data freshness. List actions completed, decisions required, owners, and unresolved data-quality issues. Put diagnostic detail in an appendix rather than forcing a stakeholder to infer the decision from a wall of metrics.
Agencies can also automate branded reports assembled from multiple networks. The narrative still needs controls. Generate it from the approved metric dictionary and decision ledger, require links back to the underlying evidence, and prevent the report from presenting a hypothesis as a confirmed cause. Automation should remove assembly work without hiding uncertainty.
Choose a pilot that tests the operating model
Evaluate AI-native tools against your workflow, not their most polished demo. The useful promise is a shared brief that can coordinate work across channels and a unified view that shortens the route from evidence to action. Whether a product can support that promise depends on its connectors, identity model, controls, and failure behavior.
Ask each vendor or internal team to demonstrate the following with a representative campaign:
Map network objects to your canonical campaign ID without discarding channel-specific structure.
Show the origin, refresh state, definition, and attribution basis of every reported metric.
Reconcile a channel view with its native platform under a written reconciliation rule.
Apply a change to the shared brief, preview the resulting channel adaptations, and route them through approval without publishing.
Expose every prompt, rule, recommendation, approval, and executed change in an audit trail.
Demonstrate what happens when a connector fails, a campaign is renamed, required data is missing, or two records appear to match.
Restrict permissions by role, channel, account, action type, and approval state.
Export the campaign registry, metric definitions, decision history, and reports in usable formats.
Show how a queued or completed change is stopped, corrected, or rolled back.
Begin the pilot with a frequent, reversible workflow such as weekly data assembly, exception detection, recommendation drafting, and report generation. Connect data in read-only mode first. Establish the campaign mappings and metric definitions, reconcile the output, and then allow the system to draft recommendations. Keep execution behind approval while you test whether the evidence, reasoning, and logs are good enough to support a real decision.
Measure the pilot against your own baseline. Track hands-on reporting time, waiting time, manual transfers, corrections, unmatched entities, stale-data incidents, recommendations accepted or materially changed, and elapsed time from signal to verified action. Do not substitute a vendor’s productivity claim for the bottleneck you observed in your own audit.
Pause expansion if the system cannot reproduce agreed totals, preserve attribution context, identify the evidence behind a recommendation, enforce approval boundaries, or reveal what it changed. Those are operating requirements, not optional refinements. Adding more channels before they work will multiply ambiguity.
Key takeaways
Optimize the delay from signal to verified action, not merely the time spent producing a report.
Create a shared campaign contract, canonical ID registry, and metric dictionary before automating cross-channel work.
Normalize identity and definitions while preserving genuine differences in channel structure and attribution.
Give AI bounded transformations, explicit inputs, structured outputs, escalation rules, and the minimum necessary permissions.
Run daily work from data, performance, decision, and execution exceptions rather than scanning every dashboard.
Test a read-only, approval-gated workflow against your own baseline before allowing broader execution.
On your next reporting cycle, start the task log before opening the first platform. Use what it reveals to write the campaign contract and select one approval-gated workflow. Once that workflow can move from clean evidence to a verified action with a complete record, you have something worth extending to the next channel.