Tag: Campaign Management

  • How to Build a Paid Search Optimization System That Learns

    How to Build a Paid Search Optimization System That Learns

    Your paid search account is probably not short of prompts to act. The harder problem is deciding which recommendation deserves budget, whether an automated result represents added business value, and how to preserve what your team learned after the interface changes.

    You need more than a collection of campaign tools. You need an operating system that connects operator skill, controlled execution, and credible measurement. That system lets you move quickly without treating every platform suggestion as an instruction.

    Key takeaways

    • Give every tool one clear job: build capability, execute a change, or verify its effect.
    • Record the hypothesis, baseline, spending limit, success metric, and rollback condition before applying a recommendation.
    • Treat platform-reported incremental lift as decision support. Compare it with the marginal cost and the business value of the added outcomes.
    • Turn Performance Max training into reusable launch and troubleshooting checklists instead of leaving the knowledge inside a course.
    • Manage additional Shopping images as structured feed data and test them against a defined commercial outcome.

    Build your optimization stack around decisions, not features

    A paid search tool earns its place when it helps you make a specific decision. A new dashboard, recommendation, feed field, or course is not automatically useful just because the platform makes it available.

    Separate your stack into capability, execution, and evidence. The separation matters because no single platform surface should be expected to train the operator, make the change, and deliver the final commercial verdict.

    LayerTools and resourcesDecision it should support
    CapabilityApplied Performance Max courses, scenarios, checklists, and reference materialCan the operator configure, review, and troubleshoot the campaign reliably?
    ExecutionCampaign controls, recommendation workflows, and product-feed image fieldsWhat exactly will change in the account, and which campaigns or products will be exposed?
    EvidenceRecommendation impact reporting, change records, and business performance dataDid the change create enough additional value to justify its cost?

    This model exposes gaps that a tool inventory can hide. A credential can support operator development, but it cannot establish campaign profitability. A recommendation can identify an opportunity, but it cannot decide how much financial exposure your business will accept. A results view can estimate added conversions, but it cannot repair an incorrect conversion action or an inflated conversion value.

    For each tool, write down its owner, required inputs, output, and resulting decision. If nobody can name the decision, the tool is adding interface activity rather than optimization capacity. If the same platform proposes a change, applies it, and scores it, add an independent business guardrail such as allowable acquisition cost, margin, qualified-lead rate, or incremental return on ad spend.

    Put every automated recommendation through an evidence gate
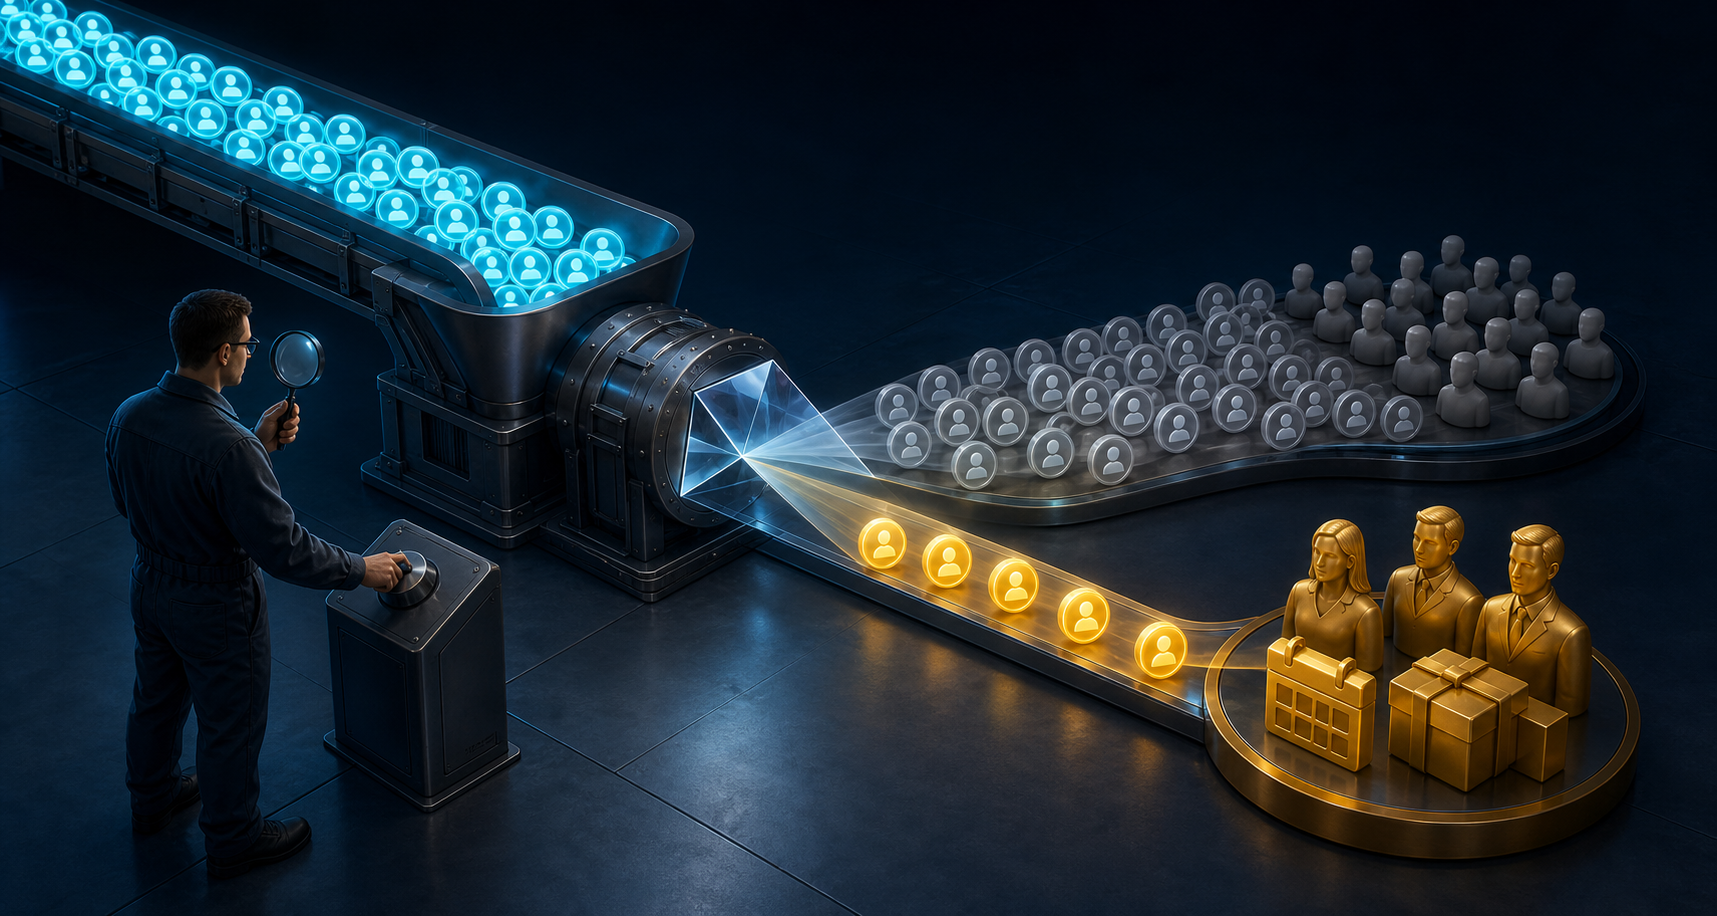
    An analyst operates a transparent inspection gate that tests glowing recommendation tiles before a few are allowed to reach a regulated budget reservoir.

    Automated recommendations are hypotheses generated from the platform’s view of the account. They may be useful hypotheses, but accepting one still changes real bids, targets, or budget. A projected improvement is not the same thing as measured incremental value.

    Google Ads is testing a Results area that adds a useful verification layer. For an applied bid or budget recommendation, the system analyzes performance one week later and compares the outcome with a baseline estimate. Its reporting uses a seven-day rolling average measured over the 28 days after the recommendation, organizes results around Budget and Target changes, and focuses on the campaign’s primary bidding objective: clicks, conversions, or conversion value.

    Availability should not be assumed because the Results area is an early pilot. The operating principle still applies in accounts without it: define the expected effect before the change, preserve the starting state, and return after a declared observation window.

    Before you apply a recommendation, add this record to your campaign log:

    • Recommendation: The exact budget, bid, or target change and every campaign it affects.
    • Hypothesis: The outcome expected to increase and the mechanism that should produce it.
    • Baseline: Current spend, the primary bidding objective, and the business metric used to judge quality.
    • Exposure limit: The maximum additional spend or efficiency deterioration you have approved.
    • Observation window: When you will evaluate the change and why that period is suitable for the available reporting.
    • Rollback condition: The result that will cause you to reverse or revise the change.
    • Confounders: Promotions, tracking changes, feed edits, landing-page releases, or other campaign changes that could affect the comparison.

    The exposure limit is not paperwork. Raising a budget can spend more money without producing proportionate business value. Set the limit before approval so a promising platform forecast cannot become open-ended authority to spend.

    When results arrive, separate volume from efficiency. Additional conversions can be valuable even if average campaign efficiency changes, but only when their marginal economics work. Calculate incremental cost per acquisition as additional cost divided by additional conversions. Calculate incremental return on ad spend as additional conversion value divided by additional cost. If clicks are the bidding objective, do not treat extra clicks as revenue; follow them through to the business outcome that justified buying the traffic.

    The baseline in the Results area is an estimate, not direct observation of what the same campaign would have done without the change. Seasonality, promotions, competitor activity, measurement changes, and delayed conversions can still complicate interpretation. Use the reported lift as evidence, then ask whether the direction appears in your business data and whether any concurrent change offers a better explanation.

    Turn Performance Max training into campaign infrastructure

    Performance Max optimization often becomes account folklore: one person knows how the setup was built, another remembers why a target changed, and nobody has a stable troubleshooting sequence. Training is most valuable when it removes that dependence on memory.

    Microsoft Advertising’s applied learning path provides a useful progression: foundations, guided hands-on setup, and advanced scenario-based implementation and optimization. The advanced course includes checklists, videos, reusable reference material, and contextual support through Help me understand during an assessment. Completion can also lead to a shareable Performance Max badge through Credly.

    Use that progression to create internal operating assets:

    • From foundations, create a shared glossary. Define each objective, target, status, input, and output in the language your team uses when approving spend.
    • From setup training, create a launch checklist. Require the campaign objective, conversion action, budget authority, target, product or asset inputs, owner, and first review point to be documented before launch.
    • From advanced scenarios, create a troubleshooting tree. Start with the observed symptom, list the measurement and input checks that could explain it, and identify the smallest reversible action for each branch.
    • From reference material, create account notes. Link each live setting to the reason it was chosen so the next operator does not have to infer strategy from configuration alone.

    Do not measure training only by course completion. Ask the operator to review a live configuration, identify one defensible change, explain the evidence required to keep it, and state the rollback condition. That exercise connects knowledge to account control without pretending that a credential proves commercial performance.

    Reusable artifacts also make optimization safer when ownership changes. The campaign retains its operating history, and a new manager can distinguish a deliberate constraint from an overlooked default.

    Treat multi-image Shopping ads as a feed experiment

    Shopping creative is partly a feed-management problem. If you treat additional images as an informal upload task, you lose control over image purpose, product coverage, and measurement.

    Microsoft Advertising’s multi-image Shopping format uses the optional additional_image_link attribute for as many as 10 comma-separated images. Those images can appear with the product’s price and retailer information, giving shoppers more visual context before the click.

    The existence of 10 available image slots does not mean every product needs 10 images. Each image should resolve a meaningful pre-click uncertainty. An alternate angle can clarify shape. A detail view can reveal construction or a feature. A variation image can help a shopper understand an option that the primary image cannot show clearly. Repetitive images consume feed space without adding equivalent information.

    Use this rollout sequence:

    1. Select a coherent product group. Start with items for which extra views communicate material information, not an arbitrary mix of the catalog.
    2. Assign every image a role. Record whether it shows an alternate angle, close detail, style, color, or another useful distinction.
    3. Validate the feed. Check that image links resolve, remain attached to the correct product, follow the intended order, and agree with the corresponding landing page.
    4. Declare the commercial outcome. Choose the metric that would justify expansion, such as qualified click-through, purchase rate, conversion value, or revenue per click.
    5. Protect the comparison. Avoid changing the same products’ bids, titles, prices, landing pages, and image sets at once. If your account structure permits it, compare a defined rollout group with a similar unchanged group.
    6. Expand only after the whole path improves. A higher click-through rate is not sufficient when the added visits convert poorly or produce weak value.

    This turns a creative feature into a testable merchandising decision. It also gives your feed team a clear rule for future images: add visual information that helps a shopper decide, then keep it only when the downstream result supports the added complexity.

    Use one repeatable loop for every campaign change
    A campaign specialist moves a glowing token around a circular workbench with stations for observation, testing, controlled change, comparison, and archiving.

    Your review process should remain stable even when platforms introduce new controls. A durable optimization loop looks like this:

    1. Start with the business decision. State whether you are trying to acquire more acceptable customers, recover efficiency, improve lead quality, or increase valuable product sales.
    2. Verify the measurement input. Confirm that the campaign’s primary objective represents the outcome you intend to optimize and that the business can interpret it consistently.
    3. Select one intervention class. Choose a budget change, target change, campaign setup correction, or creative-feed change. Separating change types makes the result easier to interpret.
    4. Write the hypothesis and guardrails. Define the expected movement, allowable spending exposure, observation window, and rollback condition.
    5. Apply the change and preserve context. Save the previous setting, implementation date, affected scope, owner, and any concurrent activity. Where Google’s pilot reporting is available, account for its 28-day measurement design rather than forcing an earlier conclusion from incomplete reporting.
    6. Evaluate platform lift and business economics separately. First determine whether the platform’s primary outcome moved. Then determine whether the additional cost produced acceptable downstream value.
    7. Turn the result into a reusable rule. Keep, revise, or reverse the change, and record what future operators should do when the same conditions appear again.

    A compact decision record needs only the campaign, owner, date, starting state, changed setting, hypothesis, spending limit, primary platform objective, business metric, observation window, result, and next action. Keep that record outside any temporary recommendation card so it remains available after the interface or account ownership changes.

    At your next account review, open the decision log before the recommendations queue. Pick one constrained problem, choose the tool that fits its layer, and define the evidence required to close the decision. That is how optimization becomes cumulative learning instead of a sequence of disconnected clicks.
    References

  • Google Ads Campaign Diagnostics: A Practical Workflow

    Google Ads Campaign Diagnostics: A Practical Workflow

    Your Google Ads account can look healthy while it produces less useful business. Conversion volume rises, cost per conversion falls, or a campaign spends its full budget, yet qualified leads, profitable orders, or product coverage move in the wrong direction.

    Random setting changes make that problem harder to diagnose. Use a fixed order instead: verify the outcome Google Ads is pursuing, check whether the right products can enter the right campaigns, investigate where lead quality breaks down, and test one plausible correction at a time. That sequence separates a measurement problem from a coverage problem, a traffic problem, and a genuine campaign-performance problem.

    Begin with the result Google Ads is being taught to pursue

    Before inspecting bids, assets, audiences, or budgets, ask one question: if this campaign generated more of its selected conversion, would the business actually want more of it?

    A form submission may be easy to count, but it isn’t necessarily a useful lead. A low cost per lead can hide bot submissions, disposable email addresses, people outside your service area, or prospects who never qualify. When those submissions are treated as successful conversions, automation has a reason to find more people who behave the same way.

    That creates a common diagnostic trap. The campaign appears to be improving against the metric shown in Google Ads while deteriorating against the outcome recorded in the CRM. The platform and the sales team aren’t necessarily contradicting each other; they are measuring different stages of the same journey.

    1. Name the commercial outcome. For lead generation, that might be a sales-qualified lead or a closed-won customer. For a product campaign, it is an order that supports the revenue or profitability objective, not merely product exposure.
    2. Map the conversion chain. Write down the observable stages between an ad interaction and the commercial outcome: form submission, booked meeting, qualified lead, and closed-won customer, for example.
    3. Identify the signal used for optimization. Confirm whether bidding is learning from the final business outcome, an intermediate event, or an easy top-of-funnel action.
    4. Connect downstream outcomes where possible. Accurate CRM tracking and offline conversion imports can give Google Ads information about sales-qualified and closed-won leads instead of treating every form fill as equally valuable.
    5. Compare platform and CRM performance by campaign. Look for campaigns where conversion volume improves but acceptance, qualification, or sales deteriorate. That divergence is evidence of a quality problem, not proof that you need a new bid strategy.

    Performance Max is especially sensitive to the signal you supply. If the selected goal rewards an easy conversion, the campaign may pursue cheaper conversions without improving the pipeline. Optimizing toward sales-qualified or closed-won outcomes gives the system a closer representation of what the business values.

    If you cannot send reliable downstream data back yet, don’t disguise the limitation. Keep platform conversions and CRM-qualified outcomes side by side in your reporting. You can still diagnose the gap, but you should not interpret a falling cost per form fill as conclusive business improvement.

    Trace product eligibility before changing bids or budget

    Unbranded products travel along a conveyor through campaign eligibility gates, while several items stop because of missing or mismatched attributes.

    When a Shopping or Performance Max product isn’t generating expected results, start with eligibility. A product that cannot enter the intended campaign will not be rescued by a larger budget. Conversely, a product included in several campaigns may create an ownership and budget-control problem that aggregate campaign reports obscure.

    The Products section can now show which campaigns each product is eligible and not eligible for. Its product table includes status, issues, and priority flags; filters help isolate relevant groups; a line graph summarizes campaign-status trends; and the product-level panel exposes campaign eligibility without requiring you to reconstruct it from separate campaign views.

    1. Choose a product group with a clear expected destination. Start with a brand, category, margin group, or set of priority products that should belong to a particular Shopping or Performance Max campaign.
    2. Filter the Products view. Narrow the account until you can compare expected coverage with actual eligibility rather than scanning a mixed catalog.
    3. Open individual product details. Review the eligible and not-eligible campaign lists, then inspect the product status, reported issues, and priority information.
    4. Classify the mismatch. Decide whether the product is missing from an expected campaign, included in an unintended campaign, or eligible as designed but simply not receiving useful results.
    5. Correct coverage before performance settings. Resolve the status, issue, or campaign-ownership problem first. Only investigate bidding, creative, demand, and budget once you know the product can participate where intended.
    6. Use the trend view after changes. Watch for a broader eligibility shift instead of checking only the individual product that first exposed the problem.
    What you seeWhat it indicatesWhat to do next
    A product is absent from the expected campaign’s eligible listA coverage or eligibility problem exists before bidding beginsInspect its status, issues, and campaign setup
    A product appears in several campaigns unexpectedlyCampaign ownership is unclear or overlappingDecide which campaign should own the product and remove unintended coverage
    A product is eligible in the intended campaign but produces no useful resultEligibility is working; the cause lies later in delivery or conversionInvestigate demand, bids, assets, landing experience, and economics
    Eligibility trends change across a larger product groupThe problem may be systematic rather than product-specificIdentify the affected group and compare the shift with recent account or catalog changes

    Eligibility is a prerequisite, not a promise of impressions, clicks, or sales. That distinction matters. Once coverage is correct, a lack of results becomes a performance question. Until then, performance adjustments are aimed at the wrong layer of the account.

    Separate conversion volume from lead quality in Performance Max

    A stream of conversion tokens passes through a sorting funnel and separates into many low-quality contacts and fewer qualified customers and purchases.

    Performance Max can reach people across Search, Display, YouTube, Discovery, and Gmail. That reach gives automation more ways to find conversions, but it also creates more routes to low-intent or spam-driven submissions when the account rewards every captured lead equally.

    Diagnose poor lead quality as a chain. The ad attracts a person, campaign settings decide where and when the opportunity can occur, the form determines who can submit, and the conversion setup tells Google which submissions count as success. A weakness at any one of those points can make the final campaign metric misleading.

    Locate where poor-quality leads enter the process

    1. Define an accepted lead. Use the criteria your sales process already applies, such as serviceable geography, valid contact information, relevant need, and sufficient qualification.
    2. Record rejection reasons. Separate bots, invalid contact details, disposable email addresses, irrelevant inquiries, budget mismatch, and leads that fail another known qualification requirement.
    3. Compare those reasons by campaign. A concentrated pattern points to a campaign-level problem. A pattern spread across all paid and unpaid traffic may point to the form or site rather than Performance Max alone.
    4. Compare captured, qualified, and closed outcomes. This shows whether quality is breaking immediately after submission, during qualification, or later in the sales process.
    5. Choose a correction that addresses the observed failure. Bot submissions call for form protection. Geographic mismatch calls for tighter location focus. A weak optimization signal calls for better downstream conversion data.

    Add guardrails at four levels

    A useful intervention changes the inputs that determine who can convert or what the system learns from a conversion. The strongest lead-quality controls for Performance Max fall into four groups:

    • Conversion goals: Prefer sales-qualified, closed-won, or another reliable downstream outcome over an undifferentiated form fill. Maintain accurate CRM and offline conversion tracking so the distinction reaches the campaign.
    • Audience inputs: Use high-value signals tied to meaningful behavior, such as people who booked a meeting, rather than treating every previous converter as equally useful. Customer Match can help the system learn from known customers, while irrelevant audience segments should be excluded where the campaign setup permits it.
    • Campaign boundaries: Apply brand exclusions when brand traffic would distort the campaign’s role. Concentrate on productive geographies and schedules, examine search themes for mismatched intent, and use sitelinks to direct people toward relevant destinations.
    • Form quality: Add reCAPTCHA to deter bots, validate fields, block disposable domains when that rule fits your legitimate audience, and ask qualification questions that sales can use. Budget fit or how the prospect heard about the company can reveal whether a submission belongs in the pipeline.

    Form friction needs judgment. Every extra rule can reject a bad submission, but it can also obstruct a legitimate prospect. Tie each validation rule or question to a rejection pattern you can actually see. A field that no one uses to qualify, route, or follow up on a lead is merely extra work for the visitor.

    Do not mistake volume levers for quality controls

    Switching bid strategies, adding assets, or increasing budget may change reach, conversion volume, or cost. None inherently teaches the campaign what a qualified lead is. Treating them as primary lead-quality fixes can scale the existing problem.

    This doesn’t make those levers useless. It means their purpose must match the diagnosis. Add budget when a campaign is producing economically useful demand and is constrained from capturing more of it. Test assets when the message or creative is the suspected problem. Change bidding when the bid strategy itself conflicts with the campaign objective. If the underlying issue is that cheap junk leads are being counted as success, repair the success signal first.

    Turn account changes into controlled experiments

    Google Ads can surface ready-to-run experiments based on account setup and performance data. Suggested tests may cover bidding, creative variations, or campaign features, and their configurations can be adjusted before launch. Final URL expansion is one example of a feature Google may propose testing.

    A preconfigured experiment removes setup work; it does not establish that the recommendation fits your objective. Treat every recommendation as a hypothesis. If you cannot state what problem it is meant to solve, don’t spend budget testing it yet.

    Write the decision before launching the test

    1. State the diagnosis. Describe the observed problem in business terms, such as weak qualified-lead volume, poor product coverage, or inefficient revenue generation.
    2. Name the change. Specify the single material difference between the existing setup and the experiment.
    3. Select the primary outcome. For lead generation, use qualified or closed outcomes when available. For commerce, use the revenue or profitability measure that governs the campaign.
    4. Choose guardrails. Identify what must not deteriorate, such as lead acceptance, total useful volume, or spending efficiency.
    5. Explain the mechanism. Write why the proposed change should affect the chosen outcome. This exposes tests that are merely settings in search of a problem.
    6. Define the decision. Decide in advance what evidence would support rollout, rejection, or further investigation.

    Keep the test narrow enough that its result is interpretable. If you change bidding, creative, destinations, audience inputs, and conversion goals together, a better result will not tell you which change helped. A worse result will be equally difficult to reverse intelligently.

    Inspect automated recommendations for hidden scope changes

    Some recommendations alter more than a visible setting. A final URL expansion test, for example, can change which pages receive traffic. Before launch, inspect the pages that could become destinations and ask whether their message, conversion path, and audience fit the campaign. Evaluate the experiment against qualified outcomes or useful orders, not merely the extra traffic or top-of-funnel conversions it may generate.

    Recommended bidding and creative experiments deserve the same scrutiny. Confirm the campaign objective, conversion action, scope, and guardrail metrics. Edit a suggested configuration when it doesn’t match the business question. The convenience of a prepared setup is valuable only after the design is valid.

    Read experiment results at the same depth as the diagnosis

    If the original problem was lead quality, a rise in platform conversions is not enough to declare a winner. Follow those conversions through qualification and, when the available data supports it, through closed outcomes. If the problem was product coverage, verify that the affected products became eligible in the intended campaign before interpreting later sales performance.

    • If platform conversions improve but qualified outcomes do not, the experiment failed the business objective.
    • If quality improves while useful volume falls, decide whether the remaining economics support the tradeoff rather than calling the result universally good or bad.
    • If results are inconclusive, do not roll out the change solely because Google recommended it.
    • If business outcomes and guardrails improve, expand carefully and continue watching the downstream metric that justified the decision.

    Key takeaways

    • Start diagnostics with the commercial outcome, not the most prominent Google Ads metric.
    • Compare ad-platform conversions with CRM-qualified and closed outcomes before concluding that lead generation is improving.
    • For Shopping and Performance Max products, verify campaign eligibility and unintended overlap before changing bids or budget.
    • Improve Performance Max lead quality through better conversion signals, audience inputs, campaign boundaries, and form controls.
    • Do not expect a bid-strategy switch, more assets, or more budget to repair a weak definition of success.
    • Use recommended experiments as editable hypotheses, and judge them against the business result that triggered the test.

    Open the account with one documented symptom, not a general intention to optimize. Trace that symptom to its first broken layer, make the smallest change that addresses the cause, and preserve the result as evidence for the next decision. That is how account maintenance becomes diagnosis instead of guesswork.

    References

  • How to Build a Paid Media Operating Structure That Scales

    How to Build a Paid Media Operating Structure That Scales

    You can have capable campaign managers, active ads and polished dashboards while paid media quietly loses its ability to drive growth. The warning sign is not always a dramatic drop. It is often a long stretch in which spend and activity continue, but pipeline stops moving.

    Adding another specialist or changing agencies will not resolve that plateau if ownership, measurement and experimentation remain unclear. You need an operating structure that turns business outcomes into campaign decisions, gives execution teams useful feedback and exposes the strategy to regular challenge.

    Replace the org-chart question with an ownership model

    The familiar choice between an internal team and an agency hides the more consequential question: who owns performance direction, and how often is that direction challenged?

    Campaign execution is only one part of the job. A durable paid media operation separates four accountabilities, even when a small team combines several of them in the same role:

    • Business outcome ownership: Someone with authority defines what paid media must contribute to pipeline or revenue, which customer segments matter and what economics the business can accept.
    • Performance direction: A named leader translates those goals into channel roles, budget priorities, measurement requirements and a testing roadmap.
    • Campaign execution: Channel operators build, monitor and adjust campaigns while documenting what changed and why.
    • Independent challenge: A qualified person outside the daily workflow questions assumptions, identifies structural weaknesses and brings perspective from other accounts, markets or growth stages.

    These are accountabilities, not a headcount plan. One person may cover more than one role. The important constraint is that performance direction cannot belong vaguely to the marketing department, an agency or a committee. A single owner must be able to make or escalate the decision.

    Test your current structure by asking the performance owner to answer the following questions without assembling an emergency meeting:

    1. What business result is paid media expected to change?
    2. What is preventing the account from producing more of that result now?
    3. Which decision is currently being tested?
    4. What evidence would cause us to maintain, change or stop the current approach?
    5. Who has authority to act when that evidence arrives?

    If the answers come back as platform metrics, disconnected tasks or conflicting opinions, the problem is not simply campaign optimization. The operating model has no clear path from business intent to action.

    Make measurement a feedback loop, not a reporting layer

    Three marketing specialists observe and adjust a circular workstation linked by an illuminated feedback path.

    A dashboard can describe activity without helping anyone improve it. Paid media needs a feedback loop that carries business outcomes back to the people and systems making campaign decisions.

    Build that loop in layers. Leadership needs pipeline and revenue evidence. The performance leader needs measures that show whether the channel is creating qualified demand at acceptable economics. Campaign platforms need conversion signals that are frequent, accurate and meaningfully related to the business outcome.

    Those layers should connect, but they should not be treated as interchangeable. A form submission can help a bidding system react quickly, for example, while still being too early to prove pipeline quality. Conversely, a closed sale may be commercially decisive but arrive too late or too infrequently to guide every campaign adjustment. Your structure must state which signal serves which decision.

    Create a measurement map for every conversion event used in reporting or optimization. Record:

    • The customer action being captured.
    • The business stage that action is meant to represent.
    • The system in which the event originates.
    • The campaign, click or audience data that travels with it.
    • The CRM status or downstream result that confirms quality.
    • The destination receiving the signal, including any advertising platform using it for optimization.
    • The person responsible for detecting and repairing a broken data path.
    • The budget or campaign decision the metric is allowed to influence.

    This exercise exposes a common structural failure: the marketing platform records a conversion, but the CRM cannot reliably connect that action to a qualified opportunity or revenue outcome. The campaign team then receives a weak signal, leadership receives a partial story and both groups optimize different versions of performance.

    Do not hide that gap by adding more charts. Mark the affected metric as incomplete, identify the missing connection and limit the decisions it can support until the data path is repaired. Otherwise, greater automation can amplify the wrong behavior because the system is being rewarded for the easiest visible action rather than the outcome the business values.

    Your leadership view should therefore show more than spend and lead volume. At minimum, it should make the following visible together:

    • Spend against the authorized budget.
    • Qualified pipeline and revenue under the organization’s agreed attribution approach.
    • Movement between the lead, qualification, opportunity and customer stages the business actually uses.
    • Known tracking gaps, data delays and attribution limitations.
    • Material campaign or measurement changes that affect interpretation.
    • The next decision, its owner and the evidence still required.

    The goal is not to claim perfect attribution. It is to make uncertainty explicit enough that the team can still decide responsibly.

    Protect testing capacity and turn reviews into decisions

    Campaign prototypes sit in separate testing lanes while a team selects an option at a nearby decision table.

    Maintenance work expands to fill the team’s available capacity. Search terms need review, creative needs refreshing, budgets need pacing and stakeholders need answers. If experimentation is treated as whatever happens after those tasks, the account may remain orderly while its growth logic goes untested.

    Separate routine optimization from experimentation. Routine optimization applies established operating rules, corrects defects or restores an expected standard. An experiment addresses a meaningful uncertainty and produces evidence for a future decision. Renaming ordinary account changes as tests does not create a learning program.

    Every proposed experiment should have a short brief containing:

    • Constraint: The business or funnel problem limiting performance.
    • Hypothesis: The reason a specific change may relieve that constraint.
    • Change: The variable being altered, with unrelated variables kept as stable as practical.
    • Decision metric: The result that determines whether the idea should influence future investment.
    • Guardrails: The outcomes that must not deteriorate while the primary metric improves.
    • Evidence requirement: The conditions needed before the team interprets the result.
    • Decision: The actions available when the evidence is favorable, unfavorable or inconclusive.
    • Owner: The person responsible for execution, interpretation and documentation.

    Start the backlog with the current business constraint, not with a platform feature the team wants to try. If qualified pipeline is weak, determine whether the likely constraint is audience fit, message, offer, conversion path, sales follow-up, measurement or something else. That diagnosis tells you what deserves testing. It also prevents the team from changing targeting, creative, bidding and landing pages at once, then being unable to explain the result.

    Many well-designed experiments will not produce an improvement worth scaling. That is not a reason to avoid testing. It is a reason to demand a useful decision from each test. An unfavorable result can still eliminate a bad assumption, narrow the next question or prevent a larger budget mistake.

    Performance reviews should use the same discipline. Replace the dashboard tour with a decision sequence:

    1. State which business outcome changed or failed to change.
    2. Identify the funnel and campaign signals that help explain it.
    3. Separate confirmed evidence from plausible interpretation.
    4. Name the current constraint and the decision it creates.
    5. Assign the action, evidence requirement and next review point.

    Match the review cadence to the feedback available. Execution signals may support frequent checks, while qualified pipeline or revenue may require a longer observation window. Do not demand final proof faster than the buying process can produce it. But do not use a long sales cycle as an excuse to ignore leading indicators, tracking health or obvious execution problems.

    End each review with a decision log. The outcome might be to continue, stop, scale, narrow, repair measurement or gather more evidence. If the meeting produces only observations and follow-up analysis, performance ownership is still unresolved.

    Use external expertise without splitting strategy from execution

    An external partner can provide pattern recognition, technical scrutiny and a challenge to assumptions that have become normal inside the business. That advantage disappears when the partner is asked to improve campaigns in isolation or when internal and external teams operate from different definitions of success.

    A hybrid structure works when each side retains the decisions it is equipped to make.

    The internal team should retain ownership of:

    • Business goals, commercial constraints and budget authority.
    • Customer, product, market and sales-process context.
    • The organization’s definitions of a qualified lead, opportunity and acceptable customer.
    • Access to CRM outcomes and the teams responsible for acting on demand.
    • Final decisions about risk, investment and strategic priorities.

    An external performance leader or specialist can be accountable for:

    • An independent assessment of account, measurement and integration structure.
    • Challenging whether platform recommendations serve the business objective.
    • Bringing relevant patterns from other accounts and growth stages without assuming those patterns automatically apply.
    • Turning observed constraints into a disciplined testing roadmap.
    • Explaining tradeoffs and structural risks in language leadership can use.
    • Reviewing whether campaign execution still reflects the agreed strategy.

    The performance owner sits across that boundary. This person does not forward agency reports to leadership or pass leadership requests to channel operators. They reconcile business context, external challenge and campaign evidence into a decision.

    Watch for signs that the hybrid model has become a handoff chain:

    • The partner reports platform conversions while the internal team separately reports pipeline.
    • Campaign operators receive tasks but cannot explain the commercial priority behind them.
    • The internal team withholds CRM or sales context, then judges the partner on revenue.
    • Strategy appears in presentations but does not change budgets, account structure or the testing backlog.
    • No one has authority to resolve conflicting interpretations of performance.
    • The partner’s work is never subjected to an informed internal or independent review.

    External support is most useful before confidence collapses. Bring it in when measurement is being designed, a new channel is being prepared, a plateau is emerging or a larger budget decision requires independent scrutiny. Waiting until leadership has already decided the channel does not work leaves less room to repair the structure and gather credible evidence.

    Key takeaways

    • Paid media needs a named performance owner with authority to connect business goals, measurement, budget and campaign decisions.
    • Business outcomes, decision metrics and platform optimization signals serve different purposes; map how they connect before relying on them.
    • Protect experimentation from routine campaign maintenance, and require every test to answer a consequential question.
    • Run performance reviews around constraints and decisions rather than collections of metrics.
    • Use external expertise to challenge strategy and structure while keeping business context and commercial authority inside the organization.

    At your next paid media review, make one structural change before asking for another campaign tactic. Name the performance owner, choose the most important measurement gap or growth constraint, and record the decision the team must make next. That creates a working feedback loop. Once it exists, better execution has somewhere useful to go.

    References

  • Google Ads API v23: A Practical Upgrade Plan for 2026

    Google Ads API v23: A Practical Upgrade Plan for 2026

    Your Google Ads integration may be stable, but that does not make the v23 decision automatic. You need to know whether upgrading will close a real operational gap: opaque Performance Max reporting, difficult invoice reconciliation, date-only scheduling, fragmented store data or an audience workflow that still depends on manual interpretation.

    Google Ads API v23 brings those changes into the same release, while also beginning a faster API release cycle for 2026. The practical response is not to adopt every feature at once. It is to connect each capability to a decision, migrate the safest read paths first and put tighter controls around anything that can change targeting, schedules or spend.

    Choose the upgrade scope from the decisions you need to improve

    Start with the workflow that consumes the data, not the endpoint that exposes it. A feature has upgrade value only when someone can name the decision it will improve, the current workaround it will replace and the failure you need to prevent.

    v23 capabilityDecision or workflow it can improveFirst acceptance test
    Performance Max breakdown by ad network typeExplaining where campaign results are occurringSegmented values reconcile with the unsplit control query for every additive metric you publish
    Campaign-level invoice details, regulatory fees and adjustmentsBilling reconciliation and client cost allocationEvery amount remains traceable to its original charge type instead of being forced into media spend
    Campaign start and end date-timesPrecise launch, promotion and shutdown schedulingA controlled write-read test preserves the intended date, time and governing timezone convention
    PerStoreView location detailsStore-level reporting and local performance analysisThe account and location scope agrees with the corresponding Stores report
    LIFE_EVENT_USER_INTERESTLife-event dimensions in audience insight workflowsThe new dimension survives extraction, storage and review without being collapsed into a generic interest label
    Surface-specific Demand Gen conversion-rate forecastsPlanning separately for placements such as Gmail and ShortsSurface remains part of the forecast key through the planning layer
    Free-text descriptions converted into structured audience attributesDrafting audience definitions from a strategist’s briefThe generated attributes are visible, validated and approved before downstream use
    Additional Shopping competitive and conversion-date metricsCompetitive analysis and conversion reportingEvery metric carries its date basis and aggregation rule into the dashboard

    This map also exposes ownership. Performance Max and Shopping changes usually begin with analytics engineering. Invoice changes require a finance or billing consumer. Date-time scheduling belongs to the team that owns campaign mutations. Audience generation needs both a technical owner and the person accountable for targeting decisions.

    A low-risk migration sequence starts on the read side. Capture representative outputs from your existing integration, upgrade the required client libraries and code in an isolated path, add one v23 capability, and compare its result with your control data. Move write operations only after your storage, validation and monitoring layers understand the new values.

    1. List every query, scheduled job, report, billing export and campaign writer affected by the upgrade.
    2. Record the account scope, selectors, reporting window and downstream consumer for each path.
    3. Capture baseline responses and the totals currently shown to users.
    4. Upgrade the client dependency and generated types without changing business logic in the same step.
    5. Add one v23 capability behind a separately testable query or writer.
    6. Define a reconciliation rule, an owner and a rollback condition before releasing it.
    7. Keep the old output available until the new consumer passes both data and operational checks.

    Rebuild reporting around the new data grain

    An analyst examines an opaque campaign object as it passes through a prism and separates into distinct reporting components.

    The reporting additions are useful because they expose distinctions that were previously difficult to retrieve. They can also break a pipeline that assumes one row per campaign, one meaning for a date or one reporting grain across every metric.

    Performance Max network breakdowns need a new row key

    Google Ads API v23 adds an ad-network-type breakdown for Performance Max reporting. Once that segment enters a result, a campaign can occupy more than one row. Any transformation keyed only by campaign can overwrite rows, duplicate joined values or accidentally recombine the split before an analyst sees it.

    Add the network dimension to the unique key at ingestion. Then run a paired query: one result at the original campaign grain and one with the network split. Reconcile metrics that your reporting contract treats as additive. For ratios and calculated metrics, recompute from their underlying components where your data model supports that; do not sum percentages merely because they arrived in separate rows.

    Label the output narrowly. A network breakdown provides a more useful view of distribution, but it should not be presented as complete Performance Max transparency. That wording matters because analysts will otherwise infer visibility into decisions the field does not actually expose.

    Shopping conversion-date metrics need an explicit time basis

    Expanded Shopping reporting includes new competitive and conversion metrics organized by conversion date. A conversion-date series answers a different question from a series organized around the ad interaction. If your warehouse stores both under an undifferentiated date column, a dashboard can produce a plausible trend with the wrong meaning.

    Give every affected metric a semantic contract. At minimum, record its metric name, date basis, source grain and permitted aggregation behavior. Carry the date basis into the BI model and display label. If you show conversion-date and interaction-date views together, identify them explicitly instead of blending them into one unlabeled total.

    Competitive metrics deserve the same discipline. Do not assume a newly available value can be summed across products, campaigns or dates. Preserve the returned grain first, then implement only the aggregation behavior your reporting definition supports.

    Use PerStoreView as a controlled local-data migration

    PerStoreView exposes store location details aligned with the Stores report. That alignment gives you a practical acceptance test. Select a known account and location scope, retrieve both views, and compare the location set and identifying details before replacing an existing store feed.

    Preserve the identifiers exposed by the API instead of matching stores only by display name. Names can be formatted inconsistently in downstream systems, while a durable identifier gives you a defensible join. Keep store attributes separate from campaign measures as well; duplicating a location attribute across performance rows does not make it an additive metric.

    Your exception report should show missing locations, duplicate mappings and conflicting attributes. Do not hide those cases inside an inner join. A clean-looking dashboard that silently drops an unmatched store is harder to repair than a visible migration exception.

    Keep billing detail and scheduling precision from creating new errors

    Two v23 features move beyond analytical convenience. More detailed invoices affect financial reconciliation, while precise campaign date-times affect when ads can run. Both deserve stronger controls than a new reporting column.

    Model invoice charges by type before calculating totals

    InvoiceService can now return campaign-specific costs, regulatory fees and adjustments. Those amounts may contribute to the same billing reconciliation, but they do not mean the same thing. Putting all of them into an internal field named spend destroys the distinction that makes the new detail valuable.

    Retain the raw response, then normalize each amount into a typed financial record. Your internal model should distinguish campaign cost, regulatory fee and adjustment, preserve the campaign association when supplied, and record the sign convention used by your system. Never change the raw value to make a reconciliation pass.

    • Reconcile typed amounts to the billing total your finance workflow expects.
    • Flag an adjustment whose sign cannot be interpreted confidently instead of silently treating it as a cost.
    • Keep fees visible as fees in client and internal reports.
    • Surface campaign references that cannot be mapped to your internal campaign table.
    • Make repeated ingestion idempotent so rerunning a billing job does not duplicate a charge.

    Release the richer invoice feed beside the existing reconciliation for at least one normal billing run in your own workflow. The purpose is not merely to reach the same final number. Finance should be able to explain which campaign costs, fees and adjustments produced it.

    Treat date-time scheduling as a write-path migration

    Campaigns can use precise start and end date-times rather than date-only boundaries. That is an operational change, not just a more detailed field. A database column, serializer or form built around dates can strip the time and still produce a syntactically valid value with the wrong schedule.

    Trace the value from the user’s input through storage, request construction and the returned campaign state. Confirm the timezone or normalization convention required by the API and your client library rather than guessing. Keep the user’s intended local time available for audit even if your integration also stores a normalized representation.

    • Test a same-day start and end.
    • Test a boundary near midnight.
    • Test a date affected by a daylight-saving transition when the campaign’s market uses one.
    • Test that an end earlier than the start is stopped by your own validation.
    • Read the campaign back after writing and compare the returned schedule with the submitted intent.
    • Verify that legacy date-only jobs do not overwrite the newer time values on their next run.

    Do not move this writer into production while the timezone or end-boundary behavior remains ambiguous. An incorrect boundary can allow spend outside the intended promotion window or stop a campaign while it should still be active. Use a controlled, low-risk campaign for the final lifecycle check and require an explicit rollback path.

    Put human review between AI assistance and campaign changes

    A campaign manager reviews AI-generated adjustment modules before allowing one to pass through an approval gate into an advertising system.

    Google Ads API v23 expands AI-assisted audience and planning workflows in three different ways: a new life-event dimension, free-text audience generation and surface-specific Demand Gen forecasting. They should not be merged into one opaque automation step. Each produces a different kind of planning input and needs a different validation rule.

    Preserve LIFE_EVENT_USER_INTEREST as its own dimension

    The new LIFE_EVENT_USER_INTEREST audience dimension gives Insights workflows a structured way to work with life-event interests. Store the dimension type separately from its returned value. Mapping it immediately into a generic interest bucket removes the distinction before a strategist can use it.

    Add explicit handling for unknown or newly returned values. A resilient integration should retain a value it does not recognize, route it for review and continue processing the rest of the response. Hard-coded mappings that discard an unfamiliar value make API evolution look like missing audience demand.

    Handle generated audience attributes as a proposal

    Generative audience tooling can translate a free-text audience description into structured attributes. That can reduce manual setup, but the structured result is still the consequential output. The input may sound reasonable while the generated attribute set is broader, narrower or simply different from what the strategist intended.

    Make generation a reviewable draft. Store the original description, the complete structured result, the version of your internal mapping logic, the reviewer decision and the eventual change applied downstream. Show the strategist a diff between the current audience definition and the proposed one. Empty attributes, unsupported values and unexpectedly broad additions should block automatic application.

    This audit trail is also how you make the feature debuggable. If campaign behavior later raises a question, you can distinguish the user’s brief, the generated interpretation and the approved configuration instead of treating them as one decision.

    Keep Demand Gen forecasts separated by surface

    Demand Gen conversion-rate forecasts can now vary across surfaces such as Gmail and Shorts. Include surface in the storage key, API-to-warehouse mapping and planning view. Otherwise, one surface can overwrite another or an early average can erase the difference the feature was designed to expose.

    Use each forecast as a planning input, not a guaranteed outcome. Retrieve the forecast without automatically changing budget or targeting, show the surface-level values to the planner, record the decision they support and compare eventual performance using the same surface distinction where your measurement data permits it.

    Key takeaways for your v23 upgrade sequence

    • Adopt v23 by workflow value, not by feature count. Tie every capability to a named decision and consumer.
    • Move read-only reporting first. Baseline, dual-run and reconcile before replacing an existing output.
    • Add the new dimension to your data key. Network, store, surface and date-basis distinctions must survive ingestion.
    • Keep financial meanings separate. Campaign costs, regulatory fees and adjustments should remain typed and traceable.
    • Test scheduling end to end. Database precision, serialization, timezone handling and legacy writers can all alter the intended date-time.
    • Keep AI-generated audience attributes behind validation and human approval.
    • Build reusable migration checks now. A faster 2026 release cadence makes a repeatable test harness more valuable than a one-off v23 patch.

    Your next step is to create one migration ticket for each capability you intend to use. Give it an owner, affected consumer, baseline sample, reconciliation rule, failure alert and rollback condition. Start with the highest-value read-only gap. Move invoice and scheduling changes only when the teams responsible for billing and campaign operations have approved the acceptance tests.

    That approach lets you capture v23’s useful reporting and planning gains without turning the upgrade into an uncontrolled rewrite. It also leaves you with a migration pattern you can reuse as the Google Ads API release pace increases.

    References

  • Google Performance Max Ad Previews: A Practical QA Guide

    Google Performance Max Ad Previews: A Practical QA Guide

    You’ve refreshed a Performance Max asset group and need a clear answer before approving it: will the creative still look deliberate when it appears across different placements? Until now, getting that answer could take more navigation than the review itself.

    The one-click preview makes the mechanical part faster. Its real value, however, depends on what you do after opening it. With a fixed review sequence, you can turn a convenient interface shortcut into a reliable quality-control step.

    Where the one-click PMax preview lives

    Google Ads has shortened the path between the asset list and the rendered ad. From the Asset Groups table, clicking an image or video now opens previews for different Performance Max placements without requiring you to leave the page.

    That is a workflow change, not a new campaign strategy. The preview does not, by itself, add targeting control, supply performance evidence, or explain why PMax gives one asset more delivery than another. It puts the creative closer to the surface so you can inspect it with less friction.

    The time saving matters most when you manage a large asset library or replace creative frequently. Instead of treating previews as a separate destination that you visit only when something looks wrong, you can use the Asset Groups table as a review queue: open an asset, inspect the available presentations, record the decision, and move to the next one.

    Do not assume that opening one image validates the entire asset group. A preview answers a narrow question about the creative in front of you. If several images or videos changed, each changed asset needs its own review.

    A repeatable workflow for reviewing PMax creative

    Hands arranging abstract ad-preview cards through visual checks for first impression, cropping, contrast, and consistency across devices.

    Random clicking is quick but unreliable. Use the same sequence every time so that a busy reviewer does not approve the first attractive rendering and miss a problem elsewhere.

    1. Define the scope before opening previews. Identify which asset groups changed and whether the change involved an image, a video, the surrounding message, or several elements. If the message changed, include older assets in the review because a previously acceptable visual may no longer fit the new offer.
    2. Set the blocking criteria. Decide what requires revision before approval: an unclear focal point, unreadable embedded text, a hidden logo, a conflicting offer, an awkward crop, or a mismatch with the destination. This keeps personal taste from becoming the approval standard.
    3. Open each image and video from the Asset Groups table. Review every placement presentation the interface makes available. Do not stop after the first version simply because it looks acceptable.
    4. Inspect in a fixed order. Check composition first, legibility second, brand and product recognition third, and message consistency last. A fixed order reduces the chance that a strong headline distracts you from a weak crop.
    5. Record an asset-level decision. Use simple statuses such as Pass, Revise, and Block. Include the asset identifier, the placement or rendering where the issue appeared, the reason for the decision, the required change, and the person responsible for it.
    6. Reopen the preview after revision. A corrected source asset can solve one problem while creating another presentation issue. Approval should apply to the revised rendering, not to the intention behind the revision.

    This process also makes team reviews easier to resolve. “The creative feels off” gives a designer little direction. “The product is no longer recognizable in the narrow rendering” identifies the visible failure and the condition the next version must satisfy.

    What to inspect across the available placements

    Image composition and legibility

    An image can be strong as a standalone file and weak once placed inside an ad layout. Review the displayed creative as a user would encounter it, not as the designer saw it on a full-size canvas.

    • Focal point: Confirm that the product, person, or action remains immediately understandable in each displayed presentation.
    • Embedded text: Check whether words inside the image remain readable. If the message depends on enlarging the preview, it is not doing its job in the ad.
    • Logo and product recognition: Make sure the identifying elements are visible without crowding the composition.
    • Edges: Look for important details that sit too close to the boundary or appear cut off in a displayed rendering.
    • Visual hierarchy: The main subject should win attention before decorative elements, badges, or background details.

    A useful test is to ignore the surrounding copy for a moment. If you cannot tell what the image is trying to communicate, the text is being asked to rescue the creative.

    Video clarity and continuity

    Review a video as a sequence, not merely as a valid uploaded file. The opening should establish enough context for the viewer to understand what follows. Watch on-screen text, scene changes, product visibility, logos, and the ending. Important information should not become hard to read or appear crowded by the displayed layout.

    Then compare the video’s promise with the rest of the ad. A polished video can still fail review if it promotes a different product, audience, offer, or next step from the copy presented with it.

    Asset pairing and destination consistency

    PMax creative should be reviewed both as individual assets and as an assembled message. When copy appears with the selected image or video, read the combination from beginning to end.

    • Confirm that the visual and copy refer to the same product, service, or action.
    • Remove accidental repetition when an image already contains the same wording shown beside it.
    • Check that a specific offer in the creative agrees with the current campaign message.
    • Make sure the requested action is a sensible next step for the user.
    • Compare the approved ad message with the destination page separately. The preview can show the ad side of the experience, but it cannot perform that destination review for you.

    This is where the preview earns more than a quick visual check. Assets that look acceptable in isolation can become confusing when presented together. Reviewing the assembled message helps you catch that problem before treating it as a performance mystery.

    What a PMax preview can and cannot prove

    Split illustration showing a controlled ad preview beside the same creative appearing in varied real-world screen contexts.

    The most important distinction is between visual evidence and performance evidence. A preview lets you examine what is displayed in the preview. It does not tell you whether that presentation will receive meaningful delivery or produce better campaign results.

    DecisionWhat the preview establishesWhat you should do
    Visual approvalWhether the displayed examples meet your creative standard.Inspect every available placement presentation for each asset in scope.
    Actual deliveryIt does not guarantee which asset combination will receive impressions.Use campaign reporting to evaluate delivery after the ads run.
    PerformanceIt does not show which asset will generate stronger results.Base performance decisions on relevant campaign data, not appearance alone.
    Destination consistencyIt shows the ad side of the message, not the full landing-page experience.Compare the creative, offer, and requested action with the destination manually.
    Root causeIt can expose a visible flaw but cannot prove that the flaw caused a performance change.Treat the preview as diagnostic evidence and investigate other campaign factors before assigning cause.

    This boundary prevents two common errors. First, an attractive preview is not proof that an ad will perform well. Second, weak results do not automatically prove that the crop, image, or video is responsible. Use previews to remove visible defects; use delivery and outcome data to make performance calls.

    The update also does not eliminate the broader transparency limits associated with Performance Max. It makes creative inspection easier, but it should not be mistaken for a complete view of the system’s selection and delivery decisions.

    Key takeaways

    • You can open placement previews by clicking an image or video directly in the Performance Max Asset Groups table.
    • Review every changed asset and every presentation available to you; one acceptable rendering does not validate the whole asset group.
    • Check composition, legibility, brand recognition, message consistency, and destination alignment in the same order every time.
    • Record Pass, Revise, or Block at the asset level, with the visible reason and required correction.
    • Use previews for creative quality assurance, not as proof of delivery, performance, or causation.

    For your next creative refresh, make preview review a release gate: no changed image or video leaves QA without a recorded pass or revision. The interface saves the clicks. A consistent checklist turns those saved clicks into fewer preventable creative mistakes.

    References

  • Campaign URL Quality Control: A Practical QA Workflow

    Campaign URL Quality Control: A Practical QA Workflow

    An ad can be approved, the budget can be live, and the creative can be right while every click goes to the wrong page. That is why campaign URL quality control cannot end with confirming that the link opens.

    When the launch window is fixed, recovery time becomes part of the loss. A single URL mistake can put a Black Friday campaign into recovery mode while paid traffic is already moving. The practical fix is a release gate that proves three things before spend starts: the visitor reaches the intended experience, the click retains its tracking data, and the measurement system records what you expect.

    Start with a URL contract, not a list of links

    A final URL is correct only in relation to an approved expectation. Give a reviewer nothing but a link and a homepage fallback can look healthy, an old promotion can look plausible, or a valid page on the wrong regional site can pass unnoticed.

    Before URLs enter the advertising platform, create one manifest row for every unique click path. A click path is unique when its destination, locale, offer, required tracking values, redirect behavior, or platform template differs. Several ads may share one row if they truly emit the same URL and promise the same experience.

    ControlAcceptance ruleEvidence to retain
    DestinationThe approved hostname and intended content path are reached.The emitted URL and final resolved address.
    Campaign promiseThe headline, offer, locale, currency, availability, and call to action agree with the creative.A capture of the clickable campaign element and landing page.
    TrackingRequired parameter names and values are present, survive redirects, and follow the naming taxonomy.The emitted URL, redirect record, and exact test values.
    MeasurementThe test visit appears in the intended analytics or advertising system with the expected attribution.A timestamp and identifiable test record.
    Search stateCanonical, indexing, metadata, and structured-data decisions match the landing-page plan.The checked page state and approval result.
    OwnershipA named builder and reviewer have approved the current version.The version, review time, status, and any documented exception.

    Keep both the intended URL and the URL actually emitted by the campaign platform. They are not always identical. Tracking templates, macros, redirects, and automatic parameters can change what the visitor receives. If you preserve only the destination copied from a spreadsheet, you cannot prove what was deployed.

    Inspect the URL as four connected layers

    Four transparent layers align to form one link path, connecting a destination window, redirect arrows, tracking tokens, and a measurement beacon.

    A link can pass one kind of test and fail another. Separate structure, redirects, page experience, and measurement so that a successful page load does not hide a tracking or content error.

    1. Parse the URL instead of scanning it by eye

    Long campaign URLs are difficult to compare visually. Break each one into its scheme, hostname, path, query parameters, and fragment. Compare those components with the manifest as data, not as one long string.

    • Confirm the hostname exactly, including any regional or campaign subdomain. A familiar brand name on the wrong host is still the wrong destination.
    • Treat path spelling, capitalization, and trailing slashes as meaningful until the live server proves otherwise. Different systems can resolve them differently.
    • Require every mandatory query parameter exactly once. Flag missing, empty, duplicated, or unexpected keys instead of guessing which value will win.
    • Check parameter values against the approved naming taxonomy, including capitalization, separators, campaign labels, and channel names.
    • Reject whitespace, unresolved template variables, copied punctuation, and malformed separators.
    • Validate percent-encoding when values contain spaces or reserved characters. An unencoded ampersand, for example, can be interpreted as the start of another parameter.
    • Do not place server-side tracking expectations after the number sign. A fragment is handled by the browser and is not included in the request sent to the server.

    A small validator can automate these checks across the entire manifest. Give it an allowlist of production domains, required parameter keys, approved value patterns, and known obsolete paths. Automation should identify the exact row and rule that failed; it should not silently repair an ambiguous URL and approve the result.

    2. Follow every redirect to the resolved destination

    The first URL is only the start of the route. A redirect can send the visitor to an old slug, switch the hostname, choose a regional site, remove a parameter, or fall back to the homepage. Test the whole route and record each address in sequence.

    • Confirm that every redirect is expected and owned by a known system.
    • Compare the parameters before and after each redirect. Required values must not disappear, change, or become duplicated.
    • Flag an unexpected domain, locale, login page, homepage fallback, or error page even when the final page technically loads.
    • Check that platform macros have rendered into real values. A literal placeholder in the emitted URL is a deployment failure.
    • Document intentional canonicalization, such as a redirect from an old approved slug to a new preferred path, so future reviewers do not treat it as unexplained behavior.

    Store the original configured URL, the platform-emitted URL, and the final resolved URL separately. That distinction tells you whether an error entered through campaign setup, platform rendering, a redirect service, or the website.

    3. Test the page state the visitor will actually receive

    A correct address can still produce the wrong experience. Open the link in a clean, logged-out session so that an existing account, cookie, or cached redirect does not hide the default visitor path. Then test only the additional states that can materially change this campaign, such as device class, locale, authentication, consent choice, or audience routing.

    • Match the landing-page headline and offer to the promise made by the ad or campaign element.
    • Check the price, currency, promotional conditions, availability, and expiration language where they apply.
    • Use the primary call to action. Confirm that its next page, form, checkout, download, or booking path is the intended one.
    • Submit forms with approved test data and verify that required fields, confirmation states, and downstream handoffs work.
    • Confirm that mobile-specific buttons, sticky controls, cookie notices, or overlays do not block the action.
    • Check what happens when optional campaign parameters are missing, empty, duplicated, or unrecognized. The fallback should be intentional.
    • Where structured data is present, verify that its offer, availability, dates, organization, and destination agree with the visible page. Stale machine-readable details are still a quality-control failure.
    • Confirm the intended canonical and indexing state. When tracking parameters do not change the page’s meaning, the preferred clean URL should normally remain the canonical destination; intentionally isolated or non-indexable campaign pages need their own documented rule.

    Do not approve a page merely because it returns content. A polished page for the wrong product, market, or promotion is a more dangerous failure than an obvious broken link because it can survive a superficial review.

    4. Prove collection, not just parameter presence

    Tracking validation requires three separate proofs. First, the emitted URL contains the expected names and values. Second, those values survive the route to the destination. Third, the receiving measurement system records the visit as intended. Passing the first two does not prove the third.

    • Click through the rendered campaign element or the platform’s preview and test mechanism. Copying the manifest URL bypasses platform-level templates and additions.
    • Record the click time, emitted URL, final URL, consent state, and exact campaign values so the test visit can be located downstream.
    • Verify the visit in each system the campaign depends on, rather than assuming one analytics record proves that every advertising or reporting destination received it.
    • Check the recorded values themselves. A session attributed to the wrong source, medium, campaign, market, or creative is not a pass.
    • Use non-billable preview or test functions when the platform provides them. If a controlled live click is required, define who may perform it and how the resulting test activity will be identified.

    Take care with privacy and consent behavior. The acceptance rule should describe what is expected before and after consent for the jurisdictions and technologies involved. A missing record can be correct under one consent state and a genuine implementation fault under another.

    Turn the checks into a release gate

    Several digital click paths enter a three-stage checkpoint, where a verified teal path passes through an open gate and a red path is diverted for review.

    A checklist helps only when a failed check can stop deployment. Build URL QA into the same approval path as creative, audience, budget, and launch timing. The manifest becomes the release record, and any material edit resets approval for the affected rows.

    1. Inventory every clickable element. Include primary ads, additional assets, buttons, email links, social placements, affiliate links, QR destinations, and any alternate mobile or regional routes in scope.
    2. Freeze the expected state. Record the approved destination, campaign promise, tracking taxonomy, page state, owner, and version before platform setup begins.
    3. Generate URLs from controlled inputs. Use a governed builder or template where possible. Prevent free-form labels when a controlled campaign name or channel value already exists.
    4. Run structural checks across every row. Validate syntax, allowed domains, required keys, values, duplicate parameters, obsolete paths, and unresolved variables in bulk.
    5. Click every unique rendered path. Test from the final platform context or the closest safe preview, not only from the spreadsheet or URL builder.
    6. Verify destination, action, redirects, and collection. Retain enough evidence to reproduce the result without relying on memory.
    7. Require an independent review. A second person should compare the deployed path with the approved contract. The builder should not be the only approver for a fixed-date or high-spend launch.
    8. Lock and label the approved version. Any later change to the URL, template, redirect, offer, page, consent implementation, or tracking taxonomy must reopen the relevant checks.

    Define blockers before launch pressure arrives

    Separate blockers from warnings in advance. Otherwise, launch urgency turns every failure into a judgment call.

    • Block launch when the destination is unavailable, the domain or page is wrong, the offer is materially inconsistent, the primary action fails, a required tracking identifier is missing or corrupted, a template variable remains unresolved, consent behavior violates the approved requirement, or the measurement test cannot be found.
    • Allow a documented warning only when the behavior is understood, does not alter the visitor promise or required measurement, has a named owner, and has an agreed resolution date.
    • Reject unexplained exceptions. If nobody can state why a redirect, parameter, or page state exists, it is not ready for approval.

    Record PASS, BLOCK, or EXCEPTION for each row. Avoid a single campaign-level checkbox when different ads, assets, markets, or templates can fail independently.

    Repeat the critical checks after launch and after every change

    Pre-launch approval proves the tested configuration. It does not prove that the live system rendered the same path after scheduling, review, propagation, or a last-minute edit. Run a controlled production check as soon as traffic is enabled.

    Use a small production-verification loop

    • Make one safe live-path check for each unique combination of destination and tracking template.
    • Compare the emitted URL and resolved destination with the approved manifest version.
    • Confirm the visible offer and primary action one more time in the production state.
    • Locate the test visit in the required measurement systems.
    • Watch for destination errors, unexpected redirect changes, unresolved placeholders, and sudden attribution gaps while the launch is active.

    Reopen QA whenever someone changes the destination URL, tracking template, naming taxonomy, redirect rule, landing-page slug, offer, localization rule, form, consent configuration, canonical, or structured data. A change that appears unrelated to paid media can still alter the click path.

    Contain a live failure before repairing it

    If the landing page is unavailable, materially misrepresents the offer, or routes visitors to the wrong destination, pause the affected traffic path while it is investigated. Continuing can waste budget and expose visitors to an invalid promise. If the scope is unclear, follow the campaign owner’s incident policy rather than making an unrecorded account-wide change.

    1. Contain the affected route. Pause or remove only the known bad placements when their scope can be isolated safely.
    2. Preserve evidence before editing. Capture the campaign element, configured URL, emitted URL, redirect path, page state, timestamps, and affected markets or devices.
    3. Find the first incorrect state. Determine whether the defect began in the manifest, platform setup, template rendering, redirect service, website, or measurement implementation.
    4. Repair the system of record. Correcting only the visible ad while leaving a shared template or URL builder wrong allows the defect to return.
    5. Repeat independent QA. Treat the repaired path as a new release, including a downstream measurement check.
    6. Resume under recorded approval. Note who approved the restart and retain the before-and-after evidence.
    7. Convert the failure into a control. Add a validation rule, allowlist, required field, ownership step, or change trigger that would have caught the same defect earlier.

    Accountability here is operational, not personal. The useful question is not simply who entered the bad value. It is why one incorrect value could move from creation to live traffic without a control detecting it.

    Key takeaways

    Campaign URL quality control is a documented pre-launch and post-launch process that verifies the emitted URL, redirect route, landing-page experience, tracking collection, and approval record for every unique click path.

    • A link that opens is not necessarily correct. It must reach the approved page, preserve the campaign promise, and produce the expected measurement record.
    • Store the configured, emitted, and resolved URLs separately so you can locate where an error entered the route.
    • Automate structural checks across all URLs, then manually test each unique destination and tracking-template combination from the rendered campaign context.
    • Make wrong destinations, broken actions, unresolved variables, missing required tracking, and unverified collection explicit launch blockers.
    • Reset approval after changes and repeat a controlled check in production. The live path, not the spreadsheet, is the final object under test.

    For your next campaign, create the manifest before the first URL enters a platform. Assign the builder and reviewer, define the blocker rules, and reserve a production-verification step in the launch schedule. Once that row becomes a deployment artifact rather than a convenient link list, URL QA becomes repeatable instead of dependent on someone noticing a typo in time.

    References

  • Google Merchant API Migration: A No-Surprises Checklist

    Google Merchant API Migration: A No-Surprises Checklist

    If your Shopping or Performance Max campaigns rely on an API-fed catalog, the Merchant API migration is a delivery dependency, not routine backend maintenance. Letting a legacy Content API connection reach its cutoff can interrupt campaigns that depend on its product feed.

    The dangerous version of this failure is not always an obvious API error. Products may arrive through the new connection while feed labels, campaign structure, or bidding logic no longer match. Your migration is complete only when the new API writes the right product data and the campaigns consuming that data still behave as intended.

    Confirm whether your account is exposed

    Start in Merchant Center Next. Open Settings > Data sources and inspect the type shown for every product source. Any source marked Content API belongs in your migration inventory. Do not assume that an ecommerce app, scheduled file, or newer integration elsewhere in the account means the legacy connection has already been replaced.

    For each Content API source, record:

    • The Merchant Center account and data source name.
    • The application, connector, platform, or custom code that writes the product data.
    • The person or provider able to change and deploy that integration.
    • How updates are triggered, including scheduled jobs and manual runs.
    • The Shopping and Performance Max campaigns that consume the products.
    • Every feed label associated with the source and what that label controls.
    • The evidence you will require before declaring the migration complete.

    If a third-party platform manages the connection, ask for more than a general confirmation that it supports Merchant API. You need four explicit answers: which connection will be replaced, when the change will reach your account, whether feed labels will be recreated or mapped, and whether you must reconnect anything inside Merchant Center Next. The provider may own the deployment, but you still own campaign validation.

    The transition began in mid-2024, and the communicated migration path cited February 28 for beta participants and August 18 for other Content API users. Those month-and-day references are not safe planning dates without the applicable year and account context. Use the dated notice attached to your own account as the operative cutoff. If nobody can produce that notice, treat the connection as an active risk rather than assuming you have more time.

    Preserve feed labels before moving product data

    Generic retail products with colored geometric tags cross a bridge between two database structures with their tags still attached.

    Feed labels can be part of your campaign architecture. They may separate inventory or support bidding decisions, yet they do not transfer seamlessly during this migration. That creates a misleading success state: the new connection works, products appear, and the technical ticket closes, but a label-dependent campaign no longer addresses the same inventory.

    Build a label map before changing the connection. For each existing label, capture:

    • The exact current value, including spelling and capitalization.
    • A small set of representative products that should carry it.
    • The campaign structure or bidding rule that depends on it.
    • The value expected after migration.
    • The person responsible for checking it in the advertising account.

    Include products from every label and at least one product that intentionally has no label. That last case helps you distinguish a valid blank value from a failed transfer. Compare the same products before and after cutover instead of checking whichever items happen to be easiest to find.

    Do not rename, consolidate, or reorganize labels during the API migration unless the old structure makes the cutover impossible. Combining cleanup with migration destroys your baseline: when inventory changes, you will not know whether the API, the new label design, or the campaign edit caused it. Move the existing behavior first, prove parity, and schedule cleanup as a separate change.

    Run the migration as a controlled cutover

    A useful migration plan separates preparation, technical cutover, and advertising validation. It also names the person who can stop or reverse the change. Use this sequence:

    1. Assign two owners. The technical owner changes the integration. The paid media owner verifies labels, inventory coverage, and campaign behavior.
    2. Freeze unrelated changes. Avoid simultaneous feed restructures, label renaming, and major campaign edits from baseline capture through validation.
    3. Capture the baseline. Save the current data source type, label map, representative products, update process, and dependent campaigns.
    4. Configure the Merchant API connection. Update the system that actually writes product data, then reconnect the data feed where the migration flow requires it. A code deployment alone does not prove that Merchant Center is receiving the new writes.
    5. Preserve rollback material. Keep the previous configuration, mappings, and baseline evidence until validation finishes. Do not allow two uncontrolled connections to write conflicting versions of the same products.
    6. Send a controlled update. If the integration permits it, change a representative product through the real production path. Choose a field whose before-and-after state is easy to verify.
    7. Check every label path. Compare the representative products against the label map and confirm that dependent campaign structures still include the intended inventory.
    8. Observe a scheduled run. A successful manual request does not prove that the recurring job, connector, or automation has been migrated.
    9. Retire the legacy connection only after sign-off. Require approval from both the technical owner and the paid media owner.

    Define rollback triggers before cutover. Missing labels, a test update that never reaches Merchant Center, or a campaign structure that loses its intended inventory are reasons to stop and investigate. A rollback should restore a known configuration, not blindly reactivate every old process.

    Validate business behavior, not just API success

    An operator oversees parallel product-data pipelines as checkpoints verify deliveries to a storefront, campaign engine, and bidding controls.

    An authenticated request proves only that one request was accepted. End-to-end validation has three layers: the connection, the product data, and the campaign consuming that data.

    Connection validation

    • Confirm that Merchant Center Next shows the intended new data-source connection rather than the legacy Content API source.
    • Verify that a deliberately changed product value arrives through the new path.
    • Run or observe the normal scheduled process and confirm that it uses the same path.
    • Record the time, product tested, expected result, actual result, and validator.

    Product and label validation

    • Check the same representative products captured in the baseline.
    • Compare each expected label character for character.
    • Confirm that intentionally unlabeled products remain unlabeled.
    • Test an ordinary product update after the initial migration so you know the connection handles ongoing changes, not only the first import.

    Campaign validation

    • Inspect every Shopping or Performance Max structure that relies on a migrated feed label.
    • Confirm that each label still selects the intended inventory and that no expected subset has become empty.
    • Check that bidding logic tied to those labels still points to the right product group.
    • Have the paid media owner sign off independently of the developer or integration provider.

    Do not use immediate spend or revenue as your only acceptance test. Auction results vary, and business metrics can lag behind a configuration error. Structural checks – the right products, labels, and campaign relationships – reveal migration mistakes sooner. Performance monitoring should follow, but it cannot replace those checks.

    Keep the validation record with the integration documentation. It should show the old and new connection, the label mapping, the test products, the scheduled-run result, the dependent campaigns, and both approvals. That evidence gives you a precise starting point if a later feed or campaign problem appears.

    Key takeaways

    • A data source marked Content API in Merchant Center Next is a migration dependency that needs a named owner.
    • Moving products is not enough. Feed labels require an explicit before-and-after mapping because they may not transfer cleanly.
    • Separate the API cutover from feed cleanup and campaign restructuring so you retain a useful baseline.
    • Validate the new connection, a normal scheduled update, representative products, labels, and every dependent Shopping or Performance Max structure.
    • Use the dated notice for your own account to determine the applicable cutoff rather than relying on an unqualified calendar date.

    Open Merchant Center Next and inspect Data sources now. If Content API appears, assign a technical owner and a paid media validator in the same work item. Close that item only after a scheduled product update reaches the new connection and the label-dependent campaigns still address the inventory you intended.

    References

  • Positionless Marketing Operations: A Practical Playbook

    Positionless Marketing Operations: A Practical Playbook

    Your campaign brief is ready and the customer signal is fresh, but the work cannot move. Insight sits with an analyst, creative with a designer, execution with marketing operations, access with an engineer, and approval somewhere else. By the time every queue clears, the moment you wanted to act on may have passed.

    Positionless marketing operations gives the person accountable for the result enough access, capability, and authority to move from signal to launch and learning. It does not ask every marketer to become an expert in every discipline. It removes routine dependencies while preserving specialist judgment where the risk or complexity requires it.

    Key takeaways

    • Organize recurring campaign work around one outcome owner rather than a chain of task owners.
    • Remove handoffs caused by missing access, inherited habits, or routine production work. Keep controls that protect customers, data, brand standards, budgets, and technical reliability.
    • Give the owner data, reusable creative, execution tools, measurement, and decision rights together. Providing only some of these capabilities creates another queue.
    • Use AI to improve predictions and prepare options, and use automation to execute approved routines. Humans should still set objectives, judge context, and handle exceptions.
    • Measure customer results, total cycle time, waiting, rework, and exceptions. A faster launch is not an improvement if quality or campaign performance deteriorates.

    Positionless is an operating model, not a staffing shortcut

    Traditional marketing operations divides a campaign into specialties and sends the work through them in sequence. Each person may complete an assigned task efficiently while the campaign as a whole remains slow. The local metrics look healthy because every department finished its part. The customer outcome still arrives late.

    A positionless model changes the unit of responsibility. Instead of owning a brief, segment, asset, workflow, or report, one marketer owns the campaign outcome from the initial signal through execution and evaluation. Other specialists can contribute, but routine progress no longer depends on each of them taking possession of the work.

    Operating questionSequential modelPositionless model
    What does a marketer own?A task or stageAn outcome and the decisions needed to reach it
    How does routine work advance?Through departmental queuesThrough self-service tools and preapproved patterns
    What do specialists do?Execute most requestsBuild systems, define guardrails, advise, and handle exceptions
    When is approval required?At each inherited stageWhen the work crosses a stated risk or authority boundary
    Who answers for the result?Responsibility is distributed across contributorsOne named owner is accountable end to end

    This is not a case for eliminating designers, analysts, engineers, channel experts, or governance teams. Their leverage often increases when they stop repeating routine production work and start building the templates, data products, controls, and escalation paths that let other marketers operate safely.

    Nor does end-to-end ownership mean one person must perform every keystroke. The outcome owner can request advice or delegate specialized work. The important distinction is that the campaign does not lose its owner each time another discipline becomes involved. That person remains responsible for the campaign logic, tradeoffs, launch, and response.

    The potential compression can be substantial when coordination is the real constraint. One documented gaming workflow required seven teams and six weeks to launch a campaign. A separate iGaming operation reduced campaign execution from five days to five minutes, while another campaign process moved from six weeks to hours. These are individual transformations in gaming-related businesses, not universal benchmarks. Use them as evidence that structural delay can be large, not as a target your team must copy.

    Find the handoffs that create delay, not safety

    An isometric workplace shows a campaign stalled at many desks on one side and moving through a shorter path with transparent safety gates on the other.

    Do not start the redesign by buying a new platform or rewriting job descriptions. Start with one recurring campaign and reconstruct what actually happened. The official process usually omits informal messages, access requests, clarification loops, and work that sits untouched between departments.

    1. Name the trigger and outcome. Write down the customer or business signal that started the work and the response the campaign was meant to produce. If the outcome is vague, ownership will be vague too.
    2. Trace the real path. List every person or team that received the work, what they were asked to provide, and what the campaign owner could not do while waiting.
    3. Separate touch time from wait time. Record when each request entered a queue, when work began, and when the usable output returned. The gap shows whether expertise or availability is constraining the campaign.
    4. Mark every return trip. A brief that comes back for missing data, an asset returned for resizing, or a workflow rebuilt after an audience change is rework. It deserves its own line rather than being hidden inside the original step.
    5. Identify the permission behind the handoff. Ask whether the next team supplied expertise, exercised a necessary control, held exclusive system access, or simply inherited the task historically.
    6. Choose the smallest removable dependency. Give the owner the access, template, or rule needed to bypass one routine queue, then observe what happens to speed, quality, and exceptions.

    Classify each dependency before removing it

    Four labels keep a workflow review from turning into an indiscriminate campaign against collaboration:

    • Expertise dependency: another person must interpret an unfamiliar problem or perform work requiring deep skill. Preserve access to that specialist, but define which routine cases can be handled through templates, training, or reusable components.
    • Control dependency: another function protects a material boundary involving customer data, regulated claims, contractual obligations, brand risk, spend, or system stability. Keep the boundary and make the escalation condition explicit.
    • Access dependency: the marketer knows what to do but cannot see the data, use the tool, create the segment, modify the asset, or publish the campaign. This is a strong self-service candidate if appropriate permissions and audit records can be established.
    • Habit dependency: the handoff exists because the work has always moved that way. Remove it unless someone can identify a current capability or control that it provides.

    The test is not whether a handoff involves an important team. It is whether transferring ownership is necessary for this class of work. A brand team may need to establish the visual system without manually adapting every approved layout. An analyst may need to define a reliable audience model without pulling every recurring segment. An engineer may need to administer the platform without configuring every routine campaign.

    Pay particular attention to clarification loops. If a specialist repeatedly asks the same questions, the answer is usually not a faster request form. Convert those questions into a required brief, validation rule, template, or in-product prompt that helps the outcome owner provide the right input before work starts.

    Build a minimum viable autonomous campaign workflow

    A marketer is not autonomous because the organization announced a new operating philosophy. Autonomy exists only when the person can complete a defined class of campaign without seeking routine access, production, execution, and measurement help.

    For the workflow you selected, assemble these capabilities as one operating package:

    • An outcome brief: the trigger, intended audience, desired response, channel, campaign constraints, and the measure that will determine whether the work succeeded.
    • Usable data access: approved customer signals, audience definitions, exclusions, and enough context to understand what the data does and does not mean.
    • Reusable creative: modular templates, approved components, brand rules, required language, and a clear route for creative work that falls outside those patterns.
    • Execution rights: permission to configure and launch the routine campaign within defined channel, scheduling, volume, and budget boundaries.
    • Measurement access: a shared view of delivery and customer response, with consistent metric definitions and enough detail to diagnose the result.

    These elements have to arrive together. Creative self-service does not help if audience creation still waits in another queue. Execution access does not create ownership if the marketer cannot see the result. A dashboard does not produce action if every campaign change needs a new approval chain.

    Write decision rights as operational rules

    Ambiguous authority sends people back to the hierarchy as soon as a real choice appears. For each recurring decision, write one of three instructions:

    • The owner may decide: the choice is inside an approved pattern and does not require consultation.
    • The owner must consult: specialist input is useful, but the outcome owner retains the decision unless the work crosses a separate control boundary.
    • The owner must escalate: the choice creates a stated risk, exceeds an approved limit, introduces a new use of data, makes a sensitive claim, or changes a protected system.

    Make the escalation route just as concrete as the boundary. Name the role that can decide, specify what information the owner must provide, and explain what happens while the decision is pending. Otherwise, an exception path becomes the same opaque queue under a new name.

    Approval should follow risk, not organizational distance. A recurring campaign built from an approved audience, template, offer, and channel pattern should not need a ceremonial review merely because several departments once touched it. A campaign introducing a new data purpose or a claim with legal implications should still reach the appropriate privacy, compliance, or legal specialist before launch. The safe way to increase autonomy is to preapprove known patterns and escalate deviations, not to let individual marketers interpret high-risk boundaries on their own.

    Specialists also need a feedback loop. When the same exception appears repeatedly, they should decide whether to turn it into a supported pattern, improve training, tighten a rule, or keep it exceptional. That is how the autonomous scope expands deliberately instead of through informal workarounds.

    Use AI and automation without outsourcing judgment

    A marketer oversees a circular campaign workflow in which automated tools connect customer signals, creative assembly, activation, and feedback while exceptions remain under human control.

    AI and automation can make positionless operations practical, but they solve different parts of the problem. AI can help interpret signals, generate options, adapt approved components, or predict a likely response. Automation can validate inputs, assemble routine workflows, apply exclusions, launch approved actions, and return results. Neither one decides what the organization should optimize or which risk is acceptable.

    The useful division of labor is straightforward: machines prepare and execute; the accountable marketer chooses and judges. The operating principle is to let AI support prediction and automation remove friction while retaining human decisions.

    • Keep objectives human-owned. A model can optimize a stated target, but the marketer must decide whether that target represents the customer and business outcome that matters.
    • Constrain the available inputs. Give tools access only to data and content approved for the workflow. More access is not automatically better if it introduces data that the marketer is not authorized to use.
    • Ground production in approved components. Templates, product facts, offer rules, brand language, and required disclosures reduce the distance between a generated option and a usable campaign.
    • Validate before execution. Check required fields, exclusions, links, audience logic, scheduling, and other campaign-specific conditions before automation can publish.
    • Route exceptions to people. Novel claims, unfamiliar audiences, unexpected model outputs, anomalous results, and decisions outside established limits need named human reviewers.
    • Retain an audit trail. Record the inputs, material choices, approvals, generated assets, final configuration, and outcome so the team can investigate errors and improve the system.

    Do not use autonomous as a synonym for unsupervised. The marketer may operate without routine departmental handoffs while still working inside centrally maintained permissions, validations, and monitoring. That combination is what turns governance from a sequence of manual approvals into part of the operating environment.

    AI also cannot repair unclear ownership. If a generated campaign still needs several people to decide what it is trying to achieve, who may launch it, and who answers for the result, the organization has accelerated production without changing operations. Establish the owner and decision rights before adding more generation capacity.

    Run one pilot and measure whether speed creates value

    Choose a recurring campaign that suffers visible delay, uses reasonably stable inputs, and can be kept within existing controls. Avoid beginning with the organization’s most novel, sensitive, or technically fragile campaign. You need a workflow that can reveal operational problems without making every run a special case.

    1. Baseline the existing campaign. Capture the signal-to-launch time, touch time, waiting, handoffs, rework, exceptions, and customer result from a comparable run.
    2. Name one outcome owner. Give that person responsibility for the brief, audience logic, creative choices, execution, and evaluation within the pilot scope.
    3. Remove a complete set of dependencies. Provide the data, templates, tools, measurement, and permissions required to bypass the selected routine queues.
    4. Publish the operating boundaries. State what the owner may decide, when consultation is optional, what must be escalated, and who resolves each exception.
    5. Run the campaign and log friction. Record every point where the owner still cannot proceed, every manual correction, and every case in which a guardrail prevents an error.
    6. Compare the whole result. Evaluate time, quality, campaign performance, rework, and risk events together. Then decide which dependency to remove or which control to improve next.

    Your pilot scorecard should answer several different questions:

    • Customer outcome: Did the intended audience respond in the way the campaign was designed to produce?
    • Signal-to-launch time: How long passed between identifying the opportunity and making the campaign available to customers?
    • Wait-to-touch ratio: How much of the total elapsed time was active work, and how much was time spent waiting for another person, permission, or system?
    • Required handoffs: How many transfers had to occur before the campaign could launch and be evaluated?
    • First-pass completion: Did the owner launch inside the approved pattern without work being returned for avoidable corrections?
    • Exception demand: Which decisions still required specialist involvement, and did the same exceptions recur?
    • Rework and errors: Did broader autonomy introduce corrections, customer-facing mistakes, reporting problems, or operational cleanup?

    Read the measures together. A shorter launch time accompanied by worse customer response may mean the team optimized for speed instead of relevance. Fewer handoffs with more preventable errors may mean the templates or training are incomplete. Faster execution with unchanged waiting may mean the bottleneck moved from production to decision-making.

    Do not borrow the five-minute or same-day timing of another organization as your success threshold. Your starting architecture, controls, channels, and campaign type determine what is realistic. The credible target is an improvement against your own baseline without deterioration in the outcome or an unacceptable increase in risk.

    Take the last routine campaign your team completed and circle every moment when its owner knew what should happen but could not proceed. Classify each stop as expertise, control, access, or habit. Remove one access or habit dependency, keep the necessary safeguards, and run the workflow again. When the same accountable person can see the signal, make an approved choice, launch, and read the response, you have a positionless operation you can expand.

    References

  • Google Ads Testing and Bid Controls: A Practical Playbook

    Google Ads Testing and Bid Controls: A Practical Playbook

    You have a Google Ads campaign that is spending, but the next move is unclear. Should you change the bid strategy, test the ad or product feed, or leave automation alone? Change all three and performance may move, but you won’t know why.

    The practical rule is simple: change the layer that answers your question and hold the surrounding layers steady. That turns bid control from a philosophical argument about manual versus automated bidding into a test that can support an actual decision.

    Separate the decision from the Google Ads setting

    The word “control” has two meanings here. In an experiment, the control is the unchanged version used for comparison. In bidding, control describes how much of the bid-setting process belongs to you rather than the platform. You need to define both before launching a test.

    Start by separating the campaign into three layers:

    • The measurement layer: the conversion action or business outcome used to judge performance.
    • The traffic layer: bidding, budget, targeting, eligibility, and the auctions the campaign can enter.
    • The message layer: ad copy, landing-page promise, product title, product image, and other information the prospective customer sees.

    A useful experiment changes one of these layers while protecting the others from avoidable movement. If you test a product title while switching bid strategies, a different result could come from the title, the traffic mix, or their interaction. If you compare bid strategies while redefining the conversion goal, you are no longer measuring bidding against a common outcome.

    This doesn’t mean every test can change only one interface field. It means every test should answer one business question. A title-and-image package can be a valid treatment if your decision is whether to adopt that package. It cannot tell you whether the title or the image caused the result.

    Question you need answeredWhat changesWhat stays stableWhat you may conclude
    Does direct bid control work better for this campaign?The bidding approach and its documented rulesConversion goal, ads, product data, landing pages, and targetingWhich bidding approach better serves the defined goal under the tested conditions
    Does a revised product title improve sales?The title treatmentImage, bidding, other feed fields, and measurementWhether the proposed title performs better than the existing title
    Does a new title-and-image package improve sales?The complete title-and-image treatmentBidding, other product data, and measurementWhether the package wins, but not which component deserves credit

    Write the hypothesis before opening the campaign settings: “If we change X, Y should improve because Z.” Name one primary outcome in place of Y. It might be sales, conversion value, qualified leads, or another result that matches the campaign’s purpose. Other metrics can help diagnose what happened, but they should not be promoted to the main success measure after the results arrive.

    Use Manual CPC when the bid itself needs to be controlled

    Manual CPC is now surfaced as “Manually set bids” within the main Google Ads bidding flow, under the Conversions goal. Advertisers no longer have to reach it through the more obscure “bid strategy directly (not recommended)” route described in the earlier interface.

    That interface change makes Manual CPC easier to select. It does not make manual bidding the correct default, nor does an automated recommendation prove that automation is right for your campaign. The decision should follow from the question you are trying to answer.

    Manual CPC is most defensible when you need the bid to behave as a known input. That can matter in a narrow or niche campaign where direct oversight is important, or when the experiment is specifically testing how your own bid policy affects cost and traffic. You set the bids, so you can document what was changed and why.

    Manual control is not the same as a controlled experiment. If you adjust bids whenever a result looks uncomfortable, the treatment keeps changing. The final total then represents a series of reactions rather than one repeatable bidding policy.

    Before using Manual CPC in a test, define:

    • The level at which you will set and evaluate bids.
    • The evidence that permits a bid increase, decrease, or no change.
    • When bid reviews will occur, so short-term movement does not trigger constant intervention.
    • The spending and performance boundaries that prevent an experiment from creating unacceptable financial exposure.
    • The campaign settings, assets, and conversion definitions that will remain unchanged.

    Automated bidding is useful when the bid is not the variable you need to study. You still control the business goal, budget, campaign eligibility, measurement inputs, and any constraints available for the chosen strategy, while Google controls the auction-level bid. If you are testing a product title or image, keeping an established bid strategy stable will usually produce a cleaner answer than introducing manual bid decisions at the same time.

    Use this decision sequence:

    • If your question is about bid policy, compare clearly defined bidding approaches while freezing the message and measurement layers.
    • If your question is about ads, landing pages, or product data, keep bidding stable enough that it does not become a second treatment.
    • If conversion tracking or the business goal is changing, repair and stabilize measurement before interpreting either bidding approach.
    • If you cannot state the rule governing your manual adjustments, you do not yet have control; you have discretion without a test protocol.

    Design a campaign experiment that produces a decision

    Two evenly split experiment lanes keep budgets, timing, and audiences identical while changing only one bidding control.

    A test is useful only if you know what you will do with each possible result. “See whether performance improves” is too vague. Decide in advance whether a clear win will be adopted, an unclear result will preserve the control or trigger a revised test, and a loss will be rejected.

    1. State the decision. Name the setting, asset, or product-data change that could be adopted after the experiment.
    2. Define the control. Record the current bid strategy, conversion goal, budget conditions, targeting, assets, feed state, and landing page that form the comparison.
    3. Define the treatment. Specify exactly what will differ, including any bundled changes that must be evaluated together.
    4. Choose the primary outcome. Use the business result that will determine the winner, not whichever metric later moves in the preferred direction.
    5. Set guardrails. Write down the cost, tracking, inventory, lead-quality, or operational conditions that can stop the test for a legitimate business reason.
    6. Freeze neighboring levers. Avoid routine edits to settings that could alter traffic, measurement, or the customer-facing treatment.
    7. Document unavoidable events. A site outage, promotion, inventory disruption, tracking failure, or other material event may make the result harder to interpret even if the test continues.
    8. Evaluate against the original rule. Adopt, reject, or retest based on the decision framework you wrote before seeing the outcome.

    Guardrails deserve special care because Google Ads spend has a direct financial consequence. Define the point at which protecting the business takes priority over preserving experimental purity. A broken conversion tag or unavailable product is a reason to pause and investigate. A few uncomfortable fluctuations are not, by themselves, evidence that the treatment has failed unless they cross a boundary you established beforehand.

    Do not end a test merely because the variant briefly moves ahead, and do not extend it only because the control is winning. Both actions let the result influence the evaluation window. Follow the planned endpoint or the experiment’s valid reporting framework unless a documented guardrail has been breached.

    Read secondary metrics as explanations, not substitute scorecards. If the primary outcome improves, changes in clicks, traffic volume, cost, or conversion behavior may help explain how. If the primary outcome is inconclusive, a favorable secondary metric does not automatically create a winner. “No defensible difference” is a usable result: it tells you the proposed change has not earned a rollout on the evidence available.

    Segment analysis should come after the main comparison. Device, audience, product, or query-level patterns can generate the next hypothesis, but selecting a winner because one small slice looks favorable invites cherry-picking. Treat an unexpected segment result as a reason for a focused follow-up test.

    Test Shopping titles and images without muddying the result

    Matching unbranded shoes sit in separated test bays where label and product-image variables are isolated from other conditions.

    Shopping campaigns have historically made clean product-feed tests awkward because changing a live title or image changes what the whole campaign uses. Google has tested product data experiments that compare title and image variations without first committing those changes across the full feed.

    The reported test was limited to a small group of merchants, so access should be treated as account-dependent rather than universal. Where the feature is available, results are expected within 3-4 weeks. That timing belongs to this product-data experiment and should not be treated as a universal duration for every Google Ads test.

    If product data experiments appear in your account, use them in this order:

    1. Choose a feed decision. Decide whether you are testing a title, an image, or a deliberately bundled presentation.
    2. Write the customer-facing hypothesis. Explain what the variation makes clearer or easier to understand without changing the product’s factual identity.
    3. Keep the comparison clean. Hold bidding, measurement, landing pages, and unrelated product fields steady wherever practical.
    4. Protect product accuracy. A treatment should remain a truthful representation of what the shopper can buy; an attention-grabbing but misleading variant is not a useful winner.
    5. Wait for the experiment’s result window. Do not treat an early directional movement as the final finding merely because it supports your expectation.
    6. Apply the conclusion at the same level it was tested. A result for one product set or presentation pattern does not automatically justify changing every item in the catalog.

    Test the title and image separately when you need to learn which component matters. Test them together when the real decision is whether to adopt a complete merchandising concept. The second approach may identify a better package, but it cannot assign credit between its components.

    If the feature is absent, do not disguise a feed overwrite followed by a before-and-after comparison as an A/B test. Time, demand, competitors, inventory, promotions, and bidding conditions can change between the two periods. You can still document the change and use the result as directional evidence, but its limitations should travel with the conclusion. A true control-and-variant setup available in your account is the safer basis for a rollout decision.

    The same isolation rule applies to feed and bid tests. If you want to know whether a title improves sales, freeze bidding. If you want to know whether a bid strategy improves performance, freeze the product presentation. Testing both together may reveal whether the whole package performs differently, but it leaves you unable to identify the driver.

    Key takeaways

    • Start with the decision, not the Google Ads setting. A test needs one primary question and a predefined action for each possible result.
    • Keep measurement, traffic acquisition, and customer-facing presentation separate. Change one layer unless a bundled treatment is the decision you genuinely need to evaluate.
    • Use Manual CPC when explicit bid behavior is part of the hypothesis or when a narrow campaign requires direct control. Write the adjustment policy before changing bids.
    • Keep bidding stable when testing ads, landing pages, titles, or images. Otherwise, the traffic mix can become a second treatment.
    • Treat an inconclusive result as information. Do not manufacture a winner from a secondary metric or a favorable segment.
    • Use product data experiments when available to compare Shopping title and image variations without committing the treatment across the full feed.

    Open one campaign and write down the next decision it needs to support. Circle the single layer that must change, list the settings that will remain fixed, and define the primary outcome and stop conditions. Launch only when another person could read that plan and reach the same conclusion from the same result.

    References