Tag: Budget Management

  • How to Feed Paid Campaign Automation Better Business Data

    How to Feed Paid Campaign Automation Better Business Data

    Your campaign is producing cheaper leads, but sales says the pipeline is getting worse. That usually isn’t a bidding failure. It is a signal failure: the platform was told to find form submissions, so it found more people willing to submit a form.

    The way out is not another manual bid adjustment or a broader deployment of AI. You need a closed optimization loop that connects ad spend to qualified leads, customers and business value. Once that loop works, automation can pursue an outcome that is worth buying.

    Automation is an objective function, not a business strategy

    An automated bidder does not know what a good customer means to your company. It knows the events, values, budgets and targets you give it. If a form submission is the only event it can observe, a low-intent inquiry and a high-value opportunity can look identical.

    That creates a predictable failure mode. The system gets better at acquiring the easiest measurable action while the business cares about something further downstream. Lead volume rises, reported cost per lead falls and sales quality deteriorates. The dashboard can look healthier at the same time the economics get worse.

    SignalWhat it tells the bidderMain limitation
    ClickThis person visited after seeing an adIt says nothing about intent, qualification or revenue
    Form submissionThis person completed the tracked lead actionSpam, poor-fit inquiries and valuable prospects can receive equal credit
    Qualified leadThis lead met criteria agreed by marketing and salesThe definition must be applied consistently in the CRM
    CustomerThis lead became businessSales may be too infrequent or delayed to provide a useful learning signal on its own
    Customer valueThis outcome contributed a specific amount of valueInconsistent or incomplete values teach the wrong priority

    The best optimization event is therefore not automatically the deepest event in the funnel. It is the deepest meaningful event that occurs often enough, arrives quickly enough and is measured consistently enough for the system to learn from it. If customer purchases are sparse, a rigorously defined qualified lead may be a better bidding signal than the occasional sale. You can still report sales and revenue as the final business outcome.

    Keep three concepts separate. A funnel stage describes what happened. A conversion value expresses the relative economic importance of that outcome. A reporting KPI tells your team whether the campaign is creating acceptable business results. Confusing these roles is how a convenient CRM status code becomes an arbitrary value signal.

    Close the loop from the ad click to the CRM outcome
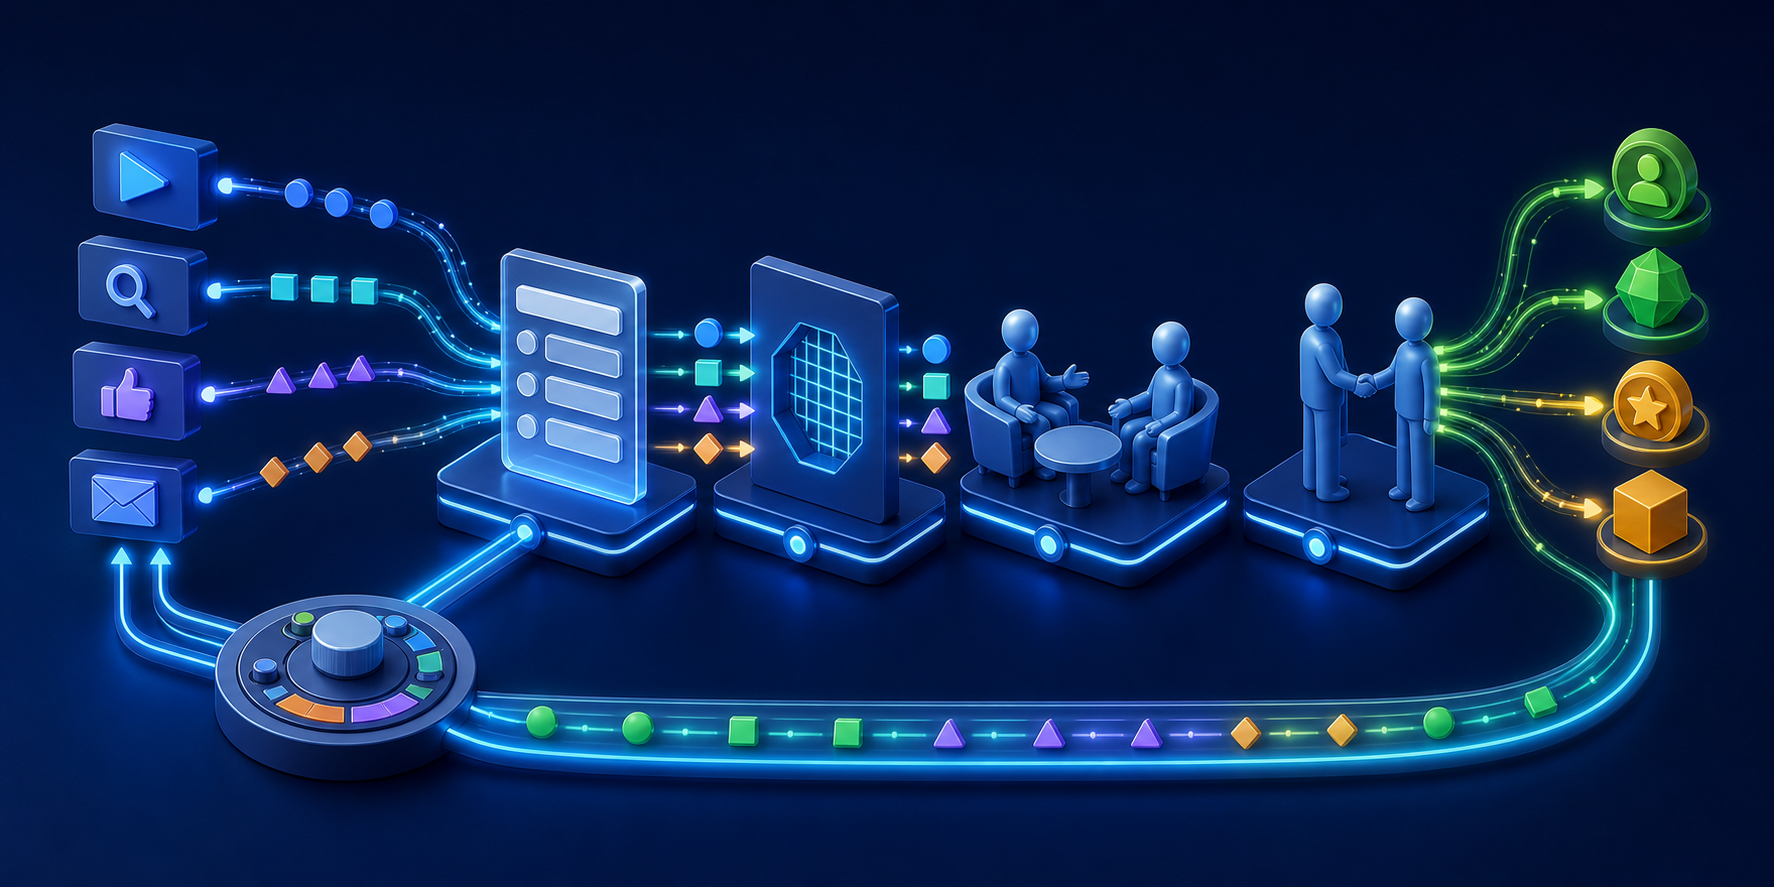
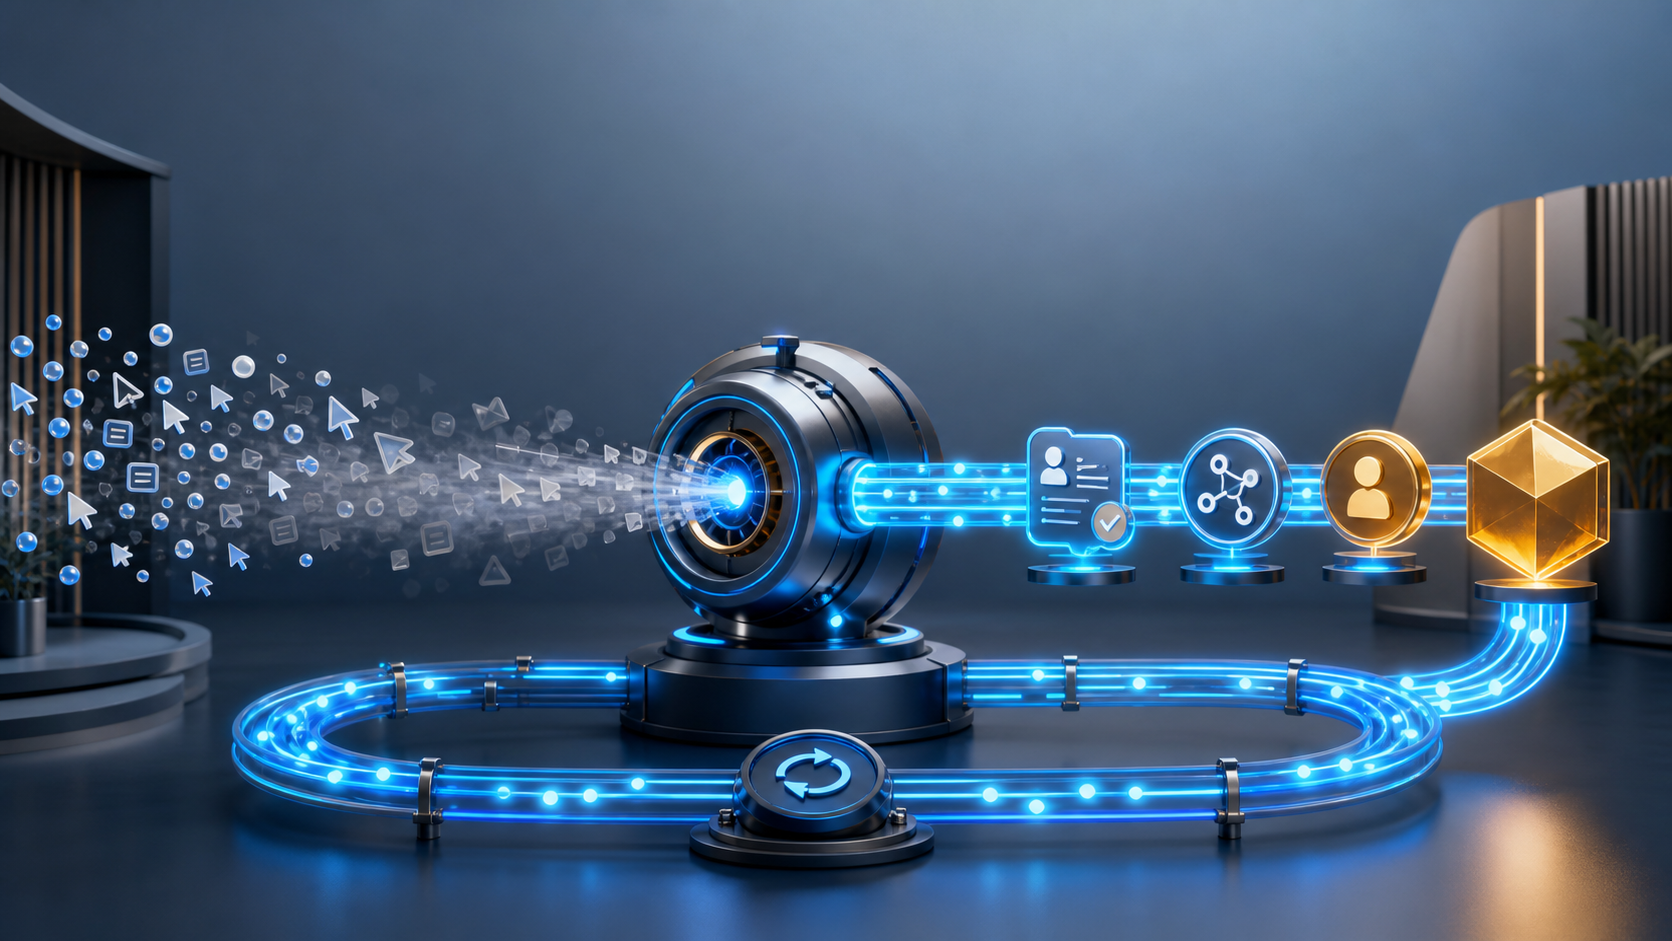
    A glowing data pathway follows an ad interaction through qualification, a sales conversation, and a customer outcome before looping back to campaign controls.

    Your CRM should return enough information for the ad platform to connect a later sales outcome with the original interaction. In Google Ads, that can involve a GCLID or first-party information such as an email address or phone number. The important part is continuity: the identifier must survive the landing page, form, CRM record and eventual conversion upload.

    1. Define qualification with sales. Start with observable criteria such as budget, service or location fit, and purchase timeline. A simple model is sufficient: 0 for not qualified, 1 for qualified and 2 for customer. Document who changes the stage and what evidence is required.
    2. Capture the matching data at the lead event. Preserve the click identifier and any permitted first-party matching fields when the form creates the CRM record. Capture only what your consent, privacy and retention rules allow.
    3. Track the outcome, not just the handoff. Record when a lead becomes qualified, is disqualified or becomes a customer. Include a clear reason when possible so marketing can distinguish poor targeting from duplicate, unreachable or otherwise invalid leads.
    4. Return outcomes on a dependable schedule. Google recommends sending offline conversion data regularly, ideally every day. GCLID-based offline conversions generally have to be uploaded within 90 days of the ad click, while enhanced conversions for leads using first-party data have a 63-day window. A technically correct integration can still lose useful outcomes if the upload arrives too late.
    5. Assign values separately from stage codes. A qualified lead can receive a consistent proxy value, while a customer can receive the value generated for the business. Do not accidentally use 0, 1 and 2 as monetary values merely because those numbers represent CRM stages.
    6. Reconcile the pipeline. Compare CRM stage counts with accepted and rejected platform uploads. Investigate missing identifiers, malformed first-party data, duplicate events and parameters lost between the ad, form and CRM before changing bids.

    The upload timing and matching details matter because Google Ads can learn from qualified and customer outcomes only when it can associate them with the original ad interactions. A daily job that silently rejects records is not a closed loop; it is an unreliable sample of your pipeline.

    Google has reported a median 10% conversion increase for advertisers using enhanced conversions for leads compared with standard offline conversion imports. That is a vendor-reported aggregate, not a forecast for your account. Treat improved matching as a way to recover observable outcomes, then judge the implementation by match coverage, qualified leads, customers and value – not by the claim alone.

    Before activating value-based bidding, inspect the data by campaign and week. Ask whether qualification is being applied consistently, whether values are present for the same kinds of outcomes and whether sales-cycle delay leaves recent periods incomplete. If the last part of the funnel is still changing, do not interpret a short-term drop as settled performance.

    Replace CPC micromanagement with business-aligned controls

    Paid platforms are steadily moving control away from individual click prices and toward objectives. Microsoft Advertising’s announced removal of Max CPC limits from new standalone Maximize Conversions, Maximize Conversion Value and Maximize Clicks campaigns makes that shift concrete. Existing campaigns retain their limits for now, while Target Impression Share, enhanced CPC and portfolio bid strategies continue to support them.

    Microsoft’s position is that a CPC cap can conflict with the stated performance target and disrupt spend pacing. Advertisers who used a cap as protection from unusually expensive clicks will have less direct control in affected new campaigns. That makes the quality of your conversion signal, budget and target more consequential, not less.

    Use each remaining control for the job it can actually do:

    • Budget: Set the amount of spend you are prepared to expose while the strategy learns. A bid target is not a substitute for a deliberate spending boundary.
    • Target CPA: Use it when the optimized conversions have reasonably similar business value. For lead generation, derive an affordable qualified-lead cost from an approved customer acquisition cost and the observed qualified-lead-to-customer close rate.
    • Target ROAS: Use it when conversion values differ meaningfully and those values are returned consistently. The target should reflect margin and payback requirements, not just top-line revenue.
    • Conversion value rules: Use them when the platform needs an explicit, defensible signal that some conversions are more valuable than others. The rule should express a real business distinction rather than compensate for a vague campaign structure.
    • Seasonality adjustments: Reserve them for known, temporary changes in expected conversion behavior. They should not become a recurring patch for weak tracking or unrealistic targets.

    Do not set a target merely to state the result you want. A target is an instruction that changes how the bidder enters auctions. If it is detached from observed performance and unit economics, it can restrict useful volume or encourage the system to pursue an outcome your CRM does not value.

    Test material changes through an optimization experiment where the platform supports one. In particular, test the effect of removing a CPC cap before rebuilding campaigns around a control that may no longer be available. Hold the conversion definition steady, avoid changing the budget and target at the same time, and evaluate qualified volume, customer value and acquisition economics alongside CPC. A cheaper click is not a win if it produces a weaker pipeline.

    Use AI analysis to generate hypotheses, not spending authority
    A campaign operator reviews AI-generated test possibilities while a locked control gate keeps the analysis separate from a reservoir of budget tokens.

    Generative AI can shorten the distance between a performance question and a usable analysis. Meta is rolling out connections between Meta AI, Meta Ads campaigns and Google Workspace, allowing the assistant to examine campaign performance with additional business context. It can surface audience, creative and budget patterns, generate reports, and support recurring analysis.

    That is useful analyst work, but it does not make the assistant the owner of your budget. A platform’s AI can identify patterns inside the information it can access. It cannot decide whether a reported conversion is incremental, whether the revenue is profitable or whether spending more on that platform is the best use of the next dollar unless you supply the relevant evidence and constraints. It is also advising you inside the advertising system whose spend it is analyzing.

    Give the assistant a structured request instead of asking, “How should I optimize this campaign?” A good request contains four elements:

    • Business objective: Qualified leads, customers or customer value – not an undefined request for better performance.
    • Evidence boundary: The campaigns, date range, attribution definition and CRM fields it may use.
    • Constraints: Budget limits, excluded audiences, minimum qualification requirements and any changes that require human approval.
    • Output contract: Observations first, followed by hypotheses, supporting metrics, possible confounders and a proposed test for each recommendation.

    Reusable request: Review the completed reporting period using qualified leads and customer value from the connected business data where available. Separate observations from recommendations. For each proposed audience, creative or budget change, show the supporting segment and metric, name a plausible confounder, propose one controlled test and state the condition that would cause us to reverse the change. Do not treat form submissions as qualified leads unless their CRM status confirms it.

    This format forces the AI to expose the path from evidence to recommendation. It also makes weak suggestions easier to reject. If a proposed budget increase is supported only by platform-reported conversion volume while CRM qualification is falling, the recommendation is incomplete.

    Recurring tasks are best used for stable checks: creative deterioration, audience shifts, budget concentration, missing CRM data and changes in qualified-lead rate. Automating the report is reasonable. Automating approval is a separate decision with direct financial consequences. Keep a human gate until the data definitions, decision rules and rollback process have proved dependable.

    Key takeaways for your next optimization cycle

    • Optimize toward the deepest business outcome that is meaningful, timely and frequent enough to provide a usable signal.
    • Return CRM outcomes regularly and monitor match failures; a scheduled upload is not useful if identifiers are missing or records arrive outside platform windows.
    • Keep funnel stages, conversion values and reporting KPIs separate so an internal status code does not become an accidental bidding instruction.
    • Use budgets, tCPA, tROAS, value rules and controlled experiments as primary levers when CPC limits are unavailable or conflict with the objective.
    • Treat AI recommendations as testable hypotheses. Require business metrics, supporting evidence, confounders and a rollback condition before changing spend.

    Start with one important campaign. Trace a recent conversion from the ad interaction through the form, CRM qualification and customer outcome. If the trace stops at the form submission, repair that handoff before adjusting the bidding strategy. Once the downstream signal is reliable, run one controlled experiment and let qualified pipeline value – not the number of dashboard conversions – decide what you scale.

    References


  • How to Plan and Test Google AI Max Search Campaigns

    How to Plan and Test Google AI Max Search Campaigns

    You have reached the awkward point in an AI Max rollout: enabling automation is easy, but proving that it deserves more budget or a different ROI target is not. A promising campaign-level result can still leave you unsure whether the broader campaign portfolio improved.

    Google’s expanded planning stack gives you a cleaner way to make that decision. You can forecast bidding and budget changes, test budgets or ROI targets across multiple Search campaigns, and retain brand and location controls in AI Max experiments. The value comes from using those capabilities in the right order: forecast the opportunity, test the decision, then implement only what the evidence supports.

    Key takeaways

    • Use Performance Planner to form a hypothesis, not to prove that a proposed change will work.
    • Use a multi-campaign A/B test when the real decision affects a group of Search campaigns rather than one campaign in isolation.
    • Keep brand and location controls in place when they represent genuine business requirements, and hold them consistent between the control and treatment.
    • Define success for the entire tested portfolio before looking at individual campaign winners and losers.
    • Treat one-click application as an execution shortcut, not as a substitute for review and approval.

    Separate forecasting, experimentation and rollout

    Campaign tokens pass through separate forecasting, controlled experiment, and rollout work zones.

    The three stages answer different questions. Performance Planner estimates what could happen under changed inputs. An A/B test measures what happens when a defined treatment competes with a control. A rollout turns the supported treatment into a live operating decision.

    Problems start when those stages blur. A forecast may justify running a test, but it cannot establish incremental impact. A positive experiment can justify adopting the tested treatment, but it does not automatically validate larger changes, different campaigns or fewer guardrails.

    CapabilityQuestion it should answerWhat it cannot establish by itself
    Performance PlannerWhat outcome might follow from a proposed bidding or budget change?Whether the change caused an incremental improvement.
    Multi-campaign A/B testDoes a changed budget or ROI target improve results across the selected Search campaign portfolio?Whether the same treatment will work outside the campaigns and conditions tested.
    AI Max experiment with controlsWhat is AI Max’s impact while required brand and location rules remain in force?How AI Max would perform with different or removed guardrails.
    Controlled rolloutCan the tested change be adopted without breaching an operational or financial limit?Whether a more aggressive, untested version is also safe.

    This separation also prevents a common reporting mistake: presenting predicted performance and observed experiment results as if they were equivalent evidence. Label forecasts as forecasts, test results as test results and post-rollout monitoring as monitoring.

    Write the decision rule before opening Performance Planner

    Do not begin with a vague instruction such as “find more volume” or “improve AI Max performance.” Begin with one decision that an experiment can resolve. A useful question identifies the campaign set, the lever, the desired business outcome and the limit you will not cross.

    Use this structure:

    If we change [budget or ROI target] across [named Search campaigns], does [primary portfolio outcome] improve enough to justify adoption without violating [business guardrail]?

    Complete a short decision brief before generating scenarios:

    • Campaign scope: Name every campaign included. Group campaigns that serve a shared business objective and use compatible conversion economics. If one campaign values a conversion very differently from another, a combined result may be difficult to act on.
    • Treatment: State whether you are changing budgets, ROI targets or AI Max itself. Avoid bundling unrelated changes into the same treatment.
    • Primary outcome: Choose the portfolio-level result that will decide adoption. Use the conversion actions and value logic that reflect the business outcome, not whichever interface metric happens to move most dramatically.
    • Required controls: Record the brand and location restrictions that must remain active. These are test conditions, not implementation details to reconstruct later.
    • Financial boundary: Set the maximum spend, minimum acceptable return or other limit your business requires. The threshold must come from your economics, not from a platform recommendation.
    • Invalidation conditions: Decide what would make the test unreliable, such as broken conversion tracking, a major landing-page change or an unusual operational interruption.
    • Decision owner: Name the person who can approve the live budget or target change. A technically positive result should not bypass financial accountability.

    Budget and ROI tests also answer different business questions. A budget test asks whether the portfolio can absorb additional spend while preserving acceptable economics. An ROI-target test asks whether the change in volume is worth the corresponding movement in efficiency. Pick the question you actually need answered instead of changing both levers merely because both are available.

    Turn the Performance Planner forecast into a testable hypothesis

    Performance Planner is being expanded so advertisers can forecast how changes such as bidding or budget targets may affect existing campaign performance. That makes it useful for narrowing the options before you expose live spend to a treatment.

    A disciplined planning pass looks like this:

    1. Capture the current state. Record the campaigns, live budgets, live targets, required controls and the measurement configuration attached to the decision.
    2. Model one decision family at a time. Examine the proposed budget change separately from an ROI-target change. If several inputs move together, you will not know which assumption produced the forecasted difference.
    3. Inspect the portfolio and its distribution. A stronger total can conceal that the projected gain is concentrated in a small part of the campaign set. Note which campaigns appear to contribute the change so you know what to inspect after the test.
    4. Reject scenarios the business cannot support. A forecast is not useful if the treatment requires spend, lead capacity, inventory or geographic coverage that the business cannot accommodate.
    5. Convert the surviving scenario into a hypothesis. Write the exact treatment you intend to test and the guardrail it must satisfy.

    A practical hypothesis is specific without pretending the forecast is a guarantee: Across [campaign set], changing [selected lever] from [current setting] to [proposed setting] is expected to improve [portfolio outcome] while keeping [guardrail] within its approved boundary. We will require an experiment before adopting the change across the full scope.

    Google also allows suggested Performance Planner changes to be applied directly to campaigns with one click. That shortens execution, but it does not reduce the financial consequence of a wrong setting. Do not click through until someone has verified the campaigns, proposed values, approval and recovery plan.

    Build the A/B test around the portfolio decision

    The multi-campaign capability scheduled for September will let advertisers test different budgets and ROI targets across multiple Search campaigns in one A/B test. Use that broader scope when management will ultimately approve or reject the change for a campaign group rather than campaign by campaign.

    Set up the experiment so the answer remains interpretable:

    1. Select a coherent campaign set. Include campaigns connected to the same decision. Do not create a larger test merely to make the result look more comprehensive.
    2. Keep the control recognizable. The control should preserve the current operating approach. Document it well enough that you can tell whether an unrelated change altered the comparison.
    3. Change only the intended decision family. If the question concerns budgets, avoid changing ROI targets, measurement rules and landing pages at the same time. If the question concerns an ROI target, keep the budget treatment and other settings as stable as the test design allows.
    4. Apply the same required guardrails. AI Max experiments will support brand and location controls, so businesses do not have to remove those restrictions merely to run the experiment. Verify that both sides reflect the intended rules. Otherwise, you are testing AI Max plus a control change.
    5. Preselect the portfolio decision metric. Decide which aggregate outcome determines adoption. Campaign-level metrics can diagnose where the effect came from, but they should not be cherry-picked afterward to replace the original decision rule.
    6. Log concurrent changes. Record changes to conversion tracking, offers, landing pages, inventory, pricing and other conditions that could complicate interpretation.
    7. Wait for an interpretable result. Do not declare a winner because an early difference looks attractive. Use the experiment’s completed readout and check that the business conditions remained valid for the comparison.

    Preserving controls does not prove that the controls themselves are optimal. It answers a narrower and more useful question: whether AI Max adds value under the constraints your business is actually prepared to keep. If you later want to test a different brand or location policy, treat that as a separate decision.

    Translate the result into a controlled budget decision

    Measured streams of budget particles flow through controlled valves into a connected portfolio of campaign vessels.

    The experiment is finished only when its outcome maps to a predefined action. Use the following decision patterns instead of looking for a metric that supports the change you already wanted:

    • Positive portfolio result, guardrails met: Adopt the treatment only for the campaign scope and settings that were tested. A positive result at one budget or target does not validate a more aggressive value.
    • Positive total, concentrated in a few campaigns: Inspect the distribution before an account-wide rollout. The aggregate result may be valid while the correct implementation scope is narrower.
    • More volume, financial boundary missed: Treat the test as unsuccessful under the original rule. Additional conversions do not compensate for breaching a required ROI or spend constraint unless the business explicitly changes that constraint.
    • No interpretable difference: Do not relabel the forecast as proof. Check whether the campaign scope, measurement or operating conditions prevented a useful answer, then revise and rerun only if the decision still matters.
    • Negative result: Keep the control. Record what was tested so the same unsupported treatment is not reintroduced later as a new recommendation.

    If you decide to implement a suggested change directly from Performance Planner, use a short release check:

    1. Confirm the exact campaigns, budgets and targets that will change.
    2. Record the current live values so they can be restored if a business guardrail is breached.
    3. Obtain approval from the budget owner before applying the change.
    4. Apply only the tested treatment to the approved scope.
    5. Monitor tracking, spend and the predefined business guardrail after launch; do not replace the experiment’s decision metric with a more flattering one.

    Your next step is small and concrete: choose one unresolved budget, ROI-target or AI Max decision, write its portfolio-level success rule, and use Performance Planner to define the treatment worth testing. That sequence turns new automation into a governed business decision rather than a leap of faith.

    References


  • Google Ads Automation: A Conversion Optimization Playbook

    Google Ads Automation: A Conversion Optimization Playbook

    Google Ads can hit a platform target while missing the outcome your business actually needs. That usually happens when automation receives a clean numerical instruction built on a weak business definition: the wrong conversion, an incomplete value, a target detached from margin, or a view-through action treated like a click.

    If you are deciding whether to loosen a target, raise a budget, accept a Demand Gen default, or retest an automated feature, use the framework below. It turns those settings into business decisions you can explain, measure, and reverse.

    Start with conversion economics, not the bid strategy

    A balance scale compares a conversion token with separate stacks representing cost, revenue, and margin beside a transparent funnel and two blank control dials.

    Smart Bidding is not a substitute for strategy. It can choose auctions and bids in pursuit of the conversion goals you supply, but it cannot repair business economics that were never encoded in those goals.

    Before touching a campaign setting, write a one-sentence optimization mandate:

    For this campaign, maximize [the desired conversion or conversion value] within [the available budget], while protecting [the business efficiency requirement], using [the eligible conversion goals] and evaluating results after [the full conversion cycle].

    Fill the brackets with account facts, not aspirations. If you cannot complete the sentence without arguing about what a conversion is worth, the account is not ready for another bidding change.

    DecisionQuestion to answerWhat to fix before automation
    Business outcomeAre you buying revenue, qualified leads, purchases, subscriptions, or another result?Name the outcome the business will recognize as success.
    Primary conversionWhich recorded action is close enough to that outcome to guide bids?Keep low-intent or diagnostic events from competing with the outcome you really want.
    Conversion valueDo recorded values reflect meaningful differences between outcomes?Correct missing, duplicated, or misleading values before relying on value optimization.
    Efficiency requirementIs the business protecting an acquisition cost, a return target, or total spend?Choose the constraint that matters outside the Google Ads interface.
    Operating contextAre promotions, inventory availability, or margins changing?Record the change so bidding results are not interpreted without business context.
    Conversion cycleHow long does it take for enough conversions and value to be reported?Do not judge an incomplete period as though all outcomes have arrived.

    The conversion cycle matters most when recent performance appears to deteriorate immediately after a change. If conversions arrive with delay, the newest period is structurally incomplete. Review performance only after accounting for the full conversion cycle, especially before changing a target in response to early data.

    Context outside the ad account matters too. A campaign can report more conversion value while selling low-margin products, pushing unavailable inventory, or benefiting from a promotion that will soon end. Promotions, stock availability, and product margins therefore belong in the bidding decision, not in a separate conversation after results arrive. Treating these business conditions as bidding inputs keeps a platform improvement from becoming a commercial disappointment.

    Use budgets and targets as separate controls

    A budget expresses how much the campaign may use. A target expresses the efficiency you want the bidding system to pursue. They are related, but they do not answer the same question.

    This distinction becomes critical when a campaign is both limited by budget and beating its target. A Smart Bidding change described for this exact combination can alter the auctions entered, bids, and CPCs. Campaigns that are not budget constrained already operate in this way, while campaigns that do not meet both conditions should not be diagnosed as though they do. Start by identifying which campaigns are actually affected.

    Campaign stateWhat it tells youPractical response
    Not limited by budgetThe budget-constrained condition is absent.Investigate conversion mix, market conditions, targets, assets, and measurement before blaming this mechanism.
    Limited by budget but not beating the targetThe campaign does not meet the complete affected combination.Do not loosen the target merely to explain a change that does not apply to this state.
    Limited by budget and beating the targetThe auction mix, bids, and CPCs may change while the target remains in place.Review average performance after the full conversion cycle, then decide whether the priority is preserving efficiency or pursuing more volume within the budget.

    Do not treat the target as a historical description or a promise. It is an efficiency lever. If current results are substantially better than the target and the campaign is budget limited, leaving the target unchanged can give the system room to pursue different opportunities. Whether that is acceptable depends on the business outcome, not on whether CPC rises or falls.

    Choose the strategy from the constraint:

    • When the budget is fixed and additional conversion volume is the priority: Maximize Conversions without a target remains an available approach.
    • When the budget is fixed and total conversion value is the priority: Maximize Conversion Value without a target remains available.
    • When an efficiency requirement is commercially binding: use a meaningful target and accept that it may restrict the opportunities the system can pursue.
    • When stakeholders demand fixed spend, fixed volume, and fixed efficiency simultaneously: surface the conflict. No bidding strategy can guarantee all of them under every auction condition.

    The two untargeted maximize strategies are specifically available to advertisers that must work within a defined campaign budget. That does not make them universally better. It means they are coherent choices when budget is the firm control and the conversion objective is trustworthy.

    Judge the change using the metric named in your optimization mandate. If the objective is higher conversion value, CPC alone cannot tell you whether the test succeeded. A higher CPC may be acceptable if the resulting value and business efficiency improve; a lower CPC is not a win if it buys weaker outcomes. Match the evaluation metric to the result the business asked the campaign to produce.

    Audit Demand Gen view-through optimization separately

    A view-through conversion credits an outcome after someone sees an ad without necessarily clicking it. That can capture influence that click-only reporting misses, but it is not the same interaction as a click-led conversion. Your bidding and reporting choices should preserve that distinction.

    Google’s announced Demand Gen rollout changes both the optimization signal and the billing model. Because the changes were scheduled to roll out over a period of months, verify the settings and behavior visible in each account rather than assuming every campaign is already in the same state.

    • View-through bidding becomes video-only. In existing campaigns, image-asset view-through conversions can remain visible as secondary conversions, but they are no longer eligible for bidding or included in the primary Conversions column.
    • New Demand Gen campaigns get view-through optimization by default. An advertiser that does not want it must opt out during setup. Existing campaigns retain their current setting rather than being automatically enrolled.
    • Eligible inventory expands. View-through optimization extends beyond YouTube and the Discover Feed to the Google Display Network.
    • Display video billing moves to CPM. Video assets served on Display are billed by impressions rather than clicks, whether or not view-through optimization is enabled.

    Those optimization, default, inventory, and billing changes create two separate decisions. The first is whether view-through conversions should guide bidding. The second is whether the campaign should serve video on Display inventory billed by impressions. Opting out of view-through optimization does not restore CPC billing for those Display video assets.

    Run this audit before launching or materially changing Demand Gen:

    1. Record the view-through setting. Check the campaign configuration itself, especially for a new campaign where the announced default is enabled.
    2. Separate optimization eligibility from reporting. An image view-through conversion appearing as a secondary conversion in an existing campaign does not mean it is still directing bids.
    3. Review the asset mix. An image-heavy campaign may show historical view-through activity that no longer participates in optimization, while video receives the eligible signal.
    4. Inspect inventory and billing together. Once Display video is billed on CPM, impression delivery and cost become necessary context; CPC is no longer the billing basis for that inventory.
    5. Compare downstream quality. Assess whether view-through-attributed outcomes produce the business result named in your mandate instead of assuming every credited conversion has equal value.
    6. Document the decision. Record why view-through optimization is included or excluded so a future default, rebuild, or handoff does not silently reverse the strategy.

    The common reporting mistake is to interpret a change in the primary Conversions column as a change in customer behavior. For existing image-heavy campaigns, part of the movement may instead come from image view-through conversions being moved to secondary reporting and removed from bidding eligibility. Check the conversion-action breakdown before explaining the result as a market shift.

    Make controlled testing the guardrail around automation

    Two matching streams of digital signals pass through parallel test lanes, with one automated module adjusted while the other remains locked as a control.

    An automated feature that failed previously has not earned a permanent rejection. Google’s models and infrastructure can change behind the scenes, so the same campaign approach may behave differently after later system improvements. That is a reason to retest selectively, not a reason to switch everything back on.

    A defensible retest needs a business hypothesis, a suitable success metric, a defined scope, and enough time for the conversion cycle to complete. Where possible, reserve a dedicated testing budget so experimentation is intentional rather than an unplanned draw on core activity.

    Write a test brief before making the change:

    • Business question: What uncertainty will the test resolve?
    • Hypothesis: Which setting or feature should change which business outcome, and why?
    • Scope: Which campaigns, assets, goals, audiences, or inventory are included?
    • Baseline: What pre-change state will you use for comparison?
    • Primary metric: Which measure determines success?
    • Guardrails: Which cost, quality, budget, or volume outcomes would make the result unacceptable?
    • Conversion cycle: When will the data be mature enough to interpret?
    • Decision rule: What evidence leads to adoption, another test, or rollback?
    • Change record: Who owns the test, what changed, and how can the prior configuration be restored?

    Isolate the control under test where practical. If you change the bid strategy, conversion goals, budget, target, creative mix, and inventory at the same time, even a strong result will not tell you what to keep. When several changes are unavoidable, record them explicitly and narrow the claim you make from the outcome.

    AI-generated account advice needs the same scrutiny. Tools such as Ask Advisor can help surface ideas, but newer AI systems should not be treated as perfectly accurate instructions. Use them to form questions and candidate actions, then verify the affected campaigns, current implementation, and business logic before making a change. That continued need for expert review of AI recommendations is a feature of responsible automation, not resistance to it.

    Read the Help Center material linked from the relevant setting as part of that verification. Documentation can lag a rollout, but it may still contain implementation details that are easy to miss in the interface. Compare the documentation with what the account actually exposes before applying broad advice.

    Automation also increases the reach of setup errors. Before launch, use an independent review for budgets, targets, conversion goals, network eligibility, asset mix, and default opt-ins. If an error causes spend or data damage, contain it, establish what was affected, communicate plainly, and improve the process that allowed it. Leadership should own the team’s output rather than blaming a junior operator in front of a client; the useful question is which control failed and how it will be strengthened.

    Key takeaways

    • Give automation a business outcome, a trustworthy conversion signal, and an explicit constraint before changing bids.
    • Do not confuse budget and target: budget controls available spend, while the target steers efficiency.
    • Check whether a campaign is both budget limited and beating its target before attributing performance changes to the relevant Smart Bidding behavior.
    • For a fixed budget, untargeted Maximize Conversions or Maximize Conversion Value may fit when volume or value is the priority.
    • In Demand Gen, audit view-through eligibility, default settings, asset type, inventory, and CPM billing as separate but connected controls.
    • Retest automated features only with a written hypothesis, mature conversion data, business-level success metrics, guardrails, and a rollback path.
    • Treat AI recommendations as proposals requiring account and business review, not as authorization to make changes.

    Before your next optimization cycle, complete the one-sentence mandate for the campaign you plan to change. Then verify its budget status, target performance, conversion maturity, and Demand Gen defaults. Make the smallest change that answers a defined business question, and leave a record clear enough for the next operator to understand why it was made.

    References


  • Paid Search Incrementality Testing: A Practical Framework

    Paid Search Incrementality Testing: A Practical Framework

    You may know exactly how much revenue Google Ads claims and still not know how much revenue the ads created. That gap matters most when branded campaigns, strong organic rankings, and direct traffic all reach the same customer.

    A paid search incrementality test replaces that ambiguity with a controlled absence. You pause a defined slice of advertising, measure what actually disappears and what moves elsewhere, then compare the incremental loss with the spend you avoided. The goal isn’t to prove that paid search works or doesn’t. It is to identify where it acquires demand, where it supports another channel, and where it charges you for demand you already own.

    Attribution records a route; incrementality measures an effect

    Platform attribution answers, “Which tracked interaction received credit?” Incrementality answers, “What would have happened without this interaction?” Only the second question tells you whether removing or reducing spend would materially change the business outcome.

    Suppose a customer searches your company name, clicks an ad above your top organic result, and buys. The advertising platform can correctly record the ad click while still overstating the ad’s causal value. The unresolved question is whether that same customer would have clicked the organic listing and bought anyway.

    You can’t settle that question with last-click, first-click, data-driven, or multi-touch attribution alone. Changing the credit rule redistributes recorded value among observed touches. It doesn’t create the missing counterfactual.

    The prior evidence is genuinely mixed. Google’s pause experiments across more than 400 advertisers estimated that 89% of ad clicks were incremental on average, while eBay’s branded-search experiment found that almost all missing paid clicks and sales moved to organic. Google’s result is platform-supplied evidence, and neither finding is a universal rule. The difference is the point: brand strength, organic visibility, query type, competition, and account structure can produce very different answers.

    For a useful diagnosis, classify paid search at the query or campaign level:

    ClassificationWhat it meansWhat you should test or decide
    IncrementalPaid search reaches customers or produces outcomes that your other channels would not have captured.Keep it when incremental contribution exceeds its cost; test expansion separately.
    DependentOrganic or another channel performs worse when paid support disappears.Measure the combined channel effect and avoid treating paid and organic as isolated budgets.
    CannibalizedThe ad captures a click or conversion that a strong unpaid result was already positioned to win.Reduce or pause the affected slice while monitoring total revenue, query clicks, and competitive pressure.

    These aren’t permanent labels. A branded query can be largely cannibalized while you rank first, then become more incremental if organic visibility falls or a competitor changes the search results. Your test should therefore support a budget rule with conditions, not a timeless verdict about the channel.

    Key takeaways

    • Test a material but reversible slice of spend instead of switching off the entire account by default.
    • Judge the test on total business outcomes, not on the revenue that disappears from the advertising platform’s report.
    • Separate branded search, non-brand search, Shopping, and Performance Max because their substitution patterns can differ.
    • Join paid search-term data with organic query data before the pause so you know where paid and organic already overlap.
    • Allow for delayed substitution. A short test can make paid search look more incremental than it is if customers and reporting take time to move.
    • Make the final decision with incremental contribution or profit, not attributed ROAS.

    Design the pause around one budget decision

    Matched groups of campaign tiles arranged for a controlled experiment, with one bounded set removed beside a stack of budget tokens.

    A broad question such as “Does paid search work?” cannot produce a clean action. Define the decision first: whether to keep branded ads in a particular market, reduce spend on terms where you already rank strongly, or retain a non-brand campaign that appears to introduce new customers.

    Then write the test plan before changing the campaigns:

    1. State the counterfactual. Write what you expect customers to do when the selected ads disappear. For example, they may move to organic listings, arrive directly, choose a competitor, or not visit at all. This forces you to measure the channels where substitution should appear.
    2. Choose one testable slice. Isolate branded search from non-brand search, Shopping, and Performance Max. A result from brand terms should not be used to cut prospecting campaigns whose job and audience are different.
    3. Select the test unit. A campaign, coherent query group, or market can be paused while a comparable unit remains active. A credible control helps distinguish the pause from seasonality, promotions, or a general change in demand. If no good control exists, be explicit that a pre-versus-post result carries more uncertainty.
    4. Lock the primary outcome. Use total revenue, qualified leads, purchases, or another business result that exists outside the ad platform. Record paid-attributed revenue, organic revenue, direct revenue, organic clicks, and total query clicks as diagnostic measures rather than competing versions of success.
    5. Define the economic rule. Decide in advance how you will compare the incremental outcome with avoided media cost. Where margin data is available, use contribution rather than revenue; otherwise a high-revenue, low-margin campaign can appear more valuable than it is.
    6. Record known disruptions. Promotions, price changes, inventory constraints, site outages, tracking changes, SEO releases, and brand publicity can alter the same metrics as the pause. Log them during the test and exclude or qualify affected periods instead of explaining them away after seeing the result.
    7. Set exposure and rollback conditions. Specify the largest acceptable business loss before launch. If the downside could be material, stage the pause or use a narrower market. Don’t invent the rollback threshold after an uncomfortable result appears.
    8. Declare the observation window. Include enough time for buying cycles, channel switching, and revenue reporting to settle. One documented pause recovered 30% of paid-attributed revenue through organic and direct within six weeks, but that figure rose to 65% by week 13. That is evidence that substitution can lag, not a universal thirteen-week minimum.

    Build the overlap baseline before you pause

    Export Google Ads search terms with their spend and outcomes, then export matching Google Search Console queries and organic clicks for the same dates. Normalize obvious differences such as capitalization and whitespace, but preserve query intent. A brand name, a brand-plus-product query, and a generic category query shouldn’t be collapsed into one row merely because all three contain the company name.

    For each matched query, record paid clicks, paid spend, paid outcomes, organic clicks, and whether a meaningful organic result is present. This gives you a map of expensive overlap. It does not prove cannibalization on its own: customers can still respond differently when both listings appear. The pause provides the causal evidence; the query join tells you where to look and how to interpret the movement.

    Protect the business without protecting the assumption

    A total-account blackout can create unnecessary financial exposure. Choose the largest coherent slice whose potential loss the business can tolerate, while retaining enough volume to produce a useful signal. If a small unit cannot distinguish normal variation from a real effect, acknowledge that limitation or have an analyst assess the design before increasing exposure.

    Monitor competitor activity on branded results during the pause, but don’t treat a competitor impression as proof that your ad is incremental. The relevant outcome is whether the changed results cause a measurable loss in total clicks, conversions, revenue, or contribution. Brand protection can be a legitimate job for paid search; it should be named and valued as protection rather than reported as customer acquisition.

    Measure substitution outside the advertising dashboard

    Customer tokens reroute from a paused paid channel into several other acquisition paths, while some demand disappears before reaching the shared sales destination.

    The moment you pause ads, paid clicks and paid-attributed revenue will fall. That is an implementation check, not the test result. The result is the difference between the total outcome you observed and the total outcome you would reasonably have expected with the ads still running.

    Use a comparable control market or campaign when you have one. Measure how the control changed over the same period, then apply that movement to the test unit’s baseline. This is more defensible than assuming the week before the pause would otherwise have repeated exactly. Without a control, compare against a predeclared baseline and carry the added uncertainty into the decision.

    Calculate the readout in this order:

    1. Estimate the paid-on counterfactual. Determine the total revenue, purchases, or qualified leads you would have expected in the test unit if ads had remained active.
    2. Measure the total incremental loss. Subtract the observed total outcome during the pause from the paid-on counterfactual. This is the business effect attributable to removing the ads, subject to the design’s uncertainty.
    3. Measure channel substitution. Compare organic, direct, and any other plausible substitute channels with their counterfactual levels. Use these movements to explain where demand went, not to override the total-outcome calculation.
    4. Calculate recapture. Divide verified substitute-channel lift by the paid-attributed revenue that disappeared. State clearly which channels were counted and how their counterfactuals were estimated.
    5. Compare incremental value with avoided cost. For a revenue-based view, divide the incremental revenue preserved by the ad spend required to preserve it. For the economic decision, apply the relevant contribution margin and subtract media cost.

    Direct traffic deserves special care. A rise in direct revenue may represent people who saw no ad and typed the address, customers returning through bookmarks, or a change in how analytics classified the visit. The first two can be genuine substitution; the third is measurement reclassification. Look for timing, market specificity, and corresponding stability in total business outcomes before counting the entire increase as recaptured demand.

    The same caution applies to organic traffic. More organic clicks after a pause are persuasive when they occur on the affected queries, in the affected market, during the declared window, and alongside the expected loss of paid clicks. A sitewide organic increase caused by an unrelated SEO release shouldn’t be credited to paid-search substitution.

    What a delayed recapture looks like in practice

    One company paused branded search in the United States, United Kingdom, Australia, and Canada, then paused most non-brand paid search by the end of the month. Its prior spend across branded search, non-brand search, Shopping, and Performance Max averaged $113,000 per month. In one branded campaign, organic already held 71% of overlapping clicks while ads were active, and only $3,945 of $36,129 in spend appeared to purchase clicks that organic could not capture. The remaining $32,184, or 89.1%, functioned as brand defense in that analysis.

    Time after the pauseMonthly organic revenue changeMonthly direct revenue changePaid-attributed revenue recaptured
    Weeks 1-6+$17,800+$14,50030%
    Weeks 7-12+$28,100+$14,10039%
    Week 13 onward+$15,800+$54,00065%

    The important pattern is the delay, not a benchmark you should copy. A six-week read would have made the ads appear much more incremental than the later observation did. The shift toward direct revenue also shows why a paid-versus-organic traffic comparison is too narrow: substitution can cross both channel and attribution boundaries.

    Don’t treat the remaining 35% as automatically incremental. Some of it may be a real paid-search effect, but the strength of that conclusion depends on the counterfactual, controls, tracking, and outside events. Report the observed total loss, the estimated substitute lift, the avoided spend, and the uncertainty separately. A single blended percentage hides the assumptions leadership needs to judge.

    Turn the result into campaign-level budget rules

    An incrementality test should end with a rule someone can execute in the account. “Paid search is incremental” and “brand ads are wasteful” are both too broad.

    • High incremental contribution: retain the tested campaign when the contribution it protects exceeds media cost. Treat expansion as a new hypothesis; the next dollar may not perform like the current dollar.
    • Low incrementality with strong organic substitution: keep the slice paused or reduce it, then monitor organic visibility, total query clicks, revenue, and competitor pressure. Define the conditions that would trigger a retest or restart.
    • Dependent organic performance: manage paid and organic as a combined search system. Investigate which queries lost total clicks or outcomes rather than assuming that an organic ranking alone guarantees replacement.
    • Primarily defensive value: label the budget as brand protection. Decide whether the measured conversion or revenue loss justifies that protection instead of letting attributed ROAS disguise it as acquisition.
    • Uncertain result: don’t force a binary decision. Restore only what is required by the predeclared guardrail, improve the control or measurement, and run a better-bounded test.

    Keep a permanent test record containing the hypothesis, test and control units, campaign changes, baseline dates, primary outcome, rollback rule, exclusions, calculation method, and final decision. Revisit the rule when organic visibility changes, competitors become more aggressive, margins shift, tracking changes, or the campaign begins serving a materially different mix of queries.

    Your next step is to choose one material but reversible slice of paid search. Write its counterfactual, export the paid-organic overlap, lock the business guardrail, and schedule the readout far enough beyond the pause to observe substitution. If the spend returns, it should return with a clear job description: acquisition, channel support, or brand defense. If it doesn’t, you can redirect the budget toward demand you weren’t already positioned to capture.

    References


  • Performance Max Local Customer Optimization: Setup Guide

    Performance Max Local Customer Optimization: Setup Guide

    You want more people to walk into a location, request directions or contact the business while they are nearby. The difficult part is making sure Performance Max is optimizing for those local actions rather than treating the campaign like a general online acquisition campaign.

    Local customer optimization gives you a more focused option, but eligibility depends on how the campaign is built. Before you turn it on, check the campaign goals and product-feed setup. That decision will tell you whether to update the existing campaign or create a separate store-goals campaign.

    What Local customer optimization changes

    Local customer optimization is available for Performance Max campaigns with store goals. When enabled, it prioritizes delivery toward nearby people who appear ready to visit, navigate to or contact a business. That includes people planning trips, actively navigating or searching for nearby businesses across Google Maps, Waze and local formats on Google Search.

    The important word is prioritizes. This is an automated delivery preference for high-intent local customers, not a promise that every impression will produce a store visit. Your selected store goals still determine what the campaign is trying to accomplish.

    Use the setting when the campaign’s primary job is generating physical-location outcomes. Store visits, direction requests and store sales are the relevant goal types named for this setup. If your real priority is an online purchase or a product-feed sale, this isn’t a switch to add casually to the same campaign.

    Check eligibility before changing the campaign

    Wordless decision diagram showing campaign goals and a product feed leading to either a mixed campaign or a separate store-focused campaign.

    The main constraint is campaign architecture. Local customer optimization doesn’t support Merchant Center, and it can’t be used in a Performance Max campaign that includes Merchant Center products or online conversion goals.

    Your current setupCan you enable it directly?Best next move
    Store-goals campaign without Merchant Center products or online conversion goalsYesEnable the setting in the campaign and keep the store goals aligned with the actions you value.
    Performance Max campaign using Merchant Center productsNoCreate a separate store-goals campaign if you need to preserve product advertising.
    Performance Max campaign with online conversion goalsNoSeparate the local objective from the online objective before enabling local optimization.
    Campaign without an eligible offline store goalNot yetDecide which store outcome the campaign should optimize for and configure that goal first.

    You could remove a Merchant Center product feed to make the campaign eligible, but that is a consequential change. It removes the product-feed component from that campaign. Unless you intentionally want to stop using it there, the cleaner choice is a separate Performance Max campaign dedicated to store goals.

    The same reasoning applies to online conversion goals. Combining online and offline outcomes may look convenient, but this feature requires a store-focused campaign. Splitting the objectives also makes the business question clearer: is the local campaign producing enough valuable store activity to justify its budget?

    How to enable the setting

    The setup path depends on whether you are creating a campaign or modifying one that already exists.

    For a new campaign:

    1. Create a Performance Max campaign for store goals.
    2. Select the relevant offline conversion goal, such as store visits, directions or store sales.
    3. Find the Local customer optimization toggle during campaign setup.
    4. Enable the toggle and complete the remaining campaign settings.
    5. Confirm before launch that the campaign doesn’t contain Merchant Center products or online conversion goals.

    For an existing eligible campaign:

    1. Open the Performance Max campaign settings.
    2. Go to Budget and bidding optimization.
    3. Find Local customer optimization.
    4. Enable the setting and save the campaign.

    Once saved, Performance Max can begin prioritizing nearby users with stronger local intent. The setting is reversible: you can turn it off later to return the campaign to standard Performance Max behavior.

    If the toggle doesn’t appear, don’t assume the account lacks access. First check the structural blockers: the wrong campaign goal, an online conversion goal or Merchant Center products. The setting belongs to eligible store-goals campaigns, so campaign composition is the first place to troubleshoot.

    Keep local and ecommerce objectives from competing

    A store-goals campaign and an ecommerce campaign answer different questions. One tries to generate actions connected to a physical location. The other tries to produce online outcomes, often with products supplied through Merchant Center. Local customer optimization forces you to make that distinction explicit.

    Before creating a separate campaign, write down the job of each campaign in one sentence. If the sentence contains both “drive store visits” and “sell products online,” the objective is still mixed. Assign each campaign a primary outcome that matches its eligible configuration.

    • Store campaign: Use store goals and Local customer optimization to pursue nearby, high-intent customers.
    • Online campaign: Retain Merchant Center products or online conversion goals where ecommerce outcomes are the priority.
    • Budget decision: Give each campaign an intentional allocation rather than allowing a newly separated local campaign to inherit spend without review.
    • Reporting decision: Evaluate the local campaign against store actions, not against an online campaign’s purchase objective.

    This separation doesn’t guarantee better performance. It does prevent a basic measurement error: declaring the store campaign weak because it didn’t behave like an ecommerce campaign, or calling it successful because it generated activity unrelated to the physical-location objective.

    Judge the feature against the store action you selected

    Illustration of store entry, map directions and phone-call actions sending separate signals to an optimization control beside a storefront.

    Turning on the toggle is an implementation step, not the success criterion. The outcome that matters is whether the campaign produces more of the store action your business values at an acceptable cost.

    Record the campaign state before enabling the feature: selected store goals, budget, Merchant Center status and any online goals. Then note the date of the change. Without that record, later analysis can confuse a goal change, feed removal or budget adjustment with the effect of local optimization.

    1. Choose the decision metric first. Use the selected store outcome, such as directions, store visits or store sales, rather than a convenient top-line activity metric.
    2. Avoid bundling unrelated changes. If possible, don’t restructure goals, alter the budget and enable Local customer optimization at the same moment. Multiple changes make the result harder to interpret.
    3. Review the mix of store actions. More direction requests may be useful, but they aren’t automatically equivalent to more store sales. Interpret each action according to its business value.
    4. Compare like with like. Keep the campaign’s purpose, geography and operating conditions in mind when reviewing performance. A directional before-and-after comparison can inform a decision, but it doesn’t prove that the setting caused every change.
    5. Use the off switch deliberately. If the campaign no longer needs local-intent prioritization, disable the feature and return to standard Performance Max behavior rather than leaving an obsolete setting active.

    Your review should end in a concrete decision: keep the feature enabled, revise the store-goal campaign, adjust how budget is divided between local and online objectives, or turn the feature off. “Monitor performance” isn’t a decision unless you have already named the outcome that will change your course.

    Key takeaways

    • Local customer optimization is for Performance Max campaigns built around store goals.
    • It prioritizes nearby people showing local intent across Google Maps, Waze and local Google Search formats.
    • Merchant Center products and online conversion goals make a campaign ineligible.
    • A separate store-goals campaign is usually the safer structure when you need to preserve ecommerce advertising.
    • New campaigns expose the toggle after you choose eligible offline goals; existing campaigns place it under Budget and bidding optimization.
    • The setting can be turned off to restore standard Performance Max behavior.

    Start with the eligibility check, not the toggle. If your current campaign mixes store and online objectives, separate those jobs first. You will get a cleaner setup, a clearer budget decision and a result you can judge against the local action that actually matters.

    References


  • Google Ads Automation Changes: What to Audit Before Rollout

    Google Ads Automation Changes: What to Audit Before Rollout

    If your Google Ads account depends on Target CPA, Target ROAS, or existing Travel campaigns, your immediate job is not to predict what the automation will do. It is to preserve enough evidence to tell a platform change from a tracking problem, a copied setting, or one of your own account edits.

    Two changes need attention. Google’s Smart Bidding rollout is scheduled to begin on August 17, 2026. Starting in Q3 2026, Google will also move existing Travel campaigns into Search campaigns for Travel. The right response is a controlled audit: document the current state, define business guardrails, and validate every migration instead of assuming automation preserved what matters.

    Separate the confirmed changes from account-level guesses

    These updates affect different parts of campaign management. The Smart Bidding change concerns how automated bidding behaves. The Travel change replaces one campaign structure with another. Combining them into a single theory about performance will make diagnosis harder.

    For Smart Bidding, the important confirmed point is the August 17 rollout date. Advertisers have raised questions about whether long-standing Target CPA and Target ROAS practices will continue to behave as expected, but that uncertainty does not establish a universal performance outcome. It does not tell you that costs will rise, return will fall, or every account will need a new target.

    The Travel migration is more concrete. Google plans to create new Search campaigns for Travel that mirror the closest equivalent settings from existing campaigns, preserving current settings where possible. The phrase “where possible” is the reason to audit. It describes an attempted mapping, not a guarantee that every control, report, or downstream workflow will remain identical.

    The new Travel workflow brings travel feeds and formats together with AI Max capabilities, advanced bidding, search-term reporting, and campaign management. That consolidation may simplify future operations, but it also creates more places where an unnoticed mapping difference can be mistaken for a bidding problem.

    Keep a simple assumption log with three labels: confirmed platform change, observed account behavior, and hypothesis. A rollout date belongs in the first category. A change in your campaign’s conversion volume belongs in the second. “The new bidding system caused it” remains a hypothesis until tracking, configuration, traffic mix, and normal business variation have been checked.

    Build a control record before automation moves anything

    A blank control console is protected under glass beside archived configuration layers, a clock, and a documentation device.

    A screenshot of the campaign overview is not a sufficient baseline. It shows results, but it rarely captures the settings and measurement dependencies that produced them. Build a record that lets another account manager reconstruct the campaign’s starting state without relying on memory.

    1. Identify every campaign using Target CPA or Target ROAS, including shared or portfolio-level bidding arrangements that affect more than one campaign. Separately inventory every campaign that will fall within the Travel migration.
    2. Record each campaign’s budget, bidding strategy, current target, conversion goals, location settings, schedules, audiences, exclusions, and feed or asset connections. For Travel campaigns, also preserve the formats and feed relationships you expect the replacement campaign to use.
    3. Export a representative performance baseline. Include spend, conversion volume, conversion value, CPA, ROAS, clicks, impressions, and the search-term information available to you. Choose a comparison period that reflects normal day-of-week patterns, conversion delay, and business conditions rather than selecting an unusually strong week.
    4. Document the measurement layer. Record which conversion actions are primary, which actions bidding uses, how values are assigned, and which dashboards or external systems consume the campaign data.
    5. Create a dated change register. Log the rollout or migration date, target changes, budget edits, conversion-setting changes, feed changes, and the person responsible for each decision.

    Use Google Ads change history as evidence of what happened, but maintain an independent register for why it happened. A target edit made during a migration may be visible in change history; the commercial reason, expected effect, approval, and stop condition usually live elsewhere.

    Do not use the bid target itself as your historical benchmark. A Target CPA is an instruction to pursue an average cost per selected conversion. Target ROAS expresses the conversion value sought relative to ad spend. Neither is proof that the account historically achieved that result, and neither tells you whether the underlying conversions were economically useful.

    Audit the business signals before changing bid targets

    Automated bidding can only optimize the goals and values it receives. Before deciding that a post-rollout movement requires a new Target CPA or Target ROAS, confirm that the account is still describing the business outcome you intend to buy.

    • Does the primary conversion represent a result the business can fund, or is bidding optimizing an earlier proxy action?
    • Are conversion values applied consistently across campaigns, products, destinations, or booking types?
    • Did a conversion action, value rule, attribution setting, tag, or import change near the rollout?
    • Does your evaluation window allow the account’s normal conversion delay to mature?
    • Has the underlying commercial limit changed even if the advertising metric has not? A target inherited from an earlier margin, price, or customer-value assumption may no longer be defensible.
    • Are budget limits preventing the strategy from operating under the same conditions as the baseline?

    Write guardrails in business terms

    Do not wait for performance to move before deciding what counts as material. Establish an expected range from comparable historical periods, then define the maximum spend or efficiency deterioration the business is willing to absorb while investigating. The guardrail should reflect actual economics, not a generic percentage copied from another account.

    Pair that loss limit with a measurement gate. If conversion tracking or value reporting cannot be verified, do not treat the displayed CPA or ROAS as a reliable bidding diagnosis. Broad target and budget edits made against broken measurement can compound wasted spend. The safer response is to limit exposure with a budget the business can tolerate while the measurement problem is isolated.

    Also define a maturity gate. Compare results only after the relevant conversions have had their usual time to arrive. An incomplete reporting window can make a normal delay look like a sudden loss of efficiency.

    Diagnose movement in a fixed order

    When results diverge from the baseline, check the measurement layer first. Then compare campaign settings, migration mappings, budgets, and eligibility. Next inspect search terms and traffic mix. Only after those checks should you treat changed bidding behavior as the leading explanation.

    When commercially safe, change one major control at a time. Editing the bid target, budget, conversion goals, and campaign structure together may produce a new result, but it removes your ability to identify which edit mattered. If the account breaches its loss limit, protect the budget first; preserving a clean experiment is less important than containing an unacceptable business cost.

    Choose a Travel migration path based on control, not convenience

    An analyst evaluates two travel campaign pathways at a controlled junction in a generic airport operations setting.

    Travel advertisers can migrate manually before their assigned transition or allow Google to perform the automatic replacement. Google will communicate account-specific timing through account notifications and email, so the first operational requirement is making sure those notices reach an accountable person.

    Migration pathWhat you gainMain riskRequired control
    Manual migrationYou choose the change window and can validate the new campaign before the scheduled automatic transition.Your team must manage the mapping and may introduce its own setup differences.Use a written preflight checklist, record the migration time, and compare the new campaign with the saved baseline.
    Automatic migrationGoogle creates the closest-equivalent replacement and reduces the setup work required from your team.Preserved where possible does not mean every setting, report, or dependency is guaranteed to match.Review the replacement immediately and have an owner ready to contain spend if a material discrepancy appears.

    Manual migration is usually the more controllable option when campaign settings are unusual, spend exposure is material, or internal reporting depends heavily on the current structure. Automatic migration may be reasonable for a simpler account with limited operational capacity, but it is not a hands-off option. Both paths require the same validation discipline.

    Run this preflight before the Travel switch

    • Save the account notification and assigned migration timing.
    • Export the existing campaign configuration and its representative performance baseline.
    • List every feed, travel format, conversion goal, bid target, budget, location control, schedule, audience, and exclusion that should carry forward.
    • Identify dashboards, scripts, exports, or business reports that depend on the existing campaign name, identifier, or type. Because Google is creating a new campaign, test those dependencies rather than assuming they will follow automatically.
    • Assign an owner for the migration window and define the measurement, maturity, and loss-limit checks that will govern intervention.

    Validate the replacement line by line

    Start with configuration, not performance. Confirm the bidding strategy and target, budget, conversion goals, locations, schedules, audiences, exclusions, feeds, and travel formats. Check that the expected AI Max capabilities and search-term reporting are available within the new workflow without assuming they are configured exactly as your team intends.

    Then test reporting continuity. Update any mapping that depended on the former campaign structure and make sure conversion value, cost, and search-term data still reach the reports used for decisions. Preserve the old exports and migration log even if the new campaign looks correct; they are your evidence if a discrepancy emerges after conversions mature.

    Key takeaways

    • The Smart Bidding rollout begins August 17, 2026, but its schedule does not prove a particular account-level performance outcome.
    • Do not diagnose a bidding change until you have checked measurement, copied settings, budgets, eligibility, and traffic mix.
    • Set business loss limits and conversion-maturity rules before the rollout so that intervention is based on evidence rather than alarm.
    • Travel campaigns begin moving to Search campaigns for Travel in Q3 2026, either manually or through Google’s automatic migration.
    • Closest-equivalent settings still require line-by-line validation, especially where feeds, conversion goals, bid targets, and downstream reporting are involved.

    Before August 17, preserve your bidding baseline and write the guardrails that will govern any response. For Travel campaigns, monitor the account-specific notice and choose the migration path that matches your capacity to validate it. Automation is manageable when you can prove what changed, when it changed, and which business limit determines your next move.

    References


  • Brand vs. Non-Brand Paid Search: A Structure for Growth

    Brand vs. Non-Brand Paid Search: A Structure for Growth

    You open Google Ads and see a healthy return on ad spend, yet total revenue and new-customer growth are barely moving. Before you approve more budget, you need to know how much paid search is reaching people who were not already looking for your business.

    You cannot answer that from a campaign that mixes brand and non-brand traffic. These searches serve different audiences, respond to different economics, and deserve different budgets. Separating them turns ROAS from a flattering account average into information you can actually use.

    Why one ROAS number cannot answer two different questions

    A branded query contains your company, product-line, or owned brand name. It expresses prior awareness: the searcher already knows enough about you to ask for you. A non-brand query describes a product, category, problem, or desired outcome without naming your business. It gives you a chance to reach someone who has not yet chosen a brand.

    Those two query classes answer different commercial questions. Brand campaigns ask how efficiently you can capture and protect existing demand. Non-brand campaigns ask whether you can acquire customers and revenue beyond the people already seeking you out.

    When both live inside one campaign, automated bidding is rewarded for finding the easiest route to its target. Branded searches are often cheaper and more likely to convert, so an algorithm optimizing toward short-term ROAS has a strong incentive to favor them. Brand consumes more of the budget, the campaign reports impressive efficiency, and harder non-brand opportunities receive less exposure.

    The blended ROAS calculation may be arithmetically correct, but it is managerially misleading. It cannot tell you whether paid search created an incremental sale, intercepted a customer who would otherwise have clicked your organic result, or merely claimed the final touch after another channel created the demand.

    Key takeaways

    • Use separate campaigns, budgets, and reporting for brand and non-brand traffic.
    • Give brand spend a defined capture or protection role rather than allowing it to maximize blended ROAS.
    • Organize non-brand campaigns around the products and categories the business wants to grow.
    • Do not require brand and non-brand campaigns to meet the same efficiency target.
    • Judge a restructure through new customers and combined paid-plus-organic results, not paid-search revenue alone.

    Build boundaries that survive real search behavior

    A magnifying-lens gateway and layered filters sort abstract search tokens into separate amber and blue campaign channels.

    Separating campaigns starts with a query taxonomy, not a naming convention. Renaming one campaign Brand and another Non-Brand achieves nothing if branded searches can still enter both, the campaigns share a budget, or their bidding goals continue to reward the same behavior.

    Traffic classWhat belongs in itPrimary jobWhat it should not prove
    BrandCompany names, owned product lines, common name variants, and brand-plus-product searchesCapture known demand and protect valuable brand resultsThat paid search generated all credited demand
    Non-brandGeneric products, categories, problems, features, and use cases without an owned brand nameReach prospective customers and expand category revenueThat it can match the conversion rate of people already seeking the brand
    Competitor or ambiguousOther companies’ names or queries whose commercial meaning cannot be classified cleanlySupport a distinct competitive strategy or remain separately measurableThat its economics represent either pure brand or pure non-brand demand

    The third row matters because forcing every query into a binary bucket can contaminate both benchmarks. Competitor queries are non-brand in the literal sense, but their intent, cost, and landing-page needs may differ sharply from generic category discovery. If they have meaningful volume, report them separately.

    Use this sequence to create the boundary:

    1. Define your owned-name set. Include the company name, owned product and service names, common variants, and queries that combine those names with a category term.
    2. Classify actual search terms. A keyword list describes what you targeted; the search-term data shows what entered the auction. Label the meaningful terms as brand, non-brand, competitor, or unresolved.
    3. Route traffic deliberately. Apply the negative-keyword, exclusion, inventory, or listing-group controls available to each campaign type. Where query control is limited, reinforce the separation through distinct inventory, goals, budgets, and campaign roles.
    4. Remove shared incentives. Give brand and non-brand their own budgets and performance expectations. Otherwise, the more efficient traffic can continue to absorb money intended for acquisition.
    5. Audit leakage after the change. Review search terms and product distribution once the new structure has begun receiving traffic. Reclassify edge cases instead of assuming the initial rules caught every variant.

    Pay special attention when your brand name includes a generic product term. Names such as Mattress Firm or Guitar Center can create more classification and defense pressure than an invented name. Write down how you will treat exact owned-name intent, broad category intent, and queries that could plausibly mean either one.

    Give brand spend a job, not a blank check

    Separating brand traffic does not mean turning it off. It means deciding what you are paying it to do.

    Brand advertising can be valuable when competitors are bidding around your name, when Shopping placements could show rival products, or when you need precise control over an offer and landing destination. In competitive categories, removing brand coverage without testing can surrender prominent paid space even while your organic result remains visible.

    The opposite mistake is treating every branded conversion as incremental. Many branded searchers were already looking for you. If the paid ad had not appeared, some might have clicked an organic result or another owned listing. That does not make the ad worthless; it means platform-attributed revenue and revenue caused by the ad are not automatically the same number.

    Set brand policy by answering four questions:

    • What are you defending? Record whether competitors or marketplace listings occupy important paid placements around your owned terms.
    • What can organic search retain? Compare branded paid and branded organic outcomes together rather than assuming every lost ad click becomes a lost sale.
    • What is the spending limit? Give brand a separate budget ceiling tied to its capture or protection role. Do not let it draw from acquisition funds merely because it can produce a higher ROAS.
    • Whom are you converting? Where customer-status data is reliable, separate new from returning customers. A brand campaign dominated by existing customers should not be presented as proof of acquisition.

    If brand spend looks excessive, reduce it in controlled stages rather than shutting it off abruptly. Watch paid brand revenue, branded organic revenue, combined Google revenue, total new customers, and visible competitive pressure. Keep major promotions and unrelated account changes out of the test where practical, and let the evaluation cover the buying cycle that matters to your business.

    A decline in paid brand conversions is not, by itself, evidence that the test failed. If organic captures much of the displaced demand and total revenue holds, you may simply have stopped paying for some navigational clicks. If organic does not recover the loss and total business results weaken, the cut may have gone too far. That is why the safe decision comes from the combined outcome, not a philosophical position that brand bidding is always good or always wasteful.

    Make non-brand campaigns accountable for growth

    Once brand has its own budget, non-brand traffic finally has room to compete. The next risk is recreating the same problem at the product level by placing an entire catalog into one broad campaign and allowing automation to favor only the products with the strongest existing history.

    That structure can maximize near-term efficiency while starving emerging categories, lower-volume products, and strategic lines that need exposure before they can build performance data. Broad catalog management effectively asks the advertising platform to decide which parts of your business matter most. Its answer will follow the campaign objective, not your merchandising or growth plan.

    Build non-brand segmentation from commercial priorities:

    • Separate strategic categories from the general catalog so they have protected budgets.
    • Isolate newer or underexposed product groups when the business has deliberately chosen to develop them.
    • Group products closely enough that bids, landing pages, and search intent can be managed coherently.
    • Keep established volume drivers visible, but do not let their history prevent other priority products from entering auctions.
    • Document the business reason for each segment. If no one can explain why a segment deserves distinct budget or control, it may not need its own campaign.

    Standard Shopping can be useful when you need stronger product-level control over bidding and budget. Performance Max can serve a narrower acquisition role rather than being asked to manage brand capture, generic discovery, and every product priority at once. One workable division of labor is to pair granular Standard Shopping campaigns with Performance Max’s New Customer Acquisition setting, where that setting is available and supported by reliable customer data.

    Treat that as an account-design pattern, not a universal template. The important principle is that each campaign receives one intelligible job. If Performance Max is responsible for customer acquisition, evaluate it against that job. If Standard Shopping is responsible for protecting investment in priority product groups, verify that those groups actually receive traffic and budget.

    Do not force non-brand campaigns to match brand ROAS. A person searching generically is less committed to your business than a person typing its name. Set a commercially acceptable acquisition constraint, then judge whether the campaign is producing new customers, non-brand revenue, and strategic category growth. If you demand brand-like efficiency immediately, automation will either retreat to the easiest available demand or stop competing where acquisition is possible.

    Campaign structure cannot rescue a poor journey. Match category intent to a useful category page, product intent to the relevant product experience, and problem-led intent to a page that resolves the searcher’s uncertainty before demanding a purchase. When non-brand performance is weak, inspect the search term, product, offer, and landing page as a connected path instead of treating the bid as the only lever.

    Read the business result without declaring the wrong winner

    Two color-coded campaign channels deliver different patterns of conversion and customer-growth tokens into a shared business outcome basin.

    A brand and non-brand restructure often makes the paid-search dashboard look worse before it makes the business easier to understand. Removing inexpensive branded conversions from an acquisition campaign lowers blended ROAS by design. That is not proof of failure. It is the expected effect of exposing the true cost of reaching less familiar customers.

    Build a scorecard with three layers:

    • Brand capture: brand spend, paid brand revenue or conversions, branded organic performance, customer status where reliable, and competitive presence.
    • Non-brand acquisition: non-brand spend, revenue, ROAS or acquisition cost, new customers, search-term quality, and product or category coverage.
    • Business outcome: combined paid and organic Google revenue, total new customers, total revenue, and the profit or contribution measure your business actually manages.

    This wider view also reduces attribution errors. A brand search can be the final step after CTV, programmatic, organic discovery, or another channel introduced the business. Without a broader attribution method such as marketing mix modeling, brand campaigns can receive credit for demand created elsewhere. The ad platform can report the conversion following a click; that alone does not establish what caused the customer to search for the brand.

    One documented account restructure shows how dramatically the interpretation can change. Paid-search revenue fell 25% year over year, or about $2.3 million, while Google organic revenue rose 99%, combined Google paid and organic revenue rose 15%, and new-customer acquisition rose 20%. That is one account, not a benchmark or a promise. Its value is diagnostic: paid revenue alone would have labeled the change a loss even though the broader business measures moved in the intended direction.

    Use directional patterns to decide what to do next. If paid brand revenue falls while branded organic revenue rises and combined results hold, substitution is a plausible explanation. If non-brand investment and new-customer acquisition rise alongside total revenue, a lower paid-search ROAS may be an acceptable cost of growth. If brand cuts are not recovered elsewhere and total results weaken, restore coverage selectively. If non-brand spend rises without acquisition or category progress after a representative buying cycle, examine targeting, segmentation, economics, offer, and landing experience rather than hiding the weakness beneath brand conversions.

    Before your next budget decision, require one page that shows brand performance, non-brand performance, combined paid and organic Google results, and new customers as separate lines. Do not approve growth spending from blended ROAS alone. Once each campaign has a distinct job and scorecard, you can fund acquisition without confusing captured demand for created growth.

    References


  • Scalable SEO Delivery: A Practical System for Scope Control

    Scalable SEO Delivery: A Practical System for Scope Control

    Your SEO engagement can look profitable until quick page reviews, extra competitor checks, implementation help, and custom reporting start consuming the capacity reserved for scheduled work. At the same time, pressure to move faster can encourage broad content rewrites that put existing rankings at risk.

    Those problems share a cause: the unit of work is unclear. Scalable SEO delivery starts when you can see exactly what was promised, move each request through the same controlled workflow, and adjust the price or schedule when the work changes.

    Turn the scope into countable work units

    A goal such as improving organic visibility belongs in the strategy. It does not define the service. If a statement of work promises technical SEO, content optimization, or ongoing support without defining the deliverables, the client and delivery team can hold completely different expectations while both believe they are reading the agreement correctly.

    Scope creep begins when work is added after the agreement without a matching change to cost or timeline. The practical defense is to describe SEO as a catalogue of countable work units rather than a collection of broad intentions.

    For every unit, define:

    • Object: The URL, page group, template, keyword cluster, market, language, report, or system being worked on.
    • Action: Whether you will inspect, diagnose, recommend, brief, write, implement, publish, validate, or measure.
    • Quantity: The exact number of pages, briefs, templates, reports, or other objects included.
    • Depth: The issues or data dimensions covered. A technical audit might include crawlability and indexing without including Core Web Vitals, structured data, internal linking, or competitive analysis.
    • Cadence: When the unit is delivered and whether unused capacity expires, rolls forward, or can be reassigned.
    • Artifact: What the recipient gets, such as an annotated audit, delta brief, implementation ticket, dashboard, or test report.
    • Completion rule: The approval, QA check, deployment state, or measurement event that marks the unit as done.

    The verb matters as much as the quantity. Review is not rewrite. Recommend is not implement. Validate is not repair. When the verb changes, the skill, access, risk, and time requirement usually change with it.

    Strategy and execution therefore need separate line items, even when the same person handles both. A strategy unit can finish with a prioritized recommendation and implementation specification. An execution unit finishes only after the agreed changes are made and checked. Without that distinction, a clear recommendation can quietly turn into an obligation to configure the CMS, coordinate developers, rewrite copy, publish the page, and investigate the result.

    SEO work unitWhat the base unit can includeWhat changes the scope
    Technical auditNamed pages or templates, specified checks, findings, and prioritized recommendationsAdditional templates, implementation, development tickets, deployment, or post-fix validation not listed in the agreement
    Content refreshBaseline review, section diagnosis, and a delta brief for the agreed URLsA full rewrite, a new page, another language or market, CMS publishing, or new creative assets
    Content strategyAgreed query set, intent analysis, page recommendations, and prioritized roadmapWriting briefs, producing copy, interviewing subject experts, or implementing the roadmap
    AI and GEO researchDefined personas, synthetic query exploration, answer-gap analysis, and recommendationsOngoing visibility monitoring, new persona sets, content production, schema implementation, or additional platforms
    Performance reportingNamed data sources, scheduled format, commentary, and a decision-focused meetingNew data cuts, extra competitors, historical investigations, custom dashboards, or unscheduled analysis

    Then write a definition of done for each recurring unit. A strategy-only content refresh might be done when the baseline is captured, every section is classified, the delta brief is delivered, and the client approves it. If implementation is included, the same unit remains open until the specified changes are published and pass QA. Measurement can be another unit with its own window and completion rule.

    This prevents a common accounting mistake: treating a recommendation, its implementation, and the eventual performance analysis as one deliverable even though they happen at different times and require different resources.

    Run every page through one visible delivery pipeline

    Abstract webpage cards move through connected trays for inspection, adjustment, approval, and completion on a modular worktable.

    You do not scale SEO by making every specialist work faster. You scale it by making the recurring decisions consistent. Each page or work package should pass through a visible sequence with required inputs, an owner, an approval state, and a controlled release point.

    1. Capture the request. Record the objective, affected URLs or templates, market, requester, desired timing, and reason the work matters. A message in a chat channel is not a sufficient production brief.
    2. Check entitlement and capacity. Match the request to a contracted unit before anyone starts diagnosing it. If it does not match, route it to substitution, change control, or the backlog.
    3. Lock the baseline. Select the pre-change window, metrics, query groups, and comparison method before editing. For a seasonal travel marketplace, a 56-day Search Console baseline matched an eight-week test period while avoiding a comparison that blended distant seasons. That duration is not a universal rule. The transferable rule is to use comparable before-and-after windows and account for seasonality before drawing a conclusion.
    4. Diagnose the existing asset. Inspect its leading queries and classify its sections as keep, fix, remove, or add. Keep protects material that remains accurate and performs a useful search function. Fix preserves the idea while correcting stale execution. Remove requires an explicit reason. Add addresses a demonstrated gap.
    5. Write the delta brief. Specify only what changes, why it changes, which query or persona supports the decision, and what must remain untouched. Do not commission a new-page brief for a live URL unless a full replacement is genuinely the approved scope.
    6. Approve the intervention. Confirm the delta, implementation owner, dependencies, publishing access, QA requirements, and delivery slot. Approval should precede production, not merely acknowledge it afterward.
    7. Implement and validate. Apply the agreed changes, check the preserved sections, verify relevant internal links and structured data, and confirm that the published result matches the approved brief.
    8. Measure against the locked baseline. Wait for the agreed test window, report the preselected metrics, and distinguish observed movement from assumptions about causation.

    Query diagnosis needs the same discipline. Top queries should be protected, positions 5–20 with weak click-through rates can identify striking-distance opportunities, and high-impression queries with almost no clicks can reveal an unanswered intent. These are prioritization signals, not automatic rewrite instructions. You still need to inspect whether the page is the right asset for the query and whether the proposed change fits its commercial purpose.

    For AEO and GEO work, keep observed and synthetic demand visibly separate. A scalable persona method can combine a 16-month sitewide Search Console query set with synthetic, LLM-style query fan-out. The first dataset reflects recorded search behavior. The second proposes plausible questions that may surface in conversational systems. Synthetic queries can expose answer gaps, but they are hypotheses rather than proof of demand. Labeling them prevents an attractive AI-generated cluster from outranking actual audience evidence in your decisions.

    The keep decision is especially important. A ranking page is not a blank document: internal links already point to it, structured data may already be deployed, and its historical performance provides a baseline. Rewriting a decaying page from top to bottom can erase useful search equity even when the intention is to refresh it. The delta brief makes restraint part of production instead of leaving it to the writer’s memory.

    Automation should enter after this workflow is stable. Claude Code or another automation layer can prepare exports, populate brief templates, apply required labels, and flag missing fields. It should not quietly turn a diagnostic signal into published copy. Keep approval and release as explicit states because the cost of a careless bulk change is carried by live pages, not by the automation queue.

    Use operational statuses that reveal where work is blocked: requested, scoped, scheduled, in progress, awaiting approval, ready to publish, measuring, and complete. A page cannot be both awaiting approval and counted as completed production. That distinction gives account leads and delivery managers a shared view of real capacity.

    Make capacity and change control the same system

    A transparent container filled with work blocks directs one new amber block toward rescheduling, replacement, or an expanded boundary.

    Scope control fails when the contract lives in one place and the delivery queue lives in another. The contract defines entitlement, but the queue shows consumption. You need both views on the same work item.

    Maintain a capacity ledger for each client, department, or SEO program. It should show:

    • The contracted work unit and its quantity.
    • The unit’s current status and owner.
    • The intended delivery window.
    • Dependencies and approvals still outstanding.
    • Actual effort and the reason for material variance.
    • Approved changes added to the plan.
    • Unplanned requests waiting for a decision.

    Track variance by cause, not merely as extra time. A refresh may overrun because the original page count was wrong, implementation access was missing, review cycles were undefined, data had to be rebuilt, or a new stakeholder changed the target. Those causes require different fixes. Historical effort alone cannot tell you whether to adjust the estimate, the intake gate, the contract language, or the approval process.

    Small requests deserve particular attention. A twenty-minute page review, keyword check, or competitor investigation can feel too minor to route formally. Repeated across reporting cycles and a full client roster, those requests become unscheduled production. Their cost also includes context switching, communication, documentation, and the work displaced from the committed queue.

    Give every new request one of these destinations:

    • Substitute it. The requester replaces an existing deliverable with the new one, and the displaced item is explicitly rescheduled or removed.
    • Approve a change. The work receives additional budget, capacity, and a revised delivery date.
    • Defer it. The request enters a prioritized backlog for a future scope or planning cycle.

    There is no invisible fourth destination in which the team absorbs the work while every existing promise remains unchanged.

    A change order does not need to be elaborate. Its minimum useful fields are the estimated hours, additional cost, and revised timeline. Add the affected deliverables, assumptions, dependencies, acceptance criteria, and named approver when they help eliminate ambiguity. Introduce the process during kickoff so it is a normal delivery mechanism rather than a policy unveiled during a disagreement.

    A useful boundary response is direct and gives the requester a choice: Yes, we can take that on. It is not included in the current deliverable. We can scope it as an added change, or replace the planned item and move that work to the backlog. Which route fits your priority?

    This is not a refusal. It makes the tradeoff visible. The requester can still choose speed, breadth, or cost, but the delivery team does not pretend all three are unchanged.

    You can often detect scope drift by watching the grammar of a request:

    • A new noun: Another URL, template, competitor, market, language, dashboard, persona, or data source has appeared.
    • A stronger verb: Review became rewrite, recommend became implement, or validate became repair.
    • A deeper question: A scheduled performance explanation became a new investigation requiring additional exports or analysis.
    • A different cadence: A recurring monthly deliverable is now expected on demand or more frequently.
    • A new dependency: The work now requires development, design, legal review, localization, subject-matter input, or publishing access.

    Each signal should trigger a scope check before production begins. If you want to include a flexible support allowance, define its size, eligible request types, approval path, and rollover rule in advance. An unnamed allowance becomes unlimited support in practice because nobody can tell when it has been consumed.

    Assign one commercial owner to approve changes and one delivery owner to confirm capacity. Specialists can estimate the work, but they should not have to renegotiate the engagement every time a request reaches them. That separation also prevents a casual message to a writer or analyst from bypassing the queue.

    Use reporting to close decisions, not open side projects

    Reporting is part of delivery, not an unlimited analysis channel. A dashboard full of unexplained numbers invites follow-up questions because the reader still has to determine what changed, whether it matters, and what to do. If every answer requires a fresh investigation, a scheduled reporting unit can expand into hours of unplanned analysis.

    Design each report around decisions. Include:

    • The agreed objective: The outcome this workstream is intended to influence.
    • The committed outputs: What was delivered, deferred, substituted, or blocked during the reporting period.
    • The preselected metrics: The measures chosen before implementation, with the applicable baseline and comparison window.
    • The interpretation: What the data establishes, what remains uncertain, and which changes are plausible explanations rather than proven causes.
    • The recommended action: Continue, stop, revise, investigate, or wait for the measurement window to close.
    • The decision required: The person who must decide and the consequence for scope, timing, or priority.
    • The investigation queue: Questions that require new work, with their scope status clearly shown.

    This format still allows questions. It simply separates explanation of the agreed report from a new analytical deliverable. A question that can be answered from the prepared analysis belongs in the meeting. A request for another competitor, query segment, attribution view, language, or historical window should return to intake.

    Reports that present numbers without enough context tend to generate additional analysis and investigation. Budget context into the reporting unit itself, then state the boundary. Define the format, cadence, included commentary, meeting length, supported data views, and route for deeper questions in the statement of work.

    Keep output acceptance separate from performance evaluation. A strategy unit can be complete when the agreed recommendations and roadmap are approved. An execution unit can be complete when specified changes are published and pass QA. A measurement unit can be complete when its window closes and the selected metrics are reported. None of those definitions guarantees a ranking or traffic result.

    That separation does not weaken accountability. It makes accountability precise. Delivery owns the agreed process, quality checks, evidence, and response to the result. Search performance remains an observed outcome affected by factors beyond whether a document was delivered on time.

    For a content refresh, report both tracks:

    • Delivery track: Baseline captured, sections classified, delta approved, changes published, internal links and structured data checked, and test started.
    • Performance track: Movement in the protected top queries, striking-distance query group, click-through rate, clicks, impressions, and average position during the agreed comparison window.

    If the page underperforms, the next diagnostic is a new decision point. It should not silently reopen every preceding deliverable. Decide whether the response is included optimization, a substituted work unit, an approved change, or a backlog item.

    Key takeaways

    • Define SEO services by object, action, quantity, depth, cadence, artifact, and completion rule. Goals belong in the strategy; they do not replace deliverables.
    • Price and schedule strategy, implementation, validation, and measurement as distinct work, even when the same team performs them.
    • Refresh live pages with a locked baseline, keep-fix-remove-add diagnosis, and delta brief. Preserve useful sections instead of treating every update as a full rewrite.
    • Route every additional request to substitution, a priced change, or the backlog. Do not leave silent absorption available as an operating choice.
    • Keep observed search behavior separate from synthetic LLM-style queries so plausible questions do not masquerade as measured demand.
    • Build reports around decisions and preselected metrics. Route new data cuts and investigations back through intake.
    • Automate repeatable preparation and validation only after the workflow has clear inputs, states, approval gates, and stop conditions.

    Start with one active statement of work and one recurring SEO workflow. Circle every vague object and verb, then replace each with a countable unit and a definition of done. Put the next unplanned request through the substitution, change, or backlog decision before anyone starts it. If the request has nowhere to go, you have found the exact gap your delivery system needs to close.

    References


  • Google Ads Bidding and Measurement: A Practical Framework

    Google Ads Bidding and Measurement: A Practical Framework

    You can choose a sensible Google Ads bid strategy and still make a bad budget decision. A campaign may hit its reported return target while capturing customers who were likely to buy anyway. Another may create additional sales but receive too little credit because part of the journey happened outside the platform’s view.

    The fix is to stop asking one metric to do three jobs. Give Smart Bidding a clean outcome to optimize, use attribution to steer observable campaign performance, and use incrementality to decide whether the spend created business that would not otherwise exist.

    Key takeaways

    • A bidding strategy is a control system, not proof that advertising caused the conversions it reports.
    • Use Target CPA when conversions have comparable value and acquisition cost is the meaningful constraint. Use Target ROAS when conversion values differ materially and those values are trustworthy.
    • Maximize Conversions and Maximize Conversion Value express volume-first objectives; adding a target introduces an efficiency constraint.
    • Attribution decides how observed touchpoints receive credit. Incrementality estimates how many additional outcomes advertising caused.
    • When Google Ads, analytics, and your business system disagree, reconcile their definitions before changing bids or budgets.

    Choose the bidding strategy from the business decision

    If your account shows Target CPA and Target ROAS as separate choices, do not assume Google has introduced entirely new bidding mechanics. Some accounts are showing a revised campaign-setup menu in which those targets sit beside Maximize Clicks, Maximize Conversions, Maximize Conversion Value, Target Impression Share, and Manual CPC. Previously, advertisers generally selected a maximize strategy and then applied the corresponding optional target. The observed change appears to affect presentation rather than how the strategies function.

    The clearer menu is useful because it forces an important distinction: do you want the system to pursue as much volume as the budget allows, or do you want it to pursue volume while steering toward an efficiency target? Answer that before you touch the campaign settings.

    Your actual objectiveRelevant bidding familyWhat must be trueMain measurement risk
    Generate as many valuable actions as possible within the available budgetMaximize ConversionsThe counted conversions represent outcomes you genuinely want more ofLow-quality and high-quality actions may be treated alike
    Generate conversions while steering toward an acceptable average acquisition costTarget CPAConversions have reasonably comparable business value, and the target reflects your economicsA reported CPA can look healthy while lead quality deteriorates
    Generate the greatest total conversion value within the available budgetMaximize Conversion ValueThe values sent to the bidding system reflect meaningful differences between outcomesIncorrect or inflated values can direct spend toward the wrong actions
    Generate conversion value while steering toward a return-on-ad-spend targetTarget ROASRevenue or another defensible value signal is available and consistently definedAttributed ROAS may be mistaken for incremental profit
    Acquire visits rather than downstream outcomesMaximize ClicksTraffic itself is the immediate objective, or downstream measurement is not yet usableMore clicks can conceal weak commercial performance
    Reach a desired level of search visibilityTarget Impression ShareVisibility is the stated objective and is evaluated separately from conversionsPresence on the results page may be mistaken for business impact
    Control bids directlyManual CPCYour team has a specific reason to manage bid-level tradeoffs itselfManual control does not repair weak conversion tracking or prove causality

    A target is a steering goal, not a promise for every auction or conversion. Target CPA does not mean every conversion will cost exactly the target. Target ROAS does not mean every segment, query, or transaction will achieve the same return. Evaluate whether the strategy is serving the portfolio-level objective you gave it.

    Use this sequence when choosing or revisiting the setting:

    1. Name the outcome. Decide whether the campaign is meant to generate purchases, qualified leads, booked appointments, visits, or visibility. Do not substitute the metric that is easiest to collect.
    2. Name the constraint. Decide whether budget, acquisition cost, return on spend, or coverage is the binding condition.
    3. Inspect the signal. Confirm that the conversion event and its value distinguish desirable outcomes from incidental activity.
    4. Select the matching bidding family. Use a conversion-volume strategy for comparable actions and a value strategy when the outcomes have materially different worth.
    5. Write down the hypothesis. State what should improve and which business metric will confirm it. This prevents a later interface metric from silently replacing the original goal.

    Give Smart Bidding a measurement contract

    Abstract ad signals pass through a filtering chamber before clean conversion signals reach an automated bidding mechanism.

    Automated bidding cannot decide which business outcome matters. It can only optimize the signals it receives. Before evaluating a bid strategy, create a short measurement contract for every conversion action used in bidding.

    Define what one conversion means

    • Event: Identify the exact action, such as an order, a submitted lead form, or a qualified opportunity.
    • Eligibility: State what makes the event valid and which duplicates, tests, cancellations, spam submissions, or internal activity are excluded.
    • Counting rule: Decide whether repeated actions by the same person represent separate business outcomes.
    • Value rule: Specify whether the value is revenue, a margin-aware amount, an expected lead value, or a clearly labelled weighting system.
    • System of record: Name the platform, analytics property, CRM, commerce system, or finance record that owns the final business result.
    • Observation point: Record when the outcome becomes reliable. A form submission, a qualified lead, and a closed sale occur at different stages.
    • Attribution rule: State which interactions can receive credit and which model distributes that credit.

    This contract exposes a common bidding error: treating events with very different commercial meaning as interchangeable conversions. If a form submission and a qualified opportunity both influence the same campaign, either separate their roles or assign values that reflect the distinction. Do not report an internal weighting as revenue merely because it is useful to the bidding system.

    Reconcile definitions instead of averaging conflicting reports

    Google Ads, web analytics, and your customer or commerce system will not necessarily report matching totals. Each can observe different interactions, apply different eligibility rules, and assign credit differently. A mismatch is a diagnostic clue; it does not automatically prove that one system is broken.

    When the totals diverge, compare these fields side by side:

    • The event being counted and the point in the customer journey where it occurs.
    • The included campaigns, channels, devices, audiences, and conversion actions.
    • The touchpoints each system can observe.
    • The attribution model and the interactions eligible for credit.
    • Whether results are assigned to an interaction date, conversion date, or later business milestone.
    • The treatment of duplicate events, cancellations, invalid leads, refunds, and later adjustments.
    • The definition of value, including whether it represents gross revenue, another business amount, or a modelled weight.
    • The delay between the advertising interaction and the final outcome.

    Do not change the bid target merely to make one report resemble another. First determine whether the systems are counting the same event under the same rules. If they are not, document the difference and assign each report a specific job.

    Use attribution to steer and incrementality to fund

    A split illustration shows customer paths passing through an attribution prism beside two matched markets used for an incrementality test.

    Attribution and incrementality answer different questions. Treating them as competing versions of one metric leaves you with a weak optimization system and a weak budget case.

    Attribution explains credit within the observed journey

    A conversion path can include display, paid social, organic search, email, and a purchase. Attribution decides which of those observed interactions receives credit and how much. In a simplified example, the same $100 conversion could give all $100 to display under first-touch attribution, all $100 to email under last-touch attribution, or divide the value across the path under a multi-touch model. Changing the model changes the allocation; it does not change the underlying sale.

    Use attribution for questions such as:

    • Which observable campaigns and touchpoints are associated with conversions?
    • Where do customers enter and continue through the measurable journey?
    • Which ads, queries, audiences, or landing experiences deserve closer inspection?
    • How should reported credit be distributed when several measurable interactions precede one conversion?

    Attribution is therefore useful for ongoing campaign steering. Its blind spot is causality. Receiving credit does not prove that the touchpoint created a sale that would otherwise have been lost.

    Incrementality estimates what advertising caused

    Incrementality asks what happened because of the marketing activity, above what would have happened without it. The basic design compares an exposed group with an equivalent control group that is not exposed to the activity being tested.

    Consider a simplified test that runs for 30 days. The exposed group completes 1,000 purchases while the control group completes 800. The estimated lift is 200 purchases. An attribution system might associate many or all of the 1,000 purchases with campaign touchpoints, while the controlled comparison identifies 200 additional purchases. The 30-day period and those totals illustrate the method; they are not universal requirements for your test.

    A credible incrementality test needs a defensible control, comparable groups, a predeclared outcome, and protection against unrelated changes that would distort the comparison. Choose a test duration that fits the actual decision and conversion cycle. Also account for the cost of holding out exposure: incrementality tests can be slow, expensive, or difficult to design, especially when audiences overlap or the business cannot isolate treatment cleanly.

    Decision in front of youPrimary evidenceHow to use it
    Which observable campaign element should be optimized?Attribution and campaign diagnosticsReallocate attention within the measurable campaign system
    How did measurable touchpoints share credit?AttributionInterpret customer paths and reported channel contribution
    Did the advertising create additional conversions?IncrementalityEstimate lift against an appropriate counterfactual
    Should the business expand, defend, reduce, or redesign the budget?Incrementality combined with business economicsJudge the value of the additional outcomes, not merely attributed volume
    Which signal should Smart Bidding optimize?Clean attributed conversion data aligned with the business objectiveGive the bidding system a frequent, operational signal while evaluating causal impact separately

    This division of labor matters. Incrementality is too coarse and test-dependent to explain every touchpoint in an individual journey. Attribution is too dependent on observed interactions and modelling choices to prove that the spend caused additional demand. You need both because the questions are different.

    Put bidding and measurement into one operating loop

    A durable Google Ads process connects campaign configuration to business validation without pretending that one dashboard contains the whole answer.

    1. Set the business objective. Name the outcome and the economic constraint before selecting the bid strategy.
    2. Create the measurement contract. Define event eligibility, counting, value, ownership, timing, and attribution.
    3. Choose the bidding family. Match conversion volume, conversion value, traffic, visibility, or manual control to the stated objective.
    4. Validate the input. Check for duplicated events, missing business outcomes, invalid leads, misleading values, and unexplained reporting gaps.
    5. Steer with attribution. Use observable campaign and journey data to improve the parts of the system you can measure directly.
    6. Validate budget impact with incrementality. When the size or strategic importance of the decision justifies a controlled test, measure additional outcomes against a counterfactual.
    7. Return the result to planning. Adjust budgets and future tests using incremental business value while retaining attribution as the operational optimization layer.

    Avoid changes that destroy your ability to learn

    • Do not change the bid strategy, conversion definition, and value rules at the same time. You will not know which change produced the result.
    • Do not tighten a CPA or ROAS target to compensate for inflated or low-quality conversion data. Repair the signal first.
    • Do not judge a recent change from outcomes that have not had time to reach the business stage named in your measurement contract.
    • Do not defend a budget using platform-attributed ROAS alone when the real question is whether the spend caused additional value.
    • Do not discard attribution because it is not causal. It remains the practical tool for distributing observable credit and steering campaigns.
    • Do not treat an incrementality result as permanent. It answers a defined test under defined conditions and should inform the decision that test was built to support.

    Your next step is small but revealing: open one campaign and complete this sentence before changing any setting: We ask Google Ads to optimize [outcome] subject to [constraint], steer it using [attribution definition], and approve its budget using [business result or incremental evidence]. If you cannot fill in all four blanks unambiguously, the bidding problem is still a measurement problem.

    References