Tag: Budget Management

  • SEO Acquisition Economics: Measuring CAC Beyond Last Click

    SEO Acquisition Economics: Measuring CAC Beyond Last Click

    Your SEO dashboard can be green while the finance conversation goes badly. Rankings, impressions, clicks, and query growth show whether search visibility is moving, but they don’t answer the budget question: did this work make acquiring customers cheaper, more scalable, or both?

    You need an economic model that reflects how people actually buy. Start with blended customer acquisition cost, preserve SEO’s observable role across the journey, and use incrementality tests where attribution cannot establish cause. The goal isn’t to manufacture a larger organic number. It is to make a defensible decision about the next dollar.

    Start with the acquisition system, not organic’s last click

    A buyer might discover you through a nonbrand search, return through a paid ad, compare options using ChatGPT, subscribe to your email list, and eventually buy from a newsletter. A last-click report calls that an email customer. A first-click report calls it an organic customer. Neither label captures the whole acquisition process.

    This is why channel CAC and blended CAC answer different questions:

    • Channel CAC divides one channel’s cost by the customers credited to that channel. It helps you operate the channel, but its result depends heavily on attribution rules.
    • Blended CAC divides total acquisition cost by all new customers acquired. It shows whether the complete acquisition system is becoming more or less efficient.

    Blended CAC = total acquisition cost for the period / new customers acquired in the period.

    The numerator should use the same cost definition every time. Agree with finance on whether it includes media, agencies, acquisition-focused payroll, content production, software, creative work, and allocated technical support. Count each new customer once in the denominator, using an agreed customer status. Don’t substitute leads, orders from existing customers, or every conversion event because those make the result look better without improving acquisition economics.

    Different channels perform different jobs in that system. Paid search often captures demand near a transaction, so spend and credited customers are relatively easy to connect. Paid social may create familiarity or warm an audience before it searches. Email can appear exceptionally cheap because the cost of acquiring the subscriber was incurred elsewhere. SEO can introduce the brand, answer evaluation questions, supply email signups, and make later paid or branded visits more productive.

    A falling blended CAC does not automatically prove SEO caused the improvement. A rising blended CAC does not automatically prove SEO failed, either. Product changes, pricing, seasonality, customer mix, media budgets, and sales capacity can all move the number. Treat blended CAC as the financial outcome to explain, not as a channel attribution model.

    Build a measurement stack finance and SEO can both use
    Two analysts examine a layered measurement system made of acquisition costs, connected customer touchpoints, and comparison groups.

    No single metric can carry the argument. Use four layers, moving from accounting truth to causal evidence. Each layer has a different job, and each has a boundary you should state openly.

    Measurement layerWhat to calculate or inspectDecision it supportsMain limitation
    Financial outcomeTotal acquisition cost divided by new customersWhether the overall acquisition engine is efficientDoes not identify which activity caused the change
    SEO operating economicsSEO cost per qualified organic lead, signup, opportunity, or customer cohortWhich page groups and initiatives deserve resourcesBecomes attribution-dependent when the denominator is customers
    Journey contributionFirst known touch, assists, return visits, email capture, and later conversion by original landing-page cohortWhere SEO participates before the final visitObserved touches are incomplete and should not be added as separate customers
    IncrementalityDifference in outcomes between a changed group and a credible comparison groupWhether the investment produced activity that probably would not have occurred otherwiseConfidence depends on test design, comparability, and spillover

    Build the stack in a fixed order so changing definitions cannot rescue a disappointing result:

    1. Lock the customer definition. Decide what event makes someone a new customer and how cancellations, duplicate records, or existing-customer purchases are handled. Reconcile the count with the system finance trusts.
    2. Inventory the SEO cost base. Include content, editing, technical implementation, design, data, tools, agency fees, and the agreed share of internal labor. Separate acquisition work from retention or general platform work when the distinction can be made consistently.
    3. Create investment cohorts. Group work by launch period, search intent, page type, and objective. A commercial comparison-page cohort should not be evaluated as if it has the same job as an informational troubleshooting cohort.
    4. Attach outcomes to the cohort. Track qualified organic entries, lead capture, opportunities, new customers, and assisted journeys originating from those pages. Preserve first known landing-page data in the CRM where consent and system design permit it.
    5. Maintain both cash and cohort views. The cash view compares current-period acquisition spending with current-period customers. The cohort view follows work launched in one period through its later outcomes. Keep them separate instead of moving conversions backward to make the original month look profitable.
    6. Document every definition. Record attribution model, lookback rules, cost allocations, filters, customer status, and known tracking gaps. A metric that changes definition between reviews is not a trend.

    The time mismatch matters. SEO costs can arrive before pages are indexed, discovered, trusted, and used by buyers, while a conversion may land after several return visits. Close a cohort only after it has passed your observed indexing-to-conversion window. Use your own search, CRM, and sales-cycle data to establish that window; a universal deadline would create false precision.

    For management reporting, label cost per qualified organic lead or opportunity exactly as such. Do not call it CAC until the denominator is new customers. That small naming discipline prevents an operational metric from being mistaken for a financial one.

    Measure hidden influence without inventing attribution

    First-click, last-click, linear, position-based, and data-driven attribution can distribute credit differently. None can recover a touch that was never observed. Consent restrictions, deleted cookies, cross-device journeys, offline conversations, long buying cycles, and disconnected systems all leave gaps. Data-driven attribution is still a model of recorded behavior, not a complete causal record.

    Search itself is also producing more exposure without a site visit. SparkToro’s analysis of Similarweb clickstream data estimated that 68.01% of U.S. Google searches ended without a click during the first four months of 2026, compared with 60.45% in 2024. A person can encounter a brand in an AI Overview or search snippet without creating the familiar impression-to-click-to-conversion trail.

    That does not mean every zero-click search has business value. Visibility is not a customer, and a brand mention is not incremental revenue. It means the observable journey is shrinking, so an unexplained organic last-click decline cannot, by itself, establish that SEO’s economic influence declined by the same amount.

    Use the following evidence to narrow the gap without assigning fictional fractions of a customer:

    • Keep first known and final touch side by side. If organic discovery repeatedly precedes paid, direct, or email conversions, show the sequence. Do not award both channels a full customer.
    • Carry acquisition metadata into the CRM. Preserve original source, landing page, content cohort, and first-seen date where your consent model permits it. Reporting stops at the lead form when those fields are discarded.
    • Separate brand from nonbrand entry points. A nonbrand problem query can introduce demand, while a branded query may capture demand created elsewhere. Combining them hides the job each page performs.
    • Record AI referrals and self-reported discovery separately. Referral traffic from AI systems and a standardized first-heard-about-us response can reveal paths analytics misses. Treat self-reported answers as survey evidence, not deterministic attribution.
    • Annotate overlapping campaigns. Paid social, public relations, product launches, and brand campaigns can affect branded search and organic behavior. Without a shared campaign log, ordinary correlation can be mistaken for an SEO effect.
    • Watch customer quality. Compare qualified opportunities, new customers, and downstream value by cohort. Cheap traffic that never reaches a meaningful business outcome does not improve acquisition economics.

    When the decision is large enough to justify a test, move from attribution to incrementality. Stagger a template or content change across comparable page groups, retain an unchanged comparison group where operationally safe, define the business outcome before launch, and run the evaluation through the normal conversion window. For market-level activity, exposed and unexposed regions can sometimes provide a comparison if their demand patterns are genuinely similar.

    SEO tests are often less clean than randomized advertising holdouts. Search demand changes, pages influence one another, and a large technical release can create spillover. Report that uncertainty. A well-matched phased rollout can be stronger evidence than a before-and-after chart without becoming proof it cannot support.

    Turn the evidence into an SEO budget decision
    A hand adds a budget token to a scale balancing search investment against customer growth, with comparison pathways in the background.

    The budget decision should be made at the initiative or cohort level before it is made at the channel level. Cutting all SEO because last-click organic CAC rose can remove the entry points feeding paid search and email. Protecting every SEO activity because organic visibility increased is equally weak. Use explicit decision rules.

    • Expand when mature cohorts produce additional qualified demand or customers under a credible comparison, and the implied incremental CAC fits the threshold finance has set for that customer type.
    • Maintain when the intended leading outcomes are moving but the cohort has not completed its normal sales cycle. Set the next review at cohort maturity instead of interpreting an incomplete denominator.
    • Fix when organic entries grow but qualified leads or customers do not. Check search intent, landing-page promise, conversion friction, brand versus nonbrand mix, CRM continuity, and whether the content answers a question buyers actually carry into a purchase.
    • Reduce when multiple mature cohorts fail to create qualified outcomes, assisted movement, or credible incremental lift. Cut the underperforming initiative first, then observe whether the broader acquisition system changes.
    • Re-measure when blended CAC moves sharply after a tracking, consent, CRM, or attribution change. A reporting discontinuity is not an economic result.

    For a tested change, you can calculate incremental CAC = added acquisition cost / estimated incremental new customers. Use the customer difference produced by the comparison, not the number an attribution model happened to credit. If estimated incremental customers are zero or negative, do not force a division into a misleading cost figure. Report that the test did not establish positive incremental acquisition.

    Compare incremental CAC with the acceptable threshold your business has set using its margins, retention, payback requirements, and cash constraints. That threshold can differ by customer segment. A blended average can conceal an efficient high-value cohort and an uneconomic low-value one, so preserve the segment definitions when the differences affect the decision.

    When blended CAC changes, force the review to answer four questions: did total spending change, did the number or mix of new customers change, did conversion behavior change, and did measurement change? Only then ask which channel deserves credit. This order prevents an attribution debate from replacing economic analysis.

    Key takeaways

    • Use blended CAC as the financial outcome, not as proof that SEO caused the outcome.
    • Use channel metrics to operate SEO, but label leads, opportunities, assists, and customers precisely.
    • Track SEO investments as cohorts so early costs are not judged against an incomplete conversion window.
    • Never add first-touch, assisted, and last-touch customer counts; they can describe the same buyer.
    • Treat AI visibility, zero-click exposure, branded search, and self-reported discovery as supporting evidence rather than invented attribution.
    • Use phased rollouts, matched comparisons, or holdouts when the size of the budget decision warrants causal evidence.
    • Expand or cut specific initiatives based on mature economic evidence before making a channel-wide decision.

    At your next acquisition review, replace the isolated organic conversion slide with one page showing blended CAC, the SEO cost base, cohort outcomes, cross-channel paths, and the confidence level behind each conclusion. Leave the unresolved measurement gap visible. A candid range of evidence gives you a stronger budget decision than a precise attribution number that the customer journey cannot support.

    References


  • SEO and PPC Alignment: Build a Total Search Operating System

    SEO and PPC Alignment: Build a Total Search Operating System

    When SEO celebrates a ranking gain while PPC defends higher spend for the same query, you do not have a keyword problem. You have two teams making locally sensible decisions that may produce an expensive result for the business.

    You get real alignment when both teams can decide where the next search click should come from, what it should cost, and which result matters. That requires shared ownership, a business-level scorecard, a recurring exchange of usable evidence, and controlled tests wherever paid and organic visibility overlap.

    Stop treating alignment as a data-sharing problem

    A shared dashboard cannot settle a conflict between incompatible targets. If SEO is rewarded only for organic traffic and PPC is rewarded only for lowering paid acquisition cost, each team will optimize its own column. Neither is accountable for the combined search result.

    That is why search alignment starts with reporting lines and decision rights. Someone must be able to resolve budget, landing-page, and query-ownership disagreements based on the total result rather than channel preference.

    Operating modelBest fitHow decisions workMain risk
    Unified total search teamMidsize and enterprise organizations that can centralize searchSEO and PPC report to the same search or acquisition leader, who can balance organic coverage, paid spend, and overall search demand.The leader needs enough technical SEO and paid-media depth to challenge both disciplines.
    Cross-functional search podComplex organizations where specialists must remain inside separate functionsSEO and PPC keep their functional reporting lines but work in a shared pod, ideally with a dedicated analyst and a required strategic review.Conflicting instructions from functional leaders can stall decisions unless the pod has a named tiebreaker.

    Choose the unified model when you can give a search leader genuine control over priorities and budget recommendations. Choose the pod when SEO, content, paid media, ecommerce, or product expertise must remain distributed. Do not create a pod without defining who makes the final call when functional goals collide. Otherwise, the structure creates more meetings without producing more alignment.

    Write the decision right down in plain language: the search lead or pod owner can recommend where paid coverage should increase, where it should be tested downward, which landing-page issue takes priority, and which team owns the next action. Leadership can still approve material budget changes, but the teams should not have to renegotiate ownership every time a query appears in both reports.

    Give both teams a scorecard they can win together

    SEO rankings, Search Console clicks, Quality Score, and paid impression share remain useful. They diagnose channel performance. They should not be the only measures used to decide whether the combined search program is succeeding.

    Build the shared scorecard around three business outcomes:

    • Blended customer acquisition cost or cost per acquisition: agree on the conversion event, attribution logic, and included search costs, then evaluate the combined cost of acquiring customers or actions through search. This gives PPC a reason to use organic coverage when it can reduce the total cost, and gives SEO a reason to prioritize queries with demonstrated commercial value.
    • Total search-results-page real estate or share of voice: define a stable set of priority queries and assess whether your brand earns the click through paid listings, organic results, or other relevant search features. The useful question is not which team received credit. It is whether your brand or a competitor captured the opportunity.
    • Margin contribution: connect the search plan to high-margin products or high-value accounts. Traffic and conversion volume can look healthy while the query mix directs effort toward less valuable demand. Margin gives both teams a reason to favor the same commercial priorities.

    Keep channel metrics underneath this shared outcome layer. If blended acquisition cost worsens, PPC can inspect paid efficiency while SEO checks lost rankings, weak coverage, or landing-page problems. The shared metric tells you that the system has a problem; the channel metrics help you locate it.

    Each shared metric also needs a written definition. Fix the priority-query set used for share-of-voice reporting. Document which conversion counts in blended CPA or CAC. Use the same margin field and attribution window across both teams. If SEO and PPC can produce different answers by changing definitions, the scorecard will recreate the silo inside a spreadsheet.

    Make the weekly exchange produce decisions, not exports

    Hands with blue and amber accents select a few geometric evidence pieces for a shared illuminated tray while blank report stacks sit at the edges.

    Ad hoc messages usually transfer isolated facts without context, ownership, or a follow-up date. A recurring strategic exchange should package each dataset with the decision it can support.

    What PPC should give SEO

    • Search terms tied to conversions and pipeline value. Include the query, destination page, cost, conversion outcome, and available value signal. SEO can then prioritize content and pages around demonstrated intent instead of treating estimated search volume as proof of business value.
    • Low-Quality Score landing-page reports. Route the affected pages into a joint audit of relevance, load performance, message continuity, and the user journey. Improving these pages can support paid efficiency and organic performance at the same time.
    • Ad-message test results. Give SEO the winning and losing variants, the query or audience context, and the landing page used. Winning language can inform organic titles and descriptions, but it should be treated as evidence about the message, not copied blindly into every page.
    • Expensive queries that convert well. These are candidates for stronger organic pages because an organic gain may create room for a controlled reduction in paid coverage. Flag them as opportunities for analysis, not automatic budget cuts.

    What SEO should give PPC

    • Paid landing-page crawl results. Use an SEO crawler to detect redirects, broken destinations, and other technical failures before they waste media spend or interfere with ad delivery. Assign the repair to an owner rather than merely forwarding the crawl export.
    • Search Console gaps. Queries with strong impressions but organic positions between 11 and 20 show established search interest that organic results are not yet capturing near the top. PPC can cover that gap while SEO works on the page and its authority.
    • The content roadmap. Share planned evergreen hubs, product pages, and important refreshes early enough for PPC to prepare campaigns, avoid sending traffic to a page about to change, and coordinate the message used at launch.
    • A stable organic No. 1 report. Identify costly, high-volume queries where the brand consistently holds the leading organic position. PPC can nominate those terms for a holdout test and move proven savings toward less-covered opportunities.

    The weekly meeting should end with a compact decision log containing the query cluster, evidence, agreed action, owner, and review point. A useful agenda asks what changed, where combined coverage is weak or unnecessarily costly, which experiment is ready, and what is blocked. If an item produces no decision or assignment, it belongs in a dashboard rather than the meeting.

    Test paid and organic overlap before moving budget

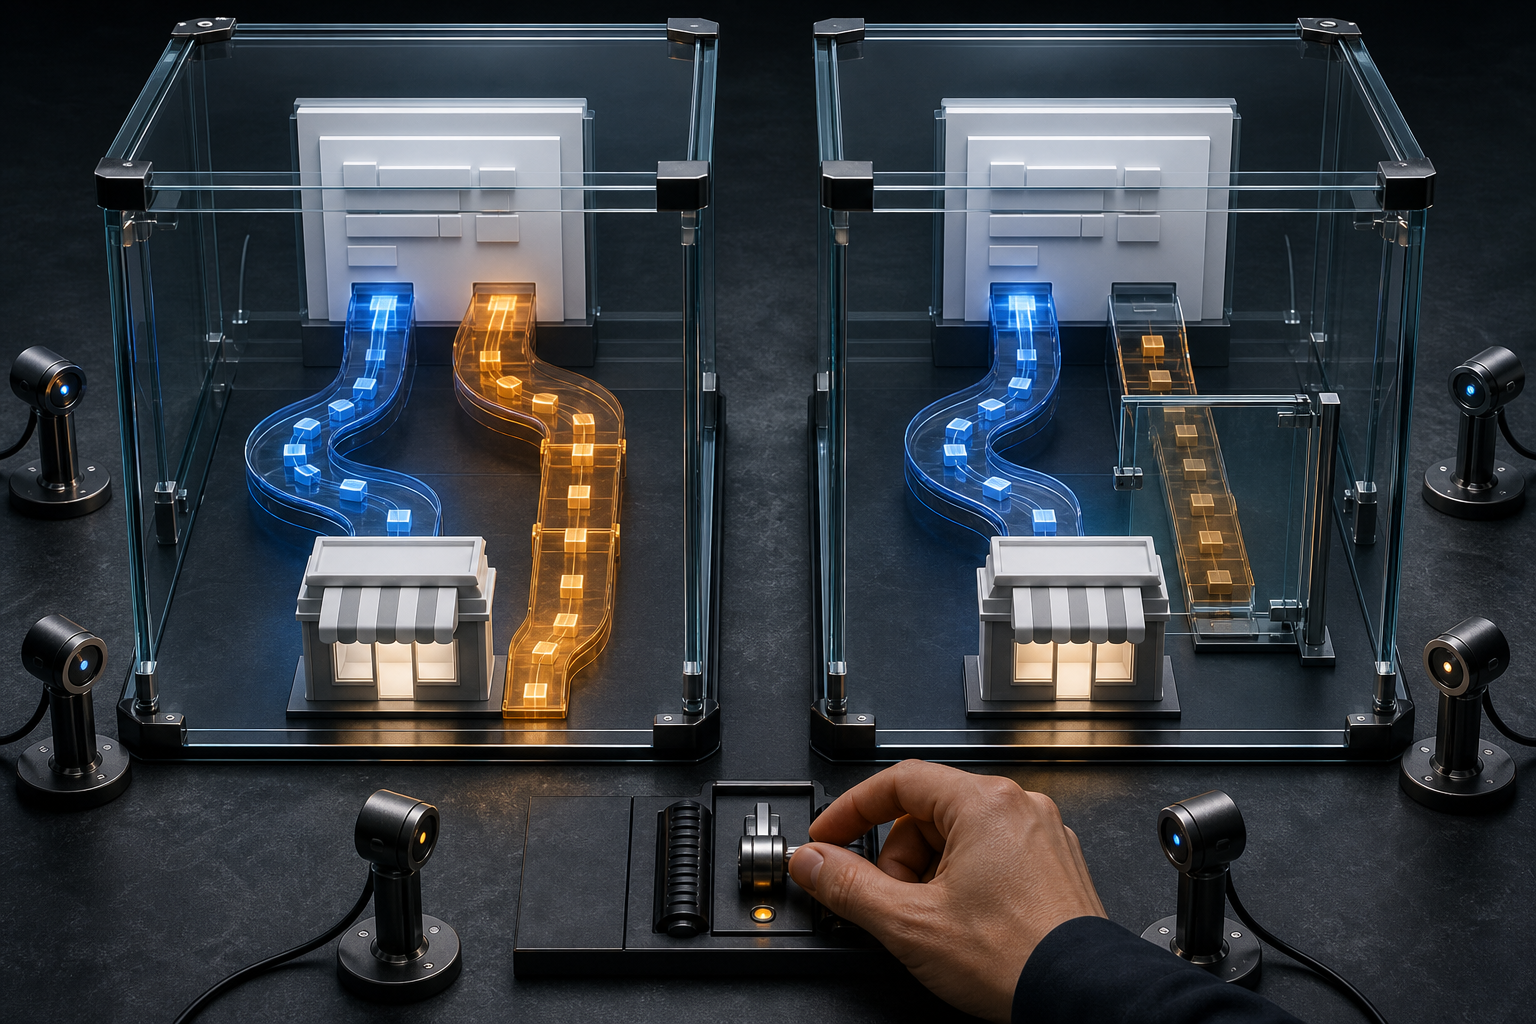
    Two transparent test chambers compare customer journeys, with blue and amber routes active together in one and the amber route paused in the other.

    An organic No. 1 ranking does not prove that the paid ad above it is wasteful. It only creates a credible test candidate. The real question is whether reducing paid exposure preserves total conversions and value while improving blended economics.

    Do not begin by switching off a broad campaign. Losing visibility and conversions can create a direct financial cost, and an account-wide change makes the cause difficult to isolate. Use a bounded, reversible test:

    1. Select a defined query group with a stable organic No. 1 position and meaningful paid cost. Keep ambiguous or volatile terms out of the initial test.
    2. Record the combined baseline for paid and organic conversions, value or margin, and blended acquisition cost. Channel clicks alone cannot tell you whether demand was preserved.
    3. Reduce paid impression share for the test group while maintaining a reasonable comparison group. Avoid changing the offer, landing page, or measurement rules at the same time.
    4. Measure whether organic results picked up the lost paid activity and, more importantly, whether total conversions and value held. A rise in organic clicks is not a win if the combined business result falls.
    5. Reallocate spend only when the combined result supports it. Move the released budget toward priority queries where organic coverage is weak, then continue monitoring the original group so a later ranking or competitive change does not go unnoticed.

    The same logic works in reverse. When an important query sits in organic positions 11-20, paid search can provide immediate coverage while SEO improves the relevant page. Once organic visibility becomes strong and stable, move the query into the overlap-testing queue. This turns PPC into a bridge and SEO into a potential source of durable efficiency without asking either team to surrender credit.

    Key takeaways

    • SEO and PPC alignment needs shared decision rights, not just shared keyword files.
    • A unified search team offers the clearest ownership; a cross-functional pod can work when it has a named tiebreaker and a disciplined operating rhythm.
    • Blended CAC or CPA, total search visibility, and margin contribution should decide strategy. Channel metrics should diagnose the result.
    • PPC should supply conversion-backed query intelligence, landing-page signals, message tests, and costly converting terms. SEO should supply technical audits, organic coverage gaps, the content roadmap, and stable top-ranking opportunities.
    • Budget reductions should follow controlled paid-organic holdout tests, not assumptions based on rank alone.

    Your next move is to choose one priority query cluster and put it through the complete operating system: one shared business outcome, one evidence exchange, one owner, and one documented decision. If the teams cannot do that for a single cluster, fix the decision rights before adding another dashboard. If they can, repeat the process across the rest of the search portfolio.

    References

  • AI Ad Campaign Controls: Automate Without Losing Control

    AI Ad Campaign Controls: Automate Without Losing Control

    When you switch an AI ad campaign from traffic to conversions, you are not handing the platform a complete strategy. You are giving it a score to maximize. If the conversion event, eligible audience, landing page, or budget rule is wrong, automation can repeat that mistake at scale.

    The safest operating principle is simple: you keep control of business constraints, while the system optimizes inside them. That means deciding what counts as success, where ads may appear, which destinations are acceptable, how spend should behave, and which changes require human review before you enable more automation.

    Key takeaways

    • Optimize for a conversion only after you have verified that the event fires correctly, represents real business value, and can be reconciled with your own records.
    • Treat an average daily budget as a pacing instruction, not a promise that every calendar day will spend the same amount.
    • Set geographic, brand, URL, product, and audience exclusions before launch. They define where the algorithm is allowed to search.
    • Keep generated assets, URL expansion, customer matching, and audience estimation under separate review because each creates a different failure mode.
    • Use bulk tools to deploy reviewed change sets. Do not let bulk creation turn an isolated configuration error into an account-wide problem.

    Give the system one objective and explicit boundaries

    The useful dividing line is not manual versus automated. It is judgment versus calculation. You should retain the decisions that require knowledge of margins, service areas, customer quality, brand policy, and operational capacity. The platform can handle the repeated calculation of which eligible opportunity appears most likely to produce the event you selected.

    Control layerYou decideThe system may optimizeWhat fails when the control is weak
    OutcomeWhich event represents valuable demandWhich eligible clicks appear more likely to produce that eventLow-value actions accumulate while reported performance looks healthy
    EconomicsThe spend ceiling and acceptable business returnBid and delivery allocation within available platform settingsMore conversions arrive without acceptable margin or lead quality
    EligibilityGeographies, audiences, brands, products, URLs, and inventory that are allowedWhich eligible opportunities receive deliverySpend reaches people or destinations the business cannot serve
    CreativeApproved claims, assets, product data, and disclosure requirementsAsset generation, selection, or combination where enabledAds become inconsistent with the offer or brand policy
    MeasurementWhich data is valid enough to influence optimizationLearning from the conversion feedback suppliedTracking defects become bidding instructions

    This distinction matters in ChatGPT Ads. Its Conversions objective supports optimized cost-per-click campaigns that favor clicks considered more likely to convert while continuing to charge on a CPC basis. That is conversion-oriented selection, not a guarantee of a conversion, acquisition cost, revenue level, or profit. You still need an economic test outside the bidding label.

    Write the objective as a complete sentence before configuring the campaign: “Acquire this type of conversion, from these eligible customers, for this business outcome, within these spending and brand constraints.” If you cannot fill in every part, the campaign is not ready for broader automation.

    Do not combine several business goals into one vague instruction. A purchase, qualified sales opportunity, app install, account registration, and page view do not carry equal value. If the platform sees all of them as equivalent success events, it can rationally pursue the easiest one rather than the one that matters most to you.

    Fix the measurement loop before optimizing conversions

    A glowing signal travels from an abstract ad to a landing page, through a verification checkpoint, and back to an optimization engine in a closed loop.

    Conversion automation is a feedback loop. An ad receives a click, a user takes an action, measurement sends that action back, and the campaign looks for more traffic resembling the credited result. A broken signal therefore does more than damage a report. It teaches the system the wrong lesson.

    1. Name the primary event. Choose the action closest to business value that you can measure reliably. Keep softer actions as diagnostic metrics unless you intentionally want the campaign to optimize for them.
    2. Test the complete path. Use the same device and journey a customer would use, then confirm that the event appears in the ad platform and in the system your business treats as authoritative.
    3. Check the event payload. Confirm the event name, value, currency where applicable, destination, and deduplication behavior. A successfully received event can still carry the wrong meaning.
    4. Separate platform credit from business acceptance. For lead generation, compare attributed leads with qualified leads. For commerce, compare purchases with valid orders rather than treating the platform count as the final ledger.
    5. Record the change point. When you alter an event definition, matching method, consent flow, or data source, annotate the date in your campaign log. Otherwise, a measurement change can be misread as a performance change.

    ChatGPT Ads has added Automatic Advanced Matching under Tools > Conversions > Data Source. It uses hashed customer data to improve website conversion attribution. Hashing changes how the data is represented; it does not answer whether your organization had permission to collect and use it. Review the applicable consent, privacy, and data-governance requirements before enabling the feature. If that review is incomplete, keep it disabled while you validate ordinary conversion tracking.

    For mobile campaigns, AppsFlyer and Adjust integrations can measure installs and in-app events. Use that distinction. An install can show acquisition volume, but a later registration, subscription, purchase, or other valuable in-app event may reveal whether that volume produced useful customers. Do not silently substitute the easier event when the business goal depends on the later one.

    Before increasing a budget, ask four questions: Did the intended event fire? Did it fire only once for one action? Did the value arrive correctly? Did your business system accept the outcome as real? A “no” to any one of them is a measurement problem to fix, not a bidding problem to automate around.

    Use budgets and exclusions as operating controls

    Monitor the budget on the window the platform uses

    A daily budget can look like a hard calendar-day cap even when the platform treats it as an average. ChatGPT Ads is shifting to average daily budgets evaluated over a rolling seven-day period, allowing daily spend to move while staying within the broader budget limits. It also paces daily budgets through the day.

    That changes how you should investigate apparent variance. Do not declare a pacing failure merely because one day is above or below the displayed average. Review the rolling seven-day spend, the campaign’s total constraints, conversion volume, and your own financial cap together. A single-day screenshot is no longer enough to describe budget behavior.

    • Write down whether the platform field is a fixed cap, an average, or a target. The label determines what a normal day can look like.
    • Maintain an internal maximum exposure for the reporting window. Your accounting limit should not depend on a team member remembering how a platform interprets “daily.”
    • Alert on cumulative spend and material configuration changes, not only on one day’s variance.
    • Check whether a performance swing coincides with a budget edit, conversion edit, or exclusion edit before changing bids.
    • Do not raise the budget simply because pacing is slow early in the day. The pacing system is already distributing delivery, and an impulsive edit changes the instruction it is following.

    A budget is also not a forecast. It describes the amount the system may use under its rules, not the number of valuable outcomes you will receive. Keep the decision to increase spend tied to reconciled conversion quality and acceptable economics.

    Apply exclusions from hardest constraint to weakest signal

    Exclusions are not merely cleanup settings. They define the search space. Configure the most defensible constraints first:

    1. Operational impossibility: exclude locations you cannot serve, destinations that cannot fulfill the offer, and products that must not be advertised.
    2. Brand and destination policy: restrict brands, landing pages, and URL expansion paths that could create an off-message or irrelevant journey.
    3. Commercial fit: exclude audiences only when reliable performance or eligibility evidence supports the decision.
    4. Estimated attributes: treat modeled classifications as weaker evidence than an explicit location, product, or URL rule.

    ChatGPT Ads now provides campaign-level geographic exclusions. Use them when a location is genuinely ineligible, not as a substitute for diagnosing a regional landing-page, pricing, or measurement problem.

    Destination controls deserve the same attention as audience controls. Google Ads Editor 2.13 supports AI Max in Shopping with automated text generation, URL expansion controls, brand lists, and URL exclusions. If URL expansion is enabled, review where the system is allowed to send traffic. A relevant query paired with the wrong page is still a failed campaign decision.

    Be more cautious with household-income exclusions in Performance Max. The setting has been observed in a European campaign with brackets from the top 10% through the lower 50%, plus an Unknown segment, but the available evidence does not establish a universal rollout. Check whether the control actually exists in your account before designing a process around it.

    If it is available, do not interpret Unknown as an income tier. It means the system has not assigned the user to one of the listed estimates. Excluding it can remove people whose commercial fit is simply unclassified. Compare measured business outcomes by segment before excluding a modeled group, document the rationale, and keep a clear route to reverse the change if reach or customer quality deteriorates.

    Scale reviewed changes, not unchecked assumptions

    A human analyst inspects a campaign module at a gated review station before approved copies move into a larger distribution network.

    Bulk management reduces repetitive work, but it also enlarges the blast radius of a bad field. ChatGPT Ads now supports asynchronous bulk creation and updates for campaigns, ad groups, and ads through its Ads API. Because the work is asynchronous, submitting a job and confirming that every requested change completed are separate steps.

    Google Ads Editor 2.13 similarly brings more AI campaign controls into an offline bulk workflow, including AI Max for Shopping, Customer Retention Goals in Performance Max, channel performance reporting, and AI-generated asset attestation controls. The practical gain is not just speed. You can review related settings as one change set before posting them.

    1. Capture the starting state. Export or otherwise record the campaigns and fields you are about to change so you can identify exactly what moved.
    2. Give the change set one purpose. Keep a budget revision separate from a conversion-goal migration, URL expansion change, or audience exclusion. If performance moves, you need to know which instruction caused it.
    3. Validate the dangerous fields. Check campaign status, objective, conversion source, budget interpretation, geography, negative targeting, brands, URLs, product scope, generated-asset settings, and any required attestations.
    4. Review the diff. Look for blank values, inherited defaults, duplicated entities, unintended status changes, and changes outside the intended campaign list.
    5. Start with a limited subset. Use a small, representative group of campaigns when the feature or configuration is new to your team. Confirm behavior before applying the same pattern more widely.
    6. Verify completion. For an asynchronous job, inspect the final job result and failed items. Then spot-check the resulting settings in the campaign interface.
    7. Keep a rollback record. Store the prior value, new value, reason, approver, affected entities, and reversal method in the same campaign log.

    After deployment, verify controls in a fixed order: eligibility first, destination second, measurement third, spend fourth, and reported outcomes last. This catches the cause before you react to the symptom. An ad that cannot serve, points to an unintended URL, or reports the wrong event should not be evaluated as a bidding-performance problem.

    Your next move is to create a one-page control sheet for one live AI campaign. Record its primary conversion, authoritative business record, budget meaning, eligible geographies, audience exclusions, URL rules, brand rules, generated-asset permissions, owner, and rollback method. Resolve every blank field before adding another automated feature. That small document gives the system room to optimize without giving up the decisions only your business can make.

    References

  • How to Make Evidence-Based SEO Investments Under Uncertainty

    How to Make Evidence-Based SEO Investments Under Uncertainty

    Your leadership team wants a yes-or-no answer: keep funding SEO while AI answers reshape discovery, or wait until the channel becomes predictable. That is the wrong decision frame. Uncertainty increases the value of protecting durable assets and buying useful information through controlled tests. It does not make inactivity free.

    You do not need to predict the final form of search. You need an investment system that distinguishes essential maintenance from speculative work, contains downside risk, and gives every experiment a clear path to scale, stop, or further investigation.

    A pause is a position, not a neutral baseline

    A budget freeze can feel reversible because no new campaign has been launched and no visible loss appears on day one. Organic visibility does not behave that way. Content freshness, technical health, trust, and authority develop over time. When that work stops, competitors can occupy the space while your recovery becomes slower and potentially more expensive. The resulting costs can appear as lost share of voice, weaker pipelines, and a longer route back to your previous position.

    That means “spend nothing” belongs in the same investment analysis as any proposed initiative. Make the pause defend itself. For each important site segment, document what would stop, what would probably deteriorate, how you would notice the deterioration, and what would have to be rebuilt when funding returned.

    • Maintain: What recurring work protects discoverability, accuracy, technical reliability, and commercially important pages?
    • Reduce: Which assets will still be maintained, and which slower deterioration are you consciously accepting?
    • Pause: What signals will warn you that the decision is damaging visibility or demand, and who has authority to restart work?

    Assess those consequences by page group, product line, audience, or market rather than relying on one sitewide average. A healthy brand section can hide a weakening non-brand category. Stable total traffic can conceal lost visibility on the queries that introduce new buyers. The investment decision should follow the exposed asset, not the reassuring aggregate.

    This does not mean every SEO budget should stay untouched. It means that reducing investment should be an explicit trade: a known saving now in exchange for defined maintenance risk, lost learning, and uncertain recovery later.

    Give every SEO dollar one of three jobs

    A stream of metallic tokens divides among crews maintaining a digital library, testing a module in a laboratory, and expanding a modular structure.

    An evidence-based budget becomes easier to defend when every line item has a distinct job. Separate foundation work, market observation, and experimentation instead of placing all three in a single “SEO growth” bucket.

    1. Protect the foundation. Keep commercially important content current, maintain technical accessibility, audit the site, preserve authority-building activity, and continue producing original information that helps people make decisions. These are durable inputs to visibility across traditional and AI-mediated search, even when individual interfaces and tactics change.
    2. Observe the environment. Monitor the parts of search that could change the return on your work: audience priorities, product strategy, competitor movement, algorithms, and LLM behavior. Observation earns its budget by producing a decision, not by producing another dashboard.
    3. Buy information through experiments. Test uncertain changes on a controlled scope, measure their incremental effect, and expand only when the evidence supports expansion. Experiments are a learning mechanism within the strategy, not a substitute for the foundation.

    Fund the maintenance floor before funding speculative tactics. If the budget cannot support the whole site, narrow the protected scope deliberately. Start with assets that combine commercial importance, evidence of existing demand, and meaningful consequences if they deteriorate. Do not spread cuts evenly merely because an even reduction is administratively simple.

    Then rank discretionary proposals with a consistent filter:

    • Expected value: What business outcome could improve if the idea works?
    • Evidence strength: Is the proposal based on your own relevant data, a credible external pattern, or an untested assumption?
    • Reversibility: Can the change be removed quickly without damaging valuable pages, revenue, or measurement?
    • Learning value: Would the result guide decisions across a meaningful group of pages, or answer only a narrow question?
    • Measurement readiness: Are the affected pages, success metric, guardrails, comparison group, and tracking already available?

    Keep expected return and learning value separate. A low-risk test can deserve funding even when its immediate upside is uncertain if the answer will improve many later decisions. A sweeping change to high-revenue pages needs stronger prior evidence because the cost of being wrong is higher.

    Turn an uncertain tactic into a decision-grade test

    A modular tile passes through a transparent two-lane testing apparatus and reaches routes for scaling, further inspection, or stopping.

    “Add more schema,” “refresh the content,” and “optimize for AI” are activities, not hypotheses. None specifies where the change applies, what should move, what must not get worse, or what you will do with the result.

    Write a hypothesis that can lose

    Use this structure: For this eligible group of pages, making this consistent change should improve this primary outcome over this measurement period, compared with this control, without causing an unacceptable decline in these guardrail metrics.

    A useful hypothesis must be actionable, consistently implemented, measurable, and allowed enough time and exposure to reveal an effect. Tiny edits on a few low-traffic pages rarely justify formal experimentation because the result is unlikely to resolve the decision. As an illustration of test scale rather than a universal benchmark, changing a word in the H1 across 30 pages receiving more than 100 monthly sessions and observing them for four weeks is more testable than changing a word buried in the body copy of a few quiet pages.

    Before approval, put the hypothesis on a one-page test record with the affected page set, excluded pages, implementation owner, launch window, primary metric, business guardrails, control group, known confounders, monitoring cadence, rollback condition, and decision owner. If the team cannot fill those fields, the proposal is not ready to consume an experimentation budget.

    Match the method to the question

    MethodQuestion it can answerMain limitation
    User-level A/B testDoes one experience improve engagement, interaction, or conversion for users who see it?Splitting visitors between versions does not isolate the ranking effect of changing the page for search engines.
    Pre/post testDid performance change after an update to the same page or page group?Seasonality, algorithm changes, competitors, and other outside factors can create the apparent difference.
    Incrementality testDid changed pages outperform comparable unchanged pages during the same period?It requires a sufficiently similar control group and clean implementation across both groups.

    Use A/B testing for user experience or conversion questions. Use pre/post analysis when a credible control is unavailable and you need directional evidence. For rankings, visibility, or organic traffic, a concurrent comparison between changed and unchanged page groups provides the strongest isolation of the three methods because both groups experience the same period while only the test group receives the intervention.

    If you must use pre/post analysis, lower the confidence of the conclusion. Check sitewide movement, seasonal patterns, other campaigns, algorithm changes, and competitor activity before assigning the difference to your change. A later staged rollout across more eligible pages can show whether the pattern repeats.

    Contain the downside before launch

    Risk planning belongs in the test design, not in the incident response. A conservative rollout can use cross-browser and device QA, a lower-value pilot page, a tracking check after three days, weekly monitoring, and a prepared rollback plan. Avoid launching immediately before a weekend or another period when nobody can respond.

    • Confirm that pages load, render, link, and report analytics as expected.
    • Test on lower-value eligible pages before exposing the pages responsible for the most leads or revenue.
    • Record the original state and the exact reversal procedure before publishing the change.
    • Increase monitoring frequency when the possible impact on revenue, conversions, or site function is high.
    • Leave enough time to complete the test and any rollout before a busy season complicates measurement or raises the cost of failure.

    Reversibility should affect test scope. A cheap, easily reversed change can justify a broader initial test. A technically risky or revenue-sensitive change should begin small even when the projected upside looks attractive.

    Read the result as a business decision, not a traffic result

    An organic sessions increase is not automatically a win. Sessions can rise while conversion rate falls, or visibility can expand around queries that do not match the audience you intended to attract. That is why result analysis must check the full data set, validate surprising numbers, and look beneath the headline metric.

    Read every completed test in the same order:

    1. Verify implementation and tracking. Confirm that the intended pages received the intended change, the control did not, and both groups produced reliable data.
    2. Inspect the before-and-after movement. Establish what changed in the test group after launch.
    3. Compare the control. Determine whether similar unchanged pages moved in the same direction during the same period.
    4. Check the site context. Look for sitewide shifts that could indicate an algorithm event, demand change, tracking problem, or another marketing campaign.
    5. Check seasonality. Compare with the relevant prior seasonal period where that context is available rather than treating every temporal pattern as a test effect.
    6. Inspect quality and business impact. Review query intent, qualified traffic, conversion behavior, leads, revenue, or the closest valid downstream outcome.

    Decide the response before stakeholders debate the most flattering chart:

    • Scale: The primary metric improves against the control, the data checks out, and important business guardrails remain acceptable. Expand in stages so the rollout continues to confirm the effect.
    • Hold: The result is inconclusive but the implementation and measurement are valid. Record what remains unknown, then decide whether more exposure or a redesigned test is worth the cost.
    • Investigate: Visibility improves while conversion quality deteriorates. Examine query and landing-page intent before calling the change successful.
    • Stop or roll back: A guardrail deteriorates, the page malfunctions, tracking becomes unreliable, or the downside exceeds the value of additional learning.

    Do not keep extending a weak test until the chart finally looks favorable. An inconclusive result is evidence about the design, exposure, or effect size; it is not permission to declare a win. Preserve the record so the next proposal starts with what you already learned.

    A winning result is not permanent law either. Search systems, competitors, content, and user behavior continue to change, so a tactic that works during one period may not retain the same value indefinitely. Monitor scaled changes as part of the maintained foundation.

    Finally, define trigger events that require the portfolio to be reviewed. Relevant triggers include a shift in products, services, audiences, internal goals, competitor behavior, major algorithms, or LLM behavior. A trigger should prompt a fresh assessment, not an automatic budget increase or shutdown. Recheck the original assumptions, then choose whether to maintain the course, expand an experiment, reduce exposure, or move resources.

    Key takeaways

    • Treat pausing SEO as an investment scenario with its own costs, risks, warning signals, and recovery requirements.
    • Protect foundational work first, fund monitoring that can trigger decisions, and isolate speculative tactics inside experiments.
    • Require every experiment to name its page set, intervention, primary metric, guardrails, comparison group, measurement period, and decision rule.
    • Use user-level A/B tests for experience and conversion questions, pre/post tests for directional evidence, and concurrent test-control groups for stronger ranking evidence.
    • Scale only when the incremental result survives data validation and business guardrails; hold, investigate, or reverse the rest.
    • Revisit the portfolio when meaningful internal, competitive, algorithmic, or LLM changes invalidate its assumptions.

    At your next budget review, bring the portfolio rather than a prediction. Approve the maintenance floor, name the next controlled bet, document its scale and rollback rules, and identify the events that would change your allocation. You may not remove uncertainty from search, but you can stop paying for it blindly.

    References

  • Google Ads Video Campaign Groups: Planning and Measurement

    Google Ads Video Campaign Groups: Planning and Measurement

    If you run several YouTube awareness campaigns against much of the same audience, each campaign can look acceptable on its own while the account-level picture remains unclear. You still need to know how many people the campaigns reach together, how often those people see your ads, and whether separate campaigns are competing for the same exposure.

    Google Ads video campaign groups give you that broader control layer. You can coordinate multiple YouTube reach and frequency campaigns around one shared reach or frequency objective without giving up their individual budgets, creative assets, or campaign settings. The opportunity is useful, but only if the campaigns belong together strategically.

    One group objective sits above campaign-level controls

    A video campaign group is not merely a folder for tidying an account. It adds cross-campaign optimization and unified reporting for eligible YouTube reach and frequency campaigns. The feature is available globally in Google Ads, but its scope matters: it is designed around reach and frequency management rather than every type of video campaign.

    Decision or controlWhere it remainsHow to use it
    Shared reach or frequency objectiveCampaign groupDefine the exposure outcome the included campaigns should pursue together.
    BudgetIndividual campaignAllocate spending according to each campaign’s role and review the combined amount before launch.
    Creative assetsIndividual campaignKeep distinct messages or executions while coordinating their overall audience exposure.
    Other campaign settingsIndividual campaignPreserve the controls that make each campaign operationally distinct.
    Unique reach and average weekly impressionsCampaign group reportingJudge the combined audience outcome instead of adding campaign reports together.

    The budget distinction deserves special attention. A shared objective does not turn separate campaign budgets into one shared budget. Check every included campaign and calculate the total amount you intend to have active. Otherwise, a clean group-level strategy can sit above an allocation that does not reflect it.

    Key takeaways

    • Use a group when several YouTube reach and frequency campaigns should pursue one audience-exposure outcome.
    • Keep using campaign-level budgets, creatives, and settings to define each campaign’s role.
    • Read unique reach at the group level; adding campaign-level reach can count the same person more than once.
    • Treat unified reporting as a decision tool, not as permission to combine strategically unrelated campaigns.

    Group campaigns by the decision you need to make

    Hands sort video campaign tiles into separate groups represented by reach, frequency, and audience-overlap symbols.

    The best grouping rule is not a naming convention, product line, or account structure. It is whether you would make a shared reach or frequency decision across the campaigns.

    Write the intended decision before building the group: “Across these campaigns, we want to manage for [reach or frequency] among [the intended audience] during [the relevant campaign period].” If that sentence describes every candidate campaign without becoming vague, the group is probably coherent. If you need several different objectives, audiences, or time horizons to finish it, you are likely forcing unlike campaigns together.

    A campaign is a sensible candidate when:

    • It is an eligible YouTube reach or frequency campaign.
    • Its audience exposure should be coordinated with the other campaigns.
    • It supports the same high-level reach or frequency outcome.
    • Its separate budget, creative, or settings serve a clear purpose within that shared outcome.
    • You would take action based on the group’s combined reach and frequency results.

    Keep campaigns in different groups when they pursue conflicting exposure goals, operate over periods that make one combined view misleading, or serve audiences whose results you would never manage together. A campaign focused on expanding the number of people reached and another intentionally concentrating repeated exposure may both be legitimate, but placing them under one ambiguous objective makes the group harder to interpret.

    Separate campaigns can still preserve different creative strategies inside a group. That is one of the feature’s practical strengths. You do not have to flatten meaningful creative or budget differences merely to coordinate delivery across the larger campaign set.

    Build the measurement plan before evaluating the group

    Unified reporting is valuable because campaign reports cannot reveal combined audience reach simply by being added together. If one person sees ads from three campaigns, each campaign can include that person in its own reach result. Summing those figures would treat repeated people as additional people. Group-level unique reach is the relevant view when the business question concerns the whole campaign set.

    The group view includes unique reach, average weekly impressions, and reach-and-frequency performance across the group. Give each metric a job:

    • Unique reach tells you whether the campaigns collectively reached more distinct people. Use the group figure rather than a sum of campaign figures.
    • Average weekly impressions helps you see how much repeated weekly exposure accompanies that reach.
    • Group reach and frequency performance shows whether the combined system is moving toward the shared objective.
    • Campaign-level results help you diagnose which budget, creative set, or campaign setting may be contributing to the group outcome.

    This creates a useful reporting sequence: assess the group first, then investigate campaigns. Starting with individual campaigns can pull you into local optimizations that look beneficial in isolation but do not improve combined reach or exposure.

    1. State whether reach or frequency is the primary group objective.
    2. Record which campaigns are included and why each one belongs.
    3. Confirm every campaign budget and the combined planned allocation.
    4. Review the group-level audience metrics before drawing conclusions from individual campaigns.
    5. Use campaign-level controls to investigate a group-level problem.
    6. Document changes so you can distinguish a strategic adjustment from ordinary variation in delivery.

    Do not expect one metric to answer every question. Growing unique reach can be desirable when expansion is the objective, while more repeated exposure can be intentional when frequency is the objective. The metric only becomes useful after you state which outcome the group is meant to produce.

    Interpret frequency as an account-specific decision

    There is no universal weekly frequency that automatically produces the best result for every advertiser. Google has cited a Meridian marketing mix modeling analysis in which 2.7 impressions per week was the modeled optimum and produced a 19% increase in ROI. Those figures show that frequency can have measurable economic consequences, but they do not establish 2.7 as a default setting for every brand, audience, creative strategy, or campaign period.

    Use 2.7 as a hypothesis worth examining, not a number to copy uncritically. Your practical question is whether additional weekly exposure is still contributing to the campaign’s purpose or merely increasing repetition among people you have already reached.

    Several reporting patterns can guide that investigation:

    • If unique reach is expanding while average weekly impressions remain consistent with your plan, the group may be balancing audience growth and repetition as intended.
    • If average weekly impressions rise while unique reach changes little, investigate whether particular campaign budgets or settings are concentrating delivery among the same people. This is a signal to inspect, not proof of waste.
    • If group performance looks acceptable but one campaign appears weak in isolation, check whether that campaign plays a useful role in the combined result before cutting it.
    • If the group average looks healthy, still inspect campaign-level reporting. An average can conceal one campaign receiving substantially different exposure from another.

    Video campaign groups can help reduce unnecessary overlap and overexposure, but grouping alone does not guarantee either result. The advantage is that you can now see and optimize the shared outcome more directly while retaining the controls needed to correct it.

    Use a controlled first rollout instead of grouping everything

    A small group of active video campaign modules is measured inside a controlled test area while additional modules remain inactive outside it.

    Start with one campaign family whose overlap is easy to explain. A smaller, coherent group makes it easier to learn what the group-level reporting changes in your decisions. Adding every eligible campaign at once can produce a combined result that is technically complete but strategically meaningless.

    1. Inventory eligible campaigns. Identify the YouTube reach and frequency campaigns that may be addressing the same exposure opportunity.
    2. Choose one shared objective. Decide whether the group should prioritize reach or frequency. Do not leave both as equally important if they would lead to different actions.
    3. Define inclusion criteria. Include a campaign only when its exposure should be coordinated with the others.
    4. Verify campaign-level controls. Check budgets, creative assets, and other settings because they remain separate after grouping.
    5. Calculate the active budget. Review the combined allocation before launch or expansion; the group objective does not replace individual budget responsibility.
    6. Assign each campaign a role. Be able to explain why its creative, budget, or settings need to remain distinct.
    7. Review from group to campaign. Start with unique reach, average weekly impressions, and overall reach-and-frequency performance, then use campaign reporting for diagnosis.
    8. Expand only when the group answers a real decision. Add more campaigns when their inclusion improves coordination, not merely because the interface allows it.

    Your first useful group does not need to contain every YouTube awareness campaign. Choose the campaigns most likely to reach the same people, define the shared objective, and use the unified report to decide whether your spending is buying broader reach or additional repetition. If the group cannot support a clear action, tighten its membership before changing its campaigns.

    References

  • How to Run a Google Ads Target ROAS and CPA Health Check

    How to Run a Google Ads Target ROAS and CPA Health Check

    Your campaigns can meet their platform target while the business loses cash. They can also miss an ambitious target while profitable demand goes uncaptured. In both cases, the dashboard is measuring performance against a number that may never have been reconciled with margin, payback, or growth strategy.

    A proper health check turns target ROAS or CPA back into a business rule. You calculate the economic boundary, decide how much profit to reinvest, check whether the account can realistically deliver the result, and then determine whether the next block of advertising spend still earns enough.

    Start with the business decision behind the bid target

    Target ROAS and target CPA look like optimization settings because you enter them in an advertising platform. Their real function is to tell the bidding system what economic outcome you are willing to accept. That makes the target a business decision, not merely an account setting.

    The direction of the constraint matters. A higher target ROAS is stricter because it demands more conversion value from each advertising dollar. A lower target CPA is stricter because it allows less spend per conversion. Tightening either target can protect unit economics, but it can also reduce volume by making fewer auctions acceptable.

    Consider two otherwise similar advertisers. One requires 800% ROAS while the other accepts 400%. The first requires twice as much revenue per advertising dollar. The second can pursue demand that would be rejected under the 800% requirement. Neither strategy is automatically correct: one may prioritize retained margin, while the other may intentionally exchange some margin for market share. The health check establishes whether that choice was made deliberately and whether the business can fund it.

    Health-check questionEvidence you needDecision it supports
    Where is break-even?Effective margin, profit per customer, lead-to-sale rate, and payback windowThe ROAS floor or CPA ceiling below which acquisition loses money
    How much profit should acquisition consume?The share of profit the business is willing to reinvestThe operating target entered into the account
    Can the account deliver that target?Actual performance, spend, conversion volume, mix, and measurement qualityWhether the target is plausible under current conditions
    Should you spend more?Incremental value or conversions produced by incremental spendWhether the next block of spend meets the business threshold

    Keep those questions separate. Break-even is not your recommended operating target. Average account performance is not the return on additional spend. And a target that is economically sound is not necessarily attainable without changes to conversion rate, offer, traffic quality, or campaign structure.

    Calculate the economic boundary with honest inputs

    An isometric workbench divides revenue from one product into production, shipping, returns, fees, profit, and advertising reserves.

    The first calculation identifies where paid acquisition stops contributing profit under your chosen cost and payback assumptions. For ecommerce, that boundary is usually expressed as a minimum ROAS. For lead generation, it is usually a maximum CPA.

    Break-even ROAS for ecommerce

    Use this formula, with effective margin expressed as a decimal:

    Break-even ROAS = 1 / effective margin

    At a 40% effective margin, break-even ROAS is 2.5, normally displayed as 250%. Every $1 of advertising spend must therefore produce $2.50 of revenue merely to replace the profit consumed by that spend. This is a boundary, not a recommendation: at exactly break-even, the acquisition uses all the profit included in the calculation.

    The dangerous input is margin. Do not copy the headline gross-margin percentage from a management deck without checking what it excludes. Effective margin should reflect the costs required to fulfill the order, including subsidized shipping, payment fees, fulfillment, and returns where applicable. A retailer that begins with a 40% gross margin and faces a 25% return rate may end up with an effective margin in the low 30% range after the relevant deductions. At 30%, the break-even ROAS rises from 250% to about 333%.

    That difference explains why a campaign can look profitable in Google Ads while finance sees weak cash generation. The platform may be reporting gross conversion value, while the business earns profit on net, fulfilled, non-returned orders. Before changing the target, reconcile those definitions. If product groups have materially different effective margins, calculate their boundaries separately rather than letting a blended average hide which sales create profit.

    Break-even CPA for lead generation

    When the advertising conversion is a lead rather than a sale, use:

    Break-even CPA = profit per customer within the payback window x lead-to-sale conversion rate

    If a customer produces $1,000 in profit within the selected payback period and one in five advertising leads becomes a customer, the break-even lead CPA is $200. Paying more than $200 per lead loses money under those assumptions. Paying less leaves some profit after acquisition.

    The payback window must be selected before you calculate the CPA. Full lifetime profit creates a more generous ceiling, but it may take years to materialize. A business that needs its cash back within six or 12 months should use only the profit expected inside that window. Using lifetime value while managing against a shorter cash requirement produces a mathematically correct answer to the wrong business question. The formula is only as reliable as its profit window and conversion-rate inputs.

    Match the lead-to-sale rate to the conversion counted by the campaign. If Google Ads optimizes toward submitted forms, do not insert the close rate for sales-qualified opportunities unless every counted form is also a qualified opportunity. Reconcile the stages first, or calculate separate economics for each lead type.

    Turn break-even into an operating ROAS or CPA target

    Break-even tells you where profit disappears. Your operating target determines how much profit the business intends to keep. The missing input is the acquisition share: the percentage of available profit you are willing to spend to acquire the customer.

    For ecommerce:

    Operating target ROAS = 1 / (effective margin x acquisition share)

    For lead generation:

    Operating target CPA = profit per customer within the payback window x lead-to-sale conversion rate x acquisition share

    Express acquisition share as a decimal in both formulas. At a 100% acquisition share, the operating target equals break-even because all available profit is reinvested. A smaller share raises the required ROAS or lowers the allowable CPA, leaving more profit after acquisition. Spending beyond 100% means accepting a loss within the defined payback window, which requires an explicit, funded strategic decision rather than an unnoticed bidding change.

    This is where finance, marketing, and leadership must agree. The correct share depends on the job paid acquisition is expected to do. A business protecting cash may retain more profit. A business deliberately pursuing market share may reinvest more. The platform cannot resolve that trade-off because it does not own the profit-and-loss decision.

    1. Get the effective margin or payback-period profit approved by the person who owns the P&L.
    2. Confirm that the revenue, lead, and customer definitions match what the advertising account measures.
    3. Choose the acquisition share based on the current cash, profit, and growth objective.
    4. Calculate the operating target and document every assumption beside it.
    5. Record who approved the target and what event will trigger a recalculation.

    Recalculate when pricing, product mix, fulfillment costs, return rates, close rates, or the payback requirement changes. Even without an obvious trigger, the owner of the number and the advertising team should review the assumptions at least once a year. An inherited target without assumptions, an owner, and a review date is not a strategy.

    Pressure-test the target against account reality

    An economically defensible target can still be unrealistic for the account in its current state. Smart Bidding cannot manufacture conversion rate, demand, measurement quality, or order value. If the target demands performance far beyond what the account can currently produce, tightening it can suppress spend and conversions without fixing the underlying economics.

    Start the outside-in check with measurement. Confirm which actions are counted as primary conversions, whether revenue values reflect cancellations and returns, whether lead quality is available downstream, and whether conversion delay makes recent performance incomplete. A target calculation built on net economics cannot be evaluated against a platform report built on inflated gross outcomes.

    Next, create a representative baseline. Put the operating target, actual ROAS or CPA, break-even boundary, spend, conversion volume, and business-quality outcome in the same view. Segment where economics differ materially, but do not fragment the data merely to find a favorable result. You need enough evidence to distinguish a persistent constraint from ordinary variation.

    What you observeWhat it may meanWhat to check before changing the target
    The platform target is met, but cash contribution is weakThe account and finance are using different value, margin, return, or payback definitionsReconcile conversion value with fulfilled orders or downstream customer profit
    ROAS repeatedly misses the target, or CPA exceeds it, while spend and conversions contractThe target may be too restrictive for current account conditionsCheck tracking, conversion rate, traffic quality, campaign coverage, and whether the economic assumptions are still valid
    Actual performance comfortably beats the target while available budget goes unusedA stricter-than-needed target, limited demand, or another delivery constraint may be suppressing growthConfirm profitable demand exists, then test a controlled relaxation rather than changing the whole account
    Spend and conversions grow, but the business return deterioratesThe additional orders, products, or leads may have weaker economics than the existing averageCalculate marginal ROAS or CPA and inspect product or lead quality mix

    These patterns identify where to investigate; they do not prove a cause. Conversion rate, Quality Score, offer strength, competition, and demand can all change what the auction permits. The target is the main bidding lever you control, but it is not the only driver of the outcome. A landing-page problem does not become a bidding problem simply because the target is the easiest field to edit.

    When a target appears unrealistic, do not immediately loosen it across the account. First decide whether the business economics are wrong, the measurement is wrong, or the account needs operational improvement. If the economics are valid and the measurement is clean, a limited test can show how much volume becomes available at a less restrictive target and whether that volume remains profitable.

    Test whether the next advertising dollar still earns enough

    Equal stacks of advertising tokens produce progressively smaller returns across a row of vessels as a hand considers the next investment.

    Average ROAS and CPA describe all the spend already in the account. They do not tell you whether additional spend is attractive. Strong existing traffic can keep an average healthy even when the newest block of spend performs below the business threshold. That is why the final health check focuses on the marginal return.

    The last advertising dollar is not meant literally. In practice, you test a measurable increment of spend under comparable conditions. Use a controlled experiment or a carefully matched baseline and test period, and avoid changing prices, promotions, conversion definitions, landing pages, and bid targets at the same time. Otherwise, you will not know what produced the difference.

    For a ROAS campaign, calculate:

    Incremental spend = test spend – baseline spend

    Incremental conversion value = test conversion value – baseline conversion value

    Marginal ROAS = incremental conversion value / incremental spend

    For a CPA campaign, calculate:

    Incremental conversions = test conversions – baseline conversions

    Marginal CPA = incremental spend / incremental conversions

    If extra spend produces no additional conversions, marginal CPA is not meaningfully calculable as a favorable result. Treat that as a failed expansion test, then check whether conversion delay, tracking, or external demand distorted the observation before drawing a final conclusion.

    1. Select a campaign or segment with clean measurement and economics you can isolate.
    2. Record baseline spend, conversion value, conversion count, and downstream business quality.
    3. Define the target or budget change, the maximum financial exposure, and the rule for stopping the test.
    4. Change one material lever and allow the normal conversion delay and lead-quality feedback to arrive.
    5. Calculate incremental results rather than comparing only the two average ROAS or CPA figures.
    6. Apply the same margin, payback, and value definitions used to calculate the operating target.
    Marginal resultEconomic meaningPractical decision
    Marginal ROAS meets or exceeds the operating target, or marginal CPA meets or beats the operating targetThe additional spend satisfies the chosen profit-retention policyConsider another controlled expansion while monitoring mix and downstream quality
    The marginal result is profitable but misses the operating targetThe added spend remains above break-even but retains less profit than the agreed policy requiresScale only if leadership deliberately accepts the margin-for-growth trade-off
    Marginal ROAS falls below break-even, or marginal CPA exceeds break-evenThe added spend destroys contribution under the approved assumptionsRevert or stop the expansion unless the business has explicitly authorized and funded a loss-making strategy

    Run this check before declaring that a profitable average justifies more budget. The useful question is not whether the account has made money so far. It is whether the incremental advertising dollar still clears the required economic threshold.

    Key takeaways

    • Break-even ROAS is 1 divided by effective margin. Use margin after the costs required to fulfill the order, not an unadjusted headline percentage.
    • Break-even CPA is payback-period profit per customer multiplied by the lead-to-sale conversion rate. The lead definition and payback window must match the business reality.
    • Your operating target should preserve the agreed share of profit. For ROAS, divide 1 by effective margin multiplied by acquisition share. For CPA, multiply break-even CPA by acquisition share.
    • A higher target ROAS and a lower target CPA are more restrictive. Either can protect profit or suppress viable volume, depending on whether the target is economically justified.
    • Average performance cannot answer whether you should spend more. Use marginal ROAS or CPA to evaluate the additional spend separately.

    Before the next bid-strategy change, put the margin, payback, close-rate, acquisition-share, measurement, and marginal-return assumptions in one worksheet. Get the definitions approved by the P&L owner, then test any expansion in a limited scope with a clear loss boundary. That turns the target from an inherited number into a decision you can defend and revise.

    References

  • Technical SEO Prioritization: What to Fix First and Why

    Technical SEO Prioritization: What to Fix First and Why

    You have a crawl report full of red warnings, a development queue with little room, and stakeholders asking what any of the proposed work will change. Turning every warning into a ticket will fill the backlog. It will not tell you what deserves to be fixed first.

    Technical SEO prioritization is a constrained investment decision. Very few technical activities deserve top priority on every website. Before requesting developer time, you need to establish that the problem exists on your site, affects something valuable, has a plausible path to a business outcome, and can be measured after the change.

    Key takeaways

    • An audit warning is a signal to investigate, not proof that development work is necessary.
    • Prioritize the obstacle and its consequence: which important pages, users, or search bots are affected, what they cannot do, and what that costs the business.
    • Only score an implementation after you have evidence, a causal mechanism, an affected scope, a success metric, and an estimate of effort and risk.
    • Core Web Vitals work, redirect cleanup, and crawl optimization become priorities when they address demonstrated harm. They are usually weak requests when they only improve an already acceptable score or remove harmless warnings.
    • Every development ticket should state the expected outcome, baseline, acceptance criteria, measurement plan, opportunity cost, and condition under which the work should be stopped or reconsidered.

    An audit finding is not automatically a problem

    An audit tool observes technical conditions. It may find redirected internal links, slow test results, duplicate URLs, crawlable parameters, or other departures from its preferred configuration. That is useful evidence, but the tool does not know which page groups produce revenue, which warnings affect real users, what your search performance depends on, or what your developers would have to postpone to clear the alert.

    This is the distinction that keeps a technical backlog under control: a finding describes what exists; a problem explains why that condition is harmful here. If the only justification is that an audit alert needs to be cleared or a best-practice box needs to be checked, the request is not ready for implementation.

    Turn each material finding into a short diagnostic brief before you prioritize it:

    1. Observed condition: Describe what is happening on production URLs, not just the name of the audit rule.
    2. Affected scope: Identify the page group, template, user journey, or crawl path involved. Separate valuable URLs from incidental ones.
    3. Failure mechanism: Explain what the condition prevents or makes harder. A bot may be unable to reach a destination, a user may struggle to load a page, or unwanted URLs may consume crawling activity.
    4. Likely consequence: Connect the failure to qualified organic traffic, conversion, revenue, churn, usability, or another outcome the business already recognizes.
    5. Baseline evidence: Record the current technical and business measurements. Without a baseline, a successful deployment can still leave you unable to demonstrate success.
    6. Counterevidence: Note what would weaken the case. If important content is already being crawled reliably, for example, a broad crawl-budget project may not solve a current problem.

    The causal sentence should be plain: Because this condition affects this valuable scope, users or bots cannot complete this behavior, which puts this measurable outcome at risk. If you cannot complete that sentence without relying entirely on words such as could or might, do not disguise uncertainty with a high audit severity. Create a smaller validation task and collect the missing evidence first.

    Compare two redirect requests. Internal links return 301 responses merely restates a crawler result. Links on an important template enter a redirect loop, so neither users nor bots can reach the intended destination describes an operational problem. The second statement provides a mechanism, scope, consequence, and testable result. The first does not.

    The same discipline applies to performance. Improve the page-speed score treats the score as the outcome. Bring a failing, revenue-producing page group into the acceptable range and test whether its conversion rate improves distinguishes the diagnostic metric from the business result.

    Use evidence, impact, reach, cost, and risk to rank the work

    An isometric system moves a broken webpage tile through checkpoints represented by a magnifying lens, connected network, tools, and shield before it reaches a workbench.

    Do not begin with a weighted spreadsheet. Scoring weakly defined tickets creates false precision. First pass each request through a decision gate; then use a consistent set of dimensions to compare the requests that remain. This matters because SEO time and developer capacity are both limited, and every accepted ticket displaces another piece of work.

    1. Is the condition real? Confirm it on representative production URLs. If the finding is stale, confined to a test environment, or caused by the crawler configuration, close it before estimating a fix.
    2. Does it affect valuable scope? Segment affected URLs by template, purpose, organic opportunity, and business role. A large count of unimportant URLs should not automatically outrank a smaller set of critical pages.
    3. Is the mechanism credible? State how the condition interferes with crawling, loading, navigation, or another necessary behavior. A correlation without a mechanism deserves investigation, not an expensive rollout.
    4. Can you name the outcome and measure it? Choose a primary business or user metric and a supporting technical metric. If the technical score improves while the meaningful outcome does not, report that distinction.
    5. Is the intervention proportionate? Estimate engineering, quality assurance, content, analytics, and release effort. Include regression risk and the availability of a safe rollback.
    6. What loses if this wins? Compare the request with the work it would displace. Opportunity cost belongs in the priority decision, not in a footnote added after approval.
    DimensionQuestion to answerEvidence that strengthens priority
    ImpactWhat meaningful outcome changes if the fix works?A direct path to revenue, qualified traffic, conversion, retention, usability, or access to important content
    ConfidenceHow certain are you that this condition causes the observed harm?Reproducible behavior, consistent measurements, and a mechanism that fits the evidence
    Reach and valueWhich pages, users, and journeys are affected?A clearly defined page group with material organic or business value
    EffortWhat must be designed, built, tested, deployed, and monitored?A bounded change with known dependencies and realistic acceptance criteria
    RiskWhat can regress, and how will you recover?A contained release, observable guardrails, and a practical rollback
    MeasurabilityHow will you distinguish a successful fix from a successful deployment?A recorded baseline, a technical indicator, a primary outcome, and a defined evaluation condition

    Put every request into one of three queues

    • Commit: The problem is demonstrated, the affected scope matters, the expected outcome is measurable, and the cost and risk are justified. Prepare the implementation ticket.
    • Validate: The suspected harm is plausible, but evidence, scope, or causality is incomplete. Approve a diagnostic task rather than the full fix.
    • Park: The request is based on a warning, cosmetic cleanliness, or incremental improvement with no material expected outcome. Record the reason and a condition that would reactivate it.

    This approach avoids two common distortions. First, URL count is not the same as business reach: one critical landing-page template can matter more than a much larger archive with no meaningful search demand. Second, a sitewide warning is not automatically severe. If users and bots can complete the required behavior and no outcome is being harmed, broad reach merely describes how widely a harmless condition appears.

    You also do not need to force every decision into a numerical score. A critical access failure can outrank other work even when its affected URL count is small. A low-risk housekeeping change can remain parked even when it is easy. Use the dimensions to expose the tradeoff, not to let arithmetic make the decision for you.

    Know when three familiar technical fixes are worth doing

    Almost any technical recommendation can be valuable in the right context. The mistake is treating the recommendation itself as the context. Core Web Vitals, redirects, and crawl-budget work show how the same task can be urgent on one site and unproductive on another.

    Core Web Vitals: fix failure before optimizing success

    Core Web Vitals work has a sensible stopping point. If an important page group is outside the applicable good range, users struggle to load it, or poor performance damages usability, there is a concrete problem to solve. Once those pages are in the good range, however, shaving a few more milliseconds from Largest Contentful Paint is likely to deliver diminishing returns.

    • Commit when valuable pages genuinely miss the target and the loading experience interferes with use of the page.
    • Validate when a test score looks poor but you have not yet established which production pages and users are affected.
    • Park when the page group is already in the good range and the proposed outcome is merely a greener score.
    • Measure the affected performance metric alongside the relevant user or business result. On an ecommerce page group, that may include conversion rate and revenue rather than load time alone.

    This does not make speed unimportant. It keeps the goal honest. A development team should know whether it is repairing a poor experience or pursuing a small technical improvement whose commercial effect is unknown.

    Redirects: treat broken paths as defects, not every 301

    A redirect is not inherently a defect. Its job is to send a request to a different destination. The prioritization question is whether that behavior prevents efficient access to the correct page.

    Redirect work becomes material when you find loops, irrelevant destinations, widespread paths that impair crawling, or chains extending beyond five hops. Those conditions can stop or hinder users and bots before they reach the intended content. A crawl report that merely contains ordinary 301 responses does not establish the same harm.

    • Commit when a loop blocks the destination, a long chain creates a meaningful access problem, or redirects repeatedly send requests to irrelevant pages.
    • Validate when the report contains many redirects but you do not know whether they form harmful chains or affect important crawl paths.
    • Park when links resolve reliably through a single appropriate redirect and no crawling or user problem is evident.
    • Handle opportunistically when you are already editing the relevant CMS content and can update an internal link to its final destination at negligible additional cost.

    The opportunistic edit and the priority project are different decisions. It is reasonable to remove avoidable hops while touching a page. It is harder to justify displacing higher-impact work solely to make a crawl report free of redirect notices.

    Crawl budget: require evidence that crawling is constrained

    Crawl optimization depends heavily on scale and site behavior. Large enterprise sites are more likely to need crawl-path work, while crawl budget is usually not a material issue for smaller sites. Site size alone is not the diagnosis, though. The useful evidence is whether bots are spending time in spider traps or unwanted URL spaces while important content is difficult to reach.

    • Commit when spider traps create uncontrolled crawling, unwanted pages consume substantial attention, or important content is not reliably crawlable.
    • Validate when the concern is based on site size or URL count but Google Search Console and your crawl evidence have not yet shown an access problem.
    • Park when important content is already crawlable and no unwanted crawl pattern is interfering with it.
    • Reactivate the work if a new template, parameter space, or navigation pattern creates a trap or makes valuable sections harder for bots to reach.

    Do not ask developers to optimize an abstract budget. Name the wasteful path, the valuable path it competes with, the evidence of interference, and the measurement that will show the intervention worked.

    Turn the winning priority into a measurable development ticket

    A developer repairs a selected broken component and restores an illuminated path through a modular website model.

    A technically correct request can still lose the sprint-planning conversation if it does not explain its value. Developers need enough detail to estimate and test the change. Decision-makers need to understand why the work is financially or operationally preferable to everything it would displace.

    A decision-ready ticket should contain the following:

    1. Problem statement: Describe the observed production behavior and why it is harmful. Do not paste the audit recommendation in place of a diagnosis.
    2. Affected scope: Name the templates, page groups, journeys, and audiences involved. Include unaffected scope when that boundary helps contain the implementation.
    3. Evidence: Attach reproducible examples and the relevant crawl, Google Search Console, performance, analytics, or business measurements.
    4. Expected outcome: State what should improve for users, search bots, or the business. Revenue, qualified traffic, conversion, and churn are stronger outcomes than clearing an alert.
    5. Proposed intervention: Define the intended behavior while leaving room for engineering to choose a safe implementation where appropriate.
    6. Acceptance criteria: Specify what must be true on the affected URLs after release. Include technical checks and any guardrail that must not regress.
    7. Measurement plan: Record the baseline, primary outcome, supporting technical metric, comparison method, and the condition under which you will evaluate the result.
    8. Effort, dependencies, and risk: Identify other teams, release constraints, quality-assurance needs, possible regressions, and rollback requirements.
    9. Opportunity cost: Name the competing work likely to be delayed. This forces an explicit choice instead of treating developer capacity as free.
    10. Reactivation or stop condition: State what new evidence would revive a parked request, invalidate the proposed fix, or end further optimization.

    Model the business case without turning a scenario into a promise

    Page speed illustrates the difference between a metric and a case for investment. Reducing load time is an implementation objective. The business case may be that a faster ecommerce experience could improve conversion on the affected page group. To test that case, record its current organic traffic, conversion rate, and annual revenue, then model what a plausible change in conversion would mean while making the assumptions visible.

    Keep a scenario labeled as a scenario. It is not a forecast merely because it appears in a spreadsheet. The ticket should separate what you know now, what you expect the intervention to change, and what you will measure afterward. That prevents a successful technical release from being reported as proven commercial growth before the business metric has moved.

    The same separation works for non-revenue outcomes. A crawl fix can be technically successful because important destinations become reachable, while qualified traffic remains unchanged. A redirect repair can remove a loop without affecting conversion. Record both results. The technical result tells you whether the implementation worked; the business result tells you whether the original prioritization hypothesis was valuable.

    Close the loop after release

    • Confirm that the acceptance criteria hold on the intended production scope, not only on a test URL.
    • Check guardrails for regressions before attributing any broader benefit to the change.
    • Compare the supporting technical metric with its baseline.
    • Evaluate the primary user or business outcome separately and preserve uncertainty where other changes could have contributed.
    • Record whether the hypothesis was supported, contradicted, or remains unresolved. Use that result to improve confidence estimates for similar backlog items.
    • Stop incremental work when the original harm is resolved and the next proposed improvement lacks a measurable expected return.

    Now open your technical backlog and take its highest-ranked request. Rewrite it in one sentence: We should make this change because this evidence shows that the current condition affects this valuable scope, interferes with this necessary behavior, and puts this outcome at risk; success will be measured this way. If you cannot fill every part with evidence, move the request to validation or park it with a reactivation trigger. That decision is useful technical SEO work too.

    References

  • Performance Max for Local Services: A 2026 Migration Plan

    When Performance Max appears next to your Local Services campaigns, the name may sound like a warning that Google is about to broaden your placements, change your billing model, or replace local lead generation with another automated media campaign. That is not what this migration does.

    The new campaign remains a keywordless, pay-per-lead product limited to Search and Maps. What changes is where you manage it, how closely it connects to your Google Business Profile, and where your reporting history lives. Your job is to preserve that history, clean up the profile data feeding the campaign, and verify the transfer instead of assuming that an automatic migration needs no supervision.

    The Performance Max name does not mean broader ad distribution

    This campaign type is being built specifically for eligible Local Services advertisers. It is not a conventional Performance Max campaign adapted to a local objective. The underlying Local Services model remains intact, including Search and Maps distribution, keywordless matching, and payment for valid leads rather than clicks.

    Campaign elementWhat happens after migrationWhat it means for you
    ManagementCampaigns, calls, and leads move into Google AdsYour team can manage Local Services alongside other Google Ads campaigns instead of using a separate dashboard.
    Ad surfacesAds continue to appear only on Search and MapsDo not build a forecast that assumes access to Google’s other advertising channels.
    TargetingThe campaign remains keywordless and uses Google Business Profile informationAccurate profile data matters more than constructing a keyword list for this campaign.
    BillingYou continue to pay for valid leads, including qualifying calls, messages, and bookings, rather than clicksClick-based campaign benchmarks are not the right basis for evaluating its economics.
    Business informationGoogle Business Profile changes sync to the campaign in real timeProfile edits become campaign-management events, not merely directory maintenance.

    This distinction prevents the most expensive planning mistake: applying a standard Performance Max playbook to a product that still behaves like Local Services Ads. You do not need a cross-channel creative plan for this migration. You need control over your Business Profile, lead operations, budget, and reporting archive.

    Your Google Business Profile becomes live campaign data

    The tighter Google Business Profile connection is the most consequential operational change. Updates to business information and photos will flow into the campaign in real time, reducing duplicate maintenance while increasing the consequences of an inaccurate or poorly coordinated edit.

    Do not respond by making more profile changes. Respond by making ownership explicit. A marketing specialist, branch manager, agency, and customer-service lead should not all be able to alter campaign inputs without a shared process.

    • Audit the public business details. Check that the information currently shown in the profile is accurate before it becomes a continuously synchronized campaign input.
    • Review the photo set. Remove the assumption that profile photos and paid creative are separate inventories. Confirm that the photos are current, representative, and suitable for prospective customers.
    • Inventory access. Identify who can change the Google Business Profile and who is responsible for the campaign in Google Ads. Resolve abandoned, duplicated, or unclear ownership before the migration notice arrives.
    • Create a change log. Record what changed, who approved it, why it changed, and when it was published. If lead performance moves afterward, you will have a credible point of comparison.
    • Coordinate local and paid teams. A profile update made for local visibility can also alter campaign information. Require both owners to review material business-detail and photo changes.

    A keywordless campaign does not mean an input-free campaign. It means the inputs are different. For this product, your Google Business Profile supplies information that a conventional search campaign might otherwise express through keywords, ads, and landing-page choices. Treating the profile as an unattended listing leaves a core campaign input without governance.

    Preserve your history before the migration window opens

    The rollout is scheduled to start with a small group of U.S. advertisers in pet care, home services, wellness, and education in early August 2026. It is expected to continue in phases through 2027, with advertisers receiving advance notice before migration. Because the rollout is phased, use the notice in your own account as the operational trigger rather than another advertiser’s migration date.

    Existing budgets, settings, and creative assets are expected to transfer automatically. Historical performance reports are not expected to move into Google Ads. That creates an asymmetric risk: the live campaign may arrive intact while the evidence you need to judge it remains behind.

    1. Download historical reporting first. Do this as soon as you receive notice. Do not postpone the export until after you have inspected the new campaign.
    2. Record the reporting cutoff. Write down the last date covered by the standalone Local Services reporting and the first date managed in Google Ads. This prevents gaps and double counting later.
    3. Snapshot the live configuration. Preserve the budget, settings, and creative-asset inventory that should transfer. Automatic transfer is a convenience, not proof that every field landed as intended.
    4. Archive the files somewhere durable. Put exports and configuration records in a location owned by the business, with a clear account name and date. Do not leave the only copy in an individual’s downloads folder.
    5. Confirm access to both systems. The people responsible for validation need working access to Google Ads and the connected Google Business Profile before cutover.
    6. Freeze unrelated edits if practical. Avoid changing the budget, settings, business details, or photos between your final snapshot and initial validation. A stable comparison makes discrepancies easier to isolate.
    7. Verify the migrated campaign promptly. Compare the transferred budget, settings, and assets against your snapshot. Then confirm that the synchronized business information and photos represent the correct business.

    The export is not administrative housekeeping. Once historical reports fail to migrate, you cannot assume that a long-term chart in Google Ads represents the campaign’s full history. Preserve the old dataset while it is still available, even if your immediate reporting needs seem modest.

    Measure lead value separately from Google’s billing status

    Centralized management can make the account easier to operate, but it does not make every lead equally useful. The campaign charges for valid leads, not completed jobs or customer lifetime value. A lead can therefore be valid for platform billing while still failing your internal qualification criteria.

    Keep two definitions separate:

    • Platform-valid lead: a call, message, or booking accepted as a billable lead under the campaign model.
    • Business-qualified lead: an inquiry that fits your service, customer, and operational requirements.

    Use the historical export and your existing lead log or CRM to maintain a continuous business view across the migration. For each lead, retain the source period, lead type, billing status, contact outcome, qualification outcome, and booked or completed outcome where your process already collects them. This lets you evaluate three different questions instead of compressing them into one metric:

    1. Did the campaign generate valid leads? Review lead volume and cost per valid lead.
    2. Did operations turn them into real opportunities? Review contact and qualification outcomes.
    3. Did those opportunities create business? Review bookings, completed work, or the commercial outcome your business already uses.

    On the first complete reporting period after migration, compare results with an appropriate pre-migration period from your archive. Annotate the cutover, any Business Profile edits, budget changes, and operational changes. If performance moves, this record will help you distinguish a platform transition from a change you made at the same time.

    Do not interpret the move into Google Ads as a new historical baseline. The interface changes, but the campaign’s economic question does not: are you acquiring enough qualified, commercially useful leads at a cost the business can sustain?

    Key takeaways for Local Services advertisers

    • Performance Max for pay-per-lead goals remains a Local Services product, not a conventional cross-channel Performance Max campaign.
    • Ads remain limited to Search and Maps, targeting remains keywordless, and billing remains based on valid leads rather than clicks.
    • Google Ads becomes the management interface, while Google Business Profile information and photos sync into campaigns in real time.
    • Budgets, settings, and creative assets are expected to transfer automatically, but you should still snapshot and verify them.
    • Historical reports will not migrate into Google Ads, so download and archive them before your transition.
    • Track business-qualified and completed outcomes separately from Google’s valid-lead status.

    Your best next step is small and immediate: assign an owner for the Google Business Profile and define where historical Local Services exports will be stored. When the migration notice arrives, you will already know who validates the inputs, who preserves the baseline, and who signs off on the transferred campaign.

    References

  • How a £50 Meta Campaign Became a £1,000 PPC Lesson

    How a £50 Meta Campaign Became a £1,000 PPC Lesson

    A small budget error can become an expensive account-management problem when it is paired with weak monitoring. Google Ads specialist Heather Robinson’s account of a Meta campaign overspend illustrates how routine work, rather than unfamiliar technology, can create the greatest operational risk.

    As reported by Search Engine Land, the campaign was supposed to spend £50 over one weekend but ultimately exceeded £1,000. The episode offers practical lessons about launch controls, conversion tracking, client communication and the proper role of AI in paid media.

    How one budget setting changed the campaign

    Robinson said the £50 budget was configured as a daily amount rather than a lifetime limit. The campaign was then left running for three weeks and was not reviewed until she prepared for a client meeting.

    The distinction between the two budget types was decisive. A lifetime budget is intended to govern spending across a campaign’s scheduled duration, while a daily budget communicates an ongoing daily spending target. Selecting the wrong option therefore changed both the amount the platform could spend and the length of time during which it could continue doing so.

    According to Robinson, the underlying problem was complacency rather than a lack of platform knowledge. Repetition had made the setup feel automatic, while a heavy workload and the absence of another reviewer allowed the incorrect setting to pass unchecked.

    Key takeaways for paid media teams

    • Familiar campaign types still require a complete pre-launch review.
    • Budget type, amount, dates and post-launch delivery should be checked separately.
    • Tracking must represent genuine business outcomes, not merely convenient website actions.
    • AI can accelerate analysis, but an experienced person should remain accountable for approval.
    • When an error affects a client, direct disclosure and a prevention plan can help preserve trust.

    A checklist must extend beyond the launch button

    The incident led Robinson to introduce a structured checklist for every Google Ads and Meta launch, regardless of how familiar the work appears. That response matters because experience and process solve different problems: experience helps a marketer make informed decisions, while a checklist protects against skipped steps, interruptions and misplaced confidence.

    A useful control should cover campaign settings before publication and confirm actual behavior afterward. Budget amount and type, start and end dates, targeting, creative, conversion actions and account ownership all deserve explicit review. An early delivery check then tests whether the live campaign matches the approved plan. For higher-risk launches, a second reviewer can provide additional protection, but even an individual practitioner can create separation by reviewing the setup after a pause rather than approving it immediately.

    Futuristic web browser and analytics dashboard overlap amid neon data streams, illustrating the convergence of SEO, PPC and AI-driven search marketing.
    Organic visibility, paid media and artificial intelligence merge into one connected search ecosystem, where vivid data streams link a creative website with a powerful analytics dashboard.

    Correct spending is not enough if measurement is wrong

    Robinson identified inaccurate conversion tracking as the most common problem she encounters when auditing new client accounts. She linked many of those problems to mistakes made during migrations from Universal Analytics to GA4, leaving some advertisers optimizing toward actions that do not produce revenue.

    In one example she discussed, an ecommerce account had spent a year treating use of the site’s search bar as the optimization goal instead of completed purchases. Once that configuration was corrected, the account effectively had to begin rebuilding its machine-learning signals around the right outcome.

    This broadens the lesson beyond budget control. A campaign can obey its spending limit and still make poor decisions if the conversion signal is misconfigured. Before evaluating automated bidding or creative performance, advertisers should verify what each primary conversion represents, whether it fires at the correct moment and whether it corresponds to a meaningful business result.

    Accountability and human review remain essential

    Robinson chose to disclose the overspend during a scheduled face-to-face meeting, accept responsibility and explain how she would prevent a recurrence. Search Engine Land reported that the client was unhappy but valued her transparency; nearly a decade later, the company remains a client. The outcome does not make the error harmless, but it shows why a candid explanation is more constructive than blaming the advertising platform or minimizing the impact.

    The same accountability principle applies to AI. Robinson uses AI for tasks such as reviewing search-term reports and identifying possible optimization opportunities, but she does not treat it as a substitute for manual checks. She also warned that unreviewed AI-generated ads can produce repetitive, low-quality messaging.

    Paid media platforms will continue adding automation and new features. The durable response is to test them within clear controls, keep a person responsible for final decisions and turn each failure into a stronger operating process.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot