Tag: Budget Management

  • How to Test Google Ads AI Max Without Losing Match Precision

    How to Test Google Ads AI Max Without Losing Match Precision

    AI Max can make a Search campaign look as if it has found new demand when much of the movement is happening inside the account. An old query may be credited to a different keyword, routed through another ad group, or served with a different URL or message. If you judge the setting from its headline totals, that movement can look like growth.

    Your real question is not whether AI Max is good or bad. It is whether the setting adds valuable searches after you remove traffic the campaign could already reach, without weakening control over brand terms, landing pages, messaging, or budget.

    AI Max turns match precision into four separate questions
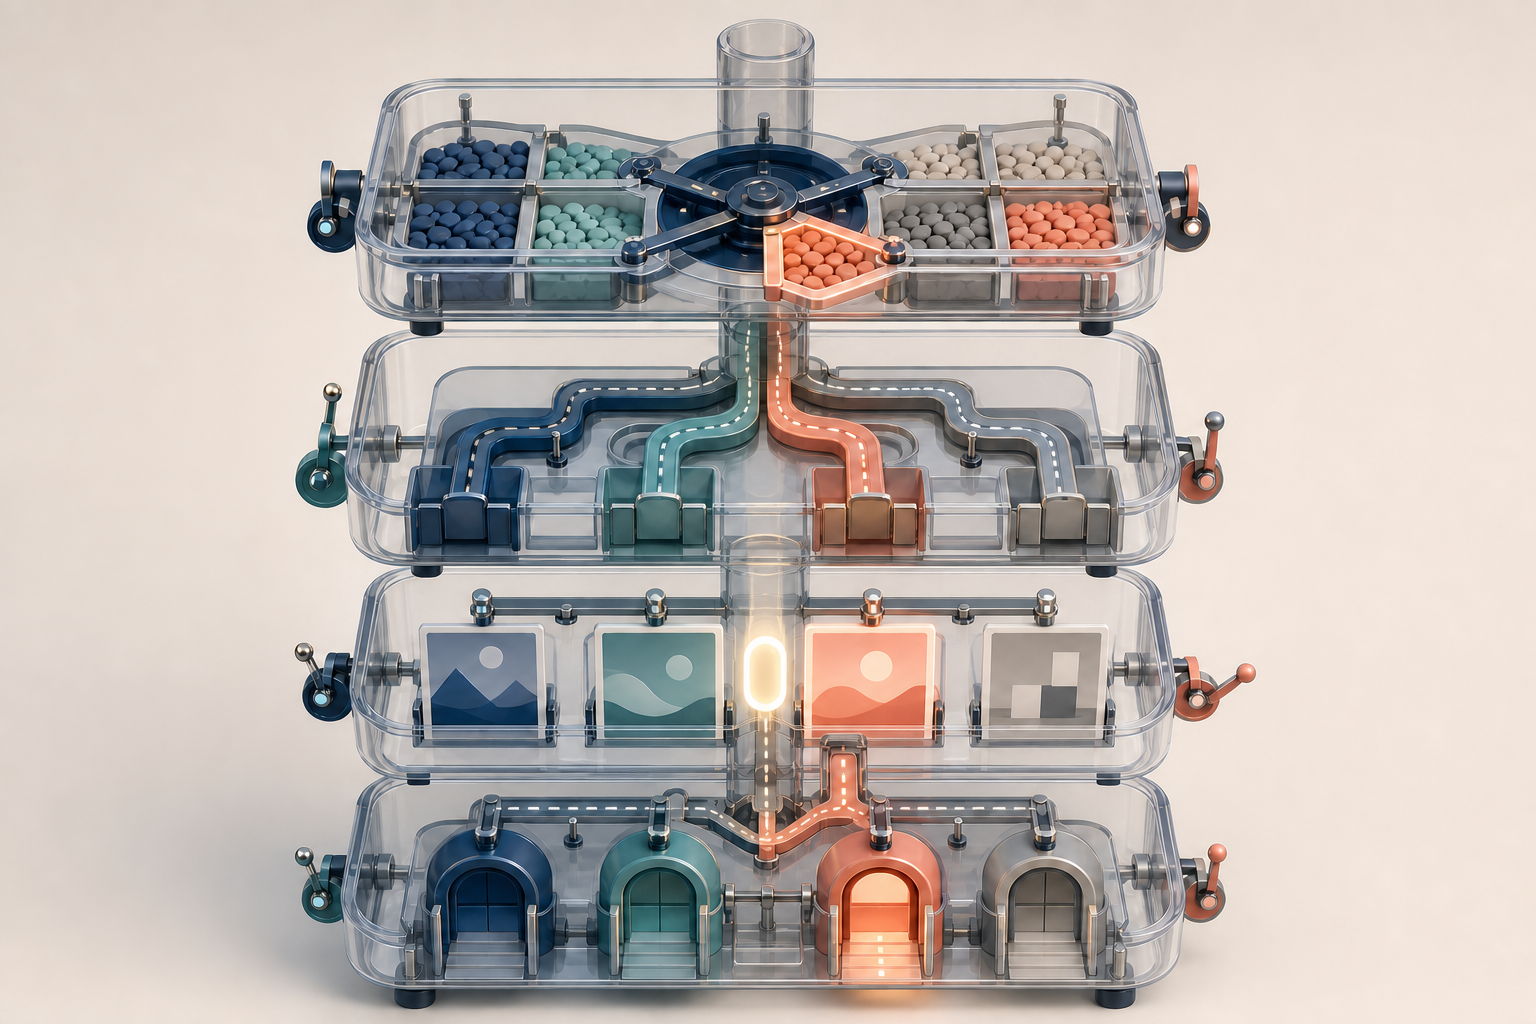
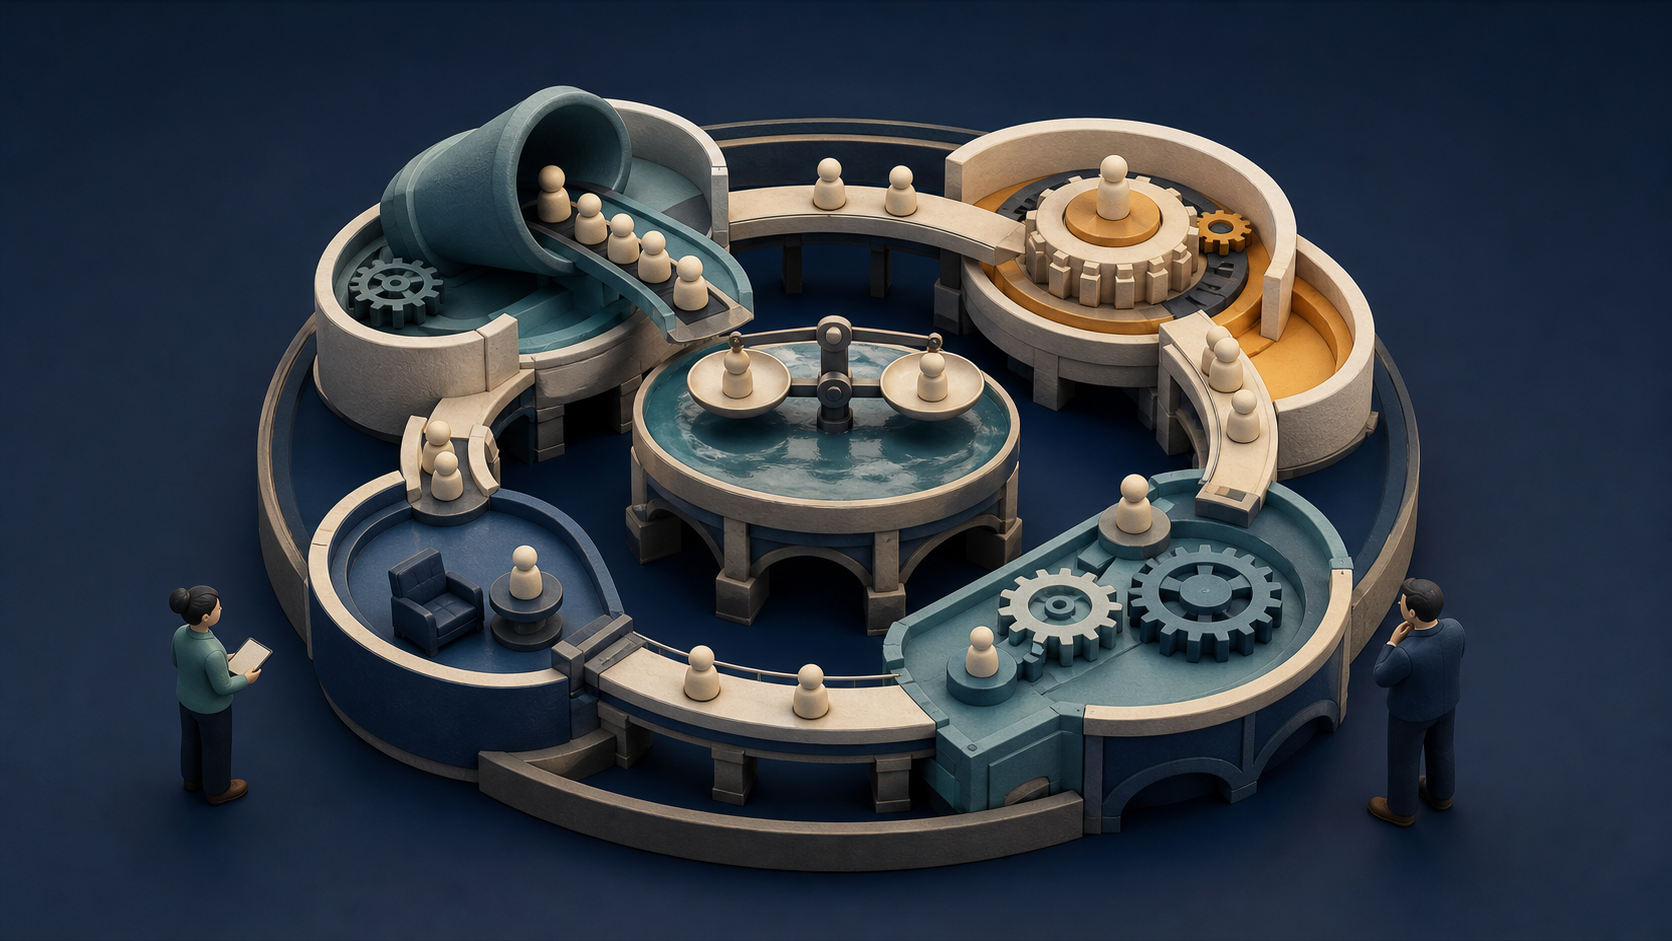
    A glowing query token passes through four independent routing chambers for keyword selection, campaign structure, message choice, and landing-page destination.

    Match precision used to be discussed mainly as the relationship between a search term and an exact, phrase, or broad keyword. That view is too narrow for AI Max. Even when you have not added a broad-match version of a keyword, AI Max can behave as if broad coverage is present and distribute traffic across existing keywords.

    A query shown under AI Max is therefore not automatically a query that AI Max discovered. It may be a search your exact or phrase keywords already captured. Evaluate precision across four separate dimensions:

    • Query precision: Does the search term express an intent you want to buy?
    • Ownership precision: Did the intended keyword, ad group, and campaign receive the query?
    • Message precision: Did the user see suitable text and reach the right final URL?
    • Attribution precision: Is AI Max receiving credit for genuinely incremental demand, or for traffic that existed before activation?

    Google’s stated matching priority gives an identical exact match precedence. In practice, AI Max has sometimes taken traffic even when a corresponding exact keyword was available. That observation does not prove every account will behave the same way, but it does mean you should treat exact priority as an expected rule rather than a substitute for auditing.

    Keep commercially important searches as explicit exact-match keywords. Add valuable misspellings and minor variants when ownership matters. This does not guarantee that every impression will follow your preferred path, but it gives you a clear control point for noticing when the path changes.

    Decide whether your account is ready for the trade-off

    AI Max is a poor candidate for automatic, account-wide adoption. Start with the conditions already visible in your account, because the feature does not erase weak economics or limited budget.

    What you see in the accountWhy it mattersPractical decision
    Broad match has repeatedly underperformedAI Max introduces broad-like expansion even without broad versions of your keywordsUse a limited, guarded test instead of assuming a different label will fix the underlying problem
    Budget already restricts strong exact or phrase keywordsExpanded traffic can compete with proven demand for the same constrained budgetFund the searches you already know are valuable before paying for wider exploration
    Brand and non-brand traffic must remain separateBrand queries can appear in non-brand areas and non-brand queries can cross into brand trafficBuild explicit negative boundaries and audit actual search terms, including variants and misspellings
    Text customization or Final URL expansion is unacceptableMatch expansion is not the only behavior involved in AI MaxDo not activate the setting solely for query expansion if you cannot tolerate its message or destination changes
    Match-type reporting must remain directly comparableReassigned impressions and clicks can make the AI Max contribution look more incremental than it isCreate a query-level baseline before activation and judge the test outside the headline attribution

    Because this is paid traffic, an overly broad launch can consume budget before the reporting explains where it went. A safer test uses a campaign where exploration is affordable, conversion measurement is dependable, and brand leakage or an incorrect destination will not create an unacceptable business risk.

    Build a precision test that can survive muddy attribution
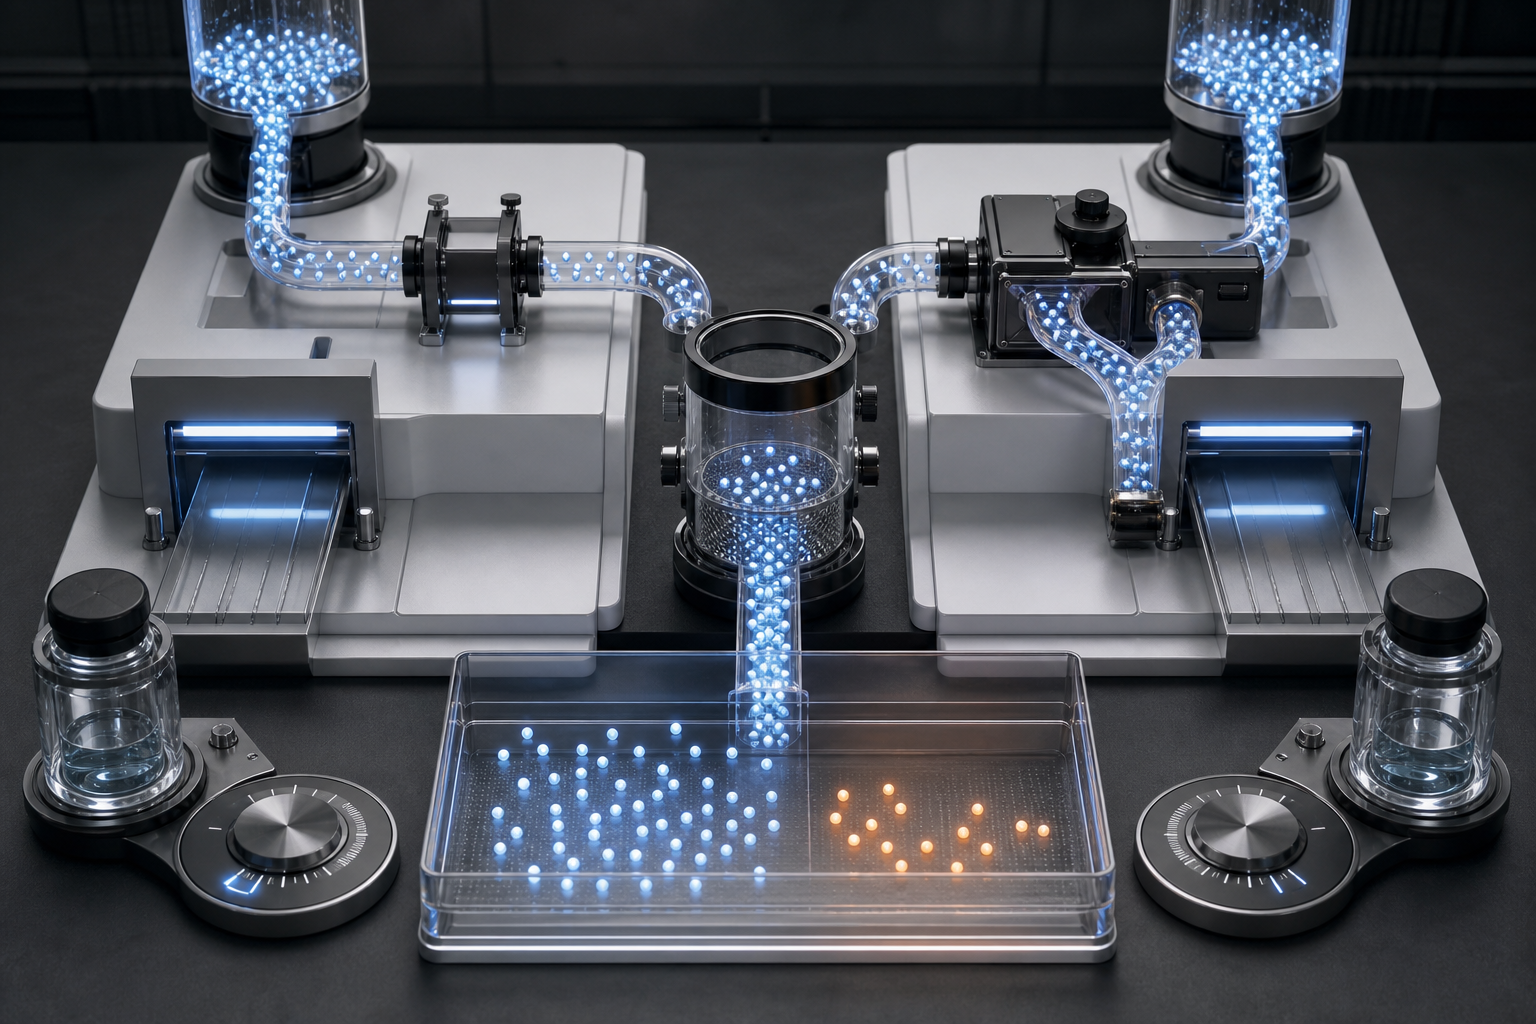
    Two parallel query-testing channels feed an overlap filter that separates shared traffic from a small set of unique results.

    The test needs to answer a narrow question: did AI Max create useful incremental reach, or did it relabel and reroute reach you already had? Set up the evidence before activation.

    1. Capture the pre-test query map. Export search terms from a period representative of the current offer, geography, and campaign structure. For each term, record its keyword, match type, campaign, ad group, cost, conversion outcome, and intended landing page. This becomes the baseline against which apparent discovery is checked.
    2. Protect high-value searches explicitly. Keep your core queries as exact keywords and add commercially important spelling variations. Record the ad group and landing page that should own each one so a later routing change is visible.
    3. Add broad versions where they improve auditability. Adding broad keywords to a test of an expansion system sounds counterintuitive. In this case, explicit broad versions of core keywords can make expanded traffic easier to identify instead of allowing it to be distributed invisibly across exact and phrase coverage. This can clarify reporting, but it does not restore guaranteed matching priority.
    4. Design brand and non-brand negatives together. Do not rely on brand filters alone. Include known misspellings and variants that could cross the boundary, then check each negative against legitimate traffic before applying it. An overly broad negative can block the very demand you meant to protect.
    5. Define acceptable messages and destinations. Record the URL family, offer, and claims appropriate for the test traffic. If text customization or Final URL expansion produces a route you cannot approve, pause the AI Max test; a keyword change alone will not solve a message or destination problem.
    6. Write the success rule before reading the results. Count a query as incremental only when it is absent from the available pre-test history, relevant to the intended offer, routed appropriately, and economically acceptable under the same business KPI used for the rest of the campaign. An AI Max label is not evidence of incrementality by itself.

    This setup will not produce a perfectly isolated experiment. It will, however, prevent the most common analytical mistake: comparing an AI Max total with zero instead of comparing each underlying query with the account’s existing coverage.

    Audit search terms by identity, not by Google’s label

    Deduplicate search terms across match types before you total their contribution. Normalize obvious differences in capitalization and spacing, but keep misspellings visible because they can receive different ownership. Then place each query into a decision bucket.

    Query bucketWhat it tells youWhat to do next
    Existing and correctly ownedThe term appeared before AI Max and still reaches the intended keyword, ad group, and destinationKeep it in campaign performance, but do not count it as AI Max discovery
    Existing but reassignedThe term existed before activation but is now credited or routed differentlyCheck whether the new route changes bids, budget, messaging, landing pages, or brand classification; reinforce exact ownership and negative boundaries where needed
    New to the available history and relevantThe term is a credible candidate for incremental reachEvaluate its economics and routing; promote it to exact or phrase coverage when it deserves deliberate control
    New to the available history but irrelevantExpansion found traffic that does not match the offer or intended buying intentAdd a precise negative and inspect nearby variants rather than blocking a broad concept reflexively
    Brand or non-brand crossoverThe term is being measured in the wrong economic or strategic segmentCorrect the negative architecture and re-evaluate the affected campaign results before scaling
    Unmapped or unexplainedThe term does not align clearly with a current keyword or known past queryInspect it manually and keep it separate from proven discovery; keywordless matching is a possible explanation, but the mechanism has not been confirmed

    How to interpret the final mix

    If most AI Max-labelled traffic falls into the existing or reassigned buckets, the result does not demonstrate meaningful query expansion. It is more consistent with reattribution, even if the AI Max line in the interface looks strong. The setting may still affect performance through routing, text, or URLs, but you should not call that new demand.

    If the new and relevant bucket produces acceptable results without displacing protected queries, the case for incremental value is stronger. Promote recurring high-value terms into controlled keyword coverage, keep the negative map current, and continue checking which ad group and destination receive them.

    A rise in conversions does not excuse a broken brand split. When branded searches move into a non-brand campaign, the non-brand line can appear more efficient while the brand line loses credit. Fix the classification first; otherwise, the next budget decision will be based on distorted campaign economics.

    Key takeaways

    • AI Max can introduce broad-like matching even when a broad version of the keyword is absent.
    • An AI Max-labelled search term is not necessarily a new search; it may be existing exact or phrase traffic that was reassigned.
    • A pre-test query map and explicit broad versions of core keywords can make the expansion easier to audit.
    • Exact keywords, valuable spelling variants, and carefully checked negatives remain essential for protecting query ownership and brand separation.
    • Scale only when deduplicated search terms show relevant, economically acceptable reach that was not already present in the available history.

    Before your next budget change, classify the highest-spend AI Max search terms into these buckets and correct brand leakage or wrong ownership first. Then let the new and relevant bucket decide whether AI Max has earned more budget. If you cannot isolate that bucket, you do not yet have evidence to scale.
    References

  • AI-Driven Paid Media Strategy: Budgets, Bids and Visibility

    AI-Driven Paid Media Strategy: Budgets, Bids and Visibility

    You’ve probably been handed a familiar contradiction: let the ad platforms automate more decisions, but remain accountable for every dollar they spend. The answer isn’t to micromanage every bid, and it isn’t to treat an automated campaign as self-driving.

    Your job is to design the system around the automation. That means concentrating the budget, assigning each campaign a clear role, measuring channels as a portfolio and checking whether AI-generated search results are changing the visibility you thought you had.

    Allocate the budget before you configure the campaigns

    Metallic budget tokens are divided among three transparent channels before reaching smaller campaign controls.

    AI can optimize toward a target, but it can’t decide which business constraint matters most. Before opening a platform, write a one-page constraint sheet that answers five questions:

    • What business outcome are you buying? Name the sale, qualified lead, subscription, store visit or other outcome that ultimately matters.
    • What economics must the outcome meet? Use the maximum acceptable acquisition cost, minimum return or other threshold your business has approved. Don’t substitute a platform metric merely because it is available.
    • How much spending is committed? Separate the budget you expect to deploy from money that is optional, experimental or contingent on performance.
    • When is demand likely to change? Mark peak buying periods, expected slumps, launches and deadlines. Historical performance and Google Trends can help shape the monthly curve because an annual budget rarely deserves twelve equal allocations.
    • Which campaigns can you actually support? A channel that needs a steady supply of approved video or social creative is not a realistic allocation if that production process is blocked.

    Then divide the available money by purpose, not by platform. A useful portfolio has three conceptual pools:

    • Core delivery funds campaigns with an established job and credible performance evidence.
    • Growth funds additional reach, audience building or expansion beyond the demand you already capture.
    • Exploration funds a specific, bounded test of a channel, format, audience or message.

    There is no defensible universal percentage for these pools. The correct split depends on budget size, demand, business maturity, creative capacity and confidence in your measurement. What does generalize is the need for concentration. Spreading a modest budget across too many campaigns limits the data each campaign can collect, leaving the platform with too little signal and you with too many inconclusive results.

    Fund the smallest coherent campaign structure first. Add another campaign only when you can state its distinct job, give it enough budget to perform that job and explain how you will judge it. A new campaign created merely to use an available targeting option is fragmentation, not strategy.

    When more money becomes available, look first for campaigns that are both efficient and budget-constrained. That is a better starting point than dividing the increase evenly. Still, don’t assume that historical efficiency will survive unlimited scale. Increase spending in stages and inspect the economics of the additional volume. A higher budget creates financial exposure; if you don’t know the acceptable marginal acquisition cost, don’t scale solely because the platform forecasts more conversions.

    Give every channel a job in the portfolio

    Four color-coded media modules perform different functions while connecting to a shared central objective.

    A channel-by-channel return table often rewards the campaign that collects the conversion and punishes the campaign that created the demand. That can produce a tidy report and a weaker media plan.

    Portfolio roleTypical campaign useReason to fund itEvidence to inspect
    Demand capturePaid search against relevant queriesReach people already expressing intentQuery quality, conversion economics, impression availability and budget constraints
    Demand creationYouTube or social prospectingBuild awareness and qualified audiences before the final searchReach, audience growth, later search behavior and change in portfolio-level efficiency
    Re-engagementViewer or visitor remarketingContinue the journey with people who have already encountered the brandIncremental outcomes, frequency and overlap with other campaigns
    ExplorationDemand Gen, a new social channel or an unproven formatTest a defined path to additional demandThe stated hypothesis, spend boundary, delivery quality and downstream business outcome

    These roles prevent two common mistakes. The first is expecting every campaign to close the sale directly. The second is excusing weak performance with a vague claim that a campaign is building awareness. A demand-creation campaign still needs a measurable theory of change.

    For example, a YouTube campaign may produce few attributed conversions while search conversion rates improve and video-viewer remarketing audiences perform well. That pattern can justify continued investigation because campaigns can affect the efficiency of other channels. It does not, by itself, prove that video caused the improvement. Seasonality, promotions, competitive changes or measurement differences may also be involved.

    Use three levels of evidence so you don’t confuse a plausible contribution with a demonstrated one:

    <!– wp:list {
  • Black Friday Ads Cost More. Fix What Happens After the Click

    Black Friday Ads Cost More. Fix What Happens After the Click

    You can run a busy Black Friday ad account and still lose money after the click. When media costs rise, every unclear offer, unnecessary form field, checkout surprise, and unworked lead consumes traffic you already paid to acquire.

    The practical response is to manage the ad, landing page, checkout or form, and follow-up process as one conversion system. That gives you more useful decisions than simply chasing cheaper clicks or celebrating a higher click-through rate.

    Higher ad costs change the acceptable post-click error rate

    Across more than 5,000 ecommerce advertisers and 16,000 lead-generation advertisers active during Black Friday 2025 and the previous year, spend increased by about 17% for both groups while impressions declined. Attention did not disappear: clicks and click-through rates improved across multiple sectors, while lead-generation advertisers recorded lower CPCs and more clicks.

    That combination matters because engagement and profitability can move in different directions. A campaign can attract more clicks while producing worse economics if its landing page converts poorly, its orders carry weak margins, its returns increase, or its leads fail to become customers. The early Black Friday figures could not settle that question because final conversion value and return on ad spend were still pending.

    Do not respond by rejecting every expensive click. A higher CPC can work when the visitor converts at a strong enough rate and produces sufficient margin. A lower CPC can fail when cheap traffic generates low-quality leads, abandoned carts, cancelled orders, or purchases that are later returned.

    Set your bidding and budget limits from unit economics before the promotion begins. For ecommerce, a useful starting relationship is:

    Maximum sustainable CPC = post-click conversion rate x contribution margin per retained order.

    Use retained orders rather than initial orders when returns and cancellations materially affect the business. Define contribution margin with the costs your finance team actually uses, rather than treating revenue as profit. If margins vary significantly by product, calculate the limit by product group or offer instead of applying one account-wide figure.

    For lead generation, work backward from acquired customers:

    Maximum sustainable cost per lead = lead-to-customer rate x acceptable cost per acquired customer.

    Base the lead-to-customer rate on qualified, followed-up leads from a comparable campaign. A form submission is not equivalent to a sale. If your sales team rejects many submissions or cannot contact them, the headline cost per lead is hiding the real acquisition cost.

    Build the destination from the ad promise backward

    Interlocking landing page and checkout modules connect a generic ad to a shopper receiving a product.

    Post-click optimization starts before anybody reaches the page. Every ad makes a promise about a product, price, discount mechanism, eligibility condition, deadline, benefit, or next step. The destination must let the visitor verify and act on that promise without reconstructing it from banners, menus, and fine print.

    1. List every decision-relevant claim in the ad. Include what is offered, who or what qualifies, how the saving is applied, and any material restriction.
    2. Send the click to the narrowest page that can fulfil that promise. A product ad should reach the relevant product or variant. A category offer should reach a filtered collection. A lead-generation ad naming a specific service or resource should reach a page dedicated to it.
    3. Repeat the decisive terms near the first meaningful action. The visitor should not need to enter checkout or submit a form to discover that the advertised condition does not apply.
    4. Remove competing actions that do not help the visitor complete the promised journey. Navigation can remain useful, but unrelated promotions should not overpower the action the ad introduced.
    5. Test the complete path with the campaign parameters attached. Confirm that the destination loads, the offer persists, the intended variant appears, the form or checkout works, and the conversion is recorded once.

    Message match does not mean copying the ad word for word. It means preserving meaning. If the ad promotes a particular item, the page should not make the visitor search for it. If a code is required, show the code and its instructions where the visitor can use them. If eligibility or availability varies, disclose that before the visitor commits time or payment details.

    For ecommerce traffic

    The first useful view of the destination should establish the product, the applicable offer, the effective price when it can be calculated accurately, availability, fulfilment terms, return conditions, and the purchase action. Do not manufacture urgency with a countdown or stock claim your systems cannot support. That may produce clicks or carts, but it also creates avoidable cancellations, refunds, support work, and distrust.

    Then test the transaction, not just the page. Add the advertised item or qualifying combination, apply the promotion as a customer would, select fulfilment, and reach the payment stage. Use an approved test environment, test payment method, or safely reversible transaction. An unreviewed live checkout change can break payments, tax handling, shipping rules, discount logic, or measurement at the most expensive point in the funnel, so keep a rollback path.

    For lead-generation traffic

    Ask for fields that support qualification, routing, compliance, or the next conversation. Every additional question should have an owner and a use. If nobody acts on the answer, remove it from the first interaction or collect it later.

    The confirmation experience should explain what happens next without promising a response time the team cannot meet. Route the submission to a named queue or owner, retain the ad and offer context, and give the follow-up team the same promise the prospect saw. A lower CPC does not help if qualified prospects wait unassigned or receive a generic response unrelated to the ad.

    Find the first expensive leak before changing the whole funnel

    An analyst inspects and repairs the first major leak in a transparent conversion channel carrying glowing tokens.

    A conversion rate tells you that a problem exists, but not where it lives. Break the journey into transitions and inspect the first meaningful loss. Use your own comparable baseline rather than a universal benchmark: product prices, offer strength, traffic intent, checkout design, sales process, and measurement rules make account-to-account comparisons unreliable.

    TransitionWhat a weak transition may indicateFirst checks
    Ad click to recorded landing sessionA destination, page-load, consent, or tracking problemFinal URL, campaign parameters, redirects, page availability, and session recording
    Landing session to product, cart, or form actionWeak message match, unclear value, poor hierarchy, or an unusable primary actionHeadline, offer terms, selected product or variant, call to action, and device behaviour
    Cart or form start to completionUnexpected cost, excessive input, validation failure, missing payment option, or confusing requirementsTotal price, fulfilment choices, required fields, error handling, promotion logic, and payment flow
    Purchase to retained orderExpectation mismatch, fulfilment issue, cancellation, or return pressureProduct and offer accuracy, availability, delivery communication, cancellations, refunds, and margin
    Submitted lead to qualified opportunity or salePoor traffic fit, weak qualification, routing delay, or ineffective follow-upLead validity, qualification outcome, owner assignment, contact attempts, opportunity creation, and closed customers

    Use a disciplined triage sequence while the promotion is live:

    1. Validate the offer and measurement first. A broken discount or duplicated conversion event can make every later decision wrong.
    2. Segment the journey by ad, offer, destination, device class, audience, and new versus returning visitor where those distinctions are available and appropriate.
    3. Locate the earliest transition that deteriorated against a comparable baseline. Downstream symptoms often begin upstream.
    4. Weight the problem by spend and business value. A severe issue on a low-spend path may matter less than a moderate leak consuming most of the budget.
    5. Change the smallest element capable of testing the diagnosis. Preserve a control where traffic supports a proper experiment, and record when each change went live.
    6. Verify both the user experience and the analytics after deployment. A visual improvement is not complete if the offer, transaction, or measurement has broken.

    Do not declare a winner from a short burst of promotional traffic simply because the percentage moved. Offer periods can change traffic mix rapidly, and returns or lead outcomes may not be visible immediately. If the campaign cannot produce enough observations for a reliable controlled test, use a careful change log, compare like-for-like segments, and label the result as directional rather than certain.

    Prioritize high-confidence friction before cosmetic experimentation. An offer that fails to apply, a dead button, an invalid form rule, or an unassigned lead has a clear mechanism and consequence. Small wording and design preferences come later unless your funnel evidence points directly to them.

    Measure the outcome that can afford the next click

    Maintain an operational view for managing the live campaign and an economic view for deciding whether it worked. Mixing them into a single dashboard encourages premature conclusions.

    The operational view

    • Spend, impressions, clicks, CTR, and CPC show how the market and ads are behaving.
    • Recorded landing sessions reveal whether paid clicks are reaching a measurable destination.
    • Product views, cart starts, form starts, and checkout starts expose intermediate movement.
    • Promotion failures, payment errors, form errors, and lead-routing failures identify problems that need immediate intervention.

    These indicators are useful for control, but they are not the final business result. A campaign should not receive more budget merely because it produces an attractive CTR or a lower CPC.

    The economic view

    For ecommerce, connect each conversion to collected revenue, discount cost, product and fulfilment economics, advertising cost, cancellations, refunds, and returns using the definitions approved by your business. Review conversion rate, cost per acquired customer, revenue per click, contribution per retained order, and campaign contribution together. A blended ROAS can conceal a shift toward low-margin products or orders that do not remain completed.

    For lead generation, retain the campaign, creative, offer, and destination identifiers through the customer system. Report submitted leads, valid leads, qualified leads, opportunities, customers, lead-to-customer rate, cost per acquired customer, and contribution from acquired customers. This prevents a cheap but unqualified lead source from taking budget away from a more expensive source that closes.

    Choose your conversion rules and reporting window before reading the result. Then maintain provisional and reconciled reporting. The initial Black Friday 2025 figures were necessarily incomplete while conversion value and ROAS were pending; your live reporting faces the same general problem whenever returns, cancellations, qualification, or sales happen after the click.

    A provisional view helps you manage active spend. A reconciled view tells you whether the campaign created durable value. Keep both, label them clearly, and use the reconciled economics when setting the next campaign’s limits.

    Key takeaways for your Black Friday operating plan

    • Set CPC, cost-per-lead, and budget guardrails from conversion rates and contribution economics, not from last year’s media price alone.
    • Treat every advertisement as a promise that the destination, form or checkout, confirmation, and follow-up process must preserve.
    • Diagnose the funnel by transition. Fix the first meaningful, spend-weighted leak before redesigning everything downstream.
    • For ecommerce, optimize toward retained orders and contribution, not initial revenue alone.
    • For lead generation, connect clicks to qualification and acquired customers, not just submitted forms.
    • Use live engagement data for operational decisions, but label profitability as provisional until delayed outcomes have been reconciled.

    Before you raise your next Black Friday budget, open the highest-spend ad and follow its actual path through the landing page, offer, checkout or form, confirmation, and order or lead handoff. Write down the first place where the promise becomes unclear or the action becomes harder. Fix that point, verify the measurement, and then decide whether the next click deserves more budget.

    References

  • A Sustainable Growth System for SaaS and Small Businesses

    A Sustainable Growth System for SaaS and Small Businesses

    Your revenue can rise while the business underneath it gets weaker. If each new customer adds more support work than margin, campaigns create leads your team cannot convert, or the founder has to rescue every handoff, more demand will amplify the problem.

    You need a growth system that shows where revenue is getting stuck, what to improve next, and whether the business can carry more volume. The same basic logic applies to a SaaS company, a professional service firm, and a small transactional business: attract the right customer, convert that customer, deliver value, retain or replace the revenue economically, and preserve enough capacity to repeat the process.

    Decide what sustainable growth means before spending more

    Sustainable growth is not simply a rising top line. It is growth the business can finance, fulfill, and repeat without progressively damaging margin, service quality, retention, or the team’s operating capacity. The practical target is predictable, profitable growth, not the largest possible number of leads.

    That distinction matters because different models carry different risks. A SaaS business may tolerate an upfront acquisition cost when retained subscription gross profit can recover it. A project-based business may need to recover most of its acquisition and delivery costs from the initial job. A capacity-constrained firm may be better served by fewer, better-fit customers than by a larger volume of low-margin work.

    Before selecting another channel, write a one-page growth model with these fields:

    • Customer segment: name the buyer, business situation, and problem. “Small businesses” or “marketing teams” is too broad to guide an offer or campaign.
    • Offer and promise: state what the customer buys, what outcome it is meant to produce, and what is explicitly outside the scope.
    • Gross profit per sale or account: start with revenue and subtract the direct costs required to deliver that revenue. For SaaS, those costs may include infrastructure, payment processing, and account-specific support. For a service business, they may include labor, contractors, materials, and fulfillment.
    • Cash-recovery path: identify how the acquisition and initial delivery outlay is recovered through gross profit. If the answer depends on renewals or repeat purchases, separate observed retention from hoped-for future behavior.
    • Capacity unit: choose the resource that actually limits delivery, such as implementation slots, billable hours, production capacity, support workload, or founder attention.
    • Failure conditions: decide which outcomes make growth unacceptable, such as declining job margin, slower onboarding, rising refunds, excessive support demand, or an inability to serve existing customers reliably.

    Use historical figures for the relevant customer segment whenever they exist. When a figure is uncertain, label it as an assumption and test it. Do not quietly treat projected lifetime value as cash already earned, and do not average strong and weak customer groups together just to make acquisition look affordable.

    These guardrails change how you judge a campaign. Cheap leads are not a win when they rarely become customers. More customers are not a win when the resulting support load destroys margin. A higher conversion rate is not a win when it is purchased through discounts that make the work uneconomic.

    Find the binding constraint in the revenue journey

    Customer tokens queue at one narrow gate along an otherwise open business pathway while an operator inspects the bottleneck.

    A growth problem is usually a stage problem. The business lacks enough qualified demand, loses prospects during conversion, fails to deliver value quickly enough, cannot retain the right customers, or cannot fulfill the work economically. Treating all five as “a marketing problem” leads to scattered activity and ambiguous results.

    Map the customer journey from first relevant contact to retained revenue. Then use observed behavior to locate the first clear break:

    Observed signalLikely constraintWhat to inspect first
    Too few right-fit inquiries or signupsQualified demandSegment definition, problem-message fit, channel targeting, and whether the offer gives the intended buyer a credible reason to act
    Relevant prospects engage but rarely buyConversionOffer clarity, proof, pricing presentation, decision friction, qualification, and the sales or checkout process
    Customers buy but stall before receiving valueActivation or deliveryOnboarding steps, handoffs, setup requirements, customer responsibilities, and the definition of the first useful outcome
    Customers reach an initial outcome but do not renew, return, expand, or referRetentionCustomer fit, reliability, continuing value, expectation gaps, and whether progress remains visible after the initial delivery
    Sales increase while cash, margin, or service quality deterioratesEconomics or capacityDiscounting, direct delivery costs, account workload, staffing assumptions, rework, and the actual cash-recovery path

    Visibility cannot substitute for revenue. Seed-stage teams are especially vulnerable to confusing attention with growth, even though the useful outcome is the right audience converting into sustainable revenue. The same mistake appears in small businesses when reach, clicks, or inquiry volume rise but paid jobs, margin, or repeat business do not.

    Read the journey by cohort or customer type, not only as one company-wide average. A SaaS team might separate customers by plan, use case, or acquisition route. A small business might separate jobs by service line, location, customer type, or lead source. The useful grouping is the one that exposes a meaningful difference in conversion, delivery effort, margin, or retention.

    Quantitative data tells you where the break occurs. Customer language often explains why. Tag sales objections, onboarding questions, support requests, cancellations, failed proposals, repeat purchases, and referrals against the corresponding stage. If prospects repeatedly misunderstand the promise, changing channels will not repair the offer. If customers buy but cannot reach the first outcome, adding more demand will feed a delivery problem.

    Start with the earliest stage where the evidence shows a material break. Keep watching downstream guardrails, but resist launching an unrelated tactic for every weak metric. One identified constraint gives your team a reason to say no to work that will not improve the current system.

    Build one customer path that another person can repeat

    A growth engine is not a collection of channels. It is a connected operating path in which each stage has an owner, a trigger, a deliverable, and a measure. Moving from an early product or service to a systematic and scalable growth engine requires this infrastructure; product quality alone does not define how customers discover, buy, adopt, and continue using what you sell.

    Define the path in operational terms:

    • Entry: specify the primary way the intended customer enters the journey. Name the channel and the action, not a broad label such as “content” or “outbound.”
    • Qualification: write the conditions that separate a plausible customer from general interest. Include the problem, fit, authority, timing, or operational requirements that matter to your offer.
    • Commitment: name the observable conversion event: a paid order, signed agreement, activated trial with a defined intent signal, booked assessment, or another commitment tied to revenue.
    • First value: define the earliest observable event showing that the customer received a useful outcome. A login is not automatically value for SaaS, and project kickoff is not automatically value for a service buyer.
    • Retention or replacement: state how revenue continues. That may be renewal, expansion, repeat purchase, rebooking, referral, or a reliably economical flow of new one-time customers.

    For each stage, assign one owner and record what the next owner needs. Marketing should know what qualifies as a useful opportunity. Sales should preserve the expectations created before purchase. Delivery or customer success should know the promised outcome and constraints. Retention feedback should return to targeting and qualification. Without that loop, every team can appear busy while the customer experiences one disconnected process.

    Prove the path in this order:

    1. Run the important steps manually so you can see where customers hesitate, misunderstand, or require help.
    2. Document the language, decisions, inputs, handoffs, and outputs that repeatedly produce a good result.
    3. Remove unnecessary steps and clarify the points that create avoidable delay or rework.
    4. Automate only the stable, understood parts of the process.
    5. Add demand after the conversion, delivery, and economic guardrails remain sound.

    Automation applied too early hides uncertainty inside a faster process. A polished sequence will not repair an unclear offer, weak qualification, or an onboarding path that does not lead to value. Manual work is acceptable while you are learning; undocumented founder heroics are not a scalable operating model.

    Repeatable does not mean identical. It means the team can explain why the path works, identify the legitimate variations, execute it without improvising every decision, and observe whether the economics remain inside the guardrails. For a capacity-constrained small business, successful scale may mean improving revenue quality and throughput with the same team rather than maximizing transaction count.

    Run experiments without creating a pile of disconnected tactics

    Two team members examine three organized test modules beside an intact central customer pathway.

    The attraction of a new channel is that it feels like forward motion. The problem is that trying every new tactic makes it difficult to learn what caused an outcome. Sustainable marketing starts with work that matches the business goal and the target audience, then tests the weakest part of that path deliberately.

    Keep one experiment backlog organized by constraint. Every proposed test should answer these questions before it receives time or budget:

    • Which customer segment does this test affect?
    • Which stage of the journey is currently constrained?
    • What single change are we making?
    • Why should that change affect customer behavior?
    • What is the primary outcome measure?
    • Which guardrail could reveal a harmful tradeoff?
    • What result would make us keep, reverse, or redesign the change?

    Write the hypothesis in one sentence: “For this customer segment at this decision point, changing this element should improve this behavior because this specific friction will be reduced.” If you cannot complete that sentence clearly, the idea is not ready to become an experiment.

    Match the test to the diagnosed constraint. If SaaS customers purchase but fail to reach first value, remove or clarify one onboarding decision and measure completion of the first-value event; use support demand or later retention as a guardrail. If a service business receives qualified inquiries but too few paid bookings, test a more specific scope, outcome, or next step; protect job margin and delivery capacity as guardrails. Neither business needs a larger audience until the evidence points back to demand.

    Choose a primary metric that sits at the constrained stage. Impressions and clicks can help diagnose an acquisition path, but they should not decide a conversion experiment whose purpose is paid customers. Leads should not decide a retention experiment. Gross revenue should not decide a pricing experiment without margin and workload beside it.

    Set the review cadence according to the buying cycle and the event being measured. A test has not produced a business answer merely because early engagement data is available. Wait until the relevant customer behavior can occur, then review the same definitions and segment used in the baseline. Where volume is limited, combine the directional numbers with documented objections, questions, and delivery friction rather than pretending the result is more certain than it is.

    Record the hypothesis, change, audience, start and stop conditions, result, guardrail effects, and decision. This log prevents the team from repeating failed ideas under new names. It also separates an unsuccessful test from a useless one: a well-designed test that disproves an assumption still improves the next decision.

    Scale only when the same customer segment follows an observable path, the economics stay within your guardrails, delivery quality holds, and another person can execute the documented process. If results depend on the founder rescuing deals, onboarding, or fulfillment, the system is not ready for more volume.

    Key takeaways

    • Define sustainable growth through gross profit, cash recovery, customer value, and delivery capacity before you optimize lead volume.
    • Diagnose whether the binding constraint is qualified demand, conversion, activation, retention, economics, or capacity.
    • Measure the journey by relevant customer segment or cohort so strong accounts do not hide weak ones.
    • Build one connected path with explicit qualification, commitment, first-value, and retention events.
    • Prioritize experiments against the current constraint, with one primary metric and at least one guardrail.
    • Add volume only after the path can be explained, executed, measured, and fulfilled without routine founder intervention.

    Your next move is small and concrete. Map one recent, complete customer journey from first contact to delivered value and retained or completed revenue. Mark the stage where progress most often breaks, confirm it with the numbers and customer language you already have, and run one controlled change there. That is how growth stops being a sequence of campaigns and becomes an operating system your business can carry.

    References

  • How to Diagnose and Improve CTV Advertising Performance

    How to Diagnose and Improve CTV Advertising Performance

    Your CTV dashboard is full of reassuring signals. Impressions are delivering, people appear to be completing the video, and the platform may even be reporting conversions. Yet sales, qualified leads, site activity, or brand demand have barely moved.

    Changing the audience, creative, bids, and budget at the same time will spend more money without explaining the gap. CTV’s upside can be undercut by avoidable campaign mistakes that weaken performance and ROI. To find them, separate delivery from response and attributed response from incremental business impact.

    Define performance before choosing a metric

    CTV can support broad awareness, demand creation, customer acquisition, re-engagement, or a combination of those jobs. Those campaigns should not share an identical definition of success.

    An awareness campaign should not be judged solely by immediate clicks because television is not primarily a click-first environment. A direct-response campaign cannot declare victory based on completed views when the intended business event is a qualified lead or purchase. Start with the decision the campaign is supposed to influence, then choose the metric that represents that decision.

    Write a short measurement contract before launch. It should answer:

    • What business question are you asking? For example, whether CTV can generate new-customer demand, extend reach beyond another channel, or improve response in selected markets.
    • What is the primary outcome? Choose the event closest to business value that can be measured credibly, such as a qualified lead, first purchase, booked appointment, or validated brand-lift measure.
    • What evidence will support the outcome? Name the delivery, exposure, response, and business metrics you will use. Do not elevate every available dashboard metric to KPI status.
    • How will credit be assigned? Document the attribution window, click-through and view-through treatment, identity method, deduplication rules, and treatment of existing customers.
    • What is the comparison? Decide whether you will use a holdout, geographic comparison, matched audience, established baseline, or another defensible counterfactual.
    • What would cause you to change course? State which finding would justify a creative change, targeting adjustment, budget move, or pause.

    This prevents a common reporting failure: choosing the most flattering metric after the campaign has run. It also keeps efficiency measures in their proper role. CPM, pacing, and completion rate can help you manage delivery, but none of them independently proves that the campaign created business value.

    Key takeaways

    • Define the campaign’s business job before selecting its primary KPI.
    • Read CTV performance as a chain: delivery, exposure, response, business outcome, and incrementality.
    • Treat completion rate as evidence that the video played through, not proof that the message persuaded anyone.
    • Reconcile platform reporting with analytics and business systems before optimizing media.
    • Change the earliest broken link in the chain and preserve a clean record of what changed.

    Read CTV performance as a chain, not a score

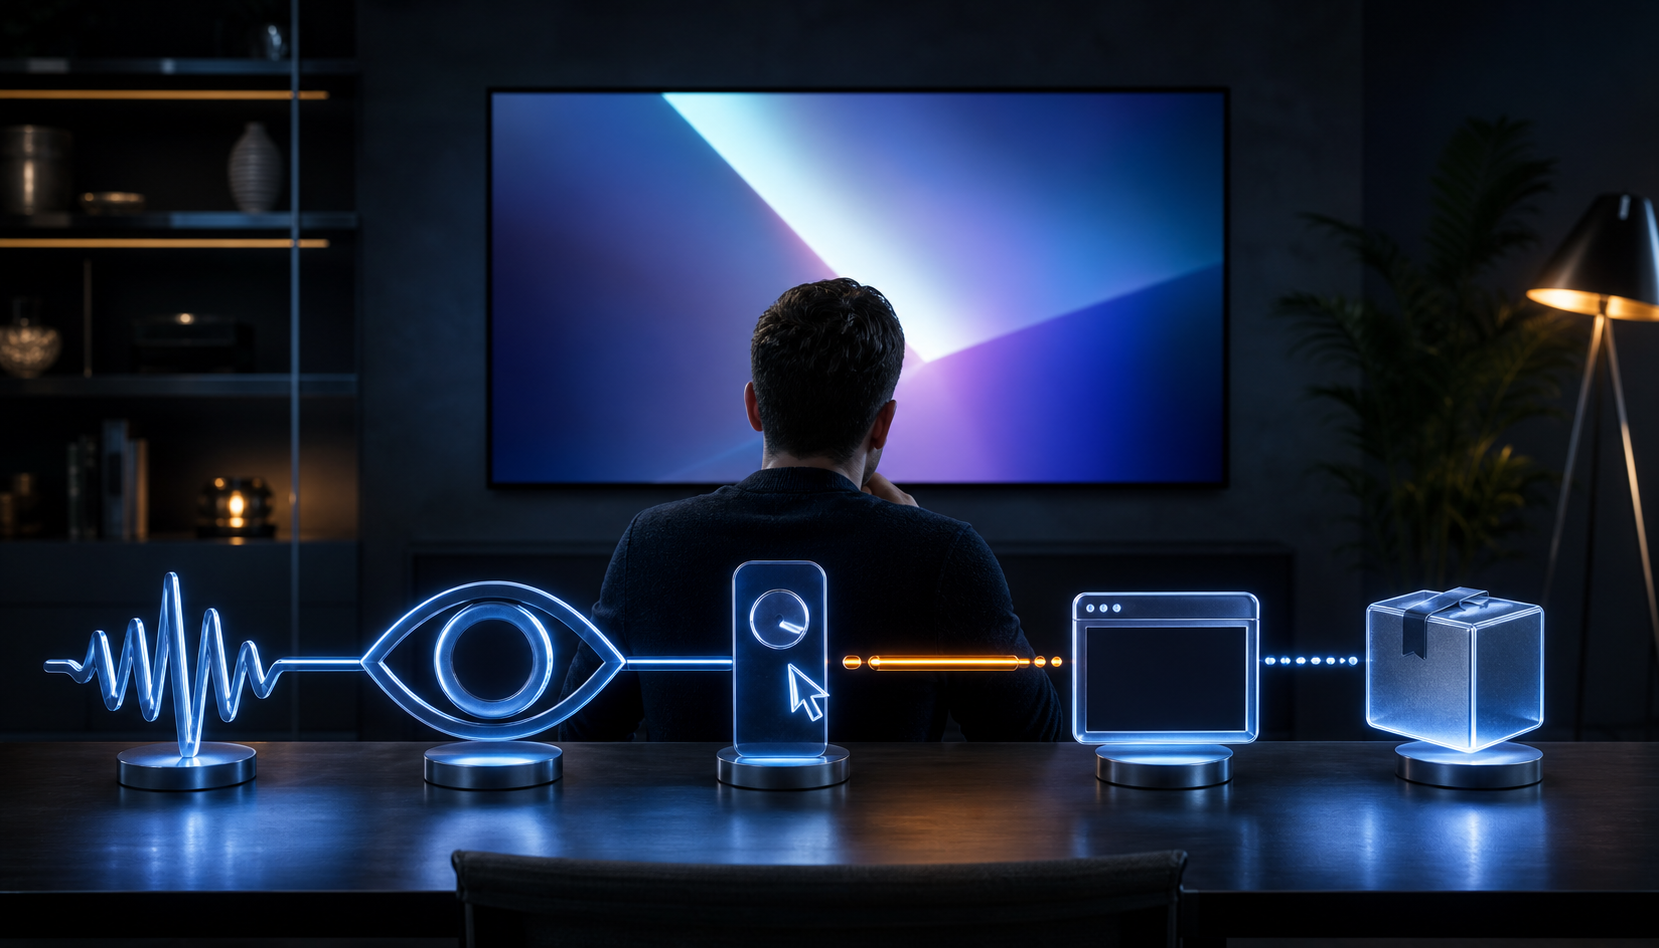
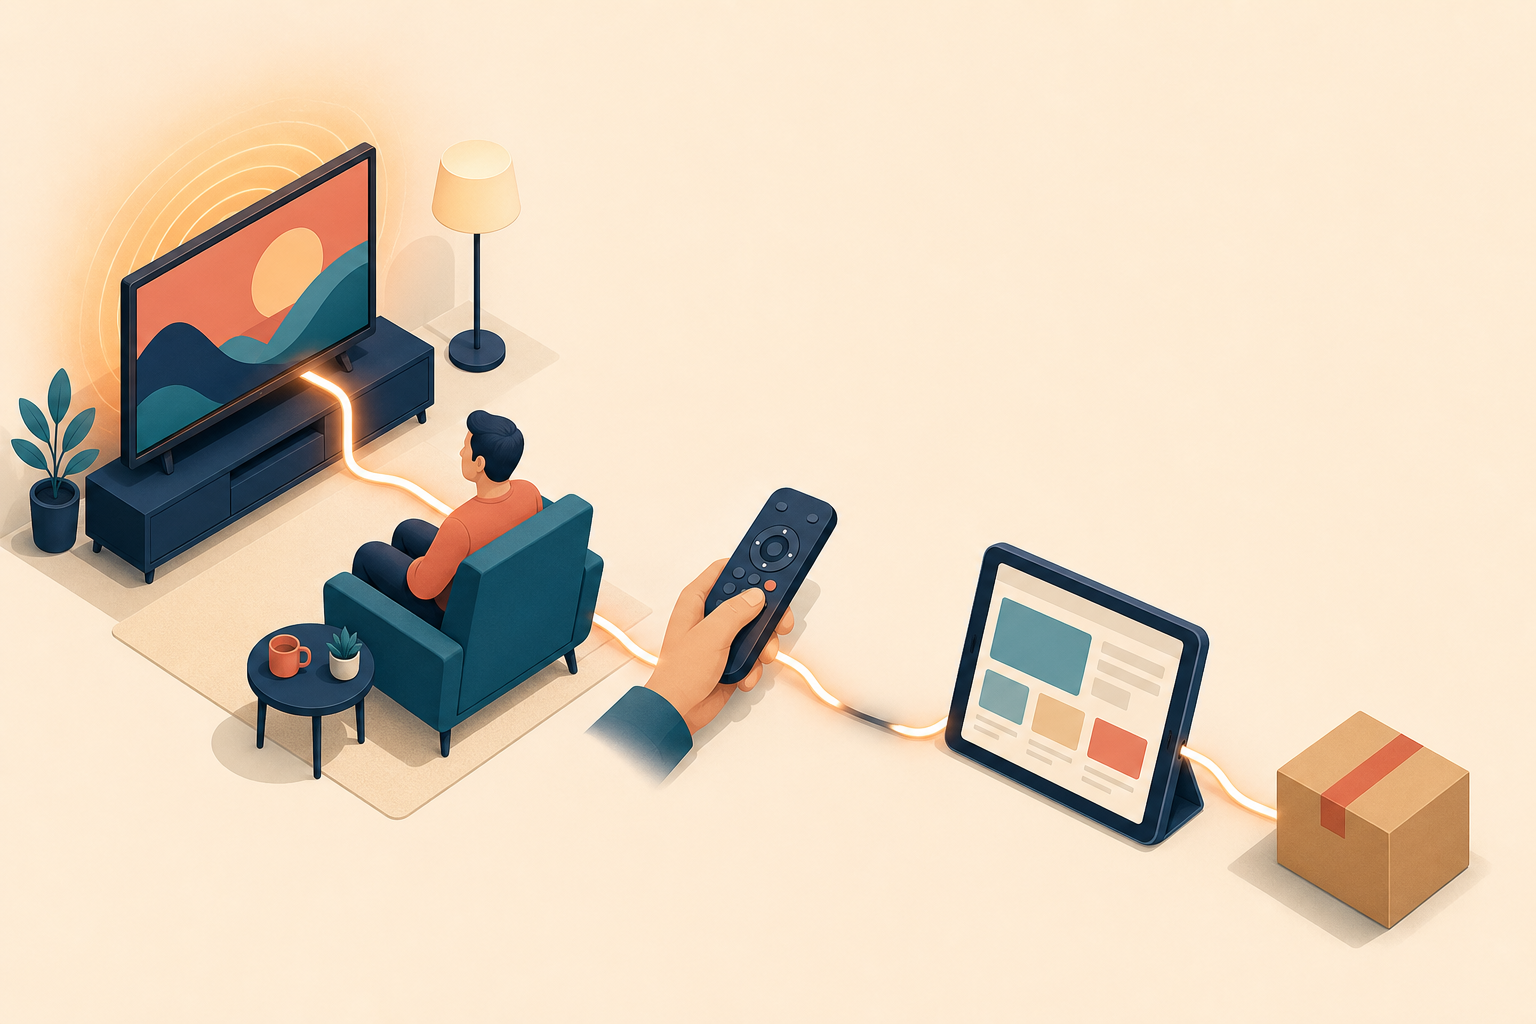
    An isometric sequence connects a television, viewer, remote, tablet, and shopping parcel with a glowing cable that weakens at one junction.

    A single blended score hides the reason a campaign is succeeding or failing. Read the evidence in layers, beginning with delivery and ending with causality.

    Performance layerUseful evidenceQuestion it answersWhat it cannot prove alone
    DeliverySpend, impressions, pacing, CPM, geography, device and inventory reportingDid the campaign buy and deliver the intended media?Whether the intended audience noticed, responded, or converted
    Exposure distributionEstimated reach, frequency, completion rate and available quality signalsHow broadly and repeatedly was the advertising delivered?Whether a completed exposure changed perception or behavior
    ResponseLanding-page visits, engaged sessions, searches, direct visits, QR activity or other campaign-linked actionsDid observable behavior move alongside exposure?Whether the campaign caused that movement
    Business outcomeQualified leads, first purchases, revenue, appointments or another validated commercial eventDid activity reach the result the business values?How much of the result would have happened without CTV
    IncrementalityHoldout lift, geographic comparison, matched testing or another credible counterfactualDid CTV create additional outcomes?Whether the same result will persist at a different budget or audience scale

    Read this chain from the top down. If geography, inventory, or pacing is wrong, downstream performance is not yet interpretable. If delivery is healthy but response is weak, inspect audience-message fit and the creative. If response rises but business outcomes do not, inspect the landing experience, offer, conversion tracking, and lead quality. If attributed conversions look strong but a comparison group shows no meaningful lift, the attribution system may be claiming demand the campaign did not create.

    Completion rate deserves particular care. It describes playback behavior under the platform’s reporting rules. It does not tell you whether the viewer remembered the brand, understood the offer, or took action. A high completion rate paired with concentrated frequency may simply mean the same reachable households received the ad repeatedly.

    Reach and frequency also require context. Estimates may depend on household graphs, device matching, or modeled identity, and separate buying platforms may not deduplicate the same household consistently. Use the numbers to manage distribution, but do not present cross-platform totals as exact people counts unless your measurement setup genuinely supports that claim.

    Diagnose the pattern before changing the campaign

    The most useful optimization question is not, “Which metric is bad?” It is, “Where does the evidence first stop supporting the expected path?” The answer gives you a testable hypothesis instead of a list of random changes.

    What you seeFirst hypothesis to investigateWhat to do next
    High completion rate, limited reach and rising frequencyDelivery is concentrated among a small reachable groupReview audience constraints, inventory access, exclusions and frequency controls before producing new creative
    Healthy delivery and completion, but little observable responseThe message is not creating action, the audience is a poor fit, or response measurement is incompleteValidate tracking first, then test a materially different message or audience while holding other variables steady
    Platform-reported conversions rise while analytics, CRM or order data stays flatAttribution rules, event mapping, view-through credit or deduplication are creating a reporting gapCompare event definitions, timestamps, attribution windows and customer records before increasing spend
    Site activity rises but conversion quality fallsThe ad is creating curiosity without qualified intent, or the landing experience breaks the promiseCompare new and returning visitors, review lead or order quality, and align the landing page with the ad’s exact proposition
    Attributed results are concentrated among existing customersRetargeting may be harvesting demand rather than creating new demandSeparate existing customers from prospects and report acquisition outcomes independently
    The campaign underdeliversAudience, geography, inventory, bidding, creative approval or brand-safety constraints may be too restrictiveFind the binding constraint and relax one condition at a time; do not broaden everything simultaneously
    Reported efficiency looks strong, but a holdout or market comparison shows little liftThe attribution model is awarding credit for outcomes likely to occur anywayMake incrementality the budget decision metric and use attribution mainly for operational diagnosis

    These patterns are starting points, not automatic verdicts. A tracking failure can imitate a creative failure. A landing-page problem can imitate weak audience quality. An aggressive attribution window can make an ordinary campaign look exceptional. Confirm the upstream evidence before acting on the downstream symptom.

    Build measurement that can survive scrutiny

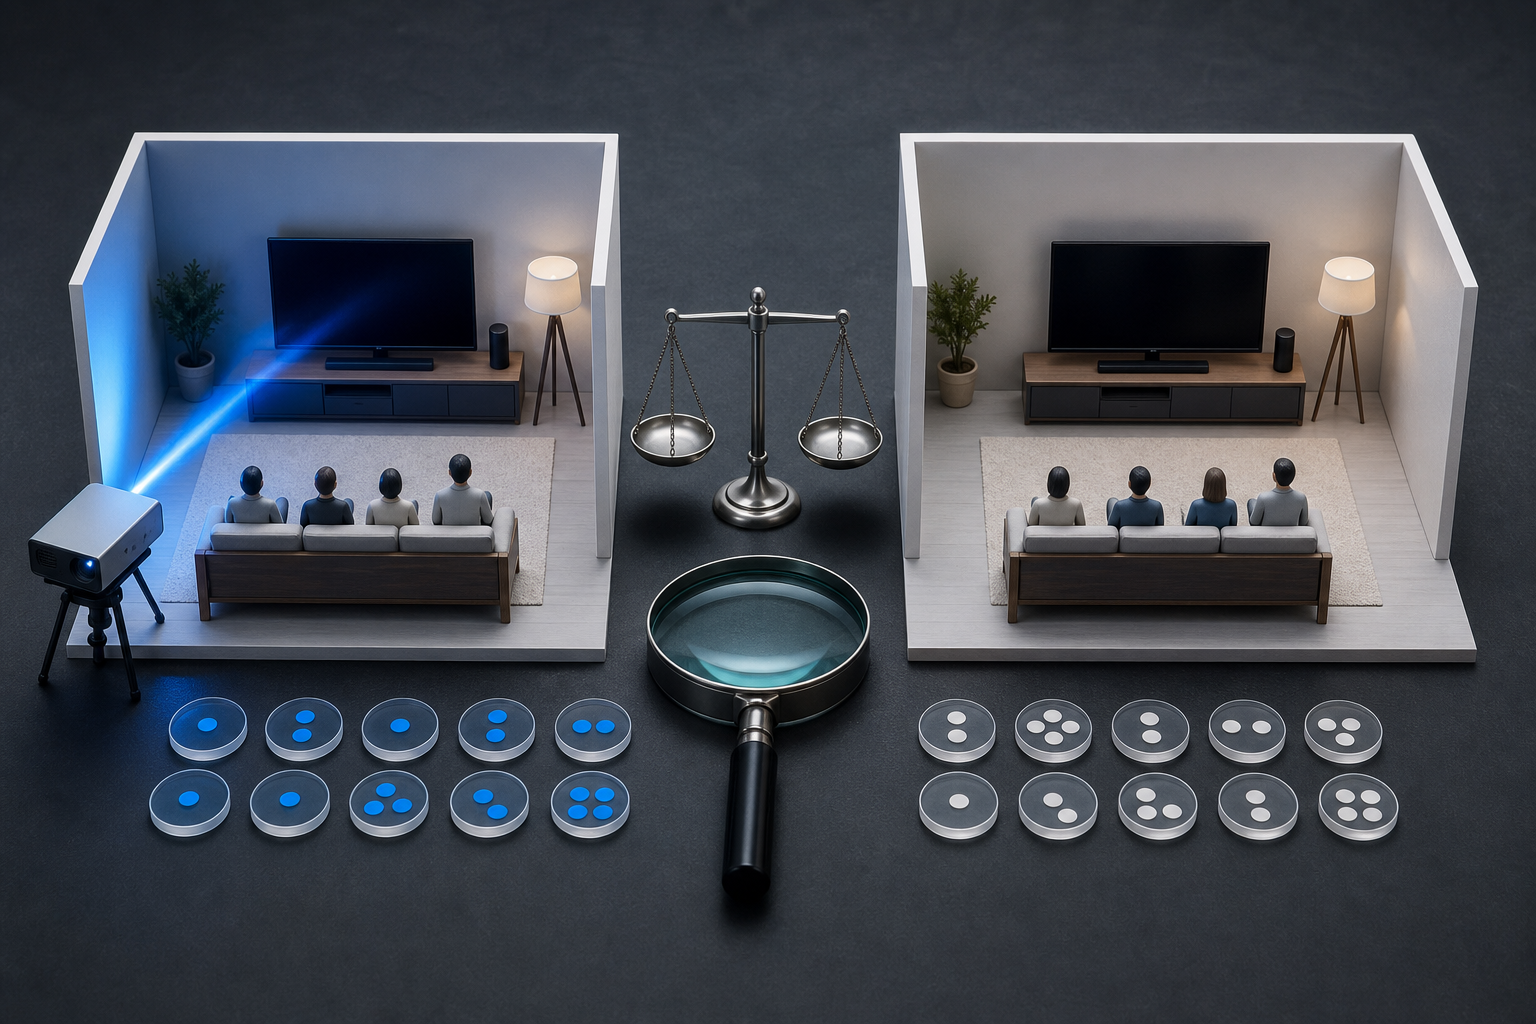
    Two matching miniature living rooms are compared on a laboratory bench, with only one receiving a projected media beam.

    Your buying platform, site analytics, ad server, and CRM do not necessarily answer the same question. A platform may assign credit when an exposed household converts within its configured window. Site analytics records sessions and events under its own identity and attribution rules. Your CRM may count only validated leads, completed sales, or first-time customers. A mismatch is not automatically an error, but an unexplained mismatch is a decision risk.

    Use this sequence to make the systems comparable:

    1. Standardize campaign identity. Carry a stable campaign name or ID through the buying platform, landing page, analytics setup, CRM, and reporting model. Preserve creative, audience, geography, inventory, and flight labels as separate fields.
    2. Define the business event. Specify exactly what counts as a conversion. A form submission, qualified lead, booked appointment, completed order, and new-customer order are different events and should not be blended.
    3. Document attribution settings. Record the click-through and view-through rules, conversion window, household or device-matching method, deduplication logic, time zone, and treatment of repeat conversions.
    4. Test the full data path. Follow a test action from the landing page through analytics and into the business system. Confirm that required fields persist and that duplicate, cancelled, unqualified, or internal events are handled as intended.
    5. Separate meaningful cohorts. At minimum, inspect prospects and existing customers independently when acquisition is the goal. Add geography, creative, audience, device, inventory, and frequency views only when they answer a real decision question.
    6. Create a counterfactual. Use a randomized holdout when the setup allows it. Otherwise, consider a carefully selected geographic or matched comparison and state its limitations. A simple before-and-after view is vulnerable to seasonality, promotions, competitor activity, and changes in other channels.
    7. Keep a decision log. Record the hypothesis, date, change, expected metric movement, guardrail, and result. This is what stops a sequence of campaign edits from turning into an uninterpretable blur.

    Use only identifiers and matching methods permitted by your consent practices, contracts, and applicable privacy requirements. More granular identity data is not automatically better measurement if you cannot use it lawfully or explain how it produced the result.

    Most importantly, distinguish attribution from incrementality. Attribution assigns credit under a rule. Incrementality asks whether the advertising produced an outcome that otherwise would not have occurred. You need attribution to operate campaigns, but you need incremental evidence to justify budget. When a rigorous incrementality test is not feasible, label the result as directional and make smaller decisions until stronger evidence is available.

    Optimize the earliest broken link in the chain

    CTV optimization works best in a deliberate order. Fixing a downstream metric while an upstream problem remains can improve the dashboard without improving the campaign.

    1. Repair measurement first. Resolve missing events, inconsistent definitions, duplicate conversions, landing-page errors, and unexplained reporting gaps. Do not move budget based on data you do not trust.
    2. Correct delivery fit. Confirm that the intended geography, devices, content environments, schedule, exclusions, and audience constraints match the plan.
    3. Improve exposure distribution. If frequency is concentrating while reach stalls, inspect frequency controls and the restrictions limiting available inventory. If reach is broad but the audience is poorly qualified, tightening the audience may be appropriate even if delivery becomes less efficient.
    4. Test the message. Change the proposition, proof, framing, or call to action rather than relying on cosmetic variations. A useful test should represent a real hypothesis about why viewers are not responding.
    5. Refine the audience. Separate prospecting from retargeting, distinguish existing customers from new prospects, and avoid treating a high-attribution segment as automatically incremental.
    6. Continue the promise after the ad. The landing experience should use the same offer, language, product, and next step. If the viewer has to reconstruct the message after switching devices, unnecessary friction has entered the journey.
    7. Reallocate budget last. Move spend after you understand whether the difference came from delivery, audience, creative, conversion quality, or incremental impact. Cheap delivery is not a bargain when it buys the wrong outcome.

    Review the creative as it will be experienced from a sofa, not as a large design file on a work screen. A viewer should be able to identify the brand and understand the proposition before the ad ends. Important text must remain legible at television distance. A QR code can support the response path, but it should not carry the entire call to action. Give viewers a brand, product, phrase, or destination they can remember and find later.

    When you run a test, preserve interpretability. State the hypothesis, change one major variable, select the primary metric, and name the guardrail before looking at the outcome. If business constraints require several simultaneous changes, separate them into distinct cells where possible or record that the result cannot identify which change caused the movement.

    Bring a one-page decision sheet to your next CTV review: the business question, primary outcome, attribution rule, comparison method, first broken link, and next test. If your team cannot complete one of those lines, that gap is the next task. Once every line is defensible, CTV advertising performance becomes a business decision rather than a collection of favorable video metrics.

    References

  • Generative Engine Optimization Tools and Pricing Guide

    Generative Engine Optimization Tools and Pricing Guide

    You are probably comparing GEO tools because your brand is difficult to find in ChatGPT, Gemini, Perplexity, or another generative answer engine. The hard part is not finding a dashboard. It is working out whether a quote buys useful measurement, practical recommendations, or the work required to change the answers.

    That distinction matters more than the advertised monthly price. A low-cost tracker can be exactly right for a team that can execute. The same subscription can become shelfware when nobody owns content, SEO, reviews, or digital PR. Use this guide to define the job, compare unlike pricing plans on the same basis, and buy only the scope you can turn into action.

    Decide whether you need a GEO tool, a service, or both

    GEO software and managed GEO services solve different parts of the problem. Treating them as substitutes is the fastest way to misread a proposal.

    A tool observes. It may collect answers for a defined prompt set, detect brand mentions, capture cited URLs, compare entities, and show changes over time. AI visibility and citation measurement across engines such as ChatGPT and Gemini are central uses of this product category.

    A service acts. It may improve pages on your website, create comparison content, pursue inclusion in third-party lists, develop review visibility, or conduct public relations. Some agencies include software access in the engagement, but the dashboard is still only the measurement layer.

    Start by naming your actual bottleneck:

    • You cannot see what is happening. You do not know which prompts matter, whether your brand appears, which pages are cited, or how competitors enter the answer. Begin with measurement software.
    • You can see the problem but cannot diagnose it. You have reports, but no reliable way to connect an answer change to content, authority, citations, or reputation. Look for a platform or advisory engagement that produces evidence-backed recommendations.
    • You know what should change but lack execution capacity. The backlog repeatedly loses to other work. A managed service may be more economical than another dashboard because implementation is the scarce resource.
    • Your website is not the main constraint. Competitors are recommended because they appear in respected comparisons, reviews, and press coverage. A tool can expose this gap, but fixing it requires off-site work.

    Do not pay for full-service execution merely because the reporting looks sophisticated. Conversely, do not buy a tracker and assume visibility will improve by itself. Write one sentence before any sales call: We need this purchase to help us decide or do ______. If a vendor cannot connect its deliverables to that sentence, the package is oversized, underspecified, or both.

    Require evidence for every capability on the feature list

    Feature matrices make GEO platforms look more interchangeable than they are. Two vendors can both advertise prompt tracking while using different engines, collection schedules, sampling methods, and definitions of visibility. Compare the records behind the dashboard, not the labels on the pricing page.

    CapabilityWhat to askAcceptable proof
    Engine coverageWhich engines, answer modes, markets, and account states are included in our quoted plan?A current coverage list and a raw result from every engine you intend to monitor.
    Prompt trackingDoes one tracked prompt cover one engine, or is each prompt-engine-market combination counted separately?The precise billing definition of a tracked prompt, including reruns and overages.
    Answer collectionHow often are answers collected, and how does the system handle variation between responses?Timestamped answer text with collection metadata and a documented sampling method.
    Brand detectionCan we define product names, parent brands, abbreviations, misspellings, and excluded terms?A configurable entity record and examples showing how ambiguous matches are handled.
    Citation captureDoes the platform preserve the cited page, domain, answer passage, and engine where the citation appeared?A citation-level export, not merely a domain total.
    Competitor analysisCan the same prompt set compare our brand with named alternatives without changing the collection method?A prompt-level view showing every detected entity and citation in the underlying answer.
    RecommendationsDoes each recommendation identify the evidence, affected prompt group, responsible team, and proposed change?A sample recommendation that can be accepted, rejected, assigned, and later evaluated.
    History and exportWhat data can we retain or export if we downgrade or leave?A machine-readable export containing prompts, answers, dates, mentions, citations, and relevant metadata.

    Raw answer evidence is essential because a brand mention, a recommendation, and a citation are not the same result. Your company can be named without being endorsed. It can be recommended without receiving a clickable citation. A page can be cited while the answer recommends a competitor. A single visibility score can hide all three situations.

    Define the scorecard before you watch the demo

    Ask every shortlisted vendor to calculate the same small set of metrics. The names are less important than stable definitions:

    • Answer inclusion rate: the share of eligible collected answers in which the defined brand or product appears.
    • Recommendation rate: the share in which the brand is presented as a suitable choice, not merely mentioned in passing.
    • Cited-source rate: the share that cites a page on a domain you own or another domain you have deliberately classified.
    • Competitor gap: the prompt groups where a named competitor appears or is recommended and your brand does not.
    • Evidence gap: the cited domains and page types supporting competitors but absent from your own authority footprint.
    • Action completion: the recommendations accepted, assigned, implemented, and annotated in the measurement history.

    Keep engine-level results separate until you have a reason to combine them. A blended score can rise because performance improved on a low-priority engine while declining where your buyers actually search. If you do create an overall index, document the business weighting so a future team member can reproduce it.

    Your prompt inventory needs the same discipline. Group prompts by the decision they represent: category discovery, direct comparison, problem diagnosis, vendor validation, or implementation. Tag branded and unbranded prompts separately. A report dominated by easy branded questions can look healthy while category-level discovery remains weak.

    Normalize GEO pricing before comparing quotes

    Three toolboxes are unpacked into matching rows of monitoring, recommendation, support, and service components beside a balance scale.

    There is no useful universal price without a common unit of scope. GEO packages can vary greatly in cost and included work, with entry-level options offering narrower functionality and premium engagements covering a broader program. A monthly total tells you little until you know what consumes the allowance and what still requires your team.

    Build a quote-normalization sheet with these rows:

    Pricing variableRecord for every quoteWhy it changes the real cost
    Prompts or queriesIncluded quantity, billing definition, and overage ruleA prompt may be counted once, once per engine, or once for every market and configuration.
    EnginesIncluded engines and any plan restrictionsBroad headline coverage is irrelevant if the engines you need sit behind an upgrade.
    Markets and languagesIncluded locations, languages, and regional configurationsLocal or international monitoring can multiply the number of configurations being tracked.
    Collection cadenceRefresh schedule, reruns, and sampling methodA frequently refreshed series is not equivalent to an occasional snapshot.
    Brands and competitorsIncluded entities and the price of additional onesA plan can become expensive when each product line or competitor consumes another allowance.
    Users and workspacesIncluded seats, clients, projects, and permission controlsAgency and enterprise use may require separation that an individual account cannot provide.
    HistoryRetention period and access after downgrade or cancellationTrend reporting loses value if the underlying evidence expires or cannot be exported.
    Exports and integrationsFile exports, API access, dashboards, and usage limitsManual transfer adds labor even when the platform subscription appears inexpensive.
    OnboardingSetup fee, prompt research, entity configuration, and trainingA low recurring fee may exclude the work needed to make the account usable.
    Analysis and executionIncluded analyst time, content work, SEO changes, outreach, reviews, and PRSoftware access should not be priced as though implementation is included when it is not.
    CommitmentBilling frequency, minimum term, renewal process, and cancellation conditionsAn annual commitment carries a different risk from a cancellable pilot, even at the same monthly equivalent.

    Then calculate the cost you will actually approve:

    Total operating cost = platform or service fee + required add-ons + internal analysis time + implementation labor + external execution spend.

    This is the figure that belongs in your decision memo. A subscription can look cheap while requiring hours of prompt cleanup, report interpretation, content production, and outreach. A managed engagement can look expensive while replacing work you would otherwise need to staff. Neither is automatically better; the relevant question is which quote buys the missing capability at the lower total cost.

    Use a common monitoring unit, but do not mistake it for value

    For quote comparison, define one monitoring configuration as a prompt paired with an engine, market, language, and refresh schedule. Ask vendors to price your exact inventory. This prevents a plan with broad but shallow coverage from appearing equivalent to one collecting the configurations you need.

    You can divide total software cost by comparable monitoring configurations to expose pricing differences. Do not use that result as your final value metric. A large inventory of irrelevant prompts is still waste. Value comes from resolving decisions: which content to improve, which evidence to publish, which citation gap to pursue, and which work to stop.

    Also separate included capacity from usable capacity. If your team can review only a small portion of the collected results, buying more prompts adds noise. If the allowance is too small to cover meaningful prompt groups, apparent volatility may send the team after isolated answer changes. Scope the inventory around decisions and ownership, then buy the capacity required to support it.

    Match the service tier to the work that must change

    Three connected workstations show analytics, collaborative content and outreach work, and improved source signals flowing into an abstract answer engine.

    Service tiers are useful as a procurement model, but their names are not standardized. Define each tier by responsibility rather than by labels such as starter, growth, or enterprise.

    • Measurement tier: establishes the prompt set, captures answers, reports mentions and citations, and identifies gaps. Choose it when your internal team can interpret the findings and implement changes.
    • Diagnosis and guidance tier: adds prioritized recommendations, content or authority analysis, and working sessions. Choose it when you have execution capacity but need help deciding what to change.
    • Managed execution tier: owns agreed work across measurement, website SEO, comparison content, reputation, third-party visibility, and PR. Choose it when the visibility gap extends beyond your site or when internal ownership is the constraint.

    A comprehensive GEO program may span several distinct workstreams. Ranking strong comparative or superlative pages can influence the information available to answer engines. Inclusion in third-party lists can create corroborating evidence. Reviews contribute reputation signals on platforms relevant to the category. Press coverage can strengthen the body of independent material associated with the brand. SEO, list visibility, reviews, and traditional PR can all form part of the broader GEO scope.

    Review work must be category-specific. Technology services may care about G2 and Clutch, software companies may encounter Capterra, travel brands may depend on TripAdvisor or Yelp, and B2B organizations may need to notice employer-review properties such as Glassdoor and Indeed. The point is not to create profiles everywhere. It is to identify which independent properties appear in the citations and recommendations for your commercial prompt set, then prioritize legitimate review generation and accurate profile management there.

    Ask a managed provider to separate owned, earned, and paid activity in its scope. A page published on your website is not equivalent to independent editorial coverage. A paid list placement is not equivalent to an earned recommendation. A review profile is not the same as a program that helps real customers leave candid feedback. If all of these appear under a vague authority-building line item, you cannot judge the method, risk, or expected deliverable.

    A lower tier is sensible when you already have strong brand recognition, search performance, editorial resources, or PR support. It is also sensible when you are still validating the prompt set. Premium execution earns its fee only when the provider is responsible for work you genuinely need and can show how that work connects to observed answer and citation gaps.

    Run the same buying test with every finalist

    1. Write the decision brief. Specify the products, market, engines, prompt groups, competitors, and business decisions the system must support.
    2. Send an identical inventory. Require every vendor to quote the same prompt-engine-market configurations, refresh expectations, users, history, and export needs.
    3. Inspect a raw record. Ask to see the prompt, collected answer, timestamp, detected entities, cited pages, and relevant collection metadata behind a dashboard result.
    4. Test a difficult distinction. Use a result where your brand is mentioned but not recommended, or where your page is cited while a competitor is favored. Ask how the platform classifies it.
    5. Request an action sample. A recommendation should identify the evidence, affected prompt group, proposed change, owner, and method for evaluating the result later.
    6. Price the full workflow. Add platform fees, overages, setup, analyst time, content or technical implementation, outreach, and any separate PR or review work.
    7. Confirm data control. Obtain the retention, export, cancellation, and post-termination access terms in writing before committing.

    If a pilot is available, judge it on traceability rather than a dramatic score change. You should be able to move from an executive chart to a collected answer, from that answer to its citations, and from the gap to an assigned action. A platform that cannot preserve that chain will make it difficult to defend spending or learn from changes.

    Key takeaways

    • Buy measurement software when you need visibility into prompts, mentions, recommendations, citations, and competitors. Buy services when you need someone to change the conditions producing those results.
    • Compare quotes using the same prompt, engine, market, language, refresh, history, entity, and user requirements. Headline monthly prices are not comparable without those units.
    • Demand raw, timestamped answer and citation evidence. A single visibility score cannot tell you whether the brand was merely mentioned, actively recommended, or cited.
    • Calculate total operating cost, including internal analysis and execution. The subscription fee is only one part of the budget.
    • Choose a lower service tier when your team already has authority and implementation capacity. Choose managed execution when content, third-party lists, reviews, PR, or ownership are the real constraints.
    • Do not reward data volume for its own sake. The best plan is the smallest one that reliably supports decisions your team is prepared to execute.

    Take your real prompt inventory and the normalization table into the next vendor call. Reject any proposal that cannot define its billing unit, expose the evidence behind its metrics, and name who owns the work after a gap is found. That will narrow the field faster than another feature comparison and leave you with a GEO budget tied to action rather than dashboard access.

    References

  • Google Performance Max Budgets: Total vs. Average Daily

    Google Performance Max Budgets: Total vs. Average Daily

    If your Performance Max campaign has a fixed pot of money and a firm finish date, an average daily budget creates an unnecessary translation problem. You have to convert the approved total into a daily amount, then recalculate it whenever the budget, schedule, or cumulative spend changes.

    Total campaign budgets are appearing alongside the classic average daily budget in PMax, including in accounts outside the U.S. That gives you a more natural control for short flights, promotional bursts, and campaigns that must stop on a fixed date. The important decision is not which option sounds stricter. It is which one matches the financial constraint you actually have.

    Choose the budget model from the constraint

    Start with the commitment you made to the business. Is the approved amount tied to the entire campaign, or are you managing an ongoing rate of spend? That distinction should determine the setting.

    Campaign situationBetter starting controlReason
    Fixed media budget and fixed end dateTotal campaign budgetThe platform receives the campaign-wide amount directly, so you do not have to translate it into a daily average.
    Always-on campaign with no meaningful end dateAverage daily budgetThe operating constraint is an ongoing pace rather than a finite flight total.
    Short promotion, launch, event, or seasonal burstTotal campaign budgetSpend has to be managed across a defined window, often with little room for a late manual correction.
    Continuous campaign reviewed and funded periodicallyAverage daily budgetThe campaign continues while its acceptable spending rate is reviewed over time.

    A total budget is not automatically safer for every campaign. It is safer when the real liability is the full cost of a finite flight. An average daily budget remains the clearer instruction when the campaign is meant to continue and the business controls its pace rather than a final total.

    Key takeaways

    • Use a total campaign budget when both the approved media amount and the campaign end date are fixed.
    • Use an average daily budget when the campaign is ongoing and the controllable variable is its rate of spend.
    • Do not treat either budget type as a profitability or performance guarantee.
    • Check your own PMax setup before planning around the total-budget option because availability is still expanding.
    • Monitor cumulative cost and the required remaining pace even when Google handles campaign-level pacing.

    Build a fixed flight without losing control of the numbers

    A transparent container of brass tokens feeds a timed path of blank calendar tiles, with used tokens separated in a tray and a movable gate controlling the remaining supply.

    A total budget removes one calculation from campaign setup, but it does not remove the need for a precise brief. Before you publish a fixed flight, make the following decisions explicit.

    1. Define the spend amount. Confirm that the approved figure represents media spend inside Google Ads. Keep agency fees, production costs, taxes, and other expenses separate unless your internal budget owner has deliberately included them.
    2. Fix the campaign window. Record the intended start date, final eligible date, account time zone, and any business deadline that falls after advertising stops. A vague end date turns a total budget into a moving target.
    3. Select the unit that matches the approval. If the account offers a total campaign budget, enter the approved campaign-wide media amount. If it does not, calculate an average daily budget from the fixed total and scheduled campaign days.
    4. Check the setting before launch. A total amount entered into a daily field can create immediate financial exposure. A daily amount entered as the total can suppress the entire flight. Have the budget owner or a second operator verify the budget type, amount, and dates together.
    5. Create a pacing check. Track cumulative campaign cost, remaining approved budget, remaining campaign days, and the business outcome you are optimizing. The budget setting controls spend instructions; your reporting still has to show whether the money is producing acceptable results.
    6. Log every material edit. Record the old and new budget, the old and new end date, cumulative cost at the time of the change, the reason, and the approver. Without that record, a later change in delivery can be difficult to interpret.

    For monitoring, subtract cumulative campaign cost from the approved total to get the remaining budget. Divide that remainder by the remaining campaign days to see the implied pace required from that point. This is a diagnostic, not a replacement for the total-budget setting. It tells you whether a late budget or date change has created an unrealistic catch-up requirement.

    Be especially careful when editing an active campaign. Changing either the total or the end date changes the implied pace for the rest of the flight. If the interface does not make clear whether an edited amount represents the whole campaign or only the remaining period, do not guess. Read the field definition presented in your account and reconcile it against cost already recorded before saving.

    Budget control is not performance control

    The new option solves a budgeting mismatch: a fixed campaign total no longer has to be expressed as a daily average. It does not make every other PMax decision correct.

    • It does not promise identical spend each day. A campaign-level budget is designed around the full flight, so assess cumulative pacing rather than expecting a perfectly flat daily line.
    • It does not guarantee full delivery. A budget is permission to spend, not proof that enough eligible opportunities exist under the rest of the campaign setup.
    • It does not guarantee profitable delivery. Conversion measurement, campaign goals, assets, bidding decisions, and the underlying offer still determine whether spend creates value.
    • It does not create an account-wide ceiling. A PMax campaign budget controls that campaign. If several campaigns draw from one commercial allocation, you still need a separate portfolio or account-level control process.
    • It does not repair a weak objective. Giving automation a cleaner spending instruction cannot compensate for an outcome that is poorly defined or measured.

    This distinction prevents a common diagnostic error. If a campaign has budget headroom but is not delivering, increasing a cap that is not binding does not address the active constraint. Investigate campaign eligibility, measurement, bidding, assets, and demand before assuming the budget is the problem. If the campaign is spending at the intended pace but producing weak outcomes, work on performance inputs rather than switching budget models.

    Handle availability as a rollout, not an assumption

    The total-budget option has been reported live beyond the U.S. after plans to extend it to Search, Shopping, and Performance Max. That is evidence of an expanding rollout, but it is not a reason to assume that every account, market, or campaign setup exposes the same control at the same moment.

    Check the budget section of the actual PMax campaign you intend to run. Look for a choice between a total campaign budget and an average daily budget. If the total option is absent, keep the campaign plan intact and use the daily-budget fallback rather than delaying a time-sensitive flight solely for a setting you cannot access.

    Your fallback worksheet only needs a few controlled fields:

    • Approved media budget
    • Campaign start and end dates
    • Number of scheduled campaign days
    • Calculated average daily budget
    • Cumulative campaign cost
    • Remaining approved budget
    • Date, owner, and reason for the latest revision

    Calculate the initial daily setting by dividing the fixed media budget by the scheduled campaign days. Treat the result as the planning input for an average daily budget, not a promise that each calendar day will produce identical cost. Recalculate it whenever the approved total, schedule, or amount already spent changes. That change control is where many flighted campaigns lose alignment with their original approval.

    Read pacing and results as separate signals

    Two separate control instruments show token flow toward a finish marker and tokens branching into several illuminated outcome channels.

    A campaign can be on budget and still be commercially weak. It can also be behind its planned pace while the results it does generate are valuable. Your review should therefore answer two separate questions: Is spend moving appropriately through the flight, and is that spend producing an acceptable business outcome?

    • Pacing is aligned and outcomes are acceptable: avoid changing the budget simply because the control is available. Preserve a stable plan unless the business constraint changes.
    • Spending is faster than expected and outcomes are acceptable: confirm the fixed financial ceiling before approving more budget. Good performance does not silently expand spending authority.
    • Spending is slower than expected and outcomes are acceptable: inspect the remaining budget and remaining time. Decide whether the campaign truly needs to catch up or whether the original total was only a maximum.
    • Pacing is aligned but outcomes are weak: leave the budget-model question aside and diagnose the performance inputs. Changing from daily to total does not improve the value of the traffic or conversions.
    • Spending is slow and outcomes are weak: do not increase budget by reflex. More headroom is unlikely to help when the current budget is already not being reached.

    For your next fixed-duration PMax launch, put the budget model directly in the campaign brief alongside the approved amount, start date, end date, and change authority. Select the total campaign budget when it is available and matches the commitment. Otherwise, use the calculated daily fallback and keep the remaining budget visible. That gives Google a clear spending instruction while leaving the financial decision where it belongs: with you and the budget owner.

    References

  • YouTube Demand Gen Cost Adjustments: A Practical Guide

    YouTube Demand Gen Cost Adjustments: A Practical Guide

    Your new YouTube Demand Gen campaign is missing its target CPA, and the early spend looks hard to defend. Before you either shut it down or assume Google will make the numbers right, separate the campaign’s performance from a new kind of reporting adjustment.

    Google is testing a narrow beta that may retroactively lower the reported cost of qualifying Demand Gen target CPA campaigns when early conversions fall short of its forecast. That can reduce some learning-period risk, but it isn’t guaranteed, it doesn’t arrive as a visible credit, and it shouldn’t be built into your budget.

    Key takeaways

    • The experiment is aimed at new Demand Gen campaigns using target CPA bidding during their initial learning period.
    • A qualifying adjustment can begin within five days of launch and remain active for up to three weeks.
    • You won’t necessarily see a separate credit or adjustment entry. The campaign’s final reported cost may simply be lower.
    • Eligibility depends in part on account quality, reliable tracking, and adherence to best practices, but meeting those conditions doesn’t guarantee an adjustment.
    • A lower CPA caused by revised cost is financially useful, but it isn’t evidence that your creative, audience, or conversion rate improved.

    What the adjustment changes – and what it does not

    Treat target CPA as an optimization goal, not a contractual price. A campaign can spend above that target while the bidding system gathers enough information to predict which impressions are likely to convert.

    Under the beta, Google monitors a new Demand Gen tCPA campaign during that uncertain opening period. If conversions trail Google’s forecast, the system may recalculate costs retroactively so the resulting CPA is closer to the campaign’s target.

    The important word is cost. Observed CPA is reported cost divided by recorded conversions. If Google lowers the numerator while the conversion count stays unchanged, CPA improves mathematically. Nothing in that calculation proves that the ads generated more conversions, attracted better prospects, or became more persuasive.

    That distinction matters when you explain the result. If only reported cost changed, don’t write that campaign optimization produced a performance gain. Say that the platform adjusted reported media cost during the learning period. You can then evaluate creative and audience performance using the conversion evidence that remains.

    It is also safer to call this a cost adjustment than a refund. The experiment is designed to produce a revised final reported cost without a separate credit or line item. Don’t promise a client or finance team that cash is coming back, and don’t book a saving before the adjusted cost actually appears.

    Use the five-day and three-week windows correctly

    Five small day tiles and three larger weekly blocks form an abstract campaign evaluation timeline.

    A retroactive change is difficult to recognize if you only look at the latest dashboard total. Build a simple record from launch so you can see whether historical cost changes later.

    1. Before launch: Record the campaign identifier, launch date, target CPA, conversion action, and maximum approved spend. This gives you a fixed baseline if settings or reported totals change.
    2. During the first five days: Capture reported cost, conversions, and calculated CPA at the same cutoff each day. A high early CPA doesn’t prove that the campaign qualifies, and it doesn’t prove that an adjustment is on the way.
    3. Through the three-week window: Revisit earlier dates instead of checking only the newest day. Compare current historical cost with the values you previously recorded. The adjustment may apply only to particular campaigns or days, so an account-level total can hide it.
    4. At the end of the window: Reconcile the latest campaign total against your snapshots. If historical cost fell without a matching conversion change, label the movement as consistent with a retroactive cost adjustment. Unless Google explicitly identifies the cause, don’t present your inference as confirmation.

    The learning period isn’t permission to ignore a broken campaign. Repair defective conversion tracking as soon as you detect it, and keep any pre-approved budget ceiling or business stop condition in force. This beta changes how you interpret early cost; it doesn’t transfer budget control to Google.

    Audit the cost change without misreading performance

    Your audit doesn’t need a complex attribution model. It needs consistent snapshots. For every observation, preserve the date range, snapshot time, reported cost, recorded conversions, calculated CPA, target CPA, and any tracking or campaign-setting change you made.

    Then compare an earlier snapshot with the platform’s latest values for the exact same reporting period:

    What changedWhat you can concludeHow to report it
    Cost fell; conversions stayed the sameThe CPA improvement came from the cost side of the calculation.Describe a reported-cost revision, not stronger conversion generation.
    Conversions changed; cost stayed the sameThe CPA movement came from the conversion side.Investigate conversion reporting before attributing the result to a cost adjustment.
    Cost and conversions both changedThe snapshot alone cannot isolate the causes.Report both changes and avoid claiming that the beta explains the full CPA movement.
    Neither value changedNo retroactive effect is visible in the compared period.Do not assume future eligibility or include an expected saving.

    This comparison protects you from a common analytical mistake: treating every lower CPA as evidence of better ad delivery. A favorable cost revision can make the campaign more economical, which is valuable in its own right. It still needs to be separated from changes in conversion volume and quality.

    Keep that separation in dashboards and stakeholder updates. Show the latest platform-reported CPA, but retain the underlying cost and conversion fields beside it. Add a note when a historical cost movement is visible. Anyone reviewing the campaign later should be able to tell whether the ads produced a different result or whether Google changed what that result cost.

    Budget as though no adjustment will arrive

    A hand places solid budget tokens into a campaign tray while faint translucent tokens remain in a separate uncertain tray.

    The beta’s stated eligibility considerations include account quality, well-maintained tracking, and consistent use of best practices. Those are factors, not a deterministic application checklist. Even an apparently well-run account may receive no adjustment, and an eligible campaign may receive one for only part of the learning period.

    • Fund the unadjusted scenario. Approve the campaign only if you can absorb its planned spend without a retroactive reduction.
    • Verify tracking before launch. A cost safety mechanism cannot rescue a campaign whose conversion signal measures the wrong action or fails to record the intended outcome.
    • Document necessary changes. If you repair tracking or alter a campaign setting during the window, record what changed and when. Otherwise, later CPA movements will be easy to misattribute.
    • Keep your economic stop conditions independent. Don’t let the possibility of an adjustment justify spend that has already crossed an approved limit or no longer makes business sense.
    • Treat an observed reduction as upside. Once it appears in reported cost, include it in reconciliation while preserving a note about how the improvement occurred.

    At your three-week review, make the next budget decision from current economics, conversion quality, and the latest reconciled cost. If the campaign only looks viable when you assume an adjustment that hasn’t appeared, it hasn’t earned more budget yet.

    References