Tag: Budget Management

  • A Practical Playbook for Automated Google Ads Optimization

    A Practical Playbook for Automated Google Ads Optimization

    You turned on Google Ads automation so the system could handle more of the bidding and delivery work. Now the campaign is spending, results are uneven, and every available adjustment seems capable of disrupting the learning you have already paid for.

    The answer is not to make more changes. It is to make changes that answer specific questions. Give the campaign one measurable job, diagnose the layer that is failing, and isolate one variable long enough to learn from it. That is how you optimize Performance Max and Demand Gen without turning the account into a collection of unexplained edits.

    Give the automation one precise job

    Automated bidding and delivery are execution systems, not business strategies. Google can pursue the outcome you define, but it cannot decide whether that outcome represents useful growth for your business.

    Before changing an asset, audience, channel, or bid strategy, complete this sentence: “This campaign exists to generate [specific outcome] from [specific audience or demand source], and we will judge it by [specific business metric].” If you cannot complete it without using a vague phrase such as “more visibility,” the campaign is not ready for detailed optimization.

    Write a short optimization brief containing four decisions:

    1. Primary outcome: Name the action that matters, such as a purchase or qualified lead. Do not let a convenient secondary action become the campaign’s de facto goal.
    2. Conversion definition: Confirm that the conversion category and tracking represent the outcome you intend to buy. A campaign trained toward the wrong event can become efficient at producing the wrong result.
    3. Decision metric: Choose the metric that will determine whether a change stays. Click volume, conversion volume, cost per conversion, and conversion value answer different questions.
    4. Campaign role: Decide whether the campaign is capturing existing demand, re-engaging known users, finding similar prospects, or creating demand among new audiences. Do not evaluate an audience-expansion campaign as if every user had already expressed search intent.

    Demand Gen makes the bidding decision especially concrete. It requires a conversion category and supports Maximize Clicks, Maximize Conversions, Maximize Conversion Value, Target CPC, Target CPA, and Target ROAS. Match the strategy to the brief: use a click-oriented strategy when qualified traffic is the actual objective, a conversion-oriented strategy when action volume matters, and a value-oriented strategy only when the values passed into Google reflect meaningful differences between conversions.

    Target CPC is a useful Demand Gen option when controlling the amount you are willing to target per click matters more than giving bidding full freedom. It does not remove the need to assess traffic quality. Cheap clicks are not an optimization win when the audience, placement, or landing experience cannot produce the intended action.

    Once the brief is set, keep it stable during the test. If you change the conversion definition, bid strategy, audience, and creative together, a better result will not tell you which decision worked. A worse result will be equally uninformative.

    Diagnose the failing layer before touching settings
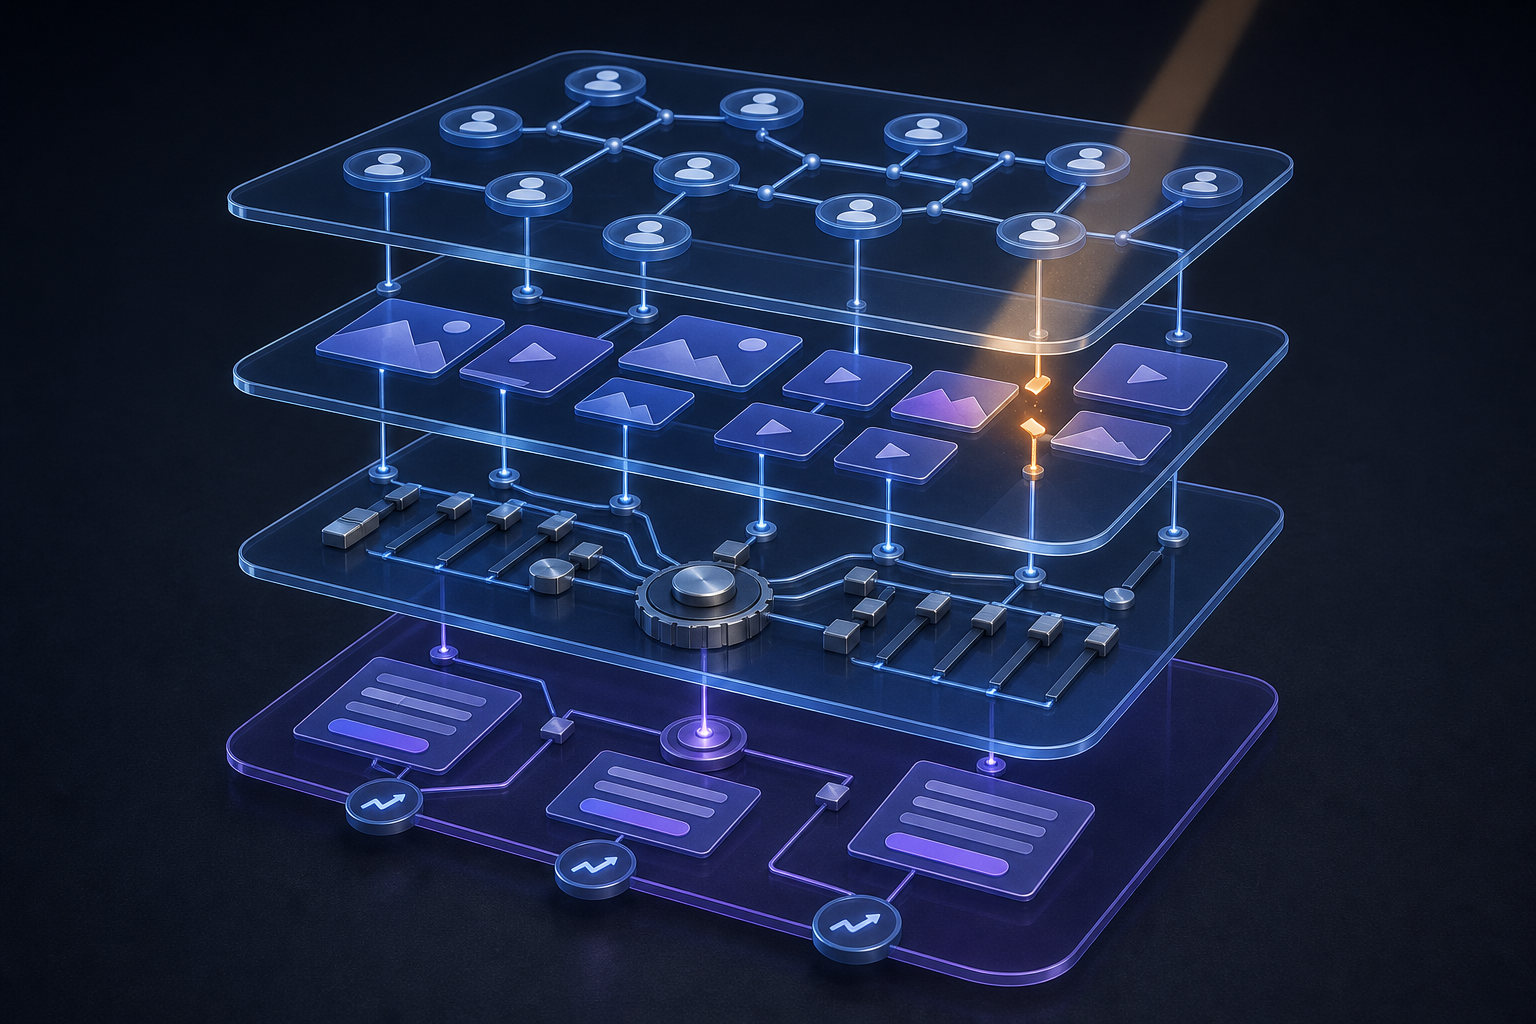
    Four transparent campaign layers float above a table while a diagnostic beam highlights one broken creative connection.

    A weak automated campaign does not automatically have an automation problem. The failure may sit in measurement, inventory, audience selection, creative, or the offer itself. Treating all five as one problem leads to account-wide changes that conceal the cause.

    Audit in this order:

    1. Measurement: Check that the recorded conversion is the action named in your brief. Inspect whether duplicate, secondary, or low-value actions are influencing your interpretation before you blame bidding.
    2. Inventory and channel: Determine where the ads appeared. A blended campaign total can hide meaningful differences between YouTube, Discover, and Gmail.
    3. Audience: Check whether the people engaging with the campaign resemble the users you intended to reach. An audience mismatch should be addressed before you conclude that the creative proposition is wrong.
    4. Creative: Look for patterns across headlines, images, videos, and formats. Use those patterns to form a testable hypothesis, not as permission to replace every asset at once.
    5. Offer and destination: Confirm that the promise made by the ad continues on the landing page and that the requested action makes sense for the user’s stage of awareness.

    Demand Gen gives you several views for this diagnosis. Its asset reporting, audience insights, channel segmentation, and YouTube placement reporting can help you locate the layer worth investigating. Use these reports as directional evidence. An asset-level performance label can identify a candidate for testing, but it does not prove that the asset alone caused the result because audience, placement, and delivery can differ.

    What you noticeCheck firstNext controlled action
    Reported conversions do not match business outcomesConversion action and categoryCorrect or separate the measurement problem before testing creative or audiences.
    One Demand Gen channel behaves differently from the othersChannel and placement reportingInspect that inventory, then decide whether the channel belongs in the campaign’s role.
    Audience insights do not resemble the intended buyerAudience constructionChange one audience boundary while keeping the offer and creative stable.
    Several assets built around one idea underperformCreative propositionBuild a coherent challenger around a different idea and test it against the original.
    Ads earn attention but the intended action does not followOffer and landing-page continuityCheck the promise, destination, and conversion ask before buying more traffic.

    Record the diagnosis before making the change. A useful optimization note states what you observed, what you think caused it, what single variable will change, and what result would support or reject the hypothesis. Without that record, campaign management tends to become a sequence of plausible edits with no cumulative learning.

    Run Performance Max asset tests as controlled experiments
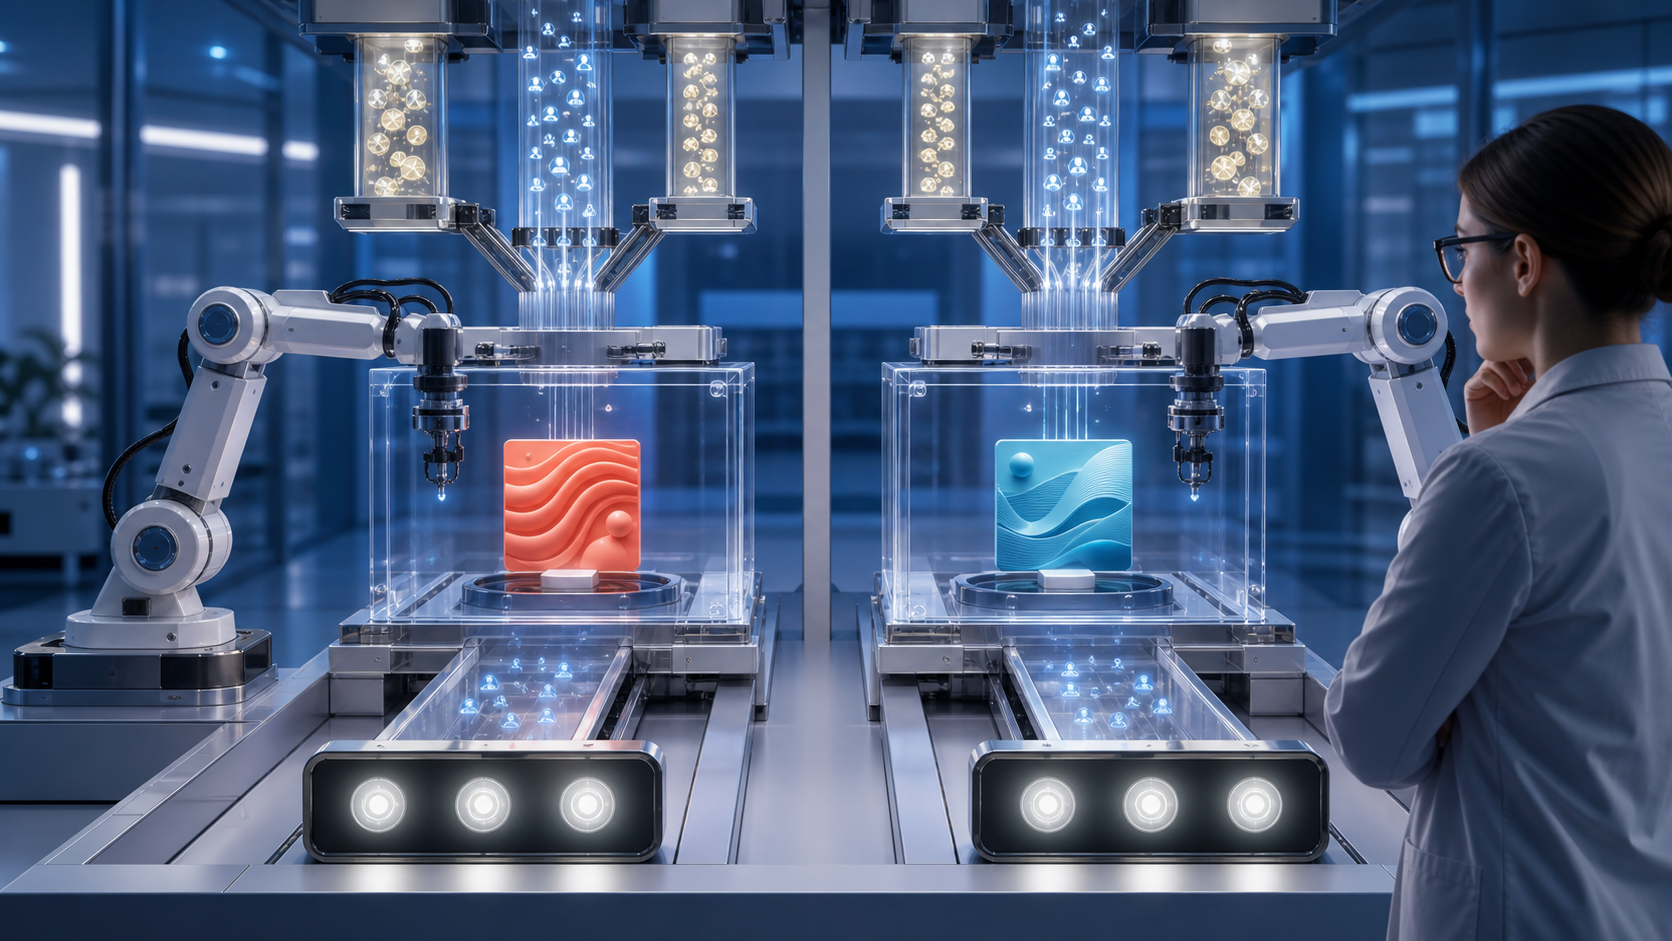
    Two matching automated test chambers compare different creative tiles while an analyst observes the experiment.

    Performance Max has historically made creative diagnosis difficult because automation decides how assets are combined and delivered. The Performance Max asset A/B testing beta allows two asset sets to be compared while common assets remain fixed. It extends the earlier retail experiment model across Performance Max campaigns and gives you a cleaner way to test creative ideas without rebuilding the entire campaign.

    If the beta is available in your account, look for the experiment from the Experiments area under Assets. Because it is a beta, document the setup outside the interface as well: campaign, hypothesis, common assets, challenger assets, start date, intended end date, and decision metric.

    Use this sequence:

    1. Write one creative hypothesis. Examples include benefit-led versus proof-led headlines, product-focused versus lifestyle imagery, or two distinct video concepts. The hypothesis should explain why one approach may work better for the intended audience.
    2. Choose the level of the test. If you change one asset family, you can learn about that family. If you change headlines, images, and videos together, you are testing two creative systems and will only learn which complete system performed better.
    3. Protect the common assets. Keep every asset that is not part of the hypothesis the same across both versions. These shared elements form the control surface of the experiment.
    4. Freeze unrelated campaign decisions. Avoid changing audiences, bidding logic, conversion definitions, the offer, or the landing page while the asset experiment is running unless there is a material tracking or business problem that makes the test unsafe to continue.
    5. Choose the decision metric in advance. Judge the test by the outcome in the campaign brief. Do not promote a challenger solely because it attracted more engagement when the campaign exists to generate profitable conversions.
    6. Allow at least four weeks. Performance Max tests need a minimum four-week window to accommodate learning and delivery stabilization. Avoid ending the experiment because of an encouraging or alarming interim swing.
    7. Apply only the supported lesson. If a complete asset set wins, you have evidence for the set, not proof that every component in it is superior. Keep the winning direction and use the next experiment to isolate the headline, image, or video question that remains.

    The distinction between an asset report and an asset experiment matters. Reporting helps you find a question. A controlled experiment is what helps answer it. Replacing assets based only on descriptive labels may change the audience and delivery mix before you have learned whether the creative itself was responsible.

    Do not run a test merely to keep the account active. A useful challenger represents a meaningful alternative: a different message, visual argument, proof point, or format. Small cosmetic changes may produce a winner, but they often leave you without a reusable insight for the next campaign.

    Use Demand Gen for intentional audience expansion

    Performance Max creative optimization and Demand Gen expansion solve different problems. If your real goal is to reach people beyond an immediate search query, repeatedly changing Performance Max assets may be an indirect way to pursue it. Demand Gen is designed around the user rather than the keyword and can distribute image or video creative across YouTube, Discover, and Gmail.

    This changes the optimization question. Search campaigns react to expressed demand. Demand Gen asks which audience, creative story, and Google-owned surface can create or develop interest. Its goal is clicks or conversions rather than the impression or view objectives commonly associated with video advertising.

    Build the audience around one reason for inclusion

    Demand Gen supports several audience approaches:

    • Remarketing for people who have already interacted with the business.
    • Lookalike audiences for reaching users who resemble existing converters.
    • In-market, life event, and affinity segments for interest and behavior-based expansion.
    • Detailed demographics when the offer is relevant to defined demographic characteristics.
    • Custom segments based on the search terms, websites, or apps associated with the intended audience.

    Give each audience a clear rationale. A segment called “high intent” is not useful documentation unless you can state what behavior or characteristic earned that label. Keep in mind that combined segments are not compatible with Demand Gen, and audience exclusions are limited to your data segments. Build the test around the targeting controls the campaign actually supports rather than importing a structure from another campaign type.

    Match the test structure to your constraint

    Your first Demand Gen campaign should answer a narrow question that matters to the business:

    • If you are working with $5 to $40 per day: Keep the structure simple. A practical starting test combines the Google Engaged remarketing audience with a Custom Segment based on top-performing search terms. Treat that range as a test constraint, not a promise of sufficient volume or a universal budget recommendation.
    • If you run ecommerce campaigns: Compare feed-backed product advertising with non-feed lifestyle creative. Demand Gen can use a Google Merchant Center feed, while its standard image, carousel, and video formats let you test whether the product itself or the surrounding story is the stronger route to action.
    • If you have enough budget for sustained audience development: Assign distinct jobs to in-market, life event, demographic, or affinity audiences instead of combining every prospect into one expansion pool. An always-on structure is useful only when each audience has a reason to exist and a business outcome by which it can be judged.

    Start with the relevant Google-owned channels enabled when you need to learn where the idea travels, then use channel segmentation and placement reporting to decide what belongs in the next iteration. If you already know that a channel cannot support the campaign’s format, audience, or objective, scope it out deliberately. Channel control should follow the campaign brief, not a blanket belief that more inventory is always better.

    Keep creative and audience questions separate when possible. If you test a new audience with a new video, new images, and a different offer, you are testing an entire go-to-market package. That can be appropriate when the package is the decision. It is the wrong design when you need to know whether the audience itself is viable.

    Key takeaways

    • Define one business outcome, one conversion definition, one campaign role, and one decision metric before adjusting automation.
    • Diagnose measurement, channel, audience, creative, and landing-page continuity in that order so you change the layer that is actually failing.
    • Use Performance Max asset reporting to form hypotheses and the asset A/B testing beta to test them.
    • Hold common assets and unrelated campaign settings steady during a Performance Max experiment.
    • Run Performance Max asset experiments for at least four weeks so learning and delivery have time to stabilize.
    • Use Demand Gen when the job is audience-led expansion across YouTube, Discover, and Gmail, then segment channel, placement, audience, and asset performance.
    • Make every optimization produce a reusable lesson, not merely a different dashboard result.

    Choose one campaign for your next optimization cycle. Write its job in a sentence, identify the first failing layer, and log one hypothesis. If the question is creative, build a controlled Performance Max asset experiment. If the question is audience expansion, scope a Demand Gen test around one audience and one outcome. Your next change should buy information as well as performance.
    References

  • Google Ads and Measurement Updates: A Practical Action Plan

    Google Ads and Measurement Updates: A Practical Action Plan

    Your Google Ads account can look healthy while the business behind it becomes harder to explain. A Vehicle Ad can generate a phone call before the shopper visits your site, tag traffic can move through your first-party domain, and a mid-month budget edit can change spending behavior immediately.

    If your reporting still assumes a neat click-to-pageview-to-form path and evenly distributed daily spend, those changes create blind spots. The practical response is to manage calls, tagging and budgets as parts of the same revenue system: capture the demand, preserve the measurement signal and control what you spend to acquire it.

    Treat the updates as one revenue system

    These changes sit in different Google interfaces, but they affect one connected workflow. Vehicle Ads determine how a prospect reaches you. Google Tag Gateway affects how reliably eligible tag requests travel from your site to Google. Campaign budgets determine how much demand you can pursue and when.

    A failure at any point can distort the others. More calls are not valuable if nobody answers them. More observable events are not useful if duplicate or poorly defined conversions inflate the count. A larger budget is not productive if finance cannot reconcile the projected spend or the sales team cannot handle the resulting demand.

    Key takeaways

    • Treat a call from an ad as the start of a measurable sales path, not proof of a sale.
    • Use first-party tag routing to strengthen signal transport, but keep consent, event definitions and data quality controls separate.
    • Model a budget change before editing the campaign because Google can alter the applicable spending limit and pacing from the change date forward.
    • Give marketing, analytics, sales operations and finance a shared definition of success before you scale any of these changes.

    The unifying document should be a measurement contract. For every important event, write down what happened, which system recorded it, who owns the next step and which business decision the event supports. That short exercise exposes gaps that a polished dashboard can hide.

    Make click-to-call accountable past the tap

    A shopper calls beside a vehicle as a glowing signal links the phone to attribution checkpoints and a sales handshake.

    Google’s click-to-call capability for Vehicle Ads reduces the distance between a high-intent vehicle search and a live conversation with a dealership. It also moves part of the conversion experience away from the landing page and into an operational channel that paid-media teams do not always control.

    That changes the question you need to answer. It is no longer enough to ask whether the ad produced a call. You need to know whether the call connected, whether the caller was a plausible buyer, whether an appointment or useful follow-up resulted, and whether the opportunity eventually generated revenue.

    Build the call conversion chain

    1. Capture the ad interaction. Retain the campaign, ad group, advertised vehicle and other available acquisition context. Do not promise fields that your advertising, phone and CRM systems cannot actually pass between them.
    2. Record the operational outcome. Distinguish an initiated call from an answered call, a missed call, a disconnected attempt and a completed callback.
    3. Classify the sales outcome. Use a small, enforced set of CRM statuses such as unqualified, qualified, appointment booked, follow-up required, closed lost and sold.
    4. Attach value at the appropriate stage. A raw call and a completed sale should not carry the same meaning. If value is unavailable, report the outcome honestly instead of inventing a revenue proxy.
    5. Reconcile the systems. Compare ad-generated call records with phone-platform and CRM outcomes. Unmatched records should enter an exception queue rather than silently disappearing from reporting.

    A simple metric ladder makes the handoff visible:

    MetricCalculationWhat it helps you notice
    Connection rateAnswered calls divided by initiated callsRouting, staffing or phone-system friction
    Qualification rateQualified calls divided by answered callsWhether the ads are attracting plausible buyers
    Appointment yieldAppointments divided by qualified callsHow effectively staff convert intent into a next step
    Sales yieldCompleted sales divided by qualified callsWhether call volume is producing business value

    Do not collapse that ladder into a single conversion count. If initiated calls rise while the connection rate falls, bidding is not the first problem to solve. Check opening hours, routing rules, queue coverage and missed-call ownership. If calls connect but few qualify, inspect campaign targeting, inventory alignment and the expectations set by the ad. If qualified calls stall after the conversation, the failure sits in sales follow-up rather than media delivery.

    Give every call an operational owner

    Before enabling call-led demand broadly, document who handles each state:

    • Which team answers during advertised business hours.
    • Where a call goes when the primary recipient is unavailable.
    • Who reviews missed and abandoned calls.
    • How callbacks are associated with the original lead instead of counted as unrelated opportunities.
    • Which CRM field records qualification, appointment and sale outcomes.
    • Who audits missing outcomes and how often that review occurs.

    This is not administrative detail. Once the ad itself becomes a direct contact point, call handling becomes part of campaign performance. Media optimization cannot compensate for unanswered demand, and a sales team should not be judged on lead quality when the acquisition data cannot be connected to actual conversations.

    Use Tag Gateway to strengthen transport, not excuse data design

    Google Tag Gateway now has a beta deployment path through Google Cloud Platform. The workflow is available from Google Tag Manager and Google tag settings and uses Google Cloud’s Global External Application Load Balancer to route eligible tag traffic through your first-party domain before forwarding it to Google.

    The architecture places Google’s tagging infrastructure behind a same-site, same-origin first-party host. It is intended to improve signal quality and make measurement more resilient to some ad-blocking behavior and browser restrictions, including Apple’s Intelligent Tracking Prevention. Treat those benefits as the purpose of the design, not a guarantee that every missing signal will return.

    The distinction matters. A gateway can improve the route a request takes. It cannot repair a badly named event, an accidental duplicate, a broken data-layer value or a conversion that has no relationship to a business outcome. It also does not turn data collection into permission. Your consent rules, disclosure obligations, retention controls and internal governance still apply when traffic uses a first-party host.

    Deploy it as a measured infrastructure change

    1. Map the current request path. Record which Google tags load, where they load, which events they send and which teams own the site, tag manager, cloud infrastructure and analytics configuration.
    2. Capture a baseline. Preserve representative event counts, conversion counts, duplicate rates and known gaps before changing the route. Without a baseline, a higher count after deployment can be mistaken for an improvement even when it comes from duplication.
    3. Choose a contained scope. Because the Google Cloud integration is in beta, begin where you can validate the route and reverse the change without disrupting every property or campaign.
    4. Use the supported setup path. Complete the workflow from Google Tag Manager or Google tag settings and review the External Application Load Balancer configuration created in Google Cloud.
    5. Validate the route. Confirm that intended requests use the first-party host and reach the expected destination. Also verify that unrelated application traffic is not being caught by the routing rules.
    6. Test event behavior. Compare event names, parameters and conversion totals before and after the change. Investigate missing events, unexpected increases and duplicate conversions before calling the deployment successful.
    7. Document ownership and rollback. Record the hostname, routing configuration, deployment owner, monitoring owner and the safe procedure for returning to the previous path.

    The new GCP workflow reduces deployment friction for teams already operating in Google Cloud. Cloudflare had been the only automated option identified for Google Tag Gateway, while other content delivery networks required manual setup. Lower setup friction is useful, but it should not remove technical review. A one-click provisioner can create infrastructure; it cannot decide whether your event model is correct.

    Use reconciliation, not event volume, as the success test

    Measure the gateway at three levels. First, confirm transport health: intended requests use the expected first-party route and complete successfully. Second, confirm analytics integrity: event names, parameters and deduplication behavior remain correct. Third, reconcile business outcomes: the conversions used for bidding and reporting still agree with downstream lead, appointment, order or revenue records.

    An increase in observed events is only useful when you can explain it. The increase might represent recovered signal, but it might also expose a pre-existing implementation difference or introduce duplicate collection. Keep the classification open until the analytics and business records agree.

    Model every budget edit before you make it

    An operations specialist compares stable and surging token flows in a tabletop simulation before adjusting a budget control.

    A Google Ads average daily budget is not a strict daily ceiling. Google may spend up to twice that amount on a high-traffic day while applying the relevant monthly charging limit. That makes smooth daily pacing a planning assumption, not a platform promise.

    A mid-month budget change recalculates the plan from the edit date forward. The applicable monthly limit reflects the old budget for the earlier period and the new budget for the later period. The potential daily overdelivery threshold adjusts immediately, and Google re-optimizes pacing for the remaining time.

    This is why simply multiplying the new daily amount by the days left can give you the wrong expectation. It ignores what has already been spent, the earlier budget period and the platform’s pacing behavior.

    Use three projections for three different questions

    ControlQuestion it answersHow to use it
    Budget reportWhat spend is Google currently projecting?Review the campaign’s budget history, change marker and projected billing outcome.
    Performance PlannerWhat performance trade-off might a different budget create?Compare budget scenarios against projected clicks, conversions and other relevant outcomes.
    Manual calculationDoes the platform projection fit the business constraint?Subtract cost to date from the revised period goal, then divide the remainder by the days left as a planning guide.

    The manual check is deliberately simple:

    Remaining allowable spend = revised period goal minus cost to date.

    Planning pace = remaining allowable spend divided by the days left in the period.

    That pace is a finance guardrail, not a guarantee that Google will spend the same amount each day. Compare it with the budget report. If the platform projection does not fit the business constraint, resolve the difference before saving the edit.

    Performance Planner answers a separate question. A budget reduction may meet the spending requirement while also reducing projected clicks or conversions. Put both effects in the approval request. Saying that a change saves money without showing the likely opportunity cost leaves the decision incomplete.

    Use a repeatable edit protocol

    • Before the edit: capture cost to date, the current budget report projection, the relevant Performance Planner scenario and the revised business target.
    • At the edit: record the old budget, new budget, campaign, timestamp, approver and reason. Google Ads reporting can display a gray triangle at the change date, but your internal record should explain why the change happened.
    • After the edit: reopen the budget report and verify that the revised projection matches the intended direction. Do not rely on the number entered in the budget field as proof.
    • During the remaining period: compare actual cost with the remaining allowable amount and watch conversion quality. A campaign can underspend because demand, targeting or return-on-ad-spend constraints limit delivery, even when budget is available.
    • At period close: reconcile billed spend, reported performance and the approval record so the next planning cycle begins with an explainable baseline.

    Manage campaign total budgets separately from average daily budgets. Campaign total budgets aim to spend a defined amount by an end date and do not use the same daily-cap model. They can suit bounded promotional or video activity, but their end-date orientation makes them a different planning instrument, not a shortcut around daily-budget controls.

    Run the rollout as a controlled operating change

    The cleanest implementation assigns an owner and evidence standard to every workstream:

    WorkstreamPrimary ownersEvidence required before expansion
    Vehicle call conversionPaid media and sales operationsCalls can be connected to answer, qualification, appointment and sales outcomes.
    First-party tag routingAnalytics, web engineering and cloud infrastructureRequests use the intended route without unexplained loss, duplication or parameter changes.
    Budget controlPaid media and financeThe budget report, performance scenario and manual constraint check tell a coherent story.
    Business reconciliationMarketing operations and the relevant revenue ownerAdvertising conversions can be compared with downstream CRM or commerce outcomes.

    Start by writing the measurement contract for a contained campaign or property. Preserve the current baseline. Make the scoped change, then reconcile platform events with operational and financial outcomes. Expand only after the team can explain both gains and discrepancies.

    Your shared dashboard does not need every available Google Ads field. It needs the fields that reveal a broken handoff: spend to date, projected spend, the latest budget change, calls initiated, calls answered, qualified opportunities, appointments, sales outcomes, expected tag events, received tag events and unresolved exceptions.

    At your next change window, trace a real prospect from the ad through the call or site event, into the downstream business record and back to the budget decision. Wherever that trace breaks is where you should work next.

    References

  • How to Build a Year-End PPC Report Leadership Can Use

    How to Build a Year-End PPC Report Leadership Can Use

    Your year-end PPC report has to answer a harder question than what happened. Leadership wants to know whether paid media created enough business value, what changed that value, and which decisions the evidence supports for the coming year.

    If your deck looks like a stack of monthly reports, the important story will disappear inside campaign detail. A year-end review has a different audience and a broader strategic purpose than a routine performance check-in. Treat it as a decision brief supported by analysis, not an archive of everything the account did.

    Define the audience and the decision before opening a dashboard

    Leadership is not one audience. A finance leader may care about efficiency, risk, and the reliability of attributed revenue. A sales leader may care about qualified lead volume and pipeline contribution. A chief executive may want to know whether paid media can support the company’s growth plan. The same campaign data has to be organized differently for each decision.

    If you do not know who will receive the report, ask your primary stakeholder before building it. Get direct answers to these questions:

    • Who will read the report, attend the presentation, or approve the resulting plan?
    • What decision should they be able to make after reading it?
    • Which business outcome do they consider the clearest definition of success: revenue, qualified leads, completed conversions, or another agreed outcome?
    • Which target, commitment, or concern is already on their mind?
    • Where will they expect detail, and what can safely move to an appendix?

    Turn those answers into a reporting brief written as a single sentence: this report is for [audience], who need to decide [decision], using [business outcome], within [commercial or operational constraint]. That sentence becomes an editing rule. A chart belongs in the main report only if it helps the audience understand the outcome, evaluate a cause, assess a risk, or make the named decision.

    Tailor the depth, not the facts. Executives should see the same definitions, totals, and conclusions as the channel team. Put the concise decision narrative in the main report and retain campaign tables, test logs, query detail, and methodology in an appendix. This gives detail-oriented stakeholders somewhere to verify the work without forcing everyone else through it.

    Build the executive summary around business outcomes

    Draft the executive summary before assembling the full deck, then rewrite it after the analysis is complete. The early draft forces you to decide what the report is trying to prove. The final rewrite removes claims the detailed evidence did not support.

    A useful summary follows a clear sequence:

    • Outcome: State the investment and the primary business result.
    • Context: Show how that result compared with the agreed target, the prior year, and any relevant external benchmark.
    • Drivers: Name the few factors that materially changed the outcome.
    • Risk: Surface the largest weakness, uncertainty, or measurement limitation.
    • Decision: State the recommendation and the approval, tradeoff, or direction leadership needs to provide.

    You can use this fill-in structure to test the summary: paid media produced [business result] from [investment], finishing [above or below target] and [up or down year over year]. The main drivers were [drivers]. The largest constraint or uncertainty was [risk]. We recommend [action], and leadership needs to decide [decision].

    Separate outcome, efficiency, scale, and diagnostic metrics

    Metric overload usually starts when every measure is treated as equally important. Give each metric a job instead:

    Metric layerTypical measuresQuestion it answers
    Business outcomeRevenue, qualified leads, completed conversionsWhat value did paid media create?
    EfficiencyReturn on ad spend, cost per acquisition, cost per qualified leadWhat did that value cost?
    ScaleSpend and total outcome volumeHow much did the program produce at the achieved efficiency?
    DiagnosticClick-through rate, cost per click, impression share, conversion rateWhy did an outcome or efficiency measure move?

    Lead with the business outcome. Use efficiency and scale to describe the tradeoff behind it. Bring a diagnostic metric into the summary only when it explains a material change. A higher click-through rate is not an executive result if revenue, qualified lead volume, or another agreed outcome did not improve.

    Be precise about what a conversion represents. If the account counts form submissions, calls, purchases, and secondary actions, do not roll them into an unexplained conversion total. If lead quality or offline revenue is unavailable, say so. Platform-attributed activity should not be presented as verified commercial value when the connection has not been measured.

    Give each comparison a distinct job

    Leadership needs context because an isolated total cannot show whether performance was good, weak, or simply different. Year-over-year results, target attainment, and industry benchmarks answer different questions:

    • Year over year shows direction and the size of the change from the previous period.
    • Target attainment shows whether the program delivered the commitment the business planned around.
    • An industry benchmark can add external context when its market, metric definition, and methodology are genuinely comparable.

    Do not use a favorable benchmark to distract from a missed internal target. Do not use year-over-year growth without disclosing a major change in budget, tracking, conversion definitions, attribution settings, product mix, geography, or brand activity. If the comparison is not like for like, explain the difference beside the result rather than hiding it in a footnote.

    Explain performance through causes, tests, and context

    An overhead arrangement of a magnifying lens, paired test cards, seasonal blocks, and connecting threads around a central marker.

    The detailed section should prove the executive summary. It is not a chronological tour through platforms, campaigns, and months. Organize it around the questions leadership will naturally ask: why did the result change, what did the team control, what happened outside the account, and what should the business do differently?

    Use a claim-evidence-decision chain

    Build every major finding with the same chain:

    1. Claim: State what materially changed.
    2. Evidence: Show the business outcome and the relevant comparison.
    3. Driver: Identify the account, market, measurement, or operational factor connected to the change.
    4. Implication: Explain why the change matters beyond the metric itself.
    5. Decision: Recommend what to continue, stop, change, investigate, or approve.

    Write slide headings as conclusions rather than topics. A heading such as Nonbrand growth added volume but reduced efficiency tells leadership what to inspect. A heading such as Campaign performance makes them find the conclusion themselves. Use the stronger form only when the underlying data supports both sides of the statement.

    Apply more scrutiny to anything labeled a top performer. Ask whether it contributed materially to the business outcome, can be repeated, has room to scale, and relies on trustworthy measurement. A branded campaign may look exceptionally efficient because it captures existing demand. A small campaign may have an attractive rate but too little volume to change the business result. Show how resources were allocated and whether the strongest areas can absorb more investment without assuming their past efficiency will continue unchanged.

    Report tests as decisions, not activities

    A test log becomes useful to leadership when it shows how uncertainty was reduced. For each material test, record the decision question, hypothesis, change made, observed outcome, confidence or limitation, and next action. Tests that did not improve performance still matter when they eliminate an option or expose a measurement problem. A list of experiments with no resulting decision is only an activity report.

    Trends deserve the same discipline. Connect a trend to the affected business outcome, show when it appeared, and distinguish a durable pattern from a temporary movement. Top-performing assets, resource allocation, tests, and trends belong in the report when they explain the year or change the next decision.

    Separate external influence from convenient explanation

    Digital platform changes, competitor behavior, demand shifts, and broader economic conditions can affect PPC performance. They should not become catch-all explanations for a weak result. Timing alone does not establish cause.

    Use a simple evidence ladder:

    • Confirmed impact: The external change has a plausible mechanism and a visible effect in your own account or business data.
    • Plausible influence: The timing and mechanism fit, but the available data cannot isolate the effect.
    • Background context: The event may matter to the market, but you cannot connect it to the reported result.

    For every external factor you include, explain the event, the mechanism through which it could affect demand or media economics, the evidence visible in your data, and the response available to the team. If you cannot complete that chain, label the factor as context rather than cause.

    Address unfavorable performance directly. State the size and location of the problem in the terms already used by the business, explain what is known and unknown, and show the corrective decision. Leadership is more likely to distrust a buried weakness than a clear limitation with an accountable response.

    Turn the retrospective into next year’s decision menu

    Hands arrange three planning pathways made from blank cards, budget tokens, and milestone blocks on a boardroom table.

    The forward-looking section should not be a wishlist of campaign ideas. It should connect evidence from the completed year to choices leadership can approve, reject, sequence, or constrain.

    Leadership decisionEvidence to presentShape of the recommendation
    How much should we invest?Business outcome, efficiency, target gap, marginal performance, and capacity constraintsA budget position with assumptions, downside controls, and the conditions for releasing more investment
    Where should funding move?Performance by meaningful segment, scalability, strategic coverage, and measurement confidenceA reallocation tied to expected business contribution, not merely the lowest platform-reported cost
    Should growth or efficiency take priority?The observed tradeoff between outcome volume, cost, and commercial qualityAn explicit priority with guardrails for the measure leadership is not optimizing first
    What should be tested?Unresolved assumptions, performance constraints, and opportunities identified during the yearA ranked test agenda with a decision question, success signal, and action attached to each test
    What should be fixed in measurement?Missing offline outcomes, inconsistent conversion definitions, attribution limitations, or data gapsA measurement priority that explains which future decisions will become more reliable

    Do not recommend a budget increase solely from platform-attributed conversion value when revenue identity, lead quality, or incrementality remains uncertain. The financial downside is straightforward: the business can pay more for outcomes that look valuable in the ad platform but do not produce equivalent commercial value. State the uncertainty, propose the measurement work, and use spending guardrails until the evidence is strong enough.

    Write each recommendation in a decision-ready form: because [evidence], we recommend [action]. We expect it to affect [business outcome]. The principal risk is [risk]. We will monitor [signal] and change course if [trigger] occurs. The owner is [role].

    Use scenarios without pretending the forecast is certain

    A fixed plan can create false confidence when demand, competition, pricing, or platform conditions may change. Present a base case grounded in current evidence, an upside case tied to a specific favorable signal, and a downside case tied to a specific risk. Each case should name the signal that identifies it and the action the team will take.

    This is the practical value of a decision framework built to adapt as conditions change. Leadership does not need a claim that every outcome is predictable. It needs confidence that the team knows what to watch, what authority it has, and when a new decision must return to the leadership table.

    Close the planning section with a decision register. Separate approvals needed now, choices deferred until a named signal appears, actions already within the team’s authority, and dependencies owned elsewhere. Assign an owner to every next step. Without an owner or decision point, a recommendation is only commentary.

    Run a leadership review before you send it

    Review the report through the eyes of an executive who is interested but skeptical. They should not have to reconcile totals, decode channel vocabulary, or search the appendix to discover a material problem.

    Use this final quality check:

    • Every chart identifies its data source, reporting period, metric definition, and relevant scope.
    • Comparisons use consistent conversion actions, attribution assumptions, currency, business scope, and time periods, or disclose where they do not.
    • Actual results, targets, forecasts, and external benchmarks are labeled as different things.
    • The executive summary contains the primary outcome, the main drivers, the largest limitation, the recommendation, and the required decision.
    • Material negative results appear early and include what is known, what remains uncertain, and what happens next.
    • Every diagnostic metric supports a business-level conclusion rather than appearing because it is available.
    • Recommendations name an owner, a decision trigger, a risk, and the outcome they are intended to affect.
    • Technical detail needed for verification remains available in an appendix.

    Then ask a colleague who did not build the analysis to read only the executive summary, headings, and recommendations. Ask them to state the year’s result, the reason it changed, the largest uncertainty, and the decision leadership must make. Any answer they cannot give points to a gap in the report’s structure.

    Key takeaways

    • Design the report for a named audience and a specific leadership decision.
    • Lead with business outcomes; use channel metrics to explain them.
    • Compare performance with the prior year, the agreed target, and only genuinely relevant external benchmarks.
    • Build every major finding from a claim, evidence, driver, implication, and decision.
    • Distinguish confirmed external impact from plausible influence and background context.
    • Convert recommendations into choices with assumptions, risks, triggers, owners, and measurement needs.

    Start your next report with the decision sentence before exporting any data. Pull only the evidence needed to validate, challenge, or qualify that sentence, and move the rest to the appendix. That discipline gives leadership a report it can use to allocate money, set priorities, and hold the next plan accountable.

    References

  • How to Build an AI-Driven Paid Search Operating Model

    How to Build an AI-Driven Paid Search Operating Model

    You can automate nearly every visible part of paid search and still make the account worse. AI will produce more copy, audience ideas, campaign variants, and reports than your team can review. If the underlying intent signal is weak, that extra output simply scales waste.

    A useful AI-driven operating model does something more disciplined. It converts conversational intent into campaign decisions, accelerates controlled creative testing, aligns each promise with the destination page, and measures whether the resulting customers are actually worth more.

    Start with the decision behind the search

    A conventional search query often captures only a fragment of the buyer’s situation. A conversation can expose the goal, constraints, comparison criteria, objections, and urgency surrounding that query. Conversational search can also create multiple relevant advertising opportunities from a detailed exchange as the user’s needs become clearer.

    Do not respond by treating entire conversations as a larger keyword list. Convert the context into an intent record your campaign team can use:

    • Situation: What is happening in the buyer’s world?
    • Desired outcome: What are they trying to accomplish?
    • Constraints: Which limits involve budget, timing, compatibility, location, policy, or skill?
    • Decision state: Are they exploring, comparing, validating, or ready to act?
    • Objection: What could prevent the next step?
    • Required proof: Do they need specifications, pricing, evidence, credentials, availability, or reassurance?
    • Next useful action: Which conversion would genuinely help them progress?

    Suppose a prospective student searches for an online master’s degree. That phrase gives you a category. A fuller interaction might reveal that the person works full time, needs a recognized credential, is comparing total cost, and cannot attend daytime classes. Those details should change the ad message, landing-page evidence, audience treatment, and conversion action. Repeating the broad phrase more often will not do that.

    Organize campaigns around the decision state as well as the topic. Exploratory demand needs orientation. Comparison demand needs explicit differences and trade-offs. Validation demand needs proof. Action-ready demand needs a clear offer and minimal friction. The journey will not always be linear, but these distinctions stop you from serving the same generic promise to everyone.

    Begin with search terms that converted, consumed spend without producing qualified outcomes, or repeatedly triggered exclusions. Rewrite each meaningful cluster as an intent record. If you cannot identify the likely decision, constraint, and next action, the cluster is still too vague for AI-generated personalization.

    Build a controlled path from AI insight to campaign

    Abstract conversational signals move through a series of human-controlled review gates before becoming organized campaign components and matching destination pages.

    The safest workflow gives AI a narrow responsibility at each stage. It also preserves a reviewable record of why an audience, message, or destination was chosen.

    1. Define the business outcome. Name the event that creates value: a completed sale, qualified lead, accepted application, booked consultation, or another verified result. Do this before generating assets.
    2. Assemble the permitted context. Supply the offer, landing-page copy, approved claims, exclusions, brand rules, past campaign outcomes, and known audience questions. Remove personally identifying information and use only data you are authorized to process.
    3. Classify demand by decision logic. Ask AI to group queries or themes by situation, desired outcome, constraint, objection, and decision state. Require it to flag ambiguity instead of forcing every input into a confident category.
    4. Turn each intent group into a campaign brief. Specify the audience problem, promise, proof, prohibited claims, destination, conversion action, and measurement rule.
    5. Generate bounded variations. Let AI vary a defined element such as the benefit, proof point, call to action, visual treatment, or voice. Do not ask it to redesign the audience, offer, message, and destination simultaneously.
    6. Validate the destination. Confirm that the landing page visibly supports the ad’s promise and that its structured data accurately describes the same entities, offer details, and attributes.
    7. Launch with a budget ceiling and rollback condition. Record the baseline, approved spend limit, primary outcome, diagnostic metrics, and the condition that will pause or reverse the change.

    A reusable generation brief can stay compact: Audience situation: [context]. Decision state: [state]. Promise: [approved benefit]. Proof: [page-supported evidence]. Variable to test: [single element]. Prohibited claims: [limits]. Destination: [matching page]. Primary outcome: [qualified business event].

    Structured data belongs in this workflow, but it is not advertising code and cannot rescue a weak offer. Its role is to make the page’s meaning more explicit. The visible page, markup, ad, and conversion action should describe the same thing. If eligibility, availability, or a limitation matters to the decision, put it in the visible content rather than hiding it only in markup.

    Use the same intent labels across paid search, paid social, creative production, landing pages, and reporting. Shared labels let you see whether a message works because it addresses a particular decision or merely because one channel received cheaper traffic.

    Use generative AI to multiply tests, not brand risk

    An AI system generates many abstract creative variants while a human reviewer filters them before selected versions proceed to matching landing pages.

    Generative tools can shorten the path from a script to storyboards, creative variations, voiceovers, and localized executions. They can also help maintain tone and pacing across repeated production work. That is production leverage, not evidence that the resulting creative will persuade anyone.

    The common failure is to generate many variations without giving each variation a job. The account receives more ads, but the team learns less because several elements changed together. A disciplined test should follow these rules:

    • Ask one commercial question at a time, such as whether proof-led copy produces more qualified actions than convenience-led copy.
    • Keep the offer, audience definition, destination, and conversion action fixed unless one of them is the stated variable.
    • Generate within approved claims and brand rules. Require human review for prices, guarantees, comparisons, regulated language, eligibility, and culturally sensitive material.
    • Name every asset by intent group, hypothesis, variable, and version so the result can be traced to the brief that created it.
    • Use engagement as a diagnostic signal, not the final verdict. A stronger click-through rate with weaker lead quality is not a win.
    • Record what the result changes. If either outcome would lead to the same campaign decision, the test is not answering a useful question.

    Write a test brief that another person can audit

    Before production, document the hypothesis, target intent, fixed elements, test variable, primary business outcome, secondary diagnostics, observation window, exclusions, and decision rule. The observation window and decision rule should reflect your normal conversion lag and traffic volume; choosing them after seeing performance invites a convenient interpretation.

    AI-assisted analytics can connect creative features with engagement patterns quickly, but correlation does not establish which feature caused the result. Use those patterns to form the next controlled test. Do not let a dashboard turn visual coincidence into a budget decision.

    Personalization also has a boundary. When targeting Gen Z, utility and authenticity are especially important. Personalize around the need the person expressed, not around a surprising personal detail inferred from unrelated behavior. An ad can be technically relevant and still feel invasive.

    Measure whether AI improves the unit economics

    Microsoft has reported a thirteen-fold increase in return on ad spend when people interacted with Copilot before searching. Treat that as a platform-reported signal, not a forecast for your account. A plausible explanation is that a person who has already clarified a need through conversation reaches search with stronger intent. That cohort may be fundamentally different from someone entering an unassisted, ambiguous query.

    Test the mechanism inside your own account. Keep the conversion definition, attribution setting, promotion, geographic scope, and brand versus non-brand treatment comparable. Separate conversationally informed demand from the existing baseline when the platform and campaign setup allow it. Otherwise, an apparent AI lift may simply reflect a different audience mix.

    Add internal measures that expose quality and waste. The names matter less than consistent definitions:

    MeasureHow to define itWhat to noticeWhat to do next
    Revenue ROASAttributed revenue divided by ad spendRevenue can look healthy while margin or customer quality deterioratesPair it with a profit or quality measure
    Qualified conversion rateConversions meeting the business qualification divided by total recorded conversionsRising conversion volume with falling qualification means the system is optimizing toward an easy eventReturn verified quality data to campaign reporting where possible
    Search-term waste rateSpend assigned to irrelevant or ineligible query themes divided by search spendA high rate reveals weak intent classification, exclusions, or match controlRefine intent groups and negative themes before expanding reach
    Intent-to-page completionCompletion of the intended action for each intent group and destinationStrong ad engagement with weak completion often signals a promise-to-page mismatchCorrect the destination or narrow the ad promise
    Creative learning yieldCompleted tests that produced a clear campaign decision divided by completed testsMany inconclusive tests indicate uncontrolled variation or weak hypothesesReduce simultaneous changes and sharpen the decision rule

    Automation can spend against the wrong objective quickly. Preserve account-native budget controls, exclusions, approval steps, and an accessible previous version. Do not shift substantial budget merely because AI-assisted creative generated more impressions, clicks, or engagement. Move it when the agreed business outcome improves without unacceptable deterioration in quality, margin, or waste.

    Key takeaways

    • Conversational demand is valuable because it reveals the decision context around a query, not because it gives you longer keywords.
    • Translate that context into intent records containing the situation, outcome, constraints, decision state, objection, proof, and next action.
    • Give AI bounded production tasks and preserve human approval for claims, eligibility, pricing, cultural adaptation, and brand judgment.
    • Change a defined creative element at a time so each test can produce a usable decision.
    • Keep ads, landing-page content, structured data, and conversion actions aligned around the same promise.
    • Evaluate qualified outcomes, waste, profit, and learning quality rather than counting how much content the system produced.
    • Treat platform-reported performance lifts as hypotheses to validate under your own audience mix, attribution settings, and business economics.

    Your next move should be narrow. Choose a high-spend, high-ambiguity query theme, turn it into a clear intent record, build an aligned ad and destination, and compare it with the existing treatment under the same outcome definition and budget controls. Expand to the next intent cluster only when the first change produces better customers, not merely more activity.

    References

  • Google Ads AI Automation: How to Keep Advertiser Control

    Google Ads AI Automation: How to Keep Advertiser Control

    Your Google Ads campaign can hit its platform target while becoming less useful to the business. Revenue may rise as margin falls. Conversion volume may look stable while lead quality weakens. Spending may accelerate into queries you would never have chosen yourself.

    You do not regain control by trying to outbid the algorithm auction by auction. You regain it by deciding what the system may optimize, where it may explore, which evidence you will inspect, and what conditions require an override. That is the operating model you need as AI Max, Smart Bidding, and AI Overview placements take on more of the execution.

    Key takeaways

    • Google Ads automation has moved advertiser control upstream. Your main levers are the conversion goal, assigned value, campaign boundaries, budget, target, targeting eligibility, and intervention rules.
    • Exact and broad match keywords can trigger ads above or below an AI Overview, but ads within an AI Overview require broad match or keywordless targeting. An exact-match version of a keyword does not block its broad-match counterpart from that placement.
    • A Smart Bidding learning period typically lasts seven to 14 days. Learning that continues beyond two weeks is a diagnostic trigger, especially when conversion volume is low or frequent edits keep resetting the process.
    • Judge automation against profit, qualified demand, cash constraints, and downstream customer value. Platform CPA or ROAS alone cannot represent business economics you have not supplied.

    Control the business inputs before you automate the bids

    A person adjusts gates controlling business-value, budget, inventory, and location symbols before they enter an automated bidding engine.

    Target CPA, Target ROAS, Maximize Conversions, and Maximize Conversion Value use machine learning to predict the likelihood or value of a conversion and adjust bids during each auction. They can process signals such as device, location, and time of day at a scale no manual workflow can match. But auction-time sophistication does not give the system access to business context you never encoded.

    This creates an important distinction: a bidding target is not the same thing as a business objective. A 400% ROAS target describes attributed revenue relative to advertising cost. It does not tell Google whether that revenue came from a high-margin product, whether the cash arrives soon enough, or whether the sales team can profitably handle the resulting leads.

    Consider two $100 orders. If one product carries a 60% margin and the other carries a 15% margin, revenue-only reporting assigns both orders the same value even though their economic contribution is very different. An algorithm asked to maximize that value can be mathematically successful and commercially wrong. Margin-based segmentation and profit-relevant reporting are what close that gap.

    Before you increase automation, write a short control brief for the campaign. It should answer five questions:

    <!– wp:list {
  • A Practical System for Ecommerce Conversion and Ad Performance

    A Practical System for Ecommerce Conversion and Ad Performance

    Your ad account can look healthy while your store quietly wastes the demand you are paying to create. A strong click-through rate cannot rescue a difficult checkout, and a high account-wide ROAS can hide a catalog in which one familiar product consumes most of the budget.

    The fix is a sequence, not another disconnected app or campaign adjustment. Remove purchase friction first. Recover shoppers who have already shown intent. Then allocate advertising spend according to product-level performance. That order makes the numbers easier to interpret and keeps automation from optimizing around a broken buying experience.

    Key takeaways

    • Audit the complete mobile path from ad click to successful payment before increasing traffic.
    • Prioritize digital wallets, then evaluate buy now, pay later against your margins and customer needs.
    • Use email and SMS recovery only with the consent and controls required for each channel and jurisdiction.
    • Separate proven products, new or low-data products, and products consuming traffic without adequate return.
    • Review product assignments on a rolling cycle, but choose the window according to your sales volume rather than treating 14 days as a universal rule.

    Fix the purchase path before asking ads to work harder

    Generic shoppers follow a simplified mobile checkout path as obstacles, extra gates, and confusing branches are removed between a shopping basket and a delivery parcel.

    Start with the device on which the transaction actually happens. With 54.5% of holiday purchases happening on mobile, a phone is not a secondary quality-assurance case. It is often the main checkout environment.

    Do not audit that environment by opening the homepage and deciding that it looks acceptable. Follow the paid journey exactly as a shopper would:

    1. Open each high-spend ad on a real phone and record the promise, product, price, and offer shown in the creative.
    2. Confirm that the landing page immediately continues the same promise. If the ad promotes one product or use case, do not make the shopper search for it again.
    3. Add the product to the cart from a clean session so saved addresses, accounts, or payment details do not conceal friction.
    4. Start checkout and count the fields and decisions required before payment. Test every wallet that appears to be enabled.
    5. Place a test order. A visible payment button is not proof that authorization, confirmation, inventory handling, and order creation work.
    6. Repeat the path for the devices, browsers, and traffic sources that matter to your store. Record failures by stage rather than describing the whole journey as a conversion problem.

    Digital wallets such as Apple Pay, Google Pay, and PayPal reduce typing by reusing stored payment and delivery details. That matters on a small screen. Their relevance is not marginal: up to 64% of Americans use digital wallets as much as traditional payment methods, while 54% prefer using them more often. On Shopify, wallet and buy now, pay later functions can be added without custom development in many standard configurations.

    A wallet removes form friction; it does not repair a weak offer. If product-page engagement is poor, adding another payment method is unlikely to solve the underlying problem. Buy now, pay later can reduce the immediate price objection, but it should not be enabled solely because it might lift checkout completion. Review provider fees, refunds, returns, and contribution margin first. A higher conversion rate can still produce worse economics.

    Use your own historical baseline when reading the funnel. There is no universal healthy rate for every catalog, price point, or traffic mix. The pattern of the drop tells you where to investigate:

    Observed patternWorking hypothesisFirst actionPrimary measure
    Ads earn clicks, but few product views become cart additionsThe ad promise, landing page, product, or offer is mismatchedBuild a landing-page variant that continues the ad’s exact messageProduct-view-to-cart rate
    Cart additions are steady, but few shoppers start checkoutThe handoff creates uncertainty or extra effortReview the cart on mobile and make the next step and payment choices clearCart-to-checkout-start rate
    Checkout starts are steady, but purchases are weakPayment or data-entry friction is blocking completionTest wallet payments and evaluate whether buy now, pay later fits the order economicsCheckout completion rate
    Purchases are steady, but ROAS is weakSpend is reaching the wrong products or trafficRebuild product groups around performance rather than category aloneProduct-level ROAS and revenue
    One product absorbs most of the campaign budgetExisting winners are preventing new or less visible products from gathering evidenceGive proven, new, and traffic-without-return products separate treatmentSpend concentration and cohort-level ROAS

    This table is a hypothesis map, not an automatic diagnosis. For example, checkout completion can rise after you change campaign targeting because the new audience was easier to convert. That does not prove the checkout itself improved. Keep traffic allocation stable during a checkout test, or use a controlled experiment, so you can separate site effects from audience effects.

    Recover existing intent without creating a consent problem

    Once payment works, focus on shoppers who reached the cart or checkout but did not buy. They have supplied more evidence of intent than a cold audience, but that does not give you unrestricted permission to contact them.

    1. If the shopper has valid email marketing permission, place them in an abandoned-cart email flow with a direct return to the relevant cart or product.
    2. If the shopper has separately provided the consent required for marketing texts, use SMS selectively for time-sensitive recovery. Do not treat the presence of a phone number in checkout as automatic marketing consent.
    3. If you cannot document the necessary permission, do not quietly add the shopper to an automated sequence. Use compliant onsite recovery and your approved advertising audiences instead.
    4. Measure each recovery channel separately. A combined recovery number can conceal an unproductive SMS program behind a successful email flow, or vice versa.

    Email and SMS programs must follow the rules that apply to the shopper, sender, channel, and jurisdiction. In the United States, CAN-SPAM and TCPA are part of that compliance landscape. Requirements and interpretations can change, so have qualified counsel review the actual capture language, records, workflows, and vendors before contacting people who did not clearly subscribe. Calling an outreach process human-assisted does not by itself settle whether it is permitted.

    Recovery is not limited to reminders. Some shoppers leave because they still do not trust the product. Reviews answer a different objection: whether the item is credible and likely to meet expectations. Spiegel Research Center found that a product with five reviews was 270% more likely to be purchased than one with none. That finding does not make five a universal target or prove the same lift for every store. It does show why a product with no visible evidence should not be treated as conversion-ready.

    • Place product-specific reviews where the decision happens, not only on a separate testimonials page.
    • Make sure the review displayed belongs to the item being purchased. General store praise cannot answer product-level questions as well as relevant customer feedback.
    • Choose a review system that can connect with your advertising stack. Shopify integrations such as Okendo, Yotpo, and Shopper Approved can sync review data with Google Merchant Center and support Google Shopping activity.
    • Track whether products that gain credible review coverage improve their product-view-to-cart and checkout-start rates. Do not attribute every store-wide change to the review widget.

    Watch the downside metrics alongside recovered revenue: unsubscribe activity, complaints, failed deliveries, discount cost, refunds, and repeat purchase behavior. A flow that produces immediate orders by exhausting customer permission is not a durable win.

    Stop letting product categories decide where the budget goes

    Unbranded products receive different streams of advertising resources based on abstract performance signals, with completed orders feeding results back into a central decision hub.

    Category-based campaign structures are easy to understand, but a merchandising label does not describe advertising performance. One popular product can consume the available budget because the platform already has strong evidence that it converts. New products remain underexposed, while weak products can stay hidden inside a category that looks profitable in aggregate.

    Create performance cohorts with rules written before you inspect the latest results. Three labels are enough to begin:

    • Proven performers: products at or above your target return with enough recent traffic to support the decision.
    • New or low-data products: launches and existing products that have not received enough exposure to be judged by the same rule as established sellers.
    • Traffic without adequate return: products that have crossed your evidence threshold for clicks or spend but remain below your required return.

    Define the variables with your own economics. A workable rule template is: proven performer equals ROAS at or above target and clicks at or above the evidence floor; traffic without adequate return equals clicks at or above that floor and ROAS below your lower limit; new or low-data equals product age within your launch window or clicks below the evidence floor. The structure is reusable, but the values are not. A high-margin accessory and a low-margin appliance should not inherit the same target merely because they share a campaign.

    If you do not have a dependable margin view, do not automate budget expansion from ROAS alone. ROAS is attributed revenue divided by advertising spend. It is not profit. Product cost, fulfillment, payment charges, returns, discounts, and the attribution model can all change the decision.

    1. Export product-level clicks, spend, attributed revenue, orders, and ROAS for a consistent window.
    2. Apply the written cohort rules using feed labels or equivalent product-grouping fields.
    3. Give each cohort a budget and campaign treatment appropriate to its job. The new-product cohort needs room to gather evidence; proven products need room to scale; weak products need a controlled test or a spending limit.
    4. Publish the same product labels to paid channels where the required data and controls are available.
    5. Recalculate labels on a rolling schedule and log every reassignment. Without a log, a product that moves between groups can make campaign trends difficult to explain.

    La Maison Simons used Channable Insights to replace static category segments with product-performance groups and refreshed them on a rolling 14-day window. It then applied the approach across Google, Meta, Pinterest, TikTok, and Criteo. In that deployment, ROAS rose from about 800% to about 1,500%, CPC fell from $0.37 to $0.30, CTR increased from 1.45% to 1.86%, and average order value increased 14% without additional ad spend.

    Those figures are one retailer’s outcome, not a forecast for your catalog. They do not establish how much of the change came from segmentation rather than other conditions. The transferable lesson is narrower and more useful: a product can receive a different advertising treatment as its evidence changes, and a winning item does not have to monopolize the budget forever.

    A 14-day window is a sensible test cadence for a fast-moving catalog with enough transactions. It can be noisy for a lower-volume store, an expensive product, or a long-consideration purchase. Use the shortest window that still supplies enough evidence for your preset rules. If products repeatedly jump between cohorts, lengthen the window or raise the evidence floor instead of manually overriding the system every few days.

    Run one operating loop from conversion to ROAS

    Advertising and conversion teams often optimize separate dashboards. The media team changes audiences and budgets while the ecommerce team changes checkout and landing pages. When both happen at once, neither team can explain the result. Use one operating loop with fixed definitions and a visible change log.

    1. Cycle setup: record the current product cohorts, attribution model, campaign budgets, landing-page versions, payment options, and funnel baseline.
    2. During the window: monitor tracking and payment failures, but do not reclassify products because of a single order or a short-lived spike. Emergency defects should be fixed immediately and marked in the log.
    3. Decision day: recalculate product labels from the same lookback window, move qualifying products according to the written rules, and record every move.
    4. Experiment selection: choose one material conversion constraint for the next cycle. Test the ad-to-page message, the landing-page treatment, the checkout path, or the recovery flow rather than changing all four.
    5. Scale decision: increase exposure only when the advertising return, checkout behavior, and unit economics point in the same direction.

    Your shared scorecard should retain the relationship between media and store behavior:

    • CTR: clicks divided by impressions. It shows whether the ad earns attention, not whether the resulting visit is valuable.
    • CPC: spend divided by clicks. A lower CPC helps only if the traffic still reaches profitable purchases.
    • Product-view-to-cart rate: cart additions divided by relevant product views. Use it to investigate message, product, offer, and page friction.
    • Checkout completion rate: purchases divided by checkout starts. Use it to inspect payment and form friction.
    • Average order value: revenue divided by orders. Pair it with margin rather than assuming a larger basket is automatically more profitable.
    • ROAS: attributed revenue divided by ad spend. Always display the attribution model and window beside it.
    • Spend concentration: the share of budget absorbed by the top product or small group of products. This reveals catalog dependence that account-wide ROAS can hide.

    GA4 can remain part of this measurement system, while a third-party attribution layer such as Triple Whale can provide another product and channel view. More dashboards do not create objective truth. Select the attribution model used for budget decisions, document it, and avoid changing it in the middle of a comparison. A last-click result from one cycle cannot be compared cleanly with a different model in the next.

    Custom landing pages deserve their own controlled tests. Shopify builders such as Replo can create and A/B test pages without changing the main theme for every visitor. Start with one ad and product cohort, keep the standard page as the control, and change one decision-relevant treatment. If the variant wins, confirm that the improvement survives after product mix and traffic quality are accounted for before rolling it across the catalog.

    Begin with one mobile test order and one export of product-level advertising data. Fix any payment failure you find, label the catalog with written performance rules, and start a single review cycle. That gives you a system you can improve. Installing the entire stack before you can explain the current funnel only gives you more places for the same leak to hide.

    References

  • How to Find and Reduce Uncontested Holiday Google Ads Spend

    How to Find and Reduce Uncontested Holiday Google Ads Spend

    Your holiday campaigns can hit their headline targets and still waste money. The blind spot is not simply an expensive click. It is a click that remains expensive during a genuine gap in competition, even though a lower bid or a brief suppression might have preserved the same profitable demand.

    Do not respond by pausing brand campaigns or cutting bids across your account. First prove where competition is absent, then test the smallest reversible intervention. That distinction separates useful savings from a bid change that quietly costs you traffic and revenue.

    Uncontested is an auction state, not a campaign label

    An uncontested moment occurs when available auction evidence indicates that no meaningful competing advertiser is present for a particular opportunity. It does not mean the campaign, keyword, product group, or brand is permanently uncontested. A competitor may disappear for one query, device, location, or part of the day and return for the next auction.

    BrandPilot calls the issue the “Uncontested Google Ads Problem”. Its position is that advertisers can continue paying elevated CPCs on brand terms, Shopping placements, and category keywords when competing bidders are absent. Because that claim comes from a vendor associated with auction-visibility and AI bidding tools, treat it as a hypothesis to verify in your own account, not as a universal savings guarantee.

    Holiday activity makes a recurring leak more consequential. Campaigns concentrate more traffic and budget into a short selling period, so a small amount of avoidable cost repeated across many auctions can consume money that could support incremental demand elsewhere.

    • Low competition is not the same as no competition. A weak or intermittent rival can still affect the placement you need to defend.
    • No competitor in a summarized report is not proof of an uncontested auction. The report may cover a broader period or segment than the bidding decision you want to make.
    • A high CPC is not automatically waste. It becomes avoidable only when a lower-cost intervention preserves the business outcome that matters.
    • Brand traffic is not automatically safe to suppress. A brand ad can protect visibility, control promotional messaging, and direct shoppers to the right landing page even when competition appears light.

    Build evidence before you calculate savings

    An analyst uses a magnifying lens to compare several translucent data layers above a desk with a laptop and holiday parcels.

    Your account-wide average CPC cannot tell you whether uncontested spend exists. Build the analysis at the narrowest level supported by both your auction visibility and your performance data. If the competition signal is hourly, for example, do not combine it with a weekly CPC and call the result auction-level evidence.

    1. Choose a bounded scope. Start with one high-spend brand campaign, Shopping product group, or category cluster. Do not classify an entire account from a few visible gaps.
    2. Preserve the baseline. Record cost, clicks, impressions, impression share where available, conversion volume, conversion value, revenue, CPA, and ROAS. Segment by the dimensions that could change the auction: query or search-term group, product group, device, geography, and time.
    3. Find candidate competition gaps. Use the most granular auction visibility available to identify periods in which meaningful rivals appear absent. Label these as candidates until a controlled bid or suppression test confirms that cost can be reduced safely.
    4. Match competition and performance at the same grain. Each analytical row should represent the same campaign cell, time interval, location, device, and traffic type. A competitor gap on mobile should not be used to justify a desktop bid change.
    5. Mark confounding changes. Promotions, feed edits, landing-page changes, inventory constraints, budget limits, match-type changes, and altered conversion tracking can all move CPC or revenue independently of competition.
    6. Rank candidates by testable cost. Prioritize cells with meaningful spend, repeated competition gaps, stable demand, and a reversible bidding lever. A large but poorly verified opportunity is a worse starting point than a smaller, cleanly measurable one.

    Do not label every dollar in a candidate window as waste. The useful counterfactual is what you would have paid after a safe intervention, not zero. Once a test produces a defensible lower CPC, calculate gross media savings as eligible clicks x (baseline CPC – tested CPC). Then subtract the value of any lost conversions, revenue, or contribution margin.

    This also prevents a common reporting error. If lower CPCs buy more clicks because the campaign remains budget constrained, total spend may not fall. That can still be a good result, but it is an efficiency or volume gain rather than reclaimed budget. Decide in advance whether success means the same demand at lower cost, more profitable demand at the same cost, or a deliberate combination of both.

    Test a reversible bid change without sacrificing revenue

    A small bid lever controls parallel test and main pathways as parcels continue moving toward a checkout symbol behind a transparent guardrail.

    A historical before-and-after comparison is weak during the holidays because demand, promotions, inventory, and competitor activity can change quickly. When your setup allows it, use a concurrent control and treatment. Both should cover comparable traffic while only the intended bid or suppression rule differs.

    1. Write the hypothesis. Name the exact segment, the evidence that competition is absent, the intervention, and the expected business result. For example: lower the effective bid in a verified competition-gap window while preserving conversion value and the required visibility.
    2. Choose the smallest useful treatment. Apply a lower bid, a bid ceiling, or temporary suppression only to the qualifying query, product, device, geography, or time cell. Avoid an account-wide cut.
    3. Keep unrelated variables stable. Do not change creative, landing pages, promotion terms, feed attributes, audience settings, and bidding logic at the same time. Otherwise, you will not know what caused the result.
    4. Set commercial guardrails before launch. Monitor impression share or another visibility measure, clicks, conversion volume, conversion value, revenue, CPA, and ROAS. For a retailer, contribution margin is often a better final judge than media cost alone.
    5. Respect conversion lag. Do not declare savings from early CPC movement while delayed conversions are still arriving. Use the same attribution and completion rules for the control and treatment.
    6. Keep a rollback trigger. Restore the prior setting if a competitor returns, visibility drops beyond your accepted limit, or lost contribution margin overtakes media savings.

    The economic test is straightforward: net benefit equals media savings minus lost contribution margin and any added technology or operating cost. A treatment that saves ad spend but loses more profit has failed, even if CPC and ROAS look better in isolation.

    Brand Search deserves particular care. Turning off an entire brand campaign is a blunt experiment because it changes message control, landing-page selection, paid visibility, and competitive exposure at once. Shopping needs equally narrow treatment: a competition gap for one product group does not establish that the rest of the catalog is uncontested. Expand only after the first segment holds its result.

    Make automation prove what it sees and what it saves

    AI-driven bidding or suppression can be useful when competition changes too frequently for a person to manage auction by auction. The valuable part is not the AI label. It is a controlled loop that detects a qualifying gap, applies a bounded change, restores the normal setting when conditions change, and records enough detail for you to audit the decision.

    • Ask about signal granularity. The competition data should be at least as precise as the rule it activates. Daily evidence cannot reliably justify minute-by-minute suppression.
    • Ask about latency. You need to know how quickly the system detects both a competitor’s departure and return.
    • Inspect false-positive handling. The system should explain what happens when visibility is incomplete or confidence is low. The safe default should reflect the revenue risk of disappearing from an active auction.
    • Require decision logs. Each change should preserve the trigger, affected segment, prior setting, new setting, time, and reversal condition.
    • Define coexistence with existing bidding. Establish which system has authority when an auction rule and your campaign’s automated bidding logic point in different directions.
    • Demand an incrementality test. A dashboard estimate is not enough. Compare the automated treatment with a credible control and include lost business value in the calculation.
    • Retain manual limits and a kill switch. Automation should not be able to suppress broad holiday traffic because one input becomes stale or unavailable.

    Give reclaimed budget a specific next job

    Lower CPCs do not create growth by themselves. Decide where verified savings will go before the test ends. Candidates include a non-brand segment that is constrained by budget and clears your marginal-return requirement, an in-stock product group with acceptable margin, or a reserve for later high-intent demand.

    Evaluate the destination at the margin. An existing campaign’s average ROAS can look strong while its next dollar performs poorly. If no alternative clears your profitability threshold, retaining the savings is a valid decision. Reallocating money merely to exhaust a holiday budget recreates the problem in a different campaign.

    Key takeaways

    • Classify uncontested spend at the query, product, device, geography, and time level rather than labeling whole campaigns.
    • Treat competitor absence as a candidate signal until a controlled bid or suppression test preserves the required business outcome.
    • Calculate net benefit from tested CPC reduction, then subtract lost contribution margin and operating costs.
    • Use concurrent controls where possible because holiday demand and competitive conditions can make simple before-and-after comparisons misleading.
    • Judge automation by signal quality, latency, reversibility, decision logs, and incremental profit rather than by its estimated savings dashboard.
    • Assign verified savings to a profitable marginal opportunity or retain them; do not re-spend automatically.

    Your next move is deliberately small: select one meaningful campaign segment, document the suspected competition gaps, set a revenue guardrail, and run one reversible test. If the savings survive conversion lag without damaging profitable demand, expand one segment at a time and give the freed budget an explicit purpose.

    References

  • Google Ads API Optimization: A Safe AI-Assisted Workflow

    You have a Google Ads performance question, but answering it means choosing fields, writing GAQL, handling authentication, and turning the result into something the team can review. AI assistance can remove much of that technical friction. It cannot decide whether broader reach, a higher bid, or a new keyword strategy makes financial sense for your business.

    The useful approach is to separate observation from action. Use the Google Ads API Developer Assistant to investigate performance through read-only queries, validate what it returns, and save repeatable analysis. Put any change to budgets, bids, targeting, or keywords through a deliberate human approval process.

    Separate faster analysis from automated optimization

    Google Ads API Developer Assistant v1.0 is a Gemini CLI extension that can translate natural-language requests into GAQL, answers, and Python code built around the google-ads-python client library. This makes it useful when you understand the business question but do not want to reconstruct every query from memory.

    The assistant can also execute read-only API calls from the terminal, display results in formatted tables, export tabular data to CSV, and place generated code in a saved_code folder. Those capabilities shorten the path from a question to an inspectable result.

    That is analysis assistance, not an optimization strategy. A table can show which campaign recorded the most conversions. It cannot determine whether those conversions were valuable, whether lead quality deteriorated, or whether the campaign consumed more budget than the outcome justified. Those judgments depend on business definitions and constraints that sit outside a generic performance query.

    Keep the boundary explicit: the assistant retrieves and organizes evidence; an accountable person decides what the evidence means and whether the account should change.

    Key takeaways

    • Begin with reporting and diagnosis. Do not treat generated output as permission to change the account.
    • Include the account scope, date range, dimensions, metrics, filters, sort order, and desired output in every request.
    • Review generated GAQL and Python as untrusted code before running or reusing it.
    • Treat Google Ads Recommendations as hypotheses to investigate, not instructions to accept.
    • Keep changes to budgets, bids, targeting, and keywords behind human approval and a defined rollback path.

    Ask questions that lead to decisions, not just reports

    A vague request such as analyze my campaigns leaves too many choices to the assistant. It does not identify the problem, the period, the level of detail, or the decision you need to make. The result may be technically valid and still be operationally useless.

    Start with the decision. If you are deciding where to investigate a conversion decline, ask for a result that isolates campaign performance over a named period and includes the metrics needed to distinguish lower volume from higher cost. If you are checking a Google recommendation, request the evidence that would support or contradict its underlying claim.

    Use this prompt pattern: Within [account or campaign scope], for [date range], return [dimensions] and [metrics]. Apply [filters], sort by [metric], and provide [GAQL, Python, a terminal table, or CSV]. Explain the row grain, field choices, and assumptions before the result.

    Each part prevents a common analytical mistake:

    • Scope prevents a manager account, client account, campaign type, or status from being included unintentionally.
    • Date range makes the comparison reproducible. Relative periods are convenient for exploration, while explicit periods are easier to audit later.
    • Dimensions determine what one row represents. Adding a date, device, or other segment can change the grain and produce many rows for a campaign.
    • Metrics determine whether you can connect activity to a business outcome. A ranking by conversions alone does not show the cost or value behind those conversions.
    • Filters remove irrelevant entities, but an overly narrow filter can hide the reason performance changed.
    • Output determines whether you get an explanation, a reusable query, executable code, or an artifact another person can inspect.

    Prompts you can adapt

    • For the previous 30 days, rank campaigns by conversions. Return the GAQL first, explain the selected fields, and then produce a read-only Python script using google-ads-python.
    • Compare campaign cost and conversion performance across two explicitly named periods. Show the row grain and flag any filter that excludes paused or removed entities.
    • Generate a read-only query that provides evidence for or against a recommendation to expand keyword matching. Separate the requested output by campaign so the account owner can review exposure and outcomes.
    • Run this approved query, display a terminal table, and export the same rows to CSV. Include the account scope and date range in the output description.

    The first example closely matches a documented use case: a request for campaigns with the most conversions in the last 30 days can produce both a GAQL query and an optimized Python script. The important addition is the review instruction. You want to see what the assistant plans to ask the API before you rely on the answer.

    Inspect five things before execution: the customer being queried, the dates, the row grain, the filters, and the metric definitions. Then look for a sanity check. Compare a small part of the result with a familiar Google Ads view or an existing trusted report. A plausible table is not proof that the query answered the question you intended to ask.

    Configure Developer Assistant v1.0 for repeatable work

    The documented prerequisites for v1.0 include a Google Ads API developer token, a configured google-ads.yaml file, Python 3.10 or later, Gemini CLI, and a local clone of the google-ads-python library. A setup script handles the library cloning step.

    Do not stop once the assistant returns its first successful table. A useful setup makes the same request behave consistently for different operators and on different days.

    1. Validate the connection with a known read-only question. Choose a result you can verify in the Google Ads interface. This separates authentication or account-scope problems from query-design problems.
    2. Define project conventions in GEMINI.md. The assistant uses GEMINI.md and configuration files as project context when tailoring code. State the expected client library, output conventions, code location, naming rules, and read-only default.
    3. Require an explanation before execution. Ask for the GAQL, selected resources, filters, dates, and row grain in plain language. A reviewer should be able to understand the intended request without reverse-engineering the code.
    4. Keep credentials out of prompts and generated files. Use the supported configuration mechanism. Review saved files before sharing them or adding them to version control.
    5. Review generated Python before running it. Check imports, customer selection, request type, file paths, exception handling, and whether the code does anything beyond retrieval and export.
    6. Preserve a verified query as a smoke test. Run it after configuration or dependency changes. If its known output or shape changes unexpectedly, investigate the environment before trusting new analyses.

    Project context is leverage. Good instructions make repeated analysis more consistent; incorrect instructions make the same mistake repeatable. Keep GEMINI.md short enough to review, specific enough to guide the assistant, and under the same change-control discipline as other project configuration.

    The saved_code folder is most valuable when it becomes a reviewed library rather than a dumping ground. Give each retained script a clear purpose, record its account scope and required inputs, and distinguish experimental output from approved reporting code. Remove ambiguity before another person schedules or modifies it.

    Turn Recommendations into an evidence-backed test queue

    Google Ads Recommendations are prompts to evaluate. They are not proof that the proposed change fits your economics. A suggestion may be informed by patterns across accounts while missing a constraint that matters in yours. For example, an account using Exact and Phrase match keywords may receive a Broad Match suggestion even when its budget or niche requires tighter control.

    The Optimization Score is easy to misread as a performance grade. It reflects how recommendations are being handled, and dismissing a recommendation can affect the score in the same way as applying it. You do not need to accept an unsuitable change merely to clear the prompt or improve the displayed score.

    Use the API assistant to build an evidence packet for each recommendation:

    1. Restate the claimed problem. Is the recommendation trying to expand reach, improve efficiency, repair setup, or remove a limitation?
    2. Request the relevant account evidence. Define the entities, period, metrics, and filters that would show whether that problem exists.
    3. Write down the business constraint. Include budget limits, acceptable lead quality, geographic restrictions, inventory realities, or other rules that the platform cannot infer reliably.
    4. Set success and failure criteria before making a change. Decide what result would justify keeping the change and what result would trigger reversal.
    5. Choose a reversible test. Limit the blast radius and preserve the prior state so the account can be restored if performance or traffic quality deteriorates.
    6. Assign an owner. One person should approve the change, monitor the agreed evidence, and decide whether to keep or roll it back.

    Auto-apply deserves stricter treatment because it can remove that review gate. The documented control path is Recommendations, All Campaigns, and Auto-Apply Settings, where you can confirm that unwanted selections are unchecked. Check the setting at the account level instead of assuming that an earlier choice still reflects current policy.

    This is a financial control, not interface housekeeping. Automatically applied suggestions can affect reach, spending, bids, or keyword behavior. Enable a category only when you have defined who owns it, what changes it permits, how the effect will be monitored, and how the prior state can be recovered.

    Do not give every interface notice the same urgency. Blue or yellow notices can represent suggestions, while red or purple notices can indicate issues such as billing errors or disapproved ads. Investigate actual delivery or account-access problems before spending time on an optional optimization prompt.

    Run one controlled loop from question to verified change

    A reliable optimization process leaves a trail from the original question to the final decision. It should be possible for another person to see what was queried, what came back, why a change was approved, and whether the expected result appeared.

    1. Name the decision. Write the question in a form that could change an action: which campaigns need investigation, whether a recommendation deserves a test, or where a recurring report shows an exception.
    2. Specify the evidence. Add account scope, dates, dimensions, metrics, filters, and output format to the prompt.
    3. Generate before executing. Read the proposed GAQL and code. Correct ambiguous fields, unintended segments, and overly broad scope.
    4. Run read-only. Display the result in the terminal and export CSV when another reviewer or a longer audit trail is needed.
    5. Validate the result. Compare a small slice with a trusted interface view or established report. Confirm that each row represents what you think it represents.
    6. Form a testable explanation. State what appears to be happening, what evidence is still missing, and which reversible change could test the explanation.
    7. Approve and implement separately. Use your normal controlled account-management process for changes. Do not turn generated analysis code into mutation code simply because the first output looked correct.
    8. Run the same query again. Reuse the reviewed query so the before-and-after comparison is based on the same scope, fields, filters, and row grain.

    Label saved queries and exports with enough context to make them interpretable later. At minimum, preserve the account scope, analysis period, purpose, and important filters alongside the artifact. A file called campaign_report.csv creates less accountability than an export tied to a specific question and approved query.

    Automate stable retrieval only after the query has survived review and repeated validation. Keep recommendations and account mutations gated. The cost of manually approving a consequential change is small compared with the cost of allowing a misunderstood prompt, broad filter, or unsuitable recommendation to alter spend without supervision.

    Start with one recurring question your team currently answers by hand. Define it precisely, run it read-only, verify the output, and retain the approved query. Once that loop is dependable, add the next question. The real efficiency gain comes from reusing trusted analysis while keeping financial decisions under human control.

    References

  • How to Measure SEO and Choose Tools That Earn Their Budget

    How to Measure SEO and Choose Tools That Earn Their Budget

    Your SEO stack can produce a dashboard full of green arrows and still leave you unable to defend the next renewal. If you are deciding whether to keep a platform, add AI-search monitoring, or build an internal agent, the first question is not which option has the longest feature list. It is what decision the investment must improve.

    Build the measurement system before the shortlist. You will expose missing data, avoid paying twice for the same capability, and give every candidate a real job to perform.

    Key takeaways

    • Define the business outcome, search signal, diagnostic evidence, decision, and owner before evaluating any tool.
    • Use the 24-hour view for investigation, weekly reporting for operating decisions, and monthly reporting for direction and resource allocation.
    • Buy a capability only when it closes a documented measurement or workflow gap. An AI label is not a use case.
    • Run trials with representative weekly work, the same inputs, and pass-or-fail criteria that matter after the demo.
    • Separate observed trial evidence from forecast business impact. A short trial can validate a workflow, but it cannot prove future revenue.

    Build a measurement brief before opening a vendor tab

    Five connected groups of objects represent a business target, search signals, evidence, a decision gate, and an action on a strategy table.

    SEO tool evaluations often begin with feature inventories because features are easy to count. That produces a weak business case: leadership generally needs a connection to business results, while many platforms stop at keyword volume, optimization speed, or activity.

    Replace the feature wish list with a short measurement brief. Complete these fields before you request a demo:

    • Business question: State the decision in plain language. Examples include which landing-page group deserves investment, whether a technical release repaired organic acquisition, or which market needs local content.
    • Outcome: Name the result the business already recognizes, such as qualified leads, completed orders, subscriptions, booked consultations, or another defined conversion.
    • Search-performance signal: Identify what you expect to move before the outcome does. Depending on the job, that could include impressions, clicks, landing-page traffic, organic conversions, or search visibility for a defined query set.
    • Diagnostic evidence: List the information needed to explain the movement, such as indexation status, page-template defects, query mix, SERP composition, country, language, or device.
    • Decision rule: Describe what you will do when the evidence changes. A metric without a resulting action is reporting inventory, not a requirement.
    • Owner and cadence: Name who reviews the result, who receives the work, and whether the decision belongs in incident response, a weekly queue, or monthly planning.
    • Boundary: Record what the measurement will not prove. This prevents a ranking change, an alert, or an AI-generated recommendation from being presented as revenue attribution.

    Keep outcomes, performance indicators, and diagnostics separate

    A useful SEO measurement model has distinct layers:

    • Outcome measures describe business results: revenue, qualified demand, completed transactions, subscriptions, or another accepted conversion.
    • Performance indicators describe how organic search contributed: query impressions, clicks, landing-page visits, conversions attributed to organic sessions, and visibility within a defined search set.
    • Diagnostic measures help explain why performance changed: crawling and indexation states, template issues, internal-linking gaps, SERP changes, or differences between markets and devices.

    Do not collapse these layers into a proprietary health score and assume the result has business meaning. A technical score can improve without demand changing. Visibility can rise on queries that never produce a useful visit. Organic conversions can move because of a pricing change, promotion, tracking repair, or landing-page redesign rather than the SEO work being evaluated.

    Write the evidence chain explicitly: the work performed, the observable search change, the on-site action, and the business outcome. Annotate releases and tracking changes. Compare the affected page or query group with a relevant unaffected group when one exists. If the chain is incomplete, call the result an association or an operational improvement rather than attribution.

    Measure at the level where the intervention happened. A template fix should be evaluated on the affected template group. A localized content program should be separated by country and language. A rewrite aimed at one query theme should not be judged only through a sitewide total. Aggregation can make a successful change disappear, or make an unrelated gain look like success.

    Match the reporting interval to the decision

    Google Search Console performance reporting now includes weekly and monthly views in addition to the familiar 24-hour perspective. The practical benefit is not another way to format a chart. It is the ability to choose a reporting grain that fits the question.

    Reporting viewQuestion it should answerWhat not to use it for
    24-hourDid an abrupt change coincide with a release, tracking failure, indexing problem, or other incident?Declaring a durable trend from a short movement.
    WeeklyIs the movement persistent enough to enter the operating queue, and did recent work affect the intended pages or queries?Proving long-term business return from a single reporting period.
    MonthlyIs the program moving in the intended direction, and should priorities or resources change?Finding the exact cause of a sudden failure.

    Use the shortest interval that can answer the decision without letting routine variation dominate it. Then preserve the finer view for diagnosis. A monthly decline can justify investigation; the weekly and 24-hour views help locate when it began and which segment moved.

    Reporting grain does not fix a poor comparison. Compare complete periods with complete periods. Keep seasonal demand and major campaigns in view. Do not compare a global total after launching a new locale without separating the new market from established ones.

    Segment before you explain. Useful cuts include query theme, landing-page group, template, device, country, language, and a documented branded-versus-non-branded rule. A flat sitewide result can conceal growth in one segment and decline in another.

    Maintain a change log next to the performance data. Include site releases, migrations, tracking changes, canonical-rule updates, internal-linking work, and major campaigns. When performance moves, check those known events before assigning the change to an algorithm, competitor, or tool recommendation.

    Turn capability gaps into must-pass jobs

    A shortlist should reflect the gaps in your measurement brief. Useful evaluation areas include advanced data analysis, SERP intelligence, meaningful automation, multilingual support, and transparent pricing. Those labels are still too broad to purchase. Convert each one into a task and a required form of evidence.

    CapabilityTrial jobEvidence required
    Advanced analysisConnect search performance, landing-page behavior, and the defined business outcome for the affected page group.Repeatable definitions, visible transformations, segment-level results, and an export that another analyst can inspect.
    SERP intelligenceExplain a visibility change for a defined query set and market.The underlying queries, capture context, date, location, device, competing results, and relevant search features rather than an unexplained score.
    AutomationComplete a recurring weekly task from detection to prioritized handoff.Rules, exceptions, deduplication, evidence attached to each recommendation, an owner, and a record of what happened after the alert.
    Multilingual supportAnalyze a real country-and-language workflow without merging markets that require different decisions.Locale-specific query and page context, correct filters, preserved terminology, and reporting that can be reviewed by the market owner.
    Pricing clarityPrice the expected operating state rather than the demo environment.A written breakdown of seats, tracked entities, usage limits, exports, integrations, AI consumption, implementation, support, and overage conditions.

    If AI-search visibility is the stated gap, define the observation before accepting a visibility score. Ask which model or search surface was checked, in which locale, against which prompt or query set, at what time, with what captured answer, and under what entity-matching rule. Treat the tracked set as a measurement panel with documented boundaries. An opaque score can summarize evidence, but it should not replace the evidence.

    The replacement standard should be especially high for established crawling and technical-audit workflows. Core technical SEO tooling is comparatively stable. If your current system reliably finds relevant issues, preserves history, and routes work to the right owner, adding an AI label is not enough reason to replace it.

    Decide whether to buy an AI tool or build an agent

    The choice between a ready-made platform and a custom AI agent belongs after the workflow is defined.

    • Buy a platform when the task is standardized and the main value comes from vendor-maintained datasets, integrations, interfaces, support, and ongoing product upkeep.
    • Build an agent when the useful context lives in internal data, business rules, approval paths, or proprietary workflows that a general platform cannot represent. Include evaluation, monitoring, security review, maintenance, and internal ownership in the cost.
    • Keep the existing stack when the real bottleneck is an undefined decision, weak implementation discipline, missing conversion data, or unclear ownership. A new interface will not repair those conditions.

    For a small team, automation must remove work rather than produce more material to review. Outputs without market and business context tend to create noise. Require the system to suppress duplicates, show supporting evidence, explain uncertainty, and hand the next action to a named owner.

    Run a trial that can survive the sales demo

    Three evaluators observe two identical workstations completing the same controlled trial with blank result cards and evidence boxes.

    Do not evaluate a tool through a polished example that the vendor selected. Start with understandable pricing, secure a trial, and test the work your team actually performs in a normal week.

    1. Lock the use case and finish line. Describe the input, expected output, decision, owner, and acceptable evidence before anyone sees the product.
    2. Capture the current baseline. Record active work time, waiting time, systems touched, manual handoffs, recurring errors, and the decision produced by the current workflow.
    3. Use representative inputs. Include ordinary data and a known difficult case. A candidate that works only on a tidy sample has not passed the operational test.
    4. Separate setup from recurring operation. Record configuration, integration, tagging, permissions, and training effort independently from the work expected after adoption.
    5. Run the same task across candidates. Keep the data, operator instructions, and required output consistent so the comparison reflects the tools rather than different demonstrations.
    6. Trace every important output. Follow recommendations back to queries, pages, captured results, or other underlying evidence. Label generated explanations separately from observed data.
    7. Count decisions changed, not alerts created. Record whether the output changed a priority, prevented an error, removed a manual step, or supplied evidence the current stack could not provide.
    8. Test the handoff. Export the result, route it to the intended owner, apply permissions, and verify that history remains understandable outside the person who configured the trial.
    9. Price the operating state. Obtain the expected cost at normal usage, including implementation, integrations, support, consumption limits, internal administration, quality assurance, and any tools the purchase would actually retire.

    Apply pass-or-fail gates before scoring convenience features:

    • Data fitness: It covers the required sites, markets, languages, queries, pages, and business data at a usable level of detail.
    • Evidence quality: Important outputs are reproducible, traceable, and explicit about assumptions or uncertainty.
    • Workflow value: It removes a documented step, improves a defined decision, or enables a necessary analysis that is currently impractical.
    • Operational fit: The intended users can configure, review, export, and act on the output without relying indefinitely on a vendor specialist.
    • Governance: Access controls, retention, deletion, input reuse, and approval requirements fit your organization’s rules.
    • Commercial clarity: The written price covers the expected usage, dependencies, overages, implementation, renewal conditions, and exit path.

    Do not upload confidential query, customer, conversion, or client data until the appropriate security, privacy, and legal owners have approved the environment. Use a sanitized export or synthetic test set while that review is incomplete. The convenience of a trial is not worth creating an uncontrolled copy of sensitive data.

    Ask vendor questions that expose operating cost

    Send the use case before the call, then ask questions that require specific answers:

    • Which assumptions about seats, sites, markets, tracked queries, prompts, exports, API use, and AI consumption are included in this quote?
    • Which capabilities shown in the demonstration require another package, service, integration, or implementation fee?
    • What work is required from our team during setup and during normal operation?
    • Which claims describe production functionality, and which depend on a roadmap?
    • Can we export raw observations, definitions, configurations, and history in a usable format?
    • How are AI inputs retained, reused, isolated, and deleted, and where can those terms be verified?
    • What happens to access, stored data, reports, and integrations if usage changes or the contract ends?

    Build a budget case without pretending the trial proved revenue

    A short trial can establish data coverage, repeatability, workflow fit, evidence quality, and whether the output changes a decision. It usually cannot establish that the tool caused a durable ranking, conversion, or revenue increase. The business case should keep observed evidence, forecasts, assumptions, and unknowns in separate fields.

    Calculate full cost as the subscription, expected usage and overages, implementation, integrations, training, quality assurance, administration, and any internal build or maintenance effort, minus only the cost of tools that will genuinely be retired.

    Treat saved labor carefully. It becomes direct financial savings only when it avoids actual spending. Otherwise, describe it as capacity and name where that capacity will be redeployed. Treat incremental business impact as a forecast with an explicit mechanism: better evidence leads to a different decision, that decision changes the work, and the work may affect the defined outcome.

    Present a range of choices: keep the current stack, make a narrow change that closes the priority gap, or fund a broader platform or internal build. Include dependencies, risks, and exit criteria for each. That is more credible than forcing every benefit into an optimistic return figure, especially while direct connections between search activity and tangible business outcomes remain uncommon in tool offerings.

    Set checkpoints before signing. Confirm usability and evidence quality at the end of the trial, review operational value after a complete reporting period, and revisit adoption, overlap, business impact, and full cost before renewal. If the tool does not improve the decision named in the original brief, downgrade it, replace it, or stop paying for it.

    Your next move should be a blank measurement brief, not another demo booking. Choose a real decision from the next closed weekly or monthly period and ask each candidate to produce evidence your current stack cannot. A tool that cannot change that decision has not earned a place in the budget.

    References