Tag: Brand Protection

  • Domain-Wide Disavowal: When to Block an Entire TLD

    Domain-Wide Disavowal: When to Block an Entire TLD

    You have traced a suspicious backlink pattern to one top-level domain, and the cleanup looks repetitive: domain after domain ends with the same suffix. Google accepts a single disavow directive that can cover that entire TLD, but convenience is exactly what makes the option dangerous.

    The line is simple. The decision behind it is not. Before you use it, you need to distinguish one bad website from a genuinely TLD-wide pattern and confirm that you are willing to disregard every useful link signal caught in the same scope.

    First, confirm which kind of domain-wide disavowal you mean

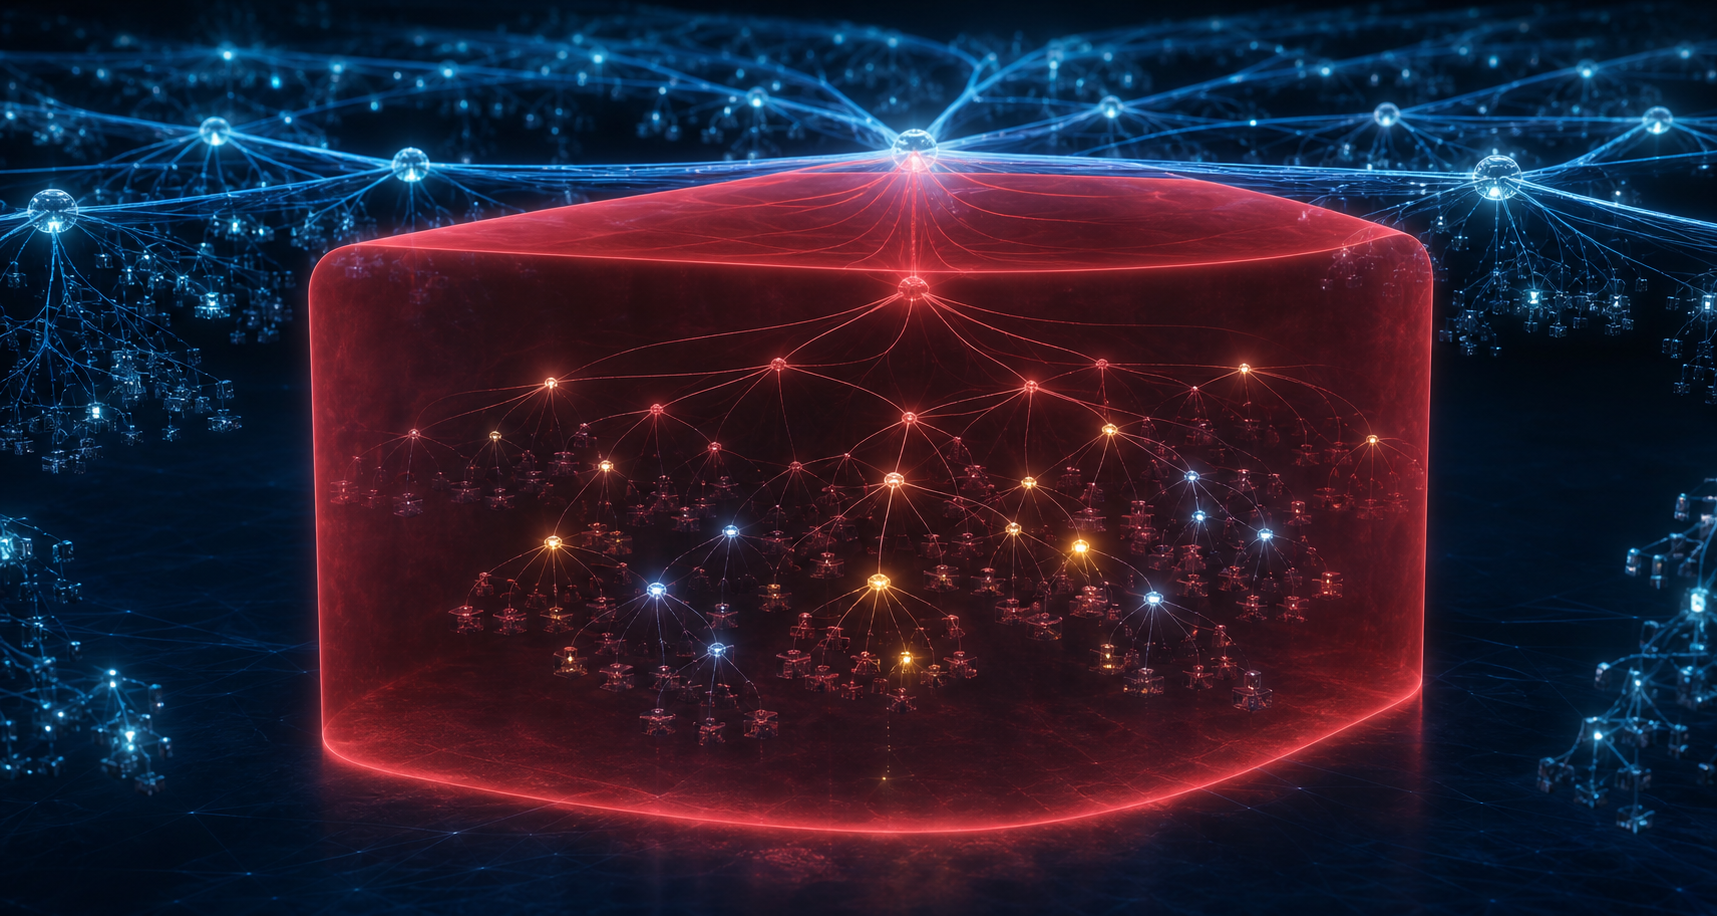
    Two different scopes are easy to conflate. A domain-level directive targets one named domain. A TLD-level directive reaches every domain using that top-level domain.

    • domain:example.abc identifies the specific domain example.abc.
    • domain:abc identifies the entire .abc top-level domain.

    The second form is the unusually broad one. It asks Google to disregard links from unrelated websites simply because they share the same ending. It does not remove those links from the web, contact their owners, or make the referring pages disappear.

    Google’s John Mueller confirmed that the bare domain:abc form can cover a whole TLD. He also cautioned that you cannot preserve selected domains beneath that directive and that every TLD is likely to contain some good sites. The behavior remains undocumented because its scope is so broad.

    That limitation should control your choice. If you want Google to retain signals from even one important site on .abc, the TLD-wide directive cannot express your intent. Disavow the unwanted domains individually instead.

    Require evidence at the same scale as the action
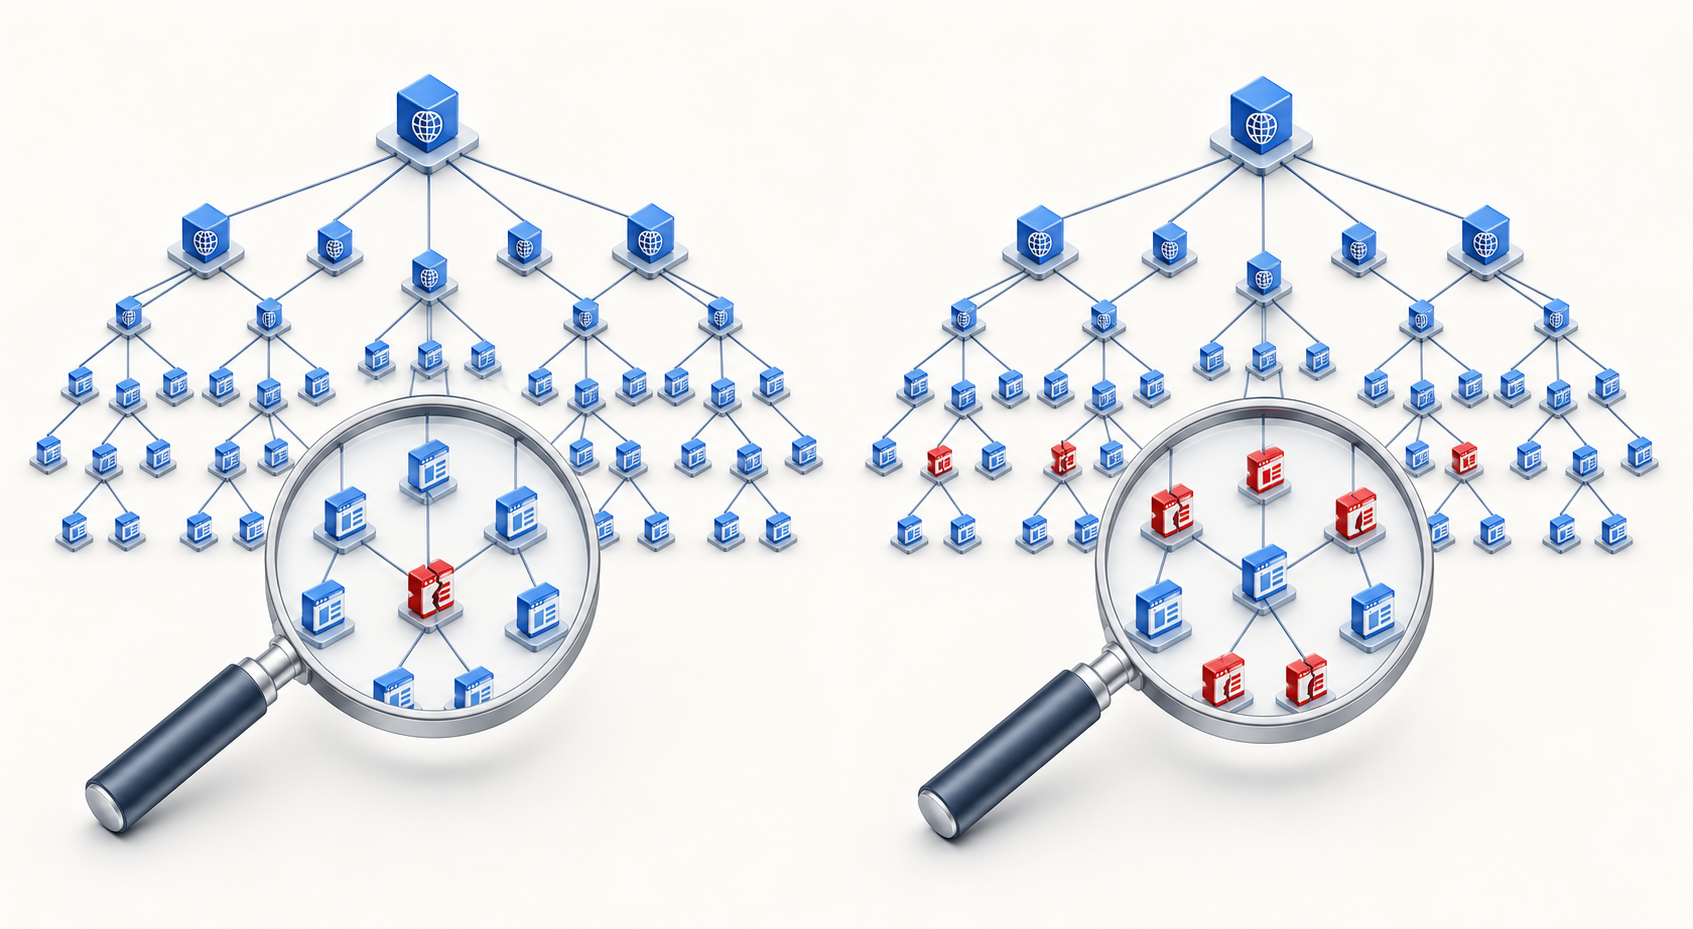
    A split illustration shows one suspicious website node isolated on the left and many suspicious nodes spread across a network branch on the right.

    A shared suffix is a clue, not a verdict. Several poor links from several domains can still represent a small cluster rather than a problem with the entire TLD. Before reaching for the broad directive, test whether your evidence is genuinely broad enough.

    1. Check distribution. Determine whether the pattern appears across many independent domains or is concentrated in a limited, repeatable set. A limited set supports domain-level action.
    2. Check context. Review the referring pages, site identities, link placement, and relevance. Do not classify a domain solely from its suffix or an unfamiliar language.
    3. Look deliberately for exceptions. Search the candidate TLD for publishers, communities, partners, directories, or other sites whose link signals you would want to keep.
    4. Define the problem. Record why these links belong in a disavow file. An unusual TLD or an unattractive page is not, by itself, evidence that the entire namespace should be excluded.
    5. Test your confidence. If your conclusion changes when you inspect beyond the most obvious examples, your classification is not stable enough for TLD-wide action.
    What your review findsAppropriate scope
    Unwanted links are concentrated in a known set of domainsHandle those domains individually
    The TLD contains a mix of unwanted and valuable sitesUse individual domain directives and preserve the valuable sites
    The pattern spans the TLD and no reviewed exception needs to be preservedConsider domain:abc
    The sample is incomplete or your classification is uncertainDo not use the TLD-wide directive yet

    Volume should tell you where to investigate, not how broadly to act. A large pile of links can originate from a small number of domains. In that case, a whole-TLD directive expands the scope without improving the precision of the cleanup.

    Build an audit trail before editing the disavow file

    A TLD-wide decision should be reproducible by someone who did not perform the first review. Create a small evidence sheet rather than relying on a filtered backlink view that may be difficult to reconstruct later.

    1. List every observed referring domain using the candidate TLD.
    2. Attach representative linking URLs to each referring domain so the classification can be checked.
    3. Record the page context, relevance, and reason each domain appears unwanted.
    4. Mark every legitimate or uncertain domain separately instead of forcing it into a binary spam label.
    5. Search specifically for an exception that would make whole-TLD treatment unacceptable.
    6. Write the final scope decision: individual domains, the entire TLD, or no change pending further review.

    This record gives you a practical stopping rule. One legitimate domain does not prove that every other domain is useful, but it does prove that domain:abc cannot preserve the distinction you have found. If that exception matters, narrow the scope.

    Keep uncertainty visible as well. A domain you have not confidently classified belongs in an uncertain group, not automatically in the unwanted group. The TLD-wide line leaves no room for that nuance once it is applied.

    Add the directive without losing control of the change
    Hands place a red rule tile at the root of a website network while an earlier version and organized evidence cards remain preserved nearby.

    For a placeholder TLD written as .abc, the special directive is:

    domain:abc

    The value is the bare TLD label. Do not turn it into a sample hostname if your reviewed decision truly covers the entire TLD. Conversely, do not use the bare label when your evidence supports action against only particular domains.

    1. Start from the current working version of your disavow file rather than rebuilding it from memory.
    2. Save a dated copy of that version before making the change.
    3. Add the whole-TLD line only after the audit and exception check are complete.
    4. Record the candidate TLD, the evidence reviewed, the reason for the decision, and who approved it in a separate change log.
    5. Review the exact scope once more before submitting the updated file through Google’s link disavow tool.

    Do not try to create an exception by placing a preferred domain elsewhere in the file. The whole-TLD directive has no carve-out mechanism. Individual directives from the same TLD are also redundant once the broader line is present; the broader instruction already captures them.

    A saved pre-change file and a written decision record will not make a poor classification harmless, but they prevent an opaque change. If a valuable domain is discovered later, you can identify why the broad line was added and reassess the scope from evidence rather than recollection.

    Key takeaways

    • domain:abc can target links from every website using the .abc TLD, not just one domain.
    • A TLD-wide directive cannot preserve selected domains that you still value.
    • Use the broad form only when the backlink pattern and your review both support TLD-wide treatment.
    • Mixed, incomplete, or uncertain evidence calls for narrower domain-level work or more investigation.
    • Keep the prior disavow file, the reviewed examples, and the reason for the scope decision.

    Before adding a whole-TLD line, try to find one domain under that suffix whose link signals you would want Google to retain. If you find one, stop and narrow the scope. If you do not, document the review and make domain:abc a deliberate final step rather than a shortcut.
    References

  • AI Marketing Governance: Scale Creative Without Losing Trust

    AI Marketing Governance: Scale Creative Without Losing Trust

    You have a campaign due, the platform wants more assets than your team can shoot, and an AI tool can produce the missing scenes in minutes. The production problem looks solved. The harder question arrives at approval: does the result still represent the product, the customer and the brand truthfully?

    You do not need to choose between using AI and being authentic. You need a governance system that distinguishes harmless assistance from consequential manipulation, preserves evidence for every claim and stops questionable work before speed turns it into scale.

    Key takeaways

    • Authenticity is not the absence of AI. It is the absence of a misleading gap between what your marketing depicts and what a reasonable customer would believe.
    • Govern the output and its likely interpretation, not the name of the tool that produced it.
    • Give every AI-assisted asset a source record, a named approver and a defined withdrawal path before publication.
    • Disclosure can explain how an asset was made, but it cannot make a false product claim, invented testimonial or nonexistent result acceptable.
    • Use the same approved facts across ads, landing pages, product feeds, public relations, structured data and answer-engine content. Contradictory claims weaken both customer trust and machine-readable credibility.

    Authenticity is a truth boundary, not a production method

    A manually produced campaign can be deceptive. An AI-assisted campaign can be accurate. The relevant distinction is not human versus machine; it is faithful representation versus manufactured belief.

    That distinction matters because AI can now support a wide range of creative operations, including background removal, lifestyle-scene generation, synthetic people and rapid asset variation. The resulting production capacity is useful, but technical permission is not the same as brand permission. Your policy has to decide what the audience may reasonably infer from the finished asset.

    Use four questions at the creative brief, review and approval stages:

    1. What will the audience think is real? Identify the likely interpretation, not merely the literal elements on screen. A person may understand that a decorative background is illustrative while assuming a product demonstration, testimonial or before-and-after image records a real event.
    2. Does the synthetic element affect the decision? Color accuracy, dimensions, included features, product condition, customer identity, quoted experience and demonstrated outcomes can all influence a purchase or trust decision. Treat those elements as material.
    3. Can the implied claim be substantiated? You should be able to trace a factual statement or visual implication to an approved product record, documented result or other internal evidence. If the evidence cannot be found, the asset is not ready.
    4. Would knowledge of the AI intervention change the audience’s judgment? If the answer is yes, redesign the asset, disclose the intervention clearly or do both. Do not hide a consequential transformation behind a broad statement that AI was used somewhere in production.

    A synthetic background behind an unchanged product may create little expectation risk. A synthetic person presented in a way that resembles a customer, employee or expert creates much more. A generated product feature that does not exist crosses the truth boundary entirely.

    Disclosure belongs after this truth test, not in place of it. A label can tell someone that an image is simulated. It cannot repair an inaccurate price, fake endorsement, invented review, altered package size or performance claim that your evidence does not support. When the underlying claim could create compliance or legal exposure, pause publication and route it to the appropriate qualified reviewer. A creative approval is not a substitute for legal review.

    Use a four-level integrity ladder for AI-assisted work

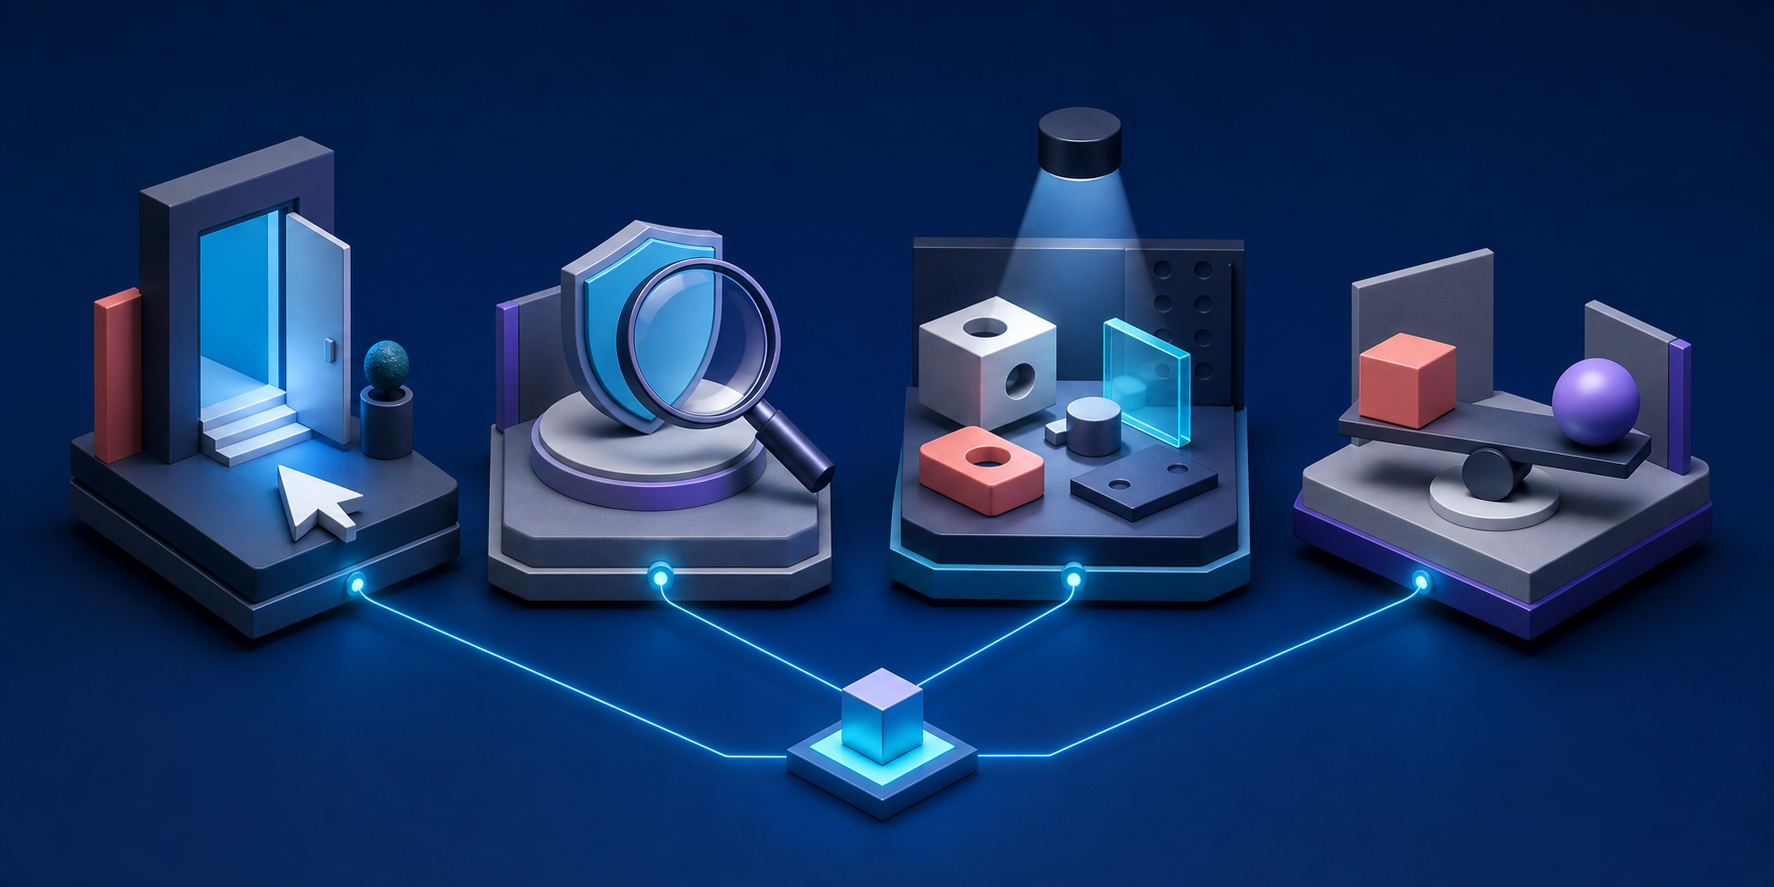
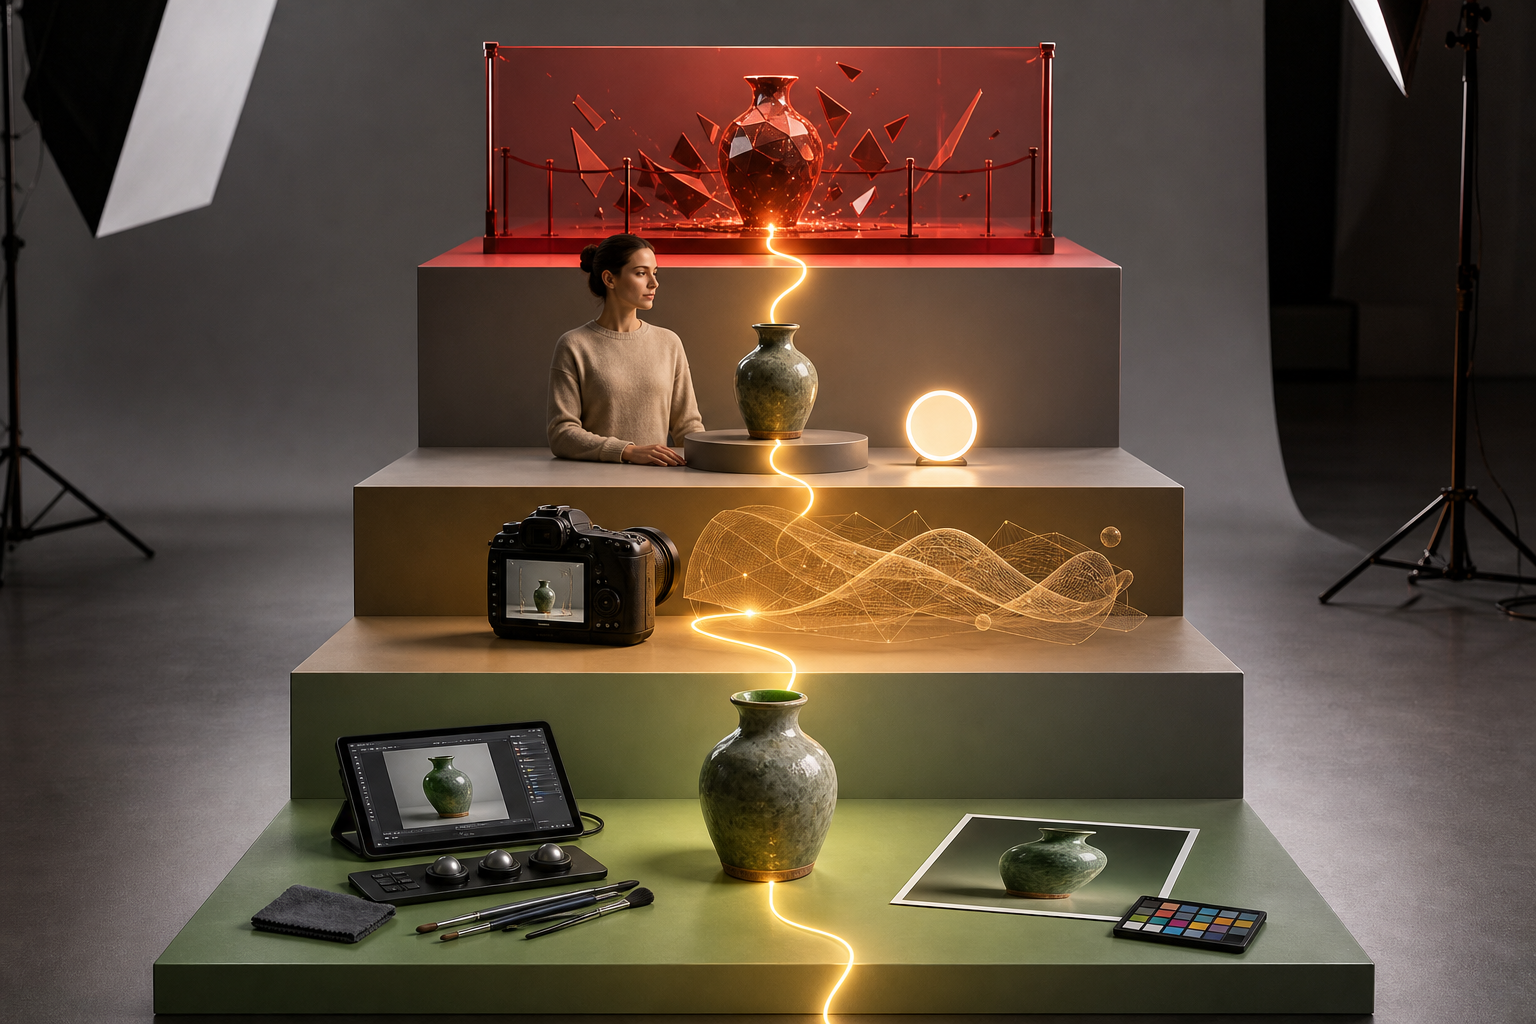
    Four ascending studio platforms show increasingly consequential forms of AI-assisted product imagery connected to a real product by a golden thread.

    A practical policy needs more than a general instruction to use AI responsibly. A four-level brand integrity hierarchy gives marketers, agencies and approvers a shared way to classify work before debating individual assets.

    Integrity levelTypical outputDefault decisionRequired control
    AssistanceResizing, cropping, cleanup, formatting or copy variation that preserves the approved meaningAllowed within documented brand rulesRetain the original and confirm that facts, qualifications and visual product attributes did not change
    AdaptationBackground replacement, contextual scenes, localization or audience variants built around a real product or approved claimAllowed with reviewRecord what was synthetic, verify the product representation and decide whether the context needs disclosure
    SynthesisSynthetic people, realistic events, demonstrations or scenes that an audience could interpret as documentary evidenceConditional and escalatedRequire an accountable approver, a documented disclosure decision, substantiation for every implication and confirmation that no real person’s identity is being misrepresented
    FabricationInvented testimonials, nonexistent features, unsupported outcomes, fake certifications or materially altered productsProhibitedDo not publish; correct the brief or obtain valid evidence for a truthful alternative

    Classify the finished output, not the software. The same generator could perform low-risk cleanup in one workflow and create an unacceptable customer simulation in another. Tool-based rules age quickly and invite loopholes; output-based rules remain understandable when platforms change their features.

    Context can also move an asset up the ladder. Replacing the background behind a product is usually adaptation. It becomes more consequential if the new setting implies that the product is certified for a particular environment, fits a space it does not fit or has a capability it does not have. Likewise, a synthetic human used as decorative illustration differs from one presented beside testimonial language that implies a genuine experience.

    Write examples from your own campaigns beside each level. Include one clearly allowed example, one conditional example and one prohibited example for the channels your team actually uses. Those precedents will resolve ordinary decisions faster than an abstract ethics statement.

    Turn the policy into a publishing gate

    Reviewers inspect a marketing image, a physical product and supporting papers as creative assets pass through a transparent publishing checkpoint.

    A governance document does not protect the brand if approval still happens in chat threads, source files disappear and nobody can identify who accepted the risk. The control has to sit inside the publishing workflow.

    Your operating policy should define:

    • Scope: the channels, teams, contractors, agencies and asset types covered by the policy.
    • Allowed uses: transformations that can proceed under standard review.
    • Conditional uses: outputs that require disclosure, specialist review or approval from a more accountable role.
    • Prohibited uses: transformations that cannot be published even when labeled as AI-generated.
    • Evidence requirements: the records that must support factual, comparative, visual and testimonial claims.
    • Disclosure rules: when a disclosure is required, where it must appear and who approves its wording and placement.
    • Responsibility: who creates, verifies, approves, publishes, monitors and withdraws an asset.
    • Exception handling: who can authorize an exception, what evidence is required and when that decision must be revisited.

    Move each asset through the same evidence path

    1. Set the truth boundary in the brief. List the product attributes, claims, qualifications and visual details that cannot change. State what may be synthesized and what the asset must not imply.
    2. Assemble an approved reference pack. Give the creator the current product images, specifications, brand terminology, claim substantiation and required qualifications. Do not make the reviewer reconstruct the ground truth after generation.
    3. Create within the assigned integrity level. Record the tool or production path, the original materials and the meaningful transformations. You do not need to archive every inconsequential interaction, but you do need enough provenance to reproduce the decision and investigate a problem.
    4. Verify the rendered output. Check the actual sizes, crops, overlays, captions, product details and landing-page destination that the audience will see. A correct master file can become misleading when a placement removes a qualification or crops out context.
    5. Approve the claim and the presentation separately. One check asks whether the underlying statement is supported. The other asks what a reasonable person will infer from the combination of words, images and placement. Passing one does not guarantee the other.
    6. Publish with a withdrawal record. Log the channels and destinations where the asset appears. If a claim changes or an error is found, the team should know where to remove or replace every affected version.

    The asset record can be compact. Capture the campaign and channel, source materials, meaningful AI transformations, claims used, disclosure decision, reviewer, approval state and publication locations. What matters is that someone other than the creator can understand why the asset was approved.

    Human review is not a control by itself. The reviewer needs access to the evidence, clear authority to stop publication and enough time to inspect the final placement. A person who can only click approve is part of the production sequence, not an effective safeguard.

    Paid media needs particular care because asset demand, automated combinations and placement variation can multiply one error quickly. Product imagery deserves a hard verification gate: visual inaccuracies can produce disapprovals or account risk in Merchant Center. Compare the rendered product with the approved reference, including packaging, included components, proportions, color and visible features. If the generated scene obscures that comparison, use a more faithful asset.

    Exceptions should be visible and temporary. Record the business reason, risk owner, supporting evidence and condition that ends the exception. The person requesting an exception should not be its sole approver. Otherwise, deadlines will quietly rewrite your policy one campaign at a time.

    Connect creative governance to SEO, AEO, GEO and PR

    Authenticity problems rarely stay inside the ad account. A generated claim can reach a landing page, product feed, public-relations pitch, social caption, FAQ and structured-data field. Each copy may look defensible in isolation while the combined public record becomes contradictory.

    Build a claim register as the shared layer beneath those channels. For each meaningful claim, record:

    • the canonical wording and any required qualification;
    • the internal evidence or approved public page that supports it;
    • the product, market and context in which it applies;
    • the accountable owner;
    • the channels where it may be used;
    • the disclosure or presentation restrictions attached to it;
    • the condition that should trigger review, correction or withdrawal; and
    • the structured-data properties, feed fields and content components that repeat it.

    This register gives your teams one approved truth rather than several channel-specific versions. Copywriters know which qualifications must survive a short format. PPC teams know which visual implications require evidence. SEO and GEO teams know which public pages should explain and substantiate the claim. Schema implementers know which statements are safe to mark up.

    Structured data should describe visible, supported content. It does not validate a claim merely because the markup is syntactically correct. If the page, product feed and JSON-LD disagree about a product attribute, fix the underlying content system instead of choosing the version most likely to attract a machine.

    Citation readiness also belongs in the governance process. Citations in AI-generated answers can contribute to credibility, and understanding how a brand appears through publicly available information can inform PR decisions. That makes the quality of your supporting pages important beyond conventional rankings.

    A citation-ready page should make the supported claim easy to identify, define its scope and keep the qualification beside it. It should also use consistent product and organization names, connect the claim to the relevant entity and avoid implying that a synthetic scene is proof. A citation can carry an unsupported statement farther; it cannot convert that statement into evidence.

    Monitor governance signals that reveal process failure rather than treating campaign performance as proof that the process worked. Useful signals include assets published without complete provenance, unresolved evidence gaps, exceptions still open, corrections caused by product mismatch, platform disapprovals associated with altered creative and the time required to withdraw a faulty claim across channels.

    Audit what is already live

    Start with a representative set of active ads, landing pages, product feeds, social assets, PR materials and structured data. Classify each AI-assisted element on the integrity ladder. Then trace every consequential claim backward to its evidence and forward to every place it appears.

    Prioritize assets with realistic people, demonstrations, testimonials, product alterations or purchase-critical details. If you cannot identify the source fact, the approving person or all publication locations, you have found a governance gap. Pause the highest-risk asset, establish the missing record and use that case to write the first concrete rule in your policy.

    For your next campaign, define the prohibited transformations in the brief, assign the integrity level before production and name the approver before generation begins. Once those decisions become routine, AI can increase creative capacity without multiplying ambiguity about what your audience is being asked to believe.

    References

  • Branded-Search PPC Defense: A Practical Campaign Playbook

    Branded-Search PPC Defense: A Practical Campaign Playbook

    Your brand ad can be winning clicks while losing the decision. If every branded query triggers the same message and lands on your homepage, a prospect searching Is [Brand] good? or Alternatives to [Brand] still has to find the answer alone. A competitor, affiliate, or review site can make that answer easier to reach.

    A useful branded-search defense does more than bid on your name. It separates navigation from validation, feature research, comparison, and objection handling. That gives you control over the bid, message, proof, and landing page at the point where each decision is being made.

    Treat branded search as four different decisions

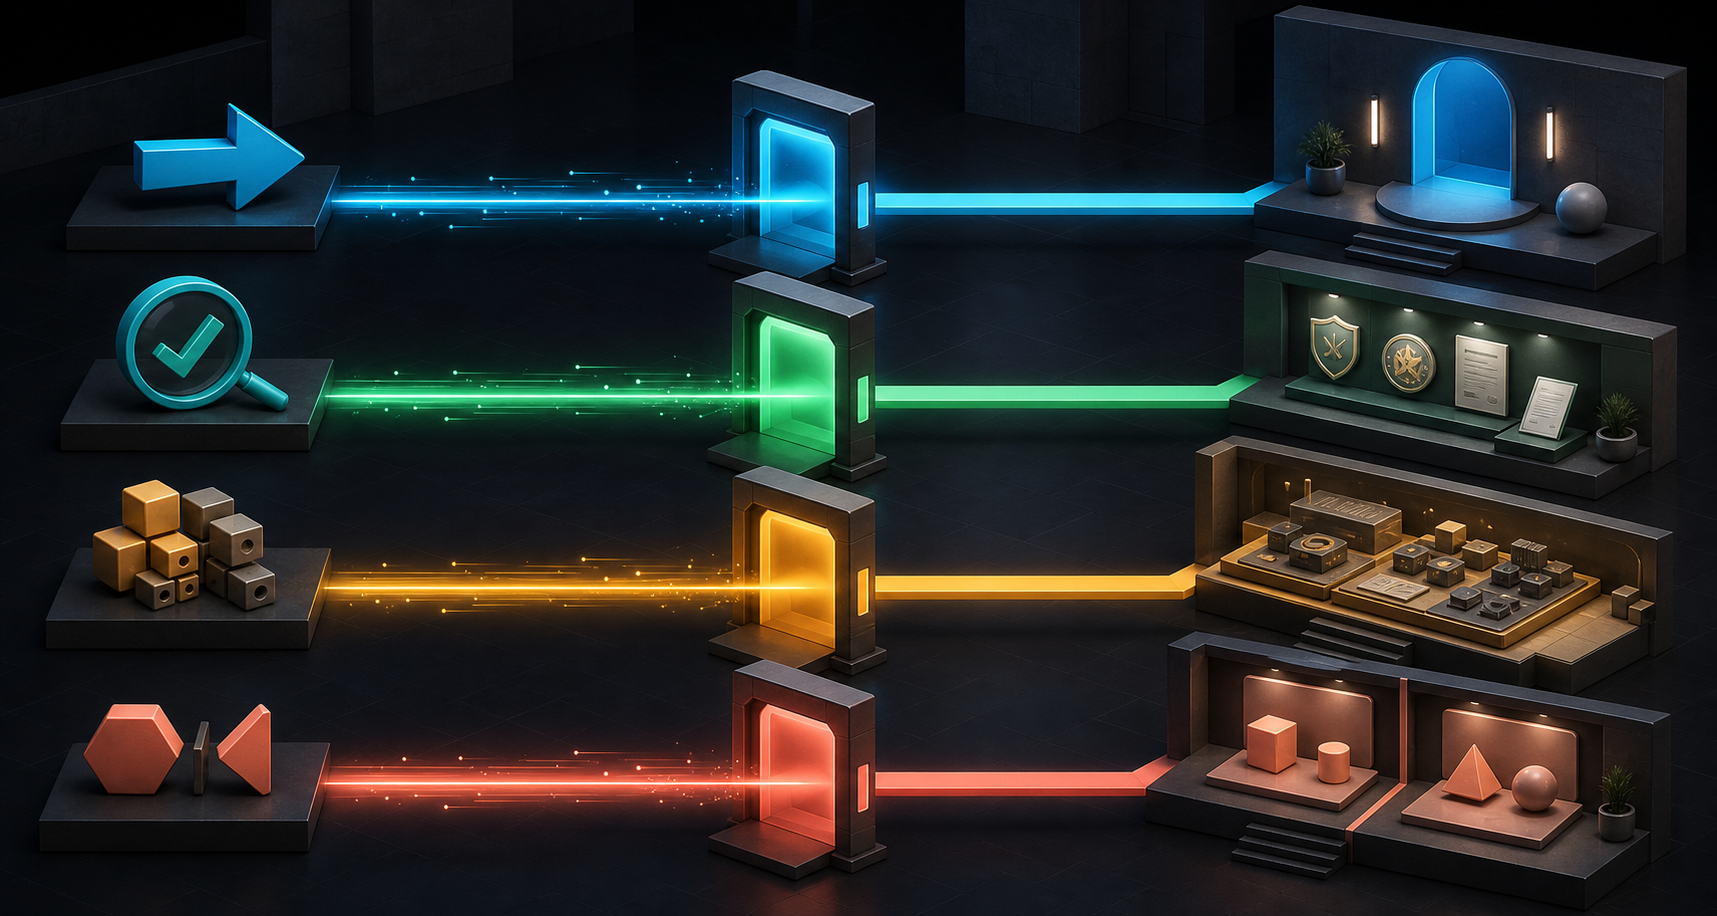
    Four connected isometric scenes depict direct navigation, proof checking, feature research, and comparison as separate decision paths.

    The exact brand name is your baseline, not your complete keyword strategy. People add modifiers when they need reassurance, confirmation, alternatives, or an answer to a specific concern. Those searches carry different risks and should not be forced through one generic ad group.

    Query familyWhat the prospect needsCompetitive openingBest response
    Trust and reputationEvidence that your brand is credible and safe to chooseReview sites can redirect the prospect toward competing offersProof-led ads and a testimonial or reputation page
    Product and featureConfirmation that a required capability existsA rival can introduce its own feature claim before you answerFeature-specific copy, sitelinks, and a relevant product page
    ComparisonHelp choosing between your brand and another optionCompetitors and affiliates can frame the comparison for youTransparent comparison content, clear positioning, and sufficient bids for visibility
    Niche question or objectionA direct answer about cost, suitability, or another concernAn unanswered concern can become a reason to leaveFAQ-style copy and a page that resolves the exact issue

    This division matters because branded searches extend across validation, feature research, comparisons, and narrow questions. Combining them hides which searches face competitive pressure and which landing pages fail to answer the prospect’s real question.

    Keep navigational searches such as the brand name by itself in their own group. Someone trying to reach your website is not in the same decision state as someone asking whether your product is expensive. The first may need a quick route to the correct page. The second needs context before a price can make sense.

    Build the campaign around intent, not one brand keyword

    You do not need a complicated account structure for its own sake. You need enough separation to change the bid, ad, and destination when the query’s purpose changes. In a smaller account, distinct ad groups may provide enough control. Use separate campaigns when an intent family needs its own budget or other campaign-level settings.

    1. Inspect the search terms that actually triggered your branded ads. Do not limit the review to the keywords you originally added.
    2. Label each useful term as navigation, trust and reputation, product and feature, comparison, or niche question. Put unclear modifiers in a review queue rather than forcing them into a convenient category.
    3. Separate the intent families that require different bids, messages, or landing pages. If two terms would receive the same treatment, they do not need artificial separation.
    4. Create a destination map before rewriting ads. Assign each group to the page that answers its question most directly.
    5. Use negative keywords to prevent obvious routing conflicts, but check the effect before expanding them. An aggressive negative list can remove the very modifier coverage the defense is meant to create.
    6. Maintain a controlled way to discover new brand modifiers. Exact-match coverage alone cannot reveal every reputation concern, comparison phrase, or feature question appearing in real searches.

    The destination map is the most important check in this process. If every row still points to the homepage, the structure has changed but the customer experience has not. Either build a page that answers the intent or acknowledge that you are not yet ready to buy that traffic aggressively.

    Query classification also prevents an easy reporting mistake. A high-converting navigational group can make the overall brand campaign look healthy while reputation or comparison traffic quietly underperforms. Review performance by intent family, not only at campaign level.

    Match the ad and landing page to the modifier

    Four icon-based search signals pass through separate colored gateways and lead to four different landing-page environments.

    Your ad should answer the extra words in the search. Repeating the brand name is rarely enough because the prospect already knows it. Use the headline and supporting copy to address what changed when the modifier was added.

    Trust and reputation searches need verifiable proof

    A query such as Is [Brand] good? is a request for reassurance, not a request for your standard value proposition. Lead with evidence the prospect can verify. That might include eligible ratings, genuine awards, a meaningful history in the market, or a concrete customer outcome, but only when the claim is accurate and supported on the destination page.

    Send the click to a page organized around trust. Put testimonials, rating context, credentials, and answers to common doubts where the visitor can find them without navigating through the rest of the site. Available rating or review assets can reinforce the message, but they cannot compensate for a landing page with no proof.

    Feature searches need a direct confirmation

    For a query containing a specific feature, lead with that capability. The brand is already present in the query, so repeating it in every headline may use space that could resolve the question. Use sitelinks to expose closely related feature pages, documentation, demonstrations, or videos when they help the prospect verify the claim.

    The landing page should make the feature easy to confirm and understand. Name what it does, show how it works, and explain any material limits. A vague product overview forces the visitor back to the search results, where a competitor may offer a clearer answer.

    Comparison searches need an honest decision page

    Alternatives to [Brand] signals active comparison. Avoid answering it with copy that pretends no alternatives exist. Explain the criteria that should drive the decision, where your offer fits, and who may not be a good fit. If your pricing is an advantage, make it easy to understand rather than burying it behind a generic call to action.

    A comparison page should not rely on a straw-man competitor. Use criteria a buyer would genuinely consider, keep claims supportable, and make the basis of each comparison visible. Monitor auction insights for this query family because a new advertiser can change the value of maintaining top-page presence even when the core brand term looks quiet.

    Niche questions need a concise answer before a pitch

    A question such as Is [Brand] expensive? exposes a specific hesitation. Route it to an FAQ-style page or a tightly relevant section that answers the concern in plain language. Explain the factors that affect the answer, then give the visitor an appropriate next step.

    Competition may be lighter on narrow questions, so test lower bids instead of copying the bidding posture used for comparison terms. Check the auction rather than assuming the query is uncontested. More importantly, treat newly appearing questions as feedback: repeated concerns may warrant changes to product pages, sales material, organic content, and customer-facing FAQs.

    Set bids by the cost of losing the decision

    Branded campaigns are often managed as if every click has the same defensive value. It does not. A clean navigational query with no visible advertiser pressure is different from a reputation query surrounded by review sites or a comparison query targeted by competitors.

    • Bid assertively on trust and reputation searches when the prospect is close to choosing and competing pages can intercept that choice.
    • Protect comparison visibility when competitors are actively appearing, but make sure the landing page can support the bid with a credible comparison.
    • Evaluate feature terms separately. A high-value feature query may justify more coverage than the unmodified brand name.
    • Start niche questions with controlled bids when competition is limited, then adjust according to conversion quality and auction pressure.
    • Set navigational brand bids from observed competition and incremental value, not from the assumption that the top paid position must be owned at any cost.

    There is real budget risk in bidding aggressively before you segment performance. Easy navigational conversions can subsidize expensive comparison clicks and conceal the difference in your aggregate return. Separate reporting before raising bids, then decide which searches are worth defending and which need a better page first.

    Judge the campaign with a small set of diagnostic questions:

    • Did the important query trigger the intended ad group and message?
    • Did it land on a page that answered the modifier directly?
    • Which competitors, affiliates, or review properties appeared in auction insights for that intent family?
    • Did the click produce the intended conversion or a qualified lead, rather than merely a high click-through rate?
    • Which new modifiers reveal objections, comparisons, or feature needs that your current structure misses?

    Do not use aggregate branded return as the only success measure. Break out conversion rate, conversion value or lead quality, search-term coverage, and auction pressure by intent. The goal is not to maximize paid brand traffic. It is to preserve access to valuable prospects when paid visibility and a better answer can influence the outcome.

    If you need to test whether paid ads are merely capturing clicks your organic result would have received, avoid pausing the entire defense in the middle of visible competition. Start with the least contested navigational segment and preserve coverage for reputation and comparison queries. A broad pause can expose the brand to competitors while producing a result that does not explain which intent family caused the change.

    Key takeaways

    • A bid on the exact brand name covers navigation, not the full branded customer journey.
    • Separate trust, feature, comparison, and niche-question searches when they need different bids, messages, or destinations.
    • Fix the landing-page route before paying more for a query. A stronger bid cannot repair an unanswered question.
    • Use proof for reputation searches, direct confirmation for feature searches, transparent criteria for comparisons, and concise answers for narrow objections.
    • Review auction insights and search terms by intent so easy brand conversions do not hide competitive gaps.
    • Feed recurring modifiers back into your organic pages and FAQs; they reveal the language prospects use when deciding whether to trust or choose you.

    Start with your existing search-term data. Label the terms by intent, identify the valuable queries currently routed to a generic page, and fix those destinations first. Then change the ads and bids. That order keeps branded-search defense tied to the decision you need to protect, rather than the position you want to occupy.

    References

  • ChatGPT Advertising: A Practical Readiness Plan for Brands

    ChatGPT Advertising: A Practical Readiness Plan for Brands

    If ChatGPT advertising has reached your planning meeting, the immediate question isn’t whether to move budget. It is whether you can run a test that teaches you something without weakening trust. ChatGPT ads have entered the marketing landscape, but an emerging ad surface should be treated as an experiment, not a finished channel.

    You don’t need a confident prediction about every format, targeting option, or pricing model. You need a campaign brief that survives uncertainty: a defined user decision, a verifiable claim, a useful destination, independent measurement, and rules for stopping or scaling. Build those pieces now and you can evaluate actual inventory on its merits when it is available to you.

    Do not treat ChatGPT advertising as another search campaign

    A conventional search campaign often starts with a query, a keyword set, and a landing page. A conversational environment starts with a person trying to resolve something. They may be defining a problem, comparing options, checking a claim, or looking for the next step. Your planning should begin with that decision state, even if the advertising product does not offer conversation-level targeting.

    That distinction matters. Copying an existing search ad into ChatGPT may preserve the slogan while losing the reason the person would care. The better question is not, “What can we promote here?” It is, “What unresolved decision can we help the right person make?”

    Give each campaign one primary job:

    • Introduce an option the person may not know exists.
    • Clarify a point that commonly blocks evaluation.
    • Support a comparison with evidence the person can inspect.
    • Offer a practical next step after the person understands the issue.

    An ad that tries to do all of these at once will be difficult to understand and even harder to evaluate. Use a decision brief before anyone writes copy:

    • User state: What is the person deciding, and what do they probably understand already?
    • Question: What would they need answered before taking another step?
    • Claim: What useful, narrow statement can your brand make?
    • Proof: Where can the person verify that statement?
    • Disqualifier: Who should not click, sign up, or buy?
    • Next step: What is the smallest useful action after the ad?
    • Success event: What behavior would show meaningful progress rather than curiosity?

    A compact objective can follow this pattern: when a person is in a defined decision state, present a verifiable claim, send them to the page that resolves the next question, and judge the test by a qualified action. If you cannot fill in every part, the campaign is not ready for budget.

    Keep paid placement separate from AI answer visibility

    An abstract conversational interface shows a promotional tile separated by a glass gap from a background layer of connected answer bubbles.

    Paid placement, an AI-generated response, and your destination page can appear within the same journey, but they do different jobs. Treating them as one system leads to two costly assumptions: that buying an ad will change what the AI says, or that an organic brand mention means the advertising worked.

    SurfacePrimary jobWhat you can prepareCommon mistake
    Paid placementEarn attention and invite a relevant next stepA narrow claim, suitable creative, budget limits, and explicit targeting assumptionsPresenting the ad as if the assistant independently recommended the brand
    AI-generated responseHelp the person understand or resolve the questionClear content, consistent entity facts, current evidence, and valid structured dataAssuming media spend controls or improves the generated answer
    Destination pageProve the claim and move the decision forwardA direct answer, supporting evidence, relevant limitations, a clear action, and measurementRepeating the ad without resolving the person’s next question

    This separation is especially important for SEO, AEO, and GEO teams. Advertising can purchase an opportunity to be seen where inventory is offered. Organic AI visibility depends on whether systems can find, interpret, and use information about your brand. Neither outcome guarantees the other.

    Run a message-parity audit before launch. Compare the proposed ad with the landing page, product documentation, policies, sales materials, and structured data. The same factual claim should have the same scope everywhere. If the ad says a capability is available, the destination should state what it does, who can use it, what conditions apply, and when the information was last reviewed.

    Create a claim register with these fields:

    • The exact claim in plain language.
    • The page or record that substantiates it.
    • The owner responsible for keeping it current.
    • The markets, products, plans, or users to which it applies.
    • The event that should trigger another review, such as a pricing, policy, or feature change.

    Use JSON-LD to describe facts that are also supported by the visible page. Choose schema types and properties that match the page’s real subject. Do not create markup that broadens a claim, hides an important limitation, or describes an offer the visitor cannot verify. Structured data can improve clarity and consistency; it does not turn an unsupported statement into truth or guarantee inclusion in an AI response.

    Build a launch-ready test before you buy media

    Emerging advertising products can change while teams are still planning around them. Keep the stable parts of your strategy separate from platform-dependent details. Your audience problem, evidence, landing experience, economics, and business outcome belong in the stable layer. Inventory, placement, targeting controls, reporting fields, and billing belong in the platform layer and must be verified at activation.

    1. Write a falsifiable test thesis. Use the form: if a defined user state receives a defined claim and next step, a named qualified outcome should improve relative to a documented baseline. Avoid objectives such as creating buzz or seeing what happens.
    2. Record what is known and unknown about the ad product. Verify available placements, sponsorship labels, audience or contextual controls, geographic and language coverage, exclusions, billing, reporting, data use, and content restrictions in the actual buying materials. Do not turn a screenshot, announcement, or assumption into a media plan.
    3. Build the destination around the next question. Its opening should confirm that the visitor is in the right place. Put evidence close to the claim, state relevant constraints, and offer an action proportionate to the person’s readiness. A comparison visitor may need specifications or documentation before a sales form.
    4. Create variants that test one meaningful difference at a time. You might test the framing of the problem, the supporting proof, or the proposed next step. If the claim, audience, destination, and call to action all change together, the result will not tell you what caused the difference.
    5. Instrument the full journey. Use a dedicated landing URL or consistent campaign parameters where supported. Confirm that analytics records the intended onsite action and that your CRM or commerce system retains the acquisition source. Test the path yourself from landing visit to recorded outcome before approving spend.
    6. Set decision rules in advance. Name the metric that permits scaling, the spend ceiling, the conditions that require a pause, and the person authorized to make each decision. This prevents a novelty-driven campaign from continuing merely because it produced traffic.
    7. Run an adversarial review. Ask someone outside the campaign team to read the ad and destination as a skeptical prospect. They should be able to identify who the offer is for, what is being claimed, where the evidence sits, what happens next, and what important limitation applies.

    Keep this material in a reusable launch packet. If the available ChatGPT inventory does not fit your decision state, measurement needs, risk limits, or economics, you can decline the test without discarding the strategic work. The same brief can guide organic content, another paid channel, or a later campaign when the product is a better fit.

    Set trust guardrails and measurement rules together

    An unbranded product moves through checkpoints represented by a magnifying lens, a balanced scale, and an independent sensor before reaching an abstract conversational screen.

    Protect the boundary between assistance and promotion

    A conversational interface can feel advisory. When a paid message appears close to a generated response, a person may infer a relationship between them even when the placement is separate. Your creative should not intensify that ambiguity.

    • Do not imitate the assistant’s voice in a way that hides the commercial role of the message.
    • Do not imply that ChatGPT independently selected, verified, ranked, or endorsed the product unless that precise claim is demonstrably true and permitted.
    • Make the sponsor identity and destination clear within the controls available to the advertiser.
    • Use claim language that remains accurate outside an ideal context. Avoid an unqualified best, guaranteed, safe, or suitable claim when the destination cannot substantiate it.
    • Do not assume that private conversational details are available for targeting. Treat every claim about contextual signals, audience creation, retention, and advertiser access as unverified until the platform documents it.
    • Route campaigns involving regulated or sensitive decisions through qualified legal, privacy, and compliance review before targeting or creative goes live.

    Add an adjacency plan as well. Decide what your team will do if the ad appears near an unsuitable response, if a user interprets the placement as an endorsement, or if a product change makes the claim stale. The plan should identify who can pause the campaign, who captures evidence, who contacts the platform, and who corrects the destination or structured data. Waiting for an incident to establish ownership turns a manageable problem into a prolonged one.

    Measure qualified decisions, not the novelty of the click

    Early curiosity can produce visits without producing durable demand. A click therefore tells you that the placement earned attention, not that it reached the right person or changed a business outcome. Build a measurement ladder that distinguishes those stages:

    • Delivery: Did the platform serve the campaign as configured?
    • Qualified visit: Did the visitor reach the intended page and meet your predefined relevance conditions?
    • Decision behavior: Did the visitor inspect documentation, compare an option, check compatibility, begin a suitable workflow, or complete another meaningful step?
    • Business outcome: Did the journey produce a qualified lead, purchase, activation, or other result that the organization already recognizes?
    • Outcome quality: Did those results remain useful after the initial conversion, or did they produce avoidable cancellations, disqualification, support burden, or low-value activity?

    Use platform reporting to understand delivery, your first-party analytics to understand onsite behavior, and your CRM or commerce records to understand downstream outcomes. If those systems disagree, investigate the definition and handoff before changing the campaign. A dashboard that blends incompatible events can look precise while answering the wrong question.

    Where a credible comparison is possible, evaluate exposed and unexposed groups or use another controlled design. If the platform does not support that design, run a bounded pilot, compare it with a relevant baseline, document competing explanations, and label the conclusion as directional. Do not present last-click attribution as proof that the ad caused the result.

    Scale only when business outcome and outcome quality move in the same direction. If clicks rise while qualified actions stay flat, the answer is not automatically more spend. Revisit the user state, message, placement, and destination. If conversions rise but quality declines, tighten qualification before expanding reach.

    Key takeaways

    • Treat ChatGPT advertising as a bounded experiment until its available formats, controls, economics, and reporting fit your use case.
    • Plan around the person’s unresolved decision, not around a recycled search ad or a broad desire for awareness.
    • Keep paid placement, organic AI visibility, and landing-page conversion separate in your strategy and measurement.
    • Maintain message parity across ad copy, visible content, product documentation, policies, and JSON-LD.
    • Verify platform capabilities in the real buying materials instead of assuming conversational context is targetable or visible to advertisers.
    • Predefine evidence, spend limits, stop conditions, trust guardrails, and qualified outcomes before launch.

    Your next move is a readiness review, not a forecast. Put the decision brief, claim register, destination, tracking map, and risk rules into a shared launch packet. When suitable inventory is available to your team, you will be able to run a controlled test, learn from it, and scale only when the result survives both a trust check and a business check.

    References

  • Google Ads Automation Without Losing Control of Your Brand

    Google Ads Automation Without Losing Control of Your Brand

    You want Google Ads automation to remove setup work, not remove your authority. The distinction matters most at launch, when a convenient default can quietly become a live campaign decision before anyone has checked it against your brand rules.

    The practical answer is not to reject automation. Give it a defined operating boundary. Decide which choices Google may make, which require human approval, and which must remain locked. Then audit the two places where that boundary is particularly easy to miss: accelerated campaign creation and location-based imagery.

    Treat automation as delegated authority, not a feature toggle

    Brand control is not the same as manual control. A campaign can use automation extensively and still be well governed. The real question is whether the system is making decisions inside a boundary you approved.

    For every automated area, define five things before launch:

    • Scope: What is Google allowed to select, assemble, or change?
    • Inputs: Which images, locations, claims, landing pages, and business data may it use?
    • Approval level: Can the decision go live automatically, or must someone review it first?
    • Consequence: What could happen if the output is wrong – wasted spend, brand inconsistency, an incorrect location, or a compliance problem?
    • Owner: Who checks the setting, approves exceptions, and acts when an unwanted asset appears?

    Use those answers to divide decisions into three control classes. Keep legal claims, regulated language, required disclaimers, protected visual assets, and prohibited imagery in a locked class. Put new creative sources and unfamiliar location imagery in a review-required class. Delegate routine choices only when their possible outputs are already acceptable.

    This classification avoids two common mistakes. The first is approving automation in the abstract without approving its inputs. The second is locking down every campaign decision so tightly that automation cannot do useful work. You need control at the points of consequence, not manual effort everywhere.

    Audit a faster campaign setup as if it were a draft

    A reviewer inspects generic campaign cards at a checkpoint beside an automated advertising setup line.

    Google Ads has tested an onboarding option labeled Create an account with campaign for faster setup. It bundles account creation with a pre-built campaign, reducing the decisions a new advertiser must make before reaching a launch-ready state.

    That convenience changes the order of work. In a conventional setup, you make choices while constructing the campaign. In a pre-built flow, you may inherit choices and review them afterward. The work has not disappeared; it has moved into the approval step.

    Treat anything created by the onboarding flow as a proposed configuration. Before it can spend, review it in this order:

    1. Confirm the business outcome. Make sure the campaign is built around the action you actually value. A polished setup is still wrong if it optimizes for an incidental action rather than the outcome your team intends to fund.
    2. Check measurement. Verify that the conversion action and destination correspond to that outcome. Resolve ambiguous or duplicate actions before using their data to steer automated decisions.
    3. Verify geography and locations. Confirm where the campaign should operate, which business locations belong to it, and whether any location should be excluded. This is especially important when several branches or franchisees share an account structure.
    4. Inspect the spending boundary. Check the budget, campaign status, and any settings that determine when the campaign can begin spending. Do not let completion of the setup flow serve as approval to launch.
    5. Review every customer-facing element. Open the ads, assets, images, copy, business information, and landing-page destinations. Look at what a customer could actually encounter, not only the campaign name and summary screen.
    6. Identify automated choices. Record which parts of targeting, creative assembly, or asset selection can change without another manual approval. Labels and available controls can vary by campaign type, so document the settings that are present in the account rather than relying on a generic checklist.
    7. Name the approver. One person should be accountable for the launch decision. Shared access is not the same as clear ownership.

    The faster setup appeared as a test rather than an officially announced universal workflow, so your operating procedure should not depend on every account displaying it. Write the procedure around the control objective: any pre-configured campaign receives the same pre-launch review, regardless of what Google calls the entry point.

    Lock down location imagery before it reaches an ad

    A brand manager reviews storefront and streetscape image tiles as an approval gate filters location-based advertising imagery.

    Campaign settings are only one part of the control surface. Google has also extended automation into creative inputs. In the Shared Library, under Location Manager, a setting called Google Owned Location Data may allow imagery from Google’s database to appear in ads connected to your business locations. When active, that creates a route for images your brand team did not directly approve.

    The critical distinction is simple: an image associated with a location is not automatically an image approved to represent your brand. It may show an outdated storefront, inconsistent signage, an unsuitable angle, a product that is no longer offered, or a visual that does not meet your organization’s rules. For a regulated business or franchise network, the problem can extend beyond aesthetics into compliance and local brand obligations.

    Use this location-creative audit:

    1. Open the Google Ads Shared Library and go to Location Manager.
    2. Look for Google Owned Location Data. If it is present, record whether it is active and which locations could be affected.
    3. Compare the possible image source with your brand policy. Ask whether imagery must receive individual approval or whether an approved source is sufficient.
    4. If the setting is active but conflicts with that policy, turn it off through the available account control and record the change.
    5. Review the ads and location-related assets separately. Changing a source setting is not a substitute for checking what is already associated with the campaign.
    6. Keep evidence of the approved state: the setting name, its value, the account or location scope, the reviewer, and the date of review.

    Do not disable the setting reflexively if your brand can accept a broader image pool. A local business with flexible visual standards may decide that the additional imagery is useful. That is a valid governance choice when it is explicit, owned, and monitored. It is not a valid choice when nobody knew the image source existed.

    If individual creative approval is mandatory, source-level permission is too broad. Keep the setting off and provide approved assets through a controlled workflow. If your policy permits automated selection from a wider pool, assign someone to review live output and define what would trigger removal.

    Build controls that survive handoffs and interface changes

    A one-time audit protects one moment. Durable brand control needs a small operating record that another employee, agency, or franchise manager can understand without reconstructing past decisions.

    Create an automation control register with one entry for each consequential setting. It does not need to be elaborate. Record:

    • the account, campaign, or location in scope;
    • the exact setting or feature name shown in the interface;
    • the approved state and the reason for it;
    • the assets or data sources automation may use;
    • the person who owns the decision;
    • the evidence captured during the last review;
    • the event that requires another review.

    Use event-based review triggers instead of relying only on a calendar reminder. Recheck controls when you create an account, accept a pre-built campaign, connect or change business locations, add a franchise or agency user, broaden an asset source, or notice unexpected creative in a live ad. These are the moments when the system’s authority can change even if your written brand policy has not.

    Performance reporting also needs a brand-control layer. Alongside the campaign’s primary business metric, track exceptions: unapproved images, incorrect location data, copy that required replacement, compliance reviews, and time spent tracing the origin of an asset. A campaign can improve a performance metric while creating unacceptable governance work. If the report excludes that work, the automation will look safer than it is.

    When an unwanted asset appears, use a consistent response:

    1. Contain it. Pause or remove the affected customer-facing output, or disable the relevant source, using the narrowest action that prevents further exposure.
    2. Capture evidence. Record the asset, campaign, location, setting state, and where the output appeared before changing multiple variables.
    3. Trace the authority path. Determine which setting, data source, inherited configuration, or user action permitted the asset to appear.
    4. Correct the control. Fix the source condition, update the register, and review other campaigns or locations that share it.
    5. Restore deliberately. Resume delivery only after the output and the enabling setting both match the approved policy.

    If the creative could create regulatory, contractual, or legal exposure, involve the appropriate compliance or legal owner before restoring it. A media buyer should not make that judgment alone.

    Key takeaways

    • Automation should operate within an approved boundary covering its scope, inputs, approval level, consequences, and owner.
    • A pre-built campaign is a draft, not a launch decision. Verify the outcome, measurement, geography, budget, customer-facing assets, and automated choices before it can spend.
    • Check Shared Library > Location Manager for Google Owned Location Data. If it is active, decide explicitly whether Google’s location imagery meets your approval policy.
    • Separate source permission from creative approval. Allowing an image source does not mean every image from that source is suitable for your brand.
    • Record consequential settings and recheck them when accounts, campaigns, locations, asset sources, or responsible teams change.
    • Evaluate automation with both performance results and brand exceptions. Efficiency that creates compliance or reputation problems is not a net gain.

    Your next step is narrow and concrete: audit the newest automated campaign in your account, then inspect Location Manager. For each choice you find, write down who authorized it and what inputs it may use. Any setting without a clear answer is not yet under brand control.

    References

  • How to Protect Brand Visibility in Google AI Search

    How to Protect Brand Visibility in Google AI Search

    You search your brand in Google and the AI-generated answer sounds confident, polished, and wrong. An old complaint has become a present-tense fact. A forum opinion outweighs your published policy. Or your brand is visible, but the answer frames it in a way no conventional ranking report would reveal.

    You cannot solve that problem by publishing more generic brand content. You need to identify the exact claim Google is repeating, trace the information environment behind it, correct the weakest evidence, and make the current facts easier to retrieve and interpret. This gives you a practical way to do that.

    Separate visibility from accurate representation

    A brightly lit geometric object appears distorted in one mirror and accurately reflected in another.

    A high organic ranking tells you that a page can be found. It does not tell you whether Google will use that page in an AI answer, whether the answer will cite it, or whether the resulting description will represent your brand accurately.

    That distinction matters because Google AI Overviews can draw information from conversational platforms such as Reddit and Quora. In some cases, old or inaccurate discussions can be resurfaced without enough context. An anecdote may then sit beside an official statement without a clear distinction between personal experience, verified fact, and current policy.

    This creates three separate jobs for your team:

    JobQuestion it answersWhat to inspect
    DiscoverabilityCan Google find and understand your material?Indexable pages, internal links, crawl access, page purpose, and entity naming
    InclusionDoes your material influence the AI answer?Citations, linked pages, quoted facts, and competing domains
    RepresentationIs the answer accurate, current, and properly qualified?Individual claims, dates, scope, omitted context, and opinion presented as fact

    Do not combine these into one visibility score. A brand can rank well but be represented poorly. It can also be described accurately without receiving a citation. Each condition requires a different response.

    Key takeaways

    • Audit what Google says about your brand, not only where your pages rank.
    • Break an AI answer into individual claims before deciding how to respond.
    • Correct factual errors at the pages and platforms that support them; publishing an unrelated positive story will not repair the evidence chain.
    • Make official facts explicit, dated, scoped, and consistent across visible copy and structured data.
    • Treat legitimate criticism differently from false or outdated claims. Reputation management should improve accuracy, not erase disagreement.

    Audit the questions that can change a decision

    Searching only your brand name produces an incomplete audit. People encounter reputation problems through questions about trust, policies, products, comparisons, and specific incidents. Build your query set around those decisions.

    Start with query families such as:

    • Identity: what is the brand, who owns it, where does it operate, and which similarly named entity is it?
    • Trust: is the brand legitimate, reliable, safe, or suitable for a particular use?
    • Customer experience: what problems do customers report, and how does support handle them?
    • Policies: what are the refund, cancellation, warranty, privacy, or eligibility terms?
    • Products and services: what does an offering include, exclude, cost, or require?
    • Comparisons: how does the brand differ from a named alternative, and what tradeoffs matter?
    • Events: what happened during a controversy, outage, recall, policy change, or other decision-relevant development?

    Add the language customers actually use. Support tickets, sales objections, review themes, branded search terms, and community discussions can expose questions that your marketing navigation does not. The goal is not to generate every conceivable prompt. It is to cover the questions where a wrong answer could change trust or action.

    For each query, use the following workflow:

    1. Save the query exactly as entered. Small wording changes can turn a factual lookup into a request for opinions.
    2. Capture the complete AI answer, its visible citations, linked pages, and any language expressing uncertainty.
    3. Record the date, location context, account state, device context, and other setup details needed to repeat the check.
    4. Split the answer into atomic claims. A statement about poor support, for example, might contain separate claims about response availability, refund handling, complaint volume, and current policy.
    5. Label each claim as accurate, incomplete, outdated, unsupported, subjective, or attached to the wrong entity.
    6. Map the page or discussion that appears to support each problematic claim. If no visible citation supports it, record that rather than guessing.
    7. Assign a correction owner and a verification step. Ownership may sit with content, SEO, public relations, customer support, product, or legal review depending on the claim.

    Prioritize consequence before sentiment. A mildly negative opinion is usually less urgent than a false statement about eligibility, pricing, safety, availability, contractual terms, or the identity of the company. An error that could cause a customer to take the wrong action should move ahead of a complaint that is unpleasant but clearly framed as opinion.

    Also check whether the claim is reproducible. One captured answer is evidence of an occurrence, not proof that every searcher sees the same thing. Use a documented setup and repeat the important query variants before estimating the size of the problem.

    Repair the evidence chain, not just your homepage

    Blank source documents and archive objects connect to a clear sphere through an evidence chain with one broken link being repaired.

    When a misleading answer cites a community thread, rewriting your homepage may have little effect on that specific claim. The correction needs to reach the part of the information environment that is unclear, stale, or unsupported.

    Choose the response according to the type of problem:

    • Factual error: publish the correct fact on the most relevant official page and provide the primary evidence that supports it. If a third-party page contains the error, send its owner the exact sentence, correction, evidence URL, and applicable date.
    • Outdated fact: state what changed, when the current position took effect, which products or regions it covers, and whether the old condition still applies anywhere.
    • Missing qualification: add the condition that changes the meaning. A policy may depend on product type, purchase channel, location, account status, or another clearly defined circumstance.
    • Identity collision: use the full entity name, location, legal or trading relationship, and distinguishing details consistently. Create an explicit clarification page if people regularly confuse separate organizations.
    • Legitimate complaint: acknowledge the underlying experience and explain the current resolution path. Do not relabel a genuine customer opinion as misinformation merely because it is unfavorable.
    • Unsupported generalization: answer with bounded language and checkable facts. A handful of complaints does not establish a universal condition, but a vague assurance that customers are happy does not rebut it either.
    • Operational failure: fix the underlying process. Content cannot permanently compensate for a policy or customer experience that continues to generate the same criticism.

    A useful correction packet is short and specific. It should contain the disputed claim, the corrected wording, the evidence, the effective date, the affected product or market, and a contact who can answer verification questions. This format gives editors, community moderators, partners, and internal teams something they can act on without reconstructing the issue themselves.

    When you respond in a forum, write for the later reader as much as the current participant. Identify your relationship to the brand, answer the factual point directly, link to the relevant evidence, and stop once the correction is clear. Arguing through every comment can make the factual answer harder to find. Fabricated endorsements and undisclosed brand advocacy are not correction strategies.

    Do not create a public rebuttal page for every fringe remark. Repeating an obscure accusation on an authoritative brand domain may give it a clearer association with your entity. A dedicated response becomes more reasonable when the claim is already discoverable, affects a real decision, and requires context that cannot fit on an existing policy, product, or company page.

    Publish facts that machines cannot easily misread

    AI-readable content is not content written in a robotic style. It is content in which the subject, claim, scope, date, and evidence are difficult to confuse.

    For every brand fact that affects a decision, inspect the page that is supposed to establish it:

    • Answer the central question near the beginning. Do not bury the current policy below a long brand narrative.
    • Name the entity and offering explicitly. Pronouns and internal product nicknames can create ambiguity when a passage is read outside the page.
    • State scope beside the claim. If a term applies only to a region, plan, product version, or purchase channel, put that condition in the same passage.
    • Show the effective or reviewed date where freshness changes the meaning. A generic site copyright date does not establish when a policy was checked.
    • Explain exceptions in plain language. A clean headline followed by contradictory fine print is easy for people and machines to misinterpret.
    • Link related facts to a stable, canonical destination. Conflicting policy summaries across help pages, campaign pages, PDFs, and partner sites create avoidable uncertainty.
    • Identify editorial or organizational ownership. Readers should be able to tell who maintains the information and how to report an error.
    • Keep critical facts in accessible HTML rather than only inside images, video, or downloadable material.

    Structured data can reinforce this clarity, but it cannot certify a claim or suppress criticism. Use JSON-LD that matches the visible page. Choose a schema type that describes the actual entity or content, connect consistent identifiers, and include only properties you can support on the page. Organization markup can clarify organization-level identity; product markup belongs with an actual product; FAQ markup should reflect questions and answers people can see. Markup that contradicts the page creates another inconsistency rather than an authority signal.

    Technical health belongs in the same operating program but a different diagnostic lane. Crawl restrictions, broken internal links, inaccessible content, accidental duplication, and unstable pages can obstruct your official information. Core Web Vitals and AI visibility also deserve careful separation: improving page experience may strengthen the site, but it does not correct an external factual error by itself. If the AI answer repeats a stale forum claim, a performance score is not the evidence repair.

    Review consistency outside your site as well. Business profiles, social biographies, distributor pages, app listings, support portals, press materials, and executive profiles should not disagree on basic identity or policy facts. You do not need identical prose everywhere. You do need compatible facts, dates, names, and relationships.

    Build a reputation workflow that survives the next answer

    A one-time cleanup will not catch narrative drift. Products change, policies change, complaints accumulate, and old discussions remain available. Monitoring should therefore be tied to both a recurring review and events that alter what searchers need to know.

    Recheck priority queries after a product launch, policy revision, naming change, service disruption, public controversy, major correction, or update to a page that previously supported the wrong answer. Keep the original captures so you can distinguish a genuine change from a difference in wording.

    Your scorecard should track more than whether the brand appears:

    • Presence: does an AI-generated answer appear for the query?
    • Accuracy: which atomic claims are correct, incomplete, unsupported, outdated, or misattributed?
    • Source mix: do the visible links include official material, independent reporting, community discussion, or pages unrelated to the correct entity?
    • Freshness: do the answer and supporting pages reflect the current policy or product state?
    • Framing: are opinions labeled as opinions, or converted into broad factual language?
    • Consequence: could the answer change a purchase, support action, application, visit, or trust decision?
    • Remediation status: which page, platform, or process is being corrected, who owns it, and what evidence will show that the work is complete?

    Set escalation rules before a problem becomes emotional. A false claim involving safety, legal status, contractual terms, or another high-consequence matter should go to the relevant subject-matter and legal reviewers before a public response is improvised. A current service complaint belongs with the operational owner as well as the reputation team. A low-consequence opinion with no factual error may need observation, not intervention.

    The objective is not to force every AI answer to sound positive. It is to make important answers accurate, current, attributable, and properly qualified. That standard gives SEO, content, public relations, support, and leadership a shared definition of success.

    Start with the branded query where an incorrect answer could do the most damage. Capture the result, split it into claims, and repair the first weak link in the evidence chain. Once that workflow works for one query, apply it to the rest of your decision-critical set. That is how Google AI reputation management becomes an operating practice instead of a reaction to the next unpleasant screenshot.

    References

  • Mastering Google Ads in Niche Markets: Strategies for 2026

    Mastering Google Ads in Niche Markets: Strategies for 2026

    Operating in niche markets with Google Ads presents unique challenges, and it’s something I’m navigating in 2026. While the search volume might be low, the potential for opportunity is significant.

    I’ve noticed that in targeted markets, people might only search a handful of times each month for my solutions. It’s a stark contrast to other advertisers who can test a plethora of headline variations with ease.

    Many niche advertisers mistakenly apply high-volume strategies to their ads. In my experience, without sufficient data, Google’s automation struggles, which can dampen or entirely stall results.

    Through this guide, I’ve found out what actually works when dealing with low search volumes and extended conversion timelines.

    Why Low-Volume Markets Challenge Google Ads

    There are a couple of scenarios I’ve encountered:

    • I own my brand space: My distinctive brand ensures that when people search for my company, I appear prominently with unique industry terms.
    • I get washed out: Sometimes, my keywords compete with those of larger brands, making it tough to stand out. Here, I battle consistent keyword pollution.

    Each situation requires a distinct approach to effectively manage my advertising strategies.

    Smart Bidding strategies, like Target ROAS, require substantial conversions that niche environments often don’t produce solely from search traffic.

    If my campaigns do hit those numbers, it’s usually due to a budget burn collecting low-quality data. It’s unsustainable for many, including myself.

    However, I’ve found that automation remains viable by feeding Google the right signals differently.

    Dig deeper: Understanding Google Ads Automation: Benefits and Drawbacks

    Signal Stacking When Search Volume is Limited

    Google’s AI has shown me that signal collection is pivotal. It learns from every conversion signal beyond just keywords.

    In my campaigns, I’ve prioritized building signals from various sources to enhance learning.

    Start with Offline Conversion Tracking

    I’ve learned that capturing offline interactions, such as phone calls and CRM entries, enriches my conversion data significantly.

    Using Google’s Data Manager API, I synchronize my sales data back to my Google Ads, amplifying the effectiveness of Smart Bidding.

    Upload Customer Match Lists

    Even a small list of quality email addresses allows Google to recognize patterns, helping me target similar audiences effectively.

    A carefully crafted list of high-value customers can outshine a larger list of less engaged subscribers.

    Use Audience Signals Strategically

    By layering audience signals in Performance Max, I’ve been able to better educate Google about my ideal customer.

    Tailoring custom segments based on recent searches has been key, aligning with detailed insights shared by experts like Jyll Saskin Gales.

    If I dominate my brand space, my focus is on signal quality over quantity. For competitive titles, using negatives is vital.

    Negative audience signals are crucial in targeting only the most relevant consumers, sidelining those that competitors might attract.

    Dig deeper: 5 Google Ads Strategies to Leave Behind in 2026

    Structuring Campaigns for Small Markets

    Relying solely on Search campaigns has proven ineffective for me, especially as Google’s AI Overviews account for a significant percentage of queries.

    Start with Search, then Move to Performance Max

    Performance Max requires solid conversion data, focusing on qualified leads or paying customers to truly optimize results.

    Audience signals guide me in allocating budgets wisely, ensuring I’m not wasting resources.

    Performance Max has served me well once I’ve accumulated sufficient data. However, dealing with keyword pollution requires aggressive negative tactics.

    ```json
{
  "alt": "Bar chart comparing conversions and cost per conversion for Exact, Broad, and Phrase.",
  "caption": "Analyzing keyword match types: A bar chart illustrates the performance of Exact, Broad, and Phrase in terms of conversions and cost-efficiency.",
  "description": "This bar chart displays the performance of three keyword match types: Exact, Broad, and Phrase. The data is represented in two colors: blue for conversions and orange for cost per conversion. Exact keywords show the highest conversions, while Phrase keywords indicate a higher cost per conversion. This visual aids in comparing the effectiveness of different keyword strategies in digital marketing."
}
```

    Use Demand Gen for Awareness

    Introducing Demand Gen has allowed me to reach users across YouTube and Gmail before they actively engage in search for my offerings.

    This strategy builds awareness, paving the way for future branded searches.

    Protect Your Brand Terms

    While organic rankings are important, I maintain a dedicated budget to safeguard my brand’s terms, especially when keywords overlap with the competition.

    Even during slower periods, maintaining control over brand terms remains a priority.

    Dig deeper: Harnessing Demand Gen Campaigns: When and Best Practices


    Keyword Strategy and Match Types

    Based on my data from a niche B2B SaaS client, exact match keywords consistently deliver leads at a lower cost, showcasing the benefits of targeted campaigns.

    Adopting a broad match approach without sufficient data may lead to unnecessary spending on low-converting searches.

    After solidifying my match strategies, I start tight and carefully expand:

    • Initiate with exact match keywords on strong intent terms.
    • Incorporate phrase matches for variation while being wary of broad match until robust data guides me.
    • Broaden match scope after accumulating 30+ conversions.

    Critical Search Term Mining

    With niche volumes, Google may not always show which search terms directed traffic, but when available, these insights are invaluable for market comprehension.

    Mining Google Ads search terms

    The terms that do surface offer significant insights:

    • Valid searches leading to clicks but not conversions (adjust bids or landing pages).
    • Wasteful, irrelevant searches depleting budget (add instantly as negatives).
    • Incorporating new keyword variations identified.
    • Handling early funnel searches strategically.

    In scenarios where brand terms are unique, I find broad match approaches more forgiving.

    Conversely, with competitive keywords, a robust list of negative keywords is imperative before considering broader matches.

    Dig deeper: Optimizing Google Ads: 5 Tips for Search Terms Reports

    Crafting Ad Copy for Niche Audiences

    Considering the limited traffic in niche markets, precise ad copy is critical to conversion success.

    Speak Your Market’s Language

    When dealing with specialized jargon, using precise language ensures proper targeting to avoid attracting uninterested clicks.

    Feature Core Differentiators Early

    By highlighting essential differentiators in the first headline, I’ve ensured my ads communicate their unique positions effectively.

    Although pinning headlines might increase CPCs, the precision outweighs these costs in niche markets.

    Test Dynamic Keyword Insertion Strategically

    While DKI can automate relevance in high-volume scenarios, it’s essential to test its impact cautiously within niche keywords.

    Dig deeper: Creating Effective Google Ads Copy

    Full Utilization of Headline and Description Slots

    With limited ad runs, maximizing headline and description slots provides ample opportunity for optimization and engagement.

    Targeted Landing Page Design

    Landing pages I design don’t just capture leads; they guide prospects through seamless self-qualification, emphasizing detailed specs or clear differentiation as necessary.

    My pages prioritize standing out, expecting that visitors have explored competitor offerings.

    Optimizing PPC Landing Page Experience

    Tracking Conversions in Extended Sales Cycles

    Standard 30-day attribution doesn’t cut it when dealing with niche markets, where decision cycles may span months.

    ```json
{
  "alt": "Google Ads report showing search terms data with a tooltip explaining hidden search terms.",
  "caption": "Peek behind the Google Ads curtain: see how much data remains hidden in search term reports due to lack of significant search volume.",
  "description": "This image displays a section of a Google Ads report focused on search terms, with metrics like clicks and costs. A tooltip is revealed, explaining that some search terms are not detailed in the report due to insufficient search volume. Key indicators in the table include clicks, cost, and CTR, providing insights into ad performance. Keywords: Google Ads, search terms, report, tooltip, digital marketing."
}
```

    I’ve extended my conversion windows for true reflection of my actual sales cycle, ensuring accurate attribution and strategy alignment.

    Differentiating conversion actions by their place in the funnel allows optimized bidding strategies focusing on true business metrics.

    Through offline conversion imports, I maintain indefinite attribution, enhancing synergy between marketing efforts and real business outcomes.

    Data-driven attribution lets me see broader campaign contributions, like Demand Gen, even when they lack last-click credit.

    Budgeting for Success with Limited Spend

    Working within budgets of $2,000 to $10,000 a month highlights the importance of strategic spend allocation in niche markets.

    Protecting brand terms, even with minimal branded budgets, is key if existing brand awareness is present.

    If brand awareness is lacking, demand gen efforts potentially offer better returns through top-of-funnel initiatives.

    Focusing budget on high-intent campaigns, complemented by Performance Max with targeted audience signals, remains my primary strategy.

    For niche markets, instead of increasing budgets at signs of limitation, I aim to enhance quality scores and target high-performance geographies.

    Analyzing areas with heightened demand, I adapt my strategies, reallocating funds to regions that yield the best results.

    Dig deeper: Understanding Google Ads Spending Dynamics

    Strategic Competitive Analysis

    Personal relationships with key competitors in niche markets enable unique strategic opportunities.

    By using Auction Insights reports, I tailor strategies when competing strategically on impression share and geography.

    Avoiding direct competitor bidding saves costs, allowing me instead to target gaps left unguarded by competitors.

    Monitoring competitor shifts in marketing approach aids my proactive adjusting of strategies.

    The Winning Formula in Niche Marketing

    If You Own Your Brand Space

    With established brand spacing, I can be more aggressive with broad matches, driving focus towards problem-based searches.

    Demand Gen campaigns help cultivate market awareness, ensuring my detailed landing pages capture quality engagement immediately.

    If You’re Battling Keyword Pollution

    In scenarios with dense keyword competition, maintaining exact matches up to 50 conversions is vital for efficiency.

    Crafting extensive negative keyword lists reduces inefficiency, aligning campaigns with high-quality audience interactions.

    Precision in demand gen campaigns is necessary, targeting custom market segments instead of industry-wide interests.

    Immediate differentiation is crucial on landing pages, so prospects understand value quicker than with competing alternatives.

    Strategies for Niche Advertising Success in 2026

    In 2026, small budget advertisers win not by spending, but by leveraging quality signals, focusing on visibility and precision.

    • My focus remains on signal quality surpassing search volume expectations.
    • Visibility across multiple platforms ensures stronger engagement than singular strategies.
    • Precise audience targeting outweighs the advantages of simply broader reach.

    Feeding Google automation with strategic, tailored data is essential to unlocking potential in niche advertising.

    The key to success in niche markets is knowing which automation to implement at the right time, the patience to accumulate sufficient data, and the foresight to disregard outdated strategies.


    Inspired by this post on Search Engine Land.


    crushpress.ai community screenshot
  • Google Review Deletions: A Local SEO Response Plan

    Google Review Deletions: A Local SEO Response Plan

    Your Google Business Profile review count dropped. A few five-star reviews vanished, the average changed, or the numbers in your report no longer match the live listing. The wrong response is to rush out and replace the missing reviews before you know what happened.

    Your first job is to separate an isolated disappearance from a repeatable moderation pattern. Once you can see which ratings, review ages, locations, and acquisition methods are involved, you can protect your local SEO reporting and correct the part of your review process that may be creating risk.

    Key takeaways

    • Five-star reviews are not protected from removal. Positive reviews can receive especially close scrutiny in some industries and markets.
    • Do not assume only new reviews are at risk. Google can remove reviews months after publication, including older feedback that once appeared stable.
    • Track displayed review count, average rating, individual disappearances, and review age by location. A stable rounded average does not prove that nothing was deleted.
    • Pause incentives and audit how reviews are requested before launching a replacement campaign. More requests will not fix a collection process that keeps producing moderation risk.

    A deleted review is not the same as a local ranking penalty

    A review can disappear at the same time that local visibility changes, but that timing does not prove Google applied a manual penalty to the business. The immediate effects are narrower and easier to verify: the public review count changes, the displayed average may move, recent feedback may become thinner, and your historical reports stop matching the live profile.

    Those changes still matter. Customers see a different reputation profile, while your SEO team may compare current performance with a review set that no longer exists. An analysis of 60,000 Google Business Profiles between January and July 2025 found that removals were becoming more common, with momentum increasing near the end of the first quarter. The pattern included five-star feedback, not just critical reviews.

    Start with the arithmetic. If the count falls and the average falls, the removed set probably had a positive net effect on the rating. If the count falls and the average rises, lower-rated feedback was probably removed. If the count falls while the average appears unchanged, the missing reviews may be mixed, too small to change the rounded display, or offset by new reviews. These are diagnostic clues, not proof about any individual review.

    Keep local visibility in a separate column from review movement. Annotate the date of a confirmed count change, but do not attribute every ranking fluctuation to it. Profile edits, competitor activity, demand, and other search changes can occur during the same period. Your review log should help you investigate correlation without turning it into an unsupported causal claim.

    Use industry and location patterns to focus the audit

    A stylized neighborhood map shows several types of local businesses with map pins and clusters of star-rating cards, some of which are faded or missing.

    Your business category changes where you should look first. It does not determine why a particular review disappeared, but it can keep you from auditing the wrong slice of data. The observed deletion patterns differ by rating, age, sector, and country.

    Business contextObserved deletion patternWhat to inspect first
    RestaurantsHighest deletion activity among the sectors examined, with removals across star ratingsAll ratings and both recent and older review cohorts
    Home servicesGreater scrutiny of five-star feedback, with many removals occurring within six monthsRecent five-star reviews and the request method that generated them
    Medical businessesFewer deletions than the highest-incidence sectors, but a noticeable bias toward five-star removalsPositive reviews from the previous six months and any coordinated solicitation campaign
    RetailRelatively high deletion activity, including older reviewsHistorical cohorts as well as current acquisition
    ConstructionAmong the sectors experiencing more deletion activityThe full review history until a location-specific pattern emerges

    Do not combine every location into one company-wide total. A restaurant group, home-services network, or retailer can gain reviews overall while individual profiles lose them. Keep one record per Business Profile, then compare locations using the same fields and checking schedule.

    Country-level differences also deserve their own view. Five-star reviews have faced more scrutiny in many English-speaking markets, while low-rated reviews in Germany have been removed more often soon after publication. The German pattern aligns with stronger legal pressure around defamation, whereas automated moderation appears more prominent in English-speaking markets. If a German review is connected to a legal complaint or threat, preserve the relevant records and obtain advice from qualified local counsel before treating the situation as a routine SEO issue.

    Build a review log that exposes removals instead of hiding them

    An analyst organizes star-rating cards into trays beside a laptop and paper audit log containing generic rows and status symbols.

    A displayed review count is a balance, not an acquisition total. If five new reviews appear while five older ones disappear, the count looks flat even though both customer activity and moderation occurred. You need a simple cohort log to see that movement.

    1. Create a baseline for every profile. Record the check date, displayed review count, displayed average rating, and the newest visible reviews. Keep each location separate.
    2. Check on the same day each week. Weekly monitoring is granular enough to catch the deletion activity that has been appearing across many profiles without confusing a long period of gains and losses.
    3. Record newly visible and newly missing reviews. For each one, note the star rating and whether it was posted within the previous six months or belongs to an older cohort. Those two age groups are useful because recent removals are more prominent in medical and home services, while older removals appear more often in restaurants and retail.
    4. Attach acquisition context. Note the date, channel, location, campaign, and whether any benefit was connected to the request. Include requests handled by staff, software, agencies, receipts, email, or in-location prompts.
    5. Estimate removal volume. Subtract the net change in displayed review count from the number of newly observed reviews. Treat the result as an estimate when your checks may have missed reviews that appeared and disappeared between observations.
    6. Annotate SEO performance separately. Record local visibility or conversion changes beside the deletion event, but preserve the distinction between events that occurred together and events you can show were causally connected.

    The useful unit is the review cohort: feedback acquired through the same location, channel, and time period. If one cohort loses a disproportionate share of its five-star reviews while organically acquired feedback remains visible, you have a much sharper lead than a company-wide count decline.

    You can also track a survival measure for each cohort: the number of originally observed reviews that remain visible after six months divided by the number originally observed. Keep acquisition and survival as separate metrics. One tells you whether customers are responding; the other tells you whether those reviews persist.

    A single missing review rarely reveals the cause. It may reflect moderation or another change outside the business’s control. A cluster tied to one campaign, request channel, rating, or location is more actionable because it gives you a process to inspect.

    Fix the acquisition process before replacing lost reviews

    Google has increased enforcement against incentivized feedback, and automated systems are being used to identify suspicious activity. If a customer received a discount, free item, entry into a drawing, or another benefit for leaving a review, stop that workflow while you assess it. Do not assume that calling the benefit a thank-you removes the moderation risk.

    Map each missing cohort back to the way the request was made. Review the audience, timing, wording, channel, and responsible vendor or team. If removals cluster around one method, pause that method instead of sending a larger campaign to compensate for the loss. A replacement burst can add more questionable activity before you have removed the original cause.

    A lower-risk process is straightforward: connect the request to a real customer interaction, use neutral language, offer no benefit for posting, and let the customer write in their own words. Build review requests into an ordinary operating workflow so you are not dependent on occasional pushes designed to hit a target number.

    If an agency or software provider manages acquisition, require a clear description of its methods. Your internal record should show which customers were contacted, when the request was sent, which channel was used, and whether the provider attached any incentive. A promise to deliver a certain number of positive reviews is not a substitute for that process evidence.

    Do not focus only on the total count. Recent, detailed reviews remain important authority signals, while older feedback can still be re-evaluated and removed later. Your working dashboard should therefore show reviews received, reviews still visible, removals by star rating, removals by age, and removals by acquisition channel.

    At your next weekly check, establish the baseline before asking for anything new. Then trace every active request path and remove any attached benefit. You cannot control every moderation decision, but you can make review losses measurable, keep your reporting honest, and build an acquisition process that does not depend on reviews Google may later remove.

    References


  • False Allegations in Google AI Answers: How to Respond

    False Allegations in Google AI Answers: How to Respond

    You search your name and find a Google AI-generated answer accusing you of misconduct, suspension, fraud or another event that never happened. Your first move matters. The answer may change after the next query, while screenshots of the original allegation could become essential to a platform report, a publisher correction or legal advice.

    Treat this as an evidence, identity and reputation incident. Preserve what Google displayed, determine how the false narrative was assembled, correct the information environment around it and keep testing until the error is genuinely gone. A rewritten answer is not necessarily a corrected answer.

    Key takeaways

    • Capture the complete output before acting. Keep the query, wording, citations, date, time, language, location and relevant account context together.
    • Diagnose the failure precisely. A false source, unsupported citation, identity collision and invented inference require different corrections.
    • Work on three tracks. Report the AI answer, correct inaccurate or ambiguous web content and assess the professional or legal risk separately.
    • Strengthen your canonical identity. Consistent profile information and accurate Person JSON-LD can reduce ambiguity, but markup cannot force Google to retract an allegation.
    • Test a query set, not one search. The wording can disappear from one answer while surviving in related queries or a vaguer narrative.

    Preserve the output before it changes

    A laptop and phone are arranged on a desk to document a generic AI-generated answer, with a clock, notebook, and evidence folder nearby.

    Do not begin by editing your website or publishing an angry rebuttal. Generated answers can vary across queries and over time. In one documented incident, later searches replaced specific accusations with different but still inaccurate language, making the original output harder to reconstruct. Your evidence packet should exist before you ask anyone to change anything.

    1. Capture the whole result page. Save full-page screenshots and, where practical, a short screen recording that starts with the query and scrolls through the complete generated answer. Do not crop out qualifications, citations or surrounding context.
    2. Copy the exact text. A searchable text copy makes it easier to compare later versions word by word. Preserve unusual punctuation, headings and certainty language such as reportedly, allegedly, faced scrutiny or was suspended.
    3. Record the search conditions. Note the exact query, date, time zone, displayed language, approximate search location, device type and whether you were signed in. These details do not prove why the output appeared, but they make reproduction more disciplined.
    4. Save every cited page. Record each URL and the passage that supposedly supports the answer. Keep a copy of the page as it appeared at the time. The page may later be edited, removed or recrawled.
    5. Preserve contradictory evidence separately. Collect official registers, employer records, court or regulatory records, dated professional biographies and other primary material that establishes the accurate facts. Do not annotate or alter the originals.
    6. Start an impact log. Record who encountered the claim, when they saw it, what they did because of it and any resulting professional, contractual or financial consequence. Save direct communications rather than reconstructing them from memory later.
    7. Give each version an identifier. Labels such as AI-01, AI-02 and AI-03 make it clear which query, screenshot, output and report belong together.

    Keep an untouched evidence set and use redacted copies when sharing it. Search pages can expose account information, location clues or other personal data that a publisher, colleague or outside adviser does not need.

    Find where the false narrative entered the answer

    Anonymous source cards connect to a central AI prism, with a magnifying glass highlighting one identity strand routed into the wrong path.

    Calling the output a hallucination may be emotionally accurate, but it is not a useful diagnosis. Break every allegation into an individual factual proposition, then trace the apparent support for each one. One paragraph can contain several different failure modes.

    1. An underlying page makes the false claim

    If a cited page actually contains the accusation, the problem begins upstream. You need a correction, clarification, removal or legal assessment involving that page as well as feedback about the AI answer. Fixing your own profile will not neutralize a false statement that remains published elsewhere.

    2. The citation does not support the generated sentence

    A page may mention the right person but not the alleged event, or describe scrutiny without documenting a suspension. Record that mismatch exactly. The strongest report is not that the answer feels misleading; it is that a specific sentence asserts fact X while its displayed citation establishes only fact Y.

    3. Google has joined two identities

    Look for shared surnames, professional titles, employers, locations, initials, channel names and subject terms. An identity collision can occur even when each underlying fragment is real. The falsehood appears in the bridge between them.

    UK doctor and YouTuber Dr. Ed Hope said Google’s AI falsely claimed that he had been suspended in mid-2025, profited from selling sick notes, exploited patients and faced discipline because of his online fame. He believed the system may have connected his inactive YouTube channel, Dr. Hope’s Sick Notes, with an unrelated sick-note controversy involving another doctor, Dr. Asif Munaf. That explanation is a plausible identity-collision hypothesis, not a verified account of Google’s internal generation process. The important diagnostic lesson is that real fragments can be connected by a completely false relationship.

    4. The answer invents a narrative between unrelated facts

    The person and event may both be identified correctly while the claimed cause, motive or sequence is fabricated. A gap in publishing activity does not establish professional discipline. Online visibility does not establish that fame caused a regulator to act. Treat every causal word, not just every name and date, as a claim requiring support.

    Build a claim map with six fields: the exact AI sentence, its displayed citation, what that page actually says, the person or event described, the evidence establishing the accurate fact and the likely failure mode. This map becomes the working document for platform reports, publisher requests and professional advice.

    Run the correction on three separate tracks

    No single action covers the entire incident. Platform feedback addresses Google’s output. Publisher corrections address material on the open web. Professional and legal advice addresses the consequences. Run these tracks in parallel, but keep their evidence and objectives distinct.

    Track 1: Report the generated answer

    Use the feedback or reporting control attached to the answer when one is available. Interface labels can vary, so focus on the substance of the submission rather than the name of the button. Include:

    • the exact query and search conditions;
    • the complete false sentence, not a paraphrase;
    • the accurate fact stated in one direct sentence;
    • the identity distinction if another person or event has been attached to you;
    • the displayed citation and the precise reason it does not support the claim;
    • links to primary evidence that a reviewer can verify; and
    • the evidence identifier for your corresponding screenshot and text copy.

    Keep the report factual. Explain which proposition is false and how it can be checked. A long argument about AI safety gives a reviewer less usable information than a short claim-by-claim correction. Save any confirmation, case number or submitted text. If a materially different answer appears, preserve it as a new version before reporting that version too.

    Track 2: Correct the cited information environment

    If an external page contains the error, send its publisher a precise correction request. Identify the URL, heading, sentence, false proposition and primary evidence. Ask for a visible correction where quiet editing would leave readers with no way to understand what changed.

    If the cited page is accurate but Google has overstated it, do not pressure the publisher to rewrite a correct record merely to accommodate the AI system. Preserve the citation mismatch and concentrate the platform report on the unsupported inference. You can still ask the publisher to make ambiguous names or relationships clearer when a reasonable reader could confuse them.

    Track 3: Assess professional and legal exposure

    Claims involving criminal conduct, fraud, professional suspension, patient exploitation or regulatory discipline can carry consequences beyond search visibility. If the allegation is serious, persistent or already affecting work, speak with a lawyer qualified in defamation and reputation matters in the relevant jurisdiction. An SEO workflow is not a substitute for legal advice.

    Do not assume that Section 230 either resolves the issue or is relevant everywhere. It is a question of US law, and some legal experts have argued that generated output may be a newly published statement rather than third-party speech. Whether that position applies to a particular output, defendant or jurisdiction requires a legal assessment.

    Before notifying an employer, regulator, insurer, client base or large social audience, decide with the appropriate legal or communications adviser what the notification should accomplish. Unnecessary circulation can expose more people to the accusation and create additional searchable copies of it. Where a stakeholder genuinely needs warning, provide the preserved output, the accurate record and a concise statement of the steps underway.

    Make your identity harder to confuse without amplifying the lie

    A cleaner entity footprint can help search systems distinguish you from a namesake or unrelated event. It cannot prove a negative, erase an external page or guarantee a corrected AI answer. Think of it as disambiguation infrastructure, not a deletion tool.

    • Choose one canonical profile URL. Put the person’s full professional name, current role, organization, jurisdiction or location where appropriate, official profile links and a clear biography on a stable HTML page.
    • Keep identity facts consistent. The name, title, organization and profile links on the canonical page should agree with the organization’s team page and the person’s legitimate professional or social profiles. Resolve old titles and unexplained variants rather than publishing conflicting descriptions.
    • Add accurate Person JSON-LD. Use a stable @id and properties such as name, url, jobTitle, worksFor or affiliation, sameAs and, where genuinely useful, disambiguatingDescription. Every property should describe visible, verifiable page content.
    • Use sameAs narrowly. Link only to pages that represent the same person. A page that merely mentions the person, covers a similar topic or belongs to a namesake is not an identity-equivalent profile.
    • Connect primary records. Where appropriate, link to an official organization profile, professional register or other authoritative record that lets a reader verify the stated status directly.
    • Add contextual internal links. Organization biographies, author pages and relevant professional pages should link to the canonical profile using the person’s full name, not vague anchor text.
    • Clarify ambiguous brands and titles. If a channel, project or company name resembles the subject of an unrelated controversy, explain what it is and who owns it on the canonical page.

    If the allegation has already reached stakeholders, a short clarification page may be appropriate after legal or communications review. Keep it narrower than the rumor. State the accurate status, link to the record that verifies it, identify any mistaken entity only as far as necessary and show a publication or update date. Put the factual clarification in visible HTML rather than hiding it inside an image or downloadable file.

    A usable correction pattern: [Name] has not been [falsely alleged action]. [Official record] confirms [accurate status] as of [date]. The event involving [different person or organization] is unrelated. Use this structure only when every part is true, supported and appropriate to publish.

    Avoid mass-producing rebuttal pages, copying the accusation into every profile or adding unsupported positive claims to structured data. Those tactics enlarge the same noisy information environment that allowed the collision. One well-supported canonical record is more useful than a network of repetitive denials.

    Verify a correction instead of mistaking change for resolution

    When the original sentence disappears, resist declaring victory. The system may have removed the panel, softened the wording, changed its citations or moved the false association into another query. Verification needs a fixed test set and a record of every result.

    Your test set should cover:

    • the person’s exact name;
    • the name plus profession, organization or location;
    • the name plus the alleged event or disciplinary term;
    • the name plus the confused person’s distinguishing details;
    • the other person’s name plus the topic that triggered the collision; and
    • a distinctive excerpt from the original false sentence.

    For every check, record whether an AI answer appeared, its exact wording, its citations, the identity it described and the degree of certainty it used. Repeat relevant checks in the languages and locations where the person’s audience actually searches. Do not organize a public campaign asking large numbers of people to run the allegation as a query; that can spread the wording without producing controlled evidence.

    A correction is credible when the false assertion is absent across the relevant query set, replacement statements are accurate, displayed citations support what Google says, the mistaken identity no longer appears and later checks remain clean. A single favorable search is only one observation.

    Changed language deserves particular scrutiny. In Dr. Hope’s case, a later answer referred more vaguely to scrutiny and suspension, but it still attached an invented professional narrative to him; another variation blurred real and fictional contexts. The incident shows why less specific wording can remain materially false.

    Once the results are clean, archive the final test log and retain the evidence packet under an appropriate retention policy. Assign one person to own future checks and record the platform, publisher, legal and communications contacts that were useful. If you have not faced an incident yet, create the canonical identity page and branded-query test set now. Those two assets remove guesswork when a harmful answer appears.

    References