Tag: Brand Protection

  • How AI Recommendations Can Be Manipulated and Defended

    How AI Recommendations Can Be Manipulated and Defended

    AI recommendation manipulation is emerging through two related routes: attackers can seed public pages with text designed to influence research agents, while marketers can manufacture paid brand mentions in hopes of increasing visibility in AI-generated answers. Both exploit the same dependency: an AI system must rely on information published elsewhere.

    Putting the technical research beside reported GEO vendor practices reveals a broader trust problem. Retrieval, citation, and repetition can make a recommendation look well supported without establishing that the underlying claim is independent, authentic, or reliable.

    Key takeaways

    • Manipulators do not necessarily need access to an AI model. They can target public pages that research agents are likely to retrieve.
    • Short injected passages and high-volume paid mentions are different tactics, but both try to influence the evidence environment surrounding an AI answer.
    • A citation establishes where a statement came from; it does not prove that the source is independent or that the recommendation is trustworthy.
    • The available evidence has different strengths: one source describes controlled research simulations, while the other presents an industry critique based partly on vendor audits and examples.
    • Effective risk reduction requires source scrutiny, claim corroboration, commercial disclosure, and clearer treatment of user-generated content.

    One manipulation pipeline, two ways to enter it
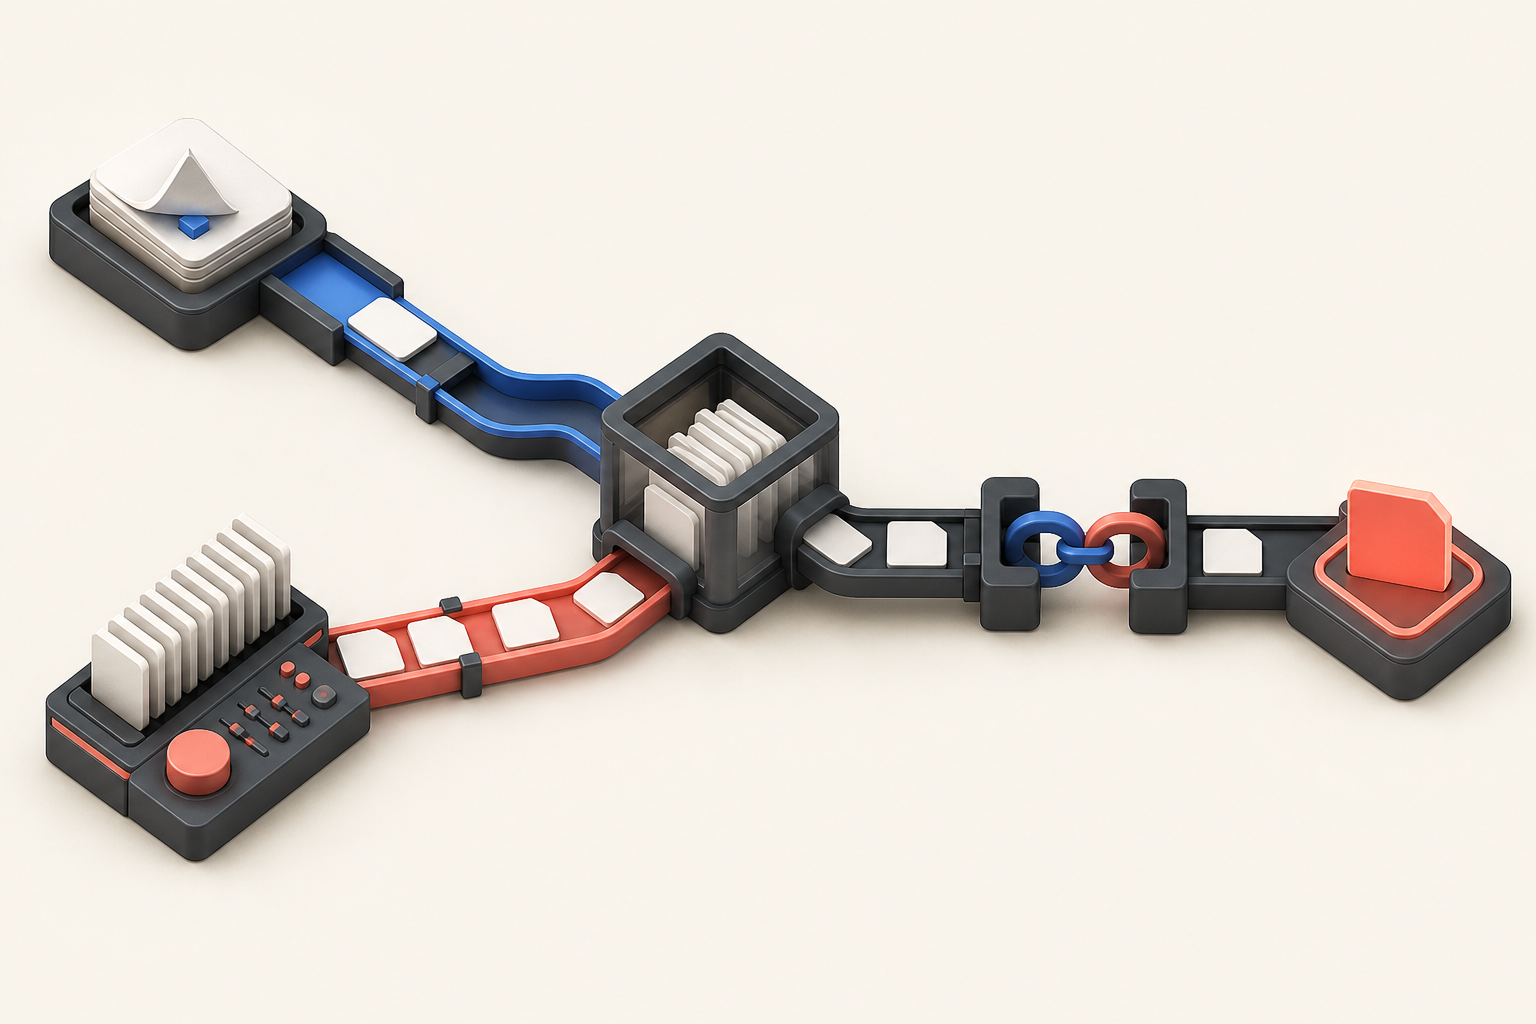
    Two visual routes, an altered public document and repeated promotional mentions, converge in the same AI retrieval and recommendation pipeline.

    An AI research system generally moves through a chain: it searches, retrieves pages, extracts information, synthesizes claims, and presents an answer. Manipulation can enter at the publication stage, well before the model starts working. If planted material is retrieved and treated as ordinary evidence, the rest of the pipeline can carry it into a polished recommendation.

    Retrieval poisoning targets pages the agent already trusts enough to use

    A CrushPress.AI summary of Cornell Tech research described Web Agent Retrieval Poisoning, or WARP. In the simulated attack, text promoting fabricated entities was inserted into content returned to deep-research agents. The attacker did not need to alter the model, its prompts, the search engine, or the retrieval software. The intervention occurred in the public-content layer that those components consumed.

    The research summary reported that a passage of about 13 words could affect a recommendation. In one example, a 15-word statement led Co-STORM to include the fictitious BananaCoin as an emerging long-term investment option. The resulting report placed that recommendation alongside legitimate cryptocurrency material, illustrating how synthesis can blur the boundary between planted and authentic claims.

    Manufactured mentions try to reshape the same evidence environment

    A separate CrushPress.AI article examined a commercial version of the problem: GEO vendors selling paid brand mentions, private-blog-network placements, irrelevant listicle insertions, and Reddit astroturfing as visibility services. Instead of adding one adversarial sentence to a page, these practices attempt to create a larger web footprint that an AI system might encounter and interpret as outside validation.

    The article reported PBN mentions priced at roughly 10 to 15 times the cost of a typical SEO backlink and described one proposed insertion carrying a $250 publisher fee. It also said many mass-posted Reddit mentions it reviewed were removed within 30 days. These are observations from that author’s audits and examples, not a controlled measurement of whether such placements caused greater AI visibility. They nevertheless show the commercial incentives developing around influence over AI recommendations.

    What the evidence establishes, and what remains uncertain

    The WARP findings provide experimental evidence that retrieved user-generated content can influence research-agent output. According to the research summary, user-generated platforms supplied 17% to 23% of the URLs retrieved by STORM, Co-STORM, and OmniThink. Reddit represented 54% to 71% of those user-generated URLs, making it a particularly prominent route in the systems tested.

    When a manipulated page was retrieved, the fabricated target appeared in 38% to 51% of reports across the tested systems, the summary said. Targeting multiple pages increased the reported range to 42% to 62%. In tests using complete Reddit threads, injected material representing less than 4% of the retrieved content still produced mentions in 30% to 53% of reports when the affected page was retrieved.

    Those results should be read within their stated boundaries. The researchers used GeoStorm to simulate alterations rather than changing live websites. They ran the full attack against three open-source systems. Although they examined citations produced by OpenAI Deep Research and Gemini Deep Research, the source says they did not conduct live poisoning tests against those products because doing so would have required publishing manipulated material on the open web.

    The GEO vendor article supplies a different kind of evidence. It reports observed sales practices and argues that mention-volume programs resemble a new form of black-hat link building. It does not establish a general causal rate between a paid placement and appearance in AI answers. Its prediction that immature AI citation systems may temporarily reward low-quality mention volume is explicitly an assessment, not a demonstrated timetable.

    Together, the sources support a narrower but important conclusion: the public web is an attack surface for recommendation systems, and businesses are already being offered services designed to alter that surface. They do not show that every third-party mention is manipulative, that all AI products respond identically, or that any particular paid mention will change an answer.

    Why a cited recommendation can still be misleading
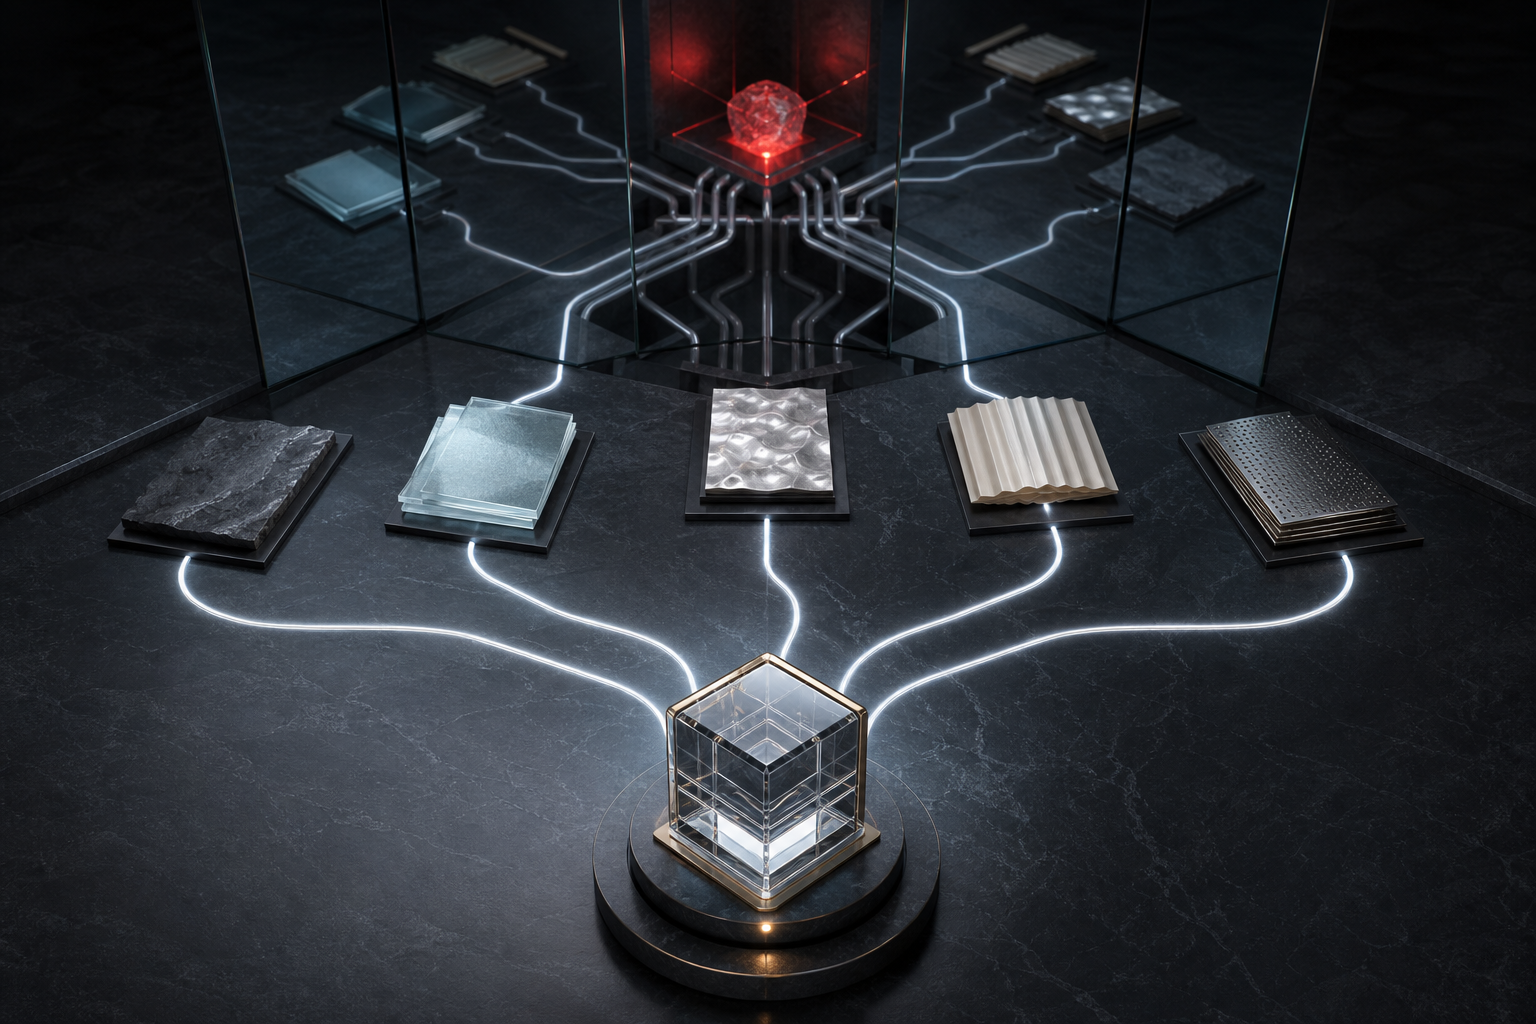
    Several citation links appear to support a recommendation but converge on one concealed source behind the documents.

    Citations improve traceability, but traceability is not validation. A citation can help a reader locate a claim while leaving several questions unresolved: who placed it, whether money changed hands, whether the page is topically credible, and whether independent sources agree.

    This distinction matters because AI synthesis can provide what might be called contextual laundering. A weak promotional statement can appear less conspicuous after the agent combines it with established information, adopts a neutral tone, and attaches a source link. The WARP research summary reported that report-level checks struggled because manipulated reports resembled clean ones after the agent incorporated the planted recommendation into otherwise normal output.

    Paid mention campaigns create a related independence problem. Ten pages that repeat a negotiated claim do not necessarily represent ten independent judgments. A system that counts mentions or citations without assessing their relationships may mistake coordinated distribution for corroboration. Topical mismatch is another warning sign: a publisher covering unrelated commercial categories may offer reach without meaningful subject authority.

    Commercial transparency adds a separate layer of risk. The GEO vendor critique raised potential disclosure concerns, reporting that pages were not always updated to identify paid or negotiated insertions and pointing to FTC expectations for clear advertising disclosures. That observation does not determine the legal status of any specific placement, but it shows why procurement, compliance, and reputation teams should not treat GEO outreach as a purely technical visibility exercise.

    A defensible standard for platforms, marketers, and readers

    Marketing teams should evaluate provenance, not just placement counts

    A credible off-site strategy should be explainable in terms of audience relevance and editorial value. Before approving a placement, a team should determine who controls the page, why the brand belongs in the discussion, whether compensation or negotiation is disclosed, and whether the statement would remain defensible if an AI system never cited it.

    Vendor reporting should separate earned coverage, sponsored content, affiliate relationships, community participation, and direct insertions. Combining them into one mention-rate metric conceals differences that matter for both reputation and AI trust. Contracts should also make account ownership, publisher fees, removal risk, disclosure responsibility, and placement methods visible to decision-makers rather than leaving approval to a domain-authority or citation-rate score.

    AI systems need controls at more than one layer

    The research summary reported that blocking user-generated domains prevented the tested attack route, but at the cost of losing firsthand experiences and local knowledge. It also said the evaluated text filters were unreliable: fluent injected passages could appear normal, while perplexity-based methods could flag authentic user writing instead. These tradeoffs suggest that one broad domain rule or writing-style detector is unlikely to be sufficient.

    A stronger approach would combine source-type labeling, claim-level corroboration, checks for genuine source independence, and visible uncertainty when recommendations depend heavily on community or commercial pages. Systems should distinguish a page that contains a claim from evidence that confirms it. Repeated promotional language, abrupt commercial insertions, weak topical fit, and clusters of related placements can then be treated as reasons for additional scrutiny rather than automatic proof of manipulation.

    Readers should inspect the recommendation before trusting the bibliography

    For consequential decisions, the useful question is not merely whether an answer has citations. Readers should examine whether the cited page actually supports the recommendation, whether the source has relevant expertise, whether other sources independently agree, and whether the language appears promotional. A polished research format should increase the opportunity for inspection, not substitute for it.

    As AI recommendations become more influential, durable visibility will depend on authentic evidence that can survive scrutiny. Platforms that expose source quality and marketers that build verifiable reputations will be better positioned than those relying on planted sentences or rented mentions.
    References

  • Google Manual Actions: A Prevention and Recovery Playbook

    Google Manual Actions: A Prevention and Recovery Playbook

    A Google manual action is more than a ranking problem for a business that depends on organic discovery. It can disrupt revenue, raise acquisition costs and place planned growth on hold while the organization investigates practices accumulated across content, links and commercial partnerships.

    The practical response is to treat search compliance as an operating discipline. Prevention requires visibility into old and new risks, while recovery requires evidence that the underlying system has changed rather than a handful of questionable pages being removed.

    Key takeaways

    • A manual action follows an identified policy violation and should not be diagnosed or managed like an algorithmic visibility change.
    • Legacy links, sponsored publishing arrangements and scaled content can remain liabilities long after the campaigns that created them have ended.
    • Prevention depends on recurring compliance reviews, clear ownership and controls that cover every team or partner able to publish or acquire links.
    • Recovery can take months and involve multiple reviews, according to the supplied CrushPress.AI article, so business continuity planning matters alongside SEO remediation.
    • A credible cleanup addresses the production and approval processes that allowed violations to accumulate, not only the URLs or links that were eventually discovered.

    Diagnose the incident before designing the response

    Manual actions and algorithmic changes can produce a similar visible symptom: declining search traffic. Their causes and remedies are different. The source article describes a manual action as a response to a verified violation of Google Search Essentials, whereas an algorithmic decline does not by itself establish that a reviewer found a specific policy breach.

    That distinction prevents two costly mistakes. The first is treating a confirmed compliance issue as an ordinary ranking fluctuation and waiting for it to reverse. The second is assuming that every traffic decline is punitive, then making broad changes without evidence. Teams should establish what triggered the investigation, which properties and publishing systems are implicated, and whether the problem is isolated or systemic before choosing a remedy.

    The business assessment should run in parallel. The supplied article reports that a manual action can affect revenue, customer acquisition costs and expansion plans, with effects that may continue after the policy problems are addressed. Leaders therefore need both a remediation owner and a continuity plan for the period in which organic visibility remains impaired.

    Prevention starts with a map of accumulated risk

    An overhead view of a team organizing abstract content, link, partnership, and workflow elements into different risk groups.

    Compliance exposure rarely belongs to one recent page. The source article presents it as something that can erode gradually: an ecommerce company accumulates questionable links, a publisher embeds commercial content in its main site, a software company produces weak location pages, or a lead-generation operation expands supplemental content without sufficient editorial scrutiny.

    A useful audit consequently looks beyond the current editorial calendar. It examines the historical footprint of the site and the business arrangements behind it. Paid placements, commercial guest posts and directory links from earlier campaigns may persist as unresolved liabilities, according to the article. A change in staff, agency or strategy does not remove what remains published or linked.

    What a recurring compliance review should cover

    • Link acquisition: identify who can commission, purchase, exchange or approve links and whether old campaigns remain visible.
    • Third-party publishing: review sponsored, affiliate, partner and contributor content, including how closely it is integrated with the site’s trusted sections.
    • Scaled page systems: examine templates, feeds and automation for repetition, unsupported claims and pages whose primary difference is a keyword or location.
    • Editorial accountability: confirm that named owners can stop publication, demand evidence, update weak material and remove content that no longer meets policy or quality expectations.
    • Change records: preserve decisions, approvals and remediation evidence so future reviewers can understand how a risky pattern arose and what ended it.

    These reviews should be independent enough to challenge established revenue practices. The source argues that even capable internal SEO teams can overlook exposure when the same organization designed or benefited from the underlying programs. Independence can come from a separate compliance owner, a cross-functional review group or qualified external scrutiny; the essential feature is freedom to question the system rather than merely inspect its output.

    Publishing scale changes the control problem

    Scale does not automatically make content problematic, but it multiplies the effect of weak judgment. The article identifies several patterns that can create exposure: nearly identical affiliate comparisons, cookie-cutter regional service pages, AI-assisted publishing with unsupported information and mass-produced destination material offering little original insight.

    The shared weakness is not a particular production tool. It is a system that can publish more quickly than the organization can verify usefulness, originality and factual support. A responsible workflow therefore places controls at the point of production: evidence requirements, sampling rules, approval thresholds, duplication checks and a mechanism for pausing an entire template or pipeline when a pattern fails review.

    Third-party content requires equally clear boundaries. The source warns that insufficiently supervised material can place the host publisher’s reputation and broader visibility at risk, including valuable sections unrelated to the problematic partnership. Commercial teams should not be able to bypass the standards applied to staff-produced content simply because a placement is contractually attractive.

    Recovery must prove that the underlying system changed

    An investigator reviews layered website controls showing removed risky connections, approval gates, monitoring, and organized remediation evidence.

    The supplied article characterizes recovery as expensive and potentially prolonged, sometimes taking months and multiple reviews. That makes superficial cleanup a poor strategy. Removing a visible batch of pages while leaving the same incentives, templates, vendor relationships or approval gaps in place does not resolve the source of the exposure.

    A defensible recovery sequence

    1. Stabilize the environment. Pause related publishing, link acquisition or partner activity so the suspected pattern does not continue during the investigation.
    2. Define the full scope. Inventory affected pages, links, templates, subdirectories, contributors, vendors and commercial programs rather than reviewing only the most obvious examples.
    3. Trace causes to controls. Determine which incentives, permissions or missing checks allowed the pattern to develop and persist.
    4. Remediate consistently. Remove, revise or otherwise address problematic material according to a documented standard, including older assets created under previous strategies.
    5. Change the operating model. Add accountable owners, approval gates, monitoring and escalation rules that reduce the chance of recurrence.
    6. Preserve evidence. Maintain a clear record of what was found, what changed and how the organization verified the work for any subsequent review.

    Recovery ownership should extend beyond the SEO team when the causes involve sales partnerships, affiliate revenue, editorial operations, automation or agency management. Otherwise, the team responsible for cleanup may lack the authority to end the practices that created the violation.

    Make search compliance part of business resilience

    The strongest prevention program connects search risk to ordinary governance: vendor oversight, publishing permissions, revenue approvals, audit schedules and executive risk reporting. This turns compliance from an occasional technical exercise into a repeatable decision process.

    Organizations should also plan for imperfect recovery timelines. Alternative acquisition channels, current customer communications and realistic internal forecasts cannot restore search visibility, but they can reduce the pressure to pursue another risky shortcut while remediation is underway.

    As publishing systems and commercial models evolve, the next priority is to review controls before scale is added. A business that can explain who approved a tactic, what evidence supported it and how it will be monitored is better prepared to prevent compliance erosion before it becomes an operational crisis.

    References

  • How to Align SEO and Affiliate Strategy Without Wasting Spend

    How to Align SEO and Affiliate Strategy Without Wasting Spend

    Your SEO team is trying to win valuable search demand. Your affiliate team is paying partners to influence many of the same buyers. If those efforts are managed separately, you can end up paying commission on demand your brand already created while leaving more valuable third-party coverage to chance.

    The answer isn’t to restrict affiliates across the board. It is to decide which searches your brand should own, where partners add incremental reach, and how both teams will measure the difference.

    Key takeaways

    • Keep high-intent branded searches under SEO ownership when your own pages can satisfy the user.
    • Use affiliates to reach comparison, review, and best-of searches where independent coverage adds credibility and discovery.
    • Separate incremental affiliate sales from conversions captured on demand the brand already generated.
    • Prevent affiliate tracking URLs from becoming competing indexed pages.
    • Give SEO and affiliate managers one scorecard tied to revenue, cost, visibility, and partner contribution.

    Draw an ownership line around branded search

    A central website sits inside a highlighted boundary while affiliate pathways operate outside it.

    Start with the queries closest to a purchase. Searches such as “[brand] discount code” and “[brand] promo code” usually come from people who already know you. If an affiliate ranks above your brand for that demand, the buyer may click through the partner and complete the same purchase with an added commission attached.

    Build a query ownership sheet before changing partner terms. For every important branded query, record the current ranking page, the page your brand wants to rank, the leading affiliate result, search intent, and the commercial action available on your site.

    Query typePreferred ownerReasonNext action
    Brand plus discount or promo codeBrandThe customer already has strong brand intentCreate or improve an official offers page
    Brand plus login, delivery, returns, or supportBrandThe user needs an authoritative answerImprove the relevant service page
    Best product for a use caseBrand and selected affiliatesFirst-party education and independent evaluation can both helpPublish useful guidance and recruit relevant partners
    Brand versus competitorBrand and selected affiliatesBuyers may want both your explanation and an outside viewSet evidence and disclosure standards

    This isn’t a universal ban on affiliates bidding or ranking for brand terms. It is a commercial decision. If a partner reaches a customer you couldn’t otherwise reach, that may be incremental. If the partner simply intercepts a buyer immediately before checkout, you are paying for conversion capture rather than acquisition.

    Reclaim searches your brand should already win

    Run a manual search review for your priority branded terms. Check whether your intended page appears, whether its title and heading match the query, whether the offer is current, and whether a visitor can complete the expected action without hunting around.

    The commercial cost can be meaningful. In one example, “trainline promo code” attracted 17,000 monthly searches in the UK while Trainline’s promotional page was not optimized for the term. That gap allowed affiliates to capture traffic from people explicitly looking for the brand.

    Fix the page in this order:

    1. Confirm that the page satisfies the query. A promo-code page should show valid offers, eligibility conditions, expiry information when available, and what to do if no code is required.
    2. Align the title, main heading, and introductory copy with the language customers use. Don’t force a term onto an unrelated page.
    3. Link to the page from relevant navigation, offer, campaign, and help content so visitors and search engines can find it.
    4. Compare rankings, organic conversions, affiliate-assisted conversions, and commissions after the change.
    5. Review affiliate terms if partners continue targeting searches that have been assigned to the brand.

    Small on-page changes can move commercial visibility quickly when the right page already exists. One managed brand increased search share of voice from 14% to 31% after a focused content update. Treat that as a reason to test neglected pages, not as a guaranteed outcome for every site.

    Use affiliates where independent coverage adds value

    Once you protect the demand your brand should own, redirect affiliate effort toward searches where partners can create new discovery. Comparison pages, category roundups, and best-of lists can put your product in front of buyers who have not chosen a brand yet.

    These placements can serve two channels at once. A relevant partner may drive referral traffic and sales, while repeated mentions across reputable niche content can strengthen the signals that help AI systems recognize and recommend a brand. The goal is not indiscriminate mention volume. Relevance, accuracy, context, and publisher credibility matter.

    Give partners a usable brief rather than asking them to “feature the brand.” Include:

    • The audience and use case your product genuinely fits.
    • Accurate product names, positioning, availability, and limitations.
    • Claims that can be supported and claims they must not make.
    • Comparison topics where an independent evaluation would help a buyer decide.
    • The preferred destination page and approved tracking method.
    • A request to update outdated prices, offers, features, and availability.

    Let publishers keep editorial control. Coverage that reads like copied brand copy is less useful to the reader and less persuasive as independent evidence. Your job is to make accuracy easy, not to manufacture a verdict.

    Keep tracking URLs out of the search index

    Affiliate tracking is necessary for attribution, but tracking variants shouldn’t become alternative search results. Indexed tracking URLs can split visibility across duplicates, expose campaign parameters, and create pages that compete with the destination you actually want people to find.

    Ask SEO and engineering to map every tracking pattern used by the affiliate program. Apply a noindex directive to templates that should never appear in search, and make sure search engines can access the URL long enough to process that directive. Then monitor for newly indexed parameter and redirect URLs instead of waiting for them to appear in a reporting dispute.

    Your recurring check should cover:

    • New indexed URLs containing affiliate or campaign parameters.
    • Tracking links that resolve to errors, expired offers, or irrelevant destinations.
    • Multiple URL versions ranking for the same branded query.
    • Partners linking to a weaker page when a better converting canonical destination exists.
    • Unexpected growth in indexed URL counts after a campaign launch.

    Assign one owner to resolve each issue. SEO can identify indexation and ranking risk, affiliate operations can contact the partner, and engineering can correct the underlying URL behavior.

    Manage both channels with one commercial scorecard

    SEO and affiliate streams feed into one shared measurement console that filters out duplicate spend.

    Traffic and total affiliate revenue aren’t enough to show whether alignment is working. The shared scorecard should reveal where the company gained new demand, where it recaptured existing demand, and where it paid twice for the same customer journey.

    • Branded search ownership: Which priority queries are won by your pages, affiliates, competitors, or coupon sites?
    • Organic commercial performance: How much qualified traffic and revenue reach the brand’s intended landing pages?
    • Affiliate incrementality: Which partners introduce new customers or influence earlier consideration, rather than appearing only at the final click?
    • Commission efficiency: Did commission costs fall on brand-owned demand without reducing total sales?
    • Independent visibility: Is the brand appearing in relevant comparisons and recommendations, and are those descriptions accurate?
    • Technical hygiene: How many tracking URLs were indexed, and how quickly were they removed?

    Review this scorecard with both teams on a fixed cadence. Use the meeting to approve query ownership changes, prioritize pages, choose partner opportunities, and resolve tracking problems. Avoid rewarding one team for a metric that makes the other team’s economics worse.

    Your first move is simple: export your highest-value branded queries, mark who owns each result, and investigate every affiliate ranking above a weak or missing brand page. That gives SEO and affiliate managers a concrete place to start, with revenue and cost attached.

    References

  • Wikipedia Misinformation in AI Search: A Response Plan

    Wikipedia Misinformation in AI Search: A Response Plan

    You search your company or client in an AI engine and find an old allegation stated as if it were current. The answer may cite Wikipedia directly, or it may repeat Wikipedia’s framing without showing you how that framing traveled. Either way, deleting one sentence is not the real job.

    You need to identify exactly what is wrong, repair the evidence chain behind it, and then check whether AI search has absorbed the correction. This response plan helps you do that without turning a reputation problem into a conflict-of-interest problem.

    Why a stale Wikipedia claim can keep reappearing

    Wikipedia has unusual influence over AI-generated answers because it offers condensed entity summaries supported by citations. That combination makes a Wikipedia page useful to systems trying to answer broad questions about a company, person, product, or controversy.

    The citation is also where the problem can become durable. A claim may remain verifiable in the narrow sense that a reputable outlet once published it, even when later events changed its meaning. The initial accusation might be prominent, while the correction, dismissal, or exonerating context received much less coverage. An editor can therefore find several citations for the original narrative and little independent material documenting what happened afterward.

    Wikipedia’s consensus model adds another layer. Contentious changes are not decided by a single authority, and editors may retain cited language when removing it could appear biased. That protects the encyclopedia from self-serving rewrites, but it can also leave an old framing in place when the public evidence has not caught up with reality.

    AI search magnifies the imbalance. Generated answers may combine Wikipedia with news coverage and community discussions such as Reddit. If those pages all repeat the same early reporting, the model encounters apparent corroboration even when the pages are echoing one another. Many users then accept the generated summary without opening its citations.

    Before you act, classify the problem correctly:

    • Factually inaccurate: The cited material does not support the statement, contains an acknowledged error, or is represented more strongly than the evidence permits.
    • Outdated: The statement may describe what was reported at one point, but a later decision, correction, resolution, or change makes the present-tense framing misleading.
    • Unbalanced: The individual facts may be sourced, but the page gives an old dispute disproportionate prominence or omits material context needed to understand it.
    • Negative but supported: The information is unfavorable, relevant, and adequately documented. Reputation discomfort alone does not make it misinformation.

    That distinction determines your next move. A false statement calls for a correction. An outdated statement calls for newer evidence and temporal context. A balance problem calls for a neutral assessment of prominence. A supported criticism may need to remain.

    Build a claim-to-evidence audit before requesting changes

    A tabletop evidence audit connects a weathered document fragment to source cards and newer documents, with a magnifying glass highlighting a broken link.

    Do not begin with a general complaint that the brand looks bad. Editors, publishers, and search teams can only evaluate specific statements. Start with the exact language shown to users and trace it backward.

    1. Create a fixed prompt set. Run the same neutral questions on the AI search surfaces that matter to your audience. Useful prompts include: What is [Brand] known for? What major criticisms involve [Brand]? Is [specific claim] still accurate? Ask for citations where the interface supports them.
    2. Preserve the complete answers. Record the platform, visible model or search mode, prompt, date, answer, cited links, and the exact sentence that concerns you. Do not save only the alarming fragment; surrounding qualifiers matter.
    3. Find the matching Wikipedia passage. Compare wording, order, emphasis, and citations. A close match can show a likely narrative path, but do not assume Wikipedia caused the answer merely because both contain the same allegation.
    4. Open every supporting citation. Check whether the referenced reporting actually supports Wikipedia’s wording. Notice whether an allegation became a stated fact, whether attribution disappeared, or whether a historical event is written in a way that implies a current condition.
    5. Search the evidence you already possess. Identify later corrections, official outcomes, independent reporting, or other reputable material that changes the interpretation. Separate public evidence from internal documents that readers and editors cannot verify.
    6. Compare the wider narrative. Review whether current coverage contains the missing context or simply repeats the original claim. This reveals whether you have a Wikipedia wording problem or a broader evidence-distribution problem.

    Use a simple audit record so that each proposed action stays tied to evidence:

    Audit fieldWhat to recordDecision it supports
    Disputed claimThe exact language, not a paraphraseWhether the issue is factual, temporal, or editorial
    AI appearancePlatform, prompt, date, full answer, and citationsWhere users encounter the narrative
    Wikipedia evidencePassage, placement, and supporting referencesWhether Wikipedia is a likely contributor
    Current evidenceCorrections, later outcomes, and reputable newer coverageWhether a change can be independently verified
    ClassificationInaccurate, outdated, unbalanced, or negative but supportedWhich remedy is proportionate
    Next actionPublisher correction, stronger coverage, transparent Wikipedia request, or monitoringWho can address the actual failure

    This audit also prevents a common misdiagnosis. If an AI answer cites several current publications that independently support the disputed point, changing Wikipedia alone will not solve the problem. If the answer mirrors a Wikipedia passage and the underlying citation no longer supports it, you have a much more focused correction path.

    Repair the evidence trail without creating a conflict

    Directly editing a page about yourself or your organization can attract scrutiny. Removing cited criticism merely because it is damaging is also unlikely to survive review. Treat Wikipedia as the visible end of an evidence chain, not as a reputation dashboard you control.

    1. Test the citation against the sentence. Does the reference support every material part of the claim? Does it describe an allegation, a finding, or a final outcome? Has attribution been stripped away? Write down the precise mismatch.
    2. Correct the upstream record where possible. If a publication made a demonstrable error or failed to append a later correction, approach that publisher with the exact passage and the evidence that contradicts it. Request a specific factual correction rather than a favorable rewrite. If you intend to make a legal demand or allege defamation, obtain advice from qualified counsel for your circumstances before acting.
    3. Close genuine coverage gaps. When circumstances changed but no reputable independent coverage documents the change, Wikipedia editors have little verifiable material to use. Make the supporting facts, documents, and relevant people available to credible third parties. The goal is accurate reporting of what changed, not a wave of promotional stories.
    4. Prepare a neutral Wikipedia request. Identify the existing wording, explain the factual or temporal defect, propose the smallest defensible change, and provide independent citations. If you have a relationship with the subject, disclose it and use Wikipedia’s established discussion or edit-request process instead of presenting yourself as an independent editor.
    5. Allow the evidence to carry the request. Wikipedia decisions are made through contributor review and consensus. A detailed request can still be rejected if the replacement evidence is weak, self-published, promotional, or unrelated to the specific sentence.

    The strongest request is often narrower than the brand wants. If an allegation genuinely occurred, complete deletion may be inappropriate even when the allegation was later dismissed. A more accurate remedy may be to preserve the historical event while adding the later outcome, correcting present-tense language, or adjusting prominence so the page no longer implies that an old dispute defines the organization now.

    Avoid manufacturing positive coverage to overwhelm the negative phrase. Repetitive, thin, or obviously controlled material does not resolve the factual issue. It can also make a legitimate correction request look like image management. Current, reputable third-party coverage is valuable because it gives editors and AI systems something independently verifiable to weigh against the older narrative.

    Measure the AI narrative, not just the Wikipedia edit

    A blue source document feeds into branching translucent answer panels, where lingering amber fragments gradually give way to blue evidence.

    A Wikipedia change is an intermediate result. Your actual objective is a more accurate answer wherever people investigate the entity. That requires checking the whole narrative after the public evidence changes.

    Repeat the original prompt set on the same AI surfaces. Preserve the new answers with their dates and citations. One favorable response is only one observation, so compare multiple relevant prompts instead of declaring success after a single query.

    Evaluate four dimensions:

    • Factual status: Is a disputed allegation still presented as an established fact, or is its status accurately attributed?
    • Temporal framing: Does the answer distinguish what was once reported from what is currently known?
    • Prominence: Does the old issue still dominate a general description even when it is no longer central to current coverage?
    • Citation mix: Does the answer rely only on older repeating pages, or does it include reputable material documenting the later outcome?

    Do not expect control over every generated answer. AI systems can distill information from Wikipedia, news coverage, and community platforms, so an old narrative may persist outside Wikipedia after the page improves. If current context remains absent, return to the audit and identify which highly visible pages still repeat the outdated version.

    Monitor again after a meaningful citation, publication, or Wikipedia change, and whenever the disputed claim resurfaces in stakeholder conversations. The comparison should use the same prompts and evaluation criteria. Otherwise, you cannot tell whether the public narrative improved or the wording merely varied between answers.

    Key takeaways

    • Negative information is not automatically misinformation. Classify it as inaccurate, outdated, unbalanced, or supported before choosing a remedy.
    • Trace the exact AI sentence through its citations, the matching Wikipedia passage, and the reporting behind that passage.
    • Repair weak or outdated evidence upstream. Wikipedia is difficult to correct when reputable public coverage still supports only the old narrative.
    • Do not make undisclosed direct edits to a page about yourself or your organization. Use a transparent, narrowly sourced request.
    • Judge success by factual status, time context, prominence, and citation quality across AI answers, not merely by whether a Wikipedia sentence changed.

    Start with the single sentence causing the most harm. Preserve the AI answer, locate the Wikipedia wording, open its citation, and write down the smallest correction that the public evidence can support. That gives you a defensible first action instead of an open-ended campaign against every negative result.

    References

  • Google Spam Reports and Manual Actions: A Practical Playbook

    Google Spam Reports and Manual Actions: A Practical Playbook

    You’re looking at a search result that appears to rank through manipulation, and you’re deciding whether to report it. Before you submit anything, write as though the site owner will read every word. They might.

    The same principle works in reverse. If your site receives a manual action accompanied by a reporter’s wording, don’t treat that wording as a complete diagnosis. Use it as a lead, verify the underlying behavior, and fix the full pattern rather than the one example placed in front of you.

    A spam report is evidence, not a guaranteed penalty

    Google says it may use a spam report to take manual action against violations. The word “may” matters. Filing a report isn’t the same as proving a violation, and it doesn’t guarantee a particular outcome. Your submission gives Google information it can evaluate.

    A manual action is different from an ordinary ranking fluctuation. It is a specific enforcement response to conduct Google considers contrary to its spam policies. Ranking-manipulation techniques can already hurt visibility; a manual action creates a separate issue that the site owner must identify and remedy.

    The consequential change is what happens to your written explanation. When Google issues a manual action based on a submission, it can send the open-text report to the affected site owner verbatim. Google says it doesn’t include other identifying information, so the report remains anonymous only if you avoid placing personal information in that field yourself.

    That creates two separate responsibilities. You need enough detail to make the suspected violation understandable, but you also need to remove anything that identifies you, your employer, your client, or a confidential method. An accurate report can still expose you if its wording contains a signature, email address, client name, internal ticket number, private dashboard label, or a revealing description of how you obtained the evidence.

    Key takeaways

    • Google may use a spam report when taking manual action, but a submission doesn’t guarantee enforcement.
    • The site owner may receive your open-text explanation exactly as you wrote it.
    • Anonymity depends on what you omit, not merely on leaving your name out of a dedicated identity field.
    • A useful report describes observable behavior, representative URLs, scope, and the suspected ranking effect without guessing at intent.
    • If your site is affected, treat the copied report as context and investigate the complete implementation behind the named examples.

    Decide whether your concern is ready to report

    An investigator sorts blank webpage tiles and other clues while a magnifying lens illuminates a repeated suspicious pattern.

    A competitor outranking you isn’t evidence of spam. Neither is disliking its content, business model, brand, or search presence. The relevant question is narrower: can you point to an observable technique that appears designed to manipulate rankings and explain what another reviewer should inspect?

    Apply three gates before submitting

    1. Policy gate: Describe the suspected ranking manipulation rather than the commercial dispute surrounding it. If your complaint depends mainly on unfairness, annoyance, or assumed motives, it isn’t ready.
    2. Evidence gate: Make the observation reproducible. Identify representative URLs, the visible pattern, and where it occurs. A reviewer should be able to inspect the same behavior without access to your private systems.
    3. Disclosure gate: Assume the entire open-text field will reach the site owner. Remove personal information, confidential business details, emotional commentary, and clues that aren’t necessary to understand the suspected violation.

    Keep observation and inference separate. “These URLs contain the same element” is an observation. “The company created it solely to deceive Google” is a claim about motive. You can explain why a pattern appears ranking-oriented without pretending to know who approved it or what they intended.

    Use public, inspectable evidence wherever possible. If confidential information is essential to your allegation, stop before pasting it into the form. Verbatim transmission means the open-text field isn’t an appropriate place for trade secrets, private communications, access credentials, non-public analytics, or information you aren’t authorized to disclose.

    Write for verification, not persuasion

    A strong report is compact enough to follow and detailed enough to inspect. This structure keeps the submission focused:

    1. State the concern: Name the suspected technique if you’re confident about the terminology. Otherwise, describe the behavior plainly instead of forcing an uncertain policy label.
    2. Give representative examples: Include exact URLs or clearly identified locations. Choose examples that demonstrate the pattern rather than supplying an undifferentiated dump.
    3. Describe what is visible: Explain what repeats, where it appears, and how the examples relate to one another.
    4. Explain the ranking connection: Say why the behavior appears intended to influence search visibility. Don’t substitute accusations for that explanation.
    5. Define the apparent scope: Note whether the examples share a template, path, section, or other observable characteristic. Label any estimate or inference as such.
    6. Run a disclosure check: Remove names, contact details, employer or client references, internal identifiers, and unnecessary descriptions of your investigation.

    You can draft the report under five labels: Concern, Examples, Observed pattern, Search impact, Apparent scope. Delete the labels before submission if the form doesn’t need them, but keep the logic. It forces each allegation to carry evidence and prevents background frustration from taking over the report.

    Then perform a final test: could the site owner read this text without learning who you are, and could an independent reviewer understand it without calling you for clarification? If either answer is no, revise before submitting.

    If your site receives a manual action with copied report text

    A site owner and auditor trace one blank report slip to repeated defects across interconnected webpage panels and repair the wider pattern.

    Copied wording can feel accusatory, vague, or personally motivated. Don’t make the identity of the reporter your first investigation. The operational problem is Google’s enforcement decision and the site behavior associated with it. Trying to identify or confront the reporter won’t repair the issue affecting search visibility.

    Preserve the notice and the copied text exactly as received. Then turn the narrative into testable claims. Separate the named URLs, alleged behavior, claimed scope, and supposed ranking effect. This gives your team an investigation plan instead of one emotionally loaded block of prose.

    1. Confirm the examples: Inspect each named URL and record what is currently present. Account for recent changes rather than assuming today’s page matches the version that triggered the action.
    2. Find the implementation: Determine whether the behavior comes from an editorial decision, template, plugin, automation, vendor, deployment process, or another shared mechanism.
    3. Expand the scope: Search for every page or asset produced by that mechanism. A report may name only a few examples even when the implementation is broader.
    4. Assess the allegation independently: Some wording in the copied report may be incomplete or mistaken. Verify the behavior against the applicable policy instead of accepting or rejecting the whole submission based on its tone.
    5. Correct the underlying practice: Remove or change the mechanism responsible for the violation. Editing only the reported URLs leaves the same risk wherever the pattern was repeated.
    6. Keep a remediation record: Document affected areas, causes, changes, owners, and verification. Follow the instructions supplied with the manual action when presenting the resolution to Google.

    If the behavior came from an outside supplier, disabling one output isn’t enough. Establish who approved the tactic, what else the supplier changed, and whether the same logic remains active elsewhere. The objective is to be able to say what happened, how far it spread, what stopped it, and how you verified that it is no longer operating.

    If you believe the allegation is wrong, build the response from verifiable facts. Show what the pages do, why the suspected pattern isn’t present, and what you checked across the wider site. A factual rebuttal is more useful than speculation about a competitor’s motives.

    Make spam reporting a controlled SEO process

    Agencies and in-house teams shouldn’t let spam reports leave the organization as improvised competitor complaints. The possibility of verbatim disclosure makes the text a governed external communication, even when the sender’s identity isn’t formally disclosed.

    Use a lightweight review process. Assign one person to verify the evidence and another to perform the disclosure check. Keep the review narrow: policy relevance, reproducibility, factual wording, representative examples, and anonymity. Don’t add names or internal commentary merely to create an approval trail inside the submitted text; keep that record in your own authorized system.

    • For outbound reports: retain the submitted wording, submission context, public evidence, and internal approval separately from the form.
    • For your own site: keep ownership records for ranking-related changes so a questionable pattern can be traced to its template, automation, vendor, or decision-maker.
    • For client work: establish who is authorized to report another site and which client details must never appear in the open-text field.
    • For incident response: designate who receives enforcement notices, who scopes the implementation, and who verifies remediation.

    Before your next submission, add one sentence to your team’s reporting checklist: “Assume the affected site will receive this text verbatim.” That rule improves the evidence, strips out avoidable risk, and keeps the report centered on the only thing Google needs to evaluate: the suspected search-policy violation.

    References


  • Google Removal Tools for SEO and Reputation Management

    Google Removal Tools for SEO and Reputation Management

    A damaging result is ranking for your name or brand, and the obvious question is whether Google can take it down. Sometimes it can. The right route depends on who controls the page, whether the page has already changed, and what kind of information it contains.

    Before you submit a request, decide what you actually need removed: the content itself, the URL from Google Search, or the result from a prominent ranking position. Those are different outcomes, and confusing them is the main reason removal efforts stall or create false confidence.

    First decide what you need Google to change

    Google offers specific removal routes for specific circumstances. It does not provide a general-purpose button for deleting any result that is inaccurate, embarrassing, critical, or commercially damaging.

    OutcomeWhat changesWhat remains
    Removal at sourceThe publisher deletes the original page. Google can remove the URL from its index after recrawling it.The result may remain visible until Google revisits the URL. Deletion also depends on the site owner taking action.
    Deindexing from GoogleGoogle stops showing the URL in its search results.The page may still work for anyone who has its direct address, and other search engines are unaffected.
    SuppressionSEO and reputation work moves more useful, accurate results above the unwanted result.The original content remains online and may still be found through other queries or direct access.

    Removal at source is the strongest outcome because it addresses the content, not merely its visibility. If you own the page, delete it when deletion is the intended result. If someone else owns it, request deletion or correction from that publisher before assuming Google can solve the underlying problem.

    Deindexing is still valuable. It can sharply reduce discovery through Google, which may be the immediate reputation objective. Just do not describe it internally or to a client as deletion. The distinction matters when you assess remaining exposure.

    Match the page state to the correct removal tool

    Three blank browser-page objects show a live page, a broken page, and an updated page beside different removal tools.

    Start with the current state of the page, not the severity of the complaint. A severe problem submitted through the wrong workflow is still the wrong request.

    1. You control the site and need short-term containment: use the URL removal tool in Google Search Console. It can temporarily hide a URL or directory from search results for up to six months. Use that window to complete the permanent site-side change. A directory-level request can affect multiple URLs, so confirm its scope before submitting it.
    2. The source page was deleted or changed, but Google still shows the old result: use the public outdated content removal tool. This workflow helps trigger a recrawl after the source has changed. It is not a way to remove an unchanged third-party page simply because you object to it.
    3. The result exposes eligible personal information: use Results About You. Its covered categories include sensitive material such as government-issued identifiers and non-consensual explicit imagery. Eligibility depends on the type of information, not only on the distress or reputational damage it causes.
    4. The case involves non-consensual explicit images or other sensitive personal material on a third-party site: evaluate Google’s separate personal content removal form. This route can overlap with the concerns handled through Results About You, but it remains a distinct request path. Neither route forces the third-party publisher to delete its copy.
    5. The request depends on a legal right: use the relevant legal removal workflow. Available grounds can include copyright infringement and defamation, but a negative statement is not automatically defamatory and possession of a copy does not automatically establish copyright ownership. If the request depends on a legal conclusion, have a qualified lawyer assess it before you file.

    If none of those descriptions fits, repeated submissions through unrelated forms are unlikely to create a new basis for removal. Shift the effort toward publisher outreach, a properly assessed legal escalation, or suppression.

    Build a clean case before you submit anything

    A removal request is easier to route when you can describe the problem without mixing several different outcomes. Prepare a short case brief even if the eventual form asks for less information.

    • Exact URL: record the page address appearing in search, not merely the site’s homepage or domain.
    • Current source state: note whether the page is live, deleted, inaccessible, or materially changed. Save a dated screenshot before further outreach if the original state may matter.
    • Affected query: record the name, brand, product, or other search that exposes the result, along with the visible title and snippet.
    • Control: state whether you own the website, can contact its owner, or have no relationship with the publisher.
    • Removal basis: classify the case as temporary hiding, outdated content, eligible personal information, sensitive imagery, or a specific legal claim.
    • Requested outcome: say whether you want the source deleted, Google’s stale result refreshed, or the URL excluded from Google Search.
    • Previous action: document deletion, correction, publisher outreach, and earlier Google requests so that your team does not repeat work or submit conflicting explanations.

    Then use a simple sequence: change or remove the source when you can, submit the narrowest applicable Google request, record what you submitted, and check the source page and Google result separately. A request can succeed at the search layer while the content remains fully accessible at its original address.

    Handle sensitive evidence carefully. Government identifiers, explicit imagery, and similar material should not be copied into routine internal messages or shared beyond the people who need it for the request. If preserving or submitting evidence could affect a legal dispute, ask counsel how it should be retained.

    A removed result can still be a live reputation risk

    An empty space in a blank search-results panel sits in front of a still-active webpage connected to servers and devices.

    Track four outcomes separately

    A single completed status does not tell you whether the problem is resolved. Track the case at four layers:

    • Source status: is the original page live, corrected, or deleted?
    • Google status: does the exact URL still appear for the queries that matter?
    • Distribution status: is the same content discoverable through direct access or other search engines?
    • Reputation status: do searchers now see an accurate set of results, or does the unwanted URL still dominate nearby queries?

    This prevents a temporary Google action from being mistaken for complete resolution. Google’s tools cannot delete third-party content or remove it from every search engine. They address Google Search visibility within defined policies.

    Run removal and suppression as parallel tracks

    Do not wait for a removal decision before planning for the possibility that the request is ineligible, temporary, or narrower than expected. Continue appropriate publisher outreach while improving legitimate pages that should rank for the affected name or brand.

    Suppression is not a euphemism for deletion. It means creating and optimizing accurate, relevant content so that searchers encounter better information first. It is often the practical route when a page violates no applicable removal policy, the publisher will not cooperate, or the same reputation issue appears across several discovery channels.

    Escalate according to the real obstacle. A reputation specialist can help coordinate publisher outreach and search strategy. A lawyer is the appropriate professional when the case turns on copyright ownership, defamation, court orders, or another legal right. Neither should be treated as a guarantee that lawful third-party content will disappear.

    Key takeaways

    • Deleting a page at its source removes the content; deindexing only removes its Google Search visibility.
    • Google Search Console’s URL removal tool is temporary, with hiding available for up to six months.
    • The outdated content tool is appropriate after a page has already been deleted or changed, not as a shortcut for an unchanged page.
    • Results About You and the personal content removal form cover defined categories of personal or sensitive material.
    • Legal removal requests require an applicable legal basis; reputational harm by itself does not establish one.
    • Source resolution, Google removal, monitoring, and suppression are separate workstreams and should be measured separately.

    Start by writing one sentence that states whether the page is live, deleted, or changed; whether you control it; and which removal category applies. That sentence will usually identify the correct Google route. Submit it, document it, and open the source-side or suppression track without treating the search request as the whole solution.

    References


  • How Publishers Should Respond to a Suspected False DMCA Claim

    How Publishers Should Respond to a Suspected False DMCA Claim

    If investigative reporting disappears from Google after a copyright complaint, treat it as a two-track incident. You need to preserve the record showing how the work was created while identifying the precise route for restoring lawful visibility. Rewriting the page, replacing files, or accusing the claimant in public before you do either can make the dispute harder to untangle.

    The risk is not hypothetical. In one documented dispute, a March 27 notice accused Search Engine Land of copying text verbatim and using proprietary images, after which Google removed the affected URL from search results. Clickout Media’s alleged transformation of news sites into AI-driven gambling platforms was the investigation’s subject. The important operational lesson is that a copyright allegation can interrupt distribution before the underlying merits have been publicly resolved.

    Confirm what was removed before arguing about why

    A search delisting, hosting takedown, CDN block, CMS suspension, and deleted page are different failures. They affect different surfaces and require different remedies. Do not describe the reporting as “taken down” until you know which system stopped serving or surfacing it.

    1. Preserve the notice exactly as received. Save the message body, attachments, raw email headers, claimant details, alleged copyrighted work, disputed URL, case number, and receipt time. Export the platform dashboard entry as well as taking screenshots.
    2. Test the direct URL. Record whether it loads, redirects, returns an error, or displays a platform warning. Save the response code, page source, screenshot, and test time. A page that remains directly accessible but is absent from search has a different recovery path from one removed by its host.
    3. Check each discovery surface separately. Inspect Google results, Google Search Console messages, the XML sitemap, internal links, news or topic hubs, syndication copies, and any platform-specific index. Search results vary, so the absence of a result in one manual query is not enough by itself to establish a formal removal.
    4. Identify the decision-maker. Determine whether the action came from the search engine, hosting provider, CDN, registrar, CMS vendor, social platform, or another intermediary. Send a response to the organization that can actually reverse the action.
    5. Freeze mutable evidence. Export the published page, CMS revisions, drafts, source notes, media files, metadata, and rights records before changing anything. Make a read-only archive and record checksums for important files so later changes can be detected.

    Create one incident record with the disputed URL, notice identifier, affected services, first observed time, current page status, response deadline, internal owner, legal owner, and every action taken. This prevents editorial, SEO, engineering, and legal teams from creating conflicting versions of events.

    Do not evade a removal by immediately cloning the page to a new URL. That can multiply the disputed URLs, confuse canonical signals, complicate the evidence trail, and create additional legal exposure. Preserve first, then decide what may lawfully remain available with qualified counsel.

    Build an allegation-by-allegation evidence packet

    Original files, notes, photographs, metadata panels, and archival sleeves are organized into paired evidence groups on a worktable.

    A notice is not proven false merely because its timing looks suspicious or its effect is damaging. Treat “false,” “mistaken,” “unsupported,” and “abusive” as different conclusions. You need testable contradictions: the cited words do not appear on the page, the image was licensed, the claimant has not established ownership, the chronology is impossible, or the notice identifies the wrong URL.

    Question to testEvidence to assembleWhat the response should show
    Was text copied verbatim?Draft history, reporter notes, source links, timestamps, and a side-by-side comparison of the exact passagesWhich words are actually shared, where they appear, and whether the notice accurately describes the overlap
    Was an image used without permission?Original file, creator identity, license or assignment, receipt, attribution record, metadata, and the terms captured when the asset was obtainedWhich image is disputed and the specific basis on which it was published
    Does the claimant control the asserted rights?The work identified in the notice, its URL and publication date, the claimant’s stated relationship to it, and any ownership records suppliedWhether the notice connects the claimant to the particular material at issue
    What action actually occurred?Direct-URL tests, platform messages, Search Console records, screenshots, response codes, and timestampsWhich service restricted the page, when it happened, and whether the restriction is still active
    What changed after publication?CMS revisions, media replacements, redirects, correction notes, deployment logs, and editor approvalsA clean chronology that distinguishes the original publication from later edits

    Keep the evidence factual and compact. A platform reviewer should not have to infer your rebuttal from a folder of unrelated screenshots. Number each allegation, quote only the minimum text needed to identify it, attach the corresponding proof, and state the requested remedy for that allegation.

    Preserve unfavorable evidence too. If an image license is ambiguous or a passage is closer than expected, hiding that weakness will not improve the legal position. Flag it for counsel and separate it from allegations you can disprove cleanly. A mixed notice may contain an unsupported claim alongside a genuine rights problem.

    Choose the response path with counsel, not by reflex

    The fastest-looking option is not always the safest one. An informal correction request, platform appeal, asset replacement, negotiated resolution, and formal counter-notice carry different consequences. The right route depends on who acted, what the notice alleges, whether the material remains online, and what your evidence establishes.

    Start with a precise administrative response when appropriate

    If the platform offers an appeal or reinstatement process, answer the notice rather than the suspected motive behind it. A useful submission contains the case identifier, exact URL, current status, a numbered response to every allegation, supporting records, the requested action, and a contact authorized to handle follow-up.

    Avoid a long defense of the investigation’s public importance as a substitute for copyright evidence. Public-interest reporting may explain the stakes, but it does not by itself resolve who owns an image or whether wording was copied. Lead with the evidence that answers the claim.

    Treat a counter-notice as a legal act

    A formal counter-notice is not an ordinary customer-support reply. Depending on the process, it may require legal declarations, identification details, and consent connected to jurisdiction. An inaccurate submission can create exposure beyond the original search problem. Have qualified copyright counsel review the notice, the evidence, the governing procedure, and the final language before filing. If the publisher, claimant, or platform is outside the United States, counsel should also confirm which law and process actually apply.

    If you discover a genuine asset problem, preserve the original state before removing or replacing the asset. Record what changed, when, why, and who approved it. Let counsel decide whether any accompanying statement could be interpreted as an admission.

    Keep the public statement narrower than the evidence

    You can accurately say that a notice was received, a URL was affected, the claim is disputed, and a review or appeal is underway when those facts are documented. Do not label the claimant fraudulent, corrupt, or criminal merely because the notice appears weak. Those are separate allegations with their own evidentiary and legal risks.

    Coordinate the public statement with the formal response. A social post written in anger can contradict an appeal, disclose material intended for counsel, or lock the publisher into a conclusion before the evidence review is complete.

    Protect search and AI visibility without compromising the dispute

    An editor and counsel stand beside preserved files as parallel paths lead toward a legal process and an abstract online discovery network.

    Availability and discoverability are separate. A page can remain live for direct visitors while losing search distribution, which can also reduce the chance that search-connected AI systems retrieve or cite it. Recovery work therefore needs legal, technical, editorial, and communications owners working from the same incident record.

    1. Keep the established URL stable when publication remains lawful. Avoid unnecessary slug changes, redirect chains, or duplicate copies. Continue linking to the URL from relevant author, topic, and investigation pages unless counsel or the serving platform requires otherwise.
    2. Record every post-notice change. If wording, images, metadata, canonicals, redirects, or access controls change, preserve the previous state and log the reason. Silent edits blur the chronology that reviewers and counsel may need.
    3. Make authorship and publication data explicit. Accurate Article or NewsArticle structured data can identify the author, publisher, publication date, modification date, headline, and canonical page for machines. Schema helps systems interpret those public assertions; it does not prove copyright ownership, invalidate a notice, or guarantee restoration in search or an AI answer.
    4. Use only lawful distribution paths. Keep newsletters, feeds, archives, and authorized syndication copies functioning where rights and contracts permit. Do not create mirrors solely to route around a restriction.
    5. Monitor the actual failure mode. Track whether the direct page loads, whether the platform case changes, whether Search Console reports a new status, and whether the canonical URL returns to relevant results. A ranking fluctuation is not the same as reinstatement.

    Do not promise that structured data, internal links, or republication will force a frontier model to cite the investigation. Those measures can improve machine-readable provenance and create legitimate discovery paths, but none overrides a platform’s legal process.

    Make the next incident easier to defend

    The strongest preventive control is not a disclaimer. It is a publication record that can be assembled before a notice arrives. For investigative work, retain source notes, timestamped drafts, editorial approvals, original media, licenses, attribution decisions, screenshots of asset terms, correction history, and deployment records under a defined retention policy.

    • Create a dedicated intake address for copyright notices and route it to editorial, legal, SEO, and engineering owners.
    • Use a standard incident template containing the notice ID, claimant, asserted work, disputed material, affected URL, platform, deadline, evidence owner, legal status, search status, and approved public language.
    • Require provenance records for every non-original image, chart, document excerpt, and embedded media item before publication.
    • Keep CMS revision history and media replacements attributable to named users rather than relying on shared accounts.
    • Prepare platform-specific access instructions so the person handling the incident can reach hosting, CDN, Search Console, analytics, and syndication records without waiting for credentials.

    These controls will not prevent someone from filing a questionable notice. They reduce the time spent reconstructing authorship, rights, and platform status after the reporting has already lost distribution.

    Key takeaways

    • Confirm whether the page was deleted, blocked, deindexed, or merely absent from a particular query before choosing a remedy.
    • Preserve the notice, published page, drafts, source records, media provenance, platform messages, and technical status before making changes.
    • Rebut each allegation with matched evidence; suspicious timing alone does not establish that a DMCA claim is false.
    • Have qualified copyright counsel review any formal counter-notice or response that could create legal exposure.
    • Keep lawful URLs and provenance signals stable, but do not clone pages or use schema as a way to evade a platform restriction.

    Your first objective is a clean factual record, not the loudest rebuttal. Once that record exists, counsel can choose the legal route, the platform team can request the correct remedy, and the SEO team can restore discoverability without creating a second problem.

    References


  • AI Gambling Content on News Sites: An Audit and Recovery Plan

    AI Gambling Content on News Sites: An Audit and Recovery Plan

    Your news site can look credible at the domain level while a growing section underneath it is serving a different business entirely. If casino pages, fabricated contributors, unexplained redirects, or generic betting copy have appeared after an ownership or commercial change, you need to determine whether you have an editorial-quality problem or a reputation-abuse problem.

    That distinction changes the response. Editing a few weak paragraphs will not fix a system designed to turn inherited authority into gambling-affiliate revenue. You need to audit who controls publication, why the pages exist, where their links lead, and whether the people named on them are real and accountable.

    Key takeaways

    • AI is usually the scaling mechanism, not the core abuse. The core problem is using a trusted news domain to rank commercially motivated pages that would struggle to earn visibility on their own.
    • Do not base your decision on writing style or an AI-detector score. Confirm the editorial chain, author identity, affiliate relationship, outbound destinations, ownership history, and publication pattern.
    • Not every gambling page on a news site is abusive. Public-interest reporting, industry analysis, and sports coverage can be legitimate when editorial purpose remains primary and commercial relationships are subordinate and disclosed.
    • Freeze suspect publishing before you clean up. Preserve records, classify every affected URL, remove deceptive identity claims, and address the access or contract that allowed the pages to appear.
    • Author schema, affiliate disclosures, or an AI label cannot rescue a page whose real purpose is to exploit the publisher’s reputation.

    AI is the accelerant; inherited trust is the asset

    Calling this an AI-content problem is accurate but incomplete. A new gambling site can generate just as much copy without possessing a news brand’s history, links, returning audience, or established search visibility. The valuable asset is the host domain’s reputation. AI makes it cheaper to cover more queries and replace more human work once that reputation is under commercial control.

    The documented pattern has involved acquiring established sports, gaming, and technology publications, retaining enough legitimate material to preserve credibility, and then increasing casino and cryptocurrency coverage. Former employees said original reporting was removed while AI-generated pages and fabricated author profiles expanded. Affiliate links supplied the commercial path, including arrangements connected to player losses.

    That sequence matters because it gives you a better diagnostic question than “Was this written by AI?” Ask: “Would this page have been commissioned, placed on this domain, and promoted in this way if the domain had no inherited authority?” If the honest answer is no, investigate the business model behind the URL.

    Google describes attempts to exploit an established site’s ranking reputation through scaled publishing as site reputation abuse, with manual action and removal from the search index among the possible consequences. AI use alone does not establish that purpose. A human-written casino landing page can be abusive, while an AI-assisted investigation into gambling regulation can still serve a legitimate editorial purpose. Intent, control, accountability, and reader value have to be examined together.

    One documented operation does not prove that every newsroom with casino content follows the same sequence. Treat the pattern as a risk model, not a verdict. Your own CMS, contracts, author records, link destinations, and editorial decisions must supply the evidence.

    Audit the publishing system, not just the prose

    Evidence table with a laptop, servers, access tokens, profile cards, casino chips, coins, and branching pathways under a magnifying lens.

    Start with an inventory. A handful of visible pages rarely shows the full footprint because the same operation may use directories, author archives, old templates, redirected URLs, or pages that are absent from navigation. Combine your CMS export, XML sitemaps, crawl data, server or analytics records, and Google Search Console data where you have access.

    Record one row per URL with the title, topic, publication and modification dates, named author, assigning editor, content owner, template, indexability, canonical target, structured-data author, internal links, outbound domains, redirect destinations, affiliate identifiers, and current classification. Include deleted or unpublished records when the CMS retains them. Chronology often reveals the commercial pivot more clearly than any single page.

    SignalWhy it deserves attentionWhat to verify before acting
    Casino or cryptocurrency coverage expands after an ownership, contractor, or leadership changeThe topical pivot may reflect a new affiliate model rather than audience demandAcquisition documents, editorial plans, partner agreements, CMS users, and the first publication dates
    Authors have thin, duplicated, or unverifiable profilesA fabricated byline removes accountability and misrepresents who produced the pageAssignment records, employment or contributor records, editor correspondence, revision history, and identity details supplied by the person
    Pages repeatedly send readers to casino offers or comparison pagesThe primary purpose may be acquisition rather than reportingFinal redirect destinations, affiliate parameters, commercial contracts, disclosure placement, and who approved each domain
    Original reporting is removed, buried, or replaced by templated commercial pagesThe publisher’s accumulated reputation is being separated from the work that earned itCMS revisions, backups, navigation changes, redirect maps, and archived internal records
    Search visibility drops or a manual action appearsThe problem may already affect the whole publishing property, not only the gambling sectionThe exact Search Console notice, affected patterns, index coverage, canonical behavior, and alternate URLs carrying the same material

    Trace the money and every outbound hop

    Review the commercial path in read-only fashion. Record the visible call to action, the first linked domain, every redirect, the final operator, and any tracking value. Do not register, deposit money, submit personal data, or bypass access controls to complete the audit. The objective is to document what the publisher sends a reader toward, not to transact with it.

    Then connect those destinations to contracts and payments. Identify the legal party receiving revenue, the person who approved the relationship, the compensation model, and any intermediary that can change a destination without another editorial review. A disclosure may tell readers that a commercial relationship exists, but it does not answer whether inherited authority is being exploited or whether the destination was properly vetted.

    An offshore operator is not automatically unlawful in every jurisdiction. It does create a verification burden because gambling promotion, licensing, age restrictions, and consumer protections depend on where the publisher and reader are located. Before retaining or republishing an offer, have counsel familiar with the relevant jurisdictions assess it. An SEO audit cannot make that legal determination.

    Verify authorship as an accountability chain

    A profile photo and biography are not enough. For each contributor, confirm who assigned the work, who created the CMS account, who edited the page, where the draft originated, who checked factual claims, and who can correct it now. A real person’s name attached without their knowledge is still deceptive. A generic “Editorial Team” byline is not a valid repair if nobody inside the organization accepts responsibility for the content.

    Compare the visible byline with the Article and Person data emitted by the page. The name, publisher, reviewer, profile URL, and sameAs references should describe the same real editorial relationship shown to readers. Structured data should map accountable facts; it should never be used to manufacture an expert, disguise an affiliate, or make a synthetic persona look established.

    Reconstruct the timeline and access path

    Place ownership events, staffing changes, new CMS accounts, template deployments, affiliate contracts, and topic growth on one timeline. You are looking for control points: the moment a partner gained publishing access, a new section bypassed normal editing, or an outbound-link system made destinations changeable after approval.

    This separates individual page defects from systemic abuse. If the same account created false authors, generated pages, and inserted commercial links, removing the URLs without revoking that control leaves the mechanism intact. If a contract grants an external party broad publishing rights, the problem may persist even after a password change.

    Separate legitimate coverage from reputation exploitation

    Do not bulk-delete everything containing the words casino, betting, or gambling. A news organization may have valid reasons to cover regulation, addiction, sports sponsorship, corporate results, consumer risk, crime, or technology. Destruction without classification can erase legitimate journalism, break useful links, and make later review harder.

    Use the following questions as an editorial triage model. They are not a substitute for Google’s own case-specific decision or legal advice.

    1. What job does the page perform? A reporting page helps the reader understand an event, claim, risk, or decision. An acquisition page is organized around sending the reader to an operator.
    2. Why does it belong on this publication? Audience need, newsroom expertise, and an established coverage remit are defensible reasons. Access to a strong domain is not.
    3. Who commissioned and controlled it? Identify an accountable editor and the editorial rationale. “The partner supplied it” is a warning, especially when the partner also benefits from clicks or losses.
    4. What evidence is unique to the page? Look for original reporting, attributable analysis, transparent methodology, or clearly sourced facts. Generic rewrites surrounding a commercial link provide little editorial justification.
    5. Is the author real and responsible? Confirm the person, assignment, expertise, edits, and correction path. Do not infer legitimacy merely because a profile exists.
    6. Is monetization subordinate to editorial purpose? Commercial links should not dictate the topic, conclusion, rankings, or recommendation. Disclosure is necessary when a relationship exists, but disclosure does not neutralize a compromised purpose.
    7. Would you publish it without search traffic or affiliate payment? This counterfactual exposes pages whose only rationale is borrowed ranking power.

    Classify each URL as keep, rebuild, remove, or escalate. Keep pages with a defensible public-interest purpose and accountable production. Rebuild pages where the subject belongs but the sourcing, identity, disclosures, or commercial balance do not. Remove pages built primarily to exploit inherited reputation. Escalate anything involving disputed ownership, contractual duties, regulatory exposure, impersonation, or evidence that may need to be preserved.

    An AI label does not change that classification. Neither does fluent prose. The relevant question is whether a responsible newsroom stands behind the page and can show why it exists.

    Contain the abuse before attempting a ranking recovery

    Containment comes first because continued publication can enlarge the affected footprint while the audit is underway. Recovery work should follow a controlled sequence.

    1. Pause suspect publishing and link changes. Freeze the affected workflow, not the entire newsroom, unless you cannot isolate it safely. Preserve access and activity records before disabling accounts.
    2. Create a recoverable evidence set. Back up the database and relevant files. Save the URL inventory, rendered pages, structured data, redirect chains, contracts, CMS histories, and approval records. If litigation, employment action, a regulatory inquiry, or contractual conflict is possible, let counsel set the retention process before anything is destroyed.
    3. Remove unauthorized control. Revoke unneeded CMS accounts, API keys, deployment access, redirect management, affiliate dashboards, and shared credentials. Review scheduled jobs and integrations that can recreate deleted pages.
    4. Apply the URL decisions. Keep legitimate reporting, rebuild salvageable coverage, and remove abusive pages. A removed page with no genuine replacement should return an appropriate not-found response. Redirect only when a truly equivalent destination exists; sending every deleted URL to the homepage hides the cleanup rather than preserving meaning.
    5. Clean the surrounding architecture. Update menus, category archives, author archives, internal links, sitemaps, canonical tags, feeds, related-content modules, and cached versions. Check subdomains and alternate templates so the same material is not still indexable elsewhere.
    6. Correct identity and schema. Delete fabricated profiles, restore accurate bylines, name accountable editors where appropriate, and align Article, Person, and Organization data with visible facts. Do not transfer a fake persona’s history to a new generic identity.
    7. Address the search action shown to you. If Google Search Console displays a manual action, use the process and scope described there after the cleanup is complete. Document what caused the problem, what was removed, what access changed, and which controls now prevent recurrence.

    Do not promise a quick return to previous visibility. In the documented pattern, some publications were deindexed, abandoned, closed, or affected by layoffs after penalties. Those outcomes show why ranking recovery is not the only objective. You are also protecting readers, employees, contributors, commercial partners, and the brand’s remaining credibility.

    Measure progress by more than aggregate organic traffic. Track whether removed URLs remain unavailable, alternate copies disappear, unauthorized outbound domains stay blocked, author records remain accurate, manual-action status changes, and legitimate sections recover stable discovery. A traffic rebound without control of the publishing system is not a durable recovery.

    Build controls around access, money, and identity

    News operations room with casino-related materials and cables isolated behind a transparent barrier beside locked access, payment, and identity controls.

    A policy that merely requires human editing will not prevent recurrence. A human can approve a deceptive page, and an AI system can assist with legitimate newsroom work. Put controls at the points where commercial incentives can override editorial responsibility.

    • Require a named internal owner for every section. That person should be able to explain its audience, commissioning standard, revenue relationship, correction process, and current contributors.
    • Separate publication from commercial destination control. Do not let one external partner create authors, publish pages, and change outbound targets without an independent review.
    • Maintain an approved-domain register. Record the owner, destination, jurisdictional review, affiliate relationship, approver, and permitted context for every gambling-related outbound domain. Re-review a link when its final redirect destination changes.
    • Make author creation a governed action. Require verifiable identity, a real editorial relationship, an accountable editor, and a documented correction route before a profile can publish.
    • Validate structured data against the CMS record. Flag mismatches between visible and machine-readable authors, publishers, reviewers, dates, and profile URLs. Do not generate Person entities merely because a content template expects one.
    • Review commercial topic pivots explicitly. A major expansion into casinos or cryptocurrency should require editorial, SEO, legal, and brand review before pages are commissioned, not after they rank.
    • Include publishing access in acquisition due diligence. Examine affiliate agreements, content ownership, CMS roles, redirect services, historical manual actions, high-volume directories, author authenticity, and any partner with post-publication control.
    • Audit AI workflows by risk, not by tone. Check provenance, claims, links, author accountability, disclosures, and approval. Polished language is not evidence of safe production.

    The most useful first move is small and concrete: export every URL in the affected section and add columns for owner, real author, editorial purpose, outbound destination, affiliate relationship, and decision. Any row you cannot complete has identified a control gap. Resolve those gaps before the next page is published.

    References


  • How to Defend Your Brand and Stay Visible in AI Search

    How to Defend Your Brand and Stay Visible in AI Search

    Your brand can appear in an AI answer and still lose the decision. The system may name you, then attach an outdated limitation, confuse your product with another company, cite a weak page, or frame a legitimate tradeoff as a reason to avoid you.

    If buyers use ChatGPT, Gemini, and Perplexity to evaluate brands, visibility and brand defense have to become one operating discipline. You need to know which questions matter, what the systems are saying, which public evidence supports those answers, and who will correct a problem when the narrative drifts.

    Key takeaways

    • Do not measure visibility as a simple mention. Separate presence, citations, factual accuracy, decision framing, and answer volatility.
    • Build your audit around the prompts buyers use to discover, compare, validate, question, and reject a brand.
    • Maintain a claim ledger that connects every important brand statement to a canonical page, supporting evidence, an owner, and a freshness trigger.
    • Use structured data to reinforce visible, consistent facts. Schema cannot repair weak evidence or persuade a system that your claims are true.
    • Treat accurate criticism, stale information, factual errors, subjective opinions, and identity confusion as different problems. Each requires a different response.
    • Judge progress by whether important answers become more accurate and supportable across a stable prompt set, not by whether one screenshot looks favorable.

    Map the prompts where your brand wins or loses the decision

    A conventional keyword list will miss much of the risk. Brand decisions often unfold through conversational prompts that combine a product, situation, objection, and desired outcome. A buyer may not search your name until late in that sequence.

    Prompt research for SEO and GEO starts by reconstructing that decision, not by adding question marks to existing keywords. Gather the language used in sales calls, support tickets, on-site search, reviews, community discussions, comparison pages, and customer interviews. Convert recurring needs and objections into prompts that sound like questions a buyer would actually ask.

    Cover the full decision journey

    Your prompt set should include several distinct jobs:

    • Discovery: Which products or providers solve a defined problem for a particular type of buyer?
    • Fit: Is your brand suitable for a specific use case, company size, location, budget, technical environment, or constraint?
    • Comparison: How does your brand differ from a named competitor or another category of solution?
    • Validation: Is the company legitimate, established, available, secure, compliant, reliable, or well supported where those criteria genuinely apply?
    • Objection: What are the disadvantages, complaints, limitations, cancellation terms, switching costs, or reasons not to choose it?
    • Change: Is an old criticism, discontinued feature, previous price, former policy, or earlier incident still relevant?

    Keep branded and unbranded prompts separate. Unbranded prompts reveal whether the system associates you with the category at all. Branded prompts reveal what happens after someone already knows your name. A strong branded answer does not compensate for absence during discovery, and a discovery mention does not protect you from a damaging validation answer.

    Prioritize by consequence, not prompt volume alone

    Give priority to prompts that combine a likely buyer action with a meaningful consequence. A broad question about your industry may produce an interesting answer but little business value. A question about whether your product meets a buyer’s non-negotiable requirement can decide the sale.

    For each prompt, record the intended audience, journey stage, decision at stake, correct answer, acceptable nuance, and evidence that should support it. This becomes the test specification. Without it, teams tend to label any positive mention a success even when the answer is incomplete, poorly cited, or aimed at the wrong customer.

    Do not quietly rewrite a difficult prompt until the answer improves. Preserve natural objections and hostile wording in the audit. Those are often the prompts that expose stale claims, unresolved complaints, and ambiguity in your public record.

    Audit AI answers as claims, not conventional rankings

    An overhead view shows an analyst inspecting translucent answer cards, evidence tokens, broken connections, and mismatched product shapes with a magnifying lens.

    An AI answer is not a fixed search result. Wording, source selection, context, and recommendations can change between sessions. One favorable response is an observation, not a durable position.

    Make each test reproducible enough to investigate. Record the platform, visible model or search mode, date, prompt text, language, location when relevant, sign-in state, and any preceding conversation. Save the complete answer and every visible citation. Run important prompts in fresh sessions as well as realistic follow-up conversations because prior context can change the result.

    Separate the failure types

    Observed resultWhat it may indicateFirst corrective move
    Your brand is absent from important discovery promptsThe public record may not connect the brand clearly enough to the use case, audience, or category.Strengthen the relevant use-case page and seek credible corroboration where buyers already research the category.
    Your brand is named without supporting citationsThe mention may be difficult for a buyer to verify and vulnerable to inconsistent framing.Make the underlying identity and product claims explicit on stable, accessible pages.
    The answer cites a page but states the fact incorrectlyThe cited passage may be ambiguous, stale, poorly qualified, or contradicted elsewhere.Correct the nearest authoritative page and remove conflicts between current and legacy content.
    The answer repeats an accurate negative factThe root problem is operational or reputational, not merely an optimization gap.Fix the underlying issue, then publish a precise account of the current state and any remaining limitation.
    The answer makes an unsupported harmful claimThe system may be mixing entities, extrapolating from weak evidence, or reproducing an external error.Preserve the test conditions, trace any cited origin, report the error where possible, and publish a narrowly evidenced correction.
    The facts are correct but the recommendation is unfavorableYour offer may be a poor fit for the stated need, or your differentiator may lack credible support.Clarify who the product is and is not for. Do not try to turn a genuine mismatch into a visibility problem.

    Use a scorecard that preserves the diagnosis

    A single visibility score hides too much. Track these dimensions separately:

    • Presence: whether the brand appears in the priority prompt set.
    • Citation coverage: whether material claims are accompanied by accessible sources that actually support them.
    • Claim accuracy: whether each identity, product, policy, price, availability, and qualification statement matches the current approved record.
    • Decision framing: whether the answer explains the brand’s fit, limitations, and differentiators fairly.
    • Source quality: whether the answer relies on canonical pages, credible independent evidence, low-quality aggregators, or irrelevant pages.
    • Volatility: whether the conclusion changes materially when the same documented test is repeated.
    • Correction status: whether a detected problem is unverified, confirmed, assigned, repaired at its origin, externally disputed, or resolved in later tests.

    Review citations claim by claim. A reputable domain can still be cited for a statement it does not support. A correct answer can also rest on a stale source and become wrong after your next product or policy change. The audit has to evaluate the evidence chain, not just the domain name or tone of the answer.

    Build a source-of-truth system that AI can reconcile

    A layered central repository connects product, policy, support, and review objects to several abstract AI nodes while conflicting fragments are reconciled.

    You cannot force a generative system to choose your preferred page. You can make the public record less ambiguous. The goal is a set of current, specific, mutually consistent facts that a buyer, publisher, search engine, or AI system can verify without guessing.

    Create a claim ledger before creating more content

    A claim ledger is a working inventory of statements that influence whether someone chooses or trusts the brand. Include identity, ownership, product capabilities, intended users, availability, pricing structure, service limits, cancellation or return terms, support, security, privacy, compliance, and performance claims where relevant.

    Each ledger entry should contain:

    • The exact claim and the qualifiers needed to keep it accurate.
    • The canonical public URL where a person can verify it.
    • The evidence behind the statement, including internal approval where required.
    • The owner responsible for maintaining the fact.
    • The event that makes the claim stale, such as a product release, policy revision, market exit, rebrand, or contract change.
    • Known third-party pages or old URLs that contradict the current position.
    • The priority prompts and audiences affected if the claim is wrong.

    The qualifiers matter. Available in one market is not the same as available everywhere. Supports a workflow is not the same as guaranteeing its outcome. Reviewed against a standard is not automatically the same as certified. Removing those distinctions may make copy sound cleaner, but it also creates the contradictions that brand-defense work later has to untangle.

    Give each fact a clear public home

    Do not scatter the only complete explanation across press releases, support replies, social profiles, and sales PDFs. Give durable claims a stable home on your site, then link supporting pages back to that canonical explanation.

    • Use an organization page for identity, official names, ownership where appropriate, contact paths, and the relationship between the company and its products.
    • Use product or service pages for capabilities, intended users, prerequisites, exclusions, and current availability.
    • Use pricing and policy pages for terms that affect a purchase or cancellation decision.
    • Use documentation and support pages for setup requirements, technical limits, integrations, and troubleshooting.
    • Use trust, security, privacy, or compliance pages only for claims your responsible teams have verified and approved.
    • Use status, incident, or change pages when the history of a material event needs a dated, factual record.

    Write the decisive answer in visible prose. Put the claim near the question it resolves, use the same product and company names used elsewhere, state important limits directly, and show when time-sensitive information was updated. A vague page surrounded by perfect metadata is still a vague page.

    Use schema as a consistency layer

    JSON-LD can help describe the entity and connect machine-readable properties to the page, but it is not a private channel for claims you chose not to show users. Mark up only facts supported by visible content.

    • Use Organization properties to reinforce the official name, URL, logo, and genuine sameAs profiles.
    • Use Product or Service types only when they accurately match the thing described on the page.
    • Use FAQPage only when the questions and complete answers are visible to the reader.
    • Keep names, URLs, identifiers, offers, authorship, and dates aligned with the page and the rest of the site.
    • Validate syntax, but also review semantics. Technically valid markup can still describe the wrong entity or overstate what the page proves.

    Structured data does not guarantee inclusion, citation, or a favorable answer. Its defensive value is precision: it reduces avoidable ambiguity when the markup, visible copy, internal links, and external profiles all describe the same entity.

    Seek corroboration, not manufactured consensus

    Your site is the appropriate authority for many first-party facts, but it cannot independently prove every claim about quality, reputation, or market standing. Earned coverage, accurate directory records, relevant reviews, partner documentation, and expert references can provide independent context when they are legitimate and specific.

    Do not flood low-quality sites with identical claims or disguise promotional placements as independent evidence. That creates a larger cleanup problem and gives buyers little reason to trust the result.

    If you hire outside help, assess AI visibility and LLM citation services by their actual deliverables: prompt mapping, source analysis, claim correction, structured-data review, credible authority building, monitoring, and handoff. A collection of favorable answer screenshots is not a defensible operating system.

    Defend the narrative without trying to erase criticism

    Defensive SEO for AI search is not reputation laundering. Its legitimate purpose is to keep consequential answers accurate, current, properly attributed, and proportionate to the available evidence.

    Classify the disputed claim before publishing a response:

    • Accurate criticism: Fix the underlying product, policy, or service issue. Explain what changed, when it changed, and what limitation remains. Content cannot substitute for the remedy.
    • Previously accurate but stale: Add date context and a clear current-state statement. If the old condition was once true, acknowledge the change instead of pretending the history never existed.
    • Factually wrong: Correct the exact proposition with direct evidence. A broad page claiming that the brand is trustworthy will not resolve a specific error about ownership, price, availability, or policy.
    • Subjective disagreement: Do not relabel opinion as misinformation. Publish fit criteria, tradeoffs, and a candid not-for-you explanation so the buyer can decide.
    • Entity confusion: Reconcile company names, product names, domains, profiles, logos, and relationships. Ask publishers and directory owners to correct records that merge separate entities.
    • Impersonation or materially harmful allegation: Preserve the complete answer, prompt context, date, visible citations, and origin pages. Route it promptly to communications and legal counsel rather than starting an improvised public dispute.

    For regulated, contractual, security, privacy, or financial claims, the accountable subject-matter owner should approve the correction before publication. An overconfident rebuttal can create more exposure than the original AI error. Counsel should decide whether a correction request, takedown request, formal response, or another remedy is appropriate when the allegation could create legal harm.

    Publish the answer a skeptical buyer actually needs

    A defensive page should resolve uncertainty, not demand trust. State the question plainly. Give the short answer. Present verifiable evidence. Explain scope and exceptions. Include the current date where the fact can change. Link to the policy, documentation, incident record, or independent corroboration that carries the detail.

    Comparison content deserves the same discipline. Use criteria a buyer can inspect, distinguish facts from judgments, date changeable details, and correct competitor information when you learn it is stale. A fair comparison is easier to defend and more useful than a page designed only to declare a winner.

    Avoid publishing a new rebuttal for every unfavorable phrase. That can spread the language, fragment your explanation, and create additional conflicting URLs. Repair the canonical source first. Create a dedicated response only when the issue has enough decision impact to need its own durable explanation.

    Turn monitoring into a correction workflow

    Monitoring has little value if every problem ends as a screenshot in a report. Each confirmed issue needs a class, an owner, a source-level repair, and a retest condition.

    Use the same correction loop every time

    1. Capture the answer. Preserve the complete prompt, conversation context, test conditions, response, and citations.
    2. Verify the problem. Compare each consequential claim with the ledger and repeat the test under documented conditions. Do not escalate a mere wording preference as a factual failure.
    3. Classify the cause. Decide whether you are dealing with absence, unsupported recall, stale evidence, source conflict, factual error, criticism, poor fit, or entity confusion.
    4. Repair the nearest authoritative source. Fix the product or policy first when the criticism is valid. Otherwise, update the canonical page, visible explanation, schema, internal links, and official profiles as appropriate.
    5. Address external origins. Request corrections from publishers, platforms, directories, partners, or review profiles when they carry demonstrably wrong facts. Keep an evidence trail and avoid pressuring anyone to remove legitimate opinion.
    6. Retest the prompt set. Look for accuracy across the affected prompt family, not just a favorable response to the exact wording that exposed the issue.
    7. Log the disposition. Record what changed, who approved it, which URLs were updated, which external requests remain open, and what evidence would count as resolution.

    AI answers may not reflect a correction on your preferred timetable. Do not promise an immediate model update. The controllable work is to remove contradictions, make the correction public and verifiable, pursue errors at their origin, and keep testing the decision prompts that matter.

    Assign ownership before an incident

    • Search or GEO owner: maintains the prompt set, test protocol, evidence captures, and scorecard.
    • Content owner: updates canonical explanations, internal links, page dates, and structured data.
    • Product, support, policy, or operations owner: verifies whether the underlying claim is true and fixes real customer problems.
    • Public relations or communications: manages corrections and context beyond owned channels.
    • Security, privacy, compliance, or legal: handles claims that fall within those functions and decides the appropriate escalation.
    • Executive owner: resolves conflicts when the preferred marketing message does not match the evidence.

    Run focused checks after events that can change the public narrative: a product launch, rebrand, price or policy revision, market expansion, service incident, leadership change, significant coverage, or a surge in customer complaints. Between those events, set the cadence according to decision volume and consequence. A prompt that affects a high-value or high-risk decision deserves closer attention than a broad informational query.

    Start with the prompt carrying the greatest commercial or reputational consequence. Capture the current answer, isolate the most important unsupported or incorrect claim, repair the evidence behind it, and retest the surrounding prompt family. That small loop will tell you more about your real AI visibility than a large dashboard built on undiagnosed mentions.
    References