Tag: Audience Targeting

  • Google Ad Creative and Targeting Updates: An Action Plan

    Google Ad Creative and Targeting Updates: An Action Plan

    If your Demand Gen video was approved down to the last line break, you now have a new reason to inspect the campaign settings: Google may place additional text over that finished creative. If your team manages Display & Video 360 through bulk files, you also have a new schema to accommodate before older workflows reach a hard support deadline.

    These changes affect different products, but they create the same operational problem. The ad that gets served or the audience that gets targeted may no longer be defined only by the asset and configuration your team originally approved. You need an audit trail that covers Google’s transformations as well as your own inputs.

    Know which control surface changed

    There are two separate updates to manage. In Google Ads, Demand Gen campaigns can use existing text assets to generate messages that appear over video. In Display & Video 360, Structured Data Files v11 expand bulk targeting controls and change parts of the file structure used by automated workflows.

    Control layerWhat changedMain riskFirst action
    Demand Gen creativeAutomatic text overlays can be generated from existing text assets.Added copy can obscure the composition, repeat burned-in text, or conflict with the approved message.Inspect the Overlay on videos setting and the text assets available to the campaign.
    DV360 audience targetingSDF v11 supports lookalike audience inclusion and exclusion across eligible ad groups.A blanket bulk-edit rule can apply the wrong audience logic or mishandle an exception.Add explicit inclusion, exclusion, and exception checks to the SDF workflow.
    DV360 location targetingBusiness Chain proximity targeting is available in the line item file format.A bulk upload can extend location targeting to unintended line items.Validate the business-chain configuration at line-item level before scaling it.
    DV360 file automationVendor fields and selected YouTube campaign structures have changed.Existing templates, parsers, and round-trip assumptions can fail or silently omit information.Diff a clean v11 file against the production schema and test a limited batch.

    Keep ownership clear. Creative teams should decide whether a video can tolerate generated copy. Media teams should control the campaign setting. Marketing operations or engineering should own the SDF schema migration. One person should reconcile those decisions before launch; otherwise each team can complete its own task correctly while the final campaign is still wrong.

    Audit Demand Gen overlays before the next launch
    A reviewer inspects a vertical video preview partly covered by blank translucent interface overlays before launch.

    The Overlay on videos control sits under Asset optimization with Shorter videos and Resized videos. It has been observed as enabled by default, so silence is a decision: if nobody checks the setting, Google may add text to a video that your team considered complete.

    Run a campaign-by-campaign creative check

    1. Open each Demand Gen campaign and record the current state of Overlay on videos, Shorter videos, and Resized videos. Do not treat the account-level expectation as proof of the campaign-level state.
    2. Review the beginning, middle, and end of every video. Mark areas occupied by burned-in copy, product details, logos, calls to action, prices, and required disclosures.
    3. Review the existing text assets Google can use as overlay inputs. Remove or revise stale promotions, weak generic claims, mismatched calls to action, and language that does not belong in the campaign’s market.
    4. Decide whether the video is suitable for an overlay test, requires a redesigned overlay-safe version, or should remain unchanged.
    5. Record the decision with the campaign identifier, approver, setting state, date, and reason. This turns an invisible optimization toggle into an accountable creative choice.

    A video with open visual space, little burned-in copy, and tightly governed text assets may be a reasonable candidate for a controlled overlay test. A dense product demonstration, carefully typeset brand film, localized creative, or video with disclosures is a poor candidate for unattended text placement. The relevant question is not whether overlays are useful in general. It is whether this particular composition and message can accept another layer without changing their meaning.

    Do not confuse a generated overlay with closed captioning. The overlay draws from advertising text assets and can reinforce a benefit, promotion, or call to action; it does not necessarily reproduce the spoken content. If the video must be understandable without sound, assess captions and visual storytelling separately.

    Use the narrowest control that matches your decision

    You can turn off Overlay on videos by itself or use Disable all for the available video optimization features. Use the individual switch when your video can tolerate shortening or resizing but not added copy. Use Disable all only when the approved composition must not be altered by any of the listed optimizations.

    Review the three settings independently. Turning off the overlay does not express a decision about shorter or resized versions. Equally, accepting alternate dimensions does not mean text can safely cover any part of the frame. Your approval record should state which transformations are allowed rather than reducing the decision to a vague yes or no on automation.

    Account for the AI-edit label

    When these optimization features modify an image or video, the served ad is labeled as created or edited with AI in the European Union, India, and New York state. That does not determine whether the creative is acceptable for your brand, but it does belong in the approval process. Tell brand, legal, and market owners which assets can be transformed and where the label may appear before they sign off.

    Make SDF v11 a controlled migration, not a file swap
    Two specialists guide blank spreadsheet-like grids through validation checkpoints during a staged file-schema migration.

    Display & Video 360 users can now download and upload SDF v11 directly in the platform. For a team that edits files manually, this is a template change. For a team that generates, validates, or ingests SDFs with code, it is a schema migration with targeting consequences.

    The audience change needs an explicit exception. V11 supports lookalike inclusion and exclusion across ad groups except those under YouTube Ad Sequence line items. A bulk updater should identify those sequence line items before it writes audience fields. Do not treat a rejected or missing value as an unexplained upload anomaly when the campaign type itself is excluded.

    Location logic also moves further into bulk management. Business Chain proximity targeting is now available in the line item format. That makes repeated setup easier, but it also increases the reach of a bad mapping. Confirm the intended business chain and destination line items in the generated output, then begin with the smallest reversible batch that can prove the rule works.

    Use this v11 migration sequence

    1. Inventory every workflow that reads, creates, validates, transforms, or archives an SDF. Include spreadsheets, scripts, data pipelines, naming rules, and reporting jobs.
    2. Record the SDF version each workflow expects. Do not assume the version selected for export is also the version understood by an internal parser.
    3. Download a clean v11 file and compare its headers, accepted values, and restrictions with your production template. Treat column names and structures as a contract; do not reconstruct unfamiliar fields from memory.
    4. Update the audience mapping to handle lookalike inclusion and exclusion separately. Add a deliberate branch for YouTube Ad Sequence line items.
    5. Update line-item logic for Business Chain proximity targeting only if the organization intends to use it. A new available field does not need to become a new default.
    6. Inspect the four updated third-party YouTube vendor columns. They now incorporate reporting IDs and allow multiple vendor assignments, while separate reporting ID columns have been removed. Any script that expects those separate columns needs revision.
    7. Test a limited upload and reconcile the accepted campaign structure against the intended file. Check line-item and ad-group counts, audience inclusions, audience exclusions, location settings, and vendor assignments.
    8. Retain the last accepted file and a change log so the team can reconstruct the previous configuration if the upload produces an unintended change.

    YouTube Instant Deals need a separate path. V11 includes columns and restrictions for their line items, ad groups, and ads, but Instant Deals remain in beta for allowlisted partners. They do not appear in downloaded SDFs and can only be uploaded through the dedicated creation workflow. A system that treats an export as a complete round-trip representation of the account will therefore have a known gap. Document that exception instead of letting the next export overwrite the team’s understanding of what exists.

    There is also a firm planning horizon. SDF versions earlier than v10 are deprecated and will stop being supported in January 2027. At minimum, remove every pre-v10 dependency before that point. Moving directly to v11 gives you time to test the current fields and restrictions without turning a support cutoff into an emergency migration.

    Test creative and targeting changes without confounding them

    An overlay changes what a person sees. A lookalike inclusion, exclusion, or proximity rule changes who can see it. If you change both at once and results move, you will not know whether the message or the audience caused the difference.

    1. Choose one question. For example: does an overlay-safe video with generated messaging improve the campaign’s business outcome, or does a particular lookalike configuration improve audience quality?
    2. Define the primary metric before launch. Click-through rate can describe response to an ad, but it should not replace conversion rate, cost per qualified lead, acquisition cost, or another outcome that reflects the campaign’s actual purpose.
    3. Keep the other major inputs as stable as the account allows. Budget, bid strategy, offer, landing page, audience definition, and creative can all obscure the effect you are trying to measure.
    4. Log the exact configuration: overlay state, shorter-video state, resized-video state, SDF version, audience inclusions and exclusions, and proximity targeting.
    5. Inspect the output as well as the metric. A performance lift does not make obscured product details, duplicated copy, an outdated promotion, or an unintended audience exclusion acceptable.
    6. Set rollback conditions from your own baseline before the change. There is no universal performance threshold that fits every account, but brand obstruction, incorrect claims, lost exclusions, or spend directed to unintended locations should trigger immediate correction.

    For overlays, your evidence should include a visual QA record and the downstream business metric. For SDF targeting, reconcile the uploaded configuration first, then evaluate reach, spend, and conversion quality for the affected audience or location. A clean measurement window cannot rescue an incorrectly configured campaign.

    Keep the change log readable by someone outside the activation team. A useful entry includes the campaign, line item, or ad group identifier; the old and new value; who approved it; the hypothesis; the measurement period; and the rollback condition. This is especially important when a platform-generated creative treatment and a bulk-generated targeting rule can both influence the same result.

    Key takeaways

    • Demand Gen can generate video overlays from existing text assets, and the setting has appeared enabled by default. Audit it rather than assuming the approved master is the served creative.
    • Overlay on videos, Shorter videos, and Resized videos are separate asset-optimization decisions. Disable only the transformations your creative cannot safely accept.
    • Modified image or video assets receive an AI creation or editing label when served in the European Union, India, and New York state, so include that behavior in market and brand approvals.
    • SDF v11 adds lookalike inclusion and exclusion for eligible ad groups plus Business Chain proximity targeting at line-item level. YouTube Ad Sequence line items are the stated lookalike exception.
    • The v11 vendor-column changes and Instant Deal workflow can break assumptions in automated imports and exports. Test the schema and document incomplete round-trip cases.
    • Support for SDF versions earlier than v10 ends in January 2027. Migrate while you still have room to validate small batches and correct the workflow safely.

    Start with two inventories: every Demand Gen campaign whose video can be altered, and every workflow that touches an SDF. Assign an owner to each, record the current state, and make one controlled change at a time. That is how you gain the reach of automation without surrendering control of the message, audience, or spend.

    References


  • YouTube Masthead Access for Online Gambling Advertisers

    YouTube Masthead Access for Online Gambling Advertisers

    Your gambling licence alone does not unlock YouTube’s most prominent advertising placement. Starting October 21, 2026, Google will extend YouTube Masthead eligibility to more certified online gambling advertisers, but access will still depend on the product, jurisdiction, registration rules, certification scope, and campaign controls.

    If you’re planning a Masthead campaign, qualify the exact product-market combination before you commit the budget or build the creative. The policy change creates an opportunity, not an automatic approval.

    The change opens one premium placement, not the whole platform

    YouTube’s Masthead requirements already permit sports betting advertising. The October change expands eligibility to additional forms of online gambling advertising, provided the advertiser holds the relevant Google Ads certification and satisfies the applicable legal restrictions.

    That distinction matters. Masthead eligibility, Google Ads certification, and campaign approval are related, but they aren’t interchangeable:

    • Eligibility means your type of gambling business may be considered for the placement.
    • Certification means Google has approved you to advertise the relevant gambling category in the jurisdictions covered by that certification.
    • Campaign approval means the specific account, targeting, creative, destination, and other campaign elements satisfy Google’s applicable policies.

    Passing one stage does not guarantee the next. A certified advertiser can still submit a campaign that falls outside its approved geography, reaches an impermissible age group, or conflicts with another Google advertising policy.

    Use this four-gate test before treating your brand as eligible

    An advertiser passes through four gates symbolizing licensing, jurisdiction, registration, and campaign controls on the way to a premium video screen.

    Run each proposed product and target market through four gates. If any answer is unknown, treat the campaign as pending rather than eligible.

    1. Does mandatory state or national registration apply? The exception is easy to misread: online gambling advertisers not subject to mandatory state or national gambling registration remain excluded from the expanded eligibility. Operating in a category without a registration requirement is not a shortcut into the Masthead.
    2. Are you legally permitted to offer the product in the target jurisdiction? Confirm the relevant registration and licensing position for the product and location. If the answer depends on an interpretation of local law, use qualified legal counsel rather than inferring eligibility from a competitor’s campaign.
    3. Do you hold the matching Google Ads certification? Certification is not a universal gambling credential. Approval depends on the gambling category, local rules, licensing requirements, and jurisdictions you intend to target.
    4. Can the campaign enforce every geographic and age restriction? The campaign must stay inside the approved markets and comply with all applicable age limits. A broad audience setup can invalidate an otherwise eligible plan.

    The third gate deserves particular attention. A government licence or registration addresses your legal status. Google Ads certification addresses your permission to advertise through Google’s systems. Keep both records in your campaign approval file; neither should be treated as a substitute for the other.

    Map eligibility by product and jurisdiction

    A compliance team reviews connections between different gambling products and selected regions on an unlabeled tabletop map.

    Don’t label the entire company “approved” because one product is certified in one market. Build a simple eligibility matrix with one row for every product-jurisdiction combination you want to advertise.

    • Product or gambling category
    • Target country, state, or other applicable jurisdiction
    • Whether mandatory gambling registration applies
    • Registration and licensing status
    • Google Ads certification status and scope
    • Required geographic exclusions
    • Applicable age restrictions
    • Overall status: eligible, pending, or blocked

    This matrix prevents a common planning error: allowing a valid approval in one market to become an assumption about another. It also gives media, legal, compliance, and creative teams the same definition of what can launch.

    Be strict about the status labels. “Pending” should mean that a required decision, certification, or legal confirmation is still outstanding. It should not be converted to “eligible” because the campaign deadline is approaching. “Blocked” should identify the failing gate so the team knows whether the constraint is the product, jurisdiction, registration rule, certification, or targeting requirement.

    Sequence the campaign so compliance is not the final dependency

    The expensive mistake is to complete the media plan and creative first, then discover that the certification doesn’t cover the proposed product or market. Use this order instead:

    1. Define the exact gambling product being promoted.
    2. List every jurisdiction the campaign would reach.
    3. Confirm whether mandatory registration applies in each product-market combination.
    4. Verify the relevant registration, licensing, and legal permissions.
    5. Obtain or confirm Google Ads certification for the applicable category and jurisdictions.
    6. Configure geographic targeting, geographic exclusions, and age controls around the narrowest permitted scope.
    7. Review the creative, destination, account, and campaign against Google’s broader advertising policies.
    8. Commit the Masthead budget and launch date only after the required approvals are confirmed.

    For the initial rollout, narrow scope is easier to govern. A campaign covering one confirmed product-market combination has fewer ways to drift beyond its permissions than a launch that combines several products and jurisdictions. Expansion can follow as additional rows in the eligibility matrix become confirmed.

    October 21 is an eligibility start date, not a guaranteed campaign launch date. Account review, certification, legal clearance, and campaign approval still determine whether your specific campaign can run. Keep an alternative media plan until those dependencies are settled, particularly when the Masthead date is tied to a fixed promotion.

    Key questions about YouTube gambling ad access

    Can every online gambling operator buy a YouTube Masthead from October 21?

    No. The expansion applies to eligible, certified advertisers that satisfy the relevant legal, registration, licensing, geographic, and age requirements. It is not blanket permission for online gambling advertising.

    Does a gambling licence replace Google Ads certification?

    No. A licence or registration establishes a legal status under the applicable jurisdiction. Google Ads certification is a separate platform requirement for advertising the covered gambling category and market.

    Does one Google certification cover every jurisdiction?

    You should not assume that it does. Certification requirements depend on the category, jurisdiction, local regulation, and applicable licensing rules. Verify the scope against every market in the campaign.

    Are sports betting advertisers newly eligible?

    No. YouTube’s existing Masthead policy already permits sports betting advertising. The change extends potential access to more certified online gambling advertisers.

    Your next move is concrete: write down the exact product and jurisdiction you want to promote, then clear all four gates before briefing the campaign. If registration, licensing, certification, geography, or age controls remain unresolved, the Masthead plan is not ready for budget approval.

    References


  • Retail Media Audience Sharing in Google Ads: A Practical Guide

    Retail Media Audience Sharing in Google Ads: A Practical Guide

    If you sell through a retailer, some of the most useful shopper signals may sit in the retailer’s account while your campaign sits in yours. Google Ads commerce audience sharing creates a bridge between those two positions. That bridge is useful, but narrow: it is limited to eligible commerce media network campaigns.

    Before you build a media plan around it, you need to know what can be shared, where the resulting audiences can be used, what each partner can see and how you will judge the outcome. Getting those decisions in writing before activation prevents an audience opportunity from turning into an account, measurement or expectations problem.

    The feature is useful, but its lane is narrow

    Commerce audience sharing lets a retailer or marketplace make selected first-party audience segments available to a brand or seller through Google Ads. That gives an advertising partner access to audiences grounded in the commerce partner’s own customer relationships and shopping activity, rather than requiring the advertiser to build the same relationship independently.

    The roles are straightforward:

    • The commerce partner is the retailer or marketplace that owns and shares the eligible first-party segments.
    • The advertising partner is the brand or seller that can use those shared segments in an eligible retail media campaign.
    • Google Ads supplies the campaign infrastructure through which the collaboration operates.

    The most important limitation is also the easiest to miss. Shared commerce audiences are available for commerce media network campaigns, not for automatic use across regular Search, Shopping or Performance Max campaigns. Operationally, you should treat this as audience access for a qualifying retail media program, not as a portable audience asset that can be reused throughout your Google Ads account.

    That boundary should shape your go-or-no-go decision. The feature is a plausible fit when your immediate goal is to reach a retailer’s existing customers, high-intent shoppers or another retailer-defined customer group inside an eligible commerce media network campaign. It is not the answer when your plan depends on carrying the same segment into ordinary Search, Shopping or Performance Max activity.

    It is also a paid media capability, not an organic visibility tactic. Activating a retailer audience does not change how your pages are indexed, cited in AI answers or surfaced through SEO, AEO or GEO. Keep retail media activation and organic search optimization as separate workstreams, even when they support the same commercial objective.

    Prove the account and campaign path before planning creative

    An isometric account-to-campaign pathway connects retailer and advertiser workspaces through eligibility and access checkpoints, while incompatible routes are blocked.

    A promising audience idea has no value if the required accounts, eligibility and campaign type are not in place. Validate the operating path before you assign budget or ask a creative team to produce segment-specific ads.

    1. Identify the commerce partner. Name the retailer or marketplace that will make the segment available. Do not leave ownership implied between a brand, agency, seller and retailer.
    2. Confirm eligibility on both sides. The commerce partner and advertising partner must each satisfy Google’s eligibility requirements. One eligible account does not make the other eligible.
    3. Confirm the campaign type. Write down that the intended activation is an eligible commerce media network campaign. If the media plan only contains regular Search, Shopping or Performance Max campaigns, stop and redesign the audience plan.
    4. Map the required account relationships. The retailer’s sharing setup involves linking its Google Ads account with the relevant Google Merchant Center and data-sharing accounts. Assign an owner for each account and identify who can approve each link.
    5. Inventory the segments that will actually be shared. Availability is a commerce-partner decision. Build the campaign around confirmed segments, not around audience names that you hope the retailer can provide.
    6. Agree on the handoff. Record who publishes the segment, who confirms that it is available, who attaches it to the campaign and who resolves access problems.

    This sequence matters because audience strategy and account setup are different jobs. The advertiser may know which shoppers it wants, while the retailer controls which first-party segments are made available. A short activation brief should join those responsibilities instead of allowing each side to assume the other has handled them.

    Your brief should name the commerce partner, advertising partner, Google Ads account, relevant Merchant Center and data-sharing relationships, eligible campaign type, approved audience segments, primary conversion and approval owners. If any one of those fields is unresolved, the campaign is not ready for an audience-dependent launch date.

    Build the audience plan around a decision, not a label

    A segment called high intent sounds useful, but the label alone does not tell you what action to take. Ask what business decision becomes different because that audience is available.

    • Existing customers: Use this type of retailer-defined segment when the campaign has a clear relationship objective, such as presenting a relevant next purchase or a distinct customer message. Decide in advance whether existing customers are the target, a separate reporting group or outside the acquisition objective.
    • High-intent shoppers: Use this type only after the retailer explains what makes a shopper high intent. The campaign message should reflect the next action you want that shopper to take, not merely repeat a broad awareness message.
    • Specific customer segments: Request a segment when a meaningful difference in customer type changes the offer, product emphasis, creative or measurement plan. If every segment will receive the same treatment, extra segmentation may add operational complexity without improving the decision.

    For every requested segment, document the following questions:

    • What customer type does the segment represent?
    • Which behavior or relationship qualifies a person for it?
    • How recent must that qualifying behavior be?
    • How is the segment refreshed?
    • Can customers belong to more than one shared segment?
    • Which eligible campaigns may use it?
    • Which conversion will determine whether using it was worthwhile?

    Those operational definitions may require a direct agreement with the retailer. The information visible to an advertising partner includes segment names, customer types and conversion data, but a usable campaign brief often needs more context than a segment name can carry.

    Naming deserves care as well. A segment name should be clear enough for the advertiser to select and report on correctly. It should not contain customer-level information or encode details that are inappropriate to expose to a partner. Use a stable naming pattern that distinguishes the customer type, intended use and any version the partners need to recognize.

    The governing principle is simple: request the smallest meaningful set of audiences that can change a campaign decision. A long list of vaguely differentiated segments makes implementation and interpretation harder. A clearly defined segment tied to a specific message and conversion creates something both partners can evaluate.

    Measure value without calling every conversion incremental

    An analyst separates a mixed stream of conversion symbols into distinct groups to distinguish observed results from possible incremental effects.

    Audience sharing gives both sides visibility, but not identical visibility. Advertising partners can see shared audience information and conversion data. Commerce partners can access performance metrics showing how their audiences are being used and how the campaigns perform. Agree on a shared scorecard before launch so that each side does not reach a different conclusion from its own view.

    Separate four measurement questions:

    1. Was the intended audience available and used? Confirm that the correct shared segment was attached to the correct eligible campaign.
    2. Did the campaign produce the selected conversion? Define the conversion before launch and use the conversion data available to the advertising partner consistently.
    3. Was performance better than a relevant comparison? Where practical, compare the audience strategy with a campaign or audience treatment that is similar enough to inform the decision. Avoid changing the audience, creative, offer and optimization objective simultaneously if you want to understand which choice mattered.
    4. What can you honestly claim? Strong performance within a high-intent audience shows that the campaign reached and converted valuable shoppers. It does not, by itself, prove that every conversion was caused by audience sharing or that those purchases would not otherwise have happened.

    The distinction between efficiency and incrementality is important. A retailer’s high-intent audience may naturally contain people who are already close to buying. That can make the segment commercially useful, but a strong conversion result is still a performance observation unless the measurement design supports a causal lift claim. Label the result accurately: performance, comparative performance or incremental lift should not be treated as interchangeable terms.

    Set the decision rule before the campaign runs. State which conversion matters, which comparison you will use, which campaign variables must remain consistent and what result would lead you to expand, revise or stop the activation. The rule does not need an invented universal benchmark. It needs to match your economics and be agreed by the people who will act on it.

    Audience collaboration also needs a governance check. Document the approved campaign purpose, the people who can access the relevant accounts, the audience naming convention and the performance information each partner expects to review. Platform eligibility answers whether the feature can be used; it does not replace the commercial, privacy or contractual review appropriate to the partners’ relationship. Involve the responsible internal teams before sharing or activating customer-based segments.

    Key takeaways

    • Commerce audience sharing lets eligible retailers and marketplaces make first-party segments available to eligible brands and sellers through Google Ads.
    • The shared segments are limited to commerce media network campaigns; they do not automatically extend to regular Search, Shopping or Performance Max campaigns.
    • The retailer’s setup depends on the relevant Google Ads, Google Merchant Center and data-sharing account relationships.
    • Advertisers can see segment names, customer types and conversion data, while commerce partners can review performance information about audience use and campaign results.
    • A useful segment needs an operational definition, a distinct campaign decision and a named conversion. A persuasive label is not enough.
    • Campaign performance and incremental impact are different claims. Use comparison-based or causal language only when the measurement design supports it.

    If the campaign qualifies, begin with one documented audience, one campaign objective, one primary conversion and one agreed comparison plan. Resolve account ownership and eligibility before creative production begins. If your strategy requires the audience in standard Search, Shopping or Performance Max campaigns, choose another audience path instead of building a plan around access this feature does not provide.

    References


  • How to Manage Google Ads Video Frequency Across Campaigns

    How to Manage Google Ads Video Frequency Across Campaigns

    Your video campaigns can each look controlled while your audience still feels overexposed. The blind spot is overlap: a person can qualify for several campaigns, so acceptable frequency inside each campaign can become excessive frequency across the account.

    Google Ads is testing Video Campaign Groups for eligible Video and Demand Gen campaigns. The beta introduces group-level choices for increasing deduplicated reach or coordinating delivery around a frequency target. Used well, it can help you answer a practical question: are you reaching more of the intended audience, or repeatedly buying access to people you have already reached?

    Campaign-level frequency can hide account-level saturation

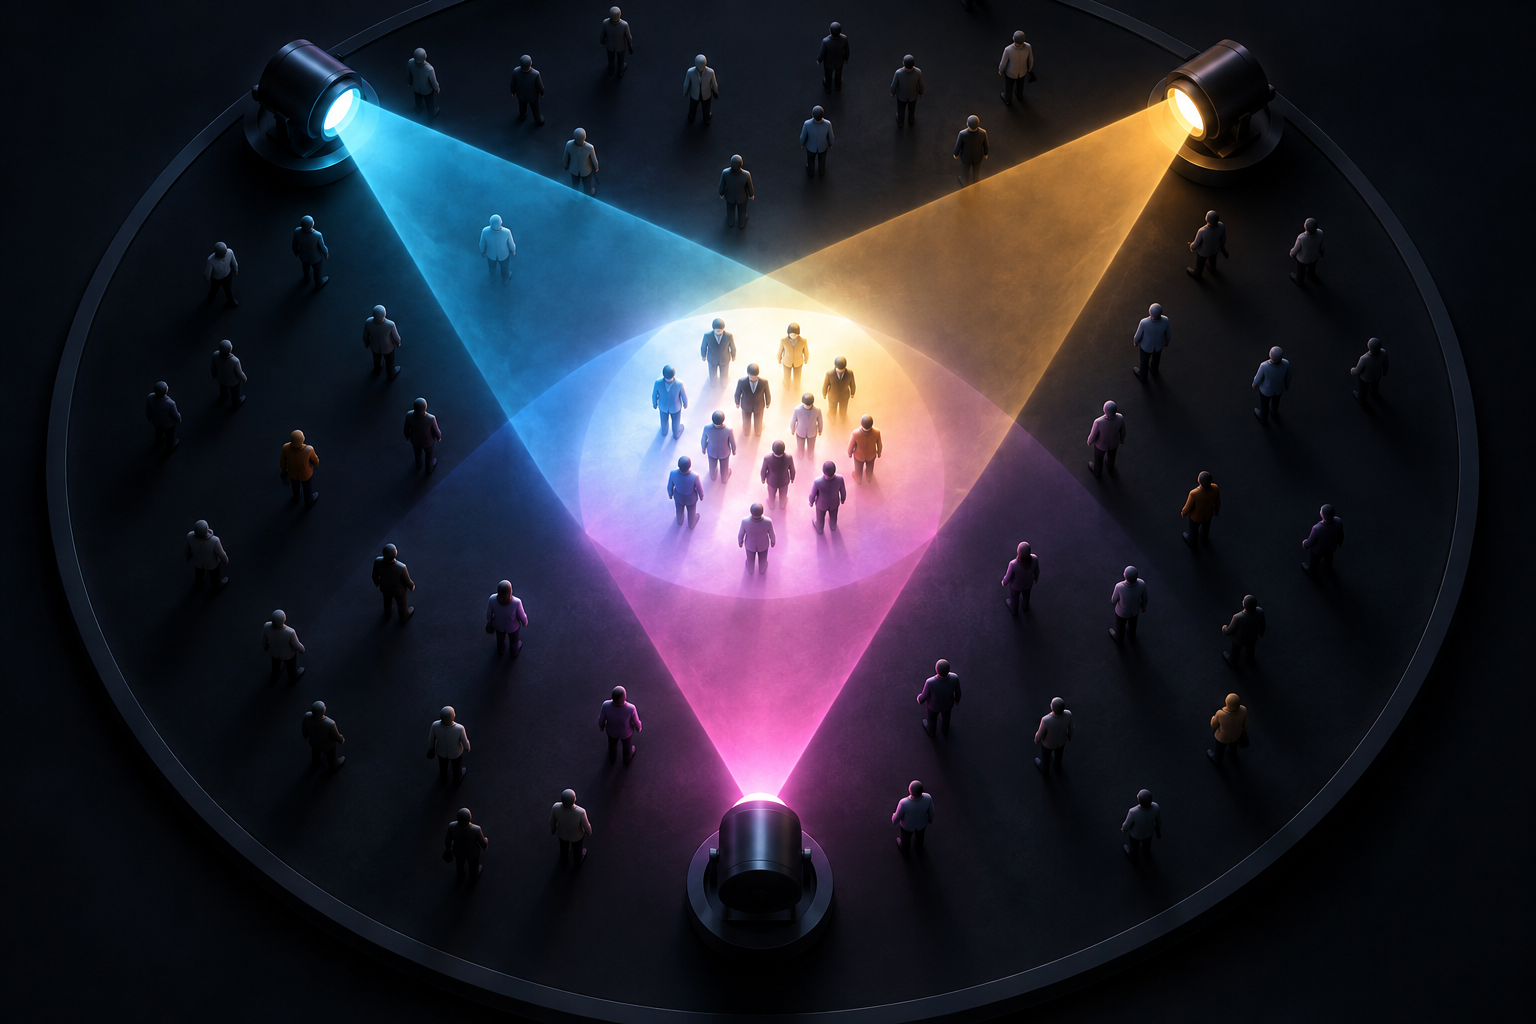
    A top-down view shows three colored projection beams overlapping on the same small group of people while others remain outside the light.

    Reach and frequency only make sense within a defined boundary. Reach represents the distinct audience exposed within that boundary. Frequency describes how often the reached audience was exposed on average. Change the boundary from an individual campaign to a collection of campaigns, and both measurements can change.

    This matters when a brand-awareness campaign, a product campaign, and a Demand Gen campaign pursue overlapping audiences during the same period. Each campaign can report a reasonable result while the combined plan keeps returning to much of the same audience. Adding the individual reach figures will not reveal the true audience size because duplicated people can appear in several campaign totals. Averaging campaign frequency figures can be equally misleading because the campaigns may have different reach and impression volumes.

    The problem is organizational as much as technical. Separate teams, agencies, product lines, or budget owners may optimize their campaigns independently. The audience does not experience those internal boundaries. It experiences the combined sequence of ads.

    Before creating a campaign group, build a simple overlap map:

    1. List the active Video and Demand Gen campaigns that could belong in the group.
    2. Record each campaign’s business objective, audience, geography, schedule, creative message, and responsible owner.
    3. Mark audience overlap as high, uncertain, or low. Treat uncertain overlap as something to investigate, not as an assumption of independence.
    4. Identify campaigns that serve a different funnel stage or require deliberately different repetition. Keep those outside the group unless a shared group objective still makes sense.
    5. Write the audience experience in plain language. If the plan sounds repetitive when described from the viewer’s perspective, campaign-level optimization is probably not enough.

    Choose between broader reach and managed repetition

    The beta presents two different strategic directions: increase campaign-group reach or set a campaign-group frequency target. Do not treat this as a routine setup choice. It tells Google what problem you want the group to solve.

    Group directionUse it whenWhat success should look likeWhat to watch
    Increase campaign-group reachYour upper-funnel campaigns compete for overlapping audiences and your priority is finding additional eligible people.Deduplicated group reach expands without unacceptable deterioration in the business outcome or audience quality you use as a guardrail.Do not confuse a larger reported audience with valuable incremental reach. Check whether the additional exposure still serves the campaign’s purpose.
    Set a campaign-group frequency targetRepetition is intentional, but you want it coordinated across campaigns rather than produced independently by each campaign.Group-level frequency moves toward the intended pattern while reach, delivery mix, and campaign outcomes remain acceptable.A target is an optimization instruction, not proof that every person receives the same number of impressions. Do not describe it internally as a hard cap unless the interface explicitly defines it that way.

    Reach optimization is usually the clearer choice when the central problem is duplication. If several upper-funnel campaigns address substantially the same market, a group-level reach objective gives the system a reason to look beyond people already reached elsewhere in the group.

    A frequency target is more appropriate when repetition has a defined role in the plan. That might include maintaining brand presence or supporting a coordinated message over time. The target still needs a business rationale. Do not borrow a universal frequency number from another account. Audience size, campaign purpose, creative variety, buying cycle, and available budget all change what a sensible pattern looks like.

    Treat your initial target as a hypothesis. Start from your own historical delivery and the point at which added exposure stopped producing enough additional value. If you do not have evidence for that point, use the group to learn before making a larger budget decision.

    Build a campaign group around one coherent job

    A central control module connects several video campaign devices and distributes light either broadly across many people or in even pulses to a defined group.

    A campaign group should represent a shared audience-management problem, not merely a convenient folder. Campaigns can use the same channel while doing very different jobs. Combining them under one reach or frequency instruction can create a clean report but a confused strategy.

    1. Confirm that Video Campaign Groups are available in your account and that the campaigns you intend to use are eligible. The capability is in beta, so do not design an account-wide process that assumes universal access.
    2. State the group’s job in one sentence. A useful statement names the audience, the intended exposure pattern, and the business purpose.
    3. Group campaigns by audience relationship and funnel role. Shared format alone is not enough.
    4. Choose either reach expansion or frequency coordination based on the problem you identified. Do not select the setting first and invent the rationale afterward.
    5. Capture a baseline for campaign reach, frequency, spend, delivery mix, and the outcome each campaign is meant to influence. Preserve the date range and reporting definitions so the later comparison is meaningful.
    6. Keep major audience, creative, bid, and budget changes to a minimum during the initial evaluation. If several inputs change together, you will not know what caused the result.
    7. Assign an owner for group-level decisions. Campaign owners should not independently undo the group’s strategy by changing their own settings without recording the change.

    Keep campaigns with incompatible goals apart. A prospecting campaign seeking new audience coverage and a narrow remarketing campaign seeking deliberate repetition may need different exposure strategies. Forcing both into the same group can make the aggregate metric look healthy while weakening one campaign’s actual job.

    Also separate the setting from assumptions about budget control. A group-level reach or frequency instruction does not automatically prove that budget, bidding, creative sequencing, or delivery priority will be coordinated in the way you expect. Rely on behavior you can observe in your account, not on what the feature name appears to promise.

    Measure delivery changes, not just cleaner reporting

    The important unresolved question is whether Video Campaign Groups will meaningfully coordinate delivery across campaigns or mainly provide aggregated reporting and deduplicated reach. Those are not equivalent benefits. Better reporting can expose waste, but only delivery changes can reduce that waste.

    Evaluate the beta in three layers:

    • Group outcome: For reach optimization, examine deduplicated group reach alongside group frequency. For frequency optimization, compare observed group frequency with the intended target while watching what happens to reach.
    • Business guardrail: Keep the outcome that matters for the campaign visible, whether that is qualified site activity, conversions, brand measurement, or another objective already used by your team. A group metric should not improve at the cost of the campaign’s purpose.
    • Delivery diagnostics: Inspect how spend, impressions, reach, and frequency are distributed across the campaigns. An acceptable group average can conceal a campaign that dominates delivery or another that has effectively stopped contributing.
    What you observeWhat it may meanWhat to do next
    Deduplicated reach expands while group frequency becomes less concentratedThe result is directionally consistent with reduced overlap and broader delivery.Confirm that the additional audience remains relevant and that the business guardrail has not weakened before increasing spend.
    Group frequency moves toward the target, but a campaign dominates deliveryThe aggregate target may be improving while the campaign mix becomes less useful.Inspect audience overlap, budgets, bids, eligibility, and campaign roles before accepting the result.
    Individual campaign reach totals look large, but deduplicated group reach is substantially smallerThe account has meaningful cross-campaign overlap.Use the deduplicated view for planning and stop presenting summed campaign reach as the size of the audience reached.
    Group reporting becomes clearer, but campaign delivery patterns barely changeThe immediate value may be measurement rather than active coordination.Use the visibility to restructure audiences or campaigns, but do not claim that automated optimization reduced wasted frequency.
    The group metric improves while the business guardrail deterioratesThe system may be satisfying the exposure instruction at the expense of audience or outcome quality.Hold expansion, diagnose the tradeoff, and revise the group membership or objective.

    Maintain a change log while testing. Record campaign additions and removals, audience edits, creative launches, bid changes, budget changes, and eligibility interruptions. Without that record, a before-and-after comparison can assign credit to the campaign group for a change caused elsewhere.

    Use cautious language when reporting results. A movement that is directionally consistent with better coordination is not the same as proof of incremental reach. If you changed several inputs at once or cannot see how delivery shifted, call the result inconclusive and refine the test.

    Key takeaways

    • Manage frequency at the level where audience overlap occurs. Campaign-level averages can hide repeated exposure across the account.
    • Use group-level reach optimization when your priority is reducing duplication and reaching additional eligible people.
    • Use a group frequency target when repetition is intentional and needs to be coordinated across campaigns.
    • Group campaigns by shared audience, funnel role, and business purpose rather than by video format alone.
    • Judge the beta by observed delivery changes and business guardrails, not by a cleaner group report.
    • Treat reported improvement as preliminary when other settings changed at the same time or delivery coordination cannot be verified.

    Your next move is to identify one coherent cluster of overlapping upper-funnel campaigns, document its current exposure pattern, and give the group a single measurable job. That limited rollout will tell you more than applying a frequency setting across the account and hoping the aggregate number improves.

    References


  • Political Campaign AI Spending: Where the 2026 Money Goes

    Political Campaign AI Spending: Where the 2026 Money Goes

    If you are building, buying, or measuring AI for a 2026 political campaign, the biggest budgeting mistake is treating AI as a single technology line. The headline total combines tools, AI-assisted work, automated outreach, and the media used to distribute AI-influenced advertising. A campaign can therefore spend little on software while creating a large AI-related footprint.

    You need to separate cost, operational use, and public exposure before deciding whether your campaign is underinvesting, overspending, or simply counting differently. That distinction turns an eye-catching market estimate into a budget you can actually manage.

    The $899 million headline is not a software market size

    Political campaigns, party committees, and outside groups are projected to spend $899 million on AI during the 2026 cycle. That would be 2.8 times the 2024 total and about 22 times the 2022 total. It is also equivalent to roughly 8.5% of the projected $10.6 billion in overall political advertising for the cycle.

    But $899 million does not mean campaigns are buying $899 million of AI software. The estimate includes three materially different forms of spending:

    • Direct payments for AI vendors, platforms, and general-purpose subscriptions.
    • The portion of production, targeting, fundraising, and outreach costs attributed to AI.
    • Media dollars placed behind advertisements generated or enhanced with AI.

    Those categories answer different questions. Direct vendor spending helps you assess the technology market. AI-attributable workflow spending tells you how deeply campaigns are using the technology. Media placement measures how much paid distribution sits behind AI-influenced assets. Combining them is useful for estimating AI’s overall campaign footprint, but it cannot tell you what AI products earned or how much a campaign saved.

    The total is also a projection, not a final audited tally. Its methodology covers more than 41,000 federal and state disbursement records, platform advertising libraries, and 57 consultant and vendor interviews, with activity tracked through September 24 and modeled through Election Day on November 3. Treat it as a structured market estimate. Do not use it as proof that every campaign classifies AI spending the same way.

    Before comparing your own budget with the market, decide which question you are asking. If you want to know what your technology stack costs, exclude media. If you want to understand operational adoption, include the AI-assisted share of labor and services. If you are assessing voter exposure, include distribution but keep it separate from production. One blended figure cannot answer all three questions.

    Distribution and outreach absorb more money than AI tools

    A small AI workstation connects through branching light trails to many phones, screens, mail pieces, and canvassing devices.

    The projected category mix shows where AI is entering campaign operations. Media placement behind AI-generated or AI-enhanced advertising is the largest category. General-purpose subscriptions are the smallest. That gap matters: the visible scale of political AI is being driven more by amplification and workflow adoption than by the price of access to a model.

    Spending categoryProjected 2026 spendingShare of totalGrowth versus 2024Question your budget should answer
    Media placement behind AI-generated or AI-enhanced ads$237 million26.4%3.3xCan you connect each placement to a specific asset, audience, and outcome?
    AI voter outreach$173 million19.2%3.0xWhen does an automated interaction move to a trained person?
    AI fundraising optimization$147 million16.4%2.4xAre you measuring net fundraising performance rather than message volume?
    AI audience modeling and targeting$131 million14.6%1.8xDoes the model improve decisions against a defined non-AI baseline?
    AI creative production$98 million10.9%4.7xWho verifies facts, voices, likenesses, and required disclosures before release?
    AI-assisted media buying fees$65 million7.2%2.8xCan you separate the service or algorithmic fee from the underlying media spend?
    General-purpose AI tools and subscriptions$48 million5.3%4.0xWho controls accounts, data access, retention, and offboarding?

    Creative production is growing fastest at 4.7 times its 2024 level, but it still accounts for only 10.9% of projected 2026 AI spending. Audience modeling is growing slowest at 1.8 times because it already had a meaningful base before the recent expansion of generative tools. Fast growth, large spending, and operational maturity are therefore three different signals.

    Do not judge an AI program by the number of assets it produces. A campaign can generate hundreds of variants without improving persuasion, fundraising, or contact quality. Measure the result associated with each workflow: approved production time for creative, net revenue for fundraising, successful contacts and escalations for outreach, incremental performance for targeting, and cost per desired action for media. Keep output volume as a diagnostic metric, not the primary success metric.

    Adoption also cuts across party lines. Republican candidates, parties, and aligned outside groups account for a projected $415 million, compared with $374 million on the Democratic side. Outside groups allocate a larger portion of their budgets to AI than candidates and parties, with Republican-aligned groups reaching 10.2%. Party affiliation is a poor proxy for AI maturity; spender type and workflow are more useful.

    Race size, geography, and timing change the right strategy

    Absolute spending concentrates in federal contests. House races account for a projected $305 million and Senate races for $286 million, together representing 65.7% of campaign AI spending. Yet smaller races use AI more intensively relative to their available media.

    Local and judicial races have AI-generated or AI-enhanced elements in 16.2% of ads, and AI represents 13.8% of their media budgets. State legislative races follow at 14.7% of ads and 12.4% of media budgets. House races are lower on both measures, at 9.2% and 8.9%, despite carrying the largest dollar total. Ballot measures sit at the other end, with AI elements in 6.3% of ads and 5.2% of media budgets.

    This is a denominator problem that can distort competitive analysis. A small campaign may look more AI-intensive because automation replaces work it could not otherwise afford. A large federal campaign can spend far more dollars while AI remains a smaller percentage of a much larger operation. Compare campaigns on both absolute spending and share of budget. Using only one will misclassify the smaller operation or obscure the larger one’s reach.

    Geography produces another concentration effect. The ten highest-spending states account for $460.1 million, or 51.2% of the projected total. Maine reaches $25.09 per registered voter, almost three times the next-highest figure in that group, as a competitive Senate race concentrates spending across a relatively small electorate. A national average will not tell you what competitive pressure looks like in an individual state.

    Disclosure practices vary just as sharply. Among the ten highest-spending states, the recorded share of AI ads carrying a disclosure ranges from 29% in Georgia to 78% in California. Across states with AI disclosure laws, 64% of AI ads carried a disclosure, versus 27% in states without one. That relationship indicates that legal requirements affect behavior, but it is not a substitute for a state-by-state compliance review.

    Build a jurisdiction field into the asset record before production begins. Record where the asset will run, what was generated or materially altered, which disclosure decision was made, who approved it, and which final version entered distribution. When the applicable rule is unclear, hold the asset and ask qualified election counsel. Retrofitting a disclosure after placement creates avoidable legal, financial, and reputational exposure.

    Timing is equally important. At the aligned one-month point, cumulative 2026 AI spending reaches $612 million, with a projected $899 million by Election Day. Spending within each cycle has roughly doubled every three months as Election Day approaches. The final month is projected to contain 32% of 2026 spending, below the 37% final-month share in 2024 because outreach and fundraising automation moved earlier to reach early voters.

    Do not postpone governance until the spending ramp. The final weeks are when review time contracts, asset volume rises, and media decisions become harder to reverse. Approve vendors, data permissions, escalation paths, disclosure rules, and evidence requirements before the high-volume period. The late-cycle budget should scale a controlled workflow, not finance the first real test of one.

    Build an AI budget that can survive scrutiny

    Transparent budget containers, coins, a magnifying glass, a locked data box, and a balance scale are arranged on an orderly campaign planning desk.

    A defensible AI budget starts with a ledger, not a list of tools. The cost of an AI program can include software, implementation, data work, human review, compliance, vendor services, and media. If you record only subscription invoices, you will understate the program. If you label every placement behind an AI-assisted asset as technology spend, you will lose sight of what the technology itself costs.

    1. Choose the unit of analysis. State whether you are tracking direct vendor cost, AI-enabled workflow cost, or media exposure. Maintain all three if leadership needs a complete view, but never merge them without labels.
    2. Classify spending at the invoice or line-item level. Assign every item to creative production, outreach, fundraising, targeting, media-buying services, general tools, or media placement. Prevent one invoice from disappearing into a broad digital-services account.
    3. Attach each cost to an accountable workflow. Record the race, jurisdiction, vendor, campaign owner, data used, synthetic or altered elements, human reviewer, approval status, and distribution channel.
    4. Set the baseline before the pilot. Compare the AI-enabled workflow with the existing process on the outcome that matters. Time saved is meaningful for production; it is not evidence of better persuasion. Message volume is meaningful for operations; it is not evidence of better fundraising.
    5. Create a release gate. Require factual verification, permission checks for voice and likeness, disclosure review, accessibility review where relevant, security review, and named human approval before an asset or automated interaction goes live.
    6. Scale only the validated component. If a creative workflow saves time but targeting does not improve performance, scale production rather than buying a larger bundled program. A vendor relationship does not have to expand as one indivisible unit.

    Your ledger should let a reviewer move in both directions: from an invoice to the assets and outcomes it funded, and from a public asset back to its production record, approval, disclosure decision, and media spend. That traceability is more useful than a generic AI policy because it shows how the policy operated in a specific case.

    If you publish or optimize political content

    More campaign investment means more creative variants, automated contacts, and paid distribution. It does not create independent corroboration. Treat campaign-generated material as a claim that requires verification, even when the asset looks polished or appears repeatedly across channels.

    • Put the publication or revision date, jurisdiction, race, candidate or issue, and sponsor context where a reader can see them.
    • Separate campaign assertions from independently verified facts, and link to the strongest available primary evidence for factual claims.
    • Keep the original approved asset and a correction history so changes do not erase provenance.
    • Use structured data only for information visible on the page. Markup can clarify entities and dates, but it cannot turn an unsupported claim into reliable evidence.
    • Do not present repeated synthetic content as multiple independent confirmations. Distribution volume and source diversity are not the same thing.

    These practices help human readers, search systems, and AI answer engines distinguish what happened, who is making a claim, when it applies, and which evidence supports it. They do not guarantee visibility or favorable treatment, but they reduce ambiguity at the point where political information is most likely to be compressed into a short answer.

    Key takeaways

    • The projected $899 million total measures a broad AI-related campaign footprint, not just software purchases or vendor revenue.
    • Media placement is the largest category at $237 million, while general-purpose tools and subscriptions account for $48 million.
    • Creative production is growing fastest, but output volume alone does not establish campaign impact.
    • Federal races lead in total dollars, while local, judicial, and state legislative races use AI more intensively relative to their media.
    • Disclosure practices differ substantially by state, so every asset needs a jurisdiction-specific review and an auditable approval record.
    • Budgeting should separate direct technology cost, AI-enabled workflow cost, and paid exposure, then connect each to a defined outcome.

    Start by exporting every AI-related expense and reclassifying it into technology, workflow, or distribution. Then choose one high-exposure workflow, give it a measurable baseline and a named approval owner, and resolve its disclosure path before shifting more money into it. That is how you turn a market trend into a campaign decision you can explain, test, and defend.

    References


  • Microsoft Ads and HubSpot: A Revenue Integration Playbook

    Microsoft Ads and HubSpot: A Revenue Integration Playbook

    If Microsoft Ads reports clicks and leads while HubSpot holds qualification, deals and revenue, you have two partial views of the same buyer journey. That gap makes a basic budget question unnecessarily hard: which campaigns are producing commercially useful demand?

    The Microsoft Ads and HubSpot integration can connect advertising activity with CRM records, activate CRM-based audiences and automate the handoff from marketing to sales. The connector creates the path, but trustworthy revenue reporting still depends on the definitions, associations and workflows you put around it.

    What the integration changes – and what it does not

    The integration brings Microsoft Advertising into HubSpot so you can use CRM data to build audiences and connect advertising activity with contacts and deals. Those audiences can support campaigns across Bing, Copilot, Outlook, Xbox and other Microsoft properties. Advertisers also gain access to LinkedIn professional audiences.

    Operationally, that creates a more useful chain:

    • A Microsoft campaign generates or influences a contact.
    • HubSpot records the contact’s lifecycle movement and sales ownership.
    • The contact is associated with a deal when an opportunity is created.
    • The deal moves through pipeline stages and eventually becomes won, lost or inactive.
    • Marketing compares campaign investment with qualified demand, pipeline and credited revenue.

    That is a large improvement over judging campaigns only by click-through rate or cost per lead. It does not, however, turn every CRM record into reliable attribution. The integration cannot decide what your company means by a qualified lead, repair missing contact-to-deal associations or settle whether a campaign sourced a sale or merely appeared somewhere in the journey.

    Key takeaways

    • Use the integration to connect Microsoft campaign activity with contacts and deals, not simply to duplicate ad-platform metrics inside HubSpot.
    • Define lifecycle stages, pipeline rules and revenue credit before treating the resulting dashboard as a source of truth.
    • Automate rep assignment and nurture sequences, but route incomplete or ambiguous records to an exception queue.
    • Separate lead volume, qualified demand, pipeline creation and won revenue so one strong top-of-funnel metric cannot hide a weak commercial result.
    • Use revenue reporting to find promising patterns and controlled experiments to test whether a campaign change actually improves performance.

    Define revenue truth before connecting the accounts

    Unlabeled contact, company, opportunity, and revenue objects connected in sequence by a highlighted data path with validation checkpoints.

    Your first deliverable should be a one-page measurement contract. It is not a technical specification. It is a set of business rules that marketing, sales and revenue operations agree to use when interpreting the integration.

    Write down these decisions before anyone builds a revenue dashboard:

    • Lead: Identify the event that creates a reportable lead. A form submission, imported record and existing contact returning to the site should not become interchangeable by accident.
    • Qualified lead: Name the fields or review step that indicate fit and intent. Do not let the mere presence of a CRM record count as qualification.
    • Pipeline: Specify the deal stage at which an opportunity enters pipeline reporting. If early, unverified deals count, label that value accordingly.
    • Revenue: Decide whether reports use the full closed-won amount, another approved amount stored on the deal or a weighted value. Use one definition consistently.
    • Date: Choose whether campaign reports group results by lead creation, deal creation or close date. These answer different questions.
    • Credit: Distinguish sourced revenue from influenced revenue. A campaign credited under an agreed acquisition model is not the same as a campaign that appeared somewhere in the recorded journey.
    • Associations: State which contact-to-company and contact-to-deal links must exist before pipeline or revenue can be attributed.
    • Exclusions: Document how employees, tests, duplicates, spam, invalid deals and other non-commercial records are removed.

    This prevents the most common reporting failure: a technically correct dashboard answering a question nobody defined. For example, a report grouped by close date tells you what revenue finished in a period. It does not necessarily tell you whether the campaigns launched in that period worked, because many of those leads may not have had time to mature.

    Keep campaign naming equally disciplined. Use a stable structure that identifies the channel, market, campaign purpose and audience without relying on a person’s memory. If names change midstream, record the change instead of silently merging unlike activity. Consistency is what lets the Microsoft-to-HubSpot relationship survive staff changes and dashboard rebuilds.

    Build and validate one complete revenue path first

    Do not begin by connecting every campaign, audience and workflow. Choose one campaign family with a clear conversion path and follow it from advertising activity to a HubSpot contact, a qualified outcome and a deal. A narrow pilot makes broken associations visible before they contaminate a larger report.

    A practical implementation sequence

    1. Confirm account scope and ownership. Record which Microsoft Advertising account and HubSpot portal belong in the connection. Assign one owner for advertising configuration, one for CRM data and one person who approves the shared measurement rules.
    2. Audit the pilot records. Inspect the fields used for lifecycle stage, source, owner, company, deal association, pipeline stage and revenue. Fix obvious duplicates and missing values before using those records as validation evidence.
    3. Connect the approved accounts. Use the Microsoft Advertising integration available in HubSpot and grant only the access required for the planned use. Record who authorized it and how your team will review access later.
    4. Select a controlled audience and campaign scope. Start with a segment whose business meaning is easy to explain. Avoid uploading the entire CRM simply because the connection makes broader activation possible.
    5. Create the minimum handoff workflow. Use the integration’s ability to assign a generated lead to a sales representative or start a nurture email sequence. Keep the first workflow simple enough to audit record by record.
    6. Run an end-to-end validation. Follow a controlled test record or policy-compliant live submission through contact creation, campaign association, lifecycle processing, ownership, workflow enrollment and deal association. Record the expected value and the actual value at each checkpoint.
    7. Reconcile before expanding. Compare the pilot’s contact and deal records with the corresponding campaign activity. Investigate unexplained records rather than forcing totals to match through manual edits.

    A successful connection should be observable. If a marketer cannot open a contact and explain why it entered a workflow, or a sales operator cannot explain why a deal carries campaign credit, the setup is not ready to drive a budget decision.

    Design workflows with an exception path

    A lead handoff should have at least three branches:

    • Ready for sales: The record meets your agreed fit-and-intent rule, contains the information needed for routing and is assigned to the appropriate sales owner.
    • Ready for nurture: The record is legitimate but does not yet meet the sales threshold, so it enters the appropriate email sequence rather than being treated as an immediate opportunity.
    • Needs review: Ownership, market, consent status, company association or another required value is missing or contradictory. The record enters a visible queue with a named person responsible for resolving it.

    That third branch matters. Automation usually fails quietly when every record is forced down a happy path. An exception queue turns a hidden data-quality problem into a manageable operating task.

    Close the loop with sales feedback as well. Use consistent reasons when a lead is accepted, rejected or returned for nurture. Marketing can then see whether a high-volume campaign is reaching the wrong companies, attracting weak intent or simply handing records to sales before enough information exists.

    Measure the funnel without overstating attribution

    Several illuminated marketing and sales paths converge around a business buyer before reaching a completed deal, with a transparent lens examining the junction.

    The integration can show which Microsoft campaigns are contributing to pipeline and revenue and support comparisons with other advertising channels. Treat that visibility as decision support, not automatic proof that an ad caused every credited sale.

    Your working dashboard should keep the funnel layers separate:

    Measurement layerQuestion it answersWhat to inspect when it weakens
    Spend and trafficDid the campaign buy the intended exposure and visits?Delivery, targeting, bidding and creative response
    LeadsDid visitors complete the defined lead action?Offer, landing-page path and tracking continuity
    Qualified leadsDid the campaign attract people who met the fit-and-intent rule?Audience composition, search intent and qualification criteria
    Pipeline createdDid qualified demand become recognized sales opportunities?Sales acceptance, follow-up, deal creation and CRM associations
    Closed-won revenueDid opportunities become revenue under the agreed reporting model?Sales-cycle maturity, deal progression, losses and revenue fields

    Calculate rates between adjacent stages as well as totals. If leads rise while the qualified-lead rate falls, cheaper acquisition may simply be moving the quality problem downstream. If qualified demand is healthy but pipeline creation is weak, inspect the sales handoff and deal-creation process before changing ads. If pipeline looks strong but won revenue lags, separate recent opportunities that still need time from older opportunities that stalled or closed lost.

    Use cohort views when the sales cycle extends beyond the reporting period. Group contacts by the period in which they entered through the campaign, then observe how that cohort progresses. Keep a separate close-date view for financial reporting. Combining those views into one number makes recent campaigns look artificially weak and older campaigns difficult to diagnose.

    Use experiments to test the next decision

    Revenue reporting can reveal an association worth investigating. A controlled test is better suited to deciding whether a change should receive more budget. Microsoft Advertising’s optimization experiments are generally available for Search, Shopping, Audience and Performance Max campaigns, with tests covering bidding, targeting, creative and other changes.

    For each experiment, change one decision you can act on and name the primary outcome before looking at results. If revenue takes too long to mature, use the closest CRM stage that has an agreed connection to commercial value, such as a qualified lead or accepted opportunity. Continue to inspect later pipeline and revenue rather than declaring success from an early-stage improvement alone.

    Keep the original campaign as the comparison, document the tested change and apply a successful variation only after it has met the decision rule your team set in advance. This protects you from promoting a variation merely because its early lead count looks attractive.

    Scale B2B activation with the platform limits in view

    The audience connection is especially useful for B2B teams because Microsoft has expanded LinkedIn company lists from 1,000 to 10,000 companies. Advertisers can upload the companies together and combine those lists with LinkedIn profile targeting in Search and Audience campaigns.

    Do not turn that larger ceiling into one undifferentiated account list. Segment companies according to the decision you need to make. For example, keep priority accounts separate from broader expansion accounts, and separate active opportunities from earlier-stage prospects when your permitted data use and available controls support that plan. Distinct segments let you compare message, response and pipeline quality instead of averaging unlike accounts together.

    Check geographic eligibility before promising reach. The company-list feature is available in supported markets globally, but the underlying consumer data excludes users in the EEA, the United Kingdom and Switzerland. Treat that as a planning constraint for audience design and regional reporting, not as a data problem the HubSpot connection can solve.

    There is also a separate technical deadline for teams maintaining custom Microsoft Advertising integrations. Developers have until January 31, 2027, to migrate from SOAP to REST. SOAP support for new features and enhancements was extended through that deprecation date. This matters to custom API work; it should not be confused with the business process of configuring the standard HubSpot integration. Inventory any custom jobs, middleware and reporting scripts now so the migration does not arrive as an attribution outage later.

    Start with one campaign family, one CRM audience, one handoff workflow and one agreed revenue view. Let that path run long enough to expose association gaps and sales-cycle lag, correct the exceptions, and only then extend the model to more campaigns. The fastest route to credible revenue reporting is a small chain your marketing and sales teams can both explain.

    References


  • Paid Search APIs: A Control Plan for PMax and Targeting

    Paid Search APIs: A Control Plan for PMax and Targeting

    Your paid search stack has more levers, but a longer settings list is not a control strategy. Your immediate job is to decide which signals belong in reporting, which controls enforce real business constraints, and which customer data should never enter an upload pipeline without an eligibility check.

    Handled carefully, the Microsoft Advertising and Google Ads APIs can help you trace intent to destinations, constrain Performance Max where the economics demand it, strengthen audience inputs, and identify bidding settings that limit auction access. The useful unit is not the endpoint. It is a closed loop: observe, diagnose, authorize, change, and verify.

    Build a control plane before you automate campaign changes

    A paid search integration should separate evidence from action. Reports, benchmarks, and recommendations tell you what may deserve attention. They do not automatically tell you which change is safe, profitable, or permitted.

    Organize the integration into four stages:

    1. Observe: retrieve delivery evidence, performance metrics, recommendations, and the current effective settings.
    2. Diagnose: classify the issue as a message mismatch, destination mismatch, targeting problem, measurement defect, auction-access constraint, or genuine business restriction.
    3. Authorize: apply an approval rule that matches the risk. A validated tracking-parameter correction is not the same decision as excluding an entire device category or changing a bidding target.
    4. Execute and verify: write the smallest eligible change, retrieve the effective setting again, and record whether the platform accepted it.

    Keep read jobs and campaign-mutation jobs separate where your architecture permits it. At minimum, every write operation should support a dry run that shows the current value, proposed value, object scope, and affected IDs before money-moving settings change.

    Your change record should capture the platform, account, campaign or asset-group ID, scope, previous value, proposed value, reason, requester, approval status, execution result, and retrieval time. Add de-duplication in your own worker so a retry cannot apply the same logical operation twice. That record becomes essential when an automated campaign behaves differently and you need to distinguish a platform decision from a change your system made.

    Turn search-term-to-page evidence into a repair queue

    An analyst traces glowing search-signal streams to model landing pages and sorts mismatches into repair trays.

    Microsoft Advertising’s Search Term Landing Page Report connects a search term, the delivered headline, the final URL, and performance metrics in the same reporting view. That closes an important diagnostic gap: you can inspect the promise a person saw and the destination that had to fulfill it.

    Do not reduce this to a list of expensive search terms. Build a mismatch workflow that preserves the full path:

    1. Store the raw evidence. Retain the search term, delivered headline, final URL, campaign identifiers, and associated metrics. Do not substitute the headline you expected to serve for the headline that was actually delivered.
    2. Create a normalized destination key. Keep the raw URL for auditing, then create a second field that removes only parameters you have confirmed do not alter page content. A parameter that controls localization, product selection, or page state is not disposable tracking noise.
    3. Score three separate relationships. Evaluate search term to headline, headline to landing page, and search term to landing page. A relevant headline can hide a poor destination, while an acceptable page can still be introduced by the wrong promise.
    4. Join relevance to outcomes. A semantic mismatch deserves inspection, but performance data determines its operational priority. A high-volume routing defect and an isolated ambiguous query should not enter the same queue with the same urgency.
    5. Assign the repair to the correct layer. Change the eligible ad messaging when the promise is wrong, adjust routing when the destination is wrong, and revise the page when it fails to answer the intent it legitimately targets.

    Suppose a term clearly asks about pricing, the delivered headline promises pricing information, and the click reaches a generic homepage that never addresses price. The weak link is the destination. Rewriting the headline may reduce the visible contradiction, but it does not satisfy the underlying intent. Your queue should make that distinction explicit.

    SEO, AEO, and GEO teams can use the same queue to prioritize clearer on-page answers. Paid query evidence can show that demand exists and reveal the language people use, but it does not prove that a page will rank organically or be cited by an AI system. Improve the visible answer first, then describe that content accurately with metadata and structured data. Schema cannot repair information the page does not contain.

    Model PMax controls by platform, object, and scope

    Performance Max is not one uniform control surface. Microsoft is adding campaign-level device exclusions, while Google Ads API v25.2 exposes URL configuration at the asset-group level and a draft-based migration path from Smart campaigns. Treating all three capabilities as a generic PMax setting will create faulty assumptions in your interface and automation.

    CapabilityScopeWhat the API permitsHow to use it safely
    Microsoft Advertising device exclusionsCampaignExclude Computers, Smartphones, or Tablets from a PMax campaignUse only after confirming that the device itself creates a durable business constraint, rather than masking a page, tracking, consent, or attribution defect
    Google Ads PMax URL configurationAsset groupConfigure tracking templates, custom URL parameters, and final URL suffixesKeep routing and measurement rules aligned with the asset group, and test the resolved URL before activation
    Google Smart-to-PMax generationCampaign draft workflowGenerate a PMax draft from an existing Smart campaignTreat the generated object as a reviewable draft, not as authorization to launch it

    Your internal model should include at least platform, control type, scope type, scope ID, requested value, effective value, and business rationale. The interface should state plainly whether a control applies to a campaign, an asset group, or a migration draft. Scope must not be inferred from a label such as PMax control.

    Device exclusion is the highest-consequence control in this set because it removes eligible reach. Before excluding a device, verify that the apparent weakness is not caused by a slow or unusable landing experience, broken conversion tracking, a consent-flow difference, or cross-device attribution. If the problem can be repaired, fix it. If the device violates a stable operating rule, document that rule and exclude it at the campaign scope the Microsoft API actually supports.

    Google’s asset-group URL controls solve a different problem. They let you attach tracking and URL information closer to the asset grouping that uses it. Validate the fully resolved destination, preserve parameters that affect content, and test that your analytics system receives the expected values. A syntactically accepted suffix can still produce a bad measurement or routing result when combined with the base URL.

    A generated PMax draft also needs a deliberate comparison with the campaign it is replacing. Review destinations and tracking, conversion goals, geography, bidding and budget assumptions, creative assets, audience inputs, and exclusions before approval. Draft generation reduces construction work; it does not transfer accountability to the API.

    Google Ads API v25.2 is a minor release without breaking changes, but integrations still need updated client libraries and code to use its additions. It is scheduled to remain supported until August 2027, so record the API version behind every capability flag and plan the next upgrade before support ends.

    Separate audience usefulness from permission to use the data

    Abstract customer-data tokens pass through separate usefulness and permission gates before entering a campaign system.

    Microsoft’s API support for LinkedIn segment targeting can add professional audience information to programmatic campaign management. That can be useful for B2B offers, but a segment name is still a targeting hypothesis, not proof of buying intent.

    For every segment, record the business question it represents, the campaign where it is eligible, and the result you expect it to influence. Your integration should also expose how the platform treats that audience object in the selected campaign context: as a reach restriction, observation layer, or automation input. Do not let a generic audience toggle hide that distinction.

    Google Customer Match introduces a more consequential data-governance decision. Advertisers can add an IP address and interaction timestamp to customer data, but both values must be uploaded unhashed. These identifiers are not available for end users in the European Economic Area, United Kingdom, or Switzerland, so geographic eligibility has to be enforced before the export reaches Google.

    Build that upload pipeline to fail closed:

    1. Check eligibility at the record level. If your collection system cannot reliably establish that the user is outside the restricted regions, omit the IP-address field for that record.
    2. Verify notice and consent before enabling the fields. The expanded matching options require appropriate collection disclosures and consent controls. Have the privacy or legal owner responsible for your markets approve the rule before activation.
    3. Use the required file format. Customer Match files can contain eight columns, and Google requires specific English-language headers, including User IP address and User Interaction timestamp. Hashing these two fields anyway does not satisfy the specified upload format.
    4. Limit exposure. Restrict access to the unhashed export, prevent raw values from appearing in debug logs, and remove temporary files according to your approved retention policy.
    5. Log decisions rather than identifiers. Record the policy version, eligible and excluded row counts, upload result, and failure reason without copying IP addresses into the operational audit trail.

    This is one place where a larger matchable audience is not automatically a better outcome. If the regional gate, collection record, or disclosure is uncertain, omit the new identifiers and use an already approved matching path. The downside of a smaller audience is preferable to transferring data you were not authorized to use.

    Use benchmarks and bidding recommendations as questions, not commands

    Google Ads API v25.2 can return competitive benchmark percentile tiers through BenchmarksService, including comparison with all advertisers and optional category filters. A percentile supplies market context. It is not a profitability target.

    Store the comparator and category filter beside the percentile. Without them, a dashboard preserves the number but loses the population that gives it meaning. Also keep the advertiser’s own absolute outcome nearby. A relative position cannot tell you whether a campaign meets its allowable acquisition cost, margin requirement, lead-quality standard, or revenue target.

    The same discipline applies to Google’s recommendations that flag Target CPA or Target ROAS settings that may be too restrictive for a campaign to enter auctions. The recommendation diagnoses possible auction-access friction. It does not establish that loosening the target will produce economically acceptable conversions.

    Before acting on that recommendation, verify the conversion definition and tracking, calculate the CPA or ROAS boundary your economics can support, decide whether the actual problem is limited auction access or weak post-click performance, and define the acceptable change before editing the target. Store whether the recommendation was accepted, modified, or declined and why. Do not make this recommendation self-executing merely because the API makes it available.

    Key takeaways

    • Separate API observation from mutation, and preserve a before-and-after record for every campaign write.
    • Evaluate search term, delivered headline, and final landing page as three connected relationships, not as independent report columns.
    • Represent PMax controls at their real scope: Microsoft device exclusions are campaign-level, while Google’s new URL controls are asset-group-level.
    • Generate a PMax draft to reduce setup work, then review it with the same standards as a manually assembled campaign.
    • Block restricted or uncertain Customer Match records before export; IP addresses and timestamps require an unhashed, region-aware pipeline.
    • Use benchmark percentiles and bidding recommendations to frame an investigation, not to replace your own economic constraints.

    For your next integration release, keep the scope small and verifiable: add one reporting path that exposes query-to-page mismatches, one write guardrail that respects the platform’s actual control scope, and one hard eligibility gate around customer-data uploads. Expand automation only after those three paths produce auditable results.

    References


  • Holiday Display Ad Costs: A Practical 2026 Budget Plan

    Holiday Display Ad Costs: A Practical 2026 Budget Plan

    You are deciding whether to spend before Black Friday or preserve your display budget for the peak shopping period. The 2026 cost signal supports an early move, but for a specific purpose: buy less expensive prospecting reach, learn which value proposition works, and build audiences you can approach again when purchase intent strengthens.

    That is not a reason to spend simply because impressions are cheaper. CPM is only the price of access to an audience. If cautious shoppers ignore the offer, inexpensive exposure can still produce expensive customers. Your budget plan therefore needs two controls: one for media cost and another for commercial results.

    Read the 2026 cost drop as an opportunity, not a forecast

    AdRoll activity from July 1 through September 8 showed a pronounced decline in display pricing. Prospecting CPMs were 45% lower year over year and 25.5% below the comparable Q2 period. Retargeting CPMs were 29.1% lower year over year and 40.2% below the comparable Q2 period.

    Display activityYear-over-year CPM changeChange from comparable Q2 periodWhat it means for your plan
    Prospecting45% lower25.5% lowerTest new audiences and messages before peak competition intensifies.
    Retargeting29.1% lower40.2% lowerReconnect with known visitors, but let the size and quality of your audience limit spending.
    Account-based marketing4.4% higher15.1% lowerBudget against the value of named accounts rather than broad-market CPM trends.

    These figures describe relative changes, not a universal dollar price for holiday inventory. They do not tell you the CPM your account, audience, placement, geography, or buying platform will receive. Treat them as a directional benchmark for the AdRoll activity captured during that period, then compare the signal with your own live auction prices.

    The timing matters too. A decline measured before the holiday rush does not guarantee that inventory will remain inexpensive around Black Friday or Cyber Monday. Competition can intensify as more advertisers enter the auction. The useful conclusion is that an early testing window may exist, not that peak-period media has become permanently cheaper.

    Demand conditions also point in two directions. U.S. inflation held at 3.4% in August, while the University of Michigan consumer sentiment index fell to 47.8 in September, 13.2% below its year-earlier level. At the same time, Bank of America card activity showed August spending per household increasing 4.5% year over year, with shoppers favoring value-oriented and big-box retailers.

    That combination does not prove that every category will enjoy strong holiday demand. It does tell you why cheap reach and difficult conversion can coexist. People may continue spending while becoming more selective about the merchant, product, price, and promotion that earns the purchase.

    Key takeaways

    • The clearest 2026 cost opportunity is pre-peak prospecting: use it to learn and build qualified audiences, not merely to accumulate impressions.
    • Lower CPM does not automatically lower customer acquisition cost. Conversion rate and contribution per order still determine whether the campaign is economically sound.
    • Keep prospecting, retargeting, and account-based marketing separate in both reporting and budget decisions because they reach different audiences and perform different jobs.
    • Make value visible in the ad and on the landing page. A vague brand message asks a cautious shopper to do too much interpretive work.
    • Do not treat pre-holiday CPM declines as a Black Friday price guarantee. Preserve budget for peak demand and release it only when current results meet your commercial rule.

    Protect conversion economics before buying more reach

    An analyst adjusts a funnel as many tokens enter near generic ad tiles and only a few emerge beside shopping parcels.

    CPM answers one narrow question: how much did you pay for 1,000 impressions? The basic relationship is straightforward: impressions purchased equal media spend divided by CPM, multiplied by 1,000. When CPM falls, a fixed budget can buy more impressions.

    That calculation says nothing about how many viewers were suitable prospects, visited the site, understood the offer, or purchased. Customer acquisition cost answers a different question: how much media spend was required for each attributable new customer? If your CPM declines while the purchase rate declines by more, acquisition cost can rise. Scaling on CPM alone can therefore turn cheaper inventory into a larger unprofitable campaign.

    Set the commercial limit before you increase the budget. For an ecommerce campaign, that normally means defining the maximum acquisition cost the order can support after the discount and variable costs are considered. For a longer B2B sale, define the lead or opportunity outcome you are willing to fund. Do not substitute impressions, clicks, or an unqualified form submission for that outcome merely because those numbers arrive faster.

    Your holiday display scorecard should separate four layers:

    • Delivery: spend, CPM, impressions, unique reach, and frequency.
    • Response: landing-page visits and the qualified action that indicates genuine interest.
    • Commercial outcome: purchases or qualified leads, conversion rate, acquisition cost, revenue, and contribution after the promotion.
    • Audience status: new prospects, previous visitors, existing customers, and purchasers who should be excluded from acquisition messaging.

    Use the same attribution window and outcome definition whenever you compare tests. Also compare like with like. A warm retargeting audience should usually behave differently from people encountering the brand for the first time, so a blended account average can hide weak prospecting behind strong retargeting results.

    Build the holiday budget in stages

    A staged budget lets you use the inexpensive window without assuming that the same economics will survive at greater scale or during peak competition.

    1. Establish your own baseline. Pull the most comparable recent campaigns and separate prospecting, retargeting, and ABM. Record their CPM, frequency, conversion rate, acquisition cost, offer, creative, landing page, and attribution settings. This is the benchmark that matters when a broad market trend does not match your account.
    2. Fund an early prospecting test. Use the lower observed prospecting cost to compare audiences and value messages before the holiday auction becomes more crowded. Change one major promise at a time so you can identify why one version performed differently.
    3. Build a usable retargeting audience. Send qualified prospects to a page that continues the ad’s promise. Segment visitors by meaningful behavior where your platform and consent setup permit it, and exclude purchasers from acquisition ads. Cheap retargeting CPM is not useful if the underlying audience is tiny, poorly matched, or already converted.
    4. Release more budget only after a commercial signal. Scale an audience-message pair when it remains within your acceptable acquisition cost or lead economics. If CPM is attractive but the downstream outcome misses the rule, revise the audience, offer, creative, or landing page before increasing spend.
    5. Keep a peak-period reserve. Do not commit the entire seasonal budget at pre-peak prices. Hold enough flexibility to support proven combinations when shopper intent strengthens, while recognizing that the auction price may also rise.

    This approach avoids two common errors. Waiting until peak week forces you to pay for learning when competition may be stronger. Spending the full budget early assumes that cheap awareness is as valuable as high-intent demand. The staged plan buys learning first and scale second.

    Match each buying method to the job it can do

    A media planner directs budget tokens toward three different ad-buying stations connected to blank display placements.

    Use prospecting to discover demand

    Prospecting is the clearest place to use the early cost decline. Its job is to reach people who have not yet demonstrated interest, identify promising audience-message combinations, and supply qualified visitors for later campaigns. Evaluate it on both audience quality and the downstream customers it creates. Do not demand the same immediate conversion rate as retargeting, but do not excuse it from commercial accountability either.

    Let retargeting audience quality control the budget

    Retargeting reaches people who have already visited or interacted, which is why it should be reported separately. The 40.2% decline from the comparable Q2 period creates an appealing cost environment, but the available spend is constrained by the number of qualified people in the audience. Raising the budget against a small pool can increase repetition instead of finding more buyers. Watch reach and frequency together, and stop serving acquisition messages to people who have already purchased.

    Judge ABM by account value, not the broad display trend

    Account-based marketing moved differently, with CPMs rising 4.4% year over year even though they were 15.1% below the comparable Q2 period. ABM targets narrower groups of named accounts, so its pricing is not a reliable proxy for the wider display market. Use it when the potential account value and sales process justify concentrated exposure. A cheap broad-reach CPM is not a reason to replace that account strategy, and a higher ABM CPM is not evidence that it has failed.

    Whatever buying method you choose, make the value proposition easy to verify. State what is being offered, who it is for, what the price or promotion requires, and why the product deserves consideration. Carry the same terms onto the landing page. If a discount requires a code, minimum purchase, or limited eligibility, reveal that condition before the visitor reaches checkout. Hidden conditions may improve the apparent click response while weakening trust and conversion.

    Test meaningful differences rather than cosmetic variations alone. Compare a price-led message with a benefit-led message, or a general promise with a category-specific one, while keeping the audience and measurement settings stable. The goal is to learn which reason to buy survives beyond the impression and produces the outcome your budget needs.

    Before adding another dollar, separate your recent results by buying method and write the acceptable acquisition cost or lead outcome beside each one. Then fund the smallest pre-peak test that can produce a clear decision. Increase the combinations that satisfy that rule; change or stop the ones that merely deliver inexpensive impressions.

    References


  • How to Audit AI Marketing Recommendations Across Audiences

    How to Audit AI Marketing Recommendations Across Audiences

    You give an AI marketing tool a clear goal, and it returns a confident audience, channel, or brand recommendation. The answer looks ready to use. But before you build a campaign around it, you need to know two things: what evidence produced the recommendation, and whether the recommendation changes when the audience changes.

    If neither is visible, you do not have decision support yet. You have a plausible output whose scope, assumptions, and failure modes are hidden. The practical fix is to audit recommendation evidence and audience variation as one workflow, then require human approval wherever a change could affect reach, spend, eligibility, or brand strategy.

    One AI answer is not a complete market view

    A single answer-engine response can be useful without being representative. The engine may interpret the question through details about the user, the wording of the prompt, prior conversational context, or other signals available to the system. Change that context and the shortlist, ranking, citations, or explanation may also change.

    A vendor analysis of 71,147 answer-engine responses found differences in brand mentions, citations, and search behavior associated with income, age, gender, and occupation. That finding does not establish that every answer engine personalizes every request, nor does it explain the cause of every observed difference. It does show why a persona-neutral prompt should not be treated as a universal picture of AI visibility.

    Some variation is appropriate. A buyer prioritizing affordability and a buyer prioritizing enterprise governance may reasonably receive different recommendations. The issue is not whether answers ever change. It is whether the change follows a relevant criterion, rests on supportable evidence, and remains consistent with the underlying facts.

    Separate the stable layer from the audience-sensitive layer:

    • Stable facts include product identity, documented capabilities, known requirements, and the meaning of cited evidence. A persona change should not silently reverse them.
    • Audience-sensitive judgments include which criterion receives more weight, which use case is emphasized, which options appear first, and which tradeoff is considered acceptable.
    • Presentation choices include tone, examples, terminology, and depth. These may change while the substantive recommendation remains the same.

    This distinction helps you spot three common measurement failures:

    • False universality: one prompt produces one answer, and the result is reported as what the platform recommends to everyone.
    • Hidden exclusion: a brand appears for one persona but disappears for another, with no visible criterion explaining the difference.
    • Averaged-away variation: a dashboard combines responses across audiences and makes unstable visibility look consistent.

    Treat an AI visibility observation as a combination of platform, prompt, audience context, and observation time. If any part changes, you may be measuring a different answer environment.

    A transparent recommendation shows decision evidence

    Hands inspect the visible source, assumption, recommendation, and approval components inside a transparent decision-making assembly.

    Transparency does not mean exposing every internal model operation or demanding a private reasoning transcript. Neither gives a marketer a reliable basis for approval. You need the evidence, uncertainty, and tradeoffs that could materially change the decision.

    This matters because marketing data is rarely as tidy as the campaign brief. A marketer searching for a completed-purchase signal may encounter several similarly named events, such as purchase, checkout success, and checkout completion. The labels alone do not reveal which event represents a confirmed order, which fires earlier in the funnel, or which remains reliable after implementation changes.

    Volume does not settle the question. A frequently firing purchase event could occur before payment confirmation, while a lower-volume checkout-success event could align more closely with the business definition of a completed order. Selecting the biggest signal without checking its meaning can create a large but conceptually wrong audience.

    Require each consequential recommendation to carry an evidence card. It can appear in a conversational response, side panel, review screen, or exported log, but it should answer the following questions:

    Evidence fieldWhat the system should exposeWhat you can decide
    Business objectiveThe outcome the recommendation is intended to support, in business languageWhether the proposed action answers the request you actually made
    Selected signal or criterionThe event, attribute, source, or decision criterion carrying the recommendationWhether the system used the right representation of the goal
    Meaning and funnel stageWhat the signal appears to represent and where it occurs in the customer journeyWhether purchase, checkout, intent, and engagement are being confused
    Provenance and observed behaviorWhere the signal comes from, how it behaves, how often it fires, and when it was last observedWhether the evidence is current and dependable enough for this decision
    Audience boundariesWho is included, who is excluded, and the resulting potential reachWhether the audience matches campaign eligibility and strategy
    Alternatives consideredThe plausible competing signals or approaches that could change the outcomeWhether an apparently obvious recommendation ignored a better-defined option
    TradeoffsHow changing a threshold or criterion affects reach, expected performance, precision, or riskWhich compromise fits the business rather than merely optimizing a model score
    Uncertainty and missing contextAmbiguous definitions, unavailable metadata, sparse observations, or assumptions supplied by the systemWhether to accept, refine, investigate, or reject the recommendation
    Decision stateWhether the output is exploratory, proposed, saved, connected, or activatedWhether any real-world action has occurred and what still requires approval

    Do not accept vague evidence labels such as recent, strong, or large when the interface can expose the underlying context. Recent relative to what observation? Strong against which alternative? Large compared with which eligible population? The system does not need to manufacture precision, but it should distinguish known values from inferred meanings and unavailable information.

    The approval flow matters as much as the evidence. For recommendations that can change spending or customer eligibility, keep proposal, saving, connection, and activation as distinct states. An exploratory conversation should not silently become an active audience. Explicit confirmation creates a point where a marketer can apply business judgment, document an override, or request better evidence.

    Conversation and direct controls also serve different jobs. A conversational agent is well suited to exploring unfamiliar data and explaining why signals differ. A visual interface is better for making precise threshold adjustments after the reach-versus-performance tradeoff is understood. A trustworthy workflow lets you move between them without losing the evidence or approval state.

    Run a controlled audience-variation audit

    Four controlled test lanes hold the same campaign brief while different audience groups lead to visibly varied recommendation objects.

    An audience audit should isolate whether persona context changes the recommendation, not merely collect a folder of unrelated prompts. Keep the decision question and test conditions stable, change one relevant audience dimension at a time, and record substantive differences separately from stylistic ones.

    Build the test grid

    1. Define the decision. Write the exact question the answer must resolve, such as which solution fits a use case or which audience should receive a campaign. State the criteria that should matter before looking at the output.
    2. Create a neutral baseline. Ask the decision question without demographic or occupational context that is not necessary to answer it. This becomes the comparison point, not the presumed correct answer.
    3. Select relevant audience dimensions. Test occupation, age, income, gender, or another persona attribute only where it could plausibly affect needs, constraints, terminology, access, or evaluation criteria.
    4. Change one dimension at a time. Keep the platform, wording, product category, requested format, and other context constant. Composite personas may reflect real buyers, but they make it harder to identify which attribute drove a change.
    5. Capture the complete response. Record the prompt, audience variation, platform and model label exposed by the interface, observation time, recommended brands or actions, ordering, rationale, citations, caveats, and omitted options.
    6. Compare decisions before wording. A different example or tone is less important than a changed shortlist, reversed ranking, new exclusion, altered factual claim, or different call to action.
    7. Inspect the support. Check whether each changed recommendation is tied to an explicit audience need and whether its cited material actually supports the criterion being applied.
    8. Assign a disposition. Mark the variation as presentation-only, relevant and supported, unexplained and substantive, or factually contradictory. Each label should lead to a different next action.

    Interpret changes by materiality

    Presentation-only variation changes the vocabulary, explanation depth, or examples without altering the decision. You may still care about tone and accessibility, but it is not evidence that brand visibility changed.

    Relevant, supported variation changes the recommendation because the persona introduces a genuine decision criterion. An occupational context may change workflow requirements. An affordability constraint may alter which options qualify. The output should make that connection visible rather than relying on an unexplained proxy.

    Unexplained substantive variation changes inclusion, exclusion, order, or recommended action without identifying a relevant criterion or supporting evidence. Do not immediately label it bias or personalization; the system may be responding to ordinary output variation, hidden context, or a retrieval difference. Rerun the unchanged baseline alongside the persona variant, preserve the outputs, and investigate before drawing a causal conclusion.

    Factual contradiction occurs when stable product facts or evidence claims change solely with the persona. That is a blocking issue. Do not use the output for activation or publish the claim until you can resolve which statement is supported.

    Pay special attention to citations. A persona may receive different cited pages even when the recommendation stays similar. Record whether a citation is present, whether it supports the nearby claim, and whether it represents the same kind of evidence across variants. Citation count alone cannot tell you whether the recommendation is sound.

    Age, gender, and income can be useful diagnostic variables because audience-linked variation has been observed, but they can also be sensitive attributes. Using them to determine real customer eligibility can create privacy, fairness, or legal exposure depending on the context and jurisdiction. Use them in testing only when necessary, minimize personal data, and route any activation rule based on sensitive traits through your legal and privacy review process.

    Turn the audit into content, measurement, and controls

    An audit is only valuable if it changes how you publish, measure, or approve marketing decisions. The goal is not to force every audience to receive identical recommendations. It is to make legitimate differences explainable and unsupported differences visible.

    Make audience criteria explicit in your content

    If an answer engine changes its recommendation because of a criterion your content barely addresses, close that evidence gap on the relevant page. Add clear passages that identify:

    • who the product, service, or method is designed for;
    • which use cases it supports and which it does not;
    • what prerequisites, limitations, or eligibility conditions apply;
    • which tradeoffs a buyer must make;
    • how important terms and outcomes are defined; and
    • which verifiable facts support each suitability claim.

    Write around decision contexts, not demographic labels. A page explaining the needs of a regulated procurement workflow is more useful than a thin page targeting an occupational persona by name. A clear affordability limitation is more informative than assuming what someone can spend from a demographic category.

    Structured data can reinforce supported facts about the page, organization, product, service, author, or other entities where the relevant schema applies. It cannot make an unsupported claim trustworthy, encode every possible persona preference, or guarantee that an answer engine will recommend a brand. Use schema to clarify machine-readable facts, then make the audience-specific reasoning legible in the visible content.

    Measure visibility at the audience level

    Do not reduce answer-engine performance to a platform-wide mention rate if your buyers approach the category with materially different contexts. Track AI visibility by audience as well as by platform, while retaining the neutral baseline so you can see where variation begins.

    For each monitored decision question, record:

    • the exact prompt and persona context;
    • the engine, interface, and model information exposed at the time;
    • whether your brand was mentioned;
    • where it appeared in an ordered recommendation, if the answer provided an order;
    • the use case or criterion attached to the mention;
    • the pages or sources cited;
    • the caveats attached to the recommendation; and
    • whether the result was stable, relevantly different, unexplained, or contradictory.

    Keep the prompt set and audience definitions fixed when comparing observations over time. If you rewrite the question, change the persona, and switch platforms at once, you cannot tell whether a visibility movement came from your content, the engine, or the test design.

    Define approval boundaries before activation

    Set review rules before an agent proposes an audience or campaign. Require human approval when:

    • the selected data signal has an ambiguous business meaning;
    • the origin, observed behavior, or recency of the evidence is unavailable;
    • a threshold creates a material reach-versus-performance tradeoff;
    • a sensitive audience attribute changes inclusion or exclusion;
    • persona variants produce contradictory facts or unexplained recommendations;
    • the action can change budget, customer eligibility, messaging, or external activation; or
    • the system cannot show which assumption would most affect the recommendation.

    Preserve the human decision in a log. Record the proposal, evidence shown, audience context, chosen action, override, approver, and activation state. This is not paperwork for its own sake. It lets you distinguish a model recommendation from the business decision that followed it and prevents later reporting from treating the two as interchangeable.

    Key takeaways

    • A single AI response represents one platform, prompt, audience context, and observation time. It is not a universal market answer.
    • Useful transparency exposes the selected signals, their meaning and recency, audience boundaries, alternatives, uncertainty, and tradeoffs. A private reasoning transcript is not required.
    • Test audience variation by holding the decision question constant and changing one relevant persona dimension at a time.
    • Separate presentation changes from substantive recommendation changes, and block activation when stable facts become contradictory.
    • Measure brand mentions, ordering, use cases, citations, and caveats by audience rather than averaging every response into one platform score.
    • Keep exploration, saving, connection, and activation distinct so a marketer can refine or override the recommendation before it affects customers or spend.

    Start with the next recommendation your team is already preparing to use. Attach an evidence card, run the neutral prompt beside one relevant audience variant, and classify every substantive difference. If the system cannot explain a changed recommendation with current evidence and a relevant criterion, do not report it as universal and do not activate it. Fix the evidence, the content, or the decision rule first.

    References