Tag: Attribution Models

  • Why Marketing Automation Still Needs Human Oversight

    Why Marketing Automation Still Needs Human Oversight

    Marketing automation can react to campaign signals faster than a person, while marketing mix modeling can help explain performance across channels and longer time horizons. Neither capability removes the need for human oversight; each moves that oversight to decisions about goals, data quality, constraints, validation, and interpretation.

    The useful question is therefore not whether people or machines should control marketing. It is where human judgment has the greatest leverage in a system that combines rapid execution with slower, broader measurement.

    Automation and measurement address different decision gaps

    Campaign automation primarily shortens the gap between an observable signal and an action. The account described in the groas report used an automated system to adjust bids, budgets, keywords, match types, campaign activity, ad copy, and landing pages in response to Google Ads data. Its proposed advantage was continuous attention: a weak search term or drifting target could be addressed sooner than under a periodic manual review cycle.

    Marketing mix modeling (MMM) addresses a different problem. Rather than managing an individual auction, it estimates how channels and outside factors relate to business outcomes over time. the MMM report said a credible implementation may require two to three years of weekly data, consistent channel-level spending, offline activity, and external variables such as pricing, competitor activity, product launches, and macroeconomic conditions.

    These approaches operate at different speeds and levels of aggregation, but their dependencies converge. Both need a well-defined business outcome, trustworthy inputs, knowledge of exceptional events, and a person capable of challenging an apparently successful output. Faster optimization cannot repair a poorly chosen conversion goal, just as sophisticated modeling cannot compensate for missing or inconsistent historical data.

    DimensionCampaign automationMarketing mix modeling
    Primary purposeAct on account-level performance signalsEstimate contribution across channels and business conditions
    Reported data emphasisSearch terms, bids, budgets, devices, audiences, conversion tracking, and auction behaviorHistorical spend, outcomes, offline media, seasonality, pricing, launches, and external factors
    Main human responsibilitySet objectives, structure the account, establish guardrails, and review consequential changesSpecify the model, resolve data problems, test assumptions, calibrate estimates, and interpret uncertainty
    Failure riskRapidly optimizing toward the wrong signalProducing a plausible but misleading explanation of performance

    Human judgment matters before, during, and after automation
    Marketing specialists set campaign goals, monitor automated activity, and review outcomes across a continuous workspace.

    Before: define what the system should optimize

    The first oversight point is objective design. In the groas account, a human account manager reportedly audited campaign structure, keywords, bidding logic, budget allocation, conversion tracking, quality scores, search terms, and auction insights before automated optimization began. The report also acknowledged that people must communicate changes in products, pricing, and the relative importance of conversions. Those choices determine whether the system is improving a meaningful business result or merely making a platform metric look better.

    MMM has an equivalent setup problem. A modeler must decide which outcome to explain, how channels should be separated, which external variables belong in the model, and how unusual periods should be represented. The MMM source described the preliminary work as data archaeology because relevant records can be divided among finance, brand teams, agencies, and old spreadsheets. Human oversight begins with reconciling those records, not with selecting a modeling library.

    During: constrain action and investigate anomalies

    The reported groas rollout illustrates one way to limit early execution risk. It began with two weeks of observation, moved into calibration during weeks three and four, looked for traction in weeks five and six, and approached scaling in weeks seven and eight. This staged process is significant because automation should earn a larger operating range through observable behavior rather than receive unrestricted control on its first day.

    Oversight during MMM is more diagnostic than operational. According to the modeling source, practitioners still have to judge solutions along a Pareto frontier, assess whether an optimizer has converged, configure adstock behavior, and investigate implausible channel contributions. They may need to determine whether a suspicious result comes from an incorrect prior, a data error, or a variable that should be excluded. Code generation can reduce implementation effort without resolving any of those substantive choices.

    After: interpret evidence without overstating it

    Automated outputs still require a disciplined reading. The groas source reported a before-and-after comparison for a U.S. online mobile recharge account in which spend increased 18% to $164,000, ROAS rose from 1.02x to 1.32x, average CPC fell from $2.34 to $2, daily conversions increased from 571 to 739, conversion value grew 44%, and cost per conversion declined 14%. It also reported that active search campaigns were consolidated from 17 to 10.

    Those figures describe the source’s account snapshot, not an independently verified or universally transferable effect. A before-and-after account comparison can show that performance changed after an intervention, but by itself it does not isolate every possible cause. Seasonality, competitive conditions, demand, pricing, and concurrent business changes still need consideration. Human oversight includes distinguishing a promising operational result from a causal conclusion.

    Model sophistication does not neutralize weak inputs

    The MMM source compared three open-source options: Meta’s Robyn, Google’s Meridian, and PyMC-Marketing. It characterized Robyn as the most approachable of the three, Meridian as a more rigorous Bayesian option with uncertainty quantification and geo-level priors, and PyMC-Marketing as the most flexible but most demanding in statistical fluency. The availability of these libraries lowers the software and access barrier, but it does not make their results automatically reliable.

    This distinction also applies to campaign automation. A system may be technically capable of adjusting every available control while remaining unable to know that a tracking event is misconfigured, a temporary promotion has changed customer behavior, or a low-value conversion should no longer guide bidding. Greater execution coverage magnifies the value of clean signals, but it can also magnify the consequences of a bad specification.

    The common governance principle is proportional scrutiny. The more quickly a system can move money or the more strongly a model can influence allocation, the more clearly its inputs, permissions, assumptions, and escalation conditions should be documented. Transparency should cover not only what the technology changed or estimated, but also which human decisions framed the result.

    A supervised operating model connects action to learning
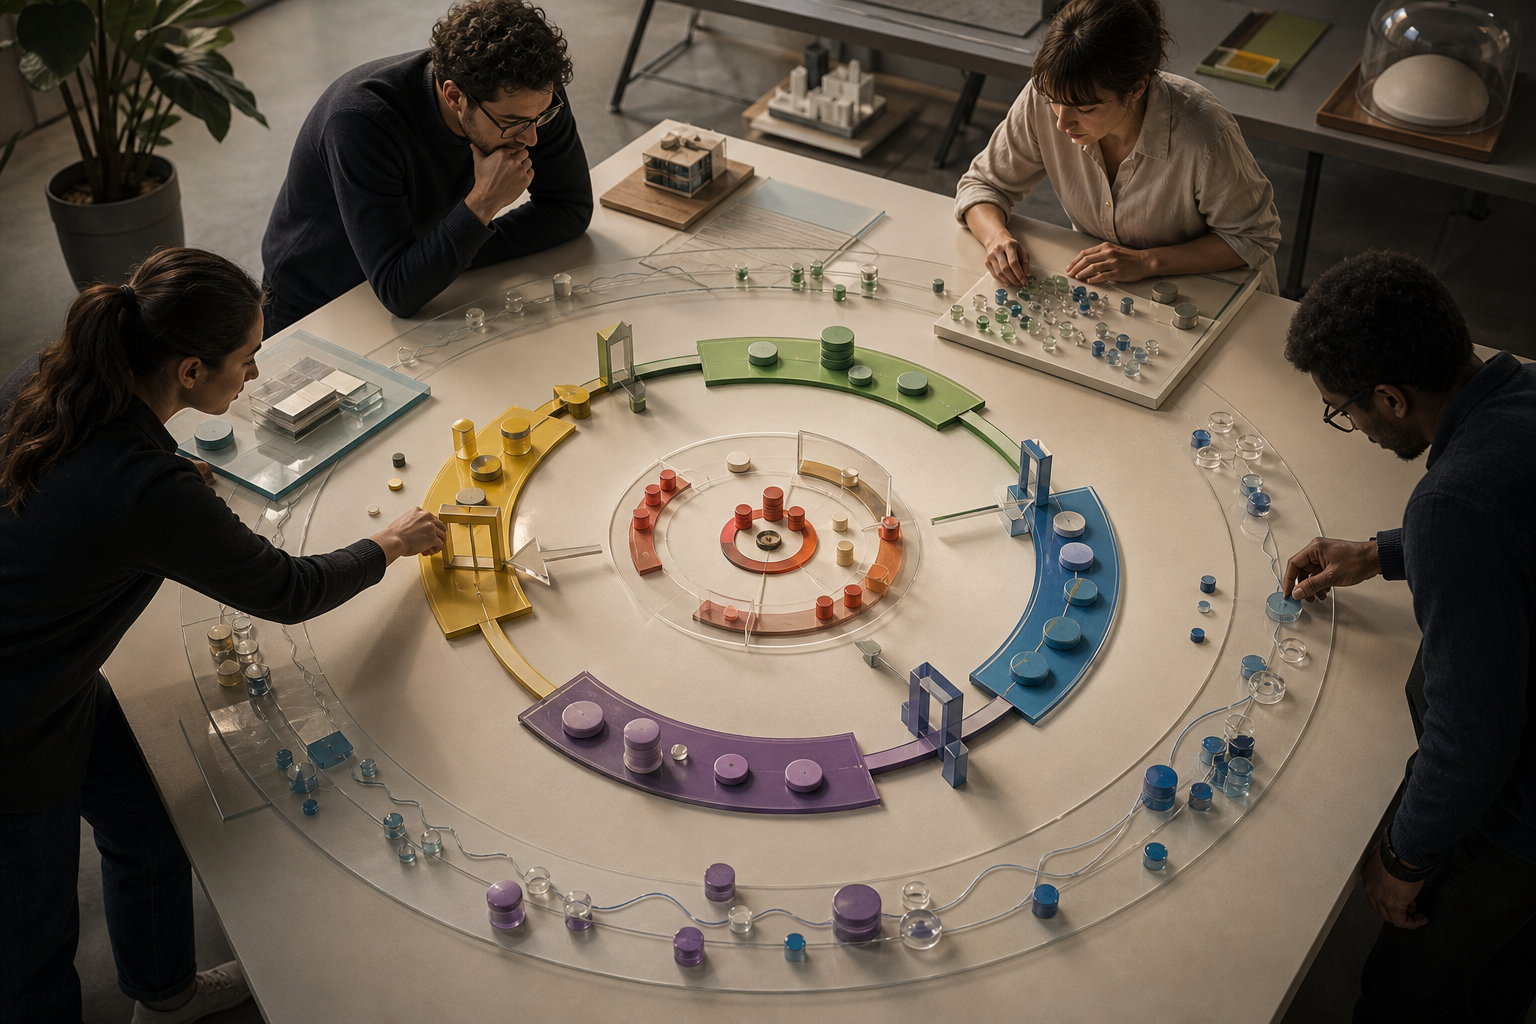
    A cross-functional team supervises a circular system of campaign actions, measurement signals, constraints, and revised decisions.

    A practical oversight structure separates responsibilities without separating the evidence. A strategy owner defines the business outcome and acceptable tradeoffs. A data owner protects conversion definitions, reconciles source systems, and records structural changes. A campaign operator monitors automated actions and intervenes when changes exceed agreed boundaries. A measurement specialist tests assumptions, communicates uncertainty, and uses experiments where possible to calibrate model estimates.

    These responsibilities should form a feedback loop. Campaign automation produces actions and fresh performance data. Broader measurement examines how channel activity relates to business outcomes. Incrementality experiments can help test selected assumptions, as the MMM source recommended. People then decide whether objectives, constraints, budgets, or measurement specifications need to change before the next cycle.

    Escalation should focus on changes that machines cannot interpret from performance data alone: broken or redefined tracking, a pricing shift, a product launch, an exceptional market disruption, an implausible channel estimate, or a budget move that conflicts with a strategic commitment. This allows routine optimization to proceed while reserving human attention for context-heavy and consequential decisions.

    Key takeaways

    • Campaign automation reduces response time, while MMM addresses cross-channel explanation; neither replaces the other.
    • Human oversight has three control points: defining objectives and inputs, governing execution and anomalies, and interpreting results.
    • Reported performance improvements should be evaluated in light of study design, business changes, and alternative explanations.
    • Open-source models and AI-assisted coding reduce technical barriers, but data reconciliation, assumption testing, and business context remain expert tasks.
    • The strongest operating model links automated action, measurement, experimentation, and human decisions in a documented feedback loop.

    As marketing systems gain more authority, oversight will need to become more explicit rather than more occasional. Organizations that define decision rights, preserve context, and test what their systems claim to learn will be better positioned to benefit from automation without surrendering accountability.
    References

  • How AI Advertising Signals Are Reshaping Audience Targeting

    How AI Advertising Signals Are Reshaping Audience Targeting

    AI-powered advertising is moving beyond simple demographic segments or keyword lists. The emerging model combines advertiser-supplied audiences, platform-native attributes, exposure data, creative inputs and conversion outcomes to help automated systems decide whom to reach and how to optimize.

    Reports about ChatGPT Ads and Microsoft Advertising illuminate different parts of that model. The former points to more direct audience control through customer-list uploads, while the latter shows how many supporting signals must work together before automated targeting can produce useful results.

    Key takeaways

    • CrushPress.AI reported an apparent ChatGPT Ads feature that accepts email- or phone-based audience lists, but the report was preliminary and did not establish match rates or performance.
    • Microsoft Advertising offers a broader signal mix that reportedly includes LinkedIn profile attributes, impression-based remarketing, landing-page imagery and conversion data.
    • An audience identifier tells an ad system who may be relevant; measurement signals tell it which outcomes should guide optimization.
    • More data does not automatically improve targeting. Clean tracking, concentrated campaign structure and relevant creative help automation interpret signals correctly.
    • Advertisers need governance for consent, list handling, exclusions and platform-specific policies alongside performance controls.

    Three signal layers now shape audience decisions

    Three layers of abstract customer, contextual, and outcome signals converge through a targeting lens toward a diverse audience.

    Advertiser-supplied identity signals

    CrushPress.AI reported that an Audiences area was appearing under Tools in ChatGPT Ads Manager. According to the report, advertisers could upload raw or hashed email addresses and phone numbers in CSV or TXT files, then use the resulting audiences as campaign filters. The account was based partly on screenshots attributed to Craig Graham and Joss Froggatt on LinkedIn, so it should be treated as an apparent rollout rather than a complete product specification.

    This type of first-party identity signal can connect an advertiser’s known customers or prospects with accounts recognized by an advertising platform. Its practical value depends on factors the report did not resolve, including audience matching, minimum usable size, availability across accounts, exclusions and measured lift. The important development is therefore not a guaranteed performance gain, but the appearance of a more direct way for advertisers to define relevant audiences inside a conversational advertising environment.

    Platform-native profile and exposure signals

    The Microsoft Advertising account describes a different source of audience intelligence: information already available within the platform’s ecosystem. It reports that LinkedIn Profile Targeting can support observation and bid adjustments, while Company, Industry, Job Function and Seniority data can serve as Performance Max audience signals. For B2B campaigns, those attributes can express professional relevance without requiring the advertiser to possess every prospect’s contact details.

    The same source highlights impression-based remarketing, which can reportedly include, exclude or adjust bids for people who have seen an ad. It says this method does not require an existing email list or site pixel and that a person may remain eligible for up to 30 days after one impression. Unlike an uploaded list, this signal reflects prior advertising exposure rather than a known customer relationship.

    Creative and outcome signals

    Audience targeting is only one part of an automated decision system. The Microsoft Advertising source also treats creative assets as signals: the platform can reportedly retrieve images from landing pages when that capability is enabled, using the advertiser’s own site as material for ad experiences. Strong, relevant imagery may help the system represent the offer, while unsuitable page images can introduce a different kind of noise.

    Conversion and attribution data complete the loop. The source identifies Microsoft Click ID, view-through conversions and simplified conversion setup as mechanisms that help connect advertising activity with outcomes. In general terms, identity and profile data indicate possible relevance, creative communicates the proposition, and conversion data tells automation which decisions appear to be working.

    Signal quality matters more than signal volume

    The two reports together suggest that AI targeting should be understood as signal engineering, not merely audience selection. Uploading a customer file may define a valuable group, but it does not establish the campaign objective, repair incomplete conversion tracking or ensure that the creative matches that group. Conversely, sophisticated bidding cannot recover reliable meaning from duplicated attribution, irrelevant conversions or poorly maintained landing-page assets.

    Campaign structure affects this interpretation. The Microsoft Advertising source argues that ad-group-level scheduling and location settings can reduce unnecessary campaign duplication and concentrate conversion activity. It also warns that automatic synchronization from an imported campaign can overwrite platform-specific changes. Importing from another advertising system may accelerate setup, but preserving the original account’s assumptions can prevent the destination platform from learning from its own audiences and auction conditions.

    Controls should be applied at the level where the underlying decision belongs. The source says Microsoft Advertising supports account-level phrase- and exact-match negatives, while noting that neither handles close variants. A broad account exclusion can remove unwanted traffic everywhere, but a nuanced restriction may belong at campaign or ad-group level. The broader lesson applies across AI advertising: guardrails help when they remove genuinely invalid choices, but overly broad rules can suppress useful learning.

    Measurement and governance determine whether targeting is useful

    A protected AI decision core filters audience signals through privacy, balance, and verification symbols before they reach groups of people.

    A useful evaluation begins by separating audience availability from audience effectiveness. The reported ChatGPT Ads capability answers a setup question: can an advertiser provide identifiers and use the matched audience as a filter? It does not, on the evidence supplied, answer whether that audience improves incremental conversions, lowers acquisition costs or simply reaches people who would have converted anyway.

    The Microsoft Advertising account emphasizes measurement before bid changes. That ordering matters because incomplete attribution can make an audience, keyword or bidding strategy appear responsible for a problem created elsewhere. Click-based and view-through measurements can also assign value differently, so teams need consistent definitions of the outcomes used to train automation.

    Before expanding an AI-targeted campaign, advertisers should establish:

    1. The targeting purpose: whether a signal is intended for inclusion, exclusion, observation, bid adjustment or automated prospecting.
    2. The source and freshness: where the data originated, how recently it was collected and whether it still represents the intended audience.
    3. The optimization event: which conversion actions represent business value and whether they are recorded consistently.
    4. The comparison: what control group, holdout or other baseline can distinguish incremental impact from ordinary demand.
    5. The creative fit: whether supplied or automatically retrieved assets accurately represent the offer for the selected audience.
    6. The governance boundary: whether collection, uploading, hashing, retention and activation follow applicable consent requirements and platform rules. Hashing changes how an identifier is represented; it does not by itself establish permission to use it.

    These checks also make cross-platform comparisons more meaningful. An uploaded customer audience, a professional-profile signal and an impression-based remarketing pool represent different relationships with a person. Treating them as interchangeable because all three appear under an audience label would conceal their different intent, reach and measurement requirements.

    The next advantage will come from coherent signals

    As conversational and established advertising platforms add more automation, audience access alone is unlikely to be a durable advantage. The stronger capability will be coordinating permissioned audience data, platform-specific context, suitable creative and trustworthy outcomes into one understandable learning loop. Marketers that can explain what each signal means, where it belongs and how its contribution will be tested will be better positioned to use new targeting controls without surrendering accountability.
    References

  • How to Measure AI Search Visibility, Citations and Impact

    How to Measure AI Search Visibility, Citations and Impact

    AI search visibility is no longer a single ranking question. A brand can appear in an answer, earn a citation, receive a visit, influence a later conversion or remain invisible to conventional attribution at each stage.

    The practical response is to connect content optimization, citation monitoring and business measurement. The sources collectively show why those disciplines must operate as one system, even though no single metric can yet describe the entire AI-assisted customer journey.

    Key takeaways

    • AI visibility begins with content that can be discovered for a broad topic, understood in context and extracted into an answer.
    • A citation is evidence of selection, not proof that a user visited or converted.
    • Referral traffic captures only journeys that include a trackable click; direct visits, calls and delayed conversions can obscure AI influence.
    • Measurement should progress from answer presence to citations, referrals, conversions and lead quality.
    • Global standards should govern technical implementation and reporting, while market experts supply differentiated local knowledge.

    Visibility depends on retrieval, selection and presentation

    Traditional rank tracking starts with a query and a results position. AI-generated answers add intermediate decisions: the system may decompose a request into related subqueries, retrieve supporting pages, synthesize their information and choose which sources to display. Visibility can therefore be gained or lost before a citation is ever shown.

    A Search Engine Land article about Google query expansion distinguishes traditional query expansion from AI Mode query fan-outs. In its account, expansion connects searches through synonyms, intent and related topics, while fan-outs generate multiple subqueries during answer construction. The article recommends using Google Search Console impressions and unexpected but relevant queries as signals for strengthening topic coverage, rather than as an invitation to add disconnected keywords.

    That retrieval perspective complements HiGoodie’s travel optimization guidance, which emphasizes direct answers, FAQs, schema markup, topical authority and content based on real traveler questions. That source reports that 40% of travelers use AI to research, compare and organize travel decisions. The percentage should be treated as reported by the article, but its strategic implication is clear: content must supply both a concise answer and enough surrounding context to be interpreted correctly.

    Selection does not guarantee equal exposure. Search Engine Land’s report on recipe links in Google AI Mode describes a visual treatment that can place creator names, images, ratings and ingredient counts near prominent links. It also notes that Google had been testing a top-stories carousel in AI Overviews but that the feature did not appear to be live at the time reported. These examples make presentation a separate measurement dimension: two cited publishers may receive materially different opportunities to be recognized or clicked.

    A citation is not the same as a visit or a customer

    A glowing source card begins a branching path of stepping stones that ends with two hands exchanging a parcel.

    The recipe treatment illustrates the distinction between attribution and distribution. More recognizable links may improve the path to a publisher, but the report leaves open whether they will generate enough meaningful traffic. Citation counts alone cannot resolve that question because a source can inform an answer without producing a click.

    The opposite measurement problem also occurs: AI may influence a customer without producing a visible referral. A Search Engine Land article based on an analysis of nearly 30 million inbound leads reports that AI-attributed leads remained a small share of total volume but were growing and appeared across multiple industries. It also describes customers who encounter a recommendation in an AI service and later call a business, creating journeys that may be classified as direct or remain unattributed.

    The same source is explicit about the dataset’s limits: it could identify cases in which customers named an AI platform as part of the route to contacting a business, but it could not reveal their prompts, platform choices or the reasons a particular company was recommended. That is evidence of association within a reported journey, not a complete causal explanation.

    Organizational interest is also moving toward this broader view. Profound’s recap of Zero Click New York 2026 says that more than 1,000 marketing leaders gathered on June 11, 2026, and that sessions addressed Claude’s citation mechanics, ChatGPT’s emerging advertising business and content signals associated with AI trust. An event recap is not outcome data, but the subjects it highlights show citations, distribution and measurement being treated as connected management questions.

    Use a measurement ladder instead of one AI metric

    Analysts examine ascending translucent platforms marked by symbols for visibility, sources, visits, journeys and value.

    A workable reporting model separates observable stages rather than combining them into a proprietary visibility score. Each stage answers a different question and carries a different evidentiary limit.

    Measurement layerQuestion it answersUseful evidenceMain limitation
    Answer presenceDoes the brand or page appear for relevant prompts?Repeatable prompt checks across selected platforms, markets and use casesOutputs can vary, so a single observation is not a stable benchmark
    Citation visibilityWhich pages are named or linked as sources?Citation frequency, cited URLs, placement and visible source treatmentA citation does not establish attention, a click or preference
    Referral activityDid a user arrive through a trackable AI link?Analytics referrals, landing pages and tagged campaign links where availableNon-click journeys and incomplete referrer data remain unseen
    Conversion influenceDid AI discovery contribute to an inquiry or sale?Lead-source questions, call attribution and customer-reported discovery pathsSelf-reporting and multi-touch journeys complicate causal claims
    Business qualityAre AI-influenced customers valuable?Qualified leads, completed transactions and downstream customer outcomesLow volume can make comparisons unstable

    These layers should be reported separately before they are interpreted together. For example, rising citation visibility with flat referral traffic could indicate a zero-click exposure pattern, weak source presentation or a mismatch between cited content and user intent. Rising customer-reported AI discovery without comparable referrals would instead point to an attribution gap. Both observations warrant investigation, but neither proves its suspected explanation by itself.

    Content research can connect the upper and lower portions of the ladder. Search Console queries can reveal adjacent questions already associated with a page, while citation observations show whether AI systems select that page for related answers. Referral and lead data then indicate whether any of that exposure reaches the business. Optimization becomes a testable cycle when the baseline, content change and subsequent observations are recorded consistently.

    Govern shared infrastructure while localizing expertise

    Measurement becomes harder when teams use conflicting entity definitions, technical rules or reporting methods. The problem is especially acute for multinational organizations because an AI system can synthesize material across markets rather than respecting the operational boundaries used inside the company.

    A Search Engine Land analysis of global SEO ownership argues that hreflang, localization and technical SEO remain necessary, but that hreflang handles routing rather than deciding which market perspective an AI answer should prioritize. It recommends central governance for areas in which inconsistency creates enterprise-wide risk, including CMS rules, structured data, entity definitions, AI crawler policies, measurement frameworks and technical infrastructure.

    The same analysis places audience research, regulatory information, local authority building and market expertise closer to in-market teams. Its central tension is not simply standardization versus translation. Multiple near-identical market pages may provide less differentiated evidence than content grounded in local terminology, regulations, customer expectations and industry practices.

    That division of responsibility also applies outside international SEO. A central team can define how citations, referrals and AI-influenced leads are recorded, while subject specialists validate the underlying claims and answer the questions their audiences actually ask. The travel guidance’s focus on traveler intent and the query-expansion article’s focus on adjacent questions both support this combination of shared structure and domain-specific knowledge.

    The next useful advance will come from disciplined linkage: connecting the content changes made, the answers and citations observed, and the customer outcomes recorded without overstating what any one dataset proves. Organizations that establish that evidence chain can adapt as interfaces and citation treatments change, while keeping investment decisions tied to measurable audience and business value.

    References

  • How AI Advertising Changes Measurement and Experimentation

    How AI Advertising Changes Measurement and Experimentation

    AI-driven advertising is making campaign delivery more adaptive while making performance harder to interpret. When platforms choose audiences, placements and combinations of creative, a conversion report can show what happened without revealing whether automation created additional demand, captured demand that already existed or simply shifted credit between channels.

    The useful response is not another all-purpose attribution metric. Advertisers need a layered measurement system that combines behavioral signals, downstream outcomes, controlled experiments and creative-quality checks. The source reports collectively show platforms moving in that direction, although each covers a different part of the problem.

    AI shifts the question from attribution to evidence

    Traditional attribution asks which interaction receives credit for a result. AI-driven campaigns create a broader question: what evidence shows that the campaign changed customer behavior? That distinction matters because an automated system may optimize successfully against its assigned conversion signal while producing little incremental value for the wider business.

    The reported expansion of YouTube measurement illustrates the shift. CrushPress.AI’s article on YouTube measurement said Google added Shorts Ad Actions to the budget optimization and reporting available for eligible Video View Campaigns. It also reported the global availability of Attributed Branded Searches, a Google Ads metric intended to identify branded Google searches following exposure to or a view of a YouTube ad.

    Those signals occupy different positions in the customer journey. A Shorts interaction describes behavior around the ad itself, while a subsequent branded search suggests that exposure may have influenced active interest. Neither is equivalent to a sale, but together they can provide a more informative path from attention to intent.

    The article relayed Google’s claim that Shorts ads associated with more than 10 seconds of watch time and a like delivered 15% higher brand consideration and 20% higher brand favourability. It also relayed Google’s statement that each additional branded search generated was associated, on average, with a $31 sales increase. These are reported platform findings and associations, not universal forecasts or proof that every additional search causes the stated sales gain.

    Signals form a measurement ladder, not a single score

    Four connected translucent platforms rise from behavioral signals to outcomes, a controlled test apparatus, and a verified decision beacon.

    AI advertising environments increasingly expose early indicators that are useful before a direct conversion occurs. The appropriate interpretation depends on how close each signal sits to the desired business outcome.

    Interaction signals diagnose relevance

    Ad dismissal is one example. CrushPress.AI’s report on ChatGPT advertising said OpenAI reported a 50% decline in dismissals after launching its advertising business and presented that change as evidence of improving relevance. A lower dismissal rate may indicate that ads feel less intrusive or more useful in a conversational setting, but it does not by itself establish incremental sales, profit or retention.

    This makes dismissal a diagnostic metric rather than a final business verdict. It can help determine whether an ad fits the user’s task and context. The same principle applies to watch time, likes and other engagement actions: they can reveal whether the experience is resonating, while stronger evidence is still required to justify budget.

    Intent and cross-channel outcomes strengthen the case

    Branded search can bridge the gap between engagement and conversion because people do not always respond through the channel that introduced them to a brand. The paid-social measurement article described a common pattern in which social advertising creates awareness and paid search later captures the visit or conversion. It recommended examining branded search activity, search click-through rate, conversion rate, lead quality, cost per acquisition and revenue-related outcomes before, during and after meaningful social changes.

    These comparisons are directional because public relations, email, influencers, product launches, seasonality and organic activity can also affect search behavior. Their value is in identifying a plausible relationship that deserves stronger testing. When branded search, search engagement and conversion efficiency move together after a campaign change, the combined pattern is more informative than any one metric viewed alone.

    Experiments are becoming the control plane for automation

    Two matched campaign environments run in parallel with one controlled variation, and their results feed back into an automation engine.

    Controlled experiments address the central weakness of observational reporting: the absence of a credible counterfactual. Instead of asking only how an AI campaign performed, an experiment asks what would likely have happened without the campaign or without the proposed change.

    Microsoft’s reported Performance Max experiment expansion separates two useful decisions. Uplift experiments compare Performance Max activity with a control group to assess incremental impact. Upgrade experiments compare an existing campaign with an upgraded Performance Max version before a broader rollout. The first tests whether the automated campaign adds value; the second tests whether changing the operating model improves results.

    Google’s Ads API v24.2 adds another level of experimental granularity. According to the source article, its COMPARE_CAMPAIGNS workflow can compare multiple campaigns or campaign types across as many as five experiment arms, including custom Performance Max experiments. A separate experiment can divide traffic within one Performance Max campaign to test text customization and final URL expansion.

    Together, these options point to three distinct testing jobs. Incrementality tests evaluate whether advertising creates additional outcomes. Upgrade tests evaluate whether a new automated campaign structure outperforms the current approach. Component tests isolate a feature or configuration inside the system. Treating these as separate questions prevents a successful feature test from being mistaken for proof that the entire campaign is incremental.

    Where platform-native experiments are unavailable, the cross-channel measurement article proposed geotargeted holdouts: paid social runs in selected test markets and is withheld from comparable control markets, with search and business outcomes compared across the groups. It also noted that this approach generally requires suitable markets, sufficient budget and enough time, while smaller advertisers may need to begin with carefully controlled pre- and post-campaign analysis.

    Creative and delivery must be measured as one system

    Automation changes what creative does. In broad-targeting systems such as Performance Max, Advantage+ and TikTok’s automated expansion, the creative does more than persuade a predefined audience. Its language, visuals, opening hook and call to action help people self-select and generate behavioral signals that influence future delivery.

    The source on creative qualification argued that specificity is therefore a performance control. A message that clearly states the relevant need, prerequisite or use case can discourage unqualified engagement while attracting people for whom the offer is appropriate. That can improve lead quality and reduce the noisy conversion data fed back into an automated system. A generic message may achieve inexpensive engagement while teaching the system to find more of the wrong response.

    Measurement should consequently connect asset-level engagement with qualified outcomes. High watch time or click-through rate is encouraging only when the same creative also contributes to appropriate leads, sales or other defined business results. Creative tests should preserve the qualifying elements that identify the intended customer, rather than optimizing hooks in isolation.

    Placement visibility is part of the same diagnosis. The Google Ads API v24.2 article reported that Performance Max placement views can be segmented by ad_network_type, providing more visibility into where performance occurs across Search, Display and partner networks. That does not remove every limitation of automated delivery, but it can help teams determine whether an apparent creative result is actually concentrated in a particular network or context.

    Build decisions around an evidence hierarchy

    A practical operating model begins by assigning each metric a job. Interaction metrics diagnose relevance, branded search and cross-channel efficiency indicate possible demand creation, and holdouts or platform experiments provide the strongest available evidence of incrementality. Business outcomes remain the decision target against which the other layers are judged.

    Key takeaways

    • Define the business outcome before choosing the platform optimization signal; the two should be connected but should not be treated as interchangeable.
    • Use dismissals, watch time, likes and clicks to diagnose relevance, not as stand-alone proof of commercial value.
    • Monitor branded search and paid-search efficiency to detect demand that an upper-funnel or social campaign may have created elsewhere.
    • Match the experiment to the decision: uplift for incrementality, upgrade tests for campaign migration and component tests for individual automation features.
    • Evaluate creative as both a persuasion mechanism and an audience qualifier, with lead quality or customer value checked alongside engagement.
    • Document delivery context, placement mix and AI-generated asset status so that experiment results remain interpretable and governable.

    The final point extends beyond performance reporting. The Google Ads API article also reported new fields for synthetic-content information and attestation. Such disclosures do not measure effectiveness, but they become important experiment metadata: teams need to know which assets were AI-generated, which controls were active and what changed between variants if they want results that can be audited and repeated.

    As automated platforms assume more control over delivery, measurement will need to become more deliberate rather than more passive. The teams best positioned for the next generation of ad products will be those that can connect useful early signals to cross-channel behavior, then challenge the apparent result with a credible control.

    References

  • How AI Brand Discovery Turns Visibility Into Recommendations

    How AI Brand Discovery Turns Visibility Into Recommendations

    AI brand discovery is not one visibility problem. It is a sequence: a system must find and understand a brand, select its material as evidence, include the brand in an answer, and sometimes recommend it strongly enough to influence what the buyer does next.

    The source material reveals why conventional search reporting captures only part of that sequence. Organic rankings can coexist with weak AI citations, while an AI recommendation can influence a later search visit without receiving credit in referral analytics. Brands therefore need a measurement and content strategy that follows the full path from discoverability to commercial action.

    AI visibility is a chain, not a single ranking

    The sources describe different stages of the same process. The B2B benchmark reported by Search Engine Land examines whether brands ranking in Google are cited in AI Overviews. HiGoodie’s guidance concentrates on making content clear, credible, and understandable to answer engines. A separate Search Engine Land report covers what users did after ChatGPT recommended a brand. Its assistive-agent framework then extends the journey from recommendation toward transactions completed by software.

    Combined, these perspectives suggest four distinct visibility questions. Can an AI system discover the relevant material? Can it interpret and trust that material as evidence? Does the resulting answer cite or recommend the brand? Does that exposure influence a visit, comparison, or purchase? Success at one stage does not establish success at the next.

    This distinction matters because citations and recommendations serve different functions. A citation identifies a source used in an answer. A recommendation places a brand into the buyer’s consideration set. Either can create value, but the downstream effect of a recommendation may be easier to see in buyer behavior than in a referral report.

    Strong organic reach can conceal an AI citation deficit

    A prominent webpage appears high in a search-results scene but remains outside the sources selected by an adjacent AI system.

    The clearest evidence of a broken handoff comes from Walker Sands’ B2B AI Search Visibility Benchmark, as reported by Search Engine Land. The analysis covered more than 45 million March search queries associated with 828 enterprise B2B companies in 14 industries. It reported that the median company ranked for about 9,700 queries and encountered AI Overviews on 48.8% of its relevant ranking keywords, yet appeared as a citation in only 3% of those AI Overviews.

    The benchmark also reported that 4.6% of the companies received no AI Overview citations for any relevant keywords. Even its top quartile reached a citation inclusion rate of only 4.5%, compared with 1.7% for the bottom quartile. These findings do not show that organic search has stopped mattering. They show that ranking coverage and selection as evidence are separate outcomes.

    Category exposure also varied. According to the report, AI Overviews appeared in a median 59.9% of cybersecurity searches, where brands achieved the study’s highest median citation rate of 4.2%. Distribution and logistics had the lowest reported AI Overview incidence, at 29.6%, while both that category and professional services recorded median citation rates of 2.1%. A visibility target should therefore reflect how often AI answers appear in the category as well as how frequently the brand enters them.

    The benchmark associates stronger citation performance with topical depth, direct explanations, structured information, and consistent coverage across related pages. HiGoodie’s article arrives at a compatible editorial prescription: organize content around real questions, connect related topics, and support claims with credibility signals. Together, the sources favor focused subject-matter coverage over simply publishing more pages for more keywords.

    Recommendations can create demand that attribution misses

    A person receives an AI product suggestion, later searches for the item, and reaches a purchase through an indirect glowing path.

    Citation inclusion is an intermediate metric; buyer response is closer to the business result. Search Engine Land’s account of a Similarweb study reported that U.S. desktop users who received a specific ChatGPT brand recommendation were, on average, 2.5 times more likely to visit the recommended brand than a direct competitor within seven days. The study followed activity from July through December 2025 across selected finance, travel, and beauty brand pairs. It excluded users who had recently visited the brand or explicitly named it in their prompt.

    The reported pattern appeared in all three sectors, although its size differed by brand pair. After a Capital One recommendation, for example, 14.2% of users visited Capital One and 3.8% visited American Express. After a Kayak recommendation, 12% visited Kayak and 3.4% visited Skyscanner. These are reported observations from an opted-in desktop panel, not proof that every recommendation will produce the same effect in other audiences or categories.

    The more consequential measurement finding is where those visits appeared. Similarweb reportedly attributed 55.9% of AI-influenced visits to search, versus 40.4% of non-AI-influenced visits. Direct traffic accounted for 19.9% of AI-influenced visits and 38.8% of standard visits. If a user learns about a brand in ChatGPT and later searches for it, a conventional last-touch view can credit search while overlooking the conversation that formed the preference.

    The study also reported deeper activity among AI-influenced visitors: averages of 12 pages and 11.8 minutes on site, compared with 6.5 pages and 5.6 minutes for other visitors. That pattern is consistent with users reaching the website after narrowing their options, although it does not by itself establish why they engaged more deeply.

    A practical operating model joins content, evidence, and measurement

    A useful program begins by separating opportunity from performance. Organic keyword coverage shows where a brand is discoverable. AI Overview incidence shows where generated answers can mediate that discovery. Citation inclusion shows whether the brand’s material is selected. Recommendation monitoring asks whether the brand enters consideration. Branded search, site engagement, qualified actions, and sales outcomes then help reveal downstream demand.

    Build the evidence layer before chasing mentions

    The shared foundation across the sources is content that both people and machines can interpret. Pages should answer a defined buyer question promptly, explain relevant concepts precisely, and make important claims easy to evaluate. Related pages should collectively demonstrate depth rather than repeat a shallow definition. Earned media and corroborating information can complement first-party material by strengthening the wider evidence available about the brand.

    The assistive-agent framework reported by Search Engine Land places this work above, rather than in place of, SEO. In that model, search supplies crawled and indexed information, assistive systems add language-model reasoning and corroboration, and agents can eventually interact with business systems. This is a conceptual framework, not a measured result, but it clarifies why technical accessibility, entity understanding, and accurate business data belong in the same plan as editorial quality.

    Audit the questions closest to a decision

    Broad awareness coverage can reveal demand, but recommendation visibility becomes especially important when buyers compare providers, test suitability, or seek a shortlist. An audit should examine what an AI answer says, which sources it cites, whether the brand appears, how it is characterized, and which competitors receive stronger treatment. Because AI answers may vary, repeated observation is more informative than treating one response as a permanent ranking.

    Measure influence without forcing false precision

    AI referral traffic remains useful, but it should not be treated as the full contribution of AI discovery. Teams can examine changes in branded search, direct visits, engaged sessions, assisted conversions, and customer-reported discovery alongside citation and recommendation monitoring. None is a perfect substitute for controlled attribution; together, they can expose demand that a referral-only dashboard would miss.

    Key takeaways

    • Organic rankings create discoverability, but they do not guarantee inclusion in an AI-generated answer.
    • AI citations, brand recommendations, website visits, and transactions are different stages and require different measures.
    • Clear answers, topical depth, structured information, and corroborating authority form the content foundation described across the sources.
    • AI-influenced demand may later appear as search traffic, so referral analytics alone can understate AI’s role.
    • Category-level AI exposure should shape priorities because the incidence of generated answers and citation rates can differ substantially.

    As more discovery and evaluation move into generated answers, the defensible advantage will come from connecting machine-readable evidence with trustworthy buyer experiences. The next step is not merely to seek more AI mentions, but to learn which questions create recommendations and whether the business is prepared to convert the demand they produce.

    References

  • Cross-Channel Acquisition: Budget Depth and True Incrementality

    Cross-Channel Acquisition: Budget Depth and True Incrementality

    Cross-channel customer acquisition is not simply a matter of adding more platforms. It requires two linked decisions: how much funding each channel needs before it can be judged fairly, and whether the customers credited to that channel are genuinely new.

    The source articles examine different sides of this problem. One warns that an undersized test can make a viable channel appear inefficient; the other warns that overlapping platform attribution can make acquisition appear more profitable than it is. Together, they point to a more disciplined way to allocate budgets and evaluate incremental growth.

    Key takeaways

    • Channel tests should reflect the expected response curve; a small trial is not equally informative for every channel.
    • Demand-capturing and demand-creating channels serve different roles and should not be evaluated with identical expectations.
    • Platform-reported conversions can overlap, particularly when customers encounter paid social and Performance Max during the same journey.
    • Budget allocation should combine marginal efficiency with evidence that spending is attracting net-new customers.

    Budget breadth depends on the channel’s response curve

    Three differently shaped waterways require varying amounts of flow before reaching productive garden plots.

    A common allocation rule is to test many channels with modest budgets and move money toward the apparent winners. The channel-strategy source argues that this approach works only when the underlying response to spend supports it.

    The article distinguishes between C-shaped and S-shaped response curves. With a C-shaped curve, the first increment of spending produces the highest marginal return, and each additional increment becomes less productive. That pattern favors breadth: several lightly funded channels may collectively produce more than concentrating the same budget in one place.

    An S-shaped curve behaves differently. Early spending can be inefficient, returns improve as the campaign approaches an inflection point, and performance eventually reaches saturation. Under that pattern, a small test may measure only the channel’s learning or warm-up phase. The article therefore argues that the choice is often binary: commit enough to reach a viable operating level or do not fund the channel yet.

    The source illustrates the risk with a hypothetical campaign targeting a $50 cost per acquisition. It reports that a $10,000 test could appear unsuccessful even though performance might become more efficient between $20,000 and $25,000. Those figures are an illustration from the source, not a universal threshold. The broader lesson is that a test budget must be large enough to evaluate the part of the curve that matters.

    This distinction becomes especially relevant for automated campaigns. The channel-strategy article reports that AI Max needs sufficient conversion data to learn effectively and that Performance Max can combine response patterns in ways that make early headline results difficult to interpret. A cross-channel plan should therefore document not only how much will be spent, but also why that amount is expected to produce a meaningful test.

    Demand creation and demand capture need different expectations

    Response curves become easier to interpret when channels are classified by their role in the customer journey. The channel-strategy source describes this as a distinction between harvesting existing demand and creating new demand.

    Branded search is given as an example of harvesting demand. It can capture people who already know the brand, producing strong initial efficiency but saturating quickly. Meta and YouTube are presented as examples of channels that can help create demand. Those channels may require more sustained investment before their incremental contribution becomes visible.

    This does not make demand capture less valuable. It means that its reported efficiency answers a narrower question: how effectively did the channel convert demand that was already present? A demand-creation channel is being asked to influence a larger population, generate consideration, and contribute to later conversions that another platform may ultimately claim.

    Cross-channel comparisons become misleading when every campaign is ranked solely by its platform-reported cost per acquisition. A capture channel may look superior because it receives credit near the end of the journey, while the channel that introduced the customer appears less efficient. Portfolio decisions should account for each channel’s intended job before treating its dashboard result as a verdict.

    Net-new measurement must account for overlapping credit

    Colored beams overlap across a crowd while a separate overhead light isolates people reached incrementally.

    The Performance Max source focuses on a related measurement problem: customers can move between paid social and paid search while multiple platforms claim the resulting conversion. It specifically warns that Performance Max can recycle traffic generated through Meta, causing both environments to report success for sales they did not independently produce.

    The sales are still real, but duplicated credit can understate their effective acquisition cost. If a business evaluates each platform in isolation, it may add together conversion totals that refer to overlapping customers or assume that customers influenced elsewhere were acquired entirely by the final reporting platform.

    The Performance Max article proposes a four-step framework intended to focus campaigns on genuine new customers. Although the supplied source does not enumerate all four steps, it identifies its principal controls: brand exclusions, audience exclusions, and Customer Match data. According to the article, these measures can reduce the extent to which Performance Max targets branded demand, known customers, or already-warm audiences.

    These controls address a different question from response-curve analysis. Response curves ask whether a channel received enough investment to demonstrate its potential. Exclusions and first-party customer data ask whether the resulting conversions represent the intended audience. Both checks are necessary: a sufficiently funded campaign can still harvest existing demand, while a tightly excluded campaign can still fail because its budget never passes the learning threshold.

    A practical decision framework for channel investment

    A useful acquisition plan starts by defining the outcome as net-new customers rather than platform-attributed conversions. First-party customer records can establish who is already known, while brand and audience exclusions can help align campaign delivery with that definition. The Performance Max source presents Customer Match as one mechanism for applying this distinction.

    Each prospective channel should then be assigned a role: capturing existing intent, creating demand, or supporting both. That classification shapes the evidence expected from the test. Fast conversion efficiency may be a reasonable signal for a harvest channel, whereas a demand-creation campaign may need a longer learning period and broader evaluation across the acquisition system.

    The test budget should be based on a response-curve hypothesis rather than divided equally by default. If a channel is expected to show diminishing returns immediately, a small initial allocation can be informative. If it is expected to have an S-shaped response, management should identify a minimum viable commitment and decide whether the available budget can support it. Funding below that level may produce data without producing a fair test.

    Evaluation should finally compare platform results with the blended economics of the portfolio. A channel deserves additional investment when the evidence supports both adequate marginal performance and incremental customer growth. If platform metrics improve while net-new acquisition does not, the likely issue is not necessarily creative or bidding performance; it may be duplicated credit, branded-demand capture, or movement of the same customers among channels.

    As automated campaigns assume more responsibility for targeting and optimization, disciplined test design and customer-level measurement will become more important. The strongest cross-channel strategies will treat budget sufficiency and incrementality as joint requirements, using platform dashboards as inputs rather than final answers.

    References

  • A Practical SEO Performance and ROI Framework for AI Search

    A Practical SEO Performance and ROI Framework for AI Search

    SEO performance can no longer be judged reliably by rankings, organic sessions, or last-click conversions alone. Buyers may discover a category in search, compare brands on marketplaces or review sites, encounter an AI-generated summary, and convert through another channel.

    A more useful strategy connects three questions: whether the brand participates in discovery, whether its value is represented accurately, and whether that visibility creates durable commercial momentum. ROI measurement can then distinguish growth, protected revenue, assisted influence, and cross-channel value without assigning SEO credit it did not earn.

    Diagnose the constraint before choosing SEO metrics

    A performance dashboard is only useful when its metrics correspond to the problem the organization needs to solve. CrushPress.AI’s article on three search-performance questions organizes that diagnosis around presence, understanding, and compounding momentum. This framework shifts attention from isolated channel outputs to the buyer’s path from initial exploration to eventual preference.

    Presence: does the brand enter the consideration set?

    Presence concerns the places where demand forms, including non-brand search results, review sites, marketplaces, creator content, social platforms, AI assistants, and private communities. A business can convert existing brand-aware demand efficiently while remaining largely absent from earlier category exploration.

    The source says this distinction emerged from tracking nearly 200 brands for a year. It uses travel as an example of a category in which people often explore before selecting a provider. The strategic metric is therefore not merely conversion rate but the share of relevant discovery moments in which the brand appears.

    Understanding: is the market receiving the intended message?

    Visibility creates an opportunity, not necessarily an advantage. Search results, advertisements, reviews, product listings, and AI summaries can describe the same business differently. Performance analysis should examine whether those representations consistently communicate what the brand offers, whom it serves, and why it should be trusted.

    The source reports that AI-originated visits can be smaller in volume but more valuable when the brand is portrayed accurately. It also reports different relationships between AI visibility and market share across industries: positive in fashion but potentially counterproductive in finance. These observations should be treated as source-reported findings rather than universal benchmarks. They reinforce the need to assess message quality and business outcomes by category instead of assuming that more AI exposure is always beneficial.

    Momentum: is performance becoming easier to sustain?

    Compounding performance appears when earlier investments continue to create demand and trust. The source identifies growing branded search without proportionate spending, increasing direct traffic, and content that keeps attracting new visitors as possible indicators. Rising paid dependency alongside weakening organic demand suggests the opposite: each sale must continually be purchased rather than supported by accumulated visibility and reputation.

    These three constraints imply different responses. Weak presence calls for broader discovery coverage. Weak understanding calls for clearer and more consistent evidence. Weak momentum calls for assets and distribution that continue producing value after the initial campaign.

    Build a measurement system around the buyer journey

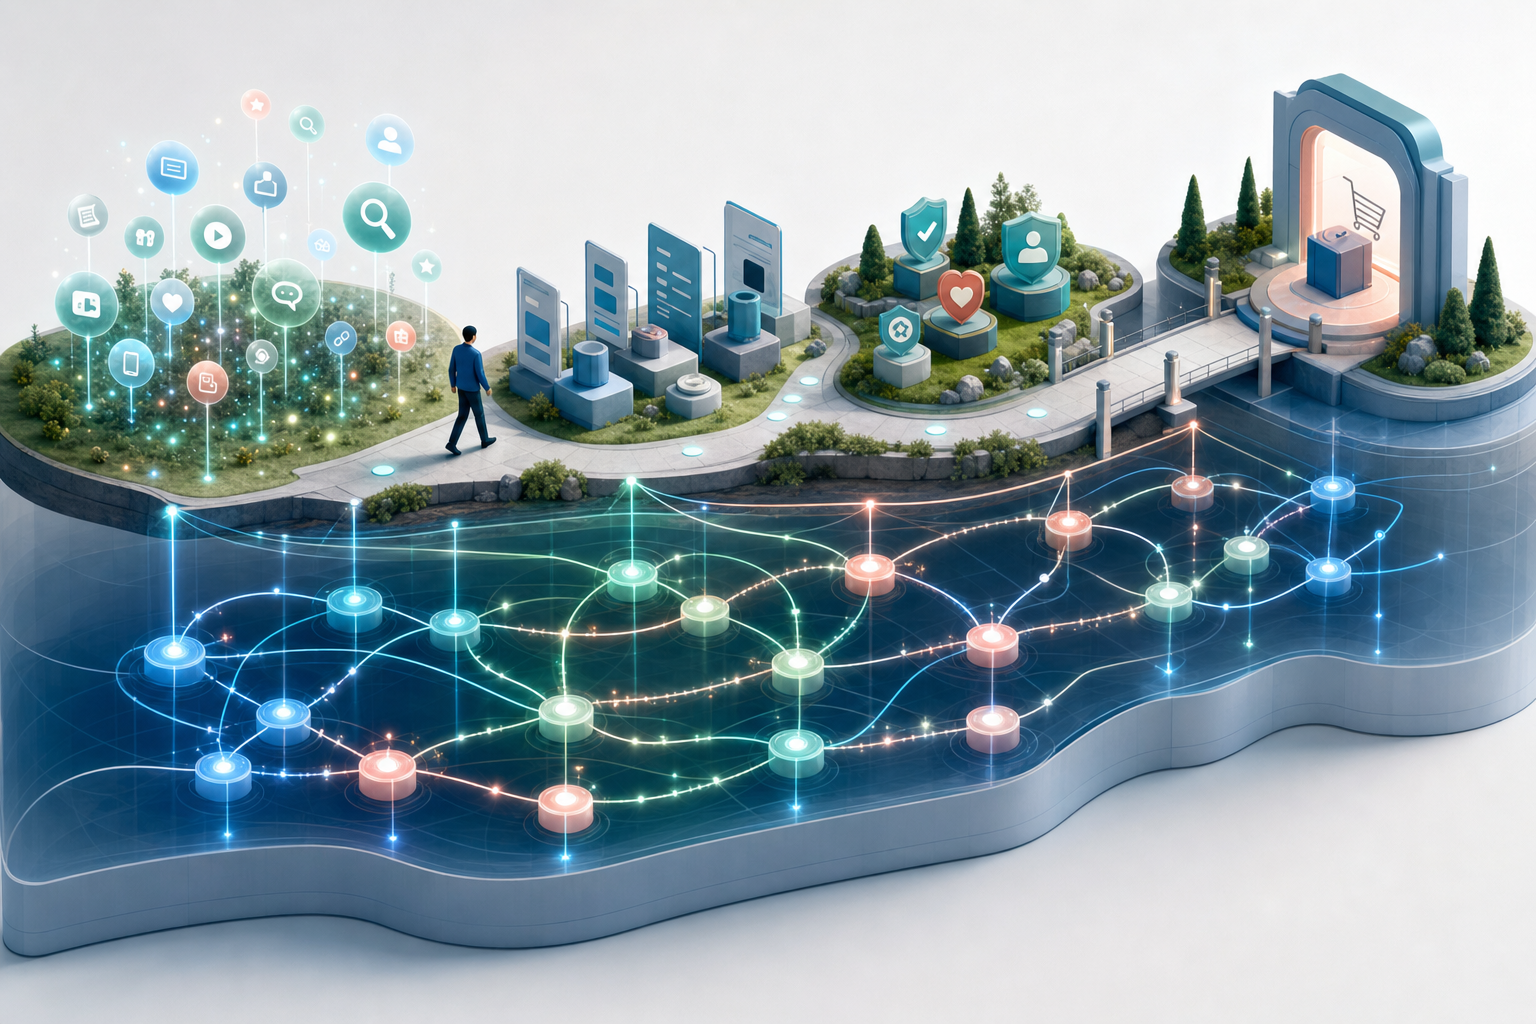
    Isometric illustration of a buyer moving through discovery, comparison, trust, and purchase stages above a connected layer of measurement nodes.

    The diagnostic framework becomes actionable when each stage has its own evidence. No single metric can represent the entire journey, and not every signal should be converted immediately into revenue.

    • Discovery evidence: non-brand visibility, coverage of relevant questions, appearances in comparison environments, and the balance between branded and non-branded search demand.
    • Representation evidence: consistency across owned pages, search snippets, reviews, advertising, marketplace listings, and AI-generated descriptions.
    • Commercial evidence: qualified conversions, revenue, assisted conversion credit, and the downstream use of SEO-created assets.
    • Compounding evidence: durable content performance, direct demand, branded search development, and the degree to which paid media must support each additional sale.

    This layered approach also prevents a common diagnostic error. Strong branded conversion does not prove that SEO is winning new demand; it may show that the site captures people who already know the company. Conversely, flat click growth does not automatically prove that search work has no value if the brand is gaining exposure in zero-click results or protecting revenue that could otherwise decline.

    Measurement should therefore begin with segmentation. Brand and non-brand search data answer different questions. New and returning audiences should not be interpreted identically. Discovery pages, comparison pages, and conversion pages have different jobs, so evaluating all of them against the same last-click target obscures how the system works.

    Expand SEO ROI without inflating attribution

    Four colored light streams pass through separate transparent channels into a balanced circular reservoir beside a precision scale and interlocking rings.

    The conventional calculation remains a useful executive summary:

    SEO ROI = ((incremental organic revenue – SEO costs) / SEO costs) x 100

    CrushPress.AI’s ROI article argues that this formula is incomplete in an environment where AI answers and zero-click results can separate visibility from site visits. The source reports that 60% of searches end without a click and characterizes SEO as both a growth investment and a defense of existing organic revenue. Because that percentage is reported by the source and not independently verified here, it should not be treated as a universal planning constant.

    Credit retained revenue conservatively

    Giving SEO credit for every organic sale would overstate its contribution, especially when public relations, advertising, word of mouth, or established brand demand generated the visit. The source proposes separating branded and non-branded clicks with Google Search Console data and applying different attribution weights.

    Its illustrative case assumes that 70% of traffic is branded and 30% is non-branded, gives branded traffic a 10% SEO weight and non-branded traffic a 100% weight, and produces a blended weight of 37%. Applied to $100,000 in monthly organic revenue, that example credits $37,000 to SEO. These figures demonstrate a method, not a standard weighting scheme. An organization should document its own assumptions and test how the result changes under more conservative and more generous scenarios.

    Include assists and early-stage influence

    Last-click reporting undervalues organic discovery when another channel completes the transaction. The ROI source points to GA4’s data-driven attribution as one way to inspect fractional contribution. In its example, 1,345.69 units of early-stage credit and 687.34 units of mid-journey credit total 2,033.03; at an illustrative value of $100 each, the attributed revenue is $203,303.

    Assisted value should be reported separately from organic last-click revenue. That separation gives decision-makers a broader view while preventing the same conversion from being presented as multiple independent sales.

    Track the value SEO assets create in other channels

    Research, landing pages, articles, and refreshed product information may later support paid campaigns, sales outreach, or other distribution. The source describes a client example involving 29 calls and five qualified leads after new articles and updates, while caution is warranted because the material provided does not establish that SEO alone caused those outcomes.

    Its separate calculation attributes $2,500 to SEO when 500 paid-search conversions worth $100 each include a 5% contribution from SEO pages. As with the brand-weighting example, the percentage is an assumption that must be disclosed. A defensible process records which assets were reused, where they appeared, what outcome followed, and how attribution was divided among participating teams.

    The resulting ROI narrative should retain separate lines for direct organic revenue, conservatively weighted retained revenue, assisted conversion value, and cross-channel asset contribution. A final roll-up can be useful, but preserving the components makes the model auditable and exposes overlapping claims.

    Make continuous learning part of performance management

    Better measurement cannot compensate for a strategy built on obsolete assumptions. CrushPress.AI’s continuous-learning article reports that platform changes, automation, AI-driven search features, zero-click experiences, and changing user behavior can make previously effective practices unreliable. It notes examples of strategies from 18 months earlier working against performance and says an approach effective six months earlier may already be obsolete. Those time frames are presented as the source’s observations, not fixed expiration dates for every SEO practice.

    The operational lesson is to treat learning as part of the performance system rather than as occasional professional development. AI may accelerate execution, but interpretation, prioritization, and judgment still determine whether teams pursue the right constraint and read results correctly.

    1. State the constraint. Define whether the current problem is presence, understanding, commercial contribution, or compounding momentum.
    2. Record the hypothesis. Specify what should change, for which audience or query group, and which leading and commercial signals would support the decision.
    3. Run a bounded test. Keep the scope clear enough to distinguish the intervention from unrelated brand, product, or media activity.
    4. Review evidence across channels. Examine discovery, representation, conversion, and assist data rather than relying on one dashboard.
    5. Update the operating assumption. Preserve what was learned, including failed tests and changes in platforms or user behavior, so outdated tactics are less likely to be repeated.

    This cadence links the three source perspectives. The diagnostic questions identify what is limiting performance, the attribution model estimates commercial value, and continuous learning keeps both the strategy and the model responsive to changes in search.

    Key takeaways

    • SEO performance should be evaluated across discovery presence, accurate brand representation, commercial contribution, and compounding demand.
    • Branded and non-branded search require separate interpretation because strong branded conversion can conceal weak category discovery.
    • A broader ROI model can include retained revenue, assisted conversions, and cross-channel content value, but every weighting assumption should be explicit and auditable.
    • Visibility metrics and revenue metrics serve different purposes; connecting them is more informative than forcing every early signal into a revenue claim.
    • Testing and shared learning are operating requirements when AI features, platforms, and user behavior keep changing.

    The next generation of SEO reporting will be strongest when it explains not only what changed, but where demand was won, how the brand was interpreted, what value was protected, and which investments are becoming more productive over time.

    References

  • Microsoft and Google Ads Updates Shift Control and Measurement

    Microsoft and Google Ads Updates Shift Control and Measurement

    Two advertising-platform updates are changing different parts of campaign management: Microsoft is adding professional seniority as an audience signal, while Google is changing how certain impression-influenced Demand Gen activity is billed.

    Together, the changes illustrate a broader operating challenge for advertisers. More precise controls can improve campaign decisions, but only when targeting, optimization, billing and measurement remain aligned with the business outcome.

    Microsoft adds a professional-identity layer to targeting

    Anonymous professionals stand on tiered platforms while a targeting beam selects levels of seniority.

    CrushPress.AI’s Microsoft Ads report says LinkedIn Profile targeting now includes job seniority for Search and Audience campaigns. Advertisers can reportedly select from 10 levels, ranging from CXO to Volunteer, and apply the setting at either the campaign or ad-group level.

    The practical value is not merely narrower reach. Seniority can help distinguish people who may approve a purchase from those who influence, evaluate or use it. A B2B advertiser could therefore separate executive-oriented messaging about organizational outcomes from practitioner-oriented messaging about operational efficiency.

    The report also says the seniority filters can be used in observation mode. That gives advertisers a lower-risk way to examine performance by professional level without initially restricting delivery. Availability was reported for selected markets across the Americas, EMEA and APAC, so account-level access should be confirmed before campaign plans depend on the feature.

    Google ties some Demand Gen charges to impressions

    Generic ad cards pass through an eye-shaped impression sensor and feed tokens into a billing scale.

    CrushPress.AI’s Google Ads report describes a different kind of change. From July 15, Demand Gen campaigns on Discover using view-through conversion optimization are reportedly moving from cost-per-click billing to cost-per-thousand-impressions billing. The transition is described as automatic and limited to campaigns with that optimization enabled.

    The reported rationale is alignment: a view-through conversion credits an impression that precedes a later conversion even when the user does not click the ad, so impression-based billing more closely matches the behavior being optimized. Advertisers that do not want the new billing treatment can reportedly disable view-through conversion optimization.

    The updates affect different campaign levers

    Microsoft’s update changes audience interpretation: it offers another signal for deciding who should see an ad, how much that audience may be worth and which message it should receive. Google’s update changes the economic frame: advertisers using the affected optimization will pay according to exposure rather than clicks.

    That distinction matters when comparing results across platforms. A Microsoft segment may appear valuable because it identifies a strategically important professional group, even if its immediate conversion volume is modest. A Google campaign may generate more billable impressions without a corresponding rise in clicks, even while the system is pursuing view-through outcomes. Neither pattern can be interpreted responsibly through a click-only dashboard.

    The common requirement is measurement discipline. Audience quality, conversion value, impression volume, click activity and attributed conversions answer different questions. Platform settings determine which of those signals influence delivery and cost, while the advertiser must decide whether they represent meaningful business progress.

    Key takeaways

    • Microsoft’s reported seniority targeting can support separate bids, messages and analysis for decision-makers, influencers and practitioners.
    • Observation mode offers a way to assess seniority performance before using the signal to limit Microsoft Ads reach.
    • Google’s reported CPM transition applies to Discover Demand Gen campaigns using view-through conversion optimization, not every Demand Gen campaign.
    • Advertisers evaluating the Google change should track spend and impression movement alongside clicks, attributed conversions and downstream business results.
    • Cross-platform reporting should distinguish an audience-targeting change from a billing change instead of treating both as ordinary performance fluctuations.

    What advertisers should watch next

    Microsoft advertisers can begin with observation data and look for durable differences in lead quality before segmenting budgets aggressively. Google advertisers affected by the billing transition should document their pre-change delivery and cost patterns, then assess whether view-through optimization continues to fit their attribution standards and campaign purpose.

    As platforms connect campaign objectives more tightly to audience signals and charging models, account teams will need to review settings as strategic choices rather than background configuration. The most useful next step is to establish which business outcome each setting is meant to improve before the resulting platform metrics begin to move.

    References

  • Why Better PPC Bidding Still Depends on Conversion Quality

    Why Better PPC Bidding Still Depends on Conversion Quality

    PPC bidding can determine which auctions an advertiser enters and how aggressively a campaign pursues demand. It cannot, by itself, determine whether a click becomes a qualified lead, a signed client, or profitable revenue.

    Taken together, the two source reports point to a more useful way to evaluate bidding: connect auction-time optimization with search intent, landing-page relevance, operational follow-up, and closed-loop measurement. That makes it possible to distinguish genuine growth from a larger volume of inexpensive but low-value conversions.

    Key takeaways

    • Automated bidding can explore additional demand, but its value depends on whether the campaign optimizes toward conversions that reflect business outcomes.
    • CPA and ROAS targets are operating controls, not complete measures of performance; qualified leads, signed cases, and revenue provide essential context.
    • Temporary bidding and budget changes can help capture peak demand when they are paired with sufficient fulfillment or intake capacity.
    • Search-term reviews, intent-specific landing pages, CRM outcomes, and offline conversion data give bidding systems more meaningful signals.
    • Budget allocation should follow marginal business value rather than lead volume alone.

    Why efficient bidding can still produce weak business results

    A platform can lower the reported cost per conversion while the underlying economics deteriorate. This happens when the conversion being optimized is too far removed from the outcome the advertiser actually values. A form submission, for example, may be easy to generate but may say little about qualification, purchase intent, or eventual revenue.

    The law-firm PPC source illustrates the problem through the difference between leads and signed retainers. It argues that cost per lead alone leaves out the intake process, response speed, qualification, and the rate at which qualified prospects become clients. Its recommended reporting chain extends from ad spend and leads through qualified leads, signed cases, CPL, and CPA, segmented by channel and practice area.

    That distinction also changes how an advertiser should interpret automated bidding. Google’s Smart Bidding Exploration update, as described in the other source, lets advertisers specify a ROAS tolerance so campaigns can pursue conversion opportunities beyond queries they might otherwise reach. The source reports that campaigns using the capability saw about an 18% increase in unique converting search-query categories and a 19% increase in conversions. Those are platform-reported expansion indicators; they do not establish that every additional conversion carried the same downstream value.

    The practical question is therefore not simply whether bidding found more conversions. It is whether the incremental conversions remained qualified and profitable after the full customer journey was considered.

    Conversion quality is built before and after the auction

    An auction gateway connects search-intent pathways on one side with a landing experience, human follow-up, and a business handshake on the other.

    Better outcome data begins with the query. The law-firm source recommends reverse-engineering keyword strategy from call transcripts and CRM records rather than beginning with broad, generic terms. It also advocates segmenting keywords and campaigns by intent, funnel stage, budget, and conversion objective, with weekly search-term reviews used to identify valuable language and exclude irrelevant demand.

    This creates an important complement to bidding automation. The algorithm decides among available opportunities, while campaign structure defines which opportunities are grouped together and which outcome signals they share. If high-intent and exploratory traffic are mixed under one target, an aggregate CPA can conceal substantial differences in lead quality.

    Landing pages provide the next quality filter. The law-firm report calls for alignment between the searcher’s intent and the page headline, supporting proof, fast mobile performance, and immediate contact options. It reports that replacing a generic page with intent-specific pages, recent reviews and results, and fewer form fields doubled one client’s conversion rate without additional ad spend. Because this is a single account example reported by the source, it should be treated as illustrative rather than a universal expectation.

    Post-contact operations complete the chain. The same source recommends a response time below 60 seconds, an answer rate above 90%, and a signed rate of 25% to 40% among qualified leads for the law-firm context. These are the source’s operational targets, not general benchmarks for every industry. Their broader significance is that slow or inconsistent follow-up can erase gains produced by bidding and landing-page optimization.

    Use automated expansion and peak bidding with guardrails

    Google’s reported updates introduce two distinct bidding use cases. Smart Bidding Exploration is intended to uncover incremental demand while allowing a degree of ROAS flexibility. Promotion Mode, described as a beta in the source, is designed for temporary changes to ROAS targets and daily budgets around seasonal events, product launches, and flash sales. The source also says Exploration was extended to Performance Max campaigns without product feeds and was being tested for Shopping ads in Performance Max and Standard Shopping campaigns.

    Exploration should be judged as a controlled expansion test. Advertisers need to compare the new query categories with established traffic on qualified-conversion rate, acquisition cost at the final outcome, and revenue contribution. Search-term analysis remains relevant even when automation broadens reach because it can reveal whether incremental volume represents new high-intent demand or merely looser matching.

    Promotion-oriented bidding requires a different guardrail: operational readiness. Raising a daily budget and relaxing a ROAS target may generate more opportunities during a short demand window, but the extra volume only has value if inventory, sales, intake, and customer service can process it. Temporary settings should also have a defined end point so an exceptional trading period does not quietly become the campaign’s permanent efficiency standard.

    For campaigns constrained by budget, the Smart Bidding source also reports a change intended to produce more consistent performance against CPA and ROAS targets. Consistency can make planning easier, but a target should not be treated as proof of profitability. Budget decisions still need to account for the quality and economic value of the outcomes being purchased.

    Build a measurement loop that bidding can learn from

    A circular system links an ad auction, webpage, customer conversation, agreement, and revenue, with outcome signals flowing back to the auction.

    A reliable PPC system connects UTMs, call tracking, website analytics, CRM stages, and final outcomes. The law-firm source specifically points to Google Analytics and CRMs such as Lawmatics or Clio as parts of that chain. Its emphasis is not the choice of software, but the ability to trace a click through qualification and retention rather than ending reporting at the ad platform.

    That closed loop supports better decisions at three levels. Search terms and landing pages can be evaluated by the quality they produce. Campaign targets can be based on downstream value instead of superficial conversion volume. Budgets can then move toward the channels, practice areas, or intent groups that contribute the strongest business outcomes.

    The law-firm source also recommends Marketing Efficiency Ratio as an ecosystem-level measure rather than evaluating every channel in isolation. Used alongside channel-level CPL, CPA, qualified-lead rates, and signed outcomes, it can help distinguish the contribution of the overall marketing mix from the performance reported inside a single platform.

    The next stage of PPC optimization is therefore less about choosing between automation and manual control than about improving the feedback connecting them. Advertisers that define valuable conversions, preserve intent distinctions, and return verified outcomes to the campaign will be better positioned to use bidding expansion without losing sight of profitability.

    References

  • Paid Media Diagnostics: From Clean Data to Catalog Health

    Paid Media Diagnostics: From Clean Data to Catalog Health

    A weak paid media result can originate in several places: the reporting may be misleading, an advertised item may be unable to serve, or eligible inventory may simply be underperforming. Treating every symptom as an optimization problem risks changing bids, budgets, or creative before the underlying fault is known.

    Recent reporting on Google Analytics source controls and Microsoft Ads catalog diagnostics points to a more disciplined approach. Measurement integrity should be checked first, delivery eligibility second, and performance efficiency only after both foundations are credible.

    A diagnostic sequence for separating symptoms from causes

    The two source reports address different parts of the paid media system. The Google Analytics changes concern how traffic is classified and which domains contribute events to reporting. Microsoft Ads Product Explorer concerns whether catalog items are eligible, sufficiently described, and producing results. Together, they support a layered diagnostic model rather than a single dashboard verdict.

    Diagnostic questionLayer under reviewRelevant evidenceDecision it informs
    Can the reported traffic be trusted?Measurement integritySource classification and hostname provenanceWhether channel comparisons are reliable enough to guide budget decisions
    Could the advertised products serve?Delivery eligibilityCatalog status, required metadata, and identified feed issuesWhether reach is constrained before bidding or creative can have an effect
    How did eligible inventory perform?Performance efficiencyProduct-level results and consistently classified conversion trafficWhich items or channels warrant optimization, expansion, or closer investigation

    This sequence matters because similar symptoms can have unrelated causes. A channel can appear fragmented when one platform is recorded under several source names. A product can show no meaningful activity because it is not eligible to serve. Only after those possibilities are addressed does an efficiency diagnosis become well grounded.

    Clean attribution before comparing channel performance

    Tangled digital signals pass through a transparent filter and emerge as clean, distinct data streams.

    The Google Analytics source reported that a new Source Group reporting dimension consolidates variations of the same traffic source. Its example groups labels such as “facebook” and “fb” into one recognizable value. It also reported improvements to the Source Platform field intended to make classifications more consistent across advertising channels.

    For paid media diagnostics, that standardization reduces a common analytical distortion: one platform appearing as several small sources while another appears as a single consolidated source. The report said the structure extends beyond Google properties to platforms including TikTok, Pinterest, and Amazon, while also accounting for AI-originated traffic such as ChatGPT and Perplexity. It further said source-group information is available retroactively for historical analysis.

    Source consolidation does not resolve every attribution limitation. It makes labels more coherent, but a consistently named source is not automatically proof that the source caused a conversion. Analysts still need to distinguish reporting consistency from causal measurement and apply the same attribution interpretation when comparing channels.

    The reported hostname filters address a separate trust issue. According to the Google Analytics source, administrators can exclude events from unapproved domains before those events enter reporting. This can help prevent traffic associated with unexpected hosts from influencing campaign analysis. The practical control is to document which domains are legitimate before filtering; otherwise, an overly narrow approval set could remove activity that should have remained visible.

    Check catalog eligibility before optimizing retail campaigns

    Generic retail products move through eligibility checkpoints while a few incomplete or unavailable items are diverted for inspection.

    Microsoft Ads Product Explorer moves the investigation from attribution to inventory readiness. The Microsoft-focused source described a searchable catalog interface with filters for SKU, title, GTIN, and product ID. It reportedly surfaces eligibility problems, metadata gaps, and other conditions that may stop products from serving, while providing recommended actions and exportable filtered product lists.

    This changes how low delivery should be interpreted. If a product is ineligible or lacks necessary feed information, adjusting campaign-level settings does not address the immediate constraint. Catalog remediation comes first. Once an item is active and capable of serving, its advertising results can be evaluated as a performance issue rather than confused with a feed-health issue.

    The source also reported product-level performance visibility covering the previous 30 days. That window can connect operational diagnostics with observed activity: advertisers can distinguish products blocked by catalog problems from active items receiving exposure or producing results. The report stated that Product Explorer was live in advertiser accounts, although the source did not independently test its coverage or recommendations.

    Turn cleaner evidence into better optimization decisions

    The strongest synthesis is not a new all-in-one metric. It is a division of diagnostic responsibilities. Analytics source controls help establish whether cross-channel reports are internally coherent. Catalog tools help establish whether retail inventory can participate in the auction. Performance analysis then assesses what happened among the traffic and products that survived those checks.

    That separation also clarifies ownership. Measurement anomalies belong with analytics governance; product eligibility and metadata gaps belong with feed operations; efficiency questions belong with campaign management. Teams can still investigate collaboratively, but each finding should be routed to the layer capable of correcting it.

    A defensible performance review should therefore record both the result and the conditions under which it was observed. Channel comparisons should note whether source grouping and hostname controls were reviewed. Retail conclusions should note whether the relevant products were eligible and whether catalog issues were present. This creates an audit trail that makes later changes in reported performance easier to interpret.

    Key takeaways

    • Validate source classification and domain provenance before moving budget based on cross-channel reports.
    • Treat source standardization as a reporting improvement, not as proof of causal attribution.
    • For retail advertising, resolve eligibility and metadata problems before diagnosing low delivery as a bidding or creative failure.
    • Evaluate product and campaign efficiency only after measurement integrity and serving readiness have been checked.

    As advertising platforms automate more campaign execution, diagnostic discipline becomes more important, not less. The next useful advance will be a repeatable review process that connects trustworthy measurement, servable inventory, and performance decisions without collapsing them into the same signal.

    References