Tag: Attribution Models

  • How to Measure AI Search Visibility Beyond Referral Traffic

    How to Measure AI Search Visibility Beyond Referral Traffic

    If your AI referral report shows a handful of visits, it is tempting to conclude that AI search does not matter yet. That conclusion may be wrong. The click is only the visible handoff; an AI-generated answer can teach the buyer, establish credible options, and shape the shortlist before anyone reaches your site.

    You need a measurement model that separates answer visibility, referral performance, and buyer influence. That distinction lets you protect the SEO traffic you already have, improve the quality of AI referrals, and judge crawler access with evidence instead of reacting to one traffic number.

    AI visibility has three separate outcomes
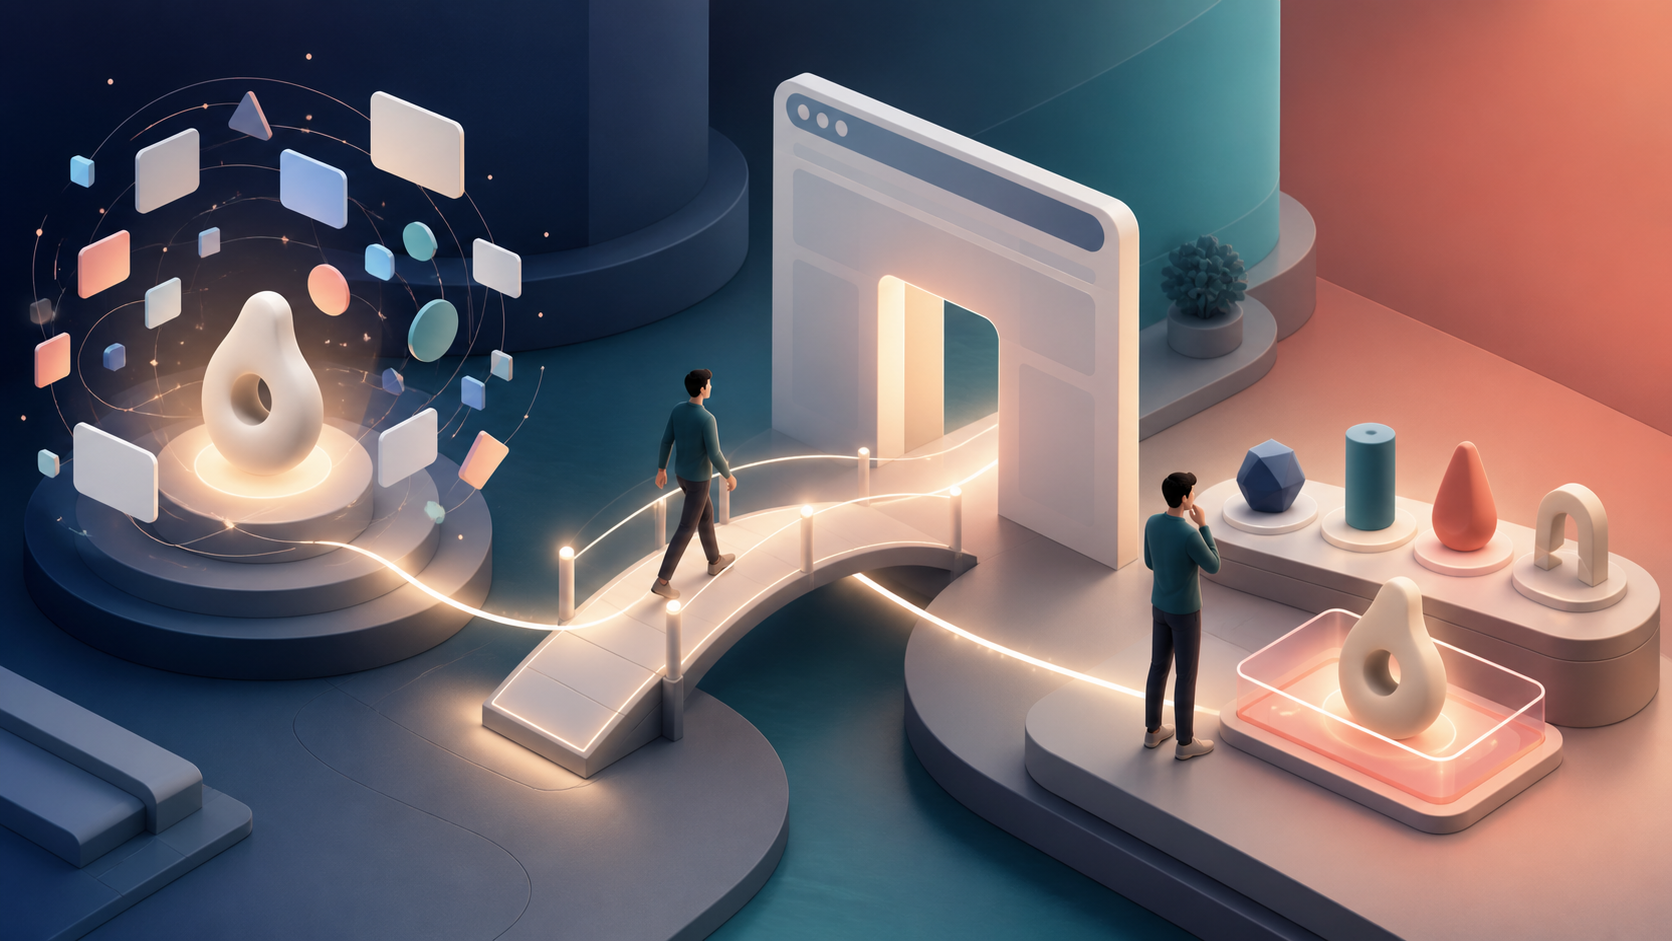
    Three connected scenes show an object appearing in an AI answer, a visitor entering a website, and a buyer choosing an option for a shortlist.

    A buyer can use an AI Overview or assistant to understand a category, compare approaches, identify evaluation criteria, and notice several brands. By the time that person clicks, a meaningful part of the consideration process may already have happened.

    That creates three outcomes you should measure independently:

    • Answer visibility: Does the AI surface name your brand, cite your page, or accurately represent your information for commercially relevant questions?
    • Referral performance: Do people who click from an AI platform engage, complete a meaningful action, become qualified leads, or buy?
    • Buyer influence: Does exposure inside an AI answer help your brand enter the shortlist, earn a later branded search, receive internal consideration, or make a subsequent ad or sales interaction more credible?

    Do not collapse these into a single metric called AI traffic. A cited page can influence a buyer without receiving the eventual visit. A referral can convert without the referring page having been cited consistently. A brand mention can also be inaccurate or unfavorable, which means raw visibility is not automatically valuable.

    Organic search still deserves its own line on the dashboard. During Shopify’s second quarter, AI-referred sessions to merchant storefronts rose 197% year over year while organic search traffic grew 12%. Organic still sent more traffic than all tracked AI platforms combined. The useful interpretation is not that one channel is replacing the other. AI referrals are growing quickly on a much smaller base while organic search remains the larger acquisition engine.

    Those figures are directional commerce evidence, not universal benchmarks. The number of merchants and transactions behind them was not disclosed, so you should not use 197% as a forecast or treat any conversion multiple as a target for your own site.

    Key takeaways

    • Keep investing in organic SEO; AI visibility currently adds another discovery surface rather than making search traffic irrelevant.
    • Track citations and brand mentions separately from AI-referred sessions because a buyer can be influenced before clicking.
    • Judge AI traffic by conversion, qualification, pipeline, and revenue, not by session count alone.
    • Expect the strongest referral quality where buyers need help comparing specifications, compatibility, evidence, or implementation details.
    • Keep visible product facts, structured data, and first-party catalog information consistent; explicit, reliable facts help both selection and conversion.
    • Use scrape-to-referral ratios as diagnostic evidence, not as an automatic rule for blocking or allowing a crawler.

    Measure the path from answer visibility to revenue
    An analyst examines linked objects representing an AI answer, source citations, a website visit, a shortlist, a sales conversation, and a purchase, with a separate crawler trail feeding into the evidence path.

    Your reporting should follow the buyer from the answer surface to the business outcome. No single system can capture that entire path, so give each tool a specific job.

    Create a repeatable AI visibility register

    Start with a fixed set of questions that represents the decisions your buyers actually make. Include problem-definition questions, comparisons, compatibility or implementation questions, evidence questions, and purchase-stage questions. Do not build the set entirely from high-volume keywords; a narrow question used by a serious buyer may matter more than a broad informational prompt.

    For each check, record:

    • The exact question and the AI platform or search surface.
    • The date of the check.
    • Whether your brand was named.
    • Whether your domain was cited and which URL was selected.
    • Which competitors appeared.
    • Your role in the answer: example, supporting authority, recommended option, alternative, or incidental mention.
    • Whether the description, product facts, and claims were accurate.
    • The buying stage represented by the question.

    Repeat the same checks on a consistent schedule. A single screenshot proves that an answer appeared once; it does not establish stable visibility. Track citation coverage as the share of monitored questions that cite your domain, but retain the underlying records so you can distinguish a valuable buying question from a low-value mention.

    Connect the visit to qualification and revenue

    Once a visitor reaches your site, web analytics becomes the operational record. GA4 acquisition reporting can separate traffic from AI assistants so you can compare it with organic, paid, direct, and other channels. Keep the operator-level referral detail as well; an aggregate AI channel can hide a small platform that sends unusually strong prospects.

    1. Separate acquisition: Build an AI-assistant view or channel grouping and retain source and referrer detail wherever it is available.
    2. Label landing-page intent: Group entry pages by research, comparison, implementation, product, pricing, or conversion intent. This reveals whether a platform sends early researchers or decision-ready visitors.
    3. Measure meaningful behavior: Track movement to relevant second pages, product exploration, sign-ups, purchases, consultation requests, form fills, and other events that correspond to an actual business outcome.
    4. Validate the journey: Use filtered session recordings to see whether visitors find the expected information, encounter friction, or leave after discovering that the page does not answer the question that brought them there.
    5. Pass attribution into the CRM: Preserve the original AI source, landing page, conversion action, and campaign context on the lead record. Web analytics can record a form submission, but the CRM must determine whether the lead became qualified, entered the pipeline, or produced revenue.
    6. Capture delayed influence: Add a short first-touch question to suitable lead forms and sales discovery notes. Options should let a buyer identify an AI assistant or AI-generated search answer without forcing that answer. Treat self-reported exposure as supporting evidence, not perfect causal proof.

    Use rates that answer different business questions:

    • AI referral conversion rate: meaningful conversions divided by AI-referred sessions.
    • Qualified lead rate: qualified AI-referred leads divided by all AI-referred leads.
    • Pipeline per session: sourced pipeline value divided by AI-referred sessions.
    • Revenue per session: closed revenue attributed to AI referrals divided by AI-referred sessions.
    • Citation coverage: monitored questions citing your domain divided by all monitored questions.
    • Accurate answer coverage: monitored questions that represent your brand correctly divided by all questions where the brand appears.

    The denominators matter. A platform with few visits can be commercially useful if those visits qualify at a high rate. A platform with many citations can still be weak if the citations occur on irrelevant questions or send visitors to a poor landing page.

    Buying intent also changes the comparison with organic search. In specification-heavy Shopify categories, AI-referred shoppers converted at roughly twice the rate of organic visitors. In broader, taste-driven categories, organic search remained the larger discovery channel. Segment your analysis by category and intent before declaring AI traffic better or worse than organic traffic overall.

    Use scrape-to-referral data as a diagnostic

    AI crawlers can request many pages while their associated platforms send relatively few identifiable visits. The scrape-to-referral ratio makes that imbalance visible:

    AI scrape-to-referral ratio = recorded AI scrape activity / recorded referral visits

    A lower ratio means more recorded referrals for each recorded scrape, but it does not automatically mean more business value. A high ratio may still be acceptable when the resulting visitors buy, become qualified opportunities, or when the platform contributes meaningful answer visibility. It may be unacceptable when crawling creates a material operational or content-use cost and produces no outcome connected to the site’s purpose.

    Microsoft Clarity’s AI Visibility Dashboard now includes an AI Scrape-to-Referral Ratio card, operator-level breakdowns, coverage safeguards, and direct access to filtered session recordings. Use that workflow in this order:

    1. Check domain coverage first. Confirm that bot activity and referral traffic are measured across the same mapped domains. A CDN, subdomain, or incomplete analytics deployment can create a misleading ratio.
    2. Split the total by operator. An account-wide average can conceal one operator that returns useful visits and another that crawls heavily with little visible return.
    3. Pair the ratio with outcomes. Compare referrals with engagement, purchases, sign-ups, form fills, qualified leads, and revenue.
    4. Inspect representative recordings. Determine whether AI-referred users reach the right page, scroll to the needed information, continue to a commercial page, or abandon the journey immediately.
    5. Compare the result with answer visibility. A platform may influence consideration without generating a directly attributed visit, so include monitored citations and brand mentions in the decision.
    6. Make operator-specific decisions. Keep monitoring useful operators, repair landing-page problems where referrals are poor, investigate coverage when the ratio looks implausible, and consider access restrictions only after confirming that the operator produces no sufficient direct or assisted value for your objectives.

    There is no universal good ratio. A publisher funded by page views, an ecommerce store, and a B2B company with a long sales cycle receive different value from the same number of referrals. Define the outcome you require before setting a threshold. Otherwise, the ratio becomes a precise-looking number attached to an undefined business decision.

    Optimize for selection, trust, and the next action

    Measurement tells you where the journey breaks. The content fix depends on whether you are missing from the answer, attracting the wrong visitor, or failing to help an informed buyer take the next step.

    For ecommerce, make comparison facts explicit

    AI referral quality is strongest when the assistant can help with a demanding decision: specifications, compatibility, alternatives, reviews, and other concrete buying criteria. Your product pages and first-party catalog should therefore agree on the facts a buyer needs to compare options.

    • Use the exact product and variant names consistently.
    • Expose identifiers, dimensions, technical specifications, compatibility, included components, price, and availability where they apply.
    • Explain the differences between variants in buyer language instead of relying only on internal model codes.
    • State limitations and exclusions close to the relevant claim.
    • Keep visible page content, JSON-LD, and first-party catalog values synchronized.
    • Do not fill structured-data fields with unsupported or stale values merely to make the markup look complete.

    JSON-LD can make a fact explicit, but it cannot resolve a contradiction between the page, the catalog, and the checkout. Consistency is part of optimization because the visitor must encounter the same product the AI answer described.

    The commercial effect can be substantial. In Shopify’s merchant data, AI-referred shoppers converted at twice the rate when AI systems used structured Shopify Catalog data rather than scraped or third-party product feeds. Because this is vendor-supplied observational evidence with an undisclosed sample size, use it as a reason to test and improve first-party data quality, not as a guaranteed uplift.

    For B2B, cover the whole decision rather than one keyword

    A B2B buyer rarely moves from a definition to a purchase in one step. Build a connected set of pages that answers how the solution works, who it is for, how approaches differ, what evidence supports the claims, how implementation fits an existing workflow, what training or support is available, and what a buyer should examine before investing.

    Each page should do four jobs: answer its primary question early, show the basis for the answer, state the important boundaries, and offer the next action that fits the buyer’s stage. A technical explainer should link naturally to a comparison or implementation page; a comparison page should make the commercial evaluation path clear without pretending that every reader is ready for a sales call.

    Continue monitoring traditional rankings and AI citations separately. A page can rank prominently without being selected as an AI supporting citation, while a cited page does not have to occupy the first organic position. The remedies are related but not identical: ranking work improves discoverability, while complete, direct, well-supported answers improve the chance that your information is useful within an AI response.

    Start with one revenue-relevant journey. List the questions a buyer asks from initial research through comparison, check where your brand and URLs appear, audit the matching pages and structured facts, separate AI referrals in analytics, and carry the source into the CRM. After enough time for your normal sales cycle to complete, compare citation coverage, referral quality, qualified pipeline, and reported first-touch influence. That gives you a defensible next investment instead of a guess based on clicks alone.

    References


  • AI Search, Publisher Traffic, and the New SEO Competition

    AI Search, Publisher Traffic, and the New SEO Competition

    If your organic visits are falling while AI referrals barely register, it is easy to reach one of two conclusions: AI search does not matter, or SEO no longer works. Neither conclusion gives you a useful plan.

    Direct AI clicks are only one part of the discovery path. Traditional search still captures demand, AI answers can influence which publishers people remember, and technical weaknesses can determine whether a system retrieves your information or a competitor’s. You need to measure those effects separately before you cut investment, chase a new optimization acronym, or publish more content.

    AI referral traffic measures the handoff, not the whole journey

    A reader follows a winding path from generic search cards through an abstract AI portal to an open publisher doorway, with secondary routes branching around the journey.

    Across millions of searches, AI conversations, and publisher visits from a privacy-safe, opt-in panel between February and June 2026, only 1.1% of publisher visits following AI conversations carried an AI referrer. About three-quarters arrived through direct navigation, while roughly 9% came through traditional search.

    That does not make AI exposure irrelevant. Readers were 20.5 percentage points more likely to visit a news publisher during the week after a news-related AI conversation than after a non-news conversation. The comparison used each reader’s browsing history, but it cannot establish that AI created the demand. A news conversation may simply occur when someone is already interested in following a story.

    The defensible interpretation sits between the extremes. AI referrals undercount journeys that continue through a branded search or a direct visit, but a later visit does not prove that the assistant caused it. Last-click analytics can tell you how a session ended. They cannot reconstruct every answer, search, and return visit that preceded it.

    Build your reporting around distinct questions instead of forcing every signal into an AI traffic total:

    SignalQuestion it answersWhat it cannot prove
    AI-referred sessionsDid an AI answer produce an immediate click?Whether exposure caused a later direct visit or search
    Mentions and citations in AI answersIs your publisher visible for priority questions?Whether the visibility produced attention, trust, or revenue
    Branded search and direct navigationAre more people deliberately seeking your brand?Which prior touchpoint caused the change
    Organic click-through rate by query typeWhere is search demand still producing visits?Whether an AI feature alone caused a portfolio-wide decline
    Conversions and assisted conversionsDoes the traffic you retain contribute to a business outcome?The exact value of every unseen exposure

    Keep those rows separate. A citation is not a visit, a visit is not a conversion, and a conversion is not proof that the last click deserves all the credit. The goal is not to replace hard traffic numbers with soft visibility metrics. It is to stop asking one metric to explain a multi-step journey.

    The available figures also describe news publishing, not every industry. The panel measured page visits rather than subscriptions, revenue, or time spent. If you operate in ecommerce, software, healthcare, local search, or another market, use the behavioral pattern as a measurement warning rather than treating 1.1% as your expected benchmark.

    AI Overviews do not reduce every query’s clicks equally

    A portfolio average can make AI Overviews look more destructive than a like-for-like comparison supports. During the February-June 2026 measurement window, AI Overviews appeared on about one in four news searches. Searches containing an Overview produced publisher clicks about 20% of the time, compared with roughly 30% when one did not appear. Yet the difference narrowed to about 2 percentage points when the same query was compared with and without an AI Overview.

    The raw 10-point gap therefore should not be treated as the causal effect of the feature. AI Overviews appeared most often on utility-style searches such as weather, market prices, and explainers – query types that already generated relatively few publisher clicks. Sports searches had the highest publisher click-through rates and rarely triggered an Overview.

    For your own diagnosis, divide queries by the job the reader is trying to complete. At minimum, separate quick factual lookups from live coverage, analysis, proprietary reporting, and navigational searches. Then examine impressions, position, click-through rate, landing-page engagement, and conversion within each group. Record AI feature presence for a stable sample of important queries rather than assuming every impression faced the same search results page.

    This segmentation changes the decision you make. A utility page that answers a self-contained question may face structural click pressure because the answer can be consumed on the results page. Publishing a longer version of the same commodity explanation will not necessarily recover that visit. Give the reader a reason to continue: original data, a live resource, methodology, deeper analysis, a consequential next step, or reporting unavailable in the answer itself.

    A page serving active coverage or proprietary analysis requires a different response. Protect its crawlability, freshness signals, internal prominence, and distinct value before redesigning it around a presumed zero-click future. Query intent should determine the intervention; an overall organic traffic line cannot.

    Fix retrieval debt before buying an AI-specific tactic

    A page can rank in conventional search and still be awkward for an answer system to use. Ranking evaluates a page as a result. Retrieval may select a particular passage, fact, or section to assemble an answer. That creates a practical gap: your domain may be authoritative while the exact information a system needs is buried, duplicated, or dependent on an unreliable interface.

    Many supposed AI visibility problems are familiar technical SEO problems that have accumulated through redesigns, migrations, campaign launches, and uncoordinated publishing. Conflicting canonicals divide signals. Redirect chains complicate access. Several near-identical pages compete to own one topic. Critical information sits behind JavaScript interactions. Weak internal links leave the intended authority page isolated. Google may compensate for some of that mess when ranking a page, while a retrieval system still chooses a cleaner competitor passage.

    Audit the site by question and passage, not only by URL:

    1. Assign one preferred page to each priority topic. If your team cannot identify the owner, a machine is receiving the same ambiguity.
    2. Map every overlapping URL. Consolidate genuinely duplicative coverage, redirect obsolete versions where appropriate, and align canonical signals before adding more pages.
    3. Locate the exact passage that answers each important question. Put the direct answer near the beginning of a clearly labeled section, then add context, qualifications, and supporting evidence.
    4. Inspect the HTML a crawler receives. Essential definitions, product facts, and explanations should not depend entirely on tabs, client-side rendering, or interactions that may not execute reliably.
    5. Strengthen internal links from relevant, authoritative pages to the topic owner. Use anchor text that explains the relationship instead of relying on generic calls to action.
    6. Remove promotional interruptions and unrelated copy that obscure the useful passage. A retrieval-ready section should make its subject, answer, and evidence easy to distinguish.
    7. Address performance and redirect inefficiencies that make repeated retrieval slower or less dependable.

    Structured data can reinforce the entities and relationships already visible on the page, but it cannot decide which of five overlapping articles owns a topic. An llms.txt experiment cannot repair contradictory canonicals or inaccessible content. Treat new protocols and markup changes as hypotheses to validate after the underlying architecture is coherent, unless your crawl evidence identifies a specific protocol-level problem.

    This work is less glamorous than an AI optimization shortcut, but it improves the same assets traditional search, AI retrieval, editors, and readers depend on. Clear topic ownership, stronger headings, accessible passages, better internal links, consolidation, and reduced JavaScript dependence are not separate SEO and GEO programs. They are one information-quality program viewed through different discovery systems.

    Compete with evidence an incumbent cannot cheaply reproduce

    A publishing team records an original experiment with cameras, measuring tools, samples, and source materials while distant competitors observe through a glass wall.

    AI discovery is not automatically leveling the market. Major publishers accounted for 82% of publisher names volunteered by AI assistants and 97% of the follow-through visits. Existing brand recognition and authority still matter.

    Being named may matter even when the answer does not generate an immediate click. When an assistant mentioned a publisher the reader had not placed in the prompt, the probability of visiting that publisher increased by 10.6 percentage points the next day and nearly 20 percentage points over the following week relative to similar publishers not mentioned in the same response. This is a routing signal, not causal proof. It does, however, show why measuring only sessions labeled as AI referrals misses a potentially important competitive interaction.

    A challenger should not respond by trying to match a leader’s entire content library. Large libraries often contain stale, overlapping, and politically difficult pages. More stakeholders must agree on consolidation, and more existing traffic appears at risk whenever a template or URL changes. That operational drag creates an opening for a smaller publisher that can establish clean topic ownership and produce evidence worth citing.

    Choose a commercially or editorially important question where the current results are generic, fragmented, outdated, or weakly supported. Build one definitive asset around a defensible contribution:

    • Original research or proprietary data with a visible methodology
    • A named subject-matter expert who is accountable for the explanation
    • Firsthand reporting or experience that a generic synthesis cannot recreate
    • Specific product, service, or category knowledge grounded in real evidence
    • Customer reviews, case studies, or other proof that supports the claim being made
    • Public relations and distribution that help relevant people discover, discuss, and reference the asset

    These assets matter because they give people and machines a reason to choose you beyond word count. Original evidence, recognizable experts, customer proof, brand recognition, and clean technical foundations take time to build and are harder to copy than another generic keyword page.

    Make each asset retrievable as well as impressive. State the central finding plainly. Show where the evidence came from. Label the section that answers the target question. Link supporting detail to the canonical asset. Remove older pages that contradict or dilute it. Then distribute it where customers, journalists, practitioners, and other publishers can encounter it. No single action guarantees inclusion in an AI answer, but the complete asset gives search and answer systems something distinct to retrieve and gives humans something worth seeking by name.

    Key takeaways for your next publishing cycle

    • Do not use AI-referred sessions as your only AI metric. Track answer visibility, branded search, direct navigation, organic performance, assisted conversions, and final outcomes as separate signals.
    • Do not apply an average AI Overview click gap to every query. Compare like-for-like queries and segment performance by the reader’s task.
    • Protect pages that still capture high-intent visits. Redesign commodity utility content around unique follow-up value instead of adding more generic explanation.
    • Resolve topic ownership, duplication, canonical conflicts, weak internal links, buried answers, JavaScript dependence, and performance problems before treating a new AI file or schema change as the strategy.
    • Compete selectively. Build a definitive, evidence-rich asset where an incumbent’s coverage is fragmented or difficult to maintain rather than copying its library page by page.
    • Keep causal claims modest. A mention, direct visit, branded search, or assisted conversion can indicate influence, but none independently proves what caused the reader’s decision.

    Your next move is concrete: select one priority topic, identify every URL currently competing to own it, mark the passage that should supply the answer, and record a baseline across search visibility, AI visibility, direct demand, and conversions. Consolidate the topic, strengthen the evidence, and watch how each signal changes. That gives you a repeatable operating model while competitors are still debating whether AI traffic is large enough to matter.

    References


  • YouTube and Discover Ad Updates: A Practical Action Plan

    YouTube and Discover Ad Updates: A Practical Action Plan

    If you manage YouTube or Discover campaigns, the dangerous mistake is to treat every Google update as a campaign change. In this case, one update changes how requirements are written; another changes what Merchant Center counts and where it places traffic. Only the second should alter your reporting workflow.

    That distinction matters because a dashboard can move even when audience demand and campaign delivery have not. Separate policy status from measurement changes before you edit creative, adjust budgets, or explain a sudden performance swing.

    Key takeaways

    • Google characterizes the YouTube and Discover Feed requirements update as an editorial rewrite with no new requirements or enforcement changes.
    • Merchant Center reporting changes scheduled to begin rolling out on August 24 affect traffic classification, organic YouTube measurement, and the campaign data included in product-level reports.
    • You may see a one-time decline in reported organic traffic, while product impressions and clicks may increase because reporting coverage is expanding.
    • Historical data back to July 1 will be revised for the YouTube affiliate classification, so a live report may no longer reproduce an export created under the previous logic.
    • Annotate the reporting transition, update dashboard definitions, and validate real delivery and business outcomes before changing spend.

    The policy page changed, but the approval standard did not

    Google revised the language and formatting of its YouTube and Discover Feed ad requirements to make them easier to interpret. It says the revision does not add requirements or change enforcement. There is no policy-driven campaign rebuild to perform solely because the page now reads differently.

    That does not make the page irrelevant. Clearer wording can help you catch an existing compliance problem during routine creative review. The important distinction is that better documentation may improve your understanding of an old rule; it does not, by itself, create a new rule.

    1. Check the actual approval, limitation, and delivery status of your ads. Account-level evidence matters more than the fact that a requirements page was reformatted.
    2. If status and delivery are unchanged, do not rewrite or resubmit approved creative solely in response to the editorial update.
    3. Use the clarified requirements during your normal prelaunch review. Compare each asset and its destination with the applicable requirement, just as you would have before the rewrite.
    4. If an ad becomes limited or disapproved, investigate the policy reason attached to that ad. Do not assume the documentation update caused the decision.
    5. Record any interpretation your team changes after reading the clearer wording. That creates a usable internal rule for future briefs without falsely labeling it as a new Google requirement.

    This approach prevents two expensive reactions: unnecessary creative work and budget changes made in response to a policy event that did not occur.

    Merchant Center numbers may move without performance moving

    A steady flow of shoppers and parcels continues below data tokens being redistributed between reporting containers.

    The Merchant Center update is different because it changes reporting definitions and coverage. Treat it as a measurement transition, not a documentation cleanup.

    YouTube affiliate traffic gets its own category

    Traffic generated by YouTube creators participating in Google’s affiliate program is moving out of Organic and into a separate YouTube affiliate category. The platform will also revise historical data back to July 1 to apply the new classification.

    A decline in Organic can therefore be a transfer between reporting buckets rather than a loss of traffic. Look for the newly separated YouTube affiliate category before concluding that free listings or creator-driven discovery weakened.

    Do not expect a simple equation in which old Organic always equals new Organic plus YouTube affiliate. Google is also revising how organic YouTube clicks and impressions are measured so that Merchant Center aligns more closely with YouTube’s definitions. That second change can reduce reported organic activity independently of the affiliate reclassification.

    Product-level reporting gains broader paid coverage

    Merchant Center product performance reporting is expanding to include data from all Google Ads channels and formats, including Performance Max, Video, App, and Demand Gen campaigns. Broader coverage can produce a one-time increase in reported impressions and clicks even if your campaigns did not suddenly scale.

    The practical question is not simply whether a metric rose. Ask whether more campaign formats are now contributing to that metric. A coverage increase and a performance increase can appear identical in a top-line chart, but they require completely different decisions.

    Google also plans to add a Network reporting dimension so merchants can eventually segment results by Google network in a way that resembles Google Ads. Treat that as planned functionality until it is actually available in your account; do not build a current reporting commitment around a future dimension.

    Build a reporting bridge across the August 24 rollout

    An analyst stands on a bridge of linked data checkpoints connecting two differently organized analytics systems.

    A reporting bridge documents what changed, when it changed, and which comparisons remain valid. It protects you from turning a measurement artifact into a real campaign intervention.

    1. Add an August 24 annotation to every Merchant Center dashboard that uses organic YouTube traffic or product-level Google Ads data. Label it as the start of the rollout, not necessarily the exact switch time for every account.
    2. Preserve existing exports where available. Include the queried date range, export date, filters, dimensions, and metric definitions. Because data back to July 1 is being revised, the export date is part of the evidence.
    3. Create separate definitions for Organic, YouTube affiliate, and paid product traffic. If an executive dashboard combines them, retain the components underneath the combined figure so that a transfer between categories remains visible.
    4. Review formulas, filters, automated alerts, and scheduled reports. An alert based on an Organic decline or an impression increase may fire because the underlying classification or coverage changed.
    5. Do not splice old-logic and new-logic values into an unlabeled trend line. Use separate series, a visible transition marker, or a restated baseline so readers know that the comparison crosses a definition change.
    6. Validate any apparent gain or loss against campaign delivery and your business outcomes before changing bids, budgets, or creative. A reporting discontinuity alone is not evidence that the campaign improved or deteriorated.

    If you do not have a pre-change export, do not manufacture a precise bridge from incomplete data. Mark history from July 1 as restated, document the current definitions, and establish a new baseline. An honest break in the series is more useful than a smooth chart built from incompatible numbers.

    Read the reporting pattern before changing spend

    What you seeLikely explanation to test firstWhat to do before acting
    Organic traffic falls as YouTube affiliate traffic appearsCreator affiliate traffic moved into its own categoryCompare the two categories together, then isolate any remaining difference
    Organic YouTube clicks or impressions fall beyond the affiliate transferOrganic YouTube measurement was revised to align more closely with YouTube definitionsCompare periods calculated under the same definition and annotate the break
    Product impressions or clicks rise after the rolloutPerformance Max, Video, App, or Demand Gen data may now be includedCheck campaign-format coverage before describing the movement as growth
    The requirements page looks different while ad status stays the sameThe policy documentation received an editorial rewriteContinue normal compliance review without rebuilding the campaign
    An ad becomes limited or disapprovedThe editorial rewrite alone does not establish a new enforcement causeInspect the specific policy status and affected asset before making changes
    You need a network-level Merchant Center breakdownThe announced Network dimension may not be available yetUse currently available channel reporting and wait for the dimension to appear in the account

    Before your next performance review, update the data dictionary, add the rollout annotation, and give stakeholders a short note explaining which series were reclassified or expanded. Then keep campaign settings stable unless delivery or business results provide a separate reason to act. That is how you prevent Google’s reporting cleanup from becoming an avoidable optimization mistake.

    References


  • Is Reddit’s Ad Platform Competitive Enough for Your Budget?

    Is Reddit’s Ad Platform Competitive Enough for Your Budget?

    You’re not deciding whether Reddit is interesting. You’re deciding whether it deserves budget that could go to a more mature channel with better targeting, forecasting, and attribution.

    The practical answer is conditional. Reddit can be competitive when your buyers use communities to investigate problems, compare alternatives, and ask for recommendations. It is much less competitive when your campaign depends on exact B2B identity, reliable exclusions, predictable scale, or automated revenue feedback. The right move is to test Reddit for the job it can do, while refusing to assume its ad manager has reached parity with Google, Meta, or LinkedIn.

    Key takeaways for your go-or-no-go decision

    • Reddit’s clearest advantage is access to decision conversations. It is not identity resolution or demographic precision.
    • A strong test separates communities, keywords, first-party audiences, and lookalikes so you can see which signal actually produces useful demand.
    • Do not trust broad audience estimates or targeting labels without validation. Build the budget around an acceptable test loss, not an optimistic forecast.
    • Use Pixel, CAPI, disciplined UTMs, and CRM outcomes together. Last-click conversions alone can miss Reddit’s role during research and consideration.
    • Wait if your economics require named-account targeting, current-customer suppression, dependable negative targeting, or closed-loop revenue optimization from day one.

    Judge Reddit by the advertising job you need done

    Reddit has moved beyond a bare-bones experimental channel. Its platform gained new ad types and AI-powered functions in 2026, shopping integrations, and video enhancements beginning in late 2025. That progress makes a test easier to justify. It does not make every campaign suitable for Reddit.

    The important distinction is between audience context and audience identity. Reddit can tell you something valuable about what a person is discussing, researching, or comparing. It is less equipped to tell you exactly who that person is inside a company or buying committee. Anonymous and pseudonymous participation helps create candid conversations, but it also limits the identity signals advertisers routinely expect elsewhere.

    Campaign requirementReddit’s current positionWhat you should do
    Reach people discussing a defined problem or categoryCommunity, interest, and keyword targeting align well with topic-driven discovery.Proceed if you can name the communities, questions, comparisons, and recommendation language that surround the decision.
    Target job title, seniority, company size, industry, or named accountsPrivacy-safe firmographic and account-level capabilities remain a major competitive gap.Do not position Reddit as a direct LinkedIn replacement. Use it only where professional interests or relevant communities provide a credible proxy.
    Reach a packaged in-market audienceReddit contains strong behavioral evidence of research, but it does not yet turn signals such as recent questions, repeated comparison activity, and alternative evaluation into sufficiently clear journey-stage audiences.Construct intent manually through narrowly themed community and keyword cells.
    Retarget or expand from first-party dataCustomer lists and lookalikes exist, but retargeting depth, CRM connectivity, lookalike reliability, and cross-community behavioral signals need validation.Keep first-party and modeled audiences separate from contextual audiences. Judge them by downstream quality rather than availability in the interface.
    Exclude irrelevant or already-acquired usersNegative keywords, community exclusions, customer suppression, lead suppression, and clearer AND/OR logic remain important advertiser requests.Assume leakage is possible. Narrow your positive targeting, separate ambiguous combinations, and identify existing customers and leads in downstream reporting.
    Forecast delivery and saturation confidentlyAudience-size ranges have drawn criticism for being unrealistic, while demographic composition, device mix, associated communities, expected conversion volume, and saturation are not sufficiently predictable.Use forecasts as directional inputs only. Cap the test at an amount you can afford to spend without a positive result.

    This creates three practical decision states. Proceed when the relevant conversation is clearly present and contextual fit matters more than precise identity. Keep Reddit exploratory when the audience is plausible but scale, exclusions, or attribution are uncertain. Defer when campaign economics depend on exact firmographics, reliable suppression, or a delivery forecast you must defend before launch.

    That distinction protects real money. Do not remove budget from a proven acquisition channel merely because Reddit offers cheaper-looking reach or an appealing audience estimate. A challenger channel earns expansion by producing incremental business value, not by making the planning screen look promising.

    Build a test around Reddit’s limitations, not just its promise

    A bounded advertising test uses campaign tokens, connected community circles, control gates, a timer, and a reserved budget.

    Turn decision language into separate audience cells

    A useful Reddit test begins with the decision your buyer is trying to make. Broad interests such as technology, finance, or fitness are usually too vague to reveal why a campaign worked. Research language is more useful: the problem being diagnosed, the product category being explored, the alternatives being compared, and the recommendation being requested.

    1. Map the decision moments. Build a short list of the questions, objections, comparisons, and alternatives that appear around the purchase. A problem-aware thread and an alternative-comparison thread represent different levels of intent, even when they mention the same category.
    2. Group communities by one coherent theme. Do not combine every loosely relevant subreddit into one audience. Separate communities centered on the problem, the profession, the product category, and adjacent interests. This makes irrelevant reach visible instead of averaging it away.
    3. Keep targeting mechanisms apart. Run community, keyword, first-party, retargeting, and lookalike audiences as distinct test cells where practical. If the interface does not make AND/OR behavior unambiguous, separate the combinations rather than guessing how the platform resolves them.
    4. Match each cell to its own message and destination. Someone asking how to solve a problem should not receive the same opening argument as someone comparing two established options. The landing page should continue the exact decision raised by the ad.
    5. Write the decision rule before spending. Define the maximum acceptable spend without a qualified outcome, the business event that counts as success, and the evidence required before moving more budget. Use your margins and conversion economics; there is no universal Reddit benchmark that can make this decision for you.

    Missing exclusions require a second line of control. If you cannot reliably suppress customers or existing leads, label those records in your CRM and remove them from acquisition reporting. This does not prevent wasted impressions, so show the contaminated share when evaluating the test. Otherwise, familiar users can make a campaign look more effective at acquiring new demand than it really was.

    Make the creative useful inside the conversation

    Reddit users are unusually sensitive to advertising that feels detached from the surrounding discussion. Native creative does not mean disguising an ad as an ordinary user’s post. It means respecting why someone opened the thread and contributing something relevant before asking for a click.

    • Lead with the specific decision, misconception, or tradeoff the audience is already discussing.
    • Identify the brand and commercial purpose plainly. Manufactured slang and fake neutrality damage credibility.
    • Put a useful premise in the ad itself. Do not make the click a toll someone must pay to understand your point.
    • Adapt the argument to each audience cell. Reusing one generic advertisement across unrelated communities defeats the contextual advantage you came to Reddit for.
    • Carry the same language and promise onto the landing page. A conversational ad that leads to a generic corporate page creates an immediate break in trust.

    Conversation Ads received useful updates in 2024, but the native-format toolkit still has room to grow. Polls, product carousels, and Q&A units would fit naturally into Reddit’s environment, while short-form video still needs stronger vertical-format and autoplay support. Build your current plan around formats you can verify in the account, not units you expect the platform to add later.

    Be especially careful when importing short-form video from another platform. Preview the actual placement, crop, playback behavior, captions, and opening frame before launch. A creative concept built around vertical autoplay can lose its premise if Reddit delivers it differently.

    Measure Reddit as influence without giving it a free pass

    Discussion groups send recommendation signals through an attribution prism toward a shopper at a checkout pedestal, while a lens captures only part of the path.

    Reddit often appears while a person is researching rather than completing a purchase. That role matters more as AI-generated search answers reduce some outbound clicks and push marketers to understand earlier stages of consideration. It also creates a convenient excuse for weak campaigns: claiming that untracked influence must exist somewhere.

    A better measurement plan recognizes upper-funnel influence while requiring evidence at every level.

    1. Establish reliable platform and site capture. Reddit introduced Brand Lift, Conversion Lift, and CAPI capabilities in 2023 and also supports Pixel and omnichannel attribution. Configure the relevant conversion events consistently, check that destinations resolve correctly, and confirm that your site analytics receives the intended campaign data.
    2. Use a strict manual UTM taxonomy. Dynamic UTM integrations remain a basic platform gap. Define source, medium, campaign, audience theme, creative concept, and decision stage before trafficking. Apply the same names across ads, analytics, and CRM records, then click every live destination to verify the parameters.
    3. Carry leads through to business outcomes. Native connections to systems such as HubSpot and Salesforce would make offline revenue feedback easier, but those integrations remain part of the competitive opportunity. Until your setup provides that connection, join campaign data to lead stage, opportunity, customer, and revenue records through your own reporting process. A form submission is not equivalent to a valuable customer.
    4. Separate attribution from incrementality. Pixel or UTM attribution can show that a conversion was associated with a campaign. It cannot prove that the conversion would not have happened without the ad. Randomized audience holdouts, geo experiments, self-serve lift studies, and incremental reach and frequency reporting are the stronger tools advertisers still need easier access to.
    5. Choose a cross-channel model appropriate to your scale. Multi-touch attribution can describe observed paths, while marketing mix modeling can estimate channel contribution from aggregated spend and outcomes. Neither is automatic proof of causality, and neither repairs inconsistent campaign naming or missing revenue data.

    If Reddit cannot provide a suitable self-serve experiment, ask whether your team has enough scale and analytical support to design an external holdout or geo test. Do not treat an ordinary before-and-after comparison as causal proof. Seasonality, promotions, other media, and changes in demand can move at the same time.

    Your campaign brief should therefore name two judgments in advance: whether Reddit produced acceptable direct outcomes and whether credible incrementality evidence justifies its broader contribution. Keeping those judgments separate prevents last-click reporting from dismissing useful influence, but it also prevents vague influence claims from rescuing poor performance.

    The competitive verdict depends on your non-negotiables

    Reddit is competitive as a gateway into candid, topic-rich decision environments. It is not yet equally competitive as an end-to-end advertising operating system. The missing capability that matters most depends on how you buy media:

    • B2B teams should prioritize job function, seniority, industry, company size, named-account, technology-use, decision-maker, and buying-committee targeting.
    • Performance teams need more dependable retargeting and lookalikes, negative keywords and communities, customer and lead suppression, explicit targeting logic, and realistic delivery forecasts.
    • Revenue marketers need native CRM ingestion and optimization toward qualified pipeline and customer value rather than shallow conversion events.
    • Brand teams need accessible randomized holdouts, geo experiments, lift studies, and incremental reach and frequency measurement.
    • Creative teams would benefit from polls, product carousels, Q&A units, and more capable vertical short-form video.

    None of those gaps automatically disqualifies the channel. A gap becomes a blocker when your campaign cannot succeed without the missing control. If community and keyword context can compensate for limited identity data, your measurement stack can follow outcomes beyond the click, and your creative genuinely serves the discussion, Reddit deserves a bounded test. If exact accounts, suppression, predictable volume, or automated revenue optimization are non-negotiable, wait rather than forcing the platform into the wrong job.

    Before you launch, put six items on one page: the decision moments you are targeting, the separate audience cells, the exclusions you cannot enforce, the creative premise for each cell, the UTM-to-CRM measurement path, and the rule for stopping or expanding spend. If any one of them is blank, the campaign is not ready. If all six are specific, you have a test that can tell you whether Reddit is competitive for your business, not merely whether it can deliver ads.

    References


  • How to Measure Google AI Search Discovery and Performance

    How to Measure Google AI Search Discovery and Performance

    Your Google organic dashboard can look steady while AI search changes how buyers discover you, compare your claims and decide whether your brand belongs on their shortlist. If you report only sessions and last-click conversions, much of that influence remains invisible.

    You do not need to solve perfect attribution. You need a measurement system that distinguishes what you can observe directly from what you can only infer. The practical model runs from verified AI access through visibility, identifiable visits, downstream demand and business outcomes.

    Google’s AI entry points change the top of the journey

    Google is experimenting with more explicit ways to lead people into AI-powered search. A limited desktop test places Create images, Ask about files and Brainstorm beneath the Google search box; selecting one takes the user into AI Mode. Google has also said that the test does not change how the main search box works.

    Do not treat a limited interface test as proof of a broad rollout or a ranking change. Its value is diagnostic: Google is testing whether clearer prompts help people discover tasks they may not associate with Search. If those entry points expand, more journeys could begin with an open-ended task instead of a conventional keyword.

    That creates two discovery questions you should measure separately:

    • Surface discovery: Where does the person begin – conventional Google results, an AI Overview, AI Mode or an external AI assistant?
    • Brand discovery: When the person asks a market, comparison, implementation or validation question, does your brand appear in the response?

    Add both fields to your query and prompt inventory. A keyword report organized only by search volume will not show whether you are present when someone asks an AI system to build a shortlist, test a claim or compare approaches. Group prompts by the job the person is trying to complete, then record the surface on which you test them.

    Use five measurement layers instead of one AI traffic total

    Five translucent platforms stack from an access gateway at the bottom to a completed transaction at the top.

    AI discovery does not produce one clean, universal tracking parameter. It produces a chain of observable signals. A useful scorecard follows five layers from AI access to revenue, with each layer answering a different question.

    LayerQuestionSignals to trackDecision it supports
    1. AI accessCan legitimate AI systems reach the pages that matter?Verified bot crawl frequency, crawl depth and coverage of priority URLsFix access, rendering or retrieval barriers before judging visibility
    2. AI visibilityDoes your brand enter relevant answers?Mention rate, citation rate, cited URLs, prompt coverage and Google Search Console impressions as supporting contextFind topics, use cases and journey stages where competitors dominate
    3. Identifiable AI visitsWhich measurable AI clicks reach the site?Recognizable AI-assistant referrals, landing pages, conversions and attributable revenueImprove pages receiving observable AI traffic
    4. Downstream demandDoes AI visibility appear alongside later brand interest?Branded clicks in Search Console, organic conversions, direct demand and repeat visitsAssess influence that referral reports cannot capture directly
    5. Business outcomesIs the program contributing to commercial value?Qualified pipeline, closed-won opportunities and revenueContinue, redirect or reduce investment

    Define the denominator for every rate before reporting it. Access coverage can be the number of priority URLs reached by verified AI bots divided by the total priority URL set. Mention rate can be valid prompt runs that name your brand divided by all valid runs. Citation rate can be valid runs that cite an owned page divided by all valid runs. A valid run is one completed under the test conditions you recorded.

    Keep the layers separate on the dashboard. A crawler request does not prove that an answer used your content. A mention does not prove that anyone clicked. A referral session does not prove that AI created all later revenue. Each signal becomes useful when it answers its own question without being promoted into evidence for the next layer.

    Start access measurement with a fixed set of commercially and informationally important URLs. Count only verified AI bot activity where possible. User-agent strings can be spoofed, so validate requests through reverse DNS, published IP ranges or a CDN’s verified-bot service. Report frequency, coverage and repeat access, but label them as retrieval indicators rather than visibility wins.

    Make prompt visibility repeatable enough to show a trend

    A few screenshots gathered after publishing a page can show that an answer occurred. They cannot tell you whether visibility is improving. AI responses vary, prompts that look similar can express different intent, and an isolated mention can disappear on the next run.

    Build a stable core prompt library around real buying tasks. Use sales questions, support questions, comparison criteria and implementation objections already present in your business. Separate the core library from exploratory prompts so adding a new idea does not silently change your historical denominator.

    For every core prompt, store:

    • A permanent prompt ID and the exact wording.
    • The intended market, audience, journey stage and task.
    • The Google surface or AI assistant tested.
    • The date, language and location, plus account or personalization state when known.
    • Whether the brand was mentioned.
    • Whether an owned page was cited, including the cited URL.
    • Which competing brands or domains appeared.
    • A saved copy of the response so the score can be audited.

    Choose a testing cadence your team can reproduce and keep the procedure consistent. Do not combine results from different surfaces as though they were interchangeable. Report each surface separately, then provide a combined view only when the weighting method is explicit.

    Score mentions and citations independently. A brand can be named without receiving a link, while an owned page can support an answer in a different way. Use four simple response states: mentioned and cited, mentioned but not cited, competitor cited instead, or no relevant brand present. Those states tell you more than a single visibility score.

    Treat the states as diagnostic clues, not automatic explanations. If verified bots repeatedly reach a priority page but the page never appears for closely aligned prompts, investigate its relevance, clarity and supporting evidence. If competitors receive citations while your brand receives uncited mentions, inspect which of their pages supplies the answer-ready detail your page lacks. If no domain is cited, do not assume your technical setup failed; the response may simply not expose supporting links.

    Read Google analytics without inventing AI attribution

    GA4 can identify referral traffic from recognizable AI assistants when a click arrives with a measurable referring source. That makes AI-assistant sessions, landing pages, conversions and revenue useful direct-response metrics.

    Google’s own AI experiences require more restraint. AI Mode and AI Overview visits are generally blended into Google organic traffic and can sometimes appear as Direct, depending on how the click is passed. They should not be added to an AI-referral segment, and all Google organic traffic should not be relabeled as AI traffic.

    Configure the report in four parts:

    1. Create a narrowly defined segment for recognizable AI-assistant referrers. Keep the matching rules documented so changes are auditable.
    2. Report sessions, landing pages, meaningful conversions, pipeline and revenue for that segment. This is the observable subset of AI-driven visits, not the total effect of AI discovery.
    3. Keep Google organic and Direct as separate channels. Use them as contextual trends, not as traffic you can confidently assign to AI Mode or AI Overviews.
    4. Chart branded clicks from Google Search Console beside organic conversions and other downstream demand. Do not imply a user-level connection that the platforms do not provide.

    Define your brand-query rule before reading the trend. Include the company name, product names and common variations that genuinely signal brand demand, then preserve that rule from period to period. Changing the query set whenever the chart moves turns the metric into a narrative tool rather than evidence.

    A rise in AI visibility followed by sustained growth in branded demand makes the influence case stronger, especially when the timing repeats across reporting periods. It still does not prove that AI caused every branded visit. Brand campaigns, publicity, product launches and offline activity can produce the same pattern, so annotate those events and state the alternative explanations.

    Review the chain in order and act on the first weak layer

    A glowing signal passes through five connected glass chambers and fades at a partially obstructed stage under an inspection light.

    Run the performance review in causal order: access, visibility, identifiable visits, downstream demand and business results. Starting with revenue and working backward encourages convenient explanations. Starting with access shows where the evidence actually breaks.

    1. Check whether verified AI bots reached the priority URL set. If access fell, resolve verification, blocking, rendering or retrieval problems before interpreting prompt results.
    2. Compare mention and citation rates using the unchanged core prompt library. If access is healthy but visibility is weak, inspect topic coverage, answer clarity and the evidence presented on the page.
    3. Inspect identifiable AI referrals. If visibility rises without referral growth, do not declare failure; many AI-influenced journeys do not produce a measurable citation click.
    4. Look for downstream demand. Compare branded clicks and organic conversion trends with the visibility timeline while accounting for campaigns and other events.
    5. Connect the pattern to qualified pipeline, closed-won opportunities and revenue. If demand rises but pipeline does not, investigate conversion quality, offer fit and the sales handoff instead of chasing more mentions by default.

    The most honest executive view contains both a result and a confidence label. Verified referral revenue is directly observable. A repeated relationship between prompt visibility and branded demand is supporting evidence of influence. A single simultaneous spike is a hypothesis. This language makes the report more credible because it prevents a plausible story from being presented as measured attribution.

    Key takeaways

    • Treat Google’s new AI entry points as behavior to monitor, not proof of a completed rollout or ranking change.
    • Measure AI search through five layers: verified access, prompt visibility, identifiable visits, downstream demand and business outcomes.
    • Verify AI bots with network-level evidence rather than trusting a user-agent string alone.
    • Keep a stable core prompt library and record mentions, citations, cited URLs and competing brands separately.
    • Use AI-assistant referrals as an observable subset. Do not label all Google organic or Direct traffic as AI-driven.
    • Use branded demand as evidence of possible influence, then qualify it against campaigns and other explanations.

    Your next move is small and concrete: choose the priority URL set, freeze the first version of your core prompt library and create one dashboard row for each measurement layer. On the next review, act on the earliest weak layer in the chain. That is where the evidence says the program is breaking, and where the next improvement is most likely to be measurable.

    References


  • From AI Visibility to Revenue: Fix the Full Growth Path

    From AI Visibility to Revenue: Fix the Full Growth Path

    Your brand is appearing in AI answers, the citation chart is moving up, and the pipeline is still flat. That does not automatically mean your GEO work has failed. It means visibility has been measured before the rest of the buying path has been examined.

    Revenue depends on a connected system: the right recommendation prompt, a useful answer, a credible reason to choose you, an obvious next step, prompt follow-up, qualification, and a sale the business can serve profitably. This framework helps you find the weakest link instead of buying more visibility on instinct.

    Key takeaways

    • Treat AI citations as leading indicators. Pipeline, revenue, and profit remain the business outcomes.
    • Monitor a defined set of purchase-adjacent prompts, not an undifferentiated count of brand mentions.
    • Build content that helps a buyer distinguish between options through criteria, evidence, tradeoffs, and clear fit boundaries.
    • Audit what happens after every inquiry. Missed calls, delayed replies, weak routing, and unclear next steps can erase the value of demand generation.
    • Use stage-by-stage conversion rates to locate the constraint before deciding whether to fund content, technical work, sales, or client-service capacity.

    Track the path from recommendation to profit

    A citation means that your brand was visible in an answer. It does not tell you whether the person had buying intent, understood your fit, contacted you, qualified, or became a customer. AI visibility and commercial performance are related, but they are not interchangeable.

    This distinction matters because a visibility dashboard can improve while commercial performance deteriorates. A growing share of mentions on broad informational prompts may conceal weak coverage of the recommendation prompts that precede a purchase. Even high-intent coverage can fail to produce revenue when the answer leads to a generic page, the offer is unclear, or the resulting inquiry sits unanswered.

    Replace the single visibility score with a chain of observable stages:

    StageWhat you need to learnUseful evidence
    AI recommendationDoes the brand appear when a suitable buyer is selecting an option?Coverage of a fixed set of purchase-adjacent prompts, answer context, cited page, and competitors included
    Commercial transitionCan the buyer identify and take an appropriate next step?Visits to relevant pages, branded follow-up activity, calls, forms, bookings, or other defined actions
    Inquiry handlingDid the business reach the prospect and provide a clear next step?Call records, reply timestamps, two-way conversations, appointments, routing status, and unresolved inquiries
    QualificationWas the inquiry a genuine fit for the offer?Qualified opportunities, disqualification reasons, use case, service area, language need, and other real buying constraints
    Commercial outcomeDid the opportunity produce viable growth?Wins, revenue, gross profit, sales-cycle length, retention where relevant, and delivery capacity

    Give every rate a clear numerator and denominator. Otherwise, teams can use the same label for different calculations and reach opposite conclusions. A practical starting set is:

    • Money-query coverage: monitored purchase-adjacent prompts in which you are recommended, divided by all monitored purchase-adjacent prompts.
    • Inquiry-to-contact rate: inquiries that become two-way conversations, divided by all valid inquiries.
    • Contact-to-opportunity rate: qualified opportunities divided by two-way conversations.
    • Opportunity-to-win rate: won customers divided by qualified opportunities whose outcome is known.
    • Revenue per inquiry: won revenue attributed to the cohort divided by valid inquiries in that cohort.
    • Gross profit per inquiry: gross profit from won business divided by valid inquiries, when reliable cost data is available.

    Do not collapse informational citations and purchase-adjacent recommendations into one total. They answer different questions. Informational visibility can support awareness and authority, but it should not be presented as equivalent to buyer selection.

    Build a money-query map around real buying decisions

    A buyer at a table evaluates products, cost, timing, delivery, support, and value before choosing one illuminated option.

    A money query is not simply a keyword with high search volume. It is a question asked close enough to a decision that the answer could change who receives an inquiry, booking, trial, purchase, or sales conversation. The useful starting point is the recommendation prompt a real buyer uses when choosing for a specific situation.

    Build the map from the language of actual demand, not from a brainstorm conducted entirely inside marketing:

    1. Collect buyer questions. Review sales emails, call notes, form submissions, chat transcripts, objections, proposal questions, lost-deal reasons, and on-site search terms. Preserve the qualifiers buyers use.
    2. Separate intent levels. Put definitions and general education in an awareness group. Put comparisons, provider selection, fit checks, alternatives, implementation constraints, pricing considerations, and risk questions in decision groups.
    3. Retain the situation. Industry, location, language, company size, integration needs, urgency, service model, and other constraints often determine whether a recommendation is commercially relevant.
    4. Name the intended next step. Decide whether a suitable reader should call, request an assessment, book a meeting, start a trial, visit a location, or continue to a more specific decision page.
    5. Assign ownership beyond marketing. Record who owns the page, who receives the inquiry, who provides backup coverage, and what event counts as a qualified opportunity.

    Use a repeatable brief for each prompt cluster. It should contain the prompt, buyer situation, decision criteria, evidence required, reasons you may be a poor fit, destination page, intended action, commercial owner, and measurement window. That brief prevents a common failure: optimizing an answer without defining what the qualified reader should do next.

    Consider a prompt such as, “Which GEO agency fits a multi-location legal practice that needs bilingual lead handling?” A useful page would need more than a definition of GEO. It would need to explain multi-location capabilities, language and intake dependencies, measurement, responsibilities, relevant limitations, and what happens after a prospect asks for help. If your business does not provide one of those capabilities, state the boundary clearly rather than trying to look eligible for every variation.

    Monitor prompt clusters separately. If you appear for general education but not for selection, your problem is not total visibility. It is recommendation relevance. If you appear for selection prompts that describe customers you cannot serve, the mention count is creating noise rather than opportunity.

    Publish evidence that helps a buyer choose

    Generic explanation pages are easy to reproduce and hard to recommend with confidence. A buyer-selection page has a different job: it helps someone decide which option fits a defined situation. That requires discriminating information, not a longer version of the same category definition.

    Apply the following standard to pages attached to money queries:

    • Lead with the answer. State the recommendation, condition, or key distinction before the supporting explanation. Make the central claim easy to identify and quote.
    • Name the decision criteria. Explain which capabilities, constraints, risks, and dependencies actually change the choice. Do not hide them inside generic benefit language.
    • State tradeoffs and wrong-fit cases. Honest fit boundaries make content resemble a useful recommendation. They also discourage inquiries your sales team will later disqualify.
    • Publish defensible first-party evidence. Turn internal data into a useful finding only when you can explain the population, method, scope, and limitation. A number no competitor can legitimately claim is more distinctive than another interchangeable explainer, but unsupported precision will weaken trust.
    • Identify responsible people. Use named authors, relevant credentials, and clear organizational information. A faceless administrative byline gives a retrieval system and a buyer less help in evaluating credibility.
    • Expose recency. Display publish and update dates, and update them only when the page has materially changed. Record what was refreshed internally so the date remains meaningful.
    • Use comparison tables for real comparisons. Put stable criteria into rows and alternatives into columns when a buyer is genuinely weighing options. Do not force nuanced claims into a table merely to create extractable markup.
    • Remove interchangeable content. If a competitor could replace your name and publish the page unchanged, it is not expressing your evidence, position, method, or fit. Consolidate it, rewrite it around a real decision, or remove it when it serves no other purpose.

    Then check retrieval. Important claims should be present in server-delivered HTML rather than available only after client-side JavaScript runs. Confirm that relevant crawlers are not blocked and that important pages are indexed in Bing, because ChatGPT web search relies on Bing’s index. A system cannot cite content its retrieval layer cannot access.

    Keep technical work in proportion. Schema can clarify entities and page structure, but it does not turn an undifferentiated page into persuasive evidence. Treat llms.txt as an unproven visibility lever rather than a substitute for buyer-focused content. The practical hierarchy is straightforward: create something worth recommending, make the claim easy to extract, make the page accessible, and use structured data as supporting plumbing.

    Every decision page also needs a next step that matches its intent. A comparison reader may need an assessment, product view, consultation, or implementation conversation. A generic “learn more” link sends the buyer back into research. Tell the person what the next action is, what information it requires, and what will happen after submission.

    Fix the handoff between marketing and sales

    A marketing team passes a glowing customer-intent baton to a sales professional as the route continues toward a consultation and handshake.

    Marketing can create an eligible opportunity and still produce no revenue. Calls go unanswered, forms route to the wrong person, inboxes accumulate, and automated acknowledgements provide no useful next step. In trust-heavy fields such as legal, real estate, and professional services, missed calls, delayed email, and unclear follow-up can cause a ready prospect to choose a competitor.

    Audit the handoff as a buyer would experience it. Do not rely only on the workflow diagram:

    1. Inventory every entry point. Include tracked and untracked phone numbers, forms, booking tools, chat, email addresses, social messages, location pages, and third-party profiles that can generate inquiries.
    2. Run controlled test inquiries. Use clearly internal test records and avoid entering false information into systems that trigger regulated, legal, financial, or emergency workflows. Test during normal coverage as well as the periods in which you promise availability.
    3. Record the complete path. Capture submission time, acknowledgement time, human response time, assigned owner, routing changes, requested information, next step, and final disposition.
    4. Inspect the reply itself. Confirm that it answers the immediate question, explains what happens next, identifies anything the prospect must prepare, and provides a working way to continue.
    5. Test promised language paths. If you advertise service in English and Spanish, compare clarity, access, routing, and follow-up in both. Do not treat a translated first message as equivalent to a supported client journey.
    6. Trace the record into reporting. Confirm that source, landing page, campaign, prompt cluster where known, consent status, and qualification details survive the transfer into the CRM or other system of record.

    Turn the audit into an operating agreement. For each channel, name a primary owner, backup owner, internal response expectation, acceptance criteria, escalation path, and closed-loop status. An automated acknowledgement can reassure the prospect that a message arrived, but it should not be counted as a completed response when the person still lacks help or a next action.

    Language coverage deserves explicit design. Spanish-speaking clients may prefer to discuss contracts, documentation, appointments, pricing, and consequential personal decisions in Spanish. If your marketing attracts that audience but the intake process cannot support the conversation, visibility is creating an expectation the operation cannot meet.

    The staffing answer can be an internal team, a trained bilingual virtual assistant, a shared intake function, or another arrangement suited to the business. Evaluate the option on coverage, training, approved scripts, escalation, documentation, data access, and quality control. In legal or otherwise regulated services, intake staff should not improvise professional advice. Give them approved boundaries and a route to a qualified professional when a question crosses those boundaries.

    Feed disposition data back to marketing. Repeated disqualification for the same reason may reveal that the page is attracting the wrong situation or omitting a decisive limitation. Repeated abandonment before a booking may indicate unnecessary form friction or an unclear next step. Repeated delays after submission point to capacity or ownership. Each pattern calls for a different investment.

    Read the scorecard and fund the actual constraint

    A revenue scorecard should let marketing, sales, and operations see the same path without pretending attribution is perfect. A person can encounter an AI recommendation and later return through branded search, direct navigation, email, or a call. Referrer data alone therefore cannot represent every influence.

    Use multiple forms of evidence without combining them into a fictional degree of precision. Keep platform and prompt monitoring, analytics, call tracking, CRM stages, won revenue, and gross-profit data distinct. Add an optional “How did you hear about us?” field where it will not create material friction, preserve the person’s wording, and compare it with recorded digital touchpoints.

    For each money-query cluster, report the prompt coverage, relevant cited pages, observable visits or follow-up actions, valid inquiries, reached prospects, qualified opportunities, wins, revenue, gross profit where available, and the most common loss or disqualification reason. Use a measurement window long enough for that cohort to move through your normal sales cycle. An open opportunity is not a loss, and an early snapshot should not be presented as a final return calculation.

    Then diagnose the first material break in the chain:

    • No recommendation on suitable money queries: inspect retrieval, brand authority, evidence, selection criteria, and whether the page answers the prompt directly.
    • Visibility only on broad informational prompts: rebuild the content plan around real selection, comparison, validation, and fit questions.
    • Recommendations without meaningful next actions: inspect answer context, destination-page alignment, fit communication, proof, offer clarity, and the call to action.
    • Inquiries without two-way contact: fix coverage, routing, ownership, response expectations, language support, and backup procedures before buying more demand.
    • Conversations without qualified opportunities: compare the prompt and page promise with actual eligibility. Tighten targeting and state disqualifying constraints earlier.
    • Qualified opportunities without wins: investigate offer fit, sales process, proof, pricing concerns, competitive losses, and unresolved objections. More citations will not repair a closing problem.
    • Wins that strain delivery or reduce profit: add service capacity, narrow eligibility, or adjust the offer before accelerating acquisition. Revenue that cannot be served well is not durable growth.

    Keep visibility in the report, but put it in the role it can honestly fill: evidence that you are eligible to influence a decision. Booked opportunities, incremental sales, and new customers are performance. Profit tells you whether that performance is economically worth scaling.

    Your next move is to choose one high-intent prompt cluster and walk one complete buyer path, from AI answer to closed outcome. Name the first broken handoff, assign its owner, and change that constraint before expanding the visibility budget. That is how GEO becomes part of a growth system instead of a separate scoreboard.

    References


  • Marketing Attribution Blind Spots: What Your Reports Miss

    Marketing Attribution Blind Spots: What Your Reports Miss

    Your campaign report says one channel drove the conversion. That may only mean the channel left the cleanest trail.

    Before you cut, scale, or defend a marketing investment, you need to distinguish three very different situations: the campaign failed, the customer journey was only partly observable, or the measurement plumbing broke. Treat those as the same problem and a precise-looking dashboard can steer your budget in the wrong direction.

    Your dashboard records evidence, not the entire journey

    Attribution works with observable events. An impression, tagged visit, form submission, CRM record, and purchase can be connected only when the necessary data survives each handoff. Anything that happens outside that chain may influence the buyer without receiving credit.

    That creates four common blind spots:

    • Unobserved exposure: Someone encounters your brand or advice without visiting your site.
    • Lost campaign context: The person visits, but an identifier disappears before analytics records it.
    • Disconnected outcomes: Marketing captures a lead, while the eventual opportunity or revenue remains in a separate system.
    • Misread evidence: A visible touchpoint receives credit even though the report cannot establish that it caused the conversion.

    AI discovery makes the first blind spot especially important. A person can read an AI-generated answer, see your company cited or recommended, and get what they need without clicking. They may return later through branded search, direct navigation, or another channel. Page views will show the later visit, if there is one, but they cannot represent the original zero-click exposure. That is why AI citations, share of voice, and revenue need distinct measurement layers.

    Lost campaign context creates a different problem. Google Analytics includes a diagnostic for URLs missing aggregate identifiers such as GBRAID and gad_. Those parameters matter to attribution in a privacy-focused measurement environment, and their absence can reduce campaign attribution accuracy. A campaign can therefore appear weaker because its evidence was dropped, not because its audience stopped responding.

    The practical distinction is simple: invisible influence calls for broader measurement, while missing identifiers call for a technical repair. Neither should be interpreted as campaign underperformance until you know which one you are dealing with.

    Measure visibility, visits, and business outcomes separately

    Three connected spaces show a beacon reaching a crowd, visitors entering a corridor, and customers completing purchases and consultations.

    A useful attribution view has three layers. Each answers a different question, and none can substitute for the others.

    LayerQuestion it answersEvidence to collectWhat it cannot prove
    AI visibilityDoes your brand appear in relevant generated answers?Mentions, citations, recommendations, answer position, tracked-query share of voiceThat a person visited, bought, or was persuaded
    TrafficDid an observable visit reach your site?Referral sessions, tagged links, landing pages, assisted paths, campaign identifiersThat every exposure produced a click or that the visit caused the outcome
    Business outcomesDid demand become something valuable?Leads, qualified opportunities, purchases, revenue, renewals, and CRM source evidenceWhich earlier touch deserves causal credit when the path is incomplete

    Define AI visibility against a fixed question set

    Do not report a vague claim such as “our AI visibility improved.” Build a query set from the questions customers ask while identifying a problem, comparing options, and making a decision. Keep that set stable long enough to make one reporting period comparable with the next.

    For every checked answer, record whether your brand was absent, mentioned, cited as a source, or explicitly recommended. Those states are not equivalent. A citation shows that your material surfaced in the answer; a recommendation is a stronger form of representation, but it still does not prove commercial impact.

    State the denominator whenever you report AI share of voice. For example, define it as the number of eligible answers containing your brand divided by the total eligible answers checked in the fixed query set. Without the query set, platforms, conditions, and denominator, a share-of-voice percentage has no stable meaning.

    Preserve traffic evidence without treating it as the whole result

    Create a dedicated segment for identifiable AI referrals. Record the landing page, referrer when available, engagement, and downstream conversion. Use tagged links wherever you control the destination link, but do not relabel unexplained direct traffic as AI traffic. “Unknown” is a more defensible classification than a confident guess.

    Compare AI referral traffic with the visibility layer instead of expecting the numbers to match. Rising citations with flat referrals can indicate more zero-click exposure, but it does not establish that the exposure caused later demand. It is a signal to investigate, not a revenue claim.

    Connect marketing evidence to outcomes the business values

    Carry a durable lead or customer key from the conversion point into your CRM where your setup permits it. Preserve the original source, the latest known source, landing page, campaign data, and relevant sales outcome as separate fields. Overwriting the first touch with the latest touch destroys evidence you may need later.

    Add a short self-reported discovery question to high-value conversion points. Offer recognizable options, including AI assistants, and leave room for free text. Self-reporting is imperfect, but it can reveal discovery paths that click-based analytics cannot see. Keep it beside behavioral attribution rather than using it to replace behavioral data.

    Report the three layers side by side. Do not collapse citations, sessions, leads, and revenue into one synthetic score. A single score hides the exact break you need to find: limited visibility, weak click-through, lost campaign data, poor lead quality, or a missing CRM connection.

    Repair campaign plumbing before judging performance

    A technician repairs loose and blocked connections in transparent pipes carrying glowing signals toward a central customer-record hub.

    A campaign-quality discussion should stop when the tracking path is visibly damaged. Creative, targeting, and bidding changes cannot repair a parameter stripped by a redirect or a revenue field that never returns to the reporting system.

    Use this sequence when Google Analytics flags missing aggregate URL parameters or when campaign data unexpectedly becomes incomplete:

    1. Record the affected scope. Note the campaign, platform, landing page, identifier involved, and example URLs identified by the diagnostic. Do not begin with an account-wide conclusion when the fault may affect only one route.
    2. Follow a controlled path. Start with a platform-generated test URL and record the browser URL at the initial landing page and after every redirect.
    3. Locate the first loss. Check link templates, shorteners, server redirects, cross-domain handoffs, consent flows, and landing-page scripts. The first point where the parameter disappears is more useful than the final unattributed session.
    4. Use generated identifiers as intended. Do not invent or reconstruct privacy-related identifier values. Preserve the parameters supplied by the advertising platform and follow its remediation guidance.
    5. Verify collection after the repair. Repeat the same controlled route and confirm that the identifier survives the handoffs and reaches the intended analytics setup.
    6. Annotate the affected period. Record when the issue began, when it was discovered, what scope was affected, and when the fix was verified. Historical reports may remain incomplete even after new traffic is measured correctly.

    The diagnostic identifies a data-quality symptom; it does not automatically identify the root cause or restore missing history. It also does not prove that every unattributed conversion belongs to the affected campaign. Use it to narrow the investigation, then validate the actual path.

    Track a simple completeness rate after the fix: eligible records containing the expected campaign evidence divided by all eligible records. The useful comparison is the rate over time and across equivalent paths. There is no universal threshold that can tell you whether your particular implementation is healthy.

    Run a blind-spot audit around decisions, not dashboards

    A generic analytics audit can produce a long list of tidy fields without protecting an important decision. Start with the decision that could move money: whether to scale a campaign, pause a channel, invest in AI visibility, or change the content program.

    Then audit the evidence in this order:

    1. Write the decision in one sentence. Name the investment being evaluated, the outcome that matters, and the reporting period. This prevents convenient metrics from replacing the business question.
    2. Draw the observable path. Map exposure, click, landing page, conversion, lead record, opportunity, purchase, and revenue. Mark which system owns each event.
    3. Mark every join. Identify the field that connects one stage to the next. If no shared key exists, label the gap instead of assuming the systems reconcile.
    4. Reconcile adjacent counts. Compare platform interactions with analytics visits, visits with form completions, form completions with CRM leads, and closed outcomes with reported revenue. You are looking for a structural break, not perfect equality between systems that measure different events.
    5. Test one known path. Use a controlled journey to confirm that the expected campaign context survives each relevant handoff. A dashboard total cannot show you where an individual field disappeared.
    6. Classify the evidence. Separate directly observed, successfully joined, inferred, and unknown data. Display the classification beside the metric used for the decision.
    7. Assign the gap. Give each material blind spot an owner, a next check, and a verification condition. “Improve attribution” is not an action; “confirm that GBRAID survives the landing-page redirect” is.

    Keep a blind-spot register with seven fields: decision at risk, missing evidence, affected systems, suspected break, owner, next verification, and confidence level. This turns uncertainty into a manageable queue instead of burying it in a dashboard footnote.

    Evidence labels also make budget conversations more honest:

    • Directly observed: The event was recorded in the system where it occurred.
    • Joined: Records were connected using a defined key across systems.
    • Inferred: The relationship is plausible and supported by directional evidence, but the individual path is not observed.
    • Unknown: The necessary evidence is missing or contradictory.

    Attribution and causality must remain separate. Attribution assigns credit under a chosen rule. It does not, by itself, establish what would have happened without the marketing activity. If a large investment requires a causal answer, use a controlled experiment where one is feasible and keep its result separate from the attribution model.

    Use a few firm decision rules. Do not declare a campaign decline while its expected identifiers are missing. Do not call growing AI citations revenue merely because branded demand also rose. Do not call unattributed traffic organic, direct, or AI-derived without evidence. When visibility, identifiable visits, self-reported discovery, and connected outcomes move in the same direction, confidence improves, but the pattern is still not automatic proof of causation.

    Key takeaways

    • An attribution report describes the observable trail, not every influence on the customer.
    • Measure AI visibility, identifiable traffic, and business outcomes as separate layers with separate denominators.
    • Treat missing GBRAID, gad_, or other expected campaign evidence as a data-quality issue before evaluating campaign quality.
    • Preserve original and later source fields instead of overwriting one with the other.
    • Label evidence as observed, joined, inferred, or unknown so decision-makers can see how much confidence a metric deserves.
    • Use attribution to allocate recorded credit; use controlled testing when you need a causal answer.

    Before your next budget review, choose the highest-consequence campaign and trace one complete path from exposure to revenue. At the same time, choose one AI discovery use case and build its three-layer view. Fix any broken handoff first. Then make the investment decision with the blind spots visible rather than pretending they are not there.

    References


  • Brand vs. Non-Brand Paid Search: A Structure for Growth

    Brand vs. Non-Brand Paid Search: A Structure for Growth

    You open Google Ads and see a healthy return on ad spend, yet total revenue and new-customer growth are barely moving. Before you approve more budget, you need to know how much paid search is reaching people who were not already looking for your business.

    You cannot answer that from a campaign that mixes brand and non-brand traffic. These searches serve different audiences, respond to different economics, and deserve different budgets. Separating them turns ROAS from a flattering account average into information you can actually use.

    Why one ROAS number cannot answer two different questions

    A branded query contains your company, product-line, or owned brand name. It expresses prior awareness: the searcher already knows enough about you to ask for you. A non-brand query describes a product, category, problem, or desired outcome without naming your business. It gives you a chance to reach someone who has not yet chosen a brand.

    Those two query classes answer different commercial questions. Brand campaigns ask how efficiently you can capture and protect existing demand. Non-brand campaigns ask whether you can acquire customers and revenue beyond the people already seeking you out.

    When both live inside one campaign, automated bidding is rewarded for finding the easiest route to its target. Branded searches are often cheaper and more likely to convert, so an algorithm optimizing toward short-term ROAS has a strong incentive to favor them. Brand consumes more of the budget, the campaign reports impressive efficiency, and harder non-brand opportunities receive less exposure.

    The blended ROAS calculation may be arithmetically correct, but it is managerially misleading. It cannot tell you whether paid search created an incremental sale, intercepted a customer who would otherwise have clicked your organic result, or merely claimed the final touch after another channel created the demand.

    Key takeaways

    • Use separate campaigns, budgets, and reporting for brand and non-brand traffic.
    • Give brand spend a defined capture or protection role rather than allowing it to maximize blended ROAS.
    • Organize non-brand campaigns around the products and categories the business wants to grow.
    • Do not require brand and non-brand campaigns to meet the same efficiency target.
    • Judge a restructure through new customers and combined paid-plus-organic results, not paid-search revenue alone.

    Build boundaries that survive real search behavior

    A magnifying-lens gateway and layered filters sort abstract search tokens into separate amber and blue campaign channels.

    Separating campaigns starts with a query taxonomy, not a naming convention. Renaming one campaign Brand and another Non-Brand achieves nothing if branded searches can still enter both, the campaigns share a budget, or their bidding goals continue to reward the same behavior.

    Traffic classWhat belongs in itPrimary jobWhat it should not prove
    BrandCompany names, owned product lines, common name variants, and brand-plus-product searchesCapture known demand and protect valuable brand resultsThat paid search generated all credited demand
    Non-brandGeneric products, categories, problems, features, and use cases without an owned brand nameReach prospective customers and expand category revenueThat it can match the conversion rate of people already seeking the brand
    Competitor or ambiguousOther companies’ names or queries whose commercial meaning cannot be classified cleanlySupport a distinct competitive strategy or remain separately measurableThat its economics represent either pure brand or pure non-brand demand

    The third row matters because forcing every query into a binary bucket can contaminate both benchmarks. Competitor queries are non-brand in the literal sense, but their intent, cost, and landing-page needs may differ sharply from generic category discovery. If they have meaningful volume, report them separately.

    Use this sequence to create the boundary:

    1. Define your owned-name set. Include the company name, owned product and service names, common variants, and queries that combine those names with a category term.
    2. Classify actual search terms. A keyword list describes what you targeted; the search-term data shows what entered the auction. Label the meaningful terms as brand, non-brand, competitor, or unresolved.
    3. Route traffic deliberately. Apply the negative-keyword, exclusion, inventory, or listing-group controls available to each campaign type. Where query control is limited, reinforce the separation through distinct inventory, goals, budgets, and campaign roles.
    4. Remove shared incentives. Give brand and non-brand their own budgets and performance expectations. Otherwise, the more efficient traffic can continue to absorb money intended for acquisition.
    5. Audit leakage after the change. Review search terms and product distribution once the new structure has begun receiving traffic. Reclassify edge cases instead of assuming the initial rules caught every variant.

    Pay special attention when your brand name includes a generic product term. Names such as Mattress Firm or Guitar Center can create more classification and defense pressure than an invented name. Write down how you will treat exact owned-name intent, broad category intent, and queries that could plausibly mean either one.

    Give brand spend a job, not a blank check

    Separating brand traffic does not mean turning it off. It means deciding what you are paying it to do.

    Brand advertising can be valuable when competitors are bidding around your name, when Shopping placements could show rival products, or when you need precise control over an offer and landing destination. In competitive categories, removing brand coverage without testing can surrender prominent paid space even while your organic result remains visible.

    The opposite mistake is treating every branded conversion as incremental. Many branded searchers were already looking for you. If the paid ad had not appeared, some might have clicked an organic result or another owned listing. That does not make the ad worthless; it means platform-attributed revenue and revenue caused by the ad are not automatically the same number.

    Set brand policy by answering four questions:

    • What are you defending? Record whether competitors or marketplace listings occupy important paid placements around your owned terms.
    • What can organic search retain? Compare branded paid and branded organic outcomes together rather than assuming every lost ad click becomes a lost sale.
    • What is the spending limit? Give brand a separate budget ceiling tied to its capture or protection role. Do not let it draw from acquisition funds merely because it can produce a higher ROAS.
    • Whom are you converting? Where customer-status data is reliable, separate new from returning customers. A brand campaign dominated by existing customers should not be presented as proof of acquisition.

    If brand spend looks excessive, reduce it in controlled stages rather than shutting it off abruptly. Watch paid brand revenue, branded organic revenue, combined Google revenue, total new customers, and visible competitive pressure. Keep major promotions and unrelated account changes out of the test where practical, and let the evaluation cover the buying cycle that matters to your business.

    A decline in paid brand conversions is not, by itself, evidence that the test failed. If organic captures much of the displaced demand and total revenue holds, you may simply have stopped paying for some navigational clicks. If organic does not recover the loss and total business results weaken, the cut may have gone too far. That is why the safe decision comes from the combined outcome, not a philosophical position that brand bidding is always good or always wasteful.

    Make non-brand campaigns accountable for growth

    Once brand has its own budget, non-brand traffic finally has room to compete. The next risk is recreating the same problem at the product level by placing an entire catalog into one broad campaign and allowing automation to favor only the products with the strongest existing history.

    That structure can maximize near-term efficiency while starving emerging categories, lower-volume products, and strategic lines that need exposure before they can build performance data. Broad catalog management effectively asks the advertising platform to decide which parts of your business matter most. Its answer will follow the campaign objective, not your merchandising or growth plan.

    Build non-brand segmentation from commercial priorities:

    • Separate strategic categories from the general catalog so they have protected budgets.
    • Isolate newer or underexposed product groups when the business has deliberately chosen to develop them.
    • Group products closely enough that bids, landing pages, and search intent can be managed coherently.
    • Keep established volume drivers visible, but do not let their history prevent other priority products from entering auctions.
    • Document the business reason for each segment. If no one can explain why a segment deserves distinct budget or control, it may not need its own campaign.

    Standard Shopping can be useful when you need stronger product-level control over bidding and budget. Performance Max can serve a narrower acquisition role rather than being asked to manage brand capture, generic discovery, and every product priority at once. One workable division of labor is to pair granular Standard Shopping campaigns with Performance Max’s New Customer Acquisition setting, where that setting is available and supported by reliable customer data.

    Treat that as an account-design pattern, not a universal template. The important principle is that each campaign receives one intelligible job. If Performance Max is responsible for customer acquisition, evaluate it against that job. If Standard Shopping is responsible for protecting investment in priority product groups, verify that those groups actually receive traffic and budget.

    Do not force non-brand campaigns to match brand ROAS. A person searching generically is less committed to your business than a person typing its name. Set a commercially acceptable acquisition constraint, then judge whether the campaign is producing new customers, non-brand revenue, and strategic category growth. If you demand brand-like efficiency immediately, automation will either retreat to the easiest available demand or stop competing where acquisition is possible.

    Campaign structure cannot rescue a poor journey. Match category intent to a useful category page, product intent to the relevant product experience, and problem-led intent to a page that resolves the searcher’s uncertainty before demanding a purchase. When non-brand performance is weak, inspect the search term, product, offer, and landing page as a connected path instead of treating the bid as the only lever.

    Read the business result without declaring the wrong winner

    Two color-coded campaign channels deliver different patterns of conversion and customer-growth tokens into a shared business outcome basin.

    A brand and non-brand restructure often makes the paid-search dashboard look worse before it makes the business easier to understand. Removing inexpensive branded conversions from an acquisition campaign lowers blended ROAS by design. That is not proof of failure. It is the expected effect of exposing the true cost of reaching less familiar customers.

    Build a scorecard with three layers:

    • Brand capture: brand spend, paid brand revenue or conversions, branded organic performance, customer status where reliable, and competitive presence.
    • Non-brand acquisition: non-brand spend, revenue, ROAS or acquisition cost, new customers, search-term quality, and product or category coverage.
    • Business outcome: combined paid and organic Google revenue, total new customers, total revenue, and the profit or contribution measure your business actually manages.

    This wider view also reduces attribution errors. A brand search can be the final step after CTV, programmatic, organic discovery, or another channel introduced the business. Without a broader attribution method such as marketing mix modeling, brand campaigns can receive credit for demand created elsewhere. The ad platform can report the conversion following a click; that alone does not establish what caused the customer to search for the brand.

    One documented account restructure shows how dramatically the interpretation can change. Paid-search revenue fell 25% year over year, or about $2.3 million, while Google organic revenue rose 99%, combined Google paid and organic revenue rose 15%, and new-customer acquisition rose 20%. That is one account, not a benchmark or a promise. Its value is diagnostic: paid revenue alone would have labeled the change a loss even though the broader business measures moved in the intended direction.

    Use directional patterns to decide what to do next. If paid brand revenue falls while branded organic revenue rises and combined results hold, substitution is a plausible explanation. If non-brand investment and new-customer acquisition rise alongside total revenue, a lower paid-search ROAS may be an acceptable cost of growth. If brand cuts are not recovered elsewhere and total results weaken, restore coverage selectively. If non-brand spend rises without acquisition or category progress after a representative buying cycle, examine targeting, segmentation, economics, offer, and landing experience rather than hiding the weakness beneath brand conversions.

    Before your next budget decision, require one page that shows brand performance, non-brand performance, combined paid and organic Google results, and new customers as separate lines. Do not approve growth spending from blended ROAS alone. Once each campaign has a distinct job and scorecard, you can fund acquisition without confusing captured demand for created growth.

    References


  • AI Search Visibility: A Strategy for Mentions and Demand

    AI Search Visibility: A Strategy for Mentions and Demand

    Your organic traffic can fall while your brand’s influence grows. The reverse can happen too. An AI answer may use your page as evidence without naming you, mention you without linking, or cite you before recommending a competitor. If your dashboard labels all three outcomes “AI visibility,” you won’t know what to fix.

    Your real job is to make your brand an easy, defensible choice and then measure whether it becomes one across repeated buying and research questions. That requires a different operating model from conventional rank tracking.

    Optimize for selection, not a familiar search position

    Classic SEO usually gives you a visible sequence: ranking, impression, click, session, conversion. AI search can compress that sequence into a generated answer. The user may finish the task without visiting a site, so a click-only report can miss the moment when your brand entered or left the consideration set.
    The scale and shape of the behavior have already changed. AI Mode reached 1 billion monthly active users, with queries around three times longer than classic searches. Longer prompts often contain the user’s situation, constraints, and desired outcome. They give an answer engine more room to compare options and make a recommendation rather than return a generic list of links.

    Whether your team calls the work AEO, GEO, or AI Visibility Optimization, separate these outcomes:

    • Citation: Your domain or page is linked as supporting evidence.
    • Mention: Your brand, product, or expert is named in the answer.
    • Shortlist inclusion: Your brand appears among the options a user is invited to consider.
    • Recommendation: The answer explicitly presents your brand as a suitable or preferred choice for the user’s conditions.
    • Accurate representation: The answer describes your offer, audience, strengths, limits, and availability correctly.

    A citation can help even when your brand isn’t named, because it supplies evidence to the answer. But a commercial brand usually gains more from being named accurately and recommended in the right context. A publisher may place more weight on citations and referred sessions. A software vendor, retailer, professional service, or local business should usually place more weight on shortlist inclusion, recommendation, and representation.

    Position still matters, but it isn’t the whole decision. Close to 75% of consumers in the reported behavior data chose the first option in an AI shortlist. A trusted brand appearing elsewhere on the list could nevertheless override that position. That gives you two distinct jobs: improve the likelihood of being selected by the system and build enough recognition that the user selects you even when you aren’t listed first.

    Define the business outcome before choosing an AI visibility metric. If you need discovery, track qualified mentions. If you need consideration, track shortlist inclusion and context. If you need authority or publisher traffic, track citations. If you need sales, connect recommendation exposure to branded demand, assisted conversions, qualified opportunities, and revenue without pretending every correlation is causal.

    Measure a prompt panel, not a single artificial rank

    Multiple blank query tiles feed signals into a transparent instrument that separates them into several distinct visibility outcomes, while one isolated pedestal sits apart.

    An AI answer isn’t a stable search result. Engine choice, model changes, reasoning settings, personalization, prompt wording, and stochastic variation can all change the output. Citation overlap is especially fragmented: 91% of citations appeared in only one of ChatGPT, Perplexity, or AI Overviews. A win in one surface doesn’t prove broad visibility, and one missing mention doesn’t prove that your optimization failed.

    Treat prompt monitoring more like recurring audience research than a daily position check. You are estimating how often and how favorably your brand appears within a defined set of decisions.

    Build the panel in this order:

    1. Start with a real decision. Use the questions that precede a purchase, sign-up, visit, specification, or vendor shortlist. A vague informational prompt may generate volume but reveal little about commercial visibility.
    2. Create prompt families. Cover category discovery, use cases, constraints, alternatives, comparisons, risk questions, and branded validation. Keep the intent stable while varying natural phrasing.
    3. Separate surfaces. Record ChatGPT, Perplexity, AI Overviews, AI Mode, or any other relevant experience independently. Don’t average unlike interfaces into one score.
    4. Preserve the conditions. Save the exact prompt, date, engine or mode, login state, relevant location, response, citations, and model details when they are visible. Without that record, a later difference is impossible to interpret.
    5. Repeat the sample. Compare distributions across the panel and over time. Don’t turn one favorable answer into a success claim or one unfavorable answer into a crisis.

    Your scorecard should answer different questions rather than collapse everything into a proprietary visibility number.

    SignalQuestion it answersPractical recording rule
    Mention rateAre we present?Share of eligible sampled answers that name the brand or product.
    Recommendation rateAre we endorsed?Share that explicitly recommends the brand for the stated need.
    First-choice shareDo we lead shortlists?Share of ordered shortlists in which the brand appears first.
    Citation rateIs our site used as evidence?Share of answers with citations that link to your domain.
    Context qualityWhy are we being named?Code each appearance as supportive, neutral, cautionary, or excluding, and retain the exact surrounding sentence.
    Representation accuracyCan a buyer rely on the answer?Check material facts such as audience, capabilities, limitations, location, availability, and pricing model when public.
    Competitor outcomeWho wins the same decision?Record the competing brands, their order, and the reason the answer gives for selecting them.

    Keep the raw responses. A rising mention rate can conceal deteriorating context, such as repeated descriptions of your product as an unsuitable option. Conversely, a lower citation rate may be less concerning if recommendation rate and qualified branded demand are rising. The underlying answer explains what the aggregate metric cannot.

    Give answer engines evidence they can use and reconcile

    You can’t force a model to cite or recommend you. You can reduce the work required to understand your entity, verify your claims, and match your offer to a specific need. That starts with information quality, not a new acronym.

    Make the owned-site answer explicit

    Pages built to satisfy a keyword can still be poor inputs for an answer engine. A long introduction, repeated category language, and an implied conclusion make the useful information expensive to extract. Content intended for AI discovery should lead with distinctive information, use direct language, remove filler, and remain fast and easy to access.

    Audit commercially important pages for the following:

    • A direct answer: State what the product, service, or page is for near the beginning. Don’t make the reader infer the category from marketing language.
    • Decision criteria: Explain who it is for, when it fits, when it doesn’t, what it requires, and how it differs from plausible alternatives.
    • Distinctive evidence: Publish facts only you can supply, such as original data, documented methodology, product specifications, implementation requirements, limitations, or clearly attributed expert knowledge.
    • Claim support: Put evidence close to the claim it supports. Avoid sending a machine or reader through several pages to determine whether a statement is substantiated.
    • Entity consistency: Use the same official names and material facts across product, company, author, location, support, and policy pages. Resolve outdated descriptions rather than letting contradictory versions coexist.
    • Accessible delivery: Keep essential text in crawlable HTML, return the correct status code, use coherent canonical URLs, provide internal links, and avoid placing the only useful answer behind an interaction a crawler may not complete.

    Structured data belongs in this system, but it has a limited role. Use relevant schema types such as Organization, Product, Service, Article, or FAQPage only when the visible page supports them. Keep names, identifiers, authorship, dates, offers, and relationships consistent with the page. Valid JSON-LD can reduce ambiguity; it cannot manufacture trust, replace missing evidence, or guarantee a mention.

    Build a corroboration footprint beyond your domain

    The low citation overlap between engines makes a one-domain strategy brittle. Different systems may assemble answers from different parts of the web, even when responding to similar prompts. Your brand therefore needs consistent, verifiable representation in the places relevant audiences and systems are likely to encounter it.

    Create a claim ledger for the facts that influence selection: what you offer, which audience you serve, where you operate, what differentiates the offer, what limitations apply, and which evidence supports each claim. Then check your site, public profiles, partner listings, documentation, interviews, reputable editorial coverage, and other legitimate references for contradictions. Correct records you control and pursue clarification where an important third-party description is materially wrong.

    Don’t try to create a large volume of shallow mentions. Repetition without independent substance can multiply inconsistent claims. Concentrate on accurate descriptions in contexts that help a buyer make the same decision represented by your prompt panel.

    Connect AI visibility to demand without inventing attribution

    Glowing visibility signals cross a layered bridge, merge with other paths, and reach people comparing unbranded products.

    Referral sessions are useful, but they aren’t a complete denominator for AI impact. A generated recommendation can lead to a later branded search, a direct visit, a marketplace search, or an offline conversation. The original answer may receive no conversion credit.

    Behavior also differs by surface. Users in AI Overviews tend to click, evaluate, and compare in a pattern closer to conventional search. In AI Mode product interactions, users accepted the recommendation as the best available option 88% of the time in the reported behavior data. That finding shouldn’t be treated as a universal rate for every audience or prompt, but it shows why an AI Overview click-through rate and an AI recommendation rate do not measure the same behavior.

    Report AI search through three connected layers:

    • Answer visibility: Mentions, recommendations, shortlist positions, citations, context, accuracy, and competitor outcomes from the prompt panel.
    • Audience response: AI referral sessions, branded search demand, direct visits, engaged visits to relevant landing pages, return visits, and on-site actions associated with the same topic.
    • Commercial outcomes: Qualified leads, assisted conversions, opportunities, sales, retention signals, or another business result appropriate to the decision.

    Use a shared topic or decision label across these layers. If you improve evidence for an enterprise-security question, compare it with the matching prompt family, related landing pages, branded query patterns, and qualified opportunities. A sitewide traffic total is too broad to show whether that work mattered.

    For a defensible evaluation, record the date and scope of each content, schema, technical, digital PR, or positioning change. Establish the prompt-panel baseline before the change. Compare the targeted prompt family with an untreated topic where possible, then inspect answer visibility and downstream behavior over the same period. Model updates and outside campaigns can still affect the result, so label the conclusion as directional unless you have a credible control.

    Present value as a range rather than a single overconfident ROI figure. The lower bound can include directly attributable conversions from identifiable AI referrals. A broader view can include assisted journeys and qualified branded demand that coincide with stronger recommendation visibility. Set those figures beside the cost of research, content, technical work, distribution, and monitoring. Keep observed value separate from inferred value so decision-makers can see where the uncertainty sits.

    This is why AI optimization behaves like a brand channel even when the team manages it like performance marketing. The system’s recommendation can shape demand before your analytics platform sees a session. Measurement must preserve that influence without claiming causation the data cannot support.

    Key takeaways for your next visibility cycle

    • Choose the outcome that fits your business: citation, mention, shortlist inclusion, recommendation, accurate representation, or a defined combination.
    • Track a stable family of commercial and informational prompts across each relevant AI surface. Evaluate distributions, not isolated answers.
    • Record context and competitor reasoning alongside presence. Being named for the wrong reason is not a visibility win.
    • Publish direct, distinctive, supported information and make it technically accessible. Remove contradictions across pages and public profiles.
    • Use structured data to clarify entities and relationships, not as a promise of citations or recommendations.
    • Connect answer-level changes to matched audience and commercial indicators. Distinguish directly observed value from inferred influence.

    Start with one commercially important decision your buyers already face. Build its prompt family, establish the baseline across the relevant surfaces, and identify the exact reason competitors are selected. Improve the content, evidence, entity data, or corroboration tied to that reason, then sample the same panel again before expanding the program. That gives you a strategy you can learn from, rather than a visibility score you can only watch.

    References


  • Google Ads Bidding and Measurement: A Practical Framework

    Google Ads Bidding and Measurement: A Practical Framework

    You can choose a sensible Google Ads bid strategy and still make a bad budget decision. A campaign may hit its reported return target while capturing customers who were likely to buy anyway. Another may create additional sales but receive too little credit because part of the journey happened outside the platform’s view.

    The fix is to stop asking one metric to do three jobs. Give Smart Bidding a clean outcome to optimize, use attribution to steer observable campaign performance, and use incrementality to decide whether the spend created business that would not otherwise exist.

    Key takeaways

    • A bidding strategy is a control system, not proof that advertising caused the conversions it reports.
    • Use Target CPA when conversions have comparable value and acquisition cost is the meaningful constraint. Use Target ROAS when conversion values differ materially and those values are trustworthy.
    • Maximize Conversions and Maximize Conversion Value express volume-first objectives; adding a target introduces an efficiency constraint.
    • Attribution decides how observed touchpoints receive credit. Incrementality estimates how many additional outcomes advertising caused.
    • When Google Ads, analytics, and your business system disagree, reconcile their definitions before changing bids or budgets.

    Choose the bidding strategy from the business decision

    If your account shows Target CPA and Target ROAS as separate choices, do not assume Google has introduced entirely new bidding mechanics. Some accounts are showing a revised campaign-setup menu in which those targets sit beside Maximize Clicks, Maximize Conversions, Maximize Conversion Value, Target Impression Share, and Manual CPC. Previously, advertisers generally selected a maximize strategy and then applied the corresponding optional target. The observed change appears to affect presentation rather than how the strategies function.

    The clearer menu is useful because it forces an important distinction: do you want the system to pursue as much volume as the budget allows, or do you want it to pursue volume while steering toward an efficiency target? Answer that before you touch the campaign settings.

    Your actual objectiveRelevant bidding familyWhat must be trueMain measurement risk
    Generate as many valuable actions as possible within the available budgetMaximize ConversionsThe counted conversions represent outcomes you genuinely want more ofLow-quality and high-quality actions may be treated alike
    Generate conversions while steering toward an acceptable average acquisition costTarget CPAConversions have reasonably comparable business value, and the target reflects your economicsA reported CPA can look healthy while lead quality deteriorates
    Generate the greatest total conversion value within the available budgetMaximize Conversion ValueThe values sent to the bidding system reflect meaningful differences between outcomesIncorrect or inflated values can direct spend toward the wrong actions
    Generate conversion value while steering toward a return-on-ad-spend targetTarget ROASRevenue or another defensible value signal is available and consistently definedAttributed ROAS may be mistaken for incremental profit
    Acquire visits rather than downstream outcomesMaximize ClicksTraffic itself is the immediate objective, or downstream measurement is not yet usableMore clicks can conceal weak commercial performance
    Reach a desired level of search visibilityTarget Impression ShareVisibility is the stated objective and is evaluated separately from conversionsPresence on the results page may be mistaken for business impact
    Control bids directlyManual CPCYour team has a specific reason to manage bid-level tradeoffs itselfManual control does not repair weak conversion tracking or prove causality

    A target is a steering goal, not a promise for every auction or conversion. Target CPA does not mean every conversion will cost exactly the target. Target ROAS does not mean every segment, query, or transaction will achieve the same return. Evaluate whether the strategy is serving the portfolio-level objective you gave it.

    Use this sequence when choosing or revisiting the setting:

    1. Name the outcome. Decide whether the campaign is meant to generate purchases, qualified leads, booked appointments, visits, or visibility. Do not substitute the metric that is easiest to collect.
    2. Name the constraint. Decide whether budget, acquisition cost, return on spend, or coverage is the binding condition.
    3. Inspect the signal. Confirm that the conversion event and its value distinguish desirable outcomes from incidental activity.
    4. Select the matching bidding family. Use a conversion-volume strategy for comparable actions and a value strategy when the outcomes have materially different worth.
    5. Write down the hypothesis. State what should improve and which business metric will confirm it. This prevents a later interface metric from silently replacing the original goal.

    Give Smart Bidding a measurement contract

    Abstract ad signals pass through a filtering chamber before clean conversion signals reach an automated bidding mechanism.

    Automated bidding cannot decide which business outcome matters. It can only optimize the signals it receives. Before evaluating a bid strategy, create a short measurement contract for every conversion action used in bidding.

    Define what one conversion means

    • Event: Identify the exact action, such as an order, a submitted lead form, or a qualified opportunity.
    • Eligibility: State what makes the event valid and which duplicates, tests, cancellations, spam submissions, or internal activity are excluded.
    • Counting rule: Decide whether repeated actions by the same person represent separate business outcomes.
    • Value rule: Specify whether the value is revenue, a margin-aware amount, an expected lead value, or a clearly labelled weighting system.
    • System of record: Name the platform, analytics property, CRM, commerce system, or finance record that owns the final business result.
    • Observation point: Record when the outcome becomes reliable. A form submission, a qualified lead, and a closed sale occur at different stages.
    • Attribution rule: State which interactions can receive credit and which model distributes that credit.

    This contract exposes a common bidding error: treating events with very different commercial meaning as interchangeable conversions. If a form submission and a qualified opportunity both influence the same campaign, either separate their roles or assign values that reflect the distinction. Do not report an internal weighting as revenue merely because it is useful to the bidding system.

    Reconcile definitions instead of averaging conflicting reports

    Google Ads, web analytics, and your customer or commerce system will not necessarily report matching totals. Each can observe different interactions, apply different eligibility rules, and assign credit differently. A mismatch is a diagnostic clue; it does not automatically prove that one system is broken.

    When the totals diverge, compare these fields side by side:

    • The event being counted and the point in the customer journey where it occurs.
    • The included campaigns, channels, devices, audiences, and conversion actions.
    • The touchpoints each system can observe.
    • The attribution model and the interactions eligible for credit.
    • Whether results are assigned to an interaction date, conversion date, or later business milestone.
    • The treatment of duplicate events, cancellations, invalid leads, refunds, and later adjustments.
    • The definition of value, including whether it represents gross revenue, another business amount, or a modelled weight.
    • The delay between the advertising interaction and the final outcome.

    Do not change the bid target merely to make one report resemble another. First determine whether the systems are counting the same event under the same rules. If they are not, document the difference and assign each report a specific job.

    Use attribution to steer and incrementality to fund

    A split illustration shows customer paths passing through an attribution prism beside two matched markets used for an incrementality test.

    Attribution and incrementality answer different questions. Treating them as competing versions of one metric leaves you with a weak optimization system and a weak budget case.

    Attribution explains credit within the observed journey

    A conversion path can include display, paid social, organic search, email, and a purchase. Attribution decides which of those observed interactions receives credit and how much. In a simplified example, the same $100 conversion could give all $100 to display under first-touch attribution, all $100 to email under last-touch attribution, or divide the value across the path under a multi-touch model. Changing the model changes the allocation; it does not change the underlying sale.

    Use attribution for questions such as:

    • Which observable campaigns and touchpoints are associated with conversions?
    • Where do customers enter and continue through the measurable journey?
    • Which ads, queries, audiences, or landing experiences deserve closer inspection?
    • How should reported credit be distributed when several measurable interactions precede one conversion?

    Attribution is therefore useful for ongoing campaign steering. Its blind spot is causality. Receiving credit does not prove that the touchpoint created a sale that would otherwise have been lost.

    Incrementality estimates what advertising caused

    Incrementality asks what happened because of the marketing activity, above what would have happened without it. The basic design compares an exposed group with an equivalent control group that is not exposed to the activity being tested.

    Consider a simplified test that runs for 30 days. The exposed group completes 1,000 purchases while the control group completes 800. The estimated lift is 200 purchases. An attribution system might associate many or all of the 1,000 purchases with campaign touchpoints, while the controlled comparison identifies 200 additional purchases. The 30-day period and those totals illustrate the method; they are not universal requirements for your test.

    A credible incrementality test needs a defensible control, comparable groups, a predeclared outcome, and protection against unrelated changes that would distort the comparison. Choose a test duration that fits the actual decision and conversion cycle. Also account for the cost of holding out exposure: incrementality tests can be slow, expensive, or difficult to design, especially when audiences overlap or the business cannot isolate treatment cleanly.

    Decision in front of youPrimary evidenceHow to use it
    Which observable campaign element should be optimized?Attribution and campaign diagnosticsReallocate attention within the measurable campaign system
    How did measurable touchpoints share credit?AttributionInterpret customer paths and reported channel contribution
    Did the advertising create additional conversions?IncrementalityEstimate lift against an appropriate counterfactual
    Should the business expand, defend, reduce, or redesign the budget?Incrementality combined with business economicsJudge the value of the additional outcomes, not merely attributed volume
    Which signal should Smart Bidding optimize?Clean attributed conversion data aligned with the business objectiveGive the bidding system a frequent, operational signal while evaluating causal impact separately

    This division of labor matters. Incrementality is too coarse and test-dependent to explain every touchpoint in an individual journey. Attribution is too dependent on observed interactions and modelling choices to prove that the spend caused additional demand. You need both because the questions are different.

    Put bidding and measurement into one operating loop

    A durable Google Ads process connects campaign configuration to business validation without pretending that one dashboard contains the whole answer.

    1. Set the business objective. Name the outcome and the economic constraint before selecting the bid strategy.
    2. Create the measurement contract. Define event eligibility, counting, value, ownership, timing, and attribution.
    3. Choose the bidding family. Match conversion volume, conversion value, traffic, visibility, or manual control to the stated objective.
    4. Validate the input. Check for duplicated events, missing business outcomes, invalid leads, misleading values, and unexplained reporting gaps.
    5. Steer with attribution. Use observable campaign and journey data to improve the parts of the system you can measure directly.
    6. Validate budget impact with incrementality. When the size or strategic importance of the decision justifies a controlled test, measure additional outcomes against a counterfactual.
    7. Return the result to planning. Adjust budgets and future tests using incremental business value while retaining attribution as the operational optimization layer.

    Avoid changes that destroy your ability to learn

    • Do not change the bid strategy, conversion definition, and value rules at the same time. You will not know which change produced the result.
    • Do not tighten a CPA or ROAS target to compensate for inflated or low-quality conversion data. Repair the signal first.
    • Do not judge a recent change from outcomes that have not had time to reach the business stage named in your measurement contract.
    • Do not defend a budget using platform-attributed ROAS alone when the real question is whether the spend caused additional value.
    • Do not discard attribution because it is not causal. It remains the practical tool for distributing observable credit and steering campaigns.
    • Do not treat an incrementality result as permanent. It answers a defined test under defined conditions and should inform the decision that test was built to support.

    Your next step is small but revealing: open one campaign and complete this sentence before changing any setting: We ask Google Ads to optimize [outcome] subject to [constraint], steer it using [attribution definition], and approve its budget using [business result or incremental evidence]. If you cannot fill in all four blanks unambiguously, the bidding problem is still a measurement problem.

    References