Tag: Attribution Models

  • How to Migrate Google Ads Conversion Tracking Safely

    How to Migrate Google Ads Conversion Tracking Safely

    Your Google Ads reports can look normal right up until an import starts being rejected. If your server-side or offline conversion pipeline includes session attributes or IP address data, the weak point is now the route those fields take, not necessarily the conversion event itself.

    The safest response is a controlled handoff. Identify every affected import, move the restricted data to the Data Manager API, verify the new route without counting the same event twice, and retire the old path only after reporting and error handling are stable.

    First, prove that your conversion import is affected

    This is not a blanket shutdown of every Google Ads API conversion workflow. The immediate trigger is narrower: new users of session attributes or IP address data cannot send those fields through Google Ads API conversion imports. Existing implementations may continue for now, but continued acceptance should not be treated as a permanent architecture guarantee.

    Start with the payload your system actually sends. A design document or old integration ticket may not reflect production behavior, especially if another team added enrichment fields later.

    • Find every sender. Inventory scheduled jobs, CRM connectors, server-side services, data warehouses, tag-management servers, and vendor integrations that import conversions through the Google Ads API.
    • Inspect the request definition. Check the serialized payload, mapping configuration, or schema for session attributes and IP address fields. Inspect field presence without copying raw IP addresses or user data into an audit spreadsheet.
    • Map the affected scope. Record which Google Ads customers and conversion actions receive data from each sender.
    • Identify the developer token. The restriction is tied to allowlisting, so two integrations serving the same advertiser may behave differently if they use different credentials.
    • Search error telemetry. Look specifically for CUSTOMER_NOT_ALLOWLISTED_FOR_THIS_FEATURE rather than relying on a generic failed-jobs total.
    • List downstream users. Note which reports, alerts, budget decisions, and automated bidding strategies depend on the imported conversions.

    You should finish this audit with one of three classifications. If neither field is present, this particular restriction is not an immediate migration trigger. If you are building a new implementation that needs either field, design it around the Data Manager API before launch. If an existing allowlisted implementation still works, use that continuity as a migration window rather than a reason to postpone the work.

    Treat the change as a data-route migration
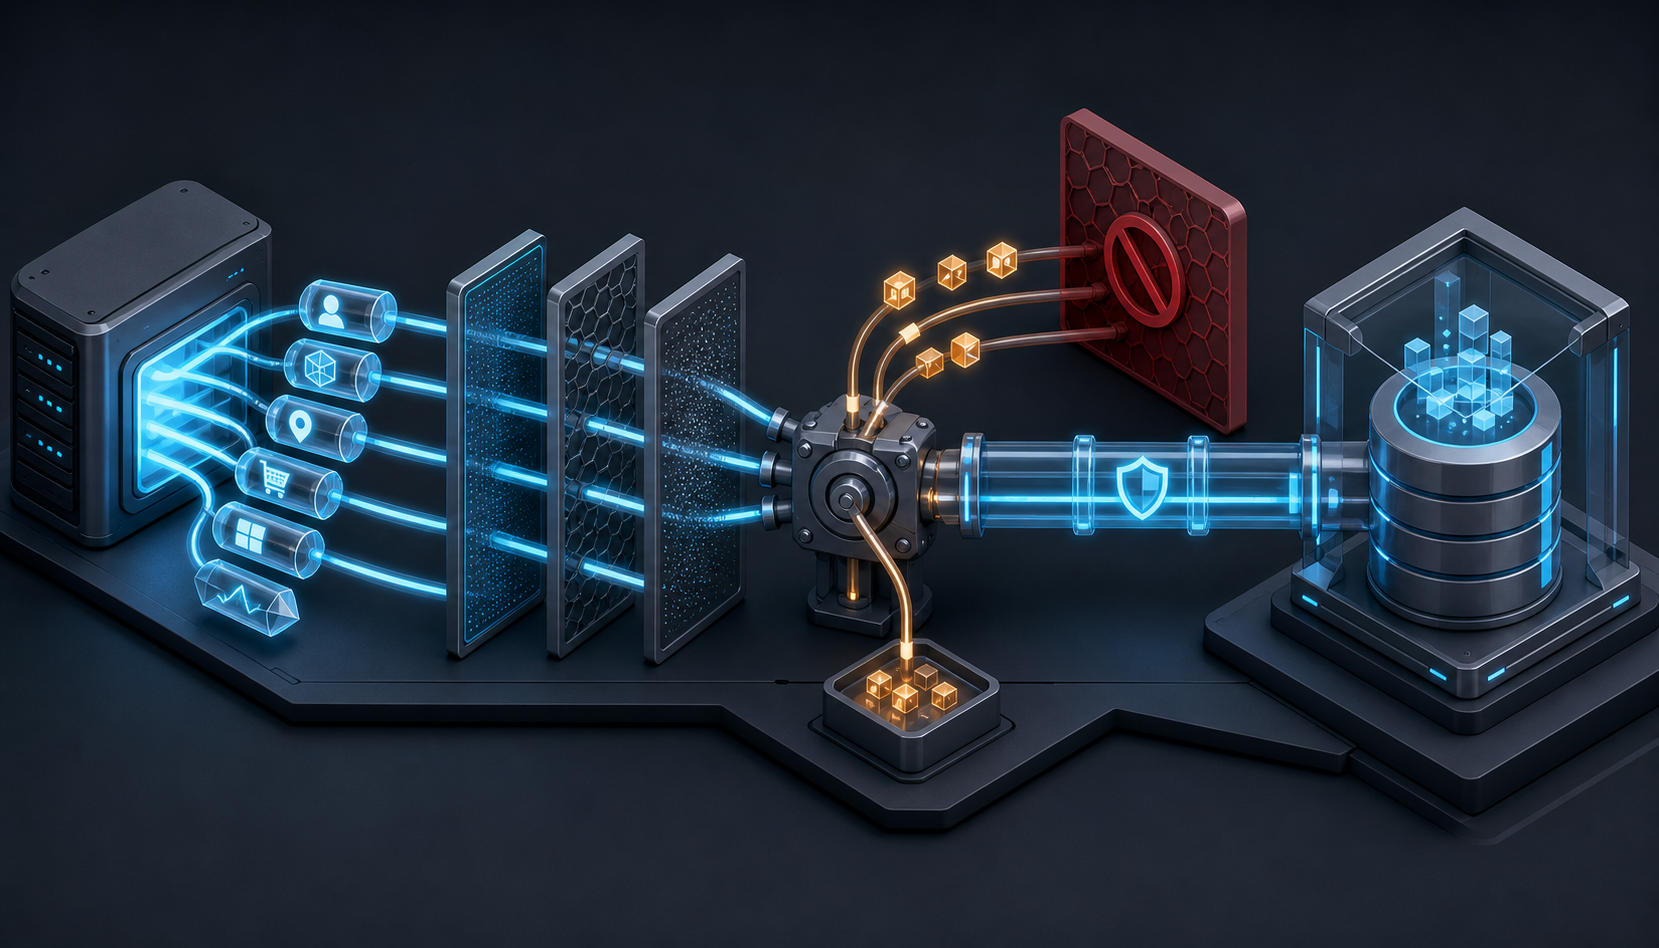
    An isometric routing junction redirects conversion events from a blocked legacy channel into a secure data channel.

    Simply renaming or deleting fields misses the architectural change. Google is positioning the Google Ads API around campaign management and core conversion workflows while directing more complex conversion and user-data transfer toward the Data Manager API.

    That means your migration plan needs to separate three responsibilities:

    • Event creation: the system that decides a conversion occurred and constructs the business record.
    • Data delivery: the API route that carries the conversion and any associated session or user data.
    • Measurement control: the monitoring that confirms events were accepted once, reached the intended destination, and remained available to reporting and bidding.

    Write a field-level migration contract before changing production code. For each field in the current payload, record its originating system, its purpose, its destination in the new route, whether it may remain in the Google Ads API request, and what should happen if the destination rejects it. Explicitly mark session attributes and IP address data so they cannot leak back into the legacy request through a shared serializer or enrichment step.

    The contract also needs an event identity rule. During a staged migration, two working API clients can be more dangerous than one broken client because both may submit the same conversion. Do not assume the two routes will deduplicate an event for you. Use a non-overlapping test scope or a verified deduplication control, and make the event identifier visible in operational logs without exposing unnecessary user data.

    Use a staged cutover that protects conversion continuity
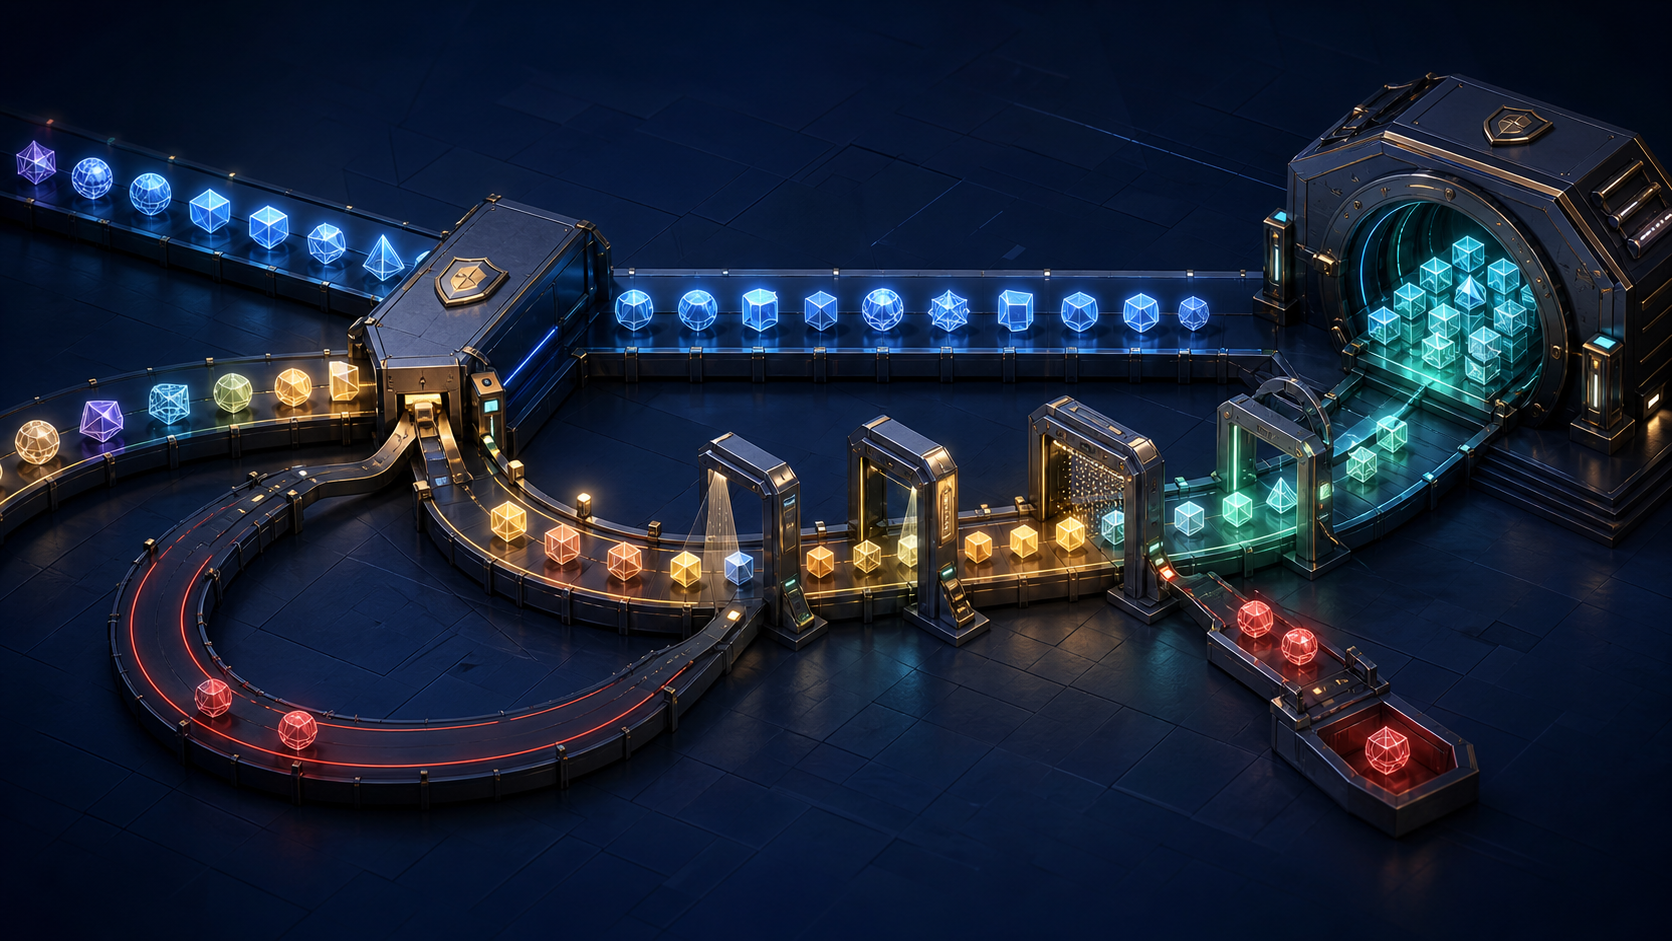
    Unique conversion tokens pass through parallel migration lanes and a deduplication checkpoint before reaching one counting destination.

    A migration should change one variable at a time. If you replace the API route, revise attribution logic, rename conversion actions, and alter campaign goals in the same release, a reporting difference will be almost impossible to diagnose.

    1. Capture a baseline. Record normal submitted, accepted, rejected, and retried event volumes for each affected conversion action. Include conversion values and delivery delays where those matter to your reporting.
    2. Instrument the current path. Make sure every submission has a traceable status and that policy errors are separated from transient delivery failures. A single generic success rate hides the failure you need to see.
    3. Build the Data Manager route. Implement the mapped destination for the complex conversion and user data, including the session attributes or IP-related data your existing workflow requires.
    4. Clean the Google Ads API payload. Remove session attributes and IP address fields from that route. This can prevent the allowlisting rejection while the new transfer path is established, but it does not prove that the resulting measurement is equivalent.
    5. Test a non-overlapping slice. Route a clearly defined subset through the new path. Keep the rest on the existing path so you can isolate differences without submitting the same events twice.
    6. Reconcile at the event and aggregate levels. Check individual event identity and status, then compare counts, values, rejection reasons, and availability timing for comparable conversion actions and time windows.
    7. Expand gradually. Increase the new route’s scope only after its error behavior is understood. Watch reporting and automated bidding inputs as closely as API health because missing conversions can distort both performance analysis and bidding decisions.
    8. Retire the legacy import. Phase out the affected Google Ads API conversion import only after the Data Manager route, monitoring, replay behavior, and operational ownership have all been validated.

    Define stop and rollback conditions before launch

    Set the conditions that pause the cutover before you begin it. Useful signals include an unexpected rise in rejected events, missing event identifiers, duplicate submissions, a material drop in accepted conversions, or delivery delays outside the range your campaigns normally receive.

    A rollback must not reintroduce restricted fields into a non-allowlisted Google Ads API request. The safer fallback is to pause expansion, keep unaffected conversion imports running, and repair the Data Manager route. Replay failed events only when your retention rules allow it and your event identity controls can prevent duplicates.

    Handle the allowlisting error as a routing failure

    The error CUSTOMER_NOT_ALLOWLISTED_FOR_THIS_FEATURE means the conversion import was rejected because session attributes or IP address data were included without the required allowlisting. Treat it as a deterministic policy failure, not as ordinary network instability.

    Automatic retries with an unchanged payload will repeat the same mistake. Your failure handler should instead follow a specific branch:

    1. Stop blind retries for the rejected payload.
    2. Record the affected customer, conversion action, event identifier, credential path, and prohibited field type without logging the raw IP address or unnecessary user data.
    3. Remove session attributes and IP address fields from the Google Ads API version of the request.
    4. Route the affected complex data through the Data Manager API.
    5. Retry the cleaned conversion only if the remaining request is valid and your event controls show it has not already been accepted.
    6. Alert the integration owner if the same policy error recurs after the payload has supposedly been cleaned. That usually points to a shared serializer, enrichment service, or secondary sender still adding the fields.

    This distinction matters operationally. A transient failure belongs in a delayed retry queue. A policy rejection belongs in a remediation queue because time alone will not change the result.

    Validate reporting and bidding, not just API delivery

    A healthy API dashboard is necessary, but it is not enough. The purpose of the pipeline is to produce trustworthy conversion signals. A request can leave your system without generating the measurement outcome your team expects.

    Use four layers of validation:

    • Transport health: attempted, accepted, rejected, retried, and permanently failed submissions by route.
    • Event integrity: missing identifiers, duplicated identifiers, unexpected field omissions, and events sent through both routes.
    • Measurement continuity: conversion counts and values by conversion action, source system, and comparable time window. Compare like with like; a changed scope can make a correct migration look wrong.
    • Decision continuity: sudden changes in the conversions used for campaign reporting or automated bidding. Avoid declaring a campaign performance change while a known tracking gap is still being repaired.

    Choose alert thresholds from your own baseline rather than copying a universal percentage. Conversion volume and delivery timing differ too much across businesses for one threshold to be meaningful. The important control is that a known policy rejection, duplicate, or unexplained loss cannot remain hidden inside an aggregate success metric.

    Keep the migration observable after cutover. The first clean deployment does not protect you from a later code change that adds the restricted fields back to the Google Ads API payload. Add a schema-level test or outbound request check that fails before such a request reaches production.

    Key takeaways

    • This migration is immediately relevant when Google Ads API conversion imports include session attributes or IP address data.
    • Existing access may continue, but it should be treated as time to migrate rather than proof that the current route is permanent.
    • Move complex conversion and user-data transfer to the Data Manager API, and remove the restricted fields from Google Ads API requests.
    • CUSTOMER_NOT_ALLOWLISTED_FOR_THIS_FEATURE is a policy and routing problem. Retrying an unchanged payload will not resolve it.
    • Test with a non-overlapping event scope, reconcile individual events and aggregate results, and prevent duplicate conversion submissions.
    • Judge the cutover by reporting and automated bidding continuity as well as API acceptance.

    Your next action is small and decisive: open the production request definition and determine whether either restricted field is present. If the answer is yes, name the migration owner, document the current baseline, and create the Data Manager route before changing the legacy importer. That sequence gives you a controlled cutover instead of an emergency caused by rejected conversions.
    References

  • Paid Acquisition Control Plan: Targeting, Lift and Search Ads

    Paid Acquisition Control Plan: Targeting, Lift and Search Ads

    Your acquisition dashboard can look healthier while your decision quality gets worse. Reach outside a service area can swell activity, a modeled lift estimate can be mistaken for certainty, and extra App Store ad slots can tempt you to chase a position you cannot buy.

    These are three different control problems: audience eligibility, causal measurement, and auction relevance. You need to separate them before deciding where the next dollar goes. This control plan shows you how.

    Separate the three decisions hiding inside campaign performance

    Paid acquisition reviews often collapse targeting, measurement, and optimization into one question: did performance improve? That shortcut is dangerous because each layer can change the same dashboard metrics for a different reason.

    Decision layerPlatform changeWhat you should control
    Audience eligibilityGoogle Demand Gen now exposes an explicit choice between Presence or interest and Presence only.Define whether a person must be inside the market to have economic value before you select the setting.
    Causal evidenceGoogle is making Bayesian incrementality measurement available with budgets as low as $5,000.Judge the posterior probability, credible interval, assumptions, and business downside instead of treating test availability as proof.
    Available optimization leverApple plans to add in-line App Store search ads in 2026, but advertisers cannot select or buy those positions directly.Improve query-to-app relevance and creative alignment rather than optimizing toward an unavailable placement control.

    The order matters. Set the eligible population first. Then ask whether advertising caused an outcome. Only after that should you optimize the lever the platform actually exposes. Reversing the order can leave you spending money to correct the wrong layer.

    • Out-of-market Demand Gen traffic is primarily a boundary problem, not evidence that the creative failed.
    • A wide Bayesian credible interval is an evidence problem, not automatic proof that the channel failed.
    • An App Store ad that never becomes auction-eligible can be a relevance problem that a higher bid will not solve.

    Set the Demand Gen location boundary before reading performance

    Demand Gen can reach people across YouTube, Discover, and Gmail. A loose location definition can therefore spread through several environments before you notice it in an aggregate report.

    Use Presence only when the conversion depends on the person being in the target market. That usually applies to a local service area, a physical catchment, a market-specific offer, or fulfillment that cannot extend beyond named locations. Use Presence or interest only when someone outside the market can still become a valid customer. Planned travel and relocation are plausible examples. Preserving a larger reach estimate is not, by itself, a reason to choose the broader option.

    Run this sequence whenever you create, migrate, or audit a Demand Gen campaign:

    1. Write the eligibility rule first. Complete this sentence: We will pay to reach people who are in, or are interested in, these markets because the resulting conversion can be fulfilled in this way.
    2. Select the location option explicitly. Do not let a copied campaign, inherited setup, or old operating habit make the decision for you.
    3. Audit legacy exclusions. Presence only is now available natively, reducing the need for manual exclusion workarounds. Remove an old exclusion only after confirming that the native control makes it redundant.
    4. Record the change date and previous setting. A switch between Presence or interest and Presence only changes the population behind the metrics. Treat it as a break in the series, not as an ordinary bid or creative adjustment.
    5. Inspect location quality before aggregate efficiency. Confirm that impressions, clicks, and conversions are coming from markets your business can serve. Only then interpret campaign-wide cost and conversion metrics.

    This distinction matters because a cost-per-acquisition change can be caused by audience composition even when the ad, bid, and landing experience remain unchanged. Comparing the periods as if they were the same population can produce a false creative, bidding, or channel conclusion.

    Presence only should reduce geo-leakage and make regional performance easier to interpret. It does not prove incrementality, validate your list of target markets, or establish that every conversion can be fulfilled. Those remain separate business and measurement questions.

    Read a $5,000 Bayesian lift test as a decision, not a verdict

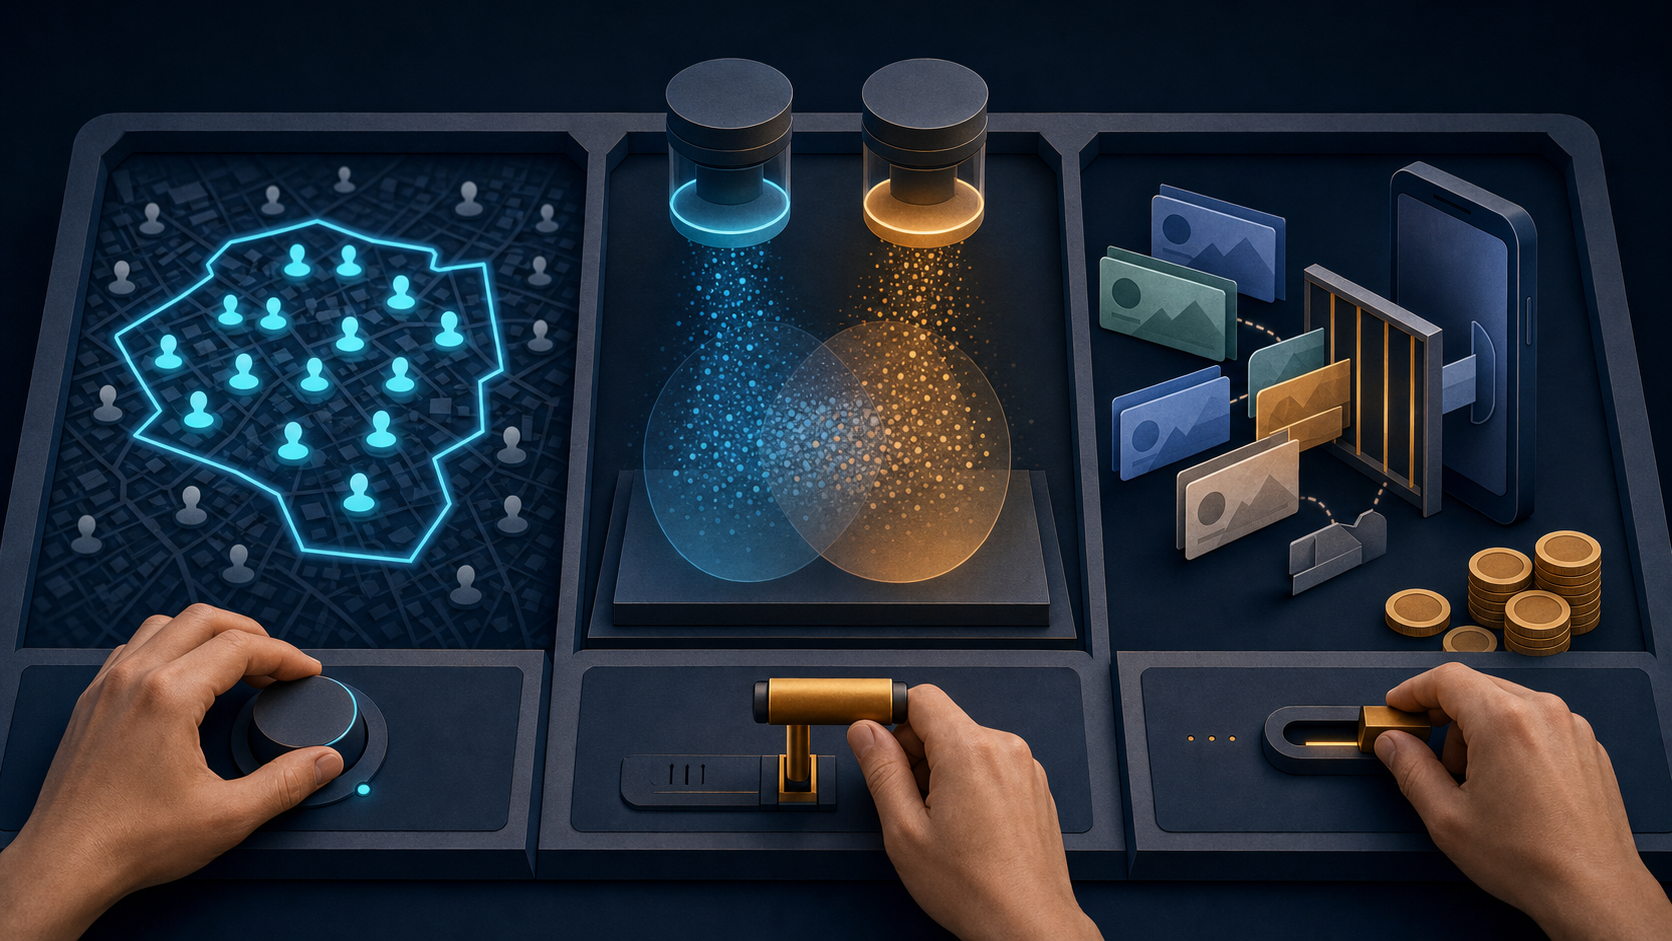
    Two transparent experiment chambers contain overlapping particle clouds beside budget tokens and a three-way decision lever.

    Lower-budget incrementality testing is useful because it gives more advertisers a way to ask a causal question: how many outcomes happened because of the advertising? It becomes dangerous when the budget figure is mistaken for a precision guarantee.

    Google’s approach uses informed priors, hierarchical modeling, and campaign history to extract useful evidence from less data. In Bayesian terms, the prior represents the belief before the test, the posterior updates that belief with observed data, and the credible interval describes a plausible range for the effect. As more relevant observations accumulate, the result should depend less on the prior and more on the test data.

    That is different from a conventional frequentist test built around a fixed sample, a p-value, and a binary statistical-significance decision. A p-value is not a Bayesian probability that the campaign worked, and a posterior probability is not the percentage lift. Mixing those interpretations can turn a technically valid output into a bad budget decision.

    Before launching a lift test, create a decision record with these fields:

    • Decision: the spend increase, reduction, continuation, or stop that the result could trigger.
    • Eligible population: the geography, audience, campaign set, and conversion outcome covered by the test.
    • Business hurdle: the smallest incremental effect that would justify the cost and operational risk.
    • Prior assumptions: whatever the platform exposes about the starting belief, historical inputs, or comparable campaign patterns. If these are not visible, record that limitation.
    • Posterior output: the probability attached to the outcome you care about, not merely a positive headline.
    • Credible interval: the plausible effect range, including whether economically unattractive outcomes remain credible.
    • Action and reversal condition: what you will do after the result and what later evidence would cause you to reverse it.

    Decide from the distribution, not the headline

    Start by separating direction from magnitude. A high probability that lift is positive can coexist with an effect too small to cover acquisition costs. Conversely, an uncertain estimate can still support a limited, reversible decision when the plausible downside is small and another test will add information.

    Next, inspect the full credible interval. If it spans both valuable and damaging outcomes, the honest conclusion is that the decision remains sensitive to uncertainty. Do not scale aggressively from the center estimate alone. Keep the change staged and use the next measurement period to narrow the range.

    Keep the result inside its tested boundary. Evidence from one geography, audience mix, campaign history, or conversion definition does not automatically transfer to another. This is especially important after changing Demand Gen location settings because you may no longer be measuring the same population.

    Finally, treat $5,000 as an access point for a modeled test, not a warranty that every campaign spending that amount will produce a narrow, decision-grade answer. Smaller tests can be useful precisely because Bayesian inference carries prior information forward. That same mechanism is why you need to examine the assumptions and uncertainty before committing more money.

    Prepare Apple Ads for a relevance gate you cannot outbid

    An unbranded smartphone projects content cards toward a gate that admits one matching card while mismatched cards and bidding tokens remain outside.

    Apple plans to place additional ads among organic App Store search results during 2026 while retaining the existing top-result ad. Advertisers will not need to opt into the new positions, and there is no placement selector that lets you buy a particular in-line slot.

    The practical constraint comes earlier in the process: an app must be relevant to the search to enter the auction. A larger bid cannot rescue an app that fails that gate. Bids can still matter among eligible candidates, but they are downstream of relevance.

    Build your campaign around a relevance chain rather than a placement wish list:

    1. Group keywords by user need. Do not combine terms merely because they share vocabulary. Two queries containing the same noun can imply different jobs, audiences, or expected features.
    2. Map each theme to an app capability. Write down the function that directly answers the search. If you cannot complete that connection without stretching the meaning, the theme is probably a poor acquisition target.
    3. Map the capability to product-page evidence. The app name, description, imagery, and surrounding product-page material should make the connection understandable without relying on the ad to explain everything.
    4. Prepare creative variations for distinct themes. Apple allows advertisers to align different creative treatments with audiences or keyword groups. Without custom creative, the ad can be generated from the app’s product page, making that page the default acquisition asset rather than an organic-only concern.
    5. Annotate the inventory change when it reaches your account. More impressions or attributed installs may reflect additional supply, stronger relevance, displaced organic discovery, or a mixture of those effects. Preserve the date so you do not mislabel the discontinuity as a campaign optimization win.

    Diagnose the funnel in sequence. If impressions expand but taps do not, inspect the query-to-creative relationship first. If taps expand but installs do not, inspect whether the promise and product page carry the same intent. If attributed installs expand, do not automatically call the difference incremental; additional ad inventory can redistribute existing demand as well as capture new demand.

    Apple has indicated that billing will remain per tap or per install, depending on the existing setup. That continuity does not make the economics static. Greater ad density can change impression availability, tap behavior, conversion quality, and the balance between paid and organic discovery.

    Do not create a performance target around owning an in-line position you cannot control. Track whether relevant searches produce qualified installs at acceptable economics. That is a lever you can manage through keyword selection, product-page alignment, creative variation, and bids among eligible candidates.

    Key takeaways

    • Choose Demand Gen Presence only when value depends on the person being inside the target market; use Presence or interest only when out-of-market interest can still produce a valid customer.
    • Treat a location-setting change as a population change. Annotate it and avoid presenting the before-and-after difference as a clean creative or bidding test.
    • Regard the $5,000 Bayesian test level as access to modeled evidence, not guaranteed certainty or a universal minimum for a reliable answer.
    • Read Bayesian results through the prior, posterior probability, credible interval, and your business hurdle. Probability of positive lift is not the size of the lift.
    • For Apple’s planned in-line App Store ads, relevance determines auction eligibility before bid size can influence the result.
    • Annotate new ad inventory and separate attributed growth from incremental growth before increasing spend.

    Before your next budget review, add three lines to every campaign brief: the eligible market, the evidence required to change spend, and the lever the platform actually lets you control. If the campaign owner cannot fill in all three, do not solve the uncertainty with a larger budget. Fix the boundary, the measurement rule, or the relevance chain first.

    References

  • A Practical System for Ecommerce Conversion and Ad Performance

    A Practical System for Ecommerce Conversion and Ad Performance

    Your ad account can look healthy while your store quietly wastes the demand you are paying to create. A strong click-through rate cannot rescue a difficult checkout, and a high account-wide ROAS can hide a catalog in which one familiar product consumes most of the budget.

    The fix is a sequence, not another disconnected app or campaign adjustment. Remove purchase friction first. Recover shoppers who have already shown intent. Then allocate advertising spend according to product-level performance. That order makes the numbers easier to interpret and keeps automation from optimizing around a broken buying experience.

    Key takeaways

    • Audit the complete mobile path from ad click to successful payment before increasing traffic.
    • Prioritize digital wallets, then evaluate buy now, pay later against your margins and customer needs.
    • Use email and SMS recovery only with the consent and controls required for each channel and jurisdiction.
    • Separate proven products, new or low-data products, and products consuming traffic without adequate return.
    • Review product assignments on a rolling cycle, but choose the window according to your sales volume rather than treating 14 days as a universal rule.

    Fix the purchase path before asking ads to work harder

    Generic shoppers follow a simplified mobile checkout path as obstacles, extra gates, and confusing branches are removed between a shopping basket and a delivery parcel.

    Start with the device on which the transaction actually happens. With 54.5% of holiday purchases happening on mobile, a phone is not a secondary quality-assurance case. It is often the main checkout environment.

    Do not audit that environment by opening the homepage and deciding that it looks acceptable. Follow the paid journey exactly as a shopper would:

    1. Open each high-spend ad on a real phone and record the promise, product, price, and offer shown in the creative.
    2. Confirm that the landing page immediately continues the same promise. If the ad promotes one product or use case, do not make the shopper search for it again.
    3. Add the product to the cart from a clean session so saved addresses, accounts, or payment details do not conceal friction.
    4. Start checkout and count the fields and decisions required before payment. Test every wallet that appears to be enabled.
    5. Place a test order. A visible payment button is not proof that authorization, confirmation, inventory handling, and order creation work.
    6. Repeat the path for the devices, browsers, and traffic sources that matter to your store. Record failures by stage rather than describing the whole journey as a conversion problem.

    Digital wallets such as Apple Pay, Google Pay, and PayPal reduce typing by reusing stored payment and delivery details. That matters on a small screen. Their relevance is not marginal: up to 64% of Americans use digital wallets as much as traditional payment methods, while 54% prefer using them more often. On Shopify, wallet and buy now, pay later functions can be added without custom development in many standard configurations.

    A wallet removes form friction; it does not repair a weak offer. If product-page engagement is poor, adding another payment method is unlikely to solve the underlying problem. Buy now, pay later can reduce the immediate price objection, but it should not be enabled solely because it might lift checkout completion. Review provider fees, refunds, returns, and contribution margin first. A higher conversion rate can still produce worse economics.

    Use your own historical baseline when reading the funnel. There is no universal healthy rate for every catalog, price point, or traffic mix. The pattern of the drop tells you where to investigate:

    Observed patternWorking hypothesisFirst actionPrimary measure
    Ads earn clicks, but few product views become cart additionsThe ad promise, landing page, product, or offer is mismatchedBuild a landing-page variant that continues the ad’s exact messageProduct-view-to-cart rate
    Cart additions are steady, but few shoppers start checkoutThe handoff creates uncertainty or extra effortReview the cart on mobile and make the next step and payment choices clearCart-to-checkout-start rate
    Checkout starts are steady, but purchases are weakPayment or data-entry friction is blocking completionTest wallet payments and evaluate whether buy now, pay later fits the order economicsCheckout completion rate
    Purchases are steady, but ROAS is weakSpend is reaching the wrong products or trafficRebuild product groups around performance rather than category aloneProduct-level ROAS and revenue
    One product absorbs most of the campaign budgetExisting winners are preventing new or less visible products from gathering evidenceGive proven, new, and traffic-without-return products separate treatmentSpend concentration and cohort-level ROAS

    This table is a hypothesis map, not an automatic diagnosis. For example, checkout completion can rise after you change campaign targeting because the new audience was easier to convert. That does not prove the checkout itself improved. Keep traffic allocation stable during a checkout test, or use a controlled experiment, so you can separate site effects from audience effects.

    Recover existing intent without creating a consent problem

    Once payment works, focus on shoppers who reached the cart or checkout but did not buy. They have supplied more evidence of intent than a cold audience, but that does not give you unrestricted permission to contact them.

    1. If the shopper has valid email marketing permission, place them in an abandoned-cart email flow with a direct return to the relevant cart or product.
    2. If the shopper has separately provided the consent required for marketing texts, use SMS selectively for time-sensitive recovery. Do not treat the presence of a phone number in checkout as automatic marketing consent.
    3. If you cannot document the necessary permission, do not quietly add the shopper to an automated sequence. Use compliant onsite recovery and your approved advertising audiences instead.
    4. Measure each recovery channel separately. A combined recovery number can conceal an unproductive SMS program behind a successful email flow, or vice versa.

    Email and SMS programs must follow the rules that apply to the shopper, sender, channel, and jurisdiction. In the United States, CAN-SPAM and TCPA are part of that compliance landscape. Requirements and interpretations can change, so have qualified counsel review the actual capture language, records, workflows, and vendors before contacting people who did not clearly subscribe. Calling an outreach process human-assisted does not by itself settle whether it is permitted.

    Recovery is not limited to reminders. Some shoppers leave because they still do not trust the product. Reviews answer a different objection: whether the item is credible and likely to meet expectations. Spiegel Research Center found that a product with five reviews was 270% more likely to be purchased than one with none. That finding does not make five a universal target or prove the same lift for every store. It does show why a product with no visible evidence should not be treated as conversion-ready.

    • Place product-specific reviews where the decision happens, not only on a separate testimonials page.
    • Make sure the review displayed belongs to the item being purchased. General store praise cannot answer product-level questions as well as relevant customer feedback.
    • Choose a review system that can connect with your advertising stack. Shopify integrations such as Okendo, Yotpo, and Shopper Approved can sync review data with Google Merchant Center and support Google Shopping activity.
    • Track whether products that gain credible review coverage improve their product-view-to-cart and checkout-start rates. Do not attribute every store-wide change to the review widget.

    Watch the downside metrics alongside recovered revenue: unsubscribe activity, complaints, failed deliveries, discount cost, refunds, and repeat purchase behavior. A flow that produces immediate orders by exhausting customer permission is not a durable win.

    Stop letting product categories decide where the budget goes

    Unbranded products receive different streams of advertising resources based on abstract performance signals, with completed orders feeding results back into a central decision hub.

    Category-based campaign structures are easy to understand, but a merchandising label does not describe advertising performance. One popular product can consume the available budget because the platform already has strong evidence that it converts. New products remain underexposed, while weak products can stay hidden inside a category that looks profitable in aggregate.

    Create performance cohorts with rules written before you inspect the latest results. Three labels are enough to begin:

    • Proven performers: products at or above your target return with enough recent traffic to support the decision.
    • New or low-data products: launches and existing products that have not received enough exposure to be judged by the same rule as established sellers.
    • Traffic without adequate return: products that have crossed your evidence threshold for clicks or spend but remain below your required return.

    Define the variables with your own economics. A workable rule template is: proven performer equals ROAS at or above target and clicks at or above the evidence floor; traffic without adequate return equals clicks at or above that floor and ROAS below your lower limit; new or low-data equals product age within your launch window or clicks below the evidence floor. The structure is reusable, but the values are not. A high-margin accessory and a low-margin appliance should not inherit the same target merely because they share a campaign.

    If you do not have a dependable margin view, do not automate budget expansion from ROAS alone. ROAS is attributed revenue divided by advertising spend. It is not profit. Product cost, fulfillment, payment charges, returns, discounts, and the attribution model can all change the decision.

    1. Export product-level clicks, spend, attributed revenue, orders, and ROAS for a consistent window.
    2. Apply the written cohort rules using feed labels or equivalent product-grouping fields.
    3. Give each cohort a budget and campaign treatment appropriate to its job. The new-product cohort needs room to gather evidence; proven products need room to scale; weak products need a controlled test or a spending limit.
    4. Publish the same product labels to paid channels where the required data and controls are available.
    5. Recalculate labels on a rolling schedule and log every reassignment. Without a log, a product that moves between groups can make campaign trends difficult to explain.

    La Maison Simons used Channable Insights to replace static category segments with product-performance groups and refreshed them on a rolling 14-day window. It then applied the approach across Google, Meta, Pinterest, TikTok, and Criteo. In that deployment, ROAS rose from about 800% to about 1,500%, CPC fell from $0.37 to $0.30, CTR increased from 1.45% to 1.86%, and average order value increased 14% without additional ad spend.

    Those figures are one retailer’s outcome, not a forecast for your catalog. They do not establish how much of the change came from segmentation rather than other conditions. The transferable lesson is narrower and more useful: a product can receive a different advertising treatment as its evidence changes, and a winning item does not have to monopolize the budget forever.

    A 14-day window is a sensible test cadence for a fast-moving catalog with enough transactions. It can be noisy for a lower-volume store, an expensive product, or a long-consideration purchase. Use the shortest window that still supplies enough evidence for your preset rules. If products repeatedly jump between cohorts, lengthen the window or raise the evidence floor instead of manually overriding the system every few days.

    Run one operating loop from conversion to ROAS

    Advertising and conversion teams often optimize separate dashboards. The media team changes audiences and budgets while the ecommerce team changes checkout and landing pages. When both happen at once, neither team can explain the result. Use one operating loop with fixed definitions and a visible change log.

    1. Cycle setup: record the current product cohorts, attribution model, campaign budgets, landing-page versions, payment options, and funnel baseline.
    2. During the window: monitor tracking and payment failures, but do not reclassify products because of a single order or a short-lived spike. Emergency defects should be fixed immediately and marked in the log.
    3. Decision day: recalculate product labels from the same lookback window, move qualifying products according to the written rules, and record every move.
    4. Experiment selection: choose one material conversion constraint for the next cycle. Test the ad-to-page message, the landing-page treatment, the checkout path, or the recovery flow rather than changing all four.
    5. Scale decision: increase exposure only when the advertising return, checkout behavior, and unit economics point in the same direction.

    Your shared scorecard should retain the relationship between media and store behavior:

    • CTR: clicks divided by impressions. It shows whether the ad earns attention, not whether the resulting visit is valuable.
    • CPC: spend divided by clicks. A lower CPC helps only if the traffic still reaches profitable purchases.
    • Product-view-to-cart rate: cart additions divided by relevant product views. Use it to investigate message, product, offer, and page friction.
    • Checkout completion rate: purchases divided by checkout starts. Use it to inspect payment and form friction.
    • Average order value: revenue divided by orders. Pair it with margin rather than assuming a larger basket is automatically more profitable.
    • ROAS: attributed revenue divided by ad spend. Always display the attribution model and window beside it.
    • Spend concentration: the share of budget absorbed by the top product or small group of products. This reveals catalog dependence that account-wide ROAS can hide.

    GA4 can remain part of this measurement system, while a third-party attribution layer such as Triple Whale can provide another product and channel view. More dashboards do not create objective truth. Select the attribution model used for budget decisions, document it, and avoid changing it in the middle of a comparison. A last-click result from one cycle cannot be compared cleanly with a different model in the next.

    Custom landing pages deserve their own controlled tests. Shopify builders such as Replo can create and A/B test pages without changing the main theme for every visitor. Start with one ad and product cohort, keep the standard page as the control, and change one decision-relevant treatment. If the variant wins, confirm that the improvement survives after product mix and traffic quality are accounted for before rolling it across the catalog.

    Begin with one mobile test order and one export of product-level advertising data. Fix any payment failure you find, label the catalog with written performance rules, and start a single review cycle. That gives you a system you can improve. Installing the entire stack before you can explain the current funnel only gives you more places for the same leak to hide.

    References

  • Google App Campaign VTC Bidding: A Practical Decision Guide

    Google App Campaign VTC Bidding: A Practical Decision Guide

    Your Android App campaign may be influencing installs that clicks never explain. Someone watches a video, remembers the app, and converts later without returning through the ad. If you optimize only for click-led conversions, that path can look invisible or less valuable than it really is.

    Google App Campaign VTC bidding gives you a way to optimize for that behavior. The setting is most relevant when video creates meaningful demand, but enabling it is not the same as proving incremental growth. You need to know what the bidding change measures, when it fits, and how to judge the result without mistaking attribution for impact.

    What VTC bidding changes inside an App campaign

    A view-through conversion is a conversion attributed to an ad exposure without an ad click, subject to the platform’s applicable attribution rules. It answers a different question from a click-through conversion:

    • Click-through conversion: Did the user click the ad before converting?
    • View-through conversion: Did the user see the ad and convert later without clicking it?
    • Incremental conversion: Did the advertising cause a conversion that would not otherwise have happened?

    Those three questions are related, but they are not interchangeable. VTC bidding concerns attributed behavior. It does not, by itself, establish incrementality.

    The important product change is that Google has made VTC optimization a visible bidding option for Android App campaigns. View-through activity was previously a quieter signal within Google’s system. Advertisers can now make it an explicit part of what the campaign is asked to optimize.

    That changes more than a report column. A reporting metric tells you what the platform credited after delivery. A bidding input can influence which opportunities the system pursues. When VTCs become part of the optimization objective, the campaign can place greater value on impressions and video interactions that do not produce an immediate click but are associated with later conversions.

    QuestionWhat to inspectWhat it cannot prove alone
    Are people converting after clicking?Click-through conversions and their downstream qualityWhether video exposure influenced non-clicking users
    Are people converting after an ad view?View-through conversions and their downstream qualityWhether those users would have converted anyway
    Is the campaign creating additional business value?Incrementality evidence and business outcomesThis cannot be established from attributed conversion volume alone

    This distinction should shape your expectations. VTC bidding can help the system recognize a real video-assisted journey. It can also increase the amount of conversion credit assigned to advertising without creating the same increase in total installs or post-install value. Treat the setting as an optimization choice, not a declaration that every attributed view caused a conversion.

    Decide whether your campaign is a good fit

    VTC bidding is most defensible when your campaign depends on video to create recognition or interest before the user is ready to act. YouTube and in-feed video placements are natural examples because the creative can communicate value even when the viewer never clicks.

    Your campaign is a stronger candidate when most of these conditions are true:

    • Video has a defined job. It demonstrates the app, communicates the use case, or builds enough recognition for a later install.
    • Your user journey is not click-dependent. People can remember the app, search for it later, or reach it through another route after seeing the ad.
    • You can evaluate post-install quality. An attributed install is not your final definition of success; you can check whether acquired users complete the actions that matter to the business.
    • Your team accepts attribution as a model. Stakeholders understand that a VTC identifies a relationship between exposure and conversion, not automatic proof of causation.
    • Your creative program can support the objective. You have video assets that make the app understandable without requiring a click to finish the message.

    Pause before switching if the campaign has little meaningful video activity, if creative quality is unresolved, or if your only success report is platform-attributed CPA. In those cases, a VTC-enabled campaign may produce more credited conversions while leaving you unable to tell whether acquisition actually improved.

    The setting is also a poor substitute for a measurement strategy. If the business question is strictly “How many additional users did advertising create?”, VTC attribution cannot answer it on its own. You need an incrementality method appropriate to your program. The platform’s attributed conversions can still guide optimization, but they should not be presented as causal evidence.

    Creative deserves special attention here. Click-oriented ads can lean on urgency or a direct call to action. Video that earns value through exposure has to do useful work before the viewer acts: show the product, make the use case memorable, and connect the app to a recognizable need. If the message is unclear without a click, expanding the bidding signal will not repair the underlying communication problem.

    Prepare a controlled rollout before changing the bid objective

    Two parallel campaign lanes lead to identical smartphones, with one lane passing through an adjustable control and a gradual safety gate.

    The biggest rollout mistake is changing the bid objective, conversion definition, creative mix, and budget logic at the same time. Even if performance moves, you will not know which decision produced it. Build a clean before-and-after record first, then keep the initial change narrow.

    1. Write down the decision you are testing. A useful hypothesis is specific: “Including view-through conversions should help this video-led Android campaign find more users who complete our chosen post-install action.” Avoid a circular goal such as “VTC bidding should increase VTCs.”
    2. Record the current campaign state. Capture the active conversion action, bid objective, budget, creative set, audience or market scope, attribution settings, click-through conversions, view-through conversions, and the downstream outcomes used to judge user quality.
    3. Confirm what counts as success. Name the conversion event the campaign should optimize and the later business outcome that validates it. If the optimization event is an install, decide which post-install behavior tells you whether those installs are useful.
    4. Check Android campaign eligibility and setting availability. The documented VTC bidding option applies to Android App campaigns. Do not assume the same control exists across every app platform or campaign type.
    5. Review video assets as conversion inputs. Each asset should make the app and its value recognizable during the exposure itself. Remove obvious ambiguity before asking the bidding system to value view-led journeys.
    6. Change one material lever first. If you enable VTC bidding, avoid simultaneously rebuilding the entire creative portfolio or redefining the conversion event. Necessary operational changes should be documented so they are not mistaken for bidding effects.
    7. Let the new setup produce interpretable data. Do not judge the change from an isolated fluctuation. Use a review period appropriate to your conversion timing and traffic, and document any promotions, product changes, or market events that could alter demand.
    8. Compare quality as well as attributed cost. Review conversion composition, post-install behavior, and overall business results. A lower platform-reported CPA is not a win if the added credited conversions have weak downstream value or total acquisition is unchanged.

    Keep the attribution rules visible

    Attribution settings determine which exposures can receive credit. That means they affect VTC volume and any CPA calculated from it. Record the applicable rules alongside every evaluation, and flag any change to them. Otherwise, a measurement change can look like a performance improvement.

    This matters when you compare periods, campaigns, or channels. Two campaigns can generate similar real-world outcomes while reporting different conversion totals because their eligible paths or attribution treatment differ. Normalize the definitions before comparing their CPAs.

    Give video a measurable role

    Do not evaluate all video merely as “awareness.” Assign each asset a concrete communication task: introduce the problem, demonstrate the app, explain a differentiating use case, or reinforce recognition. That makes creative analysis more useful when the campaign begins placing greater value on non-click exposure.

    If one creative generates view-attributed conversions but those users show poor post-install behavior, the problem may be the promise made by the asset rather than VTC bidding as a whole. Separate the quality of the signal from the quality of the message feeding it.

    Read the results without confusing attribution and growth

    An analyst uses two transparent lenses to compare traced ad conversion paths with a wider field of mobile app users.

    Expect CPA interpretation to become more complicated. Adding view-through conversions can change the conversion denominator, and the bidding system may also change delivery in response to the expanded objective. Reported CPA can therefore move even when spend, total demand, and business value do not move in parallel.

    Use a diagnostic sequence instead of asking only whether CPA went up or down:

    1. Did total attributed conversion volume change? Separate click-through and view-through conversions so you can see what drove the movement.
    2. Did the mix of attributed conversions change? A larger VTC share tells you the campaign is receiving more credit from view-led paths. It does not yet tell you whether more valuable users were created.
    3. Did post-install quality hold? Compare the downstream behavior of the users being acquired. If quality falls, a better attributed CPA may be economically misleading.
    4. Did overall acquisition or business value change? Look beyond the campaign’s attributed total. If platform credit rises while broader outcomes remain flat, attribution may have expanded more than growth did.
    5. Did creative delivery change? Identify whether spend or exposure shifted toward particular video assets. The result may reveal which messages the bidding system associates with later conversion.
    6. Were there competing explanations? Product releases, promotions, seasonal demand, measurement changes, and other marketing can all alter conversion behavior. Record them before assigning the movement to VTC bidding.

    Four common result patterns call for different decisions:

    • Attributed conversions rise, quality holds, and broader acquisition improves. This is the most encouraging pattern. Continue carefully, verify that the gain persists, and strengthen the video concepts associated with valuable users.
    • Attributed conversions rise, but broader outcomes stay flat. The platform may be recognizing journeys that were already occurring. Keep attribution and incrementality separate in your reporting before expanding spend.
    • Reported CPA improves, but post-install quality falls. The campaign is finding cheaper credited outcomes, not necessarily better customers. Revisit the conversion event and creative promise rather than declaring success from CPA alone.
    • Performance weakens across attributed and business measures. Check signal quality, conversion selection, creative clarity, and campaign fit. Do not preserve the setting merely because view-led optimization sounds more complete.

    Key takeaways

    • VTC bidding allows an eligible Android App campaign to optimize for conversions that follow an ad view without an ad click.
    • It is best suited to video-led acquisition where exposure can influence a later install or action.
    • A view-through conversion is attributed, not automatically incremental.
    • Record conversion definitions and attribution settings before rollout because either can change reported CPA.
    • Judge the result with conversion mix, post-install quality, and broader business outcomes, not platform CPA alone.
    • Creative quality becomes more important when the system is asked to value what happens after a view.

    Make the next decision from a measurement record, not a dashboard snapshot

    Start with one eligible Android App campaign where video already has a clear role. Write down the hypothesis, freeze the measurement definitions, document the creative set, and decide which downstream outcome will validate the attributed conversions. Then enable the bidding change without bundling it with unrelated revisions.
    Your next decision should follow the evidence pattern. Scale when attributed performance, user quality, and broader acquisition move together. Investigate when only platform credit improves. Reverse or redesign when the campaign finds view-attributed conversions that do not produce useful users. That discipline lets VTC bidding expand what your campaign can learn without expanding what your reporting claims.

    References


  • How to Measure Brand Growth Beyond Clicks and Traffic

    How to Measure Brand Growth Beyond Clicks and Traffic

    You open the dashboard and see fewer organic sessions, fewer referral visits, or a lower click-through rate. The immediate conclusion is tempting: the brand is losing ground. But traffic can fall even while more people are learning your name, considering your offer, and searching for you when they are ready to act.

    The answer is not to replace traffic with another all-purpose KPI. You need a measurement system that separates brand visibility, demand, demand capture, and business results. That gives you a way to judge brand growth even when AI answers, social discovery, video, marketplaces, and delayed decisions leave no clean click trail.

    Separate demand creation from demand capture

    Split illustration with a beacon creating awareness among a broad audience on the left and a funnel guiding interested people toward a purchase doorway on the right.

    A click is an observable interaction. It tells you that someone selected a tracked link on a particular device, browser, platform, and occasion. It does not tell you everything that made the person recognize, trust, or prefer the brand.

    That distinction matters because buyers rarely move through a single, fully tracked path. Someone might encounter your brand in a LinkedIn video, read independent reviews, study a case page, ask an AI assistant about the category, and return later through a branded Google search. A click-based model may credit only the final search even though several earlier interactions educated and persuaded the buyer.

    First-click, last-click, linear, and time-decay attribution models distribute credit differently, but they share the same boundary: they can allocate only the interactions the system captured. An untracked exposure cannot receive credit. Cross-device research, offline conversations, social viewing, AI answers, and delayed brand recall can therefore disappear from the reported journey.

    Traffic has a similar limitation. It measures delivery to your website, not total demand for your brand. A visit can be highly valuable, but a person can also learn enough from an answer surface to skip the visit and search for your company later. As AI and platform experiences answer more questions without an outbound click, the gap between influence and site traffic becomes harder to ignore.

    Measurement layerQuestion it answersUseful signalsDecision it should inform
    Business resultDid marketing contribute to an outcome the organization values?Revenue, qualified pipeline, sales, renewals, or another defined commercial outcomeWhether growth is reaching the business
    Brand demandAre more category buyers actively looking for us?Share of search, branded search volume, and direct brand-seeking behaviorWhether mental availability and preference may be strengthening
    Visibility and validationWhere can buyers encounter or verify the brand?Brand mentions, answer-engine presence, reviews, category visibility, video exposure, and case-content useWhere awareness or trust may be developing
    Demand captureHow efficiently do we turn existing interest into an owned interaction?Clicks, sessions, landing-page behavior, leads, and conversion rateWhether channels and experiences capture demand effectively

    No row makes the others unnecessary. Business outcomes can arrive too late to diagnose a current problem. Visibility can grow without producing qualified demand. Branded demand can rise while a weak website or sales process wastes it. Clicks can fall because distribution changed rather than because the brand weakened.

    Label every metric on your current dashboard by layer. If nearly everything sits in demand capture, you do not have a brand measurement dashboard. You have a website acquisition report.

    Use share of search as a demand signal

    Share of search compares demand for your brand with branded search demand across the category you have defined. Expressed as a percentage, the working formula is:

    Share of search = your branded search volume / total branded search volume for the selected competitive set

    This is not the same as your share of generic keyword rankings. It asks how often people look specifically for you relative to the brands against which you compete. That makes it a useful indicator of underlying consumer interest, and it has been associated with market share and future demand. Treat that relationship as a signal, not proof that search activity caused a sale.

    The calculation is simple. The definition work is where teams usually create misleading results. Build the metric with a written protocol:

    1. Define the category. List the brands a buyer would reasonably consider for the same job. Do not quietly add or remove competitors when the trend becomes inconvenient.
    2. Define each brand query set. Record the main brand name, accepted spellings, common misspellings, and any product names you intend to count. Apply the same inclusion logic to every competitor.
    3. Lock the dimensions. Use the same geography, language, search platform, device scope, and reporting period whenever you compare one period with another.
    4. Preserve the numerator and denominator. Report your own branded volume, total category-brand volume, and the resulting share. The ratio alone hides why it changed.
    5. Version the methodology. When a rebrand, acquisition, new entrant, or product change requires a revised query set, record the effective point. Do not present the revised series as if its definition had always been identical.

    Keeping the numerator and denominator visible prevents four common misreadings:

    • Your branded volume and share can both rise, meaning your brand is gaining searches while outpacing the defined category set.
    • Your branded volume can rise while share falls, meaning category-brand demand grew faster than demand for you.
    • Your branded volume can fall while share rises, meaning category-brand demand contracted faster than demand for you.
    • Your branded volume and share can both fall, which warrants checking whether visibility, consideration, availability, or category conditions changed.

    Do not merge unlike platform counts into a polished but opaque index. Discovery and search behavior can span Google, Amazon, TikTok, YouTube, LinkedIn, and AI interfaces, but each environment exposes different data. Keep platform-specific views separate unless you have a documented normalization method. A directional signal with clear limits is more useful than false precision.

    Share of search is valuable partly because an onsite optimization cannot directly manufacture the underlying act of looking for a brand. It is still not immune to interpretation problems. News coverage, controversy, promotions, product launches, seasonality, and curiosity can increase searches without creating durable preference. Low category volume can also make the ratio jump when the underlying movement is small. Always inspect the raw demand and the business outcome beside the share.

    Interpret divergent signals before changing the budget

    Three executives compare symbolic traffic, awareness, search, and purchase signals around a circular decision table before moving budget blocks.

    A brand search is evidence of active interest, but it is not a receipt showing which exposure created that interest. An AI response may introduce the name. A video may make it memorable. A review may remove doubt. A branded search may simply be the easiest route back. Crediting the final click with the whole outcome confuses demand capture with demand creation.

    Classify touchpoints by the role they can plausibly play:

    • Demand creators introduce an idea, problem, category, or brand before the buyer is actively navigating to you.
    • Validators help the buyer assess credibility and fit through reviews, demonstrations, comparisons, case material, expert discussion, or other evidence.
    • Demand capturers make it easy for someone with existing intent to find your site, contact the business, or complete the next step.

    A channel can play more than one role. The point is not to force every interaction into a permanent bucket. It is to stop treating the easiest interaction to track as the only one that mattered.

    Use divergence between metrics as a diagnostic prompt:

    • Traffic falls while share of search and business outcomes hold. Investigate changes in click behavior, answer surfaces, rankings, tracking, and channel mix before declaring a brand problem. Cutting demand creation solely because site visits fell could remove the activity sustaining later branded demand.
    • Share of search rises while business outcomes remain flat. Check whether the new interest is qualified and whether the offer, availability, landing experience, lead handling, or sales process can convert it. Also compare the observation window with the normal buying cycle before assuming the demand has failed to monetize.
    • Generic traffic rises while branded demand weakens. Your content may be capturing category questions without making the brand memorable. Review whether the brand has a clear point of view, recognizable expertise, useful proof, and a logical next step.
    • Conversions improve while share of search falls. Better capture efficiency may be supporting current results while the future demand pool softens. Do not extrapolate conversion gains without investigating the demand trend.
    • Visibility, branded demand, traffic, and outcomes all decline. Treat this as a broader performance issue. Segment the change by market, product, audience, and channel to find where the deterioration begins.

    These patterns generate hypotheses; they do not establish causes. A line that rose after a campaign is not enough to prove the campaign caused the rise. Add campaign annotations, product changes, public-relations events, distribution changes, pricing events, and measurement changes to the same timeline. Segment by exposed and less-exposed markets or audiences when the data permits. For consequential budget decisions, use controlled tests or another defensible causal design where feasible.

    Self-reported attribution can also fill part of the blind spot. A carefully phrased question about how a buyer first heard of the brand may surface video, word of mouth, communities, events, podcasts, or AI tools that click tracking missed. Keep those responses in their own evidence stream rather than forcing them to reconcile perfectly with analytics. Each method observes a different part of the journey.

    Build an executive dashboard that leads to decisions

    An executive dashboard should not reproduce every channel report. Its job is to show whether the brand is creating demand, capturing it, and turning it into a business result. The reader should be able to see where signals agree, where they diverge, and what needs investigation.

    Organize the view in this order:

    1. Start with the business outcome. Choose the result that matches the business model, such as revenue, qualified pipeline, sales, renewals, or another explicitly defined outcome. Avoid a blended success score that nobody can audit.
    2. Add the demand layer. Show share of search, your branded search volume, and the category-brand denominator together. If different markets behave differently, provide the relevant market view rather than relying only on a global average.
    3. Add visibility and validation signals. Include only the measures that reflect how your buyers actually discover and assess brands. These might cover answer-engine presence, brand mentions, reviews, category visibility, video exposure, or engagement with proof-oriented content. Label coverage gaps clearly.
    4. Add demand-capture efficiency. Retain clicks, sessions, branded and nonbranded arrivals, lead completion, and conversion rate where they help diagnose execution. Clicks belong here as context, not as a substitute for brand demand or commercial results.
    5. Add the context timeline. Mark campaigns, launches, tracking changes, category events, and material changes to the metric definitions. Without this layer, teams tend to invent explanations after seeing the chart.

    Every dashboard metric needs a small measurement contract. Record its business question, exact formula, data source, inclusions, exclusions, reporting scope, update cadence, owner, and known limitations. If two teams can calculate different values while claiming to report the same metric, the dashboard is not ready for a budget discussion.

    Give each executive metric a decision rule as well. A useful rule names the condition, the investigation it triggers, and the decision it may change. For example:

    • If share of search declines while category-brand demand is stable, inspect competitor gains, brand visibility, and market segments before changing capture-channel spend.
    • If share of search grows but qualified outcomes do not, inspect intent quality and conversion constraints before buying more awareness.
    • If traffic declines but branded demand and business results remain healthy, investigate the distribution change without treating session recovery as the automatic objective.
    • If a metric cannot change an executive decision, move it to the operating report where the channel team can still use it diagnostically.

    This structure also changes how SEO and AI-search work is evaluated. Nonbranded visibility can introduce the brand. Useful content can validate expertise. AI visibility may influence later discovery without producing a referral. Branded search can reveal active demand. The website and sales process then capture and convert that demand. Measurement becomes a connected operating model instead of a contest over which platform receives the final credit.

    Key takeaways

    • Clicks and traffic measure observable demand capture; neither one measures the full effect of brand exposure.
    • Use share of search to track branded demand relative to a stable, documented competitive set, and always show the raw numerator and denominator.
    • Keep business outcomes, brand demand, visibility, validation, and capture efficiency in separate layers so one metric cannot conceal weakness in another.
    • Treat divergent signals as hypotheses to investigate. A later branded search does not prove which earlier touchpoint created the preference.
    • Define every executive metric, disclose its coverage limits, and connect it to a decision rule before using it to move budget.

    At your next performance review, place share of search and one agreed business outcome beside the traffic chart. Keep the clicks, but require the three signals to be interpreted together. The first useful change is not a more elaborate attribution model. It is a dashboard that can tell the difference between lost traffic, weak demand, poor demand capture, and an actual decline in the brand.

    References

  • How TV Advertising Changes Search Behavior and Demand

    How TV Advertising Changes Search Behavior and Demand

    A TV campaign can do its job and still look inefficient in your dashboard. The spot creates curiosity, the viewer searches, and search receives the click and often the conversion. If the channels are reported separately, search gets credit for demand it did not create while TV loses credit for the action it caused.

    When a campaign is approaching, your practical problem is not whether TV affects search. It is whether the questions created by the commercial will meet the right result, whether your pages and paid campaigns can capture the resulting demand, and whether measurement can distinguish demand creation from demand capture. Treat those as one operating system.

    TV changes the query, not just the number of searches

    TV advertising does more than send extra people toward keywords that already exist. It can change what people search for, how specific their searches become, and which brand they include in the query.

    Someone who might otherwise search for a category such as car insurance may search for a particular insurer after seeing its commercial. Someone who was not shopping at all may search for the actor, song, claim, product, offer, or scene they remember. A later search may become more commercial: price, reviews, availability, eligibility, alternatives, or where to buy.

    That produces several distinct kinds of demand:

    • Navigational demand: The viewer remembers the company or product and wants the official destination.
    • Campaign-identification demand: The viewer remembers a celebrity, character, song, phrase, or plot but not necessarily the brand.
    • Informational demand: The commercial creates a question about what the product does, how an offer works, or whether a claim applies to the viewer.
    • Commercial-investigation demand: Interest turns into searches for pricing, reviews, comparisons, specifications, availability, or alternatives.
    • Transactional demand: The viewer looks for a store, application, booking page, product page, or other way to act.

    The sequence is not always linear. A viewer can search during the commercial on a second device, later that evening after another exposure, or days afterward when a related need appears. Comscore’s 2024 work connected coordinated TV and digital activity with stronger engagement and second-screen actions. In February 2025, YouTube also said television had overtaken mobile as the primary device for its U.S. viewing, based on Nielsen data. Your TV-to-search plan therefore needs to cover broadcast, connected TV, and streaming rather than treating them as separate consumer journeys.

    The timing can be fast. Google and Nielsen found in 2015 that TV ads could increase branded search queries by up to 20%, often within hours of an airing. DAIVID, a creative-analytics provider, has offered a higher vendor estimate of up to 60%, with the possibility of more in well-coordinated campaigns. Those figures demonstrate the possible scale, but they are upper bounds from different contexts, not universal planning assumptions. Reach, repetition, creative attention, prior brand awareness, category demand, market conditions, and the clarity of the call to action all affect the result.

    Do not place 20% or 60% into a forecast as if TV produces a fixed search multiplier. Build your planning range from your own previous airings, separated by market, creative, product, and schedule. If this is your first flight, treat branded search lift as a measurement question rather than a promised outcome.

    A useful working model is: exposure → attention → memory or curiosity → query → result → action. Search teams control the final handoffs. If the memorable clue from the commercial is absent from your pages, ads, video metadata, and entity information, viewers can be interested and still fail to find you.

    Build the search surface from the creative itself

    A television, phone, and laptop display matching unbranded visual elements connected by glowing lines.

    Keyword tools show existing demand. A new commercial can create language that did not have meaningful volume before the campaign. Start with the finished creative, not with last month’s keyword export.

    Watch the commercial without the creative brief in front of you. Record what an ordinary viewer could actually remember: the spoken brand name, product name, campaign line, spokesperson, character, visual device, offer, claim, date, location, and requested action. Then watch it again without sound. Connected-TV viewers may be distracted, and visual memory can produce a different query from the approved campaign wording.

    Turn those observations into a search-intent inventory:

    1. List exact entities. Include the brand, product, service, campaign, spokesperson, featured organization, and location named or shown in the spot.
    2. Write identification queries. Model the fragments a viewer might remember, such as [brand] commercial actor, ad with [scene], or what company made the ad about [theme].
    3. Write promise and explanation queries. Include the central benefit, claim, offer, qualification, or problem depicted in the commercial.
    4. Write action queries. Cover price, availability, release date, eligibility, locations, applications, bookings, trials, and where to buy when those intents apply.
    5. Add natural variants. Include abbreviations, common misspellings, shortened product names, and spoken versions of stylized brand names.
    6. Map every query family to a destination. Assign an existing page, create a new one, or document why paid coverage is the appropriate route.
    7. Inspect the live results. Search the phrases from the target market and device context. Check whether the correct page appears and whether the title and description make the relationship to the commercial obvious.

    The map should connect each memory or intention to an answer, not merely to your home page.

    Search signalLikely query patternBest destinationFailure to catch before airing
    Brand or product recall[brand], [product name]Official brand or product pageAn outdated page, reseller, or competitor is more prominent
    Memory of the creative[brand] commercial song, ad with [person or scene]Campaign page, video page, or concise commercial FAQThe creative clue appears nowhere in crawlable text or video metadata
    Offer or claim[offer] terms, how does [claim] workOffer page with conditions, dates, and next stepThe landing page repeats the slogan but does not explain it
    Evaluation[product] reviews, [product] vs [alternative]Product details, evidence, comparison, or review resourcesThe viewer must leave the site to understand basic differences
    Availability or locationwhere to buy [product], [service] near meStore locator, local page, product listing, or booking flowInventory, locations, or business information is inconsistent
    Eligibility or applicationwho qualifies for [offer], apply for [service]Eligibility explanation and application pageImportant restrictions appear only after the user starts converting

    The destination should visibly repeat the language and visual identity of the commercial. A viewer who searches after seeing an ad is looking for recognition as much as information. If the page uses a different product name, campaign line, image, or offer, the visitor has to decide whether they found the right company before they can consider the product.

    Put the answer to the commercial’s main unresolved question near the beginning of the page. Include dates, eligibility, price conditions, inventory limits, or geographic restrictions when the campaign depends on them. A memorable slogan is not an explanation. Sending every query to a generic home page wastes the context that made the search valuable.

    Prepare the machine-readable layer with the same discipline. Use Organization, Product, Offer, or VideoObject structured data only when the visible content supports it. Keep names, URLs, images, availability, dates, and offer details consistent across the page and markup. If you publish the commercial, include a useful title, description, transcript or summary, thumbnail, and campaign context. Structured data can clarify entities and relationships for search and answer systems, but it cannot repair an absent answer or an unsupported marketing claim.

    Write a few direct, self-contained answers for people who search conversationally or ask an AI assistant to identify the ad. State what the campaign promotes, which product or service appears, how the offer works, and where someone can act. Do not bury those facts in brand language that only makes sense after a visitor has watched the full commercial.

    Run paid and organic search as one response system

    Organic pages cannot be switched on at the moment an ad airs. They need to be published, crawlable, internally linked, indexed, and tested beforehand. Paid search can respond more quickly, but it still needs the right keywords, creative, budgets, locations, schedules, landing pages, and measurement conventions before volume arrives.

    Before the flight

    • Create one airing log with the creative ID, campaign name, product, market, channel or platform, planned timestamp, and time zone. Search and analytics teams should use the same identifiers.
    • Verify that every mapped landing page is indexable, uses the intended canonical URL, works on mobile, and completes its conversion path without errors.
    • Check page titles, descriptions, headings, visible copy, video metadata, structured data, and internal links against the language viewers will remember.
    • Build paid coverage for brand, product, campaign, offer, and high-value action queries. Review match types and negative keywords so a new campaign phrase is not accidentally blocked.
    • Confirm that budgets and targeting reflect the markets and times receiving media. A national paid-search increase is a poor response to a limited regional TV schedule.
    • Record a baseline for branded, product, campaign-related, and non-brand category queries before the campaign changes demand.
    • Test site capacity, inventory feeds, forms, phone routing, store data, and analytics events. A search spike has little value if the next step fails.

    Share creative changes immediately. A late edit to an offer, product name, spokesperson, or campaign line can invalidate keyword coverage and landing-page copy even when the media schedule stays the same.

    During the flight

    Monitor around actual airings where the volume supports that level of analysis. Look at branded and campaign-cue queries, paid impression share, spend, click-through rate, organic impressions, landing-page traffic, page errors, conversion events, on-site searches, and customer questions. Use the time zone recorded in the airing log; otherwise an apparent lag or lead may be a reporting error.

    Paid copy should repeat the recognizable product, benefit, and offer from the commercial, then add the practical detail the viewer needs. If the spot is emotional and the search ad sounds like unrelated direct-response copy, the handoff feels broken. Consistency does not require copying the script. It requires confirming that the searcher has reached the right answer.

    Do not automatically raise bids on every branded query. Blanket increases can make you pay for visits your organic result would have received anyway. Paid brand coverage is more defensible when competitors are present, the results are ambiguous, the campaign needs a precise destination, or the organic page is not yet strong enough. Where volume allows, compare markets or airing windows with and without paid brand coverage to estimate whether the ads add clicks and conversions rather than merely moving them from organic search.

    Watch the mix, not just total volume. If searches grow for the actor or song but not the brand or product, the entertainment may be more memorable than the advertiser. If viewers search for basic eligibility, pricing, or meaning, the spot has created interest but left a consequential question unresolved. Update paid copy and owned answers while the campaign is still running.

    After an airing or flight

    Do not remove campaign pages the moment paid media stops. Search can lag an exposure, and commercials can continue circulating through streaming, video sharing, press coverage, and memory. Use your own query and visit decay to decide how long active paid support should remain.

    When an offer expires, keep a useful destination if people are still searching. State clearly that the promotion ended, preserve relevant campaign context, and direct visitors to a current product, offer, or support page. Replacing a known campaign URL with a generic error page converts residual demand into confusion.

    Annotate changes to the creative, media weight, search campaigns, pages, offers, pricing, and tracking. Without that change log, a later analyst may attribute a search shift to the wrong channel or assume that two materially different commercials were the same treatment.

    Measure incremental demand without giving search all the credit

    Two miniature neighborhoods show different levels of glowing activity from televisions to phones and destinations.

    Last-click reporting answers which channel completed the recorded journey. It does not answer which channel created or accelerated the need to search. A branded search conversion after a commercial may be captured by PPC or SEO while being caused partly by TV. The reverse mistake is also possible: not every branded search during a TV flight was caused by the campaign.

    Separate three layers in your reporting:

    • Demand response: Incremental brand, product, campaign-cue, and relevant category searches associated with the airing.
    • Search capture: The portion of available demand reached through organic and paid results, followed by clicks and useful landing-page behavior.
    • Business outcome: Incremental leads, purchases, store actions, applications, bookings, or other outcomes after accounting for the demand that would have existed without TV.

    This distinction prevents a common misreading. A successful TV campaign can lower the conversion rate of search traffic because the commercial brings in a broader, earlier-stage audience. More curious visitors may arrive before they are ready to buy. Total incremental conversions can rise even while the percentage of visits that convert falls. Judge the campaign using volume and incrementality alongside conversion rate, not conversion rate in isolation.

    Use a repeatable measurement sequence:

    1. Define the expected baseline. Compare with similar non-airing periods, matched weekdays and dayparts, previous weeks, or comparable markets. Adjust the baseline when seasonality or an established trend makes a simple average misleading.
    2. Align the airing log. Use actual timestamps and markets when available, not merely the campaign’s overall start and end dates.
    3. Group queries by intent. Separate brand, product, campaign identifier, offer, high-intent non-brand, navigational, and unrelated searches. A total branded-search line can conceal what changed.
    4. Inspect multiple response windows. Look for an immediate second-screen response and a later memory response. Do not force one universal attribution window onto every product, creative, or buying cycle.
    5. Control overlapping activity. Promotions, product launches, email, public relations, influencer activity, news, seasonality, competitor campaigns, site changes, and search-platform changes can all move demand at the same time.
    6. Use a comparison design when feasible. Matched geographic markets, staggered schedules, non-airing periods, or carefully chosen holdouts produce a stronger estimate than a simple before-and-after chart.
    7. Reconcile the channels. Report how much demand appeared, how much search captured, and how much converted. Do not add TV-attributed and search-attributed conversions if both labels include the same people.

    A simple diagnostic calculation is: search lift (%) = (observed query volume – expected query volume) / expected query volume x 100. The difficult part is not the arithmetic. It is constructing a credible expected value. A baseline contaminated by a promotion or product launch will produce a precise-looking but unreliable lift figure.

    No single platform supplies the complete denominator. Google Trends shows relative interest rather than absolute query counts. Search Console shows impressions and clicks involving your properties, not every search in the market. Paid-search reporting describes the auctions and traffic your campaigns entered. Web analytics describes visits and recorded outcomes after a user reaches the site. Read those alongside airing data, direct traffic, on-site search, video search behavior, sales, calls, and customer-service questions.

    Search terms also function as creative feedback, but only when you interpret their meaning:

    • A rise in exact brand and product searches indicates that viewers connected the message to the advertiser.
    • A rise dominated by the celebrity, song, or scene can indicate strong entertainment recall but weak brand linkage.
    • Queries such as what company is that ad or repeated misspellings can expose a naming or pronunciation problem.
    • Growth in pricing, availability, location, or application queries signals movement toward action and tells you which destination must be strongest.
    • Growth in eligibility, explanation, or what does it mean queries reveals an information gap. The gap may be intentional curiosity, but the search result still has to resolve it.
    • Complaint, skepticism, or confusion queries should not be counted as favorable response merely because volume increased. Investigate the underlying issue and adjust the answer or campaign where warranted.

    Branded search volume is therefore a useful creative-response indicator, not a standalone verdict. It tells you that the commercial entered behavior. Query composition, result quality, incremental visits, and business outcomes tell you whether that behavior helped.

    Key takeaways

    • TV can create navigational, informational, commercial, and transactional searches; it can also shift an existing generic search toward a named brand.
    • Search response may begin within minutes or hours, so pages, paid campaigns, tracking, and operational systems must be ready before the commercial airs.
    • Build the keyword and content map from what viewers can remember in the creative, including the product, offer, person, phrase, scene, and unresolved question.
    • Give every important query family a recognizable destination instead of sending all TV-driven demand to a generic home page.
    • Coordinate paid-search schedules and budgets with actual markets and airings, while testing whether branded ads add incremental value over organic results.
    • Measure demand creation separately from search capture, then use matched baselines or holdouts to estimate the incremental effect.
    • Read the query mix as feedback: product searches, campaign-identification searches, action searches, and confusion searches tell you different things about the creative.

    Before the next creative lock, bring the media schedule, search team, analytics owner, web team, and campaign decision-maker into the same handoff. Leave with four concrete artifacts: a query inventory, a destination map, a scheduled paid-search plan, and a measurement sheet with baselines and comparison markets or periods.

    If one of those is missing, the campaign is not fully ready. The goal is not to make TV look like search or search look like TV. It is to ensure that the demand your commercial creates reaches a clear answer, and that each channel receives credit for the part of the journey it actually performed.

    References

  • Bing’s Grouped Search Ad Design: What Advertisers Should Do

    Bing’s Grouped Search Ad Design: What Advertisers Should Do

    If your Bing search ad click-through rate rises while conversions barely move, do not congratulate the creative team yet. The interface itself may have changed what a click means.

    Bing is testing a grouped ad design that makes paid listings look more like a continuous set of search results. The practical response is not to guess whether the format is good or bad. It is to separate useful demand from interface-driven clicks before you change bids, budgets, ads, or landing pages.

    The interface change alters what a click can mean

    In the observed Bing test, several paid listings appear beneath one “Sponsored results” label. The individual ads below the first one do not receive their own labels. Searchers can also use a “Hide” control to collapse the block and a “Show” control to restore it.

    That changes the visual unit a searcher encounters. Instead of evaluating several clearly separated ads, the user may perceive one sponsored section containing results that resemble the organic listings below it. The format could make ads more noticeable, but it could also make the paid status of an individual listing easier to miss.

    The experiment remains limited, so you should not assume every impression in your account uses this design. You also should not infer that the test changes auctions, targeting, ranking, or attribution rules. A presentation change is enough to affect behavior even when the campaign underneath it stays the same.

    This distinction matters when you review performance. A click has always combined two things: the searcher’s underlying interest and the interface’s ability to attract attention. Grouping can change the second factor. If you treat every resulting CTR increase as stronger intent, you may bid more aggressively for traffic that is no more valuable than before.

    Diagnose performance with a metric chain, not CTR alone

    Four linked visual modules represent an impression, click, landing-page visit, and completed action under a magnifying lens.

    CTR is clicks divided by impressions. It tells you whether an impression produced a click, but not whether the person understood that they were selecting an ad or whether the visit created business value. Read CTR alongside conversion rate, cost per acquisition, conversion volume, search-term quality, and post-click behavior.

    A comparable grouped design on Google prompted an informal X poll in which 63% of respondents said they had clicked an ad unintentionally. That number is a warning signal, not a forecast for Bing. A voluntary social-media poll cannot establish the accidental-click rate among Bing users or prove that grouping caused every reported mistake.

    Your own conversion economics are more useful than that headline number. Read changes as a sequence:

    What you observeWhat it may meanWhat to do next
    CTR rises, while conversion rate and cost per acquisition remain healthyThe additional clicks may be useful, although the design is not necessarily the causeCheck lead or order quality before increasing bids or budgets
    CTR rises, conversion rate falls, and cost per acquisition worsensThe extra clicks may carry weaker intent, or another campaign change may have altered traffic qualitySegment the shift by query, device, campaign, and audience before changing the whole account
    Clicks and spend rise, but conversions remain flatIncremental traffic is consuming budget without producing a matching business resultProtect the account’s cost guardrail and reduce exposure in the affected segment if necessary
    CTR rises alongside shorter or less engaged visitsUsers may be arriving with the wrong expectation, but landing-page speed or message mismatch can produce the same patternCompare the ad promise, query intent, and first visible landing-page message
    Paid clicks rise while organic clicks fall for the same query familyThe new presentation may be redistributing existing demand rather than creating more of itEvaluate total search conversions and revenue instead of celebrating one channel’s gain

    The combination of higher CTR and lower conversion rate deserves particular attention. If clicks grow faster than conversions, conversion rate falls by definition. If spend then grows faster than conversions, cost per acquisition deteriorates. That is the signature to investigate when you suspect interface-driven traffic.

    Do not automatically call it an accidental-click problem. A promotional change, broader matching, altered bids, seasonality, a slow landing page, or weaker offer alignment can create the same pattern. The layout is one hypothesis to test against the rest of the account history.

    Build an audit trail while test exposure is uncertain

    A search advertising specialist compares a grouped-results layout with campaign signals while arranging blank snapshot tiles on a desk.

    You need a record that lets you distinguish a search-interface shift from your own campaign changes. Start before performance looks unusual, because reconstructing the sequence later is difficult.

    1. Document every confirmed sighting. Save a screenshot and record the query, device type, location, date, signed-in state if known, and whether the Hide and Show controls appeared. A screenshot proves the layout was visible in that context; it does not prove all campaign impressions used it.
    2. Annotate changes under your control. Record bid, budget, targeting, keyword, creative, conversion-tracking, offer, and landing-page changes. Without this log, a performance shift that follows your own edit can easily be blamed on the interface.
    3. Create a comparable baseline. Use periods that make sense for your sales cycle and account volume. Account for promotions, weekdays, seasonality, and major demand changes. A large but poorly matched baseline is less useful than a smaller comparable one.
    4. Segment before averaging. Review brand and non-brand traffic separately, then inspect query themes, campaigns, devices, locations, and audiences using the dimensions available in your reporting. A localized problem can disappear inside an account-wide average.
    5. Pair every attention metric with an outcome metric. Match impressions with clicks, clicks with qualified visits or conversions, and spend with revenue, pipeline value, or another business result. For lead generation, include accepted-lead quality when possible; a form submission alone may hide low-intent traffic.
    6. Define your response before the numbers move. Use the CPA, return, margin, or lead-quality limits already required by the business. If performance crosses a financial guardrail, contain the affected segment rather than waiting for perfect causal proof.
    7. Label causal claims honestly. If you cannot identify which impressions received the grouped layout, you have a correlation, not a controlled test. Say that clearly in stakeholder reporting.

    The strongest comparison would separate traffic exposed to the grouped design from otherwise similar unexposed traffic. If you do not have a reliable exposure indicator, screenshots and timing can support an investigation, but they cannot turn normal account reporting into an experiment.

    Adjust the campaign without chasing a temporary layout

    A limited interface test does not justify rewriting an entire account. Start with changes that improve informed selection under any search design.

    • Make the advertiser and offer unmistakable. Use clear brand, product, service, and destination language. Do not rely on the visual ad label to explain what the person will reach.
    • Qualify before the click when it helps the user. Accurate price, location, audience, availability, or eligibility details can discourage unsuitable visits. Add only qualifications that are true and material to the decision.
    • Keep the landing-page handoff literal. The first visible page content should confirm the same offer and intent expressed by the query and ad. A user who has clicked quickly should not have to infer why the page is relevant.
    • Inspect search terms for the affected segments. If the increase comes from irrelevant or weakly related queries, refine targeting and exclusions. A visual redesign cannot rescue poor query-to-offer alignment.
    • Use meaningful conversion actions. Separate valuable outcomes from shallow actions where your measurement permits it. Otherwise, an increase in low-value activity can disguise deteriorating customer quality.
    • Protect budget at the narrowest useful level. If spend rises without a corresponding result, constrain the specific campaign, query class, device, or audience showing the problem. Broad account cuts can suppress traffic that remains profitable.

    For lead-generation campaigns, adding deliberate qualification to the page or form can reveal whether new clicks reflect genuine interest. That does not mean creating pointless friction. Ask only for information needed to assess fit, and track whether accepted leads improve rather than judging success by raw form volume.

    For ecommerce campaigns, compare paid click growth with completed orders, revenue, and margin. If traffic rises but product engagement and purchases do not, check whether the query, ad, price, and landing product still describe the same proposition. The grouped design may expose an existing mismatch rather than create it.

    SEO and paid-search teams should also review overlapping query families together. A paid CTR gain accompanied by an organic click loss may be a redistribution of the same demand. The better question is whether total qualified search traffic, conversions, and revenue increased after accounting for the added ad spend.

    Key takeaways for Bing search advertisers

    • Bing is testing multiple ads beneath one “Sponsored results” label, with controls that let users hide and restore the entire sponsored block.
    • The test is limited, so do not assume all impressions use the grouped format or attribute every account change to it.
    • A CTR increase is useful only when conversion quality and cost efficiency hold up downstream.
    • The reported 63% accidental-click figure came from an informal poll about a comparable Google design; it identifies a risk to investigate, not a Bing benchmark.
    • Document confirmed sightings and your own campaign edits so that timing alone does not become your evidence.
    • If costs deteriorate, contain the affected segment using existing business guardrails while continuing to investigate.
    • Judge paid and organic search together when both channels serve the same query intent.

    Treat the redesign as a measurement problem first. Preserve your baseline, watch the path from impression to business outcome, and make the smallest defensible campaign change when the economics require one. If Bing expands the format, you will already have the evidence needed to decide whether its extra clicks are helping you or merely costing you more.

    References

  • Google Ads and Shopping Changes: What to Prioritize Now

    Google Ads and Shopping Changes: What to Prioritize Now

    You’re deciding which Google changes deserve engineering time, which belong in your Shopping plan, and which are still too speculative to enter a forecast. The answer isn’t to treat every announcement, test, and rumor as equally actionable.

    The clearest opportunity is first-party data infrastructure. Local Shopping labels deserve feed preparation and controlled observation. Gemini advertising belongs on a watchlist, not in a committed media plan. That order will help you improve what is available without budgeting against a product that doesn’t exist.

    Key takeaways for advertisers

    • Prioritize the Data Manager API when separate integrations are creating duplicated work or inconsistent first-party data flows.
    • Treat merchant city and town labels in Shopping ads as an observed test. Prepare accurate local inventory data, but don’t forecast an uplift or assume every eligible impression will show the label.
    • Keep Gemini separate from AI Mode in your planning. Google’s stated position is that the Gemini app has no ads and there are no plans to add them.
    • Classify every platform change as available, experimental, or unconfirmed before assigning budget, engineering effort, or performance targets.

    First-party data deserves the engineering time

    Illuminated data pathways connect customer touchpoints to a protected central data hub and several activation modules.

    Google’s Data Manager API is the most concrete change because it solves an operational problem you may already have: audience data, offline conversions, and other first-party signals reaching Google through separate connections. The API is designed to provide one integration point across Google Ads, Google Analytics, and Display & Video 360.

    That consolidation matters when your team maintains one job for customer lists, another for offline conversion uploads, and additional platform-specific logic for authentication, retries, or refreshes. A shared route can reduce that maintenance burden. It can also make ownership clearer when a data flow fails.

    The API supports three jobs that directly affect campaign operations: uploading and refreshing audience lists, sending offline conversions, and supplying richer signals for bidding. Those capabilities don’t guarantee better performance. They give Google’s automated systems more useful inputs, and you still need to verify whether those inputs change measurement or campaign outcomes in your account.

    Use a bounded migration sequence rather than moving every data flow at once:

    1. Inventory the current routes. Record which process sends each audience or conversion type, how often it runs, who owns it, and what happens when records fail.
    2. Choose one well-understood flow. Start with an audience list or offline conversion type whose current volume, update pattern, and business meaning are already known. A familiar baseline makes discrepancies easier to find.
    3. Define the data contract before building the endpoint. Agree on identifiers, event names, time fields, refresh frequency, correction handling, and ownership. A unified API won’t reconcile two teams using different meanings for the same conversion.
    4. Validate the new and existing routes side by side. Compare submitted, accepted, rejected, and delayed records where those measures are available. Do not send the same event through both routes unless you have verified how duplicates are prevented.
    5. Check reporting before changing bidding. Confirm that conversion totals, audience freshness, and processing delays behave as expected. Only then should you evaluate whether richer signals help automated bidding.
    6. Retire an old connection only after reconciliation. Keep a rollback path until the new route has completed its normal refresh and correction cycles without unexplained gaps.

    This sequence protects the part of the account with financial consequences: measurement. If an integration drops conversions, submits duplicates, or changes event meaning, bidding can optimize against a distorted picture. Parallel validation is less expensive than discovering the problem after an automated campaign has reacted to it.

    The strongest adoption case is a team already maintaining several Google connections. If you have one stable data flow and little engineering overhead, consolidation may be less urgent. Start with the operational cost you can document, not the assumption that a new API automatically creates incremental revenue.

    Local Shopping labels make feed accuracy visible

    A retail employee scans a product beside organized shelves, a tablet, a stockroom, and a local pickup counter.

    Some Shopping ads using local inventory data have displayed the merchant’s city or town above the product title. The placement gives shoppers a proximity cue without requiring a separate local ad format. It is distinct from fulfillment labels such as In-store, Pickup later, and Curbside pickup.

    That distinction is important. A city label tells the shopper where the merchant is located. By itself, it doesn’t promise immediate availability, same-day collection, or a particular fulfillment method. Your inventory and pickup information still need to carry those meanings accurately.

    Google has not published rollout, eligibility, or technical requirements for the location-label test. You therefore shouldn’t look for an undocumented switch, promise the placement to stores, or build a performance forecast around it. The practical move is to make the local inventory setup reliable enough to benefit if the label appears.

    • Check store and product coverage. Confirm that the intended locations and locally available products are present in the systems supplying your local inventory data.
    • Standardize location names. Resolve inconsistent city or town naming across store records before those differences become visible to shoppers or fragment your analysis.
    • Audit location and fulfillment separately. A correct city label cannot compensate for stale availability or pickup information, and a pickup label does not confirm that the displayed city is the location you intended to promote.
    • Record observed appearances. When your team sees the label, capture the market, store, query context, device, and date. That record will help you distinguish a limited test from a broader change.
    • Measure at the local level. Compare results by store or market where activity is sufficient, rather than blending exposed and unexposed locations into an account-wide average.

    A recognizable or nearby location could make a merchant feel more relevant than a distant seller. That is a plausible shopper response, not a guaranteed click-through or store-visit lift. Let observed exposure and local results establish the value before you change budgets.

    Gemini advertising is not a 2026 media plan

    Claims that the Gemini app would receive dedicated ad placements in 2026 prompted a direct denial from Google. Its stated position was that there are no ads in the Gemini app and no plans to change that.

    That doesn’t settle how every Google AI experience will be monetized indefinitely. It does settle what belongs in a responsible plan based on the information available: no Gemini inventory, targeting assumptions, pricing model, creative specification, eligibility rule, or measurement framework should appear as a committed line item.

    Keep Gemini and AI Mode in separate rows of your channel plan. Ads associated with AI Mode do not prove that the Gemini app will use the same inventory or commercial model. Product names, interfaces, and user behavior may look related while their advertising availability remains different.

    A useful planning boundary is simple:

    • Available inventory can receive budget when your account is eligible and its economics fit the campaign.
    • An observed test can receive monitoring, data preparation, and a measurement plan, but not assumed reach or revenue.
    • A denied or unconfirmed product stays on a watchlist until Google supplies an official product path, eligibility details, and reporting expectations.

    You can still prepare strategically. Decide which customer questions, product attributes, and conversion events would matter in a conversational ad environment. Do not assume, however, that current Google Ads audiences, Shopping feeds, or Data Manager integrations will automatically transfer to a future Gemini product. No documented product connection supports that implementation decision.

    Use one evidence rule for every platform change

    The three developments require different actions because their evidence states are different. Put them in a change register that your paid media, ecommerce, analytics, and engineering teams can read without translating headlines into strategy on their own.

    Platform changeDocumented statusAction nowDo not assume
    Data Manager APIAvailable across Google Ads, Google Analytics, and Display & Video 360Pilot one audience or offline conversion flow and reconcile it before consolidationThat a new connection fixes weak data or guarantees a performance gain
    Shopping merchant location labelObserved test using local inventory data; rollout and requirements are unannouncedAudit local feeds, standardize locations, and prepare store-level measurementUniversal exposure, a configuration switch, or an automatic traffic lift
    Gemini app adsGoogle denied that ads are present or plannedKeep the possibility on a monitored watchlist2026 inventory, pricing, formats, targeting, or compatibility with AI Mode

    For each entry, record the affected surface, evidence status, business dependency, owner, next action, and condition that would justify changing the status. An official availability notice could move a test into implementation. Repeated sightings without documentation may justify broader measurement, but not a guaranteed forecast. A rumor should not advance because it has been repeated.

    Start with the first-party data inventory because it can improve infrastructure you already use. Then audit local feeds so your stores are ready for location-led Shopping presentation. Remove Gemini placements from committed projections unless Google replaces its denial with a real product announcement. That gives you a plan based on executable changes rather than imagined inventory.

    References

  • How to Measure SEO and Choose Tools That Earn Their Budget

    How to Measure SEO and Choose Tools That Earn Their Budget

    Your SEO stack can produce a dashboard full of green arrows and still leave you unable to defend the next renewal. If you are deciding whether to keep a platform, add AI-search monitoring, or build an internal agent, the first question is not which option has the longest feature list. It is what decision the investment must improve.

    Build the measurement system before the shortlist. You will expose missing data, avoid paying twice for the same capability, and give every candidate a real job to perform.

    Key takeaways

    • Define the business outcome, search signal, diagnostic evidence, decision, and owner before evaluating any tool.
    • Use the 24-hour view for investigation, weekly reporting for operating decisions, and monthly reporting for direction and resource allocation.
    • Buy a capability only when it closes a documented measurement or workflow gap. An AI label is not a use case.
    • Run trials with representative weekly work, the same inputs, and pass-or-fail criteria that matter after the demo.
    • Separate observed trial evidence from forecast business impact. A short trial can validate a workflow, but it cannot prove future revenue.

    Build a measurement brief before opening a vendor tab

    Five connected groups of objects represent a business target, search signals, evidence, a decision gate, and an action on a strategy table.

    SEO tool evaluations often begin with feature inventories because features are easy to count. That produces a weak business case: leadership generally needs a connection to business results, while many platforms stop at keyword volume, optimization speed, or activity.

    Replace the feature wish list with a short measurement brief. Complete these fields before you request a demo:

    • Business question: State the decision in plain language. Examples include which landing-page group deserves investment, whether a technical release repaired organic acquisition, or which market needs local content.
    • Outcome: Name the result the business already recognizes, such as qualified leads, completed orders, subscriptions, booked consultations, or another defined conversion.
    • Search-performance signal: Identify what you expect to move before the outcome does. Depending on the job, that could include impressions, clicks, landing-page traffic, organic conversions, or search visibility for a defined query set.
    • Diagnostic evidence: List the information needed to explain the movement, such as indexation status, page-template defects, query mix, SERP composition, country, language, or device.
    • Decision rule: Describe what you will do when the evidence changes. A metric without a resulting action is reporting inventory, not a requirement.
    • Owner and cadence: Name who reviews the result, who receives the work, and whether the decision belongs in incident response, a weekly queue, or monthly planning.
    • Boundary: Record what the measurement will not prove. This prevents a ranking change, an alert, or an AI-generated recommendation from being presented as revenue attribution.

    Keep outcomes, performance indicators, and diagnostics separate

    A useful SEO measurement model has distinct layers:

    • Outcome measures describe business results: revenue, qualified demand, completed transactions, subscriptions, or another accepted conversion.
    • Performance indicators describe how organic search contributed: query impressions, clicks, landing-page visits, conversions attributed to organic sessions, and visibility within a defined search set.
    • Diagnostic measures help explain why performance changed: crawling and indexation states, template issues, internal-linking gaps, SERP changes, or differences between markets and devices.

    Do not collapse these layers into a proprietary health score and assume the result has business meaning. A technical score can improve without demand changing. Visibility can rise on queries that never produce a useful visit. Organic conversions can move because of a pricing change, promotion, tracking repair, or landing-page redesign rather than the SEO work being evaluated.

    Write the evidence chain explicitly: the work performed, the observable search change, the on-site action, and the business outcome. Annotate releases and tracking changes. Compare the affected page or query group with a relevant unaffected group when one exists. If the chain is incomplete, call the result an association or an operational improvement rather than attribution.

    Measure at the level where the intervention happened. A template fix should be evaluated on the affected template group. A localized content program should be separated by country and language. A rewrite aimed at one query theme should not be judged only through a sitewide total. Aggregation can make a successful change disappear, or make an unrelated gain look like success.

    Match the reporting interval to the decision

    Google Search Console performance reporting now includes weekly and monthly views in addition to the familiar 24-hour perspective. The practical benefit is not another way to format a chart. It is the ability to choose a reporting grain that fits the question.

    Reporting viewQuestion it should answerWhat not to use it for
    24-hourDid an abrupt change coincide with a release, tracking failure, indexing problem, or other incident?Declaring a durable trend from a short movement.
    WeeklyIs the movement persistent enough to enter the operating queue, and did recent work affect the intended pages or queries?Proving long-term business return from a single reporting period.
    MonthlyIs the program moving in the intended direction, and should priorities or resources change?Finding the exact cause of a sudden failure.

    Use the shortest interval that can answer the decision without letting routine variation dominate it. Then preserve the finer view for diagnosis. A monthly decline can justify investigation; the weekly and 24-hour views help locate when it began and which segment moved.

    Reporting grain does not fix a poor comparison. Compare complete periods with complete periods. Keep seasonal demand and major campaigns in view. Do not compare a global total after launching a new locale without separating the new market from established ones.

    Segment before you explain. Useful cuts include query theme, landing-page group, template, device, country, language, and a documented branded-versus-non-branded rule. A flat sitewide result can conceal growth in one segment and decline in another.

    Maintain a change log next to the performance data. Include site releases, migrations, tracking changes, canonical-rule updates, internal-linking work, and major campaigns. When performance moves, check those known events before assigning the change to an algorithm, competitor, or tool recommendation.

    Turn capability gaps into must-pass jobs

    A shortlist should reflect the gaps in your measurement brief. Useful evaluation areas include advanced data analysis, SERP intelligence, meaningful automation, multilingual support, and transparent pricing. Those labels are still too broad to purchase. Convert each one into a task and a required form of evidence.

    CapabilityTrial jobEvidence required
    Advanced analysisConnect search performance, landing-page behavior, and the defined business outcome for the affected page group.Repeatable definitions, visible transformations, segment-level results, and an export that another analyst can inspect.
    SERP intelligenceExplain a visibility change for a defined query set and market.The underlying queries, capture context, date, location, device, competing results, and relevant search features rather than an unexplained score.
    AutomationComplete a recurring weekly task from detection to prioritized handoff.Rules, exceptions, deduplication, evidence attached to each recommendation, an owner, and a record of what happened after the alert.
    Multilingual supportAnalyze a real country-and-language workflow without merging markets that require different decisions.Locale-specific query and page context, correct filters, preserved terminology, and reporting that can be reviewed by the market owner.
    Pricing clarityPrice the expected operating state rather than the demo environment.A written breakdown of seats, tracked entities, usage limits, exports, integrations, AI consumption, implementation, support, and overage conditions.

    If AI-search visibility is the stated gap, define the observation before accepting a visibility score. Ask which model or search surface was checked, in which locale, against which prompt or query set, at what time, with what captured answer, and under what entity-matching rule. Treat the tracked set as a measurement panel with documented boundaries. An opaque score can summarize evidence, but it should not replace the evidence.

    The replacement standard should be especially high for established crawling and technical-audit workflows. Core technical SEO tooling is comparatively stable. If your current system reliably finds relevant issues, preserves history, and routes work to the right owner, adding an AI label is not enough reason to replace it.

    Decide whether to buy an AI tool or build an agent

    The choice between a ready-made platform and a custom AI agent belongs after the workflow is defined.

    • Buy a platform when the task is standardized and the main value comes from vendor-maintained datasets, integrations, interfaces, support, and ongoing product upkeep.
    • Build an agent when the useful context lives in internal data, business rules, approval paths, or proprietary workflows that a general platform cannot represent. Include evaluation, monitoring, security review, maintenance, and internal ownership in the cost.
    • Keep the existing stack when the real bottleneck is an undefined decision, weak implementation discipline, missing conversion data, or unclear ownership. A new interface will not repair those conditions.

    For a small team, automation must remove work rather than produce more material to review. Outputs without market and business context tend to create noise. Require the system to suppress duplicates, show supporting evidence, explain uncertainty, and hand the next action to a named owner.

    Run a trial that can survive the sales demo

    Three evaluators observe two identical workstations completing the same controlled trial with blank result cards and evidence boxes.

    Do not evaluate a tool through a polished example that the vendor selected. Start with understandable pricing, secure a trial, and test the work your team actually performs in a normal week.

    1. Lock the use case and finish line. Describe the input, expected output, decision, owner, and acceptable evidence before anyone sees the product.
    2. Capture the current baseline. Record active work time, waiting time, systems touched, manual handoffs, recurring errors, and the decision produced by the current workflow.
    3. Use representative inputs. Include ordinary data and a known difficult case. A candidate that works only on a tidy sample has not passed the operational test.
    4. Separate setup from recurring operation. Record configuration, integration, tagging, permissions, and training effort independently from the work expected after adoption.
    5. Run the same task across candidates. Keep the data, operator instructions, and required output consistent so the comparison reflects the tools rather than different demonstrations.
    6. Trace every important output. Follow recommendations back to queries, pages, captured results, or other underlying evidence. Label generated explanations separately from observed data.
    7. Count decisions changed, not alerts created. Record whether the output changed a priority, prevented an error, removed a manual step, or supplied evidence the current stack could not provide.
    8. Test the handoff. Export the result, route it to the intended owner, apply permissions, and verify that history remains understandable outside the person who configured the trial.
    9. Price the operating state. Obtain the expected cost at normal usage, including implementation, integrations, support, consumption limits, internal administration, quality assurance, and any tools the purchase would actually retire.

    Apply pass-or-fail gates before scoring convenience features:

    • Data fitness: It covers the required sites, markets, languages, queries, pages, and business data at a usable level of detail.
    • Evidence quality: Important outputs are reproducible, traceable, and explicit about assumptions or uncertainty.
    • Workflow value: It removes a documented step, improves a defined decision, or enables a necessary analysis that is currently impractical.
    • Operational fit: The intended users can configure, review, export, and act on the output without relying indefinitely on a vendor specialist.
    • Governance: Access controls, retention, deletion, input reuse, and approval requirements fit your organization’s rules.
    • Commercial clarity: The written price covers the expected usage, dependencies, overages, implementation, renewal conditions, and exit path.

    Do not upload confidential query, customer, conversion, or client data until the appropriate security, privacy, and legal owners have approved the environment. Use a sanitized export or synthetic test set while that review is incomplete. The convenience of a trial is not worth creating an uncontrolled copy of sensitive data.

    Ask vendor questions that expose operating cost

    Send the use case before the call, then ask questions that require specific answers:

    • Which assumptions about seats, sites, markets, tracked queries, prompts, exports, API use, and AI consumption are included in this quote?
    • Which capabilities shown in the demonstration require another package, service, integration, or implementation fee?
    • What work is required from our team during setup and during normal operation?
    • Which claims describe production functionality, and which depend on a roadmap?
    • Can we export raw observations, definitions, configurations, and history in a usable format?
    • How are AI inputs retained, reused, isolated, and deleted, and where can those terms be verified?
    • What happens to access, stored data, reports, and integrations if usage changes or the contract ends?

    Build a budget case without pretending the trial proved revenue

    A short trial can establish data coverage, repeatability, workflow fit, evidence quality, and whether the output changes a decision. It usually cannot establish that the tool caused a durable ranking, conversion, or revenue increase. The business case should keep observed evidence, forecasts, assumptions, and unknowns in separate fields.

    Calculate full cost as the subscription, expected usage and overages, implementation, integrations, training, quality assurance, administration, and any internal build or maintenance effort, minus only the cost of tools that will genuinely be retired.

    Treat saved labor carefully. It becomes direct financial savings only when it avoids actual spending. Otherwise, describe it as capacity and name where that capacity will be redeployed. Treat incremental business impact as a forecast with an explicit mechanism: better evidence leads to a different decision, that decision changes the work, and the work may affect the defined outcome.

    Present a range of choices: keep the current stack, make a narrow change that closes the priority gap, or fund a broader platform or internal build. Include dependencies, risks, and exit criteria for each. That is more credible than forcing every benefit into an optimistic return figure, especially while direct connections between search activity and tangible business outcomes remain uncommon in tool offerings.

    Set checkpoints before signing. Confirm usability and evidence quality at the end of the trial, review operational value after a complete reporting period, and revisit adoption, overlap, business impact, and full cost before renewal. If the tool does not improve the decision named in the original brief, downgrade it, replace it, or stop paying for it.

    Your next move should be a blank measurement brief, not another demo booking. Choose a real decision from the next closed weekly or monthly period and ask each candidate to produce evidence your current stack cannot. A tool that cannot change that decision has not earned a place in the budget.

    References

  • AI Search Visibility: Measuring Citations and Referral Value

    AI Search Visibility: Measuring Citations and Referral Value

    Your analytics can show no traffic at the exact moment an AI answer starts putting your brand into a buyer’s consideration set. The inverse happens too: a citation looks impressive in a visibility tracker but sends no qualified visitor and supports no observable decision.

    The fix is not to choose between citations and traffic. You need a measurement chain that separates presence, citation, referral, and commercial value. Once those signals have distinct definitions, you can see where your visibility is working, where the journey stops, and what to improve next.

    A citation is not a click, and a mention is not a citation

    AI search visibility is often compressed into one score. That hides four different events:

    • A mention occurs when an answer names your brand, product, expert, or other identifiable entity.
    • A citation occurs when the answer attributes information to your domain or links to one of your URLs.
    • A referral occurs when a person follows an AI-generated link and reaches your site in a way you can observe.
    • An outcome occurs when that visitor completes a meaningful action, such as starting a trial, requesting a quote, buying a product, subscribing, or entering a qualified sales process.

    These events do not always happen in sequence. An answer can mention your brand without linking to it. It can cite a supporting page without naming the brand prominently. A person can encounter your brand in an answer, return later through branded search, and leave no direct AI referrer. A crawler or agent can also retrieve a page without producing a human visit.

    Choose the primary metric from the job you expect the content to do. For discovery content, measure whether the brand appears accurately in relevant answers. For evidence-led content, measure citation coverage and the contexts in which the page is used. For decision pages, measure qualified referrals and outcomes. Do not grade all three content types against the same click target.

    This distinction matters because generative systems can handle much of the early research journey before a person reaches a website. Traditional impressions, sessions, and click-through rates therefore describe only part of the path. Pricing, comparison, product, and validation pages may receive the eventual visit, while explanatory content did the earlier work of making the brand visible.

    Build a visibility scorecard with separate denominators

    Four unlabeled measurement stations use separate containers and markers to represent appearances, citations, referrals, and commercial value.

    A useful scorecard starts with a fixed set of prompts that represents the decisions your audience actually makes. Include non-branded prompts. A test set dominated by your company name will measure retrieval of a known entity, not discovery among alternatives.

    Group prompts by intent before running them:

    • Discovery prompts ask what a problem is, why it occurs, or how to approach it.
    • Evaluation prompts ask about criteria, methods, categories, risks, or suitable options.
    • Comparison prompts weigh named alternatives, features, costs, or trade-offs.
    • Validation prompts look for reviews, evidence, limitations, implementation details, or compatibility.
    • Transaction prompts ask where to buy, what something costs, or how to begin.

    Run the same prompt set separately in each engine. Preserve the wording and record the date, engine, answer, brand mentions, cited URLs, cited domains, source type, and intended landing page. If language, location, account state, or another test condition changes, record that as well instead of mixing the results into one trend line.

    One industry analysis covered 250 million AI-generated responses. That scale is a useful warning against treating a few favorable screenshots as a baseline. Generative answers can vary, so repeat the same test design and compare like with like.

    SignalHow to calculate itWhat it tells youCommon misreading
    Mention coverageEligible prompt runs containing the entity divided by all eligible prompt runsWhether the brand enters relevant answersTreating any mention as positive without checking context or accuracy
    Owned citation coverageEligible prompt runs citing an owned domain divided by all eligible prompt runsHow often your site supplies answer evidenceCalling a citation a visit
    Citation shareUnique citations to your domain divided by all unique citations in the tested answersYour presence within the observed source setPresenting test-set share as market-wide share
    Qualified referral rateAI-referred visits meeting your quality criteria divided by all tracked AI referralsWhether arriving visitors fit the page’s intended audienceJudging value from raw sessions alone
    Outcome rateDesired outcomes divided by tracked AI referralsHow observable AI traffic contributes to the businessCrediting every later direct or branded visit to AI

    Define a unique citation consistently. Counting the same URL several times inside one answer can inflate the result, so a practical default is one occurrence per unique URL per response. Keep domain-level and URL-level views. The domain view shows authority concentration; the URL view reveals which content actually earns the citation.

    Do not roll every prompt into a single average too early. A brand may be absent from discovery prompts but dominant in transaction prompts. That is a very different problem from broad underperformance. Report by engine, intent, topic cluster, market, and source role first. Use an overall score only as a navigation aid.

    Match your source strategy to the engine and the prompt

    AI engines do not necessarily choose the same kinds of evidence for the same request. In a 2025 holiday-season analysis of tens of thousands of identical ecommerce prompts, retailer sources appeared in about 4% of Google AI Overview results and 36% of ChatGPT results. Google leaned more heavily on YouTube, Reddit, Quora, and editorial sources, while ChatGPT more often surfaced retailers, brand pages, and manufacturer pages.

    That finding is specific to ecommerce prompts from that holiday period. It is not a universal rule for B2B software, healthcare, local services, finance, or every future version of either engine. The actionable lesson is narrower: segment your citation strategy by platform and query type instead of assuming one source profile applies everywhere.

    Build a source-role map before creating more content

    For each important prompt cluster, label every recurring citation as an owned brand source, retailer, editorial publication, community discussion, video source, or another relevant category. Then look for the missing role.

    • If owned pages are repeatedly cited, identify the exact passages and page formats supporting the answers. Maintain those facts instead of replacing a successful page simply because it is old.
    • If editorial and video sources dominate, give legitimate reviewers accurate specifications, evidence, and access to the material they need. Independent coverage cannot be replaced by publishing another self-authored claim.
    • If community discussions recur, improve the underlying product information and customer experience that people can discuss. Manufactured participation creates reputation risk and does not provide durable corroboration.
    • If retailer pages dominate, make product names, variants, attributes, and purchasing details consistent across the manufacturer site and authorized listings.
    • If competitors appear through a source type you lack, close that source-role gap rather than copying the competitor’s wording.

    For retail research prompts following the observed Google pattern, an owned product page alone may not cover the sources the answer prefers. You may also need accurate independent reviews, useful demonstrations, and authentic community evidence. For ChatGPT prompts following the observed retail pattern, complete brand, manufacturer, and retailer pages deserve closer attention because those sources appeared much more often.

    Validate both patterns against your own prompt set. Platform averages are a starting hypothesis, not a substitute for sector-specific observation.

    Keep discovery content even when its clicks decline

    Across an analysis of more than 7.2 million sessions to industry blog content, pricing and cost pages showed the strongest growth, comparison content also gained, and traditional guides declined. The scope matters: this was blog performance, not every content format, and the pattern does not by itself prove that AI caused the changes.

    Deleting top-of-funnel content would still be the wrong response. Discovery material can supply the definitions, criteria, and explanations that generative engines use before a person is ready to visit. If you remove it because direct sessions fell, you may also remove the material capable of earning early mentions and citations.

    Give each content layer a clear job:

    • Discovery pages should answer a narrow question directly, state their scope, distinguish easily confused concepts, and lead to the next decision.
    • Evaluation pages should provide criteria, trade-offs, limitations, and evidence a buyer can use to narrow the field.
    • Decision pages should expose pricing, comparisons, compatibility, availability, implementation requirements, or another concrete next step appropriate to the offer.
    • Product and service pages should keep names, claims, attributes, and calls to action consistent with the supporting content that introduces them.

    Connect these layers explicitly. A cited explainer should link to the relevant comparison or decision page, while the decision page should link back to the evidence behind its claims. This gives a human visitor a coherent path even when the AI engine exposes only one page.

    Use JSON-LD as a consistency layer, not as a citation counter. Mark up entities and attributes that are visible on the page, and keep names and relationships consistent with the readable content. Deployment is not the result. The result is whether the intended entity is understood accurately, cited in the right context, and connected to a useful next action.

    Turn sparse AI referrals into commercial evidence

    Three glowing droplets pass through transparent tracking rings and illuminate objects representing an inquiry, an opportunity, and realized value.

    AI referral volume can be small while the visitors who do arrive are close to a decision. Generative systems may complete much of the discovery and evaluation work before sending a person to a pricing, comparison, calculator, retailer, or product page. Measure the quality of that arrival before deciding the channel has little value.

    Build attribution in layers:

    1. Create an analytics channel for observable AI referrers. Keep the underlying source visible so you can compare engines instead of hiding them under one label.
    2. Record the landing page, content type, engagement events, and business outcome. A visit to a decision page should not be evaluated like a visit to an explainer.
    3. Separate human referrals from bot and agent retrievals in server-side reporting. A fetch can indicate access or use, but it is not a human session and should not be counted as one.
    4. Pass the original source into your CRM or lead system when your setup allows it. This lets you inspect lead quality, pipeline progression, and revenue instead of stopping at form completion.
    5. Add a short self-reported discovery field where the value of the decision justifies the extra question. Treat the answer as complementary evidence because memory and channel overlap make it imperfect.

    Not every AI-influenced journey will carry a usable referrer. A person may see a mention, open a separate tab, search the brand, or return later. Branded search growth, direct navigation, and self-reported discovery can help you notice that spillover, but they do not prove that a particular answer caused a particular visit.

    Keep direct attribution and assisted evidence in separate columns. The first contains observable referrals and outcomes. The second contains correlated signals such as stronger branded demand following improved answer visibility. Combining them produces an impressive number but a weak decision tool.

    Evaluate referral value with metrics that reflect your business:

    • Qualified visit rate: the share of tracked AI visits that meet your engagement or audience criteria.
    • Decision-action rate: the share that completes the action the landing page was designed to support.
    • Lead acceptance or sales progression: whether AI-sourced leads remain useful after the initial conversion.
    • Observable pipeline or revenue: the commercial result tied to tracked referrals under your normal attribution rules.
    • Landing-page concentration: which pages and intent stages receive the traffic, even when total volume is limited.

    Compare equivalent journeys. An AI referral landing on a pricing page should be compared with other channels entering that pricing page or the same intent stage, not with the sitewide average. Otherwise, differences in landing intent can be mistaken for differences in channel quality.

    Use the same discipline when evaluating citations. A citation on a broad educational prompt and a citation on a named comparison prompt have different commercial proximity. Report both, but do not assign them the same expected referral value.

    Key takeaways

    • Measure mentions, citations, human referrals, machine retrievals, and outcomes as separate events.
    • Use a stable, non-branded prompt set grouped by intent, then report results by engine before calculating an overall score.
    • Count citation coverage against eligible prompt runs and define duplicate handling before collecting data.
    • Audit the source roles each engine favors. Improve owned pages where owned sources win, and earn legitimate independent evidence where editorial, video, or community sources dominate.
    • Maintain discovery content for mentions and citations while strengthening pricing, comparison, and decision pages for the visits that arrive later.
    • Judge AI referrals by qualified actions, pipeline, and revenue, while keeping unproven assisted effects in a separate evidence column.

    Start with your highest-value prompt cluster and one engine. Freeze the prompt wording, capture the current answers and citations, map each cited source to its role, and connect every owned landing page to a measurable action. Change one content or source gap, repeat the same test, and let the movement in the correct signal determine the next change.

    References