Tag: AI Visibility

  • How to Choose an AI Search Optimization Agency in 2026

    How to Choose an AI Search Optimization Agency in 2026

    If you are comparing AI search optimization agencies, the hard part is not finding firms that promise more visibility. It is identifying which one can turn your content, technical foundation, brand knowledge, and authority into a coherent program without selling you a renamed SEO retainer.

    Your decision should leave you with a defined problem, an evidence standard, and a clear ownership model. Choosing well means testing an agency’s experience, previous work, AI expertise, and fit with your brand. Because discovery now extends into LLM and AI-driven search experiences, conventional ranking reports cannot carry the whole business case.

    Define the job before you ask agencies to solve it

    AI search optimization is not a single deliverable. It is a set of connected activities intended to make your brand and content easier for AI systems to retrieve, understand, represent accurately, cite, and recommend when the context warrants it.

    That distinction matters during procurement. If your brief says only that you want to improve AI visibility, every agency can interpret the assignment in a way that matches what it already sells. One may propose content production, another may lead with JSON-LD, and another may offer a monitoring dashboard. Those services can be useful, but none is a strategy by itself.

    Start by defining the change you want across four layers:

    • Representation: AI-generated answers describe your company, products, people, and claims accurately.
    • Discovery: your brand or content appears for relevant questions where you have a legitimate reason to be included.
    • Evidence: the answer can connect its claims to useful, authoritative pages rather than merely mentioning your name.
    • Action: the visibility supports a sensible next step, such as visiting a product page, reading supporting evidence, comparing options, or contacting your team.

    This framing prevents a common measurement mistake. A brand mention, a linked citation, an accurate recommendation, a referred visit, and a qualified conversion are not interchangeable outcomes. Record them separately. Otherwise, a dashboard can show improvement while the answers remain inaccurate or commercially irrelevant.

    Your agency brief should give every contender the same operating context:

    • Your priority products, services, audiences, markets, and buyer situations.
    • The questions people ask while identifying a problem, comparing approaches, checking trust, and making a decision.
    • The pages, databases, documentation, and internal experts that act as your sources of truth.
    • Claims that require legal, compliance, technical, or subject-matter approval.
    • Your current content, development, analytics, public relations, and editorial resources.
    • The systems the agency may advise on and the systems it will actually be allowed to change.
    • The business outcomes you ultimately care about, along with the earlier signals you can observe before those outcomes occur.

    Include a baseline rather than asking the agency to invent one after work begins. For each important question, save the exact wording, the AI service used, the date, the resulting answer, any linked citations, and whether the brand representation was accurate. Keep the relevant landing-page and conversion data alongside those observations when available.

    A useful objective might be: improve accurate inclusion and citation for priority decision questions, direct qualified visitors toward authoritative pages, and establish a repeatable process for finding and fixing representation gaps. It is specific enough to guide a proposal without pretending that you control an external answer engine.

    Inspect whether the strategy works as a connected system
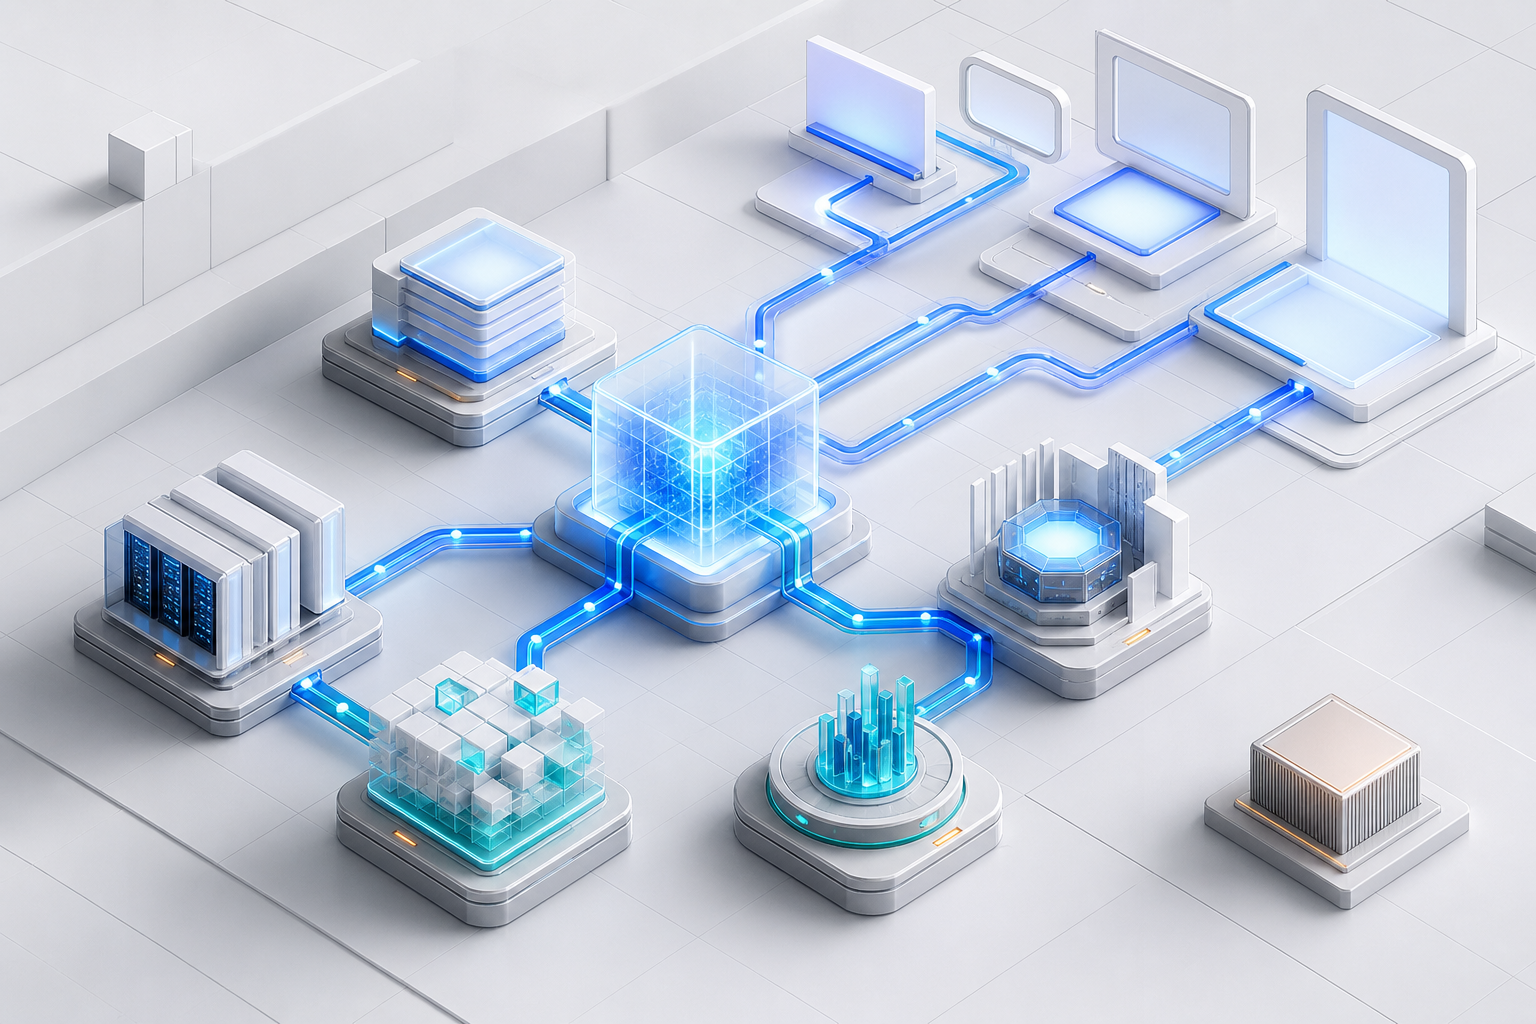
    Five connected modules feed a central translucent AI core, while one isolated module remains outside the working system.

    A credible agency should be able to explain how audience demand, content, entity signals, technical access, outside authority, and measurement reinforce one another. It does not need to perform every activity itself. It does need to identify the dependencies and tell you who owns each one.

    Question and intent discovery

    Keyword research is useful input, but it does not fully describe the questions people put to an assistant. Ask how the agency will build a working set of questions from customer language, sales objections, support issues, product comparisons, documentation gaps, and conventional search demand.

    The result should be organized by user task, not presented as a shapeless list of prompts. Someone defining a problem needs a different answer from someone comparing vendors or checking whether a solution fits a regulated workflow. That difference affects the required evidence, page format, and appropriate call to action.

    Watch for invented precision. A prompt list becomes useful when the agency can explain why each question matters, which audience it belongs to, what a good answer must contain, and which page should support it. A large list with no decision context is inventory, not strategy.

    Content and entity clarity

    The agency should examine whether your pages answer the target questions clearly and whether the supporting claims are specific, consistent, and attributable. It should also distinguish between a missing page and a weak page. Publishing something new when an existing authoritative page needs a clearer answer can create duplication and split maintenance effort.

    For each priority page, the plan should identify its subject, intended audience, direct answer, supporting evidence, related entities, internal links, maintenance owner, and next action. This turns vague advice such as improve content quality into an editable specification.

    Entity consistency matters as well. Product names, company relationships, leadership details, service areas, and other defining facts should not conflict across core pages and structured data. Ask how the agency will find discrepancies and decide which internal record is authoritative before it recommends markup or rewrites.

    Technical access and structured data

    The technical review should cover whether important information is available on stable, indexable URLs; whether internal links make relationships understandable; whether canonicalization or access rules create conflicts; and whether templates hide, fragment, or duplicate key answers.

    JSON-LD belongs in this workstream, but it should describe facts that users can verify on the page. Structured data can clarify the type of entity or content being presented and expose defined relationships in a machine-readable form. It cannot manufacture expertise, prove an unsupported claim, or rescue content that never answers the question.

    Ask for a structured data inventory rather than a promise to add schema. The inventory should connect each proposed type and property to a visible fact, a source-of-truth field, an eligible page template, a validation method, and an owner responsible for keeping the information current.

    Authority, distribution, and measurement

    An on-site plan is incomplete if it ignores how the brand is represented elsewhere. Relevant mentions, expert contributions, documentation, original evidence, partnerships, public relations, and other legitimate forms of distribution can help establish context beyond your own domain. The agency should explain which activities are justified by the audience and where another team must participate.

    Measurement completes the system. The agency should connect each recommendation to an observable change: a clearer answer on the page, corrected entity information, valid structured data, stronger citation coverage, more accurate AI representation, useful referred traffic, or a downstream business action. If the plan jumps from publishing content directly to revenue without showing the intermediate signals, you will struggle to diagnose either success or failure.

    Test agency claims with evidence, not vocabulary

    Most contenders can discuss AEO, GEO, AI SEO, entities, retrieval, citations, and structured data. Terminology tells you that the team follows the market. It does not tell you whether the team can diagnose your situation, prioritize work, implement recommendations, or separate its contribution from unrelated changes.

    Use the same evidence request for every finalist:

    Evaluation areaAsk to seeEvidence that matters
    Relevant experienceA comparable, sanitized case narrativeThe starting condition, diagnosis, intervention, implementation owner, observed change, and limits of the result
    AI search expertiseA live explanation of one priority question and pageClear reasoning across intent, answer quality, entities, technical access, authority, and measurement
    MeasurementA sample baseline and recurring reportRaw prompts, captured answers, citations, accuracy judgments, dates, page metrics, and change history behind any summary score
    ImplementationA sample content brief, technical ticket, or schema specificationNamed owners, dependencies, acceptance criteria, quality checks, and a route from recommendation to release
    Brand fitAn explanation of how the plan changes for your audience and constraintsChoices tied to your products, source material, risk, market, workflow, and business goals
    Commercial clarityA scope showing included and excluded workSeparate visibility into strategy, tools, production, development, outreach, reporting, and optional work

    Do not accept a case study that starts with a result. Ask what was happening before the work, what changed, what else changed at the same time, and what evidence would weaken the agency’s interpretation. A team that can discuss confounding factors and uncertainty is giving you more useful information than one presenting a smooth success story with no audit trail.

    A working session is especially revealing. Give each finalist the same page, target audience, and small group of priority questions. Ask the team to talk through what it would inspect first, which assumptions it would verify, what it would avoid changing prematurely, and how it would turn the diagnosis into tasks. You are assessing the reasoning process, not asking for unpaid strategic work.

    Ask who will actually do the work after the sales process. You need to know which roles will handle strategy, content, technical analysis, JSON-LD, analytics, and project management; whether those people are assigned to your account; and where subcontractors or software-generated work enter the process. Senior expertise in a pitch has little value if delivery depends on an unnamed team using an undefined workflow.

    Several claims deserve immediate scrutiny:

    • Guaranteed placement in generated answers. An agency cannot control the output of an external AI service, so it should promise defined work and transparent measurement rather than a specific placement.
    • A proprietary visibility score with no underlying observations. A score can summarize data, but you still need access to the prompts, outputs, citations, classification rules, and sampling conditions behind it.
    • Schema as the complete solution. Markup is one technical layer and should be connected to accurate visible content, source-of-truth data, and ongoing maintenance.
    • Content volume as the primary strategy. More pages can add duplication, inconsistent claims, and editorial debt when question coverage and page purpose have not been mapped first.
    • A monitoring dashboard presented as optimization. Monitoring can expose a problem; it does not research, edit, implement, validate, distribute, or govern the fix.
    • AI search results credited entirely to ordinary organic growth. Ask the agency to separate conventional search improvement, branded demand, public relations activity, product changes, and AI-specific observations wherever the available evidence allows.
    • Recommendations with no implementation owner. A technically correct audit still fails if nobody can convert it into approved changes in your CMS, codebase, data layer, or editorial process.

    Build your scorecard before proposals arrive. Evaluate strategic fit, evidence quality, technical breadth, content judgment, measurement rigor, implementation clarity, governance, team continuity, and commercial transparency. Decide which criteria matter most for your current constraint. A company with strong in-house developers may need strategic and editorial depth, while a lean team may need a partner that can carry more implementation.

    Put measurement, ownership, and change control in the scope
    A conference table displays an evidence portfolio, a balance, verified tokens, and a locked asset box with a key.

    AI-generated answers can vary with prompt wording, service, context, and time. That makes a single screenshot weak evidence. It does not make measurement pointless. It means the method must preserve enough context for you to distinguish an observation from a trend and a trend from a business outcome.

    For each monitored question, the measurement record should retain:

    • A stable identifier, exact wording, audience, intent, and market or language context when relevant.
    • The AI service, capture date, and other available execution context.
    • The complete answer or a faithful stored capture, not only a yes-or-no brand mention.
    • Whether the brand appears, what role it is assigned, and whether the description is accurate.
    • Every visible citation and whether it points to your site, another source, or no accessible supporting page.
    • The owned page intended to answer the question and its publication or revision history.
    • Referred visits, meaningful on-site actions, and business outcomes when those can be observed responsibly.

    Keep three layers separate in reporting. Visibility observations describe what appeared. Quality judgments describe whether the answer and citation were useful and accurate. Business outcomes describe what people did. Combining all three into one number hides the very information you need for prioritization.

    Require a change log beside the baseline. It should connect recommendations to approved work, affected URLs or templates, release dates, validation results, and subsequent observations. Without that record, the agency can report movement but cannot show which intervention may have contributed to it.

    The scope should also resolve ownership before work starts:

    • Who approves the question set and can add or retire monitored questions.
    • Who controls analytics, monitoring, CMS, schema, repository, and reporting access.
    • Who supplies subject-matter evidence and approves sensitive claims.
    • Who writes, edits, develops, validates, publishes, and maintains each type of change.
    • Who owns the resulting briefs, dashboards, configurations, structured data specifications, and historical captures.
    • How open recommendations and data are handed over if the engagement ends.

    Retain administrative control of your own site, analytics, and core business data. Give the agency the access required for its role, but avoid making your ability to operate dependent on an account only the vendor controls. The same principle applies to prompt histories and reporting data: you should be able to inspect and export the evidence used to evaluate performance.

    If uncertainty remains, use a bounded pilot to test the working relationship. Give it a defined audience, question set, group of pages, deliverables, implementation route, evidence method, and decision point. The purpose is to learn whether the agency can diagnose, communicate, ship, and measure within your environment. A short pilot should not be treated as proof that every market-level outcome will move.

    Compare the cost of the full operating model, not only the agency fee. A proposal may exclude monitoring software, content production, development, design, public relations, or subject-matter review. Make those dependencies visible so a cheaper retainer does not become the more expensive program after implementation begins.

    Key takeaways before you sign

    • Define AI visibility as a set of observable outcomes: accurate representation, relevant inclusion, useful citations, qualified action, and business impact.
    • Give every agency the same priority audiences, questions, pages, constraints, baseline, and implementation boundaries.
    • Look for a connected strategy spanning intent, content, entities, technical access, structured data, authority, distribution, and measurement.
    • Ask for raw evidence behind case narratives and visibility scores, including prompts, answers, citations, dates, changes, and limitations.
    • Reject guaranteed placements, schema-only plans, volume-first content programs, and dashboards presented as complete optimization.
    • Put owners, access, deliverables, acceptance criteria, change history, data control, handover, and excluded costs into the scope.

    Your next move is straightforward: choose one important audience, one decision journey, a manageable set of questions, and the pages that should support the answers. Capture the baseline, send the same brief to each finalist, and require each team to show how it would move from diagnosis to an implemented, measurable change.

    Select the agency whose reasoning remains clear when the evidence is incomplete. The right partner will make assumptions visible, define what it can and cannot control, and leave your organization with a stronger operating system for AI discovery rather than a collection of unexplained tactics.
    References

  • US B2B SEO Agencies for 2026: A Practical Hiring Guide

    US B2B SEO Agencies for 2026: A Practical Hiring Guide

    You can find US B2B SEO agency candidates for 2026 quickly. The expensive part is deciding which one can understand your market, earn trust from technical buyers, and connect search visibility to qualified pipeline.

    The right agency is not necessarily the largest, the most visible, or the one offering the longest list of services. It is the team whose operating model fits your buyers, internal resources, website, sales process, and evidence requirements. Use the framework below to make that fit visible before you sign.

    Define the commercial job before you contact an agency

    A weak agency search usually begins with a weak brief. If you ask candidates to increase traffic, each agency can tell a plausible story while solving a different problem. One may pursue high-volume informational queries, another may rebuild technical foundations, and another may publish comparison pages. All of those activities can be legitimate, but they do not produce the same commercial result.

    Start with the buying motion. Your brief should give every candidate the same operating context:

    • Your priority products or services, including which offers matter most commercially.
    • The industries, company types, account sizes, and buyer roles you want to reach.
    • The problems buyers recognize before they know your category or brand.
    • The questions, objections, security concerns, integration requirements, and proof requests that appear during sales.
    • The actions you treat as meaningful conversions, such as a qualified demo request, assessment, trial, application, or sales conversation.
    • Your website platform, analytics setup, CRM workflow, approval process, and technical constraints.
    • The subject-matter experts, developers, designers, legal reviewers, and sales staff the agency can realistically access.
    • The work that must remain internal and the work you expect the agency to own.

    Be precise about what US-based means to you. A US headquarters, experience selling into the US market, working-hour overlap, a US legal entity, and an entirely onshore delivery team are different requirements. If procurement, security, or customer commitments restrict where work can be performed, state that before agencies prepare proposals.

    Then write the commercial assignment in plain language: improve discoverability for a defined set of buyers, move those buyers toward a defined action, and show how organic work contributes to qualified opportunities. This gives agencies a problem to solve rather than a traffic target to decorate.

    Look for an operating system, not a service menu

    Two specialists inspect a modular system connecting research, website, content, authority, measurement, and sales opportunity symbols.

    Most credible proposals contain familiar components: technical SEO, content, digital PR, reporting, and some form of AI search optimization. The labels tell you little. What matters is how the agency connects those disciplines and makes decisions when data, buyer needs, and internal constraints conflict.

    Buyer-led search architecture

    A B2B content plan should reflect the decisions buyers make, not just the keywords an SEO tool can export. Ask the agency to map search demand to recognizable buyer jobs:

    • Understanding a problem and its business consequences.
    • Learning the available approaches to solving it.
    • Defining requirements and evaluating fit.
    • Comparing categories, methods, or vendors.
    • Checking implementation, integration, security, and operational implications.
    • Finding evidence that reduces perceived risk.
    • Preparing a recommendation for colleagues, procurement, or leadership.

    Each proposed page should have a clear buyer, decision, next action, and relationship to the rest of the site. If an agency cannot explain why a page belongs in the journey, publishing it will probably add inventory rather than influence.

    Technical and entity foundations

    A useful technical audit does more than list warnings. It establishes which pages search systems can discover, render, index, interpret, and connect. It should distinguish defects that suppress important pages from housekeeping that has little commercial effect.

    Expect the agency to examine crawling and index controls, canonical signals, redirects, internal links, page templates, duplicate or competing pages, structured data, navigation, and the relationship between your organization, people, offerings, evidence, and editorial content. Ask how each recommended change affects an important page group. A severity label without an affected business area is not prioritization.

    Structured data should describe what is genuinely present on the page and remain consistent with visible content. It can improve machine interpretation, but it does not guarantee rankings, inclusion in an AI answer, or a citation. Be wary of any proposal that treats JSON-LD as a substitute for clear information, credible evidence, or sound site architecture.

    Subject-matter expertise turned into usable evidence

    Your strongest B2B knowledge often lives in sales calls, implementation teams, product specialists, technical documentation, and customer questions. The agency needs a repeatable way to extract that knowledge without turning every draft into a burden for your experts.

    Ask to see the workflow from interview or internal input through briefing, drafting, fact review, optimization, approval, publication, and refresh. The agency should define what it needs from an expert, what its writers can resolve independently, and how unsupported claims are flagged. A writing sample alone does not prove that this system exists.

    Useful content makes definitions explicit, separates similar concepts, states assumptions, answers the next likely question, and supports claims with evidence a reader can inspect. Those qualities help a human evaluator and also make passages easier for search and answer systems to retrieve accurately.

    Authority beyond your own website

    An agency should be able to explain how it will build recognition outside your domain. Depending on your market, that may involve expert contributions, original data, useful tools, partner content, relevant industry publications, public documentation, or digital PR. The method should fit how your buyers establish credibility.

    Ask where links, mentions, and citations are expected to come from, why those environments matter, and what editorial value earns placement. A large outreach count is not the same as relevant authority. You need a defensible acquisition method, quality controls, and a clear boundary around tactics the agency will not use.

    Measurement across search, AI visibility, and pipeline

    Traditional search performance and visibility in AI-generated answers overlap, but they are not identical. Your measurement plan should keep them distinct while connecting both to commercial outcomes.

    For search, define how the agency will monitor priority query groups, important landing pages, branded and non-branded demand, conversions, assisted journeys, and changes in lead quality. For AI visibility, define the questions or buying scenarios that matter, which brands and pages appear, whether your company is represented accurately, and where observable citations or referrals point. Where a platform does not expose reliable data, the report should label the limitation instead of converting an estimate into a fact.

    The agency should also show how website and search data will connect to CRM stages. Perfect attribution is rarely a reasonable promise, especially across long and multi-person journeys. A practical model records what can be observed, separates leading indicators from business outcomes, and makes uncertainty visible.

    Make every agency prove its claims the same way

    Polished pitches are difficult to compare because each agency controls the frame. Give shortlisted teams the same evidence request and evaluate the people who would actually work on your account.

    1. Ask for a live walkthrough of your website. The team should identify a meaningful opportunity, show the evidence behind it, explain what remains uncertain, and name the information needed before acting.
    2. Request redacted working artifacts, not just finished success stories. Useful examples include a technical backlog, buyer-journey map, content brief, editorial review, reporting view, or prioritization document.
    3. Choose one proposed page or campaign and ask the agency to trace it from buyer problem to search demand, production workflow, distribution, conversion path, and measurement.
    4. Ask the agency to map a sample report from query and landing-page behavior through your accepted conversion and CRM stages. Confirm which connections already exist and which require implementation.
    5. Meet the strategist, technical lead, content lead, and account owner who will do the work. Clarify responsibilities, availability, approval authority, and any planned subcontracting.
    6. Ask about a program that underperformed. A credible answer should distinguish the initial assumption, the evidence that challenged it, the decision that changed, and what the team would now do earlier.

    Use direct questions that expose the agency’s decision process:

    • Which assumption about our market would you test first?
    • What would make you recommend against publishing a page that has measurable search demand?
    • Which deliverables depend on our subject-matter experts, developers, or sales team?
    • How will you separate awareness traffic from buying intent and branded demand?
    • How will you report AI visibility when a platform does not provide complete referral or citation data?
    • Which activities are explicitly outside your scope?
    • Who can change priorities, and what evidence justifies that change?

    Several warning signs should lower your confidence immediately:

    • Guaranteed rankings, traffic, leads, or AI citations without control over the systems that produce them.
    • Success stories that omit the starting condition, work performed, commercial context, or agency responsibility.
    • A content commitment defined mainly by publishing volume.
    • A large audit with no method for converting findings into an owned, sequenced backlog.
    • Reporting that stops at rankings and sessions even though the stated goal is pipeline.
    • Plans to publish at scale before the team understands your evidence, approval rules, brand constraints, and buyer journey.
    • Proprietary language used to avoid showing deliverables, methods, or measurement definitions.

    Compare proposals with a decision scorecard

    A cross-functional team uses matching tokens and blank criteria tiles to compare three anonymous agency proposal folders.

    A scorecard prevents presentation quality, brand familiarity, or executive chemistry from quietly becoming the selection method. Use the same decision areas for every agency, record the evidence you saw, and distinguish a demonstrated capability from a promise.

    Decision areaWhat strong evidence looks likeWhat should lower confidence
    Commercial alignmentThe agency connects priorities to buyers, offers, conversion events, sales stages, and qualified pipeline.The plan treats traffic or keyword movement as the final outcome.
    Buyer understandingThe team maps problems, evaluation questions, objections, stakeholders, and proof needs to page roles.The strategy is primarily a list of high-volume keywords.
    Technical executionFindings include affected page groups, business impact, dependencies, owners, and validation steps.The audit produces warnings without a defensible order of work.
    Content operationsThe workflow shows how expert knowledge becomes reviewed, evidence-backed, maintained content.The proposal emphasizes output volume without explaining fact review or refreshes.
    Authority developmentThe agency names relevant environments, editorial value, quality controls, and acquisition methods.The pitch relies on link quantities or vague relationship claims.
    AI search readinessThe plan covers extractable answers, entity clarity, supporting evidence, independent mentions, and observable visibility.The agency promises citations or treats schema markup as a shortcut to authority.
    MeasurementThe model separates leading indicators from outcomes and documents attribution limits.The dashboard cannot connect important pages and conversions to CRM stages.
    Delivery governanceNamed practitioners, dependencies, approvals, priority rules, escalation paths, and scope boundaries are clear.The sales team disappears after signing or delivery depends on unspecified resources.

    Do not let the scorecard become false precision. Its purpose is to expose missing evidence and tradeoffs. Record a short reason beside each judgment, then discuss material disagreements among the people who will fund, support, and evaluate the engagement.

    Once you select a preferred agency, translate the pitch into a statement of work. For every important workstream, specify the intended outcome, required artifact, acceptance condition, owner, client dependency, approval path, reporting method, and change-control process. Define who owns accounts, data, briefs, written work, code, creative assets, and reporting configurations.

    Protect access as carefully as scope. Grant only the permissions required for the current work, use named accounts where possible, document publishing and rollback authority, and remove access when responsibilities change. Do not hand over unrestricted production or administrative access simply because implementation will be faster.

    Contract language about confidentiality, data use, intellectual property, termination, liability, and subcontracting can create material exposure. Have the person responsible for your vendor contracts review those clauses before signing; an SEO evaluation is not a substitute for legal or procurement review.

    Key takeaways

    • Define the buyer, commercial outcome, internal constraints, and meaning of US-based before requesting proposals.
    • Evaluate how an agency connects technical SEO, expert content, authority, AI visibility, and pipeline measurement.
    • Ask every shortlisted team for the same working artifacts, live diagnosis, delivery-team access, and attribution explanation.
    • Treat guaranteed rankings or AI citations, volume-led content plans, and traffic-only reporting as warning signs.
    • Put deliverables, dependencies, ownership, access controls, measurement definitions, and change rules into the agreement.

    Your next step is to write the internal brief before opening another agency website. Give each candidate the same commercial problem, run the same evidence review, and score what the delivery team can demonstrate. The best choice is the agency whose methods still make sense after the pitch deck is closed.

    References


  • How to Build an SEO Strategy for Visibility in AI Search

    How to Build an SEO Strategy for Visibility in AI Search

    Your pages rank, your crawl reports look clean, and your brand still disappears when an AI assistant answers the same question. That gap does not mean SEO has stopped working. It means ranking is now one checkpoint in a longer path through discovery, interpretation, citation, recommendation, and action.

    You need a strategy that can diagnose where that path breaks. The framework below will help you make important pages easier for search engines and language models to understand, support, select, and represent accurately without abandoning the technical and editorial fundamentals that already earn search visibility.

    Key takeaways

    • Keep technical SEO in place, but stop treating indexing as proof that an AI system understands the page correctly.
    • Make the primary entity, page purpose, relationships, authorship, scope, and date unmistakable in both visible copy and structured data.
    • Treat factual accuracy and citation grounding as separate requirements. An answer can be correct while its linked evidence fails to support it.
    • Give AI systems a defensible reason to recommend your brand, including a defined audience, meaningful distinctions, limitations, and corroborating evidence.
    • Measure mentions, factual representation, citations, recommendations, visits, and business outcomes separately. They are different stages, not interchangeable measures of success.

    Treat AI visibility as four separate outcomes

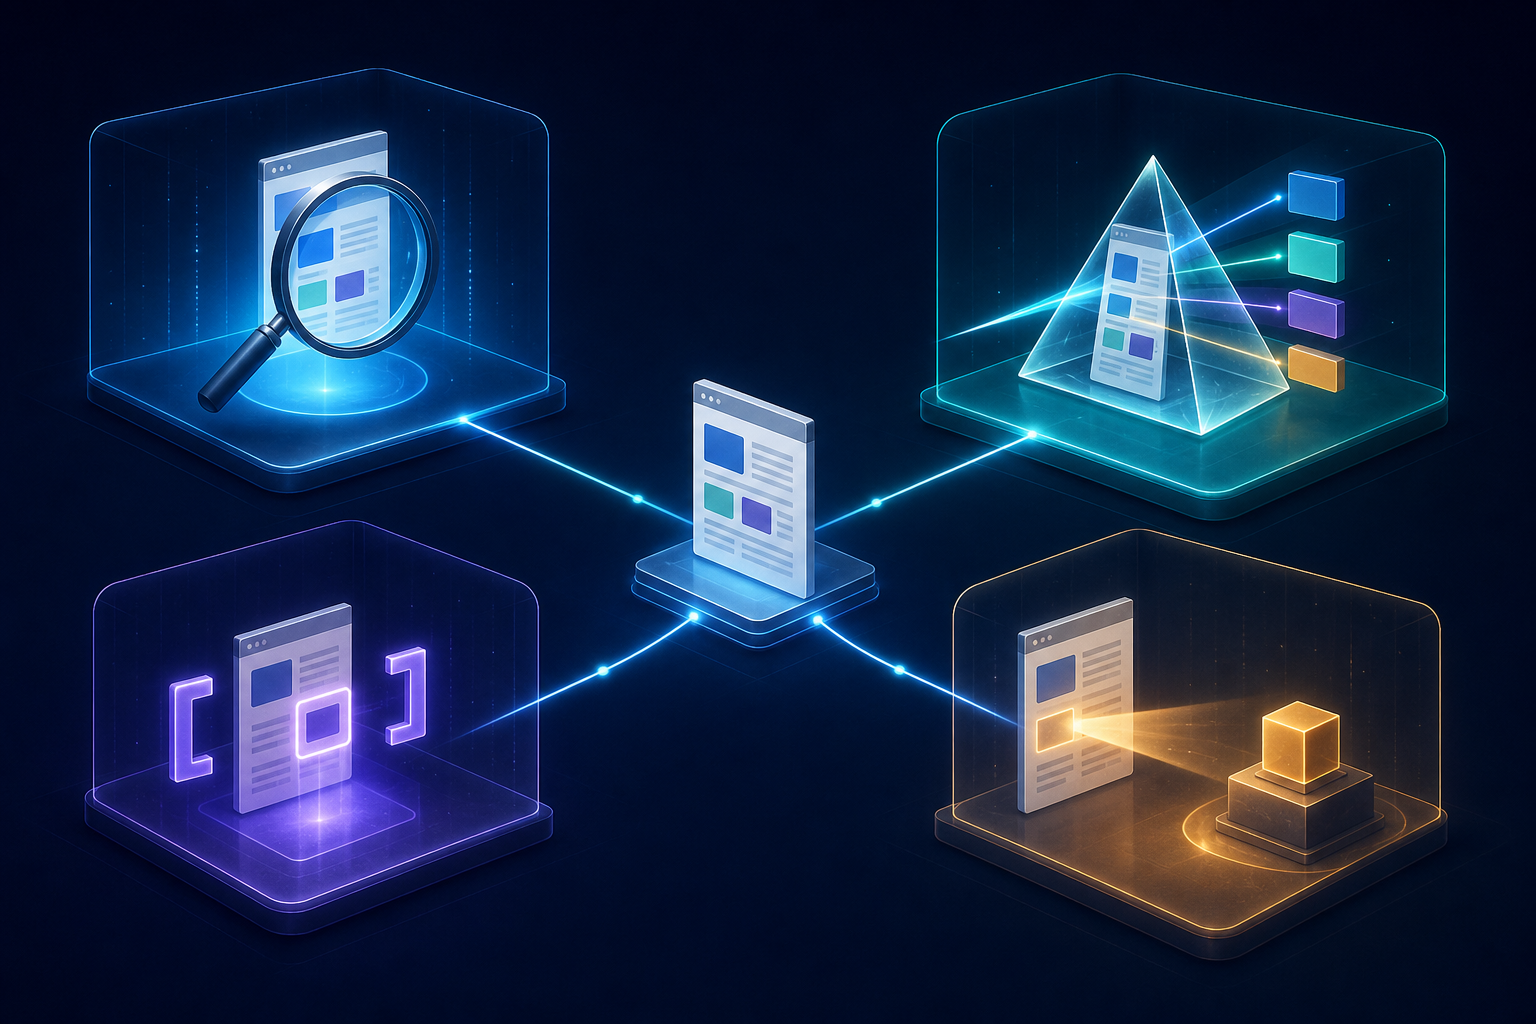
    A web page tile branches into four separate chambers containing discovery, organization, quotation, and recommendation symbols.

    AI visibility is too broad to be a useful diagnosis. A brand can be retrievable but misunderstood, correctly described but not cited, cited but not recommended, or recommended without receiving a visit. Calling all of these states visible hides the work you actually need to do.

    OutcomeWhat must happenWhat you should inspect
    EligibilityThe page can be discovered, crawled, indexed, and retrieved for a relevant need.Robots directives, index status, canonicals, internal links, renderability, page status, and information architecture.
    InterpretationThe system identifies the correct entity, attributes, relationships, intent, scope, and authorship.Opening copy, headings, bylines, dates, terminology, page context, structured data, and contradictory signals.
    SelectionThe page or brand is chosen as evidence, a citation, or a recommendation.Claim clarity, extractability, qualifications, supporting evidence, external corroboration, and differentiation.
    Business impactThe answer produces recognition, preference, a visit, or a valuable action.Referral traffic, branded demand, assisted conversions, landing-page fit, lead quality, and revenue-related outcomes.

    Not every engine exposes these stages, and different products implement retrieval differently. Use the model as a diagnostic framework, not as a claim that every system has an identical architecture.

    The important distinction is between storage and understanding. A page can be indexed while its entities, roles, intent, or useful passages are annotated with low confidence or classified incorrectly. That page is technically present but competitively weak for the questions it was meant to answer.

    A practical annotation model starts with gatekeepers such as language, geography, time, and entity identity. It then moves through attributes and relationships, query intent and expertise, confidence and corroboration, and finally extraction quality. A failure near the beginning contaminates everything that follows. If the system mistakes a reviewer for the author, an old price for the current price, or a regional service page for a global offer, more keyword coverage will not repair the underlying interpretation.

    This is why conventional SEO still matters. Technical optimization and site architecture remain part of the foundation. They create eligibility. They do not, by themselves, establish what the page means or why the brand deserves to be selected.

    Make every important page easy to classify and quote

    Start with pages tied to a meaningful audience decision: core service pages, product pages, category pages, comparison resources, original analysis, and authoritative explanations. Audit each page in the order below. The sequence matters because later improvements cannot reliably compensate for an ambiguous identity.

    1. State the page’s category and job early. The opening should identify the subject before it introduces a slogan, story, or broad market claim. A useful pattern is: [entity] is a [category] for [audience]. It helps with [task] in [context].
    2. Choose one primary entity. Decide whether the page is principally about a company, person, product, service, location, event, or concept. Use its exact name consistently, and make the relationship between that entity and any secondary entities explicit.
    3. Align names and roles. The visible byline, author biography, reviewer credit, publisher identity, organization page, and structured data should describe the same relationships. Do not place a prominent expert biography where a system could reasonably interpret that expert as the author.
    4. Qualify important claims locally. Put the relevant date, region, version, audience, unit, or limitation next to the claim it changes. A distant disclaimer is weak context for an extracted sentence.
    5. Make useful passages self-contained. A heading and its following paragraph should identify the subject without depending on several earlier sections. Pronouns such as it, they, and this approach become ambiguous when a passage is retrieved on its own.
    6. Remove competing answers. Reconcile old and new descriptions across product pages, help content, author profiles, location pages, PDFs, and structured data. If an old page must remain available, label its historical scope clearly.
    7. Inspect the rendered page, not only the editor. Navigation, related-content modules, biographies, popups, templates, and injected markup can introduce entity signals that are more prominent than the copy you intended an engine to interpret.

    The risk is concrete. Two Barry Schwartz articles were temporarily connected to another contributor’s Knowledge Panel after that contributor’s name and biography became a prominent person signal on the pages. Crawlability was not the problem. The system resolved the wrong person into the author role.

    Use JSON-LD to reinforce the visible page, not to create a second version of it. Entity names, authorship, publishing relationships, dates, page type, and material attributes should agree with what a reader can see. Passing a syntax validator only proves that the markup can be parsed. It does not prove that the graph identifies the correct entity or that its claims are supported.

    Run a simple extraction test after editing. Copy each important section without its site header or preceding paragraphs. Check whether a reader can still identify who or what the section concerns, what is being claimed, where the claim applies, when it applies, and what supports it. If you have to reconstruct those details from elsewhere on the page, the passage is not yet robust enough for independent retrieval.

    Give engines evidence to ground and reasons to recommend

    Correctness is not the same as grounding. In Oumi’s 4,326-query SimpleQA benchmark, Google AI Overviews answered 91% correctly in the February test, up from 85% in the October test. Yet 56% of the correct February answers were classified as ungrounded because their linked references did not fully support them, compared with 37% in October.

    Those figures should not be treated as a settled measure of everyday search quality. Google disputes the benchmark’s resemblance to normal search behavior and argues that its methodology has serious gaps. The useful lesson does not depend on choosing a side: you should audit whether an answer is accurate and whether its cited page actually substantiates that answer as two separate questions.

    Build a claim that survives verification

    For every commercially important or frequently repeated claim, create an evidence unit that contains the following information close together:

    • Claim: the precise assertion you want a person or system to understand.
    • Scope: the audience, location, product, plan, version, or situation to which it applies.
    • Basis: the method, documentation, data, policy, test, or first-party record that supports it.
    • Time: the publication, verification, or effective date when recency changes the meaning.
    • Limitation: the material exception, uncertainty, tradeoff, or condition that prevents overstatement.

    Keep the evidence on the page that makes the claim whenever practical. A generic references page may help a diligent reader, but it forces an extraction system to join distant context correctly. A short local explanation, followed by a relevant link to deeper evidence, creates a cleaner relationship.

    Do not manufacture certainty with structured data, repeated wording, or unsupported superlatives. No schema property can turn best, safest, fastest, or most trusted into evidence. Replace the superlative with a bounded fact the reader can evaluate, or remove it.

    Make the recommendation case explicit

    A page can explain a category perfectly and still give an answer engine no reason to favor its brand. Recommendation visibility requires a proposition, not merely topic coverage. The system needs evidence about who the offer suits, what makes it meaningfully different, and why that distinction matters in the user’s situation.

    • Define the audience and use case narrowly enough that suitability can be evaluated.
    • Describe meaningful differences in capabilities, process, scope, support, availability, or constraints.
    • Explain the consequence of each difference instead of presenting an unprioritized feature list.
    • State who or what the offer is not suitable for when that boundary affects the decision.
    • Support self-published claims with appropriate corroboration, such as substantive reviews, independent recognition, documented results, or consistent coverage beyond your own domain.

    AI-mediated recommendations can draw on reviews, brand prominence, positioning, and other signals of authority and preference. That makes brand building, public relations, reputation management, product clarity, and SEO connected parts of the same job. Publishing more informational pages will not compensate for a proposition nobody can distinguish or evidence nobody else confirms.

    Design for the question behind the query

    Traditional keyword lists are an incomplete map of AI demand. In ChatGPT clickstream data, roughly 65% to 85% of prompts took the form of complex, conversational inputs rather than conventional search queries. A user may supply a role, budget constraint, prior attempt, location, required integration, and desired outcome in the same prompt.

    Build topic coverage around decisions rather than endless keyword variations. Alongside a definitive category page, cover the problems that create demand, the situations in which different approaches work, evaluation criteria, important constraints, implementation questions, comparisons, and current facts that genuinely change the answer. Link these pages through shared entities and consistent terminology so the site forms a coherent explanation instead of a pile of loosely related posts.

    Write headings that reflect real subquestions, then answer each one directly before adding nuance. This does not require robotic question-and-answer copy. It requires a reader to know, within the first sentence of a section, whether that section resolves the condition they included in their prompt.

    Measure the path from answer to business result

    A glowing path leads from an abstract answer panel through a source tile and visitor doorway to a completed product interaction.

    Referral sessions are useful, but they are not a complete AI visibility metric. Many answers do not trigger a live web search, and many users receive enough information without clicking. A brand can therefore gain or lose influence inside an answer before analytics records a visit.

    Semrush’s analysis of more than a billion lines of U.S. clickstream data from October 2024 through February 2026 found that ChatGPT referrals grew 206%, but the outbound traffic remained concentrated. Google received 21.6% of outbound clicks, while the ten largest destinations collectively received more than 30%. The number of sites receiving any referral traffic peaked around 260,000 in 2025 and later settled near 170,000.

    Live search was also triggered for 34.5% of observed queries, down from 46% in late 2024. These findings concern one platform and one clickstream dataset, so they are directional rather than a universal forecast. They still expose the reporting error to avoid: more AI referrals across the market do not guarantee meaningful referral traffic for your site, and a missing referral does not prove your brand was absent from the answer.

    1. Define stable query families. Include prompts about the brand, category discovery, problem solving, comparison, suitability, objections, and facts where freshness matters. Use prompts that contain the context a real buyer would provide.
    2. Record the test conditions. Save the exact prompt, date, platform, visible model or mode, whether live search occurred, and whether the session had context that could affect the response.
    3. Score each stage separately. Record whether the brand was mentioned, represented accurately, supported with a citation, linked to the correct page, included in a recommendation, visited, and associated with a valuable action.
    4. Inspect the words around the brand. A mention framed as unsuitable, outdated, expensive, unverified, or intended for the wrong audience is not a visibility win. Capture the attributed category, strengths, weaknesses, and comparison set.
    5. Preserve a baseline before editing. Document the affected pages and the specific change, then rerun the same prompts under comparable visible conditions. Individual answers can vary, so do not declare a trend from one response.
    Observed patternLikely gap to investigateNext action
    No mention and no citationEligibility, relevance, or entity recognitionCheck crawl and index status, internal linking, category clarity, and whether the page directly addresses the prompt’s need.
    Brand mentioned inaccuratelyEntity or relationship classificationAlign names, roles, attributes, dates, visible content, profiles, and structured data; remove contradictory descriptions.
    Accurate answer with weak or irrelevant citationGrounding and evidence alignmentMove support closer to the claim, make passages self-contained, and strengthen the relationship between the assertion and its evidence.
    Cited but not recommendedPositioning, suitability, or corroborationClarify the intended audience, meaningful differences, tradeoffs, and credible proof beyond the brand’s own assertions.
    Recommended but rarely clickedPossibly no failure at all, or an answer that satisfies the user before a visitAssess brand representation and downstream demand alongside referrals; give users a legitimate reason to continue without withholding the basic answer.
    Referral traffic without valuable actionPrompt-to-page or page-to-offer mismatchCompare the referring conversation with the landing page’s promise, audience, next step, and conversion path.

    Start with one query family tied to a real decision. Confirm technical eligibility, audit entity and claim clarity, strengthen the evidence and recommendation case, and then measure every stage with the same prompts. The first useful win is not a larger content calendar. It is knowing exactly where your current pages stop being understood, trusted, selected, or acted on.

    References

  • Unveiling the Power of AI: Boosting Citation Impact

    Unveiling the Power of AI: Boosting Citation Impact

    I am thrilled to share the news of an exciting new partnership that is set to revolutionize the way we connect AI visibility data to tangible citation outcomes and impacts.

    This collaboration promises to enhance the visibility of AI-generated insights and effectively translate them into actionable citations, thereby amplifying their real-world influence.

    In a world where AI continues to drive change and innovation, ensuring that these contributions are recognized and used is crucial, and this partnership is a significant step in that direction.


    Inspired by this post on Conductor Blog.


    crushpress.ai community screenshot
  • How to Build AI Search Visibility With Answer-First Content

    How to Build AI Search Visibility With Answer-First Content

    If your pages rank but your brand rarely appears in AI-generated answers, publishing more content can multiply the same problem. First find the break: can the system access your page, retrieve the right passage, reuse that passage without repairing it, and connect the claim to you?

    The practical goal is not to make your writing sound machine-generated. It is to make useful knowledge easy to find, extract, understand, trust, and attribute while keeping the page genuinely useful to the person who lands on it.

    AI visibility depends on four separate gates

    A document passes through an access portal, a retrieval lens, an extraction frame, and a source-attribution junction.

    Answer engine optimization, or AEO, is the practice of making information usable inside generated answers. AI search visibility is the outcome: your organization, experts, pages, or ideas appear when an answer engine responds to a relevant question.

    That outcome is not controlled by a single optimization. AI systems can retrieve a passage without treating the whole page as one indivisible result. A technically healthy page can therefore remain invisible if its useful answer is buried, vague, or difficult to attribute.

    • Access: The system must be allowed and able to reach the page. Crawl rules, indexing controls, rendering, canonicalization, and page availability belong here.
    • Retrieval: A passage must clearly match the question. Descriptive headings, explicit terminology, and focused sections help the right material get selected.
    • Reuse: The selected passage must answer the question cleanly. If it depends on missing context or requires substantial rewriting, it is a weak answer candidate.
    • Attribution: The system must be able to associate the information with a recognizable brand, author, dataset, framework, or other entity.

    These gates give you a useful diagnostic sequence. If a page cannot be accessed, rewriting its introduction will not help. If a passage is accessible but says nothing until its fifth paragraph, adding more schema will not solve the retrieval problem. If a useful passage could have been written by any competitor, it gives an answer engine little reason to name you.

    Key takeaways

    • Optimize complete answer passages, not just whole pages.
    • Put the direct answer immediately below the heading that states the question or task.
    • Use structured data to clarify accurate page facts, not to compensate for thin or ambiguous content.
    • Build consistent associations between your entity, its experts, and the topics they can credibly address.
    • Measure access, retrieval, reuse, and attribution separately so you know what to fix.

    Turn each important question into a standalone answer passage

    A page can cover the right topic and still contain no passage that directly resolves the reader’s question. This often happens when an introduction delays the answer, several sections repeat the same background, or a heading uses a clever label that does not reveal what follows.

    Build each important section as an answer unit. It should make sense when separated from the title, introduction, navigation, and surrounding paragraphs. That does not mean every section must be short. It means the section should identify its subject, answer its assigned question, and explain any necessary limits without forcing the reader to reconstruct context.

    Use this answer-unit workflow

    1. Assign one clear question. Write down the exact question the section must resolve. Split sections that attempt to answer unrelated questions.
    2. State the answer first. Make the opening sentence useful on its own. Put qualifications in the same passage rather than hiding them elsewhere.
    3. Explain the mechanism. Tell the reader why the answer is true, what makes it work, or where it stops applying.
    4. Add a decision or action. Give the reader a check, choice, sequence, or correction they can apply.
    5. Make the subject explicit. Replace vague references such as “this,” “it,” or “that approach” when the missing noun would make an extracted passage ambiguous.
    6. Add distinct value. Include an original definition, framework, dataset, expert interpretation, or unusually precise boundary when you can support it.

    Consider a section headed “Why it matters” that opens with: “This makes the process more effective and improves visibility.” A human who has read the previous section may infer the meaning. An isolated passage cannot. The heading does not name the subject, and the sentence does not identify the process, mechanism, or outcome.

    A stronger version would use the heading “Why answer-first passages improve AI retrieval” and open with: “Answer-first passages improve AI retrieval because the question, subject, and usable response appear in one self-contained section.” The next paragraph can add nuance, examples, and limitations. The direct answer has already done its job.

    Distinct framing helps with attribution, but do not confuse distinctiveness with invented jargon. Renaming a familiar checklist does not create authority. A useful framework separates a messy problem into decisions the reader could not make as easily before. Name it only if the name makes that reasoning easier to remember and reference.

    Run the isolation test during editing

    Copy a candidate section into a blank document without its page title or preceding text. Then ask:

    • Can you identify the exact subject from the heading and opening sentence?
    • Does the passage answer a real question before expanding on it?
    • Are important qualifications present in the same section?
    • Would a quotation preserve the original meaning?
    • Is there a specific reason to associate the passage with your organization or expert?

    If the section fails, repair the passage before adding more copy to the page. This editing method follows the underlying shift toward modular, answer-first content with clear structural signals.

    Keep technical SEO and structured data in their proper roles

    AEO adds a retrieval and attribution layer; it does not replace technical SEO. A blocked, unavailable, insecure, or badly implemented page gives every downstream system less to work with. At the same time, technical compliance alone is not differentiation.

    HTTPS appears on more than 91% of pages, while title-tag adoption is close to 99%. Those figures show how thoroughly basic practices have become embedded in platforms, content management systems, and plugins. They also explain why merely having a title tag or secure connection is not an AI visibility strategy. These are prerequisites that protect the opportunity to compete.

    Audit the foundation before changing the prose

    • Access and indexing: Confirm that the intended canonical page is reachable, indexable where appropriate, and not contradicted by template-level controls.
    • Titles and headings: Give the page a descriptive title and use headings that identify the actual question, entity, comparison, process, or decision in each section.
    • Crawl policy: Review robots.txt as a publishing-policy decision. Make crawler access intentional instead of inheriting a default that no one has checked.
    • Structured data: Ensure every declared fact agrees with the visible page. Names, descriptions, relationships, authorship, and other identifiers should not conflict across templates.
    • Rendered output: Check the final HTML, not only the editor. A plugin setting is not proof that the intended markup, heading hierarchy, or metadata reached the published page.

    JSON-LD can clarify what a page describes and how its entities relate. It cannot manufacture expertise, repair an unclear answer, or guarantee inclusion in an AI response. Treat it as a factual declaration layer: the markup should describe the page that exists, using values you can keep consistent and maintain.

    FAQPage markup deserves the same discipline. Its continued use despite Google limiting FAQ snippets points to a broader reason for structured data: explicit machine-readable context can remain useful even when a particular visual search feature is unavailable. Use FAQPage only when the visible page contains genuine questions and answers. Do not add repetitive FAQs merely to create more markup.

    Apply similar restraint to llms.txt. Adoption has been cautious, so it should not displace crawlability, clear content, accurate structured data, or entity work. You can evaluate it as an additional publishing signal, but do not treat the file as a universal inclusion switch. By contrast, robots.txt already has a practical policy role and deserves a deliberate review.

    Make your entity recognizable and your knowledge worth citing

    A complete content block is retrieved from fragmented material and linked through a glowing line to a distinct source entity.

    Extraction gets your words into consideration. Attribution gives the system a reason to connect those words to you. That connection becomes easier when your owned pages describe the same organization, experts, topics, and claims consistently.

    Backlinks still matter, but AEO authority also involves brand mentions, citations, and clear associations between an entity and its areas of expertise. A mention does not guarantee a citation, and repetition does not make an unsupported claim true. The useful objective is credible corroboration: relevant publishers and experts repeatedly associate your entity with information it is qualified to provide.

    Create an internal entity brief

    Before you try to earn external recognition, make your own representation coherent. Maintain a brief that records:

    • The exact organization name and a plain description of what it does.
    • The audience it serves and the topics it can credibly address.
    • The names, roles, and relevant credentials of contributing experts.
    • The principal pages that define the organization, people, services, research, and terminology.
    • The original frameworks, datasets, benchmarks, or recurring claims the organization owns.
    • The preferred language for relationships that are often described inconsistently.

    Use the brief as a consistency check, not as a script to paste everywhere. About pages, author profiles, editorial pages, structured data, media biographies, and contributed commentary should agree on factual identity while fitting their individual contexts.

    Publish assets other people have a reason to reference

    Generic opinion posts rarely create a strong attribution hook because another publisher can replace them without losing information. Reference-grade assets are harder to substitute. Suitable formats include original research, industry benchmarks, visual explainers, definitive resources, and glossaries.

    Choose the format after identifying the evidence you actually possess. If you have original data, publish the method, definitions, limitations, and findings clearly enough for someone to cite the result accurately. If your advantage is practitioner expertise, answer a narrow question with named expert input and explicit reasoning. If the market suffers from inconsistent terminology, build a glossary that defines boundaries instead of recycling dictionary-level descriptions.

    Then distribute the asset to people who already cover the subject. A workable outreach sequence is:

    1. Identify a narrow question journalists, analysts, creators, or industry writers repeatedly need to answer.
    2. Produce a citable asset that resolves that question with evidence or qualified expertise.
    3. List the people and publications for whom the finding is genuinely relevant.
    4. Pitch the usable finding, definition, or visual rather than asking for a generic mention.
    5. Keep the asset accurate so future citations do not point to stale or contradictory information.

    Do not make every sentence a brand claim. Put the entity name where attribution matters: beside an original definition, owned methodology, expert interpretation, or dataset. Natural, precise attribution is stronger than repeating the brand in passages where it adds no meaning.

    Measure the query, passage, citation, and next action

    Conventional rank tracking cannot tell you why an answer system omitted your brand. Build a fixed query set from real customer questions, category questions, comparisons, definitions, and decision-stage concerns. Keep the wording and tested surface recorded so later checks are comparable.

    For each query, capture:

    • Whether an AI-generated answer appeared.
    • Whether your brand or expert was named.
    • Whether your page was cited or linked.
    • Which passage, claim, or asset appeared to support the response.
    • Which competing entities were repeatedly named or cited.
    • Whether the answer represented your position accurately.
    • What changed after a content, technical, entity, or distribution update.

    Do not compress those observations into one visibility score before diagnosing the failure. The visible symptom should determine your next check.

    What you observeLikely gateWhat to inspect next
    The relevant page cannot be found or reachedAccessCrawl policy, indexing controls, canonical target, rendered output, and page availability
    The page is available, but another passage answers the queryRetrievalHeading specificity, question alignment, terminology, and section focus
    The right section is found, but it is not used cleanlyReuseOpening answer, missing context, vague pronouns, qualifications, and passage completeness
    Your information appears without your brand or expertAttributionEntity naming, authorship, original value, external mentions, and citation-worthy assets
    Your brand is named inaccurately or for the wrong topicEntity consistencyConflicting descriptions, outdated profiles, ambiguous relationships, and unsupported topic associations

    This approach also prevents false wins. A cited page is not useful if the answer misstates your position. A brand mention for an irrelevant topic does not strengthen the association you need. A technically perfect page is not finished if it contains no extractable answer. Record the outcome at the same level at which you intend to improve it.

    Start with the highest-value question your audience asks. Trace it through the four gates, repair the first failure you find, and make that page the pattern for the rest of your library. AI search visibility becomes manageable when you stop treating it as one mysterious ranking and start treating it as a chain of observable decisions.

    References

  • How to Measure and Improve Visibility in AI Search

    Your page ranks, the answer is on the page, and your technical SEO looks sound. Yet Google AI Overviews does not cite it, and chatbot answers either omit your brand or mention it inconsistently. That is not a contradiction. It means organic rank and AI visibility are measuring different selection systems.

    You need a baseline that separates AI-answer eligibility, brand mentions, citations, accuracy, and business outcomes. Once those signals are split apart, a visibility problem stops being mysterious: you can tell whether to change the query set, the page, the answer structure, the evidence, or nothing at all.

    Rankings and AI visibility answer different questions

    An organic ranking tells you where a page appears in a conventional result set. An AI citation tells you whether an answer system retrieved that page for a particular response. A brand mention tells you whether the system represented the entity in its answer. These outcomes can overlap, but none is a substitute for the others.

    BrightEdge measured the overlap between organic rankings and AI Overview citations rising from 32.3% in May 2024 to 54.5% in September 2025. The increase matters, but the remaining gap is just as important. A highly ranked page can still be omitted, while a lower-ranked page can be selected because its passage is easier to retrieve and use in an answer.

    Record rank and citation status together. The four possible states point to different work:

    • Ranked and cited: preserve the passage that is being retrieved, then look for ways to improve the accuracy and prominence of the brand representation.
    • Ranked but not cited: investigate a retrieval gap. The page is competitive in organic search, but its answer may be buried, mismatched to the prompt, weakly structured, or insufficiently supported.
    • Not highly ranked but cited: inspect the selected passage closely. It may reveal an answer format, level of specificity, or intent match worth extending elsewhere without assuming that the page’s organic SEO is complete.
    • Neither ranked nor cited: check query-to-page relevance, crawlability, indexation, topical coverage, authority, and content quality before making narrow AI-focused edits.

    AI-answer eligibility is another separate variable. One late-2025 estimate put AI Overviews at 16% of searches, with uneven coverage across query types. Transactional, navigational, and local searches were less likely to trigger them than many informational searches. If a query produces no AI Overview, do not record the page as a failed citation. Record no trigger, then continue measuring organic visibility and any other AI surfaces relevant to that query.

    This distinction prevents a common reporting error. A falling citation rate can mean your content lost retrieval visibility, but it can also mean fewer tracked searches produced an AI answer. Trigger rate gives you the denominator needed to tell those situations apart.

    Build a tracker that makes every observation reproducible

    An AI visibility record is useful only when you can reconstruct how it was produced. Start by naming the exact surface. A practical tracker might cover ChatGPT through an API, Claude through an API, Gemini through an API, Google AI Mode, and Google AI Overviews. Do not merge them into a generic AI result. Each surface has different retrieval behavior, citations, interfaces, and conditions.

    An API model response should also remain distinct from the corresponding consumer product. The model, system instructions, browsing or grounding capability, account state, and product interface can change what appears. Labeling everything ChatGPT or Gemini without those qualifiers creates a trend line that cannot be interpreted.

    1. Define the surface and environment. Store the platform, product or API, model identifier when available, browsing or grounding state, locale, language, device class, and signed-in state where those conditions apply.
    2. Create a query inventory around decisions and problems. Include unbranded discovery questions, comparison prompts, implementation questions, troubleshooting prompts, and branded fact checks. Assign each prompt to a topic, intent, funnel stage, market, and target page.
    3. Freeze the wording. Give every prompt a stable ID and preserve its exact text. If you want to test conversational variants, create separate prompt IDs rather than silently changing the original.
    4. Save the complete output. Store the raw answer, cited URLs, cited domains, response timestamp, and any visible ordering. A screenshot is useful for visual evidence, but searchable response text is better for rescoring and analysis.
    5. Choose a repeatable cadence. Weekly checks can suit an active launch or optimization cycle; monthly checks can suit a stable portfolio. Consistency matters more than an aggressive schedule you cannot maintain.

    Your query inventory should reflect the questions that matter to the business, not merely prompts that are likely to mention the brand. Include current search demand, sales objections, support questions, category-selection decisions, and prompts where competitors are already visible. Keep branded and unbranded prompts in separate cohorts so improved branded recognition does not disguise weak category discovery.

    At minimum, each observation should contain a run ID, prompt ID, exact prompt, topic cluster, surface, model or product, environment, timestamp, completion status, AI-answer trigger status, raw response, brand mentions, owned citations, other cited domains, accuracy assessment, prominence assessment, and organic position where applicable. Add the target landing page and business outcome fields if you can connect the observation to analytics.

    Protect the evidence before automating the score

    Use persistent storage from the first working version. Keep the original response even after you add parsing, classification, or scoring. Raw API responses make parsing failures visible, while saved outputs let you apply a revised rubric to historical observations without rerunning every prompt.

    If you build the tracker yourself, connect one surface and validate it before adding the next. Test authentication, response persistence, citation extraction, long-answer handling, and error states separately. Save a working version before changing a connector or parser. Otherwise, a software regression can look like a visibility loss.

    Measure trigger, mention, citation, accuracy, and outcome separately

    A single visibility percentage conceals the mechanism behind the result. Keep the component metrics visible, even if leadership also wants a roll-up score.

    MetricCalculationWhat it tells you
    AI-answer trigger rateCompleted searches with an AI answer divided by all completed searchesHow often the tracked surface created an AI visibility opportunity
    Conditional brand mention rateGenerated answers naming the brand divided by all generated answersHow often the brand appears when an answer exists
    Owned citation rateGenerated answers citing an owned domain divided by all generated answersHow often your content is retrieved as supporting material
    Accurate mention rateMaterially accurate brand mentions divided by all reviewed brand mentionsWhether visibility represents the brand correctly
    Portfolio reachCompleted searches producing a brand mention or owned citation divided by all completed searchesExposure across the whole tracked query set, including searches with no AI answer
    Business outcomeObserved visits, assisted actions, leads, or conversions connected to the cited page or AI referralWhether exposure contributes to a useful result

    The denominators matter. Conditional brand mention rate answers what happens when an AI answer appears. Portfolio reach answers what happens across every tracked opportunity. Reporting only the first can make performance look strong when AI answers rarely trigger. Reporting only the second can make good content look weak when the surface itself has limited coverage.

    Treat failed requests as null observations, not zero visibility. Retry timeouts, authentication failures, truncated outputs, and parsing errors. Treat a completed AI answer with no brand or owned citation as a genuine zero. For Google AI Overviews, treat a completed search with no Overview as no trigger: it belongs in the trigger-rate denominator but not in an answer-quality score.

    Use a transparent five-signal response score

    If stakeholders need one roll-up number, use a five-point rubric whose components remain auditable. A generated answer can earn one point for each of these signals:

    • The brand is named.
    • The brand is described materially accurately.
    • The brand appears in the main answer or an explicit shortlist rather than in incidental text.
    • An owned page is linked or cited.
    • The cited owned page directly supports the claim or recommendation beside it.

    Define borderline cases before the first run. Decide, for example, whether a source carousel without an in-text citation counts, what qualifies as prominent placement, and which factual errors fail the accuracy signal. Keep those rules unchanged during an optimization cycle.

    Average the response score by surface, query cluster, intent, and market. Always display mention rate, citation rate, and accuracy beside it. Two portfolios can have the same average score while needing opposite fixes: one may receive frequent uncited mentions, while the other earns citations that never surface the brand.

    Do not add organic rank to the five-point score. Rank is a diagnostic dimension, not another form of AI visibility. Keeping it separate preserves the ranking-citation gap you need to investigate.

    Turn each miss into a specific content change

    Optimization should begin with the failure state, not with a sitewide rewrite. The smallest change that addresses the observed mechanism is easier to evaluate and less likely to disrupt content that already performs.

    1. No AI answer appears for the query. Move the query out of the AI Overview citation cohort, but retain it for organic search and other AI surfaces. Recheck it at the next scheduled run. A missing Overview is not evidence that the page needs rewriting.
    2. The page answers the topic but not the prompt’s version of the question. Write down the exact decision, constraint, or task expressed by the prompt. Add a section that resolves that need directly, or map the prompt to a more suitable page. Repeating the target keyword will not repair an intent mismatch.
    3. The answer is present but buried. Put a direct response near the beginning of the relevant section, then supply context, conditions, evidence, and exceptions. AI systems favor clear answers that can be extracted without reconstructing a long narrative.
    4. The page is difficult to parse. Replace vague headings with headings that name the actual question or subproblem. Keep each section focused, use concise paragraphs, and make essential qualifiers part of the answer rather than scattering them through unrelated sections.
    5. The answer lacks visible reasons to trust it. Add an accurate byline, relevant author credentials, dates, named evidence, methodology for original analysis, and links supporting consequential claims. Credibility needs to be visible on the individual page, especially for health, financial, legal, educational, and other high-consequence subjects.
    6. The page is cited but the brand is absent or misrepresented. State the relevant entity facts plainly near the answer. Keep product names, organization details, authorship, and descriptions consistent across visible copy and structured data. Do not force promotional language into an informational answer; that can make the passage less usable.
    7. One page carries the entire topic. Fill genuine coverage gaps with supporting pages that answer adjacent questions, comparisons, implementation needs, and limitations. Broader topical coverage gives an answer system more precise passages to retrieve than one oversized page trying to satisfy every intent.

    JSON-LD can clarify entities and page attributes, but it is not an AI citation switch. Use applicable types such as Article, Person, Organization, Product, or FAQPage only when the markup accurately describes visible content and meets the relevant eligibility rules. Structured data cannot compensate for an answer that is vague, unsupported, or aimed at the wrong question.

    Keep a query-to-page diagnosis sheet with six columns: prompt ID, intent, required answer, current target page, observed failure state, and proposed change. That sheet forces every edit to answer a measurable problem. It also exposes prompts competing for the same page and pages expected to satisfy incompatible intents.

    When another domain is cited, compare the exact passage, not the entire competing page. Note how quickly it answers, which qualifiers it includes, what evidence is visible, and whether its heading makes the passage understandable out of context. The goal is not to imitate wording. It is to identify the retrieval need your page leaves unresolved.

    Run controlled cycles and judge results by query cluster

    AI outputs can vary between runs, so one favorable answer is not a durable win. Collect repeated baseline observations, preserve the raw outputs, and compare cohorts under the same conditions. You may not have enough observations for formal statistical claims, but you can still avoid declaring success from a screenshot.

    1. Freeze the test cohort. Keep prompt wording, surface, model or product, locale, and other recorded conditions stable.
    2. Choose one hypothesis. Examples include a buried answer, an intent mismatch, weak page-level evidence, or inconsistent entity information.
    3. Change the smallest relevant unit. Edit the introduction, one answer section, one evidence block, or the applicable structured data rather than rewriting unrelated material.
    4. Record the deployment. Save the prior page version and note the publication time, changed section, hypothesis, and expected metric movement.
    5. Rerun the same observations. Compare trigger rate, mention rate, citation rate, accuracy, prominence, and the five-signal score by query cluster and surface.
    6. Check guardrails. Review organic rankings, search clicks, engagement, conversions, factual accuracy, and content readability. A citation gain is not worthwhile if the page becomes less useful or loses the outcome it was built to produce.

    Use different success criteria for different goals. An informational publisher may prioritize owned citations and qualified visits. A recognized brand may care more about accurate representation in category answers. A newer brand may focus first on unbranded mention reach. The metric should follow the decision the business needs to make.

    Keep AI visibility and business impact connected but distinct. A citation is evidence of retrieval, not proof of traffic or revenue. A brand mention can shape awareness without producing a trackable click. Report the visibility event honestly, then attach referral traffic, assisted behavior, leads, or conversions only where your analytics can support the connection.

    Key takeaways

    • Track AI-answer triggers, brand mentions, owned citations, accuracy, prominence, and outcomes as separate signals.
    • Record the exact prompt, surface, model or product, environment, timestamp, raw answer, and cited URLs for every observation.
    • Keep organic rank beside AI visibility as a diagnostic; do not blend it into the same score.
    • Classify the failure before editing: no trigger, wrong intent, buried answer, opaque structure, weak evidence, inconsistent entity information, or insufficient topical coverage.
    • Test one hypothesis on a stable query cohort, preserve the prior version, and judge movement across repeated observations rather than one response.

    Start with one commercially important topic cluster and build a clean baseline before changing its pages. Your first useful result is not a bigger visibility score. It is knowing whether the next action belongs in measurement, retrieval optimization, brand representation, or content strategy. Once that distinction is visible, the next edit becomes much easier to defend.

    References

  • AI Search Data Access and Platform Control: A Practical Guide

    AI Search Data Access and Platform Control: A Practical Guide

    You publish a technically sound page. One AI engine cites it, another repeats an older version of the information, and a third never mentions your brand. That doesn’t automatically mean the page is weak. Each engine may be working from a different pool of accessible data.

    Your job is no longer just to rank one URL. You need to make important facts discoverable, retrievable, understandable, and attributable across systems you don’t control. The way to do that is to diagnose the access path, strengthen the parts you own, and measure each platform separately.

    AI search doesn’t operate from one universal index

    From 2023 through 2026, deals, restrictions, and lawsuits changed how data could flow into AI systems. By 2026, tighter platform control was contributing to more fragmented answers. A page can therefore be visible in one AI product and effectively absent from another without changing at all.

    That fragmentation makes a single visibility score misleading. AI search products can differ at several layers:

    • Discovery: The system has to find the URL through a crawl, feed, index, link, API, licensed collection, or another permitted route.
    • Access: The relevant crawler or retrieval service has to receive the content rather than a block, login screen, consent wall, empty shell, or error response.
    • Parsing: The system has to extract the main facts, entities, relationships, dates, and supporting evidence from the returned content.
    • Retrieval: The page has to be considered relevant when a user asks a particular question. Being stored somewhere does not guarantee selection for that query.
    • Synthesis: The answer generator has to use the retrieved information accurately and preserve material qualifications.
    • Attribution: The interface has to decide whether and how to display a citation. An accurate mention and a visible link are separate outcomes.

    This distinction matters because each failure calls for a different fix. Adding more schema won’t correct a crawler block. Rewriting a page won’t repair an outdated third-party profile. Securing a brand mention won’t necessarily produce a clickable citation.

    Use the following as a fault-isolation chart, not as proof of a cause. One observation is a lead; repeated tests and access evidence are what establish the diagnosis.

    What you observeEarliest likely failureWhat to inspect next
    The URL is absent everywhere you testDiscovery or accessSitemaps, internal links, server responses, robots.txt, page-level directives, and authentication requirements
    One engine uses the current fact while another gives an older answerRetrieval freshness or a stale copyThe URLs each engine cites, cached or syndicated versions, and the last verified canonical update
    The answer is accurate but has no linkAttribution or interface behaviorTrack the mention as answer inclusion, then record citation presence separately
    A third-party profile is cited instead of your siteSource selection or owned-page accessWhether the profile is more complete, more current, easier to parse, or the only version available to that engine
    Your page is cited for branded questions but absent for category questionsRetrieval or evidence strengthWhether the page directly answers the non-branded need and supports its claims with specific, verifiable information

    Audit the entire route from page to AI answer

    An abstract web page passes through a series of gated processing chambers before its information reaches an AI answer interface.

    Start with a query-level audit. A domain-wide score can hide the difference between a commercially important failure and an irrelevant miss. Choose questions tied to an actual decision: selecting a provider, verifying a product capability, comparing an approach, confirming eligibility, or checking whether information is current.

    1. Define the fact that should survive the journey. Write down the exact claim an accurate answer needs to contain, the canonical URL that supports it, and any condition that must remain attached. If a limitation changes the meaning, include it in the expected answer.
    2. Separate branded, non-branded, and verification queries. A branded prompt tests whether the engine recognizes your entity. A non-branded prompt tests whether you are retrieved for the problem you solve. A verification prompt tests whether the engine can confirm a precise fact. Do not blend these intents into one score.
    3. Keep test conditions stable. Use the same query wording while comparing engines. Record the product, model or mode when displayed, date and time, account state, region when relevant, and whether web retrieval was enabled. Change one variable at a time.
    4. Capture the answer before judging it. Save the wording, named entities, qualifications, citations, linked URLs, and any visible freshness indicators. Mark factual accuracy and citation presence in separate fields.
    5. Trace every cited URL. Determine whether the engine selected your canonical page, a syndicated copy, a marketplace listing, a social profile, an aggregator, or another publisher. That choice reveals which data route is currently carrying your visibility.
    6. Inspect the owned page as a machine receives it. Check the response status, redirect chain, canonical target, robots.txt rules, meta robots directives, X-Robots-Tag headers, rendered content, and the text available without a user completing an interaction. Confirm that the critical claim is present in the accessible page body.
    7. Classify the earliest failure. Label it discovery, access, parsing, retrieval, synthesis, attribution, or external-copy drift. Fix that layer first. Later-stage optimization cannot compensate for an earlier-stage block.

    Your audit sheet should preserve evidence, not just a final grade. Useful columns include query ID, intent, expected fact, canonical URL, engine, mode, test conditions, answer text, accuracy, qualification preserved, citation present, cited domain, cited URL, access result, failure class, owner, and next action.

    Retest after a meaningful change to content, access controls, structured data, distribution, or a cited external record. Avoid repeatedly changing the prompt until you receive the answer you want. That measures prompt manipulation, not dependable visibility.

    Build visibility that can survive platform boundaries

    You cannot force every AI platform to ingest, retrieve, or cite your content. You can make your facts easier to obtain through permitted routes and reduce the damage when a platform changes its access policy.

    Maintain a canonical fact layer on property you control

    Give every decision-critical fact a stable home. The page should state the fact plainly, identify the entity it belongs to, carry necessary conditions beside the claim, and show the information needed to judge freshness. Essential information should not exist only in an image, video, downloadable file, tab, or client-side widget.

    Create a fact register for content that commonly drifts. For each item, record:

    • The approved wording and any mandatory qualification
    • The canonical URL and responsible owner
    • The visible page element where the fact appears
    • The structured-data field, if one legitimately applies
    • The event that should trigger an update
    • The approved external channels carrying a copy

    This turns freshness into an operating process. When a product detail, policy, service area, leadership record, or other material fact changes, you know which owned page and external records need attention.

    Use external platforms as distribution, not the master record

    Third-party platforms can be valuable discovery routes, especially when an AI engine has stronger access to them than to your site. They also create dependency. A profile can become stale, change format, restrict access, or disappear from an engine’s retrieval set.

    Publish a compact, consistent version of important facts on approved channels, then maintain a map from each external record back to its canonical owner. Avoid copying every page everywhere. Full duplication multiplies the places where old wording can survive. Distribute the facts a channel genuinely needs, preserve qualifications, and link to the canonical page where the channel permits it.

    If a platform restricts automated access or reuse, do not bypass its controls to create an unofficial data pipeline. Use its approved API, feed, export, publishing workflow, or licensing route. Circumventing access rules can create contractual or legal exposure, and the resulting pipeline is likely to break without notice.

    Treat structured data as translation, not permission

    JSON-LD helps a parser connect a page to an entity and interpret supported properties. It does not grant crawler access, compel retrieval, prove a claim, or guarantee a citation.

    Use the schema type that matches the visible entity and content. Keep names, identifiers, URLs, dates, and relationships consistent with the page. Do not place promotional or unsupported claims in markup that a reader cannot verify in the visible content. After publishing, validate both the syntax and the rendered values; syntactically valid markup can still describe the wrong entity or carry an outdated field.

    Support the same canonical layer with ordinary discovery mechanisms such as coherent internal links, XML sitemaps, useful page titles, stable URLs, and feeds where appropriate. For partners that accept structured submissions, maintain those feeds from the same fact register instead of editing each destination independently.

    Measure access, inclusion, and citation separately

    Three inspection stations separately examine whether web information passes an access gate, enters a knowledge repository, and remains linked to a source in an AI response.

    A blended AI visibility score can rise while the wrong fact is being repeated, or fall because an interface stopped displaying citations even though your information still shapes answers. Keep the signals separate so each metric leads to a clear decision.

    SignalEvidence to recordDecision it supports
    Technical availabilityResponse, redirect, crawler rule, authentication, and returned HTMLWhether discovery and access need repair
    Content extractabilityWhether the expected fact and qualification appear in the fetched or rendered textWhether essential content must be moved, clarified, or exposed more reliably
    Answer inclusionWhether the answer accurately contains the expected fact or entityWhether retrieval and content relevance are working
    Citation attributionWhether a citation appears and which exact domain and URL receive itWhether owned visibility or an external dependency carries the answer
    Factual alignmentCorrect, incomplete, contradicted, or unsupported, with the answer text preservedWhich misinformation or missing qualification needs priority
    FreshnessWhether the answer matches the current canonical record and which version appears to be usedWhether an old owned page, stale external copy, or retrieval lag needs investigation
    Cross-platform coverageThe result for each engine and query rather than one combined rankWhich platforms matter enough to justify targeted work
    Dependency concentrationWhich external domains repeatedly carry mentions or citationsWhere loss of access could remove a large part of your visibility

    Use clear labels such as pass, partial, fail, and not observable, then retain the underlying evidence. Not observable is important: you usually cannot inspect an engine’s private corpus or prove why it selected a particular passage. State what the test demonstrates and keep inference separate.

    Prioritize wrong and outdated facts before missing citations. Next, fix owned-page access and parsing problems that affect several queries. Then address stale external copies and weak non-branded retrieval. An accurate uncited answer may still matter, but it should not be reported as equivalent to an owned citation.

    Do not treat every engine discrepancy as a data-access failure. Query wording, retrieval timing, answer mode, personalization, and normal generation variation can also change the result. A stable query set, captured citations, server evidence, and repeated observations help you distinguish a platform pattern from a one-off response.

    Key takeaways for an AI search access strategy

    • AI visibility is platform-specific because engines do not necessarily discover, access, retrieve, or cite the same data.
    • A public URL is not automatically discoverable, fetchable, parseable, retrievable, or eligible for visible attribution.
    • Audit the answer path in order and fix the earliest failing layer before changing later-stage content or schema.
    • Track accurate inclusion and visible citation as separate outcomes.
    • Keep critical facts on an owned canonical page, then distribute controlled versions through approved external routes.
    • Use JSON-LD to clarify visible information, not to replace access, evidence, maintenance, or content quality.
    • Measure each engine and query independently, preserve the evidence, and mark private platform behavior as inference rather than fact.

    Start with one page tied to a real customer decision. Write down the fact it must communicate, test the corresponding query across the AI products your audience uses, and trace the route from discovery through citation. Fix the first broken layer, update every approved copy from the same fact register, and repeat the test after the change. That gives you a visibility system you can operate even when the surrounding platforms keep moving.

    References


  • How to Integrate PR and Social Media for AI Visibility

    How to Integrate PR and Social Media for AI Visibility

    You have earned media coverage. Your social accounts are active. Your website explains the product. Yet when a buyer asks an AI assistant about the problem you solve, your brand is absent, mischaracterized, or mentioned without a citation.

    The answer usually isn’t another disconnected content calendar. You need an evidence chain in which PR, social media, and owned content support the same defensible claims. That is the practical value of connecting SEO, social presence, PR, and content creation: every campaign can leave behind material that people can understand, publishers can corroborate, and AI systems can retrieve and cite.

    Start with the answer you want the market to repeat

    AI visibility is not simply a contest to repeat your brand name across more channels. A high volume of vague mentions does little to clarify what your company does, who it serves, or why its claims deserve to be trusted.

    Begin with a buyer question, not a campaign slogan. Write down the question in the language a customer would use when asking ChatGPT, Gemini, Perplexity, or another answer engine. Then define the answer you can substantiate.

    A useful claim map contains:

    • The audience question: the specific problem, comparison, definition, or decision the campaign will address.
    • The approved answer: a concise statement that names the brand or product consistently and explains its relevance.
    • The supporting proof: evidence, methodology, product documentation, expert attribution, or another verifiable basis for the answer.
    • The necessary qualification: the conditions, limitations, or scope that must travel with the claim.
    • The canonical destination: the stable page where the complete explanation and supporting evidence will live.
    • The corroboration goal: the independent context that PR outreach should seek to establish.

    If the team cannot complete those fields, the claim is not ready for distribution. Publishing it more widely will multiply ambiguity rather than authority.

    A practical drafting pattern is: For [audience], [product or organization] addresses [defined problem] through [specific mechanism], supported by [verifiable evidence]. The final wording should sound natural, but the structure forces the team to identify the entity, problem, mechanism, and proof.

    Be especially careful with superlatives such as best, leading, fastest, and most trusted. Those words require a defined comparison and defensible evidence. Replace an unsupported category claim with a narrower factual statement that a publisher could verify without relying on your press release.

    This discipline matters because useful AI citations must be credible and traceable. Your PR brief, spokesperson notes, owned page, and social adaptations should preserve the same underlying meaning even when their formats differ.

    Build the citation-ready destination before outreach begins

    A press release, interview, social thread, or video should not be the only place where a campaign’s central explanation exists. Publish a stable, readable HTML destination before outreach so every later asset has somewhere authoritative to point.

    The page does not need to be long for its own sake. It needs to resolve the reader’s question without making them assemble the answer from several campaign fragments. Include:

    • A descriptive title that identifies the subject rather than merely naming the campaign.
    • A direct answer near the beginning of the visible copy.
    • Consistent organization, product, and spokesperson names.
    • The evidence behind the claim, with methodology and limitations when those details affect interpretation.
    • Definitions for specialized terms that a buyer or journalist could reasonably misunderstand.
    • Clear authorship, editorial ownership, or expert attribution where relevant.
    • A stable URL that will remain useful after the launch period ends.
    • Accurate structured data that matches the visible content and identifies the page’s real entities and content type.

    Structured data can clarify what a page represents, but it cannot turn an unsupported assertion into independent evidence. JSON-LD, page copy, metadata, and PR materials must agree. If the markup identifies an author, organization, product, or frequently asked question that the visible page does not substantiate, fix the content-model mismatch instead of adding more markup.

    Turn one campaign into connected answer units

    Once the canonical page is ready, run the campaign in a deliberate sequence:

    1. Publish the complete owned explanation. Make the central answer, evidence, terminology, and limitations available in crawlable text.
    2. Build the pitch around the audience question. The news angle may change by publication, but the verifiable claim should not.
    3. Prepare corroboration material. Give spokespeople and PR teams the original evidence, methodology, definitions, and approved entity names rather than a shortened claim with no context.
    4. Earn accurate coverage. A link to the canonical destination is useful when editorially appropriate, but accurate naming and faithful context still matter when a publisher does not link.
    5. Adapt the explanation for social surfaces. Preserve the answer and proof while changing the delivery for video, executive commentary, community discussion, or short-form updates.
    6. Connect the assets. Point social audiences to the complete explanation, add earned coverage where it provides useful corroboration, and update the owned page when a campaign exposes a real unanswered question.

    Do not lock the only usable explanation inside an image or video. Publish the substance as readable text, then use richer formats to demonstrate, discuss, or distribute it. YouTube, Reddit, and substantive long-form content can support AI visibility and citation, but only when the material contains enough context to stand on its own.

    Give PR and social media different jobs in the evidence chain

    Press equipment reveals a central verified object while connected social nodes distribute it, all anchored to an organized archive of source materials.

    Integration does not mean copying the same announcement onto every channel. It means assigning each surface a clear job while keeping the claim, entity names, evidence, and qualifications aligned.

    SurfacePrimary jobUseful formatCommon failure
    Owned websiteEstablish the canonical explanationHTML explainer, evidence page, documentation, or question-led landing pageA campaign page that contains slogans but no direct answer or proof
    Earned PRAdd independent context and corroborationReported coverage, expert commentary, interview, or contributed analysis with clear disclosureRepeating an announcement without verifying or explaining its central claim
    YouTubeDemonstrate or explain the answer in depthWalkthrough, interview, demonstration, or question-led explanation supported by descriptive textA promotional clip whose title, description, and spoken content never resolve the question
    Reddit or another communityAddress real questions in the language people useTransparent participation, a substantive answer, or a clearly identified expert discussionAstroturfing, undisclosed promotion, or dropping links without answering the question
    Executive or expert social accountAttach informed interpretation to a named personCommentary, a concise explanation, or a response to a relevant industry questionGhostwritten claims that exceed the person’s actual expertise or omit important limits
    Short-form brand socialDistribute and reinforce the campaign’s core languageKey finding, visual excerpt, short clip, or link to the complete resourceSplitting the claim into fragments that lose their evidence and context

    This is where answer engine optimization changes the social brief. An AEO-driven social strategy pursues discoverability and citations as well as engagement. That does not make likes, comments, and watch behavior irrelevant. It means engagement is no longer the only outcome the team should inspect.

    Keep the handoffs explicit. The SEO or GEO owner defines the target question, canonical page, internal links, and structured data. PR owns the evidence pack, editorial angle, spokesperson preparation, and coverage accuracy. Social owns format adaptation and community participation. A measurement owner preserves the prompt set and records what answer engines retrieve before and after the campaign.

    Each team should be allowed to improve the presentation, but no team should silently strengthen the claim. When a social caption removes a qualification or a pitch turns a narrow result into a universal one, the integrated campaign becomes inconsistent at the point where consistency matters most.

    Measure retrieval, citation, and description accuracy

    Three analysts inspect an AI-generated product model whose illuminated paths lead back to source fragments in an organized repository.

    Reach and engagement tell you whether people encountered a social asset. They do not tell you whether an AI answer can find the brand, cite the right URL, or explain the claim correctly. Add an answer-level measurement layer.

    Build a fixed prompt set from real sales, support, search, and customer-research questions. Include brand-neutral discovery prompts as well as branded prompts. The first group tests whether you appear when the buyer has not selected you; the second tests whether AI systems describe you accurately once your name is present.

    Useful prompt patterns include:

    • What is [category or problem]?
    • How can [audience] solve [specific problem]?
    • Which approaches are suitable for [defined use case]?
    • How does [brand or product] address [problem]?
    • What evidence supports [specific claim]?
    • What are the limitations or tradeoffs of [approach]?

    Run the same set across the answer engines that matter to your audience. Preserve the date, product or model label when visible, complete response, cited URLs, and relevant screenshots or exports. AI outputs can vary, so a single favorable response is an observation, not proof of durable visibility.

    For every response, record:

    • Presence: whether the brand is absent, merely mentioned, presented as an option, or used as a substantive part of the answer.
    • Citation: whether a citation is present and which exact URL receives it.
    • Source path: whether the cited destination is owned content, earned coverage, YouTube, Reddit, or another surface.
    • Description accuracy: whether the answer identifies the right entity, audience, capability, evidence, and limitations.
    • Claim fidelity: whether the wording remains within what your evidence supports.
    • Competitive context: which alternatives appear and what evidence seems to support their inclusion.

    Establish the baseline before launch. Recheck after the owned resource, earned coverage, and social adaptations are available. Look for repeated changes across related prompts and systems, then inspect the URLs behind those changes. Do not attribute an improvement to a single social post merely because the timing overlaps; answer engines can draw on many changing inputs.

    Tracking social AI citations and platform-specific visibility patterns can make this review easier, but a dashboard still needs human verification. Open the cited pages. Confirm that the citation supports the answer. Separate a visible brand mention from a cited recommendation, and flag cases where the answer is favorable but factually wrong.

    If you hire outside help for LLM visibility and citation work across ChatGPT, Gemini, and Perplexity, ask for the prompt set, URL-level citation evidence, captured answer context, and a record of when each check was performed. Require the provider to distinguish mentions from citations and observations from causal claims. Avoid any service that guarantees placement in a probabilistic answer system.

    Key takeaways

    • Choose a buyer question and a defensible answer before planning channel output.
    • Publish a stable canonical page with the complete explanation, evidence, terminology, and necessary limitations.
    • Use PR to build independent context, not merely to replicate a brand announcement.
    • Adapt the same substantiated claim for YouTube, community discussion, expert commentary, and short-form distribution without stripping away its qualifications.
    • Keep entity names, product descriptions, evidence, and structured data consistent across the campaign.
    • Measure whether AI systems retrieve, cite, and describe the brand correctly; treat engagement as a supporting diagnostic rather than the final visibility result.

    Apply this system to your next campaign before the pitch list or social calendar is finalized. Pick its most defensible buyer-facing claim, create the claim map, and build the canonical destination. Once that foundation exists, every PR placement and social asset can strengthen one coherent answer instead of creating another disconnected mention.

    References


  • Is Your Website Ready for AI Agents? A Practical Audit

    Is Your Website Ready for AI Agents? A Practical Audit

    You can have a fast, attractive website that still leaves an AI system guessing. A person may work around a price that appears late, two conflicting policy pages, an unlabeled button, or a confirmation shown only through a visual change. A machine may stop, cite the wrong fact, or repeat an action because it cannot tell whether the first attempt worked.

    The goal is not to rebuild your site for bots at the expense of people. It is to make public information retrievable, meaning explicit, and actions safely bounded. That is the practical response to the shift toward machine-led website visits. This audit shows you where to look and what a passing result should look like.

    Audit the journey, not the bot name

    Agent readiness is broader than allowing a particular crawler through robots.txt. An AI search system may retrieve a page to answer a question, compare facts across pages, send a person to a landing page, or help a signed-in user complete a task. Each journey fails differently.

    Start with the intent that matters, then follow it from request to outcome. Choose priority journeys from three groups: finding an answer, making a decision, and taking an action. Write the expected result before you test so that a plausible but incorrect response does not pass by accident.

    JourneyWhat the machine needsWhat failure looks like
    Answer or citeA public, stable page with a direct answer and enough context to interpret itThe answer is absent from the retrieved HTML, buried in an image, or contradicted elsewhere
    Compare and decideConsistent names, identifiers, attributes, prices, conditions, and limitationsThe same offer has different facts across the page, structured data, and linked policies
    Act and confirmClearly labeled controls, explicit prerequisites, bounded permissions, and a machine-readable resultThe agent cannot identify the correct control, understand an error, or confirm whether the action succeeded

    For each journey, name the authoritative page, the facts that must be preserved, the actions that are permitted, and the state that proves completion. This turns an abstract AI-readiness project into a set of testable requirements.

    Make important pages retrievable without guesswork

    A page is not agent-ready merely because it looks correct in your browser. Your browser may have cookies, cached scripts, a logged-in session, and enough processing time to assemble the page after the initial response. A fresh machine client may have none of those advantages.

    Test every priority URL from a clean, logged-out session. Inspect the returned HTML as well as the rendered screen. The page title, primary heading, main answer, relevant entity name, and essential links should be available without requiring a person to reveal them through hover effects, tabs, or visual-only controls. When a fact is central to the page, do not assume every client will execute and wait for the same JavaScript path as a full browser.

    • Confirm that the preferred URL returns a successful response and does not enter a redirect loop, soft-error state, consent loop, or challenge page.
    • Review robots.txt, meta robots directives, and the X-Robots-Tag together. An accidental conflict can make an otherwise public page unavailable. Robots directives are discovery instructions, not security controls, so private information still belongs behind real authentication.
    • Use one canonical URL for each primary resource. Internal links, canonical tags, redirects, and the XML sitemap should agree on that URL.
    • Keep the sitemap focused on live, canonical pages that you actually want discovered. Remove obsolete, redirected, private, and erroring URLs rather than asking machines to sort through them.
    • Link important pages through ordinary crawlable navigation. Descriptive link text such as “Enterprise pricing” carries more meaning than repeated links labeled “Learn more.”
    • Provide an HTML version of essential facts that otherwise live only in an image, video, downloadable document, or interactive widget.
    • Test firewall, bot-management, content-delivery, and rate-limit rules with a fresh client. Record whether a failure comes from the application or from an infrastructure layer in front of it.
    • Never weaken authentication to make an agent test pass. Keep protected data protected and expose only the public information or authorized interface the task genuinely requires.

    A useful retrieval record includes the requested URL, response status, final URL after redirects, declared canonical, applicable robots directives, and whether the required facts appeared in the response. A screenshot can confirm appearance, but it cannot replace those checks.

    Make the page’s meaning explicit in content and JSON-LD

    An abstract machine agent connects directly to a central web page shown in visible-content, semantic, and linked-data layers within an orderly site structure.

    Once a machine can retrieve a page, it still has to identify what the page describes and which claims belong together. Ambiguity usually enters through inconsistent naming, missing qualifiers, stale duplicates, and structured data that says something different from the visible page.

    Give each priority page a clear job. Put the direct answer near the point where the page establishes the question or offer, then supply the evidence, conditions, and alternatives a reader needs. Do not force the machine to combine fragments from a feature grid, tooltip, footer, and separate policy page just to understand the basic proposition.

    • Name the entity in full before relying on abbreviations or pronouns. If two products, locations, plans, or organizations have similar names, state the distinction on the page.
    • Attach qualifiers to the claim they modify. Geography, currency, billing period, eligibility, availability, effective date, tax treatment, shipping limits, and plan restrictions should not be left to implication.
    • Use stable identifiers where your operation already has them, such as a product code, plan name, location identifier, or internal service name. Keep the same identifier across templates, feeds, and structured data.
    • Choose an authoritative home for reusable facts such as the legal organization name, support contact, returns policy, or service-area definition. Other pages should link to or consistently reproduce that truth.
    • Update, redirect, remove, or clearly label stale pages. Two accessible pages that make incompatible claims create an interpretation problem even when only one appears in navigation.
    • Show ownership and maintenance information where it helps a reader judge the claim, such as an author, responsible team, publication date, or last reviewed date. Do not add decorative dates that are unrelated to a substantive review.

    Use JSON-LD to restate and connect meaning that is already visible. Select the most specific appropriate schema type for the resource, such as Organization, Product, Service, Article, or BreadcrumbList. Treat the type as a description of the actual page, not as a keyword target.

    • Make names, URLs, prices, availability, dates, and identifiers agree with the visible content.
    • Give important entities stable @id values and reuse those identifiers when another object refers to the same entity.
    • Connect related objects deliberately. An article’s publisher, a product’s brand, and a service’s provider should resolve to the organization you actually mean.
    • Include only properties you can support and maintain. An empty or guessed field adds ambiguity rather than clarity.
    • Validate syntax after template changes, then inspect the generated object for meaning. Syntactically valid markup can still describe the wrong entity or carry stale values.
    • Do not use structured data to make claims that a person cannot verify on the page. Markup cannot repair inaccessible, contradictory, or inaccurate content, and it does not guarantee inclusion in an AI answer.

    The final check is simple: read the visible page and the JSON-LD side by side. If they would lead a careful reader to different conclusions, the page is not ready.

    Treat agent actions as controlled transactions

    A transaction object passes through guarded verification, review, execution, and confirmation chambers while a duplicate action token is diverted into a holding loop.

    Retrieving a shipping policy is a read. Changing an address, booking an appointment, placing an order, publishing content, or deleting data is a write. Your design should preserve that boundary even when the same assistant handles both parts of the journey.

    Public facts should not require authentication without a business reason. Actions that expose personal data or change state should require an authenticated, authorized user. Do not create a machine-only shortcut around the permission model used by your human interface.

    • Use real links, buttons, and form controls with persistent programmatic names. An icon, color change, or visual position alone is not a dependable instruction.
    • Give every field a label and every validation failure an actionable message. State what is missing or invalid and preserve valid input so the task can continue.
    • Show prerequisites and consequences before submission. Required documents, inventory constraints, cancellation terms, units, time zones, and final charges belong before the committing action.
    • Require review or explicit user confirmation before consequential actions involving payment, publication, deletion, cancellation, or a binding reservation. Automation is not a reason to remove a safety boundary.
    • Make retries safe. If a client repeats a request after a timeout, the system should not silently create duplicate orders, bookings, messages, or records.
    • Return an unambiguous result after submission. The response should state whether the action succeeded, failed, remains pending, or requires another step, along with the relevant record or transaction identifier.
    • Keep errors distinct from success states. A generic page refresh, disappearing modal, or disabled button does not prove what happened.
    • Apply the least privilege needed for the requested task. Scope credentials, sessions, and connected tools so that a narrow action does not grant unrelated access.
    • Log enough context to investigate a failure or duplicate action, while avoiding unnecessary capture of personal data, credentials, or sensitive form contents.

    Test consequential paths in a staging environment or with a non-destructive mode whenever possible. If a production check could charge money, delete data, publish material, or create a real reservation, use an authorized test path rather than discovering the guardrails through a live transaction.

    Measure readiness from fetch to business outcome

    Referral traffic is useful, but it is not a complete AI-search scorecard. A system may use your information without sending a click, while a detected visit may still land on an inaccurate or unusable page. Keep the stages separate so you know which problem you are fixing.

    • Availability: Can a clean client retrieve the preferred page, and are canonical and robots signals aligned?
    • Comprehension: Can the required answer and its qualifiers be extracted from the visible content? Do the structured data and page agree?
    • Representation: Does a fixed set of relevant prompts produce an accurate description, mention, or citation on the AI surfaces you monitor? Record the prompt, surface, location or account context, date, output, and cited URL so later checks are comparable.
    • Referral: Which detectable AI referrals reach the site, where do they land, and do they engage with the intended next step? Treat missing referral data as unknown, not as proof that your content was never used.
    • Outcome: Do those visits or assisted journeys produce the qualified lead, completed task, sale, subscription, support resolution, or other result the page exists to support?

    Create a worksheet with a row for each priority intent. Include the authoritative URL, approved answer, required fields, expected entity, permitted action, passing condition, owner, last test date, observed output, and remediation status. A useful AEO system of record should show where performance is strong and why, not merely accumulate screenshots and isolated visibility scores.

    Establish a baseline before changing templates or access rules. Rerun affected journeys after changes to navigation, rendering, structured data, robots directives, authentication, forms, firewall policy, or core content. Keep the prompt and acceptance criteria fixed when you want a meaningful comparison; create a new test when the underlying intent changes.

    Key takeaways

    • AI-agent readiness has four practical layers: retrieval, interpretation, safe action, and measurement.
    • A passing visual check is not enough. Inspect the response, redirects, canonical, robots directives, rendered content, and required facts.
    • Visible content and JSON-LD must describe the same entity with the same claims, identifiers, and qualifiers.
    • Read access and write access need different controls. Consequential actions require authorization, confirmation, retry protection, and an explicit final state.
    • Measure fixed intents across availability, comprehension, representation, referral, and outcome instead of treating traffic as the whole result.
    • Technical readiness improves eligibility and reduces ambiguity, but it cannot guarantee ranking, citation, recommendation, or agent selection.

    Start with a revenue page, a policy page, and a consequential conversion path. Fetch them logged out, compare their visible facts with their JSON-LD, complete the permitted action in a safe environment, and record every point where the result becomes ambiguous. Fix those failures before expanding the audit across the rest of the site.

    References


  • How to Build Search Visibility for AI Agents and Answers

    How to Build Search Visibility for AI Agents and Answers

    You can rank in conventional search and still be absent when an AI system assembles an answer. The missing piece is often not another keyword. An agent has to reach your content, isolate the relevant passage, connect it to the right entity and decide that the claim is clear enough to reuse.

    Treat that sequence as a visibility pipeline. When you control access, extraction, delivery and measurement separately, you can diagnose why a page is missing instead of making broad content changes and hoping one of them works.

    Key takeaways

    • Set separate policies for model-training crawlers and agents that retrieve information for live answers. Blocking a vendor name broadly can block the function you actually want.
    • Make the core answer understandable in raw HTML, then use semantic sections and accurate structured data to reduce extraction ambiguity.
    • Keep titles, canonicals, essential metadata and critical structured data early in the HTML response. A page that renders correctly in your browser can still present an incomplete document to a crawler.
    • Use pull crawling for durable pages, push discovery for important updates, machine-readable delivery for structured facts and MCP access when an agent genuinely needs current data.
    • Measure bot access, extracted content, citation share and business outcomes as separate signals. Referral traffic alone cannot tell you whether generative visibility improved.

    Build a five-entry visibility pipeline

    Traditional search workflows often compress discovery, indexing and ranking into one mental model. Generative systems add retrieval, passage extraction, entity annotation and answer assembly. Your content can enter that process through five distinct routes.

    Entry routeWhat it doesWhere it fits
    Pull crawlingA crawler discovers and fetches a public URL on its own schedule.Evergreen pages, documentation, category hubs and other durable web content.
    Push discoveryYou notify a participating system that a URL is new or has changed.Pages whose value depends on being discovered soon after publication or revision.
    Push dataMachine-readable facts are delivered directly instead of relying only on page extraction.Structured catalogs, feeds and other data with a defined receiving system.
    MCP accessAn agent requests current information through a Model Context Protocol connection.Data that changes too quickly to be represented reliably by an occasional crawl.
    Ambient entryA system recommends or introduces information without a conventional explicit search query.Brand and entity discovery influenced by consistent, well-annotated information.

    These routes are complementary, not maturity levels. An evergreen explainer usually needs a clean crawl path more than an MCP server. A changing first-party dataset may need a direct machine interface because a cached page can become stale between fetches. Map each important content type to the least complicated route that preserves its accuracy.

    All five routes eventually depend on annotation: the system has to associate a fact with the correct organization, product, person, place or topic. That is why delivery alone is insufficient. Conflicting names, unclear ownership, inconsistent dates or schema that disagrees with visible copy can weaken the content after it has been successfully fetched.

    Separate training permission from live-answer retrieval

    The label AI bot hides several different jobs. The same provider may use one user agent for model training and another for retrieval or search. Current crawler distinctions include separate training, crawling and live-search identities:

    • OpenAI: GPTBot is associated with training, while OAI-SearchBot is associated with search and retrieval.
    • Anthropic: ClaudeBot is associated with training; Claude-User and Claude-SearchBot serve retrieval or search functions.
    • Perplexity: PerplexityBot is the crawler identity, while Perplexity-User is associated with user-driven searching.

    Decide what you want before editing robots.txt. For each user agent, record whether public editorial pages, product information, support documentation and downloadable resources should be accessible. Make the training decision independently from the retrieval decision. A company can decline training access while still choosing to make public pages available to a search-oriented agent.

    A narrowly scoped rule can look like this:

    User-agent: GPTBot
    Allow: /public/
    Disallow: /private/

    Do not use robots.txt to protect confidential information. It is a crawler directive, not an authentication system. Private, customer-specific and administrative content needs server-side access control whether a path is disallowed or not.

    After deployment, inspect server logs by user agent. Confirm that the intended crawler reaches the intended URLs, receives a successful response and can fetch resources needed to interpret the page. A syntactically tidy policy is not evidence that the access path works.

    Use llms.txt as a map, not a dependency

    The emerging llms.txt convention can give agents a concise map of important links, while llms-full.txt can aggregate larger amounts of text into one machine-oriented resource. Adoption is not universal, so neither file should be the only way to discover or understand your content.

    If you publish llms.txt, generate it from the same canonical content inventory used by your sitemap and navigation. Include public, authoritative URLs rather than every filtered, duplicated or campaign-specific variation. Keep the file synchronized when pages move or claims change. It does not override robots.txt, authentication, canonical signals or the content of the page itself.

    Make each page fragment-ready

    A digital page separates into modular content cards while an AI lens selects one card and links it to a network of entities.

    An agent rarely needs every sentence on a long page. It needs a passage that answers the current question without losing essential qualifications. Your job is to make that passage easy to locate and safe to reuse.

    Build each important section in this order: state the answer, name the entity it applies to, add the condition or limitation, then provide the supporting explanation. Put exceptions beside the claim they qualify. If a warning appears several sections later, extraction can separate it from the advice it was meant to constrain.

    • Use a descriptive heading that reflects the question or decision addressed by the section.
    • Answer immediately beneath that heading instead of opening with scene-setting copy.
    • Name the product, organization, method or audience inside the passage. Avoid relying on vague references such as it, they or this solution when the fragment could be retrieved alone.
    • Keep definitions stable. Do not alternate between near-synonyms if they could make one entity look like several unrelated entities.
    • Use lists for steps and criteria, and tables only when rows and columns express a real comparison.
    • Link supporting detail close to the claim it supports rather than collecting all evidence in an unrelated footer.

    Semantic HTML helps establish those boundaries. Use <article> for the primary work, <section> for coherent subtopics and <aside> for genuinely supplementary material. This does not guarantee selection, but it gives crawlers a clearer representation than a page composed entirely of generic containers.

    Structured data should agree with the visible page. Use the schema type that matches the content, identify the same entities named in the copy and omit properties you cannot support on the page. JSON-LD can reduce ambiguity; it cannot repair an unclear claim or turn unsupported markup into trustworthy information.

    Put critical information within the fetched bytes

    Payload order matters when a crawler stops before the document ends. Googlebot fetches up to 2MB for an individual non-PDF URL, with the HTTP response headers included in that limit. When an HTML response exceeds the threshold, the downloaded portion is passed to indexing and the Web Rendering Service as though it were the complete file. Bytes after the cutoff are not fetched, rendered or indexed. PDFs have a higher 64MB limit.

    The Web Rendering Service can fetch referenced resources separately and execute JavaScript like a modern browser, so external scripts and styles do not consume the parent HTML document’s byte allowance. That is a reason to remove oversized inline payloads, not a reason to hide the central answer behind unnecessary client-side execution.

    Do not generalize Google’s exact limits to every AI crawler. Use them as a concrete reminder that a page visible in your browser is not necessarily the same document a bot received or completed.

    • Inspect the raw server response as well as the rendered page.
    • Place the title, canonical link, essential meta tags and critical structured data early in the HTML.
    • Move large CSS and JavaScript payloads into external resources where appropriate.
    • Remove duplicated navigation, serialized application state and other bulky inline material that delays the primary content.
    • Verify that the central answer appears without requiring a click, expansion control or user-specific session.
    • Compare raw and rendered text so you know what depends on JavaScript.

    Response performance belongs in the same audit. When a server cannot deliver resources efficiently, fetchers may slow their activity to avoid adding load, which can reduce crawl frequency. Review latency alongside status and crawl counts instead of interpreting fewer requests as a content-quality judgment.

    Add push paths where freshness changes the answer

    Publishing and waiting remains reasonable for stable content, but it is incomplete when discovery speed or data freshness affects whether an answer is useful. Add proactive delivery in layers, after the public URL and its canonical content are sound.

    1. Preserve the pull foundation. Give every durable page a crawlable canonical URL, sensible internal links and an accurate sitemap entry. Push mechanisms should supplement this foundation.
    2. Notify systems about meaningful URL changes. Bing’s IndexNow can accelerate discovery by telling participating systems that content is new or updated. Treat the notification as an entry signal, not a substitute for a fetchable and interpretable page.
    3. Provide machine-readable data when a receiver supports it. Use a structured feed or direct data connection for facts that should not depend on extracting prose. Define one authoritative source so the feed and public page do not contradict each other.
    4. Use MCP for genuinely current interactions. An MCP connection is justified when an agent needs information that could become stale between crawls. Specify what each tool exposes, which fields are authoritative, how errors are represented and who may call it. Do not create an MCP layer merely to duplicate static editorial pages.
    5. Strengthen the inputs to ambient discovery. Keep names, descriptions and relationships consistent across your first-party content and machine-readable outputs. Ambient recommendations are not a submission box you can force; they depend on whether systems can confidently recognize and contextualize the entity.

    Use a freshness test when choosing the route: if an older value would make the answer materially wrong, evaluate direct data or MCP access. If the information remains accurate until the next normal crawl, keep the architecture simple and focus on extraction quality.

    Centralize the underlying data before adding several delivery methods. Otherwise a page, feed and agent tool can expose three different versions of the same fact. Faster delivery only makes that inconsistency spread sooner.

    Measure access, citations and outcomes separately

    Three parallel visual channels depict content access, citation connections, and human outcomes using abstract gateways, fragments, and symbols.

    A click-only dashboard cannot explain generative visibility. An answer may cite you without sending a visit, retrieve your page without using it or mention your brand while linking elsewhere. A practical GEO technical audit combines citation share, log analysis and zero-click behavior rather than collapsing them into one traffic number.

    • Access: Group server requests by user agent. Record which important URLs were requested, whether they were allowed, how the server responded and whether latency changed.
    • Extraction: Compare the raw response with the rendered page. Confirm that the answer, entity name, qualifications, canonical and structured data are present and mutually consistent.
    • Interpretation: Check whether headings, visible copy, schema and linked canonical resources describe the same entity and claim. Flag conflicting names, dates, ownership or status.
    • Visibility: Maintain a fixed set of representative questions. Citation share is the portion of checked answers that cite your domain or a tracked URL. Record the engine, model, query, cited page and claim so later checks remain interpretable.
    • Outcome: Track identifiable AI referrals and their business actions, but keep citations as a separate measure. No referral does not prove that the system ignored you; the generated answer may have satisfied the user without a click.
    • SEO context: Compare changes in AI visibility with domain metrics, backlink profiles, keyword research and organic-search data. This helps distinguish an agent-access problem from a broader authority, demand or search-performance problem.

    The combination of signals points to the next action. No crawler requests usually directs you toward discovery or access controls. Successful fetching with no usable passage points toward rendering or extraction. Clear extraction with weak citation presence points toward annotation, relevance or authority. More citations without more referrals may reflect zero-click use rather than failure.

    Keep the prompt set and measurement method stable while evaluating a change. If you replace the questions, engines and success definition at the same time, the before-and-after comparison cannot tell you which intervention mattered.

    Start with one content cluster tied to a real business or reputation goal. Verify crawler policy, raw HTML, semantic sections and structured data; then add IndexNow, a structured feed or MCP only where the content’s freshness requires it. Record access and citations before and after the change. Once that evidence chain works, make it part of the publishing workflow for every similar page.

    References