Tag: AI Visibility

  • How to Restart Search Growth in the Age of AI Answers

    How to Restart Search Growth in the Age of AI Answers

    If your search impressions still look healthy while organic clicks and conversions have flattened, publishing more content may deepen the problem. AI answers have changed which searches produce a visit, but they have not removed the need for useful pages, credible evidence, or clear decisions.

    You need to find the exact layer where growth is breaking: discovery, answer visibility, click capture, on-page usefulness, or conversion. Once you separate those layers, you can stop treating every plateau as a rankings problem and make the change that the evidence supports.

    Reset what search growth means

    The familiar organic growth model is simple: rank for more queries, earn more clicks, and turn those visits into outcomes. AI-generated answers insert another possible stopping point. A search engine may resolve a narrow question on the results page, while a person with a more involved problem still needs to visit a website.

    Google’s stated view is that AI Overviews can filter low-value, single-fact visits while prompting people to search more frequently and in greater detail. That is a platform position, not proof that every publisher benefits. A lost click is still a lost opportunity unless the search creates some other measurable value for your brand.

    The practical change is to stop using total organic sessions as the only definition of growth. Evaluate four different outcomes:

    • Discovery: your pages appear for the questions and problems that matter to your audience.
    • Answer visibility: your brand, explanation, product, data, or page is represented when an AI answer is shown.
    • Qualified visits: people click because they need depth, proof, a tool, a comparison, or a next step that the results page cannot provide.
    • Business outcomes: those visits lead to the action the page was built to support, such as a signup, inquiry, purchase, or informed move to another page.

    This does not make clicks unimportant. A page does not become valuable merely because an AI system might summarize it. It means a click-through rate decline has more than one possible cause, and you should identify that cause before rewriting titles or adding pages.

    Start by labeling your important queries by the job they perform. A closed-answer query asks for a fact or definition. An exploration query helps someone understand a problem. A decision query compares options or constraints. An action query looks for a product, service, process, or implementation path. Closed answers are more exposed to instant resolution. Exploration, decision, and action queries give you more room to earn a meaningful visit, provided the page does more than restate a generic answer.

    Build a query map around complete problems
    An overhead strategy table shows blank tiles and glowing connections arranged around a three-dimensional problem-solving scene.

    AI-assisted search encourages people to express more of their situation in the query. Instead of reducing every topic to a short keyword, users can include their goal, constraints, experience level, and desired format. Google has observed longer, more conversational searches that describe the underlying need more clearly.

    Your keyword map should preserve that context. A broad term such as “schema markup” identifies a subject. A question such as “which schema should a service-area business use when it has no public storefront?” identifies a decision, a constraint, and the evidence the answer must contain. The second query is easier to turn into a useful content brief because it reveals what could make an answer wrong.

    Build each topic cluster from real language found in search performance data, site search, customer questions, sales conversations, support requests, and community discussions available to your team. For every meaningful query or prompt, record:

    • The exact question, including qualifiers rather than a cleaned-up head term.
    • The user’s likely stage: learning, evaluating, validating, or acting.
    • The constraint that changes the answer, such as business type, location, platform, audience, or implementation state.
    • The decision the person needs to make after receiving the answer.
    • The evidence or experience required to make the answer credible.
    • The page and section that should satisfy the need.
    • The next useful action you want the visitor to take.

    Do not turn every wording variation into a separate page. If several prompts have the same intent, require the same evidence, and lead to the same decision, they usually belong on one well-structured page. Split them only when the constraint materially changes the answer or when each audience needs a distinct path.

    Then inspect the live result for your priority prompts in a consistent setup. Record the exact query, search surface, date, location context, whether an AI answer appeared, which domains were cited, which brands were mentioned, and what conventional results remained visible. AI Overviews are not activated for every query, so testing a few broad keywords cannot tell you how an entire topic behaves.

    Treat this prompt set as a stable observation panel. Reuse the same important prompts when you review visibility, and add new ones only when customer language or search data reveals a genuinely different need. That gives you a comparable record instead of a collection of one-off screenshots.

    Make the page valuable after the instant answer

    The right response to AI answers is not to hide the answer deeper in the page. Give the reader a direct answer, then provide the judgment, evidence, and implementation help that a short synthesis cannot carry.

    A useful page can be built in layers:

    1. Answer the core question in plain language near the beginning.
    2. Name the conditions that would change the answer. This prevents an accurate general rule from becoming bad advice in a specific case.
    3. Explain the decision logic so the reader can apply the answer rather than merely repeat it.
    4. Provide evidence or utility that is difficult to replace with a generic synthesis: an original example, a documented process, a worked configuration, a template, a calculator, a comparison framework, or first-party data you genuinely possess.
    5. Offer the next action that fits the reader’s stage instead of forcing every visitor toward the same conversion.

    Use a replacement test during editing: if a generic answer box can reproduce the entire value of the page, the page is not finished. Add the constraint, evidence, or usable asset that a person needs after learning the basic answer. Do not add length for its own sake. More words do not create more value when they repeat the same conclusion.

    Machine readability matters, but it cannot rescue an undifferentiated page. Use descriptive headings, stable terminology, explicit relationships between entities, and internal links whose anchor text explains the destination. If you add JSON-LD, choose a valid type that accurately represents the page, keep names and other entity details consistent with visible content, and update the markup when the page changes. Structured data is a machine-readable description, not a relevance generator or a guarantee of inclusion in an AI answer.

    Credibility also has to be inspectable. Identify who created or reviewed the material when that identity helps the reader judge expertise. Link claims to the evidence you actually used. Distinguish observed results from editorial recommendations. Display a date when freshness affects the answer, not as decoration. Remove unsupported ratings, fabricated experience, and schema properties that are absent from the visible page.

    Mass-producing near-duplicate pages is especially weak in this environment. Google’s stated position is that generative AI has increased the volume of low-quality material while its ranking systems continue trying to suppress it. Whether those systems succeed in every result is a separate question. Your controllable advantage is to publish material that has a clear reason to exist: a different decision, better evidence, a useful tool, or a perspective grounded in real expertise.

    Diagnose the stalled layer before choosing a fix
    A technician examines a blockage inside one chamber of a transparent multi-stage pathway carrying streams of light.

    When organic search growth stalls, asking what to publish next is premature. First determine which part of the system stopped moving. Rankings, result-page behavior, content usefulness, conversion, and measurement can produce similar top-line charts while requiring completely different fixes.

    1. Validate the measurement. Confirm that analytics events, search reporting, consent behavior, and conversion definitions have not changed. A tracking break should not become an SEO project.
    2. Check technical access. Review indexing, robots directives, canonicals, redirects, rendering, internal links, and template changes on the affected pages.
    3. Segment the change. Break performance down by query group, page type, intent, device context, market, and brand versus non-brand demand where those dimensions are available. A sitewide total can hide a concentrated loss.
    4. Separate impressions from clicks. Falling impressions point you toward demand, coverage, indexing, or competitive visibility. Stable impressions with falling clicks point you toward the result-page environment, snippet appeal, or changed intent.
    5. Separate visits from outcomes. If qualified traffic is steady but conversions fall, inspect message alignment, page usability, the offer, and event tracking before changing the query strategy.
    6. Inspect representative results. Look for AI Overviews and other result features, note which needs they satisfy, and compare the remaining clickable results. Do this for the query groups that matter rather than whichever examples are easiest to find.

    Use the observed pattern to choose the first test:

    Observed signalStart by testingFirst useful action
    Impressions decline across established query groupsDemand, indexing, coverage, or competitive visibilityVerify technical access, then compare the affected queries and pages instead of rewriting every snippet.
    Impressions hold while clicks declineResult-page changes, instant answers, intent, or snippet appealInspect the live results, classify the lost queries, and strengthen both the search snippet and the page’s beyond-the-answer value.
    Visits hold while outcomes declineTracking, landing-page alignment, usability, or offer fitValidate events and compare each landing page with the promise and intent of its incoming queries.
    Important customer questions have no relevant visibilityContent coverage or insufficient evidenceRevise the best existing page or create a focused resource only when the question requires a materially different answer.

    Maintain a scorecard that matches those layers. Search performance data can show impressions, clicks, click-through rate, queries, and landing pages. A prompt observation log can show sampled AI-answer presence, citations, mentions, and competing domains. On-site analytics can show whether visitors continue to a useful next step or return. Business systems can show qualified inquiries, purchases, signups, or other outcomes where attribution is available.

    Keep the limits of each measure visible. Click-through rate without result-page context can mislead you. A brand mention without a citation may not create a visit. A citation may appear for a low-value prompt. A hand-checked prompt panel is a sample, not a complete census of AI visibility. Report the measures together so one flattering metric cannot conceal a broken path.

    Key takeaways for your next growth cycle

    • Classify important queries by the job they perform before assuming every lost click has equal value.
    • Map conversational prompts with their goals, constraints, required evidence, and next decisions intact.
    • Answer the core question early, then earn the visit with decision support, credible evidence, or practical utility.
    • Use valid, visible-content-aligned structured data to clarify meaning, not as a shortcut to rankings or AI inclusion.
    • Diagnose discovery, click capture, page usefulness, and conversion separately before choosing an intervention.
    • Measure search performance, sampled AI visibility, visit quality, and business outcomes in the same scorecard.

    Start with the query cluster most closely tied to a real audience decision. Record its current result environment, repair the page that should own the problem, and define the outcome you expect before making the change. Your next growth move should come from the failed layer you can see, not from a general fear that AI has made search traffic impossible.

    References


  • How to Earn Accurate AI Citations and Protect Brand Trust

    How to Earn Accurate AI Citations and Protect Brand Trust

    An AI answer can cite your website and still get your product wrong. It can also describe your brand accurately while sending the reader somewhere else. If your reporting treats both outcomes as a visibility problem, you won’t know what to fix.

    You need to evaluate three things separately: whether your brand was selected, whether the cited evidence supports the generated claim, and whether a person would trust the answer enough to act. This framework helps you diagnose each layer without mistaking citation volume for accuracy or brand authority.

    Key takeaways

    • A citation proves that a page was selected as a reference. It does not prove that the generated sentence is accurate, complete, current, or supported by that page.
    • Audit the relationship between each claim and its citation. Counting links or brand mentions alone hides the errors most likely to damage trust.
    • Segment testing by platform, query language, market, intent, and phrasing. A blended visibility score can conceal serious gaps in a priority language or buying journey.
    • Maintain a canonical claim layer with explicit evidence, scope, market, and update information. Align your visible content and JSON-LD with that same version of the truth.
    • Earn independent confirmation by helping people in the communities and channels where decisions are verified. Repetition from your own properties is not the same as corroboration.

    A citation proves selection, not accuracy

    Grounding means connecting a generated answer to external evidence. It can reduce unsupported generation, but it does not turn every cited sentence into a verified fact. Retrieval can surface a relevant page while the model overgeneralizes its wording, misses a qualifier, combines incompatible details, or attaches the citation to a broader claim than the page supports.

    Suppose an answer says a company provides same-day support in every market. Its citation leads to a support page that promises that service only to selected customers in one region. The link is real and topically relevant, but the generated claim is still wrong. A dashboard that records only citation presence would count that outcome as a success.

    That is why an AI visibility audit needs four separate tests:

    LayerQuestion to askCommon false conclusionWhat to inspect
    Citation presenceWas your brand or page selected?Being cited means being represented correctly.The cited URL, its position, the surrounding answer, and competing domains.
    Claim supportDoes the cited passage support the exact generated claim?A relevant page is sufficient evidence.Wording, scope, qualifiers, dates, markets, exceptions, and the cited passage itself.
    Entity accuracyAre the brand, product, policy, location, and relationships correct?A fluent description must be reliable.Names, attributes, availability, ownership, pricing claims, and product-to-brand relationships.
    User trustWould a reasonable reader accept and act on the answer?Exposure automatically creates confidence.Independent corroboration, transparency, review quality, community sentiment, and unresolved contradictions.

    The practical unit of analysis is the claim-citation pair. Break an answer into factual claims, then open the citation attached to each one. Grade the pair as supported, partially supported, unsupported, or contradicted. Use a separate label when no citation is provided.

    Partial support deserves its own category. It often reveals the most important content problem: your page contains the right concept but leaves enough ambiguity for the model to enlarge its scope. A statement that is correct for one plan, country, customer type, or time period needs that qualifier in the same sentence as the claim. Do not leave the limitation in a footnote, accordion, or unrelated section and expect retrieval to preserve it.

    Accuracy and trust also need different owners. A content or product team may be able to correct an outdated policy page. Public relations or community teams may need to address persistent third-party confusion. Technical SEO can improve entity consistency and structured data, but it cannot manufacture independent belief. Your audit should route each failure to the team that can change its underlying cause.

    Query language can change who gets cited

    A glowing inquiry passes through a prism and branches toward three different source documents, with each path representing a different citation outcome.

    You cannot infer global AI visibility from English-language testing. In one large cross-platform analysis, 3.25 billion citations across seven AI models and 14 countries showed query language as the main catalyst changing citation rates. Google AI Overviews and ChatGPT also displayed different response patterns for non-English prompts. That finding should be treated as a strong warning about aggregation, not as a universal rule for every query or brand.

    Language changes more than the words in the prompt. It can change the pool of retrievable pages, the entities a model recognizes, the regional sources available to support an answer, and the way a user expresses intent. A literal translation of an English prompt may therefore test translation quality rather than the search behavior of a person in that market.

    Build your prompt set from real decisions instead of a list of brand keywords. Include the questions people ask when they are discovering a category, comparing options, checking a claim, assessing risk, resolving a problem, and preparing to buy. Then vary the constraints that matter to the decision: location, use case, customer type, compatibility, availability, policy, or another relevant condition.

    Use a segmented test matrix

    For every prompt, record the exact wording and the conditions under which the answer appeared. At minimum, preserve:

    • The user’s underlying intent and the decision the answer is meant to support.
    • The exact prompt, including follow-up questions and any constraints introduced earlier in the conversation.
    • The query language and intended market. Keep them separate because a language can span several markets, and a market can contain several languages.
    • The AI platform or search surface. Do not merge ChatGPT results with Google AI Overviews or another system under a single generic AI ranking.
    • The date of capture and any visible model or product label, so later retests can be compared with the right context.
    • Whether the session was signed in, personalized, location-aware, or part of an existing conversation.
    • The complete answer, every citation URL, and the passage that supports or fails to support each material claim.

    Have a fluent local speaker or market specialist adapt important prompts. Ask how a real customer would phrase the problem, what local terminology they would use, and which proof they would expect. The localized prompt should preserve the intent, not the English syntax.

    Report results by language and platform before calculating any overall figure. If your brand performs well in English but disappears or becomes inaccurate in another priority language, an average can make the program look healthy while the affected market sees a different brand. The segment is the truth; the blended number is only a summary.

    Build a truth layer that models and people can verify

    A central knowledge core sends consistent product and policy information to web pages, documents, an AI system, and a human reviewer.

    The safest way to improve citation accuracy is to make consequential claims easy to retrieve, hard to misread, and consistent across the properties you control. That work begins before schema markup. A perfectly marked-up contradiction is still a contradiction.

    Create a canonical claim ledger

    Maintain a working record of the claims that affect whether someone chooses, trusts, or rejects your brand. Each record should contain the entity, approved wording, supporting URL, evidence, scope, exceptions, applicable language and market, content owner, review date, and current status.

    Prioritize claims about what a product does, who it is for, where it is available, what it costs, what is included, what it integrates with, and what policies govern its use. These are the statements most likely to change a decision. They are also vulnerable to drift when product pages, help documentation, sales copy, partner listings, and old announcements describe different versions of reality.

    Give each consequential claim a clear canonical home. The page should state the fact directly, place its qualifier beside it, explain the evidence, identify the applicable product or market, and make the update status visible. If the answer differs by plan or region, present those differences as structured comparisons rather than scattering them across several pages.

    Review conflicting owned pages before publishing more content. A new explainer cannot establish clarity while an old pricing page, support document, or local site still makes the opposite claim. Correct, redirect, archive, or clearly date obsolete material according to its purpose. If an older page must remain accessible, label its historical status where a person and a retrieval system can encounter it.

    Use JSON-LD as a consistency layer

    JSON-LD can clarify entities, properties, and relationships. It cannot supply evidence that the visible page lacks, resolve disagreement between departments, or make an exaggerated claim trustworthy. Treat structured data as a machine-readable expression of the same facts a reader can verify on the page.

    • Use the schema type that accurately describes the visible entity or content, such as Organization, Person, Product, or Article where appropriate.
    • Keep names, canonical URLs, identifiers, brand relationships, and other entity attributes consistent with the page and your canonical claim ledger.
    • Do not place a material claim only in markup. If it matters enough to encode, it should be supported in the visible content.
    • Match market- and language-specific markup to the corresponding page. Do not attach a global claim to content that supports only one region.
    • Update structured data when the underlying fact changes. A stale JSON-LD property can preserve the contradiction you just removed from the copy.
    • Validate syntax and then inspect meaning. Technically valid markup can still identify the wrong entity or express an unsupported relationship.

    This approach gives you one controlled path from approved fact to human-readable evidence to structured representation. It also makes corrections easier: when an AI answer exposes a problem, you can trace the claim to its owner and every place where it appears.

    Earn confirmation outside your own website

    People rarely make an important decision inside one answer box. The search journey can move through AI tools, marketplaces, reviews, forums, video, friends, and knowledgeable people as the user looks for stronger confirmation. Yext reported that 75% of consumers were using more platforms than a year earlier, while only 10% trusted the first result.

    That behavior reflects three judgments: whether people trust themselves to evaluate the subject, whether they trust the platform presenting the answer, and whether they trust the underlying information source. Your citation work can improve the last layer, but brand trust also depends on what people encounter when they leave the generated answer to verify it.

    Independent confirmation cannot be produced by repeating the same marketing claim across more company profiles. It comes from useful participation in places where people exchange experience: practitioner communities, customer conversations, events, forums, reviews, social channels, and expert-led media. The operating rule is simple: listen for the unresolved question, help with that question, and let the brand mention remain secondary to the answer.

    • Track recurring questions, objections, misconceptions, and vocabulary in the communities relevant to your buyers.
    • Answer with specific, verifiable information. Link to documentation when it genuinely helps rather than treating every interaction as a distribution opportunity.
    • Turn recurring questions into durable resources on your own site, then keep those resources aligned with the conversations that inspired them.
    • Make it easy for customers, partners, practitioners, and journalists to verify factual details without copying promotional language.
    • Correct errors openly and precisely. State which claim is wrong, what the accurate scope is, and where the supporting information lives.
    • Never manufacture reviews, personas, community conversations, or supposed independent consensus. Discovery gained through deception creates the exact trust problem the program is meant to solve.

    The goal is not to control every mention. It is to make the accurate account easier for other people to confirm and repeat in their own words. That creates a healthier evidence environment than a large collection of identical brand-authored claims.

    Audit the failure pattern before choosing the fix

    A useful AI citation audit should reproduce an answer, isolate the error, identify the controllable cause, and verify the correction. Screenshots of favorable mentions are not enough.

    1. Define the decision. Start with prompts tied to meaningful user actions or material brand risk. Record what a correct answer must help the user understand.
    2. Capture the full context. Save the exact prompt sequence, language, market, platform, date, answer, citations, and visible session conditions.
    3. Split the answer into claims. Separate factual statements from recommendations, opinions, and connective language. Mark the claims that could change a purchase, eligibility, support, compliance, or reputation decision.
    4. Check every citation. Open the linked page, locate the supporting passage, and grade the relationship as supported, partially supported, unsupported, contradicted, or uncited.
    5. Check the entity. Verify names, product relationships, attributes, locations, policies, availability, and other details against the canonical claim ledger.
    6. Trace the likely cause. Look for unclear wording, missing qualifiers, stale owned pages, inconsistent markup, weak localized evidence, entity ambiguity, or repeated third-party misinformation.
    7. Fix the highest-consequence origin. Correct the canonical page and contradictory owned properties first. Then update structured data, partner records, listings, and other controllable representations. Seek corrections from external publishers or platforms where an appropriate process exists.
    8. Retest the original conditions. Use the same prompt and context, then test natural variants. A changed answer may indicate improvement, but it does not prove that every platform, language, or user will now receive the same result.

    Measure accuracy and trust separately from reach

    Your reporting should preserve the distinction between being visible and being represented well. Useful measures include:

    • Citation presence: how often your brand, canonical pages, or relevant independent pages appear for eligible prompts.
    • Claim support rate: how often cited passages fully support the claims attached to them. Keep partial support visible instead of counting it as success.
    • Brand claim accuracy: how often material statements about your entity match the approved facts and their qualifications.
    • Uncited material claim rate: how often consequential factual statements appear without a reference a reviewer can inspect.
    • Cross-platform consistency: whether different AI surfaces agree on the material facts, not whether they use identical wording.
    • Language and market gap: the difference in citation presence, support, and accuracy between priority segments.
    • Independent confirmation: whether the answer’s important claims can be verified through credible, non-owned evidence where independent evidence should exist.
    • Correction latency: how long your organization takes to correct the controlled origin of a material error and complete the relevant retest.

    Avoid setting a citation target without a support target. A campaign can increase the number of citations while also increasing the number of confidently misstated claims. That is not improved visibility; it is wider distribution of an accuracy problem.

    Let the pattern determine the intervention

    • High citation presence, low claim support: clarify the canonical content, move qualifiers beside their claims, remove contradictions, and inspect why irrelevant passages are being treated as evidence.
    • Low citation presence, high brand accuracy: improve retrievability, entity clarity, localized coverage, content distribution, and credible external confirmation without rewriting already-clear facts for novelty.
    • High accuracy, low user trust: examine reviews, community sentiment, transparency, proof quality, and what a person encounters after clicking. More owned content may not solve this failure.
    • Strong English results, weak priority-language results: build native-language evidence and entity consistency for that market. Do not rely on literal translation or a global average.
    • Conflicting answers across platforms: preserve the platform split in reporting, inspect each citation pool, and fix shared contradictions before chasing platform-specific tactics.
    • A material uncited error: treat the incorrect claim as the incident, even if the rest of the answer is favorable. Prioritize errors that change cost, availability, eligibility, obligations, safety, or a buyer’s ability to make an informed choice.

    Start with the decision-heavy query where a wrong answer would cost the most trust. Test it in your primary language and the highest-priority additional language, grade every claim-citation pair, and correct the most consequential contradiction you control. Do that before pursuing a larger citation count. The citation is not the finish line; an accurate, verifiable, and trusted answer is.

    References


  • Yelp AI-Assisted Bookings: A Local Optimization Playbook

    Yelp AI-Assisted Bookings: A Local Optimization Playbook

    If your Yelp profile gets seen but still produces too few bookings, the problem may no longer be simple visibility. A customer can now ask a detailed question, compare the suggested businesses, and act without following the familiar path from search result to website.

    Your job is to make that compressed journey work. Yelp needs clear business facts, customers need credible evidence of fit, and the booking or ordering connection needs to survive the handoff. A weakness in any one of those layers can turn a recommendation into an abandoned transaction.

    Optimize the decision, not just the listing

    Traditional local SEO often treats discovery and conversion as separate stages. You rank or appear in a marketplace, earn a click, and then persuade the visitor on your own site. Yelp Assistant narrows that distance because it can answer complex questions, recommend businesses, explain why a business fits, refine the results conversationally, and continue into supported booking, ordering, or quote flows.

    That changes the optimization target. A conversational local request usually contains several constraints at once: the service, location, occasion, timing, preferences, and desired next step. A profile can be relevant to the broad category while failing to resolve one of those constraints. The customer may never reach your website to investigate further.

    Audit your Yelp presence against four questions:

    • What does the business actually provide? Categories, service names, menu items, and descriptive copy should agree about your core offer.
    • Who or what situation is it suitable for? Include meaningful distinctions customers use when choosing, but only where they are accurate and supported by your operation.
    • Why should the customer believe the fit? Reviews and photos should give the customer evidence, not merely repeat promotional claims.
    • What can the customer do next? The appropriate reservation, appointment, quote, or ordering action should be visible, current, and connected to a working destination.

    Build the audit from real customer language. Collect the questions that appear in calls, messages, quote requests, appointment notes, and reviews. Group them by intent, then check whether a person could answer each one from the information visible in Yelp. If the answer depends on an assumption or an old photo, you have found a content gap.

    Correct the underlying field wherever possible. Put hours in the hours field, services in the relevant service area, menu information in the menu, and the primary transaction in the appropriate action. Descriptive copy can clarify the offer, but it should not become a container for disconnected phrases. Treat this as an answerability audit, not as a claim that repeating keywords will influence Yelp’s selection logic.

    Your website still matters, including its LocalBusiness structured data. Keep the name, address, telephone number, URL, hours, and applicable business subtype aligned with the facts you publish elsewhere. Use a sameAs link when it accurately identifies your Yelp profile. That consistency helps search systems understand the same entity, but JSON-LD on your website cannot repair stale Yelp information or reconnect a broken booking calendar.

    Close every gap between recommendation and transaction

    A recommendation is not the conversion. The final action may depend on Yelp, your profile configuration, a scheduling or delivery partner, inventory or calendar data, and the confirmation experience. Every connection can look present while still sending the customer to the wrong service, location, or availability view.

    Yelp has expanded integrations involving Vagaro, Zocdoc, and Calendly across areas such as beauty, healthcare, and home services, alongside delivery support involving DoorDash. The practical implication is not that every business automatically receives every transaction type. It is that a connected marketplace profile and the external system behind it must be managed as one customer journey.

    Test the journey in the environment where customers encounter it:

    1. Open the Yelp profile on a supported mobile experience and identify the primary action presented to a customer.
    2. Confirm that the action matches the intent you want to win. A restaurant reservation, food order, healthcare appointment, service appointment, and home-service quote are not interchangeable conversions.
    3. Follow the action into the connected system. Verify the business name, location, selected service, availability, and contact information at each step.
    4. Continue to the final confirmation screen, but do not consume a real appointment or reservation unless your operation has a safe test procedure.
    5. Check the resulting confirmation or lead record. It should give both the customer and your staff enough information to fulfil the request without another round of clarification.

    Test more than the happy path. Try a service that has limited availability, a different location if you operate more than one, and a request that should become a quote rather than an instant booking. The purpose is to find mismatches between what the profile promises and what the connected system can actually accept.

    Assign ownership for each layer. The person updating the Yelp profile may not control the scheduling platform, menu, delivery availability, or service calendar. Record who owns each one and where changes originate. Otherwise, a corrected profile can be overwritten by old partner data, or the profile can continue advertising an option that operations no longer fulfils.

    The initial feature availability was described as mobile-first on iOS and Android, with broader category and desktop expansion planned. Rollout scope can differ by experience, so verify what customers can actually see instead of assuming that an announcement describes every account, category, or device.

    Give the assistant evidence it can explain

    An abstract AI lens gathers visual details about a restaurant's amenities, service, atmosphere, and customer evidence to guide a recommendation.

    Yelp Assistant draws on Yelp’s reviews and photos to tailor recommendations and explain why a business may be a good match. That makes customer-generated evidence part of the conversion surface. Your description can state that you provide a service; reviews and photos can show what receiving it is like.

    Do not translate that into a campaign for generic praise. Broad comments such as great service reveal little about the specific situations in which the business succeeds. Honest reviews are more useful when customers naturally mention the service received, the type of need, the location, and the experience. Any request for feedback should remain neutral and comply with the platform’s current policies.

    Use reviews as an operating dataset, not as copy you control:

    • Identify recurring service names and customer questions. Check whether your profile uses the same clear, accurate terminology.
    • Notice repeated misunderstandings. If customers arrive expecting an option you do not provide, correct the promise in your profile or connected flow.
    • Look for evidence gaps. A service may be listed but rarely described or photographed, leaving a customer with little basis for choosing it.
    • Respond to factual confusion calmly. Clarify the business detail that matters, then fix the underlying listing or operational issue when you control it.

    Photos need a similar job-based audit. Cover the decision points a new customer cannot infer: what the exterior looks like on arrival, what the relevant space or service looks like, what is actually delivered, and how distinct options differ. Accuracy matters more than decorative volume. An attractive image that no longer represents the current offer can create a stronger expectation mismatch than having no image at all.

    Restaurants have an additional surface to watch. Yelp’s revised Menu Vision can place dish information, reviews, and photos into visual overlays while a customer browses a menu. Menu item names, current availability, and corresponding images therefore need to describe the same dish. Remove or update obsolete material wherever your listing or connected system gives you control; do not let a retired item become the evidence for a current order.

    The same principle applies outside restaurants. A salon service name, healthcare appointment type, contractor quote category, and the evidence surrounding each one should remain consistent from recommendation through confirmation. The assistant can shorten the journey, but it cannot reconcile a profile, photograph, review pattern, and booking system that tell different stories.

    Measure the compressed funnel with transaction outcomes

    If a customer can complete more of the journey inside Yelp or a connected partner flow, website traffic alone becomes an incomplete scorecard. Flat website sessions do not prove that local visibility is stagnant, and more profile activity does not prove that qualified business increased.

    Choose the completed outcome that matches the action:

    • For restaurants, distinguish completed reservations or orders from action taps.
    • For appointment businesses, track booked appointments separately from completed appointments and cancellations.
    • For home services, separate raw quote requests from requests that fit the service area and become qualified opportunities.
    • For delivery, distinguish an ordering action from a completed order that the business successfully fulfils.

    Use the reporting fields available in Yelp and the connected platform, and keep definitions stable. If a partner exposes an origin label or channel field, preserve it through your export or customer-management workflow. If it does not, do not manufacture precise attribution from incomplete data. Record the limitation and compare only metrics that are defined consistently.

    Read funnel patterns as diagnostic clues, not proof of a single cause. If profile visibility rises while actions stay flat, start by checking whether the listing resolves fit and presents a clear next step. If actions rise while completed transactions do not, inspect the partner handoff, availability, eligibility rules, and confirmation flow. If transactions rise but cancellations, no-shows, or poor-fit requests also rise, compare the promise in Yelp with what the customer can actually book.

    Keep a change log alongside those measures. Record which profile fact, image set, menu item, service name, or transaction connection changed and when. Without that record, several simultaneous edits can make an improvement impossible to interpret and a regression hard to reverse.

    Key takeaways

    • Optimize for the customer’s complete decision, not for a broad category phrase in isolation.
    • Keep business facts, customer evidence, and the connected transaction system consistent.
    • Test booking, ordering, appointment, and quote paths from Yelp through confirmation.
    • Use reviews and photos to find unanswered questions and expectation mismatches; do not treat them as keyword containers.
    • Measure completed business outcomes because an in-platform transaction may never appear as a website visit.
    • Use website schema to reinforce accurate entity information, not as a substitute for maintaining the Yelp profile itself.

    Run the audit around one valuable customer intent

    A business owner examines a visual pathway from customer intent through recommendation, comparison, scheduling, payment, and booking confirmation.

    A full profile overhaul can hide the problem you need to solve. Start with one commercially meaningful intent: the reservation type, appointment, service request, or order you most need Yelp to support.

    1. Write the exact questions and constraints a suitable customer brings to that intent.
    2. Mark where each answer lives: profile field, service or menu information, review evidence, photo, booking system, or confirmation.
    3. Correct contradictions and remove unsupported promises before adding more copy.
    4. Test the transaction path on the customer-facing experience available to your category.
    5. Record the current funnel outcomes, the change made, and the operational owner responsible for keeping it accurate.
    6. Recheck the path whenever hours, services, locations, menus, calendars, or integration settings change.

    The businesses best prepared for AI-assisted local bookings will not necessarily be those with the longest descriptions. They will be the ones whose facts answer the question, whose evidence supports the choice, and whose transaction path does exactly what the recommendation promised. Pick the path tied most closely to revenue or qualified demand, and make that one dependable first.

    References


  • AI Search Visibility: An SEO Plan for Zero-Click Results

    AI Search Visibility: An SEO Plan for Zero-Click Results

    Your ranking report looks healthy, but organic visits are slipping. That gap does not automatically mean your SEO has failed. It can mean that more of the search journey is happening inside an AI answer, featured result, or search-results page before a visitor reaches your site.

    Zero-click behavior also predates generative search. Rand Fishkin traces its emergence to around 2011, estimates that nearly half of searches ended without a click by 2016-2017, and puts the current share above two-thirds. Those estimates should not become a universal benchmark for your reporting, but the direction is clear: you need to measure whether your brand influenced the answer, not only whether your page received the visit.

    Replace the traffic funnel with a visibility ladder

    Traditional SEO reporting often jumps from ranking to session to conversion. AI search introduces several observable outcomes between ranking and session. If you skip them, every answer that satisfies a user without a click looks like failure, while every low-quality visit looks more valuable than it really is.

    Use a visibility ladder instead:

    • Retrievability: The page can be found, crawled, understood, and associated with the relevant question.
    • Answer inclusion: Your information, page, or brand appears in an AI answer, AI Overview, featured result, or other search feature.
    • Attribution: The answer names your brand, cites your page, or provides a link. These are different outcomes and should be recorded separately.
    • Recognition: Searchers repeatedly encounter your brand in connection with the subject, even when they do not leave the results page.
    • Engagement: Some searchers click, return directly, subscribe, or continue into another measurable interaction.
    • Business impact: The interaction contributes to a qualified lead, sale, subscription, renewal, or another outcome your organization actually values.

    A mention is not a conversion, and a citation is not revenue. They are upstream signals. Keeping the stages separate prevents you from assigning invented financial value to an AI appearance while still acknowledging that search visibility can exist without a session.

    Visibility layerWhat to recordWhat it helps you decide
    Answer exposurePresence in AI answers, AI Overviews, featured snippets, and other answer surfacesWhether your content is entering the visible answer set
    AttributionBrand mentions, citations, links, cited URLs, and the context surrounding the mentionWhether the platform connects the information to you
    Site engagementSearch impressions, click-through rate, AI referral visits, deep-link landings, and useful on-site actionsWhether the visible answer creates a reason to continue
    Brand demandBranded searches, direct visits, returning visitors, subscriptions, and preferred-source selection where availableWhether repeated exposure is becoming intentional demand
    Business outcomeQualified leads, purchases, subscriptions, renewals, or another agreed conversionWhether the search program contributes to the organization

    Do not collapse these measures into a single visibility score unless every weight has a defensible business meaning. A composite score can rise because mentions increased while qualified visits disappeared. A stage-by-stage dashboard makes that tradeoff visible.

    Publish an answer that earns visibility and a page worth visiting

    A concise content module moves from a larger web page into an abstract AI answer panel beside a richer page with supporting material and exploration paths.

    The wrong response to zero-click search is to conceal the answer and force the user to hunt for it. That weakens the page for the person who does visit and makes its central purpose harder to identify. The stronger model has two layers: an answer layer that can stand on its own and a continuation layer that helps the reader make a decision or complete a task.

    Layer one: make the direct answer unambiguous

    Start the relevant section with the conclusion, definition, instruction, or status the query requires. Name the subject explicitly. State important scope conditions beside the claim instead of hiding them in a distant caveat. A reader and an answer system should not need to combine several vague paragraphs to work out what you mean.

    This is the practical value of utility content: service-oriented explanations, checklists, FAQs, and comprehensive guides answer immediate audience questions in a simple form. Simple does not mean thin. A short answer can be clear while the rest of the page handles exceptions, evidence, consequences, and application.

    • Use a heading that matches the real question rather than a clever label that needs interpretation.
    • Put the answer immediately beneath that heading.
    • Identify the product, platform, location, audience, or version whenever the answer depends on it.
    • Keep names and terminology consistent across the title, headings, copy, internal links, metadata, and structured data.
    • Separate facts from recommendations. Readers should be able to tell what is documented, what is conditional, and what you advise them to do.
    • Correct or update the visible passage when the underlying fact changes; changing only a date or schema field does not repair stale content.

    Layer two: give the reader a reason to continue

    An answer surface can usually absorb a definition, a short explanation, or a basic checklist. It is less able to replace the work that comes after the answer. That is where your page should become more useful.

    • Decision support: Explain the criteria, tradeoffs, exceptions, and consequences that change the choice.
    • Application: Show how the answer changes for distinct situations instead of repeating the same generic advice.
    • Original value: Add evidence, examples, tools, templates, calculations, or analysis that cannot be reproduced accurately from a short summary alone.
    • Execution: Turn the answer into a sequence the reader can follow, including what to inspect and what a failed check means.
    • Maintenance: State what can change, then update the page when that trigger occurs.

    Do not add length merely to manufacture a click. A long generic page gives an AI system more interchangeable language without giving the reader more value. The continuation layer should resolve uncertainty that remains after the top-line answer.

    This also changes how you manage evergreen content. Keep a working inventory of the questions each page owns. Watch the events that could invalidate an answer. Refresh the relevant explainer when the facts change, create content only where a genuine question remains uncovered, and consolidate overlapping pages into a maintained topic library. Recirculate the useful resource when demand returns. Evergreen should describe the question, not an assumption that the answer never needs attention.

    Make important passages reachable as well as readable

    Passage-level visibility matters when a search result sends the reader to a specific section rather than the top of the page. Google’s read-more snippet links make that path possible, but the destination has to survive the load process. The first test is not whether the section exists in your content management system. It is whether a visitor following the deep link can see the intended passage immediately.

    Google’s published implementation advice is concrete: keep the destination content visible, avoid JavaScript that takes control of the user’s scroll position during page load, and preserve the hash fragment when using the History API or changing window.location.hash.

    • Do not hide the answer exclusively inside a closed tab, accordion, carousel, or other expandable control.
    • Give major sections descriptive headings and stable fragment identifiers.
    • Paste the complete deep URL, including its fragment, into a fresh browser tab and confirm that it lands on the intended section.
    • Watch the page after scripts, banners, fonts, and late-loading components finish. The destination should not be pushed away or replaced by a scripted scroll.
    • Test the same URL from a mobile-sized viewport because overlays and responsive components can change the landing behavior.
    • If a script rewrites the URL during load, verify that it does not remove the fragment or redirect the visitor to a generic location.

    Treat structured data the same way. JSON-LD should clarify the entities and relationships already supported by the visible page. It should not introduce answers, authorship, reviews, dates, or other claims that a visitor cannot verify in the content. Valid markup can improve machine readability, but validation alone does not guarantee an AI citation, a rich result, or a ranking.

    Your final quality check should follow the user’s route: search result, deep link, visible passage, supporting detail, and next action. A technically valid page can still fail if that route breaks after the click.

    Measure repeated visibility, not a lucky screenshot

    An analyst reviews a matrix of abstract answer panels in which the same amber source marker appears repeatedly across multiple results.

    Generative answers are not fixed search listings. The same or similar request can produce different wording, citations, and omissions across attempts. That variability makes a single screenshot useful as evidence of an occurrence, but weak as evidence of reliable visibility. A more defensible process repeats prompts and looks for consistent patterns across the outputs.

    1. Define a stable query set. Include the actual questions behind your important pages, not just head terms. Preserve the wording so changes in the test do not masquerade as changes in visibility.
    2. Record the observation context. Log the platform, search surface, model or mode when shown, prompt, date, location, device context, and sign-in or personalization state when relevant.
    3. Repeat the observation. Check whether the brand, citation, linked page, and answer framing persist across attempts. Do not report a single appearance as durable coverage.
    4. Separate mention from citation and link. A brand can be named without receiving a citation, and a page can be cited without the brand being prominent. Each outcome creates a different opportunity and risk.
    5. Capture the cited destination. A citation to an obsolete page, weak supporting page, or unintended URL can produce visibility while sending the user into the wrong experience.
    6. Compare exposure with behavior. Review answer presence beside impressions, click-through rate, AI referrals, branded demand, useful on-site actions, and business outcomes. Look for aligned movement without pretending that correlation proves causation.
    7. Turn the finding into an editorial action. Repair incorrect framing, strengthen a missing answer passage, consolidate competing URLs, add continuation value, or refresh a fact that has fallen out of date.

    The pattern matters more than any isolated metric. If search impressions remain strong, clicks decline, and attributed AI appearances become more consistent, zero-click consumption is a plausible explanation. Protect the accurate answer while improving the reason to continue. If rankings hold but your brand rarely appears in answer surfaces, inspect the directness, scope, freshness, entity consistency, and passage accessibility of the page before producing more content on the same question.

    If citations increase but qualified actions do not, inspect the query and landing experience. The content may be visible for an informational question that has little relationship to the business, or the cited passage may answer the question without leading naturally to a useful next step. That is not an argument for making the answer worse. It is a reason to stop treating every impression as equally valuable.

    Brand framing deserves its own review. An unlinked but accurate mention can still support recognition. A prominent but inaccurate mention can damage it. Record the surrounding claim, not merely the presence of your name. Where a platform lets users choose preferred sources, inviting an existing audience to select your publication can support future visibility and loyalty, but it should remain a separate measure from organic inclusion.

    Key takeaways

    • Falling clicks do not prove falling visibility. Measure answer inclusion, brand mentions, citations, links, engagement, and business results as separate stages.
    • Give the immediate question a direct, visible answer, then earn the visit with decision support, application, original value, and a workable next step.
    • Maintain evergreen pages around durable audience questions while refreshing the answers whenever facts, products, or conditions change.
    • Keep important passages visible and deep-linkable. Preserve URL fragments and prevent scripts from overriding the visitor’s landing position.
    • Repeat AI-search observations because an isolated output cannot establish dependable visibility.
    • Use structured data to describe supported, visible content. Do not treat valid JSON-LD as a guarantee of rankings or citations.

    For your next publishing cycle, choose a commercially meaningful topic cluster and map its visibility ladder before adding more pages. Rewrite the primary answer for clarity, strengthen the continuation value, test every deep link, and add repeated AI observations to the same dashboard as traffic and conversions. You will then be able to distinguish lost demand from changed behavior and make the right fix.

    References


  • How to Build Website Authority for AI Search Visibility

    How to Build Website Authority for AI Search Visibility

    If an AI answer gets your business wrong, leaves you out, or cites a competitor, publishing another broad article is rarely the cleanest fix. You need to make the right facts easy to crawl, easy to retrieve, difficult to misinterpret, and consistent everywhere they appear.

    That turns website authority from a vague reputation goal into a practical system. You can inspect each part, find the break, and fix the page or fact that is actually limiting your visibility.

    Treat authority as a chain from crawl to customer

    AI search visibility can fail at several different stages. A page may be accurate but inaccessible to a crawler. It may be crawlable but poorly matched to the question. It may be retrieved but not selected as supporting evidence. Your brand may even appear in an answer without earning the customer’s trust afterward.

    Separate the chain into these diagnostic layers:

    • Crawl access: Can relevant crawlers request the public URL and receive the page successfully?
    • Interpretation: Does the page identify the business, service, location, product, or person without ambiguity?
    • Retrieval: Does one section closely answer the user’s actual question?
    • Selection: Is the answer precise and well-supported enough to be used or cited?
    • Validation: Do your other pages and external profiles confirm the same facts?
    • Conversion: Can a person who follows the recommendation verify the offer and take the next step?

    This distinction matters because a citation is not the same as a recommendation, and a recommendation is not the same as a sale. A citation means your URL supported an answer. A mention means your name appeared. A recommendation places you among the options. Authority has to carry the user through all three and then survive their visit to your site.

    Retrieval is especially important. Across an AirOps analysis of 16,851 unique queries, the first retrieval result was cited 58.4% of the time, while the result in tenth position was cited 14.2% of the time. Pages with headings that strongly matched the query were cited 41% of the time. Those figures do not establish a universal ChatGPT ranking formula, but they show why a generally authoritative domain can still lose a particular answer: the wrong page or passage wins retrieval.

    When you diagnose a visibility problem, do not begin with, “How do we make the whole domain more authoritative?” Begin with a narrower question: “For this customer question, which URL should be retrieved, which passage should be selected, and which facts must another source be able to confirm?”

    Design pages to win retrieval, not merely cover topics

    An organized modular website feeds distinct fact objects into a central retrieval beam while cluttered pages sit outside it.

    A page earns retrieval by making its purpose obvious. The title, primary heading, opening answer, supporting details, and internal links should all point to the same intent. A page called “Our Solutions” forces a system to infer what it contains. A heading such as “Does the service include installation?” identifies both the question and the expected answer.

    Build each important answer in this order:

    1. Choose one real customer question. Pull it from sales emails, support conversations, reviews, search queries, and questions on business profiles.
    2. Decide what kind of answer the user needs: a fact, qualification, process, comparison, availability check, or next action.
    3. Place a query-shaped heading above the answer. Use the customer’s language where it remains accurate.
    4. Answer immediately in plain sentences. Do not make the reader cross an origin story, promotional introduction, or table of contents to reach the useful fact.
    5. Add the conditions that prevent a misleading extraction. State relevant locations, exclusions, eligibility rules, dependencies, or situations in which the answer changes.
    6. Support the answer with concrete business information, then point the reader to the appropriate verification or action page.

    A narrow page is not necessarily a short or shallow page. It is a page with one dominant job. A service page can explain scope, suitability, process, limitations, and next steps without becoming a general guide to the entire industry.

    Conversely, long content is not automatically authoritative. In the same query analysis, pages between 500 and 2,000 words performed best for citations, while pages over 5,000 words were cited less often than even the shortest pages. Content with 4 to 10 subheadings also performed notably well. Treat those as observations from that dataset, not mandatory publishing limits. The useful principle is precision: stop when the question has been answered, qualified, and supported.

    A practical site architecture usually needs both hubs and focused pages. Use a broad hub to organize a subject and help users navigate it. Use a focused page when a distinct question requires its own evidence, conditions, or conversion path. Do not create separate URLs for trivial wording changes; consolidate near-duplicate questions under the clearest heading so your own pages do not compete to be the answer.

    Before publishing, apply a simple extraction test. Read only the heading and the paragraph beneath it. If that fragment would be accurate when shown without the rest of the page, the answer is well-formed. If it would overpromise, omit a location, or confuse one service with another, add the missing qualifier beside the answer rather than burying it later.

    Make your website the canonical truth layer

    Your site cannot function as an authority if its own facts drift. A homepage may use one business name, a location page another, and a profile an old address or schedule. An AI system then has to resolve the conflict, and the version it chooses may not be yours.

    This is particularly important in local search, where services, locations, hours, reviews, and business profiles help establish whether a recommendation fits the query. AI recommendations can be checked against multiple online profiles, while customers commonly validate the choice by visiting the website and reading reviews. Your site therefore has two jobs: provide precise information for the recommendation and provide enough proof for the person evaluating it.

    Create a fact inventory with one row for every claim that can change or cause a customer to choose incorrectly. Useful fields include:

    • The fact itself, written in its approved form.
    • The canonical page where that fact is explained.
    • Every important internal page and external profile that repeats it.
    • The person responsible for verifying it.
    • The event that should trigger an update.
    • The date on which someone last confirmed it.

    Start with identity and decision facts: business name, locations, service areas, hours, contact details, offerings, eligibility, availability, policies, and important limitations. For a local business, compare those facts with its Google Business Profile and major directories. For a product or service company, compare landing pages with pricing, support, policy, and documentation pages. Resolve contradictions at the canonical page first, then update every surface that repeats the fact.

    Authority also depends on evidence placement. Put identity information on the homepage and about page. Put service scope and limitations on the service page. Put location-specific availability on the relevant location page. Put policy details on the policy page. Repeating a short fact for context is reasonable, but one page should remain the full, maintained explanation.

    Use JSON-LD to identify facts, not manufacture authority

    Structured data helps a machine identify entities and relationships, but it cannot make vague copy precise or reconcile conflicting claims. In the citation dataset, pages with JSON-LD had a 38.5% citation rate, compared with 32.0% for pages without it. That is a useful but modest association, not evidence that schema alone causes citations.

    Use JSON-LD as a faithful machine-readable version of the visible page:

    • Select the most specific schema type that truthfully describes the entity or content.
    • Mark up only facts that users can verify on the page or through an appropriate canonical page.
    • Use stable URLs and identifiers for the same entity across connected markup.
    • Keep names, addresses, service descriptions, dates, and other properties aligned with visible content.
    • Validate syntax after changes and include structured-data checks in the same workflow that updates the page.

    If you have to choose between adding more properties and correcting a contradiction, correct the contradiction. Clear content establishes the claim; structured data labels it.

    Run an audit that separates visibility from accuracy

    A digital workbench uses separate illuminated lanes to inspect website fact modules for discoverability and consistency.

    An occasional vanity prompt will not tell you whether authority is improving. Generative answers can vary, and one broad question mixes discovery, retrieval, recommendation, and citation into a single result. Use a fixed audit that preserves the wording, platform, run date, and evidence.

    1. Build a prompt set around real decisions. Include questions about fit, availability, location, process, limitations, alternatives, and the next step. Use neutral language rather than inserting your brand into every prompt.
    2. Run the same prompts on the AI systems your customers are likely to use. Repeat important prompts so a single variable response does not become your conclusion.
    3. Record whether your brand appears, how it is described, whether the description is correct, whether your site is cited, which URL is used, and which competing or third-party sources support the answer.
    4. Inspect the cited or likely landing page. Check whether its title and headings match the question, whether the answer appears near the relevant heading, and whether all necessary qualifiers sit beside it.
    5. Check crawler access. Confirm that important URLs can be requested, do not return error responses, and are not unintentionally restricted by access rules.
    6. Fix the earliest broken link in the chain. There is little value in rewriting an answer passage if the page cannot be crawled, or adding schema while external profiles still carry the wrong location.

    Server-log analysis can expose crawler activity that ordinary traffic reports do not make obvious. Logs can show the requested URL, time, declared user agent, and response status. They cannot prove that a model stored, trusted, retrieved, cited, or used the content. Treat them as crawl evidence, then use prompt audits and citation tracking to evaluate the later stages.

    Prioritize corrections by consequence. Fix inaccurate high-intent facts first, followed by access failures, conflicting profiles, missing direct answers, and stale supporting content. This order protects the customer decision while also improving the material available for retrieval.

    Freshness deserves a targeted approach. Pages published 30 to 89 days before collection had the strongest citation performance in the AirOps dataset, while content less than 30 days old performed slightly worse and content older than two years struggled. That pattern may reflect the time needed to accumulate retrieval signals, and it does not justify rewriting every page on a fixed schedule. Use it as a reason to review older pages that already serve valuable queries, especially when their facts, examples, policies, or answer structure have drifted.

    Measure the outcome at each stage

    Your reporting should make failures distinguishable. Track prompt coverage, accurate-answer rate, brand mention rate, citation rate, owned-site citation share, cited URLs, crawler access, corrected fact conflicts, and the customer actions that follow AI-assisted discovery. Keep the prompt set stable long enough to detect a direction, and log material page changes so you can connect movement to an intervention.

    Do not use organic clicks as the sole verdict. An Ahrefs analysis found that 99% of keywords triggering an AI Overview were informational, while navigational keywords accounted for 0.13%. In that dataset, AI Overviews were concentrated overwhelmingly in informational searches. A decline in clicks from quick-answer queries can therefore coexist with useful visibility, but only if your brand is represented accurately and decision-stage users can still reach a convincing destination.

    Report exposure and business impact separately. Exposure tells you whether the brand and site enter the answer. Accuracy tells you whether the answer helps or harms. Decision actions tell you whether the website completes the job. Combining them into one visibility score hides the part you need to fix.

    Frequently asked questions

    What does website authority mean in AI search?

    Website authority in AI search is the site’s ability to provide crawlable, unambiguous, retrievable, consistent, and verifiable information for a particular question. It is not just a domain-level reputation score. A strong domain can lose a citation when its relevant page is vague, stale, inaccessible, or poorly matched to the query.

    Should every customer question have its own URL?

    No. Give a question its own page when it has distinct evidence, conditions, search intent, or a separate next action. Put closely related questions on one focused page under descriptive headings. Creating near-duplicate URLs for every phrasing makes maintenance harder and leaves several pages competing to represent the same answer.

    Can an uncited AI mention still be valuable?

    Yes, but count it separately from a citation. First check whether the mention is accurate, relevant to the question, and likely to lead a user toward verification. Then inspect whether your website supports the description and offers a clear next step. An inaccurate mention is not positive visibility merely because the brand appeared.

    What should you fix first?

    Fix the error with the greatest decision consequence. An incorrect location, service condition, eligibility rule, or availability claim comes before a missing optional schema property. After factual accuracy, address crawl failures and retrieval structure, then improve supporting depth and presentation.

    Start with the questions closest to a real customer choice. Assign each one a canonical page, verify every changeable fact, correct conflicts across your profiles, and make the answer extractable beneath a precise heading. Then rerun the same prompt set and inspect the logs. That cycle gives you something more useful than a vague authority campaign: a clear record of what AI systems can access, what they say, and what you need to improve next.

    References


  • AI Visibility Beyond Topical Authority: A 9-Cell Audit

    AI Visibility Beyond Topical Authority: A 9-Cell Audit

    Your site can cover a subject from every angle and still be absent from an AI answer. When that happens, publishing another adjacent page is often the wrong move.

    The practical gap is between being relevant enough to consider and being clear, credible, and distinctive enough to select. You can diagnose that gap by auditing three layers: coverage, architecture, and position.

    Topical authority can qualify you without differentiating you

    Topical authority describes what you have built around a subject: the questions you answer, the relationships among those answers, and the depth with which you handle them. That foundation matters. A shallow or fragmented site will struggle to establish relevance in either conventional search or AI-mediated discovery.

    But relevance is only the first gate. Several sites can cover the same topic competently. The harder question is why an AI system should use your entity, page, or explanation instead of another eligible candidate.

    This creates a useful distinction:

    • Eligibility: Does your content belong in the candidate set for this question?
    • Selection: Once several candidates qualify, does your content give the system a reason to prefer it for this particular answer?

    The desired state is sometimes called topical ownership. It does not mean owning a subject exclusively or appearing in every generated response. It means becoming a repeatedly plausible choice because coverage, architecture, and position reinforce one another.

    You can usually locate a visibility problem by asking three diagnostic questions:

    • If no page fully resolves the user’s question, you have a coverage problem.
    • If the answer exists but is buried, fragmented, or connected ambiguously to other pages, you have an architecture problem.
    • If the answer is complete and clear but could have come from almost any competent site, you have a position problem.

    Key takeaways

    • Topical authority helps you qualify; it does not automatically make you the preferred choice.
    • AI visibility depends on what you cover, how clearly you encode it, and which entity is associated with it.
    • More pages will not repair weak differentiation, ambiguous ownership, or poor information architecture.
    • Audit selection at the query-family level before expanding the entire site.

    Use the 9-cell model to find the actual weakness

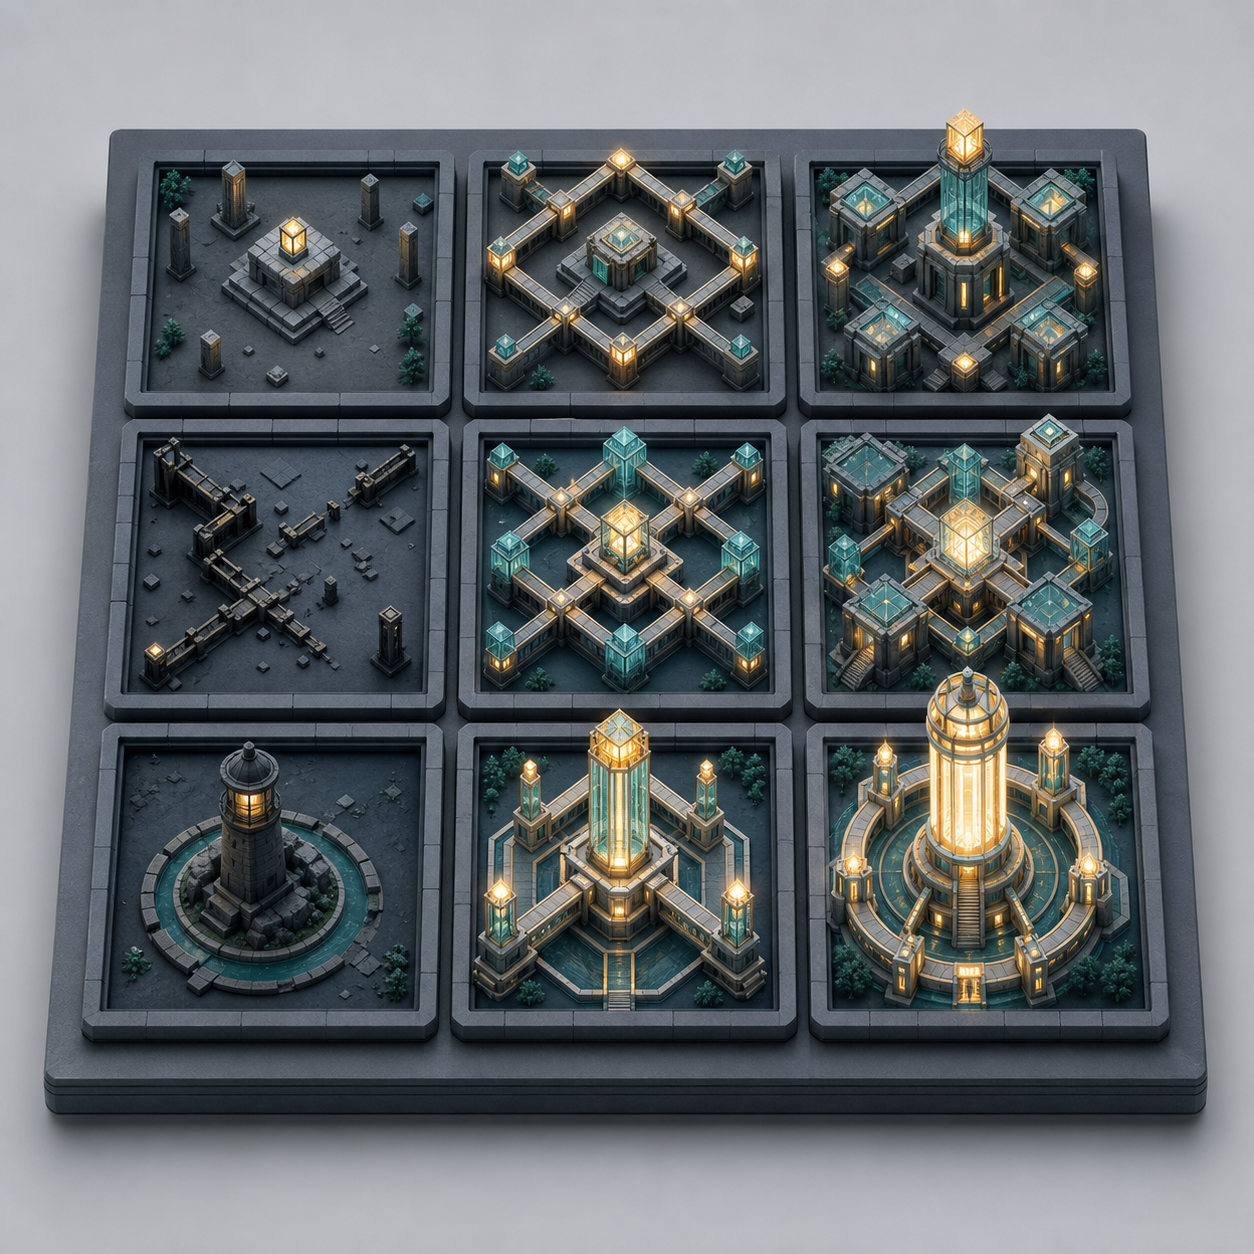
    An isometric square platform contains nine visual audit chambers, including illuminated strengths and a few disconnected or dim weaknesses.

    A three-by-three model turns an abstract visibility problem into an operating audit. Each row represents a layer. Each cell asks a different question that your content must answer.

    LayerCell 1Cell 2Cell 3
    CoverageDepth: Does the content resolve the core question, not merely introduce it?Breadth: Does it address the related decisions and necessary follow-up questions?Distinct insight: Does it contribute a defensible idea, judgment, or method?
    ArchitectureClarity: Can the central answer be understood without reconstructing it from scattered passages?Relationships: Do headings and internal links make the topic hierarchy explicit?Source context: Is it clear who is speaking, in what capacity, and within what time context?
    PositionEntity identity: Is the responsible person, organization, or product named consistently?Authority: Is there a credible reason to trust this entity on this particular subject?Selection relevance: Is there a concrete reason to choose this contribution over an equally complete alternative?

    Mark every cell red, amber, or green for each priority query family. Red means the requirement is absent or contradictory. Amber means it is present but implicit, thin, or inconsistent. Green means it is explicit, supported, and consistent across the relevant page, surrounding content, and entity information.

    Do not average the colors into a reassuring score. A site can be green on breadth and still fail because its authorship is unclear. It can have a strong brand position and still fail because no page directly answers the question. The weakest required cell can limit the whole result.

    Run the audit against a specific user decision, not a broad keyword. A query such as how to audit AI citations has a clearer success condition than the topic AI SEO. The narrower framing exposes whether you have a page that resolves the task, whether its answer can be extracted cleanly, and whether your entity has a defensible connection to it.

    Build coverage and architecture for selection

    Coverage should resolve a decision, not fill a topical map

    Coverage is not a page-count target. Depth, breadth, and distinct insight perform different jobs.

    • Depth resolves the main question, explains the mechanism behind the answer, and deals with the conditions that could change it.
    • Breadth covers the neighboring questions a reader must settle before acting, without forcing one page to absorb an entire subject.
    • Distinct insight gives the content a reason to exist when other sites already explain the basics.

    A long page can still be shallow. Length often accumulates definitions, restatements, and generic examples without resolving the reader’s decision. Test depth by removing the introduction and asking whether the remaining material tells the reader what to do, why that action fits, and when it would not fit.

    Breadth also gets misread as publishing every conceivable subtopic. Useful breadth follows the decision path. If a supporting question changes the main recommendation, prevents a common error, or determines the next action, it belongs in the cluster. If it only shares vocabulary, it may not deserve a page.

    Distinct insight is the selection delta. It can be an operational definition, a framework, a reasoned position, a transparent analysis, or a clearer way to separate two concepts people routinely conflate. It must be defensible. Invented statistics, decorative terminology, and unsupported contrarian claims create novelty without authority.

    Use this sequence when improving coverage:

    1. Write the exact question or decision the page owns.
    2. State the shortest accurate answer before expanding it.
    3. List the conditions, trade-offs, and follow-up questions that could change the action.
    4. Separate what is broadly established from your interpretation or recommended method.
    5. Add a contribution your entity can explain and defend consistently elsewhere.
    6. Remove or consolidate pages that compete for the same purpose without adding a distinct role.

    The final step matters because duplication can disguise itself as authority. Ten overlapping pages may create more text while making it less obvious which page represents your best answer.

    Architecture should remove interpretation work

    Architecture is the translation layer between what you know and what another system can understand about it. It operates inside sentences, across the page, and throughout the site.

    • Lead with the resolution. Put the direct answer near the question it resolves. Add qualifications immediately after it rather than several sections later.
    • Give each section one job. A descriptive heading should tell the reader what decision, mechanism, or distinction the section handles.
    • Keep claims and conditions together. If a recommendation only applies in a particular situation, do not separate the qualifier from the recommendation.
    • Use internal links as relationship labels. Explain whether the destination is a prerequisite, a deeper method, an example, or the next step. Generic anchor text hides that relationship.
    • Make ownership visible. Connect the page to consistent author, organization, product, and editorial context where those entities are relevant.
    • Represent only visible facts in structured data. JSON-LD can clarify entities and relationships, but it should mirror the page rather than make unsupported claims the reader cannot verify.

    Sentence clarity is not the same as oversimplification. A technical claim can remain precise while placing the subject, action, and condition in an explicit order. If a sentence depends on three undefined pronouns, an unexplained category, and context from two paragraphs earlier, the reader and the machine both have extra reconstruction work.

    Review architecture by trying to extract three things from the page: its central answer, the entity responsible for that answer, and the conditions under which it applies. If you cannot identify all three without interpretation, reorganize the page before adding more content.

    Position is built across entities and time

    A luminous central object gains stronger connections to institutions, documents, experts, and reference nodes across repeated layers of time.

    Position answers the question coverage cannot: why you? It is the association between an identifiable entity and a defensible area of competence.

    You cannot create that association with one declaration of authority. It develops when the same entity repeatedly makes useful, coherent contributions within a recognizable territory. Your content, author information, organization pages, terminology, and external recognition should point in the same direction.

    Write a positioning statement for each strategically important topic area by answering these questions:

    • Which entity is speaking: a person, organization, publication, product, or another clearly defined entity?
    • Which specific problem or decision does that entity have standing to address?
    • Who is the intended audience, and what context does that audience bring?
    • What expertise, method, evidence, or body of work supports the claim?
    • What contribution should remain recognizably associated with the entity?

    If the answers change from page to page, your position is not yet coherent. Fix naming, roles, scope, and topic ownership before pursuing a broader footprint.

    Recognition must connect the entity to the topic

    Recognition is more useful when it reinforces a specific association. A generic mention of a company name says less about topical position than a relevant citation, reference, or discussion that connects the entity to the contribution it actually makes.

    This changes how you approach digital PR, partnerships, expert contributions, and brand mentions. The objective is not simply to accumulate appearances. It is to make the entity-topic relationship legible. Use the same canonical name, describe the relevant expertise accurately, and direct attention to the page that best represents the contribution.

    Do not manufacture evidence of recognition. Weak guest posts, inflated biographies, unsupported superlatives, and interchangeable expert commentary can increase the number of claims about an entity without making any of them more credible.

    Time tests whether the position is real

    Position has a temporal dimension. A clear idea published once may be useful, but a coherent body of work maintained over time is easier to associate with an entity than a sequence of disconnected claims.

    Build time into the content system:

    • Define what would trigger a meaningful review, such as a changed platform behavior, new evidence, or a shift in the decision criteria.
    • Record substantive revisions so the current position is distinguishable from an abandoned one.
    • Consolidate obsolete or contradictory pages instead of leaving several competing answers live.
    • Keep stable definitions and entity names consistent unless there is a genuine reason to change them.
    • Explain an evolved position rather than silently replacing it and creating unexplained contradictions.

    Changing a date without improving the content does not strengthen temporal authority. The useful signal is continued stewardship: the page remains accurate, its ownership remains clear, and changes have an intelligible reason.

    Run a selection audit before producing more content

    A selection audit should end with an editorial queue, not a strategy presentation. Start with a query family that matters to the business and complete the following workflow.

    1. Define the decision. Record the exact question, intended user, and action the answer should enable.
    2. Observe the current answer space. Note which entities and pages are used or cited, which parts of the question they resolve, and which distinctions recur. Treat this as a snapshot, not a permanent ranking.
    3. Assign one primary page. Select the URL that should provide your best answer. If several pages compete for that role, resolve the overlap first.
    4. Audit all nine cells. Mark depth, breadth, distinct insight, clarity, relationships, source context, entity identity, authority, and selection relevance as red, amber, or green.
    5. Repair the limiting layer. Create missing coverage only when no page resolves the task. Rework architecture when the answer exists but is hard to isolate. Strengthen position when the page is complete and clear but interchangeable.
    6. Write the selection delta. State in one sentence what your page contributes that another competent explanation does not. If you cannot write that sentence honestly, the page needs a stronger contribution.
    7. Retest the query family. Use the core question and natural follow-ups. Record whether the correct page appears, whether your distinct framing survives paraphrase, and whether the entity is represented accurately.

    Keep a one-page selection memo

    For each priority query family, maintain a short working record containing:

    • the user’s exact decision;
    • the primary page and its one-sentence answer;
    • the necessary supporting questions;
    • the page’s distinct contribution;
    • the responsible entity and relevant authority context;
    • the internal pages that establish prerequisites or deepen the method;
    • the event that should trigger the next review; and
    • dated observations from repeated AI-answer checks.

    This memo makes gaps harder to hide behind aggregate traffic or publishing volume. It also gives writers, technical SEO teams, schema implementers, and digital PR teams the same definition of the page’s job.

    Avoid fixes that change the surface but not selection

    Several familiar tactics can consume effort without repairing the weak cell:

    • Publishing more adjacent pages when the existing cluster already overlaps.
    • Making an article longer without resolving additional decisions.
    • Adding schema to content whose entities or claims remain ambiguous on the visible page.
    • Changing publication dates without a substantive revision.
    • Pursuing generic mentions that do not connect your entity to the relevant topic.
    • Renaming familiar ideas without adding a defensible insight.

    Do not judge the result from one generated answer. Prompt wording, context, and system behavior can change the output. Look for a pattern across the core question and its close variants: the correct page becomes a plausible choice, the distinctive contribution is represented accurately, and the responsible entity is not confused with another one.

    Start with one query family where selection would matter. Complete the nine-cell audit, fix the weakest required cell, and document what changes. That gives you a grounded path to AI visibility before you scale another topical map.

    References


  • Gemini SEO: A Practical Guide to Content Visibility

    Gemini SEO: A Practical Guide to Content Visibility

    If Gemini answers a question your page already covers but never names your brand or links to your content, adding more keywords is unlikely to solve the underlying problem. First ask whether the page provides a clear, self-contained answer that Gemini can understand, attribute, and represent accurately.

    That shifts the work from chasing an AI-specific trick to improving answer quality. You still need sound SEO, but you also need content that resolves the user’s decision, identifies its claims precisely, and gives an answer engine a credible page to cite.

    Treat Gemini visibility as answer eligibility

    Conventional search visibility and Gemini visibility overlap, but they are not identical outcomes. A page may deserve a click because it promises useful information while still making the actual answer difficult to locate. It may bury the conclusion, leave important conditions unstated, or use vague language that only makes sense after reading the entire site.

    The practical objective is to make your content easier to use across AI Overviews and answer engines. That means treating each important page as a candidate answer, not merely as a container for keywords.

    A useful answer candidate has four qualities:

    • Relevance: It resolves the question the user actually asked rather than discussing the surrounding topic indefinitely.
    • Clarity: The main conclusion, subject, and conditions are explicit. The reader does not have to infer what “it,” “this,” or “the solution” refers to.
    • Support: Important factual claims have evidence, context, or a clear explanation behind them.
    • Identity: Products, organizations, authors, places, and concepts are named consistently enough to avoid confusion.

    Key takeaways

    • Optimize for the complete question and decision, not an isolated keyword.
    • Put a direct, qualified answer where both readers and machines can find it quickly.
    • Keep names, claims, visible content, and structured data consistent.
    • Measure brand mentions, citations, factual accuracy, and useful visits separately.
    • Diagnose the specific visibility gap before rewriting an entire page.

    This framework also prevents a common strategic mistake: treating every absence from a Gemini response as a technical SEO failure. Sometimes the page is accessible but does not answer the prompt. Sometimes it answers the prompt but lacks enough support. Sometimes Gemini recognizes the brand but has no definitive page worth linking. Each condition calls for a different edit.

    Build each page around a complete user decision

    An isometric decision path connects a question, several options, comparison pieces, evidence, risk checks, and a final selection.

    Start with the prompt behind the keyword. A keyword names a subject; a prompt usually reveals a situation, constraint, or decision. Someone asking how to optimize content for Gemini may be trying to diagnose missing citations, plan a new page, improve an existing ranking page, or decide what to measure. Those needs overlap, but they do not require the same answer.

    Before drafting or revising a page, write an answer specification:

    • Target question: Write the question in the language a real user would use.
    • Reader state: Note what the reader already knows and what has prompted the search.
    • Decision: Identify what the reader should be able to choose, change, or check after reading.
    • Short answer: State the smallest answer that would still be responsible and useful.
    • Conditions: Record where the answer changes by product, page type, audience, market, or other relevant constraint.
    • Support: List the evidence, examples, definitions, or reasoning needed to justify the answer.
    • Follow-up questions: Add only the questions that naturally arise before the reader can act.

    This specification exposes thin content early. If you cannot state the decision or the short answer, another introductory paragraph will not fix the page. You either need a narrower question or better information.

    Use the primary question as the page’s organizing spine. Put the direct answer near the relevant heading, then develop the reasoning, qualifications, process, and next step. Cover close follow-up questions when they help the same reader complete the same task. Split the material when a follow-up serves a different intent or leads to a different decision.

    For example, “Why is my page absent from Gemini?” is a diagnostic intent. “How should I structure a new page for Gemini?” is an implementation intent. Forcing both into a long, unfocused page can make each answer less distinct. A diagnostic page can link to the implementation workflow after it identifies the likely problem.

    Write answers that can be extracted without losing context

    Answer-first writing does not mean reducing every page to a blunt definition. It means making the conclusion visible before asking the reader to process all the supporting detail.

    A strong opening answer usually contains the subject, the recommended action or conclusion, and the condition that prevents the statement from becoming misleading. Compare these two constructions:

    Weak: There are many factors to consider when pursuing better AI visibility, and every business needs a comprehensive approach.

    Stronger: To improve Gemini visibility, make the page answer a specific user question directly, support its important claims, and identify the entities and conditions involved.

    The stronger version does not guarantee inclusion in a generated answer. It does give the reader an immediate orientation and makes the page’s central claim easier to interpret.

    Use this editing pass on every priority page:

    • Replace generic headings. “Benefits” says little on its own. A heading such as “Clear answers reduce ambiguity for readers and answer engines” announces the point of the section.
    • Keep qualifiers beside the claim. If advice applies only to a certain page type or use case, state that condition in the same paragraph. Do not hide it several sections later.
    • Name the subject again when needed. Repeating a product or organization name is better than using an ambiguous pronoun where several entities are in view.
    • Use stable terminology. If “AI visibility” and “organic traffic” mean different things in your measurement plan, do not switch between them as though they were synonyms.
    • Separate fact from judgement. Mark recommendations as recommendations. A clear editorial position is more trustworthy than advice disguised as a universal rule.
    • Make lists genuinely parallel. Steps should be actions in sequence. Criteria should be comparable qualities. Do not mix outcomes, warnings, and instructions in the same list without labels.
    • Use descriptive internal links. Tell the reader what the destination will help them do instead of relying on “learn more” or “click here.”

    Do not repeat the same short answer mechanically across several pages. Near-duplicate answers create uncertainty about which page is authoritative. Choose a primary page for the question, let related pages handle their own distinct intents, and connect them with contextual internal links.

    Align entities, evidence, and structured data

    Gemini cannot represent your content accurately if your own site is inconsistent about who or what the content describes. An entity pass is therefore more useful than inserting extra keyword variants.

    Check the visible page for consistent organization names, product names, service labels, author information, and relationships between them. If a product has been renamed, explain the relationship instead of silently alternating between old and new names. If an acronym could refer to several things, define it before relying on it.

    Then perform an evidence pass:

    • Identify the claims a reader would reasonably want verified.
    • Link to the originating authority when a primary reference is available.
    • Name the relevant product, model, version, jurisdiction, or other constraint when it changes the meaning of the claim.
    • Place the supporting citation close to the statement it supports.
    • Remove outdated or contradictory statements elsewhere on the site.
    • Distinguish documented facts from your own interpretation or recommended practice.

    Structured data can reinforce that clarity, but only when it describes what the visitor can see. Use the schema type that matches the page, and keep names, authorship, dates, and other marked-up properties aligned with the visible content. Validate the syntax and remove properties that make claims the page itself does not substantiate.

    Think of JSON-LD as a disambiguation layer. It can express meaning in a machine-readable form, but it cannot supply missing expertise, rescue an unclear answer, or guarantee selection in a Gemini response. If the markup and the page disagree, fix the underlying content before adding more schema.

    Technical accessibility remains part of the foundation. A public page that cannot be crawled reliably is not a dependable citation target. Check crawl access, canonicalization, index eligibility, rendered content, and internal linking before diagnosing the problem as an AI-specific visibility issue.

    Measure Gemini visibility with a prompt-led audit

    An overhead audit workspace shows question tokens being traced through an answer to connected and omitted source cards.

    A conventional rank tracker does not capture the whole outcome. Generated responses can change with prompt wording and conversational context, so a single manual query is not a reliable benchmark. Build a stable prompt set around the real questions your audience asks and preserve the exact wording for later checks.

    Your set should include the distinct situations that matter to the business: discovering a category, understanding a concept, comparing approaches, applying a constraint, troubleshooting a problem, and choosing a next action. Do not pad the set with superficial variants that test the same intent repeatedly.

    For every check, record the prompt, the answer’s factual accuracy, whether the brand appears, whether a page is linked or otherwise cited, which page is used, whether the response satisfies the intent, and what the user could reasonably do next. Keep brand mentions separate from citations and referral traffic. They represent different levels of visibility.

    What you observeWhat may be happeningWhat to change first
    A competing page is cited while yours is absentThe competing page may answer the prompt more directly or support the answer more clearlyCompare decision coverage, qualifications, and evidence; add the missing substance rather than copying its wording
    Your brand appears, but no useful page is citedThe entity may be recognized while your site lacks a definitive answer pageStrengthen the best existing page with a direct answer, clear identity, and supporting evidence
    The answer describes your brand or product incorrectlyYour public information may be ambiguous, inconsistent, or outdatedReconcile names and facts across the relevant pages, then make the canonical explanation explicit
    A ranking page is omitted from the generated answerThe page may satisfy click intent but bury the extractable conclusionAdd a concise, qualified answer under the relevant heading and keep its evidence nearby
    The result changes when the prompt is slightly rewordedThe page may cover only part of the user’s underlying intentMap the meaningful prompt branches and address the missing condition or follow-up question

    Turn that diagnosis into a controlled workflow:

    1. Save the exact benchmark prompts and current responses.
    2. Assign the best page on your site to each prompt. If no suitable page exists, record the content gap.
    3. Classify the issue as access, intent, answer clarity, evidence, entity consistency, or page authority.
    4. Make the smallest change that addresses the diagnosed problem.
    5. Confirm that the updated page remains useful to a human reader and can still be crawled and indexed as intended.
    6. Retest after search systems have had an opportunity to rediscover the change, using the same prompts and recording any differences.

    Avoid rewriting the title, introduction, schema, internal links, and page structure simultaneously. If visibility changes, you will not know which intervention mattered. Controlled edits make the audit useful even when Gemini’s output itself varies.

    Start with the prompt most closely tied to a real reader decision. Give it a definitive page, a direct but qualified answer, consistent entity information, and evidence a reader can inspect. That is a stronger Gemini SEO program than publishing more vaguely related content and hoping the model connects it for you.

    References


  • Integrated AEO Growth Marketing: A Practical Operating Model

    Integrated AEO Growth Marketing: A Practical Operating Model

    Your team can publish technically sound pages and still be absent when an AI answer system handles a question you should own. The missing piece may not be another optimization tactic. It may be the gap between your answer content, technical SEO, public relations, social distribution, and measurement.

    Integrated AEO growth marketing closes that gap. It gives every channel one shared job: make a useful answer easy to find, understand, verify, repeat accurately, and connect to a meaningful next step.

    Treat AEO as an operating model, not a publishing checklist

    Answer engine optimization improves the conditions under which an AI system can discover and use information about your brand. It cannot guarantee a mention or citation. That distinction should shape your strategy: you are building a reliable information system, not inserting a keyword into a page and waiting for a predictable ranking.

    A page can contain a strong answer but receive no meaningful distribution. A PR campaign can earn attention while sending people to a vague or outdated destination. A social team can discover the audience’s real questions without returning those insights to the content team. Each channel may be performing well by its own standards while the combined system fails.

    An integrated AEO program connects five layers:

    • Demand: What is the audience trying to understand, compare, verify, or decide?
    • Answer: Which page gives that person a direct, qualified, and complete response?
    • Evidence: What supports the claims, and who is responsible for keeping that support current?
    • Distribution: How will the answer reach relevant audiences and become part of the wider conversation?
    • Growth: What useful action can the reader take, and how will you tell whether the answer contributed to it?

    This model changes what counts as completed work. A page isn’t finished merely because it was published. It needs an owner, a distribution plan, an evidence trail, a measurement definition, and a rule for revisiting it when the market or the underlying facts change.

    Look at your current reporting. If SEO reports pages, PR reports placements, social reports engagement, and growth reports conversions without a shared question or destination connecting them, you don’t yet have integrated AEO. You have several channel plans occupying the same calendar.

    Build one authoritative answer asset before planning the campaign

    Hands assemble a layered knowledge hub that sends matching information through several distribution channels.

    Start with a decision your audience needs to make, not a loose topic you want to rank for. A broad theme such as enterprise automation can produce dozens of unfocused pages. A decision question such as how a buyer should evaluate an enterprise automation platform gives the team a clear answer to build, support, and distribute.

    Create a brief that every channel can use. It should contain the exact audience question, the reader’s situation, the shortest responsible answer, the qualifications that prevent overstatement, the evidence needed, the primary destination, and the next useful action.

    1. Define the decision. Write the question in the language a real prospect, customer, practitioner, or evaluator would use. State what the person is trying to decide after receiving the answer.
    2. Write the direct answer first. Put a concise response near the beginning of the page. Don’t make the reader assemble your position from a long preamble.
    3. Add the necessary boundaries. Explain when the answer applies, when it doesn’t, and which variables can change it. Qualification makes an answer more useful; it is not a weakness to conceal.
    4. Support the important claims. Connect each material claim to evidence that a reviewer can inspect. Assign an internal owner to claims that depend on changing products, policies, prices, or market conditions.
    5. Clarify the entities. Use consistent names for the company, product, service, people, and concepts involved. Explain unfamiliar relationships in plain language instead of expecting a system or reader to infer them.
    6. Describe the visible page accurately. Structured data should represent information people can actually find on the page. It cannot repair a weak answer, manufacture authority, or guarantee inclusion in an AI response.
    7. Choose the next action. Let the reader compare options, inspect supporting material, request an assessment, start a process, or move to a closely related question. The action should follow naturally from the answer rather than interrupt it.

    Keep a claim ledger beside the brief. For every consequential statement, record the approved wording, supporting evidence, owner, and condition that should trigger a review. This prevents a common integration failure: PR, social, sales, and website copy gradually describing the same offer in incompatible ways.

    Choose one primary destination for the answer. Supporting pages can address narrower questions, and off-site material can adapt the message for different audiences, but the team should know which page holds the maintained version. Without that anchor, updates fragment and measurement becomes difficult to interpret.

    Give SEO, PR, social, and growth distinct jobs

    Integration does not mean asking every channel to publish the same paragraph. It means preserving the same defensible answer while each channel contributes something different. Coordinating SEO, PR, social media, and AI-assisted audience targeting can strengthen AI visibility by connecting on-site answers with distribution and public context.

    WorkstreamJob in the AEO systemUseful outputFailure to watch for
    SEO and contentCreate the primary answer and make its structure understandableQuestion map, answer brief, maintained destination, internal connections, accurate structured dataPublishing pages without evidence, distribution, or a defined reader decision
    Public relationsDevelop credible reasons for other people and publications to discuss the subjectExpert commentary, evidence-led angles, attributable claims, relevant coverage opportunitiesWinning attention for a message the website cannot support or explain
    Social mediaExpose the answer to audience language, objections, and follow-up questionsMessage variants, question patterns, response themes, reusable explanationsOptimizing engagement around claims that never improve the primary answer
    Growth and conversionConnect information needs to an appropriate next stepJourney hypothesis, offer alignment, conversion path, experiment backlogForcing every informational question into an immediate sales action
    AnalyticsPreserve a record of what changed and what happened afterwardPrompt observations, representation checks, referral data, conversion evidence, change logCollapsing unlike signals into one unexplained visibility score

    The handoffs matter more than the channel labels. Search research should change the questions PR prepares experts to answer. Objections found in social responses should improve qualifications on the primary page. PR feedback should reveal unsupported claims or missing evidence. Conversion behavior should show whether the content attracts the audience the business can actually help.

    Run this work from one shared backlog organized by audience questions. Each item should name the primary answer asset, evidence owner, distribution opportunities, channel dependencies, measurement plan, and decision-maker. Channel-specific task boards can still exist, but they should point back to this shared record.

    Consistency does not require mechanical repetition. A technical page may need a precise explanation, a PR pitch may foreground the newsworthy implication, and a social response may answer one objection in plain language. The underlying claim, scope, and evidence should remain compatible across all three.

    Measure the chain from answer availability to business value

    Illuminated gateways form a connected measurement pathway while a strategist monitors signals moving through each stage.

    AEO reporting becomes misleading when a single visibility score is treated as the whole outcome. A brand mention, a linked citation, a correctly represented answer, a referred visit, and a qualified conversion are different events. Keep them separate so you can see where the chain is working and where it breaks.

    Use a measurement ladder with distinct layers:

    • Answer coverage: Do priority audience questions have maintained destinations, direct answers, supporting evidence, owners, and distribution plans?
    • Technical availability: Can the intended audience and permitted automated systems access the page, and does its visible structure match the information you want understood?
    • Observed representation: For a fixed set of monitored questions, is the brand absent, mentioned, cited, or described accurately? Record accuracy separately from presence.
    • Engagement: Do referred visitors continue to relevant material, interact with the intended next step, or leave because the destination does not match the answer that brought them there?
    • Growth outcome: Does the work contribute to qualified demand, assisted conversion, retention, or another outcome the organization has explicitly chosen?

    Build your monitoring set from the question map, not from prompts invented solely to make the brand appear. Include discovery questions, comparison questions, objections, implementation questions, and brand-specific verification questions where they reflect a real journey.

    For each observation, record the question, exact wording, answer system, date, response, cited destinations, brand presence, factual accuracy, and any relevant campaign change. Generated answers can vary, so an isolated result should be treated as an observation rather than proof of a stable position.

    Keep a change log beside those observations. Note material revisions to the answer, structured data, internal links, external coverage, and distribution. Without that record, a visibility change may look meaningful while giving the team no defensible explanation for what caused it.

    Turn the log into an experiment backlog. A useful hypothesis names the question cluster, the weakness, the proposed change, and the signal expected to move. For example: if the primary page answers an eligibility question directly and places its supporting evidence beside the answer, accurate representation for that question cluster should improve. Make a bounded change, preserve the previous version in your records, and evaluate the whole measurement chain rather than celebrating one favorable response.

    AI-assisted analysis can help cluster audience language, identify repeated objections, and draft message variations. It should not be allowed to approve factual claims or decide that two questions have the same intent without human review. Faster targeting is useful only when it sends the team toward the right problem.

    Choose ownership before you choose an agency

    An integrated growth agency can provide coordination across specialties, but hiring one is not the strategy. The stronger question is whether your operating model has a clear owner, shared evidence, access to the necessary systems, and authority to resolve conflicts between channels.

    In-house ownership can work when your specialists already share priorities and can move an answer from insight through publication, distribution, and measurement. An agency becomes more useful when the bottleneck is cross-functional capacity or orchestration. A hybrid model can keep subject expertise and claim approval inside the organization while external specialists handle defined research, production, technical, distribution, or measurement work.

    Before selecting a model, answer these questions:

    • Who can choose the audience questions that receive investment?
    • Who owns the accuracy of each consequential claim?
    • Who can approve changes to the primary answer and its structured data?
    • Who connects PR and social feedback to the maintained page?
    • Who defines the business outcome and has access to evaluate it?
    • Who decides whether weak performance calls for a better answer, stronger evidence, wider distribution, or a different audience?

    If you evaluate an agency or consultant, ask to see the operating artifacts they will produce. A credible plan should include a shared question map, an example answer brief, claim governance, channel handoffs, a measurement dictionary, a change log, and named decision rights. A slide full of channel tactics is not a substitute for those working documents.

    Be cautious with guaranteed citations or promised placement in generated answers. Ask which parts of the result the provider can control, how observations are collected, how accuracy is scored, and how the work connects to business value. If the answer depends on an unexplained proprietary visibility number, you will struggle to diagnose failure or retain the learning after the engagement ends.

    Is AEO the same as SEO?

    No. They overlap, because useful content and technical accessibility matter to both. Integrated AEO also coordinates how an answer is supported, distributed, represented in generated responses, and connected to growth. SEO remains a core workstream rather than the entire program.

    Does every answer asset need PR and social support?

    No. Apply channel effort according to the importance of the audience decision, the evidence gap, and the distribution opportunity. A narrow support question may need a clear maintained page and internal connections. A category-defining claim may justify expert input, public evidence, PR outreach, and sustained social discussion.

    Should you hire a growth marketing agency for AEO?

    Hire one when it can solve a defined capability or coordination gap and work inside clear decision rights. Don’t outsource ownership of truth. Your organization should still approve claims, provide subject expertise, grant appropriate access, and know how success will be judged.

    For your next campaign, choose one consequential audience question and build the complete chain around it: a maintained answer, approved evidence, accurate structured data, coordinated distribution, and a logged measurement plan. That single working system will teach you more than adding another disconnected AEO task to every channel.

    References


  • How to Make Content Visible in Search and AI Answers

    Your page is indexed, technically sound, and even earns search impressions. Yet it rarely appears in AI answers, recommendations, or citation-style results. That usually isn’t a signal to add more keywords. It is a signal to find the exact point where discovery breaks.

    Content visibility is a chain: access, extraction, intent matching, evidence, selection, and measurement. If you diagnose those stages in order, you can make a targeted change instead of rewriting a useful page on instinct.

    Visibility is a chain, not a single ranking setting

    A search engine or AI system must first reach the URL. It then has to extract the main content, determine what the page is about, match it to a user’s need, and decide whether the material is suitable to surface or reuse. A failure at any stage can look like the same outcome: no visibility.

    This is why crawlability and AI visibility should be treated as related but separate requirements. Allowing a crawler through the door does not make an ambiguous page understandable. Clear writing and schema cannot compensate for a blocked, redirected, or non-indexable URL.

    Distribution is also more fragmented than a conventional rankings report implies. A dataset covering 42 million Google Discover cards from December 2025 through February 2026 identified 20 selecting pipelines organized into six broad layers: core editorial, news urgency, trends, local or geographic content, social or video content, and commercial content. The sample came from hundreds of devices, so it is a substantial snapshot, but it is not a permanent map of every Google or AI system.

    The practical lesson is narrower and more useful: different surfaces can select the same URL for different reasons. A traditional ranking, a Discover recommendation, and an AI citation should not be treated as three readings from one universal visibility score.

    Key takeaways

    • If a system cannot fetch the final page, content changes will not solve the problem.
    • If the title, description, opening, headings, and structured data imply different purposes, the page’s intent is unclear.
    • If important claims lack context, dates, ownership, or supporting links, the material is harder to evaluate and safely reuse.
    • Google Search Console queries show the demand already reaching each page, making them a better starting point than a speculative keyword list.
    • Search, Discover, referral traffic, brand mentions, and AI answer citations need separate measurements.

    Diagnose the earliest broken stage before rewriting

    Start with the URL, not the copy. Work through the following checks in order and stop when you find a material failure. There is little value in polishing an answer that the relevant systems cannot reliably retrieve.

    1. Confirm access. Open the public URL without an authenticated session. Check the response, redirects, canonical target, robots rules, and page-level indexing directives. Review any firewall, bot-management, or consent layer that could return a challenge instead of the article. If your organization blocks categories of crawlers, make that an explicit policy decision rather than an accidental side effect of a security preset.
    2. Inspect the extractable page. Make sure the main answer, headings, lists, links, and evidence exist in the delivered document. Do not assume every retrieval system will execute a client-side application exactly as a human browser does. Remove overlays and template elements that obscure the opening or make navigation look like the main content.
    3. Verify page identity. The title, meta description, visible heading, introduction, canonical URL, breadcrumbs, and structured data should describe the same resource. A page presented as a tutorial in one field and a product category in another creates unnecessary ambiguity.
    4. Compare the promise with real demand. In Google Search Console, inspect the queries associated with this specific URL. Group them by the job the searcher is trying to complete, such as learning, comparing, troubleshooting, evaluating, or buying. Then compare the dominant job with what the page promises near the top.
    5. Audit evidence and ownership. Mark claims that depend on a date, platform, version, dataset, or named organization. Add that context where it changes the answer. Identify the author or responsible publisher and link important factual claims to the material that supports them.
    6. Check each outcome separately. Review organic search performance, Discover exposure where applicable, observable AI referrals, brand mentions, and citations in a controlled set of answer prompts. One healthy channel does not prove that the others are healthy.

    The first failed stage determines the next action. Fix access before content. Fix a query-to-page mismatch before adding schema. Strengthen evidence and entity clarity when the page is reachable and relevant but difficult to quote or attribute. If all of those checks pass, improve distribution and measurement instead of forcing another rewrite.

    Use Search Console to measure the intent gap

    Most content briefs begin with the audience a business hopes to attract. Search Console shows the audience Google is already connecting to the page. The difference between those two groups is your intent gap.

    That gap is about meaning, not merely shared words. Vector embeddings can place queries and page descriptions in the same semantic space, allowing their distance to be scored. A documented implementation compares page-level Search Console queries with the page’s meta description and uses the distance to identify weak alignment.

    Treat such a score as a diagnostic proxy. It is not an official Google metric, it does not prove why a page ranks, and a high similarity score does not guarantee inclusion in an AI answer. Its value is prioritization: it helps you locate pages whose positioning is far from the demand already reaching them.

    A query-to-page workflow that does not require a special tool

    1. Export queries by page. Preserve impressions, clicks, position, page, and query so that demand remains attached to the URL receiving it.
    2. Separate different kinds of demand. Keep branded or navigational searches distinct from problem, comparison, and transaction-oriented searches. They represent different reasons for reaching the page.
    3. Cluster by user task. Group queries that ask for the same outcome even when they use different vocabulary. Do not create a separate intent simply because a synonym appears.
    4. Write the demand in one plain sentence. Complete the statement: People reaching this URL mainly want to… If several unrelated endings carry meaningful demand, the page may be trying to do too many jobs.
    5. Write the page promise. Read only the title, meta description, main heading, opening paragraphs, and section headings. Complete the statement: This page helps you… Use what is actually on the page, not what the content brief intended.
    6. Choose a structural response. Keep the positioning when promise and demand agree. Refocus the opening and headings when the right answer is buried. Expand the page when it omits a necessary subproblem. Split the page when distinct audiences or tasks require incompatible answers.

    Look for five common forms of mismatch:

    • Scope gap: searchers want an implementation answer, but the page stays at the strategy level.
    • Audience gap: the page addresses specialists while the queries come from beginners, or the reverse.
    • Stage gap: the page tries to sell while the dominant demand is educational, or teaches basics to people already comparing options.
    • Format gap: the query calls for steps, criteria, or troubleshooting, but the page provides a continuous essay.
    • Outcome gap: the copy describes a topic without resolving the decision or problem behind the query.

    Do not rewrite the meta description in isolation just to improve semantic similarity. It is useful because it expresses the page’s promise compactly. If that promise changes, make the same intent visible in the heading, introduction, body, internal links, and structured data. Otherwise, you have improved the label while leaving the resource unchanged.

    Build an answer asset without weakening the full page

    An AI-visible page still needs to work as a page. Compressing everything into short definitions may make individual sentences easy to extract, but it can remove the qualifications and evidence that make the answer trustworthy. Build a clear answer core, then support it with the depth the decision requires.

    Put the answer core near the top

    Answer the main question in direct language before moving into background. State who the answer applies to, what conditions change it, and what the reader should do next. If the subject requires a sequence, expose that sequence in an ordered list. If it requires choosing among options, name the decision criteria before describing every option.

    Use headings that identify an actual subproblem. A heading such as Diagnose the earliest broken stage tells a reader and a machine what the section resolves. Generic labels such as Overview or More information do not.

    Use structured data as clarification, not decoration

    Select the most accurate schema type for the visible resource. Mark up only information a visitor can verify on the page. Keep names, authorship, publisher identity, dates, breadcrumbs, and canonical references consistent across HTML and JSON-LD. When an organization or product appears across multiple pages, use stable identifiers and naming rather than creating slightly different versions of the same entity.

    Schema cannot repair a blocked URL, substitute for a missing answer, or make unsupported claims trustworthy. Its useful role is disambiguation: it helps a system interpret the type of resource and the relationships already expressed in the visible content.

    Make provenance part of the answer

    Durable visibility in generative systems depends partly on consistent metadata, provenance, and trust signals. Give time-sensitive claims a date or version. Name the organization responsible for the content. Link to the originating evidence when a factual claim depends on it. Distinguish observed facts from your recommendation.

    This is not a request to add a long author biography to every page. It is a request to remove uncertainty that matters. A reader should be able to tell who is making the claim, when it applies, what supports it, and whether it is a fact, interpretation, or recommendation.

    Package the content for its genuine distribution context

    The measured Discover environment separated selection into layers for editorial content, urgent news, trends, local material, social or video content, and commercial content. It also evaluated pipelines by reach, speed, exclusivity, and feed volume. Those dimensions explain why a URL can have broad reach, fast pickup, or exclusive distribution without performing identically across every surface.

    Use only the attributes your content genuinely has. Preserve geographic specificity when the answer is local. Make publication and update context clear when timing changes the value. Treat an original video as a first-class resource when video is integral to the answer. Do not imitate urgency, locality, or trend relevance that the page cannot substantiate.

    Measure search and AI visibility as a portfolio

    A single visibility percentage collapses different systems, intents, and outputs into a number that is hard to act on. Use a small scorecard that keeps the stages separate:

    LayerWhat to recordWhat a weakness meansFirst response
    AccessPublic response, redirects, canonical, robots rules, indexing directives, and extractable main contentThe resource may not be consistently retrievable or eligibleFix the technical path before editing copy
    Search demandPage-level queries, impressions, clicks, and position from Search ConsoleDemand may be weak, changing, or attached to a different intentInspect query clusters and competing pages
    Intent fitAlignment between dominant query tasks and the title, description, opening, and headingsThe page promise does not match the audience reaching itDefend, refocus, expand, or split the page
    Answer readinessDirect answer, qualifications, evidence links, author or publisher, dates, and consistent structured dataThe material may be relevant but difficult to interpret, attribute, or reuseClarify the answer and its provenance
    AI presenceMentions and citations from a versioned set of prompts, plus identifiable referral traffic where availableThe page is not being selected consistently in the observed answer environmentCheck intent, evidence, entity clarity, and competing answer formats
    Discovery distributionDiscover or recommendation exposure reported separately from standard searchA distribution surface may value different timing, format, or contextual signalsImprove truthful packaging for that surface

    For AI answer checks, record the full prompt, engine, date, locale, and any account state that could affect the output. Reuse the same prompt set when evaluating a change. A single answer is an observation, not a trend, and it should not trigger a site-wide rewrite.

    Keep a change log for the URL. Record whether you altered access rules, positioning, the answer core, evidence, structured data, or distribution packaging. Then compare equivalent periods and inspect the metrics closest to the stage you changed. If you modify every layer at once, any improvement will be difficult to explain or repeat.

    Choose one page with meaningful Search Console impressions and uncertain AI visibility. Run the diagnostic from access through measurement, fix the earliest material failure, and document that change. That gives you a defensible optimization process you can apply to the next page instead of another collection of AI SEO guesses.

    References


  • AI Search Visibility When Referrals and Rankings Diverge

    AI Search Visibility When Referrals and Rankings Diverge

    If your organic sessions are falling while your brand still appears in AI answers, you do not have one visibility problem. You have at least three: whether machines can access your content, whether answer systems select it, and whether people visit after seeing it.

    Those stages need different measurements and different fixes. Separate them, and you can tell whether to improve a page, investigate a ranking change, strengthen attribution, or restrict a crawler before it consumes more value than it returns.

    Key takeaways

    • Measure content access, AI mentions and citations, referral sessions, and business outcomes separately. A lost click is not automatically lost visibility.
    • Diagnose impressions, rankings, click-through rate, and AI referrals before editing content. Ranking loss and referral loss can happen together, but they are not the same failure.
    • Give answer systems a clear, supportable answer while giving people a practical reason to visit, such as a workflow, template, decision tool, original data, or implementation detail.
    • Classify bots by identity and business role. Allow, rate-limit, license, challenge, or block them according to their value, cost, and contractual status.

    Build a visibility ledger that follows the whole journey

    An isometric table shows a document moving through connected access, selection, citation, and visitor stages.

    Sessions used to serve as a rough proxy for search visibility because discovery commonly led to a results page and then a click. An AI interface can now retrieve a page, use its information, mention its brand, cite its URL, and still satisfy the user without sending a visit. One traffic graph cannot show which of those events occurred.

    Use a ledger with three distinct stages:

    • Access: a search crawler, training crawler, or real-time fetcher can retrieve the page.
    • Selection: an answer system uses the information, mentions the brand, or links to the page.
    • Referral and value: the user visits, engages, subscribes, generates a lead, or completes another meaningful action.

    The distinction matters because the gap can be severe. Akamai measured application-layer traffic across websites, apps, and APIs from July through December 2025 and found AI bot activity up 300% during 2025. Within that analysis, AI-chatbot referrals delivered about 96% less traffic than traditional search, while only about 1% of users clicked sources cited in AI answers. Treat those figures as directional evidence, not universal benchmarks: your result will depend on your audience, query mix, business model, and the interfaces that expose your content.

    LayerRecordWhat a change can indicateFirst response
    Traditional search exposureImpressions, query, landing page, market, and average positionChanges in demand, ranking, eligibility, or query mixSegment the loss before changing pages
    Traditional search referralClicks, click-through rate, sessions, and landing-page outcomesA difference between being shown and being chosenInspect result presentation, search features, intent, and page promise
    AI selectionAccurate brand mentions, linked citations, cited URLs, and factual errors across a fixed prompt setWhether the brand is represented and whether an owned page receives attributionCheck entity clarity, answer structure, evidence, and page accessibility
    AI referralRaw referrer, channel, landing page, engagement, conversion, and revenue where availableWhether observed visibility produces visits and business valueImprove the post-answer reason to visit and the landing experience
    Machine-access costVerified agent identity, requests, pages fetched, bandwidth, cache use, and origin loadWhether retrieval consumes infrastructure without a corresponding benefitAllow, rate-limit, license, challenge, or block by bot class

    For AI selection, build a repeatable prompt panel rather than collecting convenient screenshots. Include the questions that matter at each stage of your customer’s decision, then preserve the exact prompt, interface, language, market, date, response, mention, citation, and cited URL. If you operate across languages or countries, maintain separate panels; visibility in one market does not establish visibility in another.

    1. Choose prompts from real search queries, support questions, sales objections, and tasks associated with your important pages.
    2. Run the same prompts under comparable conditions. Changing the wording and the interface at the same time makes the result difficult to interpret.
    3. Record an accurate mention separately from a linked citation. A brand can be visible without receiving an owned link.
    4. Check whether the answer represents the brand, product, author, and claim correctly. An inaccurate mention is not a visibility win.
    5. Annotate content releases, schema changes, crawler-policy changes, major deployments, and confirmed search updates beside the results.

    Create simple rates from this ledger: prompts with an accurate mention divided by prompts checked; prompts with an owned citation divided by prompts checked; and AI-referred conversions divided by identifiable AI-referred sessions. Keep the underlying counts beside every rate. A perfect percentage from a tiny or changing prompt set can create more confidence than the measurement deserves.

    Normalize recognizable AI referrers into a reporting channel, but preserve the raw referrer and landing page. Do not depend on campaign parameters for links you do not control. Some interfaces expose little or no useful referral information, so analytics should be treated as the observable portion of AI traffic, not a complete census of AI influence.

    Separate ranking loss from click loss before editing content

    A traffic decline near an algorithm update invites a quick rewrite. That can destroy useful evidence and change the page before you know what failed. Start by marking the rollout window. The March 2026 Google core update ran from March 27 through April 8, finishing after 12 days and 4 hours. A comparison that mixes rollout days with stable periods cannot cleanly separate the before and after states.

    1. Annotate the confirmed update window and every important site change, including migrations, template releases, internal-link changes, rendering changes, and crawler rules.
    2. Compare matched periods outside the rollout. Account for normal seasonality, promotions, and demand changes that affect the same queries.
    3. Segment by query group, page type, directory, market, and device. Sitewide averages can conceal a concentrated loss in one template or topic.
    4. Inspect impressions, position, clicks, and click-through rate together. Then compare those patterns with your sampled AI visibility and AI-referral data.
    5. Review the affected page group only after the failure mode is visible. Preserve an export or snapshot before making material changes so you can evaluate and reverse them.

    Use the pattern, not one metric, to choose the next action:

    • If impressions and positions decline for the same queries and pages, investigate a ranking, relevance, eligibility, or demand problem. Do not assume that a lower sitewide average tells you which one.
    • If impressions remain broadly stable while clicks and click-through rate decline, the result is still being shown but fewer searchers are choosing it. Inspect the result-page features, title and snippet promise, intent fit, and competing ways the query is answered.
    • If traditional search remains stable while sampled AI citations or identifiable AI referrals decline, check machine access, citation selection, brand ambiguity, and measurement coverage before rewriting the page.
    • If sessions decline but qualified leads, subscriptions, or revenue do not, quantify the commercial effect before setting a traffic-restoration target. Not every lost informational click has the same value.
    • If several layers decline at once, keep separate workstreams. A content review cannot repair broken bot access, and a crawler rule cannot make an unsatisfying page more useful.

    Google’s standing position is that a core-update decline does not necessarily mean something is wrong with the site, and meaningful recovery may depend on a later update. That is a reason to avoid panicked reversals, not a reason to wait passively. Review whether affected pages deliver helpful, reliable, people-first information, especially where the page promise and the actual answer have drifted apart.

    Create pages that can be cited and still deserve a visit

    Trying to withhold the basic answer is a poor response to zero-click search. It frustrates readers and leaves answer systems with weaker material to interpret. State the answer clearly, support it, and make the rest of the page valuable after the answer is known.

    A citation-ready, visit-worthy page usually needs these layers:

    • A decisive answer: address the page’s main question directly instead of making the reader extract it from a long preamble.
    • Scope and qualifiers: state the country, language, platform, version, date, audience, or conditions that change the answer. A technically correct statement can still mislead when its scope is hidden.
    • Evidence: connect important claims to their originating authority, underlying data, or documented method. Distinguish a fact from an inference or editorial recommendation.
    • Entity clarity: use consistent names for the organization, product, author, location, and service. Explain relationships that a reader should not have to infer from branding alone.
    • A decision layer: show trade-offs, applicability, exclusions, and common misreadings so the reader can decide whether the answer fits their situation.
    • An action layer: provide the procedure, checklist, template, calculator, original data, implementation detail, or troubleshooting path that helps the reader complete the task.

    This structure makes the central claim easy to identify without turning the page into a disposable definition. The answer earns selection; the decision and action layers earn the visit.

    JSON-LD can clarify what a page represents, but it is not a referral strategy and it does not guarantee selection in an AI answer. Use the schema type that matches the visible content, connect related entities consistently, and validate the markup after publishing. Do not place claims, reviews, authorship, dates, or relationships in structured data that the page itself does not support.

    Apply the same discipline to freshness. Show a meaningful update date when the substance changed, identify version-dependent instructions, and remove contradictions between the page, its metadata, and its structured data. Changing a date without revising stale information creates a freshness signal for the editor, not new value for the reader.

    Before consolidating or unpublishing a weak page, check its inbound links, internal links, ranking queries, citations, conversions, and role in a topic cluster. Preserve a copy and plan the appropriate destination before removing a URL. A careless cleanup can erase authority or break an existing citation even when raw sessions look unimportant.

    Turn AI crawler access into an explicit business policy

    A person controls open, metered, and closed gates between geometric crawler machines and a secure digital archive.

    More machine access does not automatically produce more discovery, attribution, or revenue. It can also increase server and CDN costs. The 300% rise in AI bot activity observed during 2025 makes bot classification an operating issue, not merely a security log to review after something breaks.

    Start by separating training crawlers, which collect material for model development, from real-time fetchers, which retrieve current content to answer a live request. Their timing, potential value, and commercial relationship differ. A single allow-or-block rule ignores those differences.

    Bot classPossible business rolePolicy optionsMain risk to check
    Search or discovery crawlerMakes pages eligible for a discovery surfaceVerify and allow under controlled limitsBlocking can remove a path to visibility
    Authenticated licensed agentAccesses content under agreed commercial termsAllow only within authenticated scope and limitsUnverified requests may exceed the agreement
    Real-time answer fetcherRetrieves current information for an immediate answerAllow, rate-limit, or license according to measured value and costFresh content may be consumed without useful attribution or referral
    Training crawlerCollects content for model developmentAllow, block, or license according to rights and commercial policyDirect referral value may be weak or unobservable
    Unknown or abusive scraperNo verified legitimate roleChallenge, rate-limit, block, or cautiously tarpitSpoofed identities and false positives can misclassify traffic

    A user-agent string is a claim, not proof. Where an operator publishes a verification method, use it. Keep agent identity, request behavior, targeted URLs, bandwidth, origin load, and any referral or licensing value in the same review. That turns a vague bot debate into a policy decision supported by observable costs and benefits.

    1. Observe before enforcing. Establish which agents request which page groups and how much infrastructure they consume.
    2. Verify identity. Do not grant privileged access or apply a punitive rule solely from a self-declared bot name.
    3. Assign a role. Record whether the agent supports discovery, live answering, training, a licensed relationship, or no recognized purpose.
    4. Choose the least disruptive effective control. Options include scoped access, caching, rate limits, authentication, challenges, blocking, and carefully tested tarpitting.
    5. Stage material changes with a rollback path. Watch crawl activity, indexation, sampled AI citations, referrals, server load, and user errors after enforcement.
    6. Review licensing and content-rights terms with appropriate legal counsel before charging for access or signing an agreement. A crawler configuration cannot determine ownership or contractual rights.

    Robots directives can communicate preferences to compliant agents, but they are not authentication or an access-control wall. Enforce sensitive or paid access with controls that can identify and authorize the requesting agent. If you use tarpitting, apply it only after careful classification: deliberately slowing the wrong traffic can harm legitimate discovery or user-facing performance.

    Emerging approaches such as Know Your Agent identity verification and TollBit pay-per-crawl access are intended to turn retrieval into an authenticated, manageable transaction. Treat that model as an option to evaluate, not guaranteed replacement revenue. The commercial case still depends on enforceable identity, demand for your content, contract terms, delivery cost, and the value of any visibility you give up by restricting access.

    Your next move should come from the first broken link in the chain. Build the ledger, mark known update and deployment dates, test the questions that matter, and classify the agents consuming your pages. Then change one layer at a time and keep a rollback path. That is how you protect visibility without mistaking every lost click for a lost audience.

    References